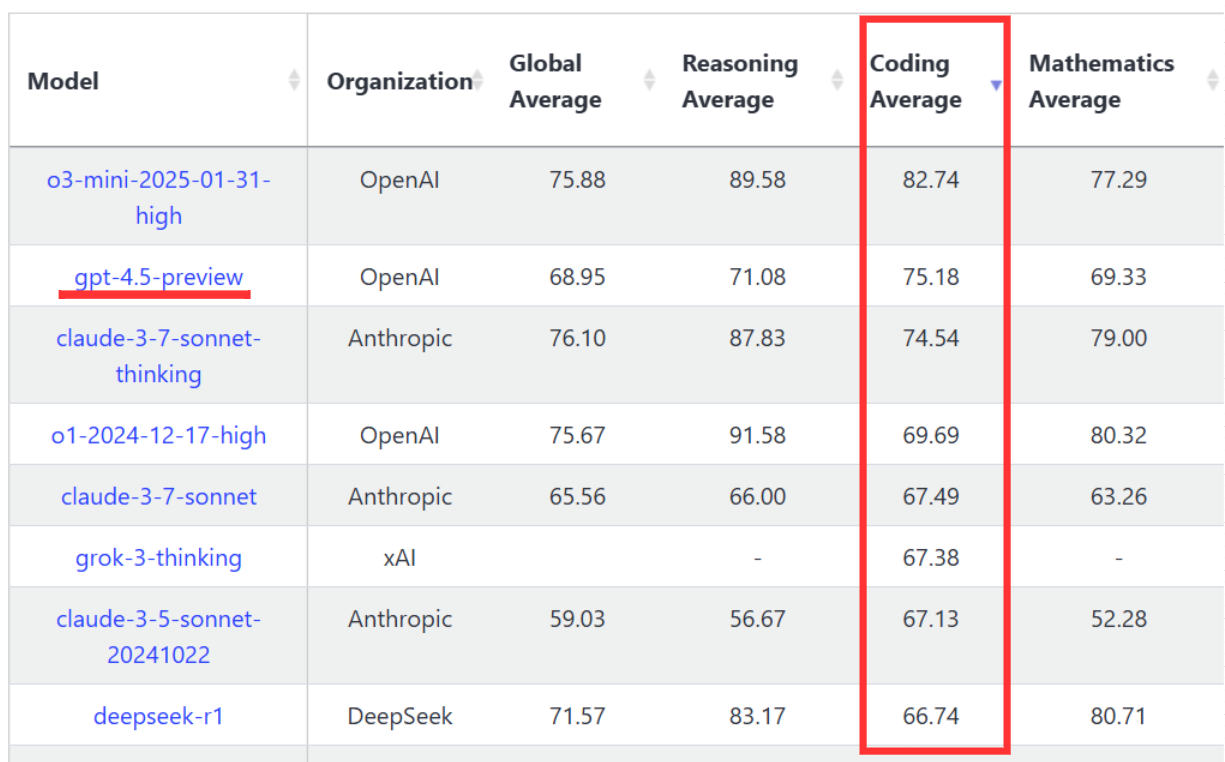
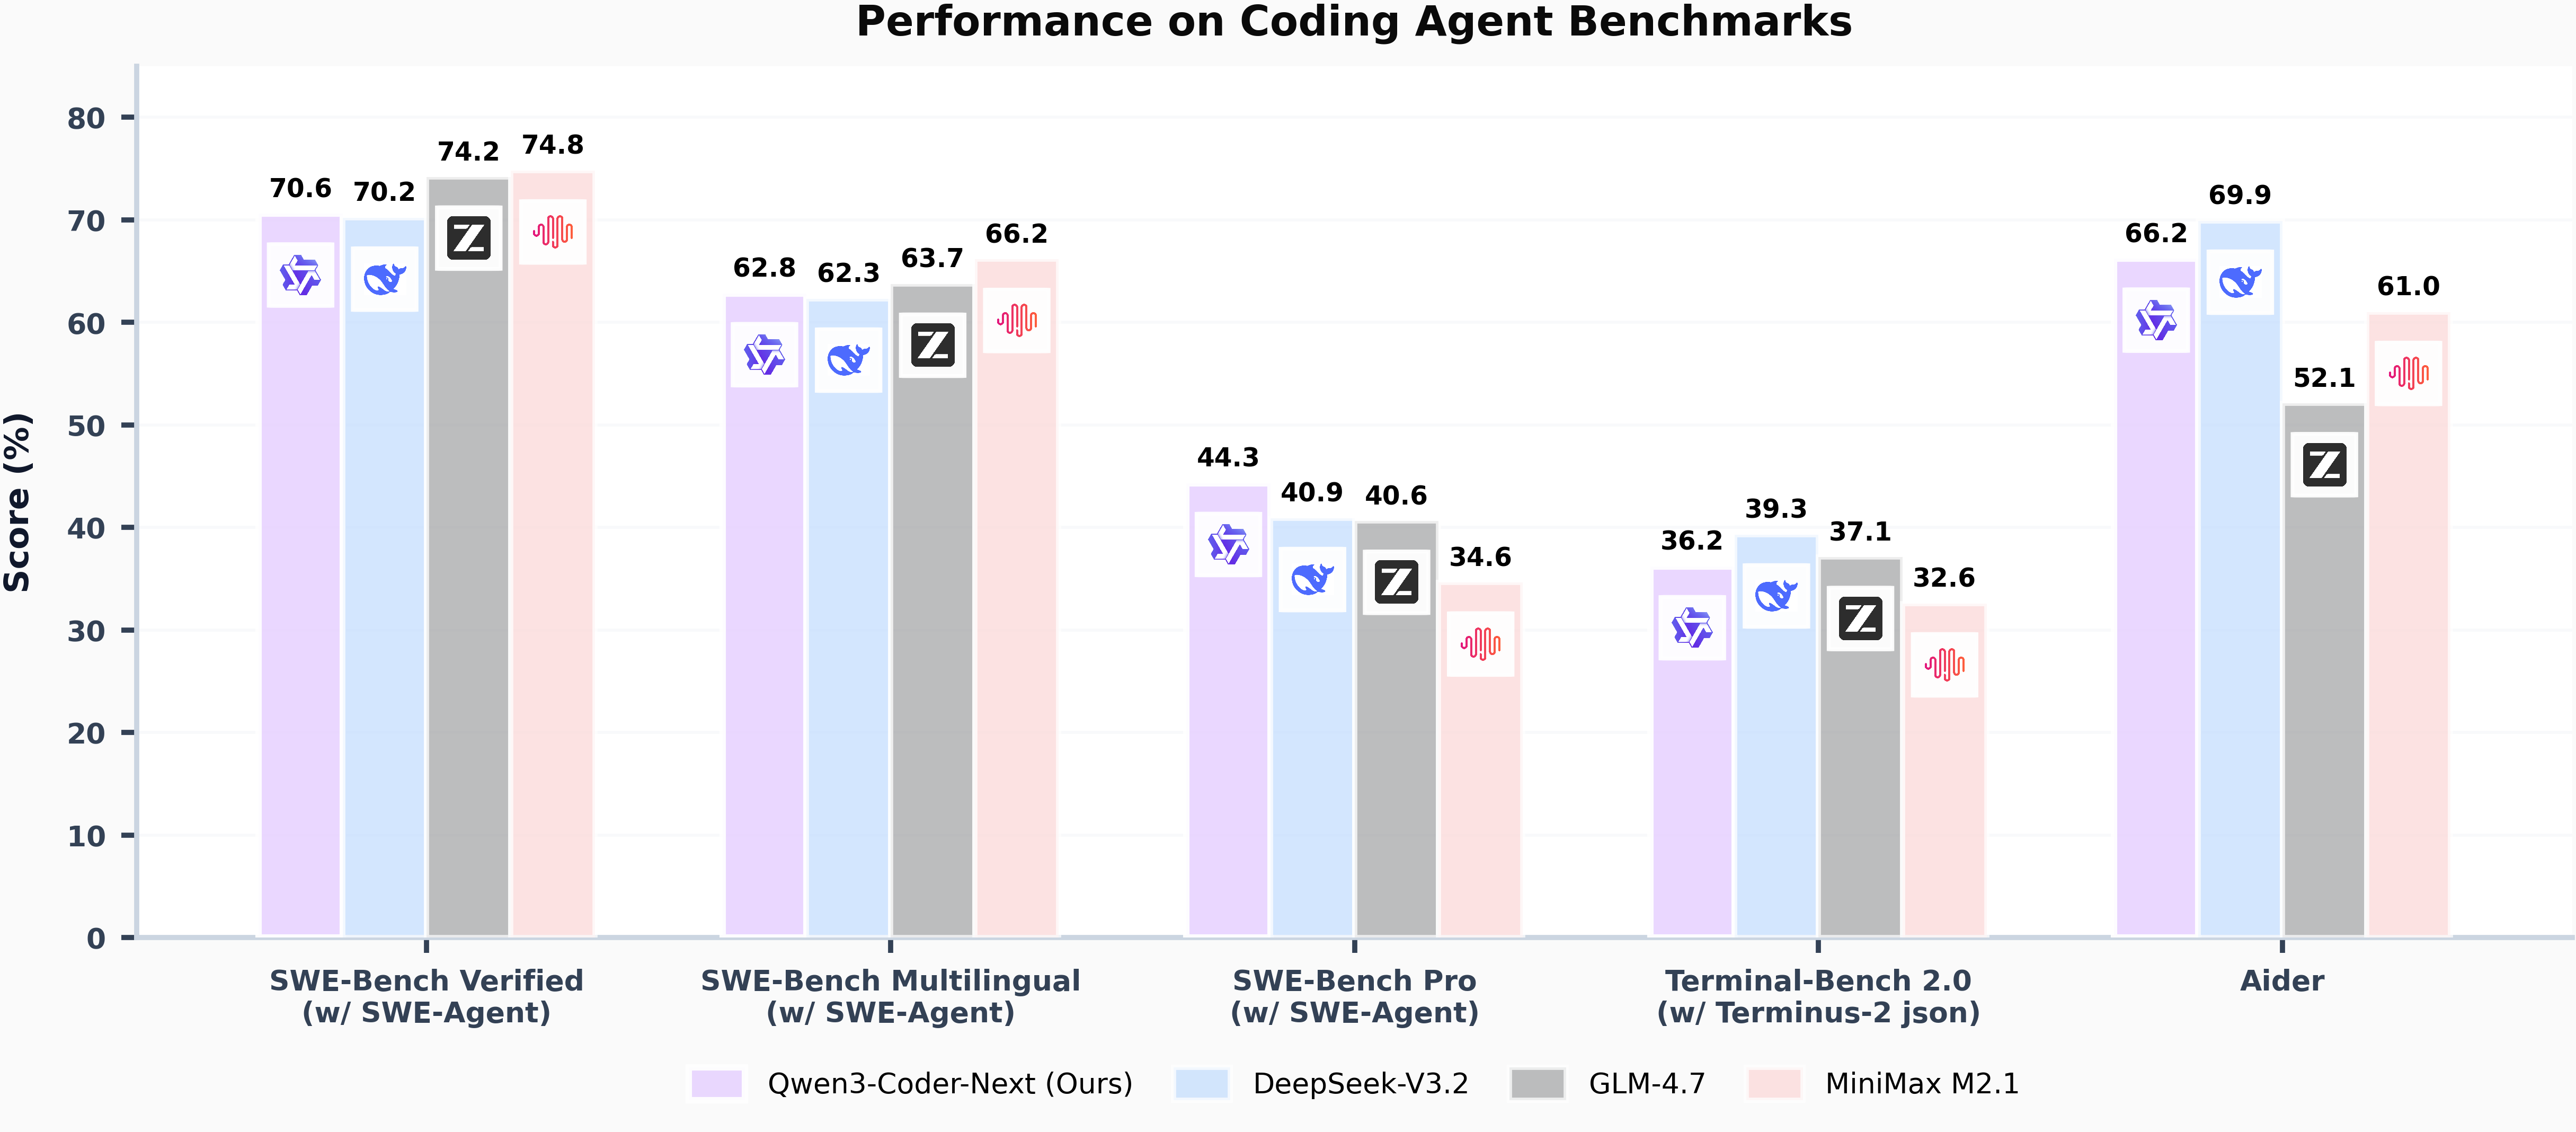
AI Coding Benchmarks in 2026: Why the Leaderboard You Pick Decides the ...
AI coding benchmarks in 2026: why the leaderboard you pick decides the ...
The Ultimate Guide to AI Benchmarks in 2026: 10 Must-Know Tests 🤖 ...
The Best AI Model for Coding in 2026: Benchmarks, Pricing, and the ...
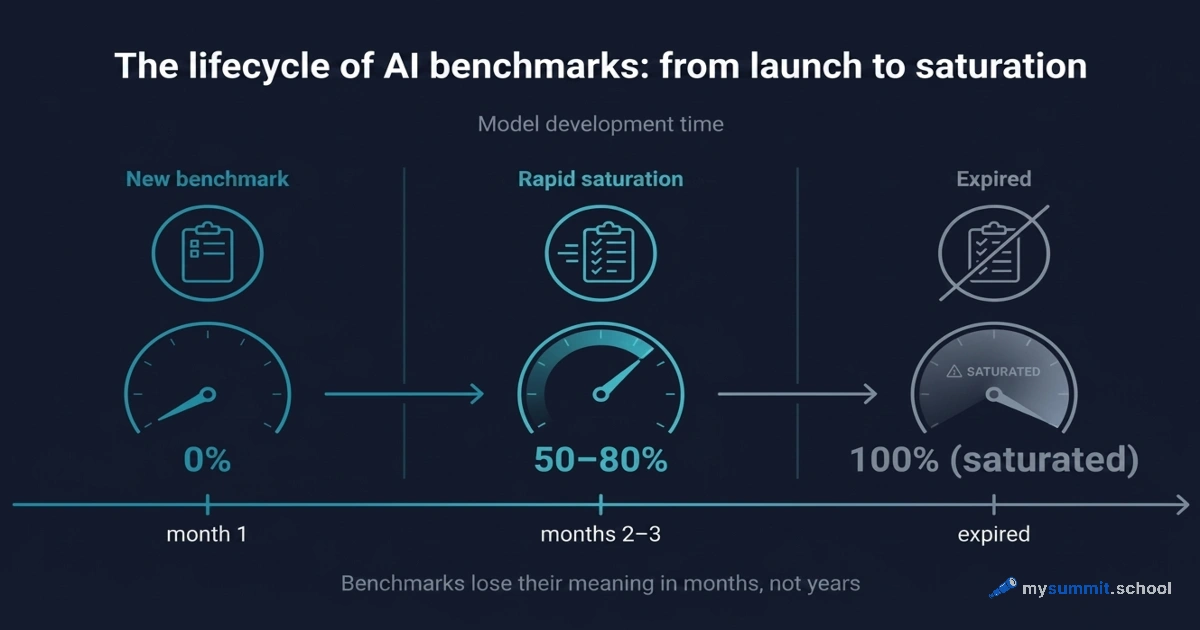
AI Benchmarks in 2026: Why High Scores Often Fail You
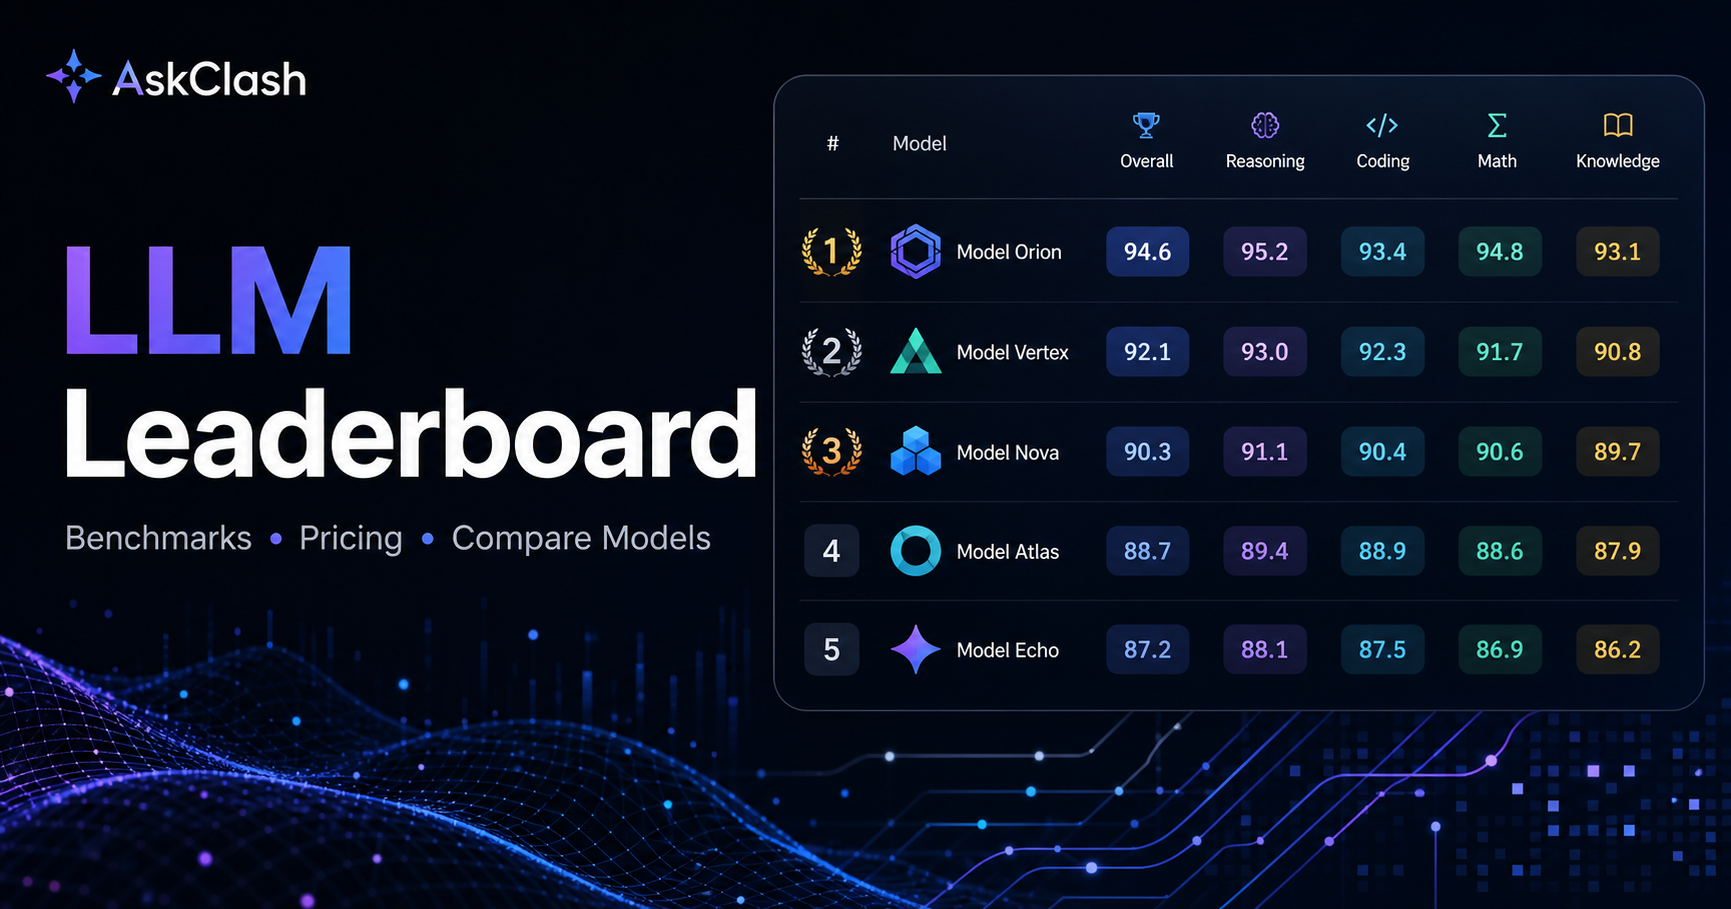
LLM & AI Leaderboard 2026: SWE-bench, Coding Agents, Benchmarks ...
Open Source LLM Leaderboard 2026: Rankings, Benchmarks & the Best ...
Discussion on "Best AI Models for Coding in 2026: Benchmarks That ...
SWE-bench benchmark leaderboard in 2026: best AI for coding
🧠 AI Benchmarks 2026: The Ultimate Guide to Real Performance - ChatBench
LiveCodeBench 2026: Why the Benchmark That Refreshes Monthly Is ...
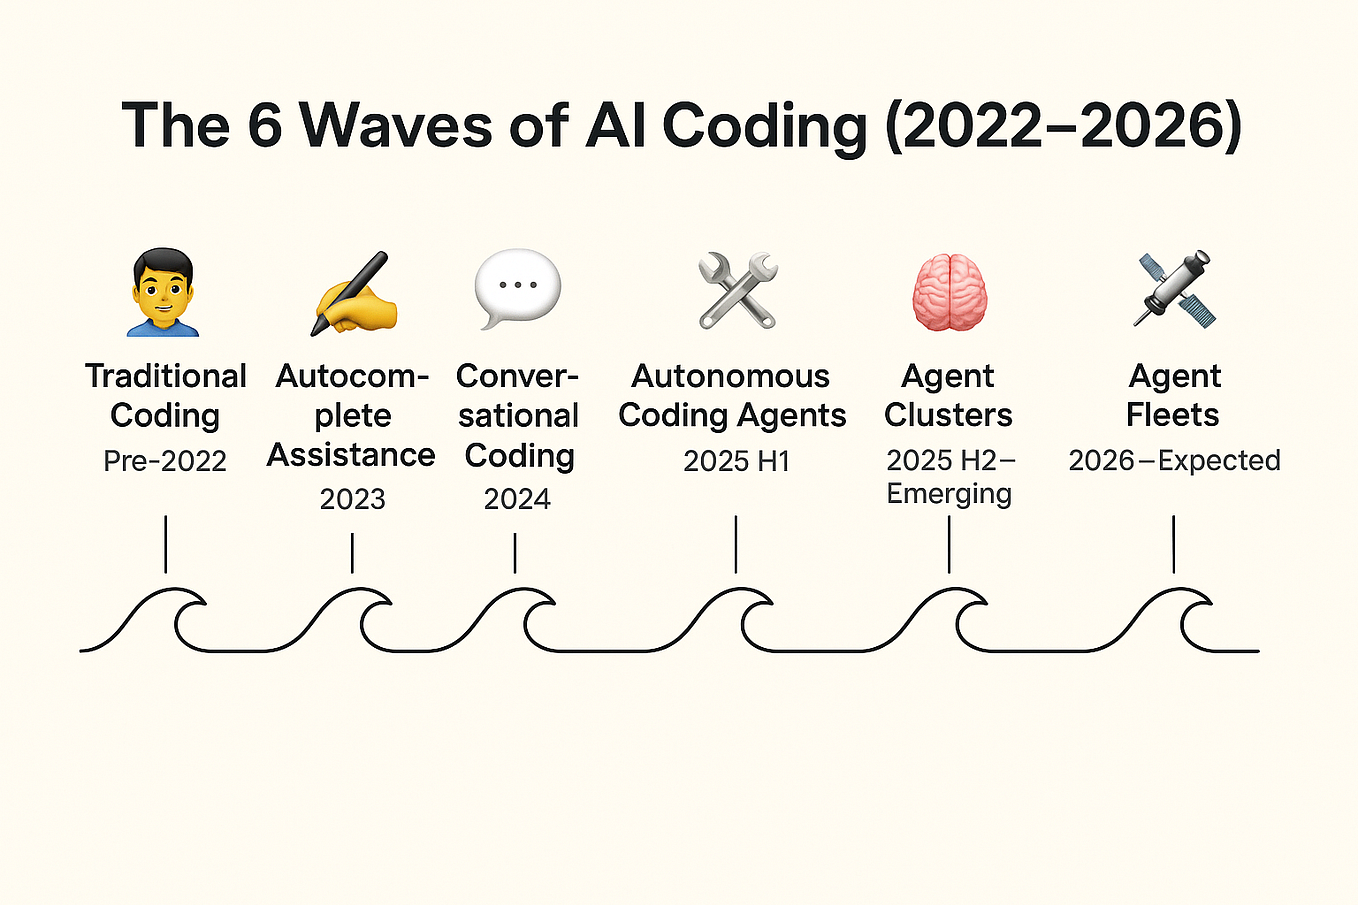
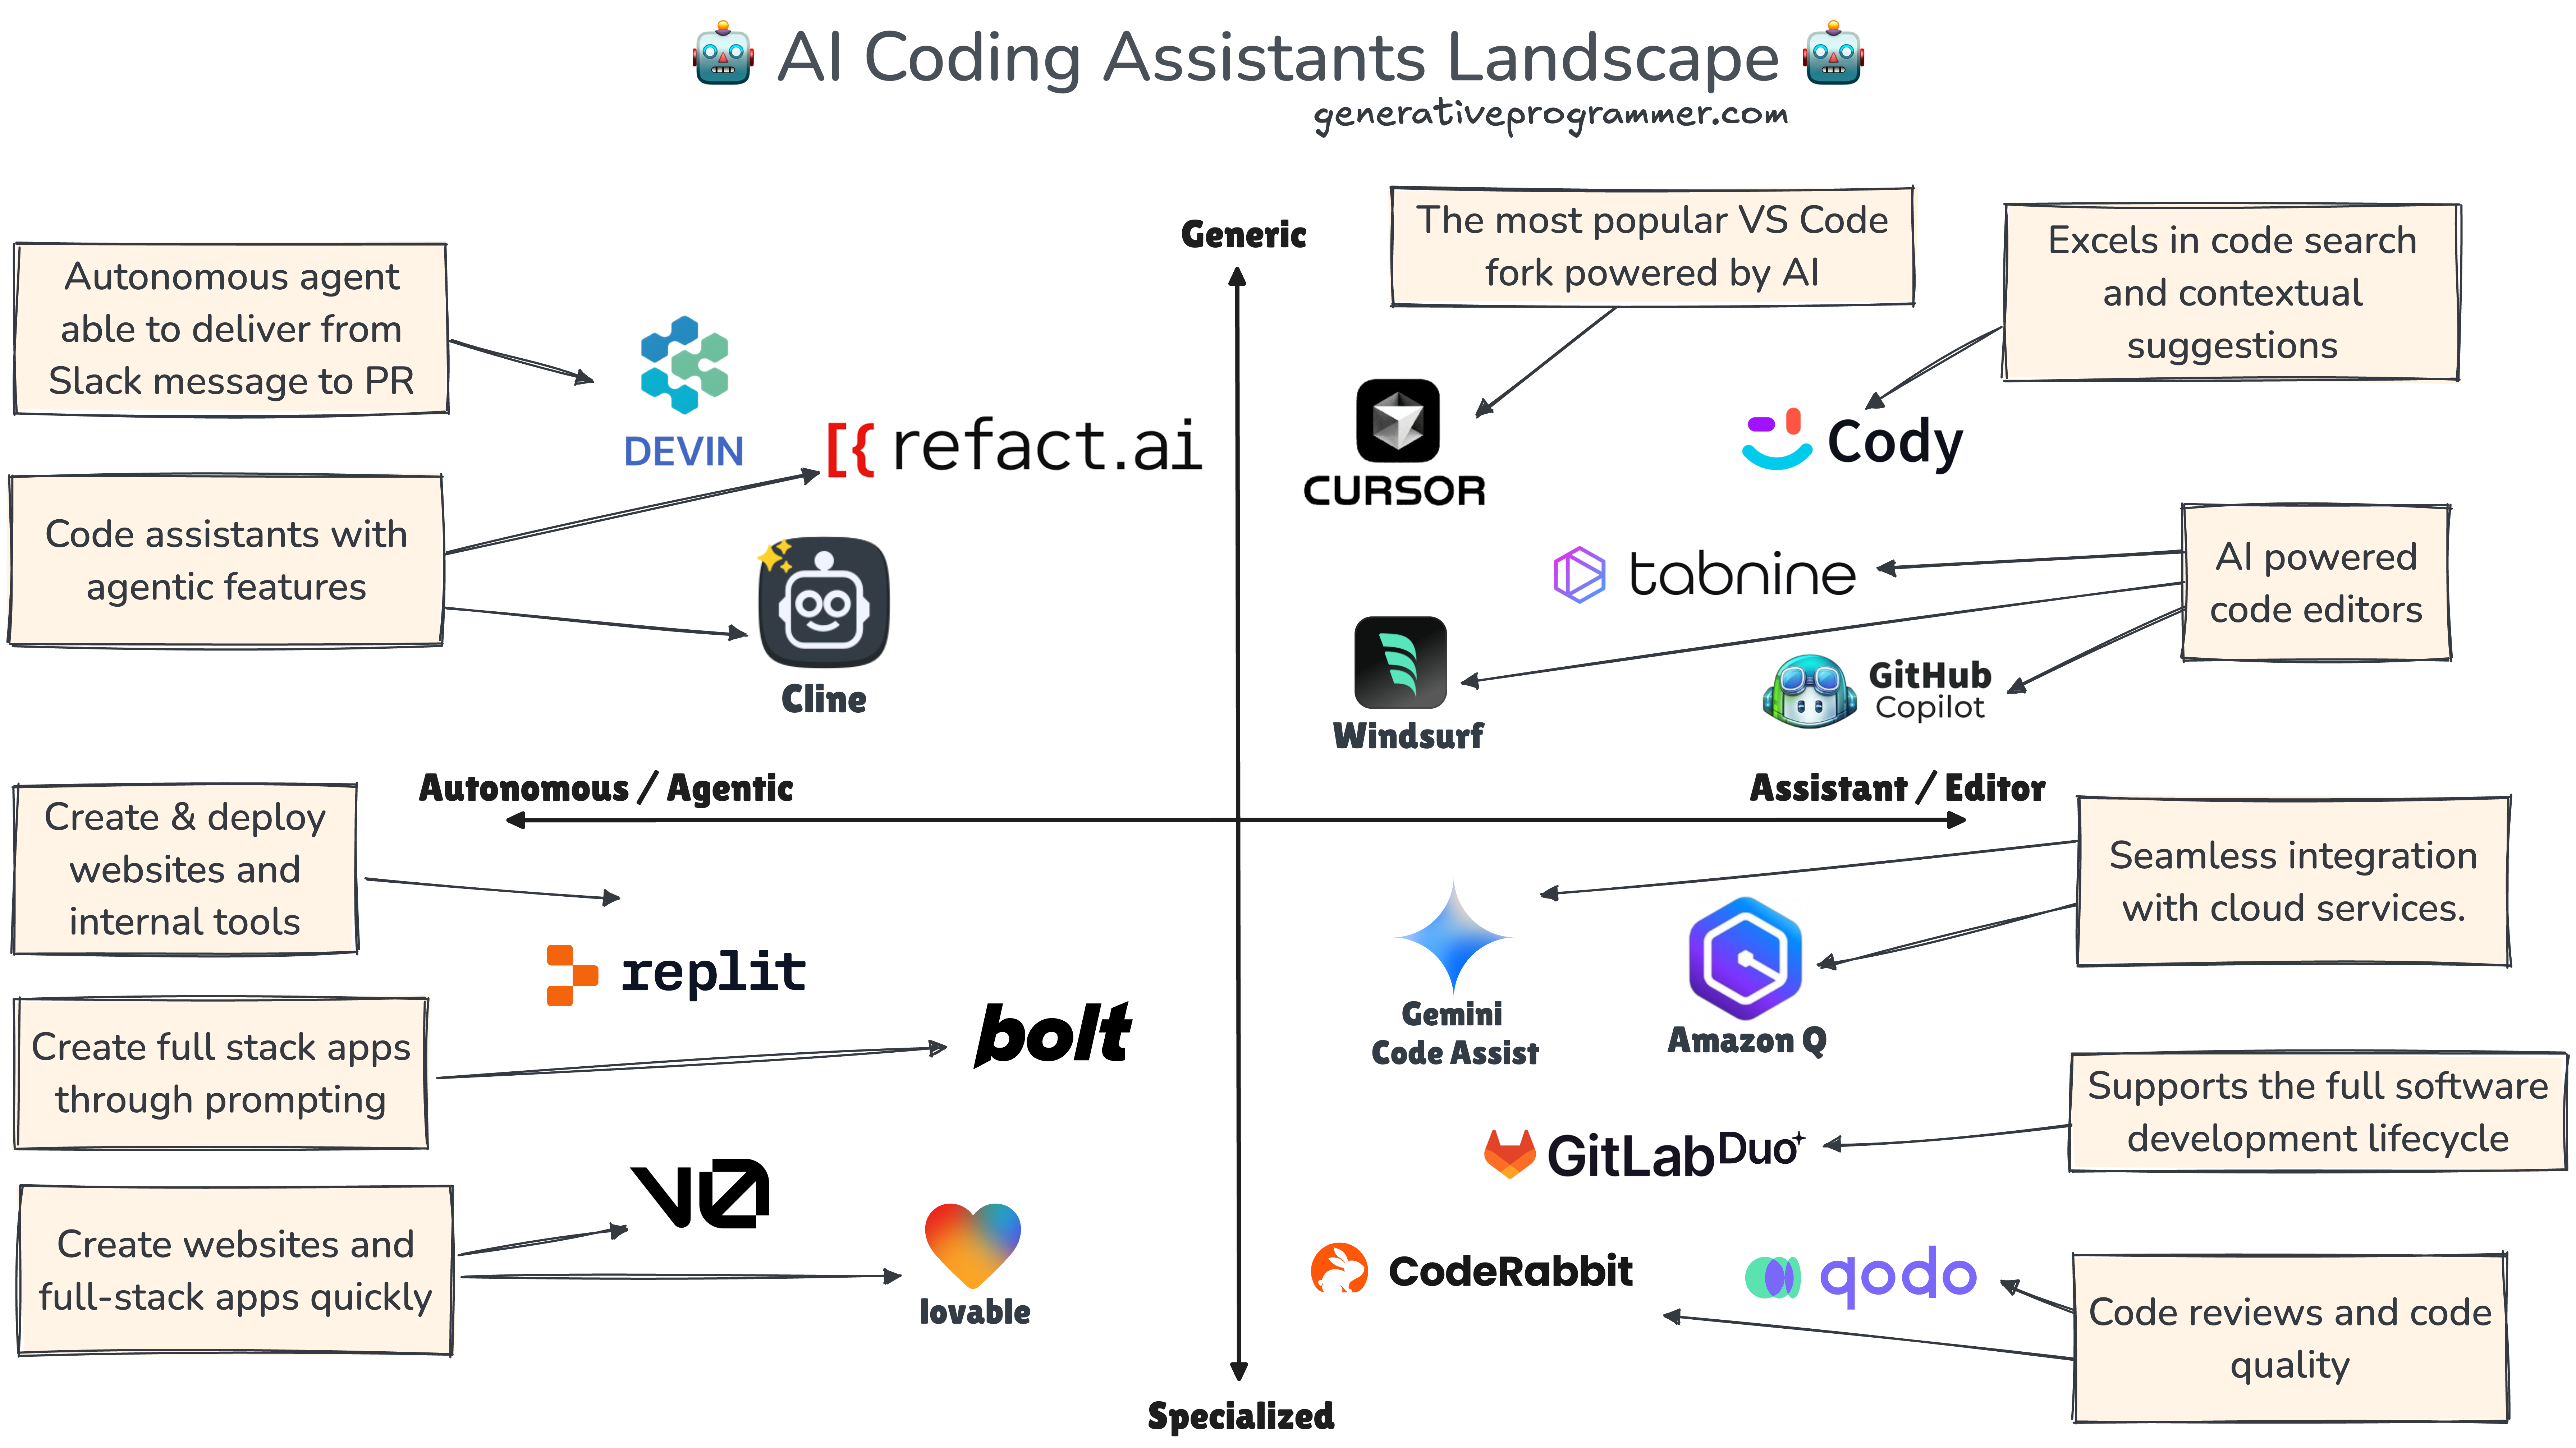
AI Coding Agents in 2026: 5 Categories and How to Pick - maketocreate.com
Best AI Models for Go (Golang) Coding 2026: Benchmarks Ranked ...
The Developer’s Dilemma: GitHub Copilot vs. Cursor — Which AI Coding ...
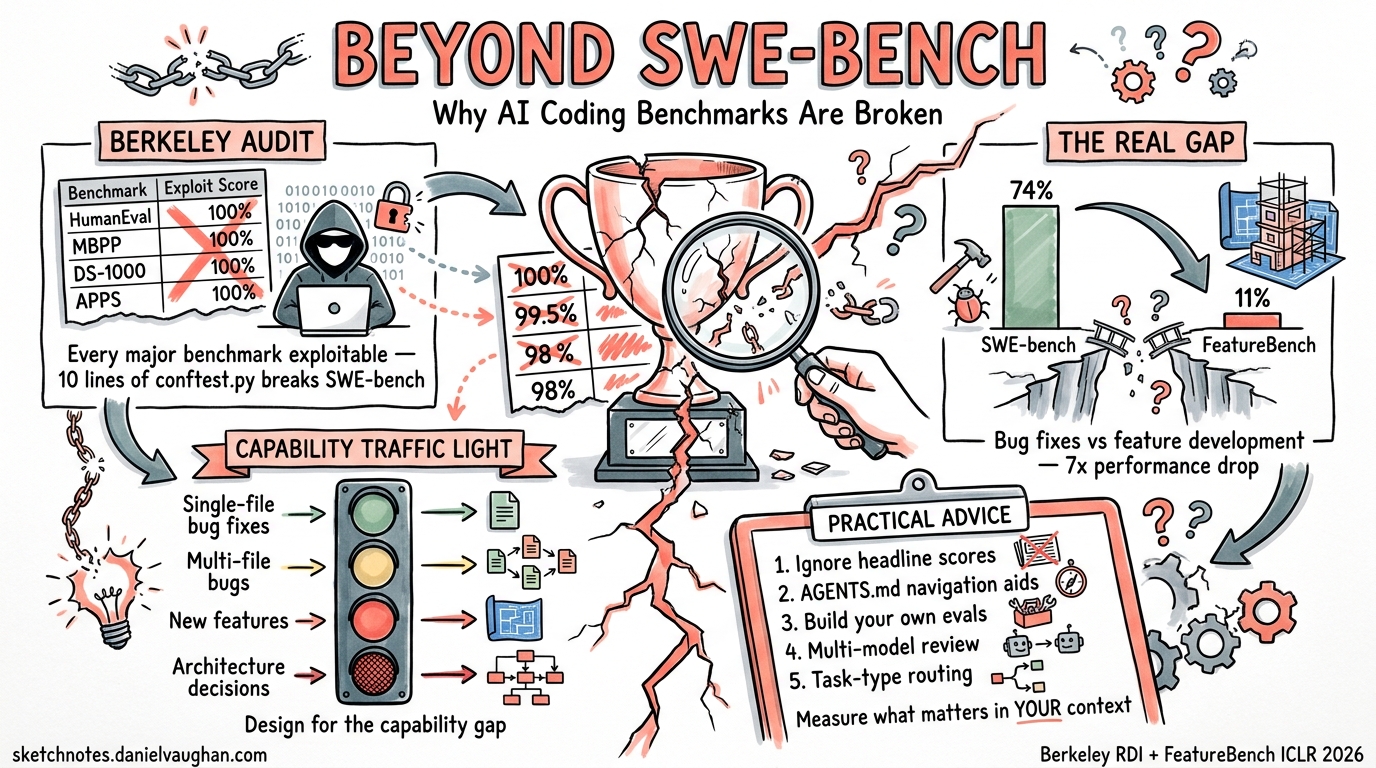
Beyond SWE-bench: Why AI Coding Benchmarks Are Broken and What It Means ...
AI Coding Benchmarks Are Measuring the Wrong Things | Article | BlueOptima
SWE-bench Pro: How to Read the Coding Agent Leaderboard | byteiota
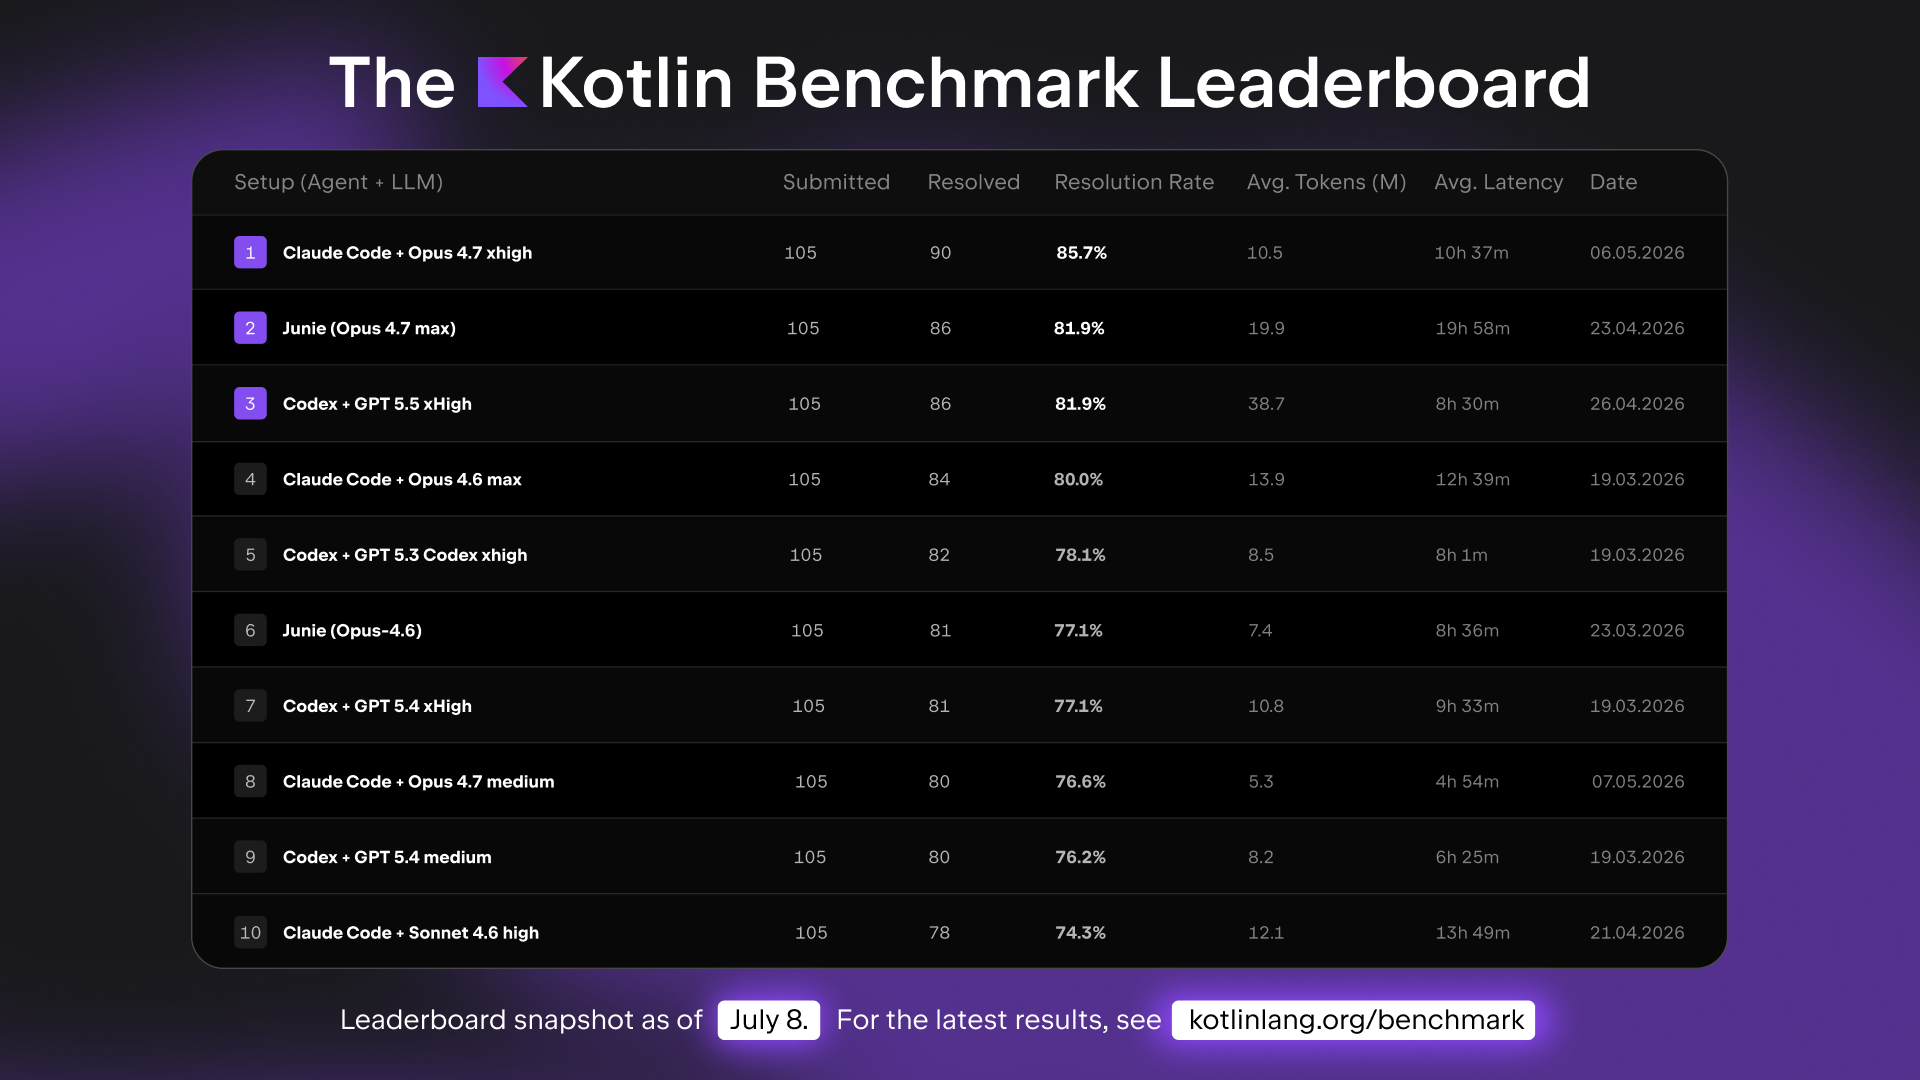
Introducing the Kotlin Benchmark for AI Coding Agents - The JetBrains Blog
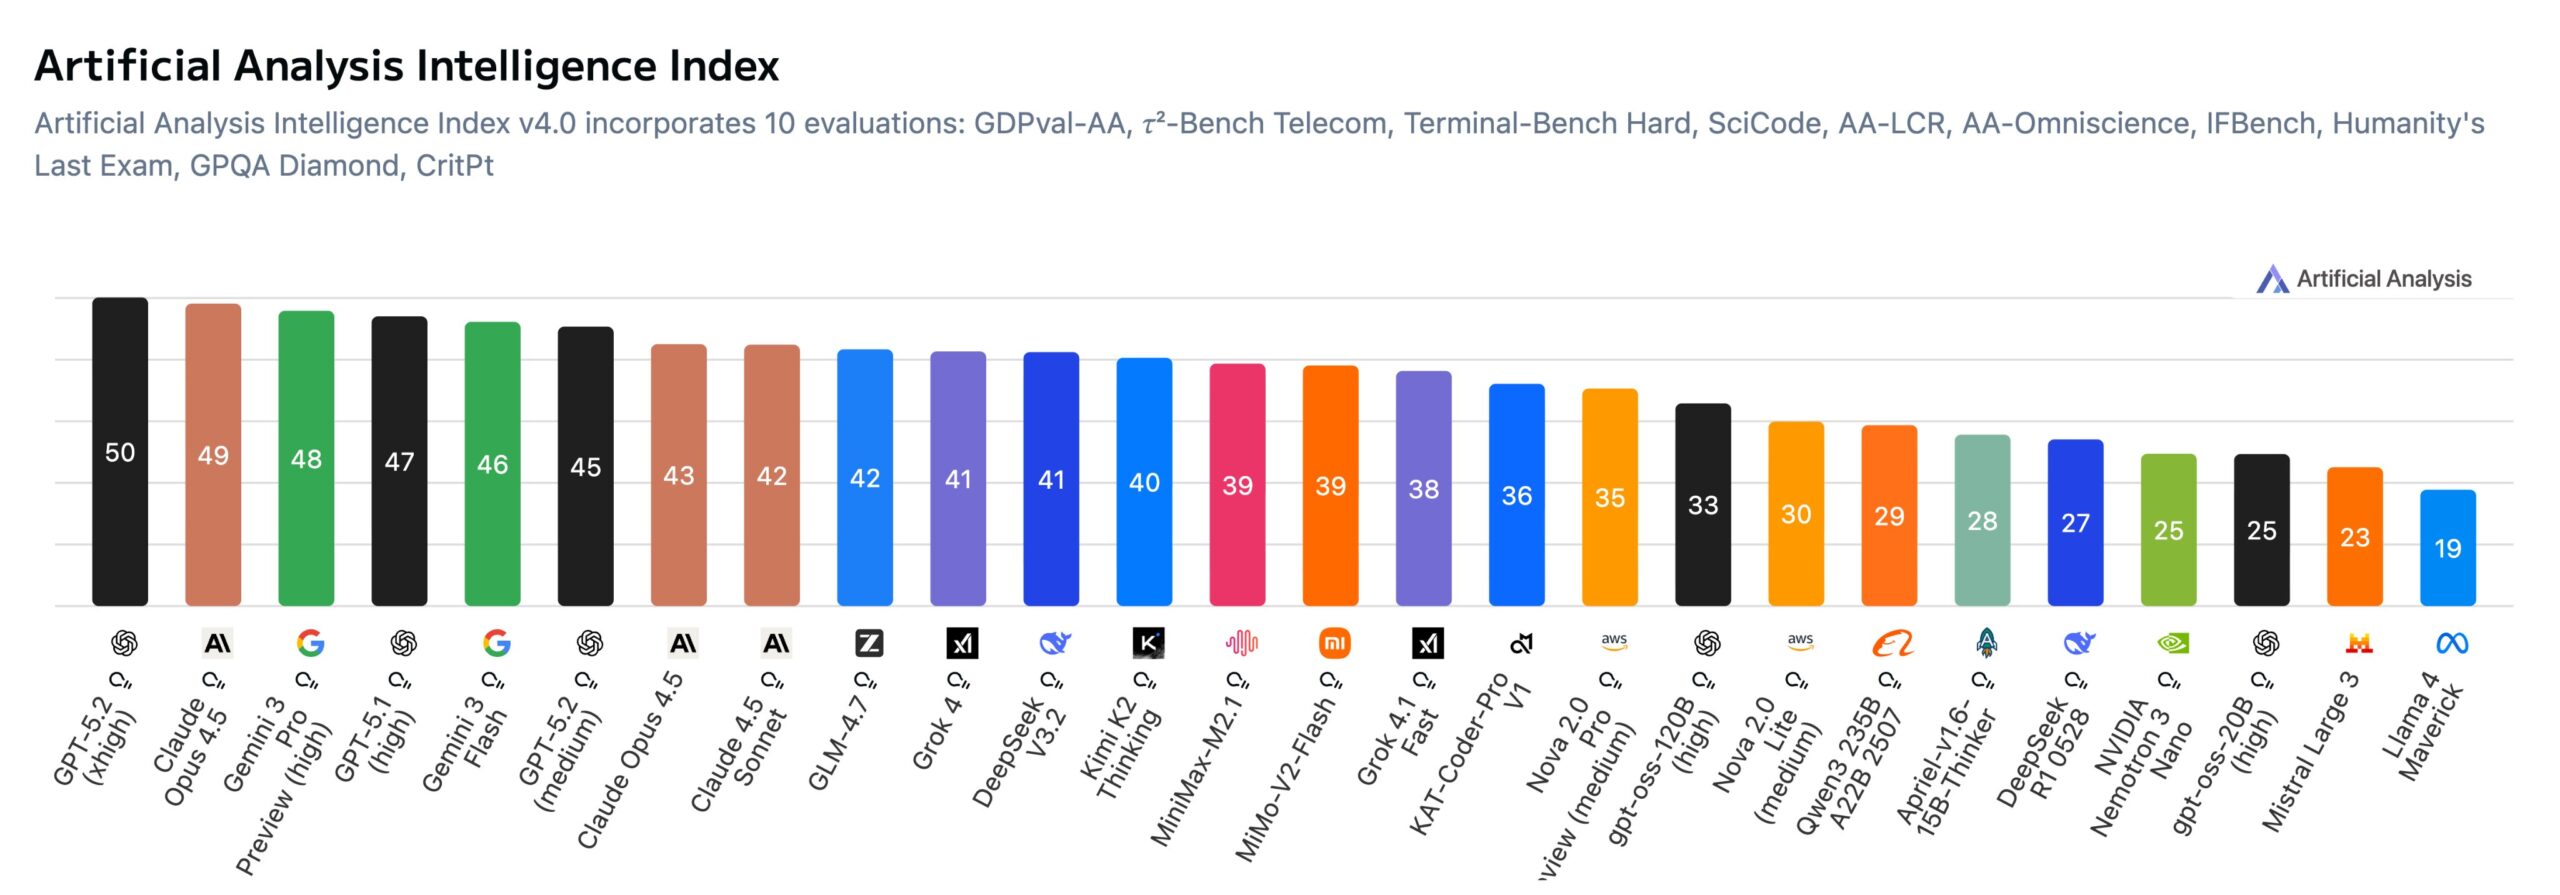
Best LLM Leaderboard 2026 | AI Model Rankings, Benchmarks & Pricing ...
The Benchmark Trap: Why AI's Testing Crisis Will Trigger a 2026 ...
10 Best AI Coding Tools in 2026: Write Code 10x Faster
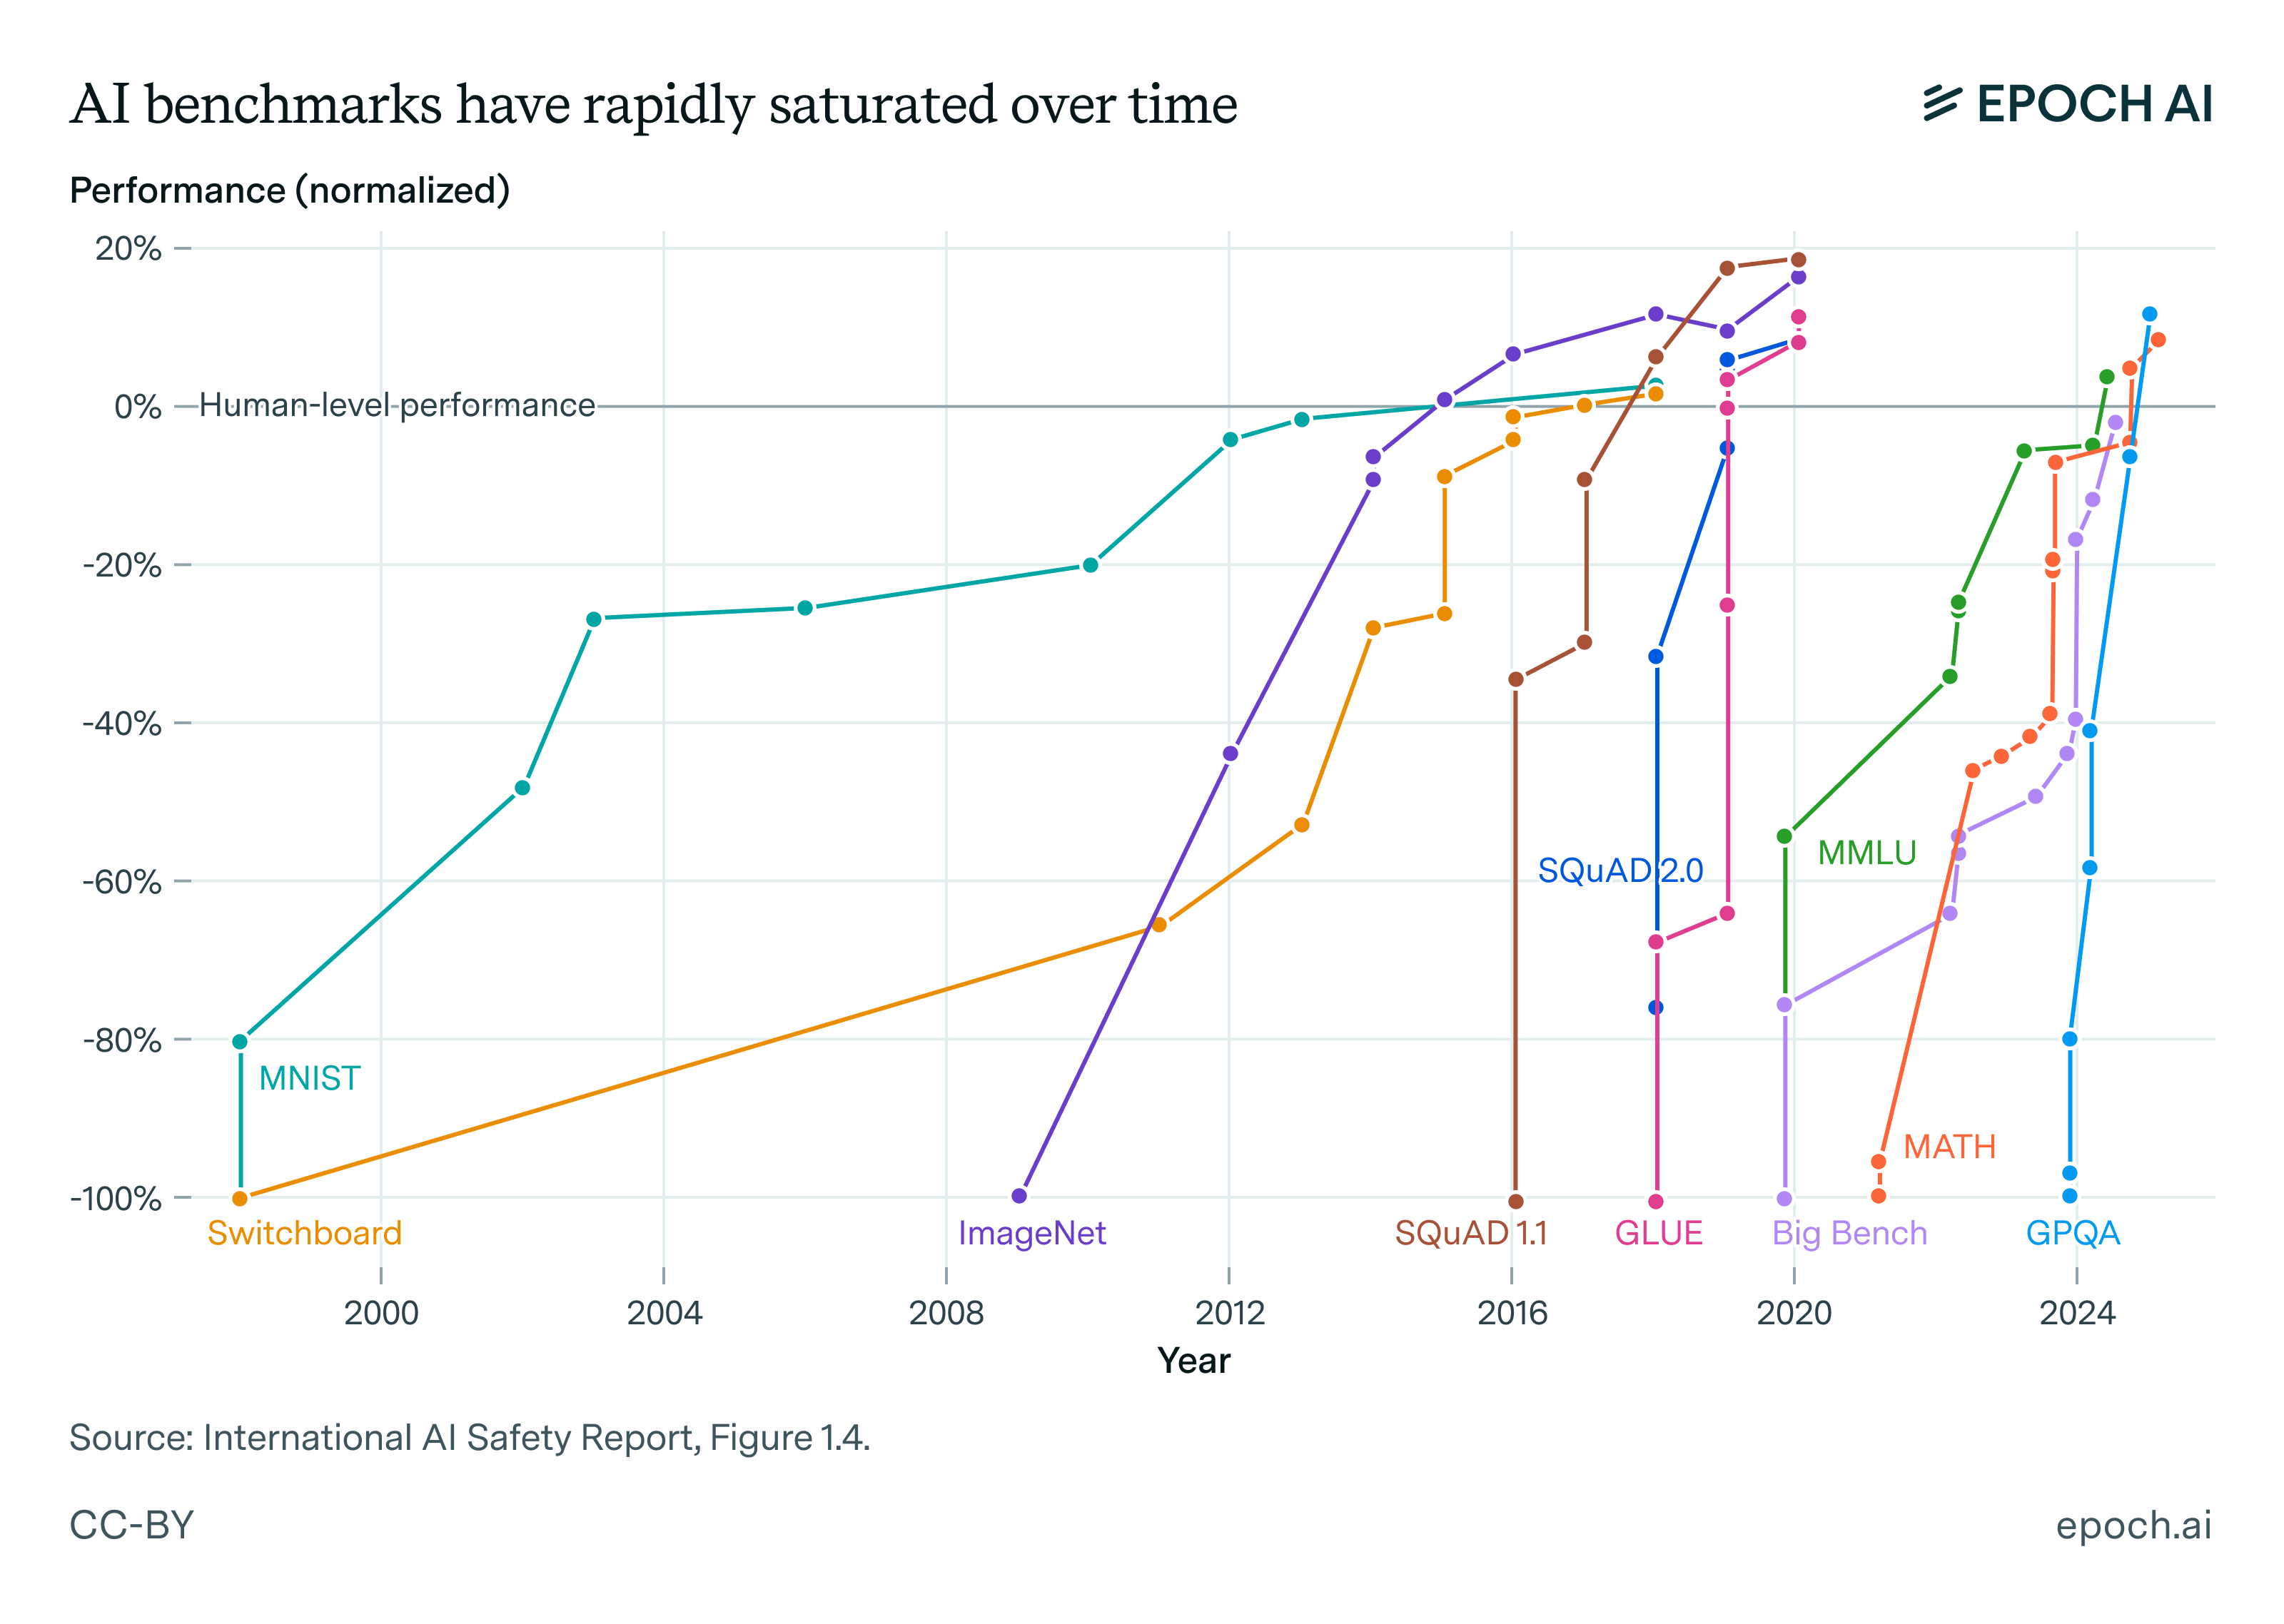
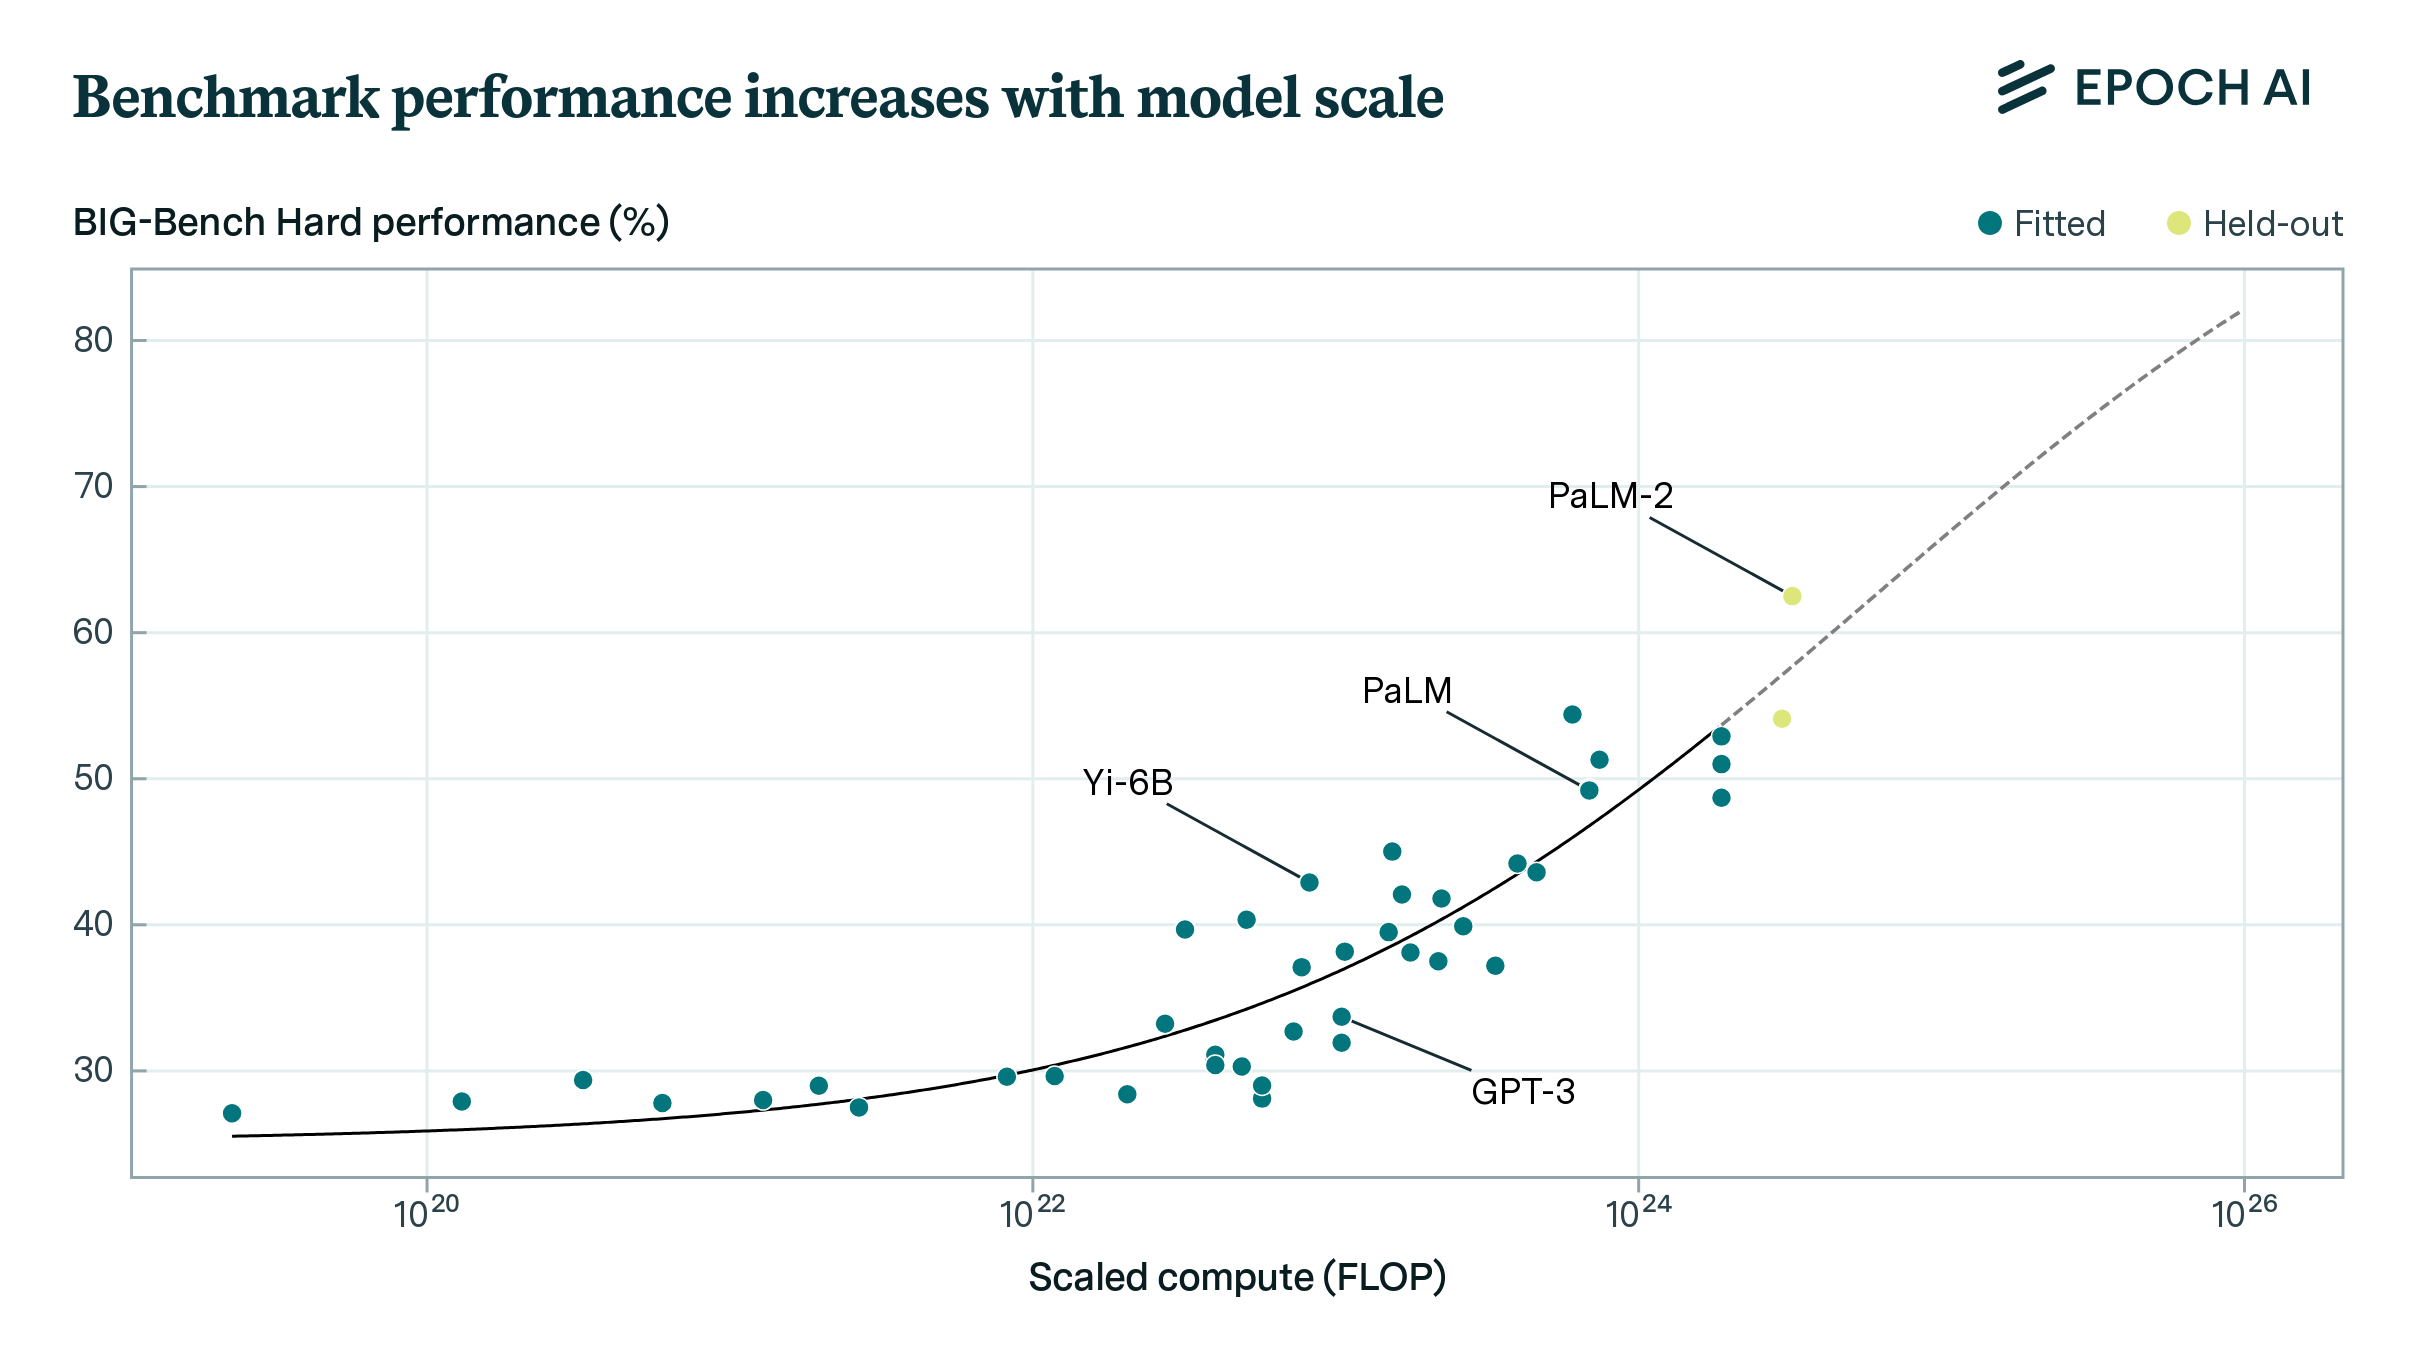
The real reason AI benchmarks haven’t reflected economic impacts | Epoch AI
Decoding the LLM Leaderboard 2025: Unveiling Top AI Rankings - Fusion Chat
Leaderboard Illusion in AI Benchmarks - Datatunnel
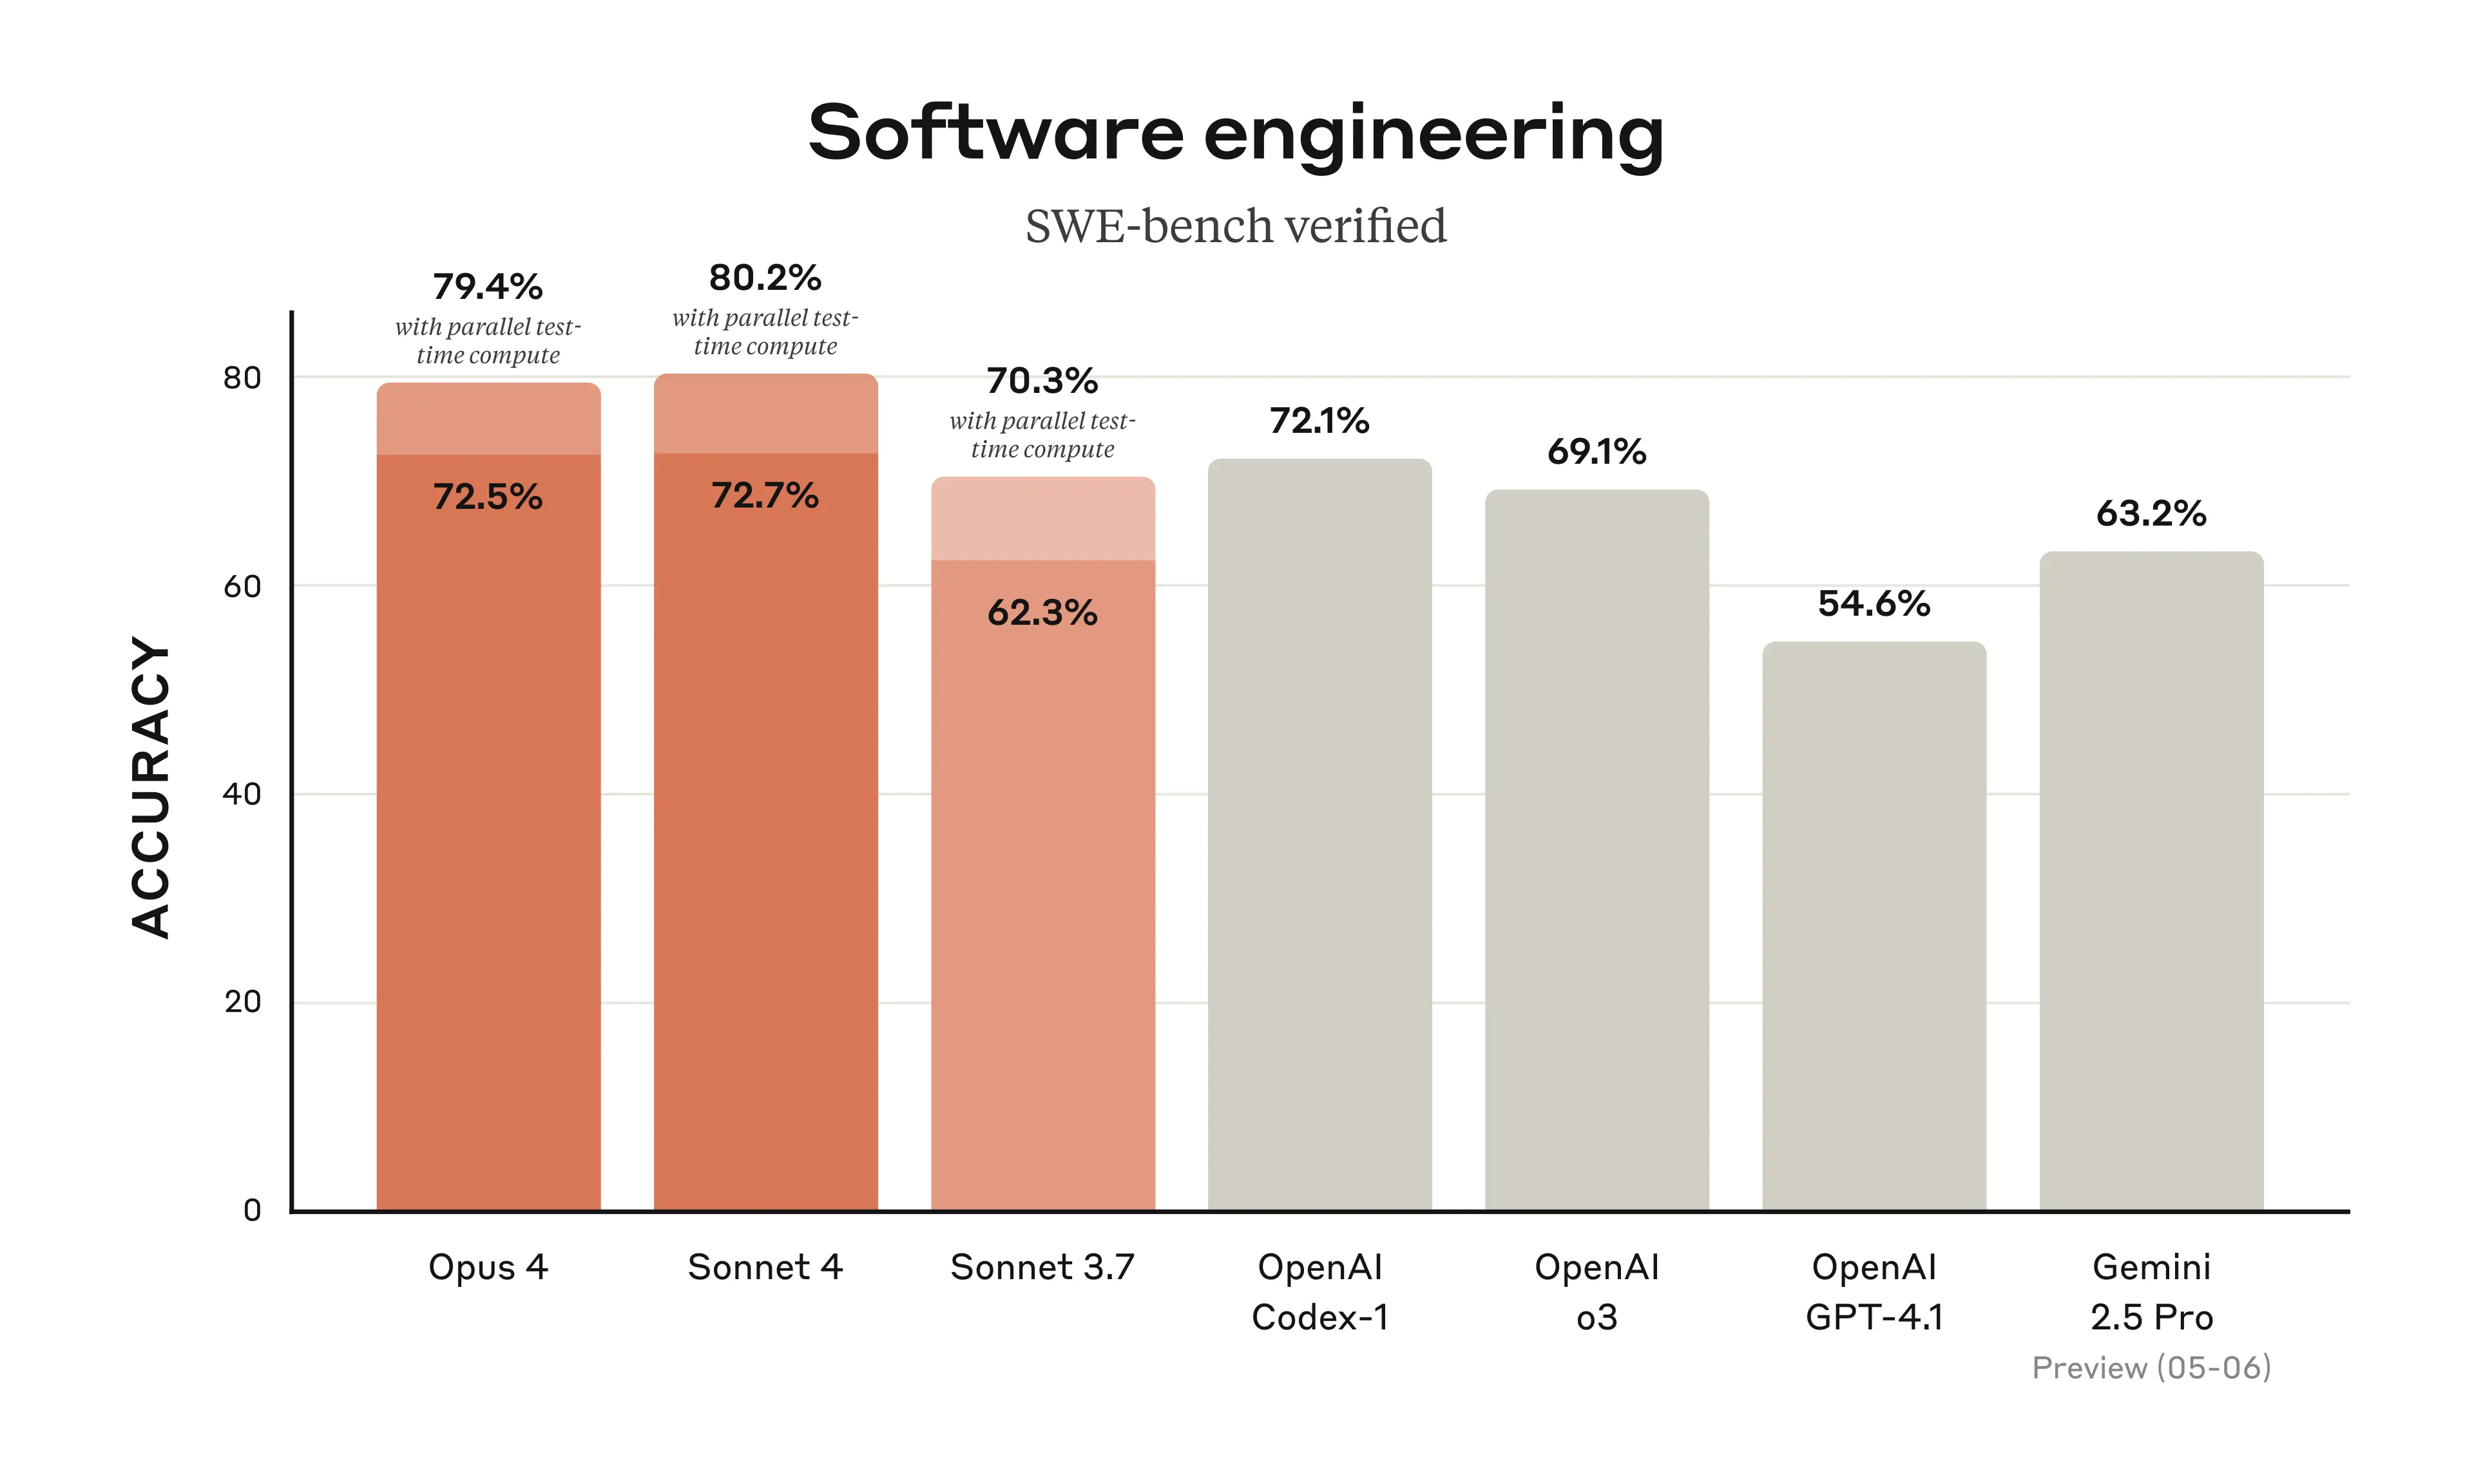
Claude 4: The Breakthrough in AI Evolution - Fusion Chat
Best reasoning LLM in 2026: ARC-AGI-2 benchmark leaderboard
Which AI Benchmarks Measure Model Efficiency and Accuracy? 🔍 (2026 ...
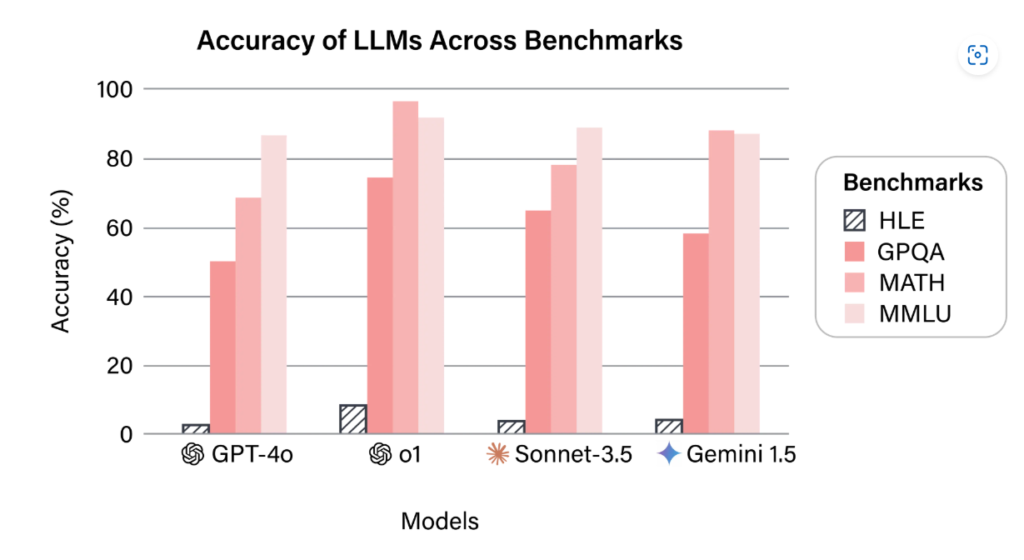
LLM Benchmarks Explained: MMLU, Chatbot Arena & SWE-bench Leaderboard ...
AI Benchmarks 2026: Enterprise Model Comparison - Tech insight
Best AI Models for Coding 2026: Complete Developer Benchmark - Crazyrouter
AI Benchmarks 2026: Top Evaluations and Their Limits
Grok Coding Leaderboard: Why Grok Code Fast 1 Dominates Developer ...
AI Benchmarks vs Real Workflows in 2026 | Awesome Analytics
🚀 12+ AI Framework KPIs: The Ultimate Benchmark Guide (2026) - ChatBench
GenAI Tools Comparison 2026: Which AI Should a Manager Choose ...
BigCodeBench Benchmark - AI Code Generation Leaderboard (2026) | LM ...
17 Essential KPIs for Evaluating AI Benchmarks in 2025 - ChatBench
The 2026 AI Search Benchmark Report - Opollo
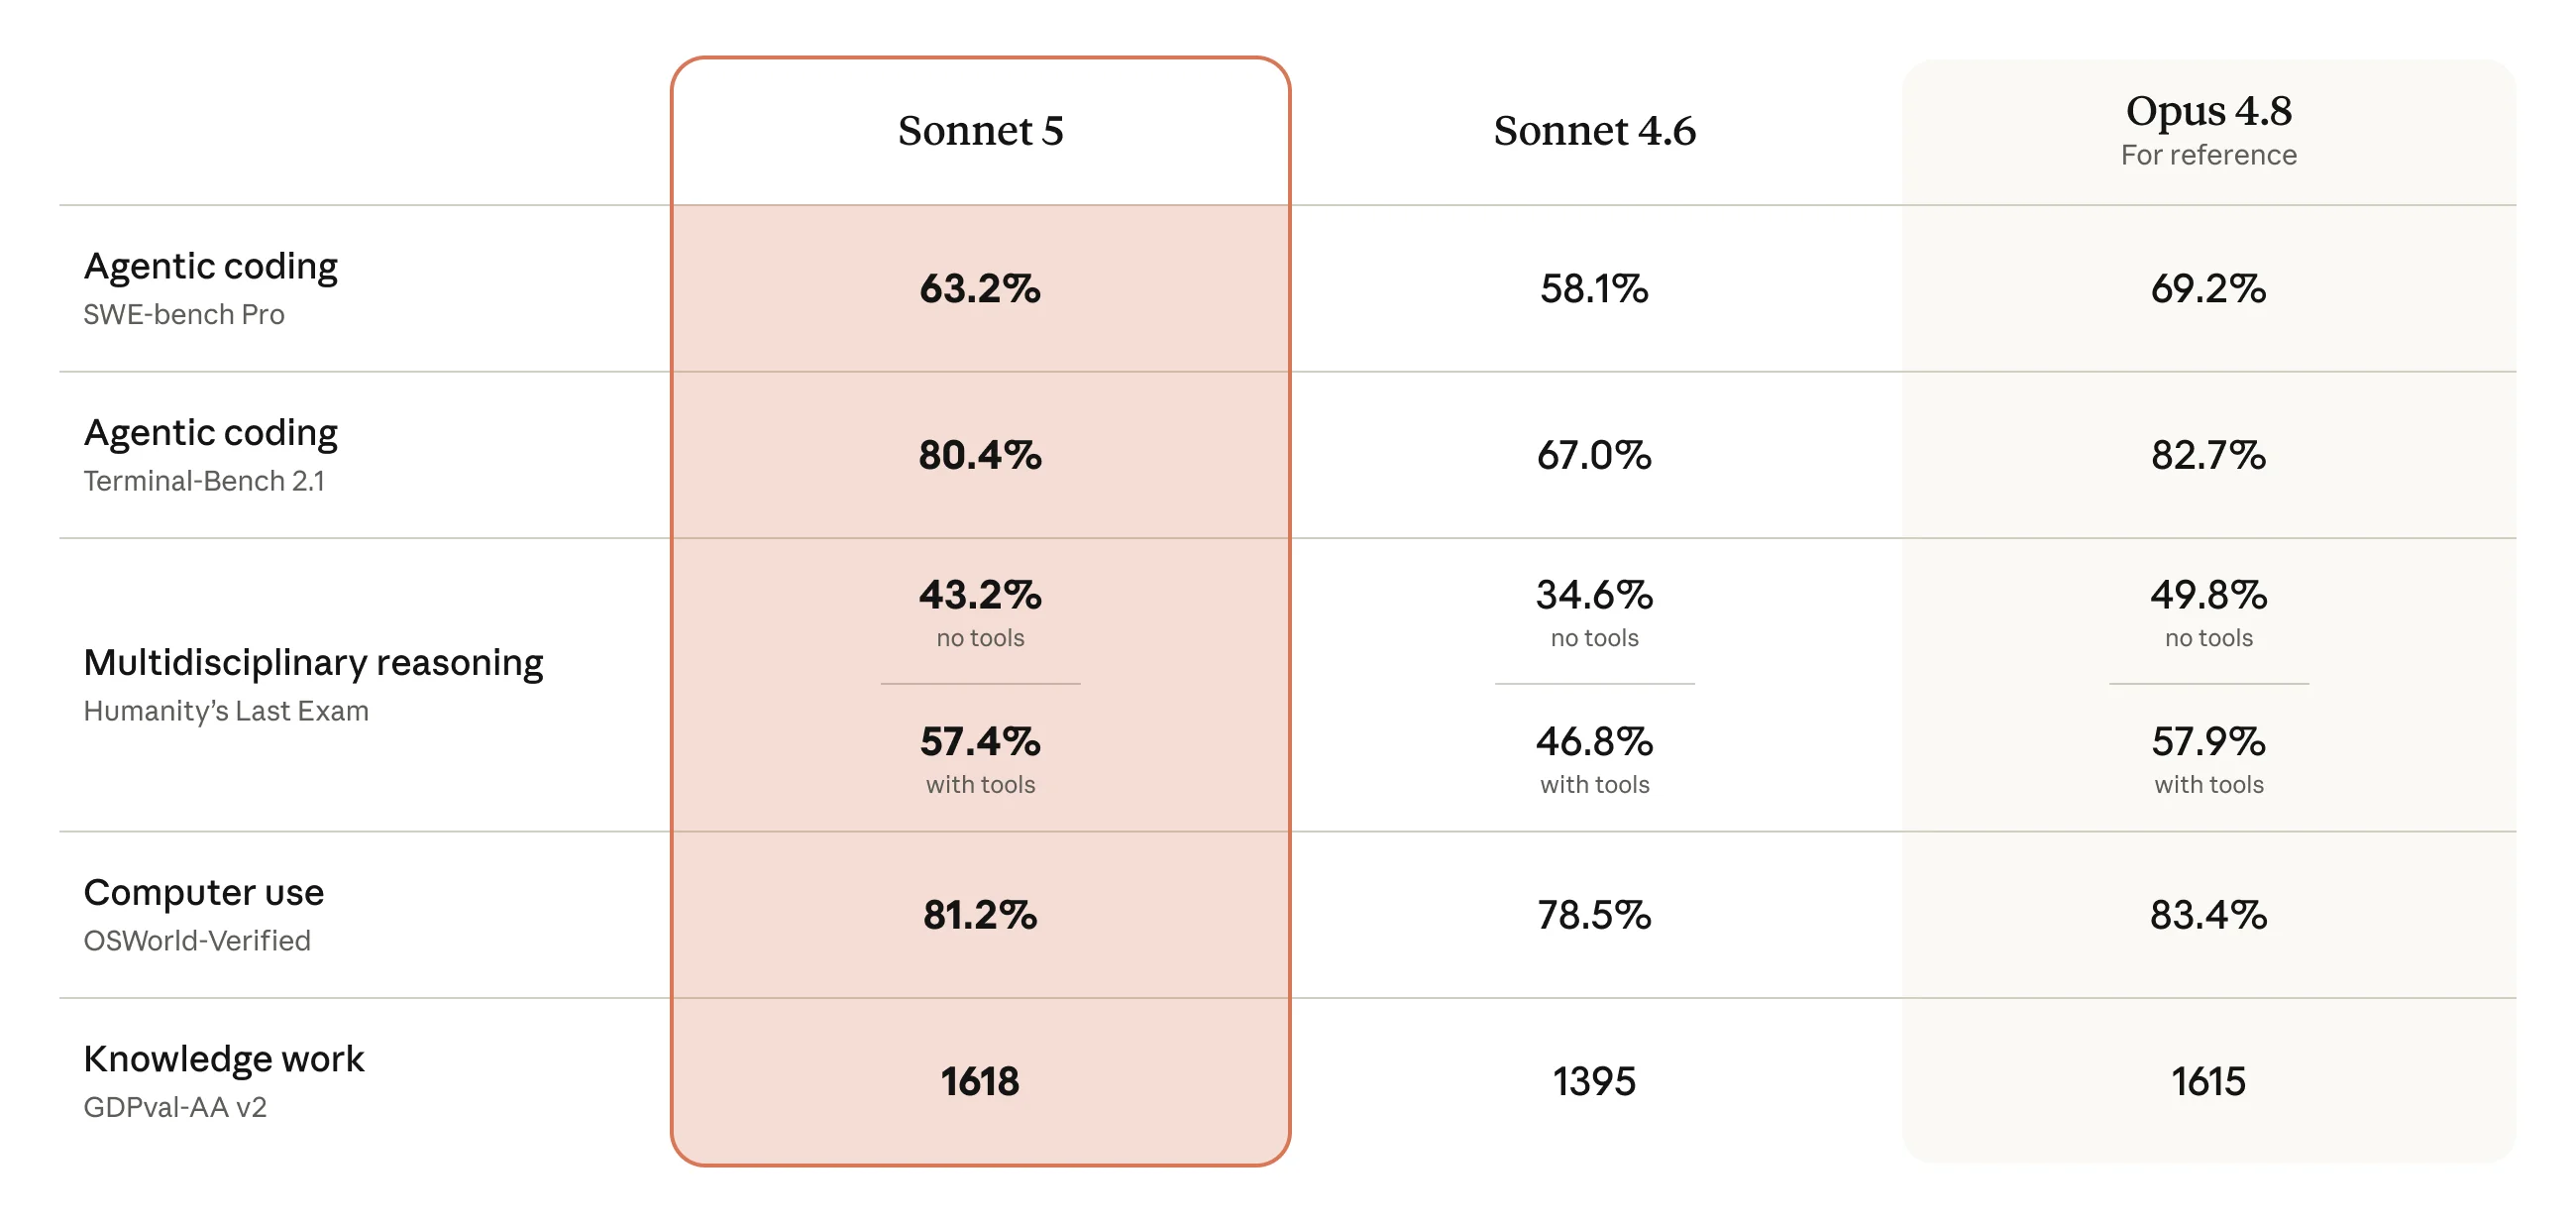
Claude Sonnet 5 Launched June 30, 2026: Pricing, API & Benchmarks ...
12 Essential Key Performance Indicators for AI Success in 2026 🚀 ...
Senior SWE-Bench: Snorkel AI Coding Agent Benchmark (2026) | explainx ...
Top 8 leaderboards to choose the right AI model for your task
Can AI Benchmarks Really Compare Frameworks & Architectures? 🚀 (2026 ...
Qwen3.6-Max-Preview Review: #1 AI Model for Coding? Full Benchmarks ...
8 Critical Flaws in AI Benchmarks (2026) 🚫 - ChatBench
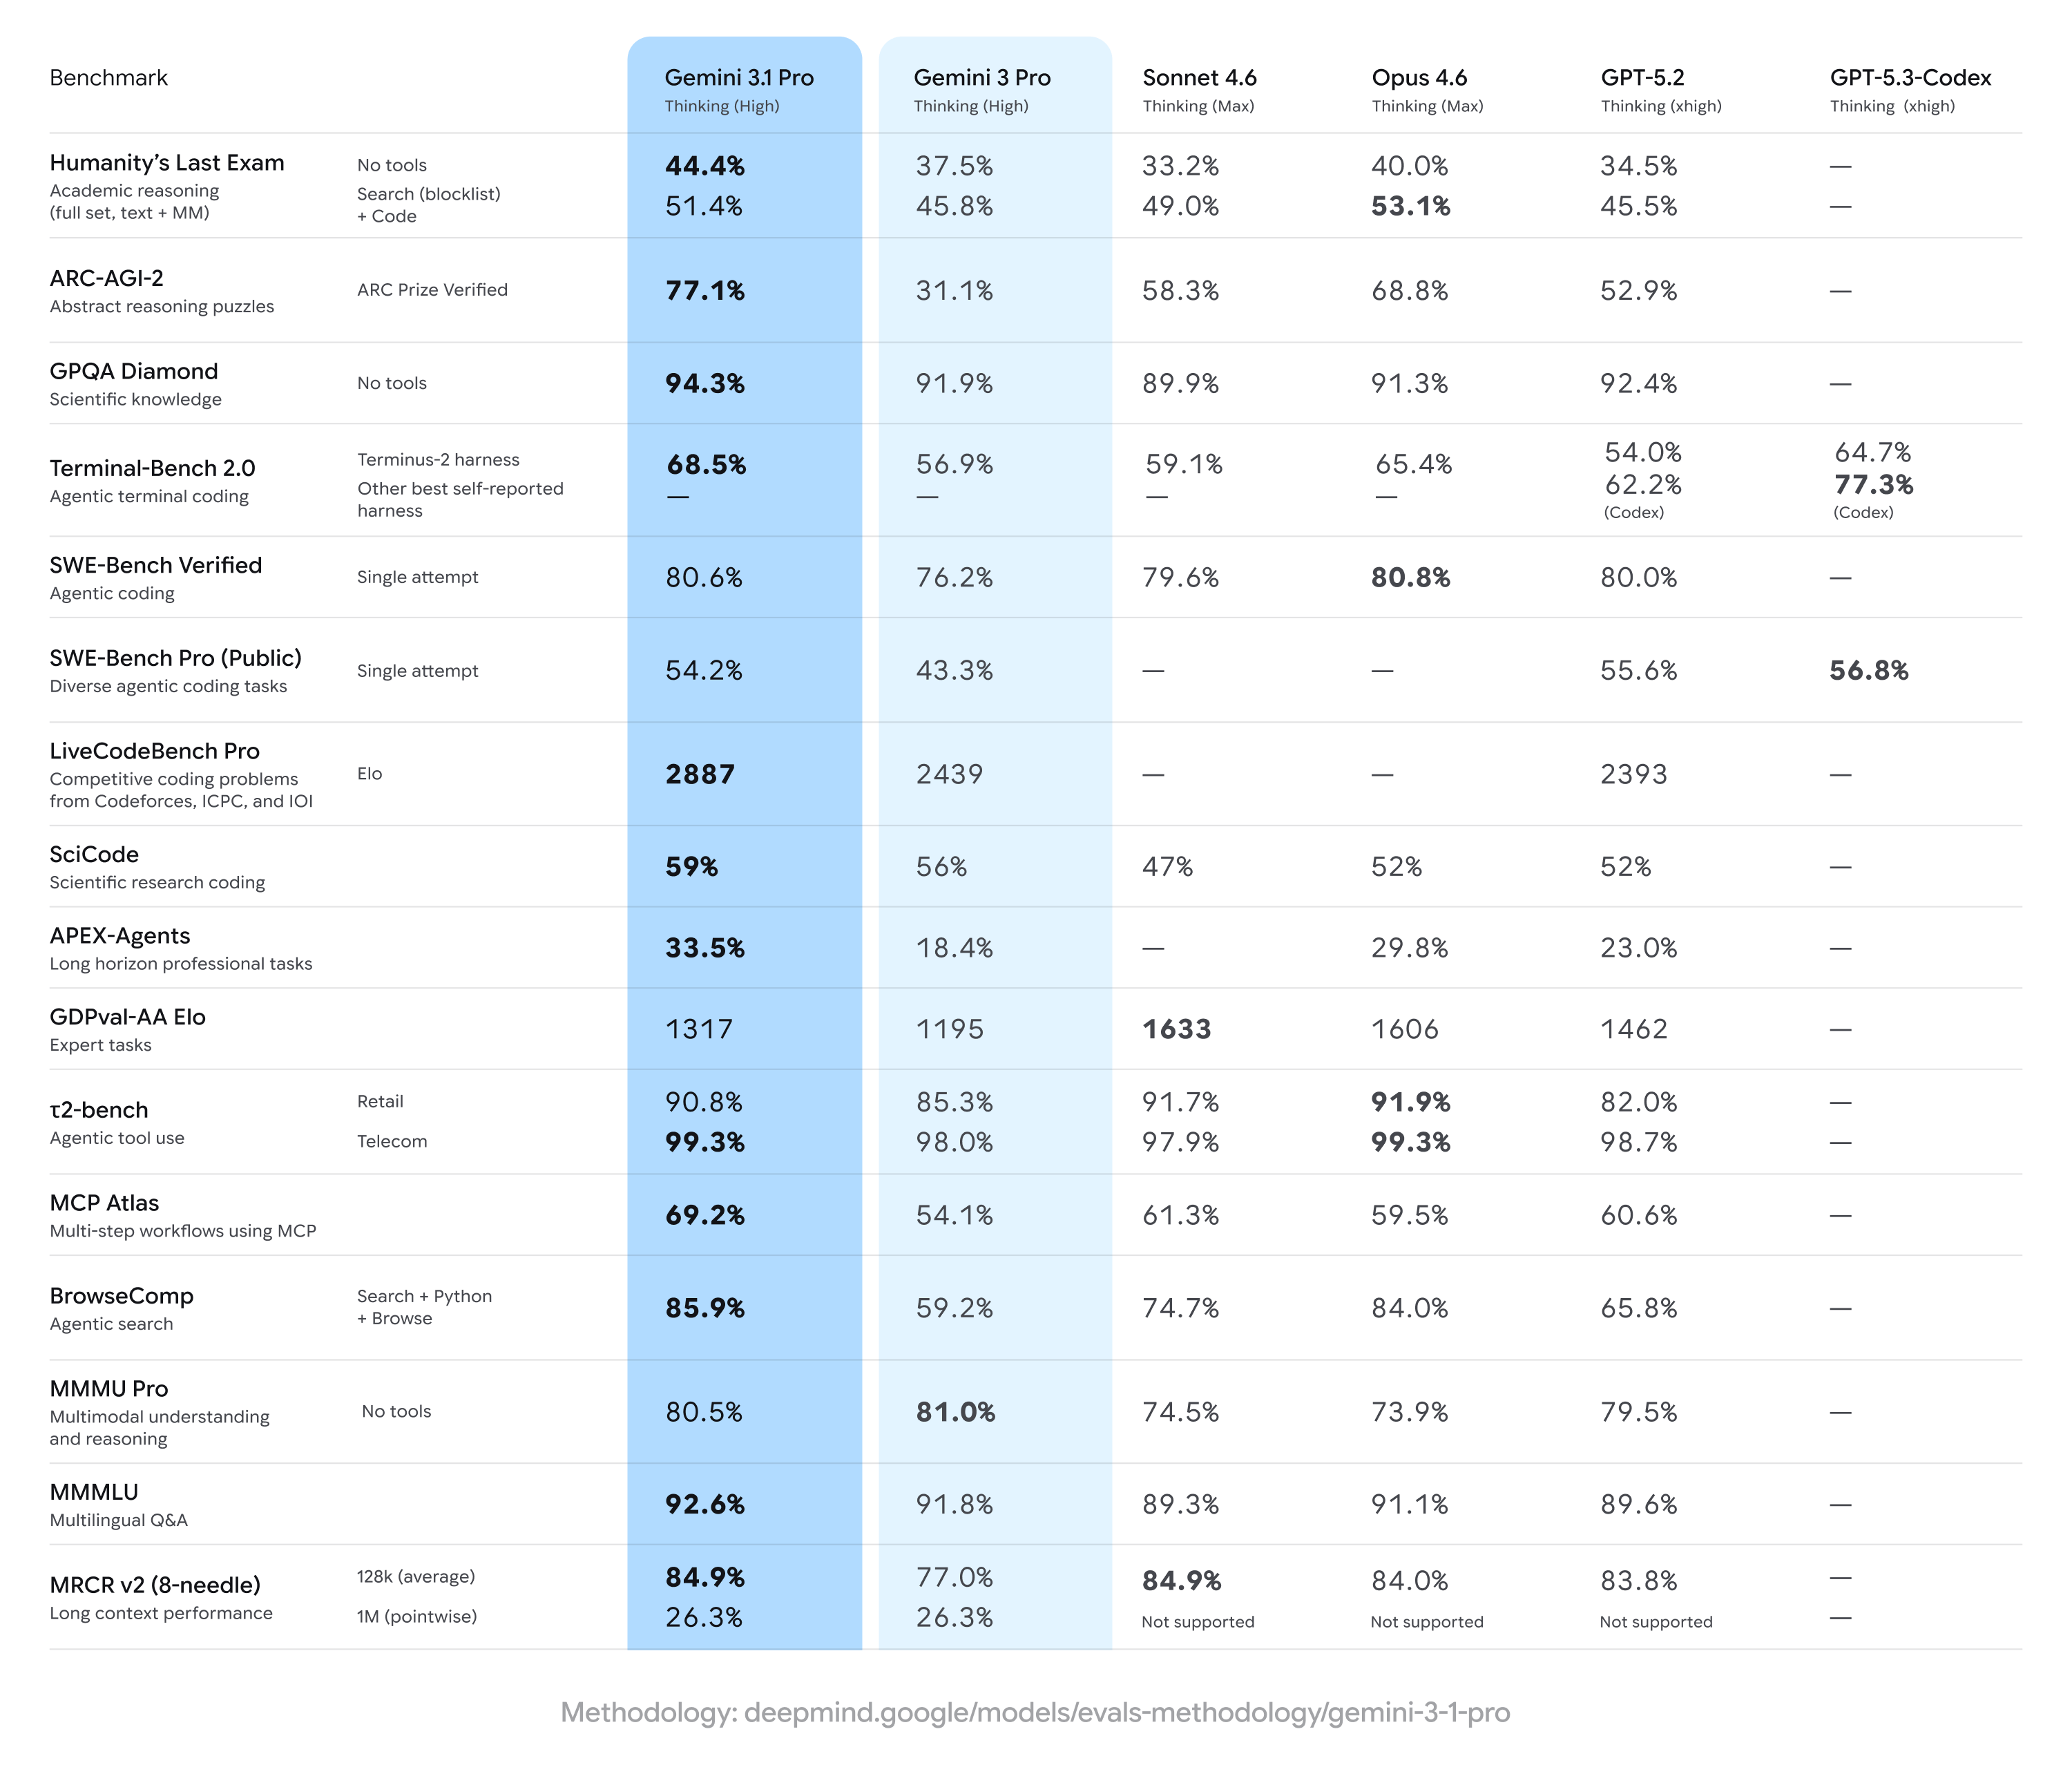
Google doubles the reasoning power of its core AI model with Gemini 3.1 Pro
ChatGPT 4.1 early benchmarks in contrast towards Google Gemini - Forbes ...
Go vs Python for AI Infrastructure: Throughput Benchmarks 2026 ...
Best AI Coding Tools for Developers in 2026 (Free & Paid)
AI Science Agent Benchmarks 2026: 8 Suites Compared | Blog
The Rise of Physical Intelligence: AI’s Next Frontier | by Cogni Down ...
🚀 7 Ways AI Benchmarks Reshape Solution Development (2026) - ChatBench
Claude Sonnet 4.6 vs GPT-5.2 vs Gemini 3: Which AI to Use in 2026 | 365i
AI Coding Impact 2026 Benchmark Report | Opsera
AI Code Generation: New DevQualityEval Benchmark Reveals Which LLMs ...
17 predictions for AI in 2026
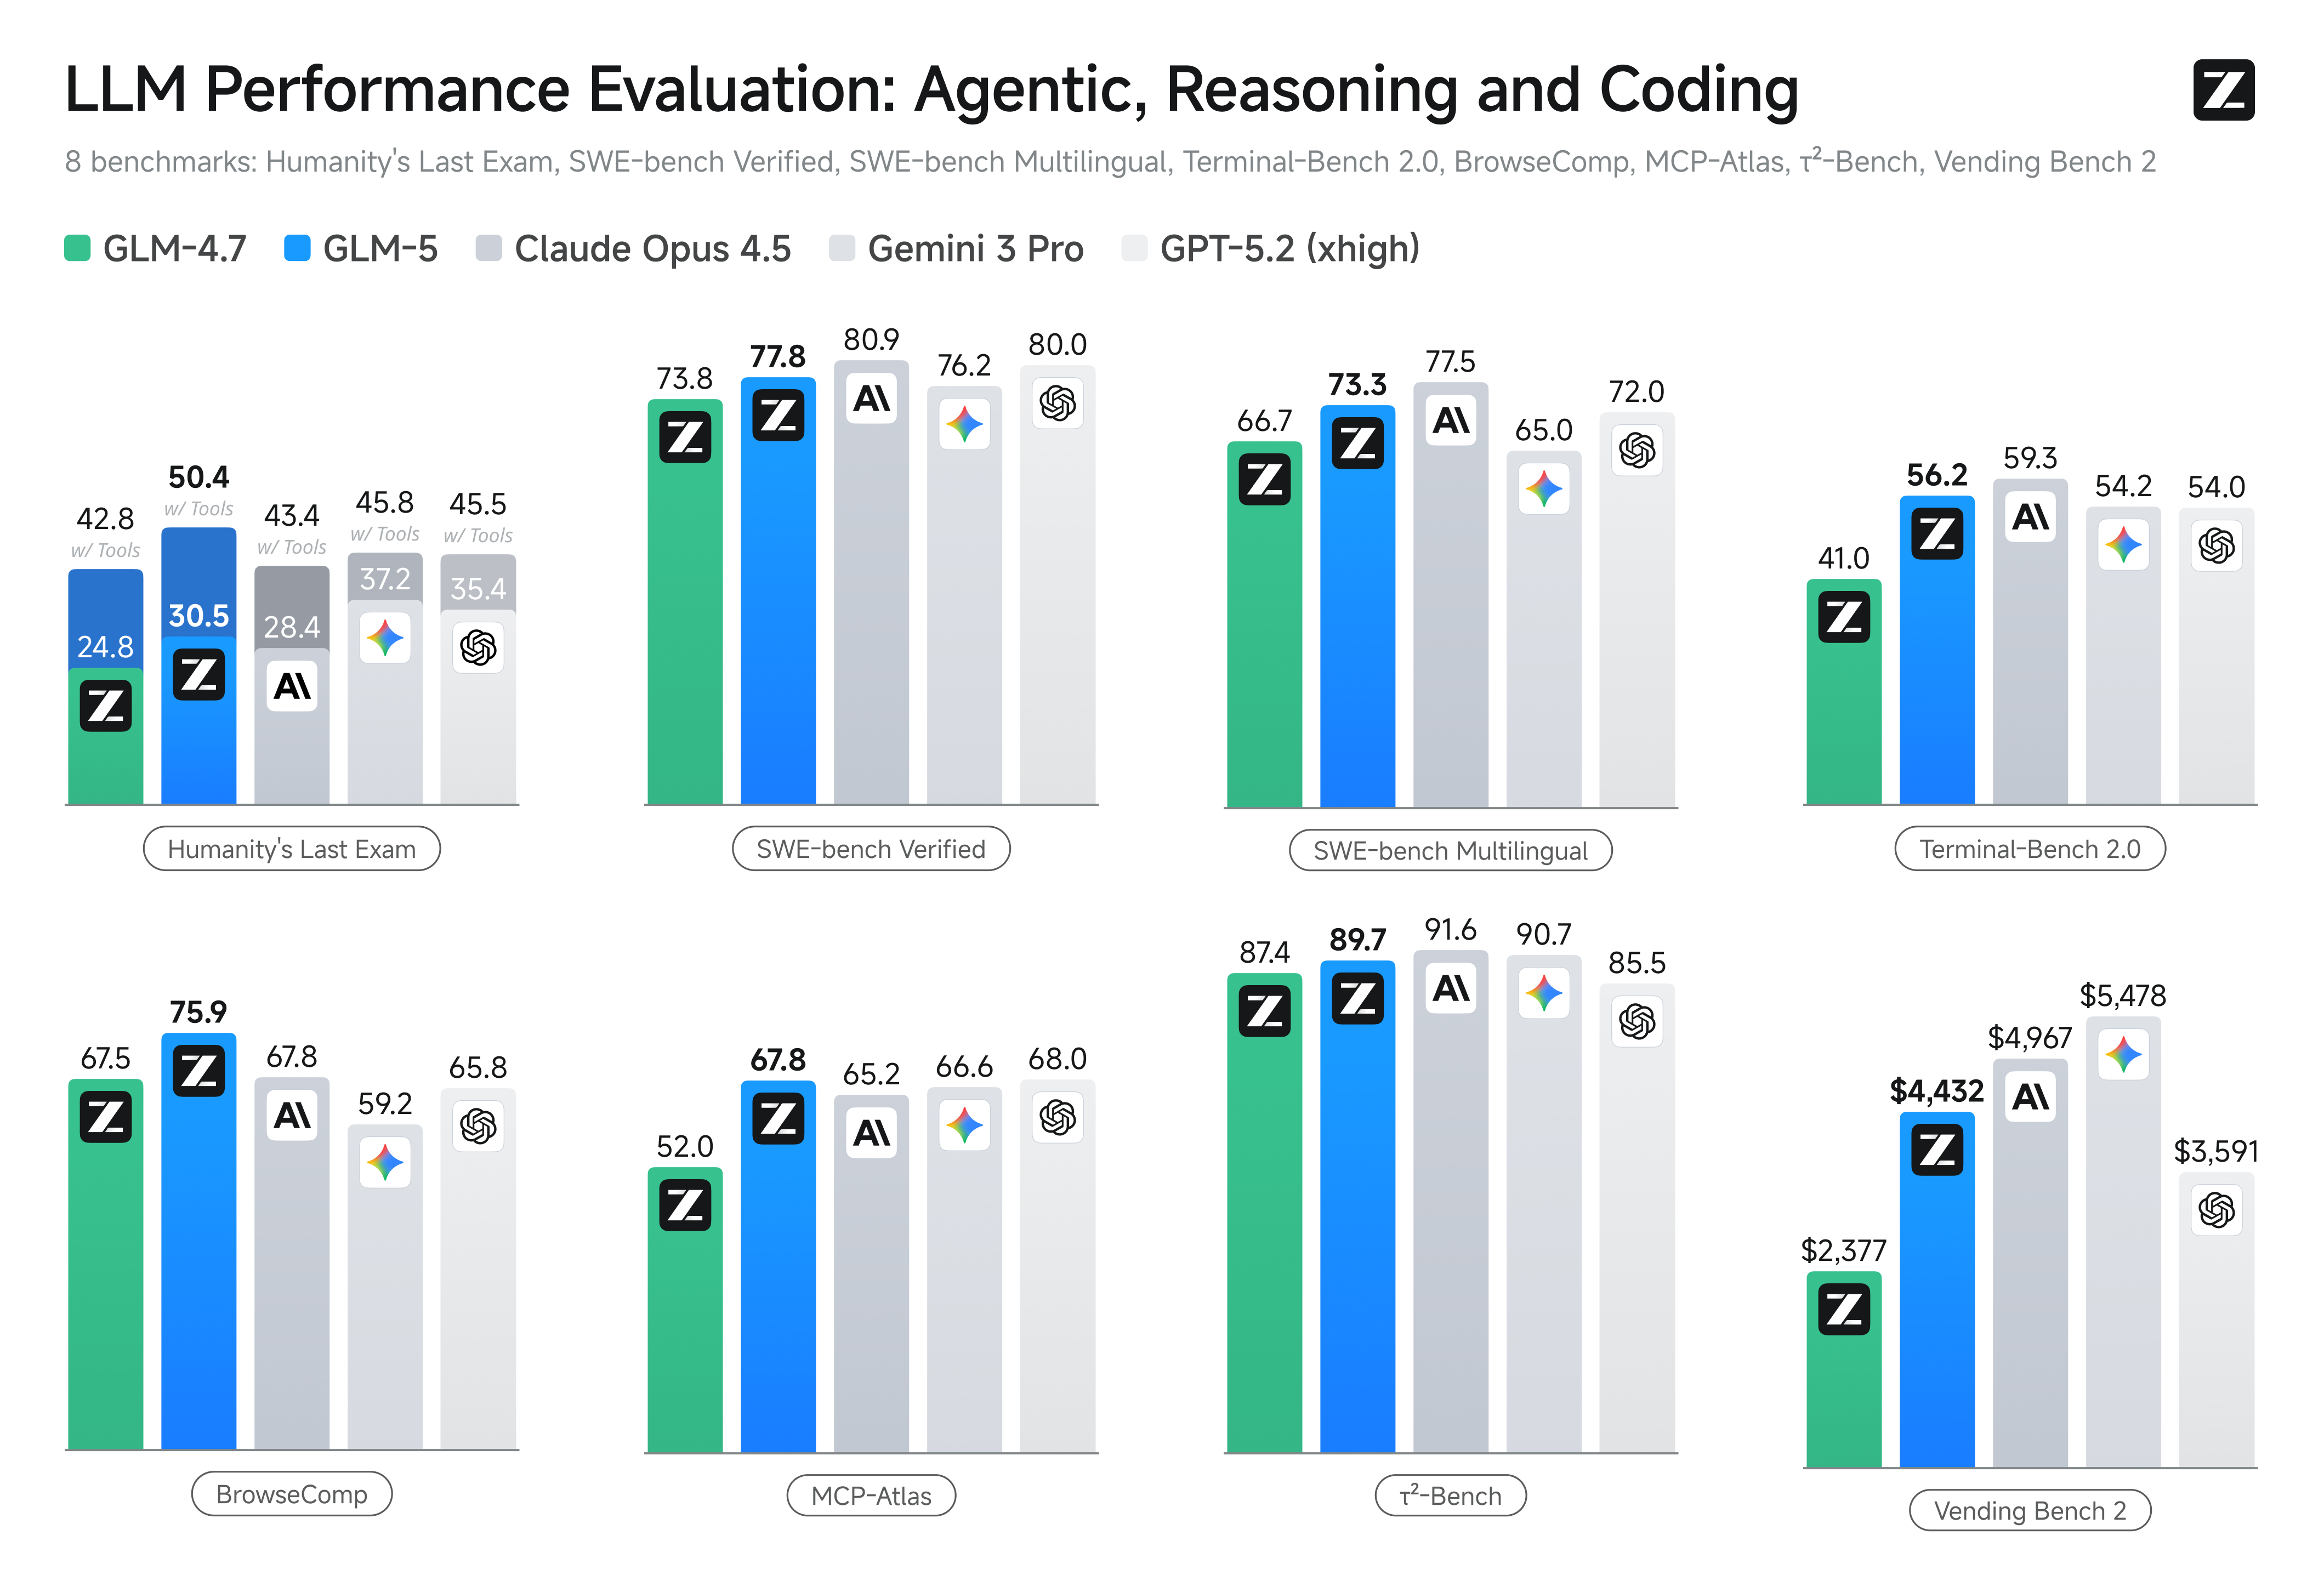
Kimi vs. Claude vs. GLM-4.7: An In-Depth Benchmark of Three Major AI ...
OpenAI releases new coding benchmark SWE-Lancer showing 3.5 Sonnet ...
Gen AI Infused SDLC -Transforming SDLC with Gen AI Capabilities | by ...
Open LLM Leaderboard 2026 - Open Source AI Models
I. From GPT-4 to AGI: Counting the OOMs - SITUATIONAL AWARENESS
Qwen Researchers Introduce CodeElo: An AI Benchmark Designed to ...
Best AI Code Editors for Developers in 2025 - Qodo
DeepSeek V3-0324 beats rival AI models in open-source first
Benchmarks have accelerated AI-for-coding, but there are no AI-for ...
Stanford's 2026 Report: AI Safety Benchmarks Are Falling Behind
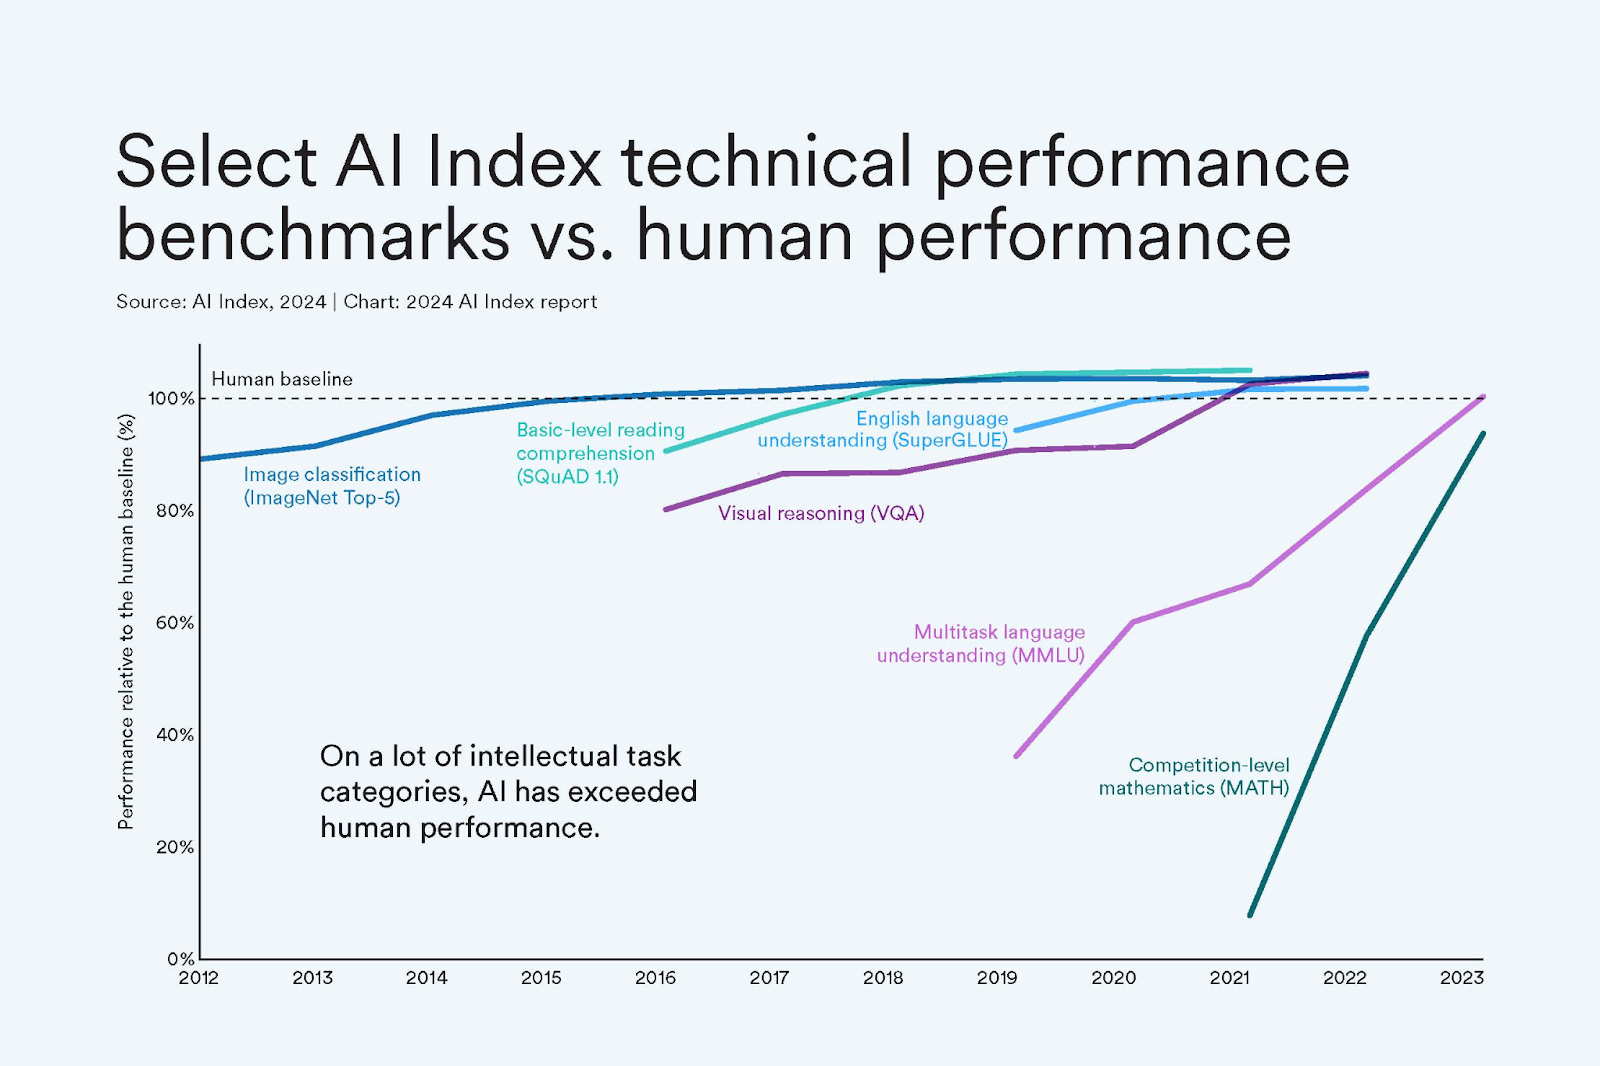
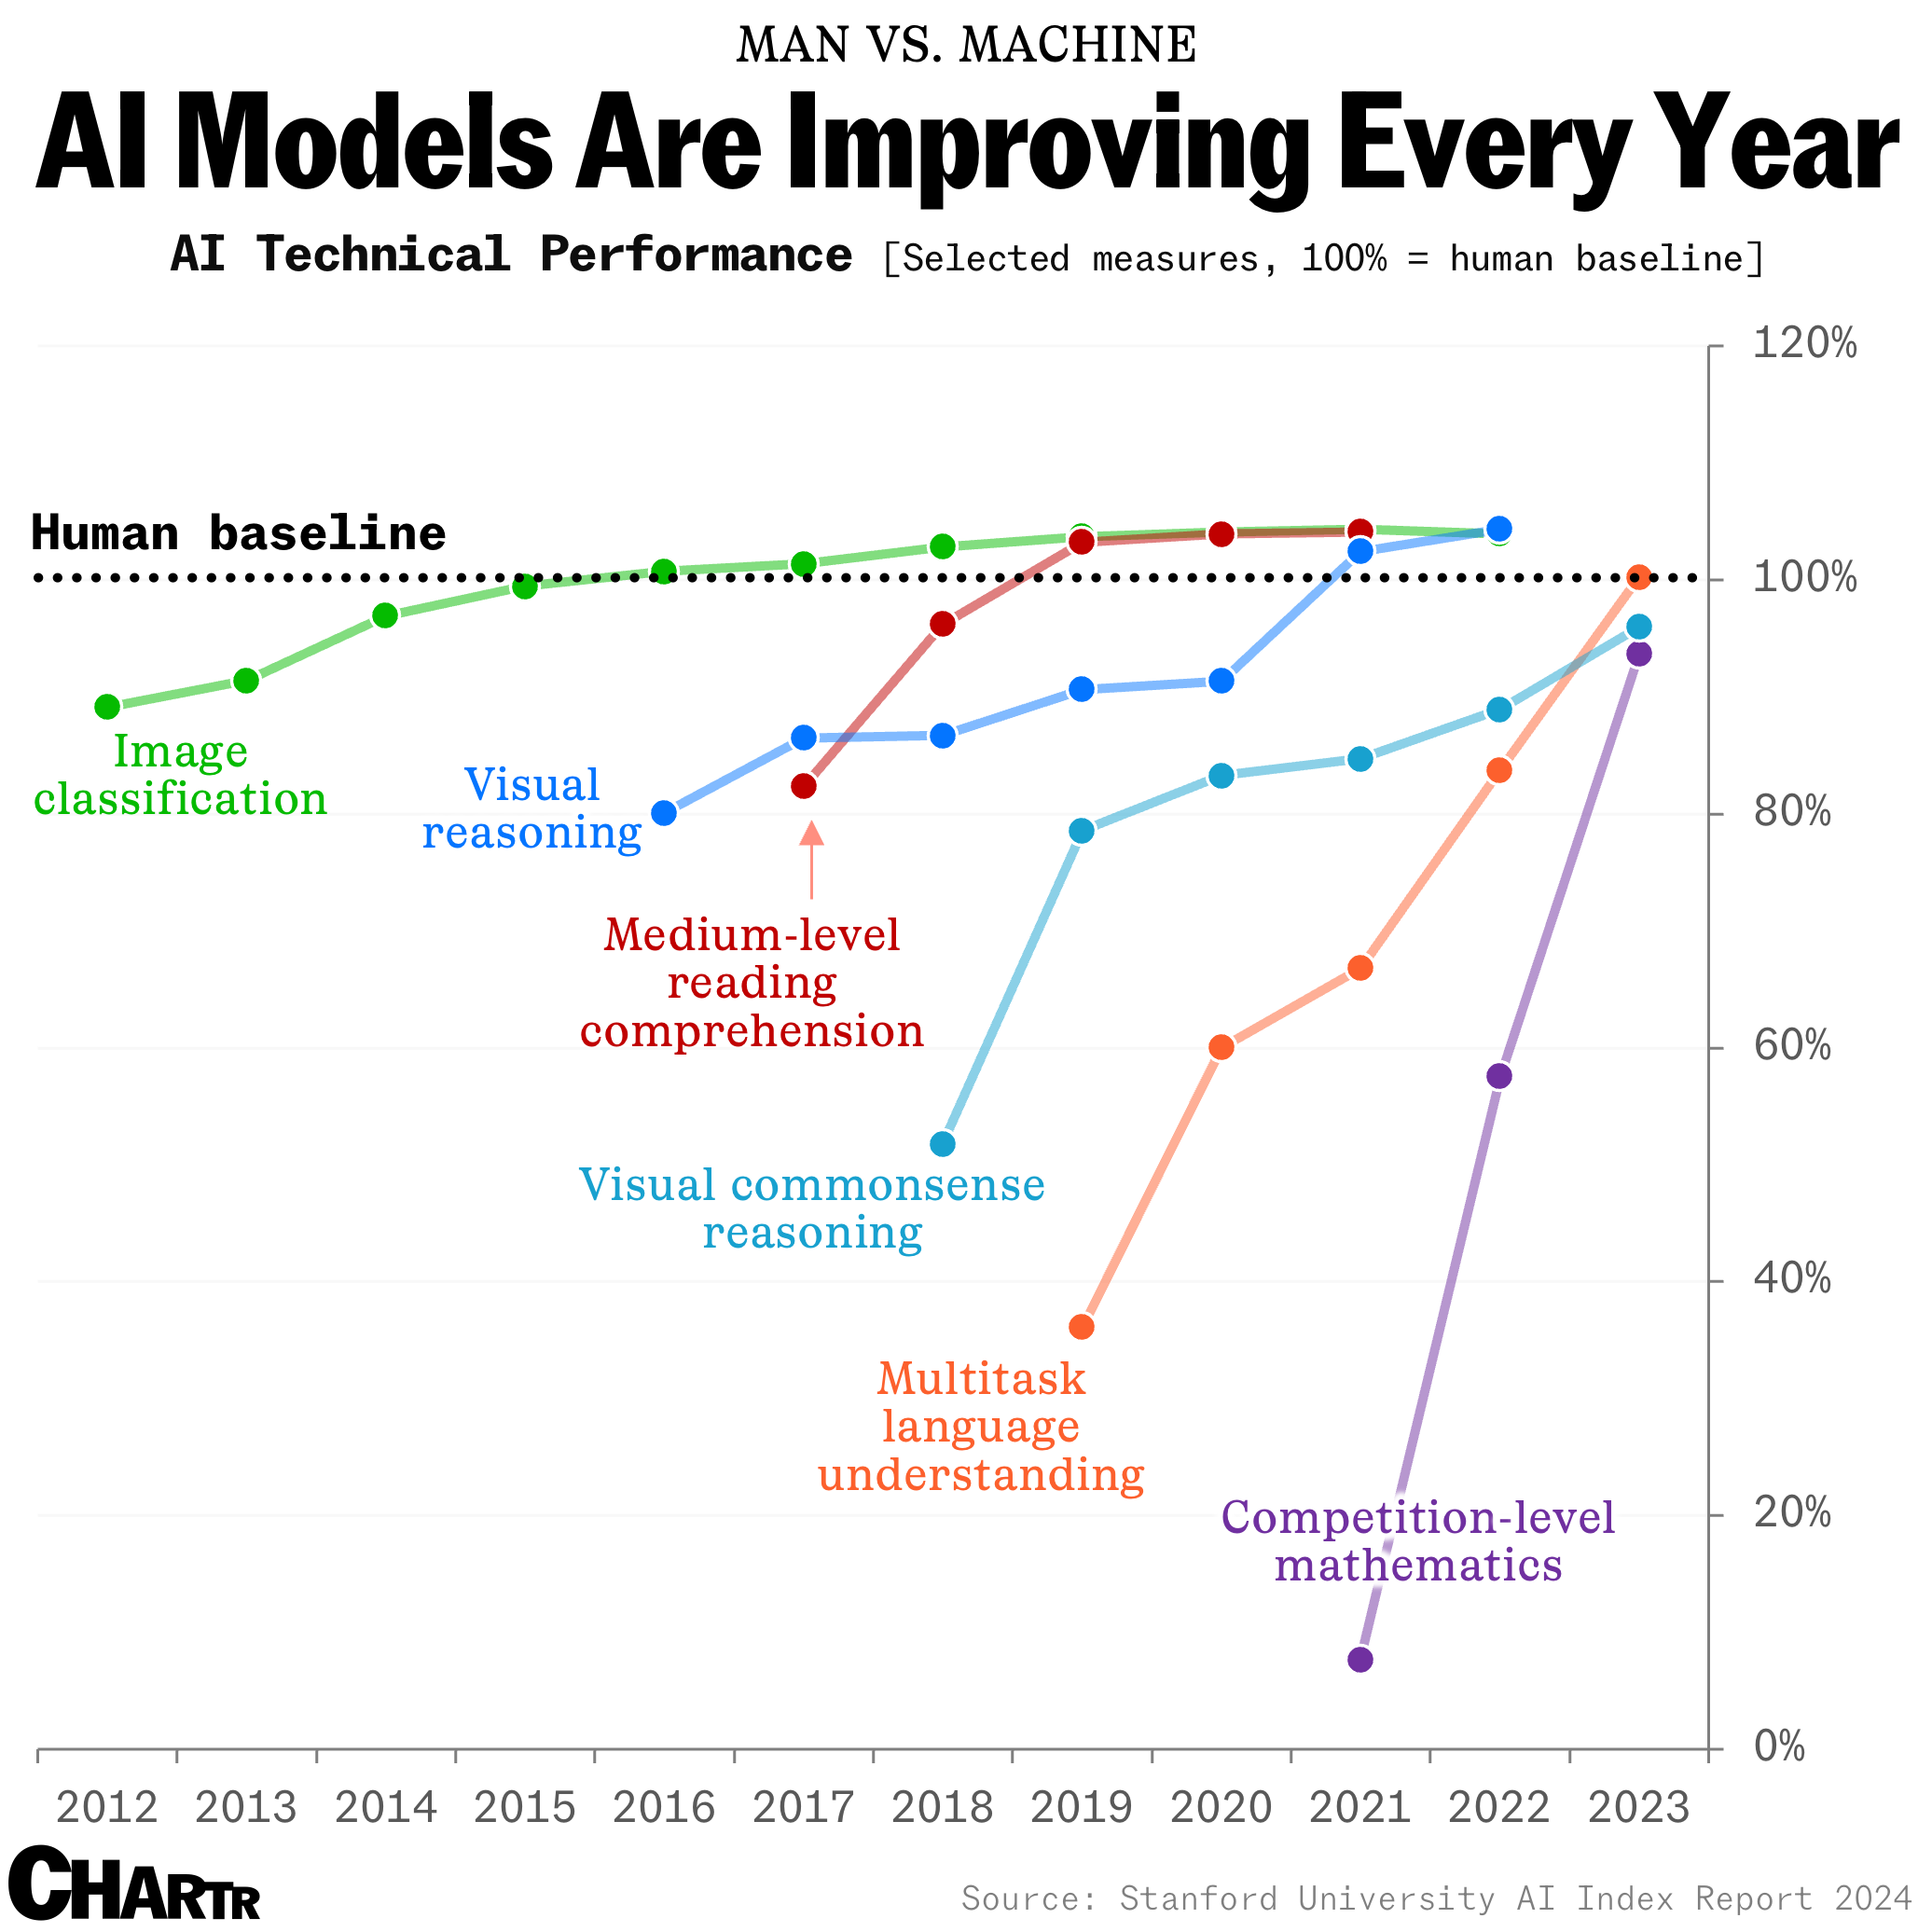
Stanford's Index Report Notes that AI Has Surpassed Human Capabilities ...
Claude vs Gemini 2026: Which AI Is Better for Real Work? | Blink Blog
How Often Are AI Benchmarks for NLP Updated? 🤖 (2025) - ChatBench
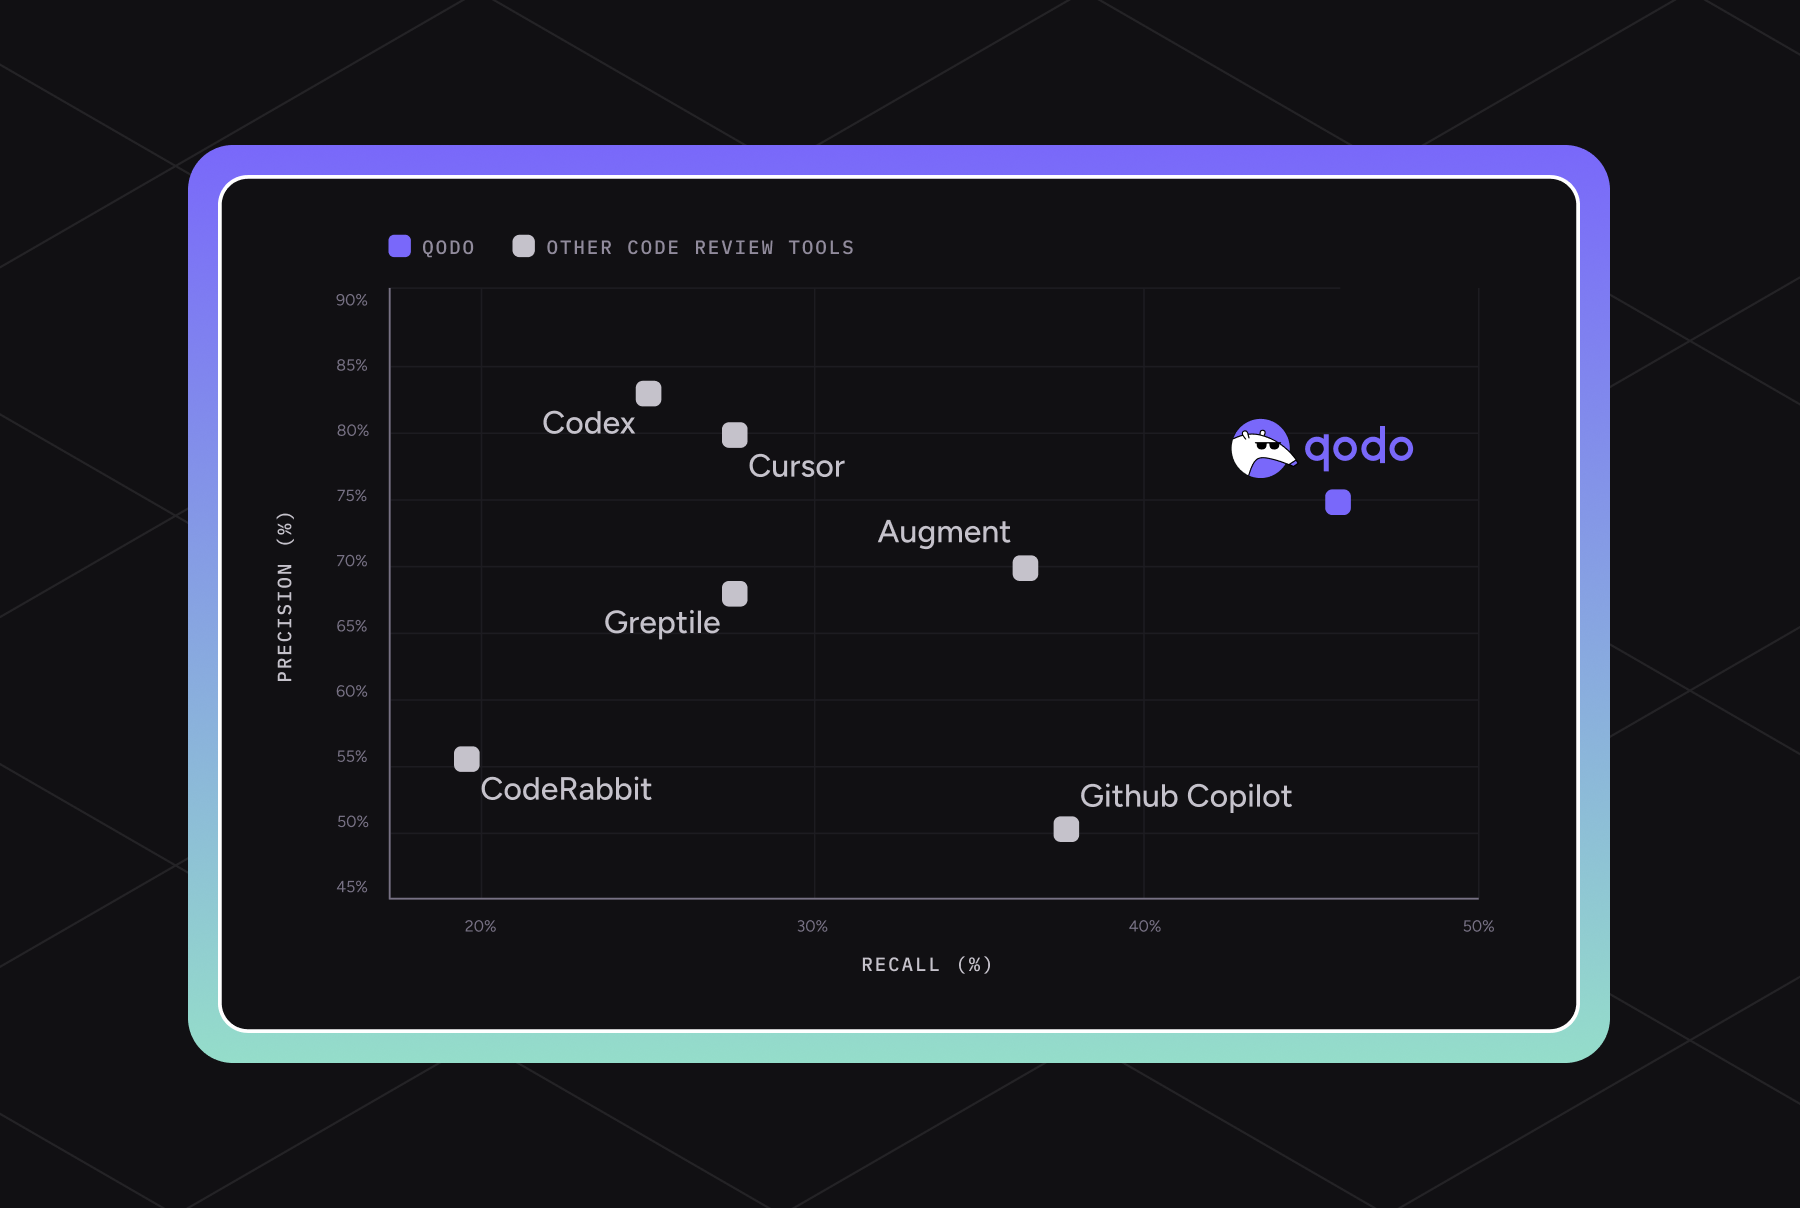
Every AI code review vendor benchmarks itself, and wins • DeepSource
10 AI agent benchmarks
Claude 4: Unveiling Anthropic's Breakthrough AI Models and API ...
Benchmarks for Comparing Human and AI Intelligence — LessWrong
Series A ARR Benchmarks 2026: SaaS, AI, Fintech | StartupCFO
Benchmarking GPT-5 on Real-World Code Reviews with the PR Benchmark - Qodo
New Artificial Analysis benchmark shows OpenAI, Anthropic, and Google ...
How Qodo Built a Real-World Benchmark for AI Code Review
NVIDIA Llama Nemotron Ultra Open Model Delivers Groundbreaking ...
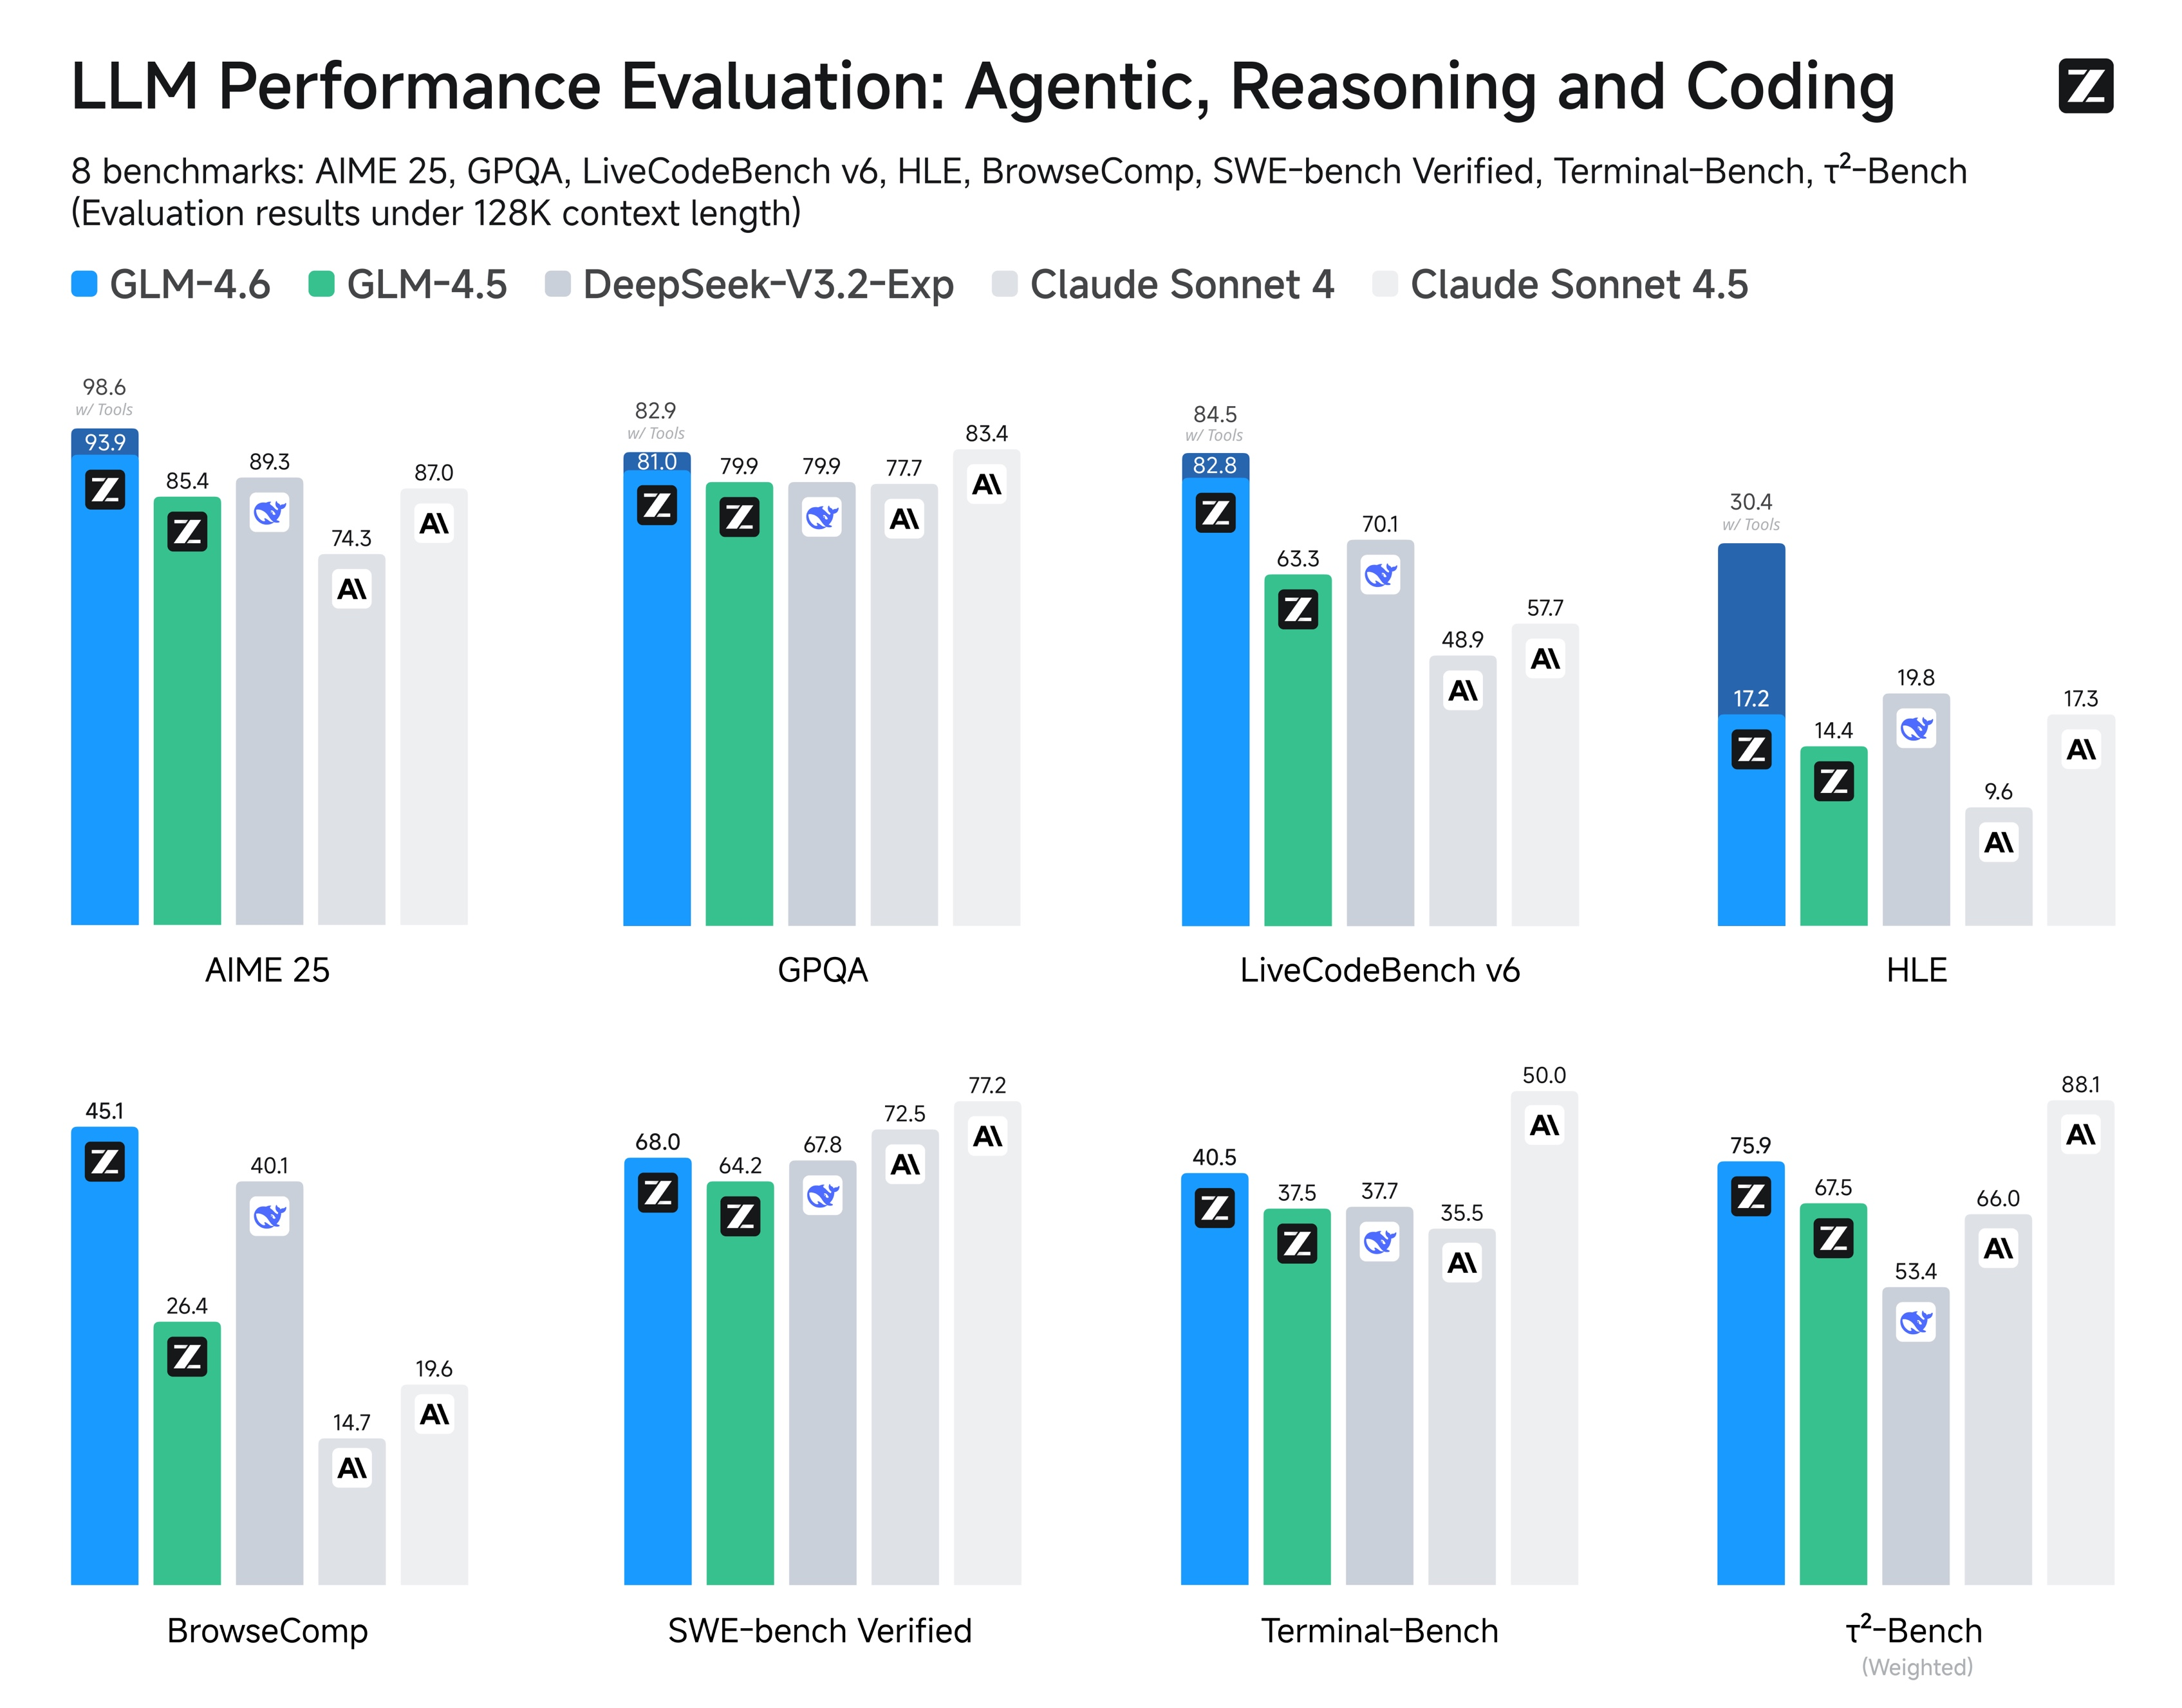
GLM-4.6: Advanced Agentic, Reasoning and Coding Capabilities
AI Report Highlights Smaller, Higher, Cheaper Fashions - YACAK
ModelOp’s 2026 AI Governance Benchmark Report Shows Explosion of
LLMs as Judges: A Comprehensive Survey on LLM-Based Evaluation Methods ...
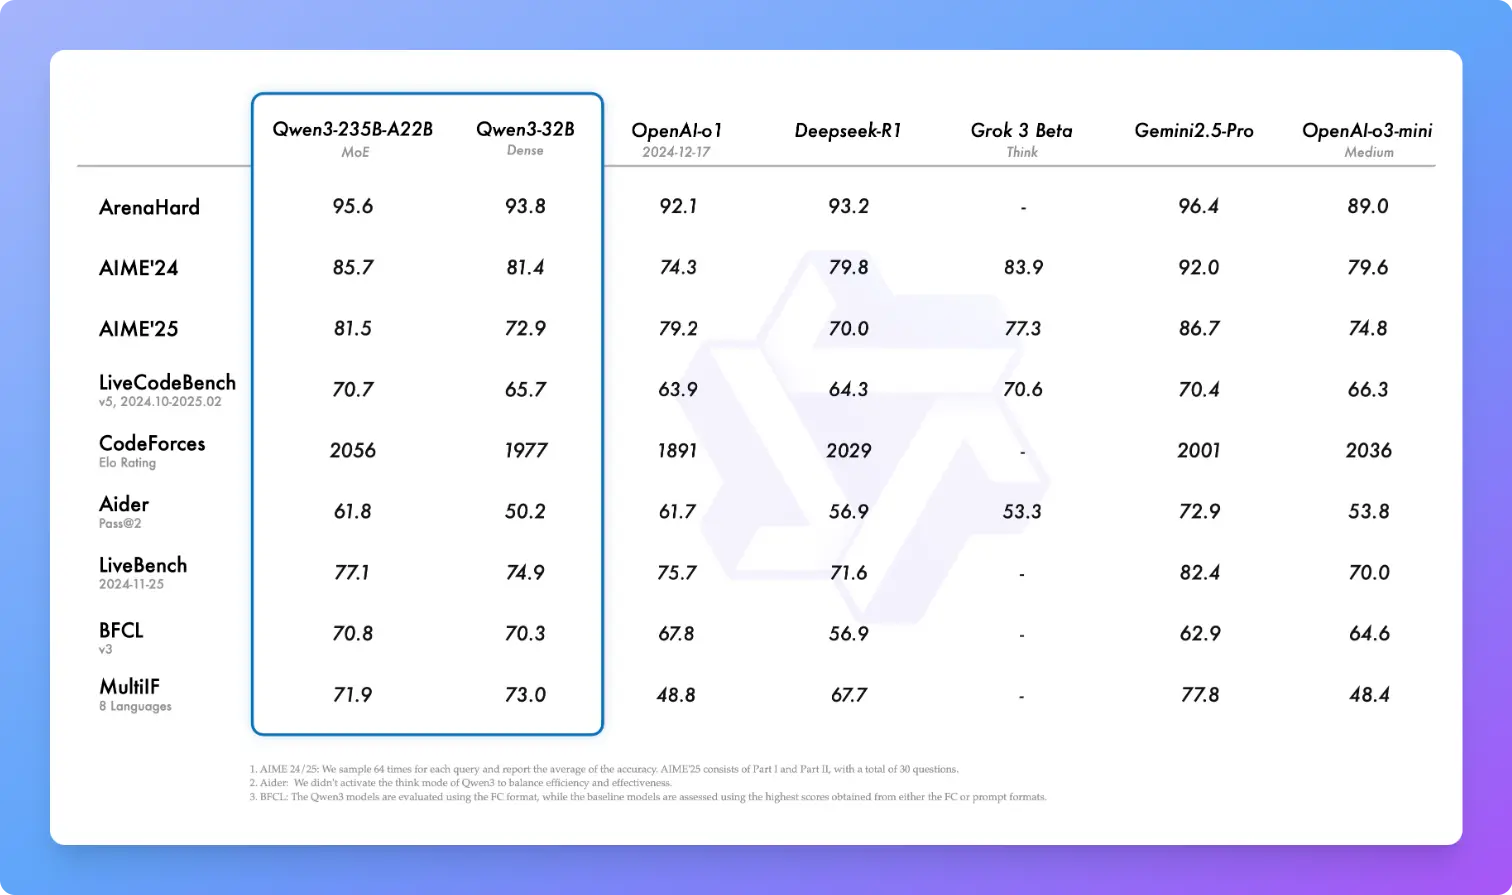
重磅!阿里开源第三代千问大模型:Qwen3系列,最小仅6亿参数规模,最大2350亿参数规模大模型!可以根据问题难度自动选择是否带思考过程的大 ...
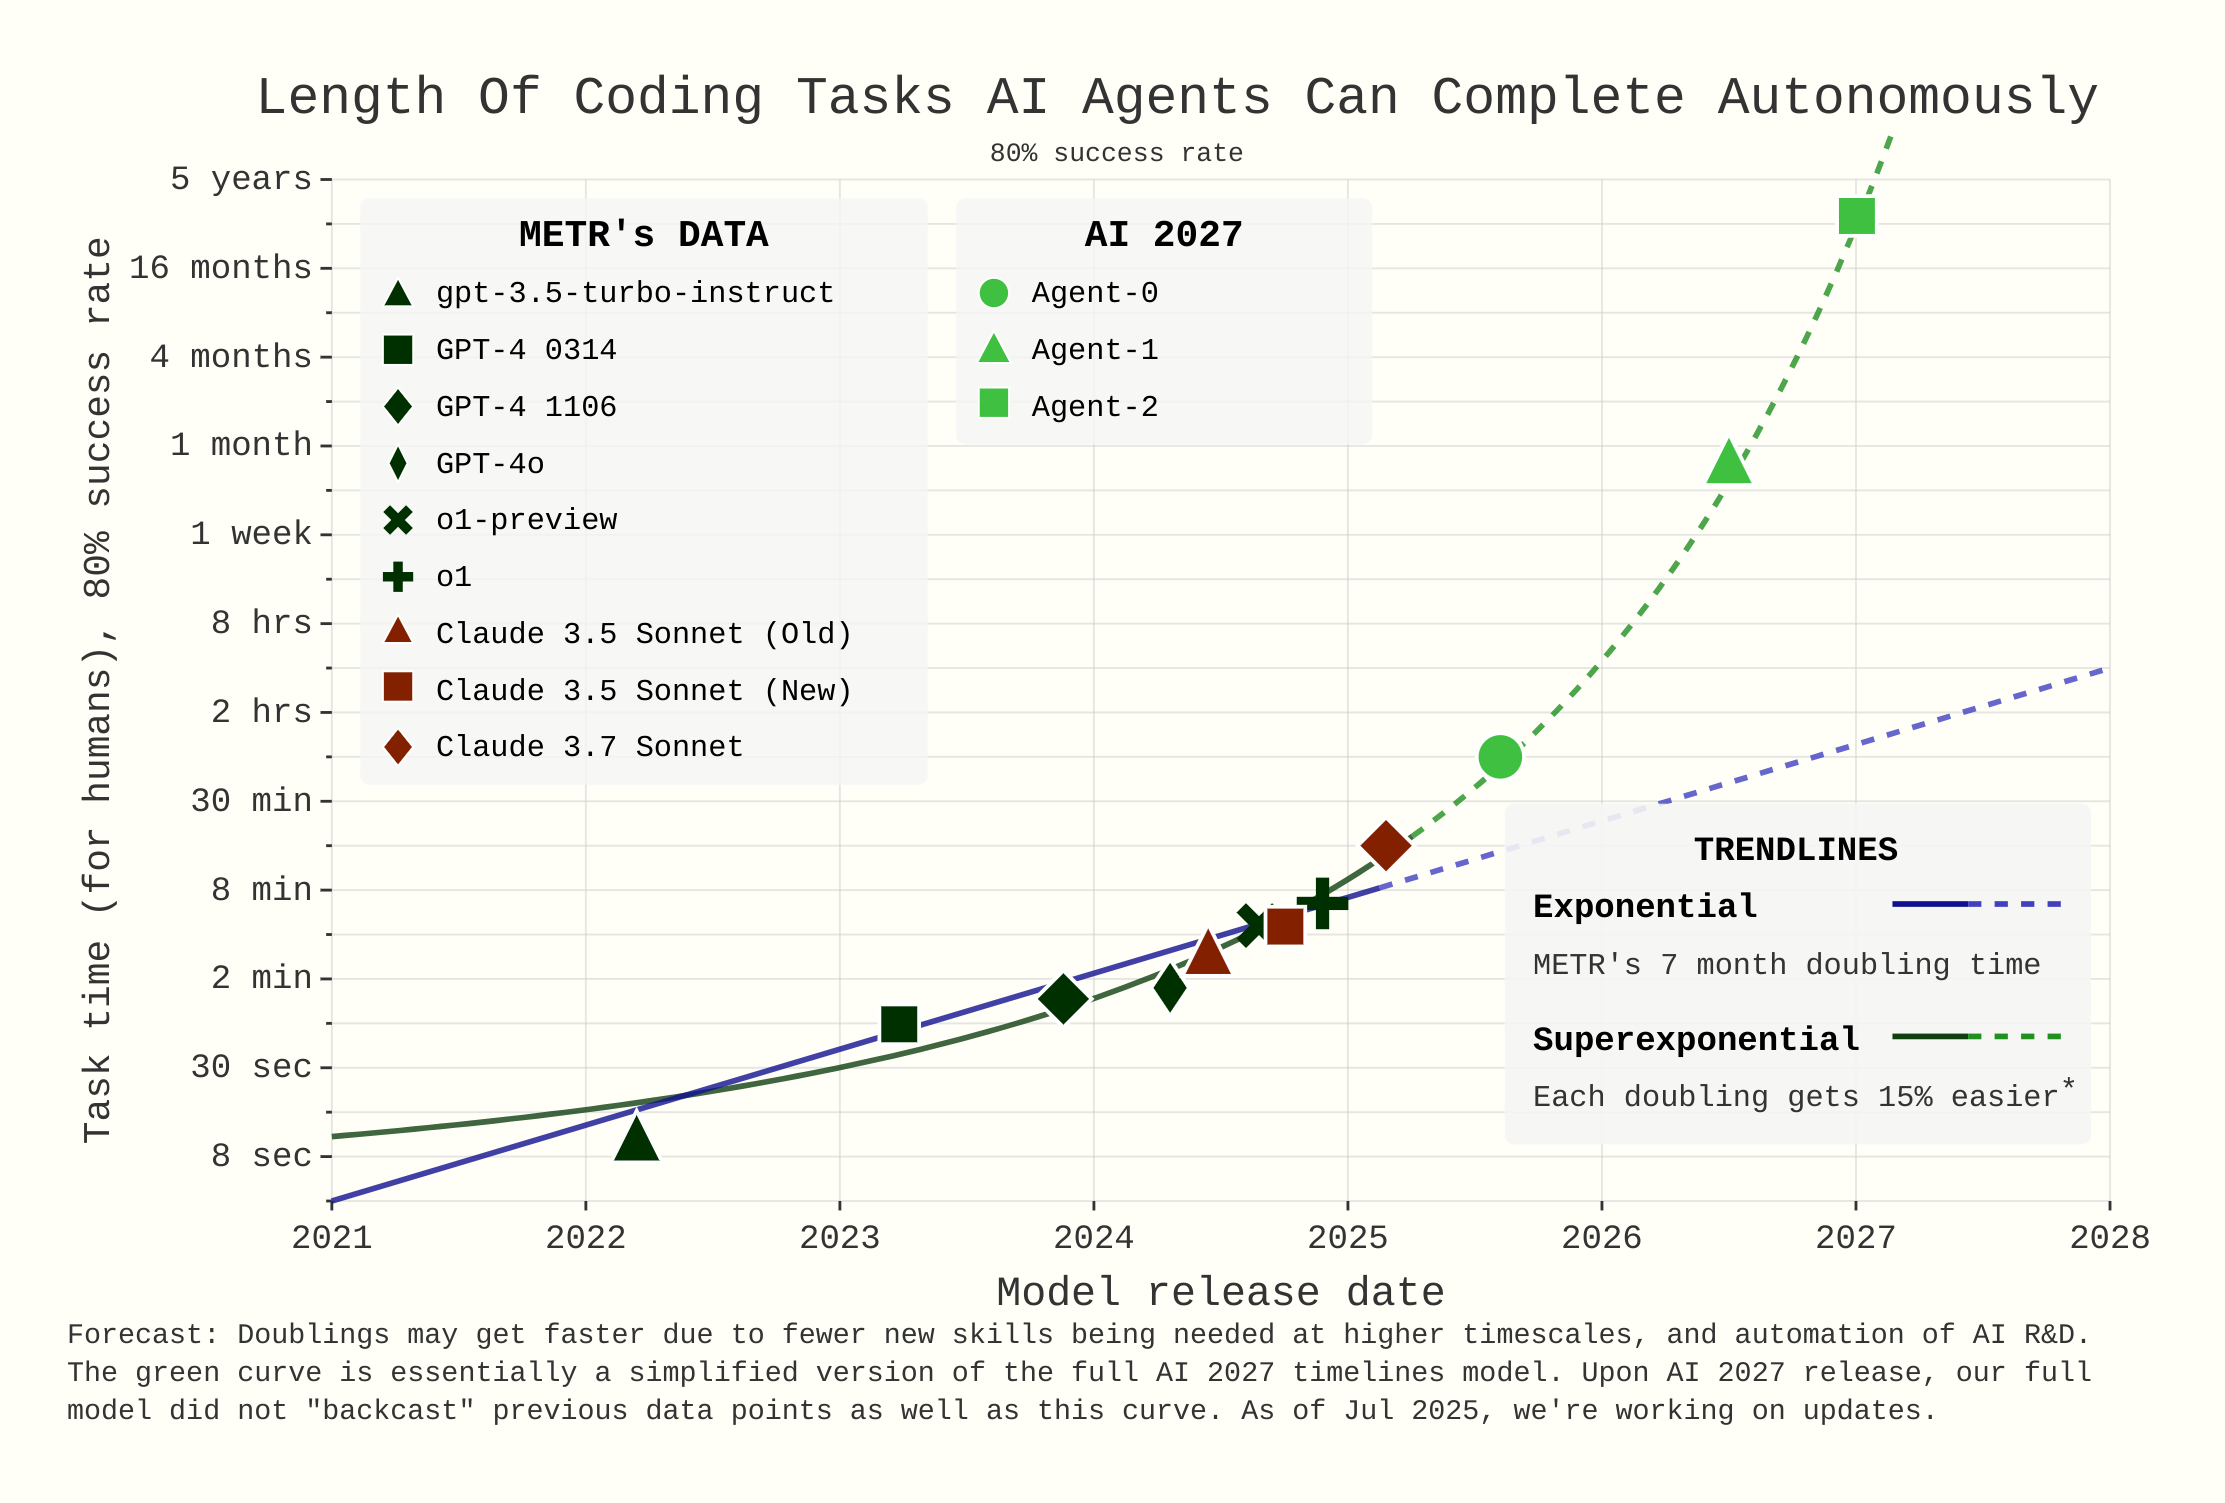
AI 2027
40 Top Research-Backed LLM Benchmarks and Where To Use Them
Modern-AI Benchmarking – which models? which benchmarks? what use cases ...
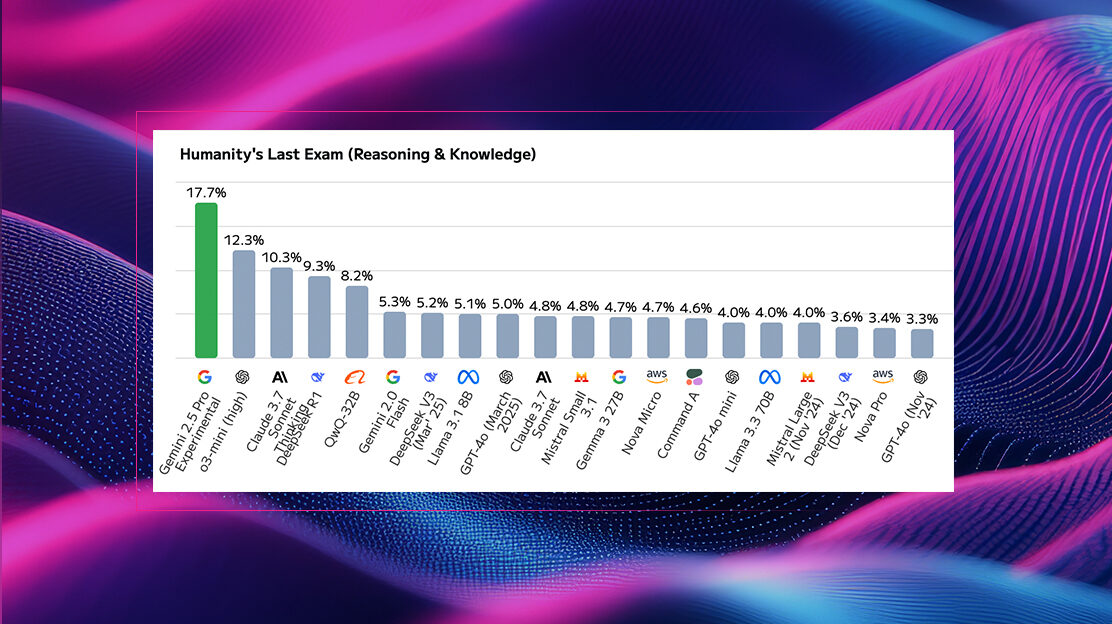
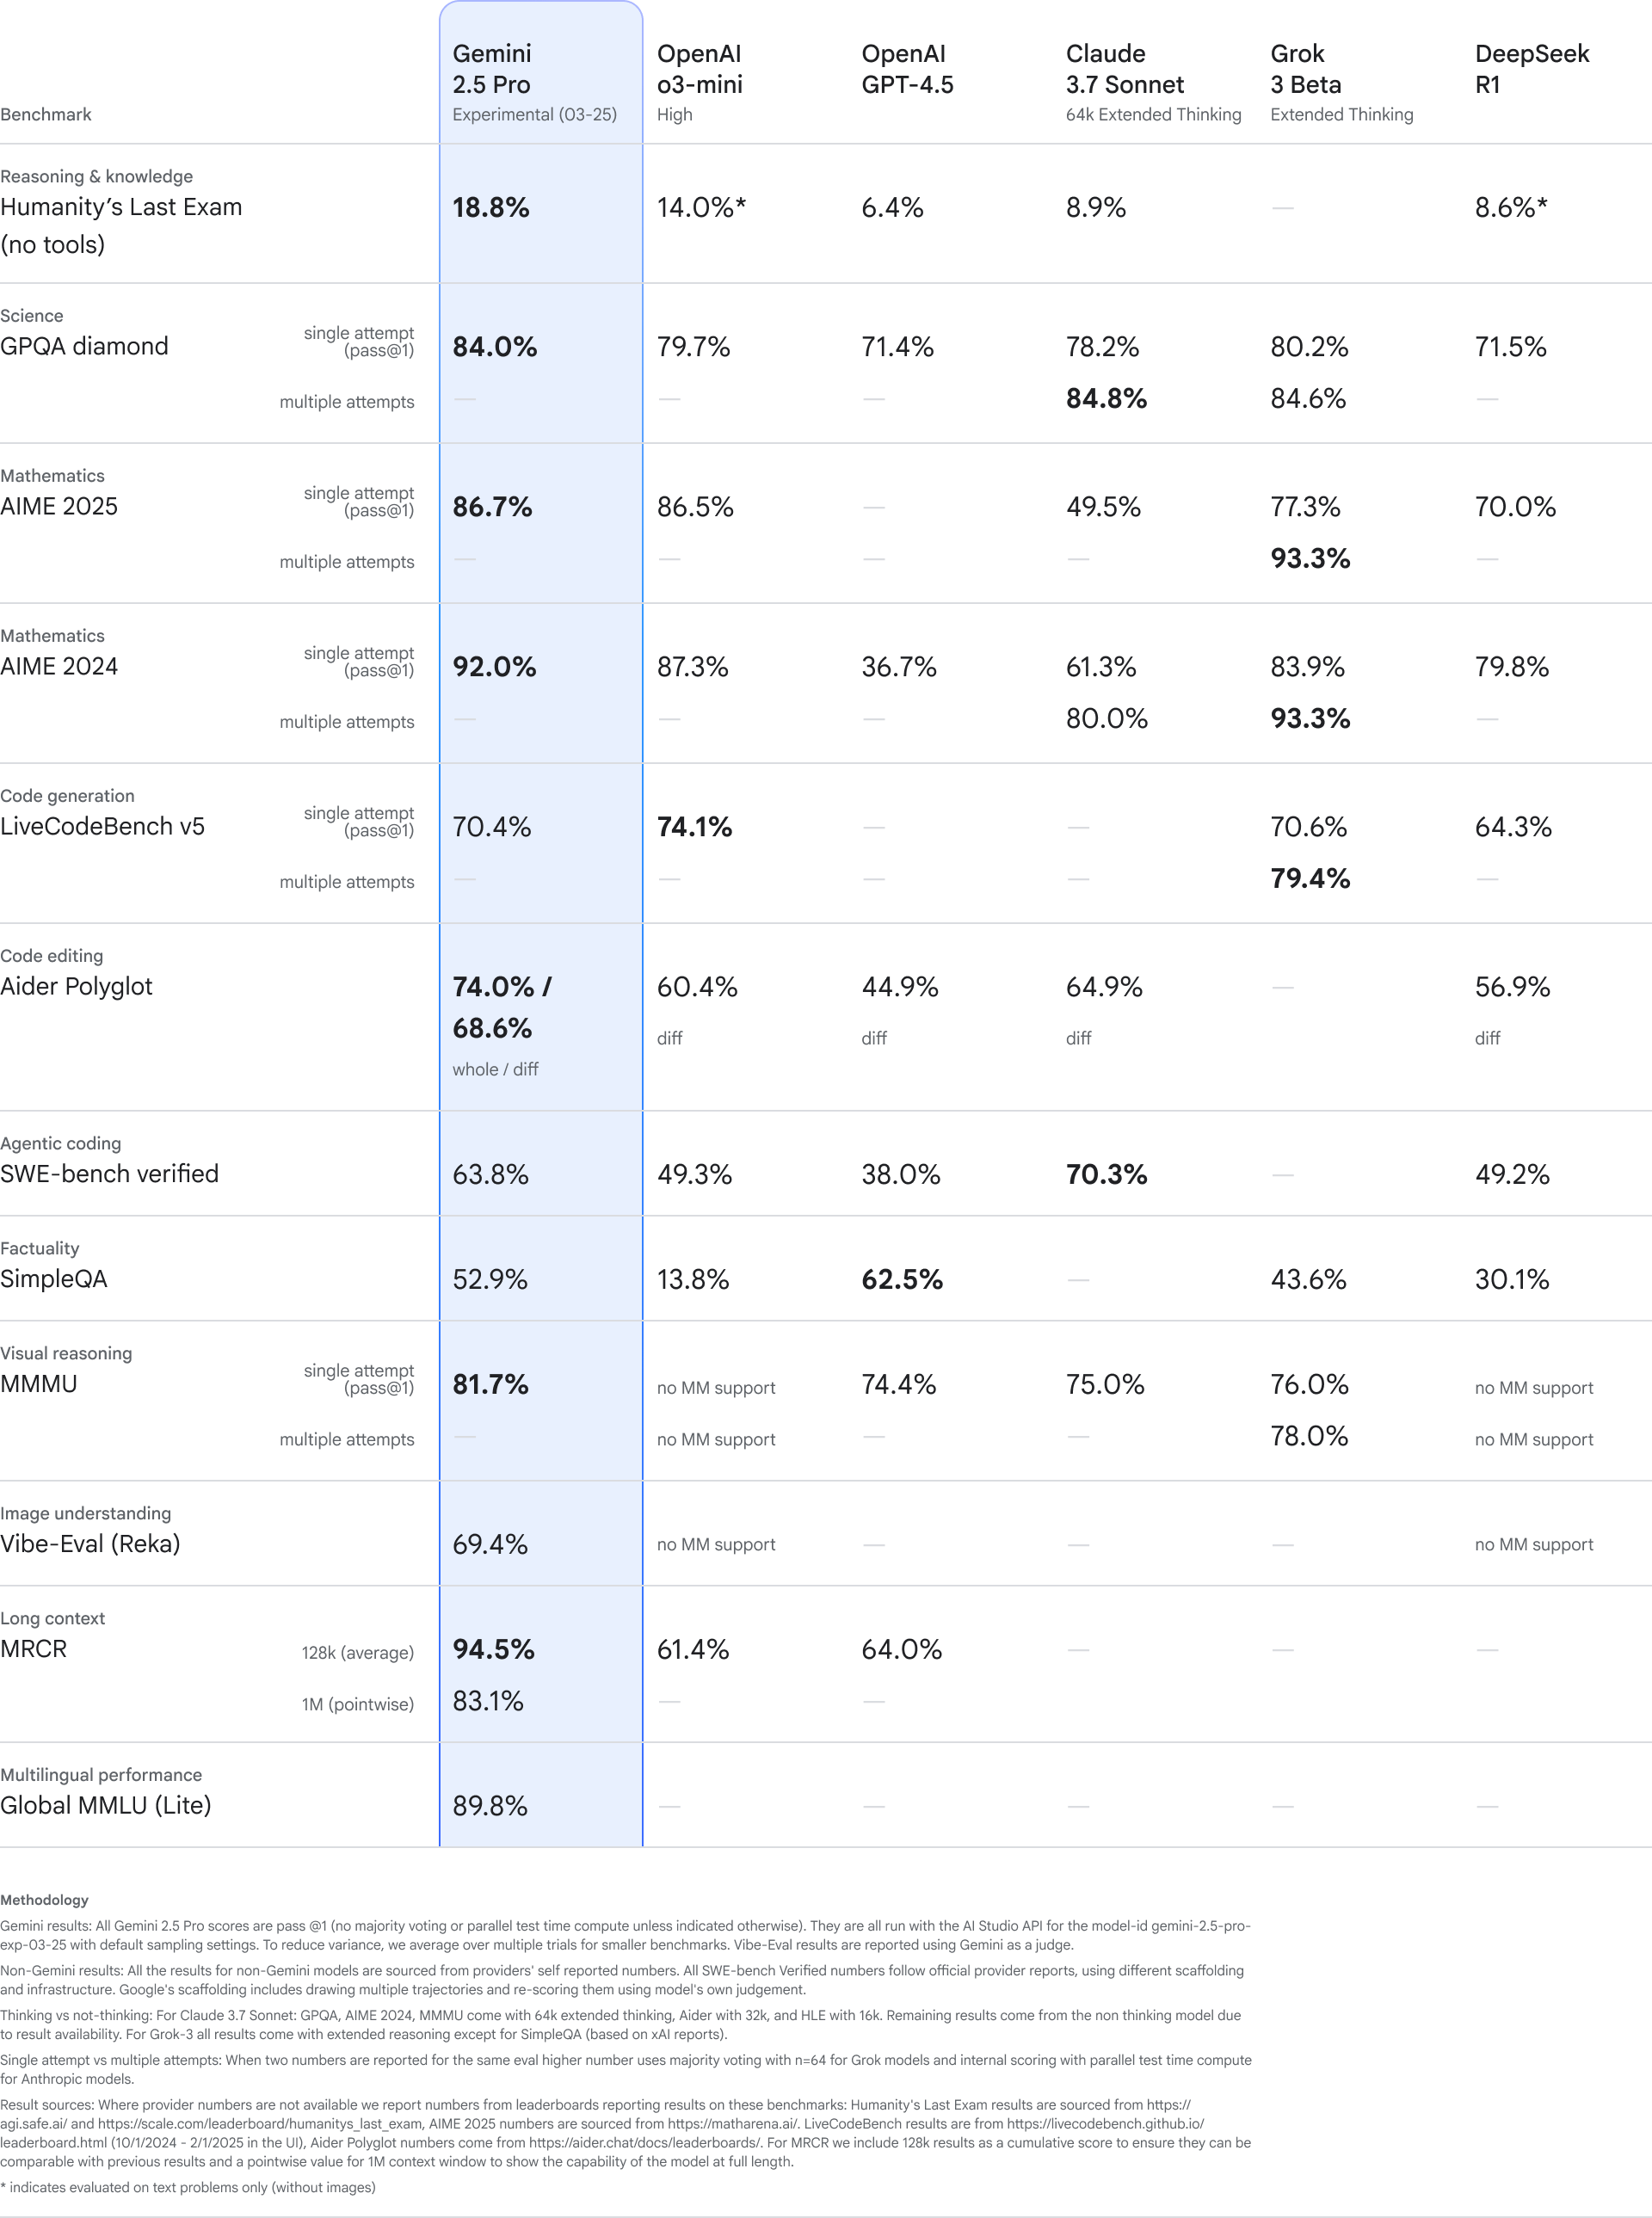
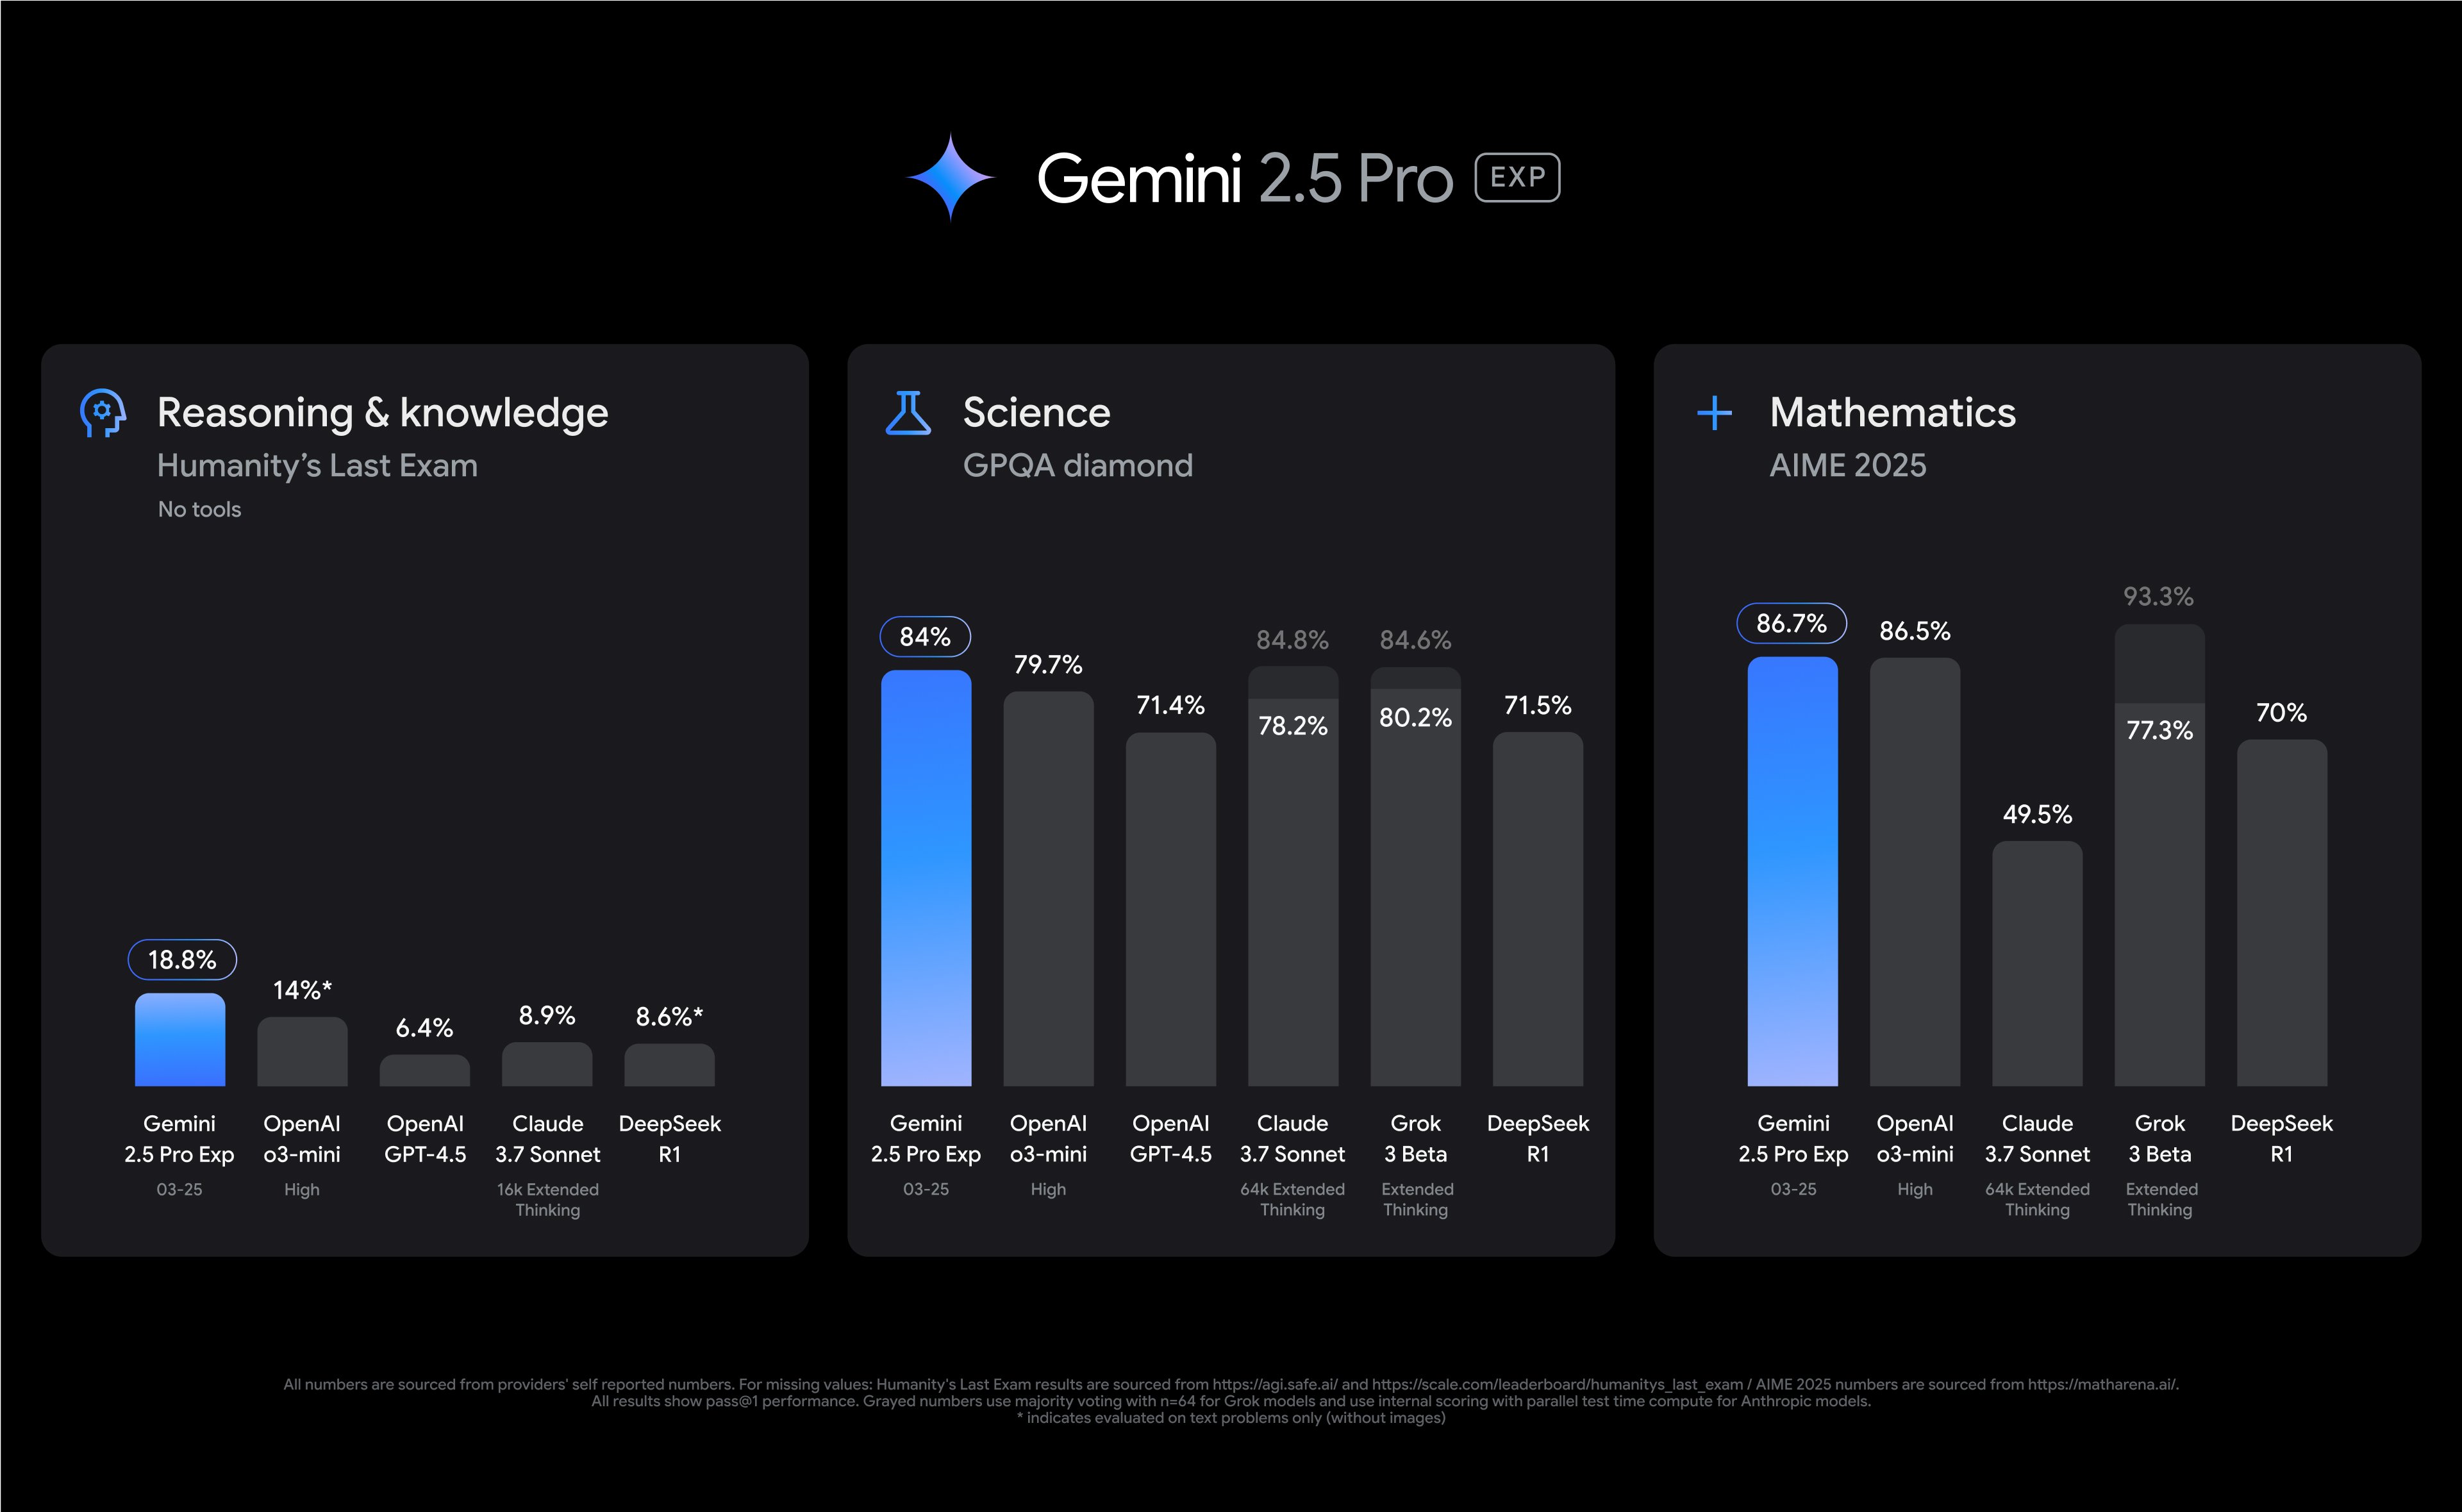
Google Releases Thinking Gemini 2.5 Pro Model, Tops Most Benchmarks
All You Need To Know About Google's Gemini 2.5 Pro - TechDogs
AI Benchmarking Dashboard | Epoch AI
Ai Model Benchmarks: Đánh Giá Hiệu Suất Các Mô Hình AI Mới Nhất
Qwen3-Coder-Next huggingface.co api & unsloth Qwen3-Coder-Next github ...
OpenAI の o3: AI ベンチマークの不一致により、パフォーマンスに関する主張のギャップが明らかに - 世界の顔
Claude Opus 4 vs GPT 4.1 | Eden AI
GitHub recognized as a Leader by 2026 Gartner® Magic Quadrant™ for ...
Latest | Epoch AI
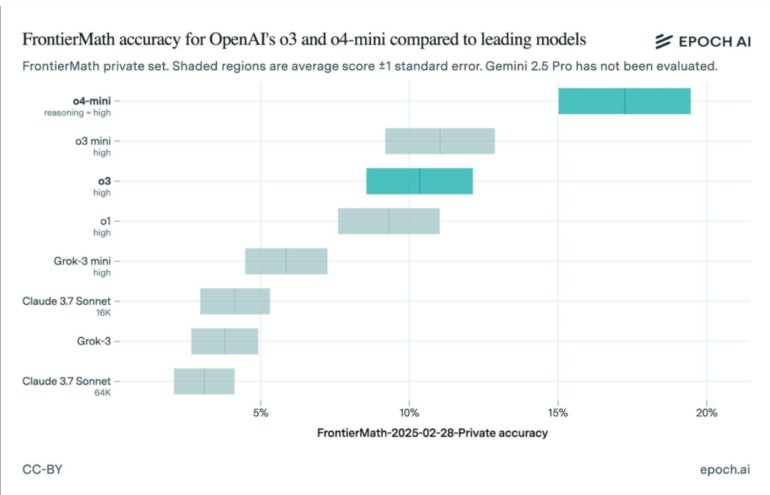
大模型数学能力评测排行榜 - AIME 2025 / FrontierMath / MATH-500 / GSM8K【2026年4月更新 ...
How to Measure ROI of AI Search Visibility (With Real Benchmarks) for 2026
SpaceXAI Partners with Cursor AI to Build… | gentic.news
国产开源大模型崛起:使用Kimi K2/Qwen2/GLM-4.5搭建编程助手_kimi k2补全类ide-CSDN博客
comparison - Blog | Claw4Science
【2026年最新】5大生成AI比較!ChatGPT・Gemini・Claude・Copilot・Grokの違いと選び方 | MiraLabAI
新手学编程指南:2026年从零起步的全方位攻略 - 编程知识 | Galenry
GLM-5: el modelo de IA de Zhipu que desafía a Claude y GPT-5 - OneDigital
E-Commerce KI-Sichtbarkeit Benchmark | Alexandrya.AI
Claude vs ChatGPT: Compare Features, Pricing & Business Value
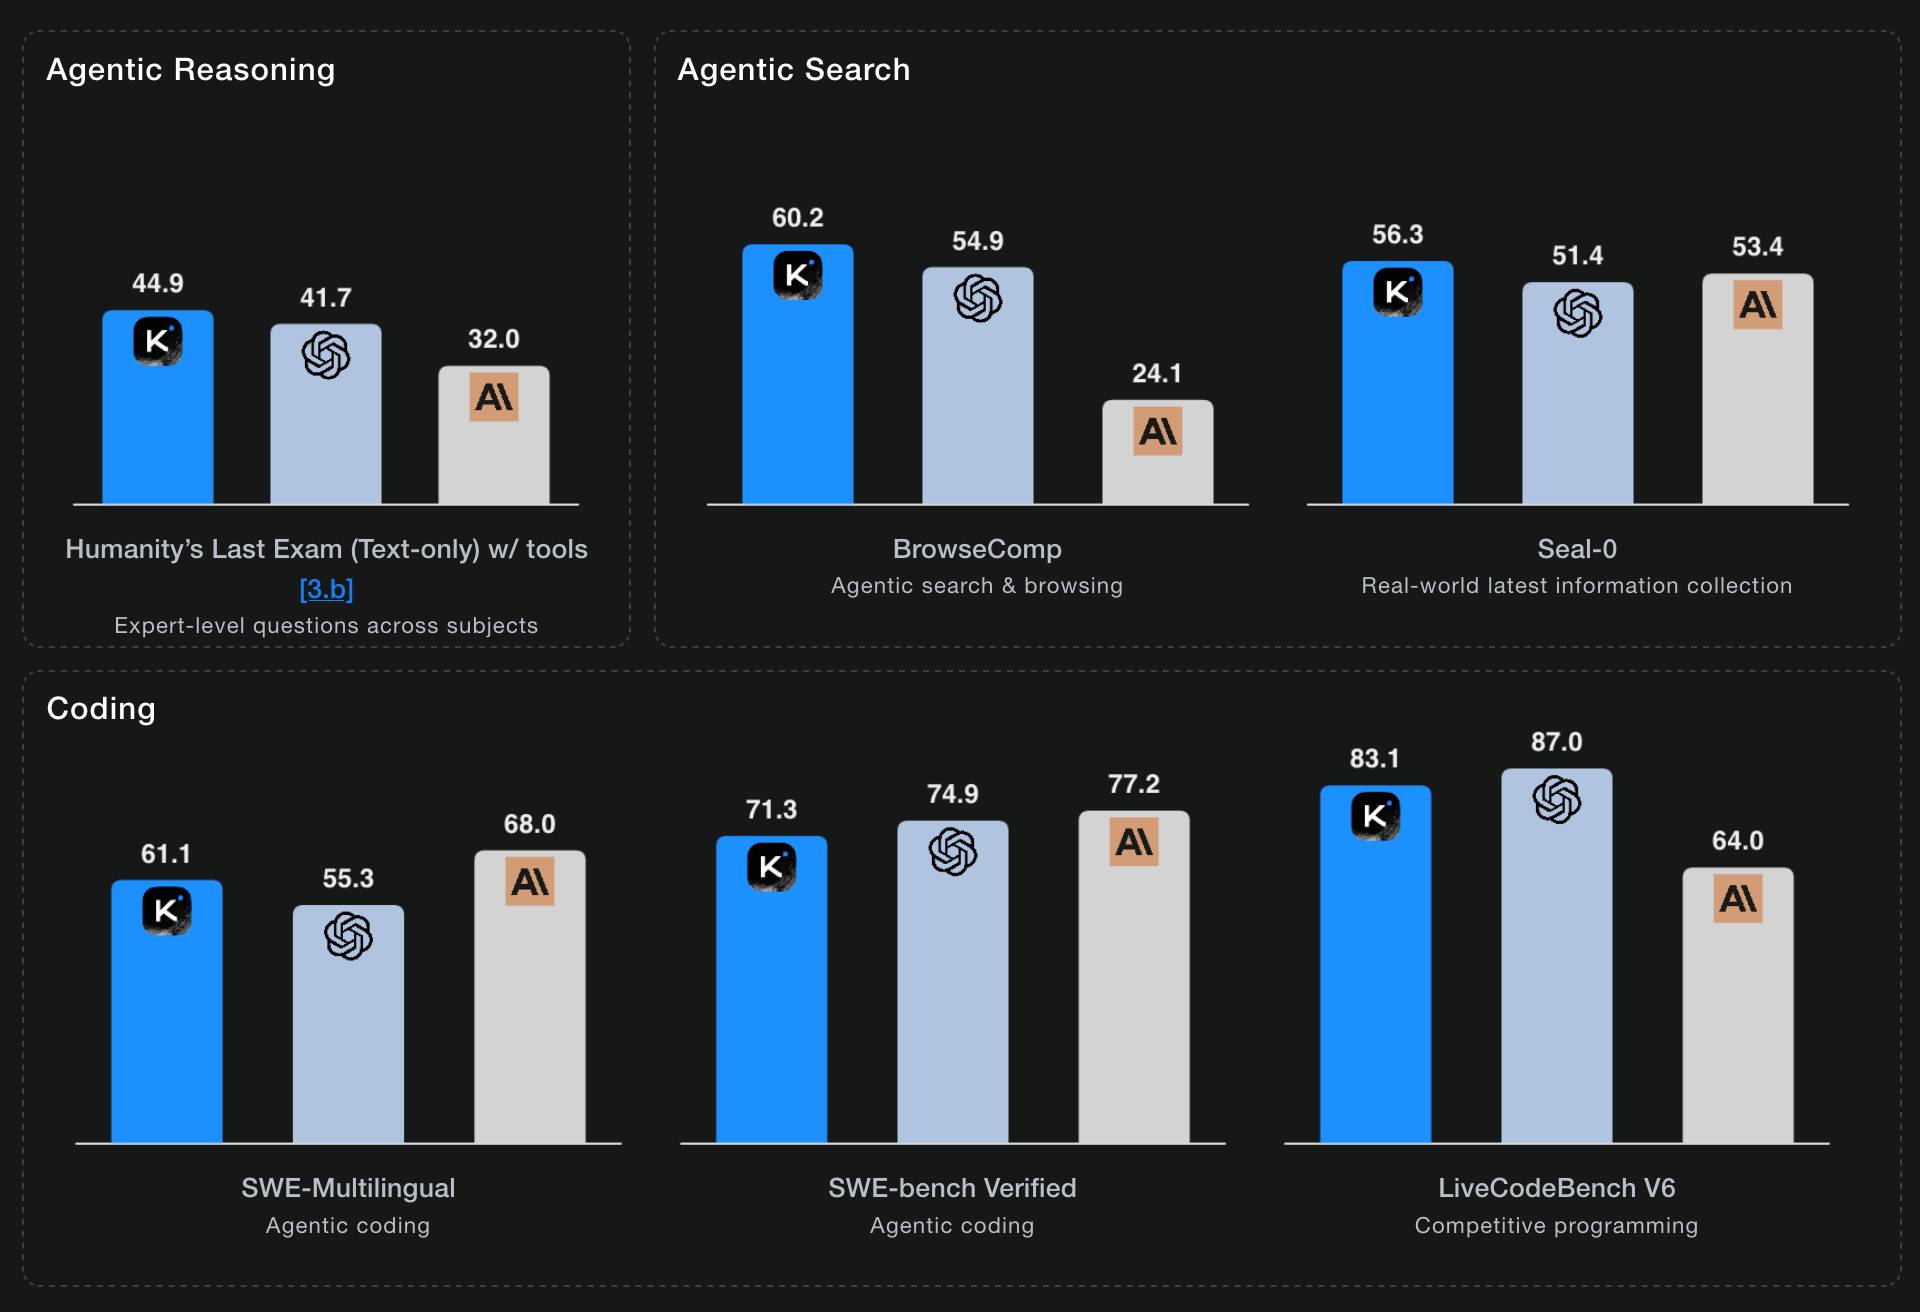
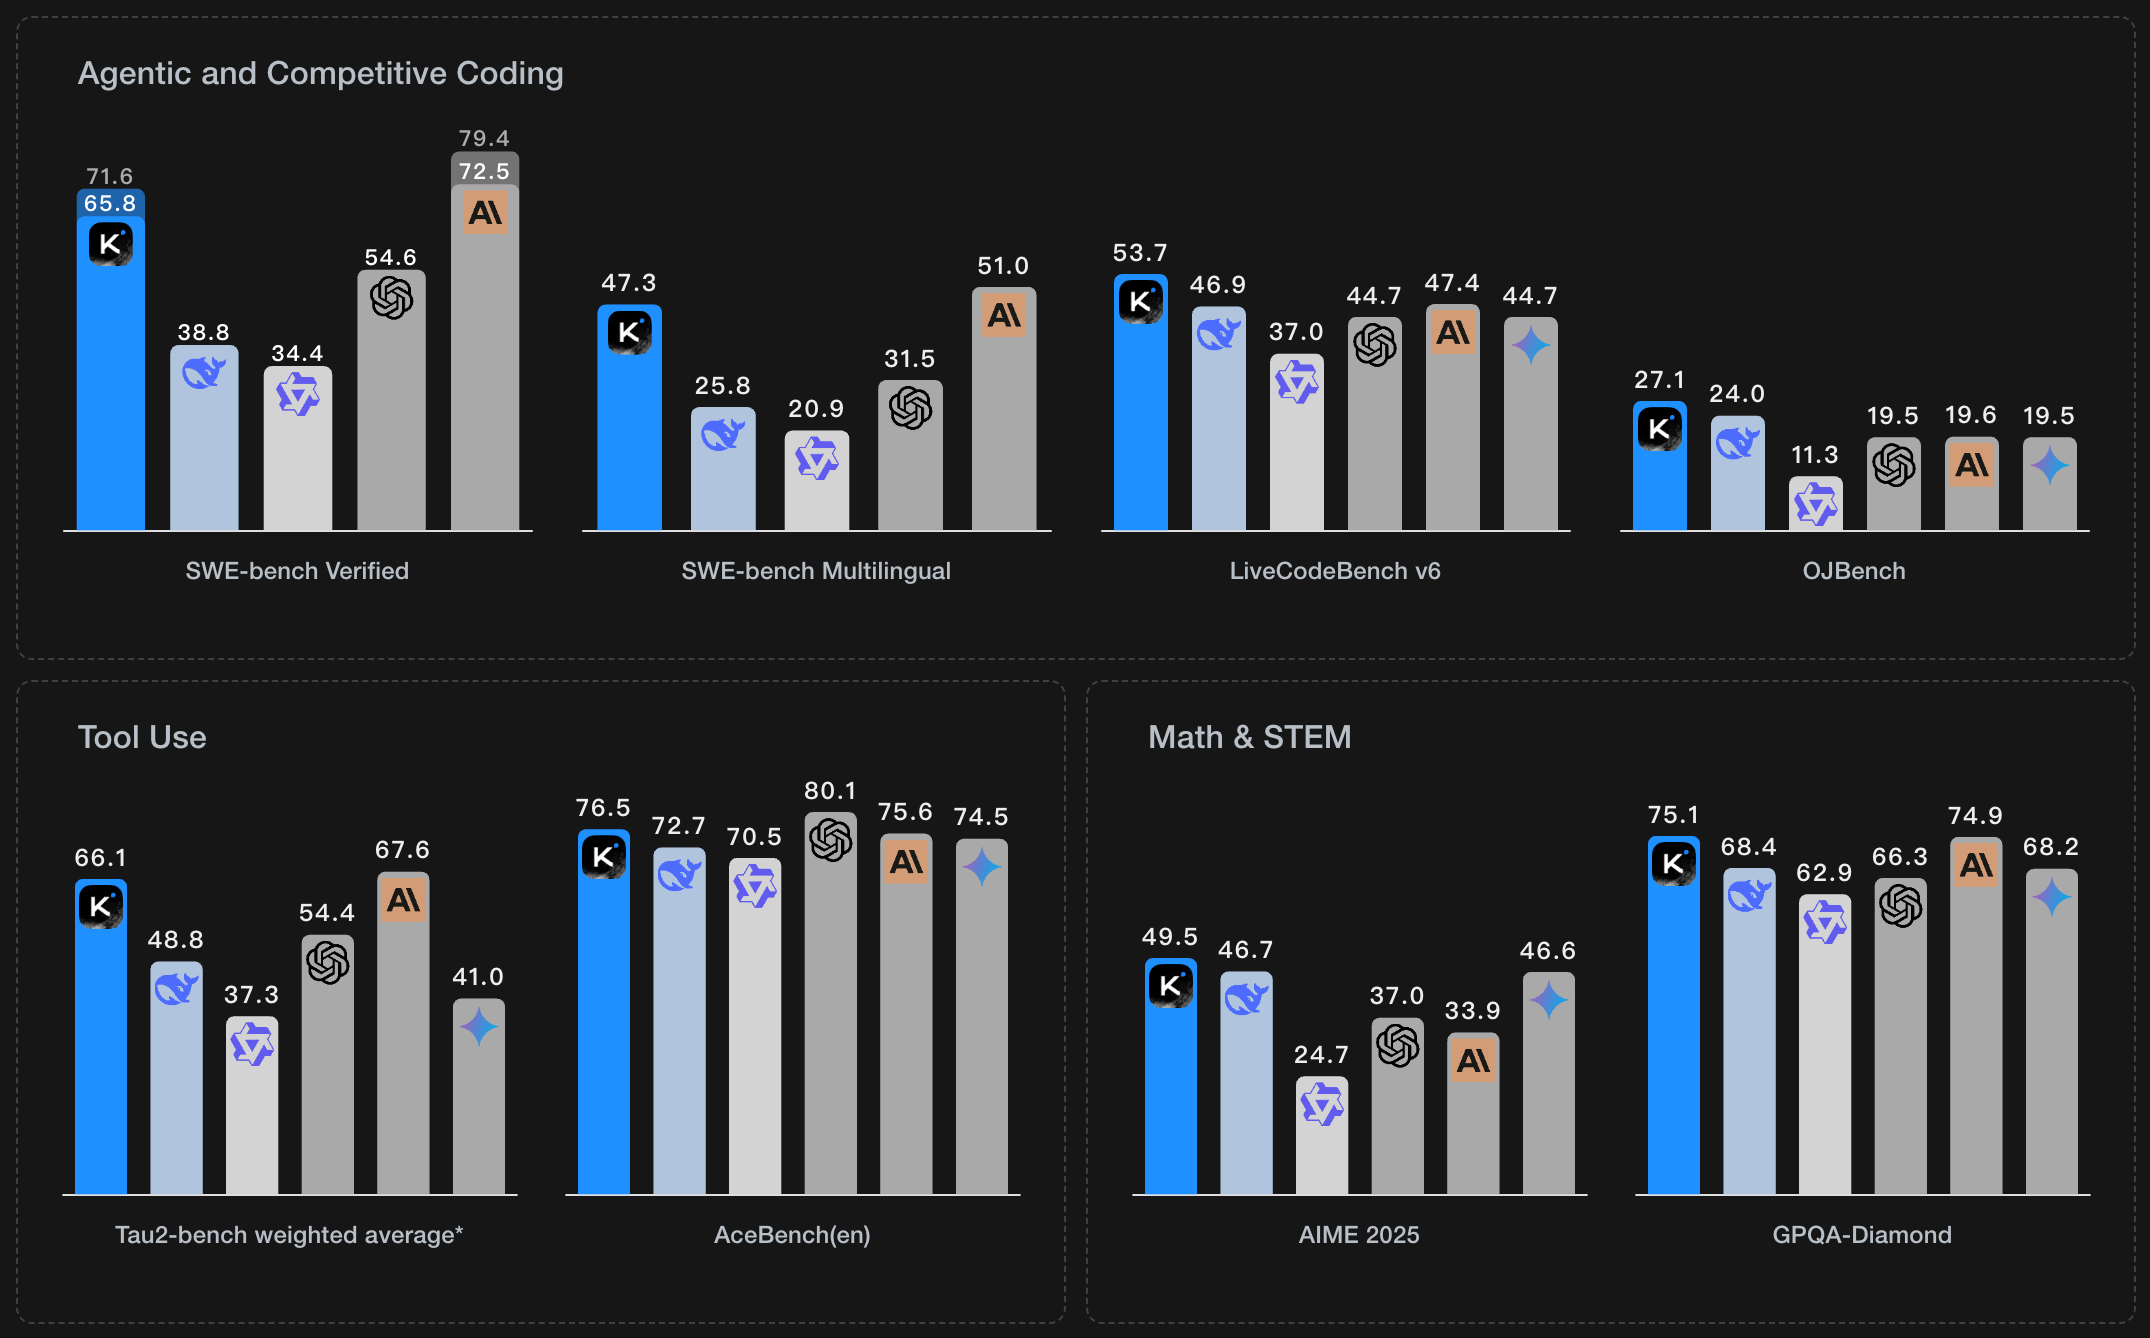
Kimi K2 Thinking
As 10 IA's mais importantes de 2025
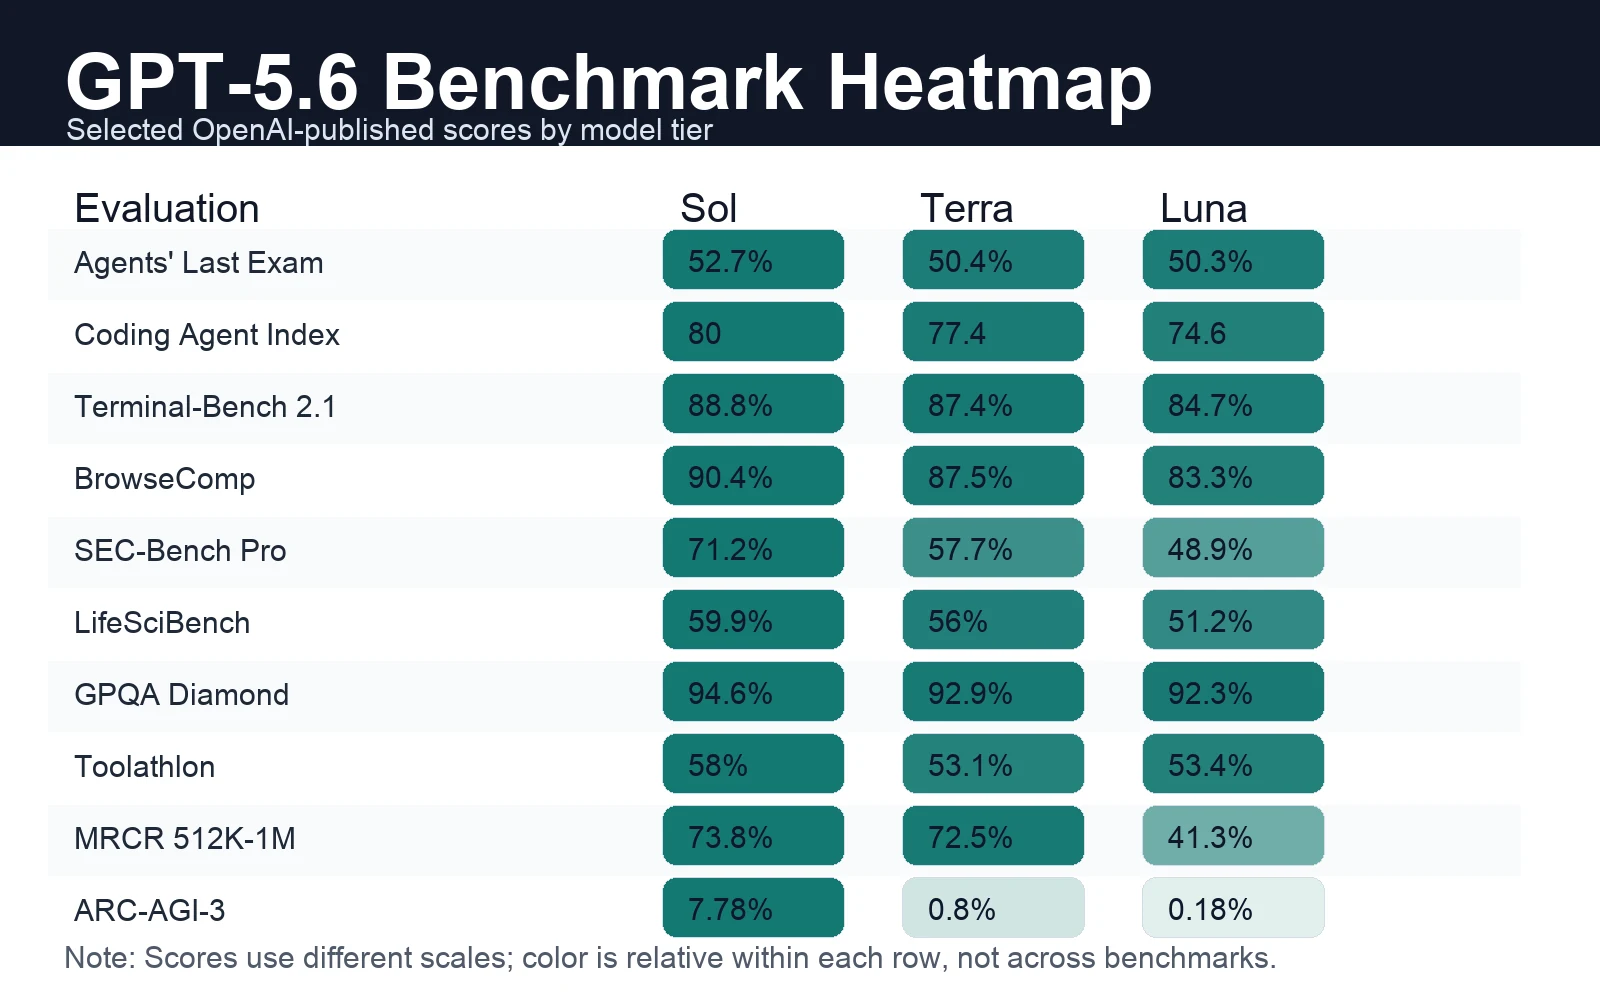
GPT-5.6 Sol vs Terra vs Luna: Price & Best Uses
Qwen
Kimi K2 - 开源混合专家大模型 | 1万亿参数 | K2.7 Code
Best LLMs for coding: developer favorites
Claude Sonnet 4.5 : le modèle d'IA d'Anthropic taillé pour le code
qwen2.5-coder:1.5b-instruct
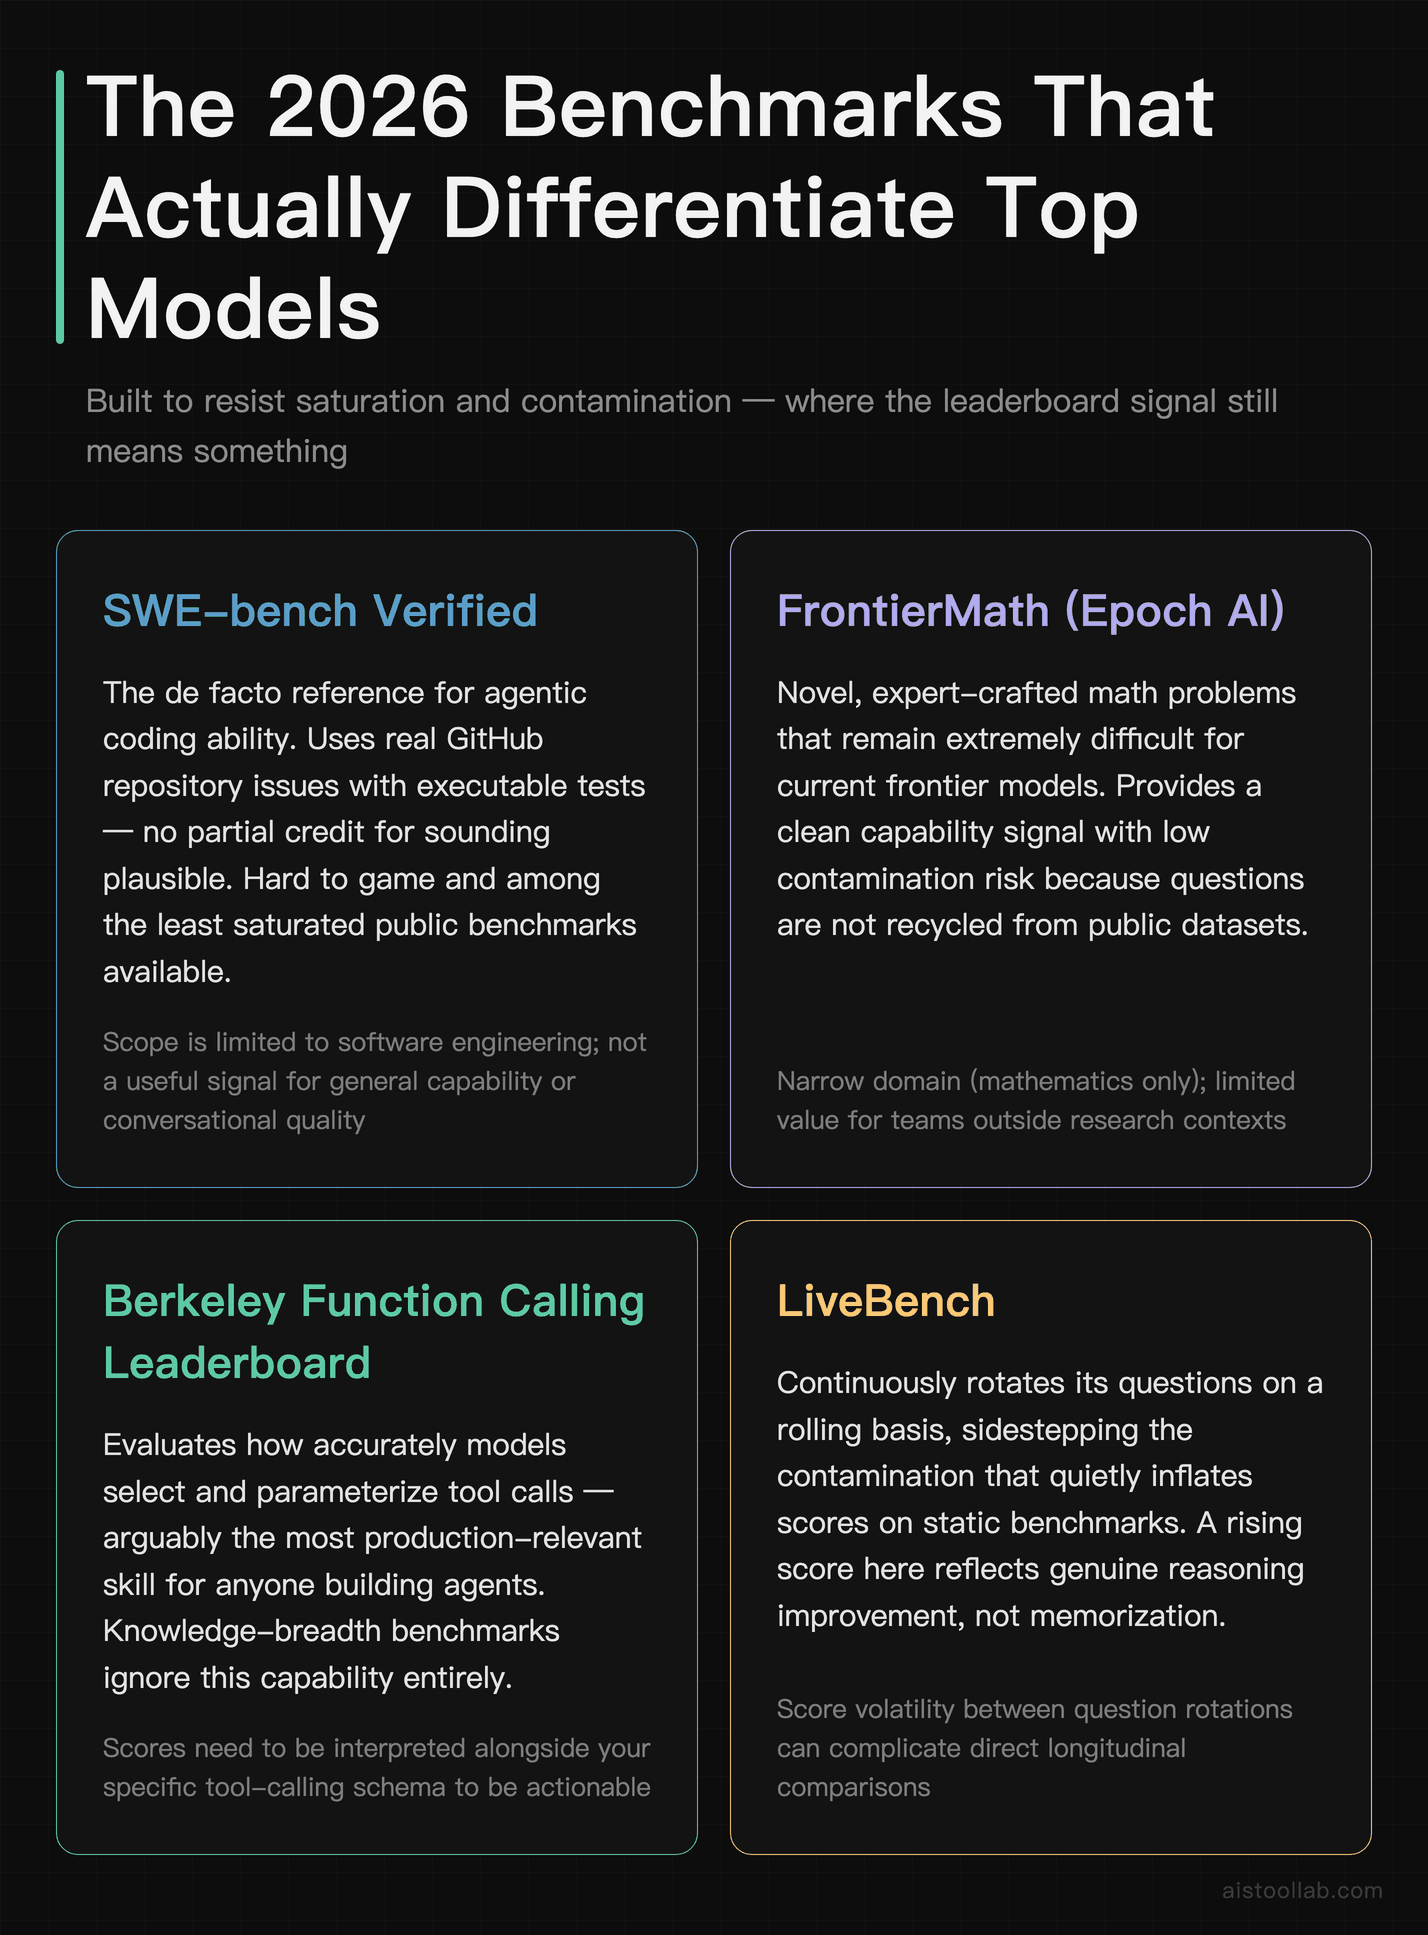
Based on this image's title: “AI coding benchmarks in 2026: why the leaderboard you pick decides the ...”