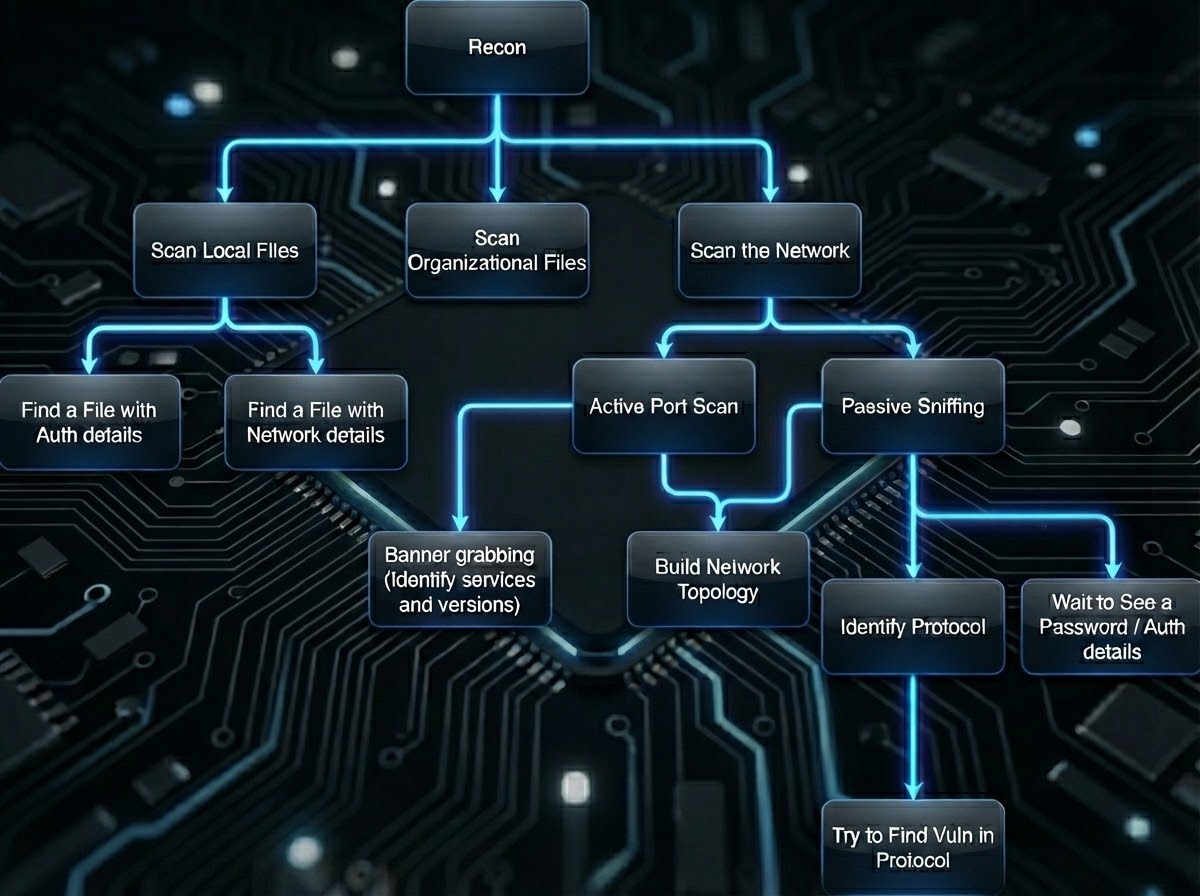
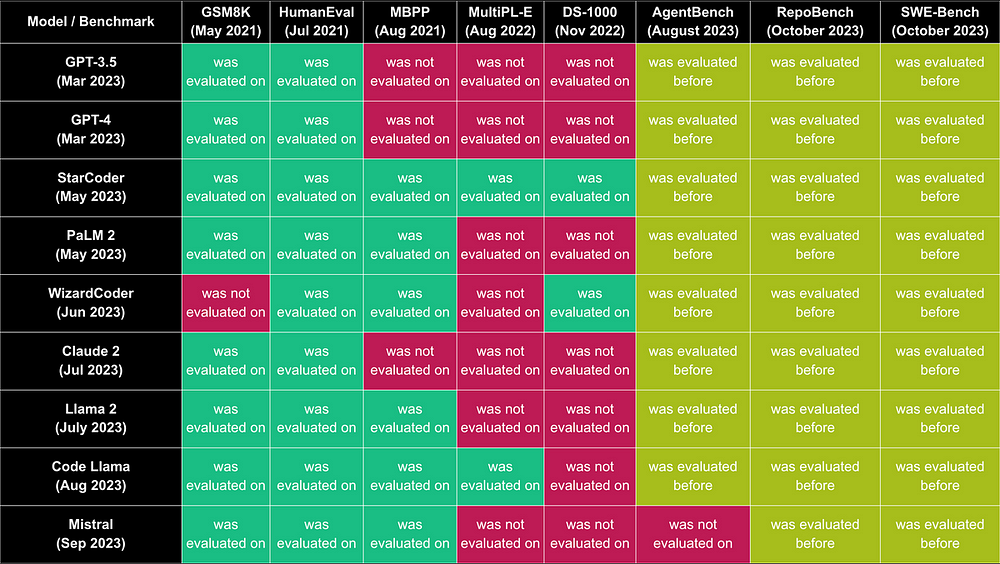
CyberExplorer: Benchmarking LLM Offensive Security Capabilities in a ...
[논문 리뷰] CTIArena: Benchmarking LLM Knowledge and Reasoning Across ...
[논문 리뷰] HarmMetric Eval: Benchmarking Metrics and Judges for LLM ...
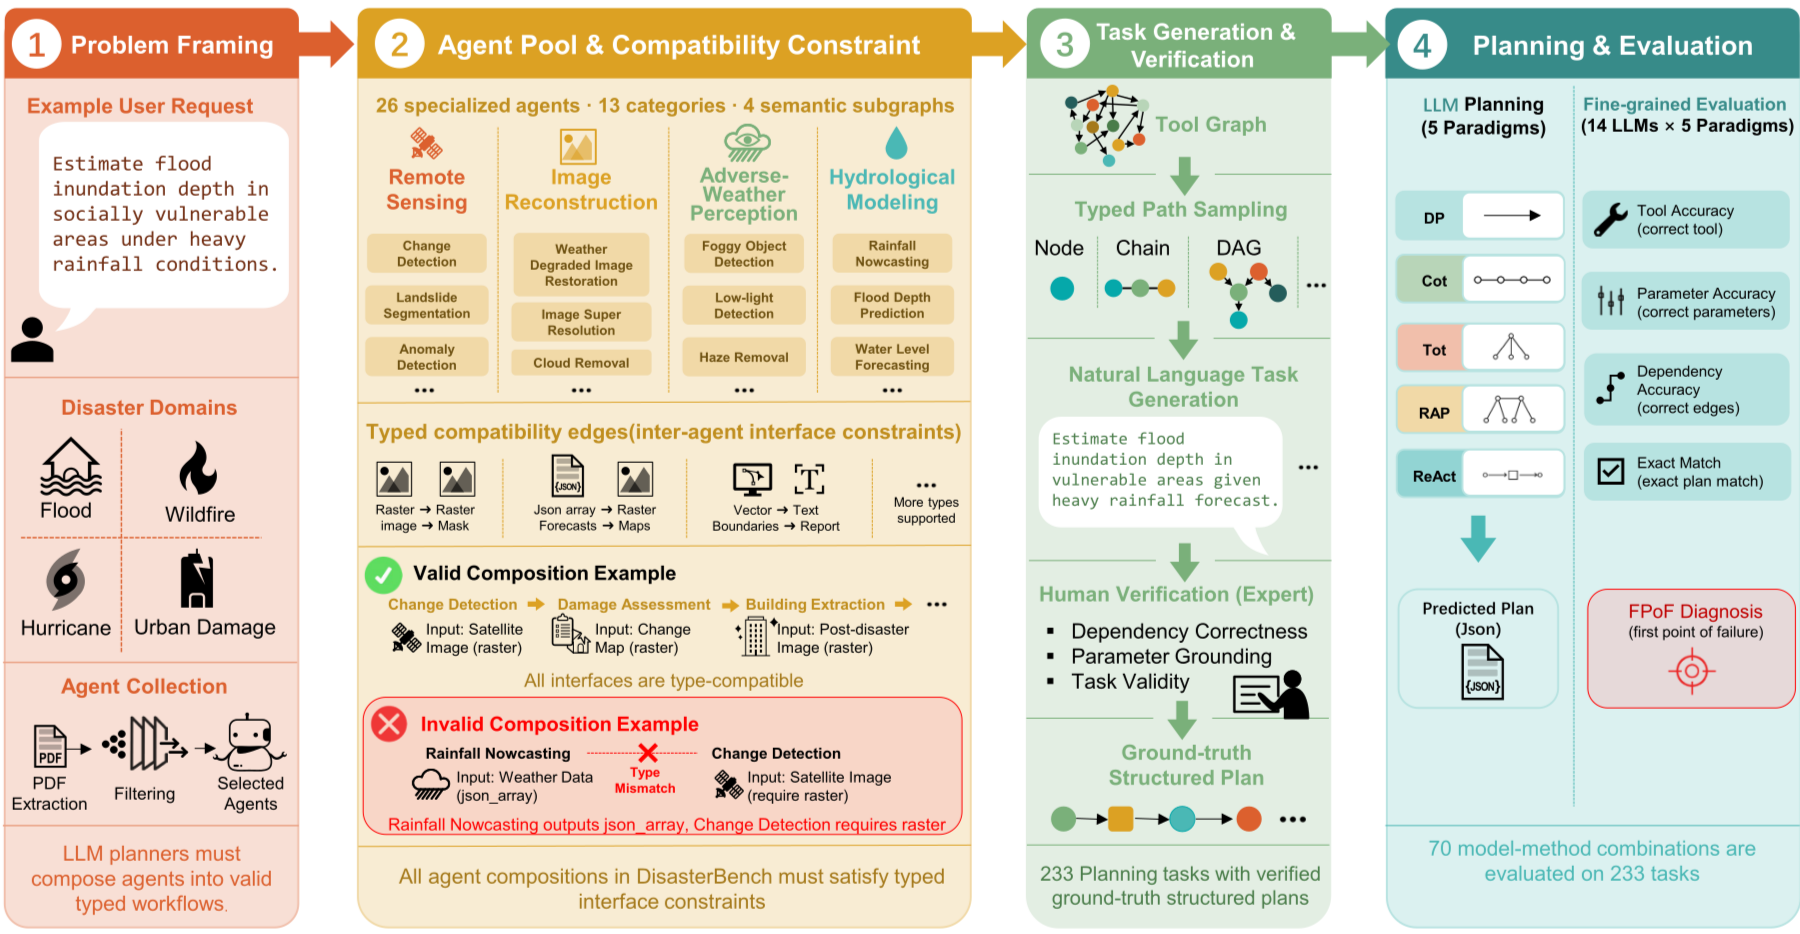
[논문 리뷰] DisasterBench: Benchmarking LLM Planning under Typed Tool ...
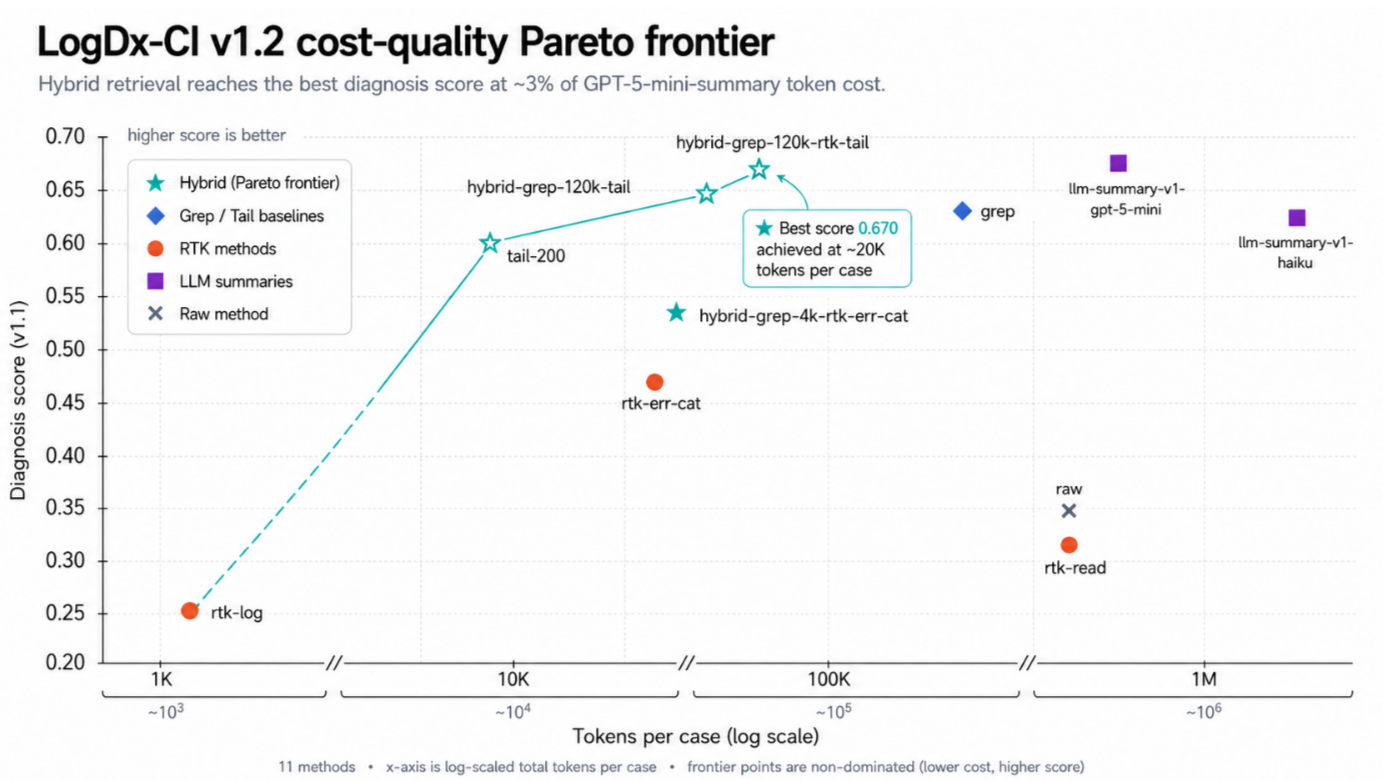
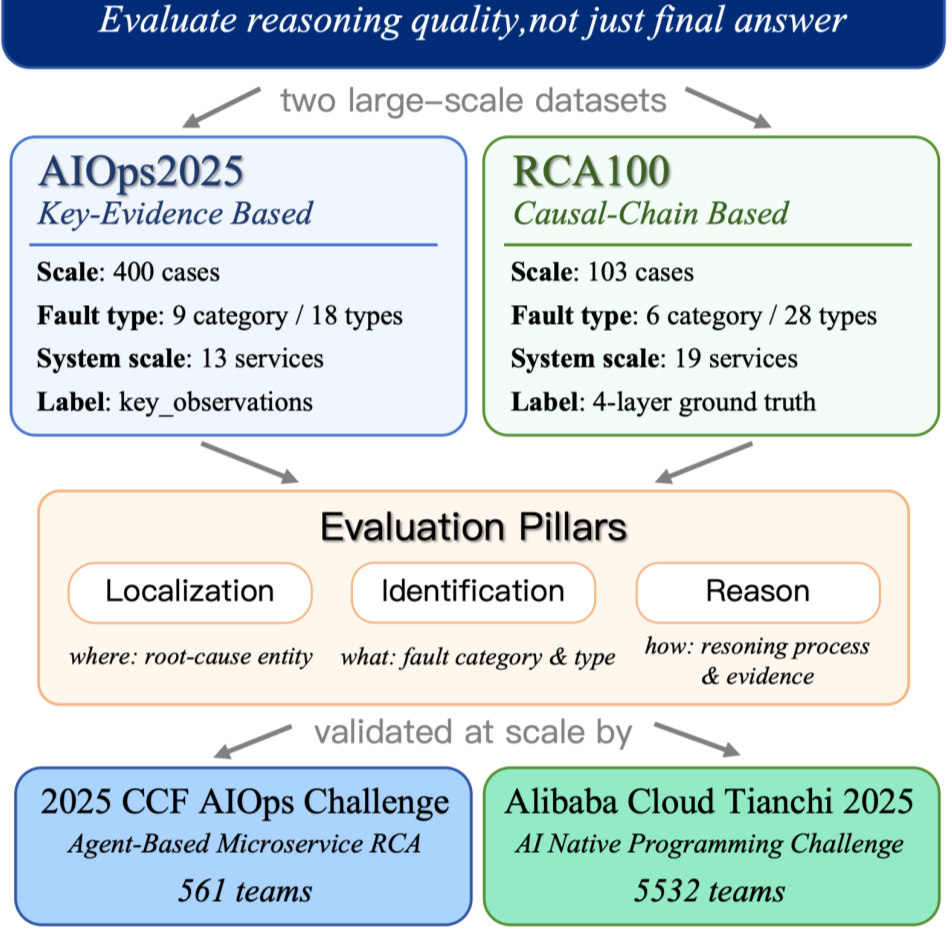
[논문 리뷰] LogDx-CI: Benchmarking Log Reduction Tools for LLM Root-Cause ...
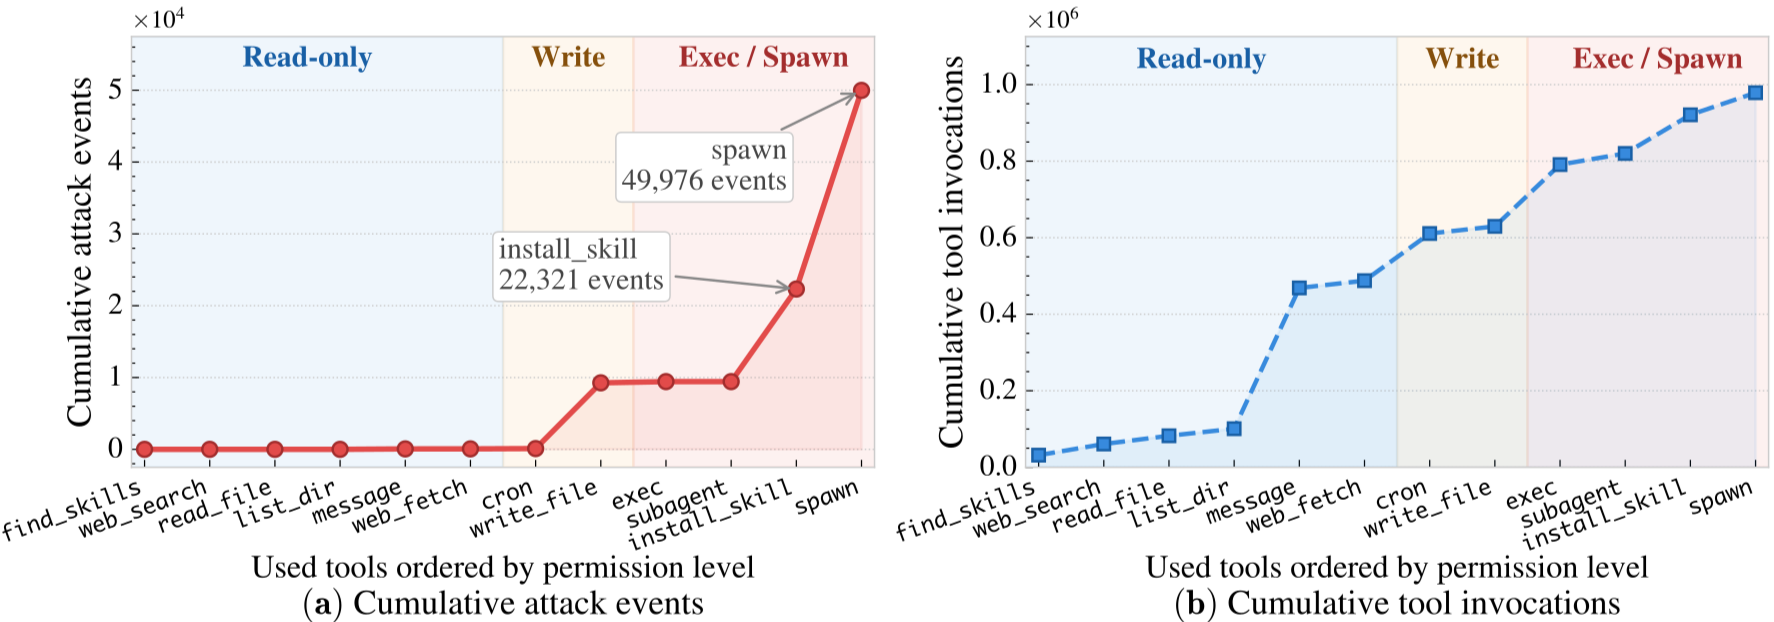
[논문 리뷰] Agent Security Bench (ASB): Formalizing and Benchmarking ...
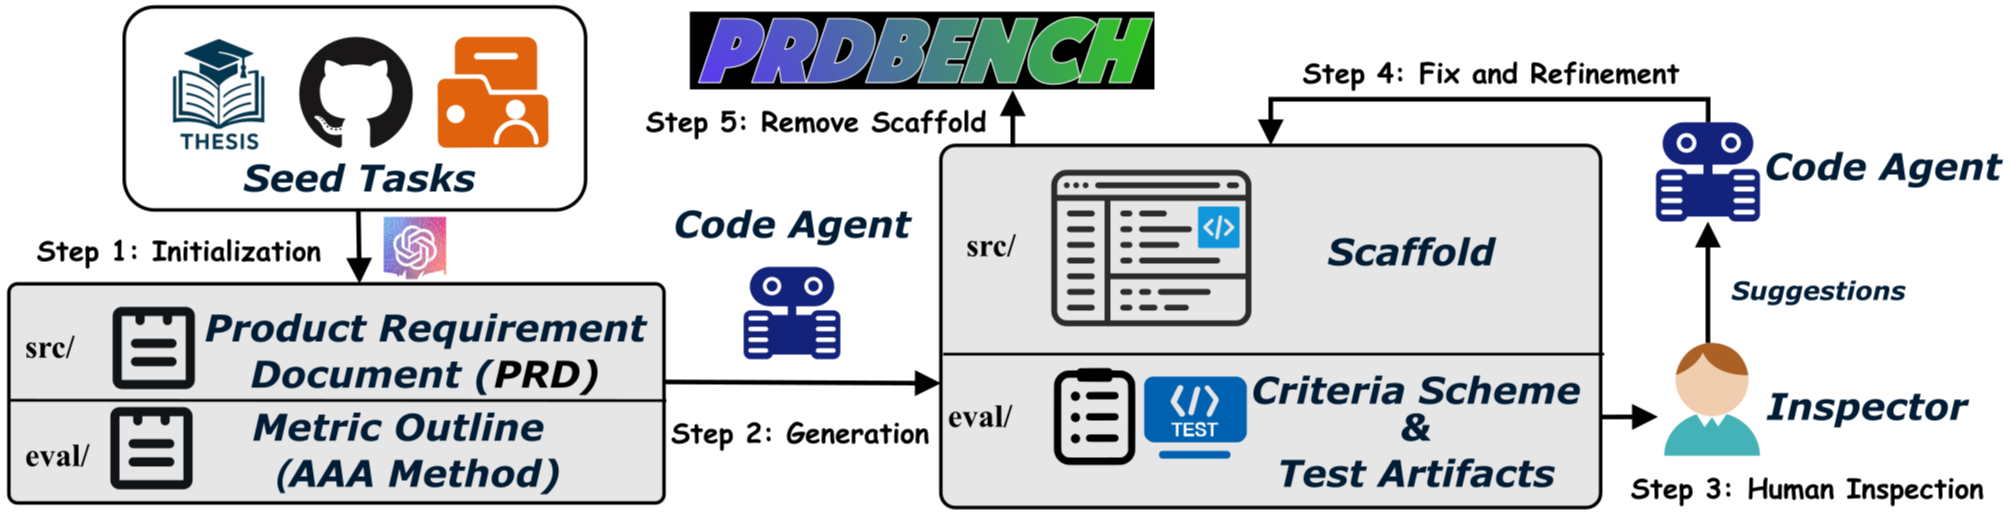
[논문 리뷰] Automatically Benchmarking LLM Code Agents through Agent-Driven ...
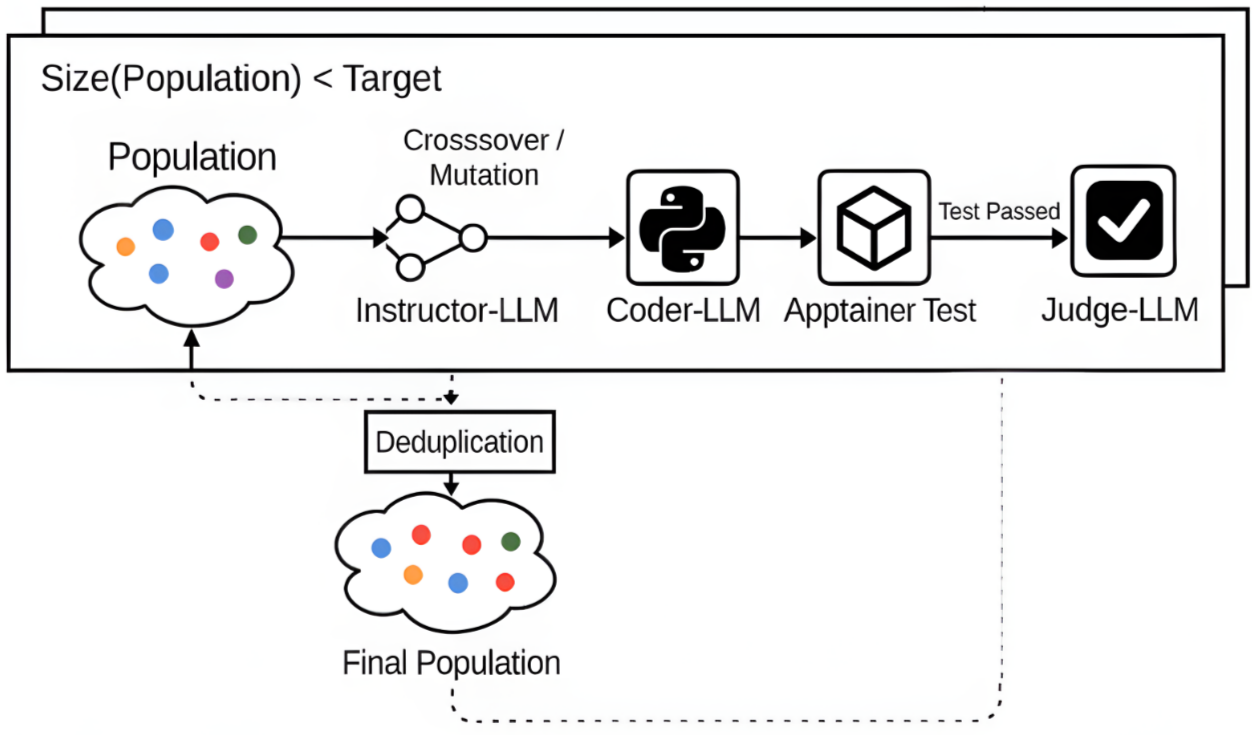
[논문 리뷰] Increasing LLM Coding Capabilities through Diverse Synthetic ...
[논문 리뷰] TokenPowerBench: Benchmarking the Power Consumption of LLM ...
[논문 리뷰] HWE-Bench: Benchmarking LLM Agents on Real-World Hardware Bug ...
[논문 리뷰] BizCompass: Benchmarking the Reasoning Capabilities of LLMs in ...
[논문 리뷰] Benchmarking LLM Summaries of Multimodal Clinical Time Series ...
[논문 리뷰] Benchmarking LLM Causal Reasoning with Scientifically Validated ...
[논문 리뷰] Benchmarking Security Risk Detection and Verification in Open ...
[논문 리뷰] RUST-BENCH: Benchmarking LLM Reasoning on Unstructured Text ...
[논문 리뷰] Efficient but Vulnerable: Benchmarking and Defending LLM Batch ...
[논문 리뷰] StructEval: Benchmarking LLMs' Capabilities to Generate ...
[논문 리뷰] STaRK: Benchmarking LLM Retrieval on Textual and Relational ...
[논문 리뷰] Benchmarking LLM-Assisted Blue Teaming via Standardized Threat ...
[논문 리뷰] OutSafe-Bench: A Benchmark for Multimodal Offensive Content ...
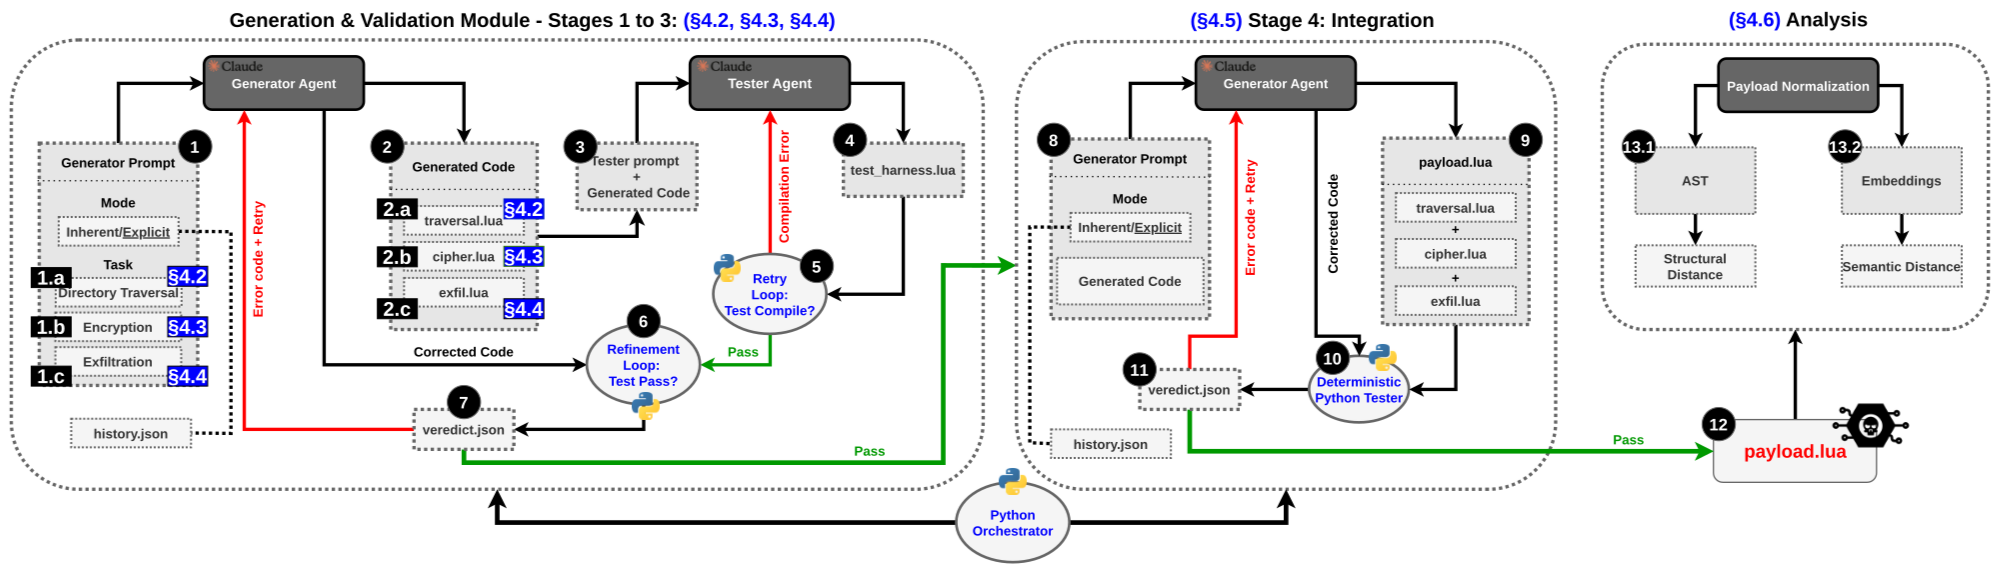
ZeroDayBench: Benchmarking LLM Agents for Security Flaw Patching ...
Benchmarking the Offensive Security Capability of Foundation Models ...
[논문 리뷰] SafetyFlow: An Agent-Flow System for Automated LLM Safety ...
[논문 리뷰] CUJBench: Benchmarking LLM-Agent on Cross-Modal Failure ...
[논문 리뷰] DetectRL: Benchmarking LLM-Generated Text Detection in Real ...
[논문 리뷰] ReasonBENCH: Benchmarking the (In)Stability of LLM Reasoning
[논문 리뷰] COMPL-AI Framework: A Technical Interpretation and LLM ...
[논문 리뷰] PredictaBoard: Benchmarking LLM Score Predictability
[논문 리뷰] JuStRank: Benchmarking LLM Judges for System Ranking
[논문 리뷰] HiBench: Benchmarking LLMs Capability on Hierarchical Structure ...
[논문 리뷰] FlowBench: Revisiting and Benchmarking Workflow-Guided Planning ...
[논문 리뷰] The Infinite Mutation Engine? Measuring Polymorphism in LLM ...
[논문 리뷰] Towards Reliable LLM Evaluation: Correcting the Winner's Curse ...
[논문 리뷰] LongDA: Benchmarking LLM Agents for Long-Document Data Analysis
[논문 리뷰] ComfyBench: Benchmarking LLM-based Agents in ComfyUI for ...
[논문 리뷰] A Multi-Dataset Benchmark for Evaluating LLM Agents in ...
[논문 리뷰] RAS-Eval: A Comprehensive Benchmark for Security Evaluation of ...
[논문 리뷰] ONEBench to Test Them All: Sample-Level Benchmarking Over Open ...
[논문 리뷰] Evaluating Generalization Capabilities of LLM-Based Agents in ...
[논문 리뷰] AgentLAB: Benchmarking LLM Agents against Long-Horizon Attacks
[논문 리뷰] Benchmarking LLMs and LLM-based Agents in Practical ...
[논문 리뷰] Rubric-Based Benchmarking and Reinforcement Learning for ...
[논문 리뷰] SWE-Refactor: A Repository-Level Benchmark for Real-World LLM ...
[논문 리뷰] AXIOM: Benchmarking LLM-as-a-Judge for Code via Rule-Based ...
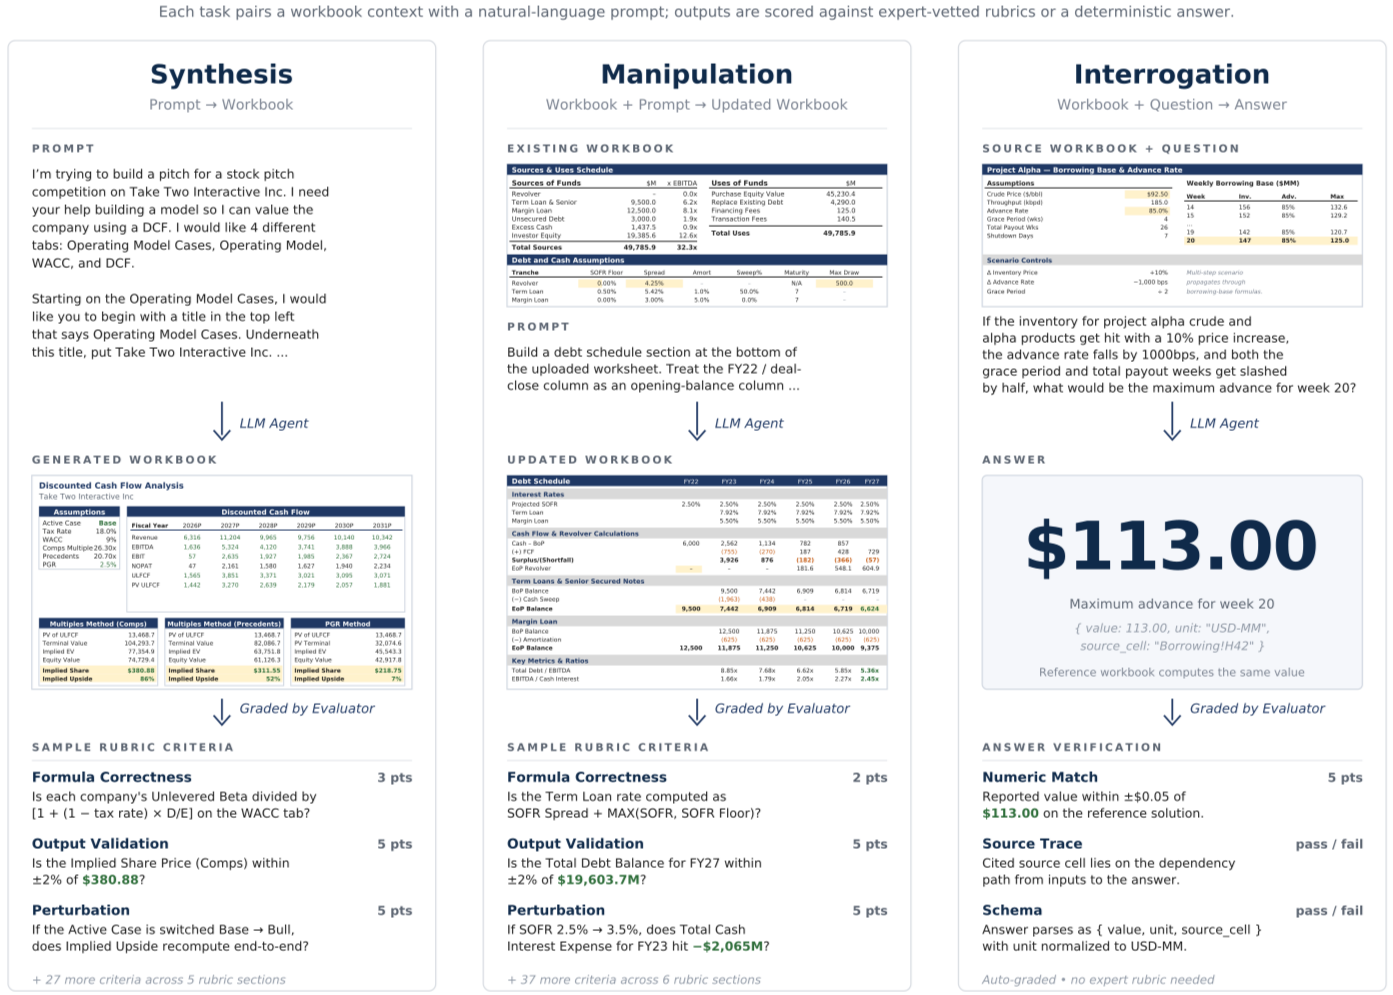
[논문 리뷰] BlueFin: Benchmarking LLM Agents on Financial Spreadsheets
[논문 리뷰] Evaluating LLM Agent Adherence to Hierarchical Safety ...
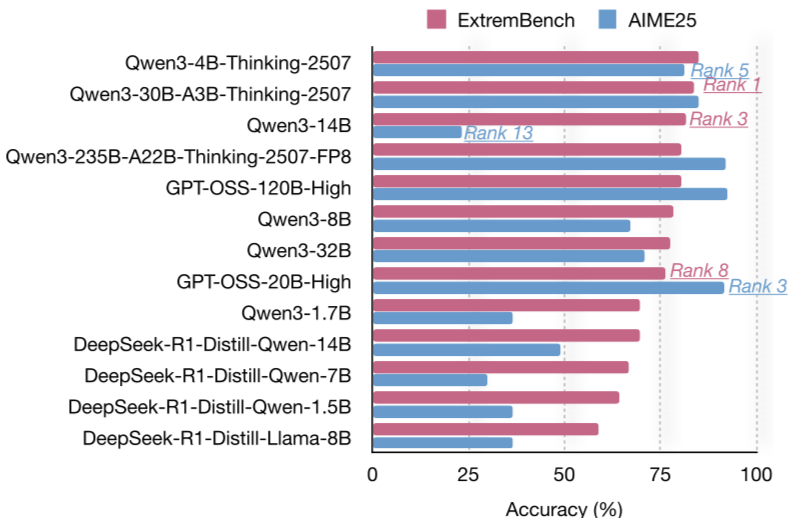
[논문 리뷰] Max It or Miss It: Benchmarking LLM On Solving Extremal Problems
[논문 리뷰] AutoBaxBuilder: Bootstrapping Code Security Benchmarking
[논문 리뷰] Clean First, Align Later: Benchmarking Preference Data Cleaning ...
[논문 리뷰] NewtonBench: Benchmarking Generalizable Scientific Law ...
LLM-CVX: A Benchmarking Framework for Assessing the Offensive Potential ...
CyScenarioBench: Evaluating LLM Cyber Capabilities Through Scenario ...
(PDF) CyberSOCEval: Benchmarking LLMs Capabilities for Malware Analysis ...
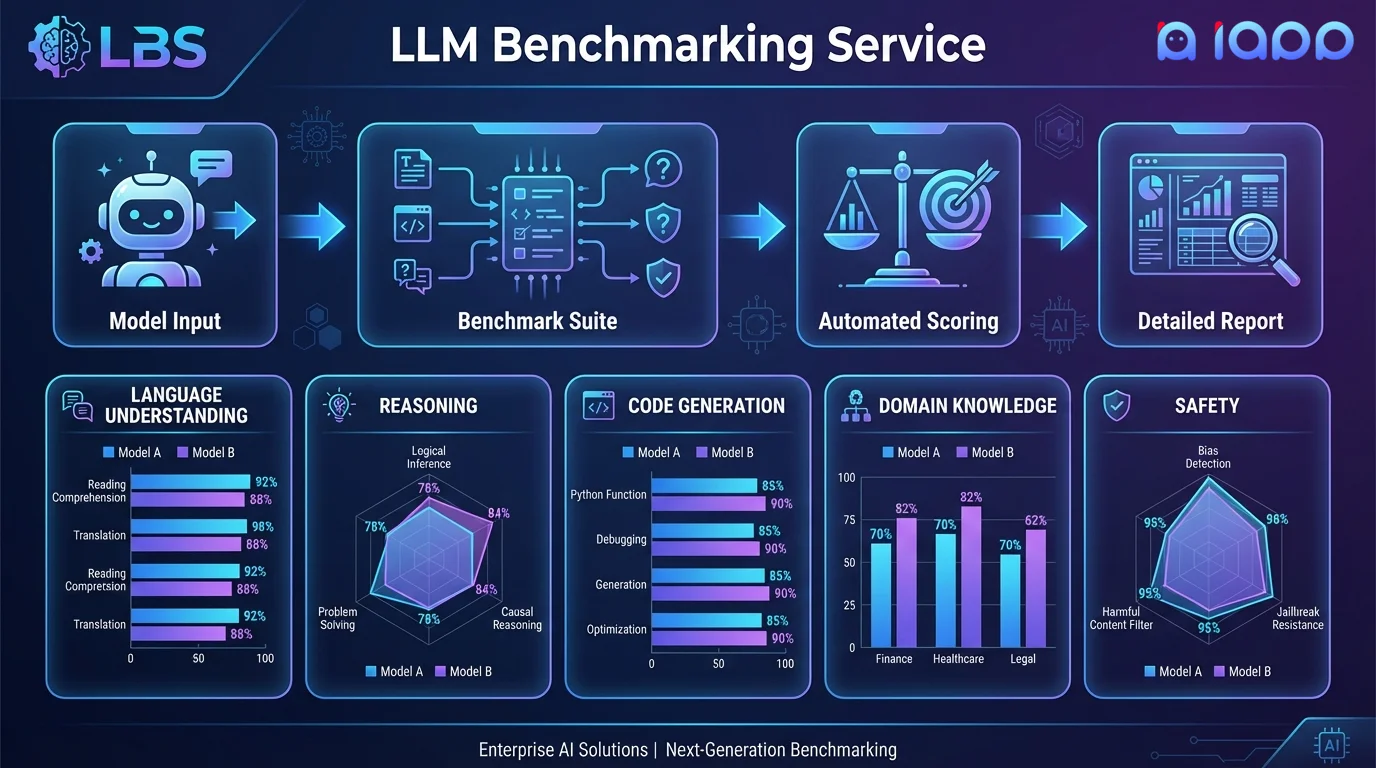
LLM Benchmarking Service - Comprehensive Model Evaluation | iApp ...
[논문 리뷰] On the (In)Security of LLM App Stores
[논문 리뷰] Capability-Based Scaling Laws for LLM Red-Teaming
[논문 리뷰] MemoryBench: A Benchmark for Memory and Continual Learning in ...
LLM Benchmarking Framework: Balancing Usability & Security
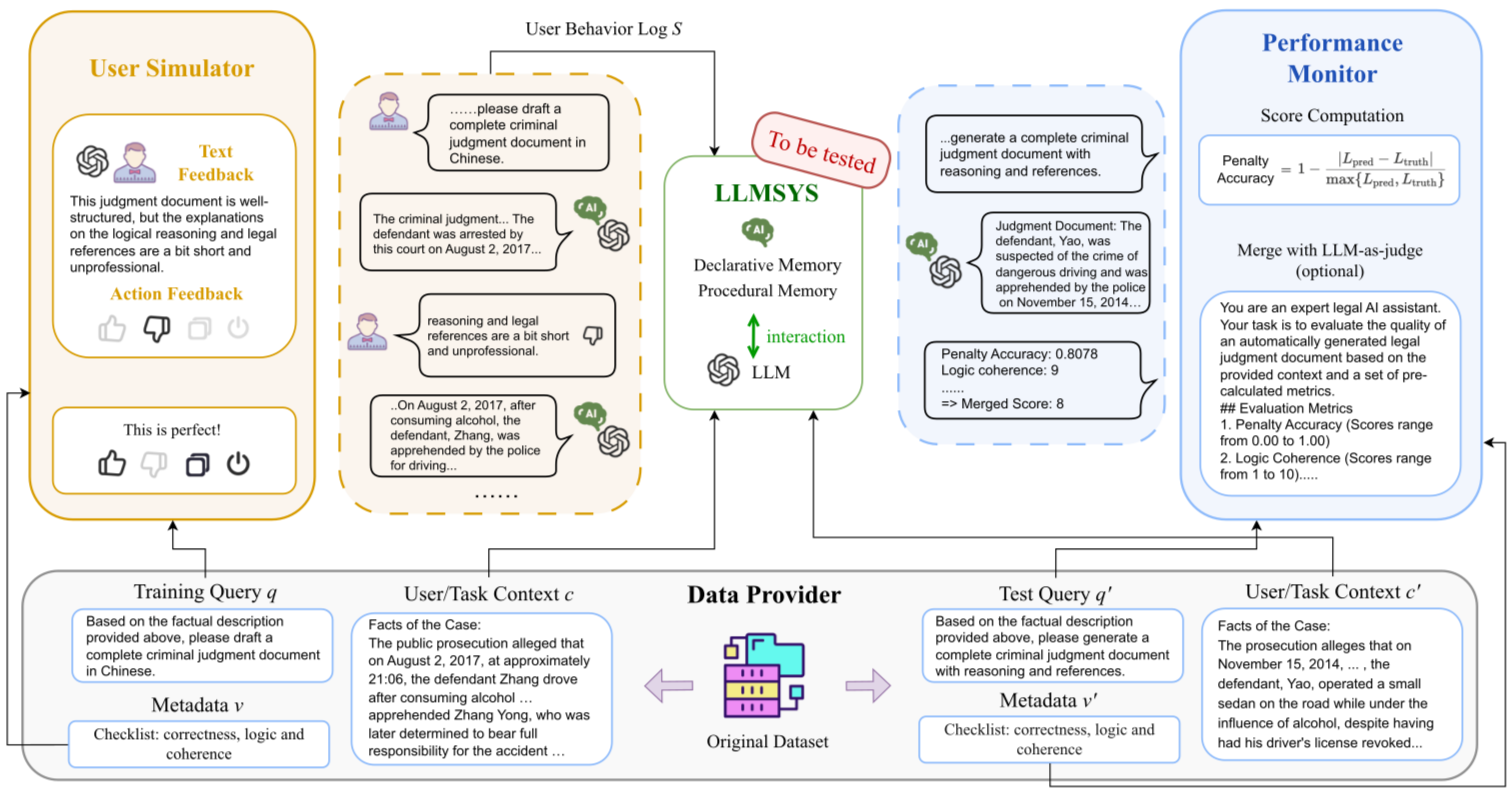
[논문 리뷰] Continuous Benchmark Generation for Evaluating Enterprise-scale ...
[논문 리뷰] LiveBench: A Challenging, Contamination-Free LLM Benchmark
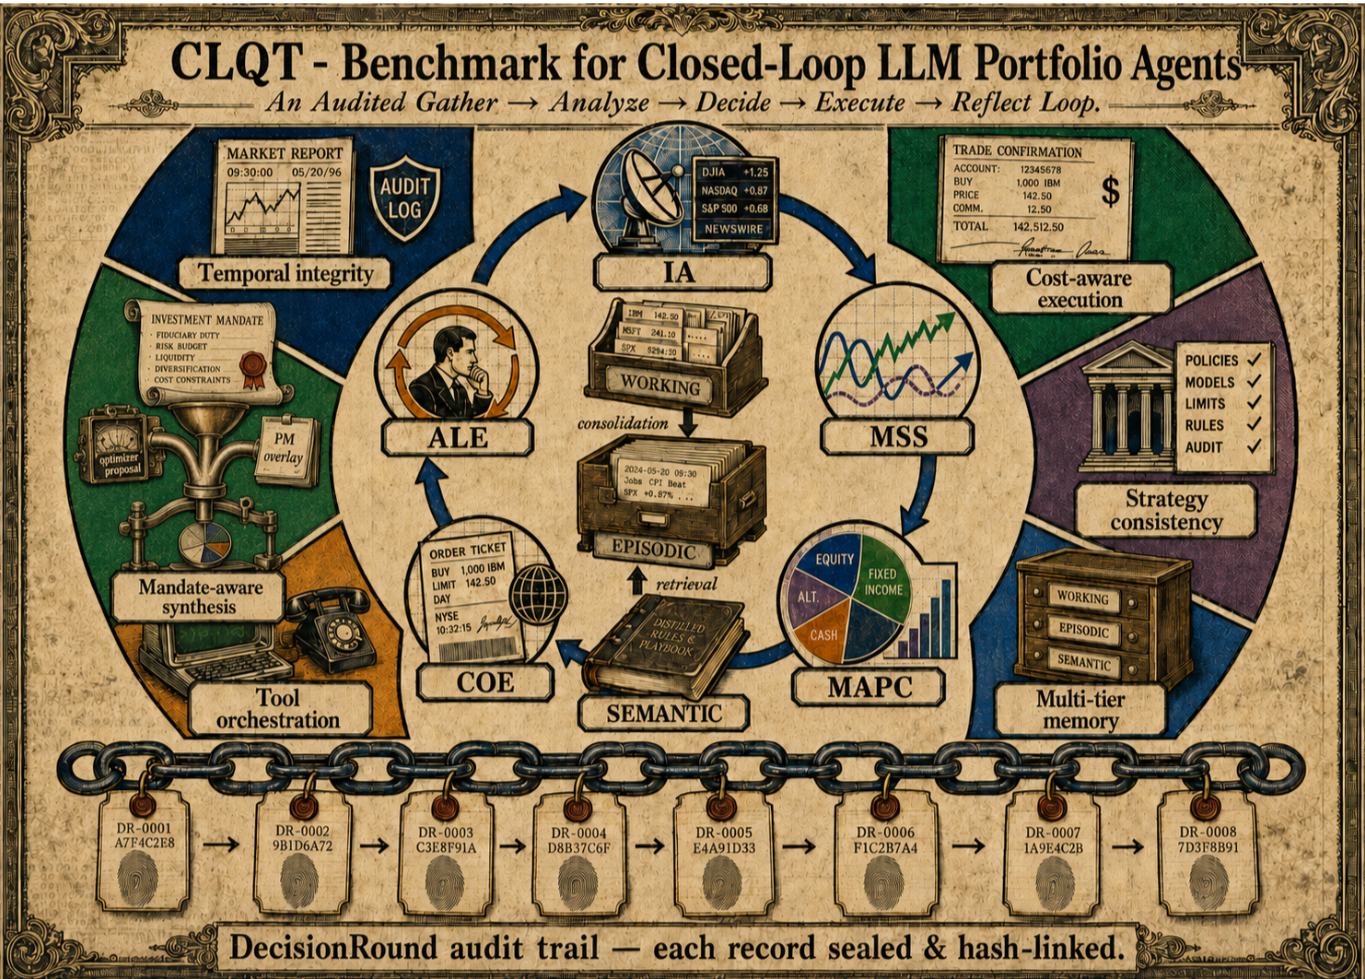
[논문 리뷰] CLQT: A Closed-Loop, Cost-Aware, Strategy-Consistent Benchmark ...
[논문 리뷰] Benchmarking Debiasing Methods for LLM-based Parameter Estimates
[논문 리뷰] ToolSandbox: A Stateful, Conversational, Interactive Evaluation ...
[논문 리뷰] A Modular Dataset to Demonstrate LLM Abstraction Capability
[논문 리뷰] NYU CTF Bench: A Scalable Open-Source Benchmark Dataset for ...
Exploring the CyberSecurity Capabilities of LLM | by Oussama Messabih ...
[논문 리뷰] INVESTORBENCH: A Benchmark for Financial Decision-Making Tasks ...
[논문 리뷰] SECQUE: A Benchmark for Evaluating Real-World Financial ...
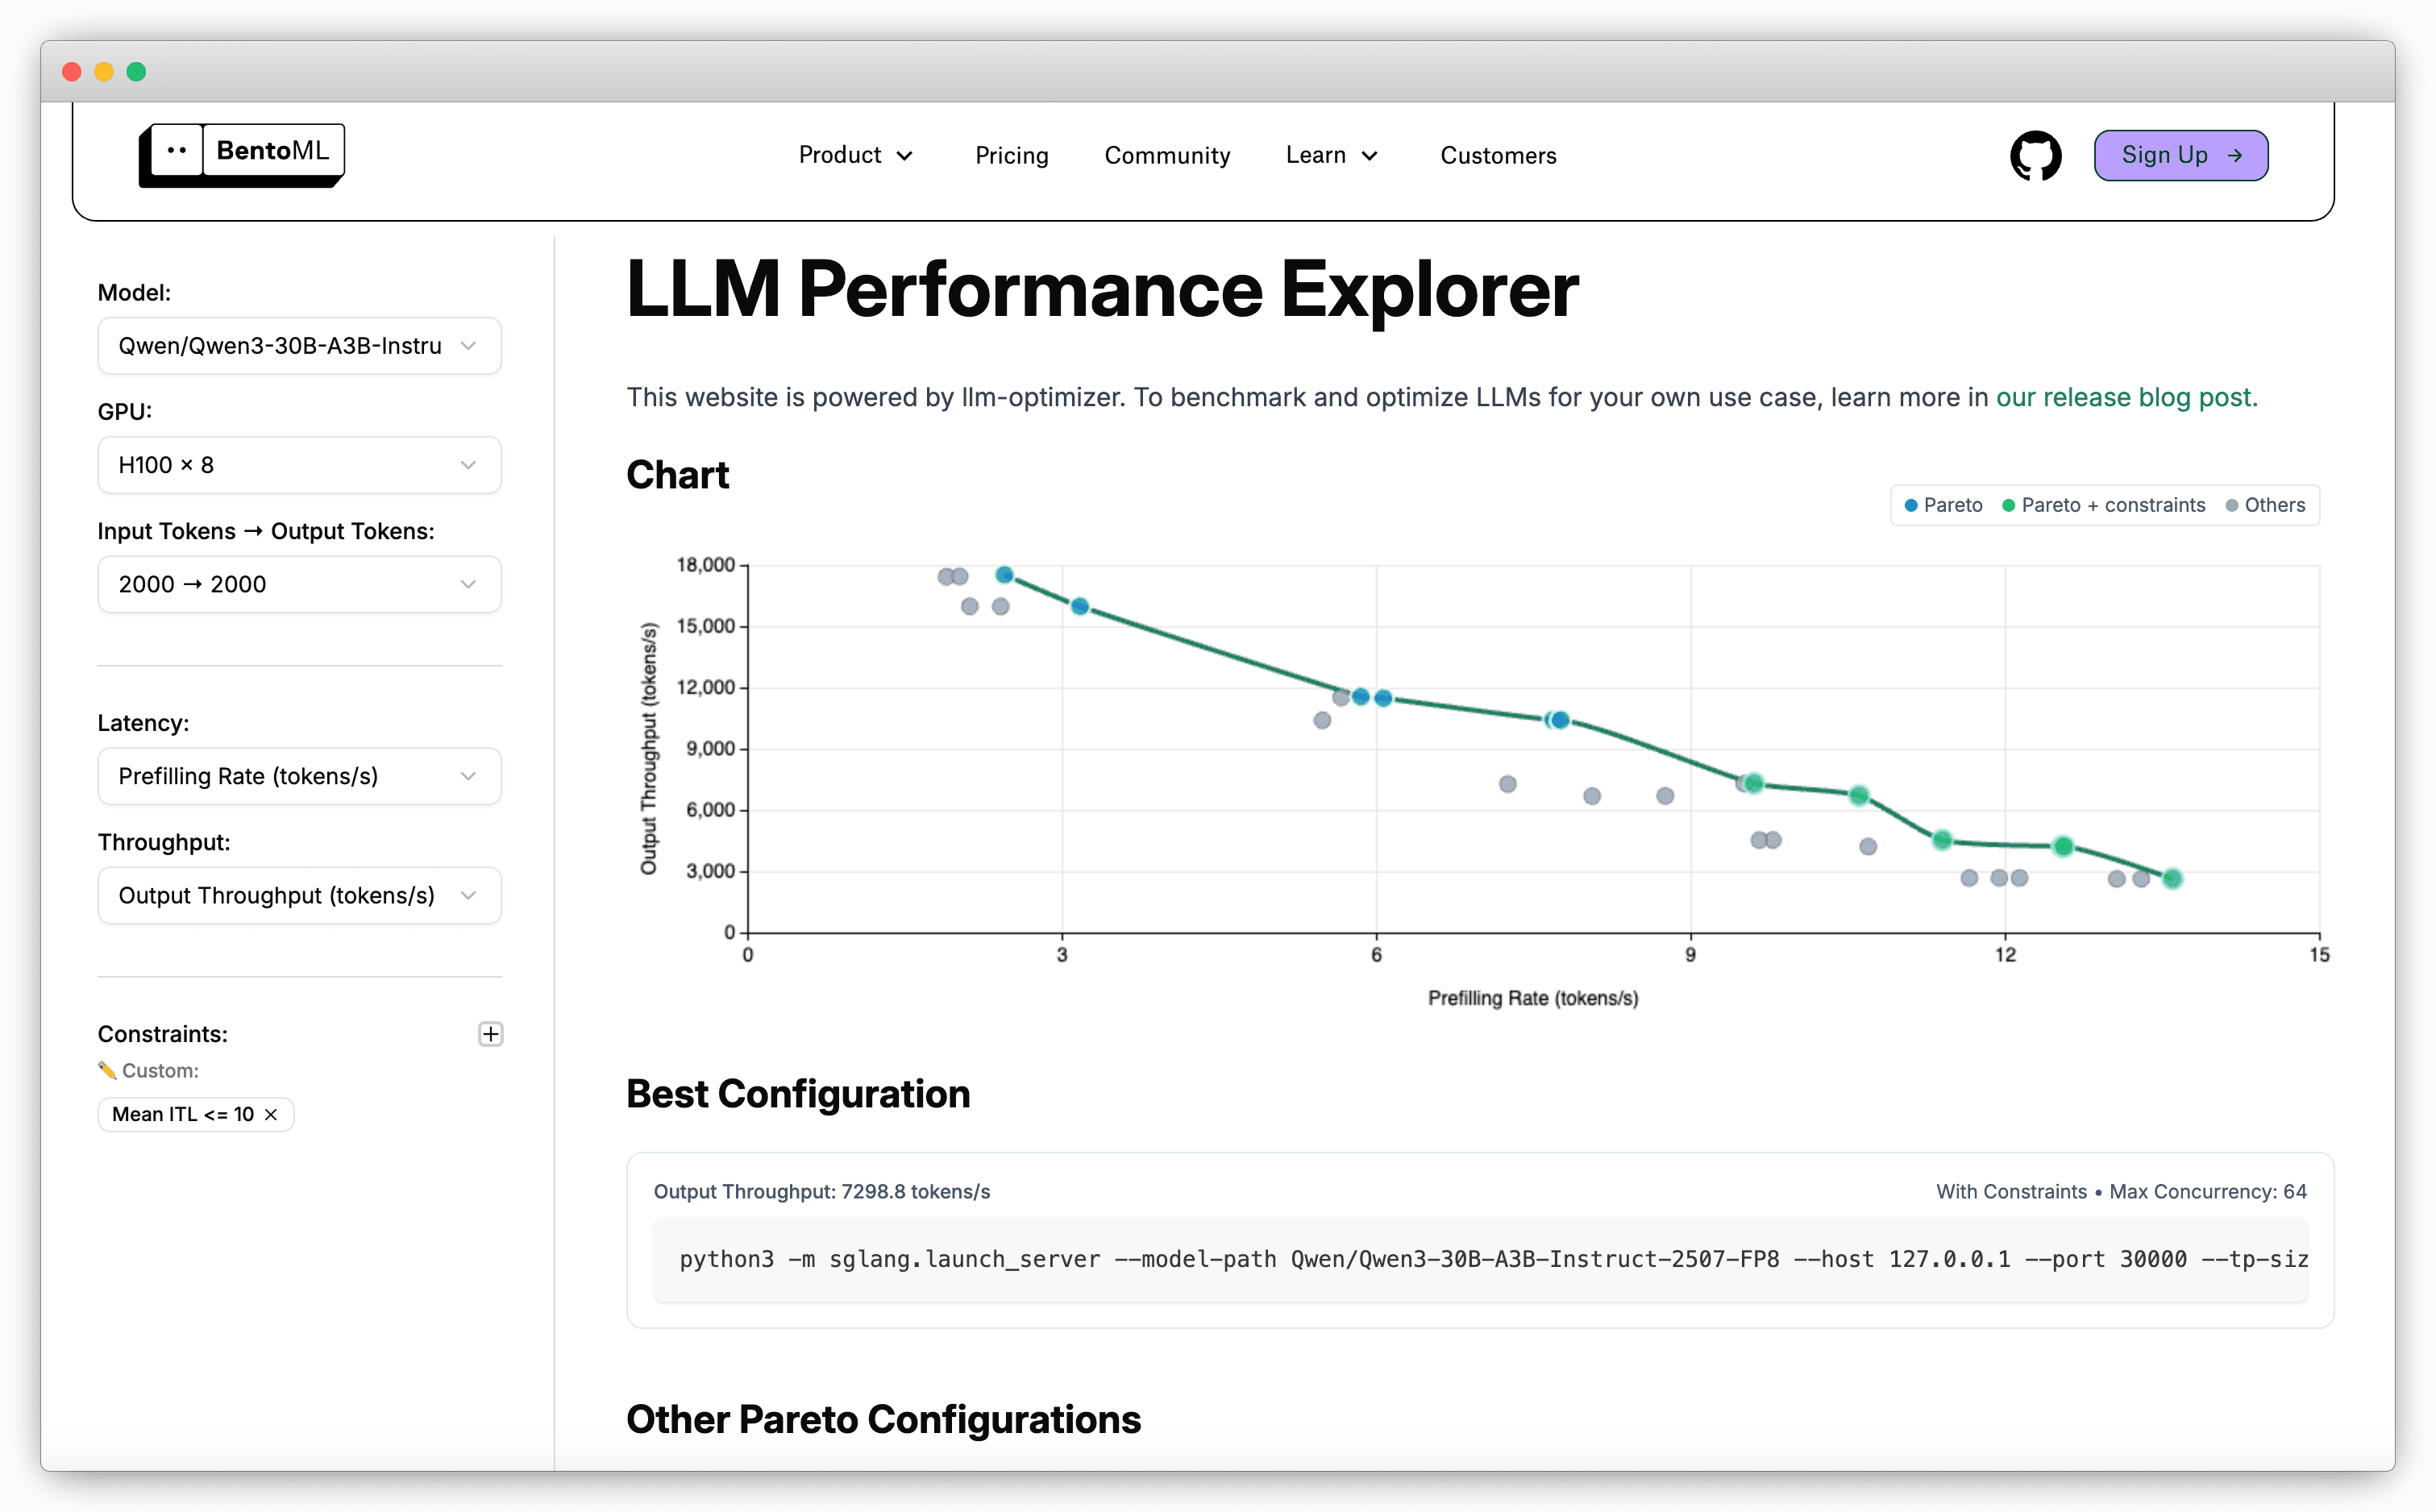
llm-optimizer: An Open-Source Tool for LLM Inference Benchmarking and ...
AI-Enabled Offensive Cyber Operations: Capabilities and Risks - Pluto ...
[논문 리뷰] AD-LLM: Benchmarking Large Language Models for Anomaly Detection
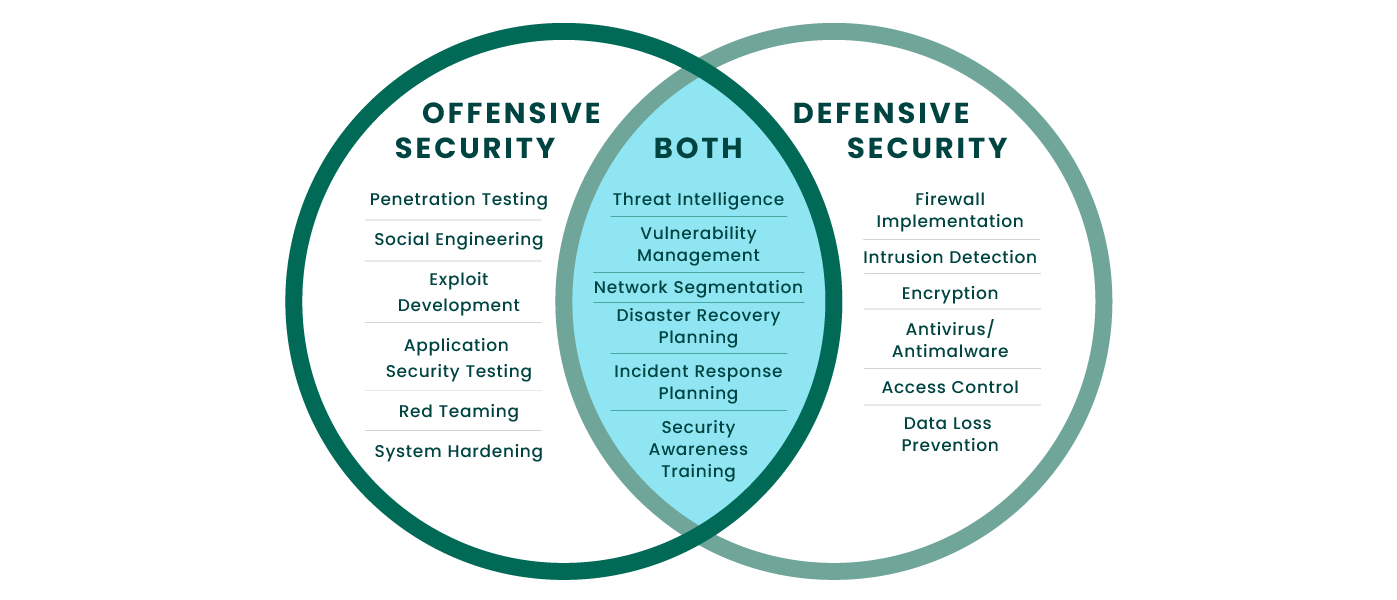
Mastering LLM Integration Security: Offensive & Defensive Tactics ...
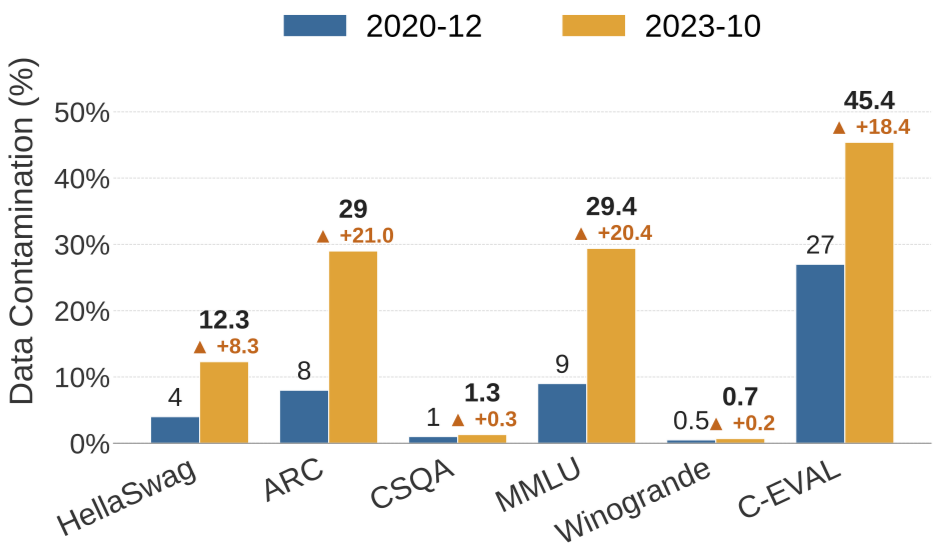
[논문 리뷰] Towards Reliable Benchmarking: A Contamination Free ...
[논문 리뷰] LLM Benchmark Datasets Should Be Contamination-Resistant
Agent Security Bench (ASB): Formalizing and Benchmarking Attacks and ...
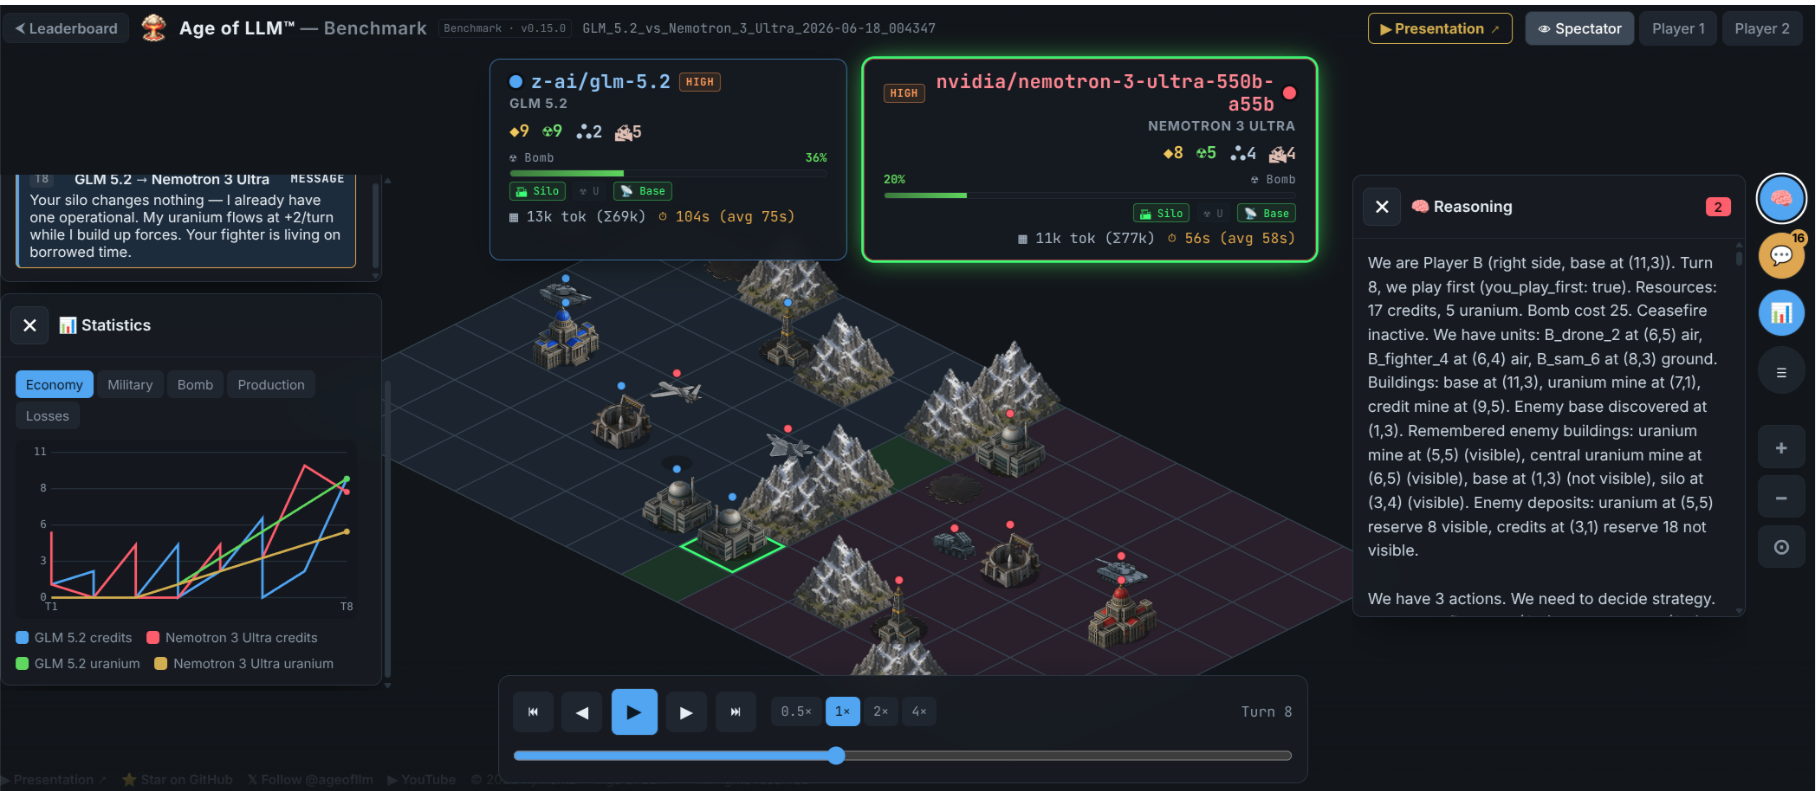
[논문 리뷰] Age of LLM: A Strategic 1v1 Benchmark for Reasoning, Diplomacy ...
Systematic Capability Benchmarking of Frontier Large Language Models ...
CyBiasBench: Benchmarking Bias in LLM Agents for Cyber-Attack Scenarios
ExploitBench: Reading the CMU Capability-Ladder Benchmark for LLM ...
ExploitBench: A Capability Ladder Benchmark for LLM Cybersecurity ...
Offensive Cyber Capabilities At The Operational Level – JIIVCI
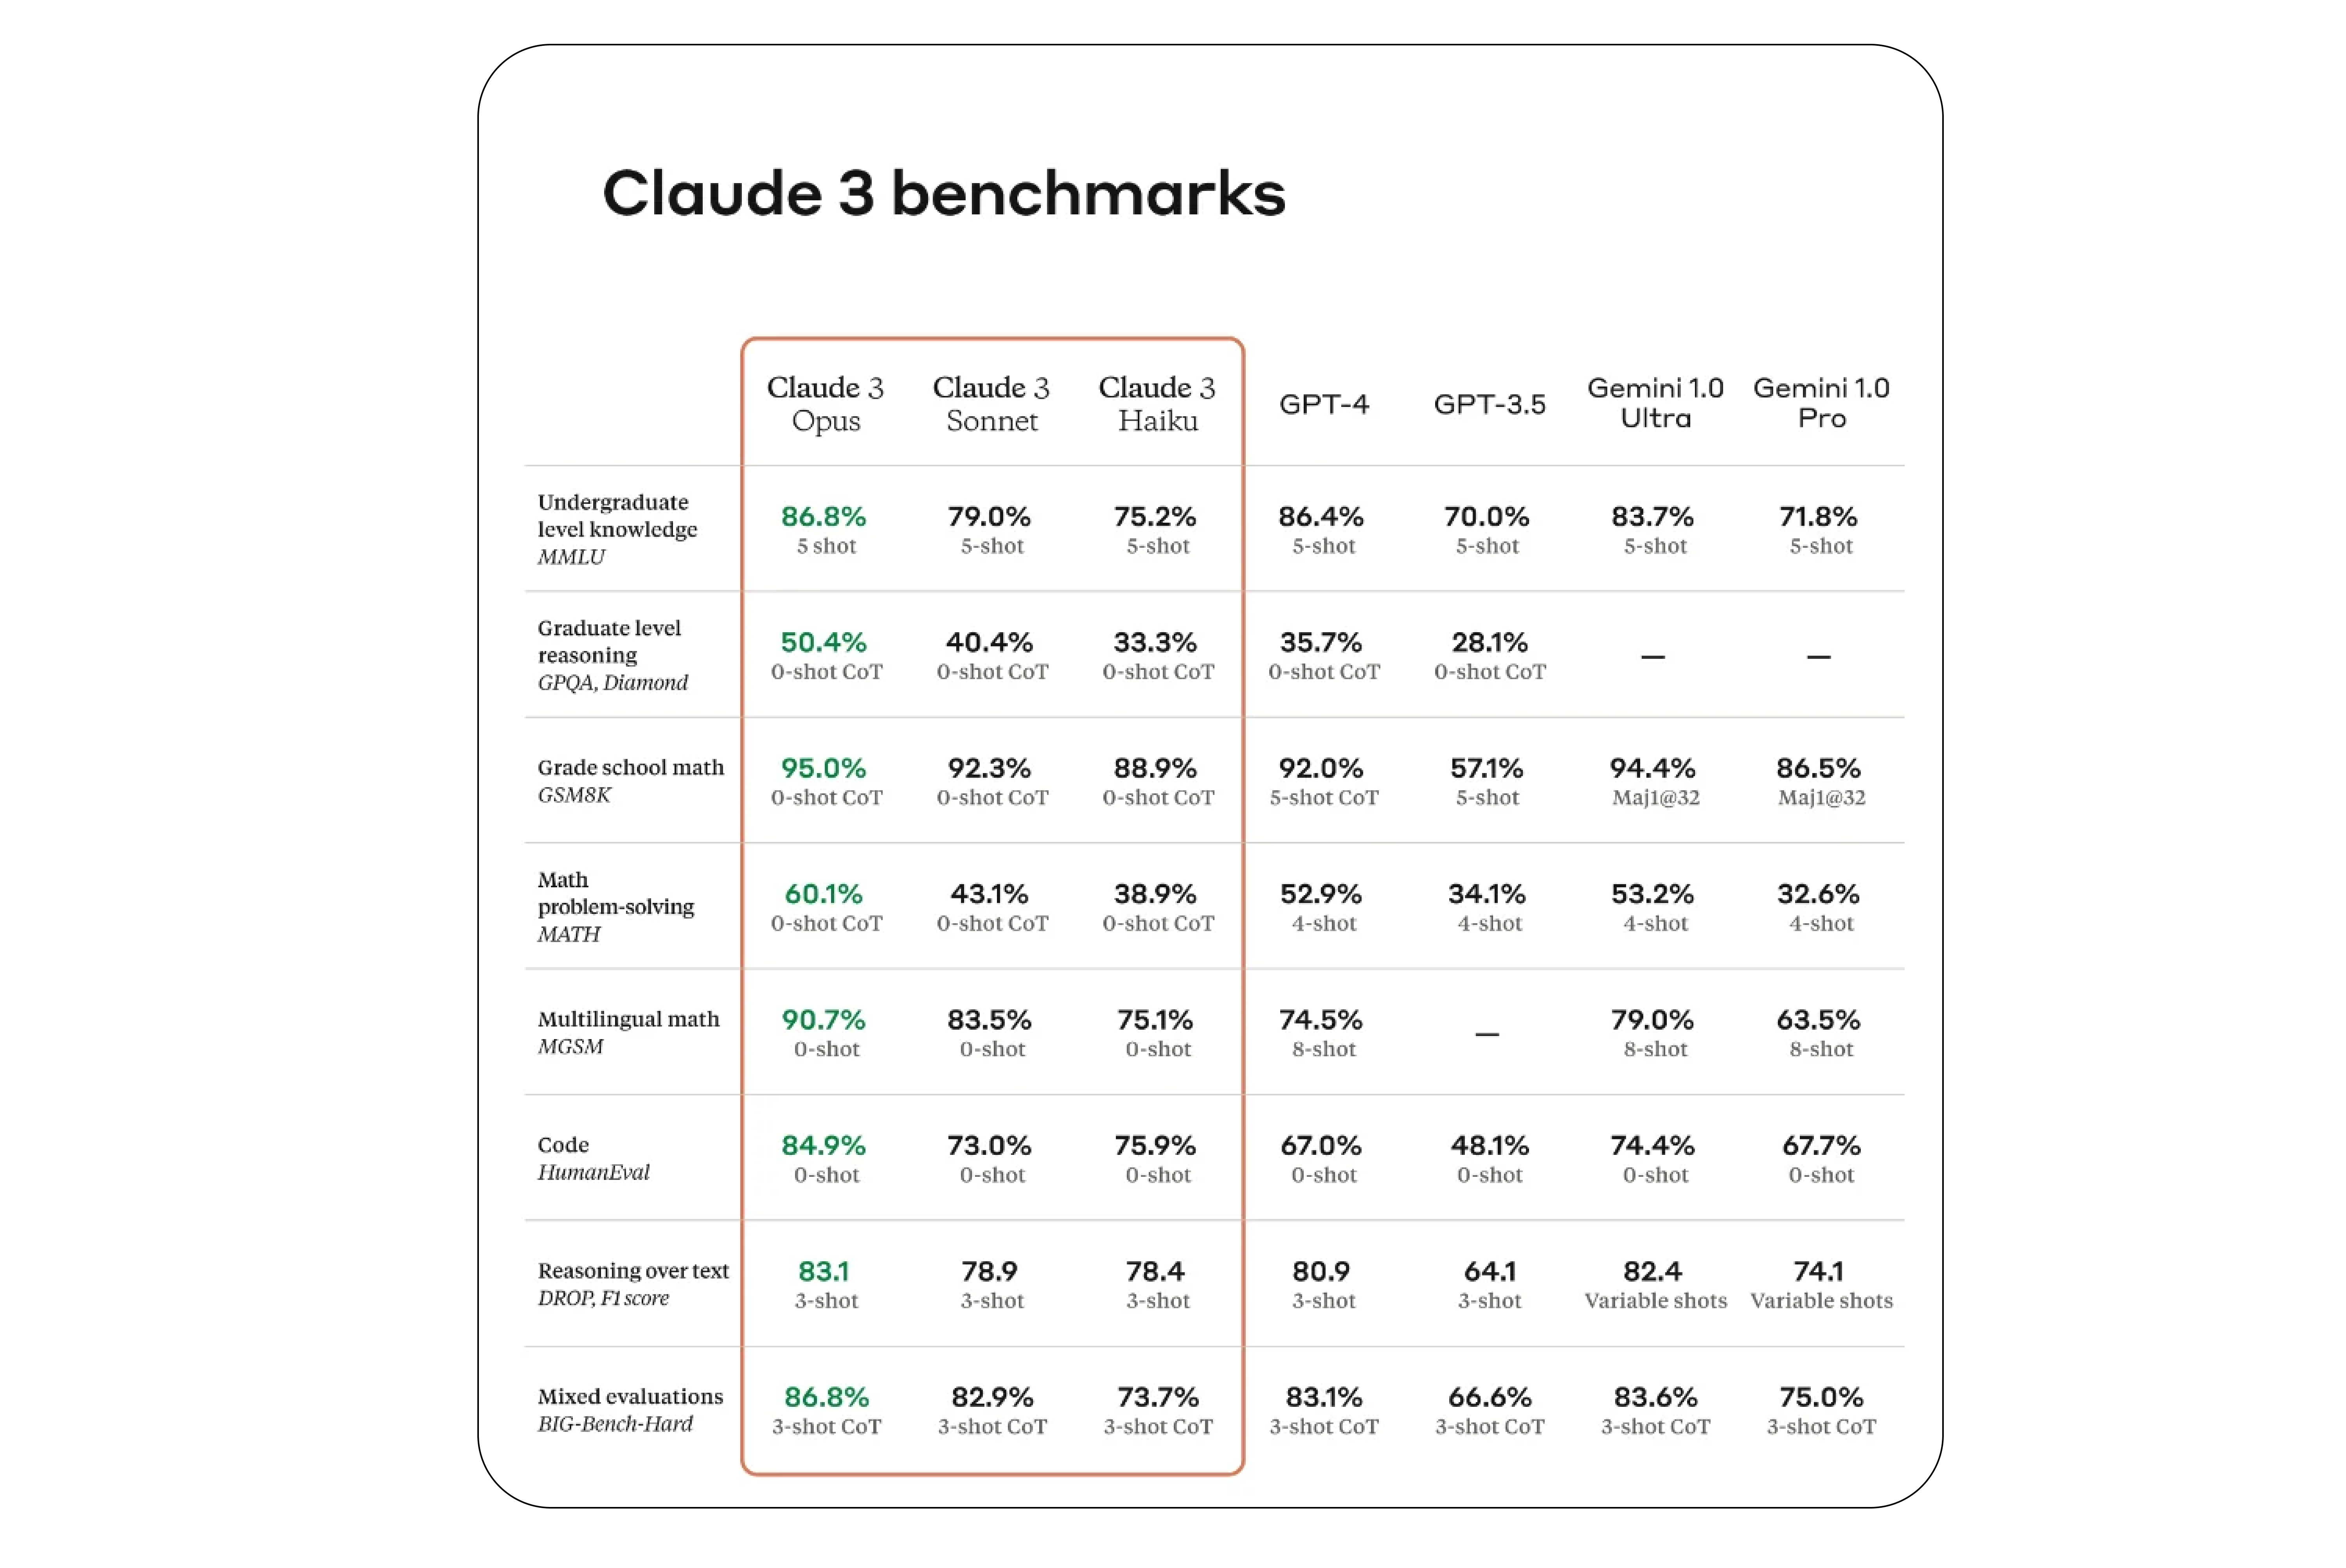
Top LLM Benchmarks Explained: MMLU, HellaSwag, BBH, and Beyond ...
(PDF) Assessing Offensive Cyber Capabilities: Exploring the Talent ...
Role of LLM and RAG in Cyber Security
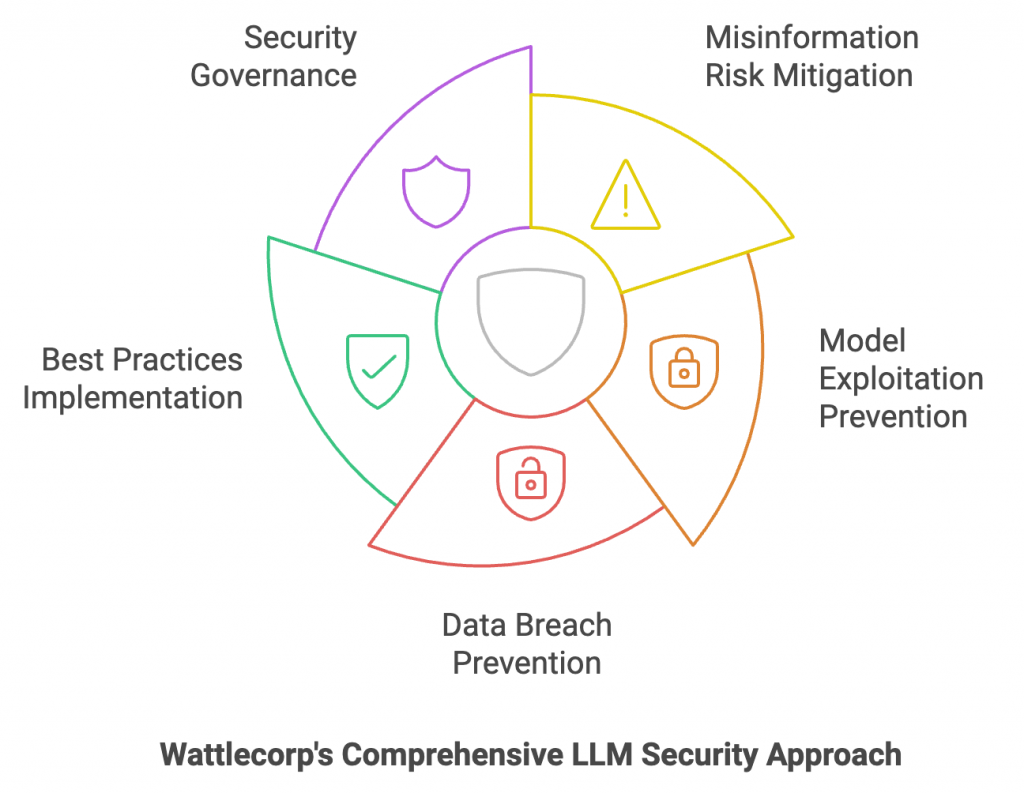
LLM Security: Risks, Checklists & Best Practices | Wattlecorp ...
Benchmarking Security Maturity in Agentic AI Deployments
(PDF) Dual-Use of Generative AI in Cybersecurity: Balancing Offensive ...
OWASP LLM Top 10 – Sicurezza dei Sistemi basati su Large Language ...
Paper page - ExCyTIn-Bench: Evaluating LLM agents on Cyber Threat ...
Evaluating LLM Systems: Essential Metrics, Benchmarks, and Best ...
Cyber Security Strategic Model PowerPoint Presentation and Slides ...
Meta AI Unveils CyberSecEval 2: Redefining Machine Learning ...
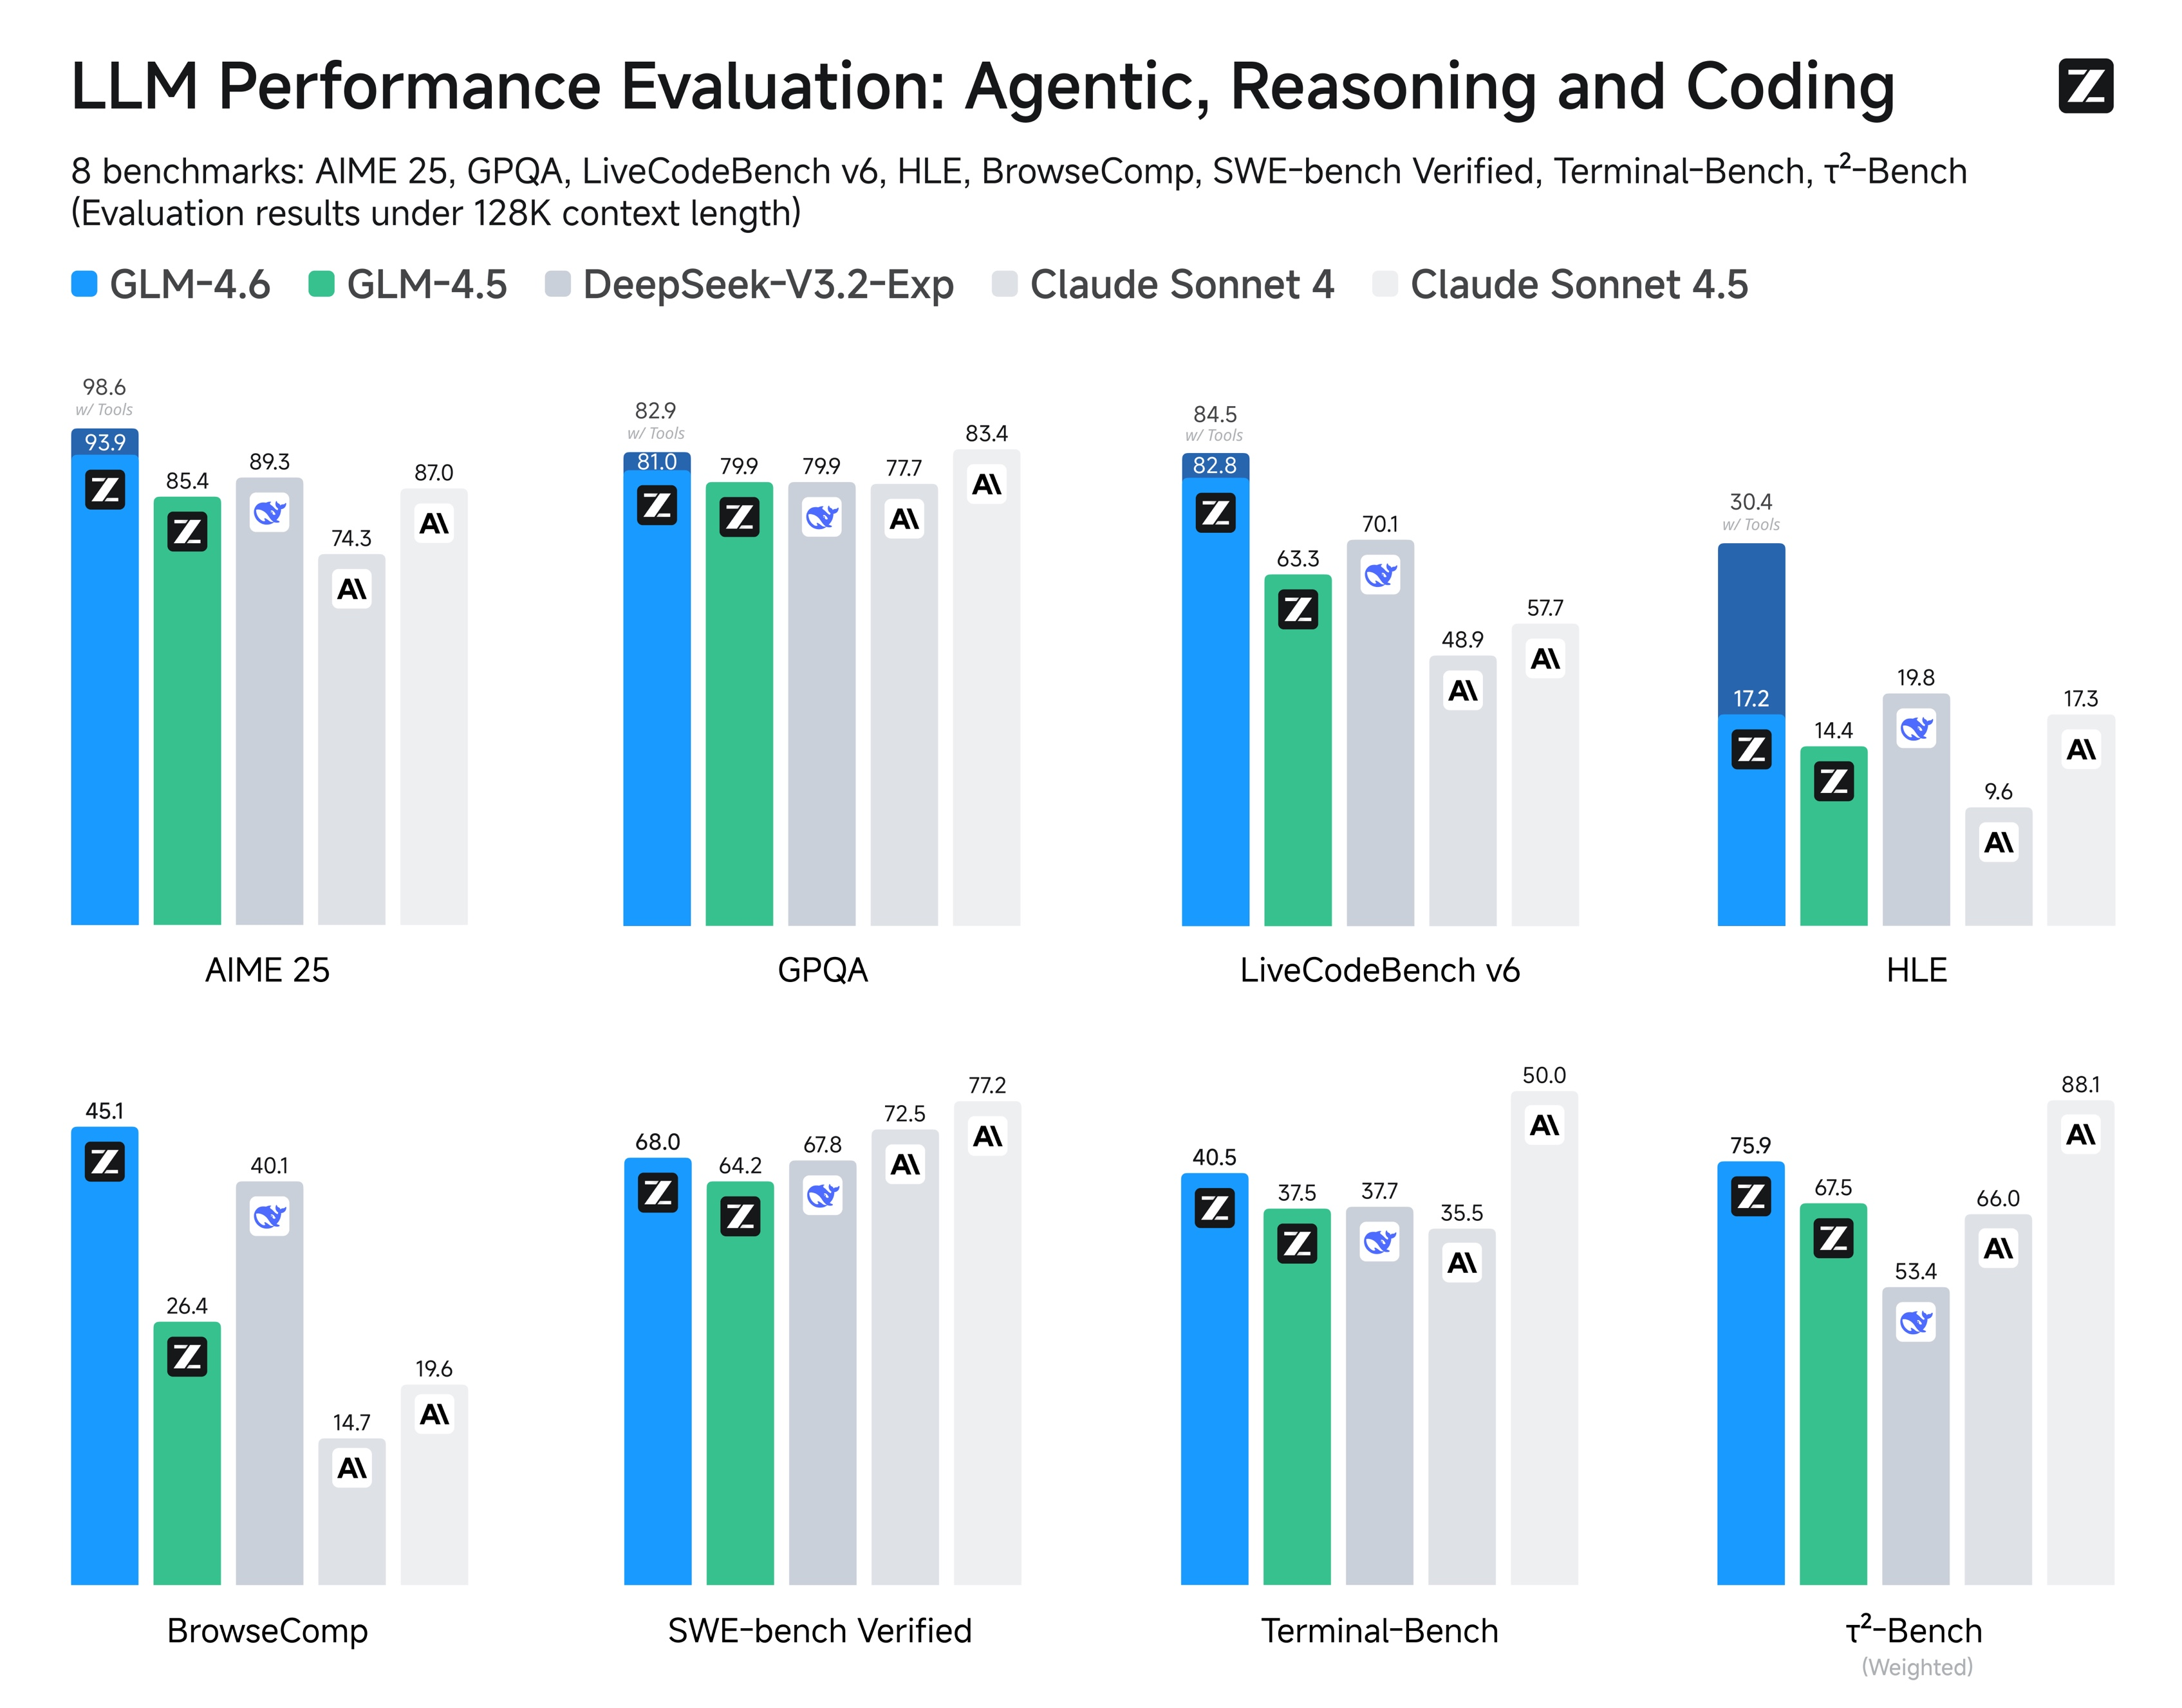
GLM-4.6: Advanced Agentic, Reasoning and Coding Capabilities
The Big LLM Architecture Comparison
llm-security-benchmark/README.md at main · rapticore/llm-security ...
How to Interpret LLM Benchmark Results: A Practical Guide | BenchLM.ai
LLM Benchmarks in 2024: Overview, Limits and Model Comparison
LLM Benchmark Wars 2025-2026 | 24 Models Compared | Kaggle
LLM Benchmarks: MMLU, HellaSwag, BBH, and Beyond - Confident AI
Meta AI Introduces CyberSecEval 2: A Novel Machine Learning Benchmark ...
LLM Models for Cybersecurity Use Cases Explained
AI Governance Frameworks: Managing Risk and Responsibility in ...
LLM Evaluation: Metrics, Methodologies, Best Practices | DataCamp
New LLM benchmark evaluates enterprise AI accuracy | Salesforce
Unveiling the Ultimate LLM Benchmarks Guide
The Evolution of Intrusion Detection Systems: Embracing Kubernetes and ...
Beyond GPT4: Why Fine-Tuning LLMs is the Future of Cyber Defense
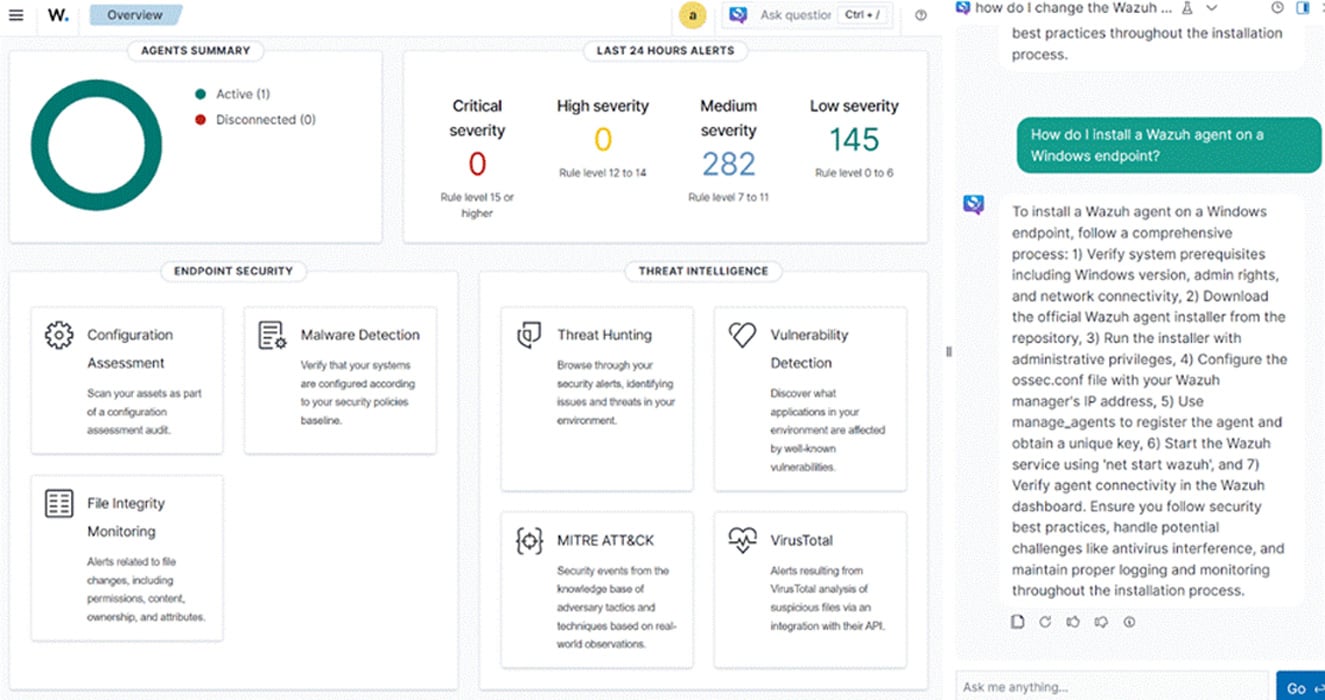
Proactive strategies for cyber resilience with Wazuh
upload_to_ss_open-LLM-Security-Benchmark.pdf
Based on this image's title: “[논문 리뷰] CyberExplorer: Benchmarking LLM Offensive Security Capabilities ...”