GitHub - epfml/llm-optimizer-benchmark: Benchmarking Optimizers for LLM ...
GitHub - LMCache/LMBenchmark: Systematic and comprehensive benchmarks ...
GitHub - chenxuniu/LLM-Inference-Engine-Benchmark: A comprehensive ...
GitHub - MinhNgyuen/llm-benchmark: Benchmark llm performance
GitHub - PRAISELab-PicusLab/ToonBenchmarking-Structural-Environmental ...
GitHub - appleboy/LLM-action: A GitHub Action to interact with OpenAI ...
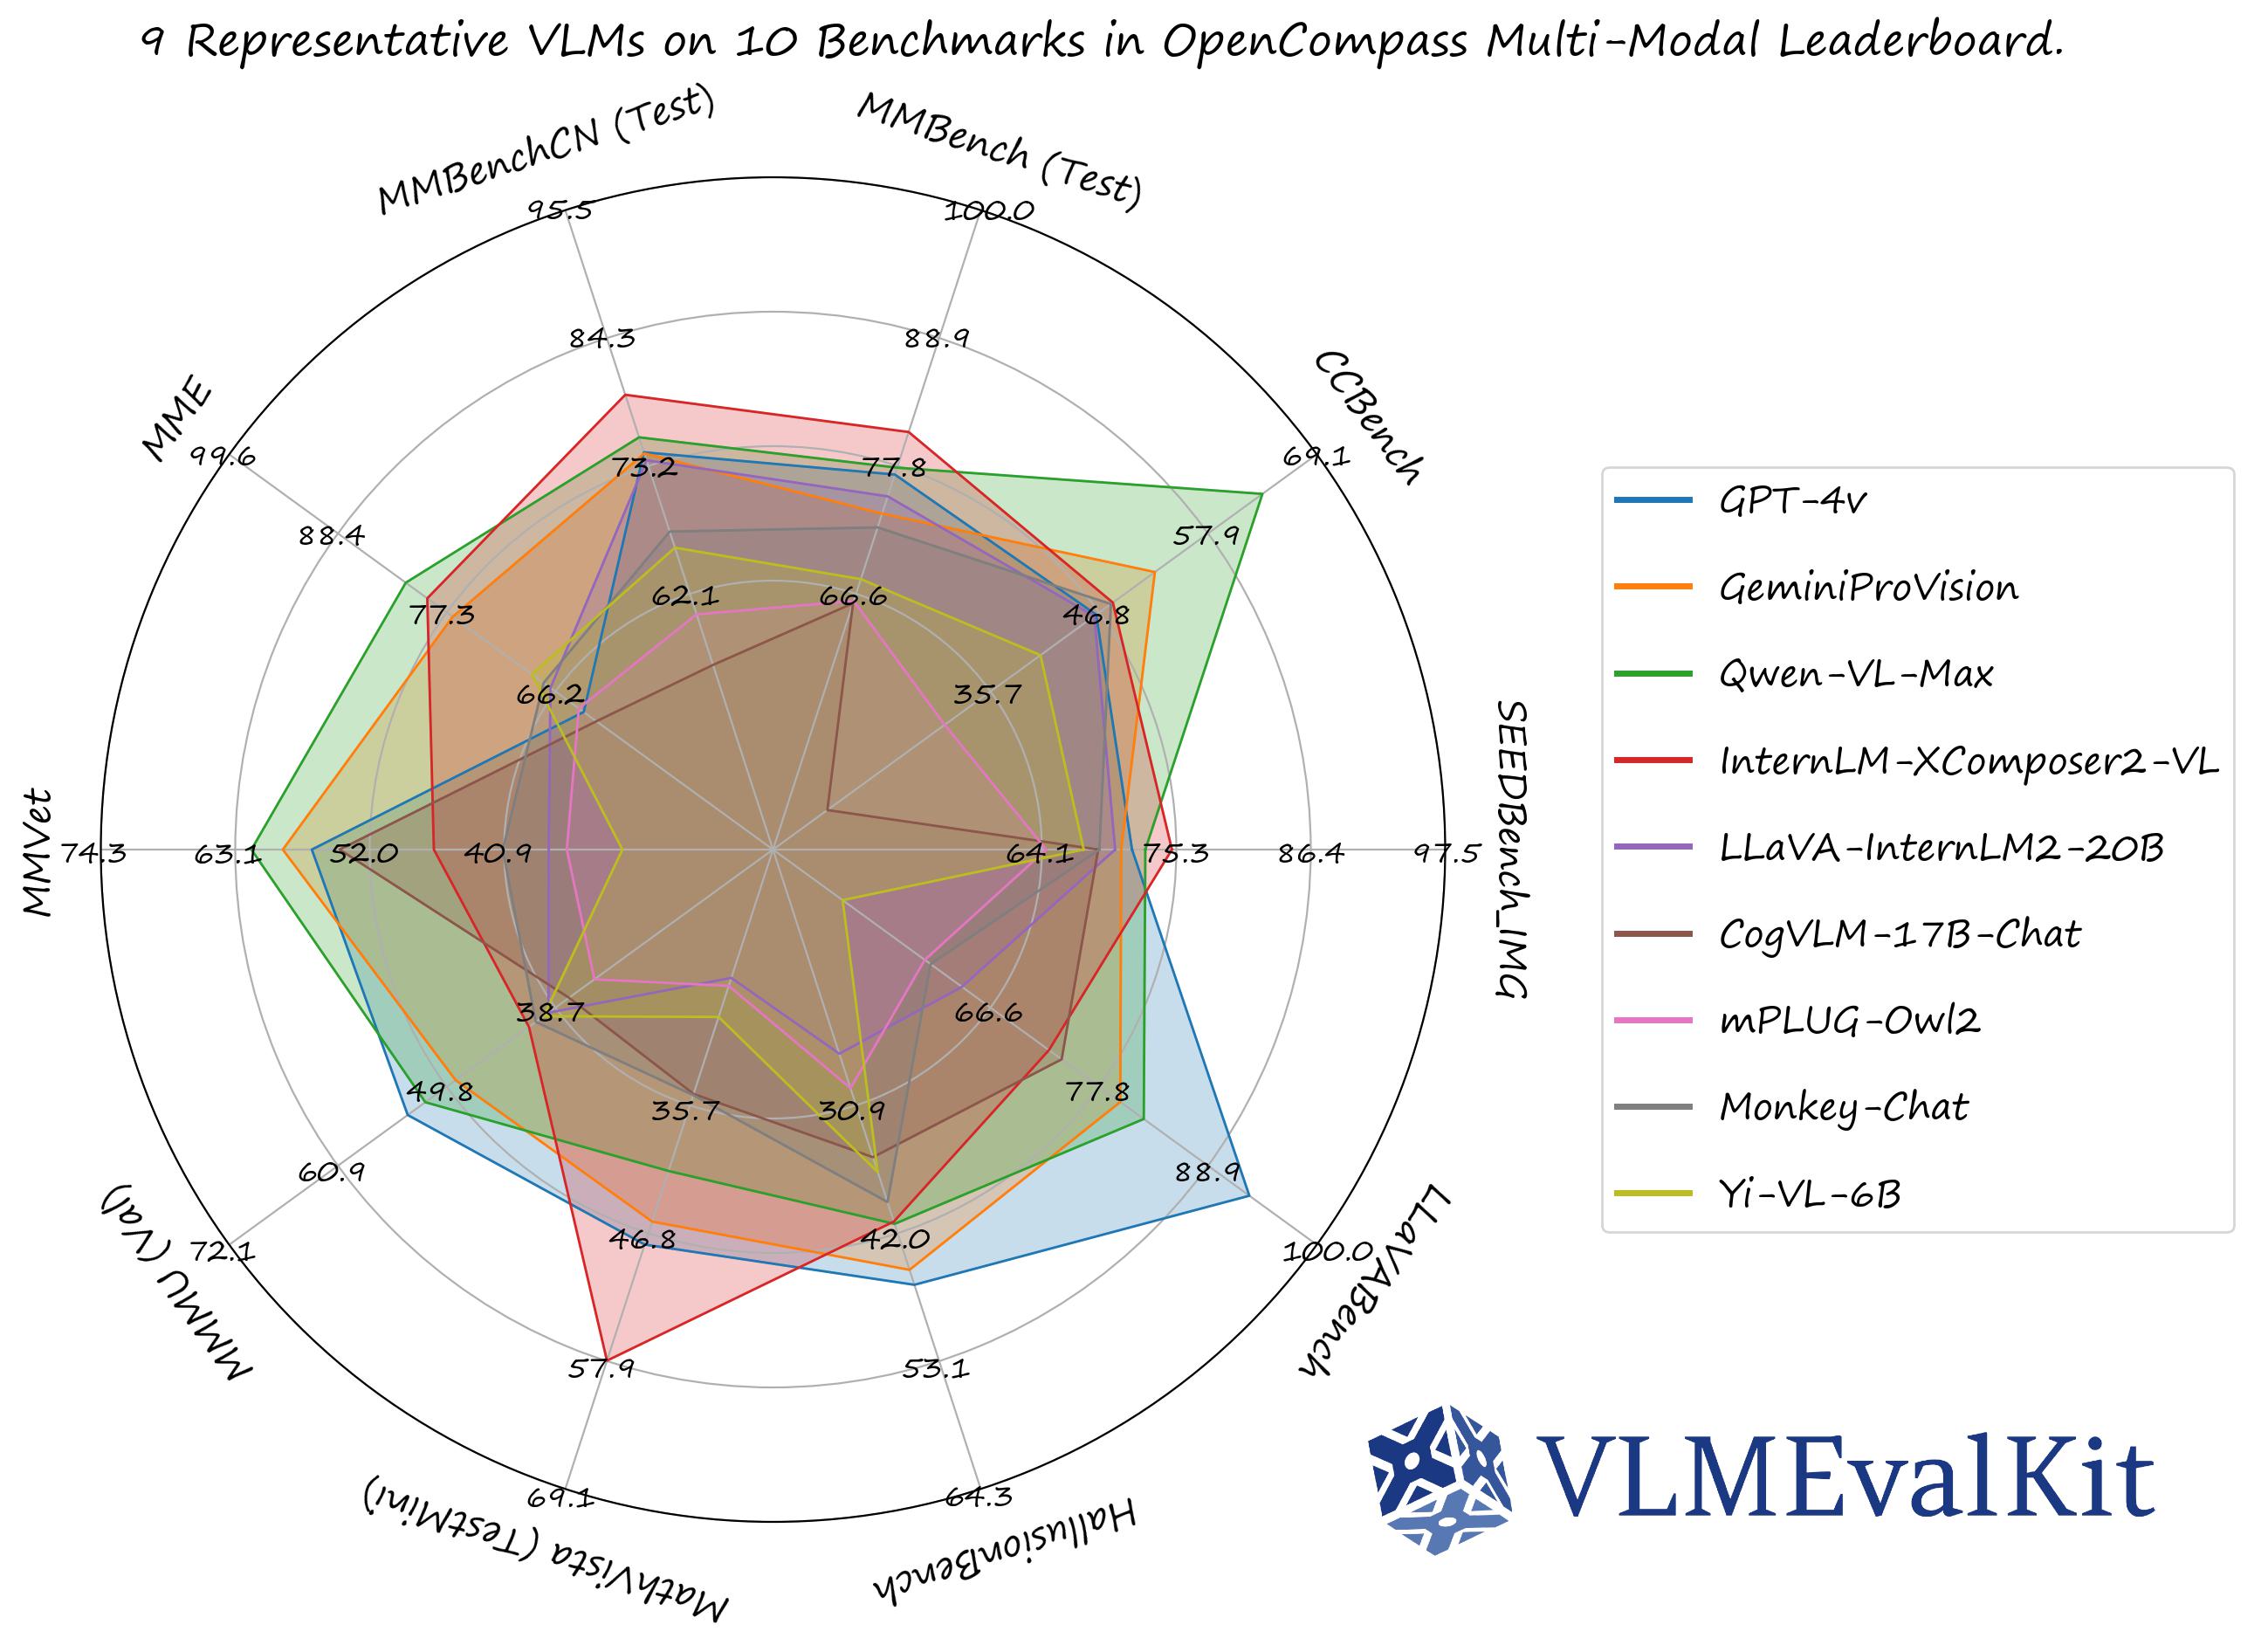
GitHub - OpenGVLab/VLMEvalKit_InternVL2_5: Open-source evaluation ...
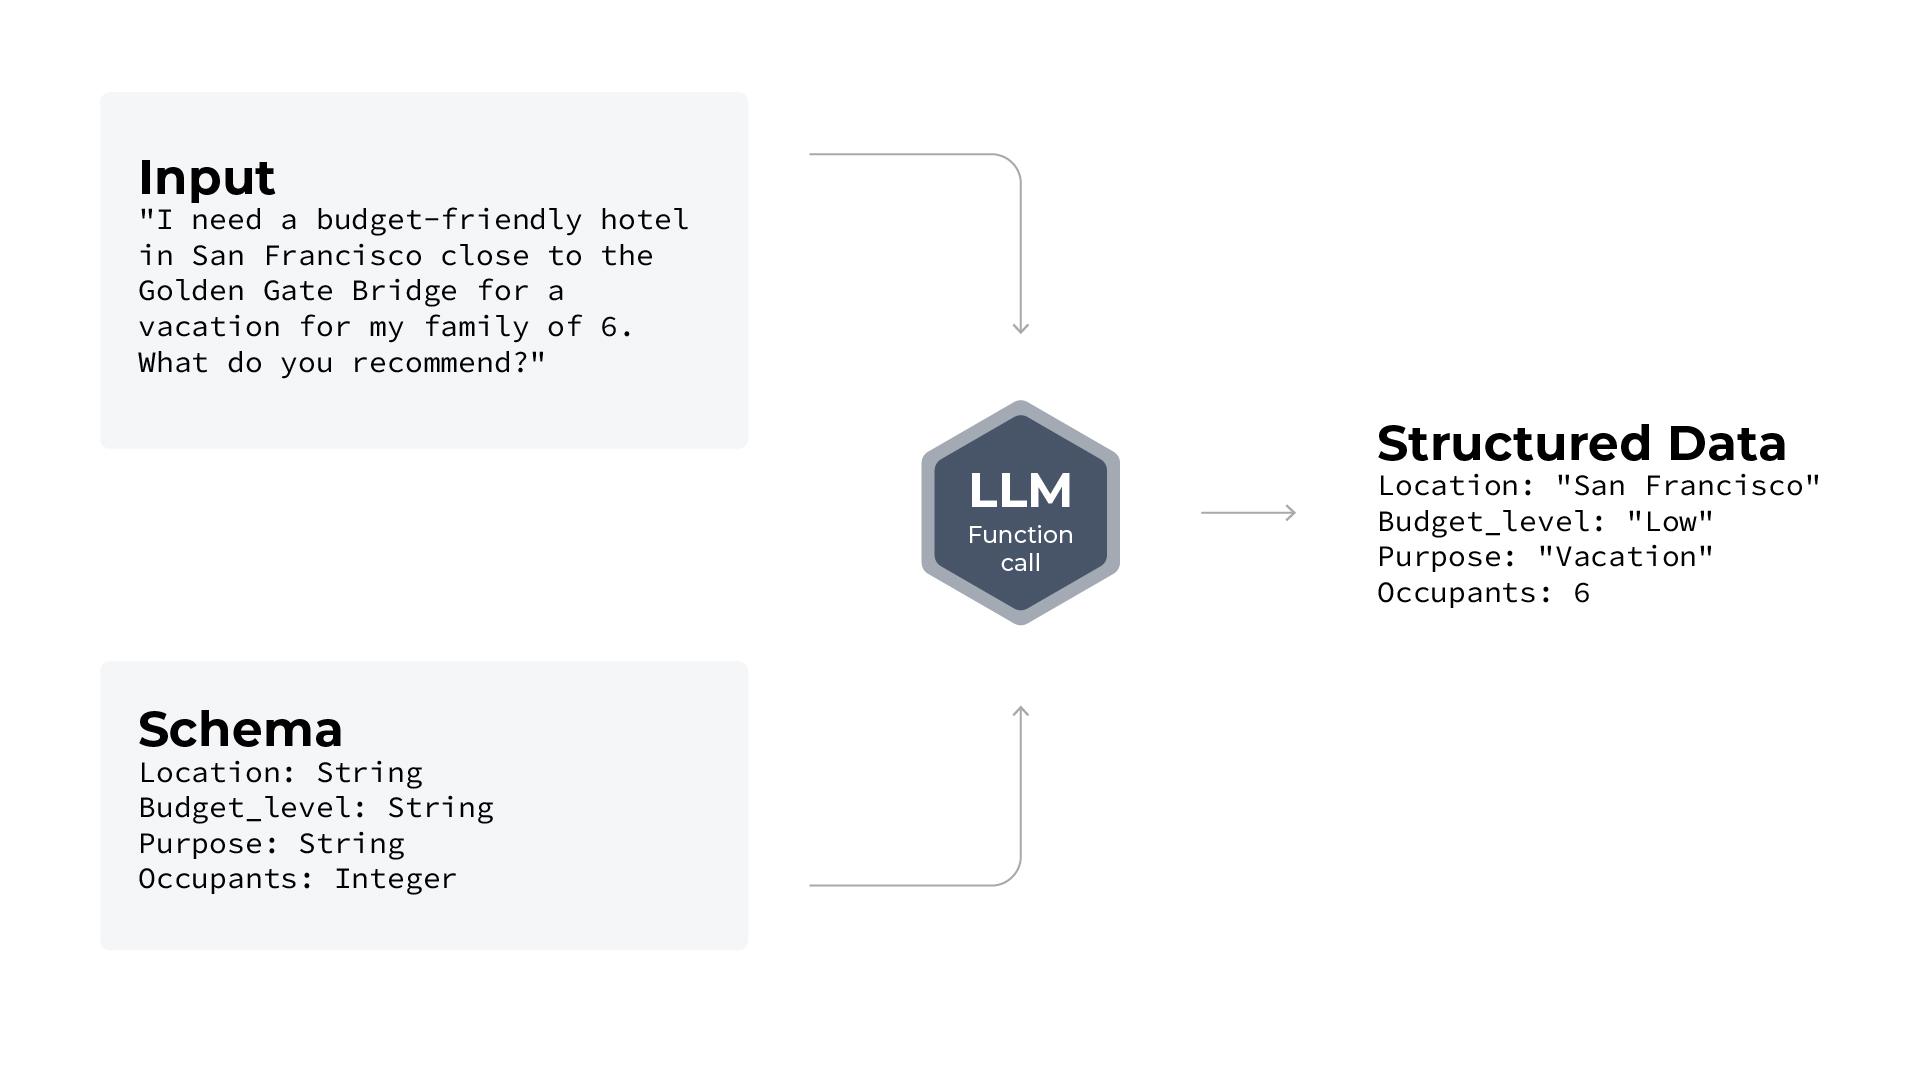
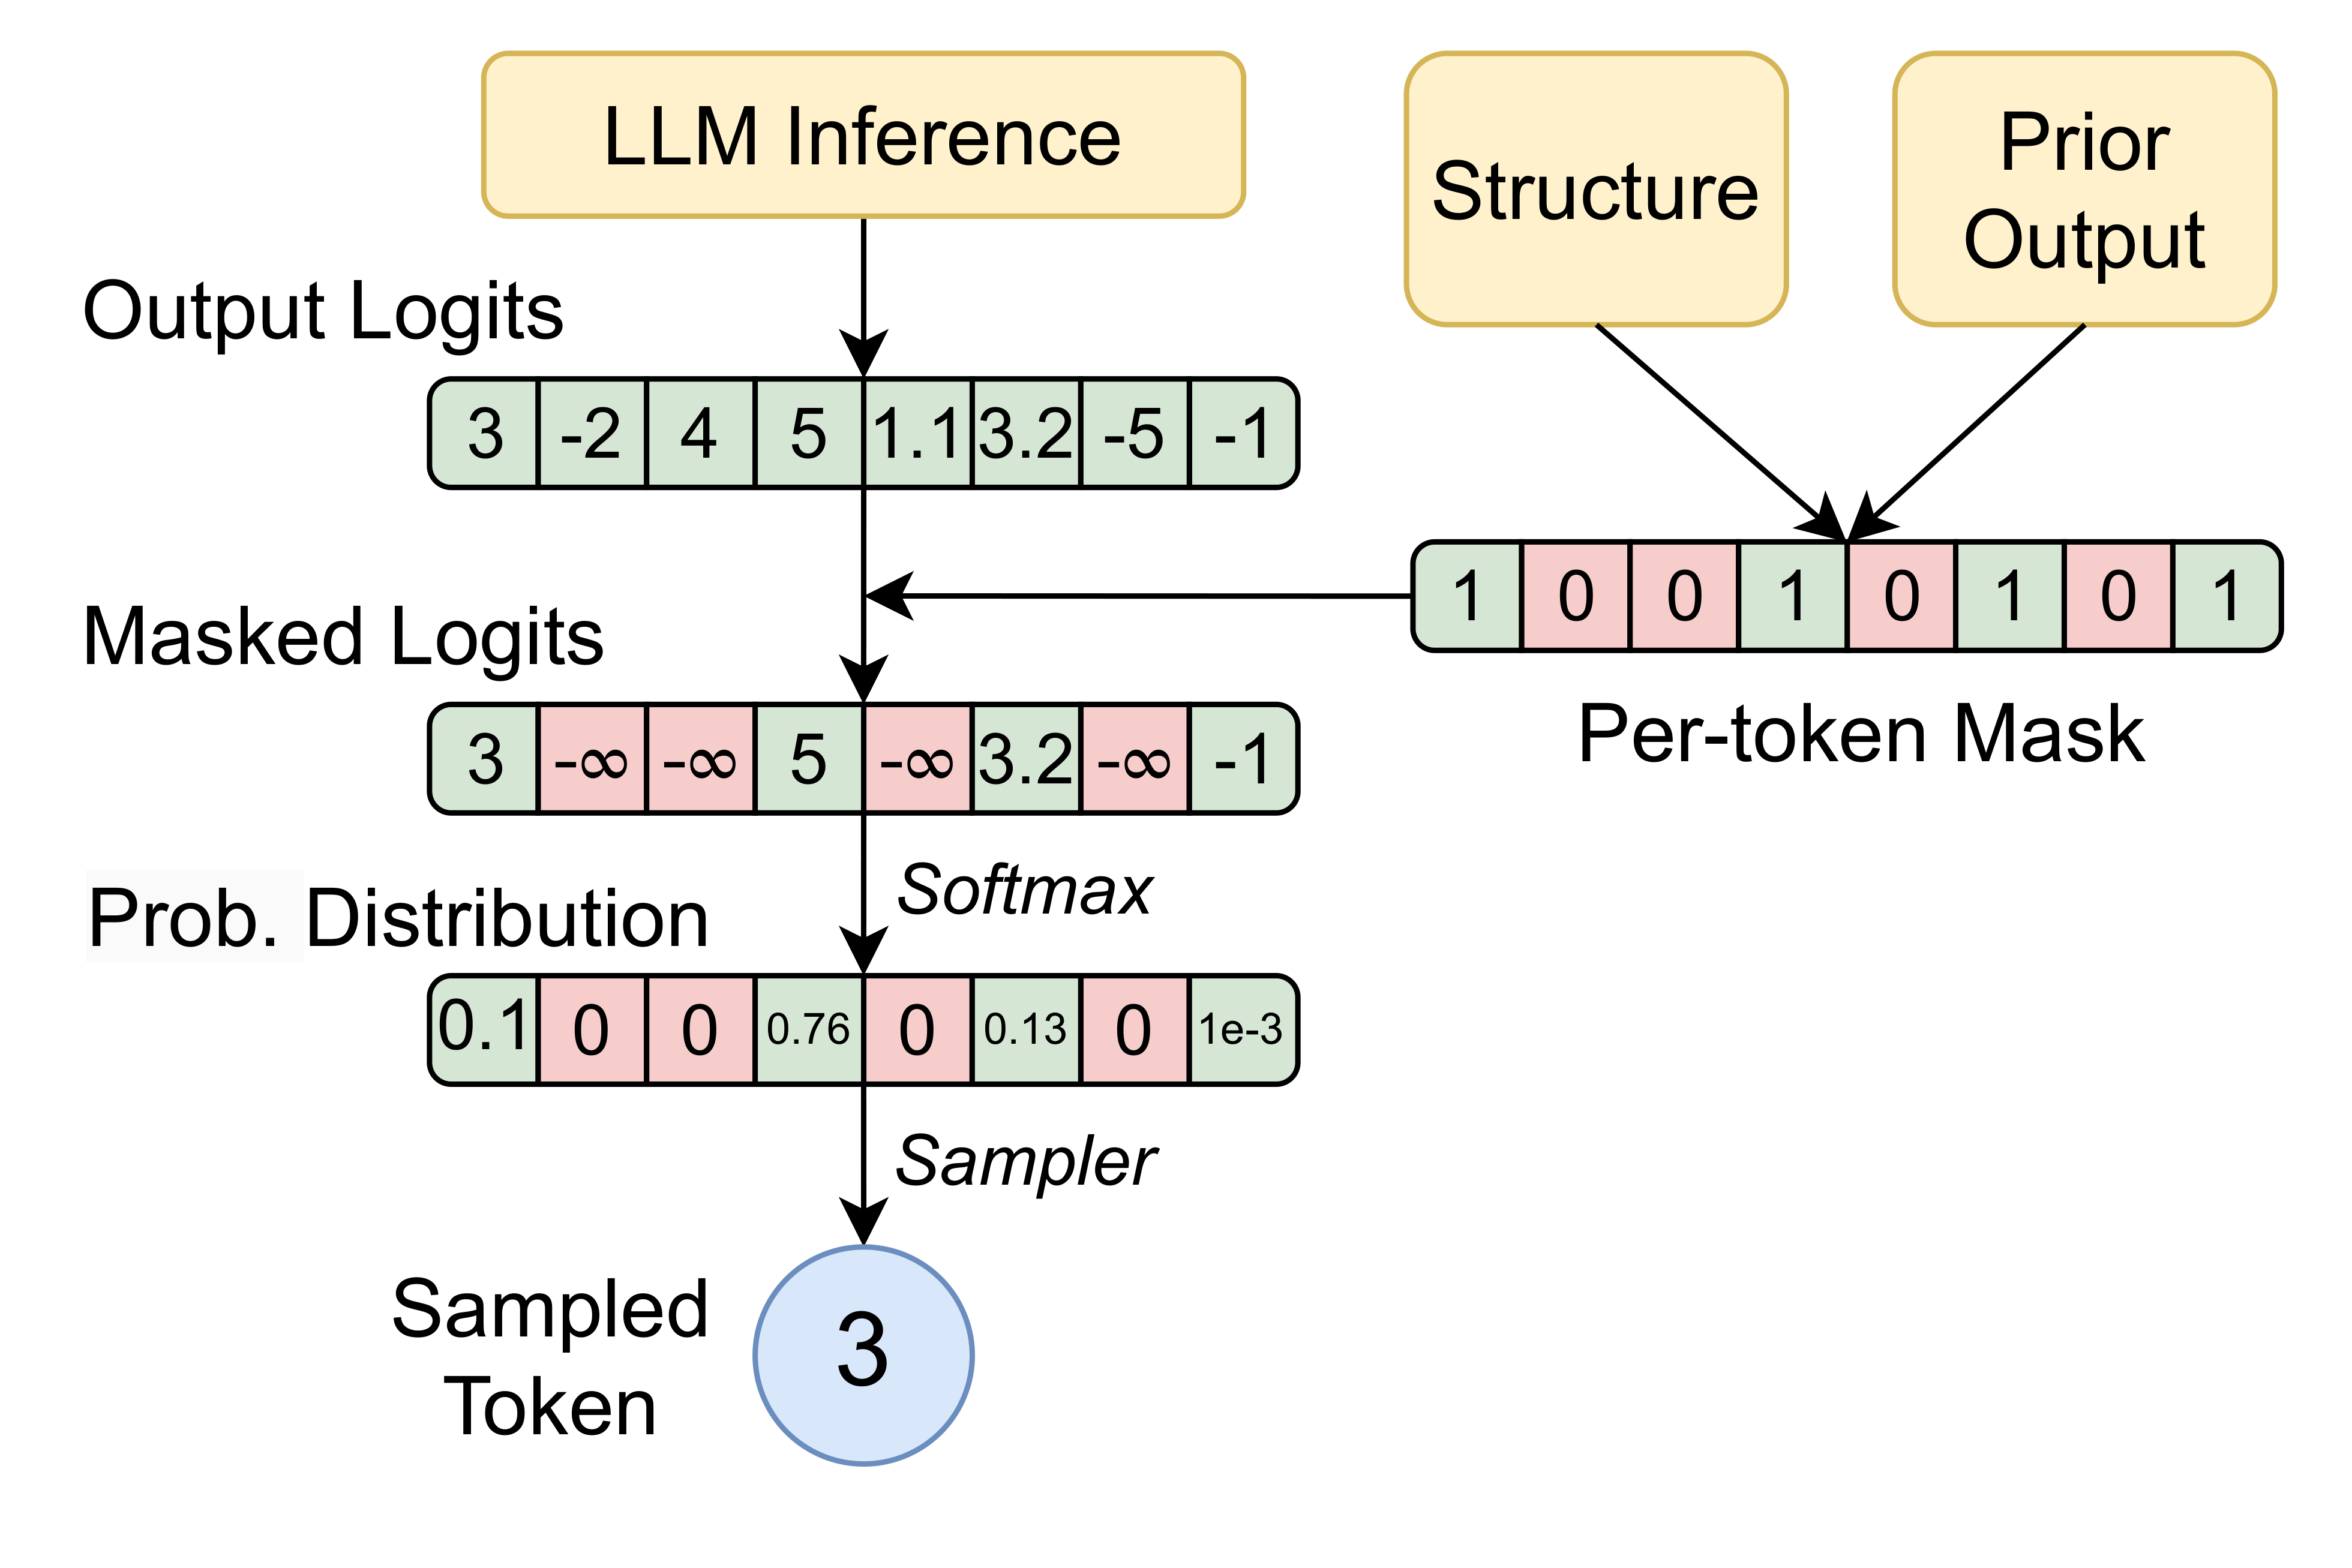
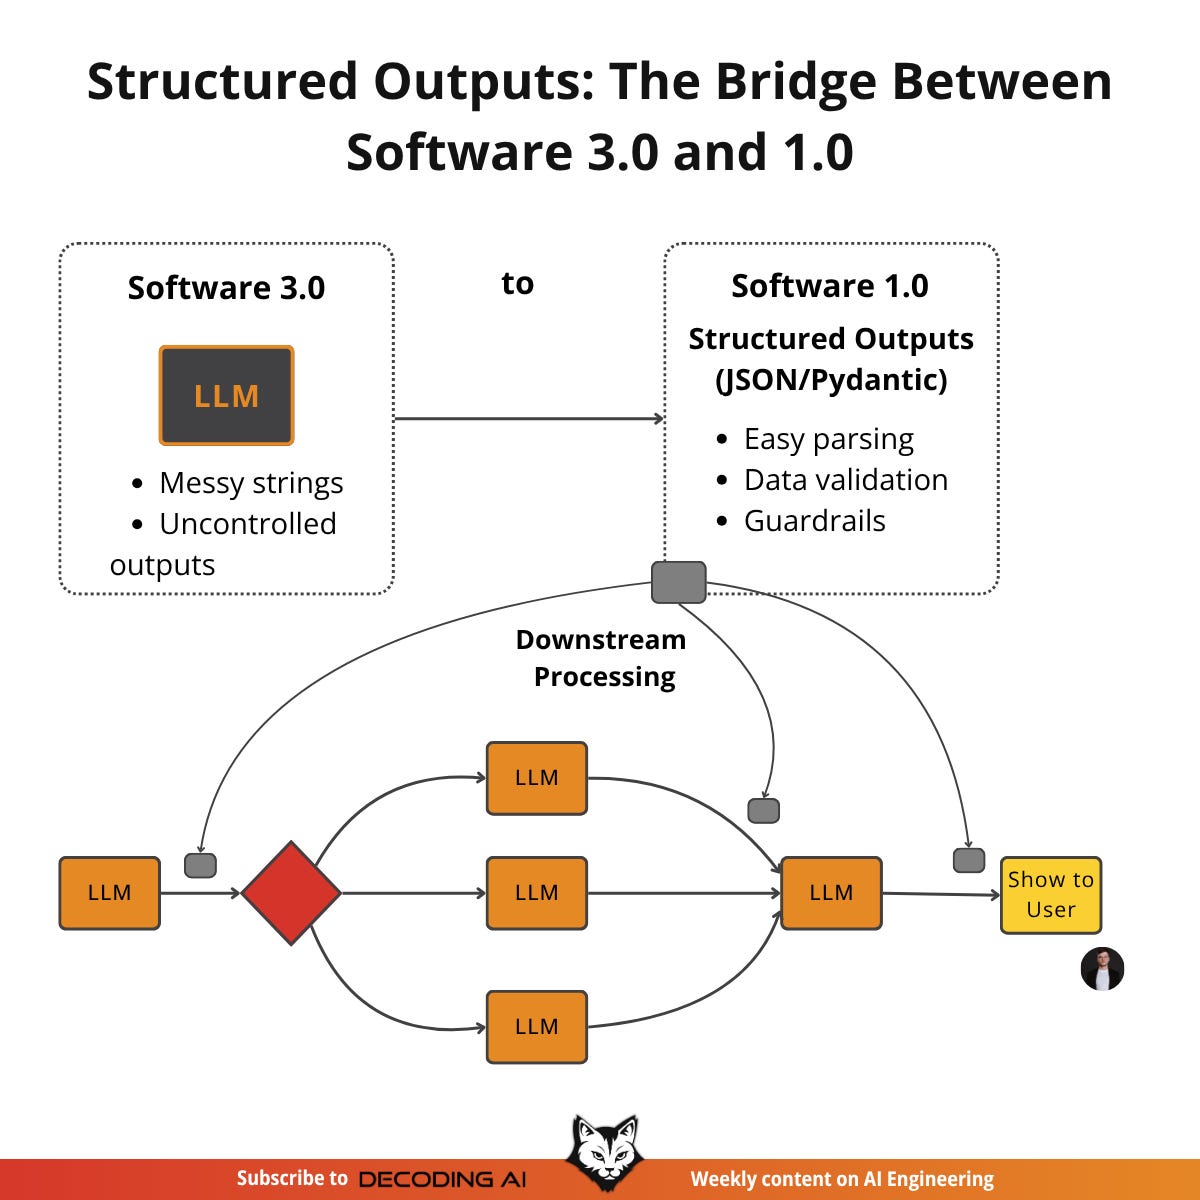
GitHub - Prajwalsrinvas/getting_structured_llm_output: Code files from ...
[论文评述] HeuriGym: An Agentic Benchmark for LLM-Crafted Heuristics in ...
llm-optimizer: An Open-Source Tool for LLM Inference Benchmarking and ...
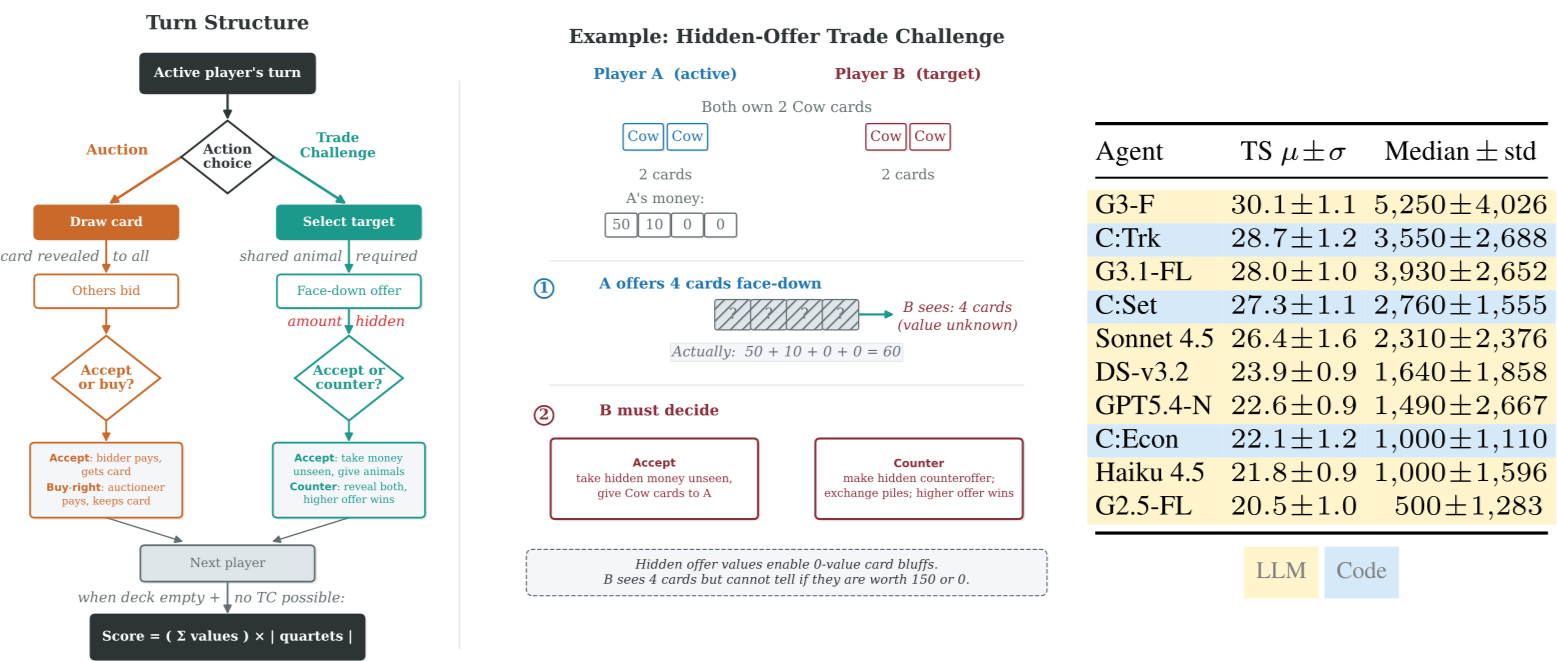
[논문 리뷰] Cattle Trade: A Multi-Agent Benchmark for LLM Bluffing, Bidding ...
GitHub - lework/llm-benchmark: LLM 并发性能测试工具,支持自动化压力测试和性能报告生成。 · GitHub
llm-ui-coord-benchmark: UI Eval Benchmark for ML Engineers
GitHub - mk7sub/log-analyze-llm-benchmark: ログ解析に適したLLMモデルを比較評価するためのプロジェクト。
AI tools list for Benchmark Llms | Toolerific
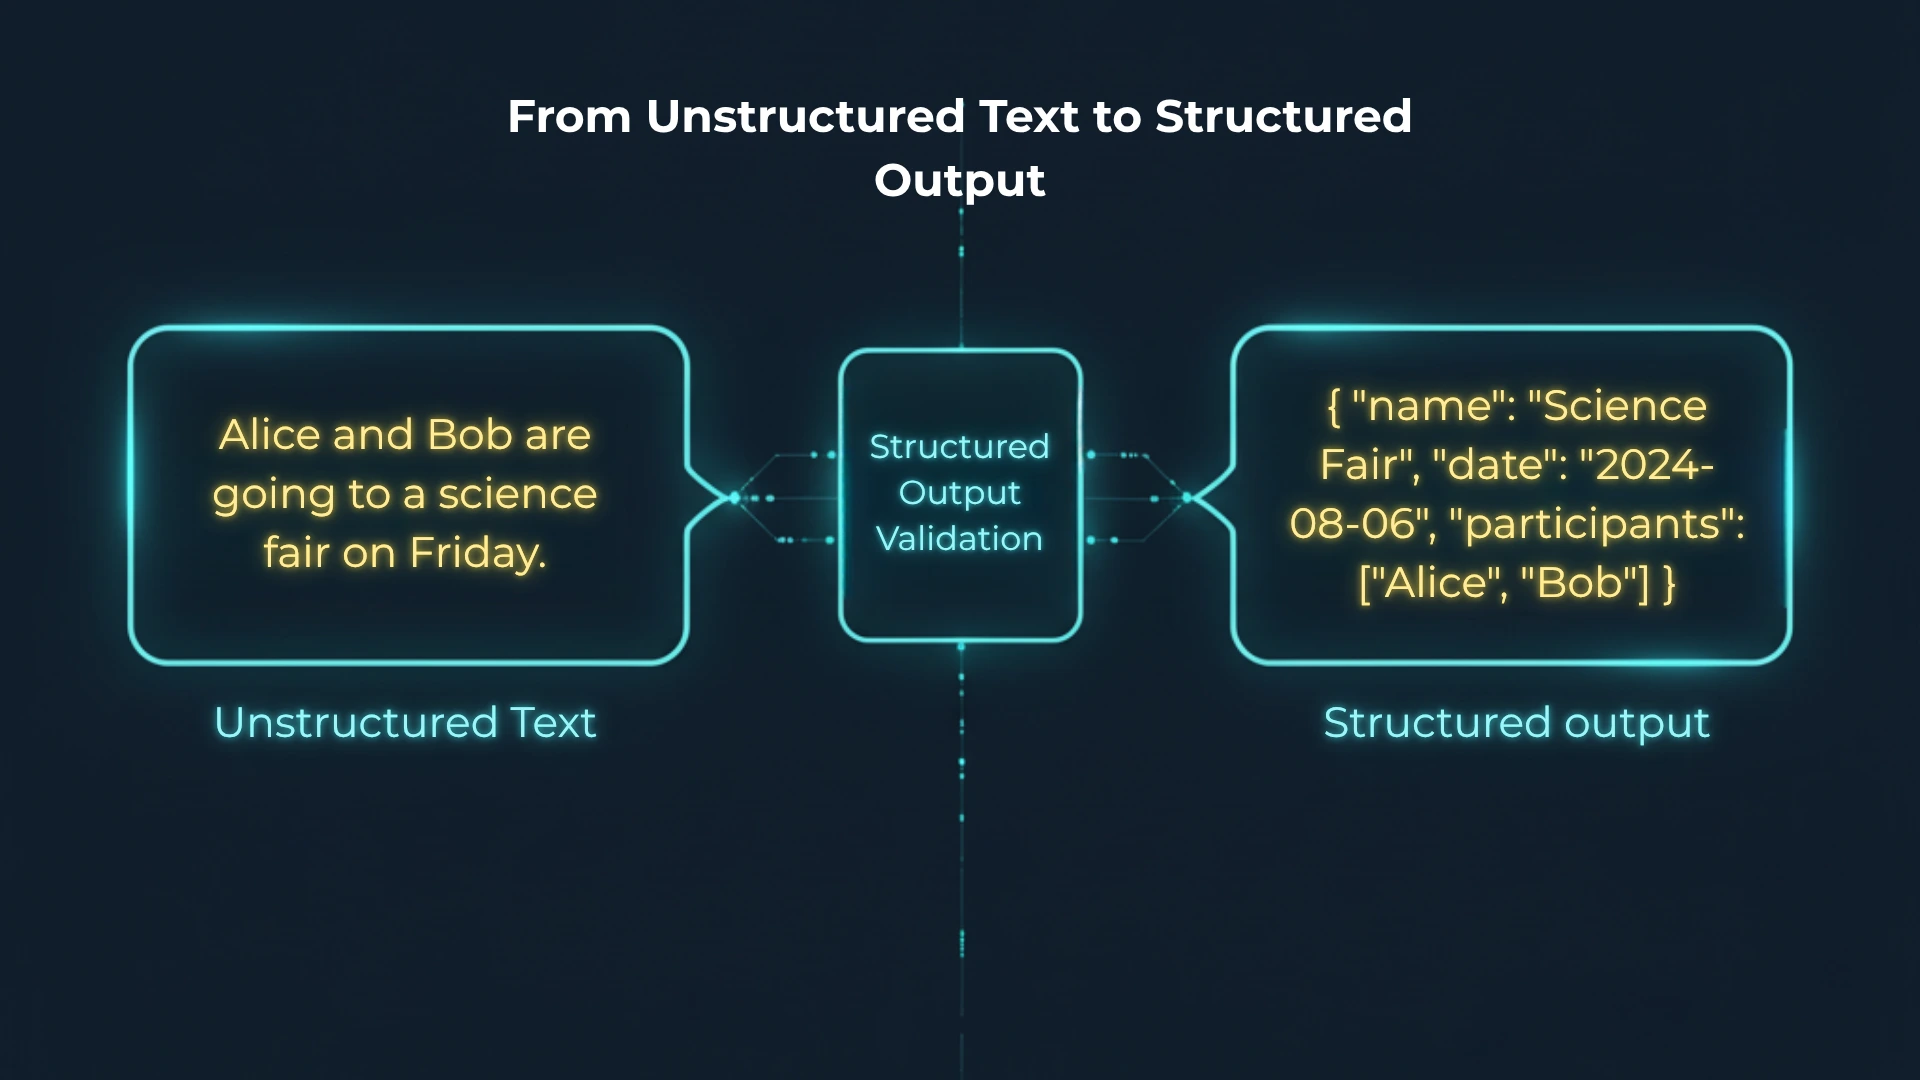
New benchmark targets LLM structured output reliability | The Agentic ...
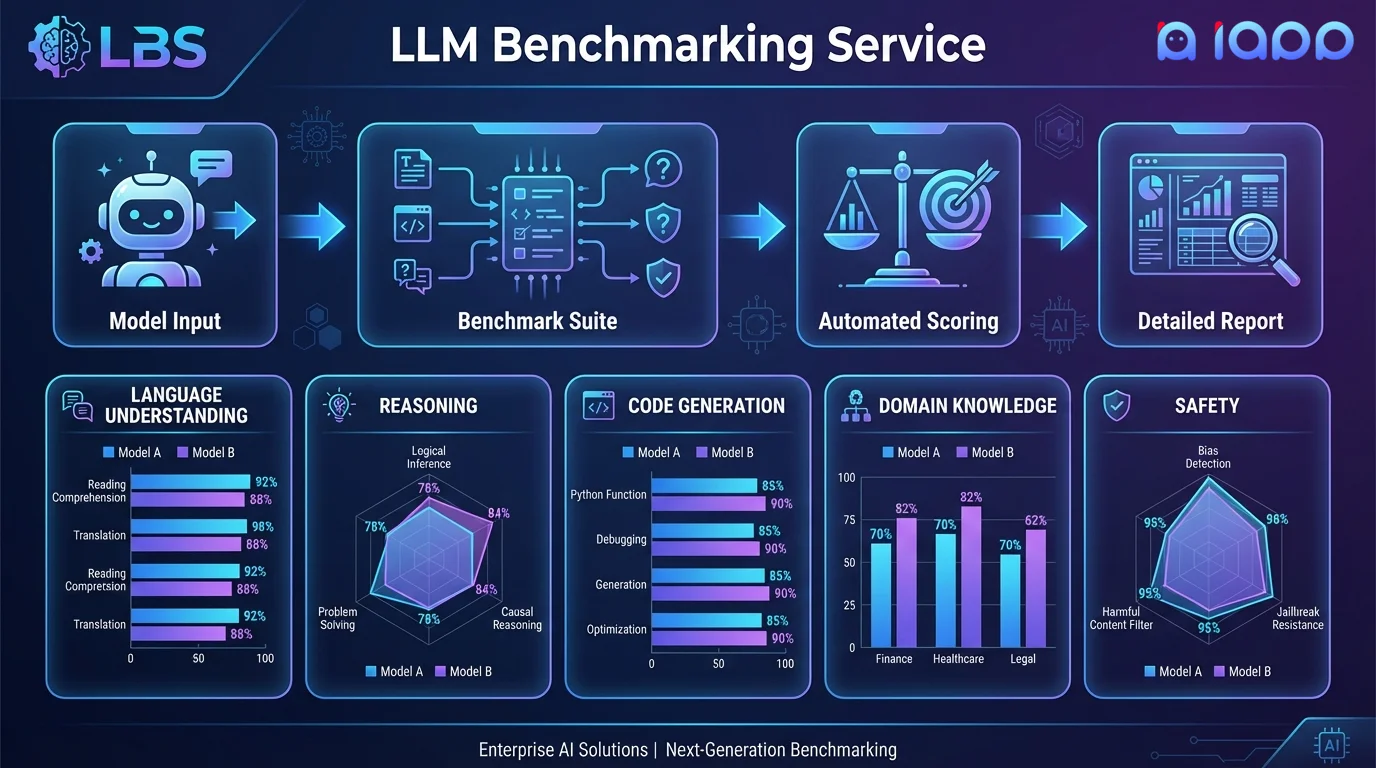
LLM Benchmarking Service - Comprehensive Model Evaluation | iApp ...
AI Code Generation: New DevQualityEval Benchmark Reveals Which LLMs ...
GitHub - TRAIS-Lab/LLM-Structured-Data
How to Build Custom LLM Benchmarks for Your AI Applications - Geeky Gadgets
Giselle Introduces GitHub Vector Store Nodes: Build Code-Aware RAG ...
GDPval Benchmark Explained: Best AI Models for Real-World Work Tasks (2026)
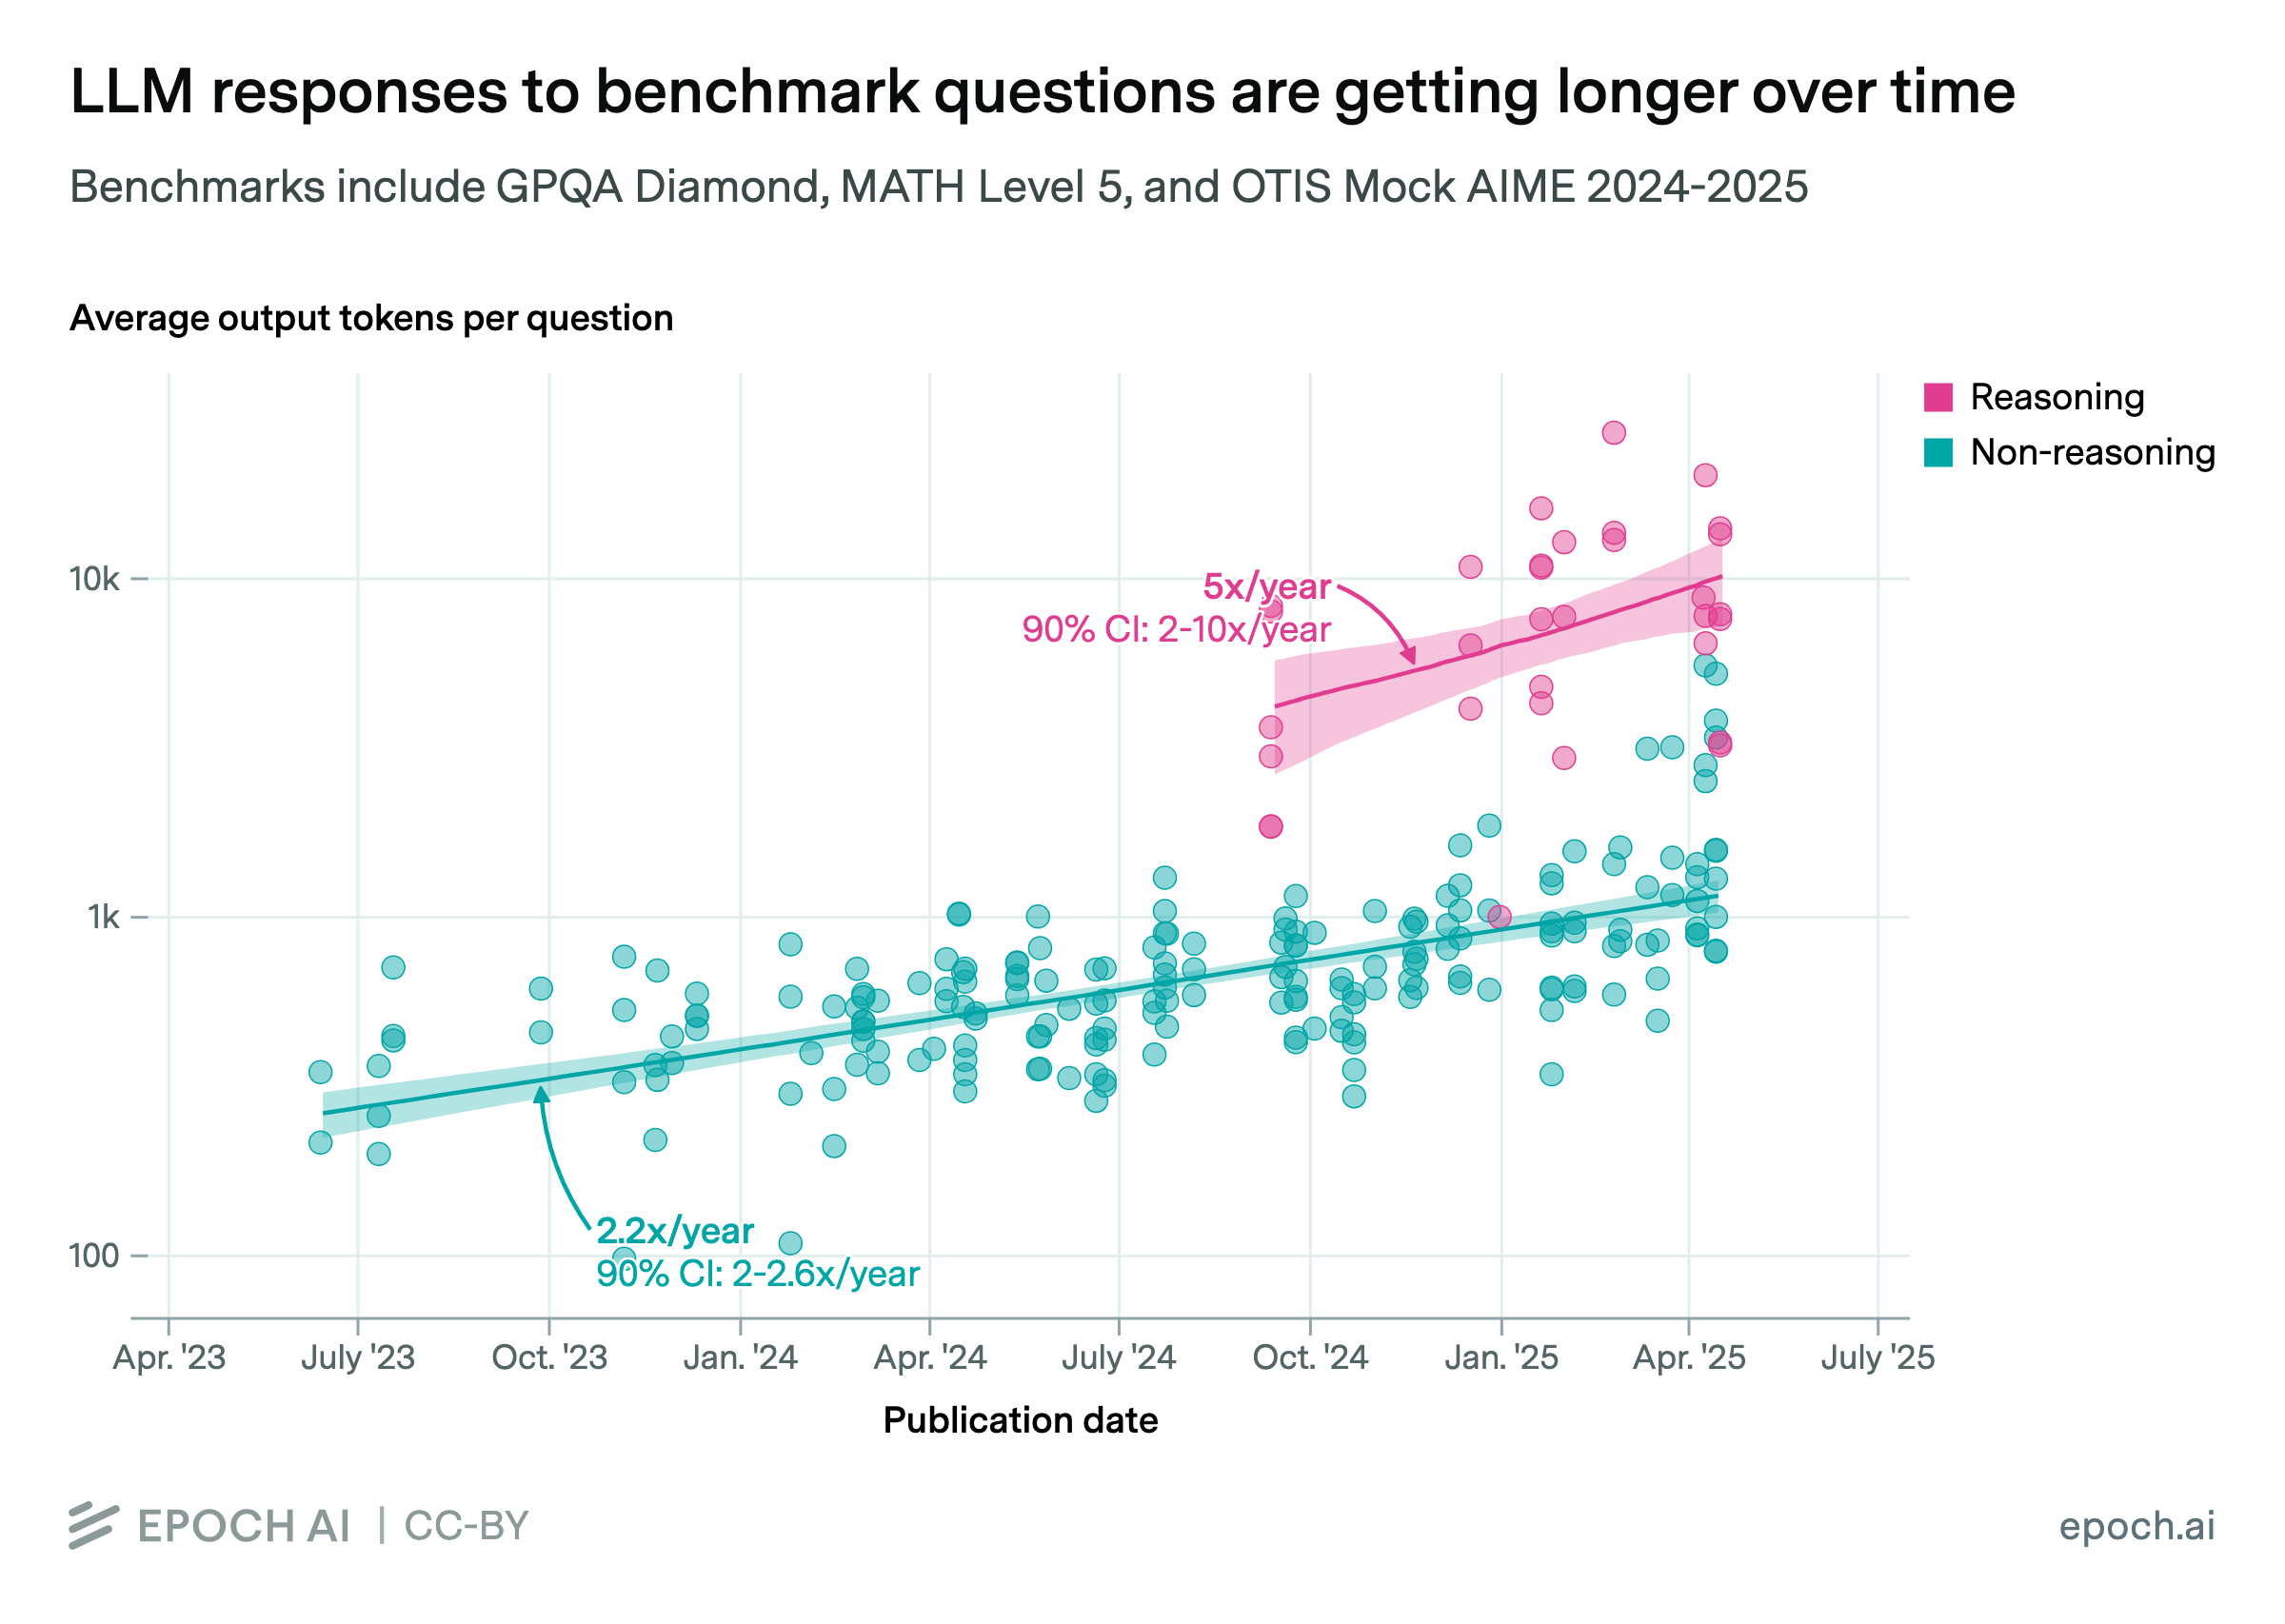
LLM responses to benchmark questions are getting longer over time ...
Marktechpost Releases 'AI2025Dev': A Structured Intelligence Layer for ...
LLM-GLOBE: A Benchmark Evaluating the Cultural Values Embedded in LLM ...
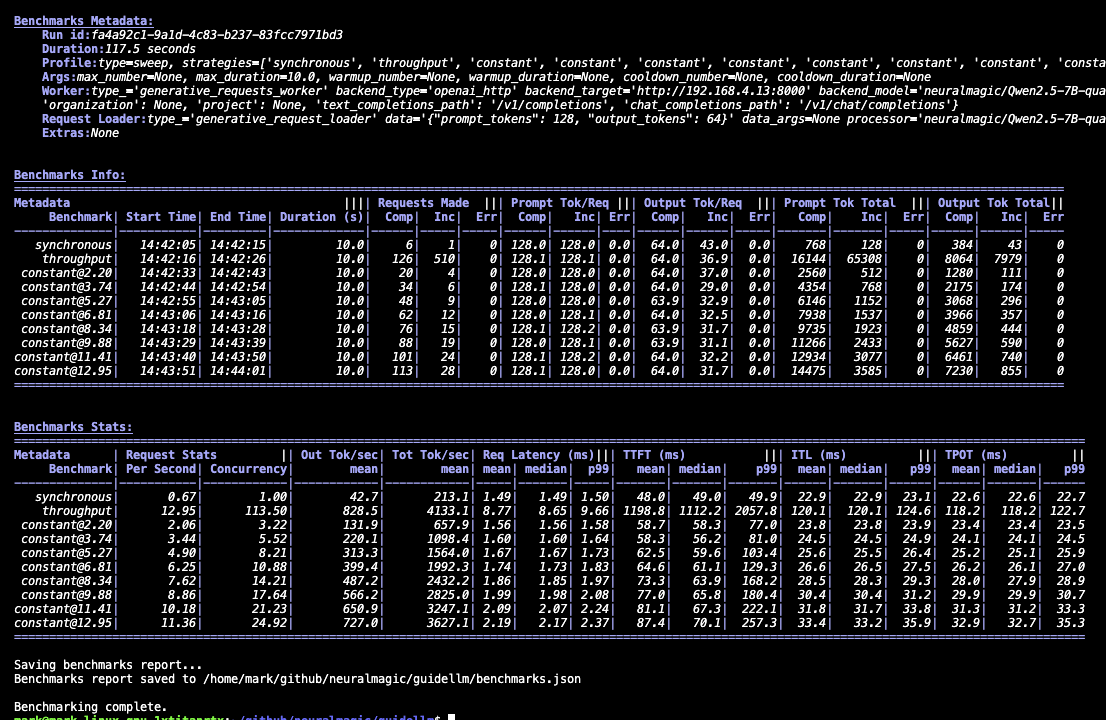
guidellm/README.md at main · vllm-project/guidellm · GitHub
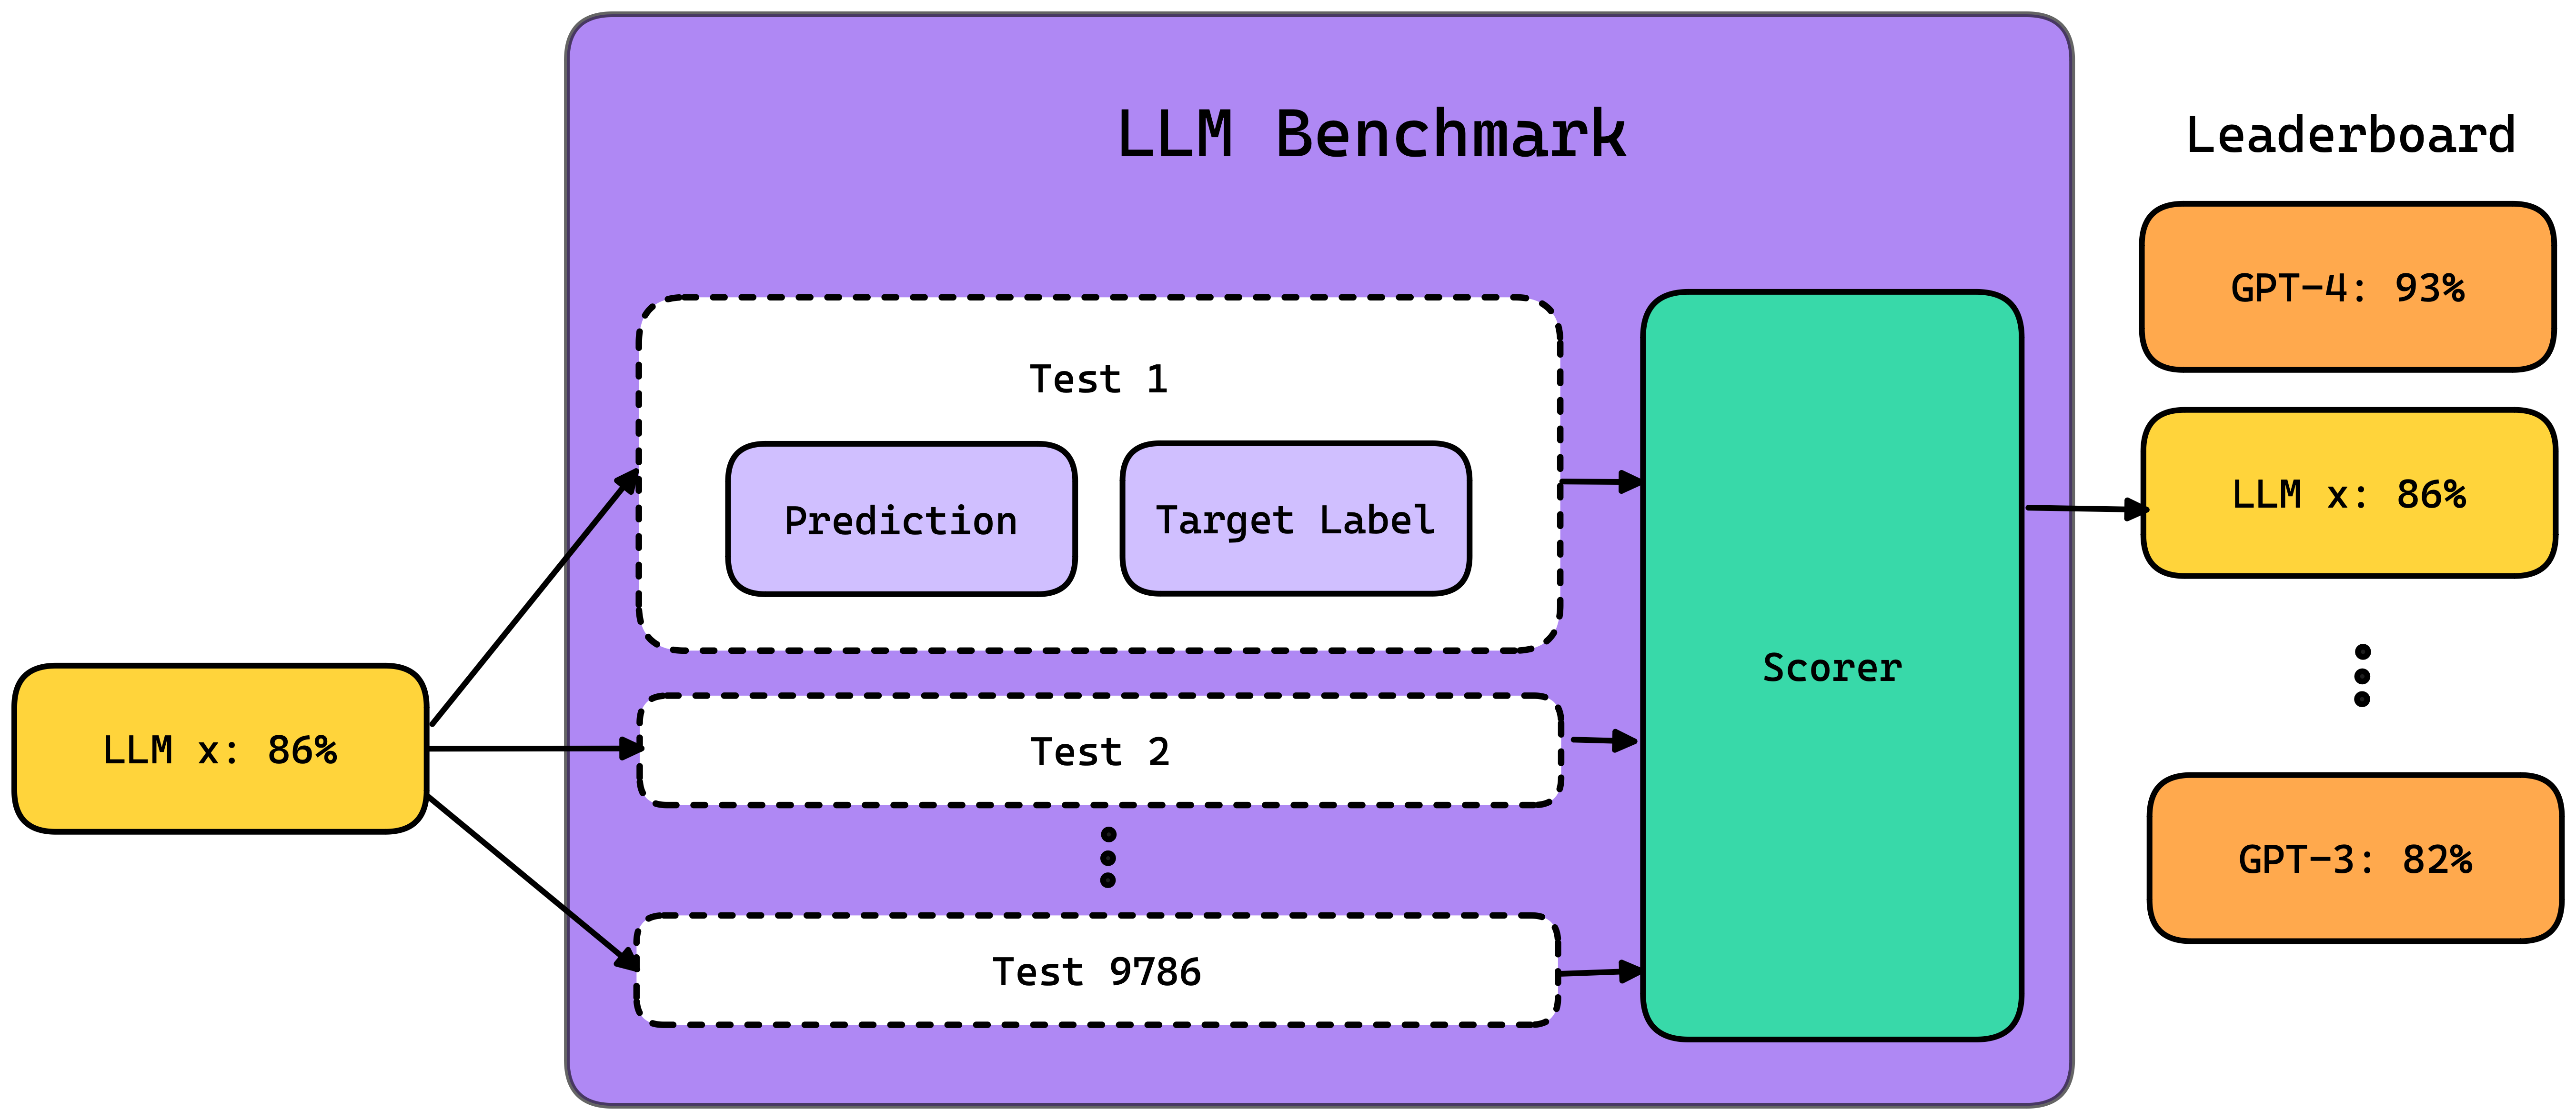
LLM Benchmarks: MMLU, HellaSwag, BBH, and Beyond - Confident AI
Evaluating LLM Systems: Essential Metrics, Benchmarks, and Best ...
New LLM benchmark evaluates enterprise AI accuracy | Salesforce
High-performance OpenAI-compatible LLM inference API Blibs for developers
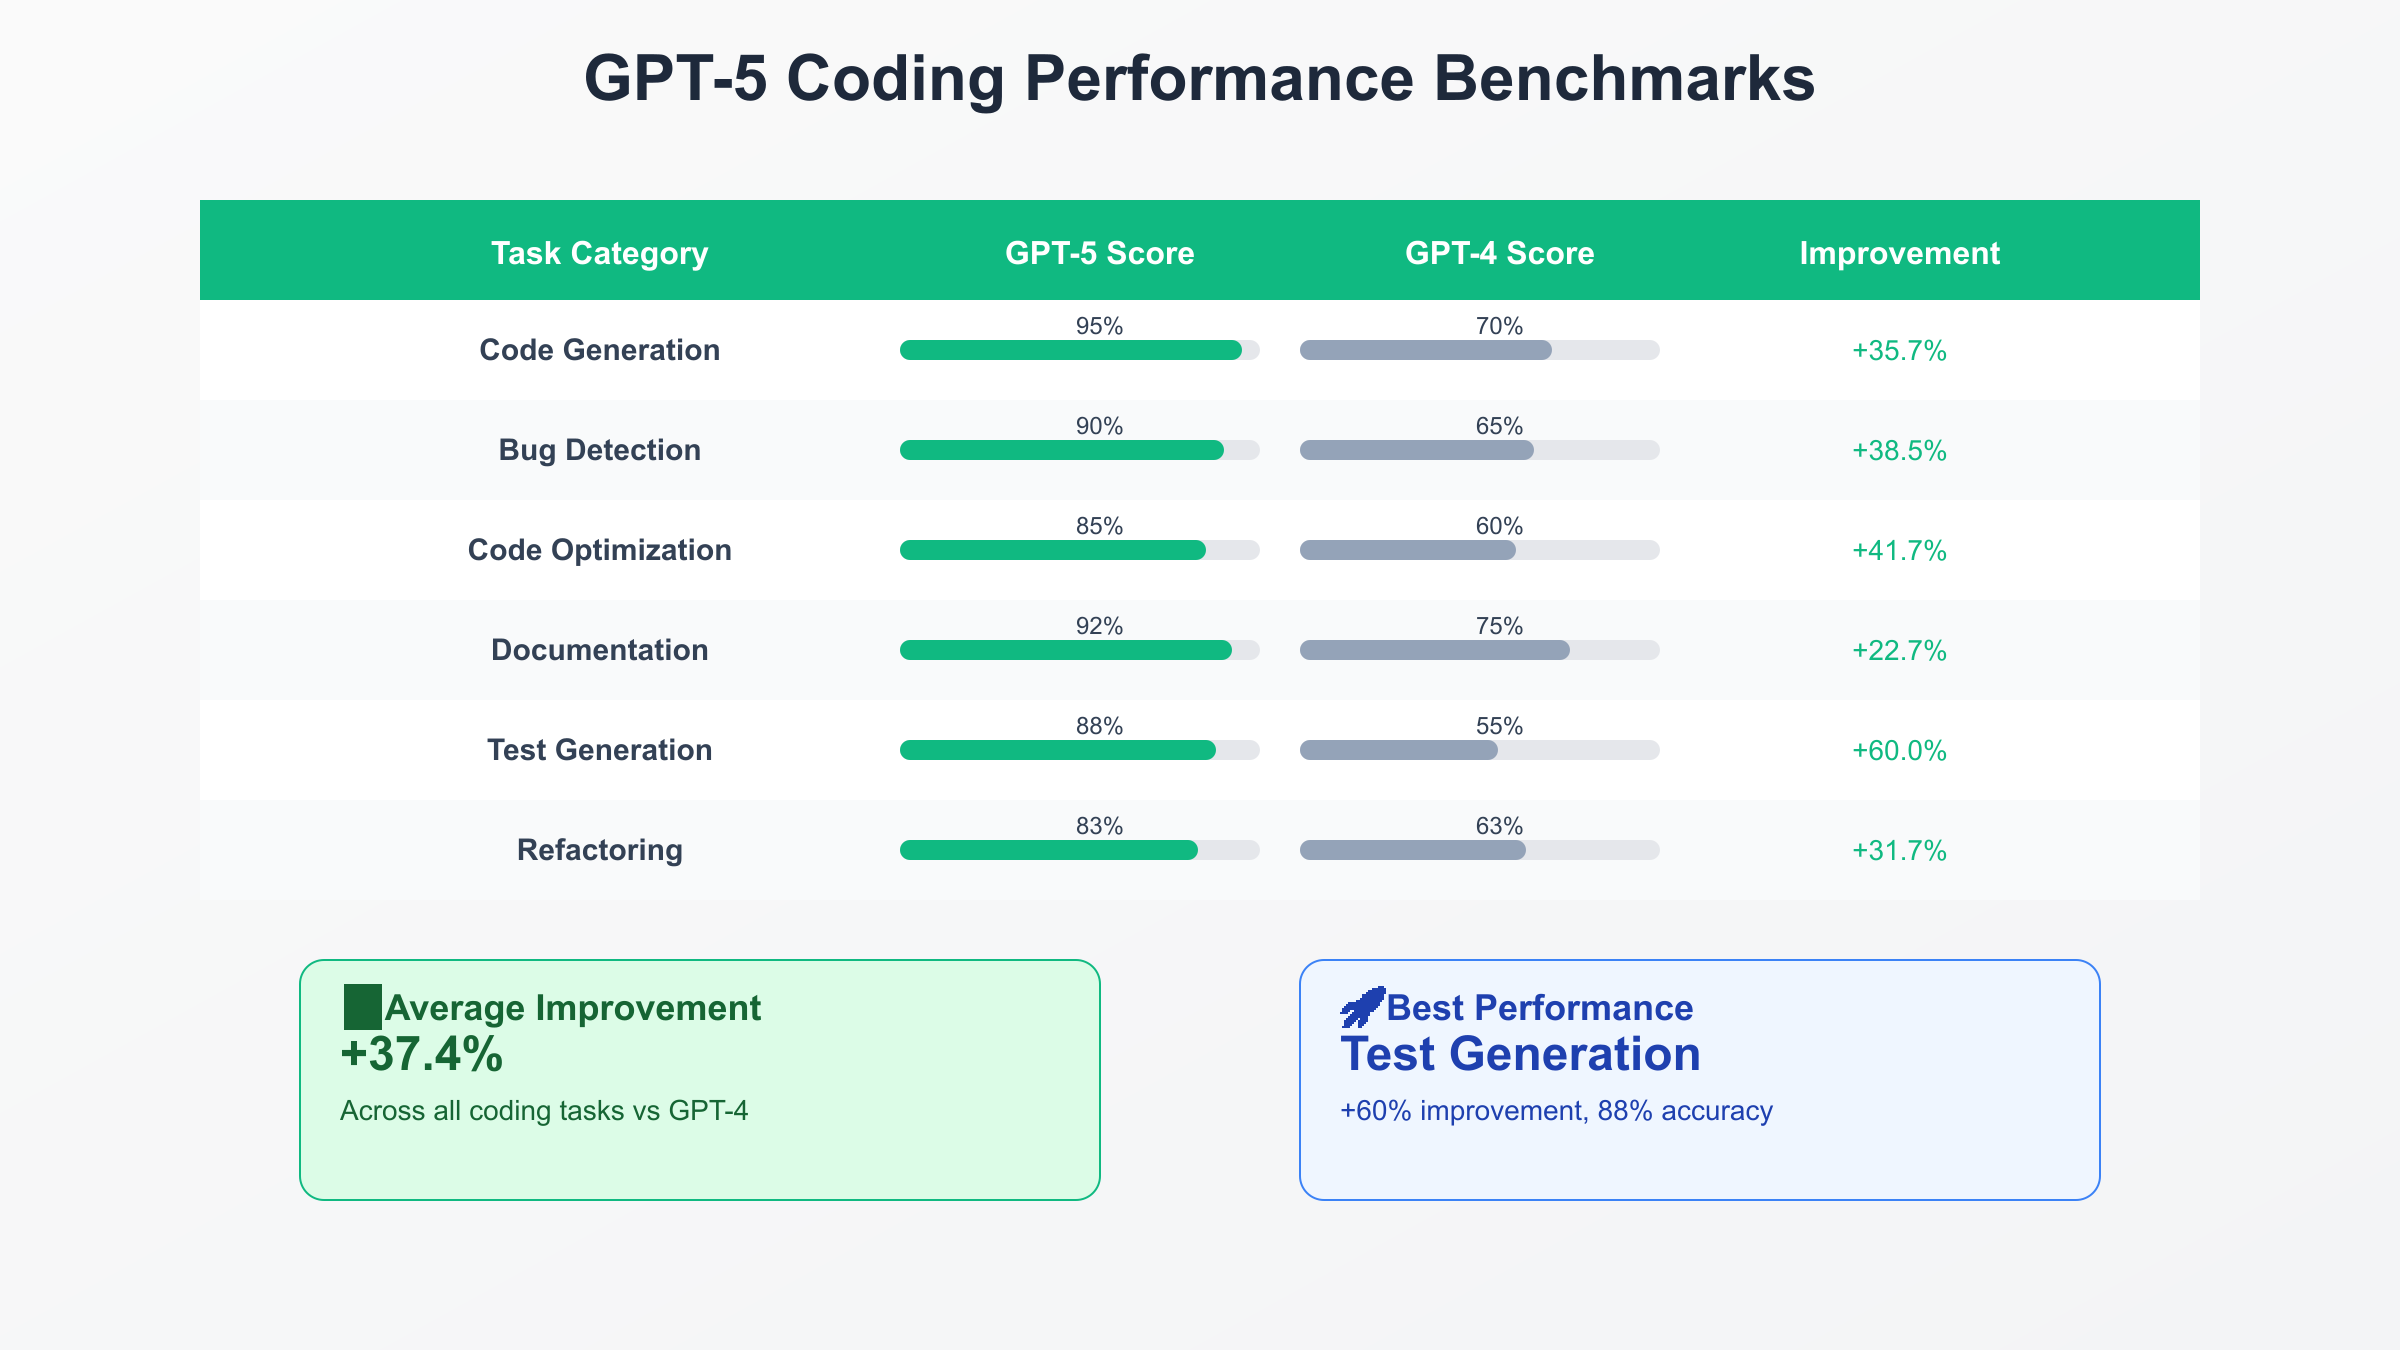
GPT-5 Coding: 74.9% SWE-bench & 88% Aider Performance [August 2025 ...
AI-Security-Benchmark/output/codegemma_temp1.0 at main · miroku0000/AI ...
OpenAI’s Open‑Weight GPT‑OSS Models: A Comprehensive Review | by ...
How to Interpret LLM Benchmark Results: A Practical Guide | BenchLM.ai
How to Build an LLM Evaluation Framework, from Scratch - Confident AI
10 Must-Know LLM Benchmarks for Comprehensive Analysis
LLM API Benchmark MCP Server | MCP S... · LobeHub
NVIDIA Llama Nemotron Ultra Open Model Delivers Groundbreaking ...
Qwen — Model Architecture Across Generations — Model Architectures — A ...
Interfaze Structured Output Benchmark Review & Alternatives | SmarToolbox
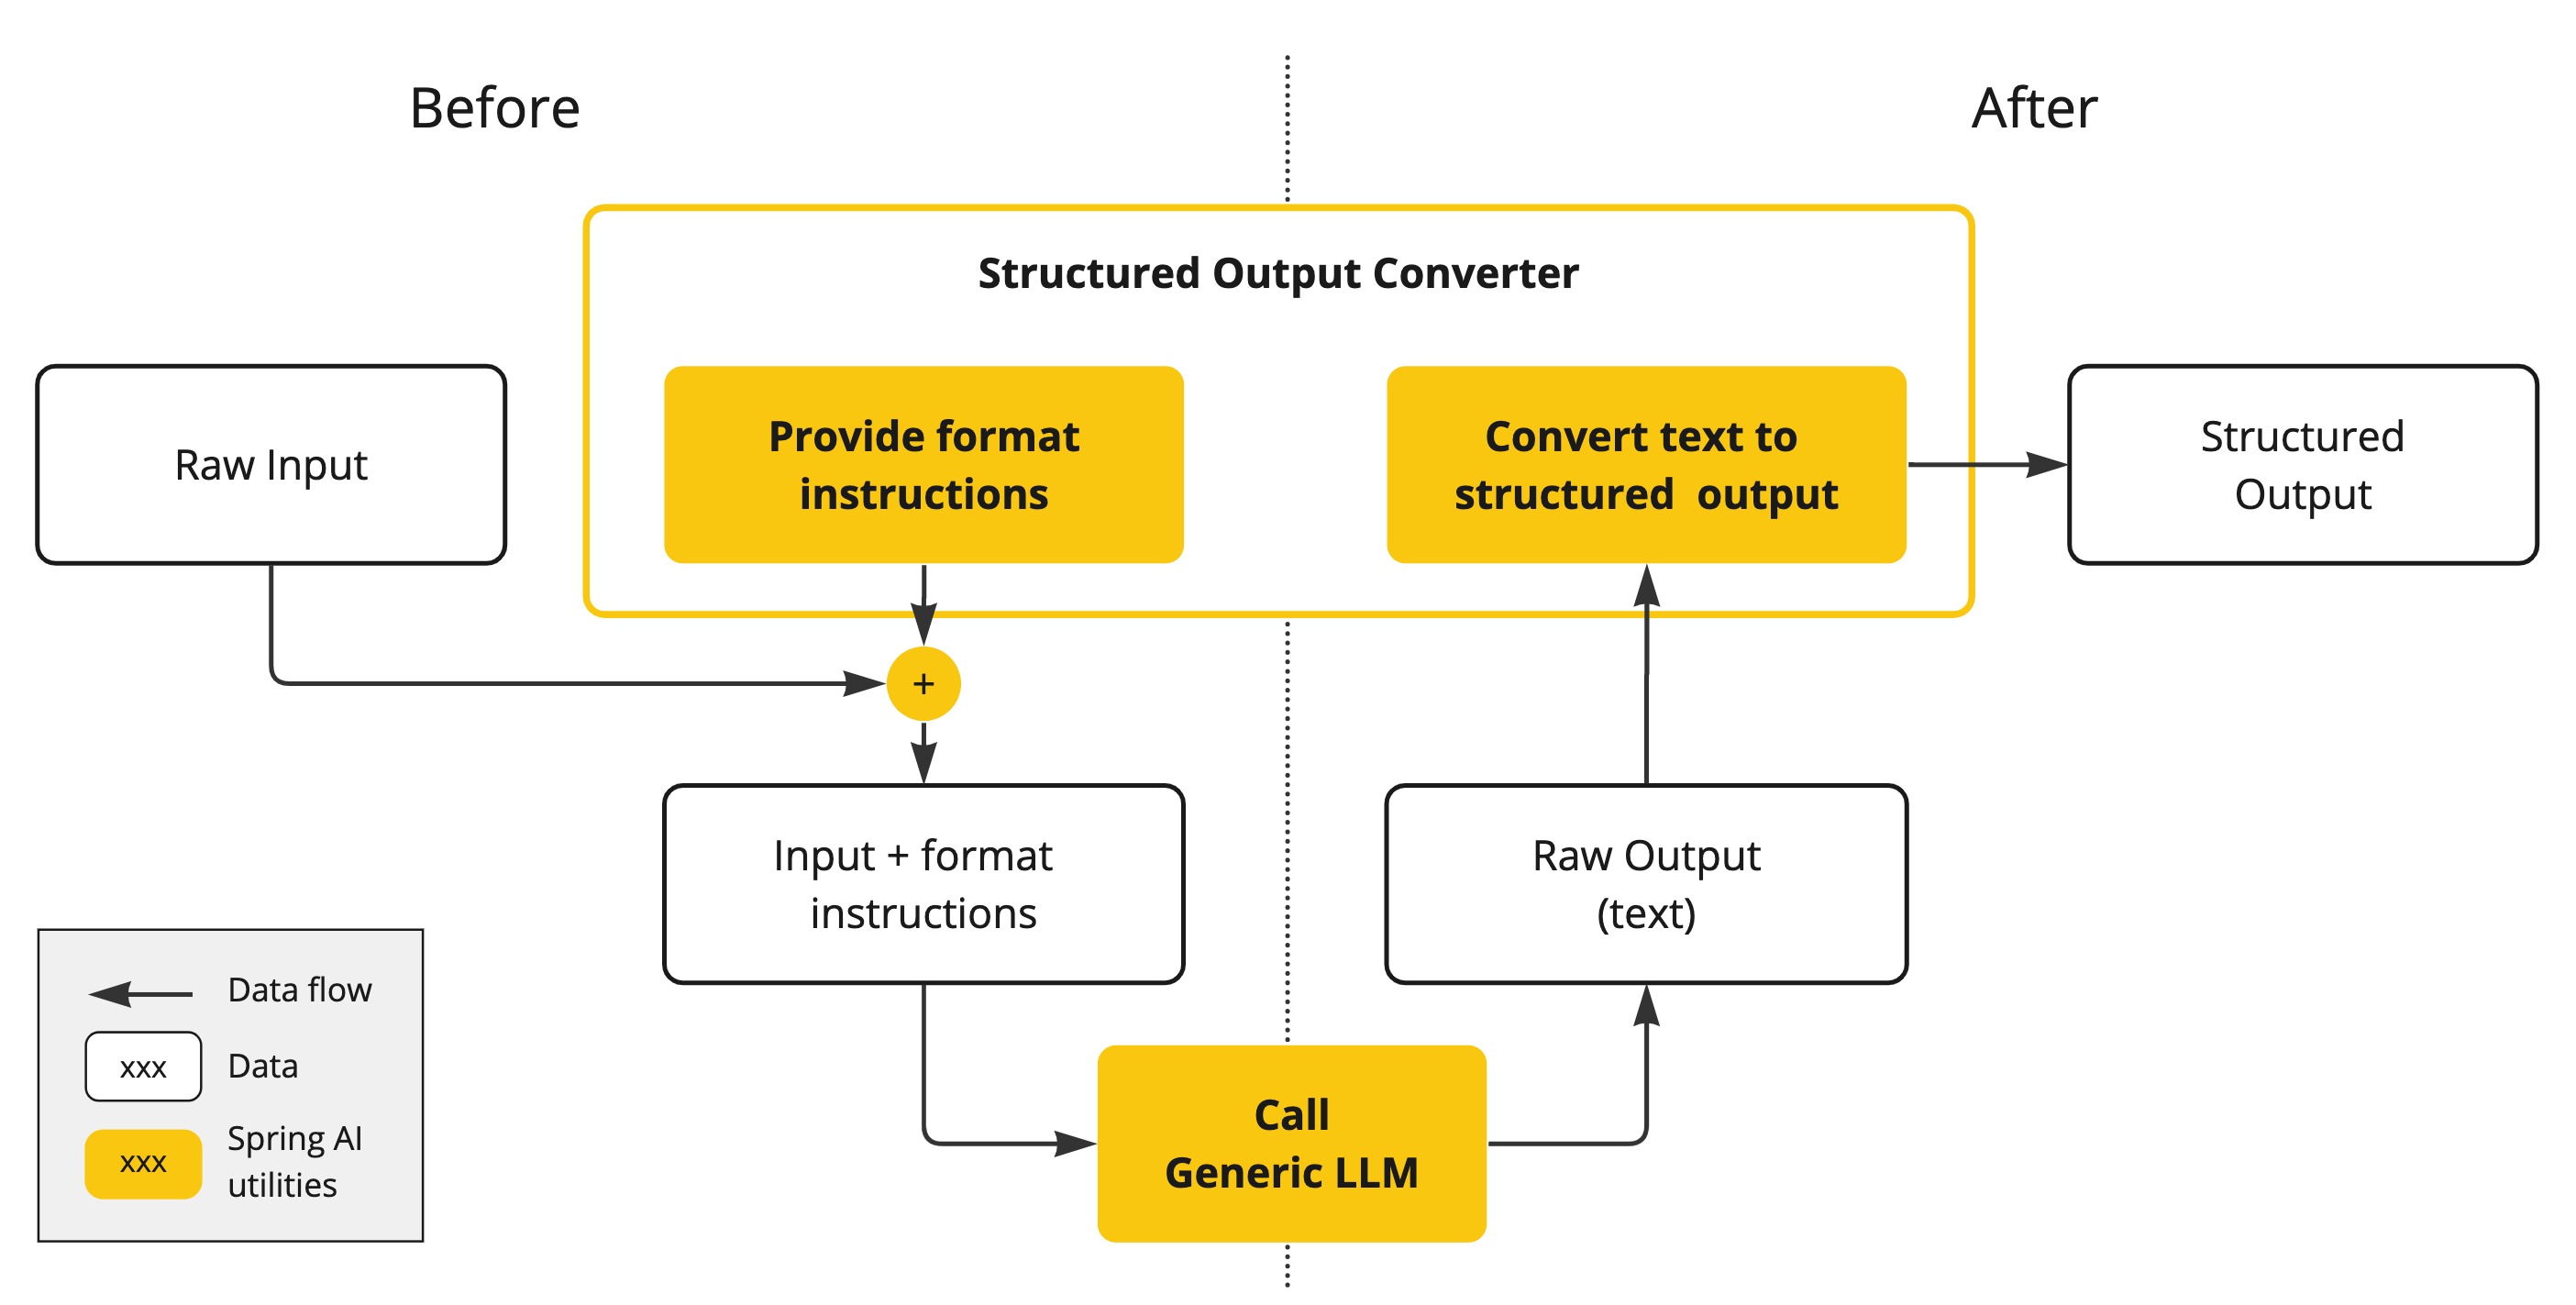
Structured Output (Structured Output) | Spring AI1.1.0中文文档|Spring官方文档 ...
From Feelings to Metrics: Understanding and Formalizing How Users VIBE ...
LLM Benchmarks Explained: MMLU, Chatbot Arena & SWE-bench Leaderboard ...
[NEW] Structured Prompt Outputs & Variable Pathing - YouTube
🐺🐦⬛ LLM对比/测试:DeepSeek-V3、QVQ-72B-Preview、Falcon3 10B、Llama 3.3 70B ...
LLM Structured Output 実践ガイド — JSON Mode、Tool Use、Pydanticスキーマ検証 | Chaos ...
5-dollar-llm/benchmarks at main · Open-Superintelligence-Lab/5-dollar ...
[논문 리뷰] RUST-BENCH: Benchmarking LLM Reasoning on Unstructured Text ...
Testing LLMs on real tasks shouldn’t live in scattered scripts ...
Getting Structured LLM Output - Mosu
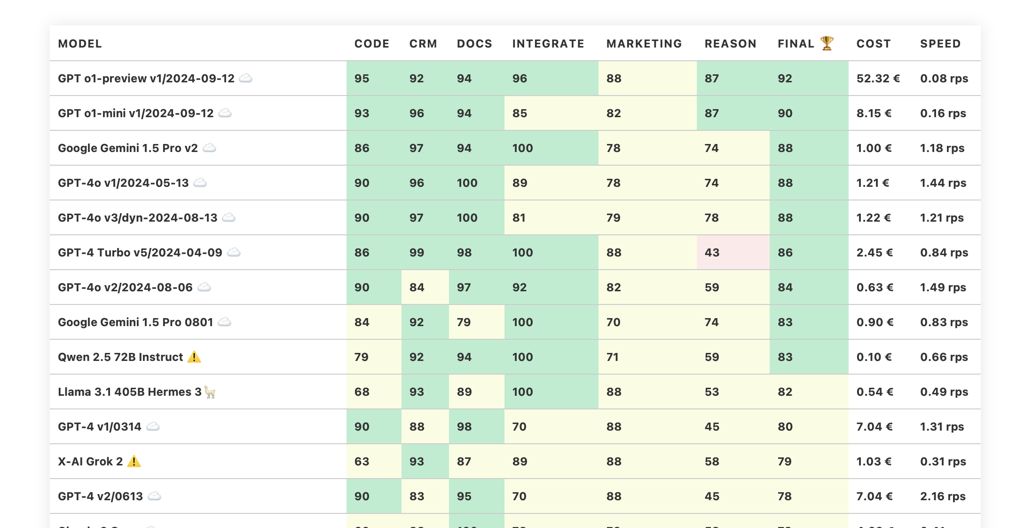
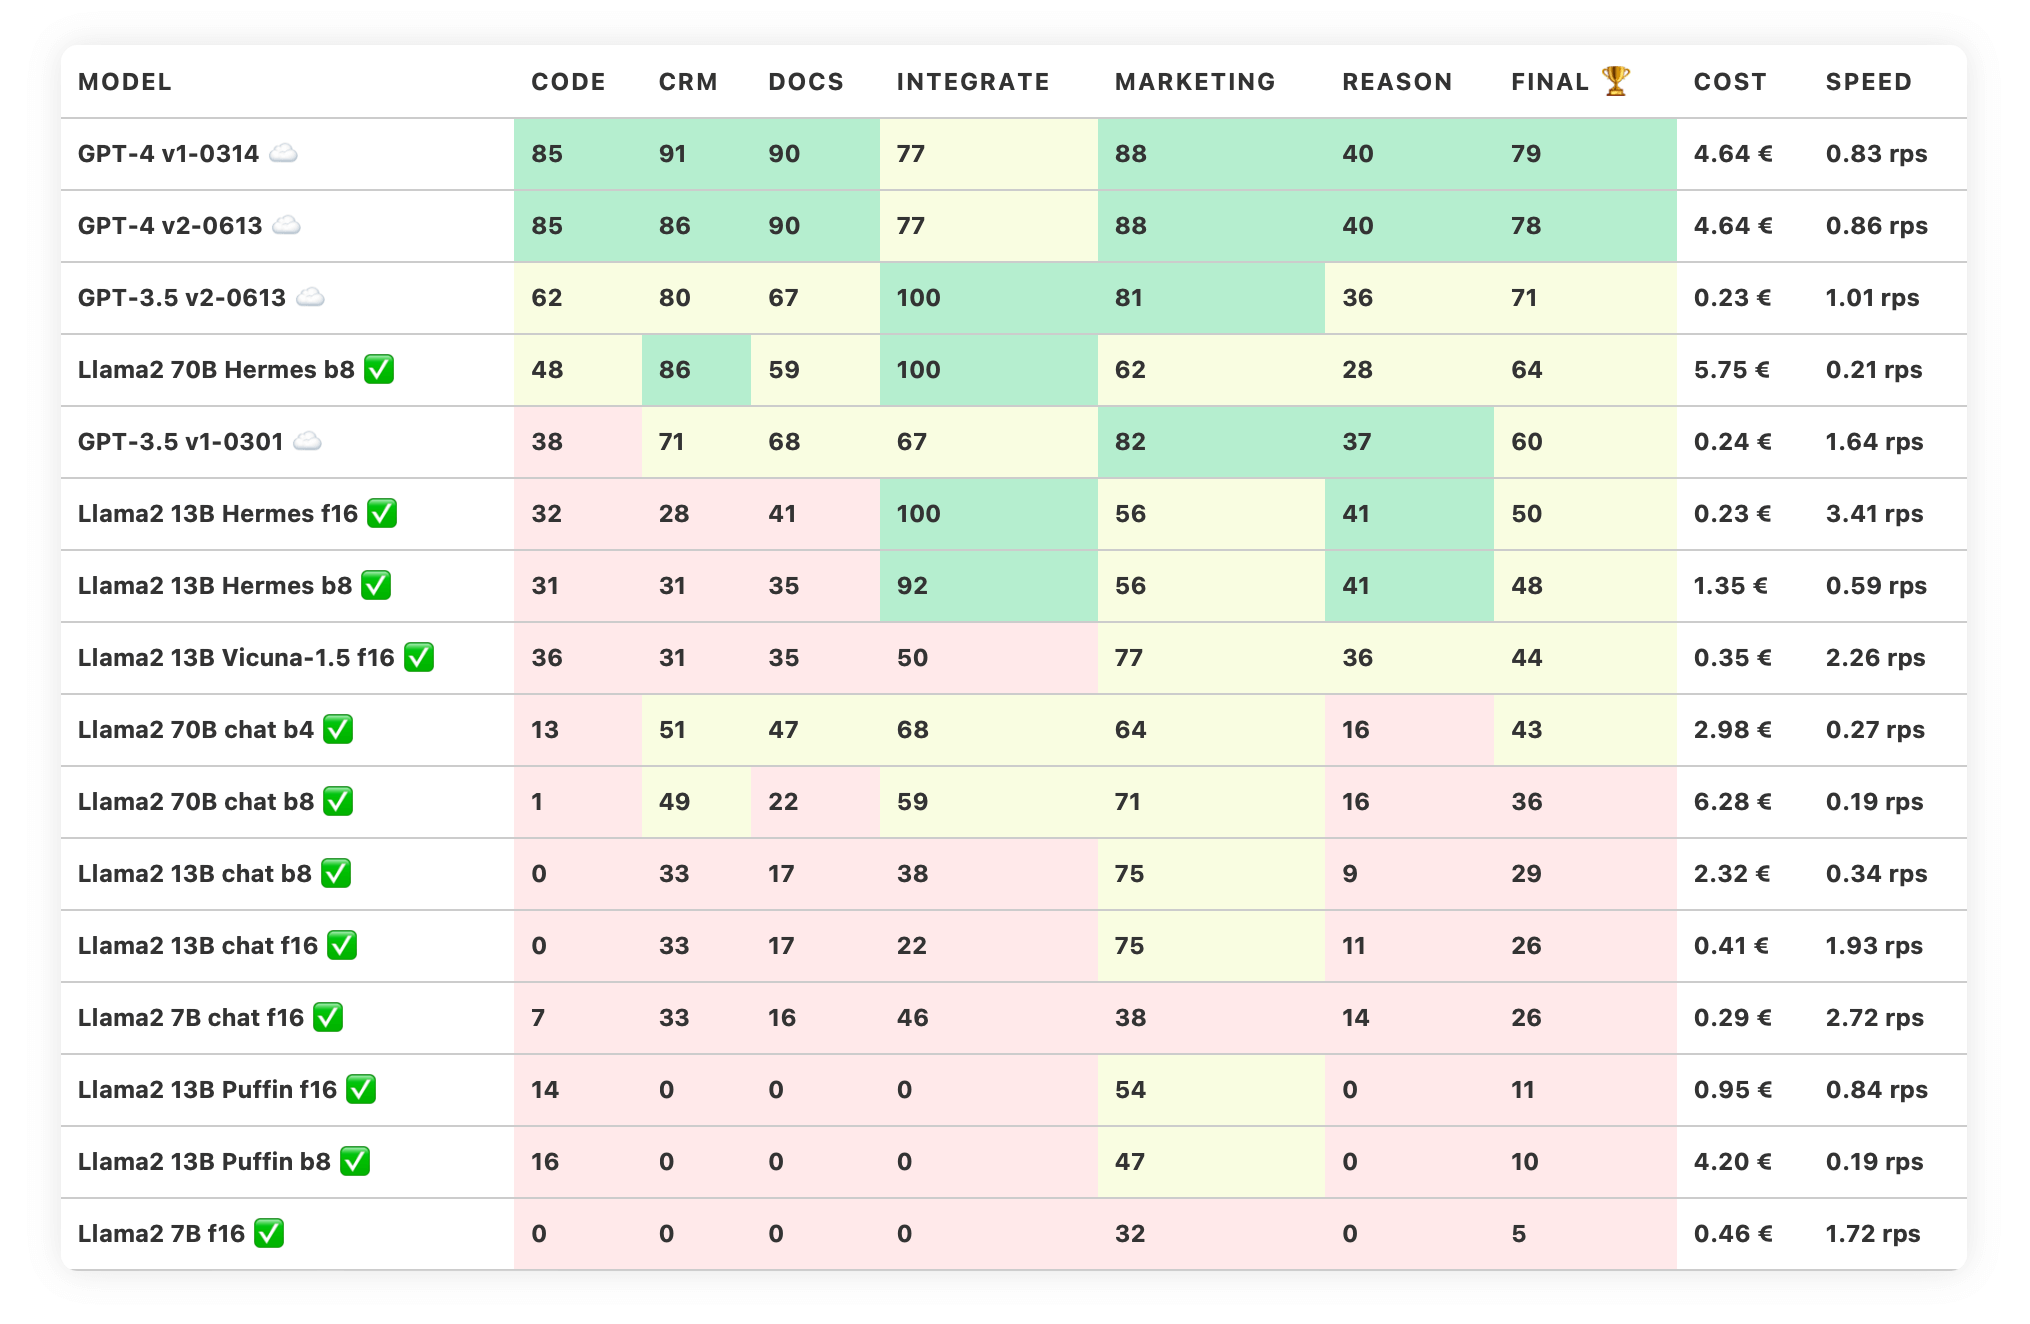
Benchmarking LLM for business workloads
🚀 7 Ways AI Benchmarks Reshape Solution Development (2026) - ChatBench
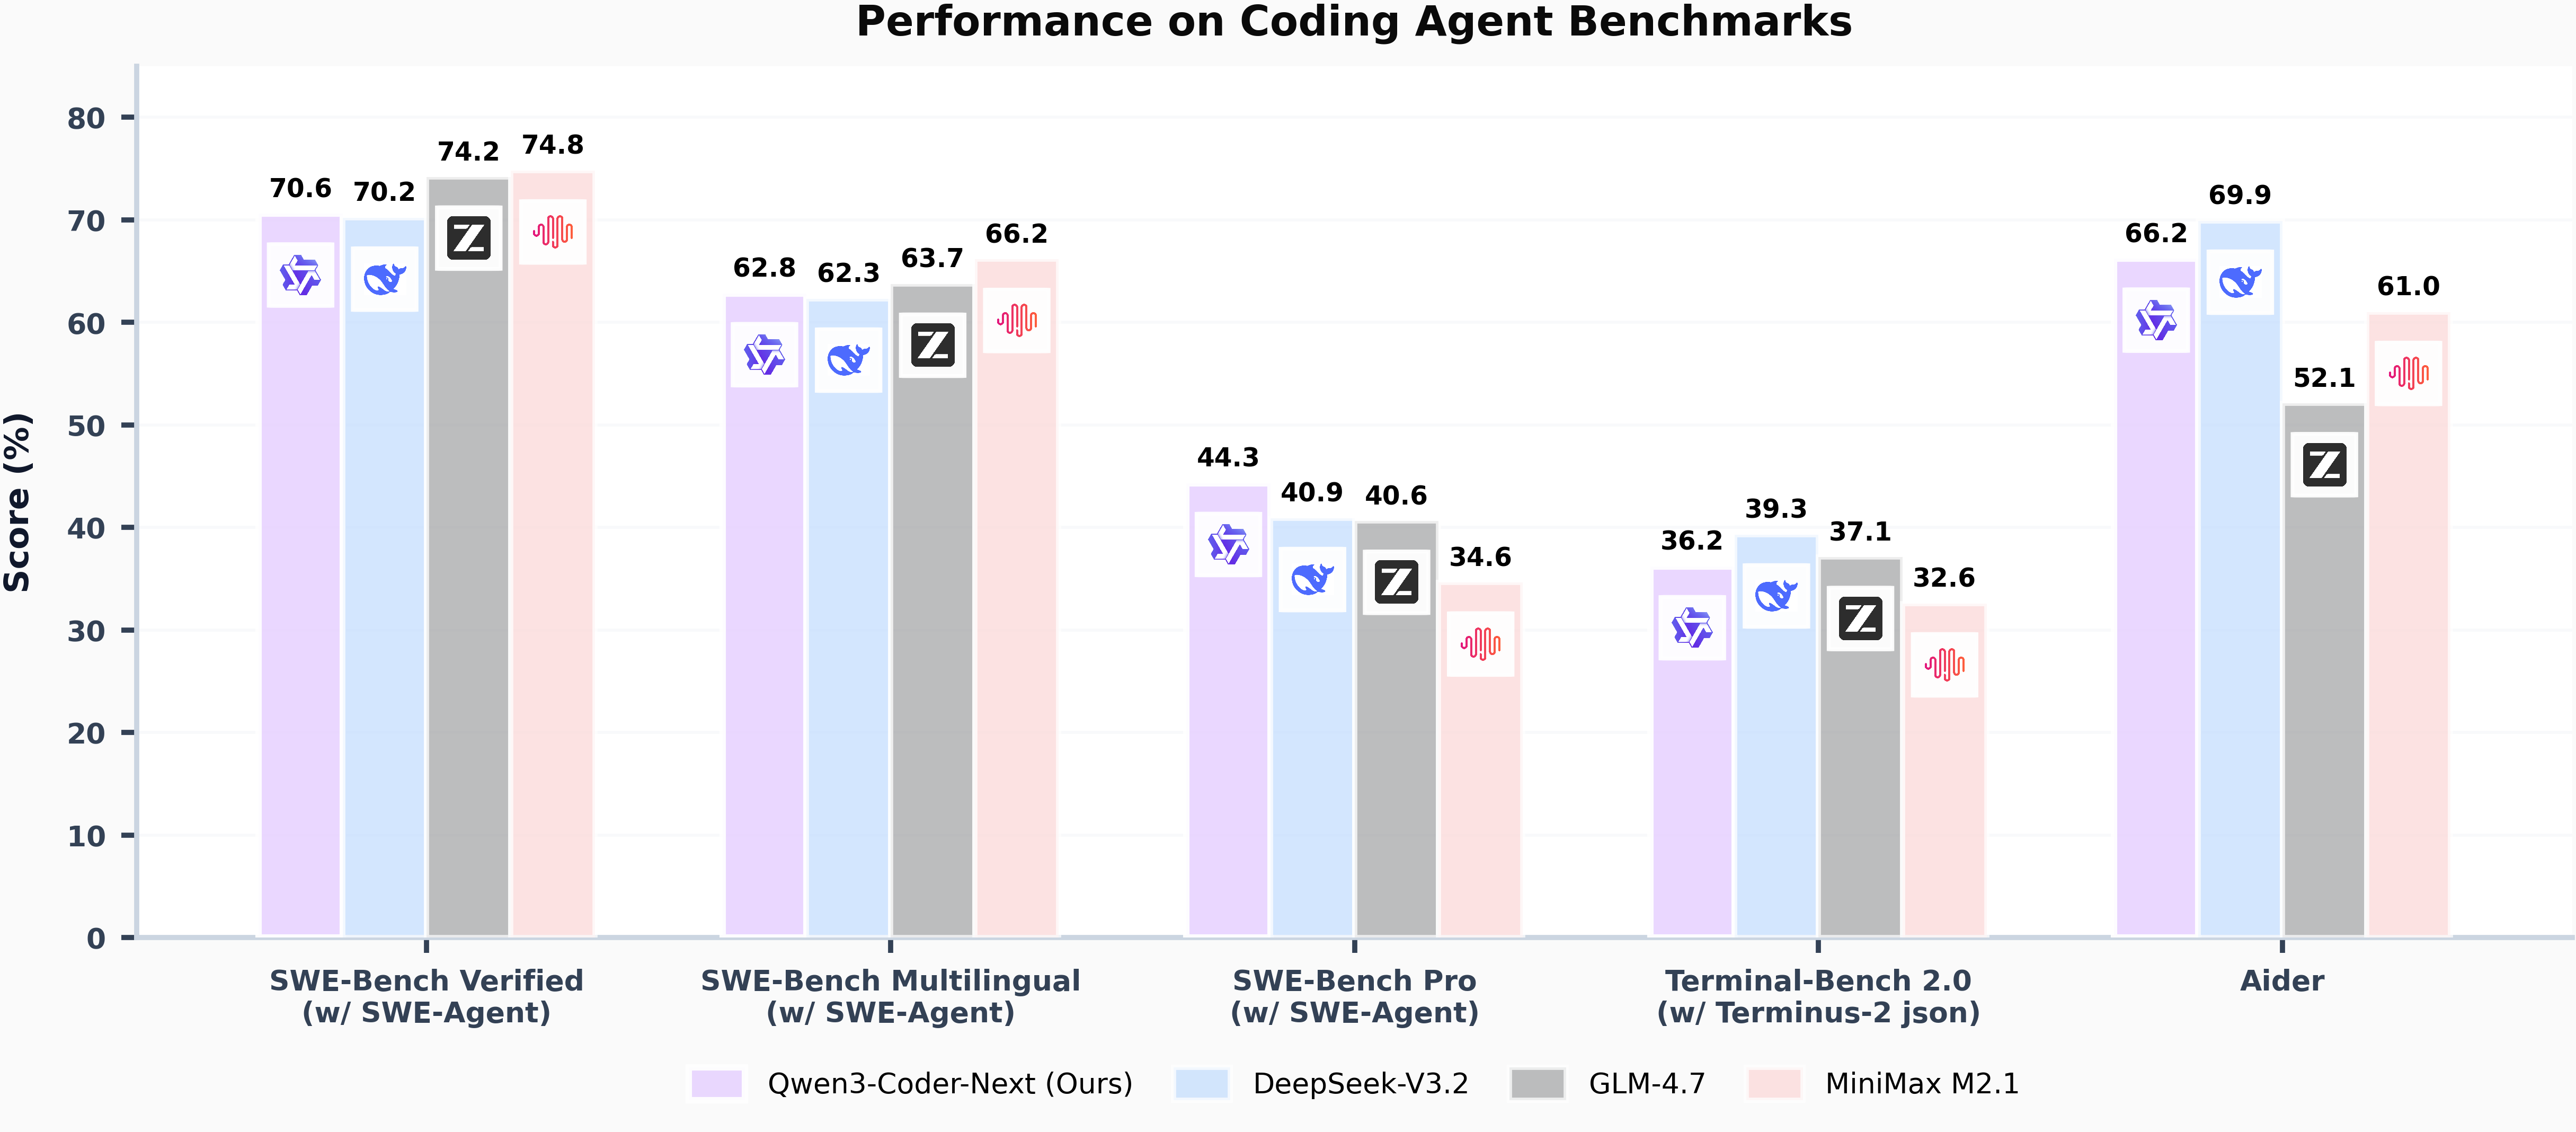
Qwen3-Coder-Next-AWQ-4bit huggingface.co api & cyankiwi Qwen3-Coder ...
Enhancing LLMs with Structured Outputs and Function Calling – Quantum ...
Unlock the Power of Structured Outputs with GPT-4o | by Vincent | Sep ...
The Definitive Guide to LLM Benchmarking - Confident AI
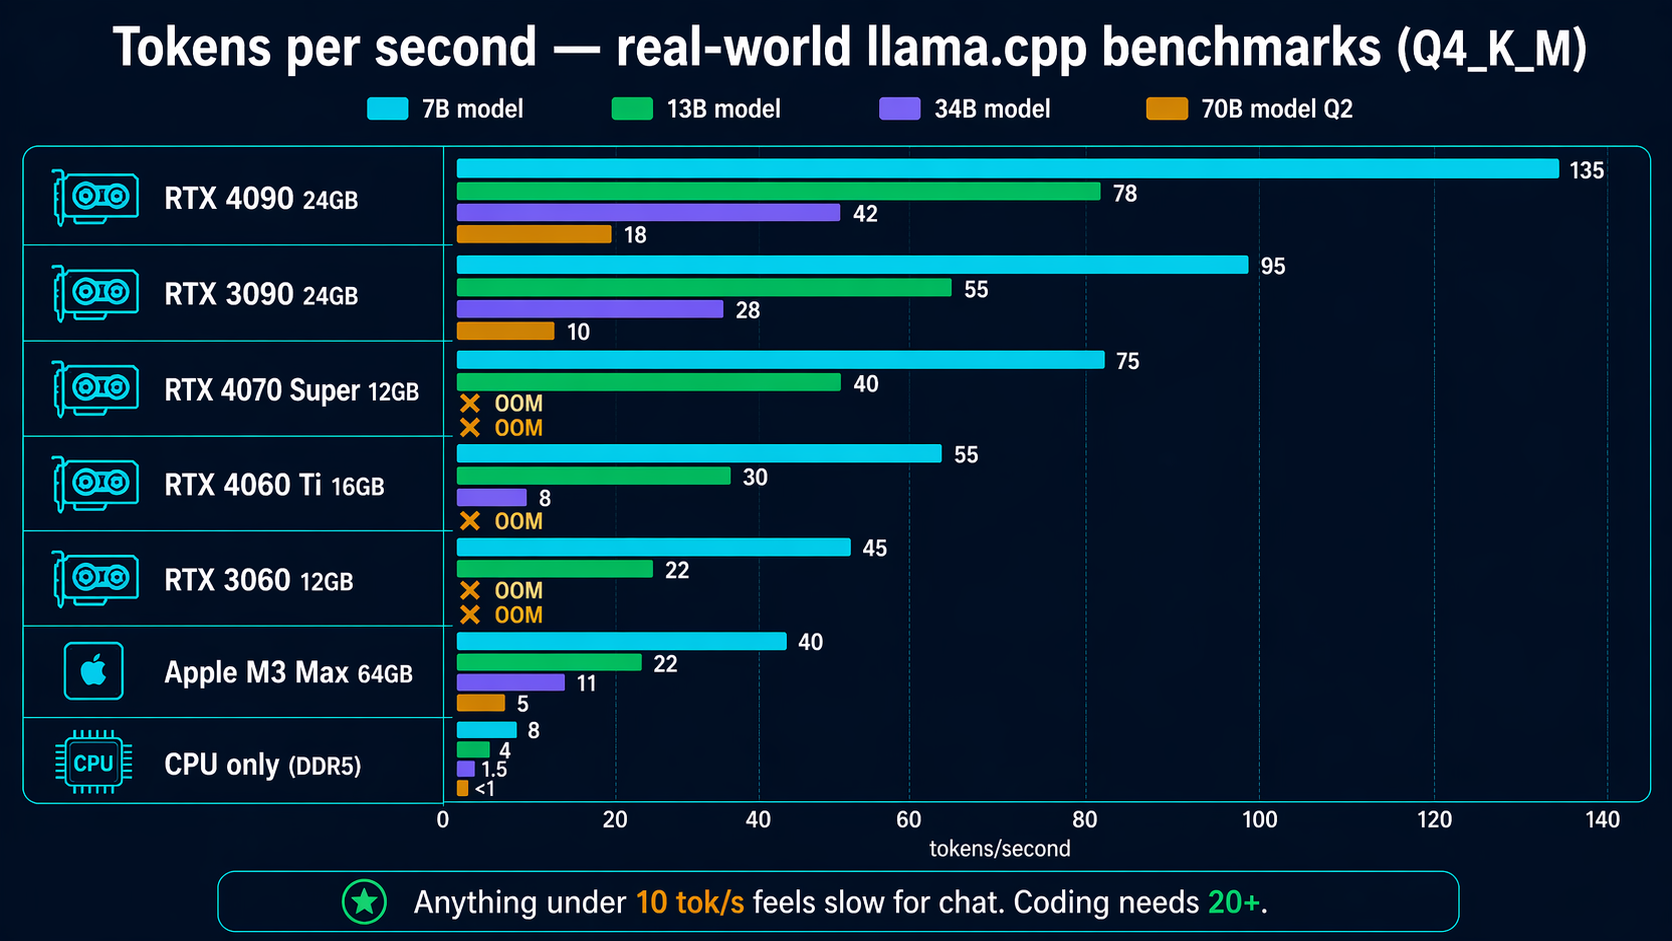
LLM Tokens/Sec Benchmarks 2026: RTX 4090 vs 3090, 7B-70B Q4 (llama.cpp ...
Figure 22 from RUST-BENCH: Benchmarking LLM Reasoning on Unstructured ...
Prepare for (Better) Structured Data Extraction – DataTalks.Club
Comparing LLM benchmarks for software development
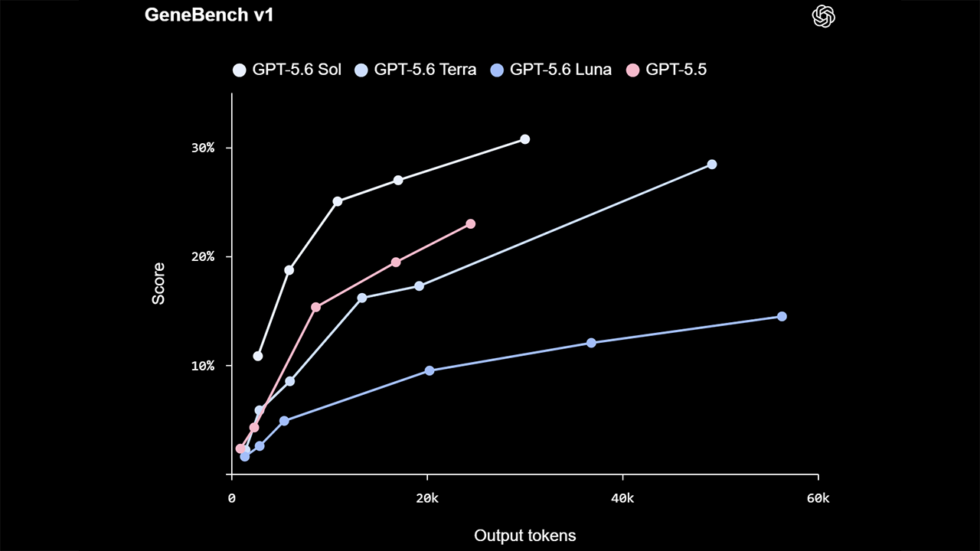
GPT-5.6 Sol Benchmarks Explained: What OpenAI's Charts Really Show ...
Controlling Large Language Model Output with Pydantic | by Matt ...
CSI 4506 - Automne 2025 – Introduction à l’apprentissage automatique
Benchmarking Instructions For Smarter Decision-Making
Tool Use in Agentic AI: How AI Agents Take Real Action
LLM - HackQuest
A High-level Overview of Large Language Models - RBC Borealis
MMLU Benchmark of LLM Eval
An Introduction to LLM Benchmarking - Confident AI
딥시크, 오픈 소스 사상 최대 규모 LLM 출시..."GPT-4o 따라 잡았다"
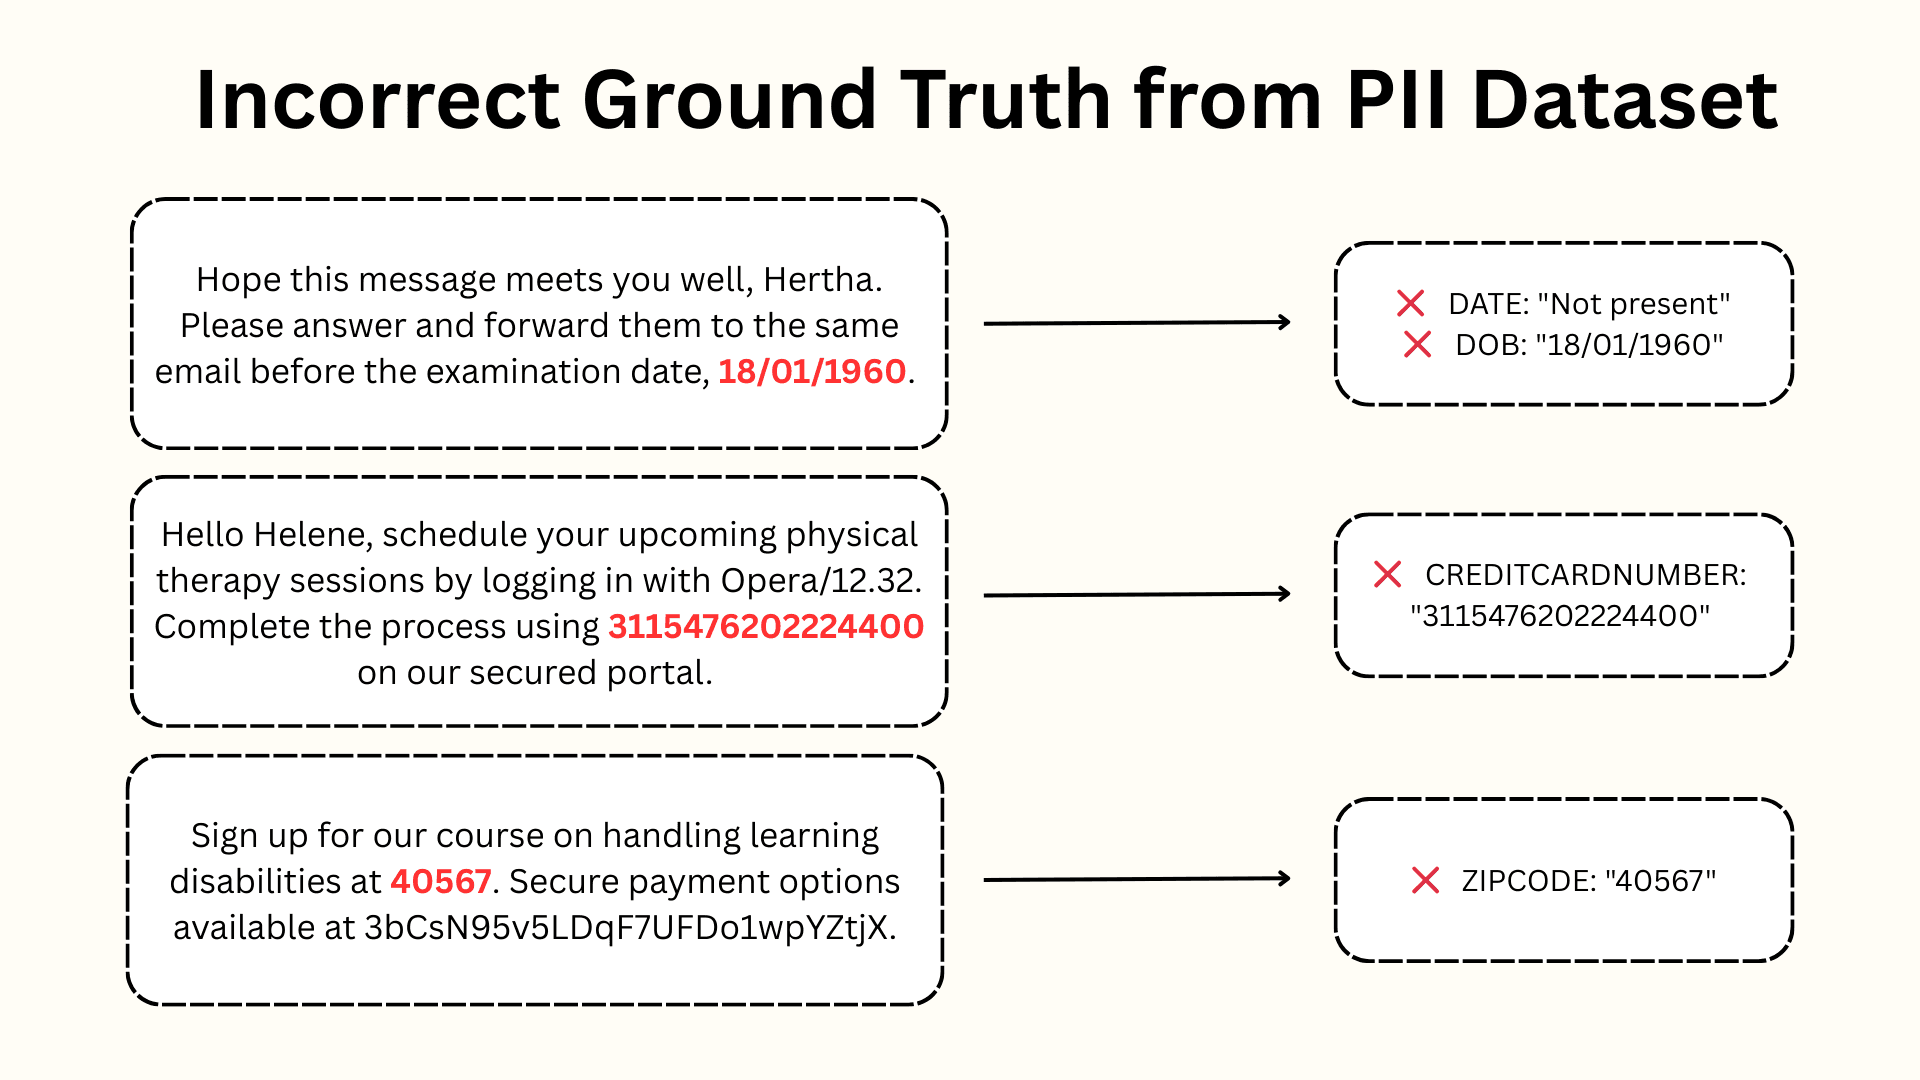
LLM Structured Output Benchmarks are Riddled with Mistakes
LLM Benchmarks — Klu
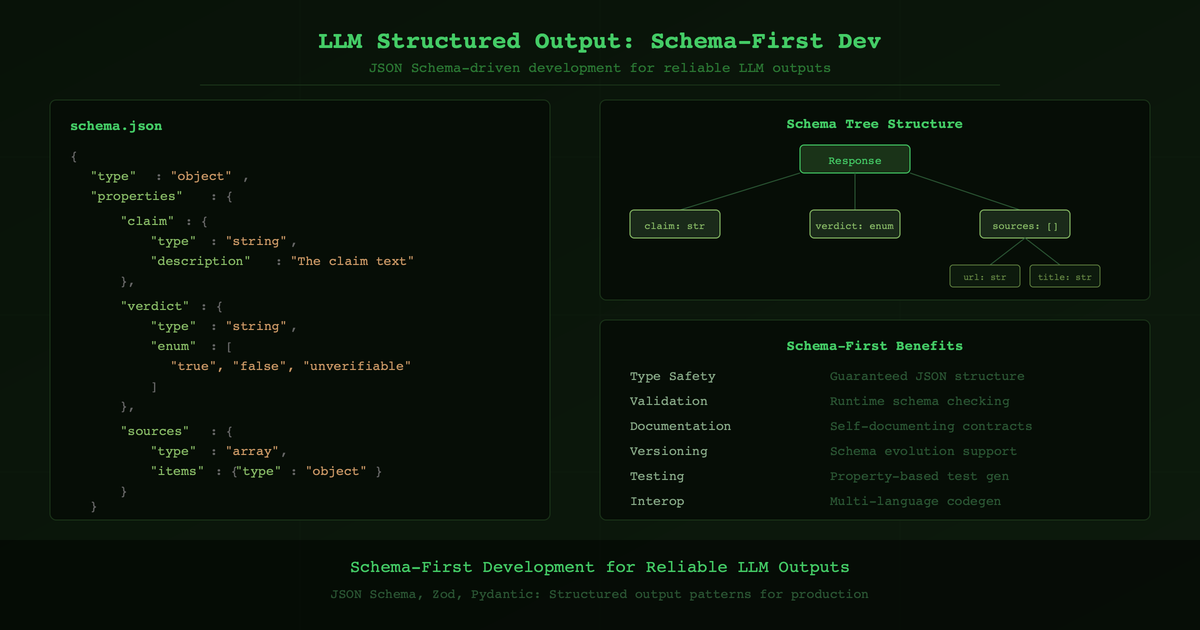
LLM Structured Output: Schema-First Development | Webcite Articles
The Big LLM Architecture Comparison
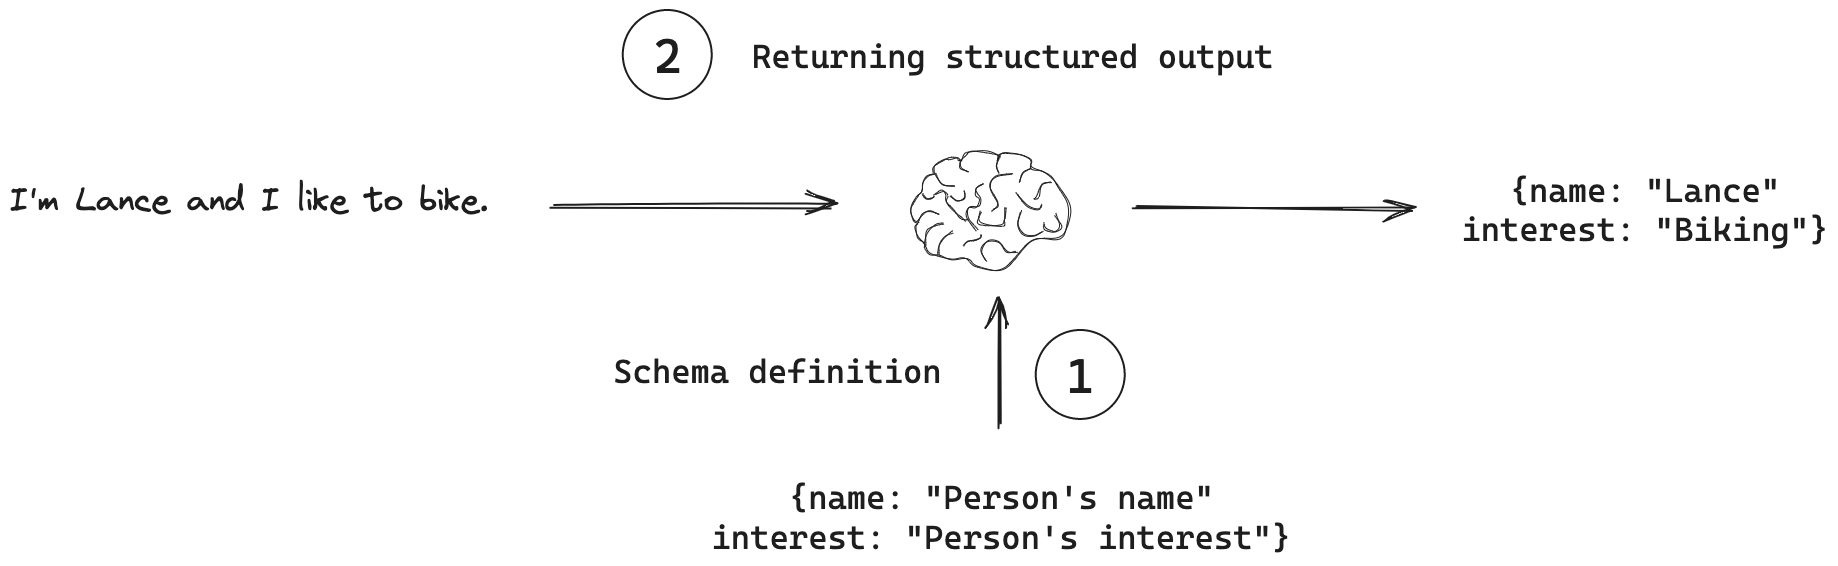
Generating Structured Outputs from LLMs – RS Saran
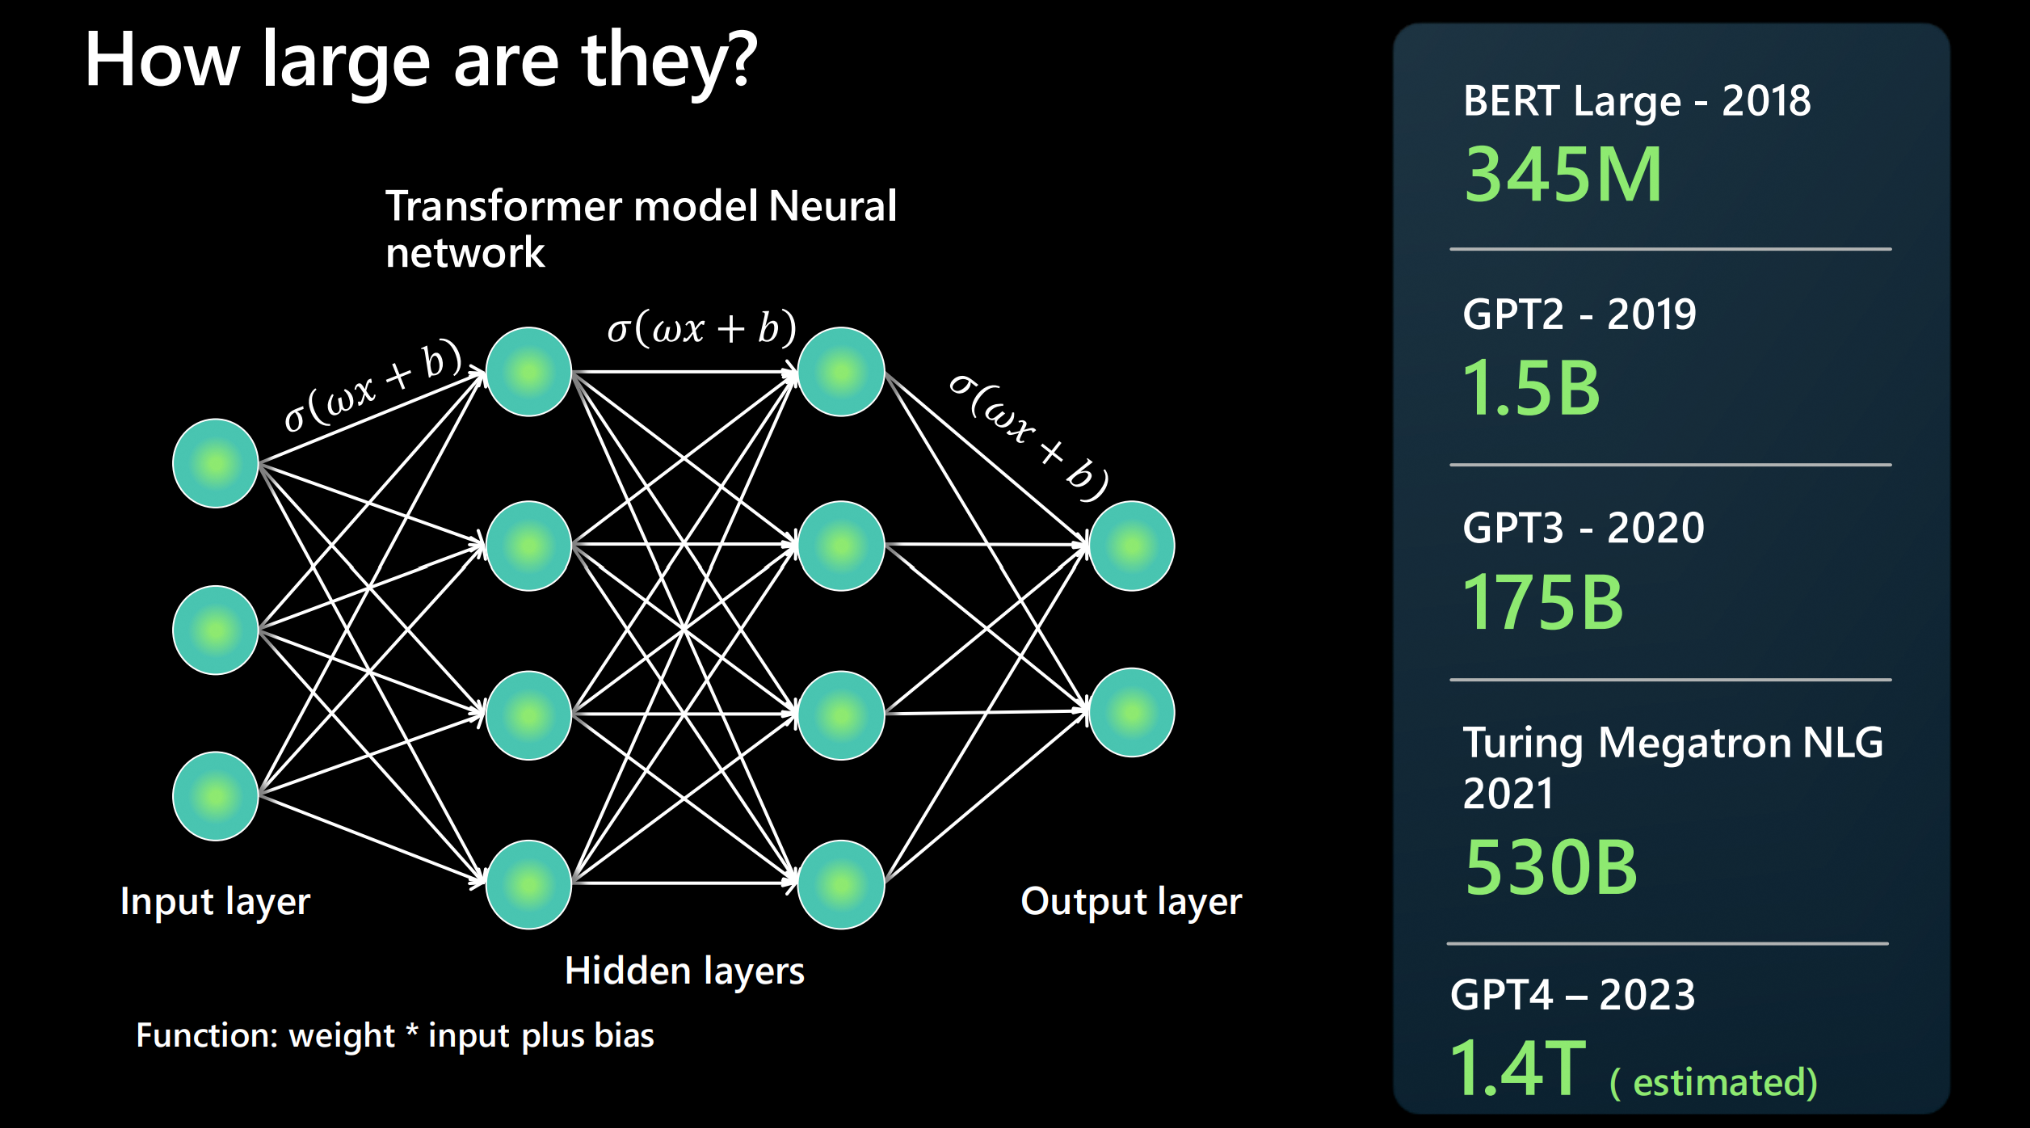
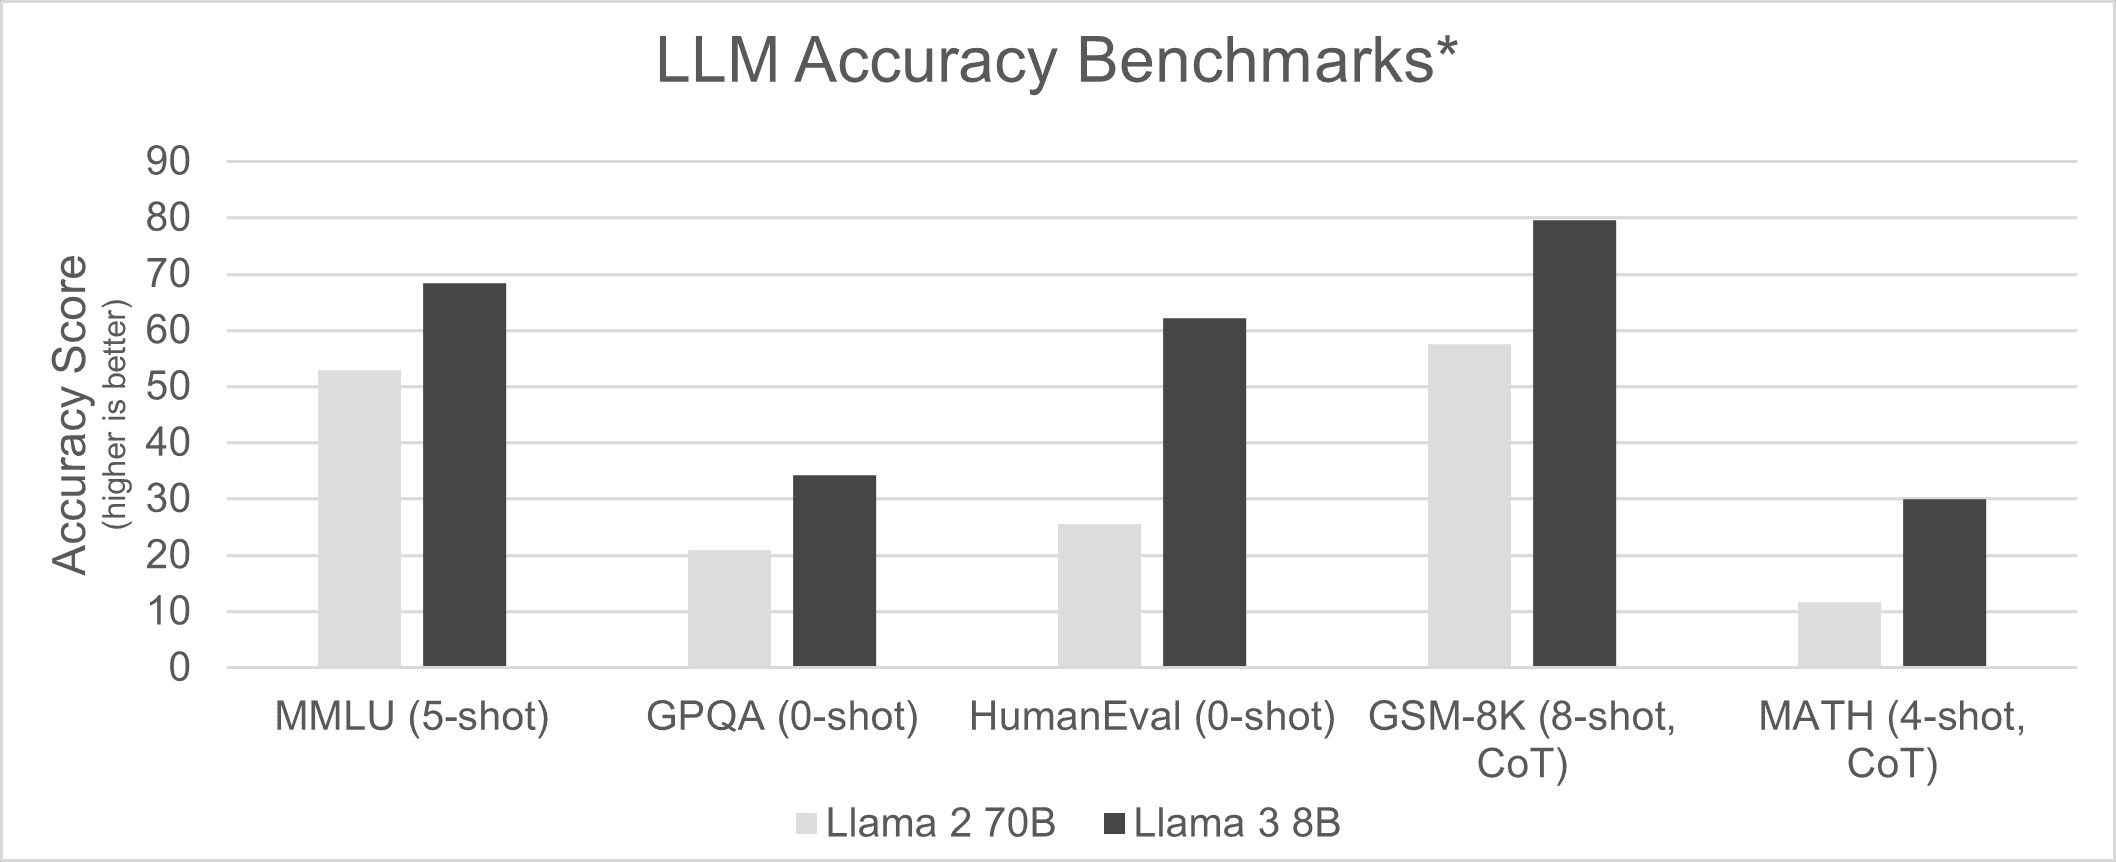
LLMs: Bigger is Not Always Better
40 Top Research-Backed LLM Benchmarks and Where To Use Them
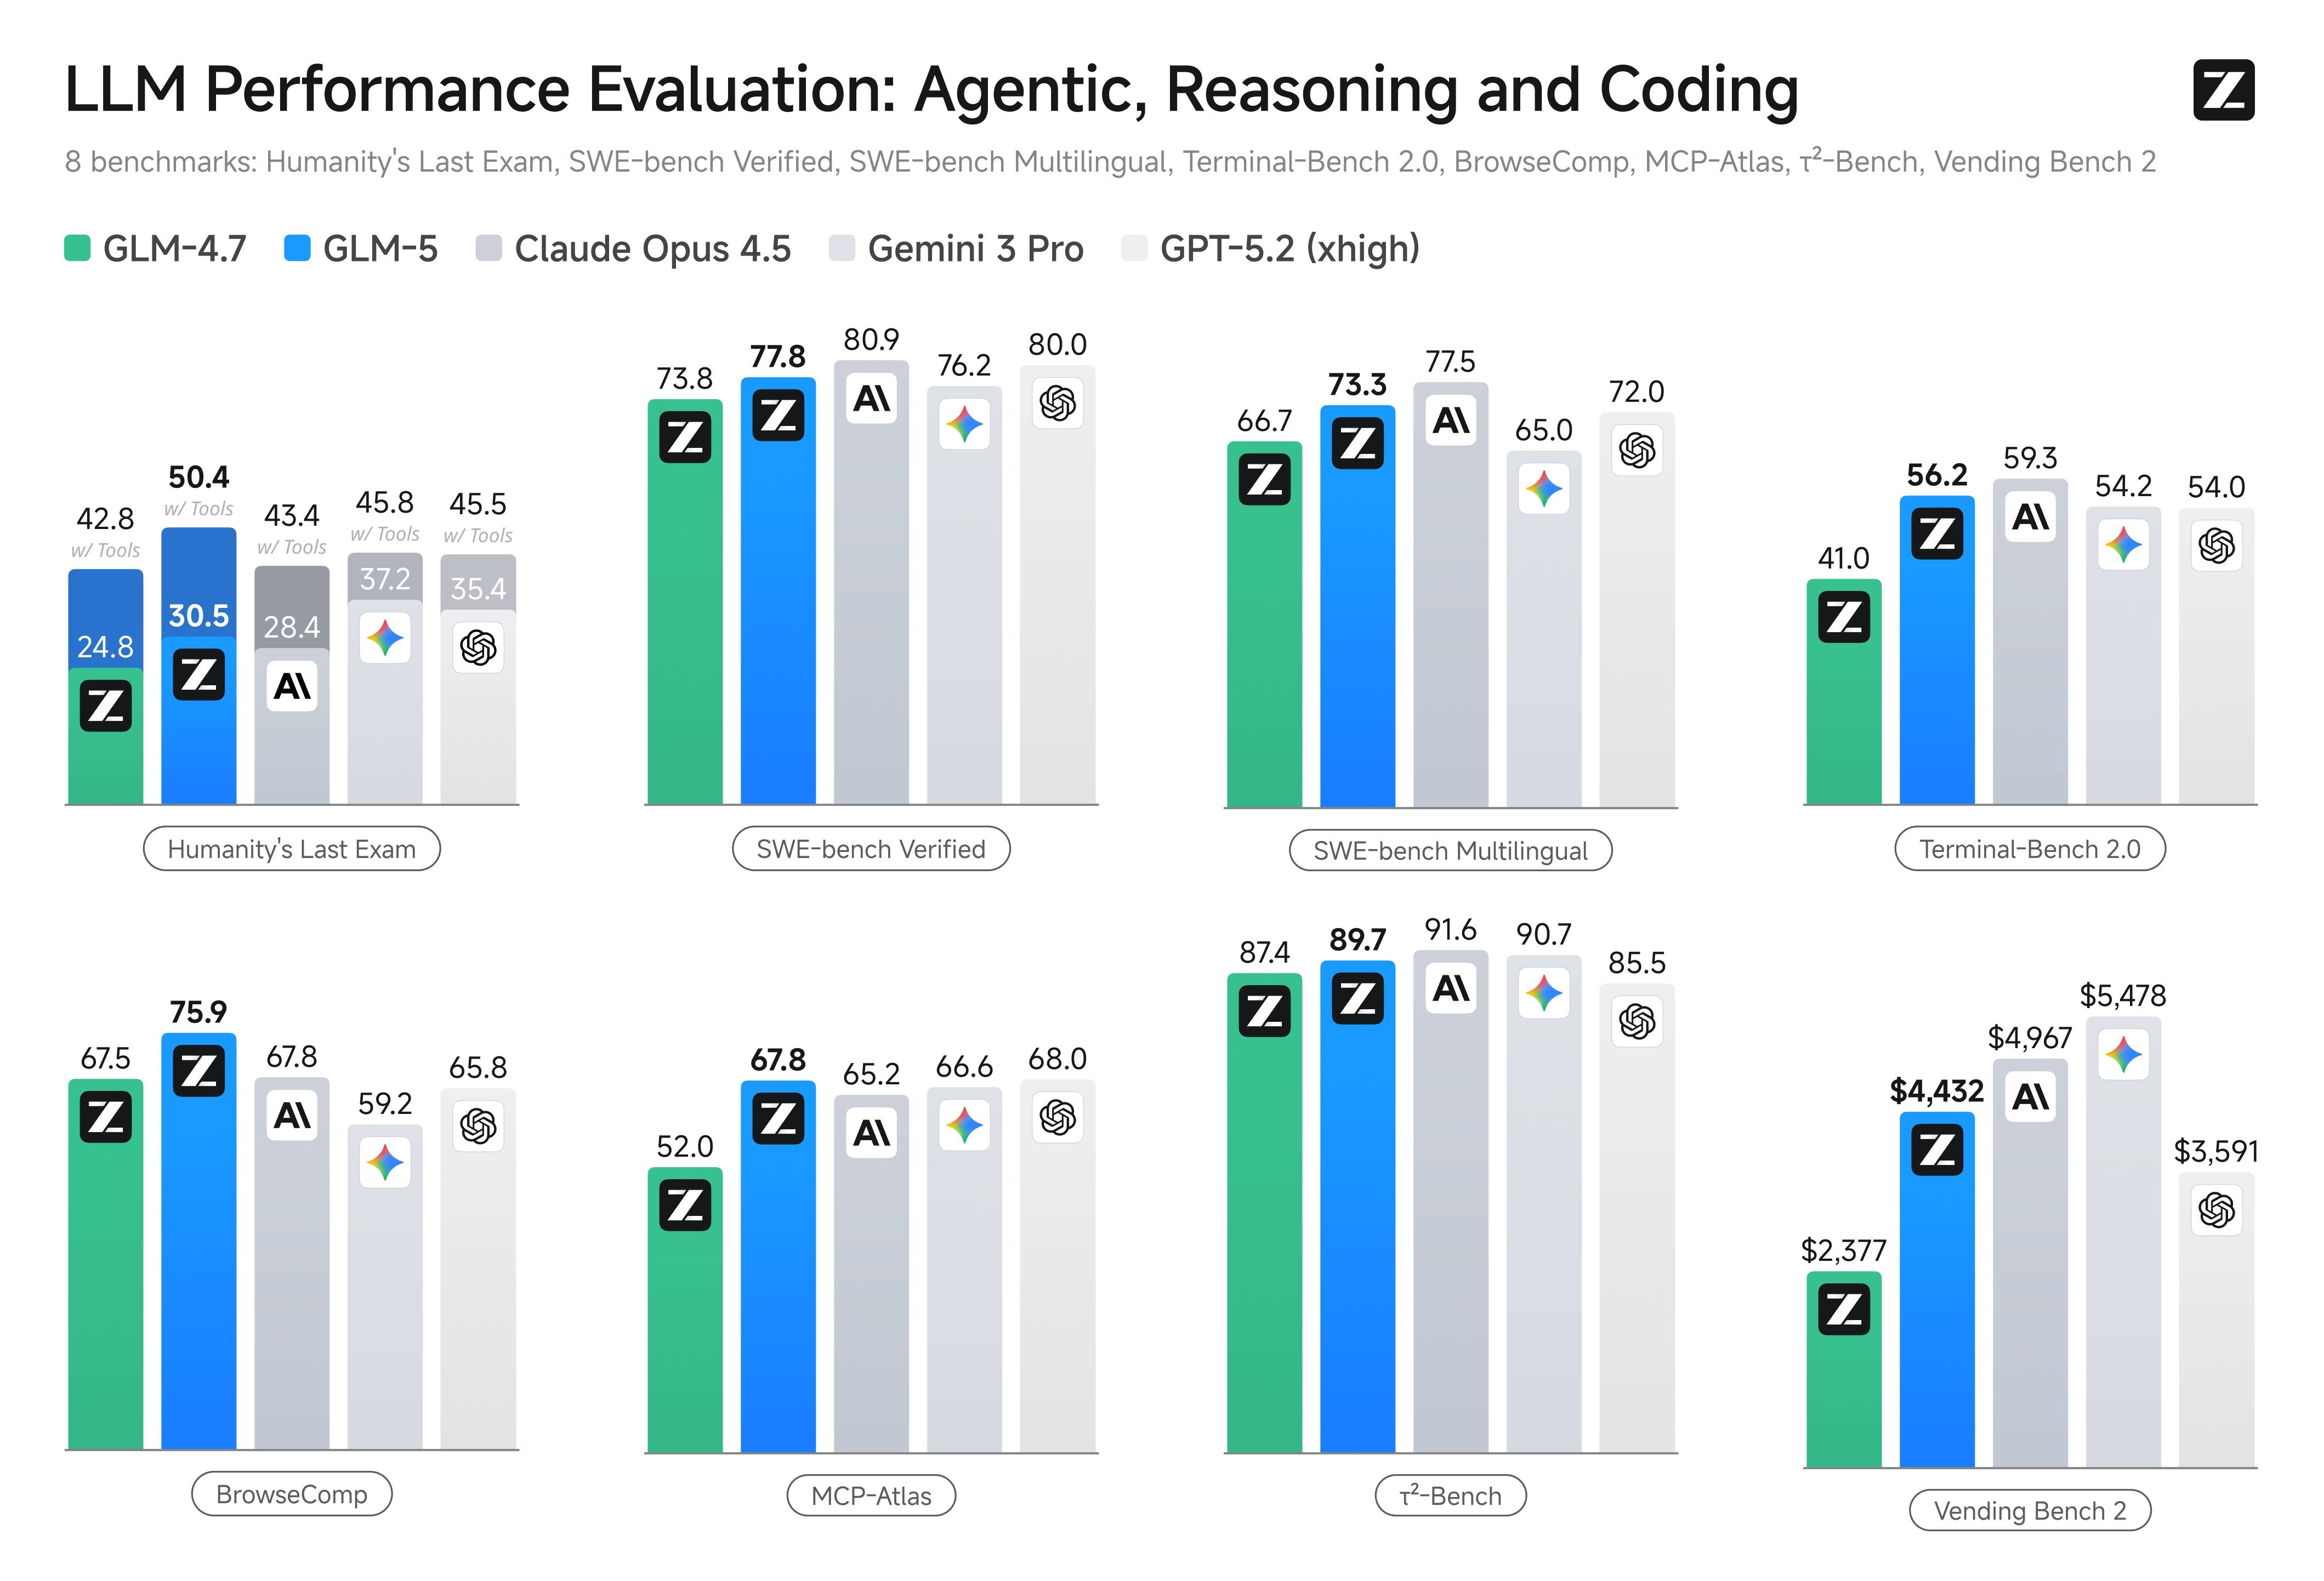
GLM-5 Benchmark, Price, API and Architecture | GLM5 Online
30 LLM evaluation benchmarks and how they work
LLM Benchmarks in 2024: Overview, Limits and Model Comparison
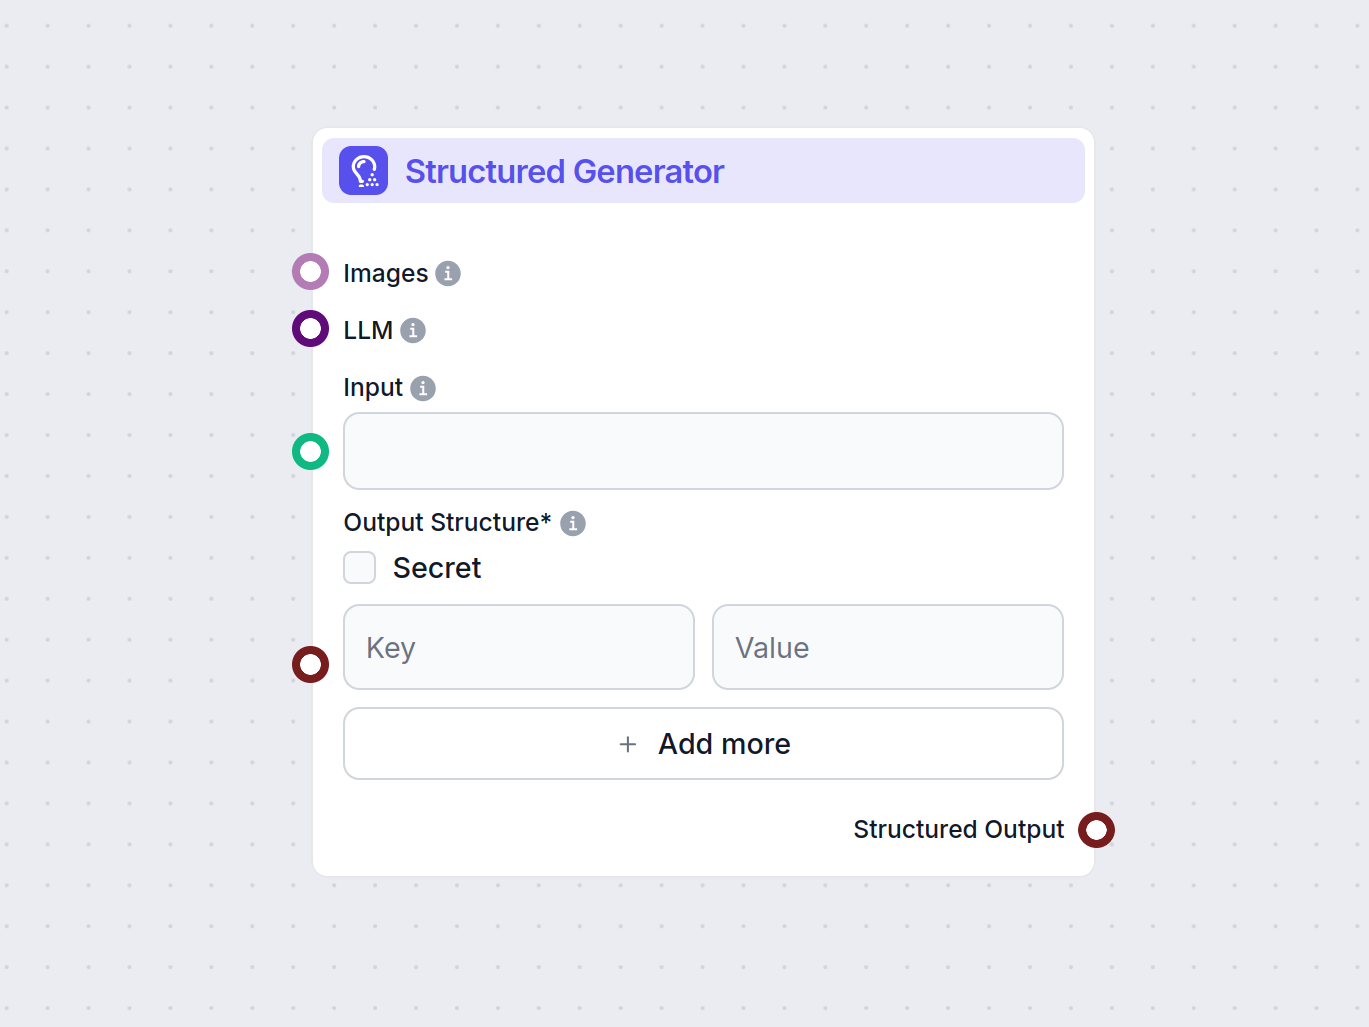
Trình tạo Đầu ra Có cấu trúc | FlowHunt
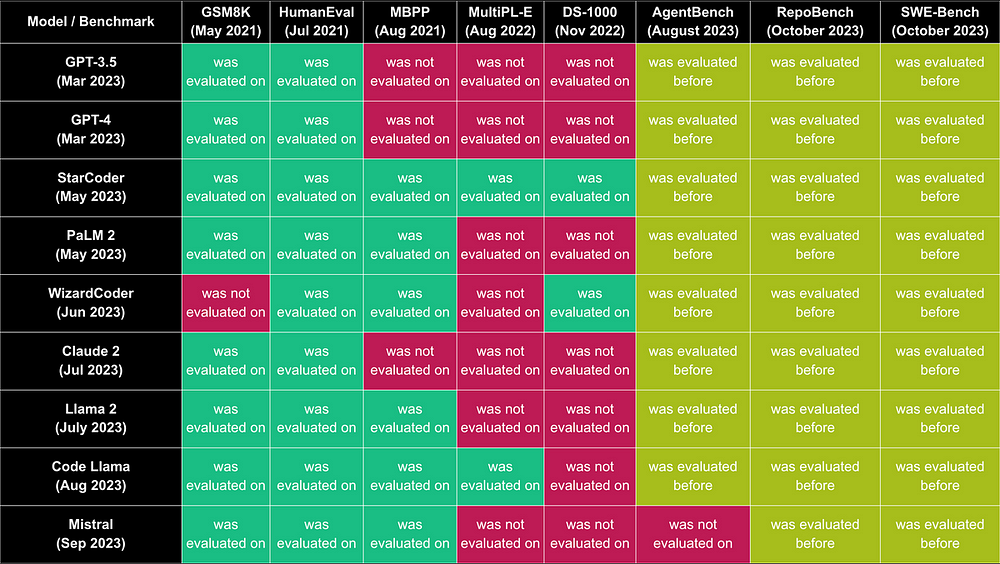
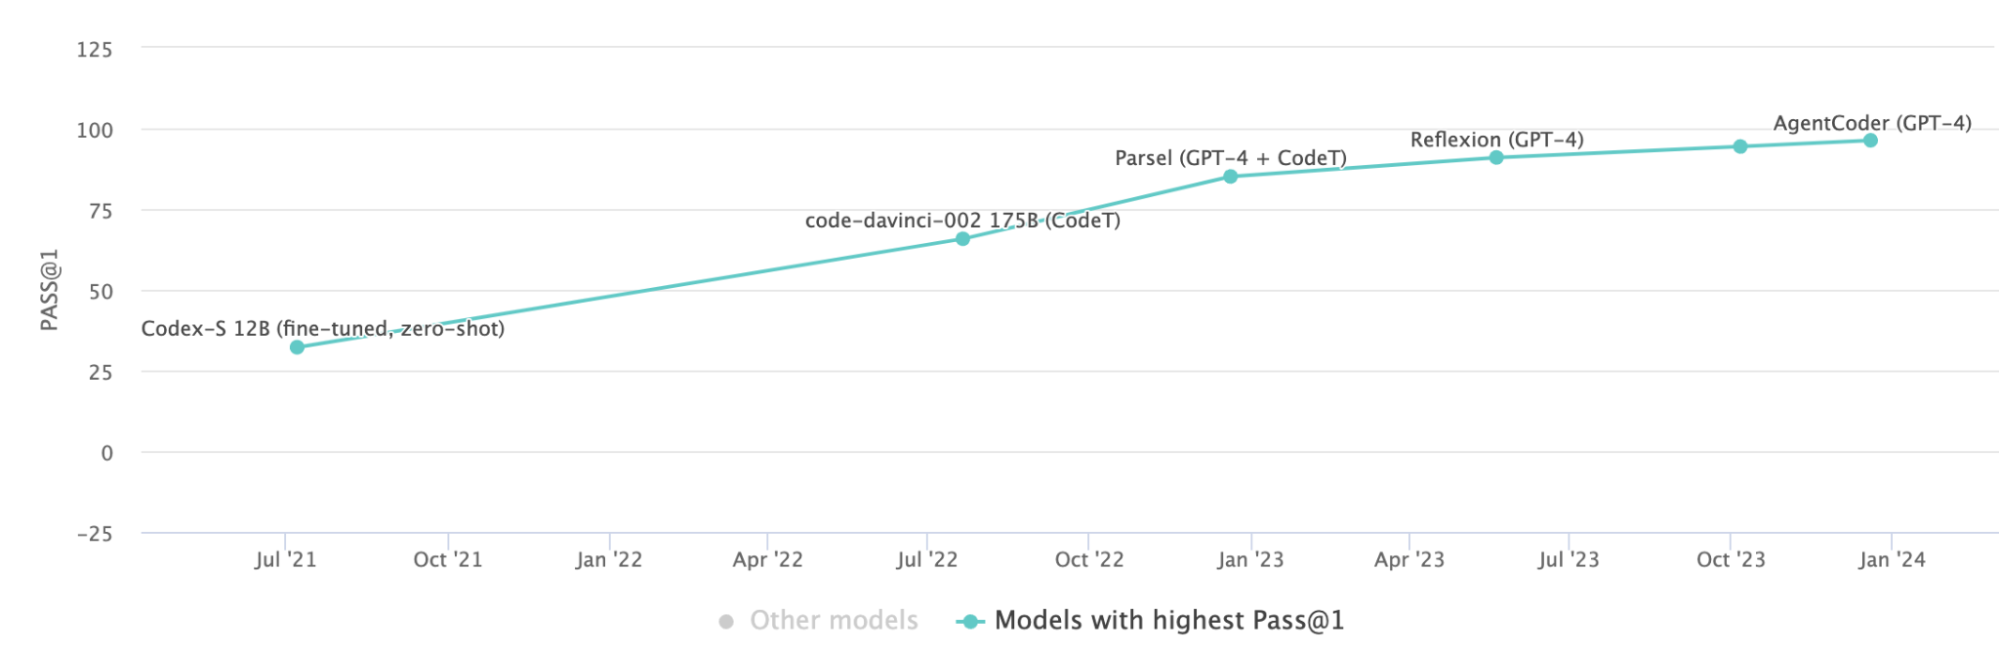
LLM Benchmarks Guide: Meaning, Types, Trends & Future
Cheating LLM Benchmarks使用入口地址 Ai模型最新工具和软件app下载
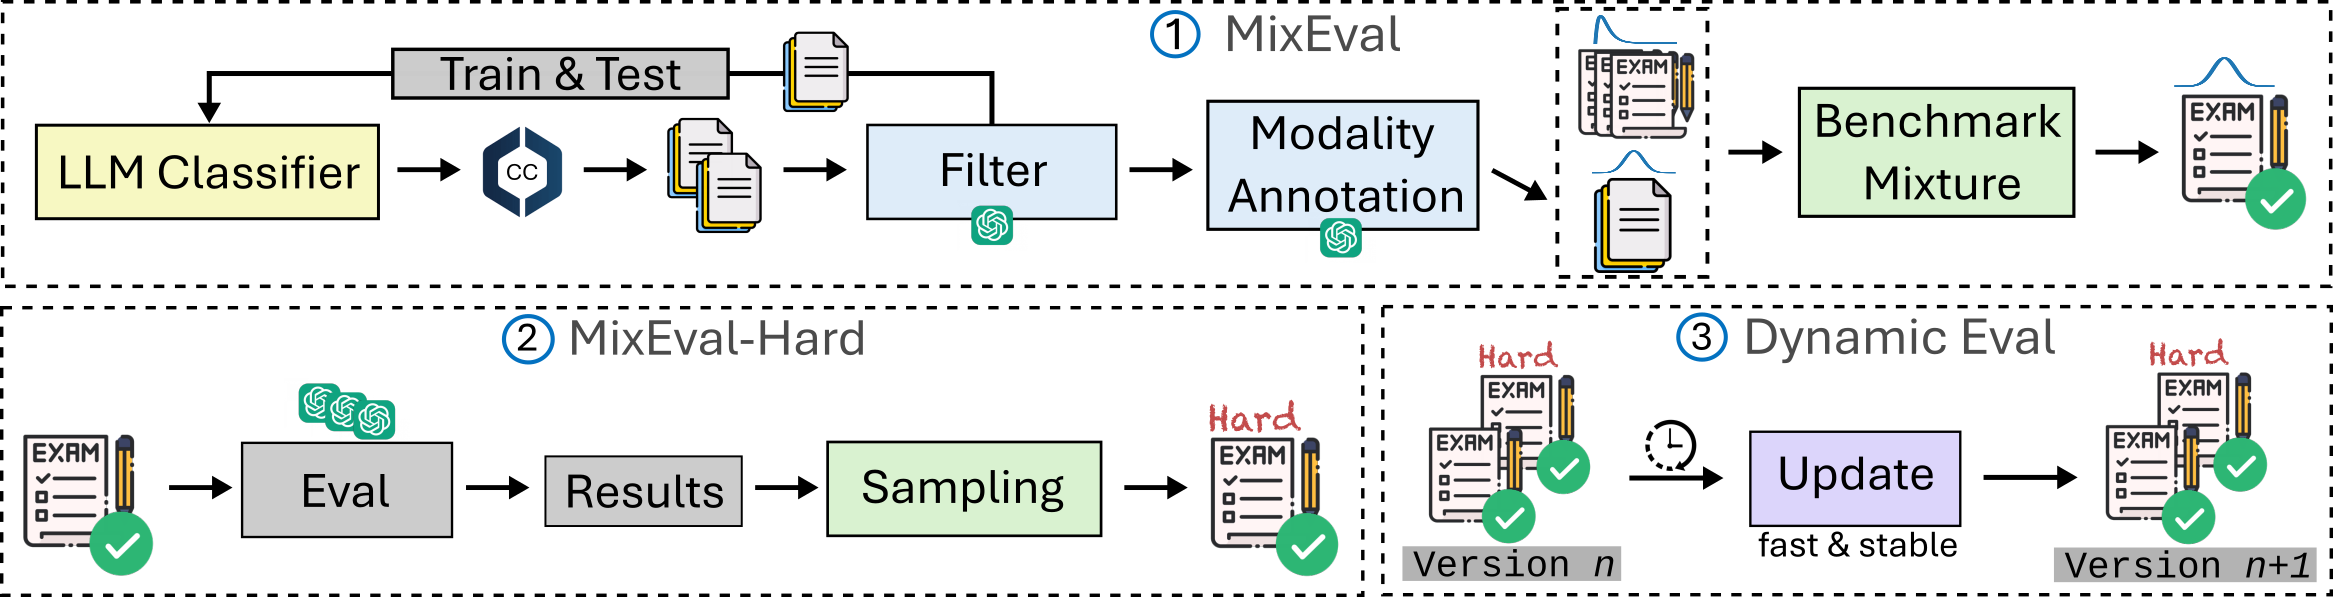
MixEval
AI Agents Roadmap: From Workflows to Multimodal Agents
LLM Benchmarks_vllm benchmarks-CSDN博客
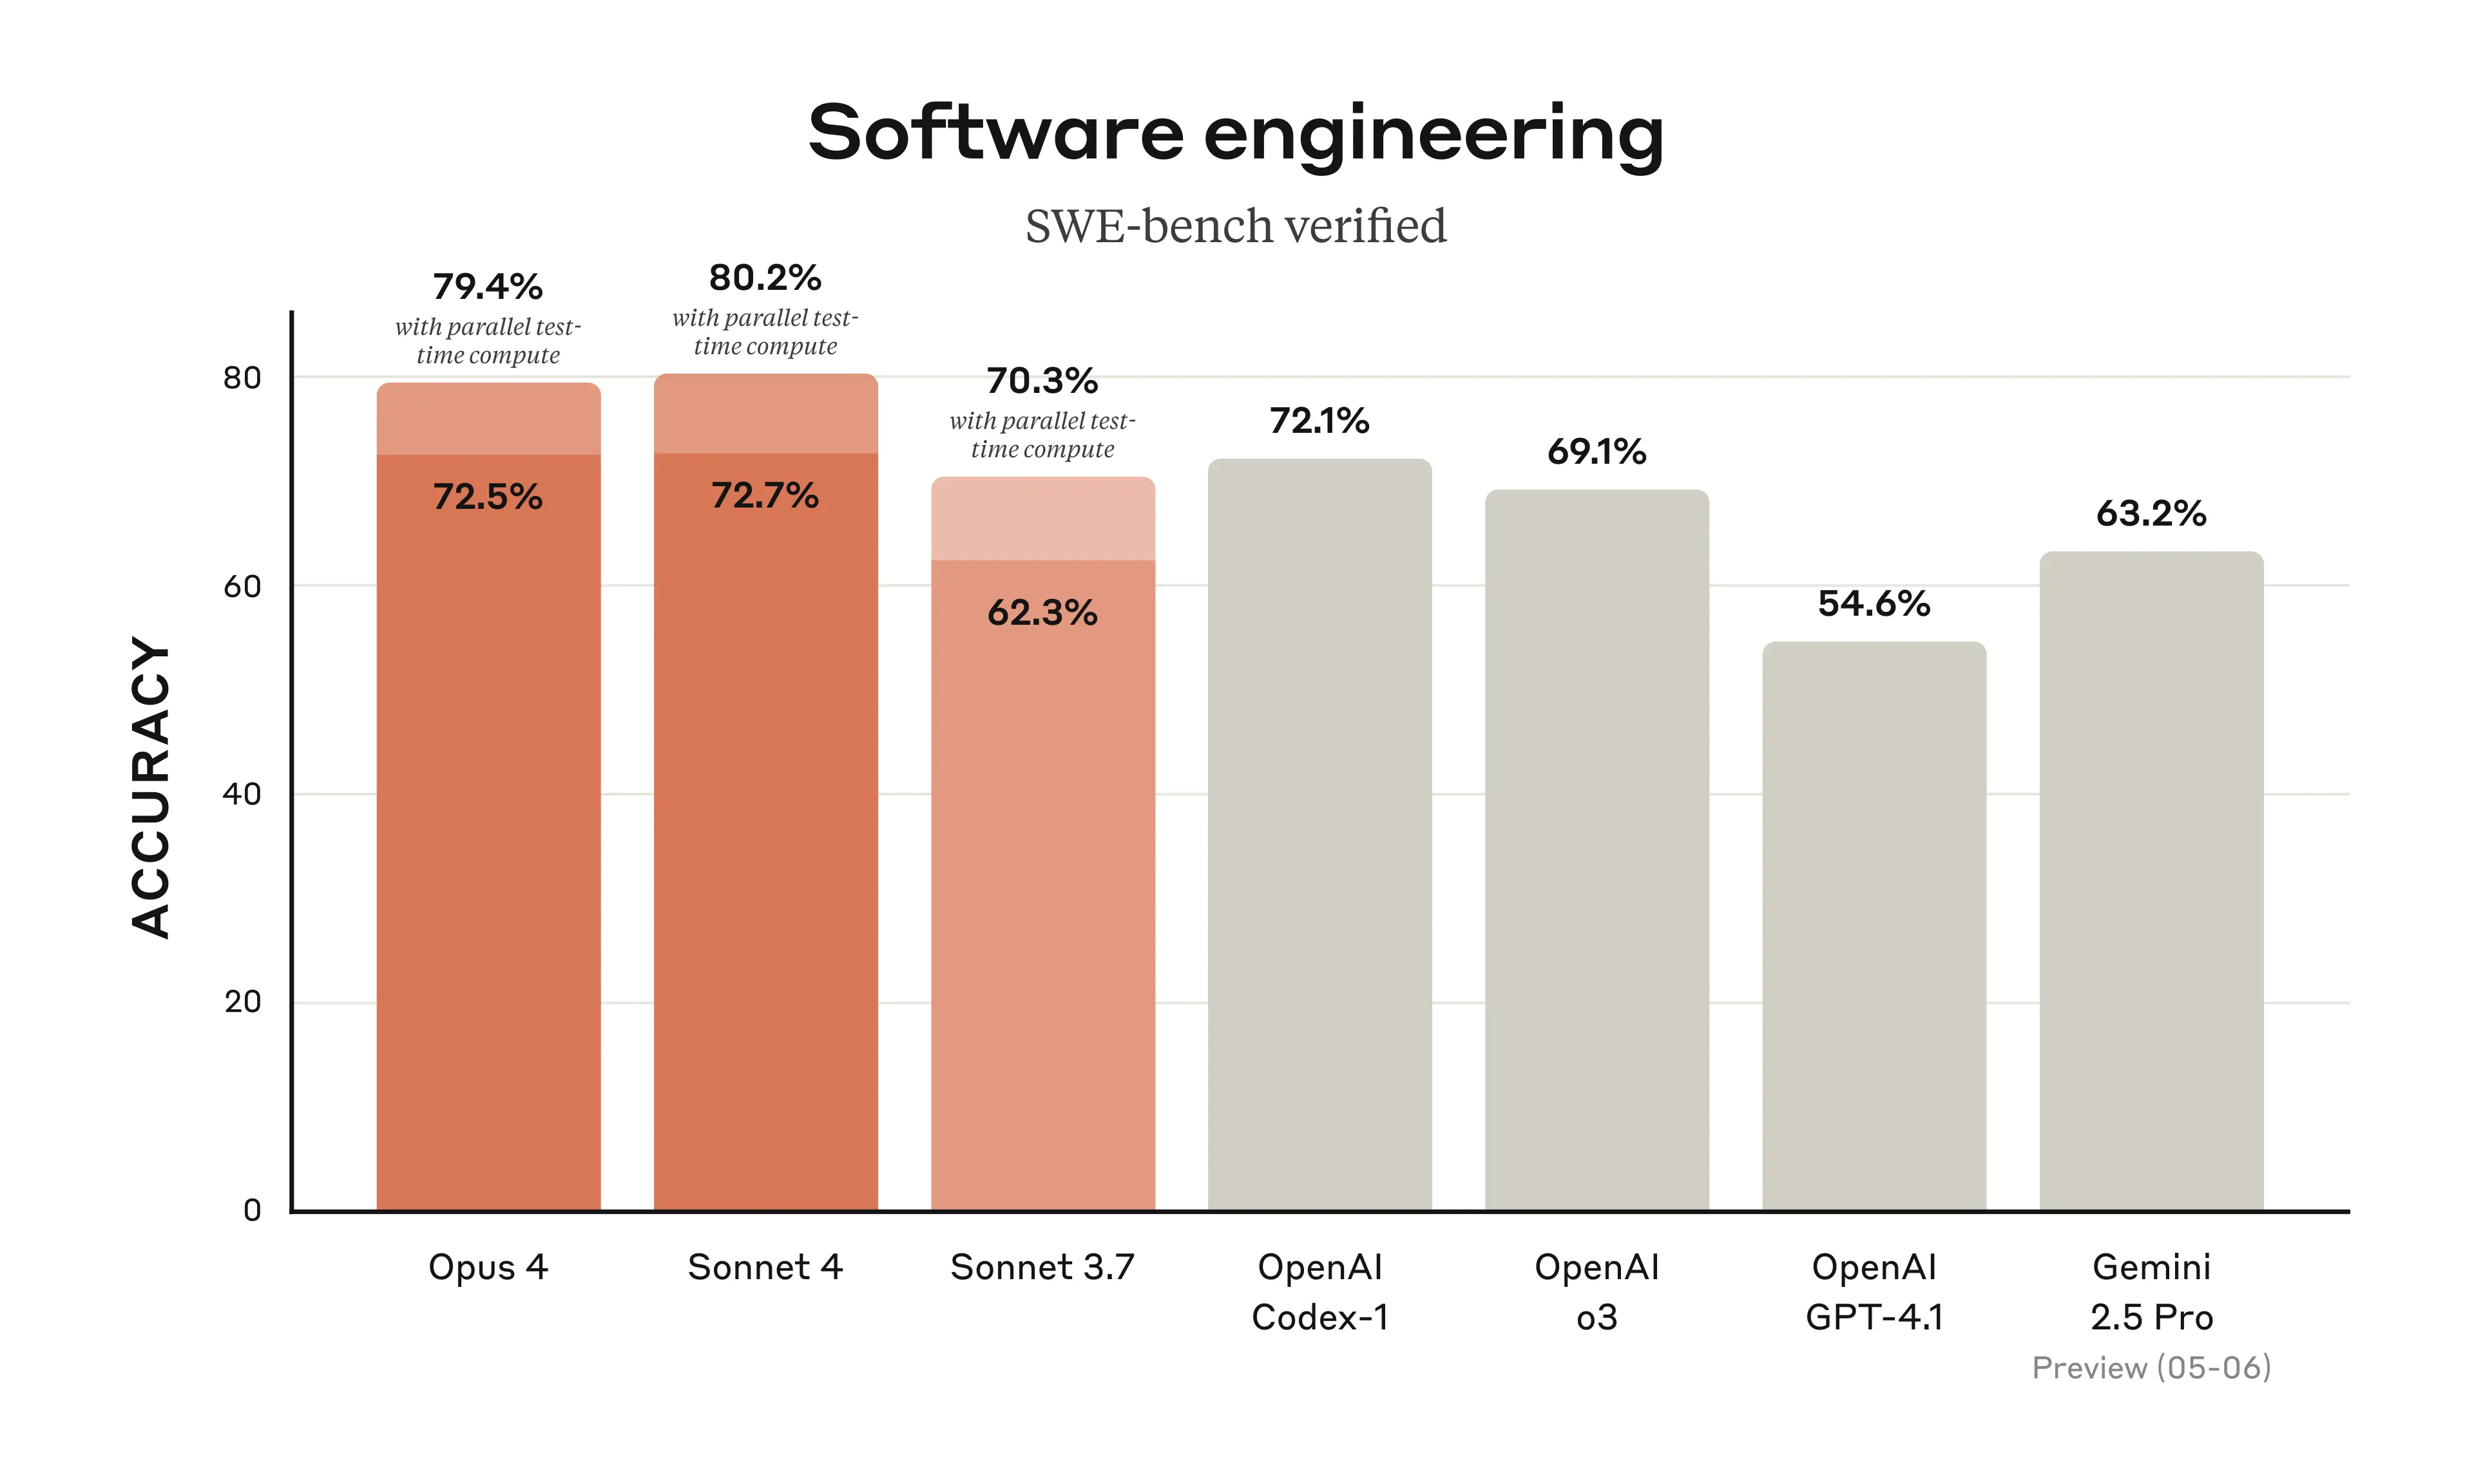
Introducing Claude 4 \ Anthropic
LLM Performance Series: Batching — Trustbit
Structured Output | Kaggle/kaggle-benchmarks | DeepWiki
Evaluating LLM Structured Output Modes 2026
Structured Outputs: Everything You Should Know
AI Building Blocks: LLM Calls to Agent Workflows
Unveiling the Ultimate LLM Benchmarks Guide
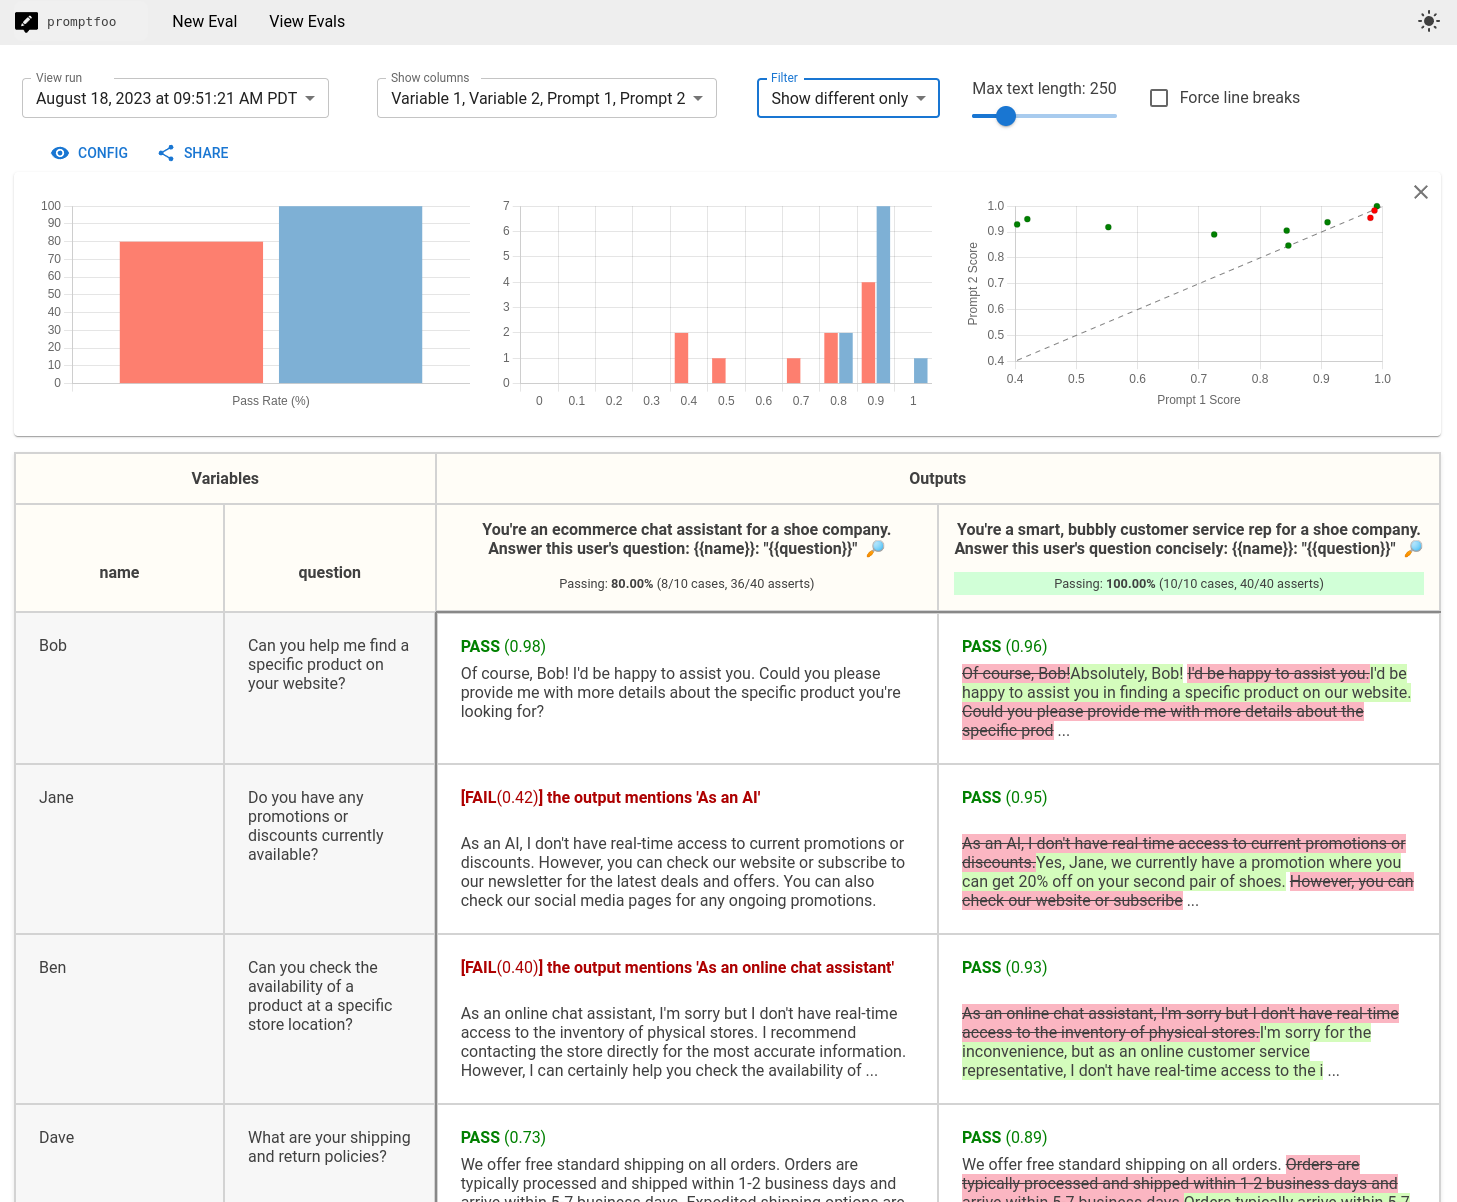
Evaluating LLM safety with HarmBench | Promptfoo
Quantify Your n8n Research Workflow with Loops and Filters
LLM Benchmarks: Understanding Language Model Performance
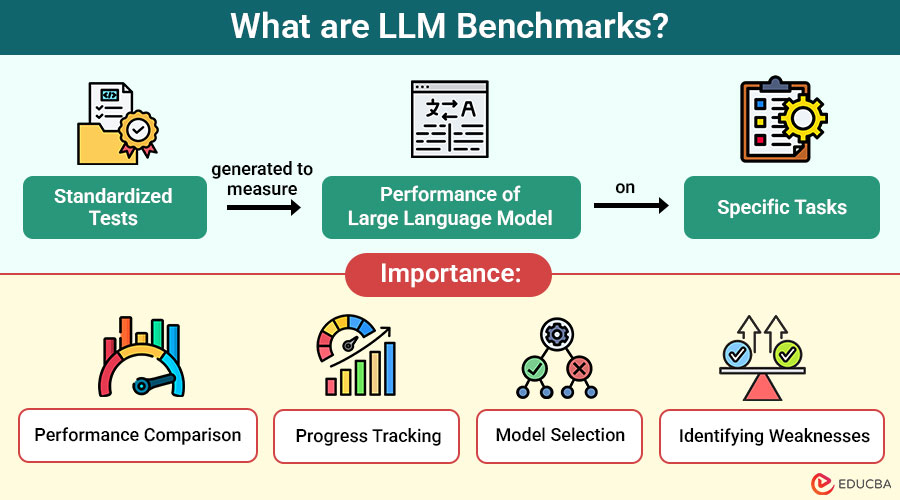
What is LLM Benchmarks? Types, Challenges & Evaluators
Understanding LLM Benchmarks: The Ultimate Guide
Alt om Claude 3: Chatboten som knuser ChatGPT • AIavisen
Benchmark: Wie valide sind LLM für die GKV? – Erste Ergebnisse
Support Wolfram Ravenwolf
LLM Structured Outputs Guide 2026: JSON Mode, Instructor & Outlines | RockB
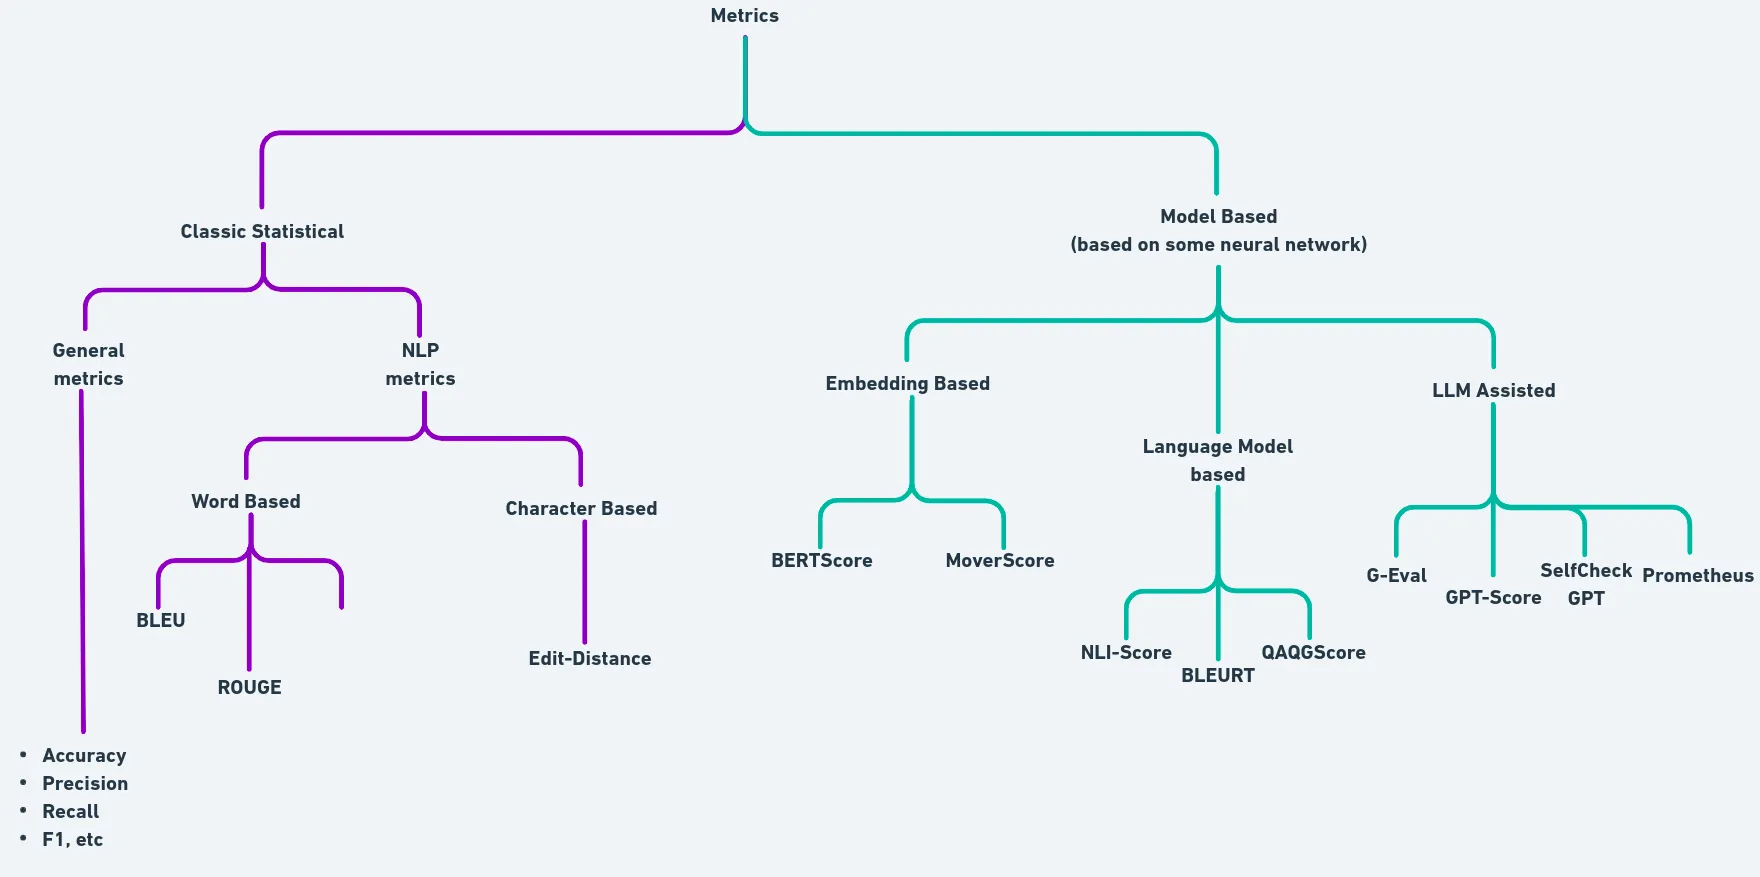
LLM Evaluation: Metrics, Methodologies, Best Practices | DataCamp
10 LLM safety and bias benchmarks
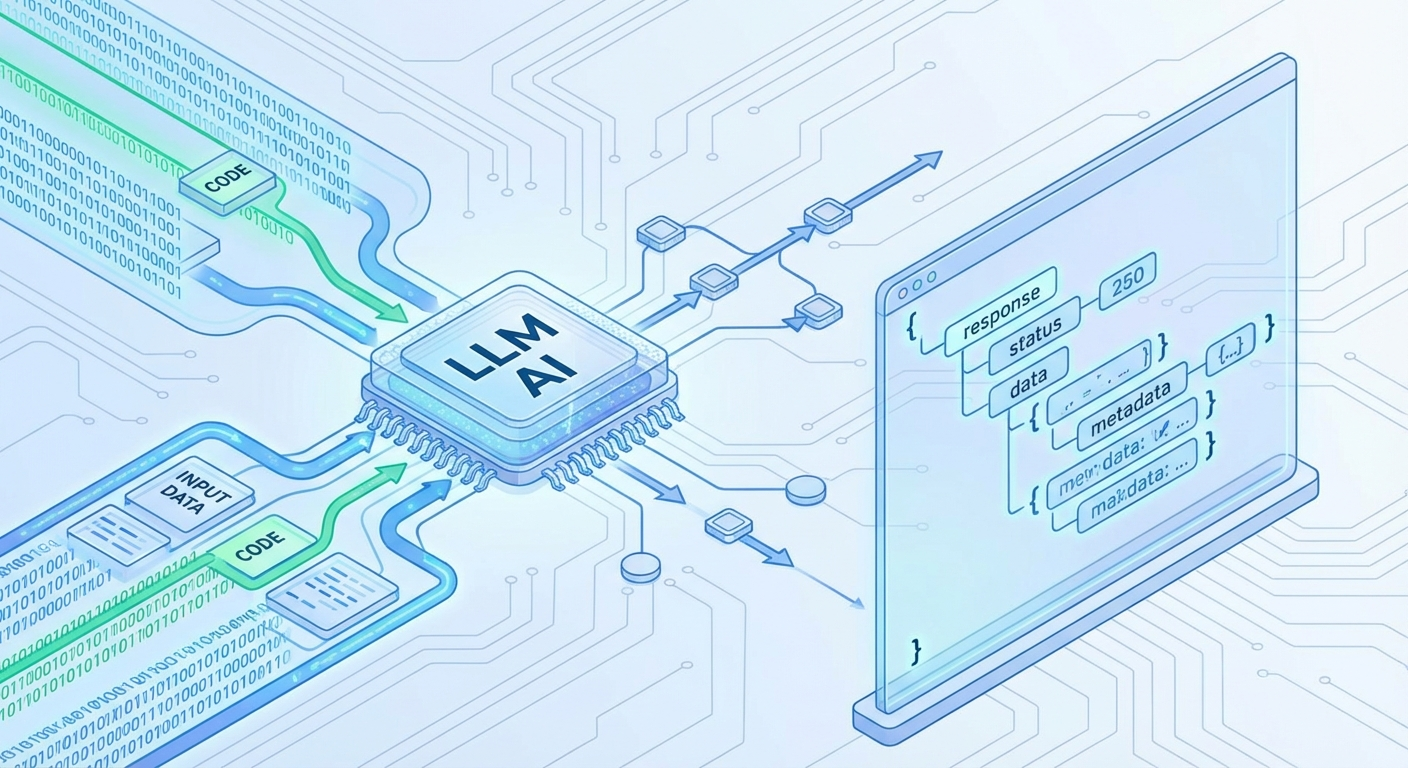
Deterministic, Structured LLM Output
Benchmarking LLM Structured Outputs | Carrick
LLM Leaderboard: AI Model Benchmarks & Pricing
Using Structured Outputs to Chain LLM Pipelines | Simbian AI Insights
Medium
Best Local LLM Models 2026: Benchmarks & Use Cases
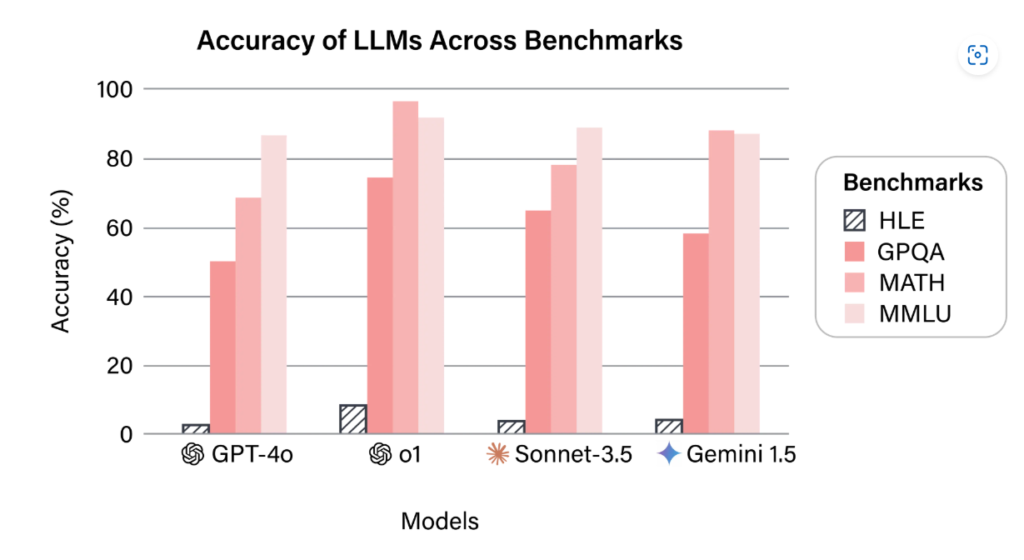
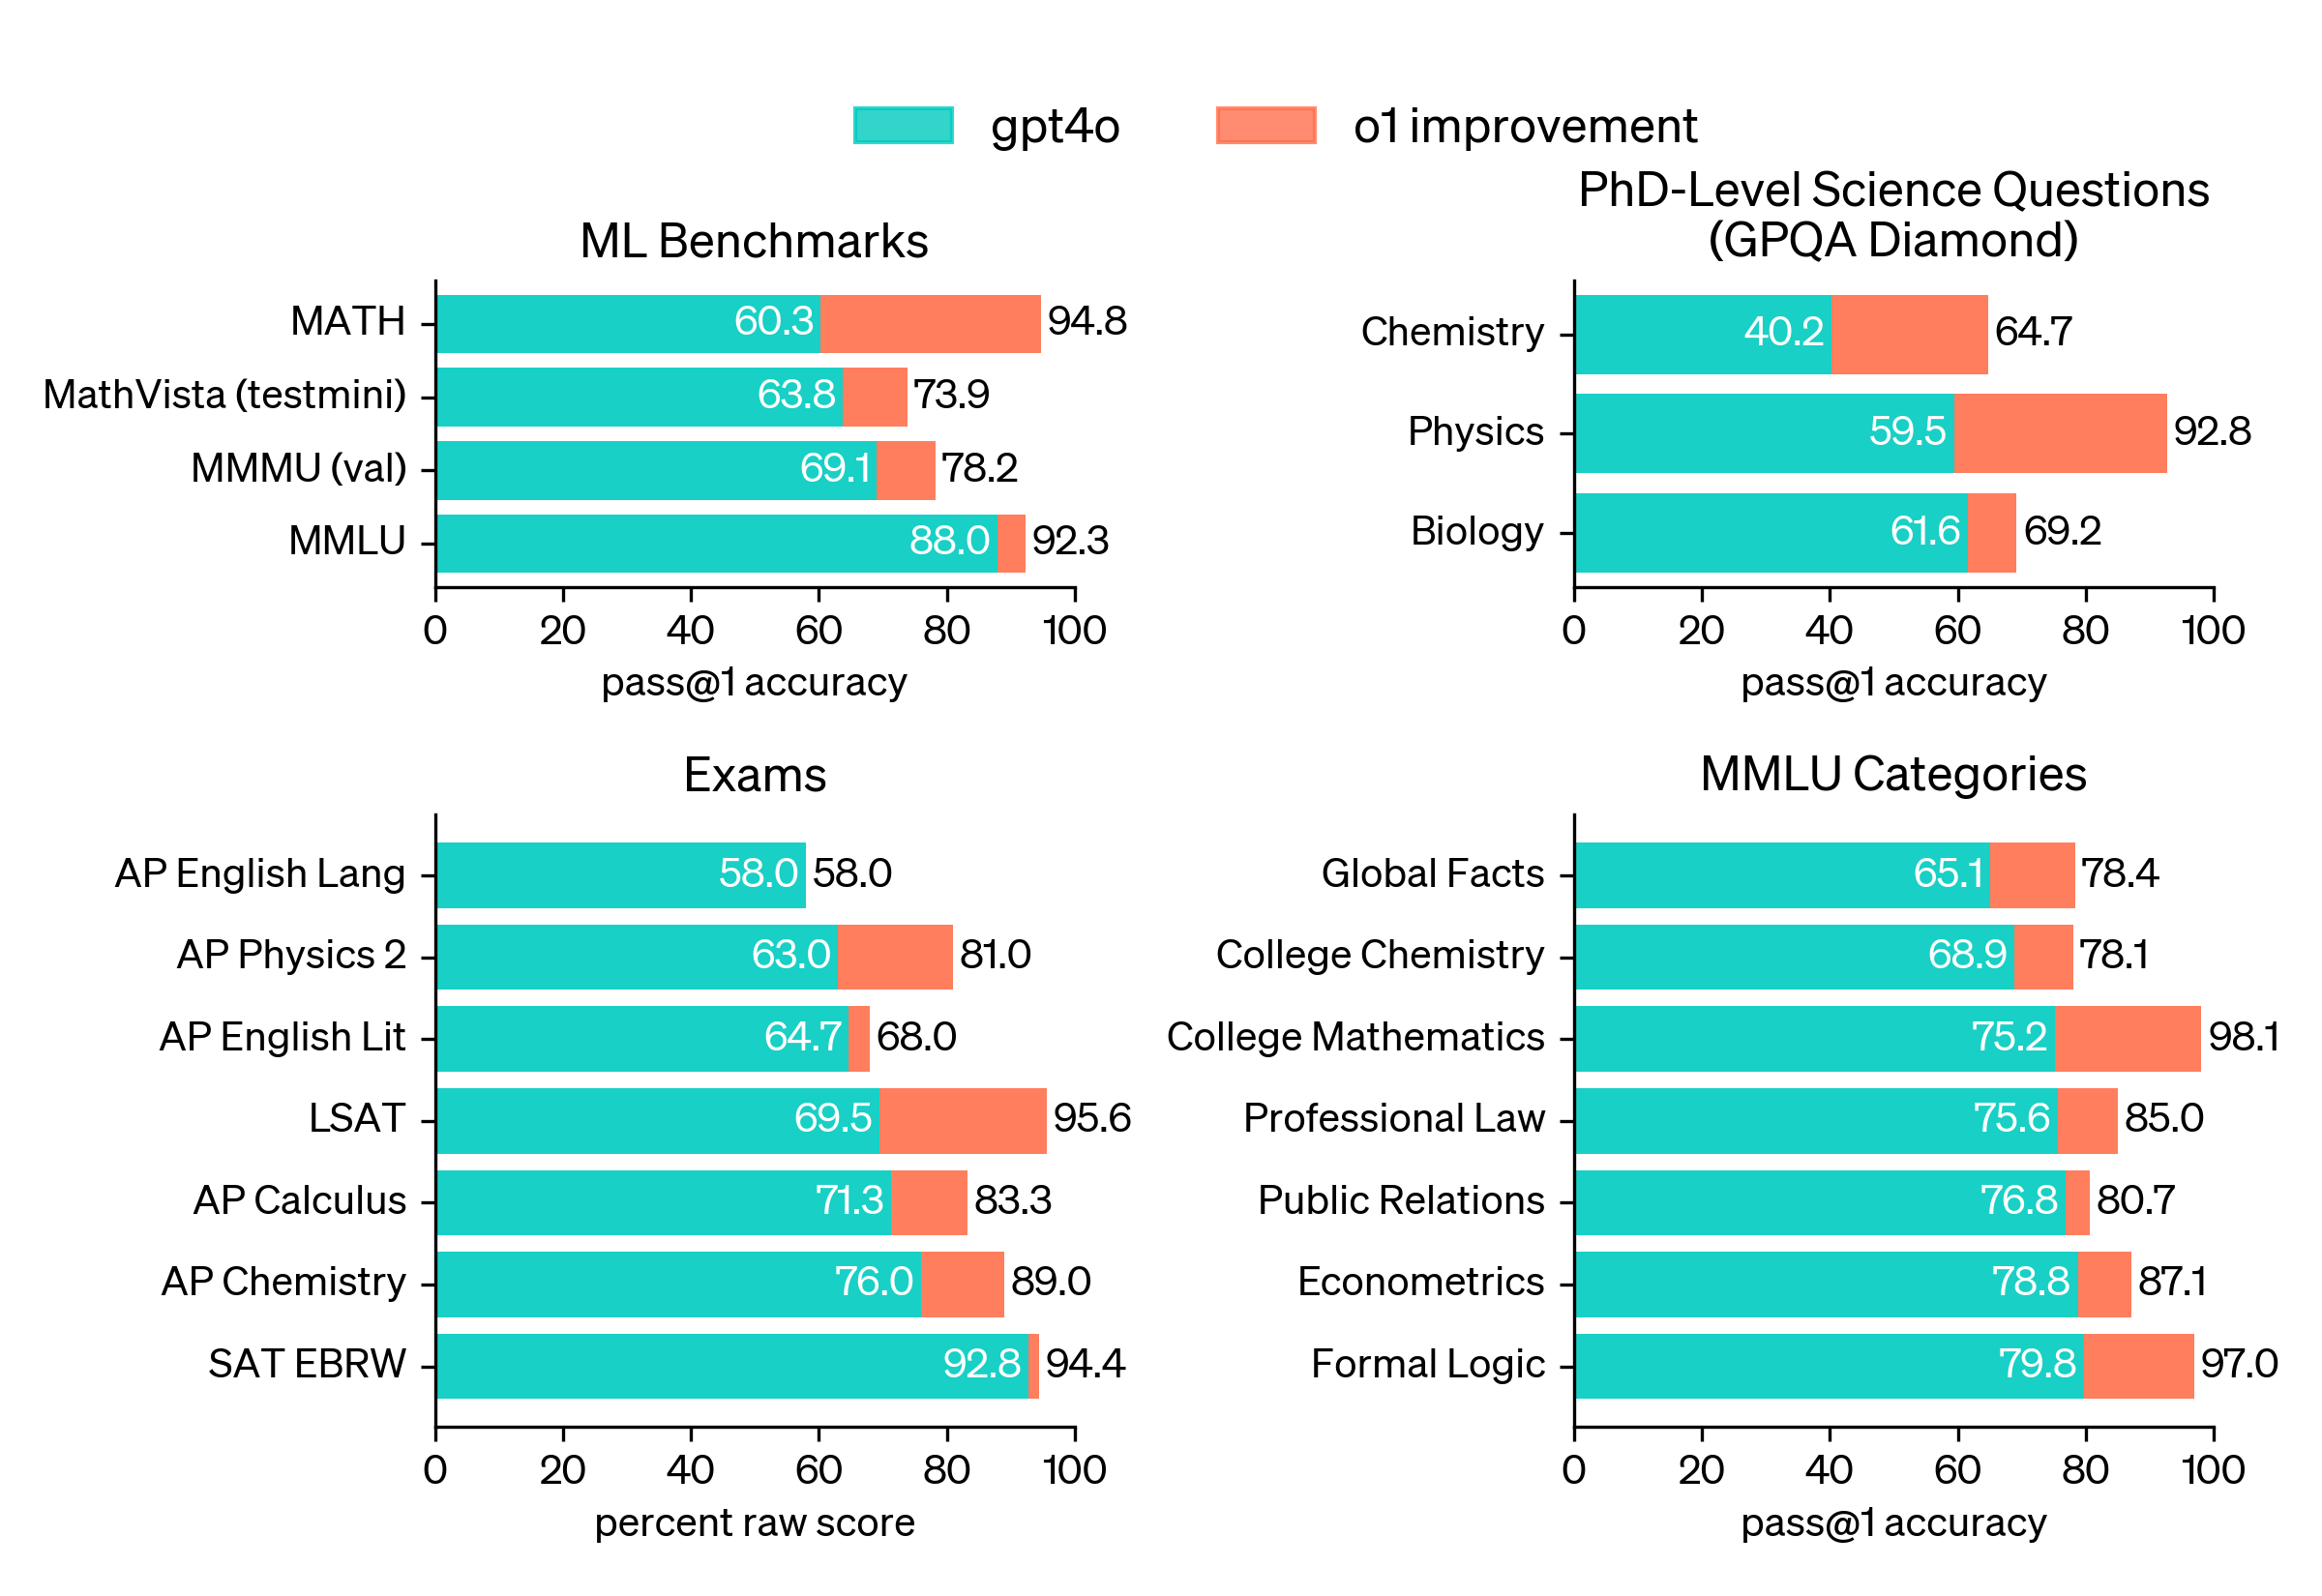
Learning to reason with LLMs | OpenAI
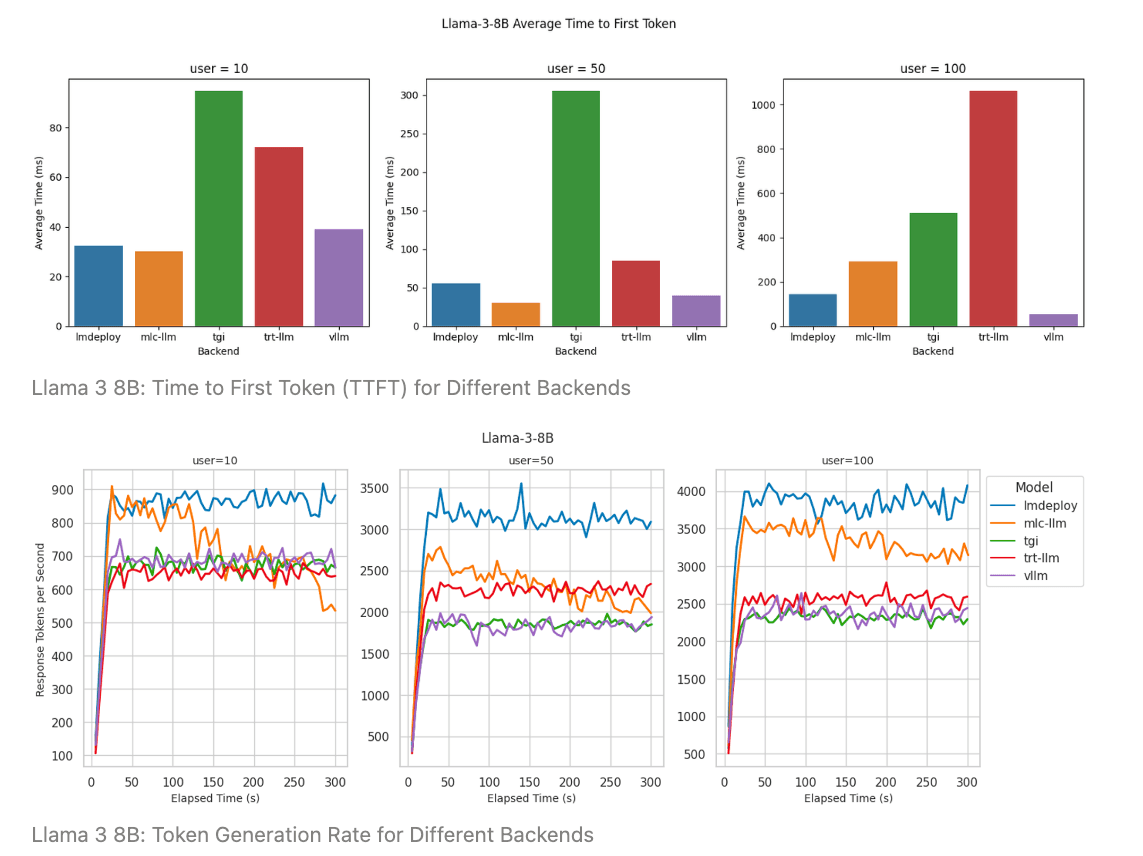
Benchmarking LLM Inference Backends