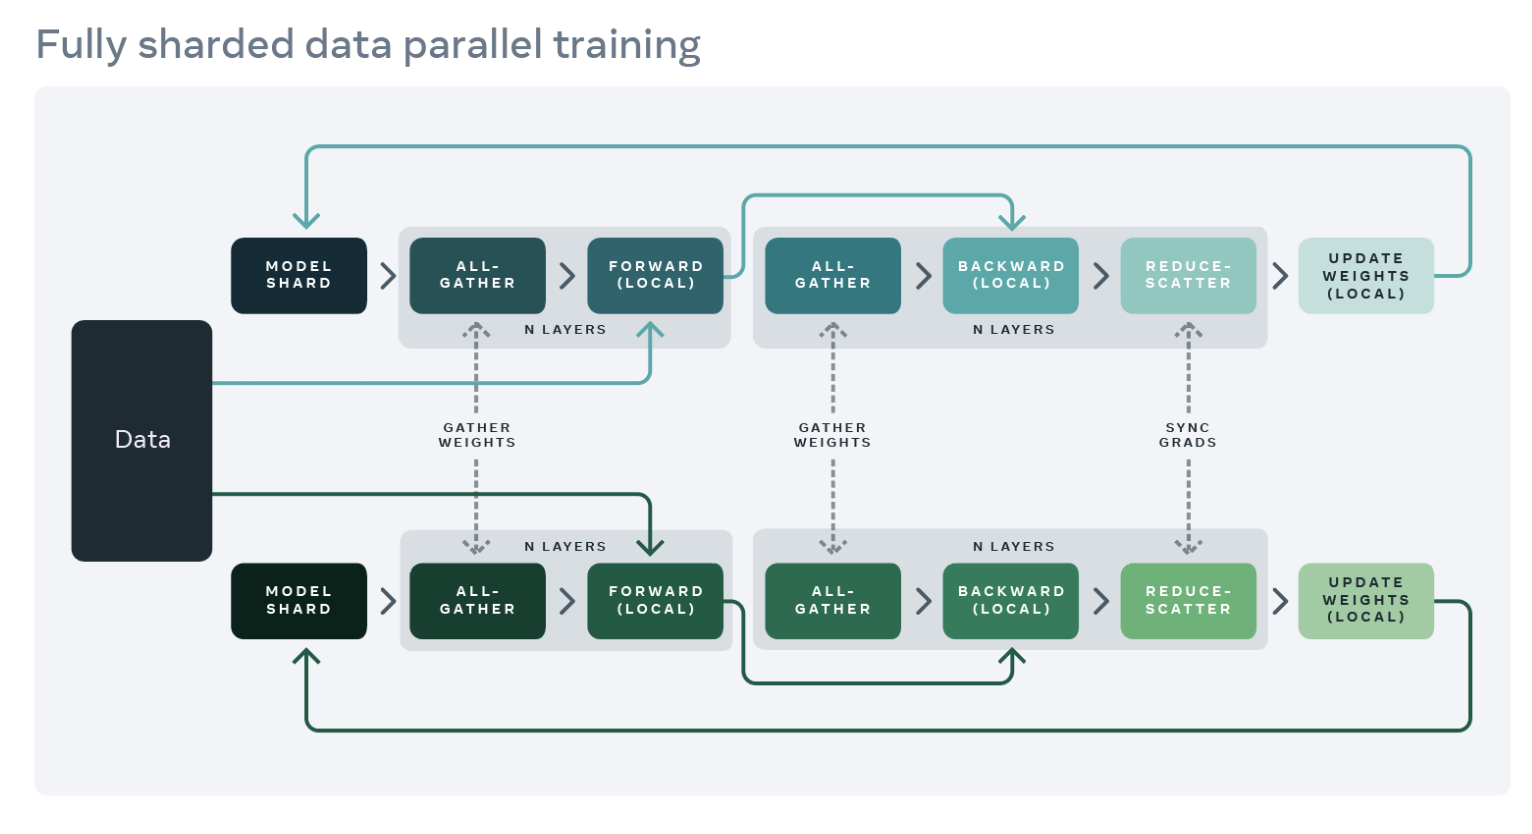
LLM Training — Fully Sharded Data Parallel (FSDP): An Efficient ...
Fully Sharded Data Parallelism: Scaling LLM Training | by Abhinav ...
Fully Sharded Data Parallel (FSDP) Theory of Operations — Gaudi ...
Tutorial 2: Data Parallel and Fully Sharded Data Parallel Training ...
Report on PyTorch Fully Sharded Data Parallel (FSDP): Architecture ...
Training and Inference of LLMs with PyTorch Fully Sharded Data Parallel ...
Fully Sharded Data Parallel: faster AI training with fewer GPUs ...
MCore Custom Fully Sharded Data Parallel (FSDP) — Megatron-LM
Paper page - SimpleFSDP: Simpler Fully Sharded Data Parallel with torch ...
Large Parallelism Post: Part V. FSDP: Fully Sharded Data Parallel ...
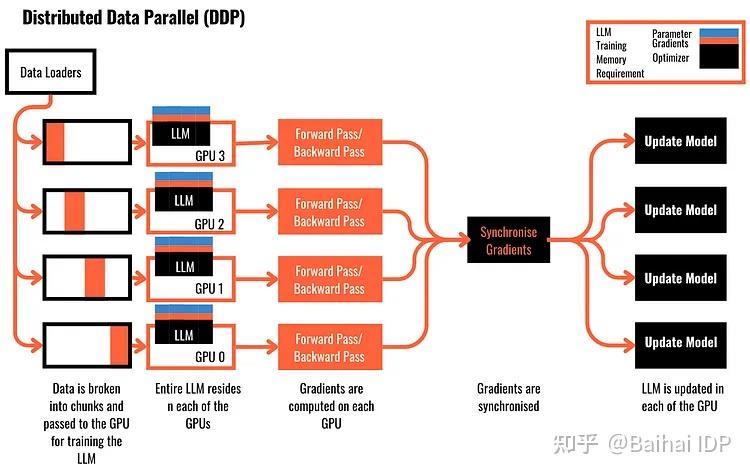
Distributed Data Parallel (DDP) vs. Fully Sharded Data Parallel (FSDP ...
Getting Started with Fully Sharded Data Parallel(FSDP) — PyTorch ...
I explain Fully Sharded Data Parallel (FSDP) and pipeline parallelism ...
How to Train LLM? - From Data Parallel To Fully Sharded Data Parallel ...
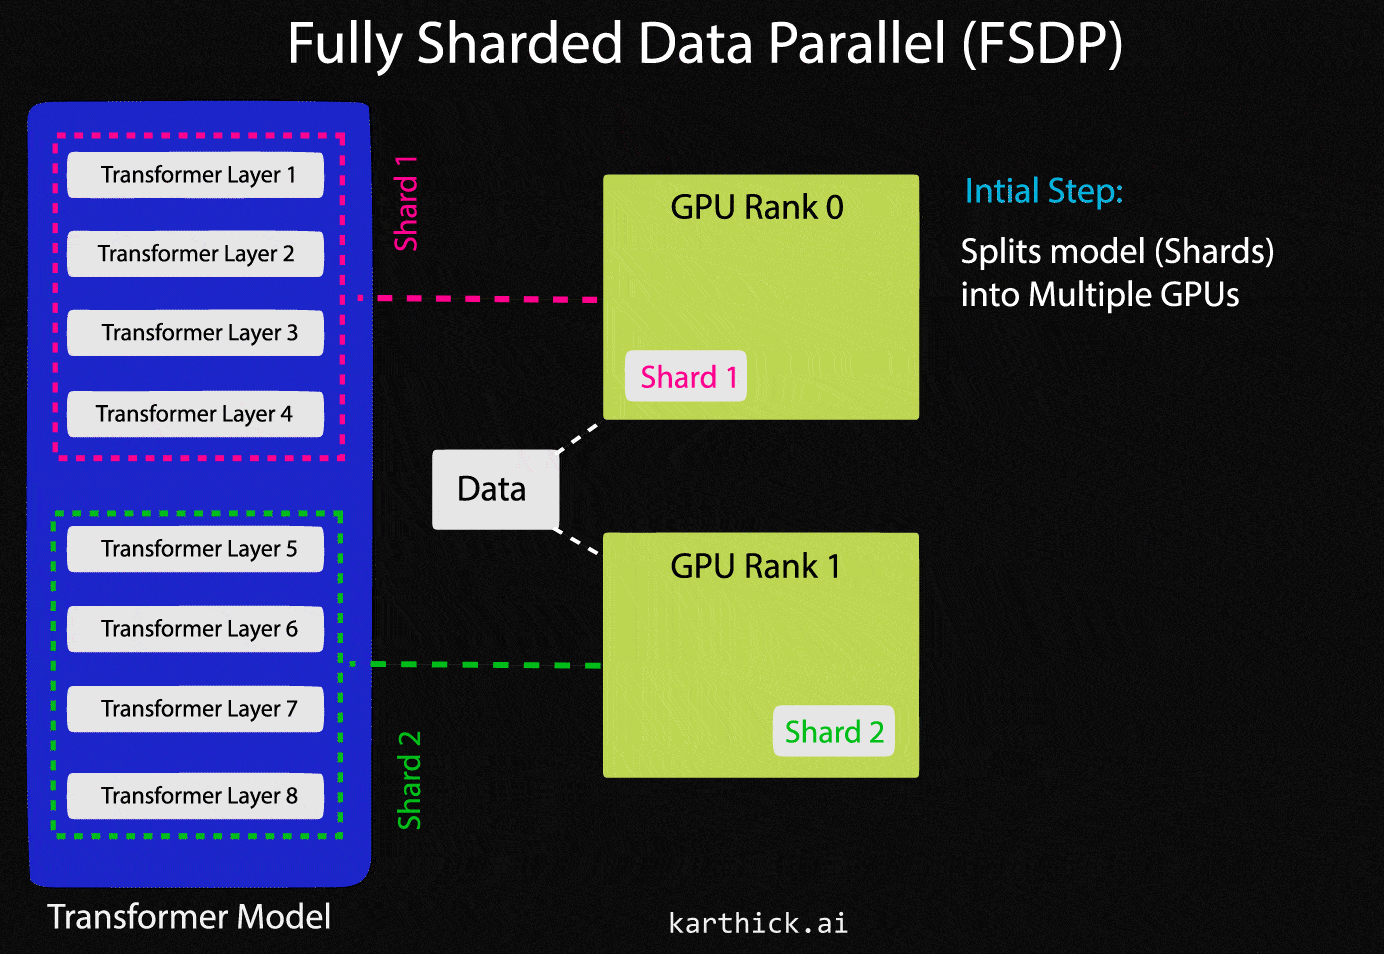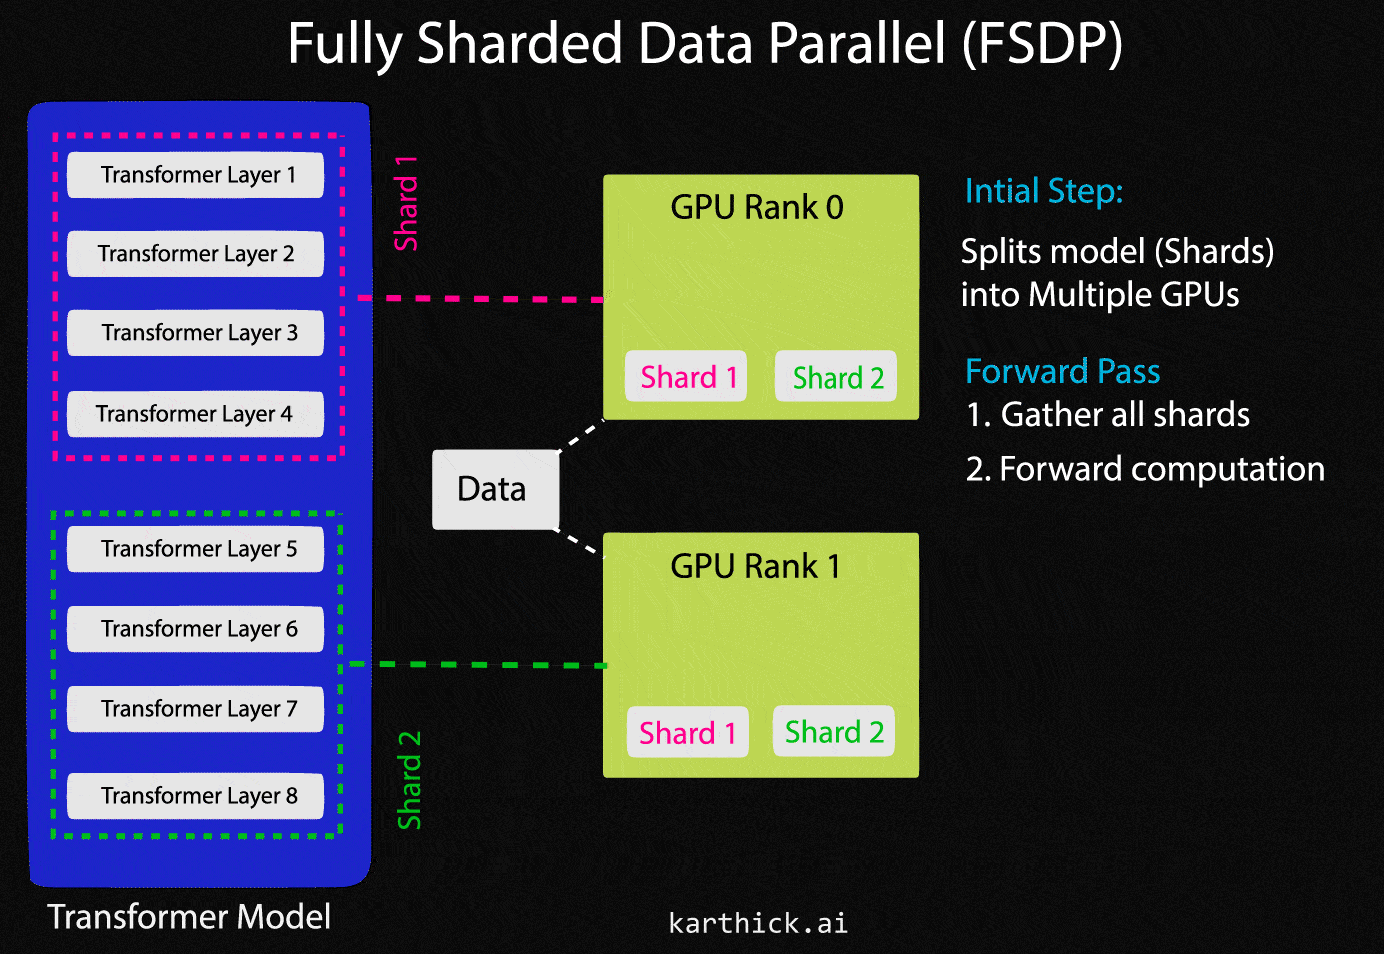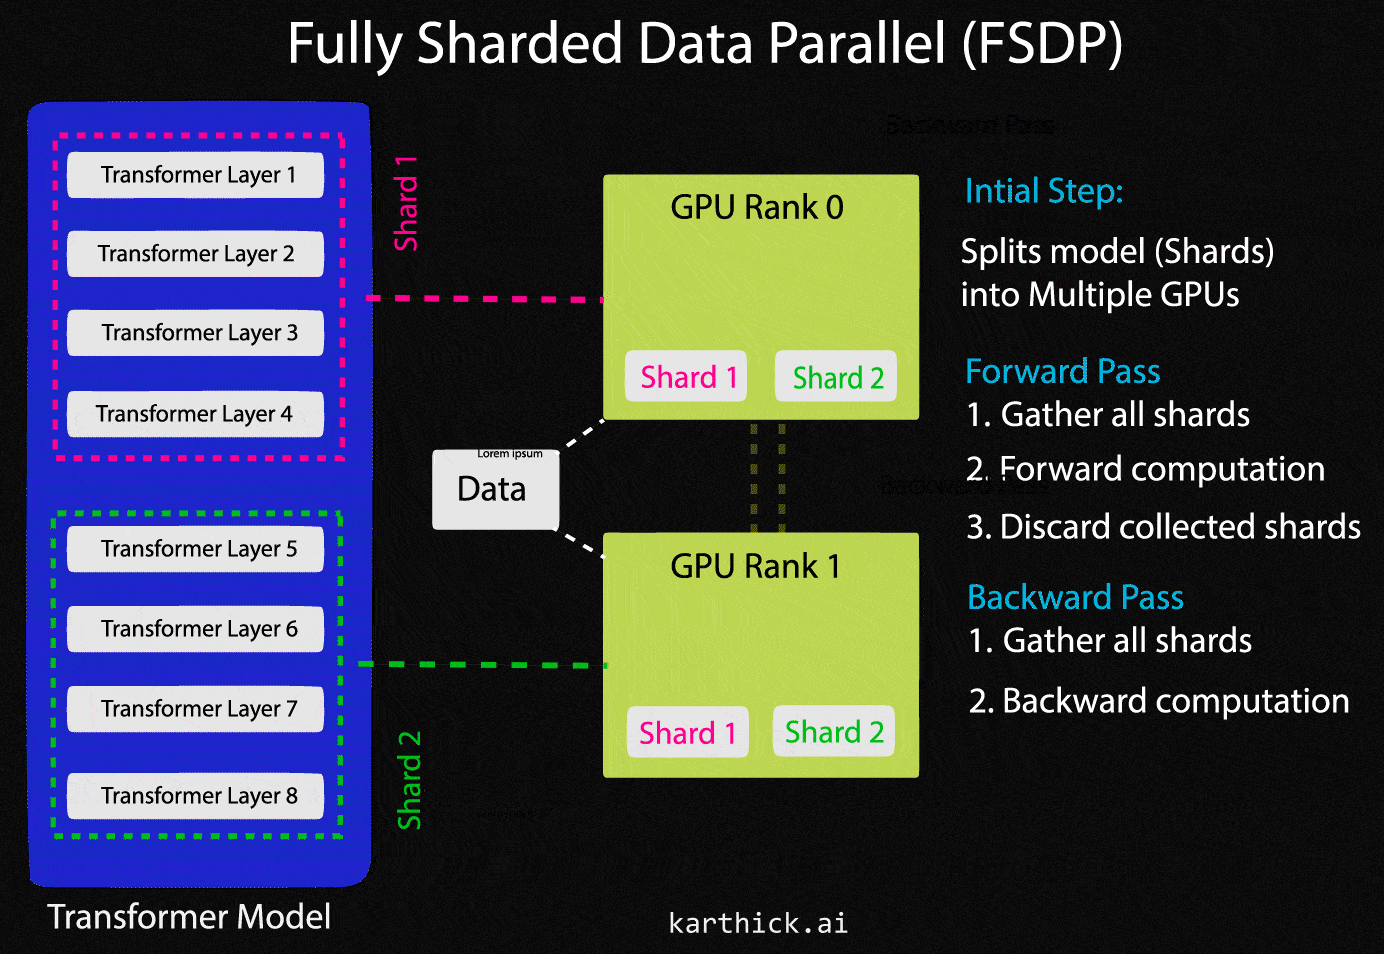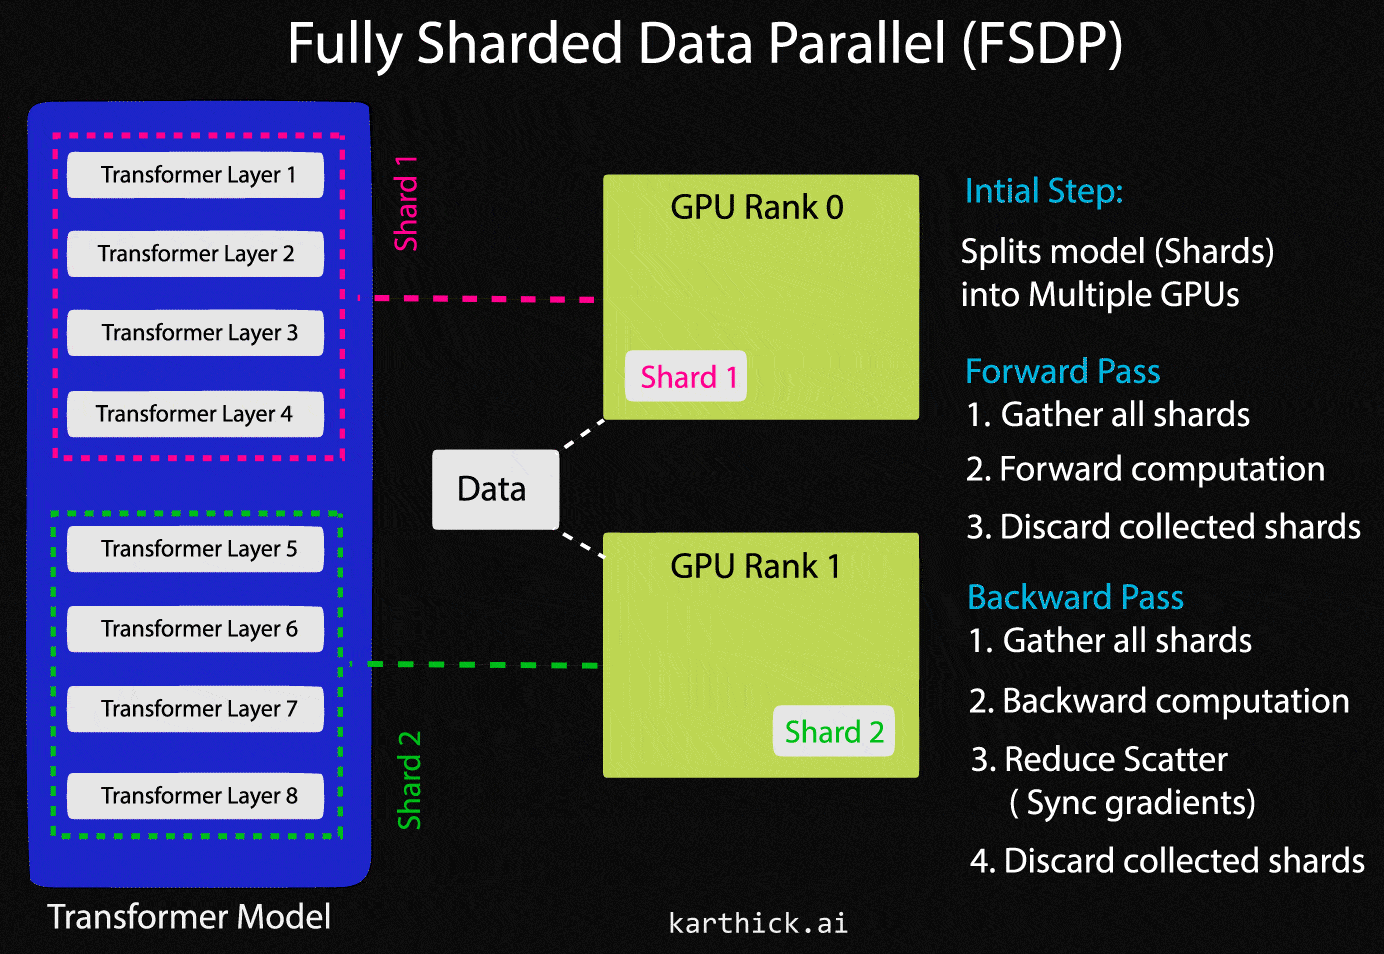
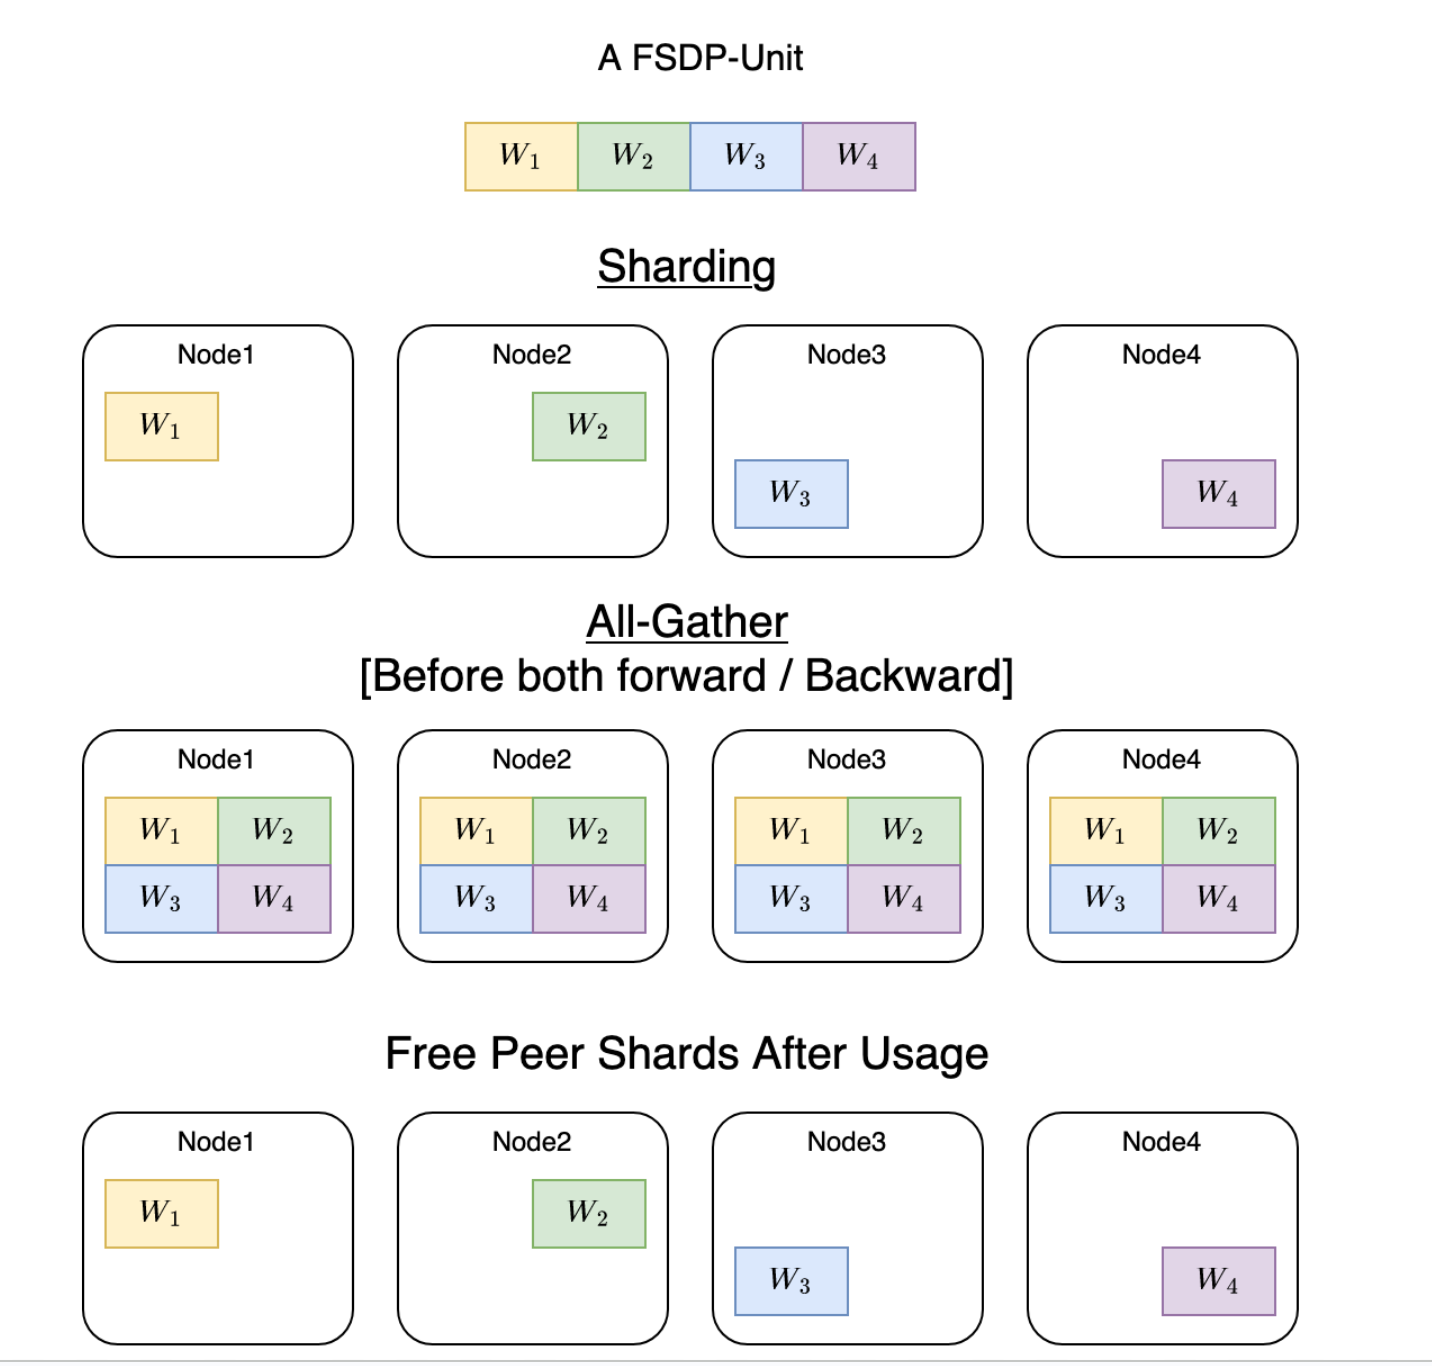
Fully Sharded Data Parallel (FSDP) | Karthick Panner Selvam
(PDF) PyTorch FSDP: Experiences on Scaling Fully Sharded Data Parallel
FSDP - Fully Sharded Data Parallel | Sharpen's Blogs
YaFSDP: Yet another Fully Sharded Data Parallel : r/mlscaling
How Fully Sharded Data Parallel (FSDP) works? - YouTube
Fully Sharded Data Parallel (FSDP) - GeeksforGeeks
Training LLMs: FSDP (Fully Sharded Data Parallelism)Explained Like ...
PyTorch FSDP: Experiences on Scaling Fully Sharded Data Parallel | DeepAI
How to Enable Native Fully Sharded Data Parallel in PyTorch
An Introduction to FSDP (Fully Sharded Data Parallel) for Distributed ...
FSDP: Fully Sharded Data Parallel | pytorch/pytorch | DeepWiki
Paper page - PyTorch FSDP: Experiences on Scaling Fully Sharded Data ...
PyTorch FSDP: Experiences on Scaling Fully Sharded Data Parallel
(PDF) SimpleFSDP: Simpler Fully Sharded Data Parallel with torch.compile
Large Scale Transformer model training with Tensor Parallel (TP ...
Everything about Distributed Training and Efficient Finetuning ...
Inside FSDP with PyTorch and Ray: Scaling Model Training with Fully ...
Fully Sharded Data Parallelism (FSDP) - Edge AI and Vision Alliance
PyTorch Distributed Data Parallel (DDP) Training in Kaggle
Fully sharded data parallel(FSDP) in Pytorch - 知乎
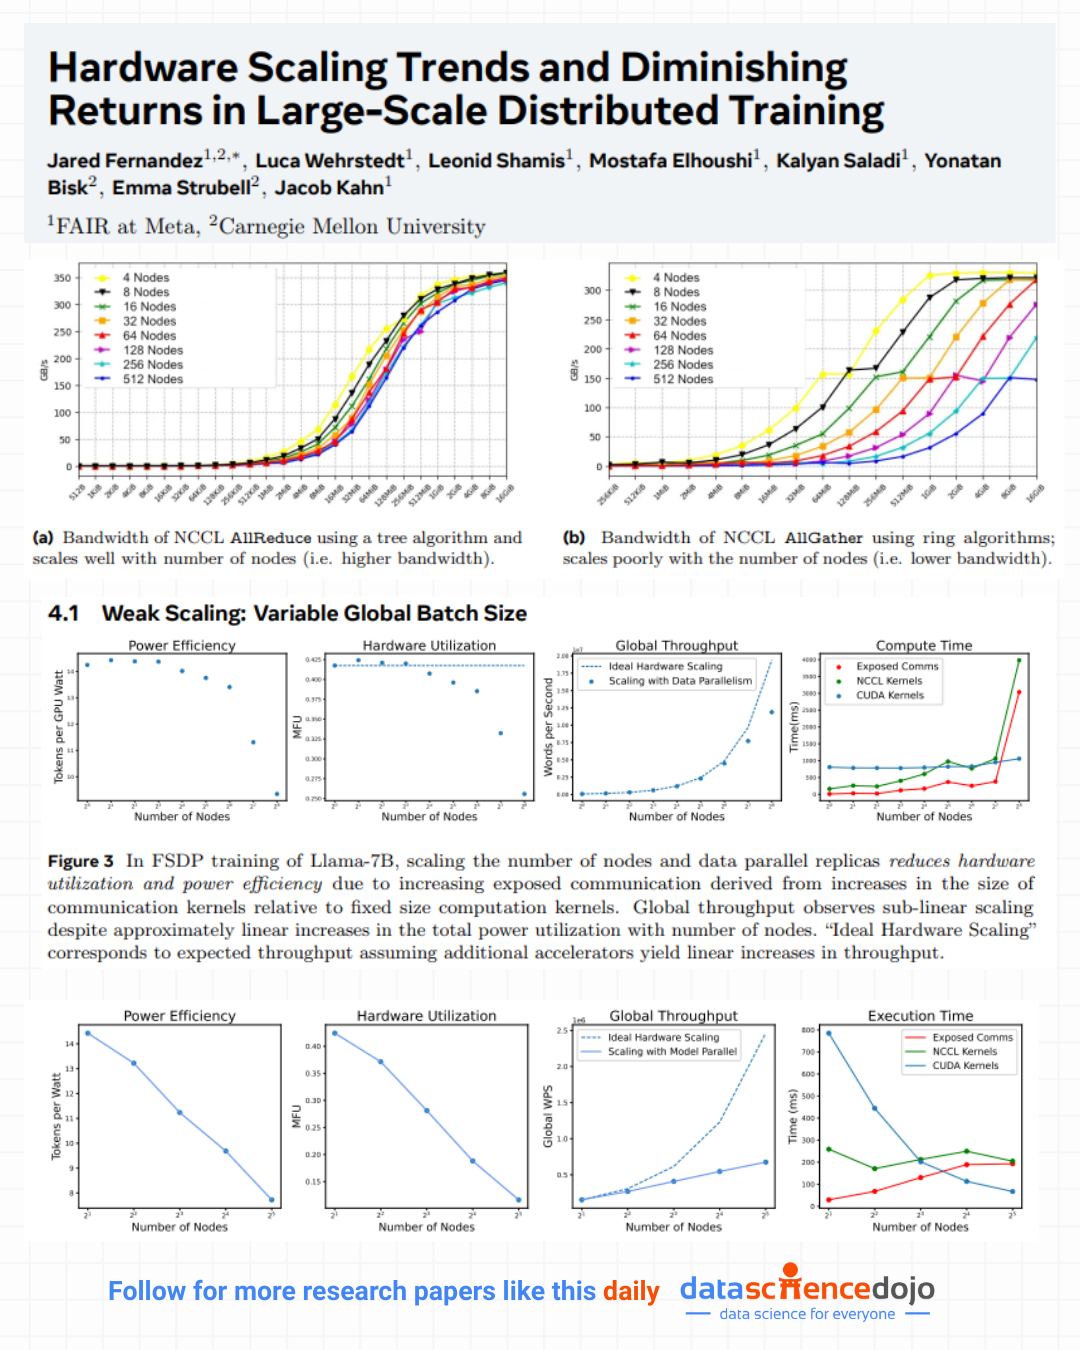
Data - 🔥 Meta just released a hard-hitting reality check on scaling LLM ...
Distributed Parallel Training: Data Parallelism and Model Parallelism ...
How to train a specialized LLM over data | Cameron R. Wolfe, Ph.D ...
Fully Sharded Data Parallelism (FSDP) in PyTorch
Distributed Training and Efficient Finetuning - FSDP vs DeepSpeed: A ...
How to Fine-Tune an LLM with Argo Workflows and Hera
FSDP(Fully Sharded Data Parallel)-CSDN博客
(4/6) AI in Multiple GPUs: Grad Accum & Data Parallelism – Lorenzo ...
Multi-Gpu Training In Pytorch. Data And Model Parallelism – OBEA
分布式并行训练 FSDP (fully sharded data parallel) - 知乎
🧰大模型分布式训练篇——从零实现 ZeRO3 / FSDP (Fully Sharded Data Parallel) - 知乎
Training large language models on Amazon SageMaker: Best practices ...
FSDP(Fully Sharded Data Parallel)详解:大模型分布式训练的终极指南 | AwesomeML
FSDP(Fully Shared Data Parallel) : Llama3 70B 모델을 멀티 GPU로 파인튜닝 방법 (feat ...
Scaling Multimodal Foundation Models in TorchMultimodal with Pytorch ...
Top Five Tips and Tricks for LLM Fine-Tuning and Inference
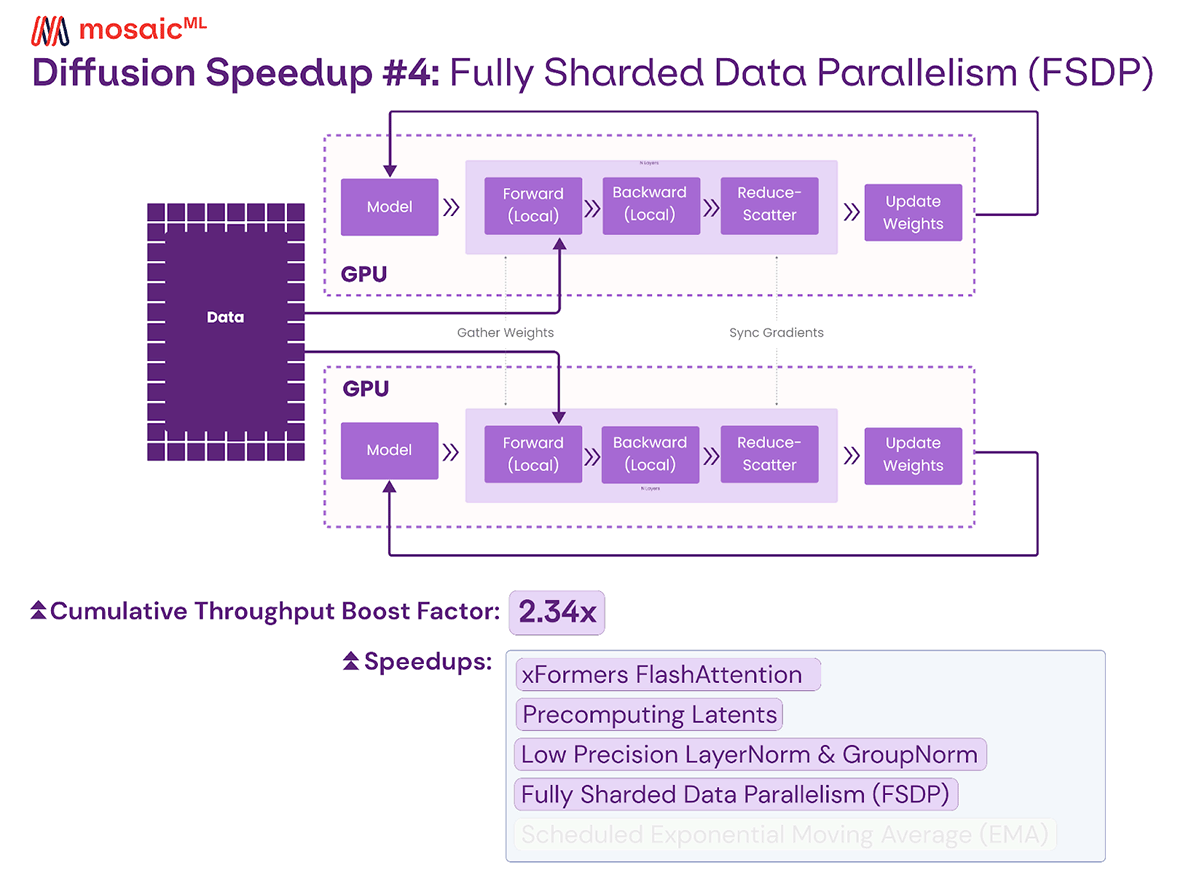
How We Trained Stable Diffusion for Less than $50k (Part 3 ...
AI/ML Infra Meetup | TorchTitan, One-stop PyTorch native solution for ...
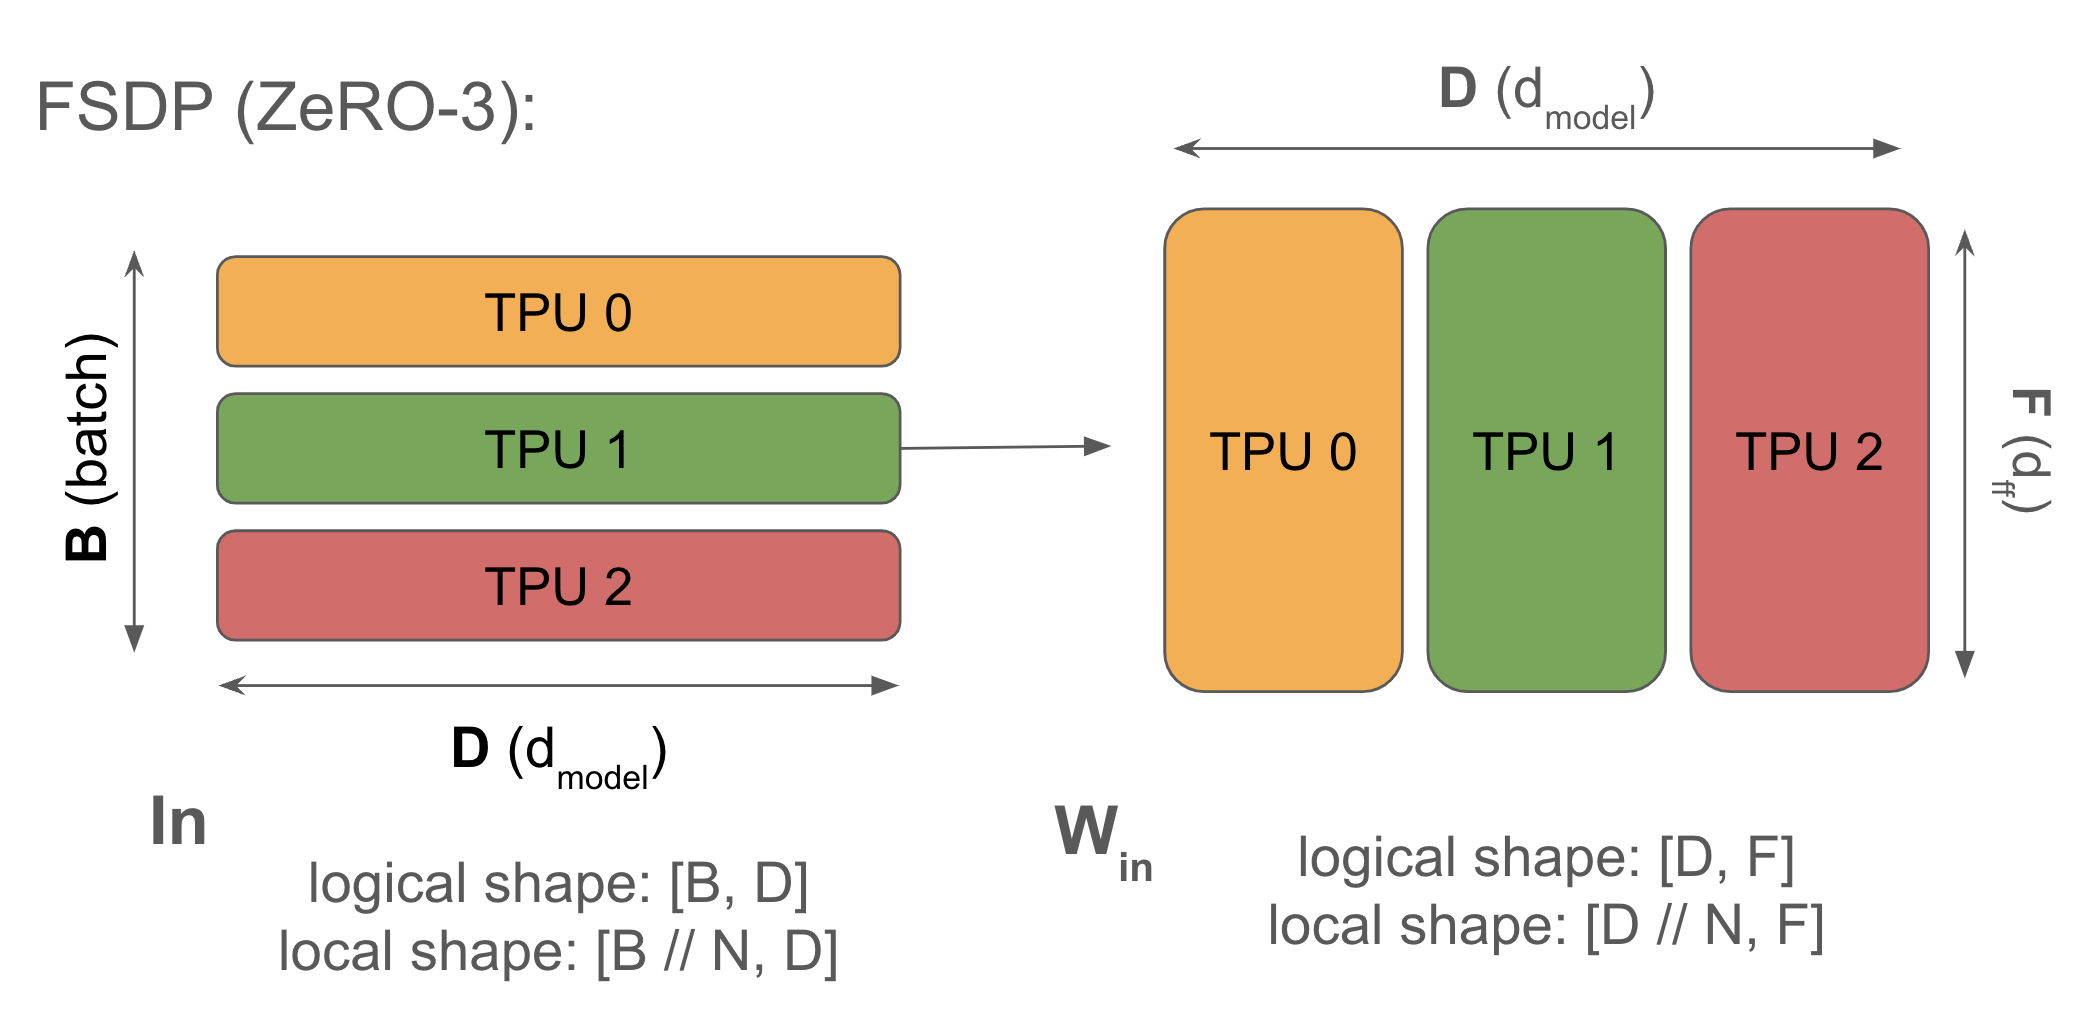
How to Parallelize a Transformer for Training | How To Scale Your Model
Training MoEs at Scale with PyTorch | PyTorch
From RAG to ReST: A Survey of Advanced Techniques in Large Language ...
Sharding Large models for parallel inference | by shashank Jain | Medium
Accelerating PyTorch Model Training
Scale LLMs with PyTorch 2.0 FSDP on Amazon EKS – Part 2 | Artificial ...
[GenAI] L1-P2-2. Computational Challenges, How to overcome by FSDP ...
GitHub - IST-DASLab/HALO: HALO: Hadamard-Assisted Low-Precision ...
#largelanguagemodels #llmtraining #pytorch #deepspeed #megatronlm ...
MegaScale-Omni: A Hyper-Scale, Workload-Resilient System for MultiModal ...
LLM 모델 파인튜닝을 위한 GPU 최적화 | 패스트캠퍼스
大模型并行训练入门指南:极简版基础知识与核心概念解析!_token streaming-CSDN博客
Medium
PyTorch Parallelism - talk notes - 知乎
Deep Learning Archives - GeeksforGeeks
LLMs高效的多 GPU 计算策略Efficient multi-GPU compute strategies_llm支持多显卡-CSDN博客
生成式 AI 术语指南:带有配图说明,没有数学公式 - 知乎
FSDP-vLLM Integration | hiyouga/EasyR1 | DeepWiki
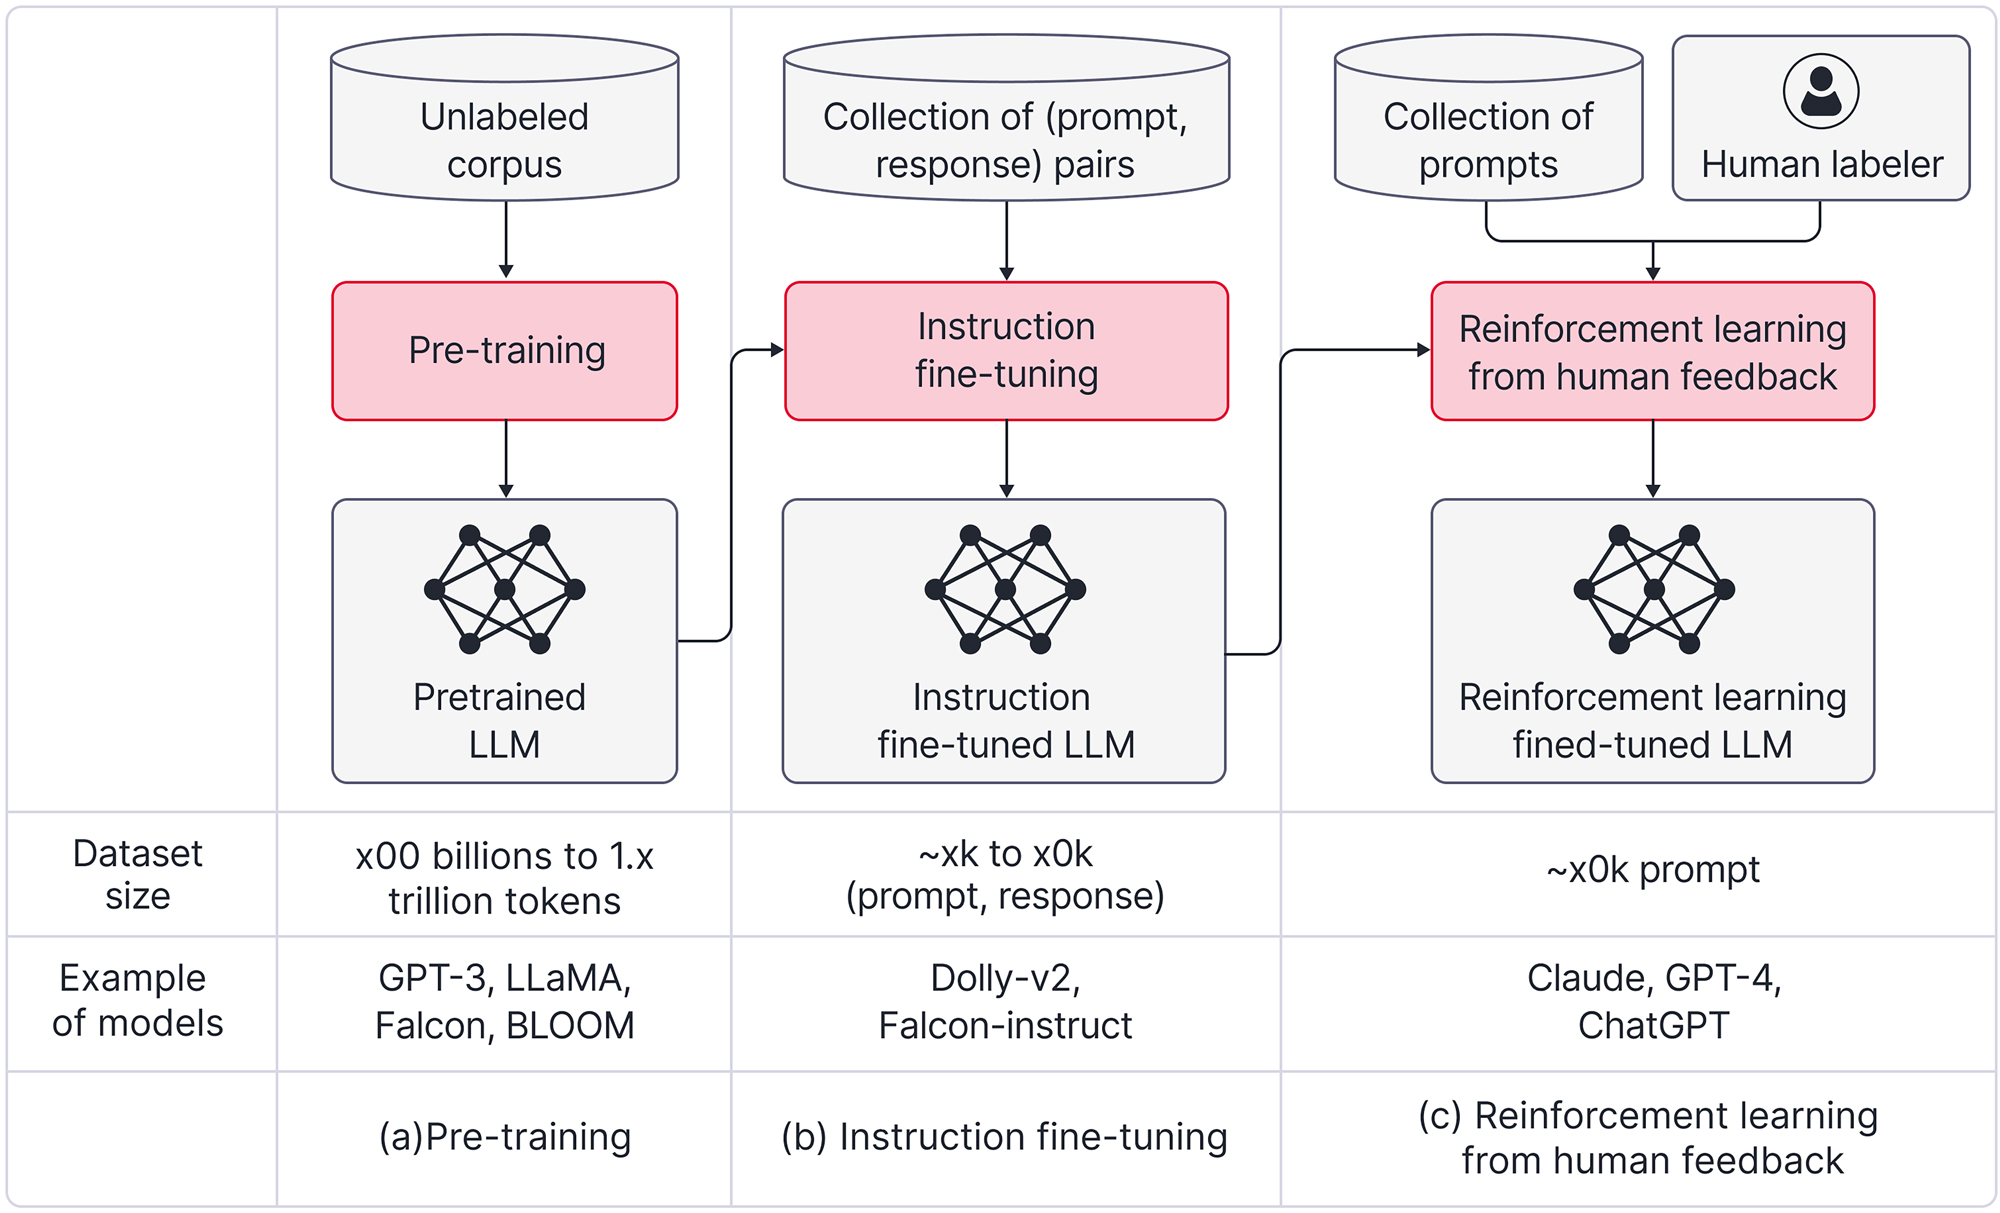
A High-level Overview of Large Language Models - RBC Borealis
AI Infra Day | Composable PyTorch Distributed with PT2 @ Meta | PDF
LLM分布式训练方法汇总-图解 - 知乎