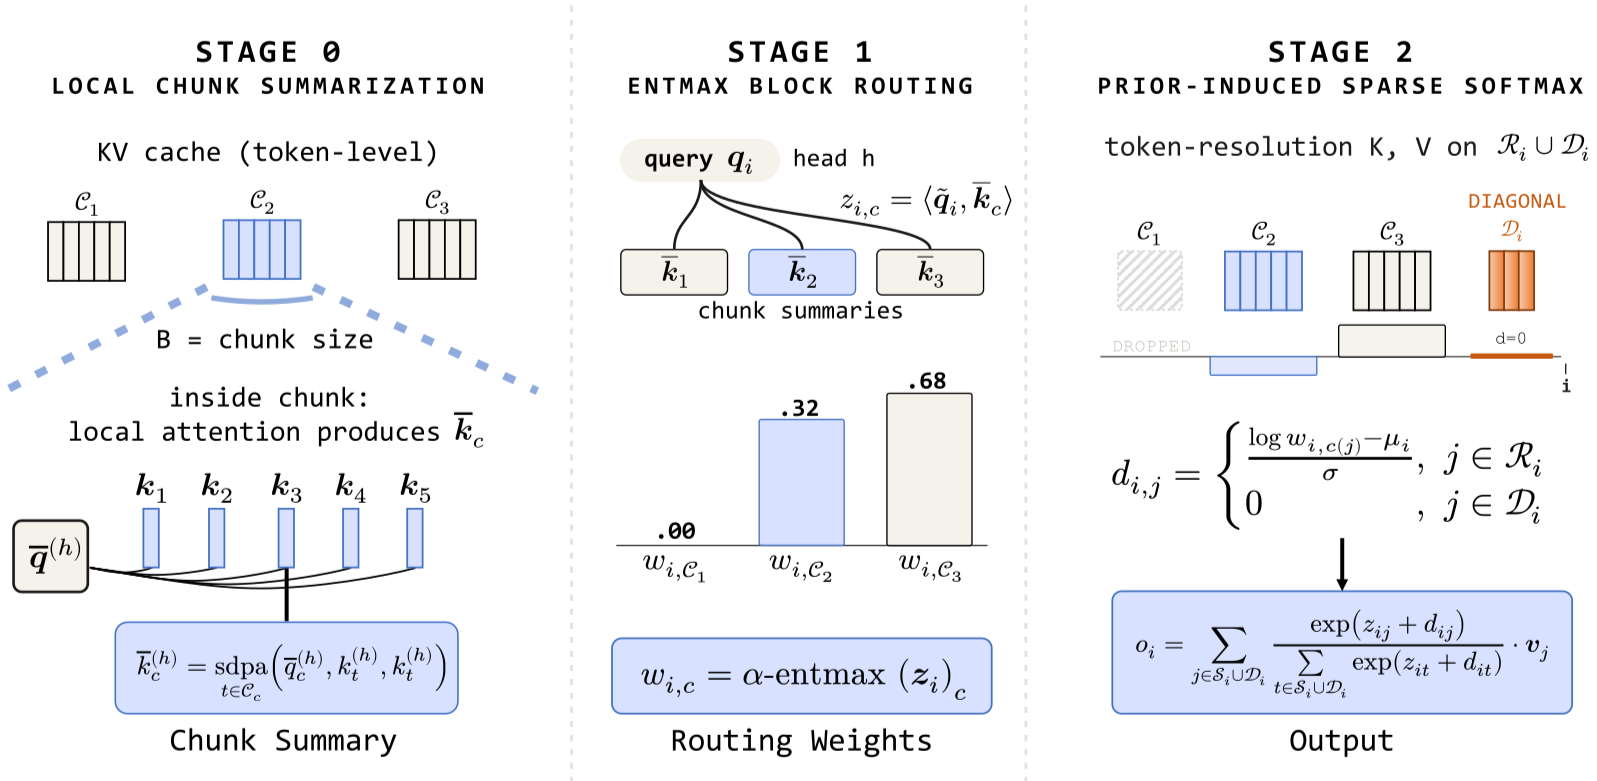
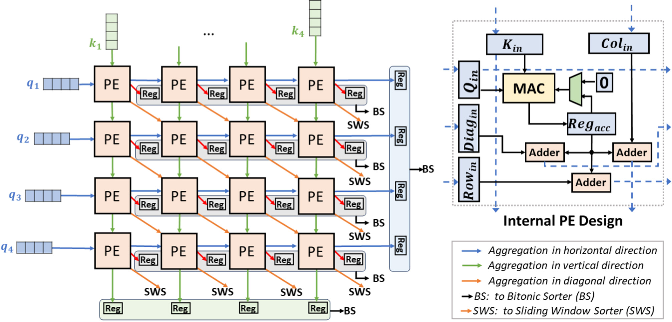
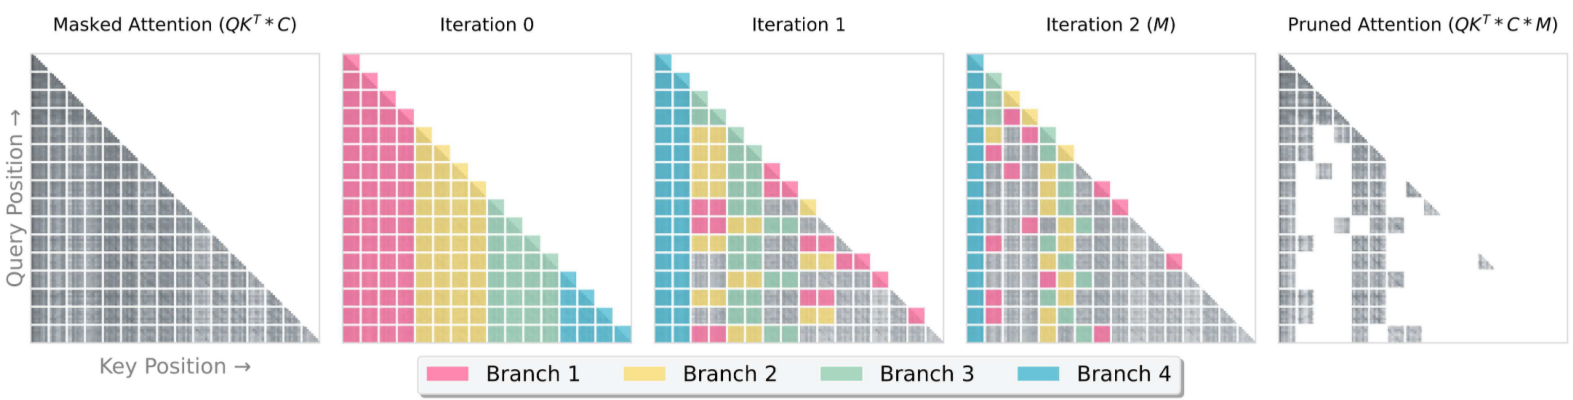
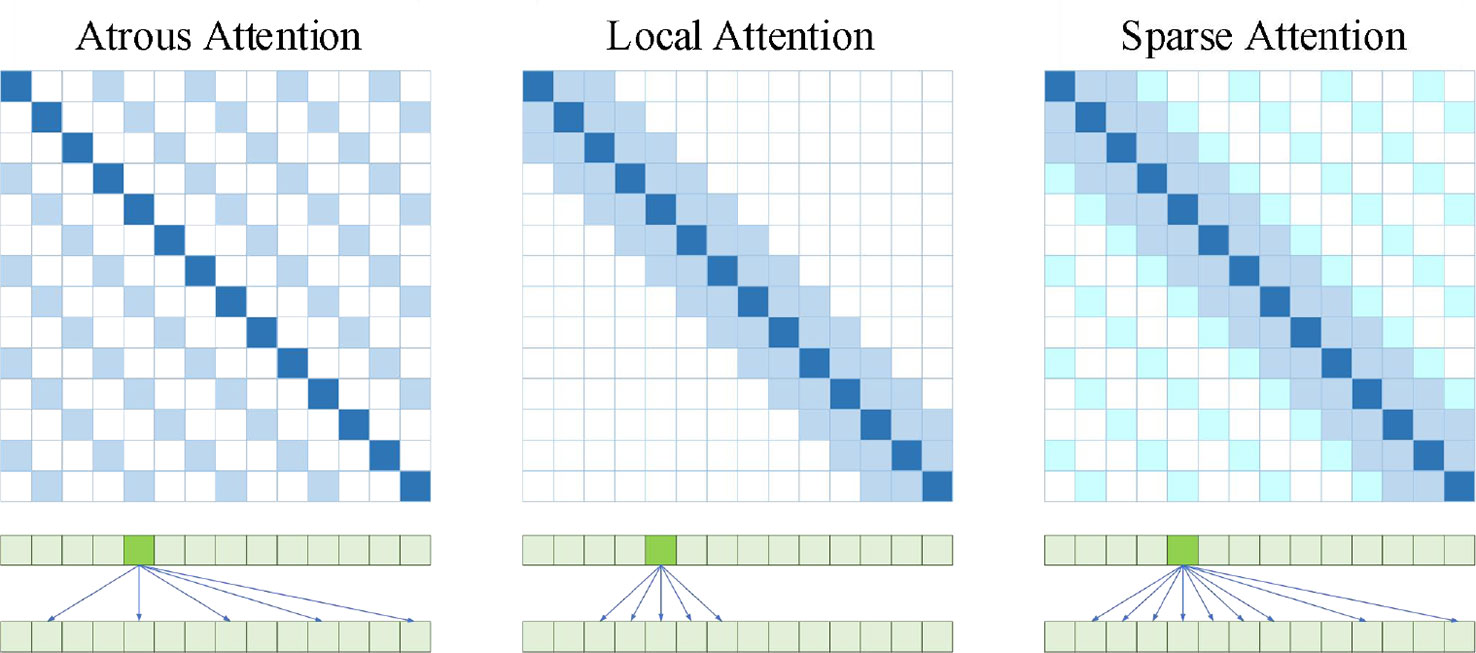
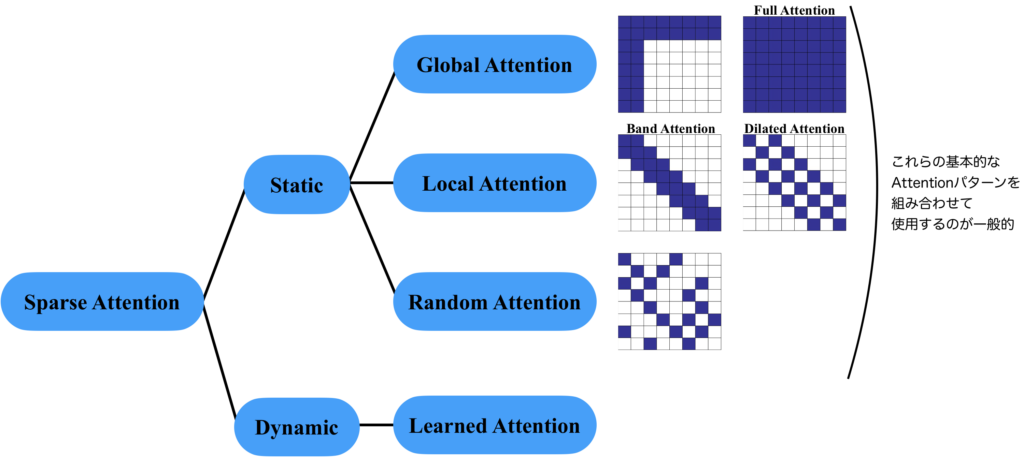
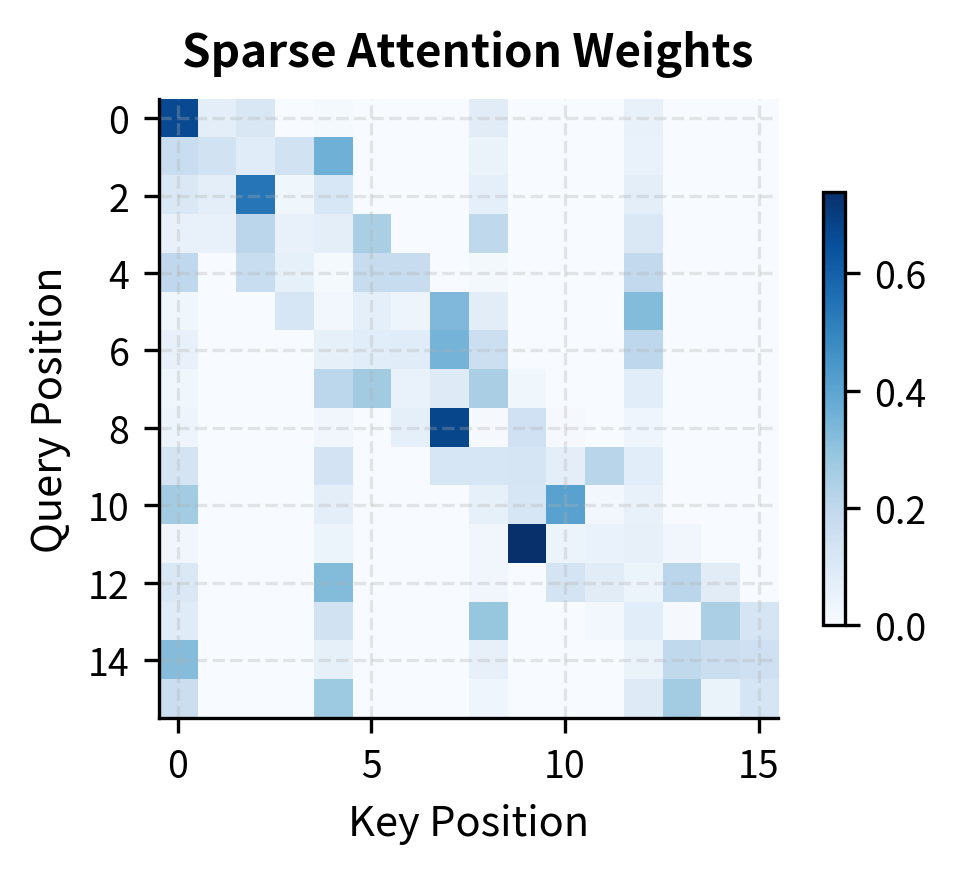
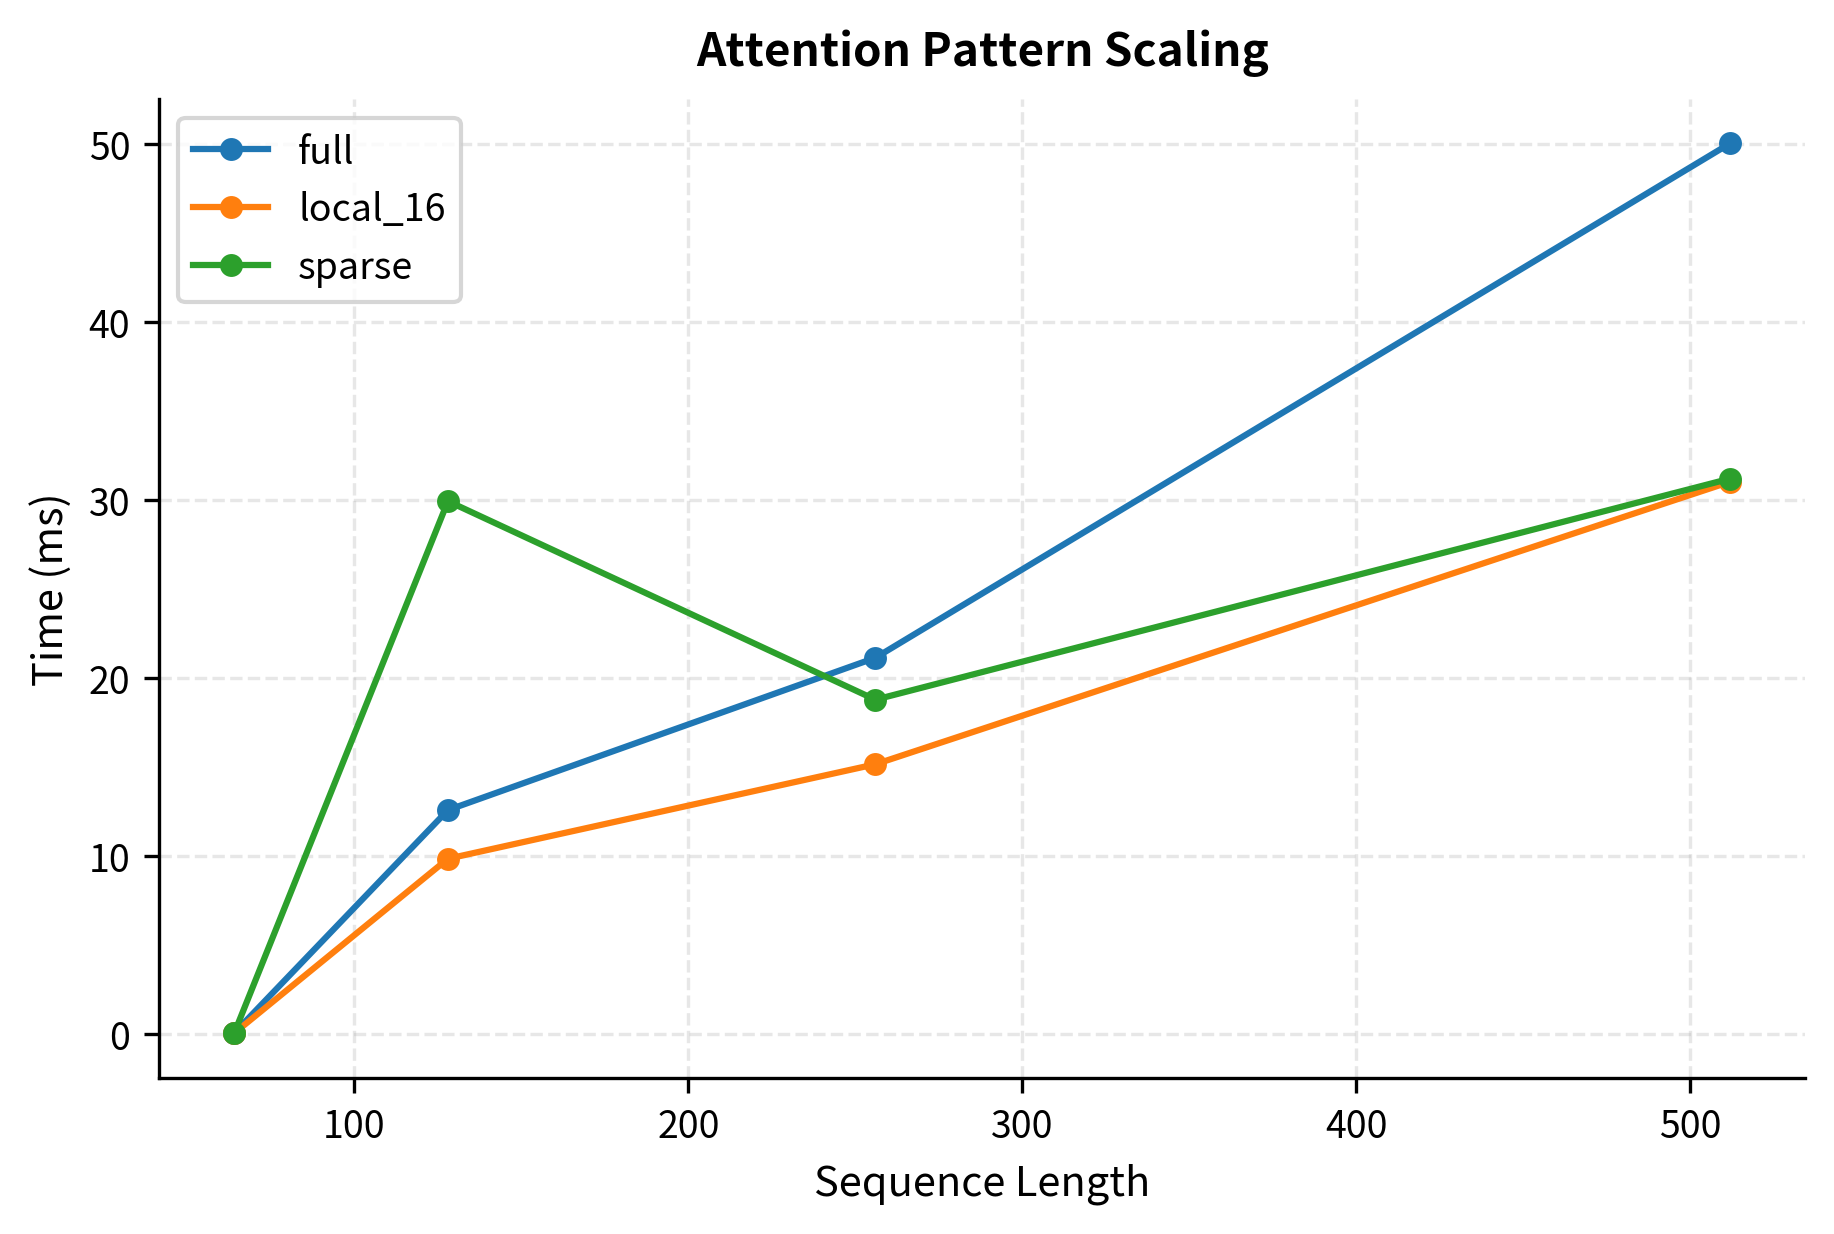
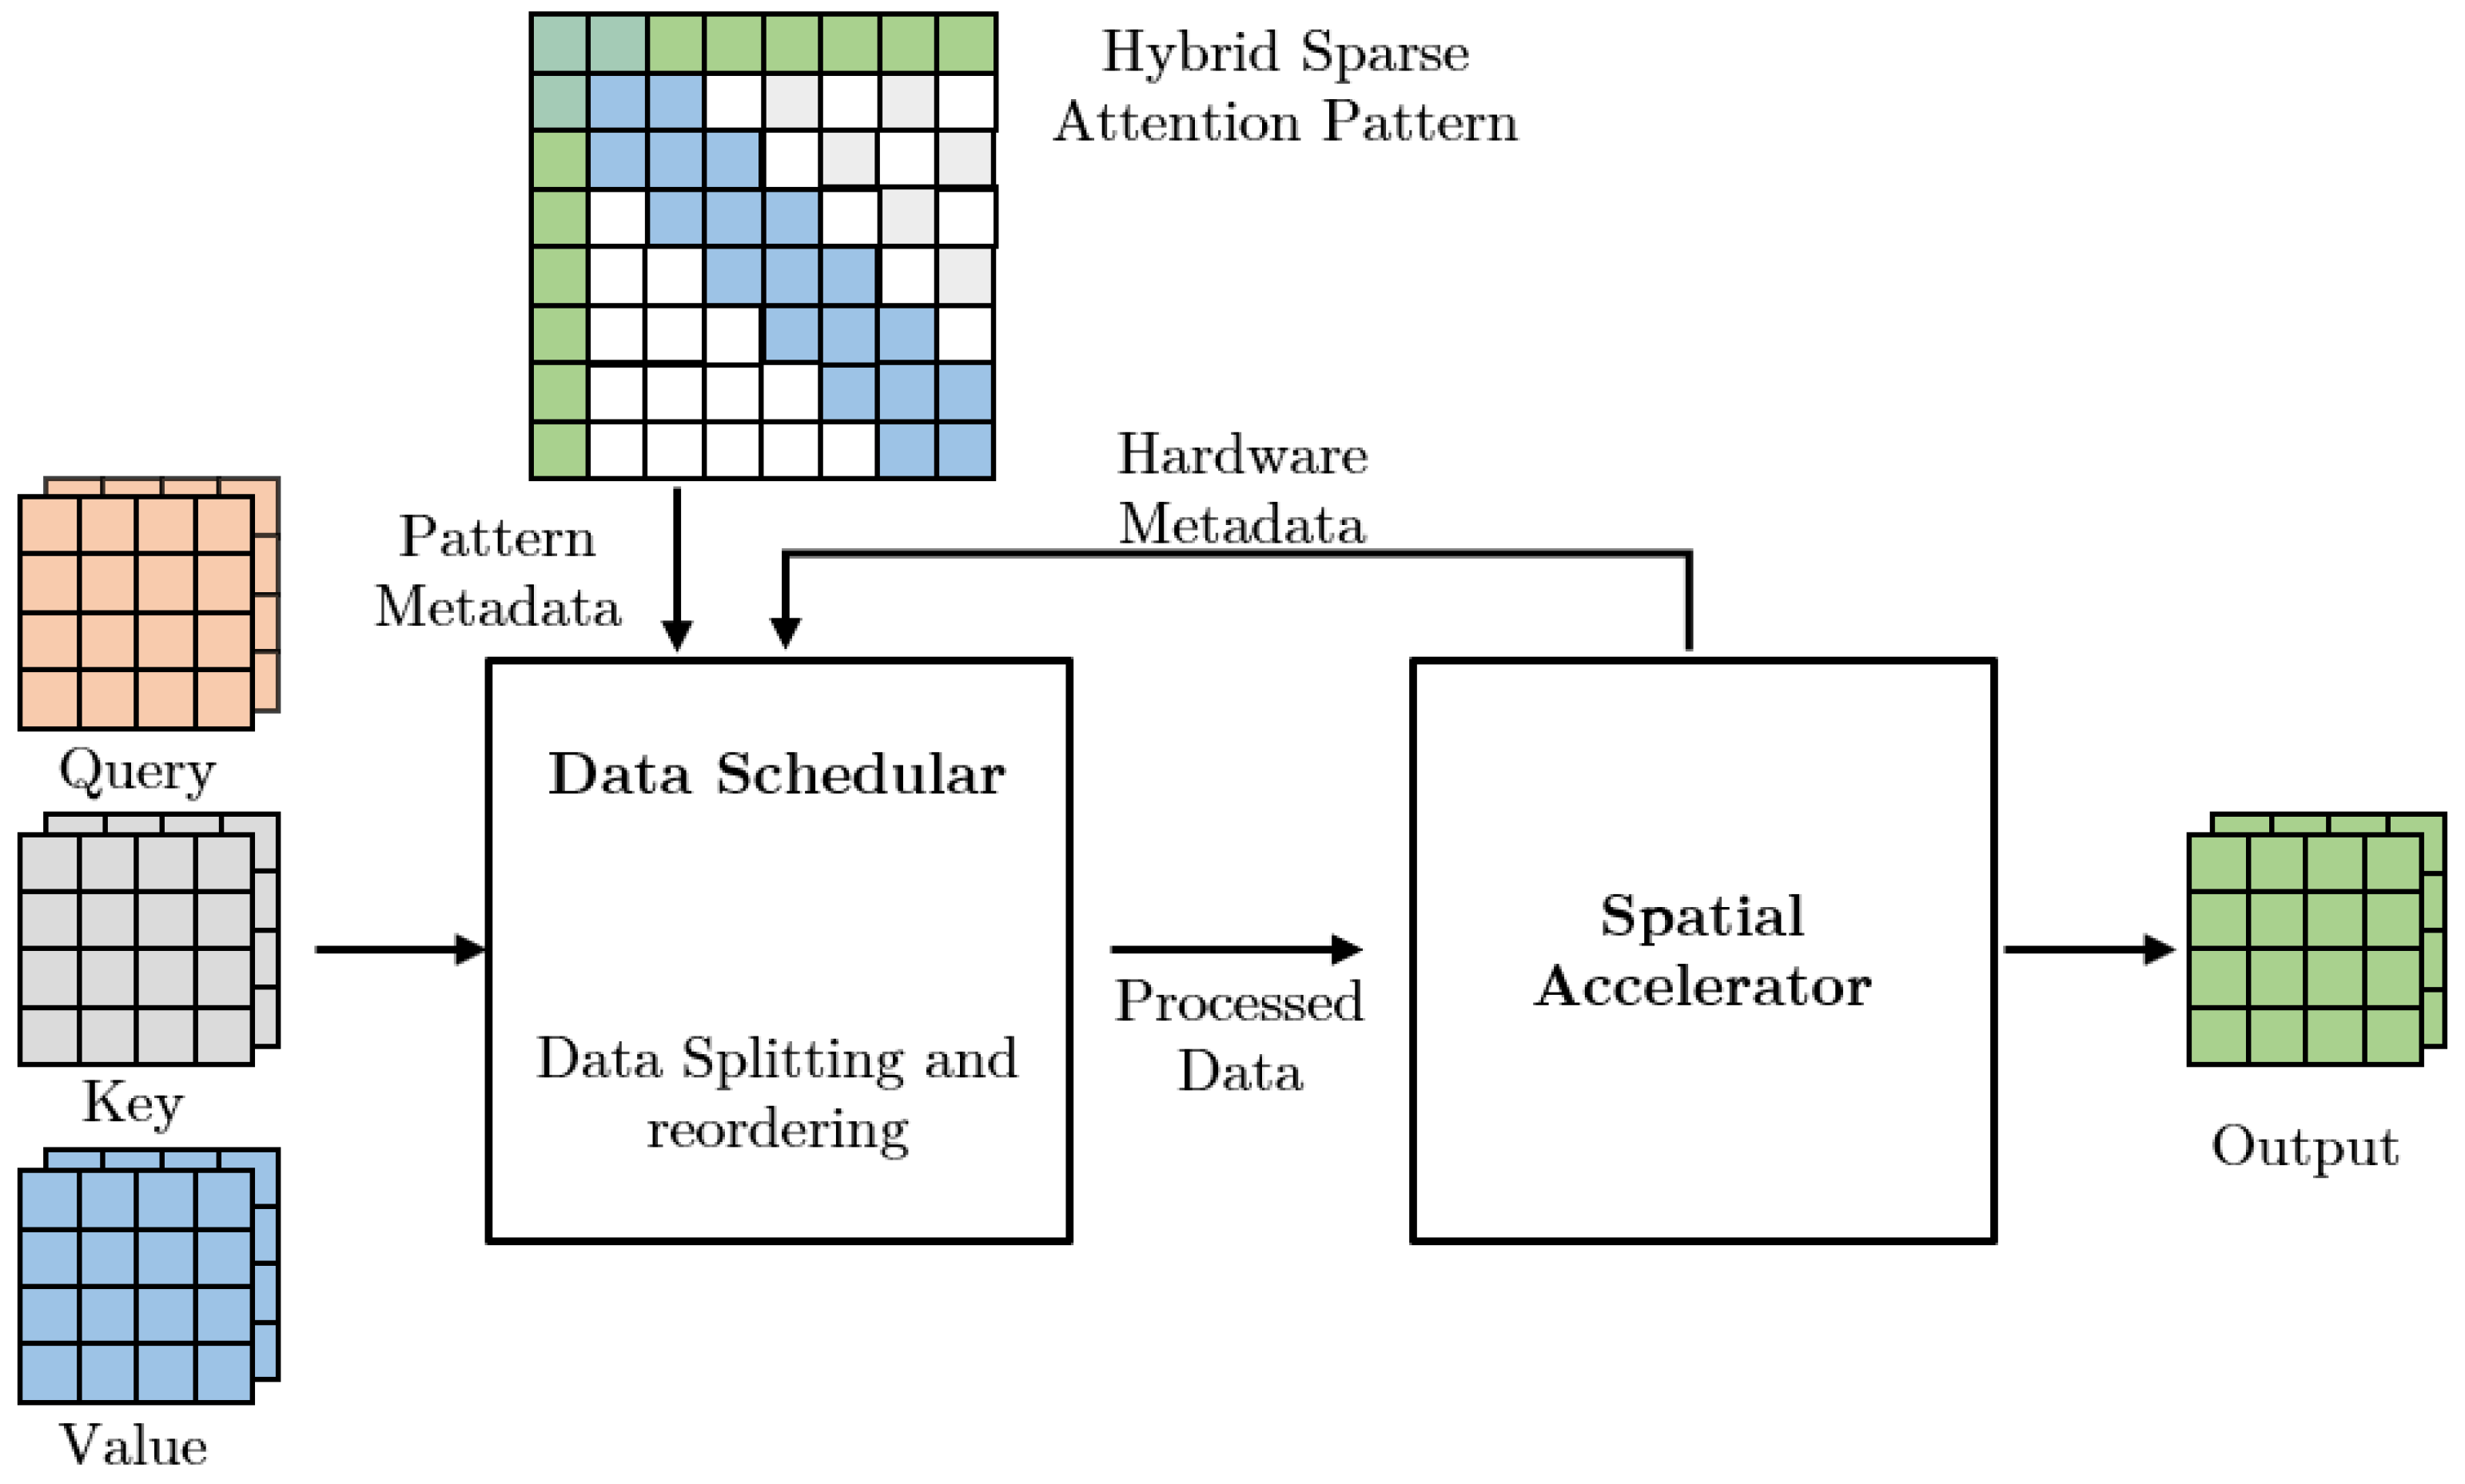
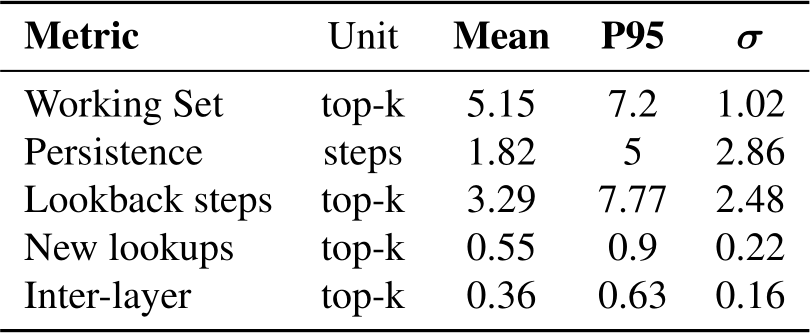
Dynamic Sparse Attention: Access Patterns and Architecture
Trainable Dynamic Mask Sparse Attention: Bridging Efficiency and ...
[논문 리뷰] MiniCPM-SALA: Hybridizing Sparse and Linear Attention for ...
[논문 리뷰] RRAttention: Dynamic Block Sparse Attention via Per-Head Round ...
[논문 리뷰] DashAttention: Differentiable and Adaptive Sparse Hierarchical ...
[논문 리뷰] Scaling Graph Transformers: A Comparative Study of Sparse and ...
[논문 리뷰] DSparsE: Dynamic Sparse Embedding for Knowledge Graph Completion
[논문 리뷰] Sparser is Faster and Less is More: Efficient Sparse Attention ...
[논문 리뷰] Flash Sparse Attention: An Alternative Efficient Implementation ...
[논문 리뷰] Improving Sparse Autoencoder with Dynamic Attention
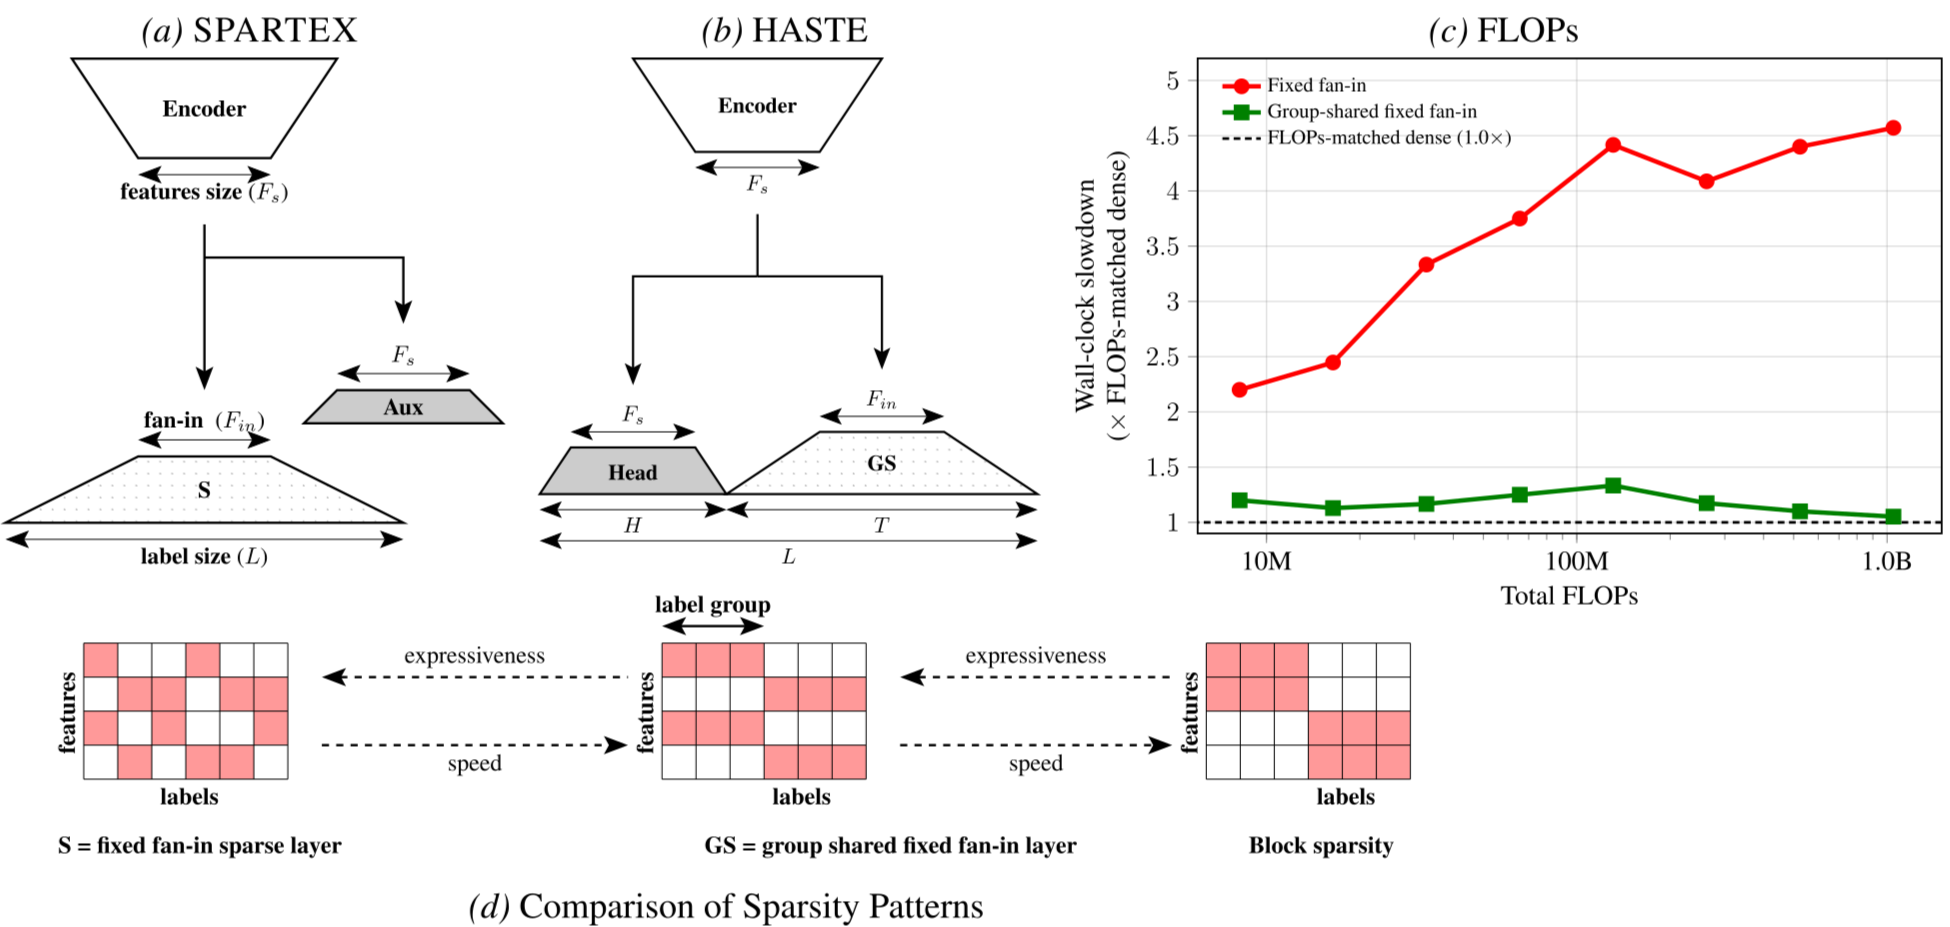
[논문 리뷰] HASTE: Hardware-Aware Dynamic Sparse Training for Large Output ...
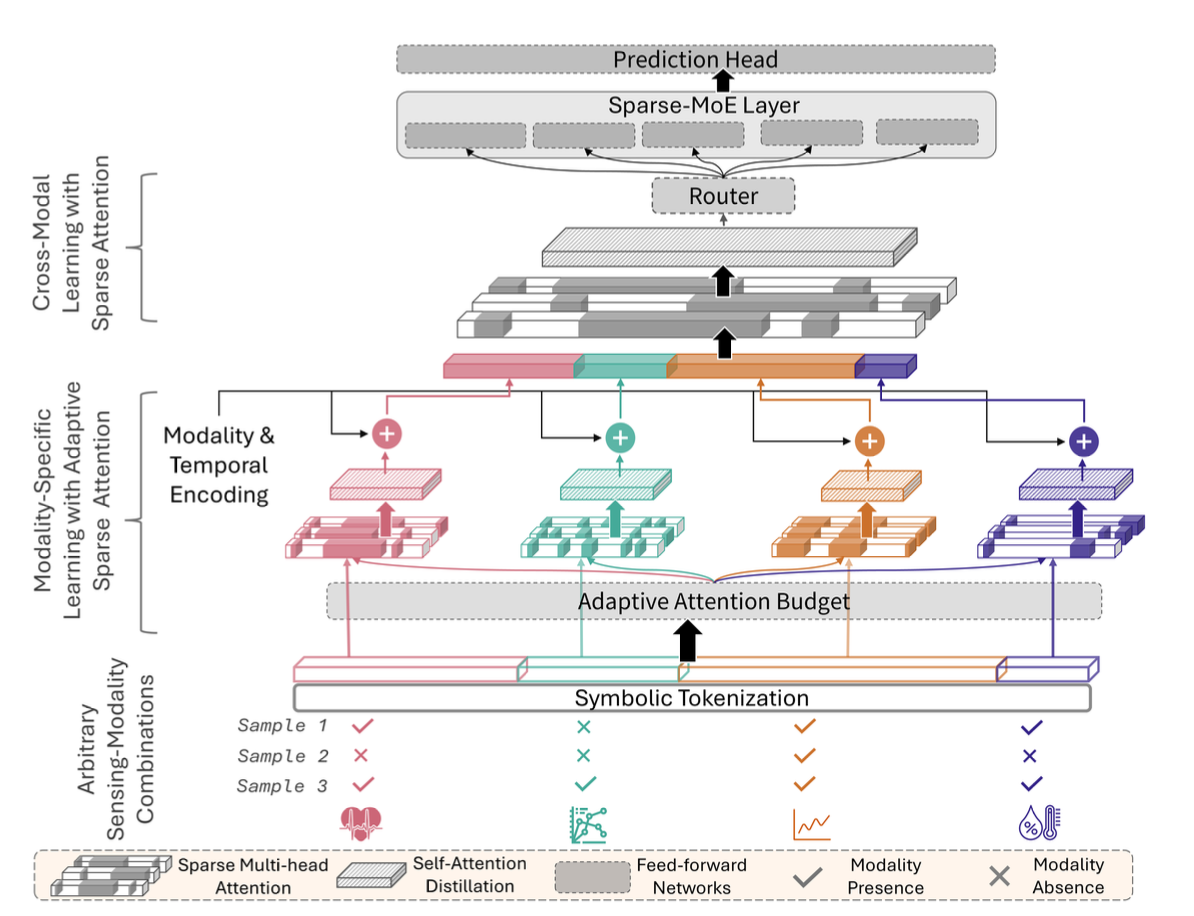
[논문 리뷰] MAESTRO : Adaptive Sparse Attention and Robust Learning for ...
[논문 리뷰] Dynamic Training-Free Fusion of Subject and Style LoRAs
[논문 리뷰] Strengthening Layer Interaction via Dynamic Layer Attention
[논문 리뷰] BlossomRec: Block-level Fused Sparse Attention Mechanism for ...
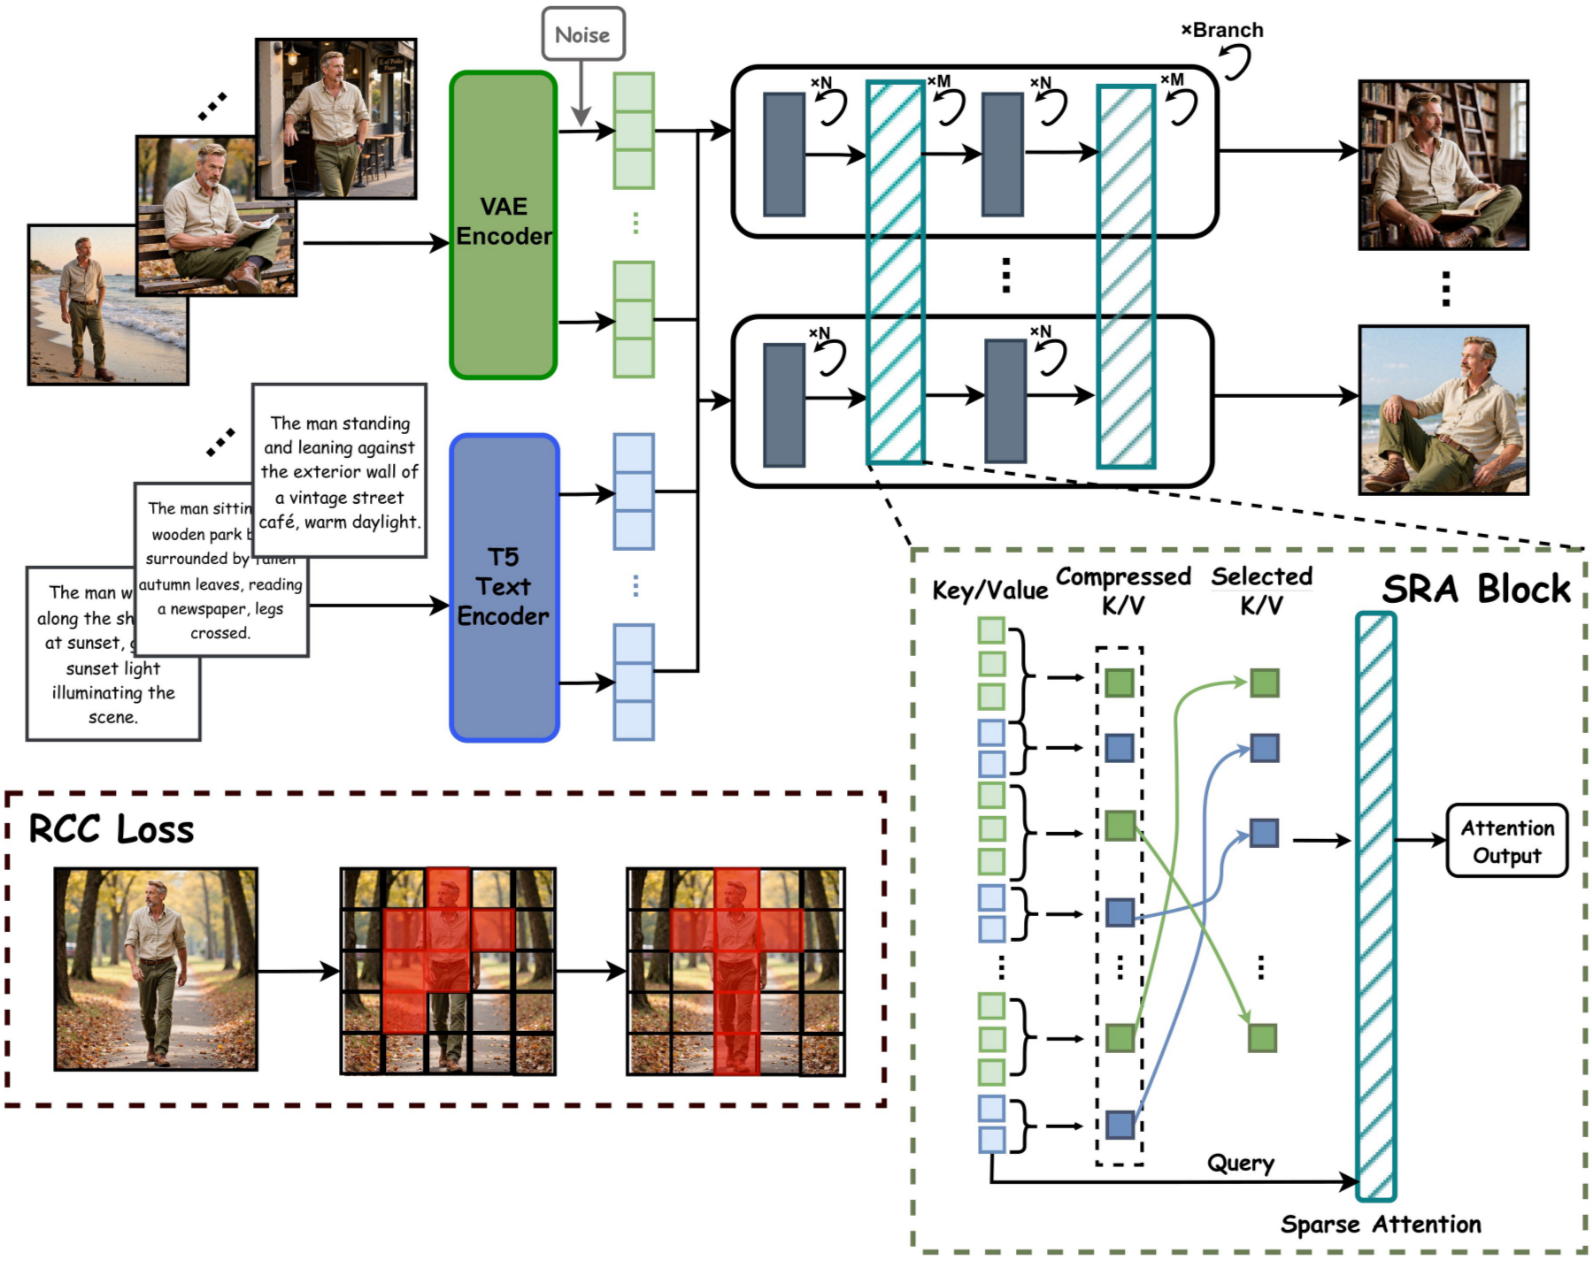
[논문 리뷰] LCG: Long-Context Consistent Image Generation with Sparse ...
[논문 리뷰] PSA: Pyramid Sparse Attention for Efficient Video Understanding ...
[논문 리뷰] Adamas: Hadamard Sparse Attention for Efficient Long-Context ...
[논문 리뷰] SeerAttention: Learning Intrinsic Sparse Attention in Your LLMs
[논문 리뷰] DynamicRad: Content-Adaptive Sparse Attention for Long Video ...
[논문 리뷰] Faster Video Diffusion with Trainable Sparse Attention
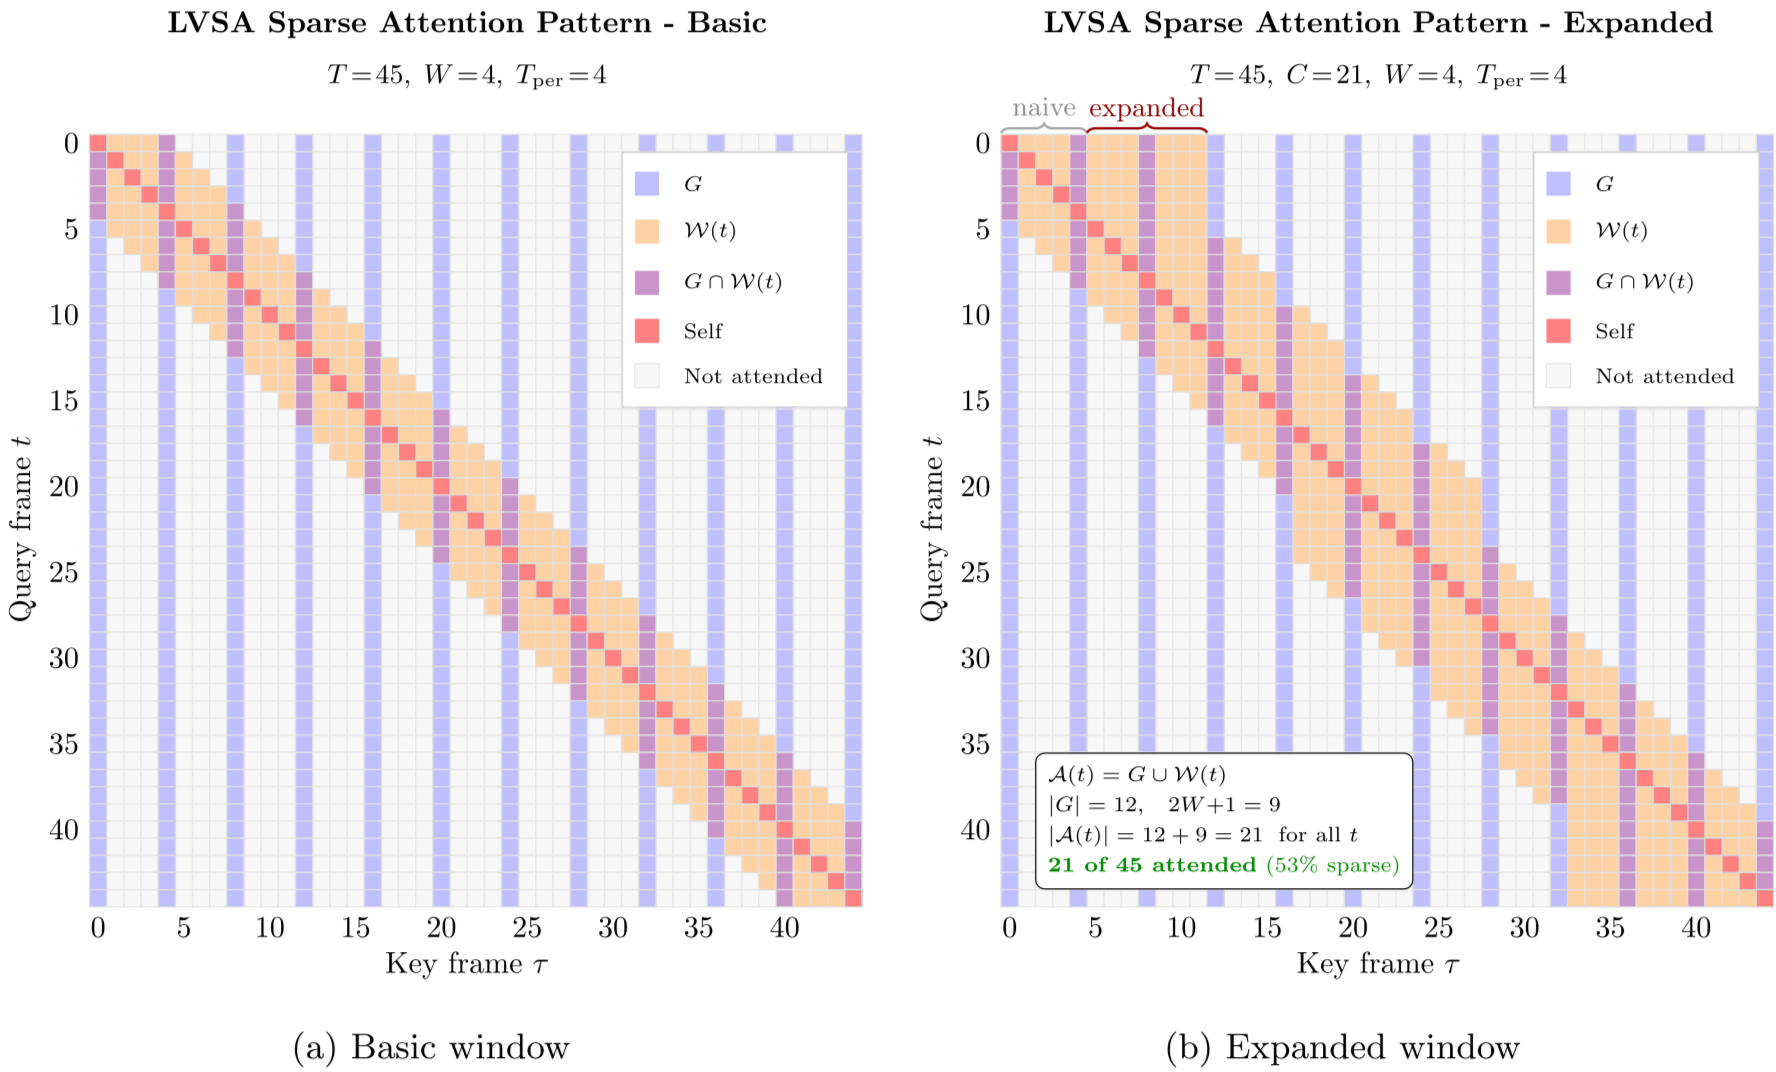
[논문 리뷰] LVSA: Training-Free Sparse Attention for Long Video Diffusion
[논문 리뷰] Trainable Log-linear Sparse Attention for Efficient Diffusion ...
[논문 리뷰] The Sparse Frontier: Sparse Attention Trade-offs in Transformer ...
[논문 리뷰] Attention-Guided Patch-Wise Sparse Adversarial Attacks on ...
[논문 리뷰] STS: Efficient Sparse Attention with Speculative Token Sparsity
[논문 리뷰] VideoNSA: Native Sparse Attention Scales Video Understanding
[논문 리뷰] An Efficient Hybrid Sparse Attention with CPU-GPU Parallelism ...
[논문 리뷰] VSPrefill: Vertical-Slash Sparse Attention with Lightweight ...
[논문 리뷰] Rectified Sparse Attention
[논문 리뷰] VRS-NeRF: Visual Relocalization with Sparse Neural Radiance Field
[논문 리뷰] Efficient Transformer-Based Piano Transcription With Sparse ...
[논문 리뷰] Interpreting Attention Layer Outputs with Sparse Autoencoders
[논문 리뷰] GraphFusion3D: Dynamic Graph Attention Convolution with ...
[논문 리뷰] SparseD: Sparse Attention for Diffusion Language Models
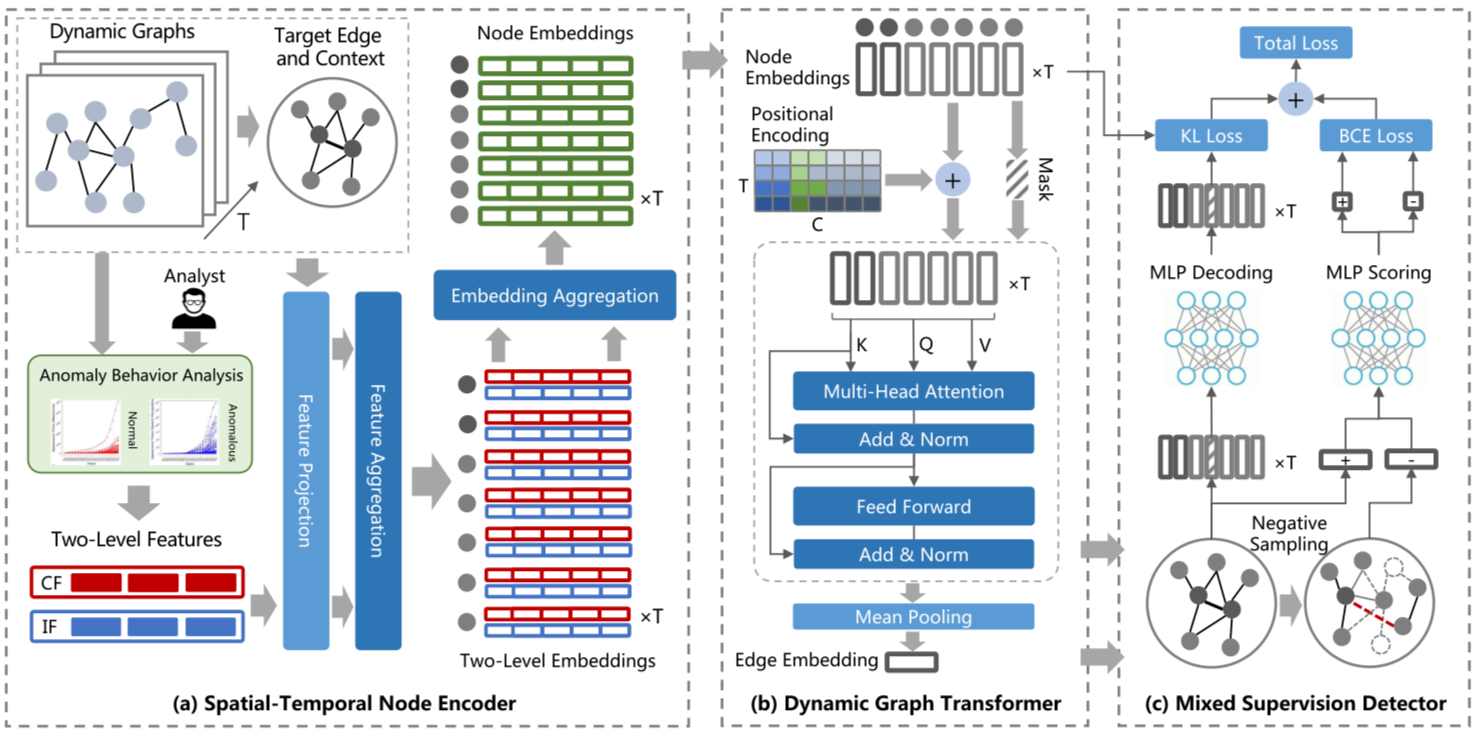
[논문 리뷰] Structural-Temporal Coupling Anomaly Detection with Dynamic ...
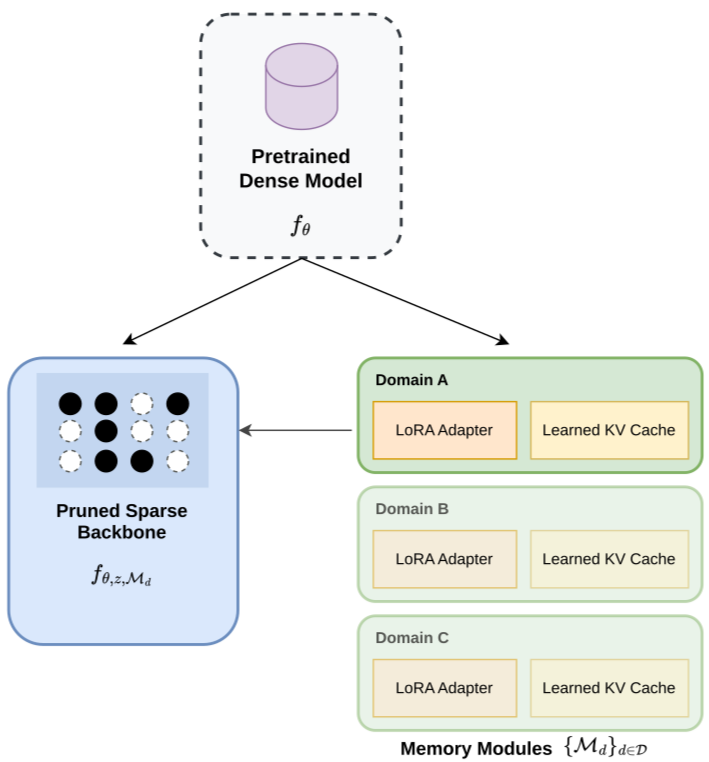
[논문 리뷰] Knowledge Offloading: Decomposing LLMs into Sparse Backbones ...
[논문 리뷰] FlashInfer: Efficient and Customizable Attention Engine for LLM ...
[논문 리뷰] Orion-MSP: Multi-Scale Sparse Attention for Tabular In-Context ...
[논문 리뷰] PointGS: Point Attention-Aware Sparse View Synthesis with ...
[논문 리뷰] Federated LoRA with Sparse Communication
[논문 리뷰] FeedbackSTS-Det: Sparse Frames-Based Spatio-Temporal Semantic ...
[논문 리뷰] DBMovi-GS: Dynamic View Synthesis from Blurry Monocular Video ...
[논문 리뷰] Meta-Sparsity: Learning Optimal Sparse Structures in Multi-task ...
[논문 리뷰] Self-Indexing KVCache: Predicting Sparse Attention from ...
[논문 리뷰] Hierarchical Sparse Attention Framework for Computationally ...
[논문 리뷰] SPOT-Occ: Sparse Prototype-guided Transformer for Camera-based ...
[논문 리뷰] SnipSnap: A Joint Compression Format and Dataflow Co ...
[논문 리뷰] Sparse Deformable Mamba for Hyperspectral Image Classification
[논문 리뷰] SALS: Sparse Attention in Latent Space for KV cache Compression
The architecture of adaptive sparse attention-based feature fusion ...
MAESTRO: Adaptive Sparse Attention and Robust Learning for Multimodal ...
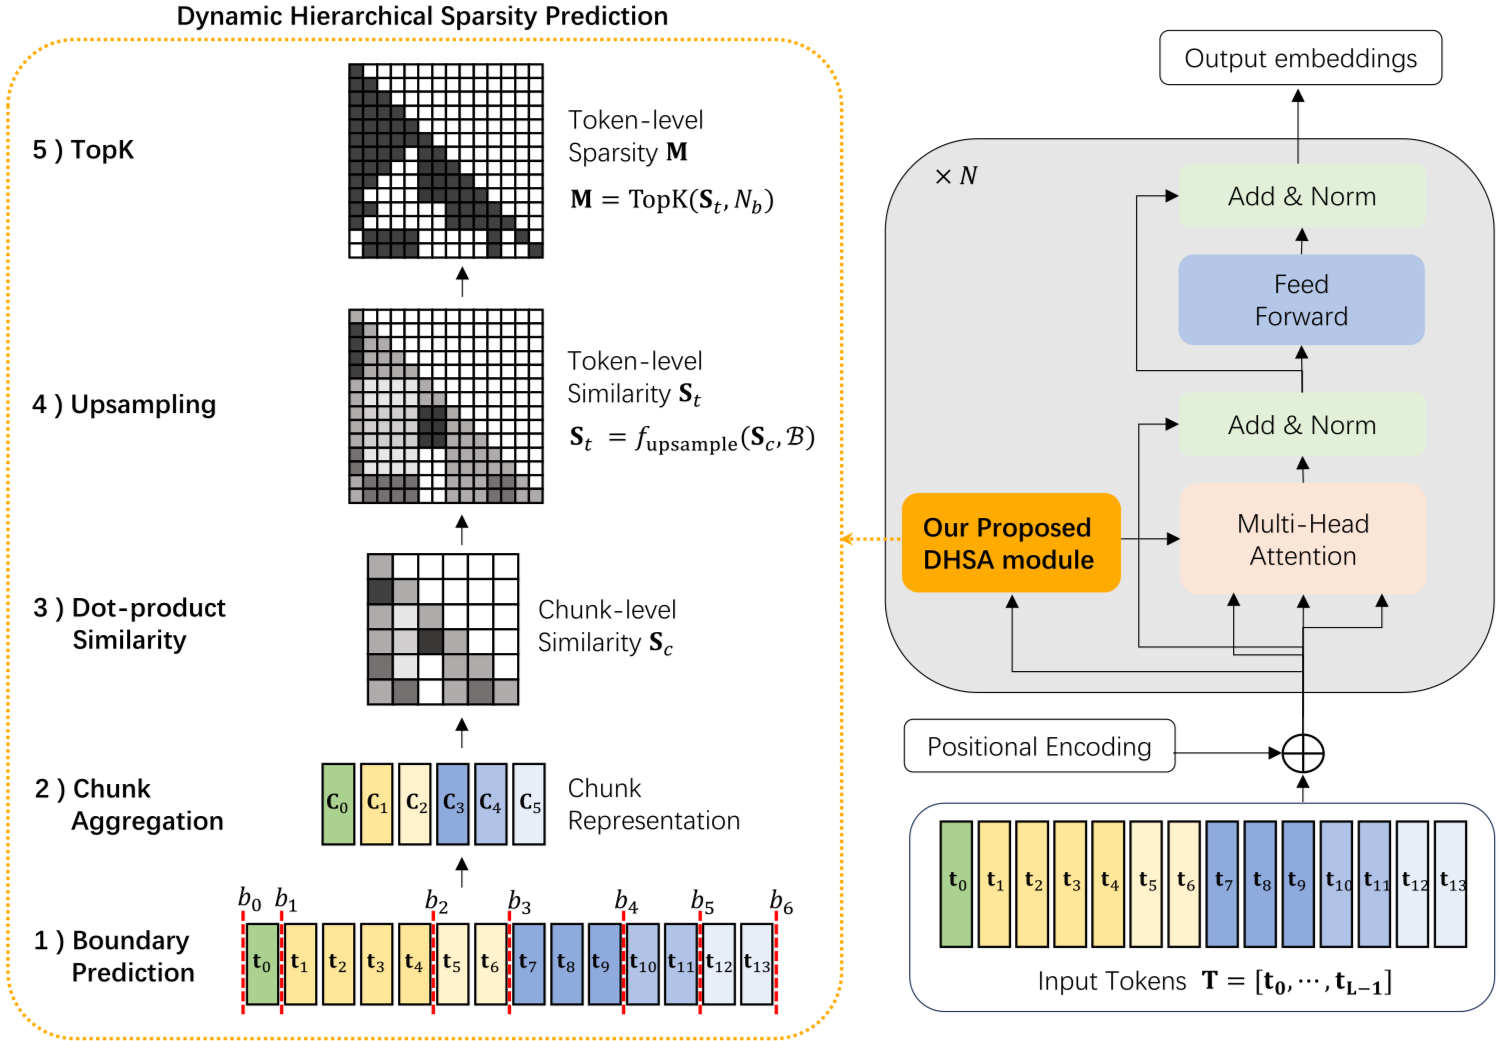
[論文レビュー] Long-Context Modeling with Dynamic Hierarchical Sparse ...
Trainable Dynamic Mask Sparse Attention | AI Research Paper Details
[논문 리뷰] PowerAttention: Exponentially Scaling of Receptive Fields for ...
[논문 리뷰] Extra Global Attention Designation Using Keyword Detection in ...
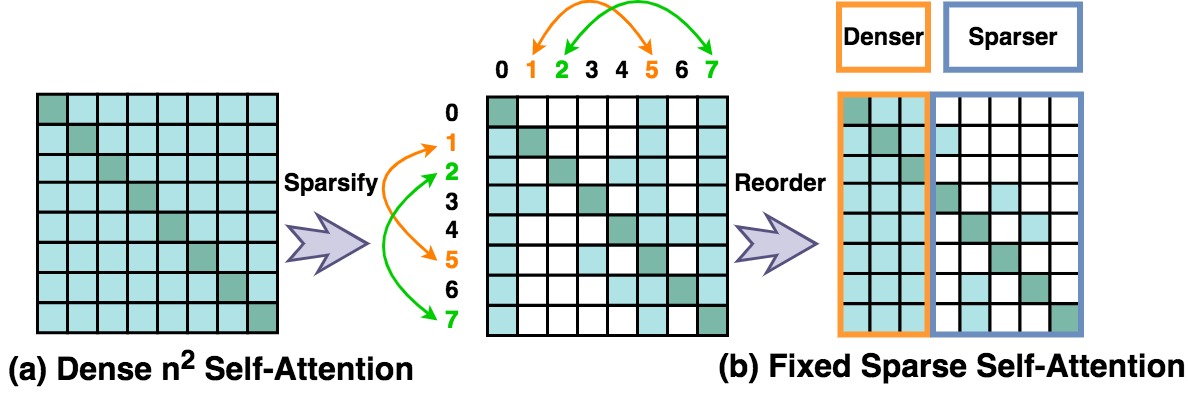
Dynamic Sparse Attention For Scalable Transformer Acceleration | PDF ...
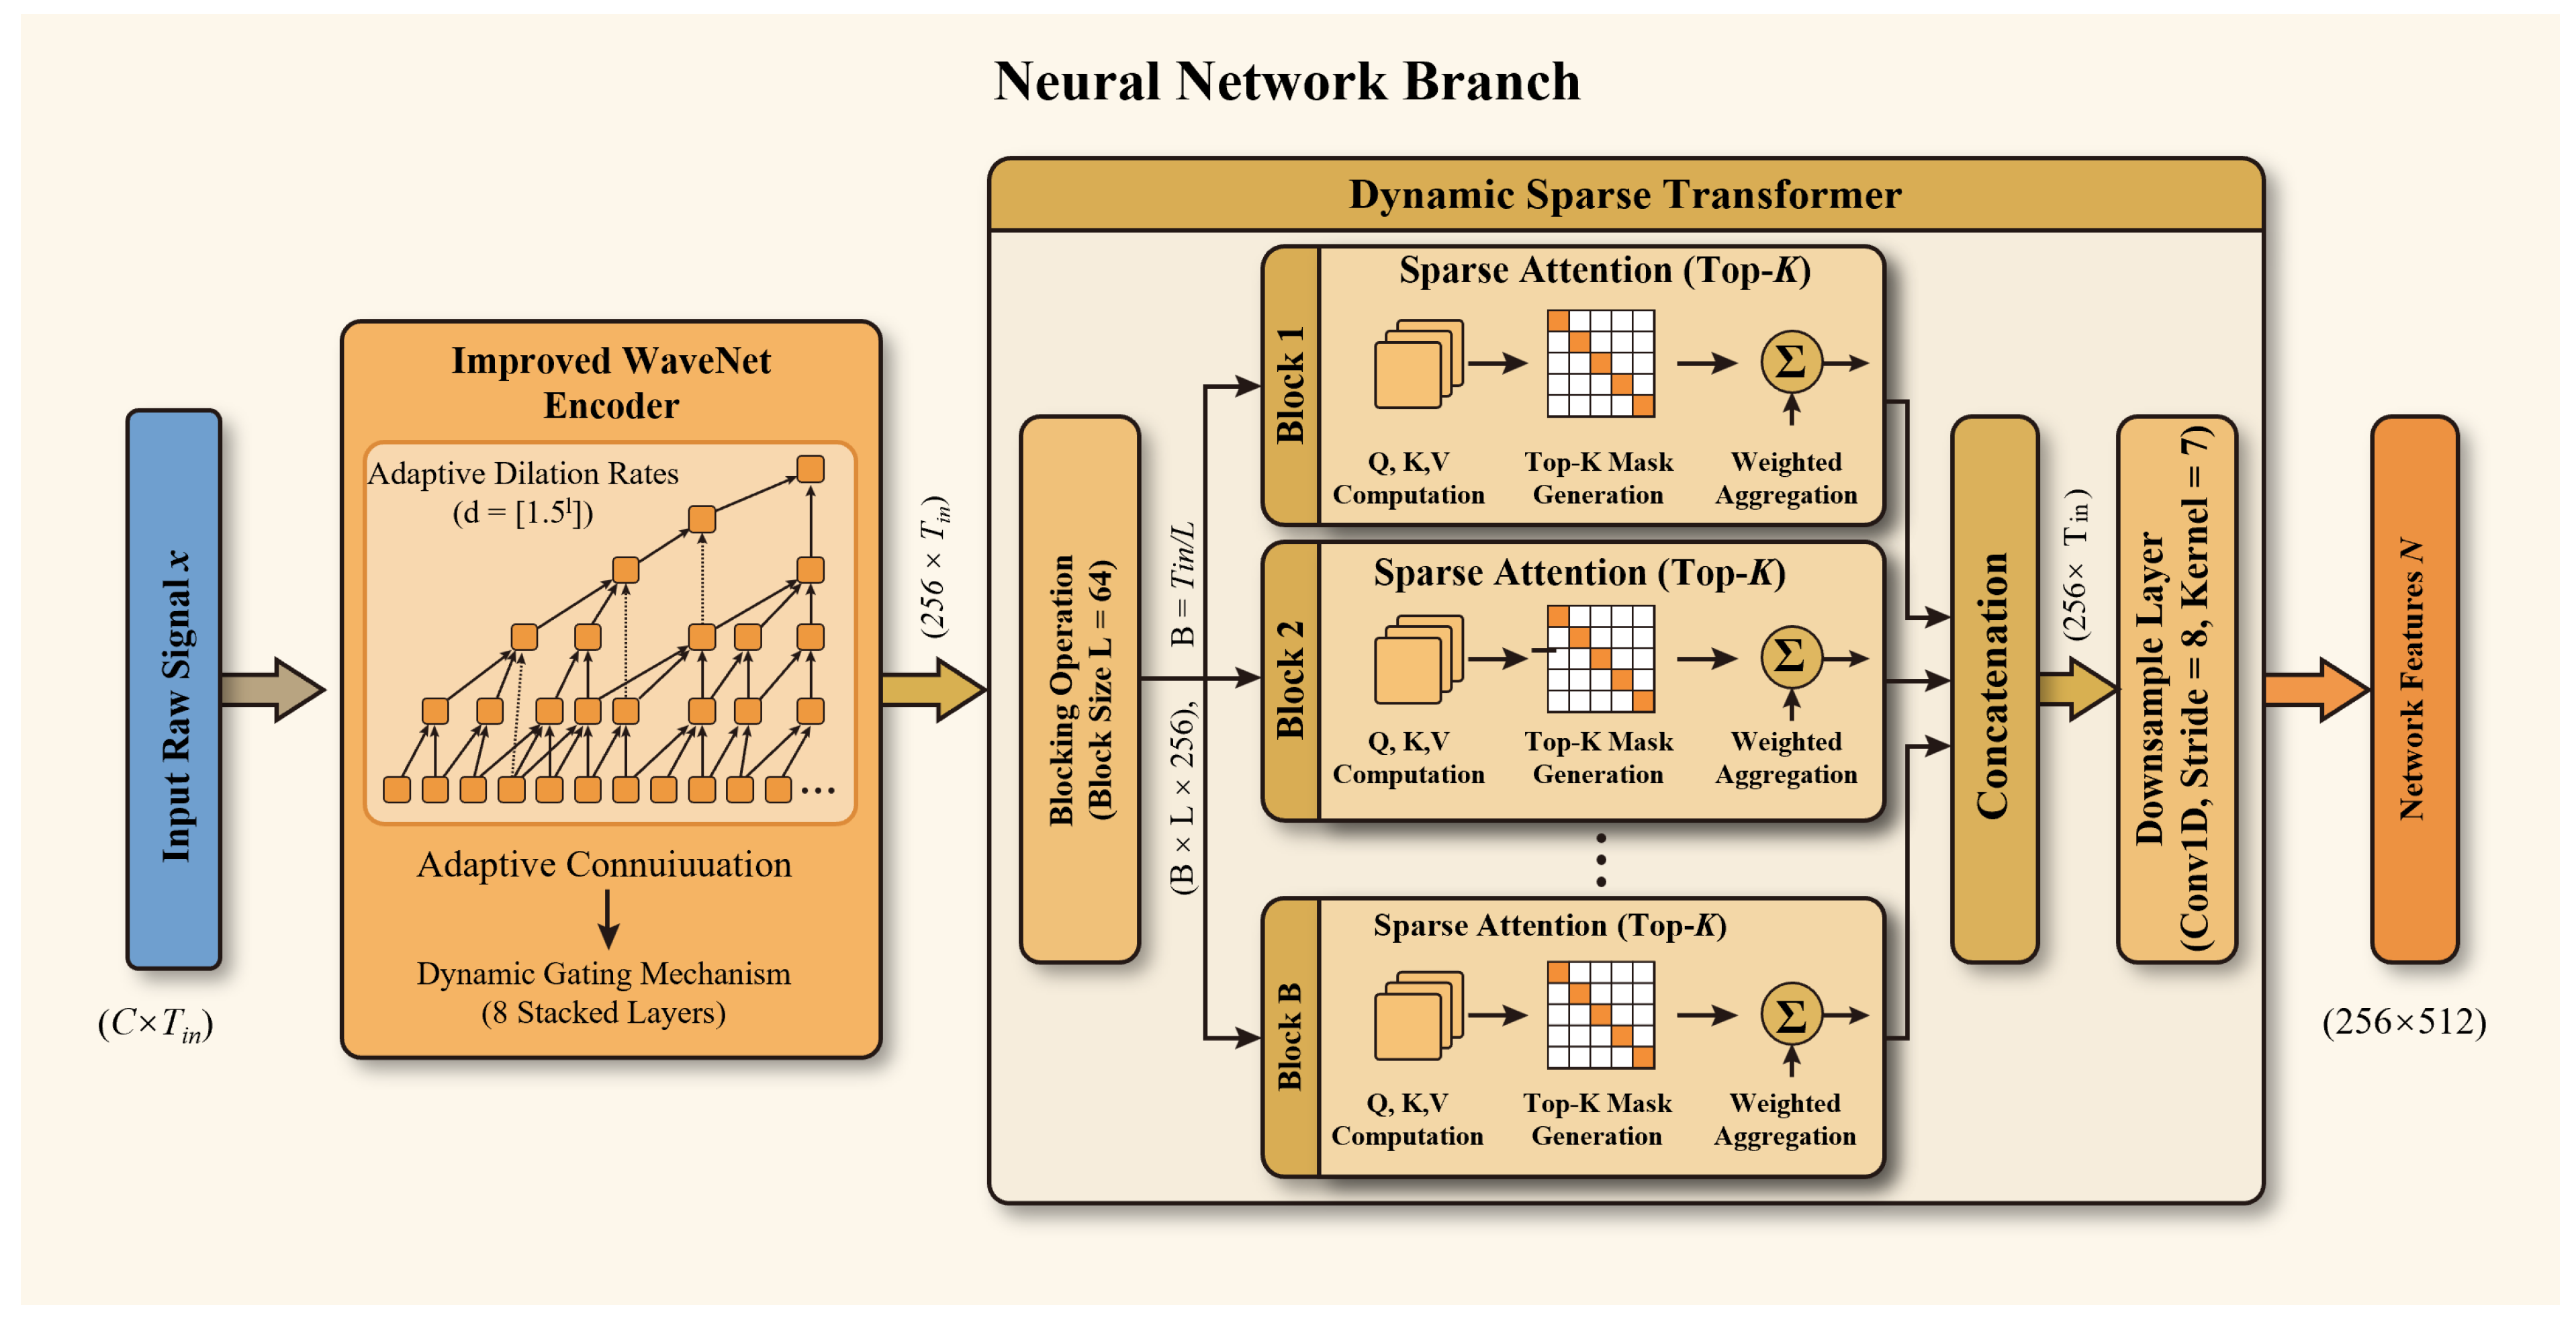
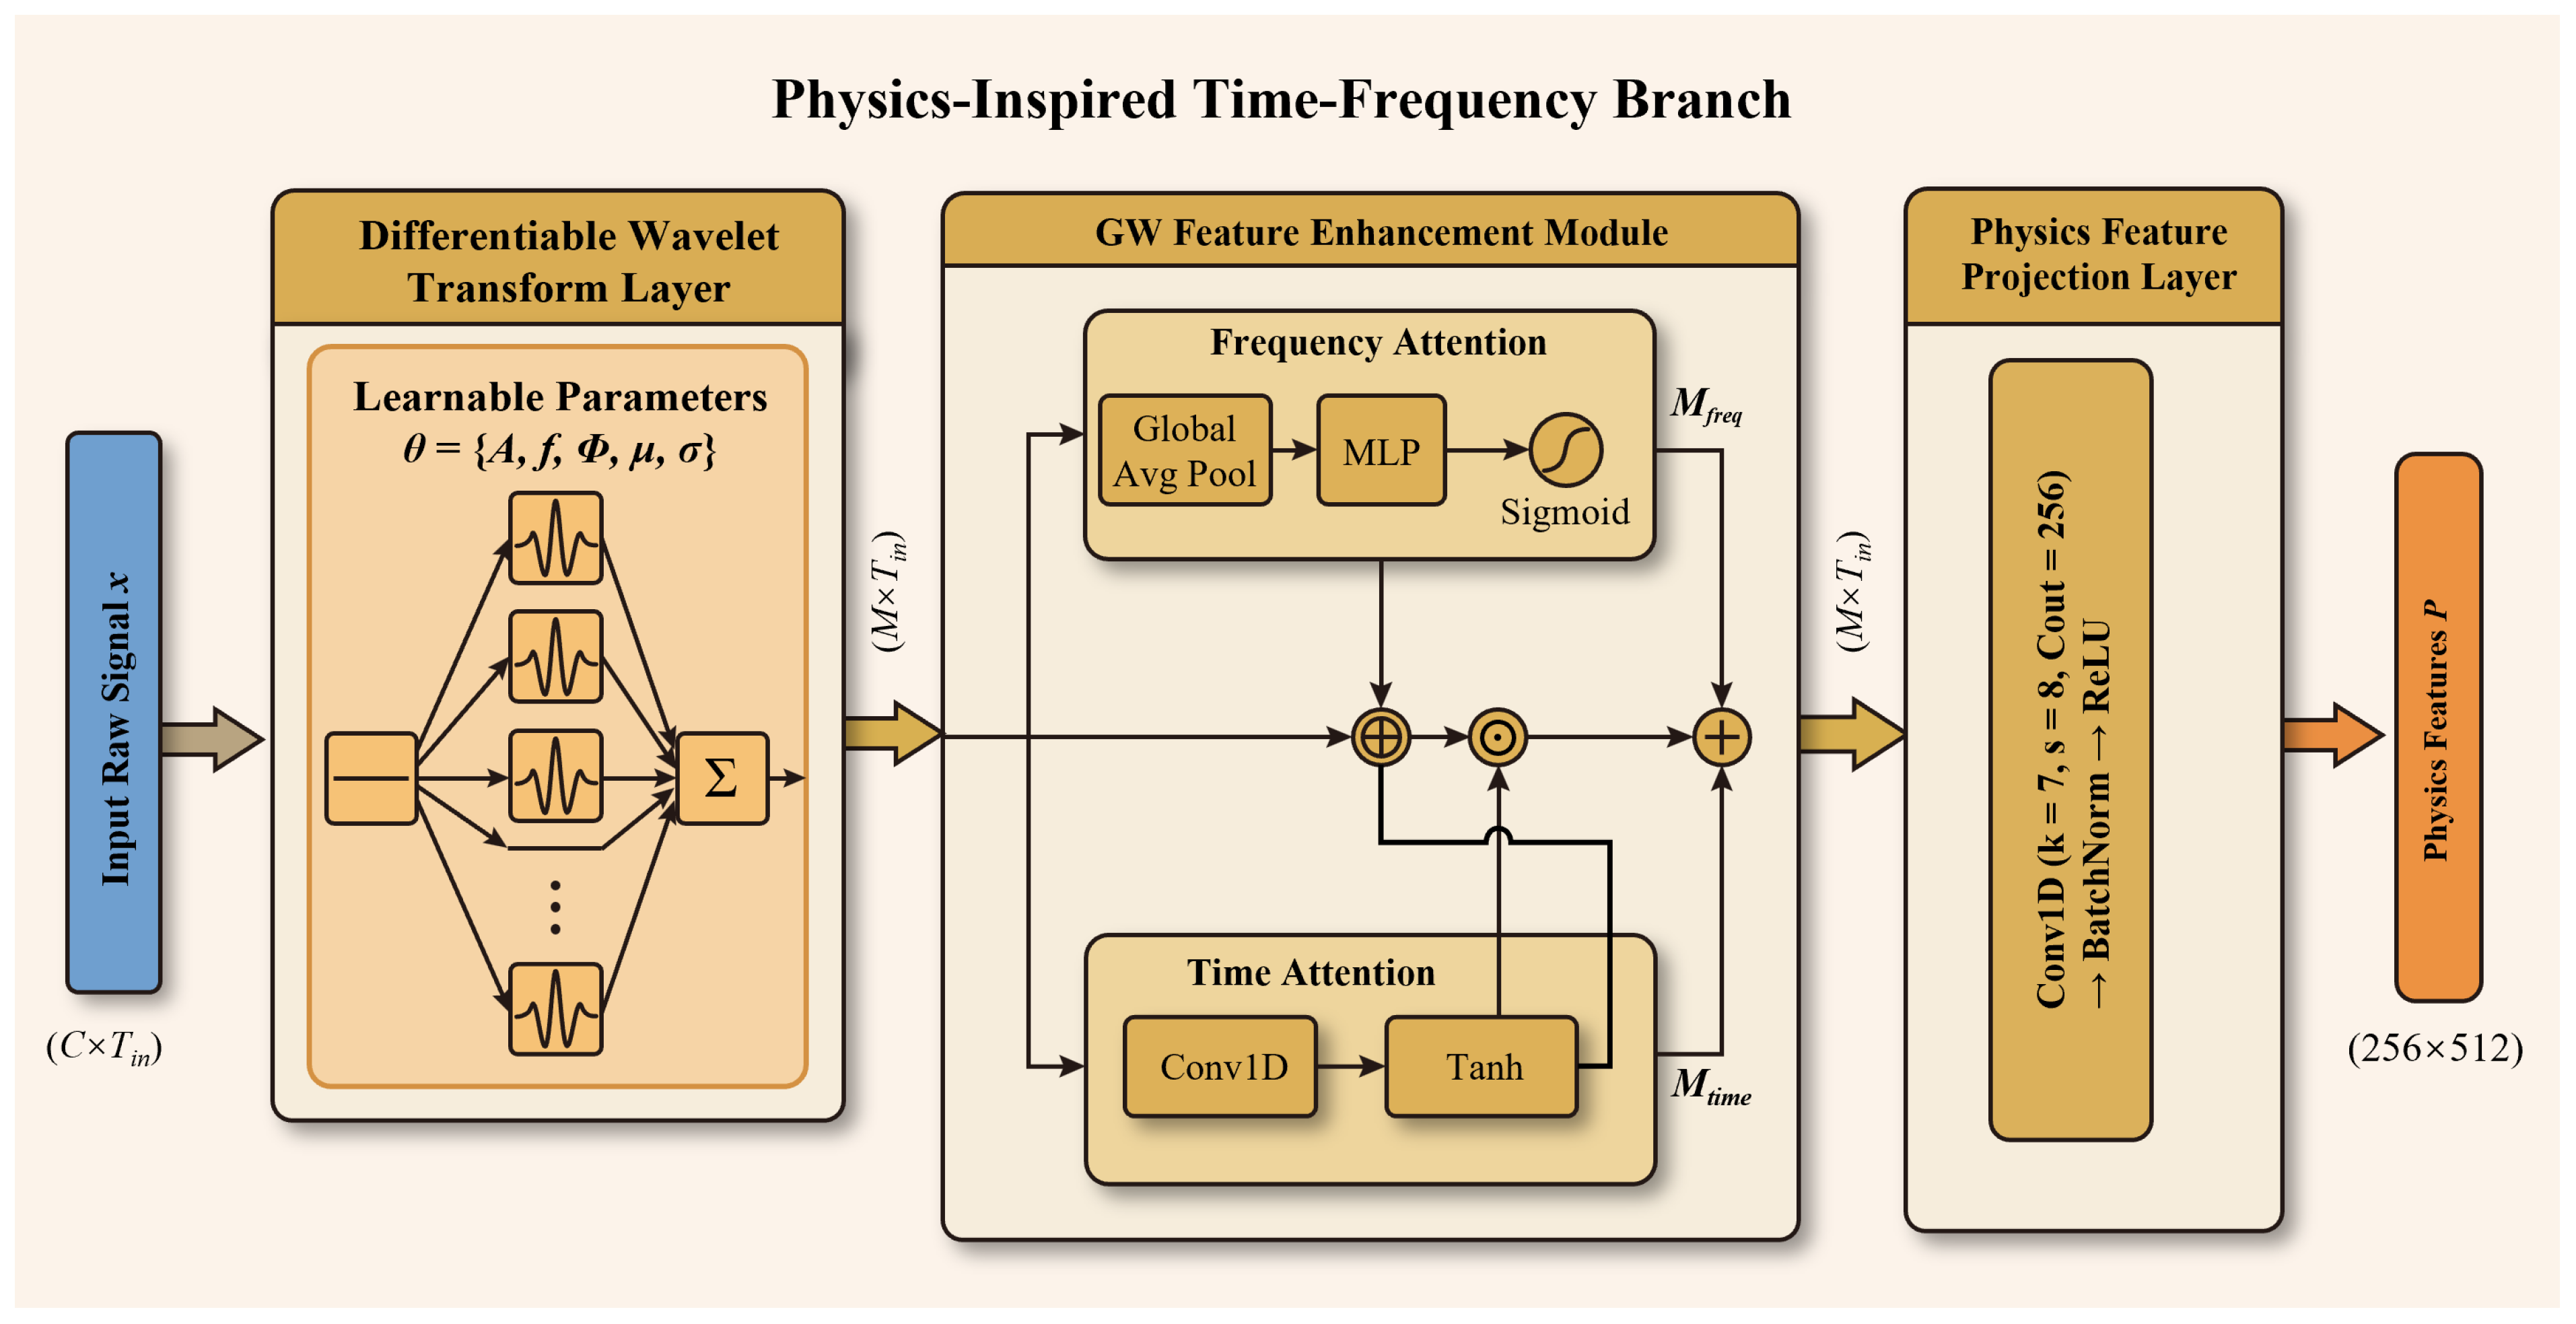
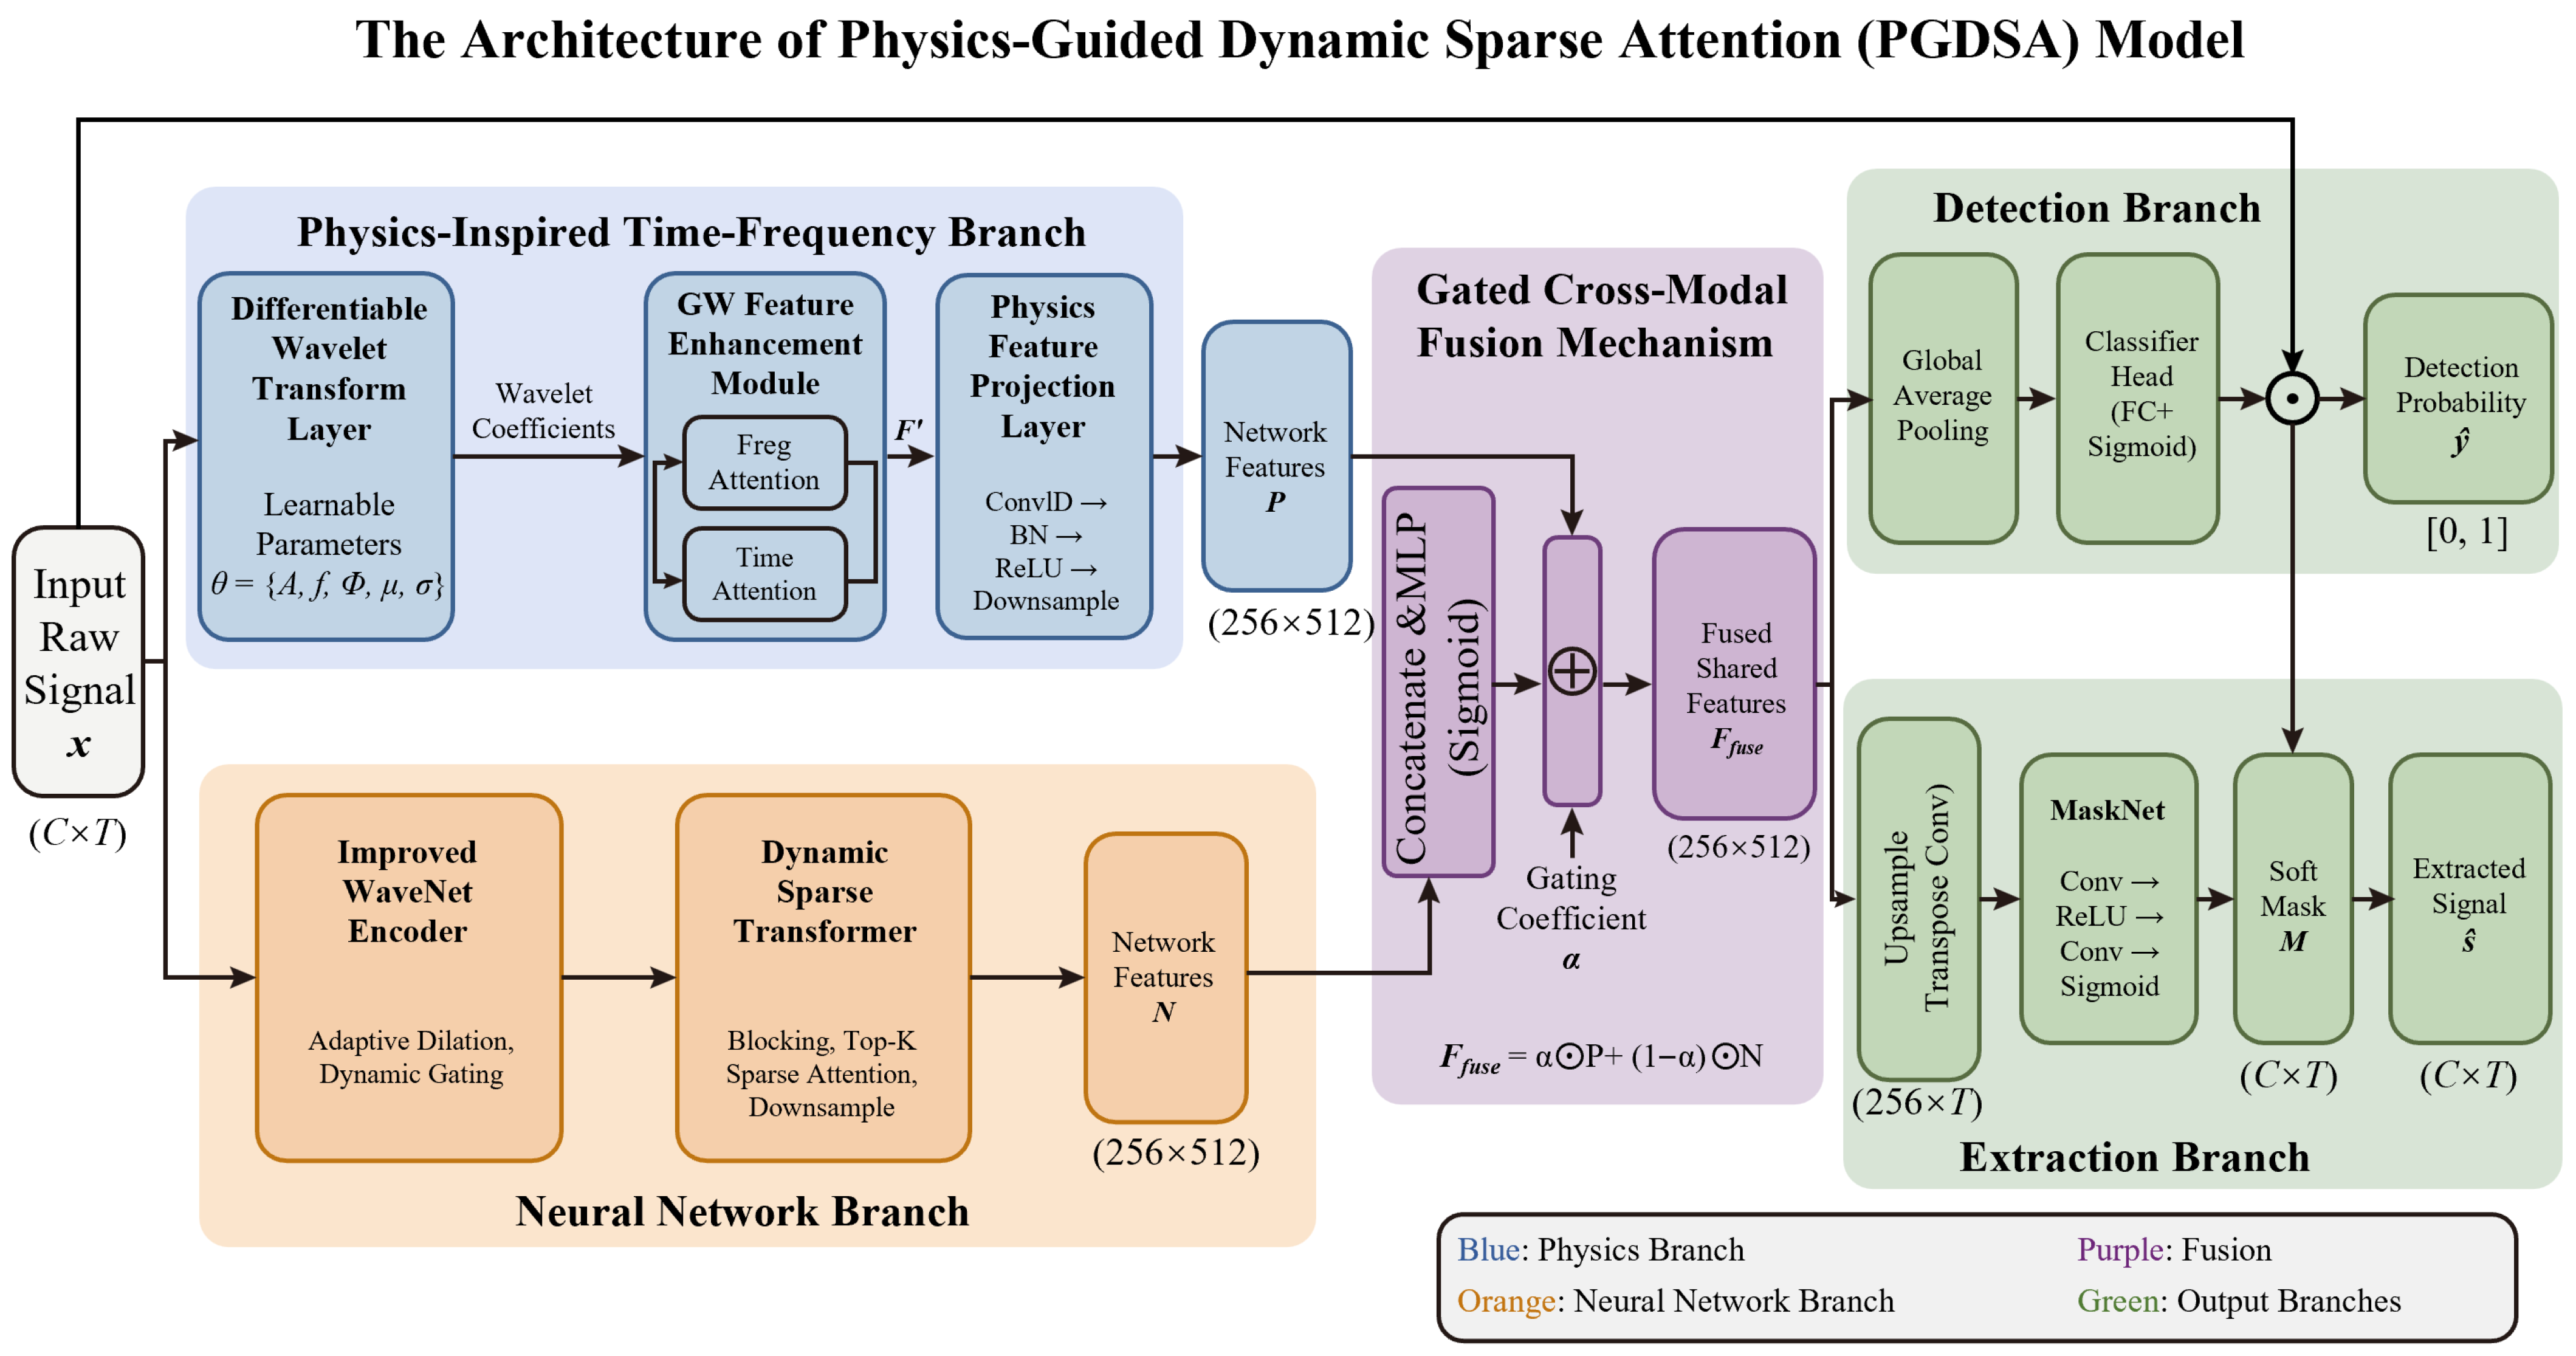
Physics-Guided Dynamic Sparse Attention Network for Gravitational Wave ...
DSF-Net: Dynamic Sparse Fusion of Event-RGB via Spike-Triggered ...
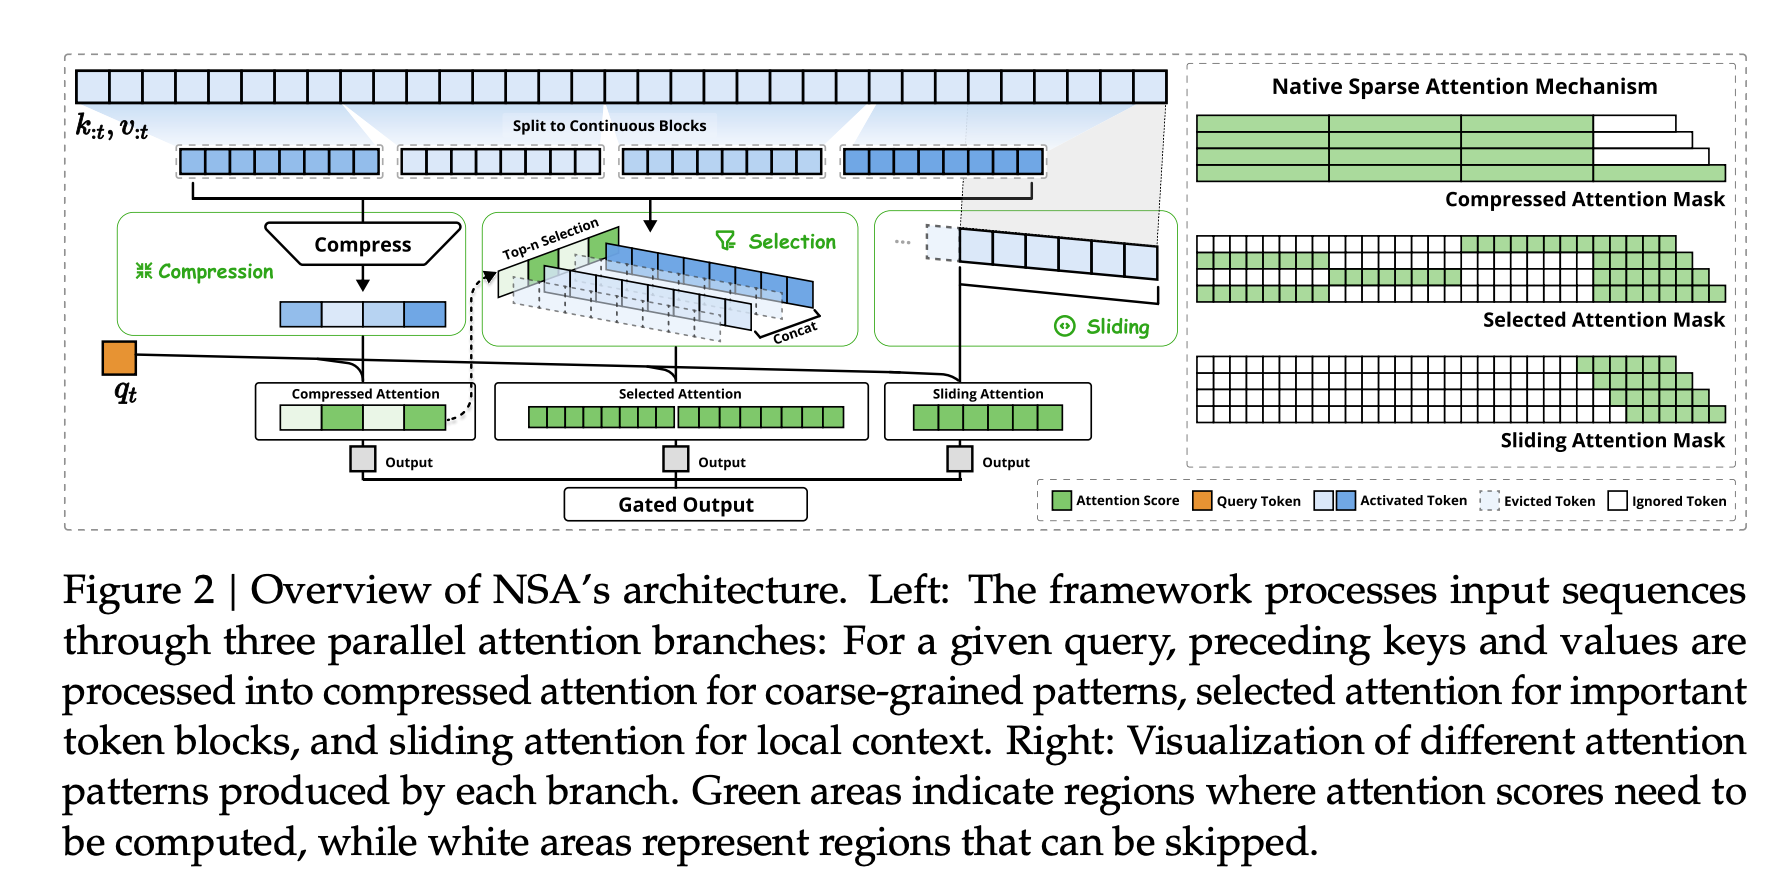
🚀 Introducing NSA: A Hardware-Aligned and Natively Trainable Sparse ...
Figure 10 from Hardware–Software Co-Design Enabling Static and Dynamic ...
Incremental Learning of Sparse Attention Patterns in Transformers | AI ...
[논문 리뷰] Attention-based multiple instance learning for predominant ...
Transformer Acceleration with Dynamic Sparse Attention | DeepAI
[논문 리뷰] Attentional Graph Meta-Learning for Indoor Localization Using ...
[논문 리뷰] MoGA: Mixture-of-Groups Attention for End-to-End Long Video ...
[논문 리뷰] Stream: Scaling up Mechanistic Interpretability to Long Context ...
Optimizing Native Sparse Attention with Latent Attention and Local ...
Figure 9 from DSAP: Dynamic Sparse Attention Perception Matcher for ...
Structure of LASEM. A lightweight attention module and a sparse ...
Figure 2 from PIT: Optimization of Dynamic Sparse Deep Learning Models ...
(논문 요약) Native Sparse Attention; Hardware-Aligned and Natively ...
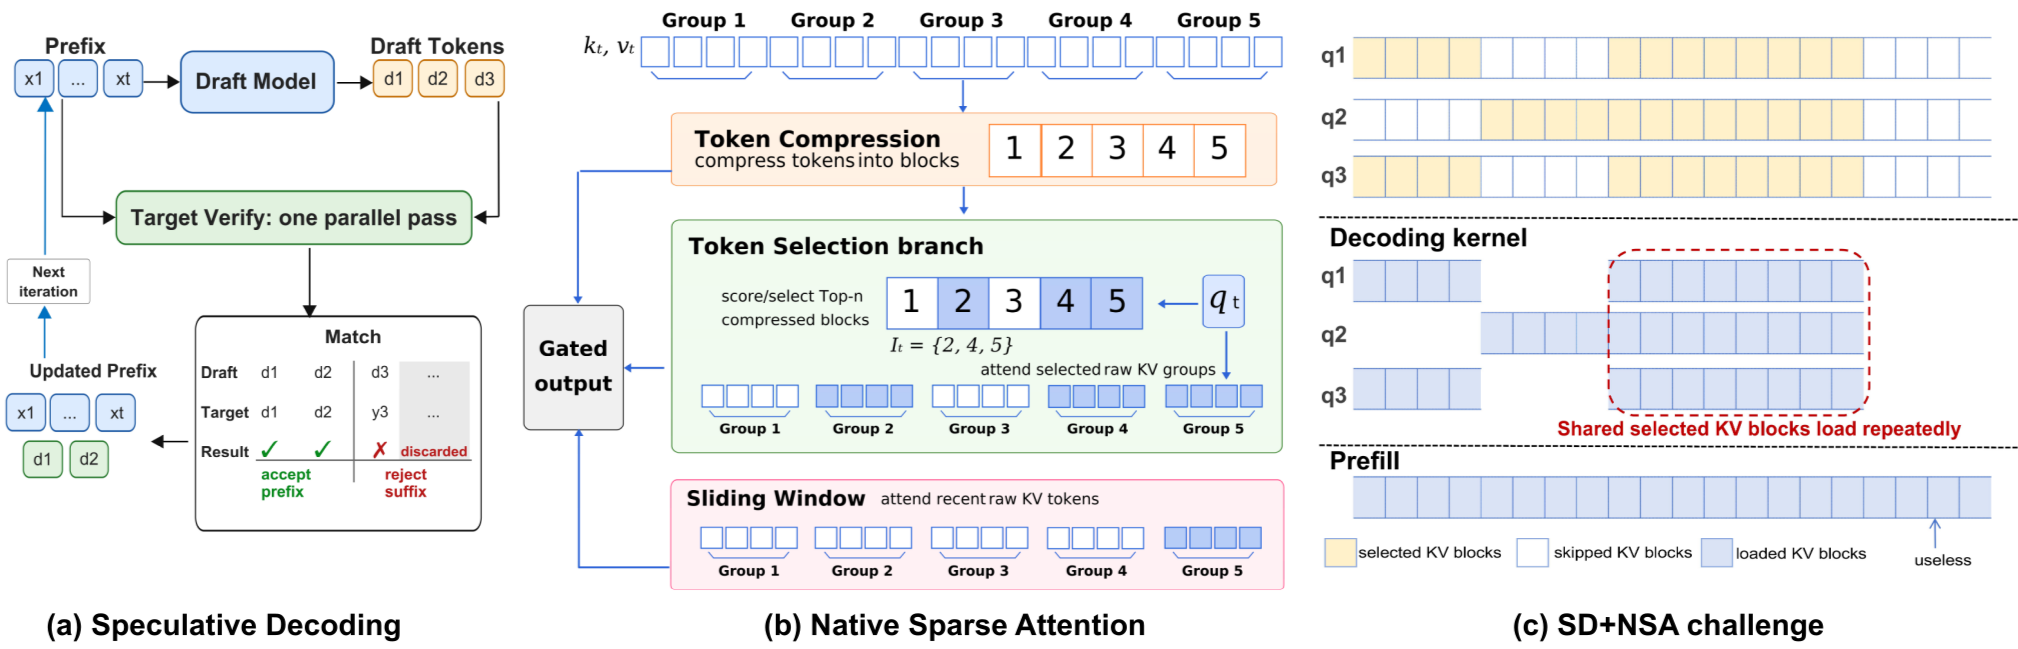
[论文评述] SpecSA: Bridging Speculative Decoding and Sparse Attention for ...
[논문 리뷰] Towards Understanding the Nature of Attention with Low-Rank ...
DeepSeek V4 architecture deep dive - by Hamza Farooq
Attention patterns for the examined architectures: Hierarchical ...
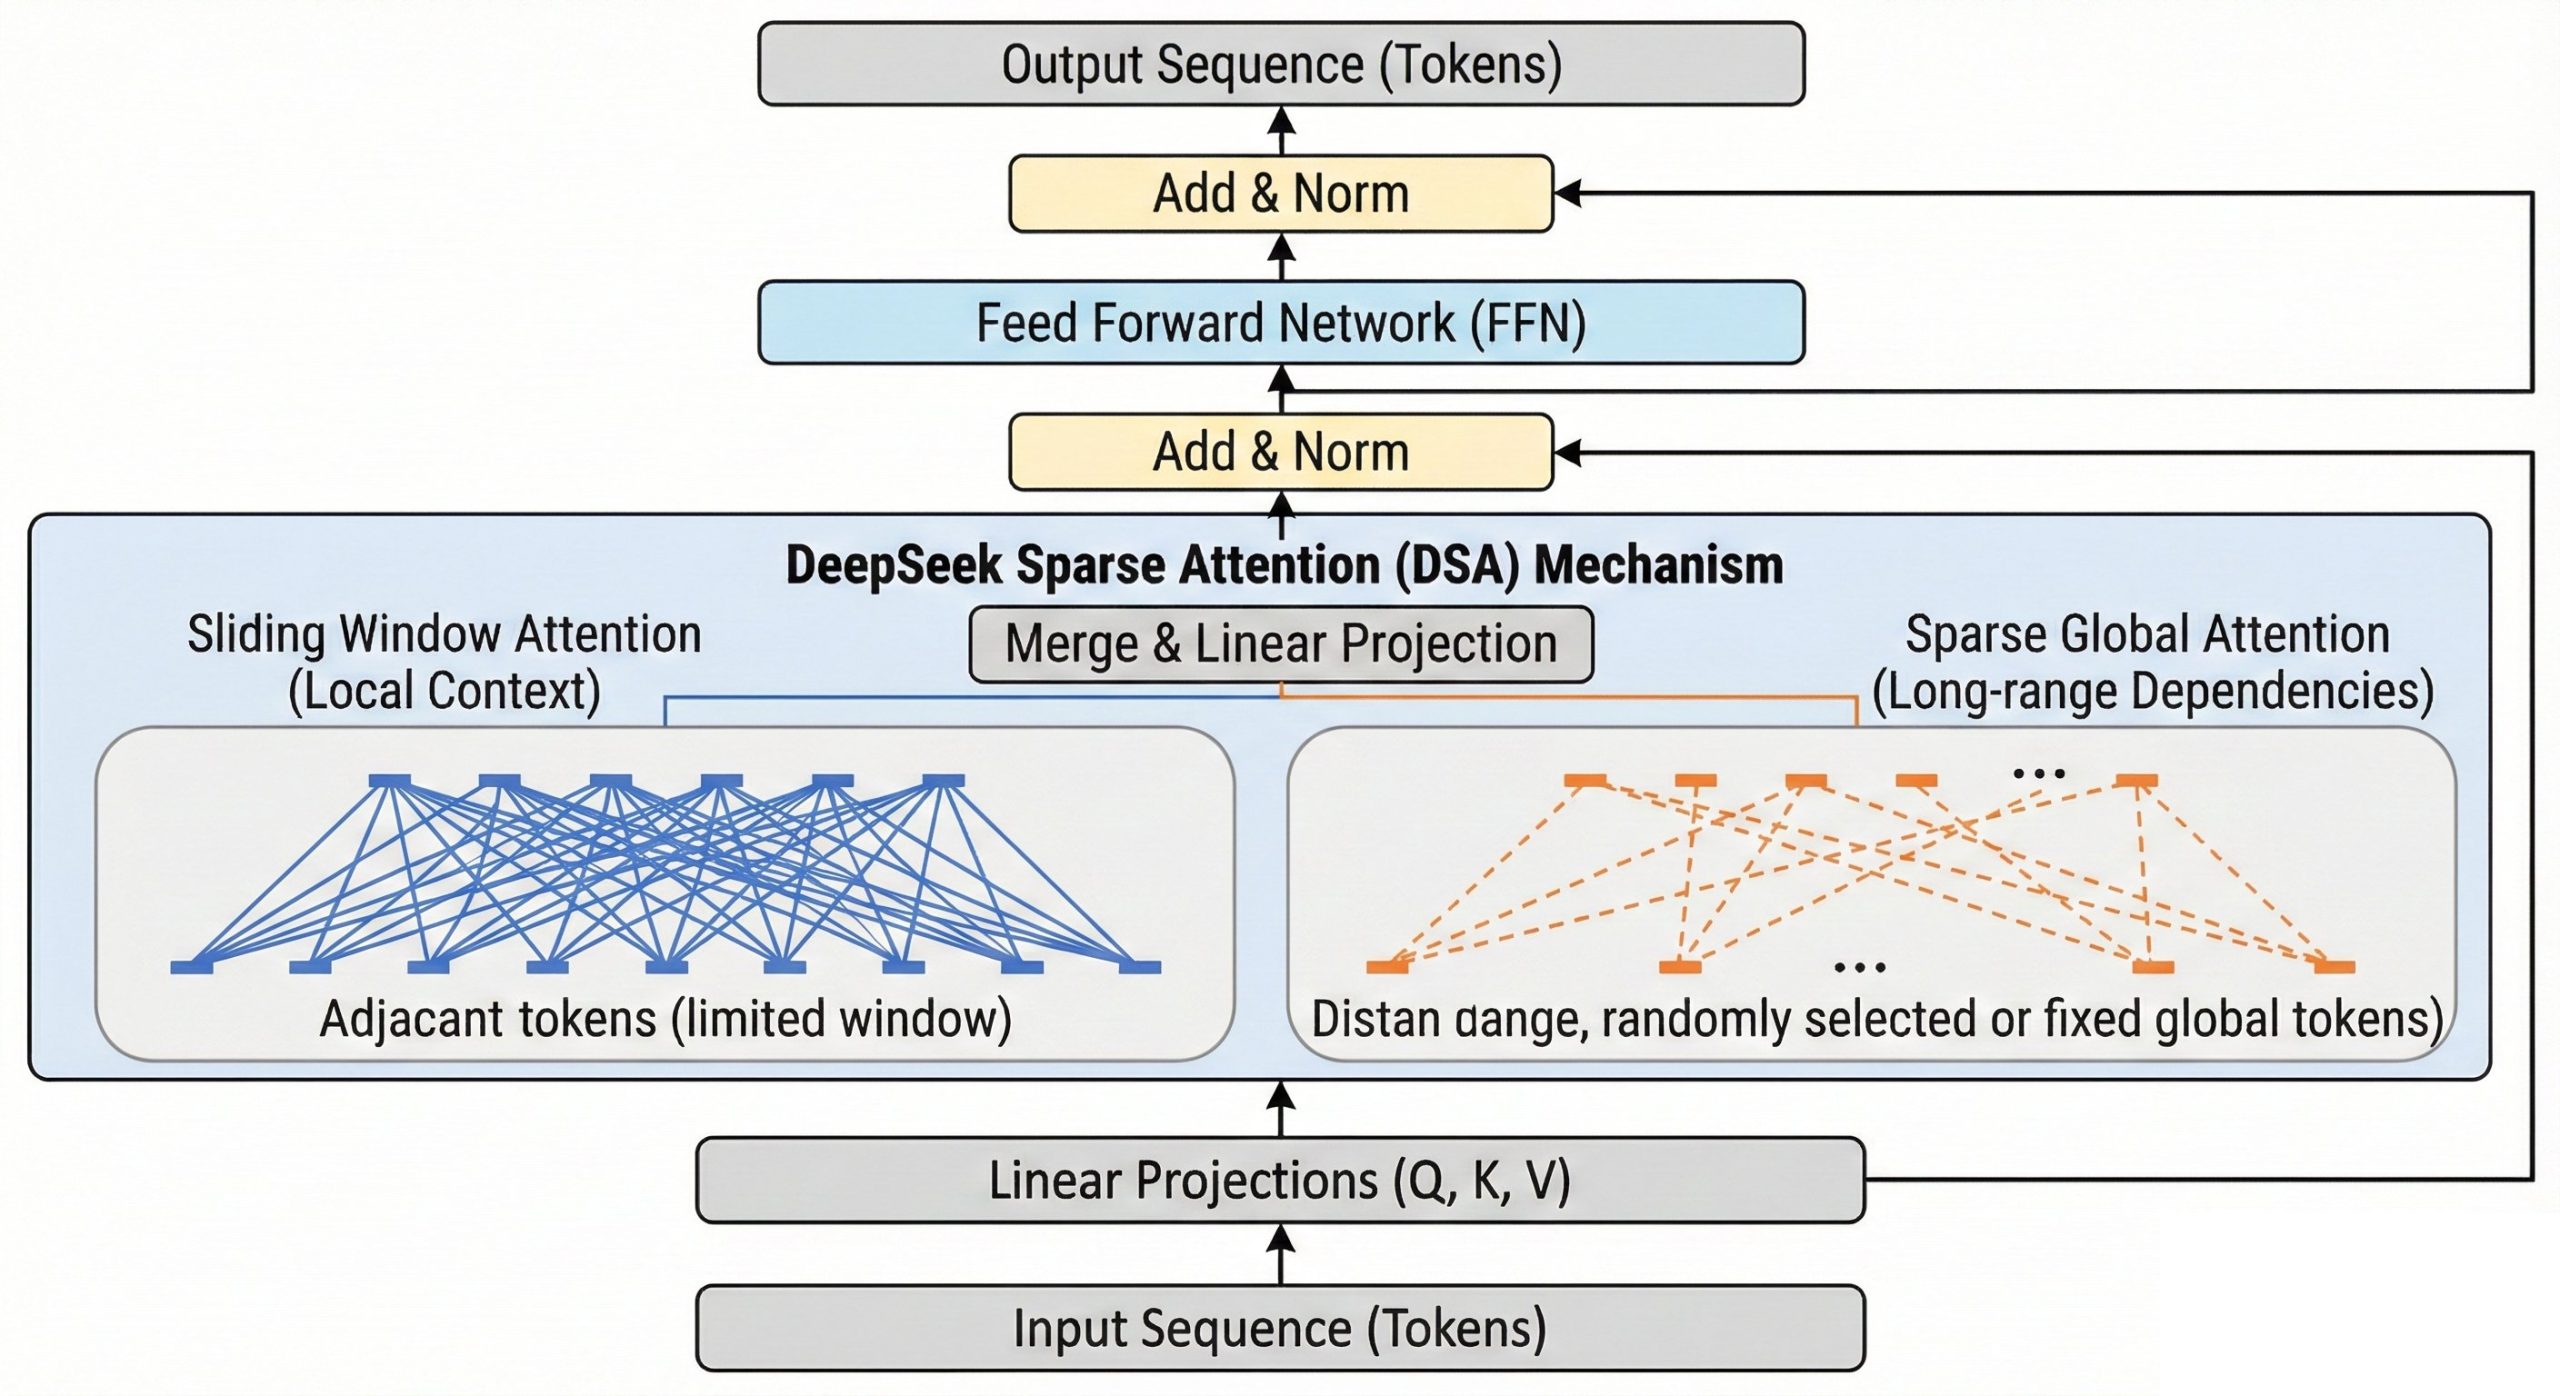
DSA: DeepSeek Sparse Attention - Tim Kellogg
Frontiers | Sparse attention double-channel FCN network for numerical ...
Sparse Attentionについて分かりやすく解説! | AGIRobots Blog
Sparse Attention Patterns: Local, Strided & Block-Sparse Approaches ...
LServe: Accelerate Long-Context LLM Inference with Unified Sparse ...
Understanding The Sparse Transformers!
TabNet 논문 리뷰 - 표 데이터에 Sparse Attention을 적용한 네트워크
【CVPR2023】Learning A Sparse Transformer Network for Effective Image ...
Sparse Attention Transformers for Long-Form Math | AI Tutorial | Next ...
DeepSeek AI Unveils Native Sparse Attention Mechanism for 10x Faster ...
Breaking News! MiniMax M3 Will Be Released: Sparse Attention ...
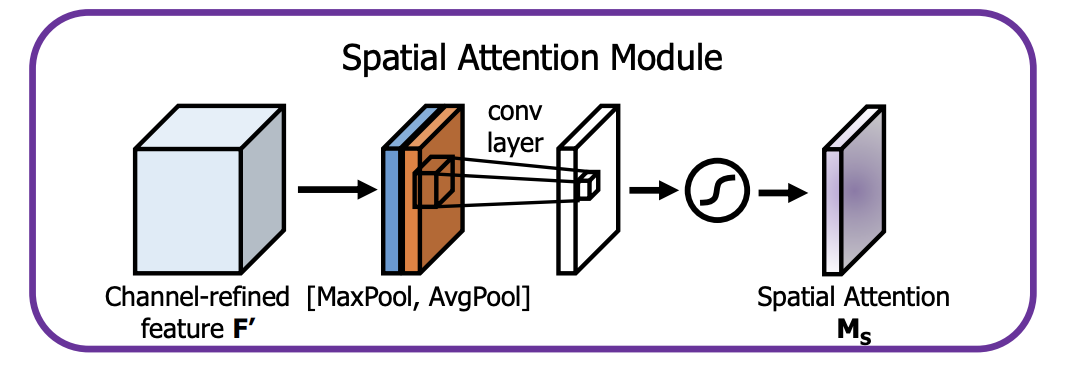
[논문 리뷰]_CBAM: Convolutional Block Attention Module
The proposed DSN model (left), which includes several sparse CNN ...
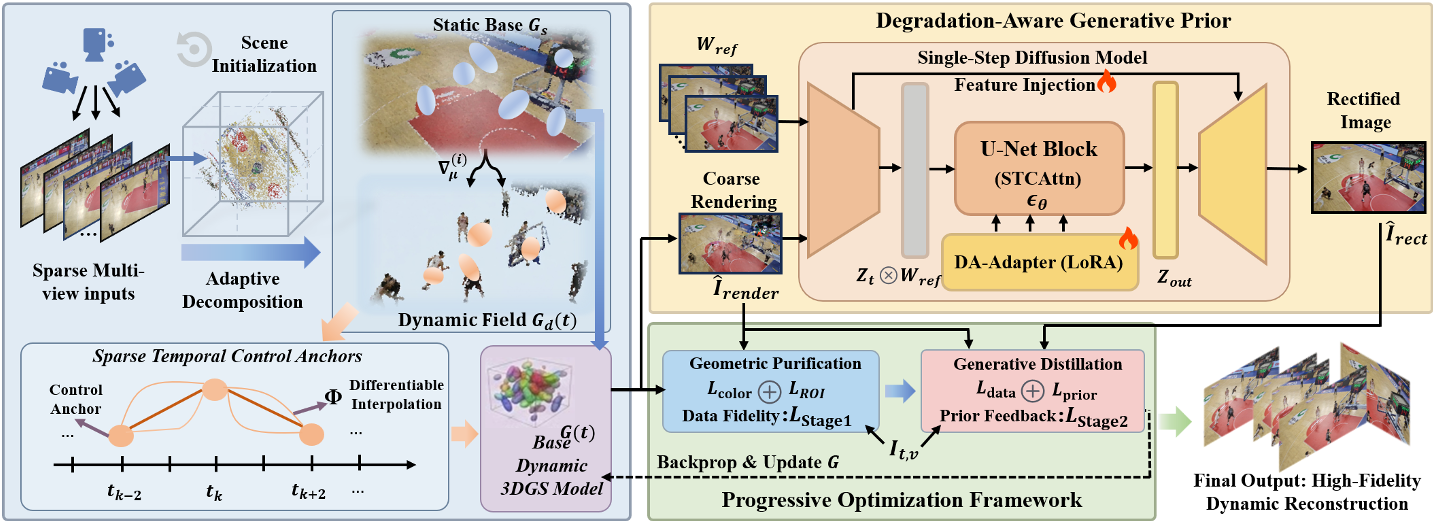
GeoRect4D: Geometry-Compatible Generative Rectification for Dynamic ...
SparseD: Sparse Attention for Diffusion Language Models | AI Research ...
OpenVINO™ Blog | Optimizing Whisper and Distil-Whisper for Speech ...
Figure 1 from Change Detection in Remote-Sensing Images Using Pyramid ...
A Visual Guide to Attention Variants in Modern LLMs
A Survey on Sparsity Exploration in Transformer-Based Accelerators
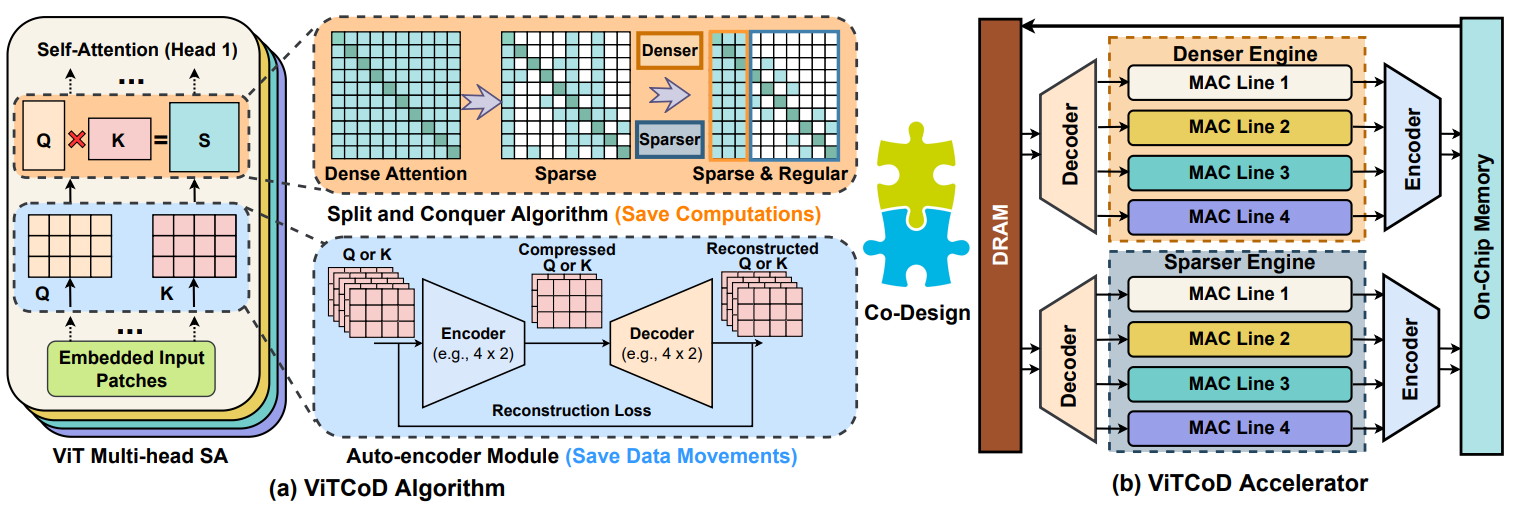
[2210.09573] ViTCoD: Vision Transformer Acceleration via Dedicated ...
image
MiniMax M3: Open-weight model with a million-token context challenges ...
Shuo Yang
Microsoft Research Introduces MMInference to Accelerate Pre-filling for ...
MRSNet: Multi-Resolution Scale Feature Fusion-Based Universal Density ...
ViTCoD
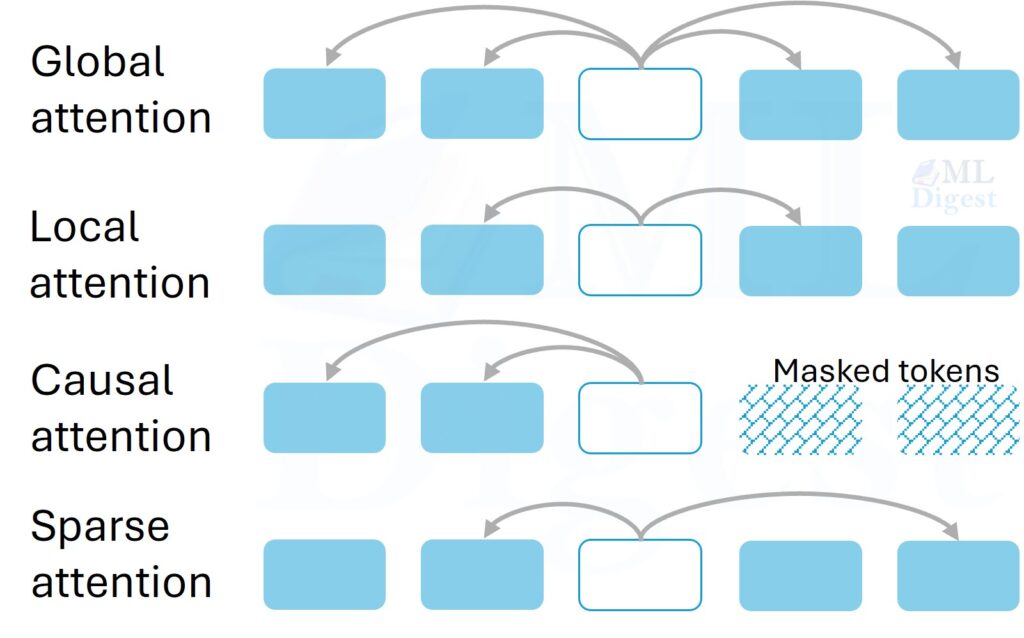
Attention Mechanisms Made Easy: All Types Explained in One Post - ML Digest
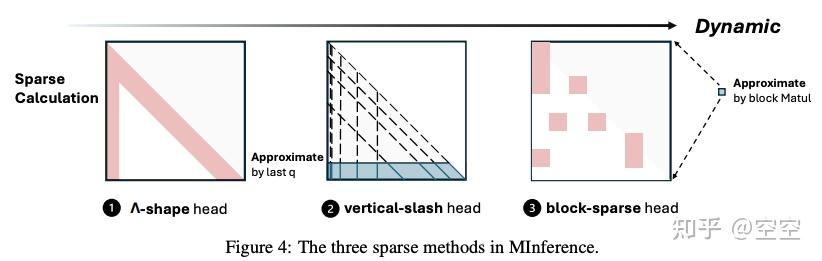
MInference: Million-Tokens Prompt Inference for LLMs
《MInference 1.0: Accelerating Pre-filling for Long-Context LLMs via ...
Figure 6 from Change Detection in Remote-Sensing Images Using Pyramid ...
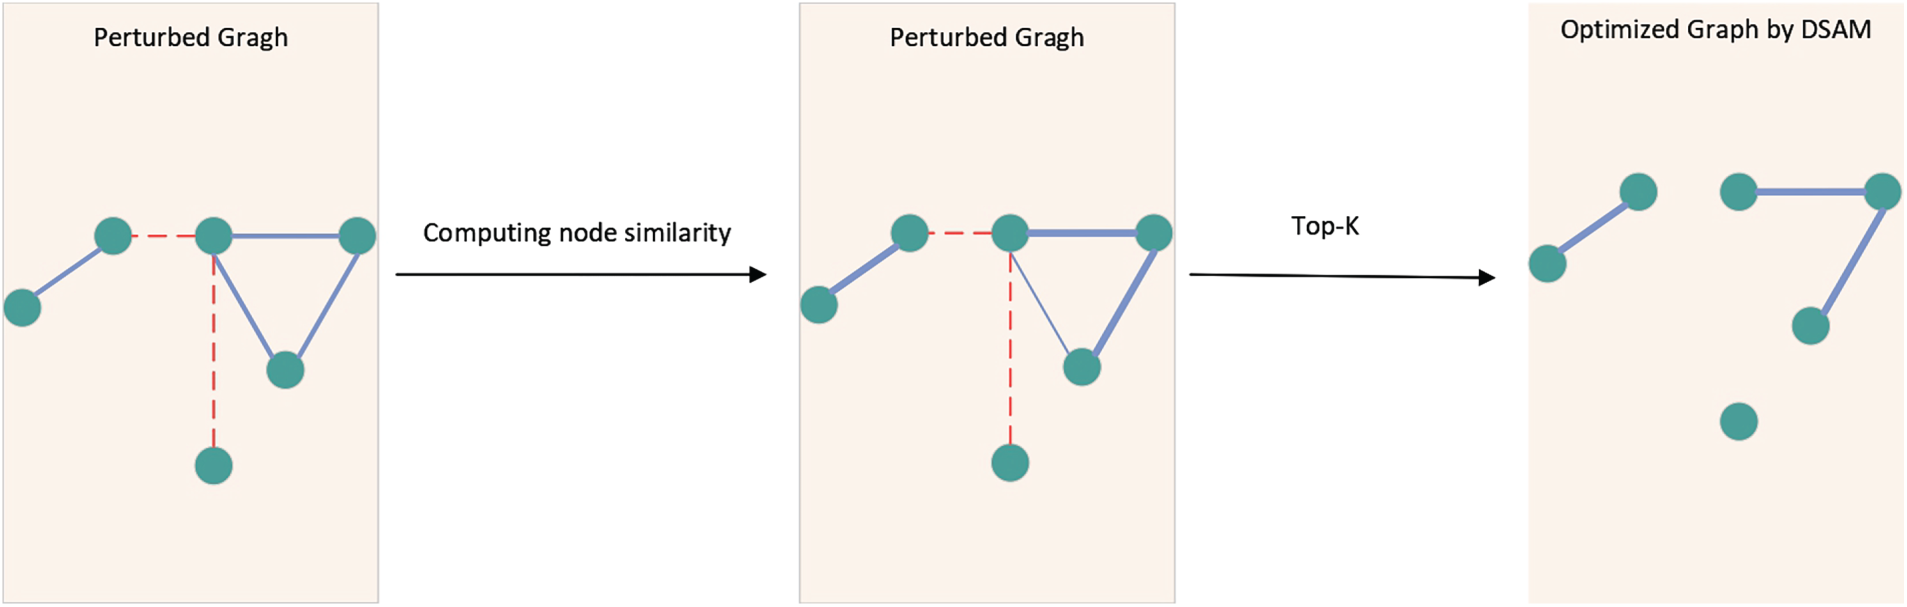
CMC | Free Full-Text | Adversarial Attack Defense in Graph Neural ...
MInference: Million-Tokens Prompt Inference for Long-context LLMs ...
Based on this image's title: “[논문 리뷰] Dynamic Sparse Attention: Access Patterns and Architecture”