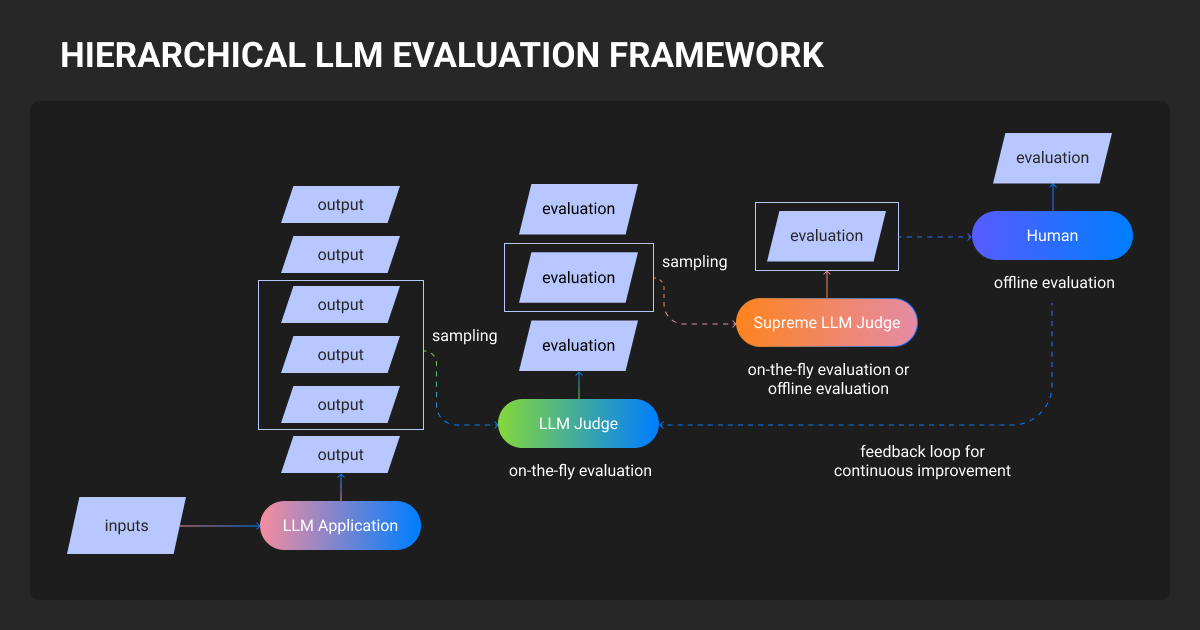
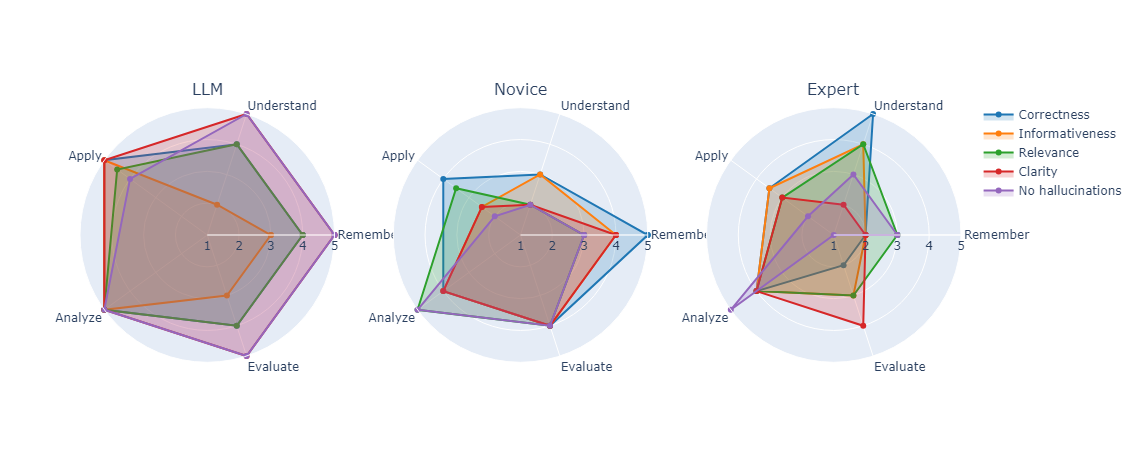
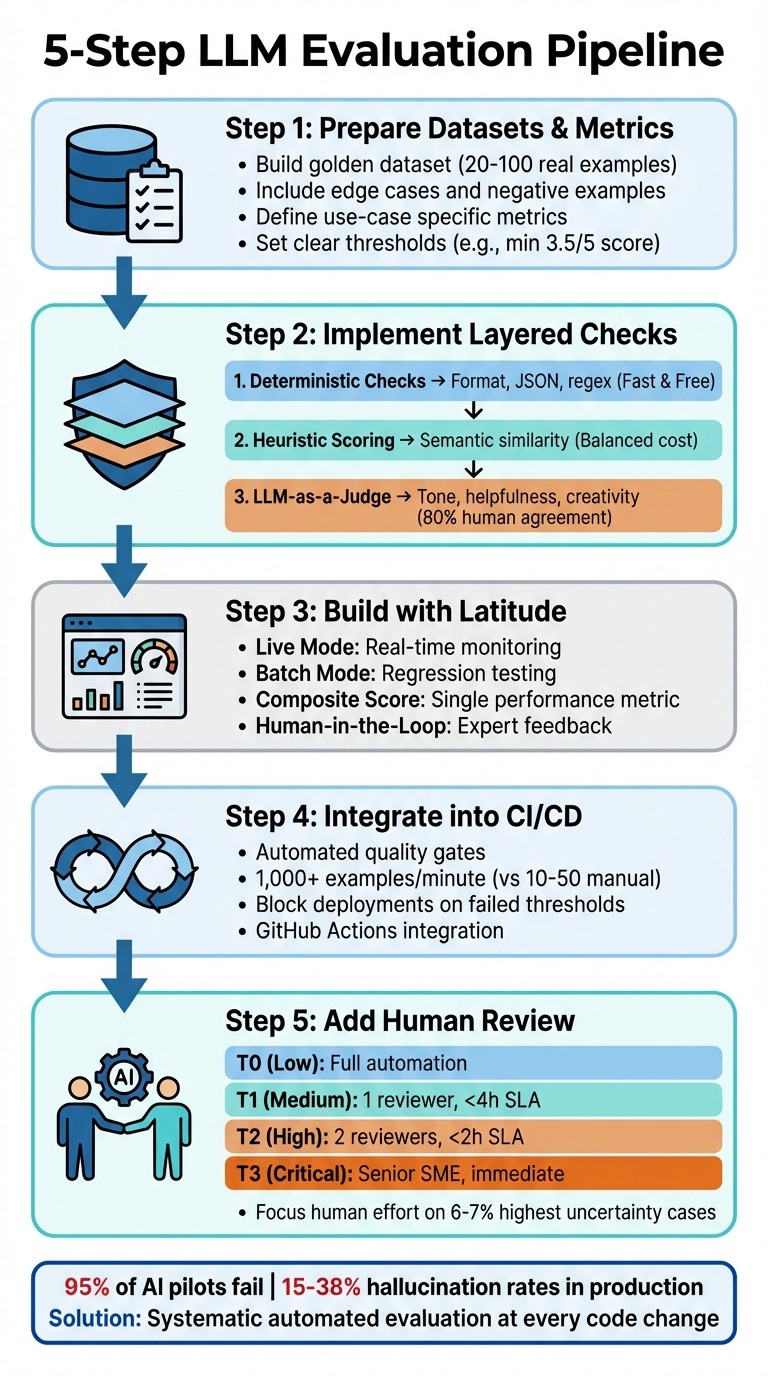
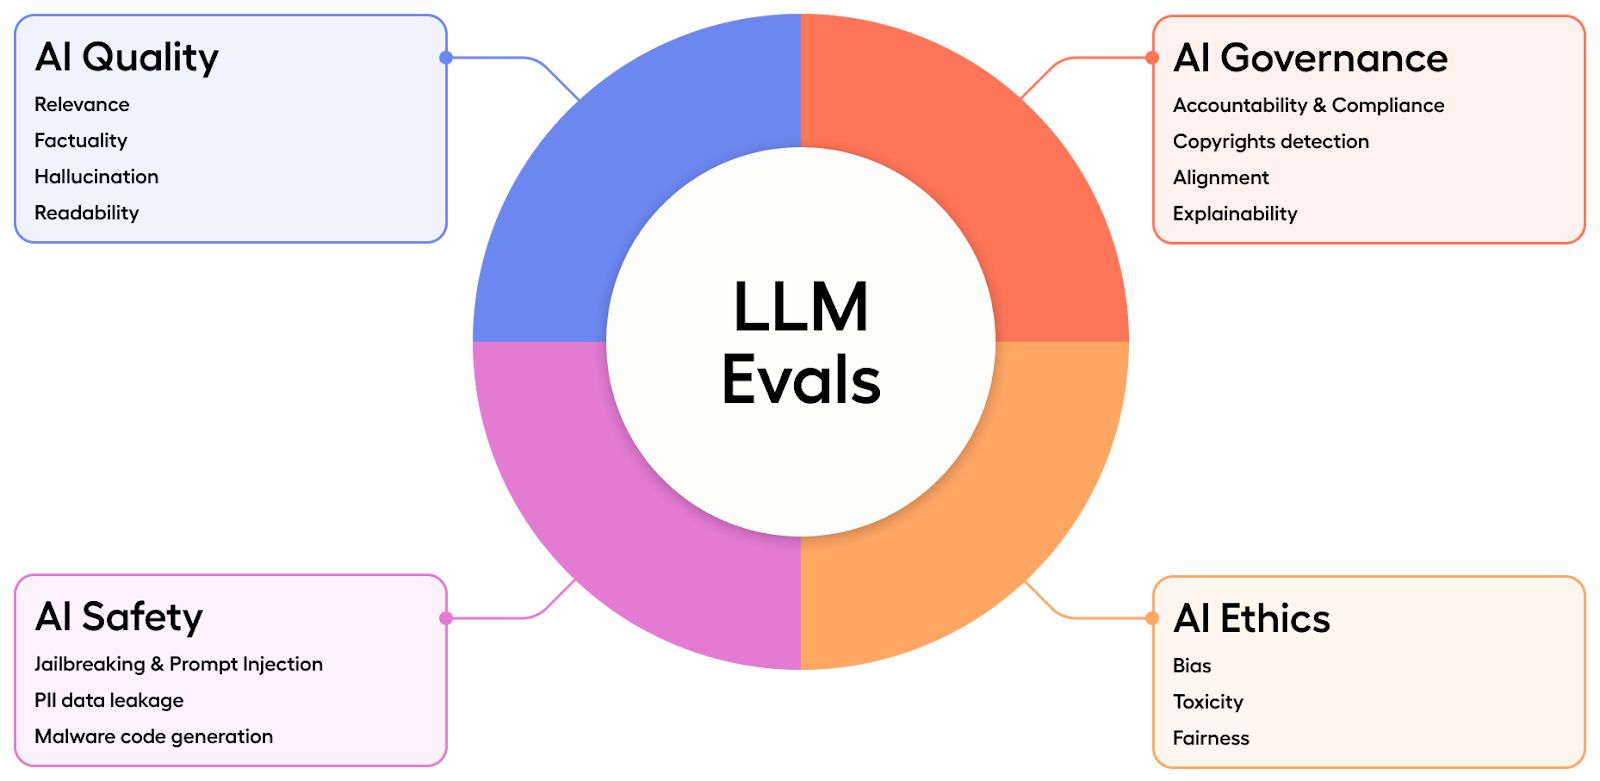
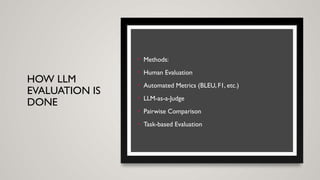
LLM Evaluation: Human, Automated & Function-Based Approaches
Announcing Lens for LLMs: Combining Human and Automated LLM Evaluation ...
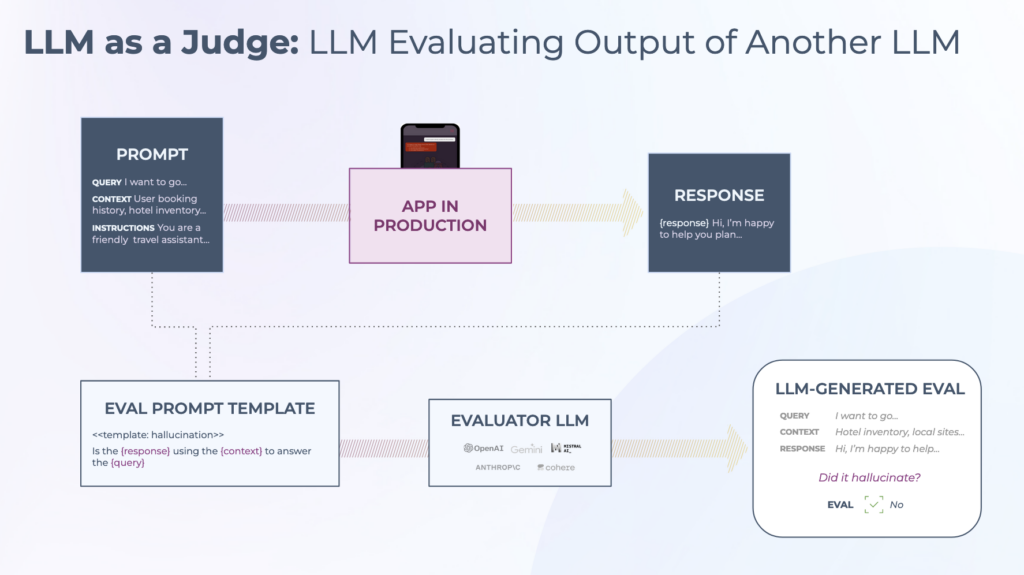
LLM as a Judge: A 2026 Guide to Automated Model Assessment | Label Your ...
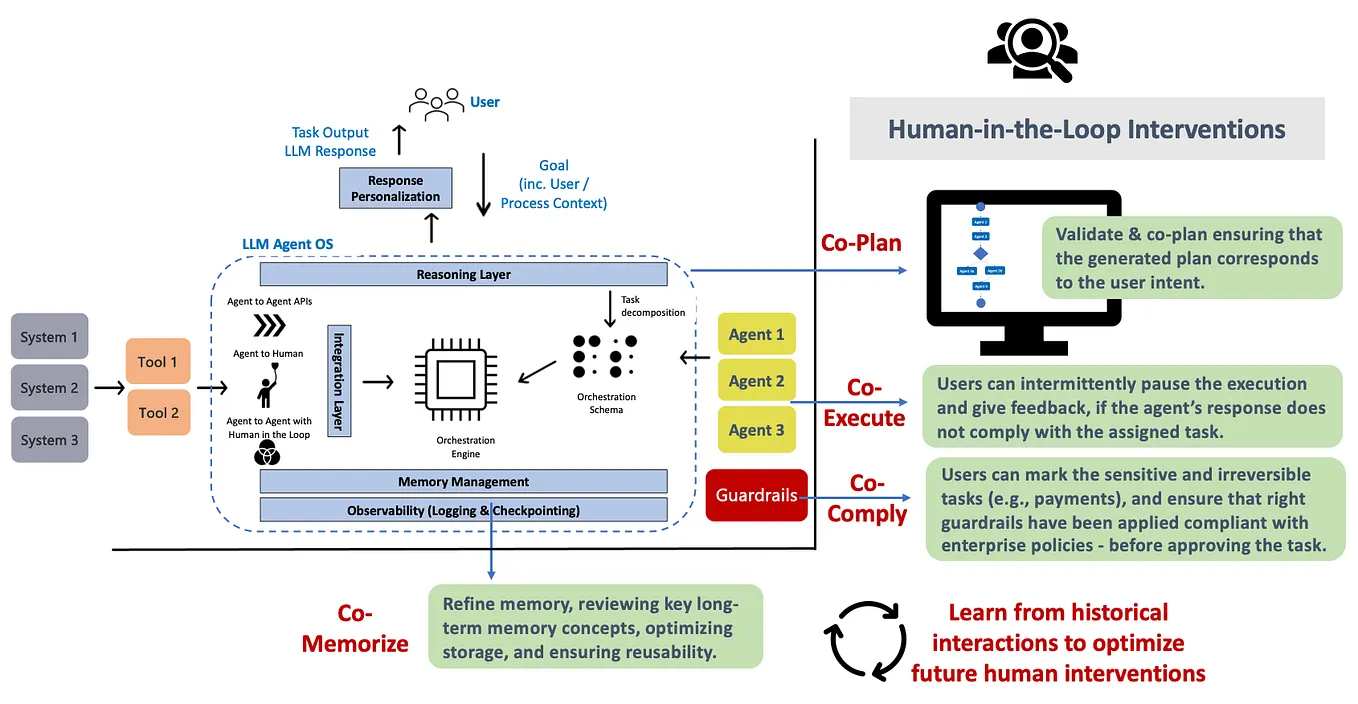
LLM Agents in 2026: Definition, Use Cases, & Tools
The Challenges of Evaluating LLM Applications: An Analysis of Automated ...
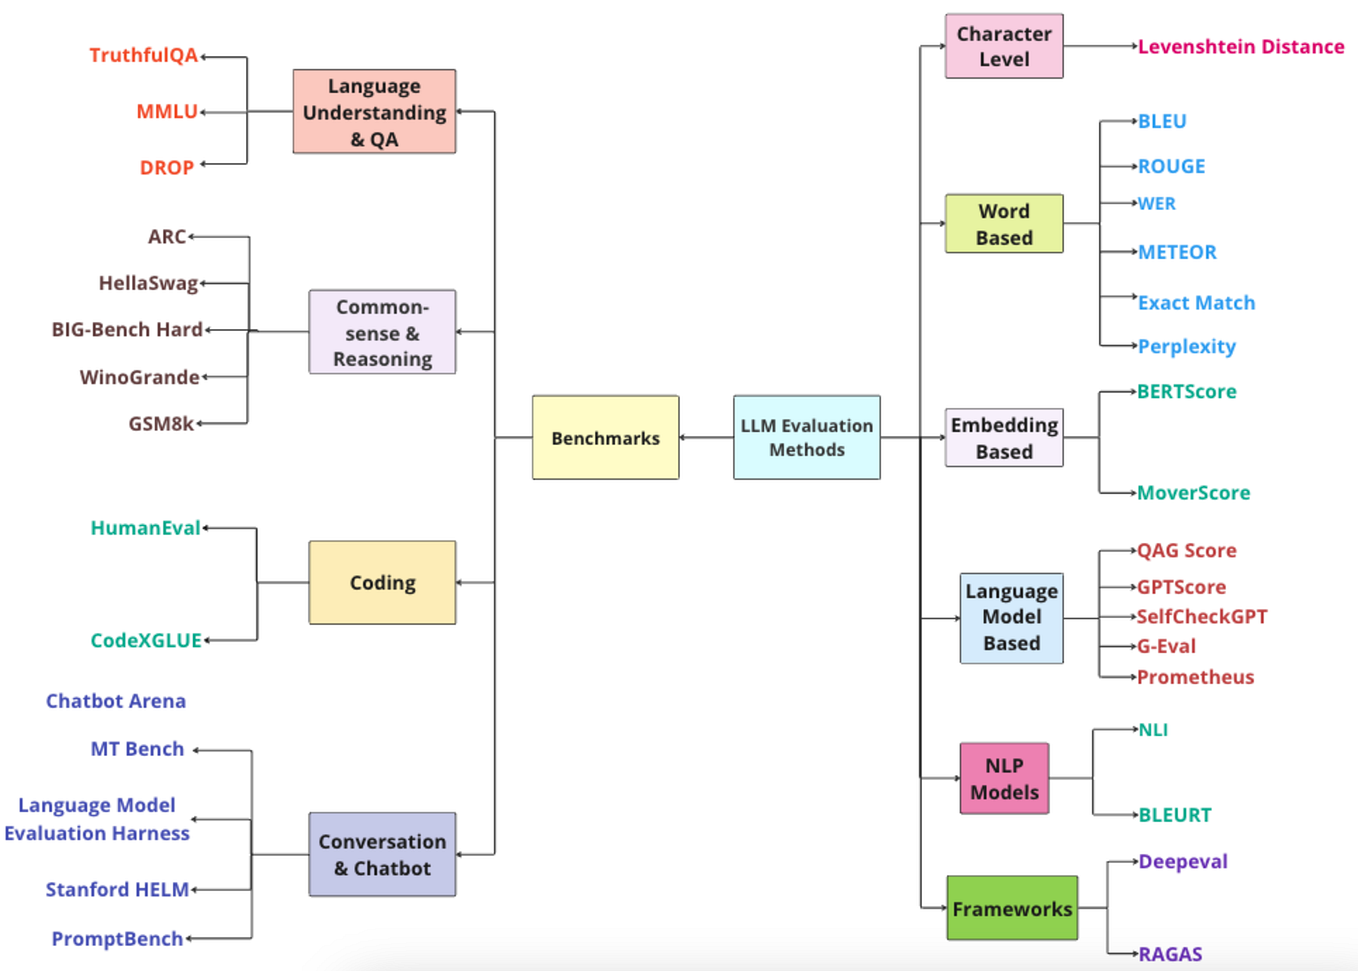
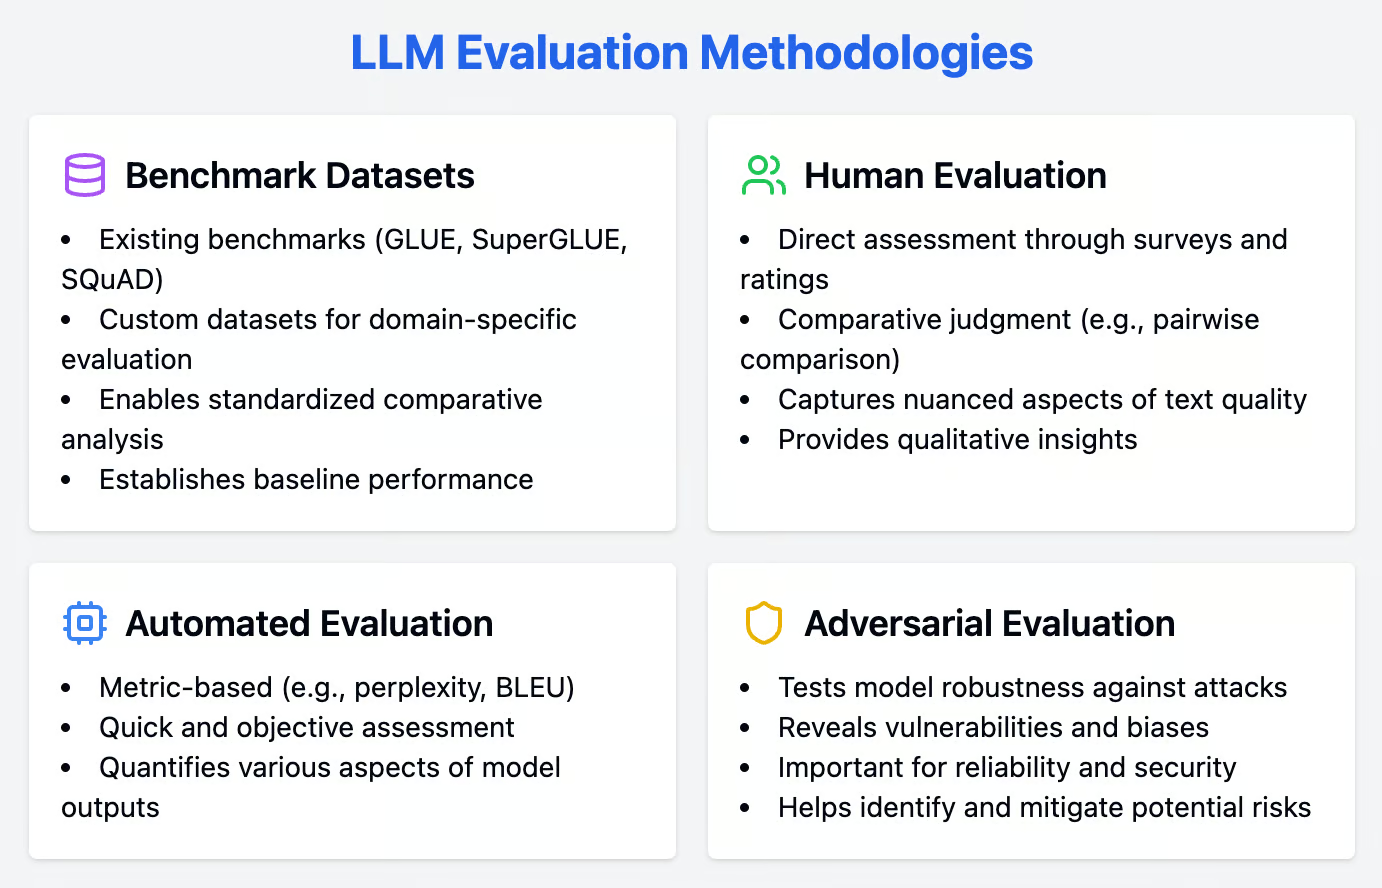
LLM Evaluation Explained: Metrics, Benchmarks & Human Validation
How to Build Automated LLM Evaluation Pipelines | Latitude
[Literature Review] Assessing Automated Fact-Checking for Medical LLM ...
Understanding the 4 Main Approaches to LLM Evaluation (From Scratch)
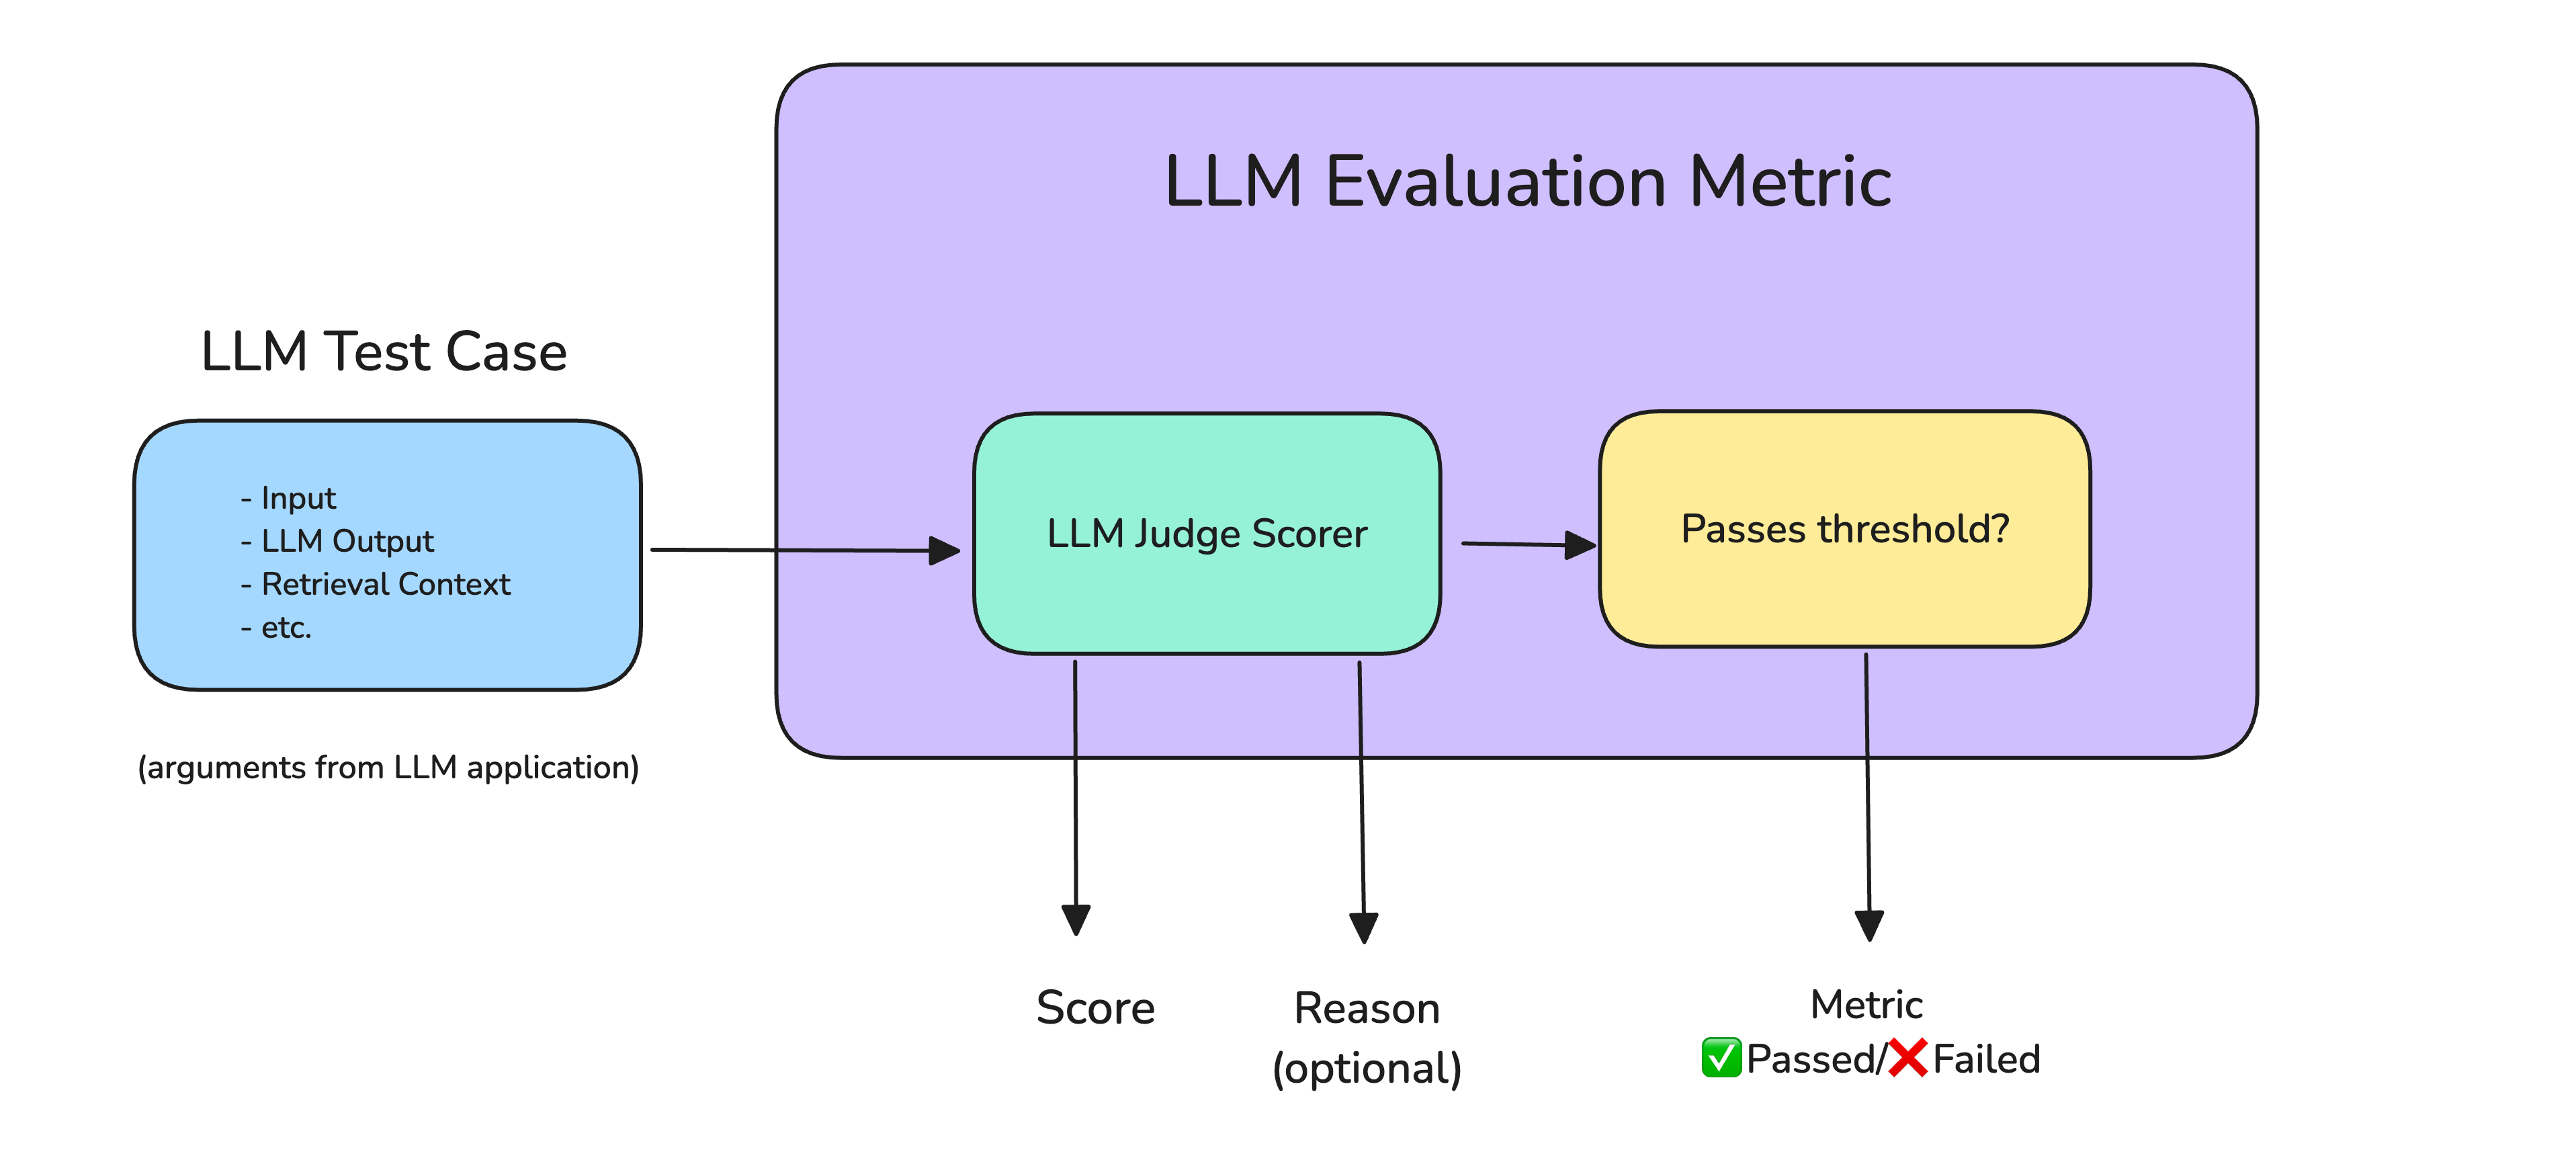
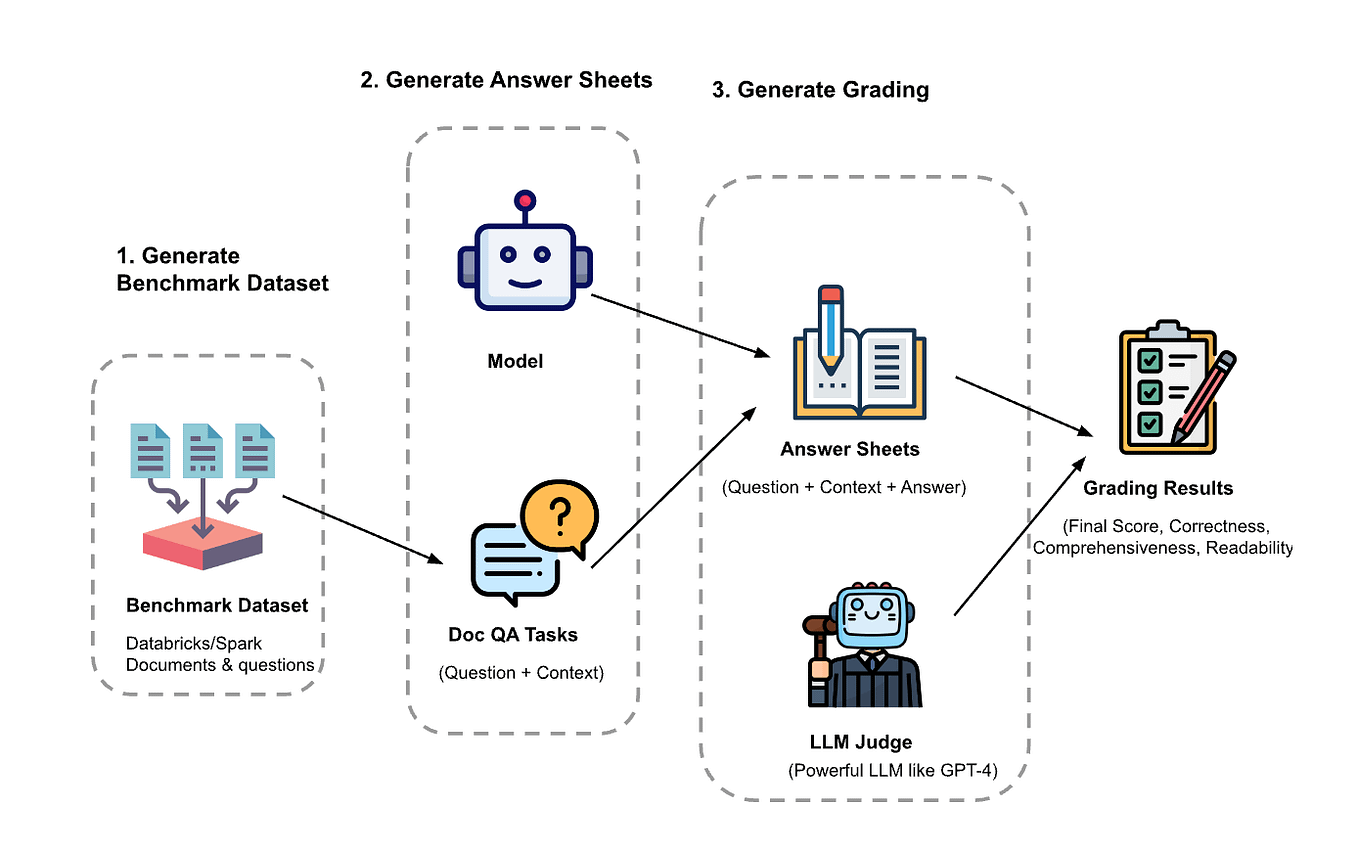
LLM as a Judge: Guide to LLM Evaluation & Best Practices
What Is LLM As A Judge? Strategies, Impact & Best Practices | Deepchecks
LLM Evaluation: Frameworks, Metrics, and Best Practices | SuperAnnotate
Automated LLM Evaluation Benchmarks
Evaluating LLM Content Quality with Automated Metrics: A Comprehensive ...
[논문 리뷰] Towards Automated Penetration Testing: Introducing LLM ...
Paper page - RocketEval: Efficient Automated LLM Evaluation via Grading ...
How to Use Adaptive Rubrics for Automated LLM Output Evaluation on ...
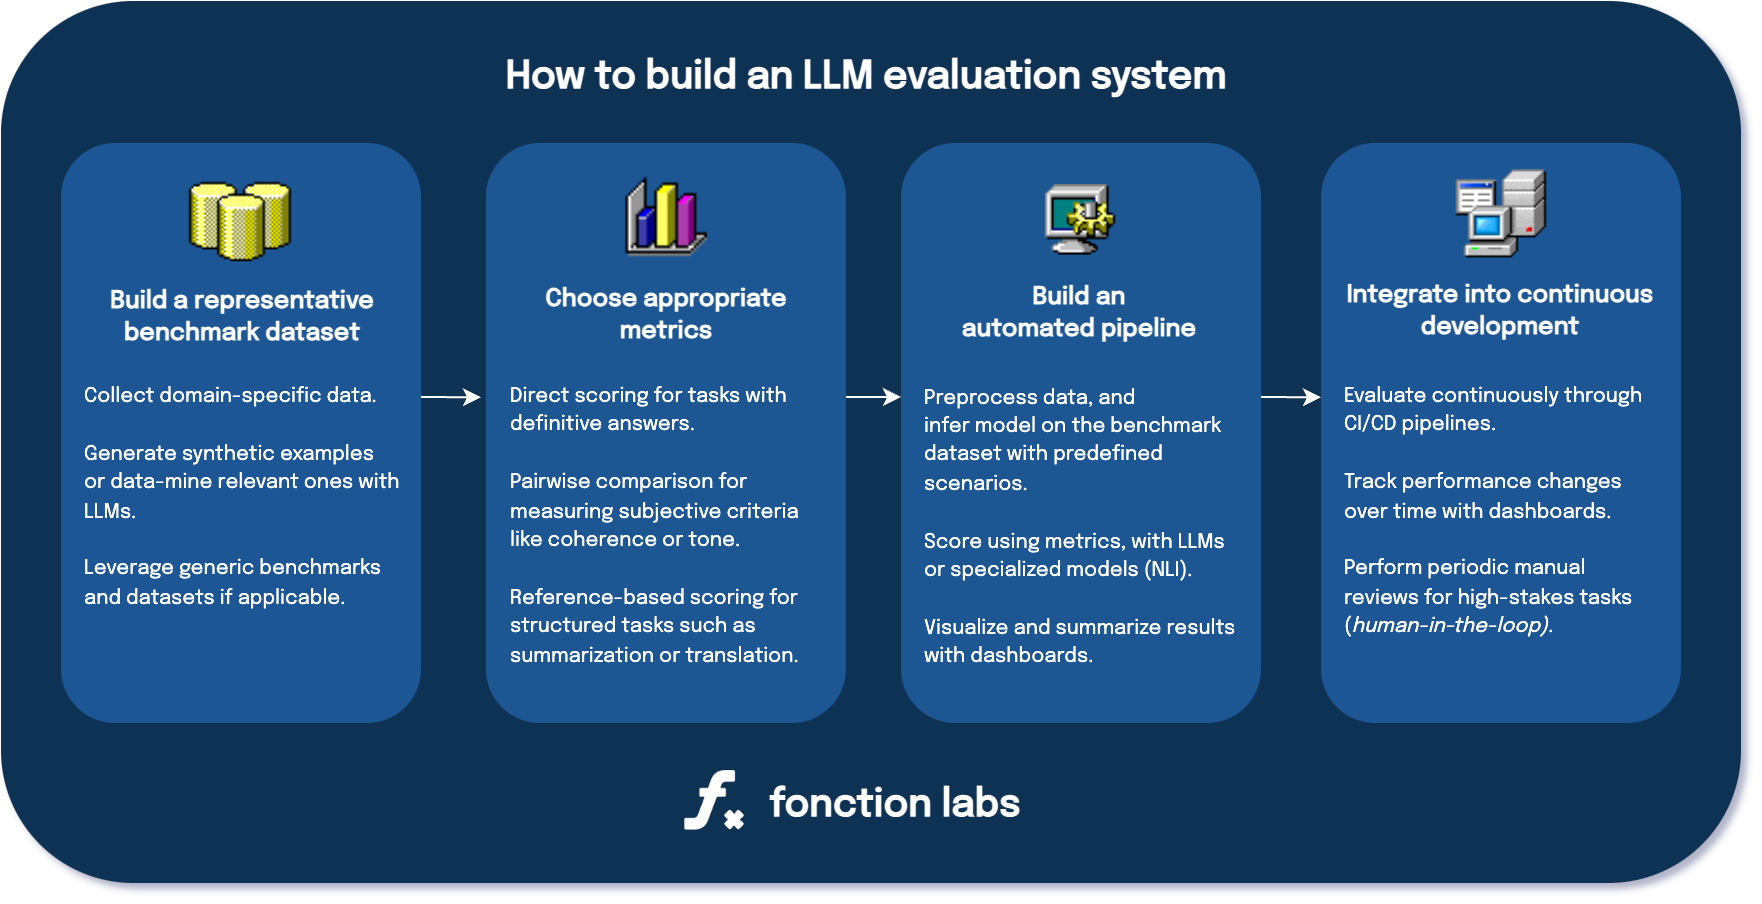
Evaluating LLM Performance at Scale: A Guide to Building Automated LLM ...
Why LLM evaluation matters
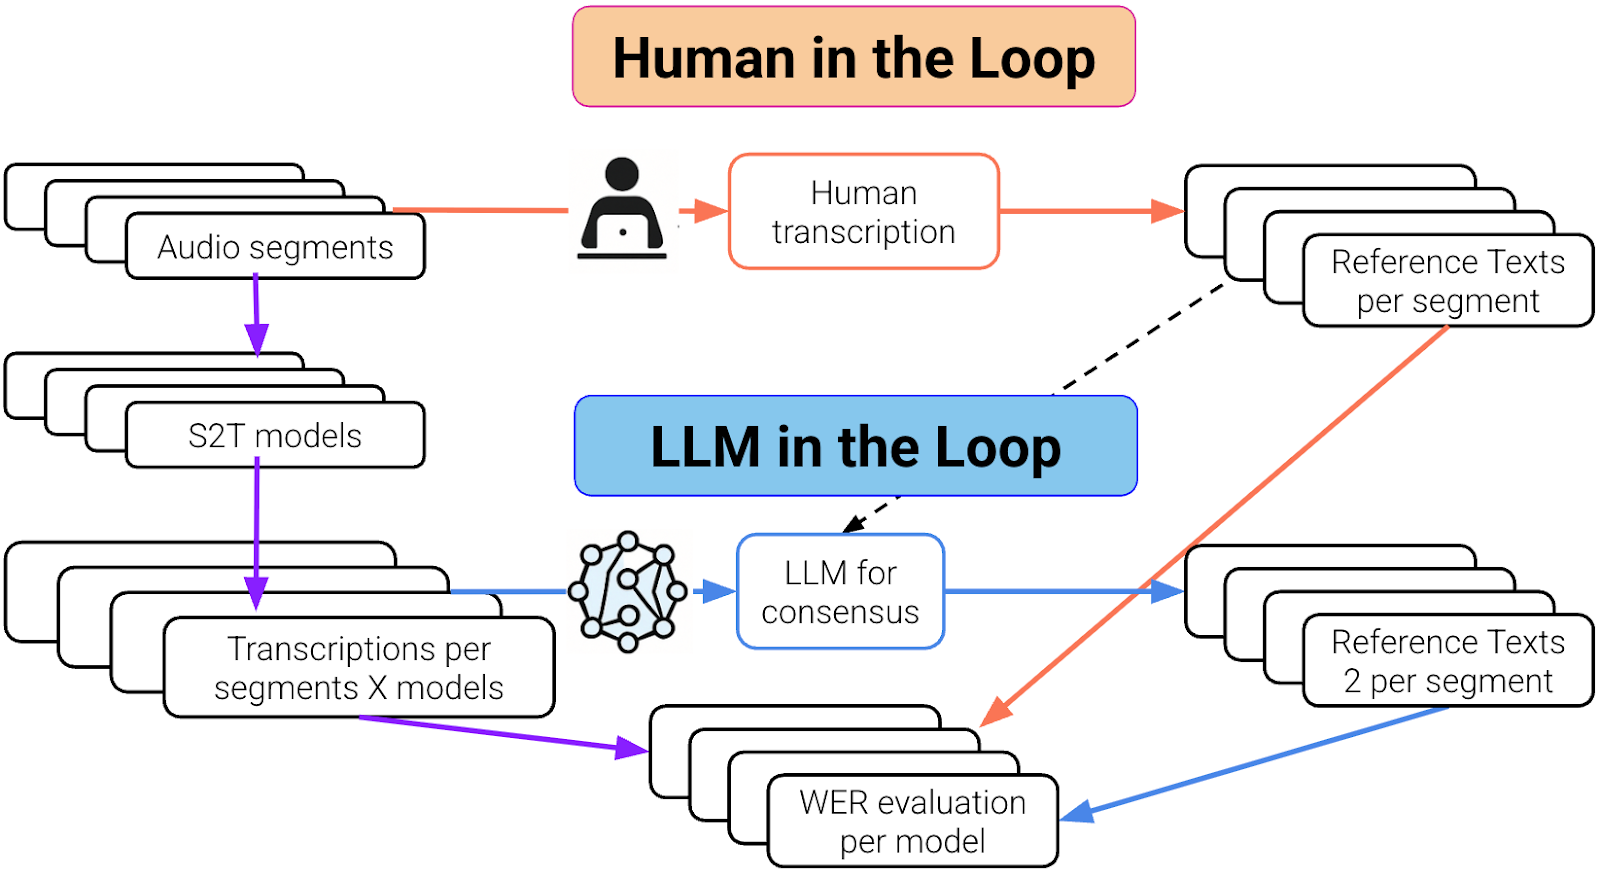
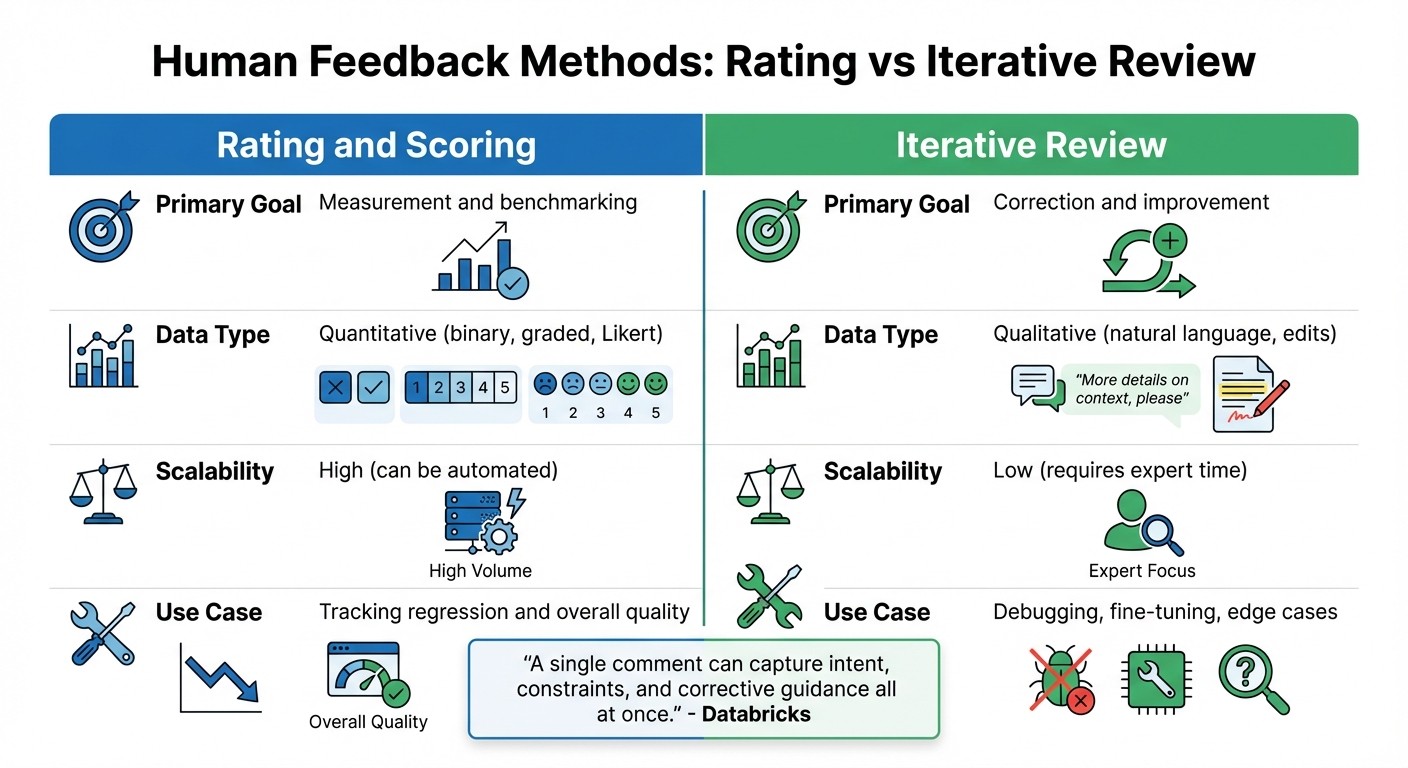
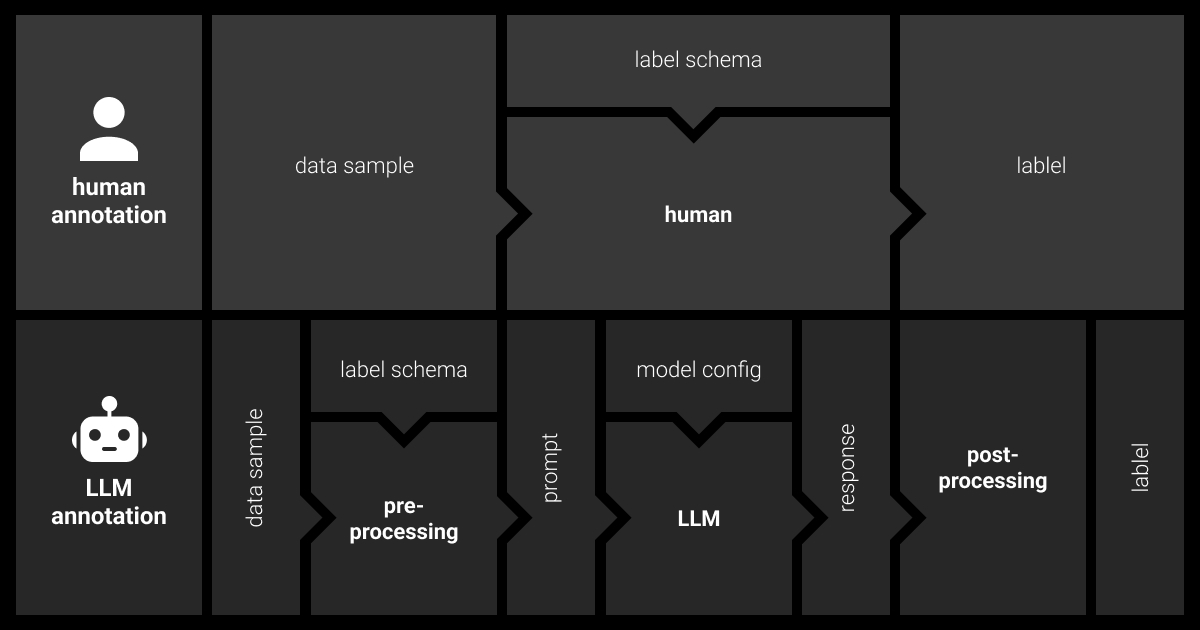
Man in the Loop vs. LLM in the Loop
LLM agent-CSDN博客
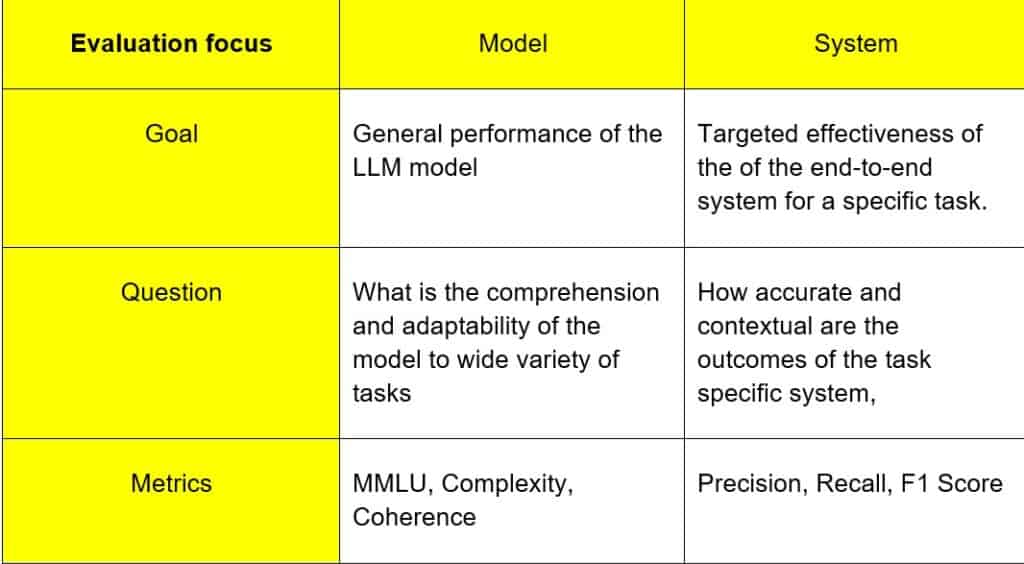
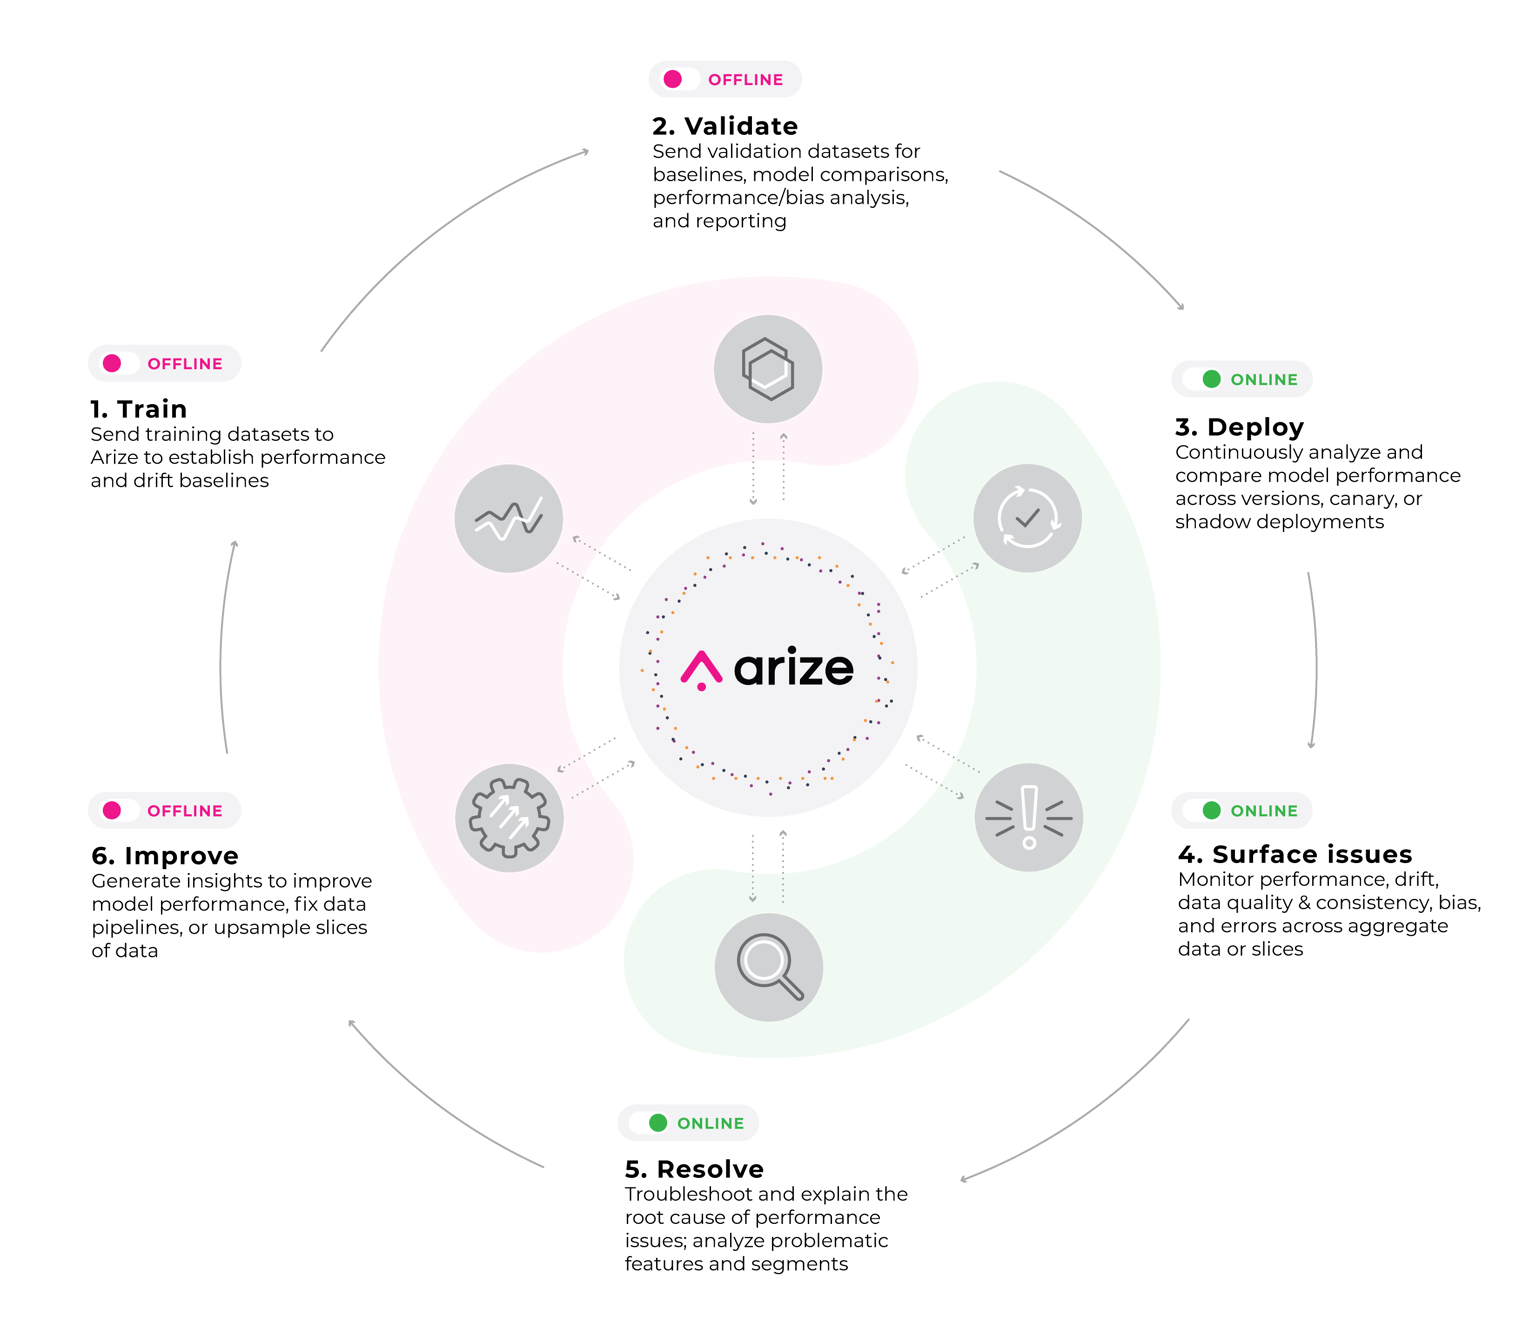
The Definitive Guide to LLM Evaluation - Arize AI
How To Evaluate State‑Of‑The‑Art LLM Models: A Complete Guide | Deepchecks
[论文评述] LLM-based Automated Grading with Human-in-the-Loop
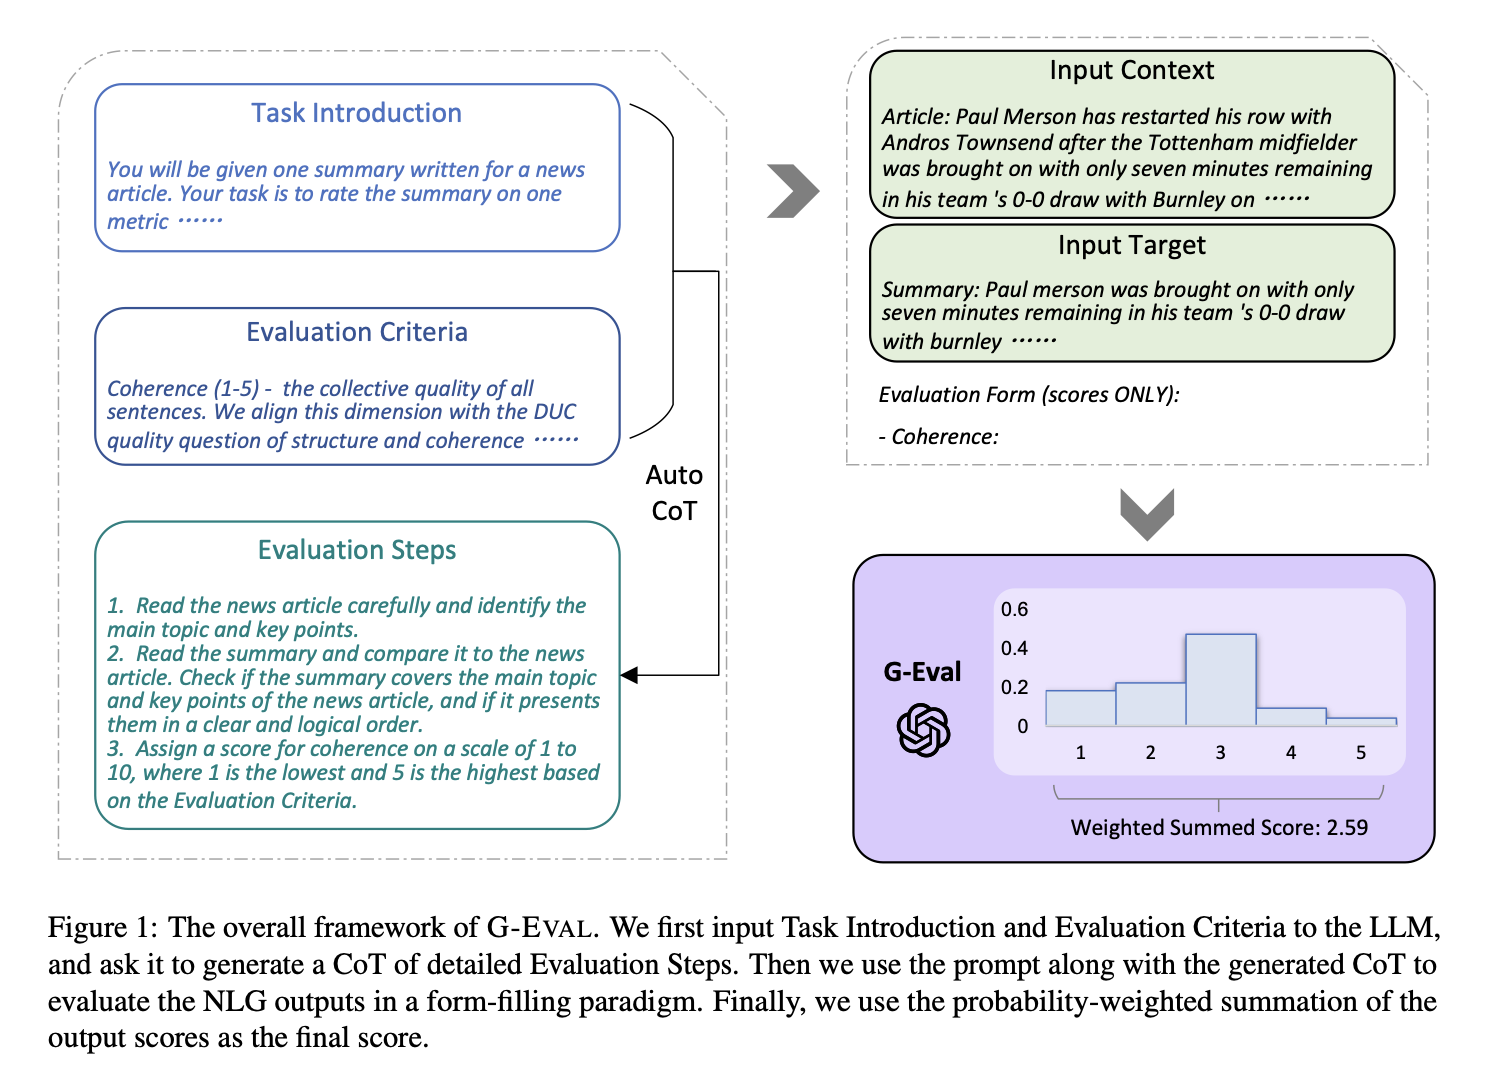
The Definitive LLM-as-a-Judge Guide for Scalable LLM Evaluation | by ...
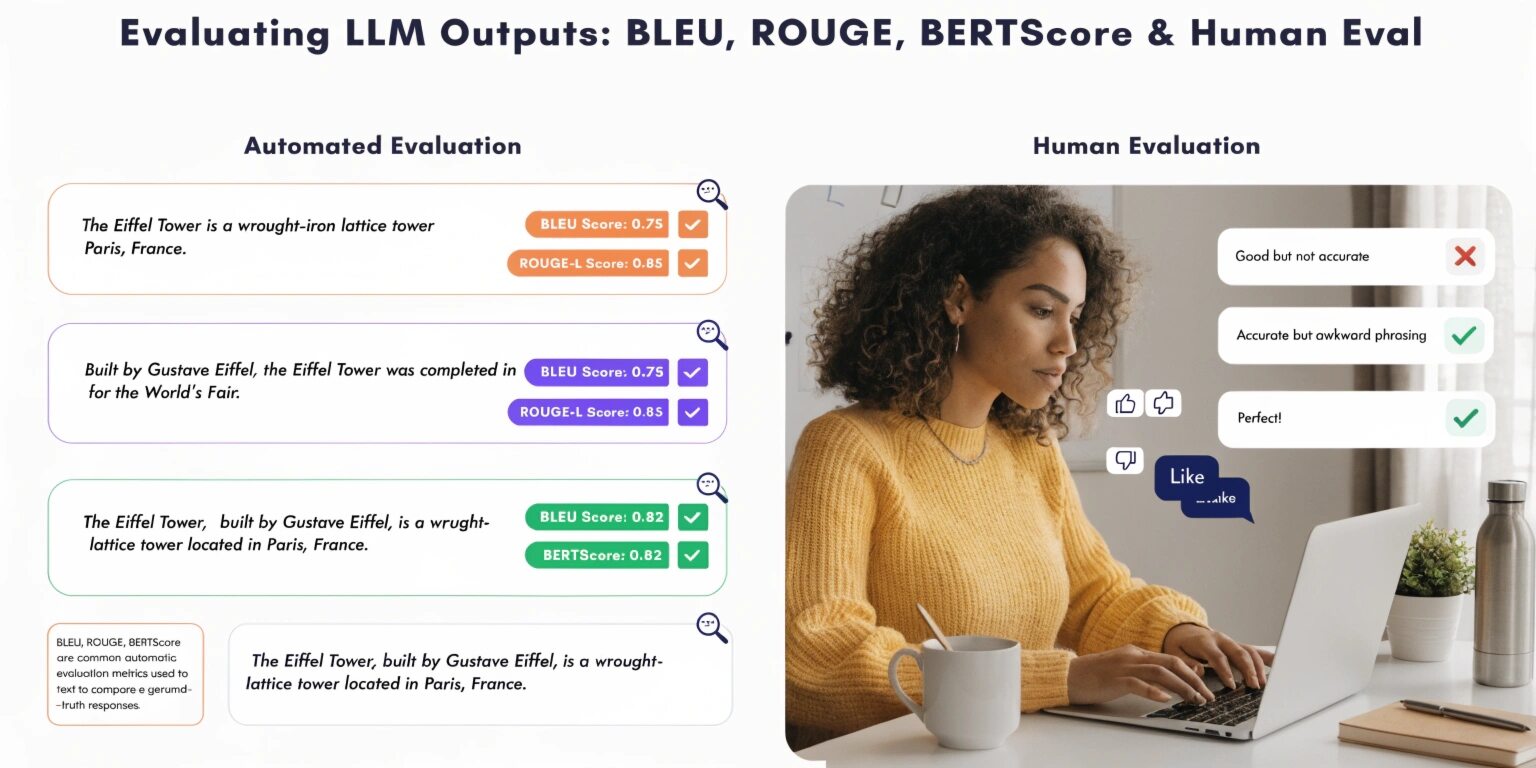
Evaluating LLM Outputs Using BLEU, ROUGE, BERTScore and Human ...
Designing LLM Systems - by Thota Adinarayana
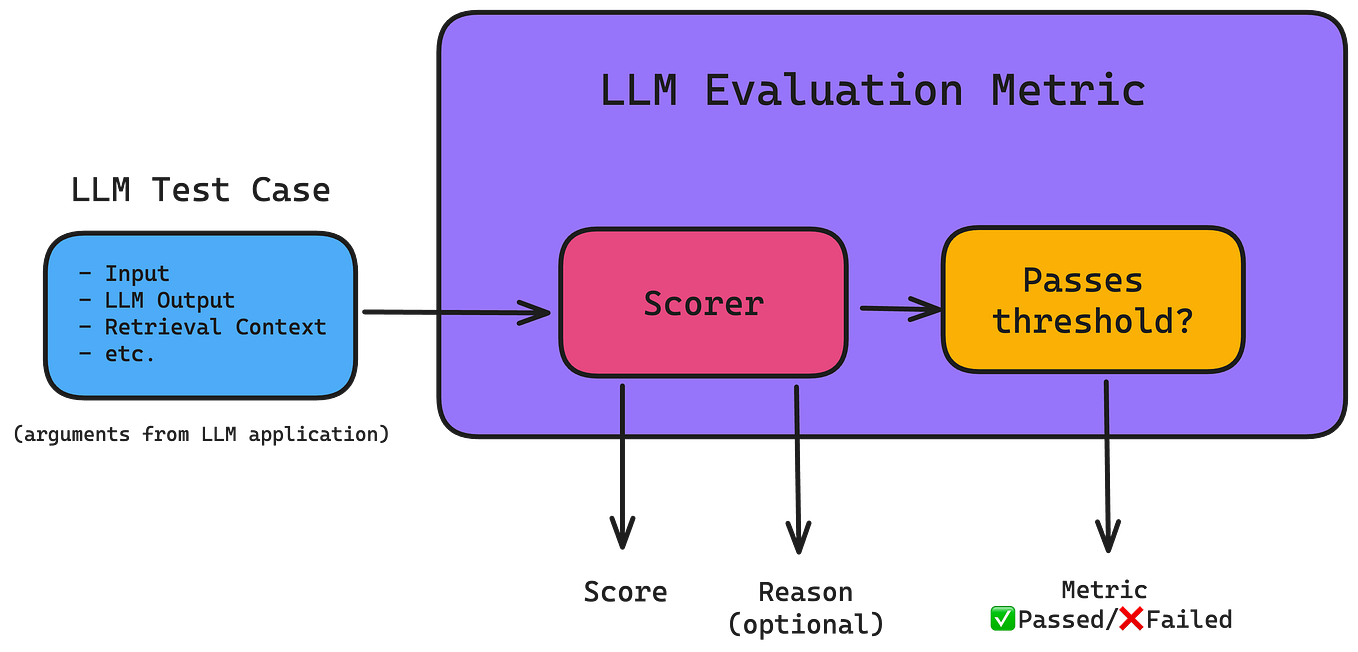
LLM Evaluation Metrics: The Ultimate LLM Evaluation Guide - Confident AI
LLM-as-a-Judge: Automated Scoring and Reliability vs. Human Evaluation ...
Mastering LLM Testing: Ensuring Accuracy, Ethics, and Future-Readiness ...
Solutions to LLM Evaluation Challenges: Metrics, Advanced Methods ...
How to Measure the Quality of LLM Outputs
Benchmarking PDF Accessibility Evaluation: A Dataset and Framework for ...
Figure 1 from Rubric-based Automated Essay Scoring and Providing ...
My Learning Journey into LLM-Based Automated Evaluation
Quality Evaluation Gap: Human vs. Automated Metrics in LLM-Based MT ...
Using LLM to Design Reward Function for Bipedal Walker-v3 | Proceedings ...
Human Feedback in LLM Validation Workflows | Latitude
Crafting the LLM Workbench: A Blueprint for GenAI Evaluation - GoDaddy Blog
LLM Evaluation Frameworks – Measuring AI Performance at Scale
How to Build an LLM Evaluation Framework, from Scratch - Confident AI
[논문 리뷰] Automated Rewards via LLM-Generated Progress Functions
How to Improve LLM Evaluation Systems | Deepchecks
LLM Evaluation Framework: A PM's Guide to Measuring AI
Can LLM Agents Drive Like Human Beings? Benchmarks, Feature ...
[논문 리뷰] BLADE: Benchmark suite for LLM-driven Automated Design and ...
LLM Evaluation - AI Glossary | PromptOT
How to Build, Evaluate, and Manage Prompts for LLM | Deepchecks
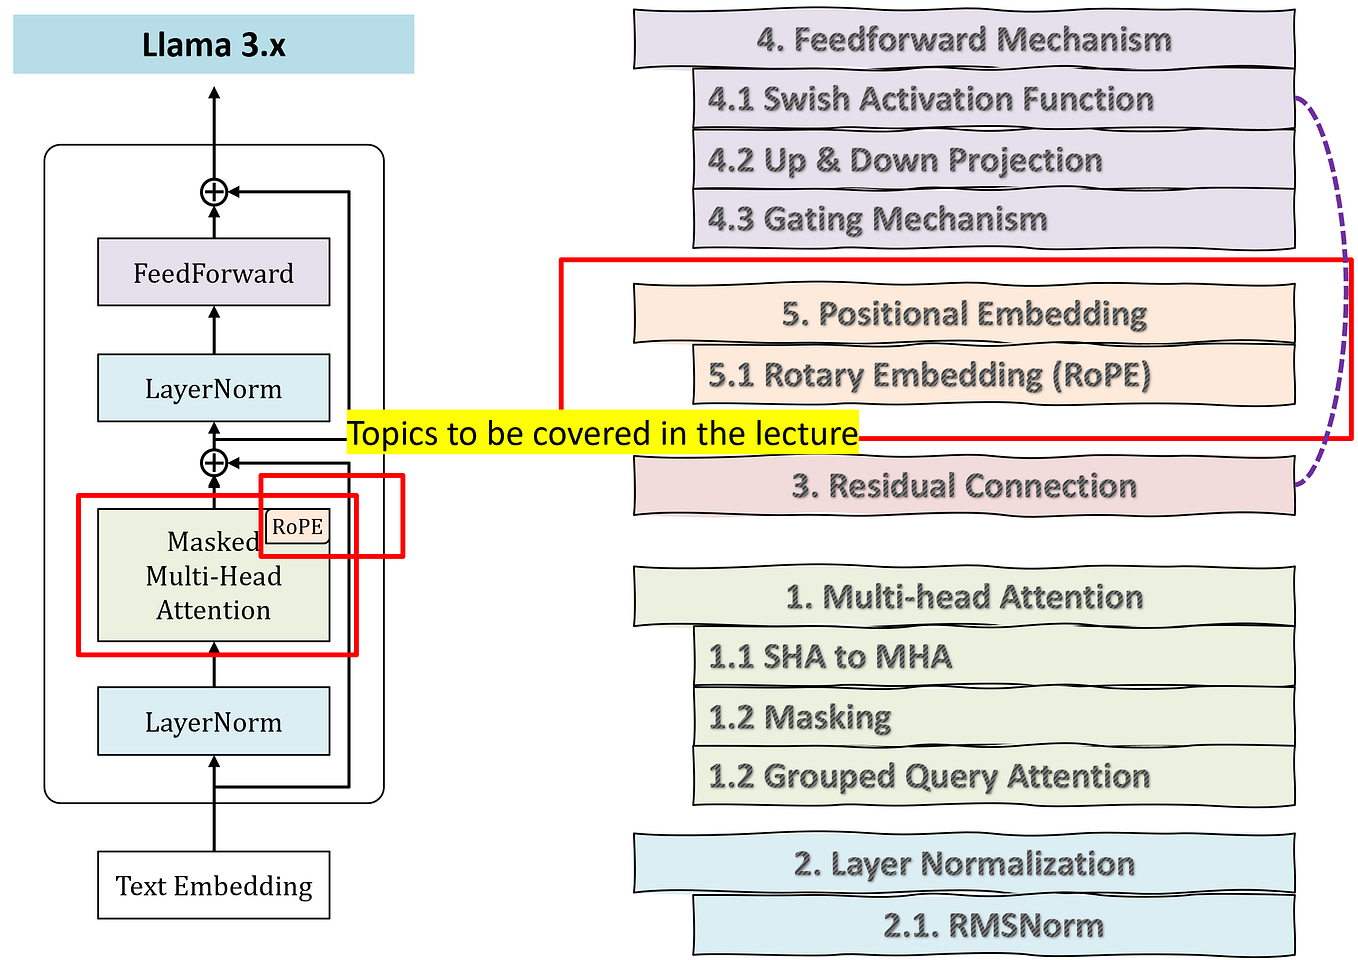
Understanding the Depth of Foundational Large Language Models & Text ...
The Prompt Alchemist: Automated LLM-Tailored Prompt Optimization for ...
LLM Data Labeling: How to Use It Right in 2025 | Label Your Data
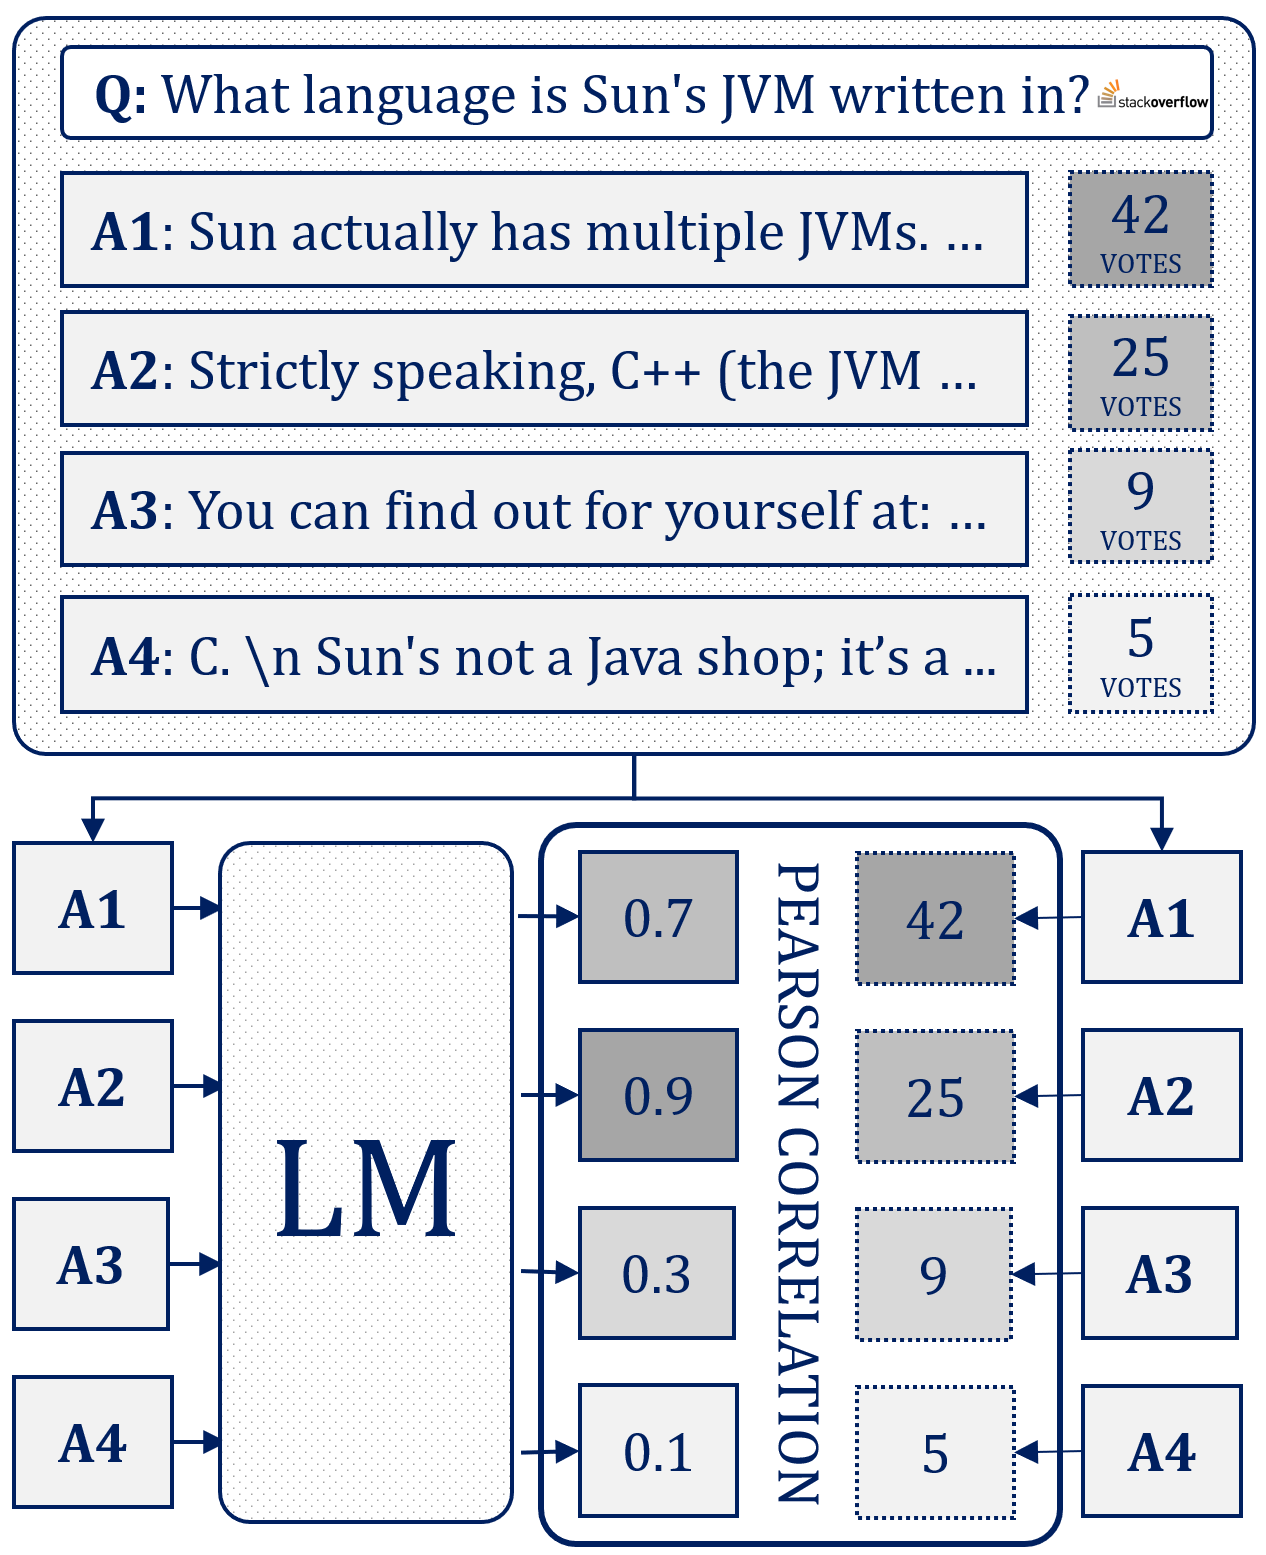
Modeling and automating human preferences for LLM evaluation
Best LLM Evaluation Tools: Top 9 Frameworks for Testing AI Models ...
[論文レビュー] AgentA/B: Automated and Scalable Web A/BTesting with ...
LLM Evaluation Metrics: Everything You Need for LLM Evaluation ...
Demystifying LLM Evaluation Frameworks: A Closer Look at Metrics ...
The Top 10 LLM Evaluation Tools - Big Data Analytics News
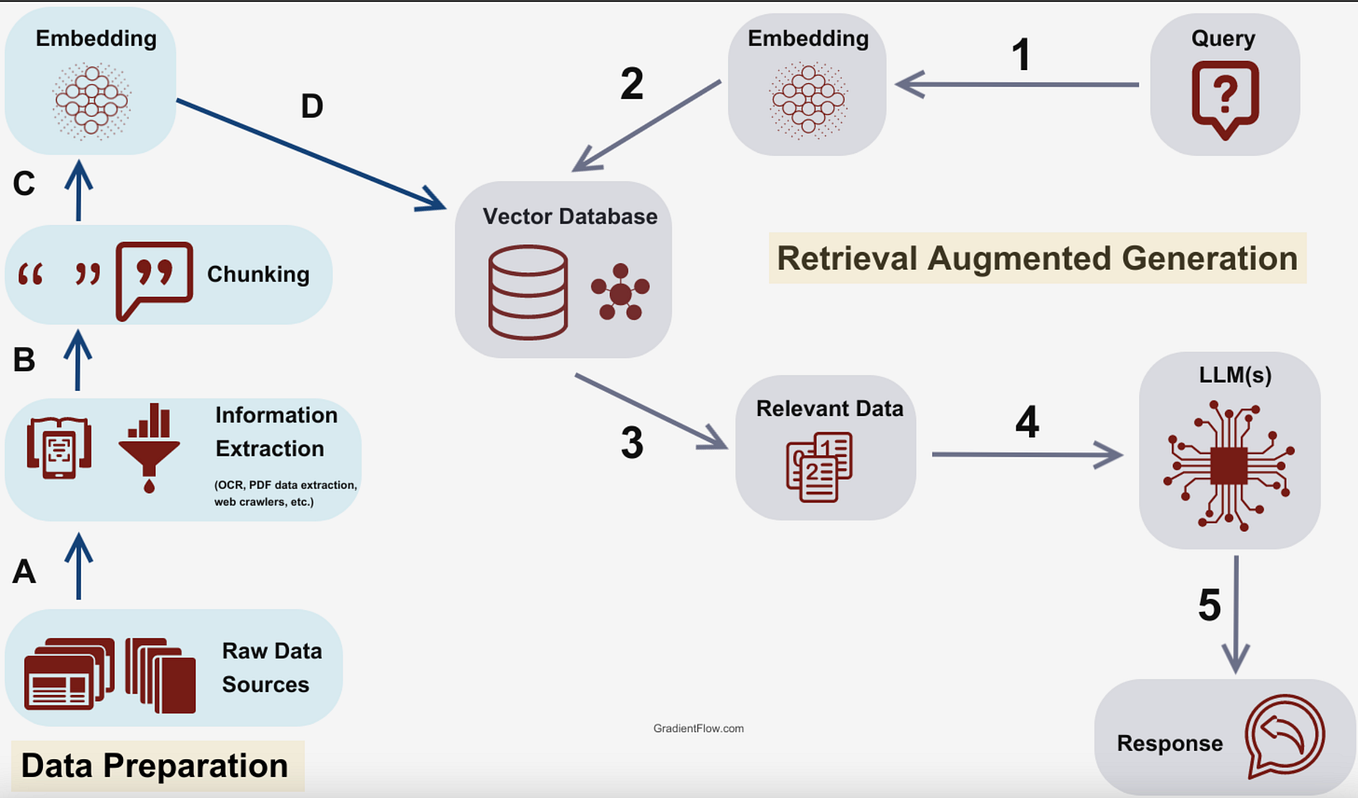
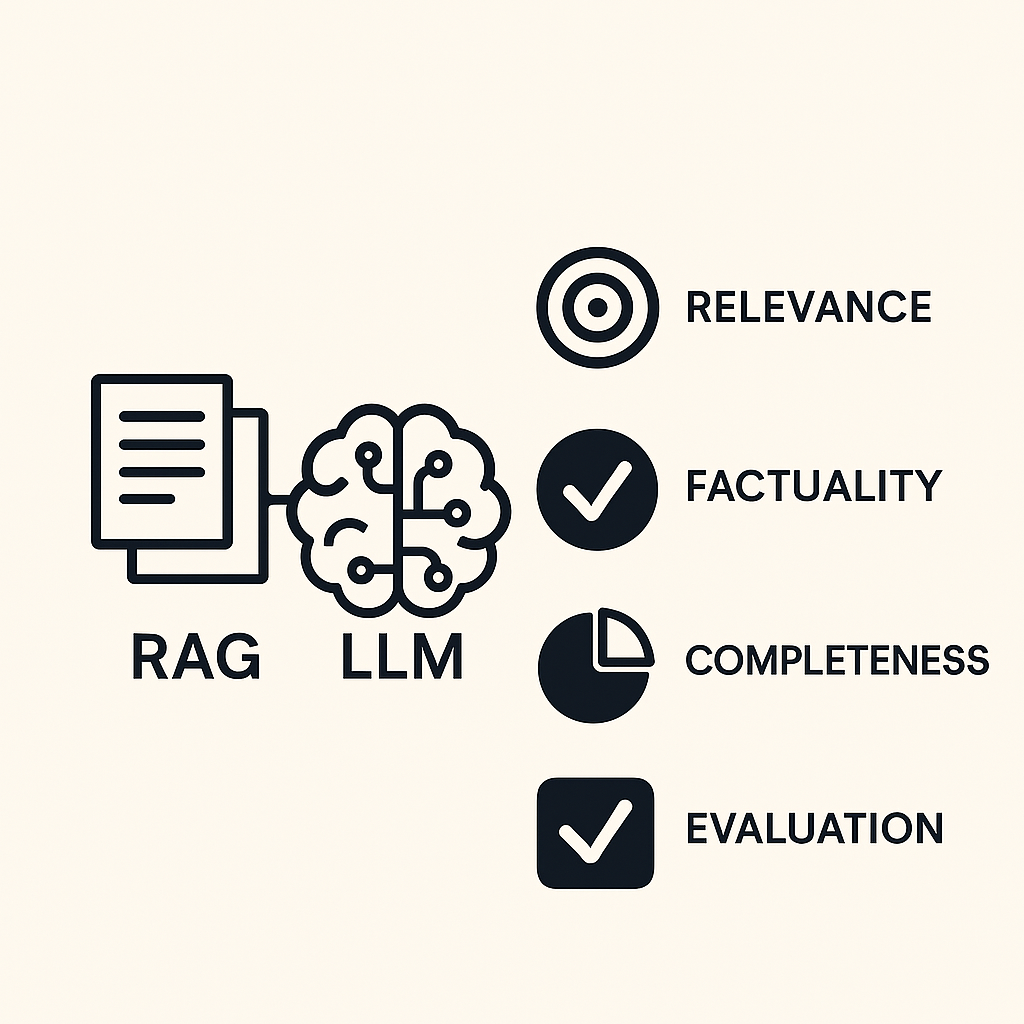
LLM Evaluation for RAG and Summarisation | by ASHPAK MULANI | May, 2025 ...
Paper Review: AgentA/B: Automated and Scalable Web A/BTesting with ...
LLM Cheatsheet and it's brief introduction | PDF
Build an automated generative AI solution evaluation pipeline with ...
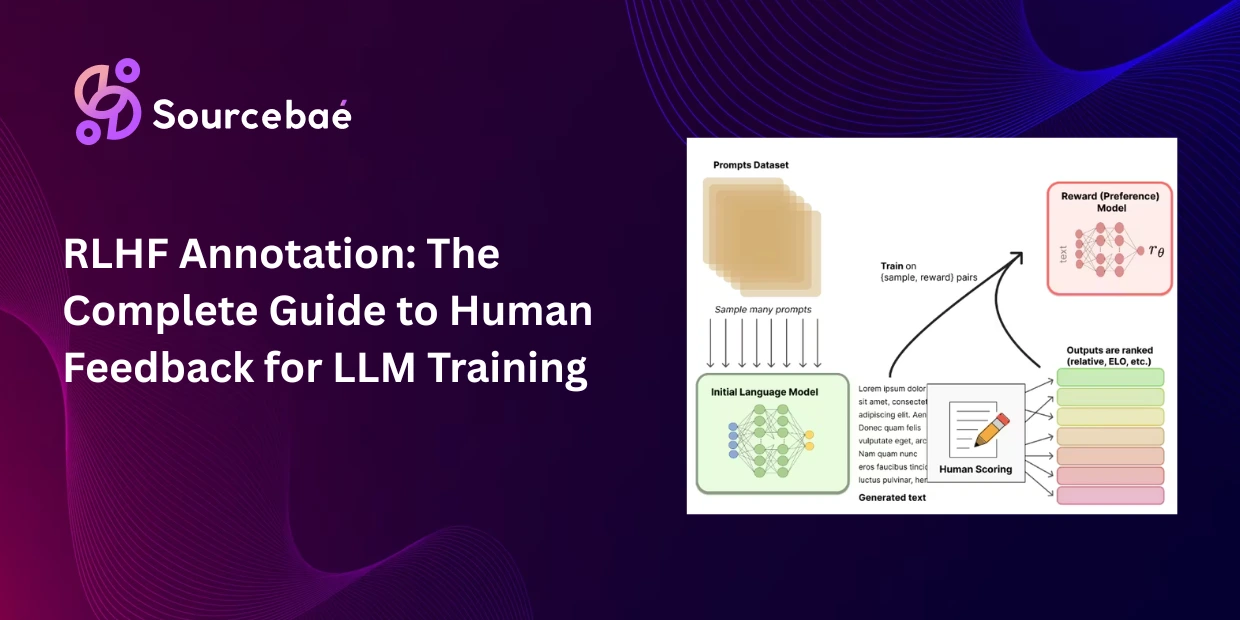
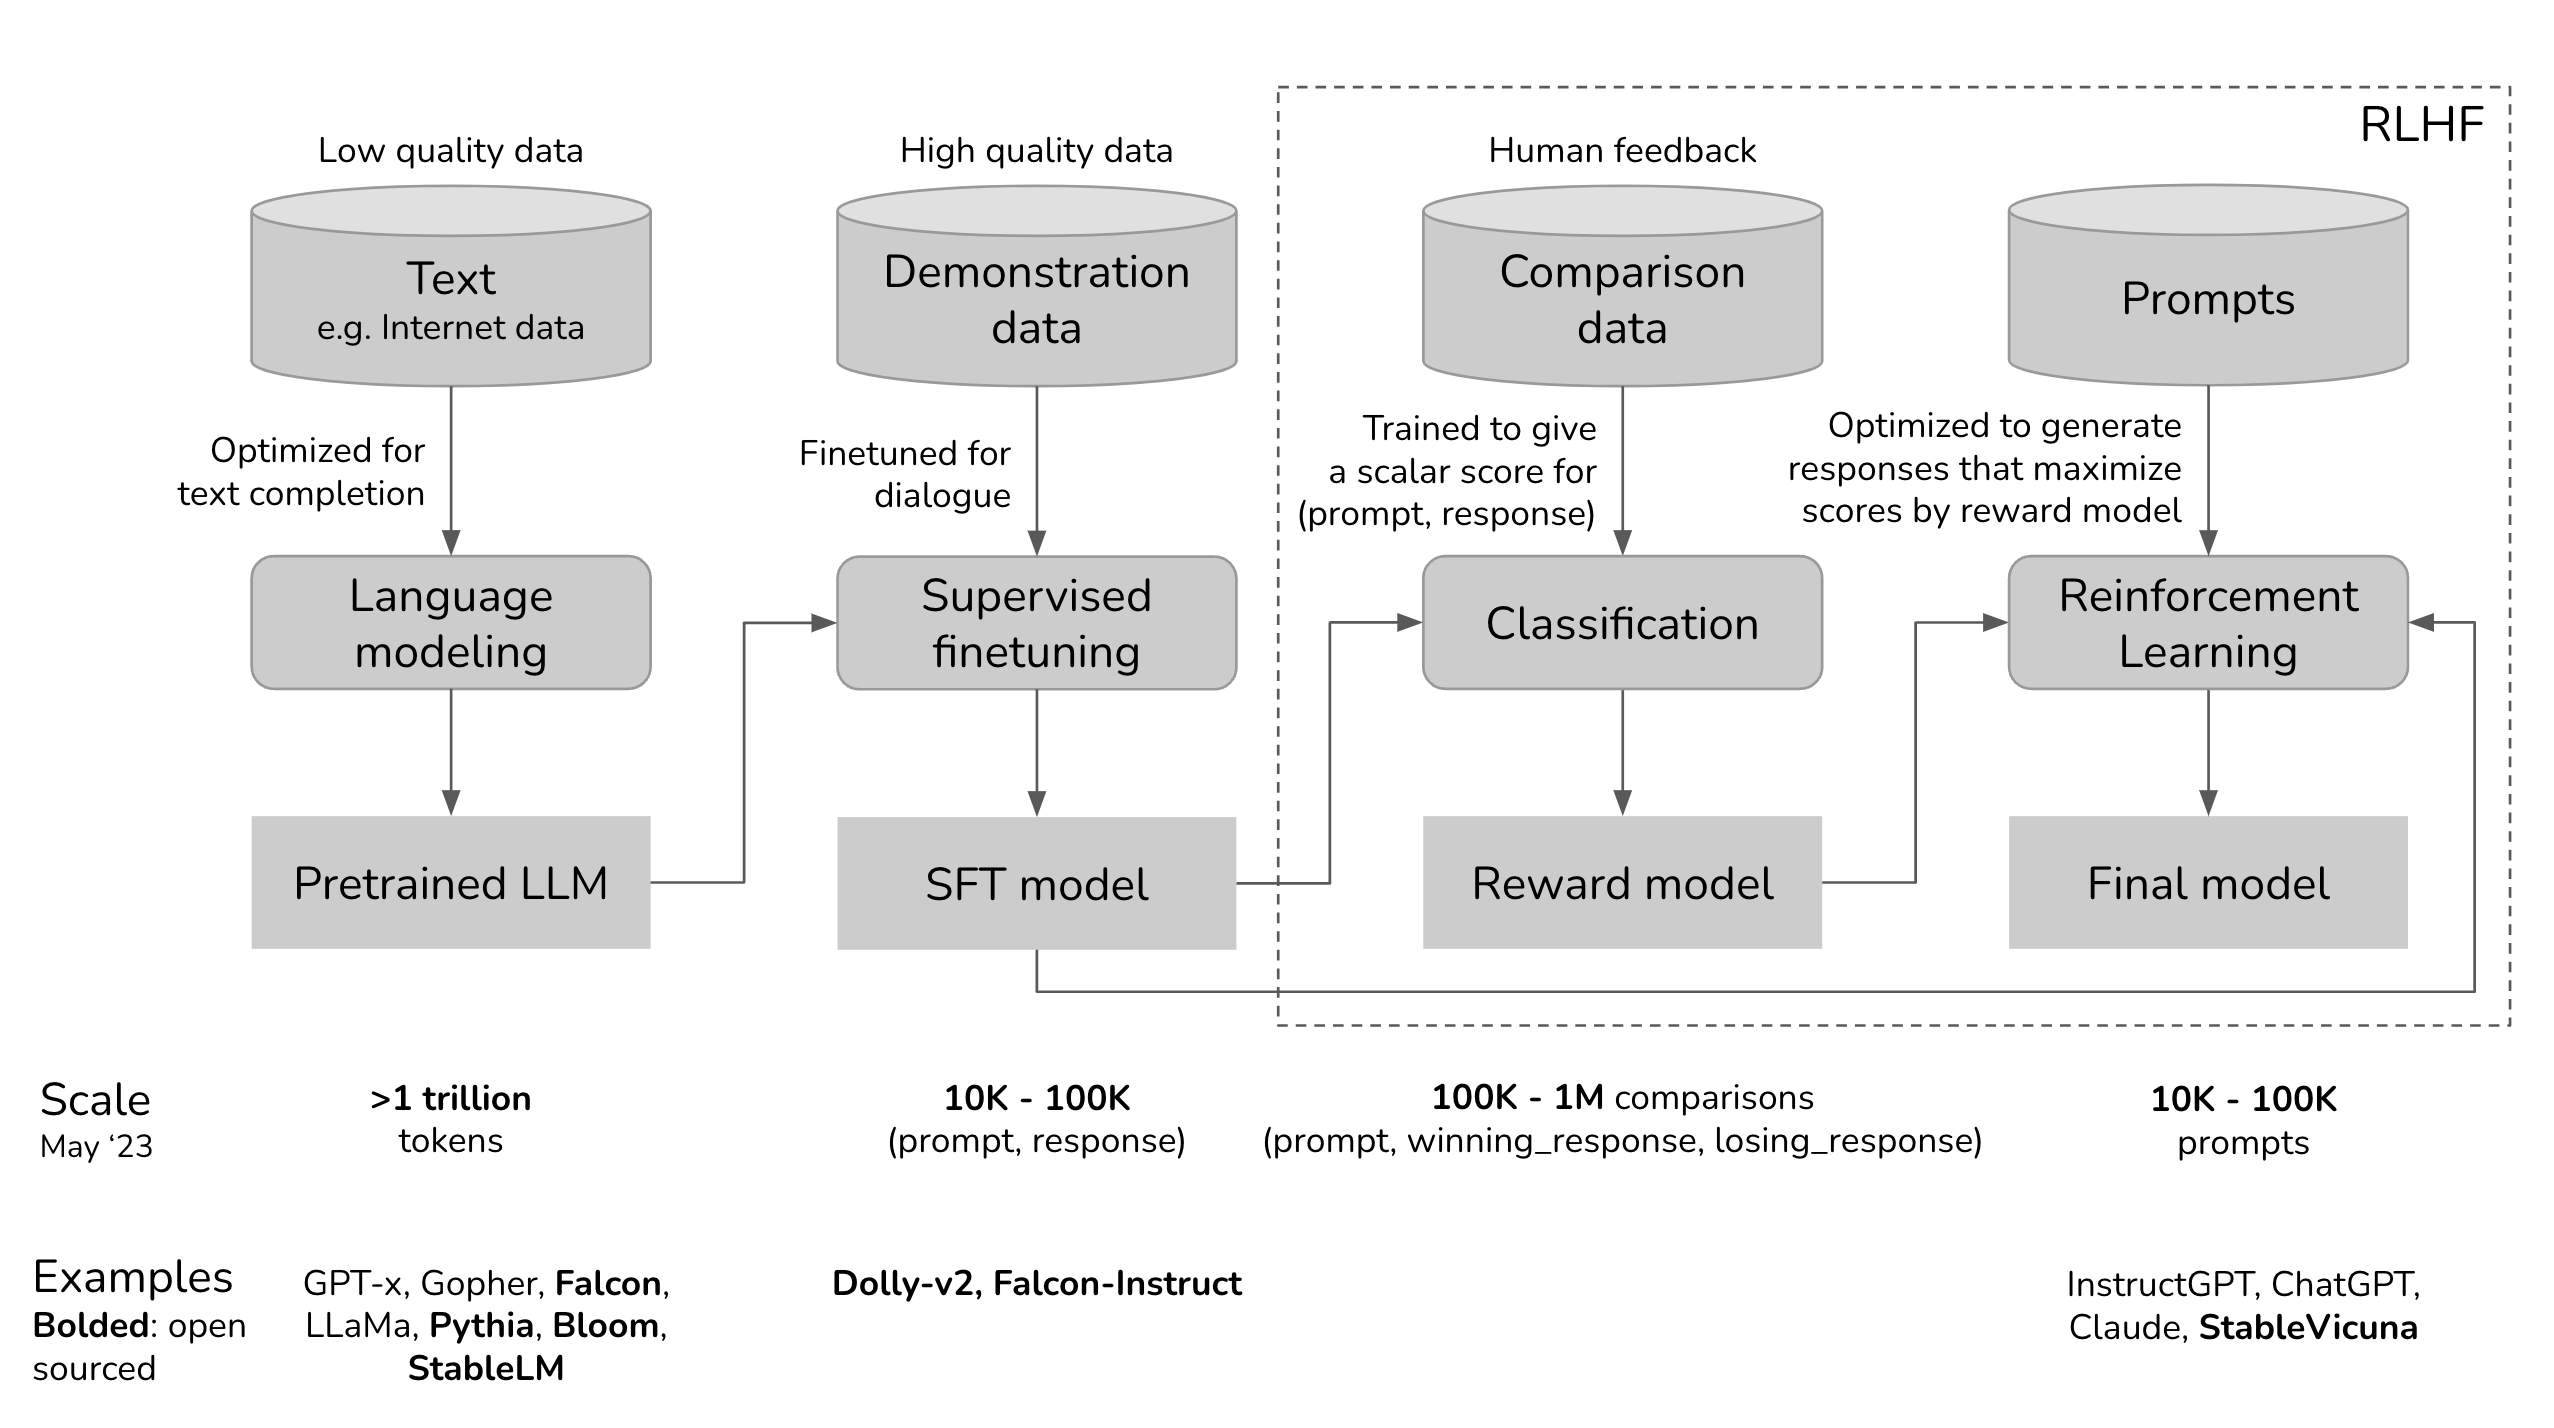
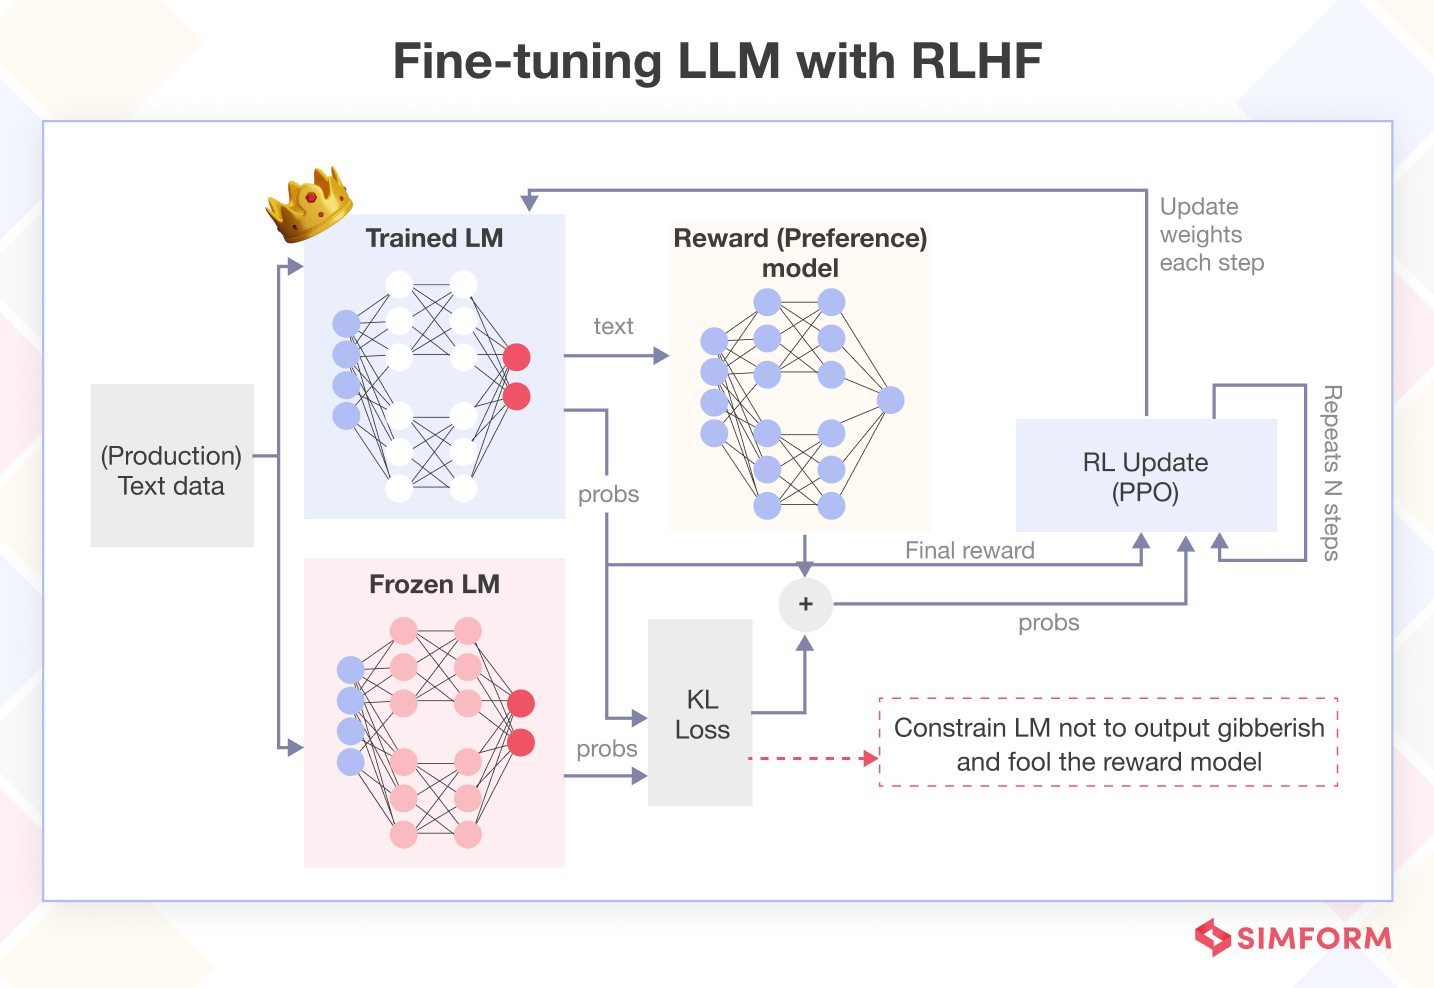
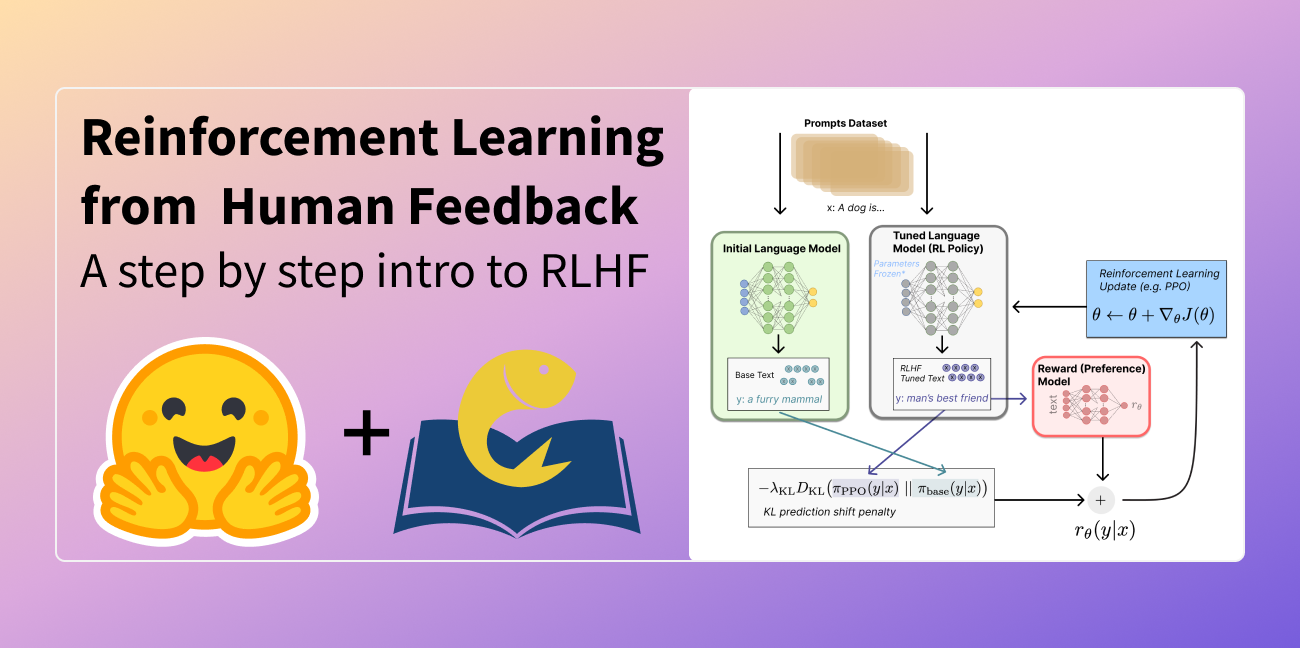
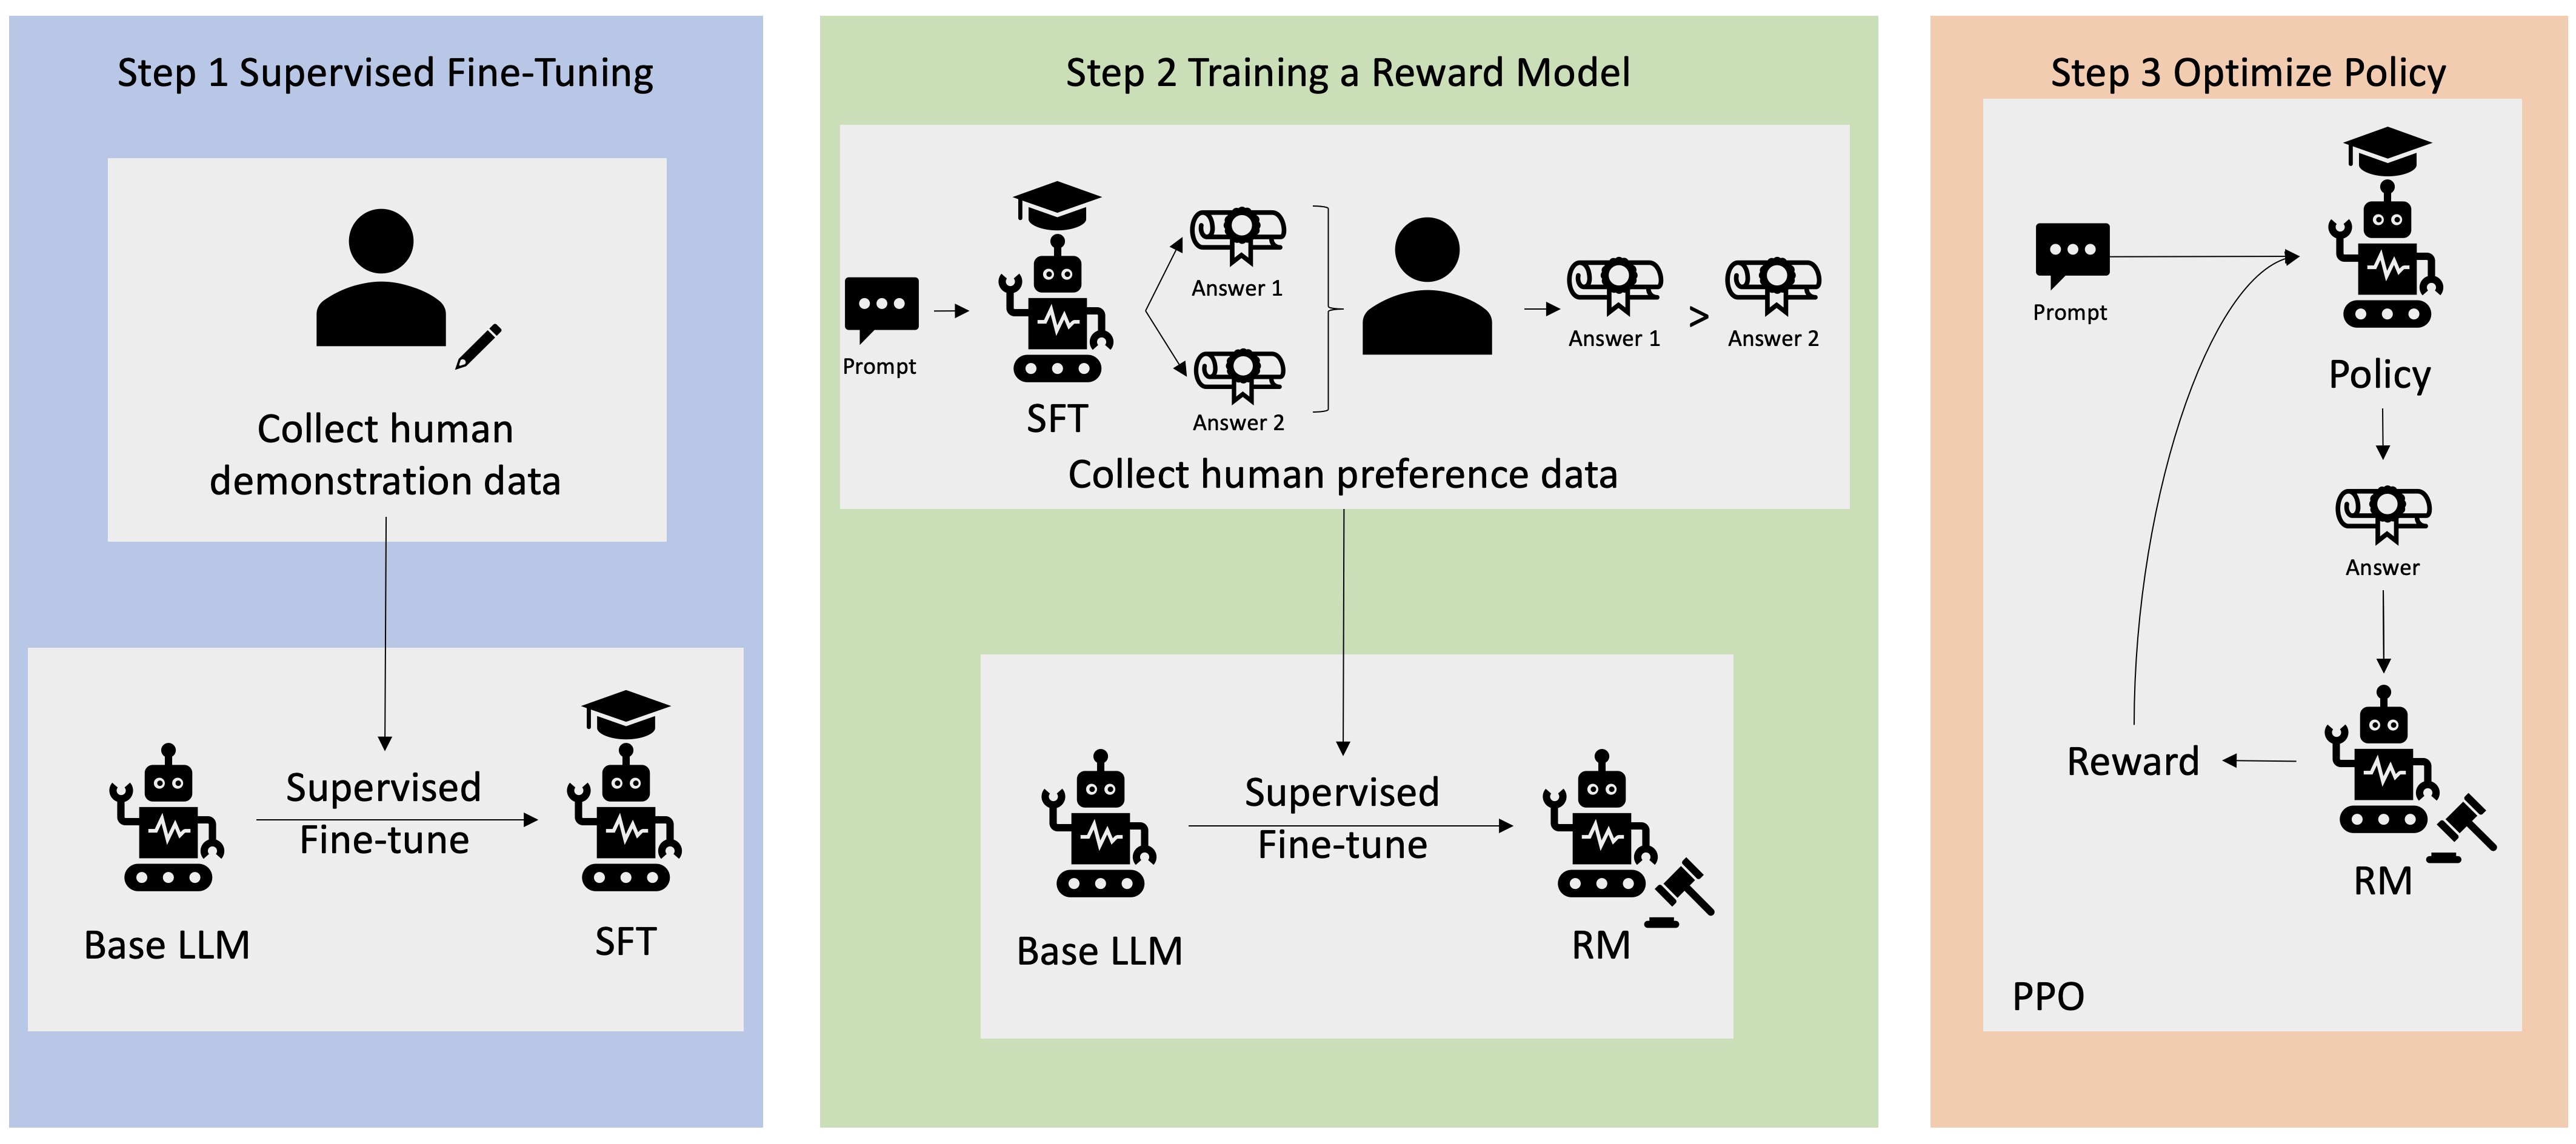
RLHF Annotation: The Complete Guide to Human Feedback for LLM Training ...
[论文评述] RoSE: Round-robin Synthetic Data Evaluation for Selecting LLM ...
Evaluating LLM Accuracy with lm-evaluation-harness for local server: A ...
Navigating the LLM Evaluation Metrics Landscape - RTInsights
[논문 리뷰] Steamroller Problems: An Evaluation of LLM Reasoning Capability ...
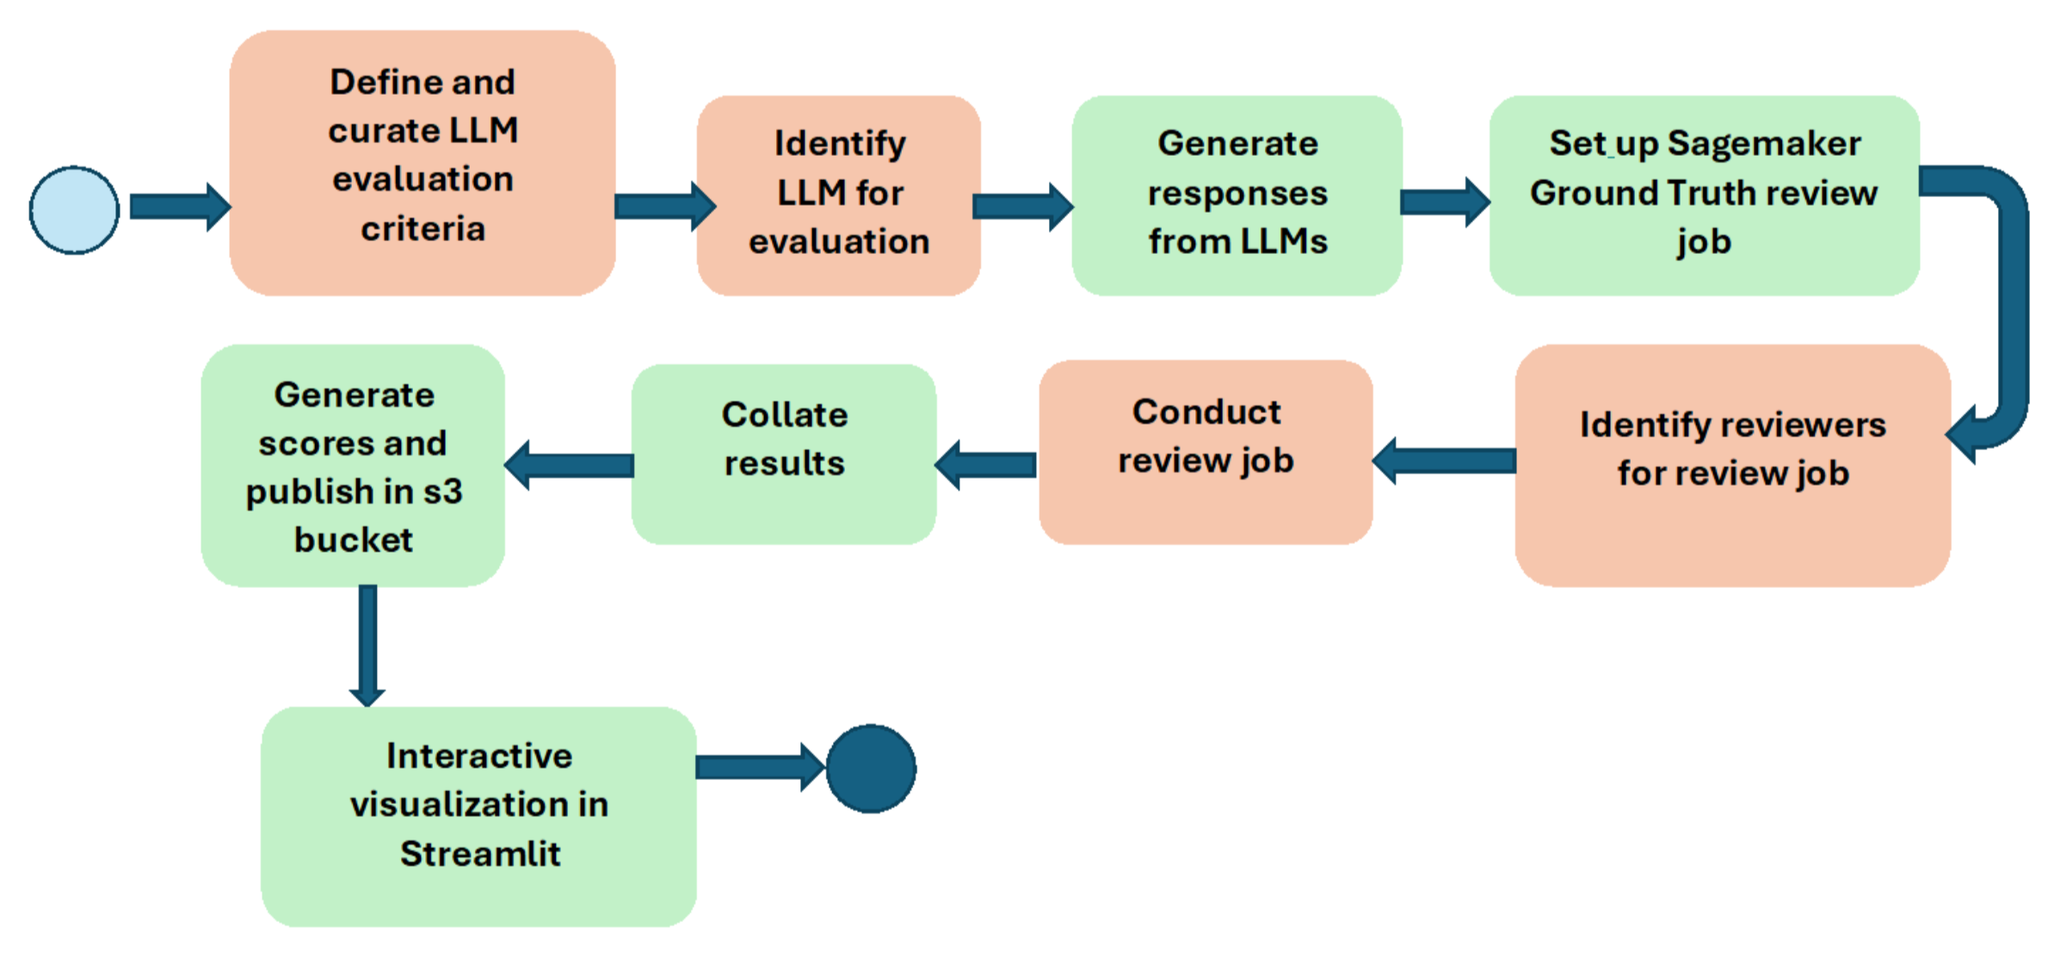
Operationalize LLM Evaluation at Scale using Amazon SageMaker Clarify ...
The Complete Guide to LLM Evaluation Tools in 2026
An LLM Evaluation Framework for AI Systems Performance | Leading EDJE
Agent-as-a-Judge: Redefining LLM Evaluation with Agent-Based Assessment ...
(PDF) Aligning ASR Evaluation with Human and LLM Judgments ...
LLM-as-a-judge: can AI systems evaluate human responses and model outputs?
Evaluación de un LLM: Métricas, metodologías y buenas prácticas | DataCamp
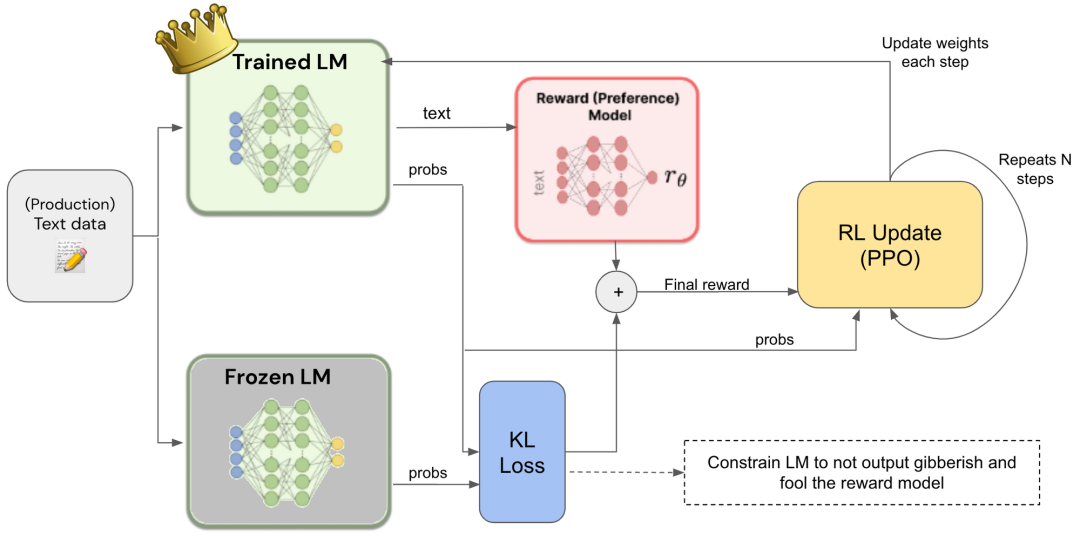
Apprentissage par RLHF pour les LLMs et autres modèles
An overview of an LLM-based Human-Robot Collaboration System, featuring ...
📝 Guest Post: Designing Prompts for LLM-as-a-Judge Model Evals*
Model Accuracy Evaluation Guide | Label Studio
GraderAssist: A Graph-Based Multi-LLM Framework for Transparent and ...
Fine Tuning Process _ The Art of Fine-Tuning AI Models: A Beginner’s ...
一文彻底搞懂大模型 - 基于人类反馈的强化学习(RLHF)_大模型强化学习rlhf-CSDN博客
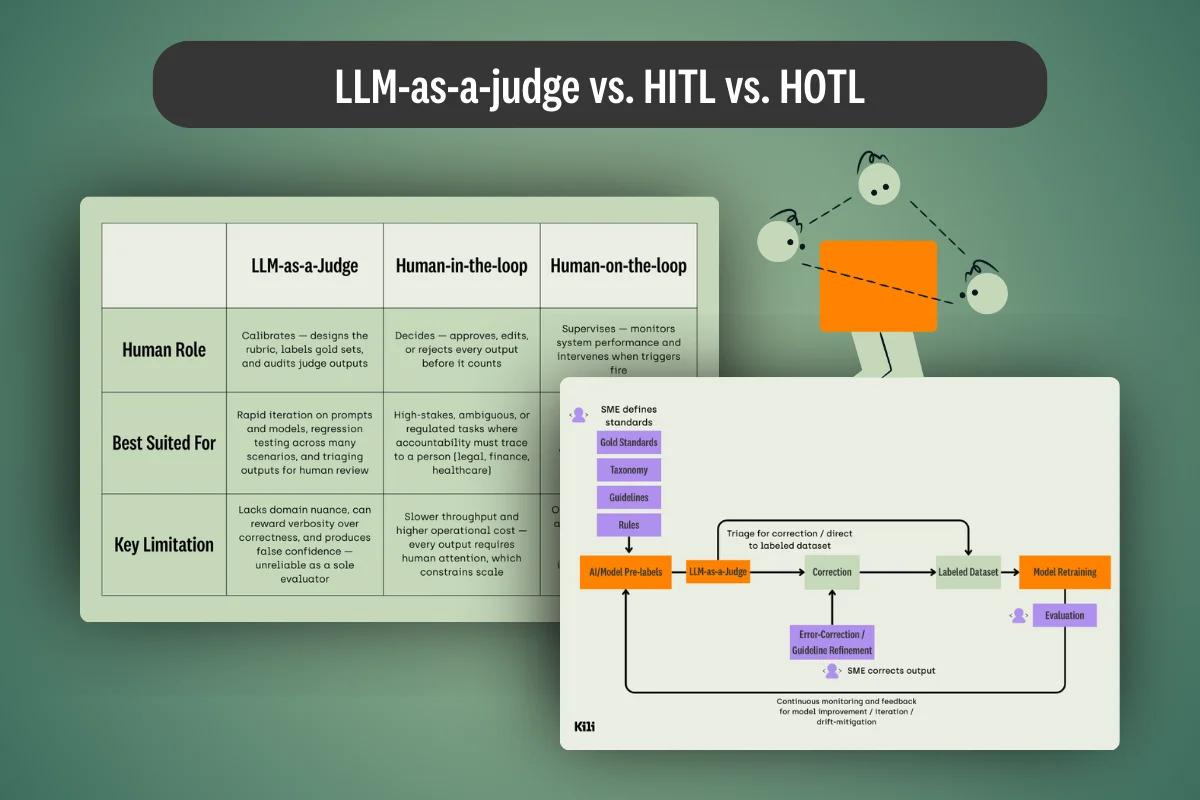
Human-in-the-Loop, Human-on-the-Loop, and LLM-as-a-Judge for Validating ...
Evaluation metrics | Microsoft Learn
LangChain: Automating Large Language Model (LLM) Evaluation
RAG evaluation with Ragas. Retrieval Augmented Generation (RAG)… | by ...
Tracy Allison Altman, PhD on LinkedIn: Impressive work summarizing ...
Can Large-Scale Language Models Replace Humans in Text Evaluation Tasks ...
LLMOps: Automation and Orchestration of LLMs’ Workflows | by Sulaiman ...
ChatGPT 背后的“功臣”——RLHF 技术详解
Paper page - Who Validates the Validators? Aligning LLM-Assisted ...
Exploring the Different Types of Foundational Models in AI | Deepchecks
RLHF とは何ですか? - 人間のフィードバックによる強化学習の説明 - AWS
LangSmith_and_LLM_Evaluation_Session 1.pptx
GitHub - CSHaitao/Awesome-LLMs-as-Judges: The official repo for paper ...
Check Your Facts and Try Again: Improving Large Language Models with ...
ModernBERT: The Next Generation of Encoder Models — A Guide to Using ...
AI Model Evaluation Explained | Miquido
[论文评述] VeriLA: A Human-Centered Evaluation Framework for Interpretable ...
Valutazione del modello linguistico di grandi dimensioni nel 2026 ...
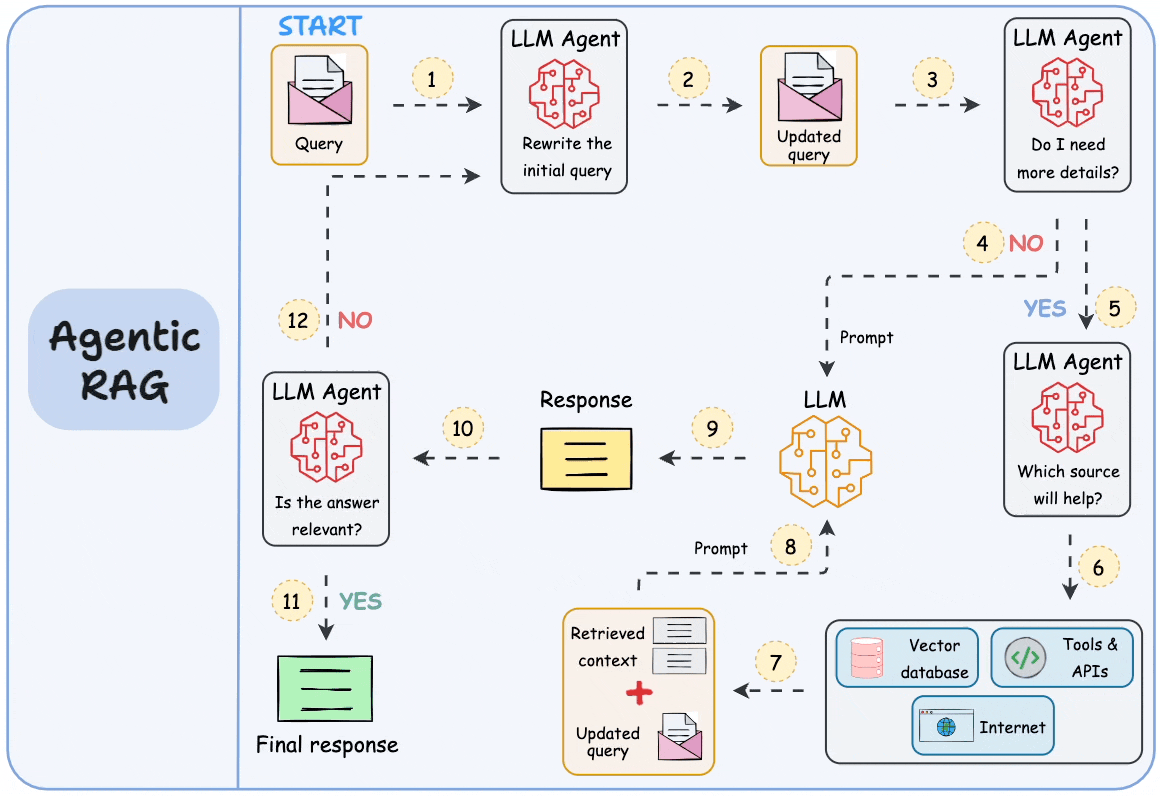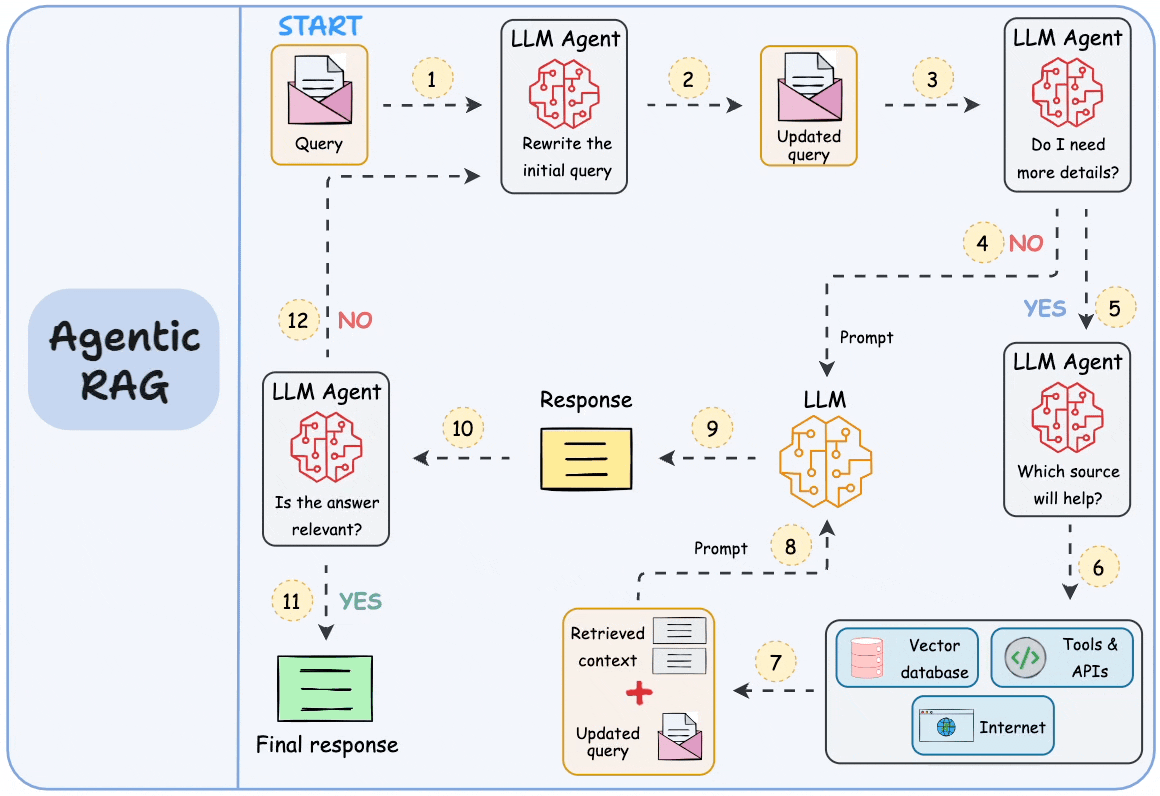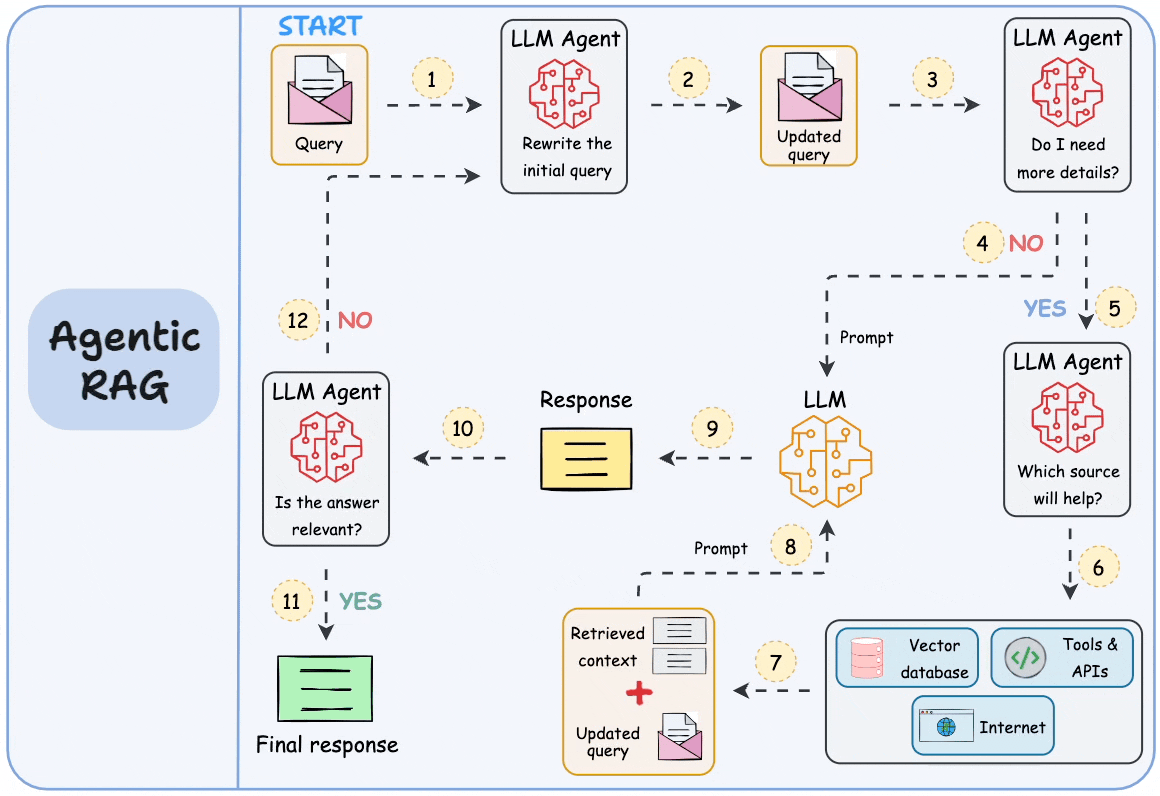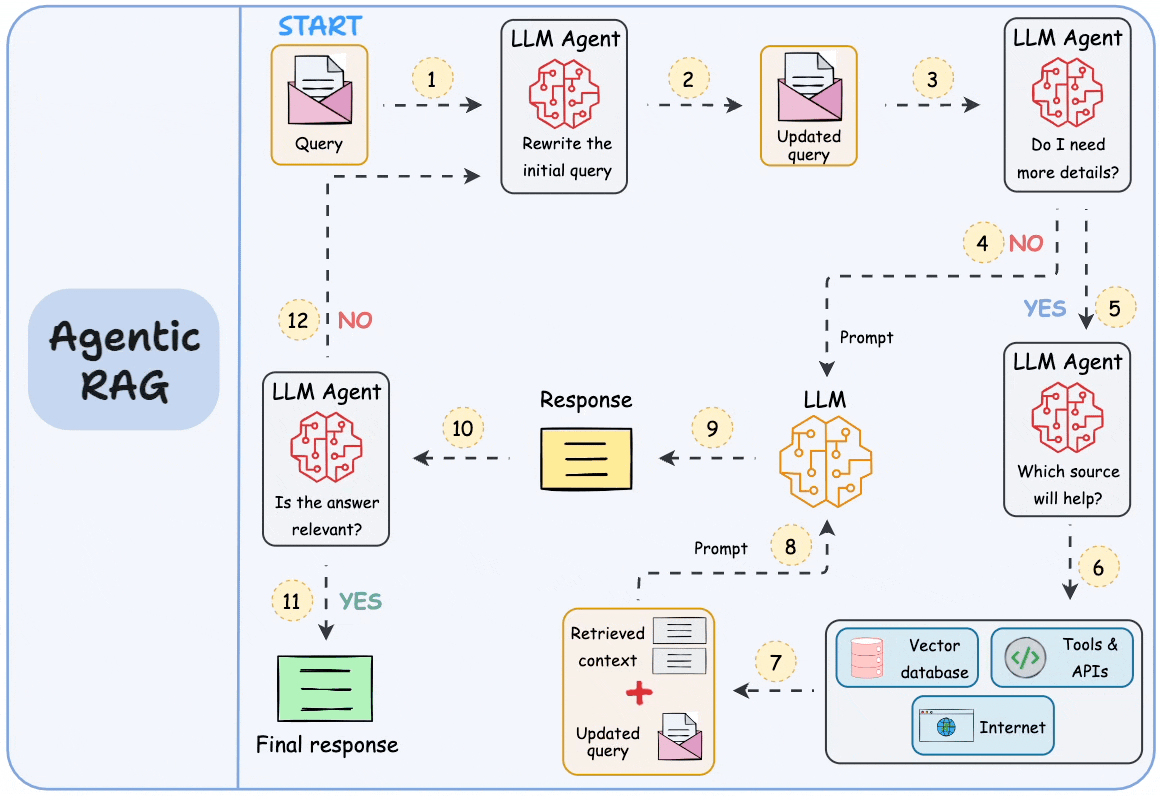
大模型LLM | 一文彻底搞懂大模型Agent(智能体):Agent、Agent + RAG_llm agent-CSDN博客
LLM-powered function calling — get started! A simple example in Python ...
[논문 리뷰] LLM-Rubric: A Multidimensional, Calibrated Approach to ...
Best Practices and Metrics for Evaluating Large Language Models (LLMs)
[Literature Review] Memory-Augmented LLM-based Multi-Agent System for ...
LLM-as-a-Judge: Essential AI Governance for Financial Services
Finetuning LLMs Efficiently with Adapters
Comprehensive Evaluation Metrics for Retrieval-Augmented Generation ...
A Comprehensive Guide to Function Calling in LLMs - The New Stack
Based on this image's title: “LLM Evaluation: Human, Automated & Function-Based Approaches”