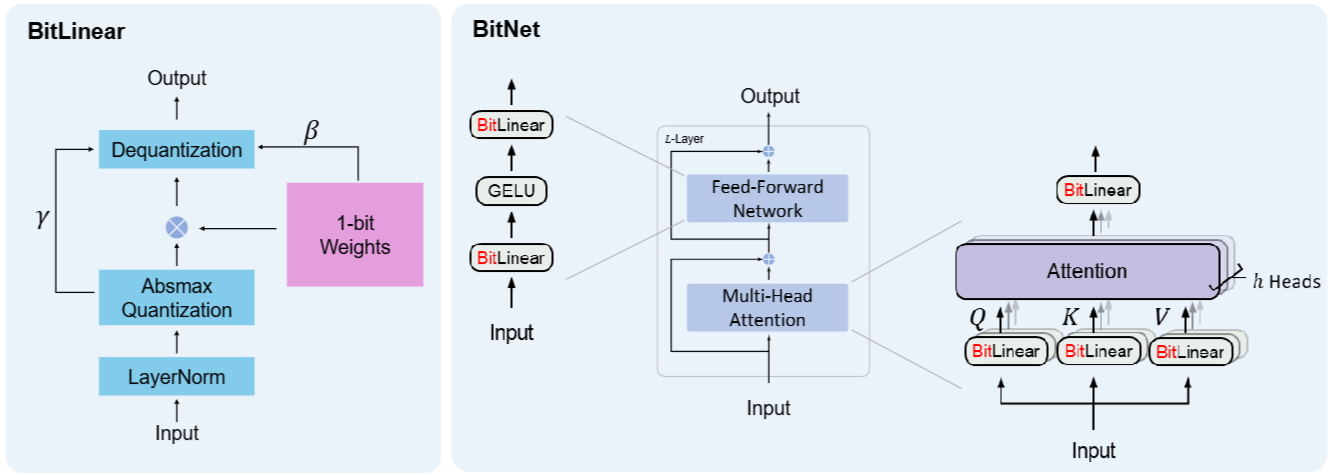
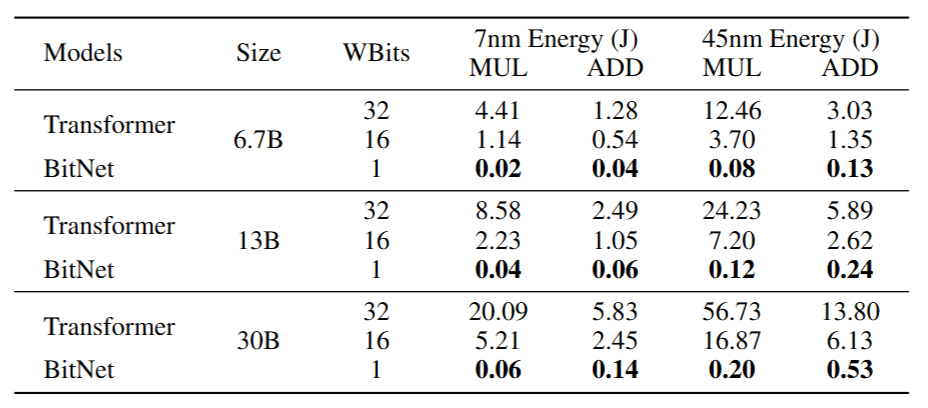
BitNet: Scaling 1-bit Transformers for Large Language Models review and ...
BitNet: Scaling 1-bit Transformers for Large Language Models ...
BitNet: Scaling 1-bit Transformers for Large Language Models : r ...
BitNet: Scaling 1-bit Transformers for Large Language Models - Paper ...
BitNet: Scaling 1-bit Transformers for Large Language Models | Unknown ...
BitNet: Scaling 1-bit Transformers for Large Language Models - JunHan’s ...
[2310.11453] BitNet: Scaling 1-bit Transformers for Large Language Models
BitNet: Scaling 1-bit Transformers for Large Language Models - YouTube
論文要約:BitNet: Scaling 1-bit Transformers for Large Language Models ...
42. BitNet: Scaling 1-bit Transformer for Large Language Models & The ...
BitNet: Scaling 1-bit Transformers for Large Language Models - AIincider
BitNet: Scaling 1-bit Transformers forLarge Language Models (2023) Review
BitNet Scaling 1-bit Transformers for Large Language Models
The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits and ...
2. The Era Of 1-bit LLMs: All Large Language Models Are In 1.58 Bits ...
Revolutionizing Large Language Models with 1-Bit Transformer
The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits
BitNet b1.58: Pioneering the Future of Efficient Large Language Models ...
BitNet 1-Bit LLM: Revolutionizing On-Device Language Models | by ...
The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits - 智源社区论文
Free Video: BitNet.cpp - CPU Inference Framework for 1-bit Large ...
GitHub - Rifsx/BitNet-: Implementation of "BitNet: Scaling 1-bit ...
Microsoft 1-bit transformers for LMM
How 1-bit transformer works for AI | Georgios Korpas, Ph.D., MSCS ...
A Gentle Introduction to 8-bit Matrix Multiplication for transformers ...
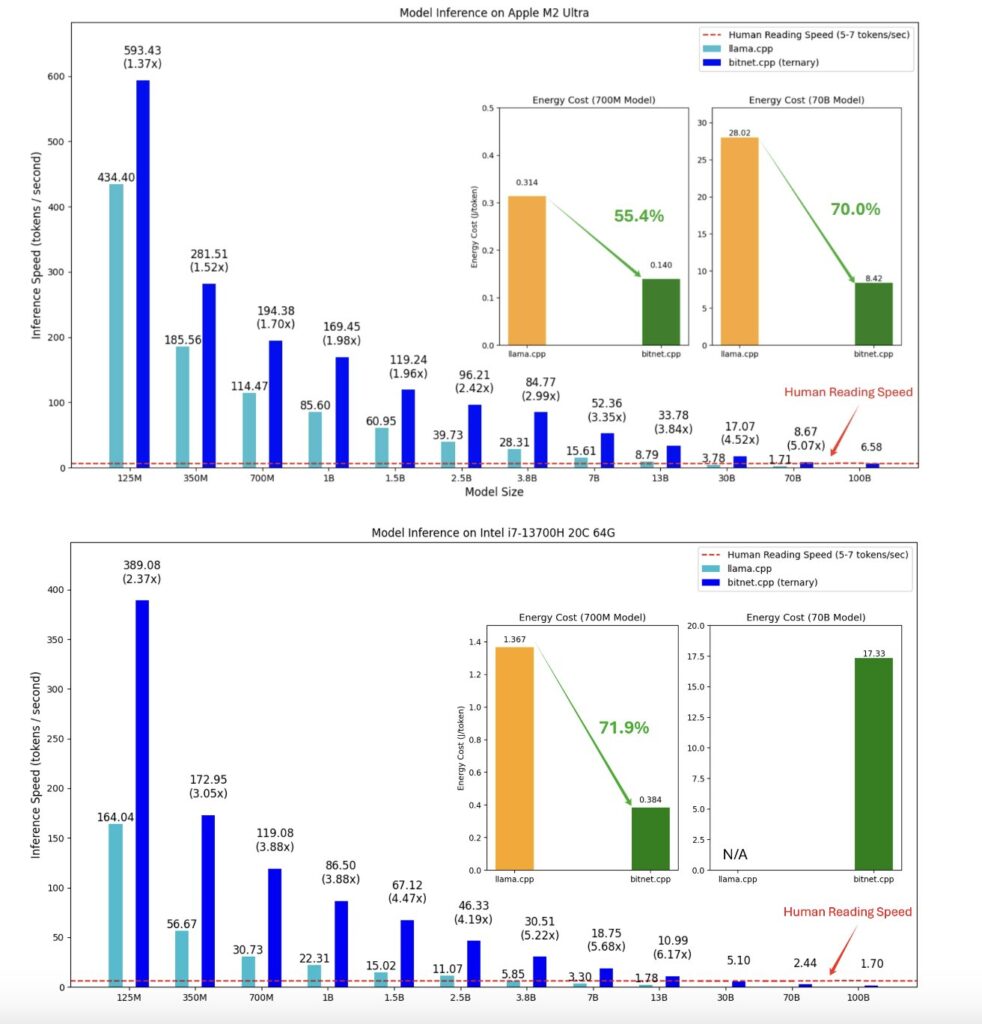
Microsoft Open-Sources 1-bit LLMs: Run 100B Parameter Models Locally ...
AILAB Blog: Revolutionizing AI: The Breakthrough of 1-bit Large ...
George Z. Lin on LinkedIn: MSR has showcased BitNet, a novel 1-bit ...
Microsoft Unveils BitNet b1.58 2B4T, 1-Bit LLM Trained on 4T Tokens ...
Paper page - BitNet a4.8: 4-bit Activations for 1-bit LLMs
GitHub - kurhula/microsoft_BitNet: Official inference framework for 1 ...
BitNet v2: Native 4-bit Activations with Hadamard Transformation for 1 ...
Bit-LoRA as an application of BitNet and 1.58 bit neural network ...
Microsoft and UCAS Develop BitNet v2 with Native 4-Bit Activations ...
BitNet a4.8: 4-Bit Activations for LLMs | PDF | Applied Mathematics ...
GitHub - Beomi/BitNet-Transformers: 0️⃣1️⃣🤗 BitNet-Transformers ...
人工智能 - 「模型量化技术」可视化指南:A Visual Guide to Quantization - IDP技术干货 ...
Une plongée technique dans BitNet. L’art de la quantisation. | by ...
Why isn't Microsoft's You Only Cache Once (YOCO) research talked about ...
Is HuggingFaceTB’s SmolLM2–1.7B Good Enough ? A Comparative Analysis ...
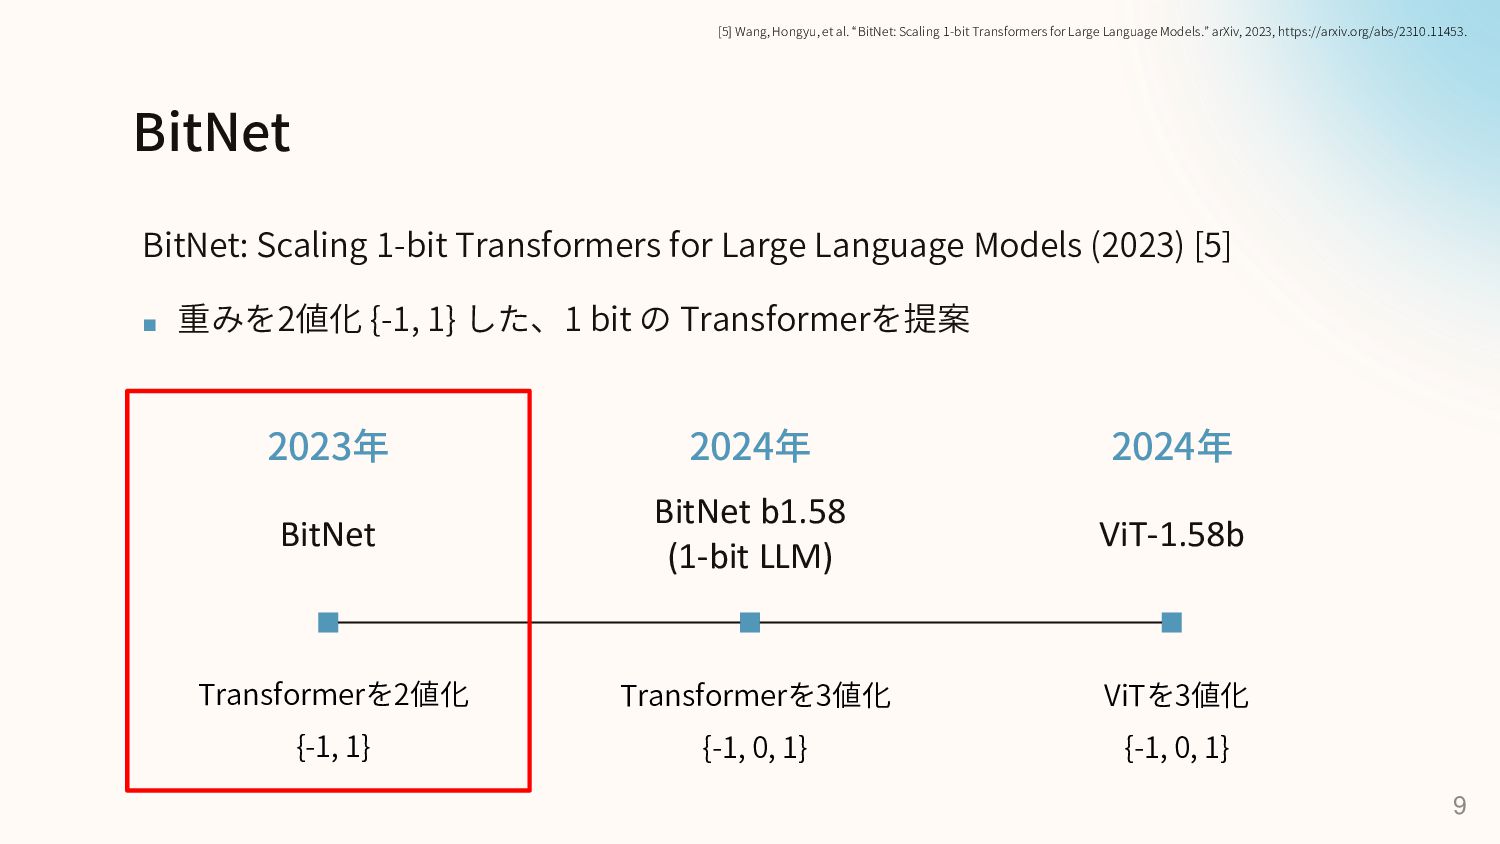
[論文輪読会] ViT-1.58b - Speaker Deck
Microsoftが驚異の1ビット大規模言語モデルを発表 | TEXAL
#bitnet #languagemodels #ai #machinelearning | Enrique Acuay
论文阅读:BitNet_Scaling_1-bit_Transformers_for_Large_Language_Models | Blogs
BitNet - 知乎
[논문 리뷰 | 정리 | 코드] BitNet
Deep Learning/NLP course – Current frontiers
微软、国科大开启1Bit时代:大模型转三进制,速度快4倍能耗降至1/41|内存|微软_新浪科技_新浪网
BitNet:1-bit Transformer - 知乎
How to Fine-tune LLMs to 1.58 bits? - Analytics Vidhya
LLM - HackQuest
1-bit大模型还能再突破!新一代BitNet架构启用4位激活值 - 知乎
今日收揽697星 BitNet:微软开源的1比特LLM推理框架,让CPU也能高效运行大模型 - 贝克街的捉虫师
微軟發表首個超過20億參數的1-bit模型 同樣效能但更省電、不占記憶體 | iThome
从0开始实现LLM:6、模型量化理论+代码实战(LLM-QAT/GPTQ/BitNet 1.58Bits/OneBit) - 知乎
BitNet Distillation | AI Research Paper Details
1bitLLM/bitnet_b1_58-3B · Is it bitnet {-1,0,1}?
分享10篇优秀论文,涉及LLM对齐、LLM评估、LLM隐私、RAG增强等热门话题! - 知乎
How BitNet b1.58 Achieves Full-Precision Performance with 1.58-Bit Weights
(논문 요약) BitNet | Jaemin’s Arxiv
BitNet - Microsoft Foundry Labs