Showing 119 of 119on this page. Filters & sort apply to loaded results; URL updates for sharing.119 of 119 on this page
python - PyTorch Optimizer: AdamW and Adam with weight decay - Stack ...
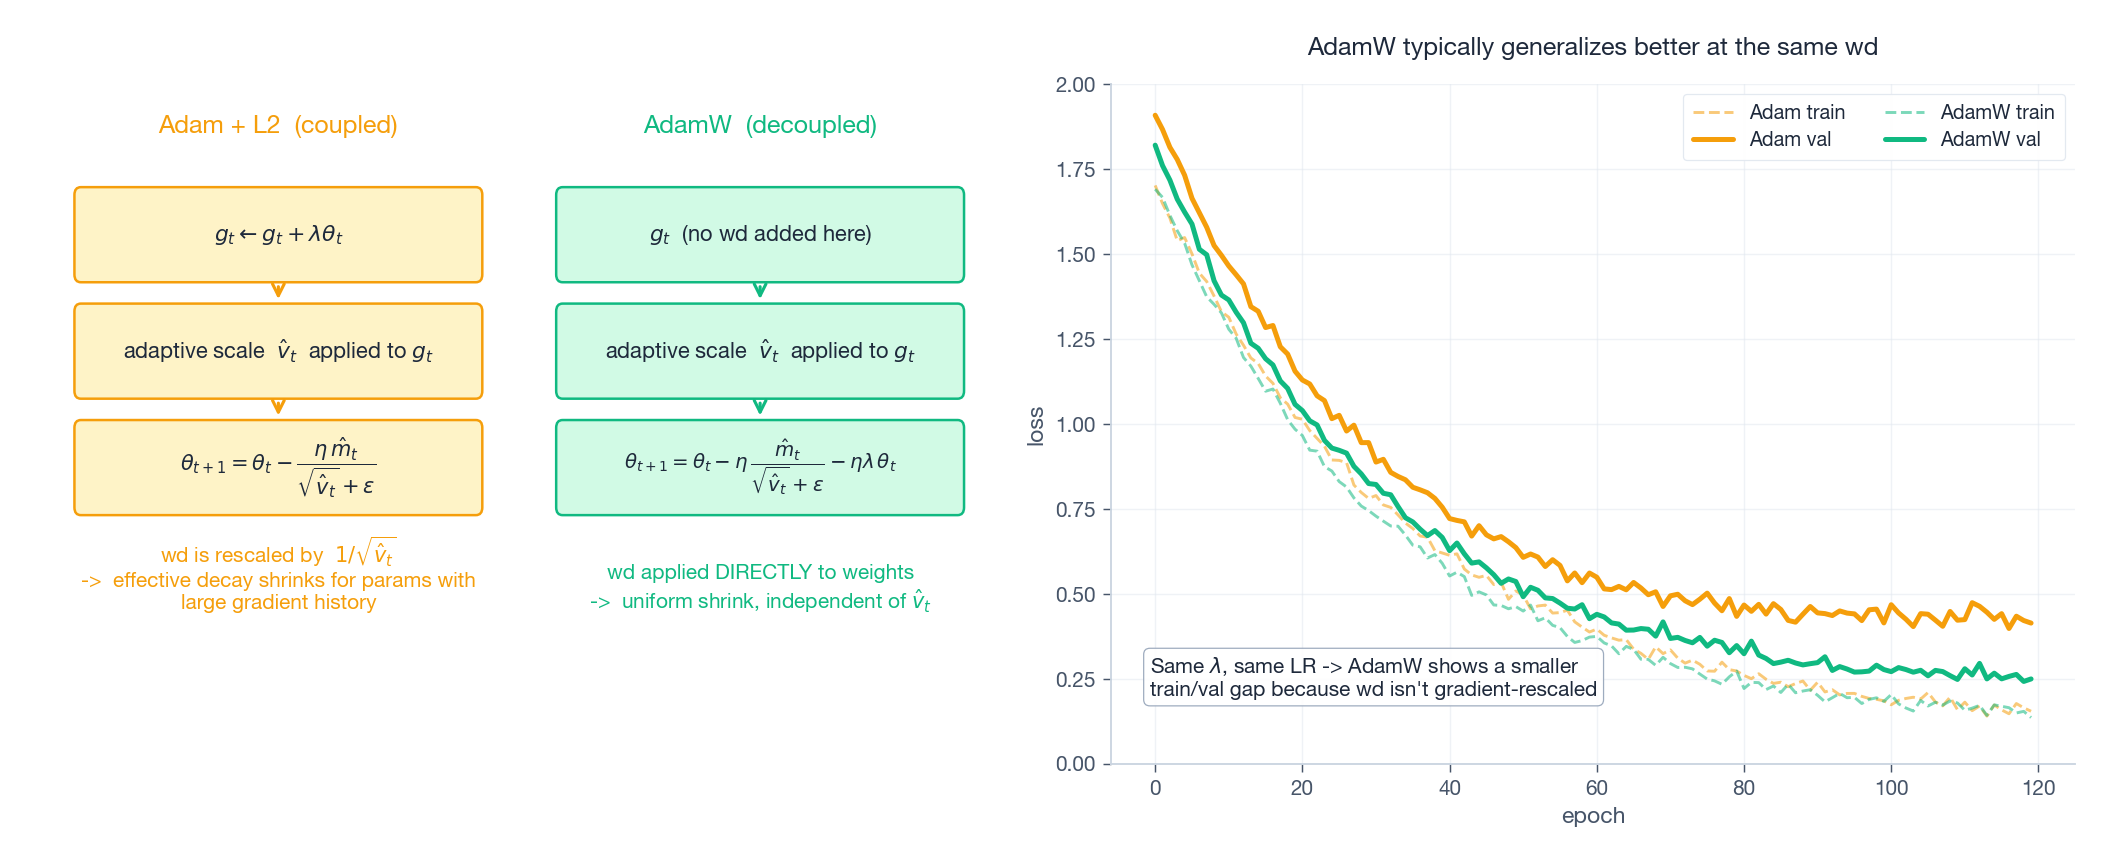
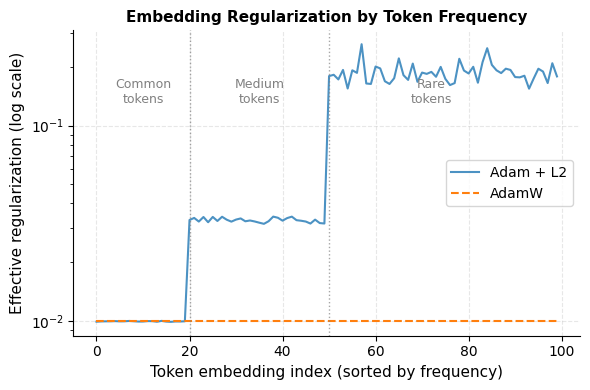
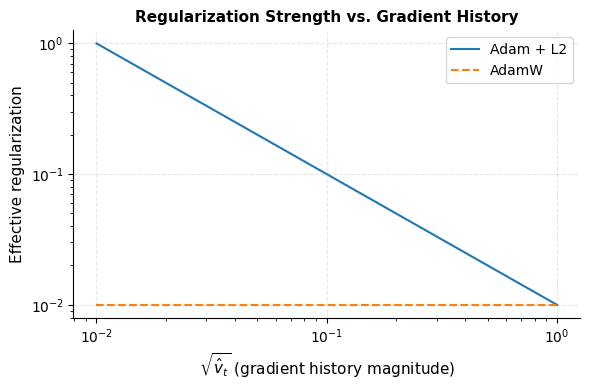
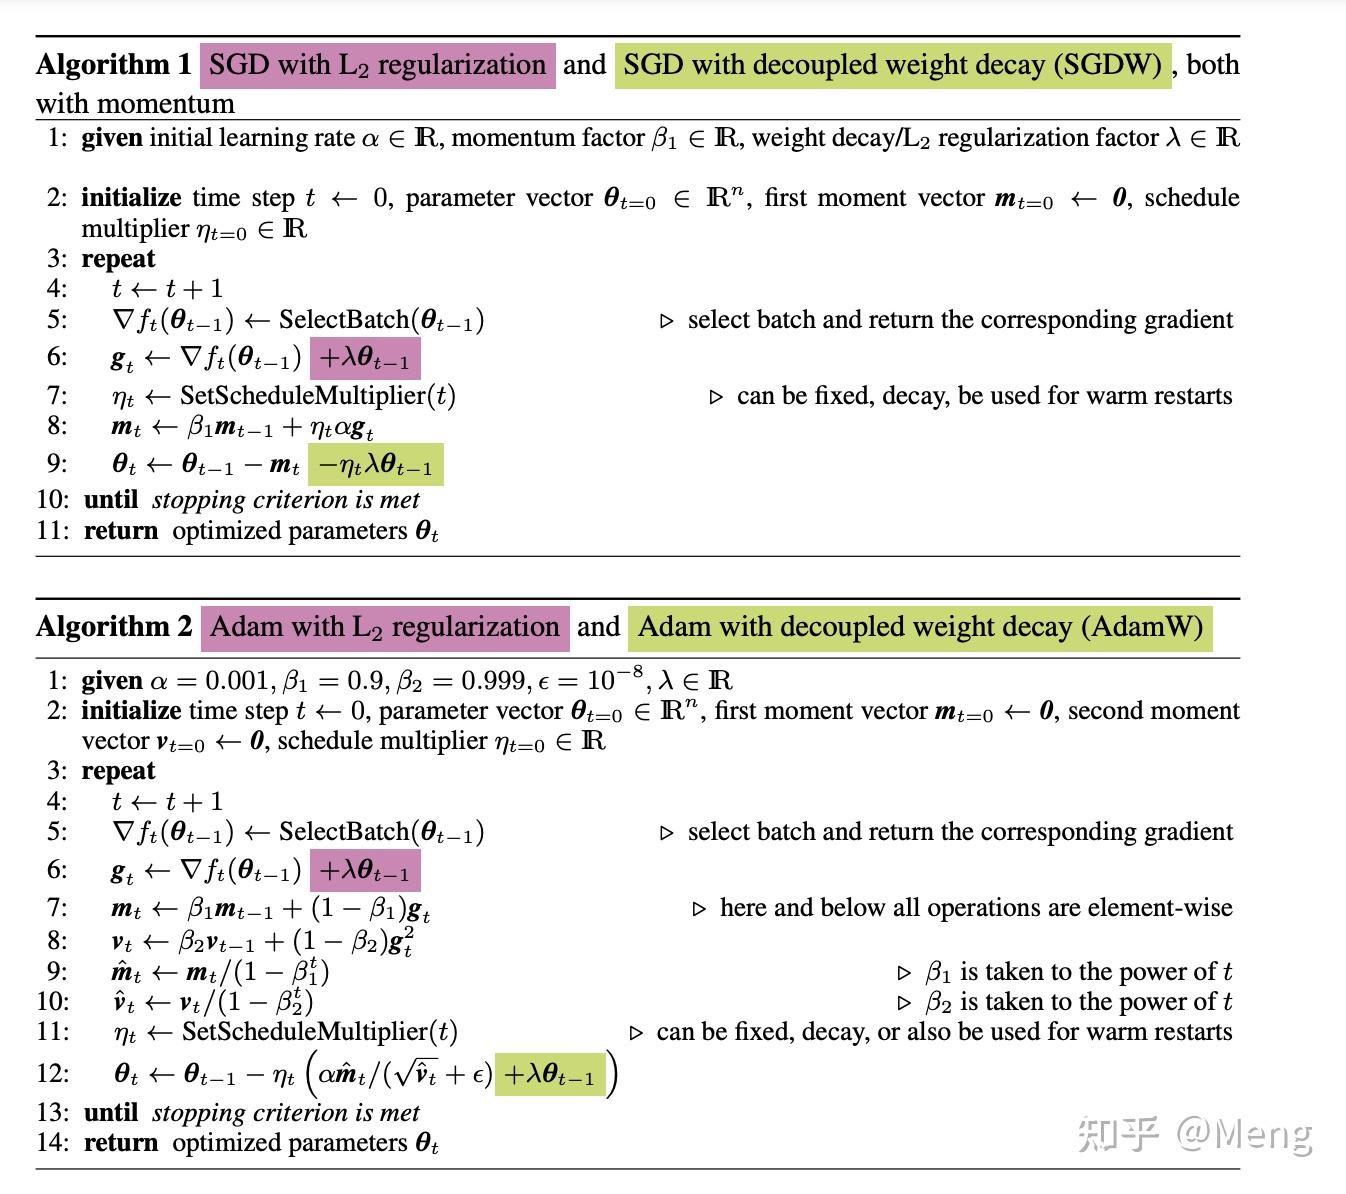
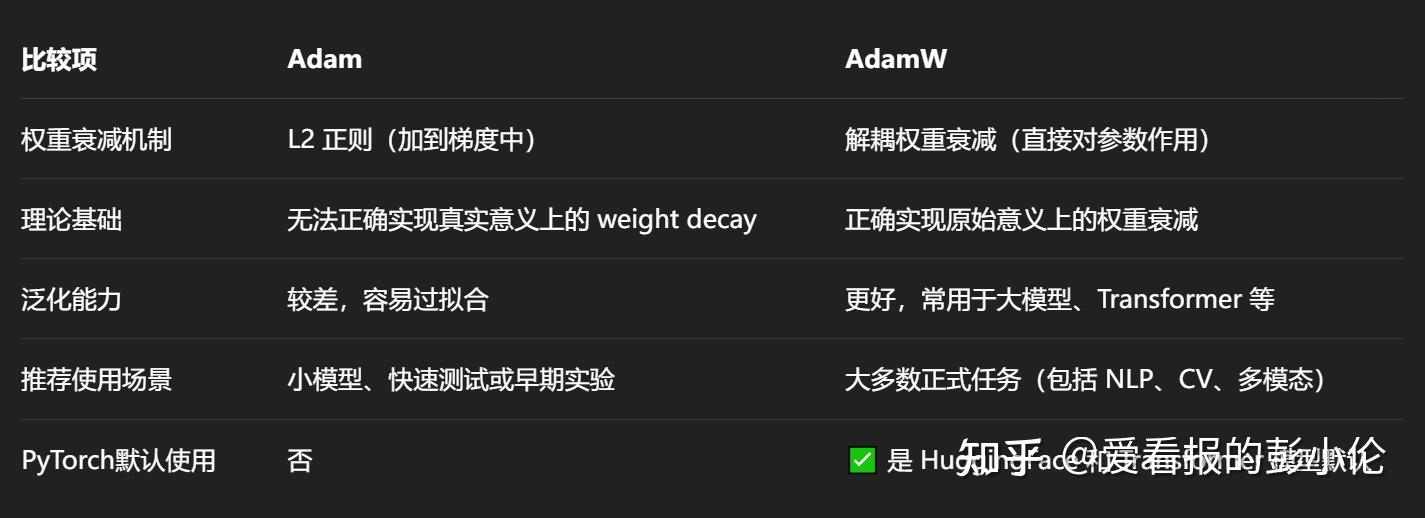
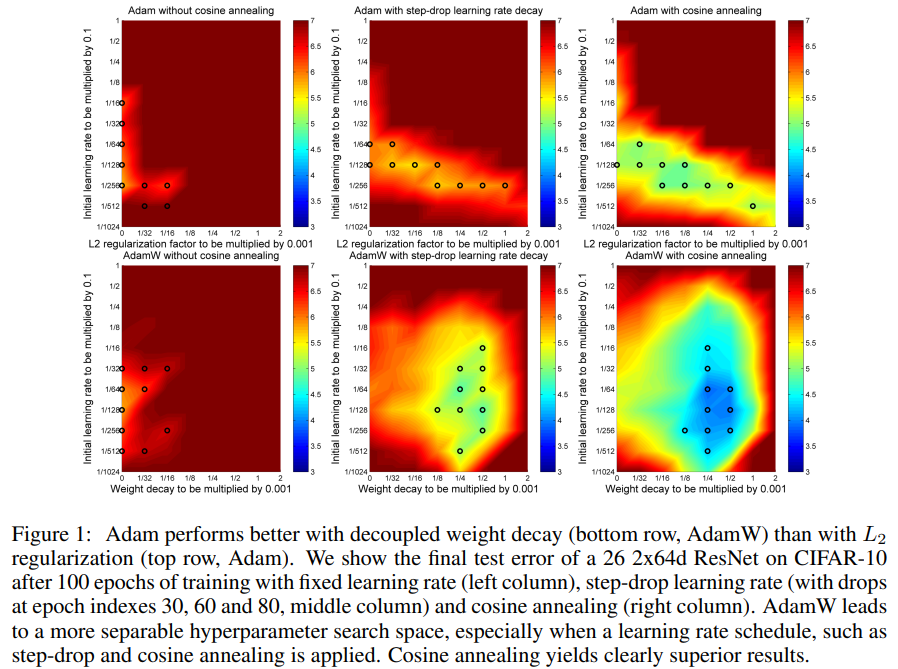
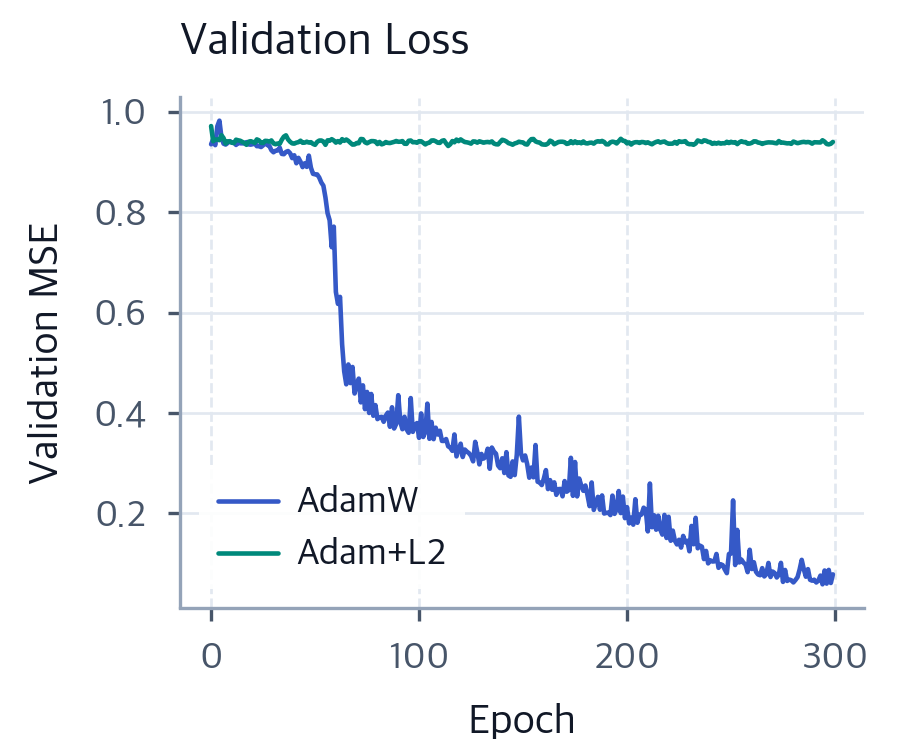
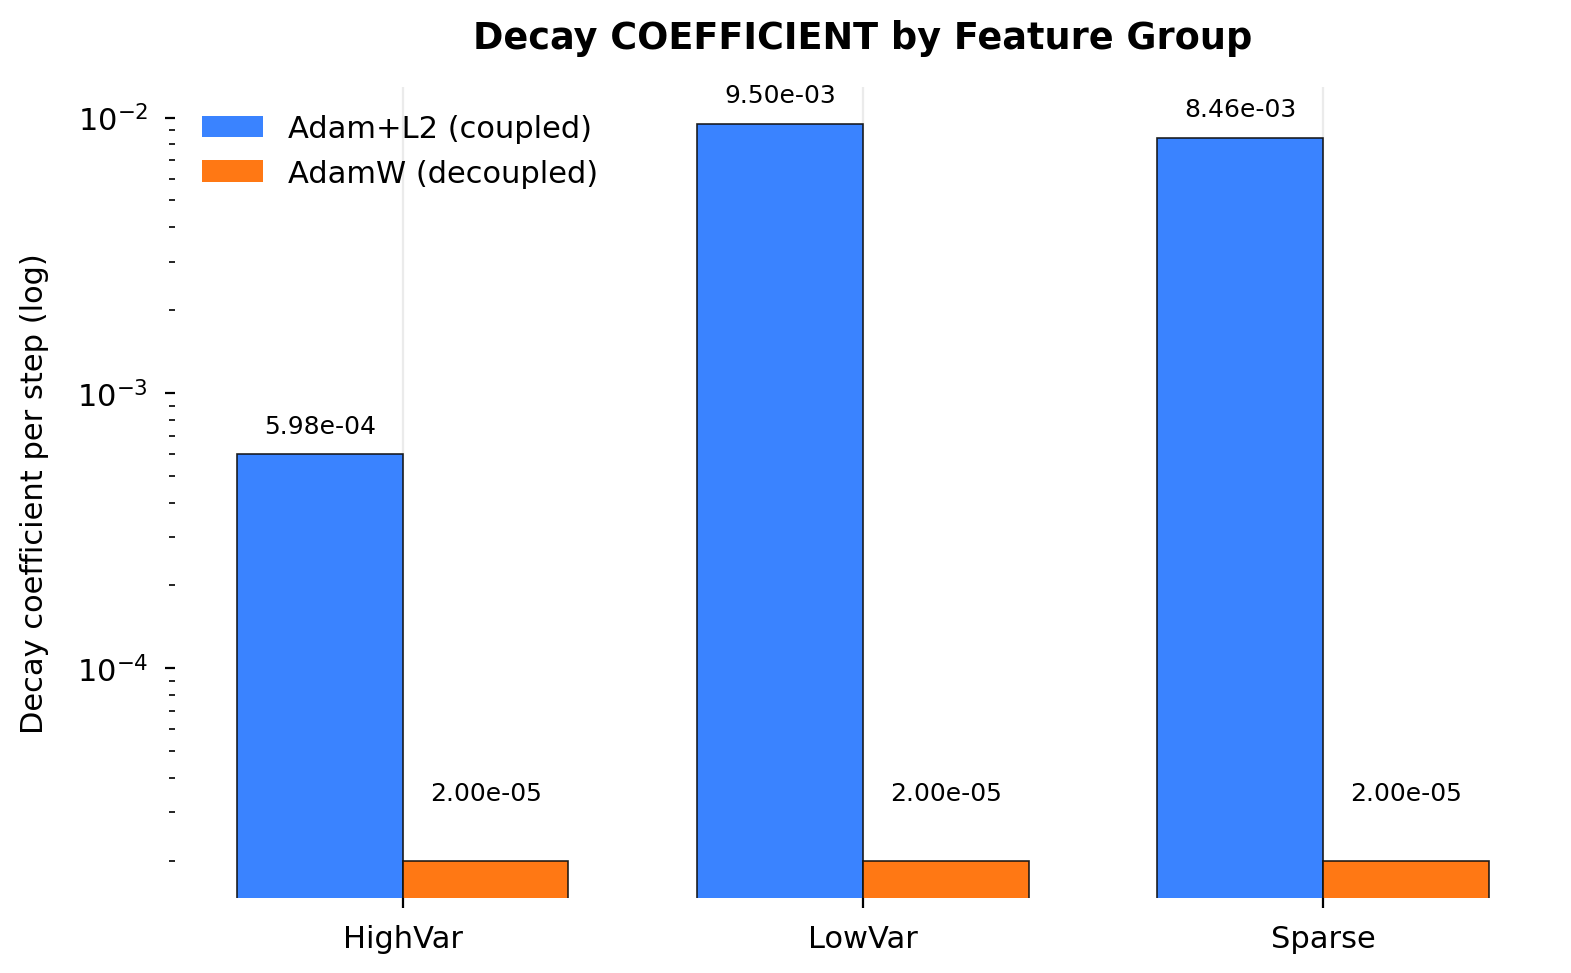
Why is AdamW Often Superior to Adam with L2-Regularization in Practice ...
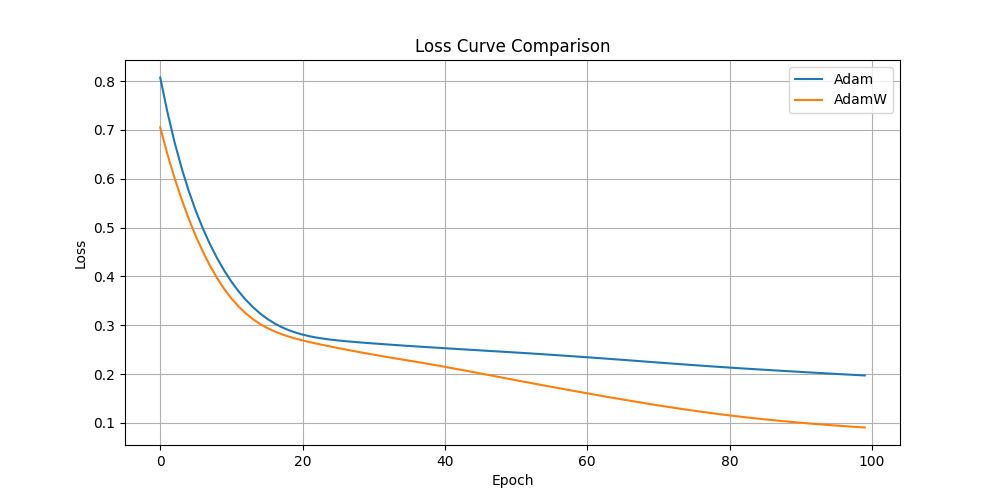
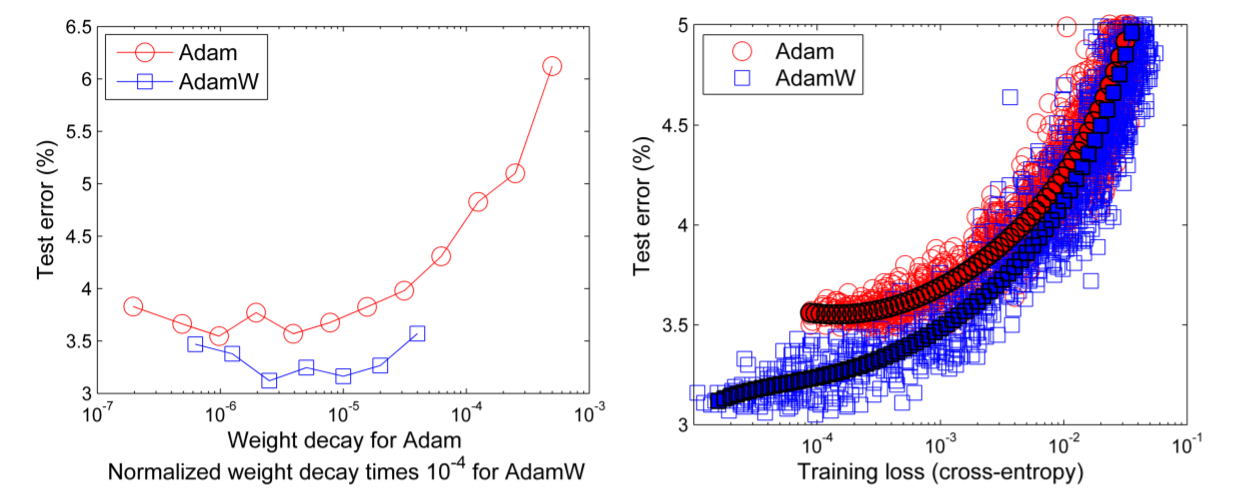
Comparison of performance between Adam and AdamW optimizers: (a ...
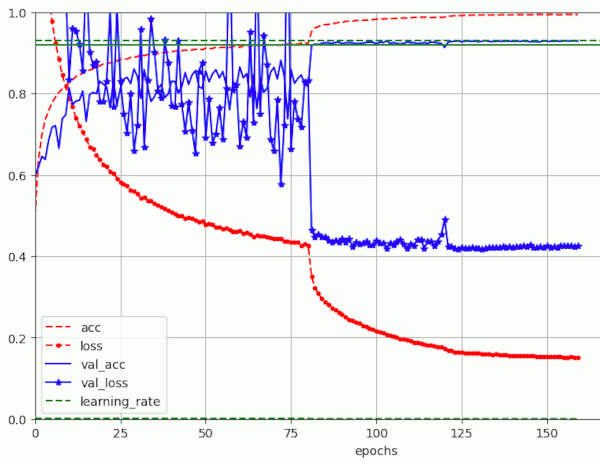
Adam vs AdamW:精度はどう変わる?weight_decay設定を実験で比較【Keras】 - わすれなメモ
Adam and AdamW Optimizers Explained
Convergence of AdamW vs SGD | Download Scientific Diagram
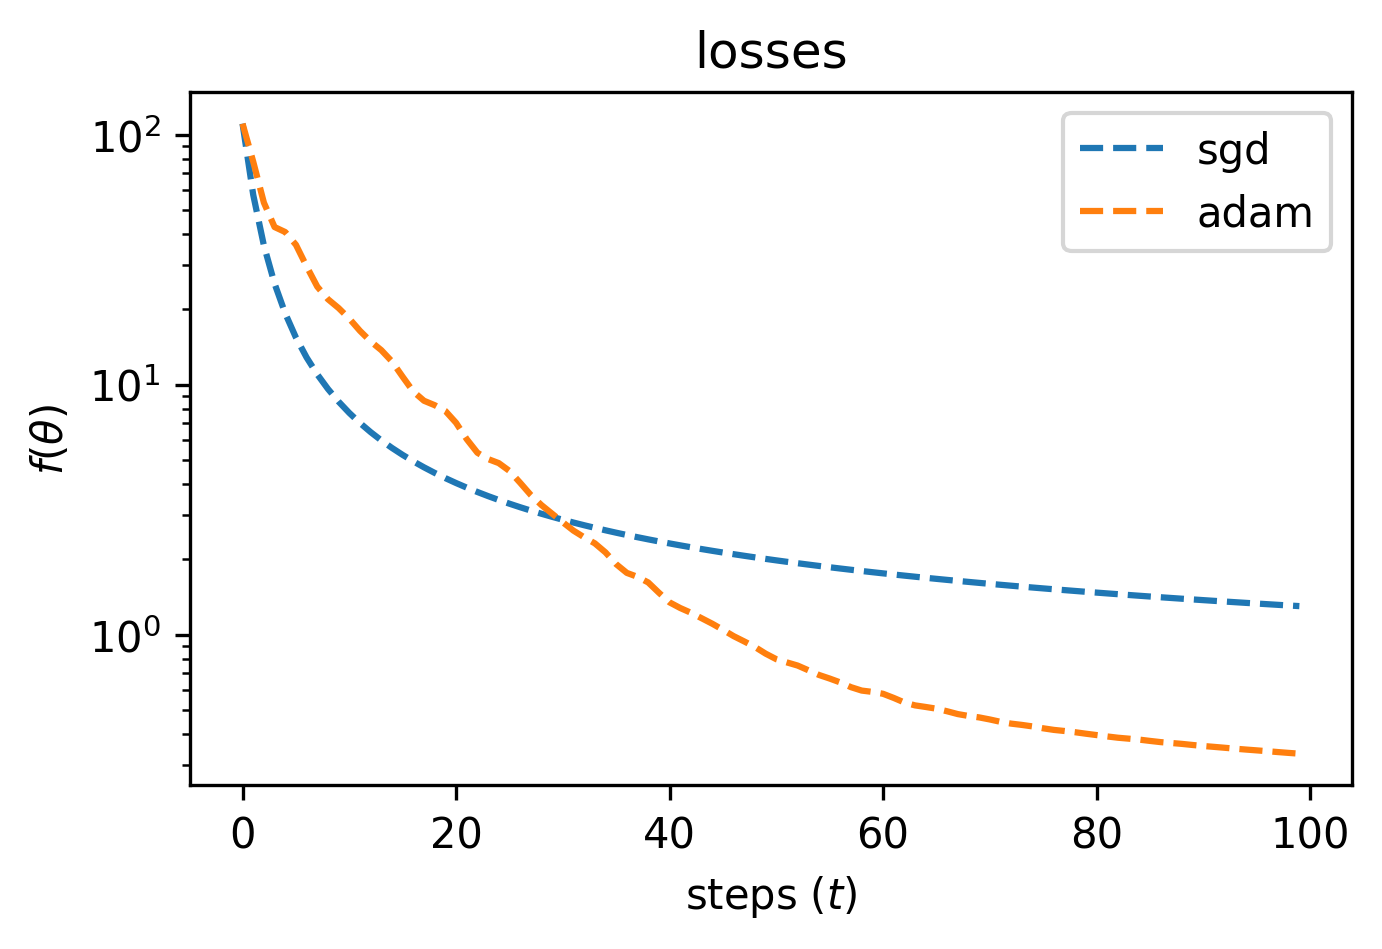
Sgd Vs Adam Converge – How does the Adam method of stochastic gradient ...
Shazam Vs Black Adam Injustice
RMSProp vs SGD vs Adam optimizer - YouTube
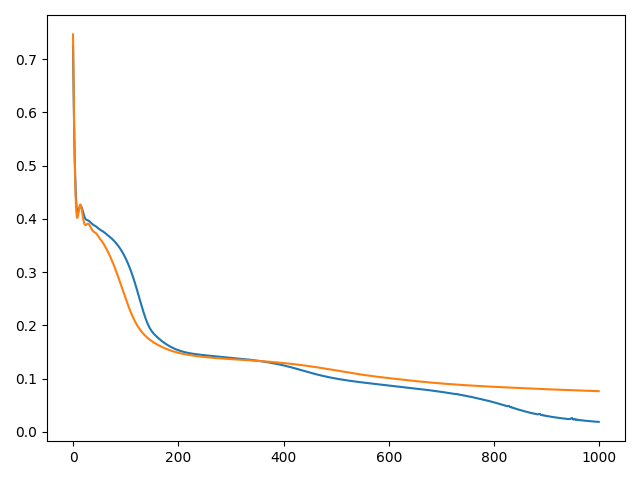
4가지 옵티마이저에 따른 성능평가 비교 Adam vs Nadam vs RMSProp vs SGD
Adam vs AdamW: The Truth About Weight Decay (Fixed) - ArhFoundation.org
Optimizer Choice: SGD vs Adam · Issue #4 · ultralytics/yolov3 · GitHub
Batch size 30 AdamW vs Batch Size 1 Adafactor SDXL Training Comparison
PyTorch Adam vs Tensorflow Adam - PyTorch Forums
Green Lantern Vs Black Adam
Black Adam Vs Shazam Injustice
The ADAMW optimizer. Introduction to weighted Adaptive… | by Fernando ...
Adam vs. AdamW: A Practical Deep Dive into Optimizer Differences | Adel ...
Nowadays, most LLMs get trained with the AdamW optimizer as opposed to ...
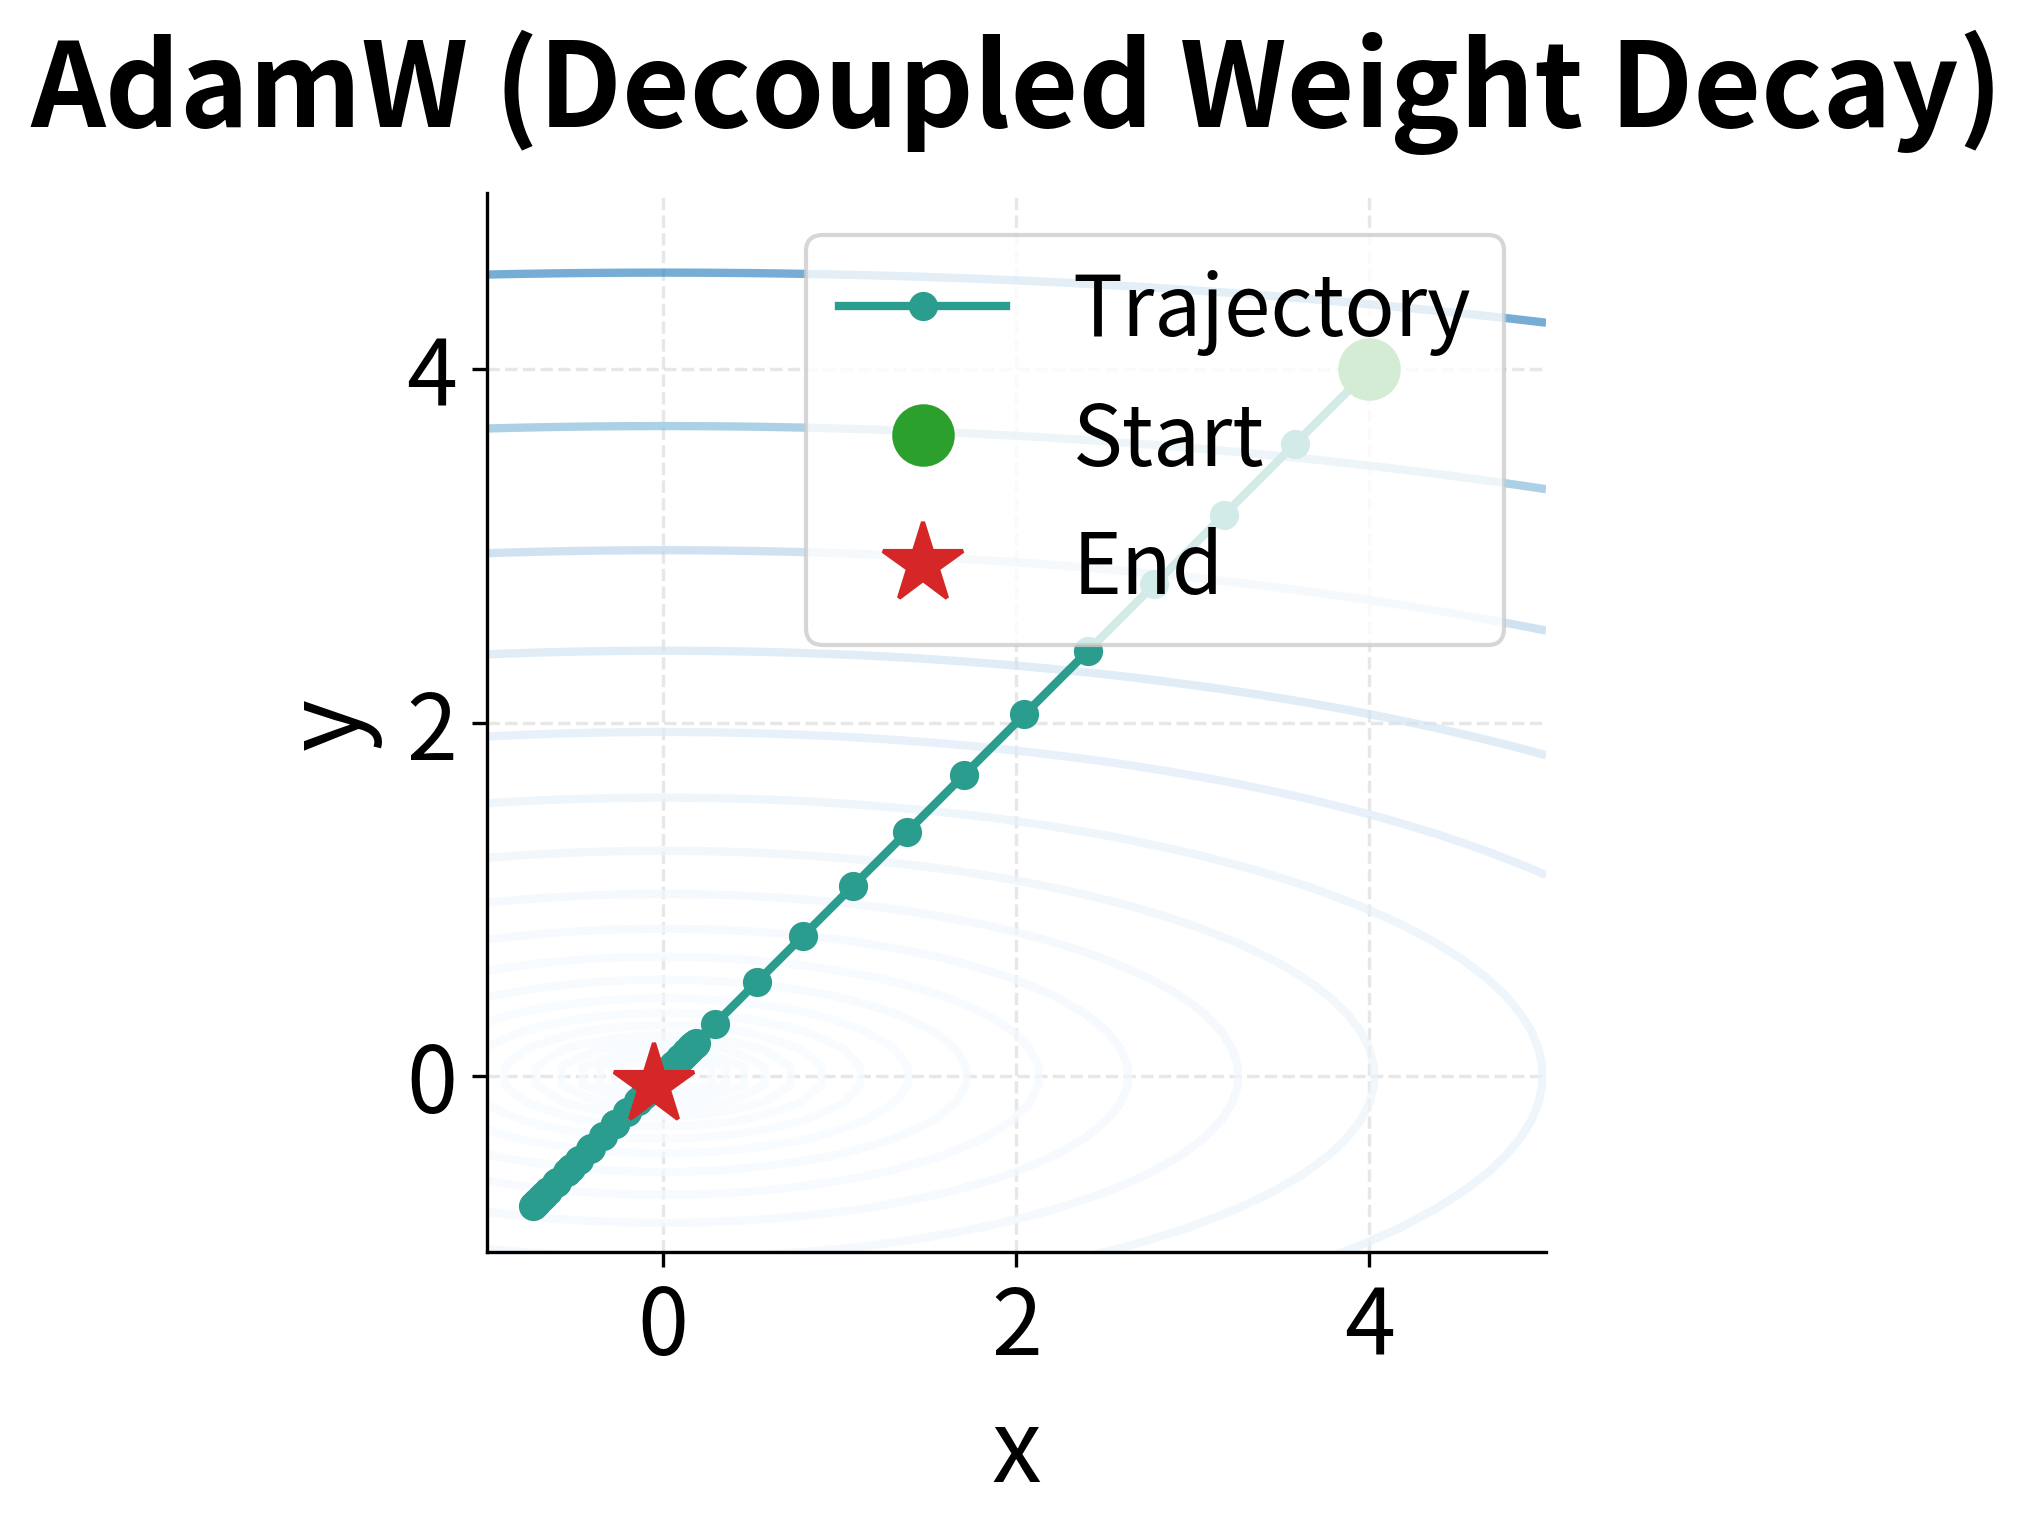
AdamW Optimizer: Decoupled Weight Decay for Deep Learning - Interactive ...
AdamW Optimizer Explained #datascience #machinelearning #deeplearning # ...
Torch Adam Optimizer _ Adam Optimizer Pytorch – FFPKG
Pytorch Adam Optimizer : Tuning Adam Optimizer Parameters in PyTorch ...
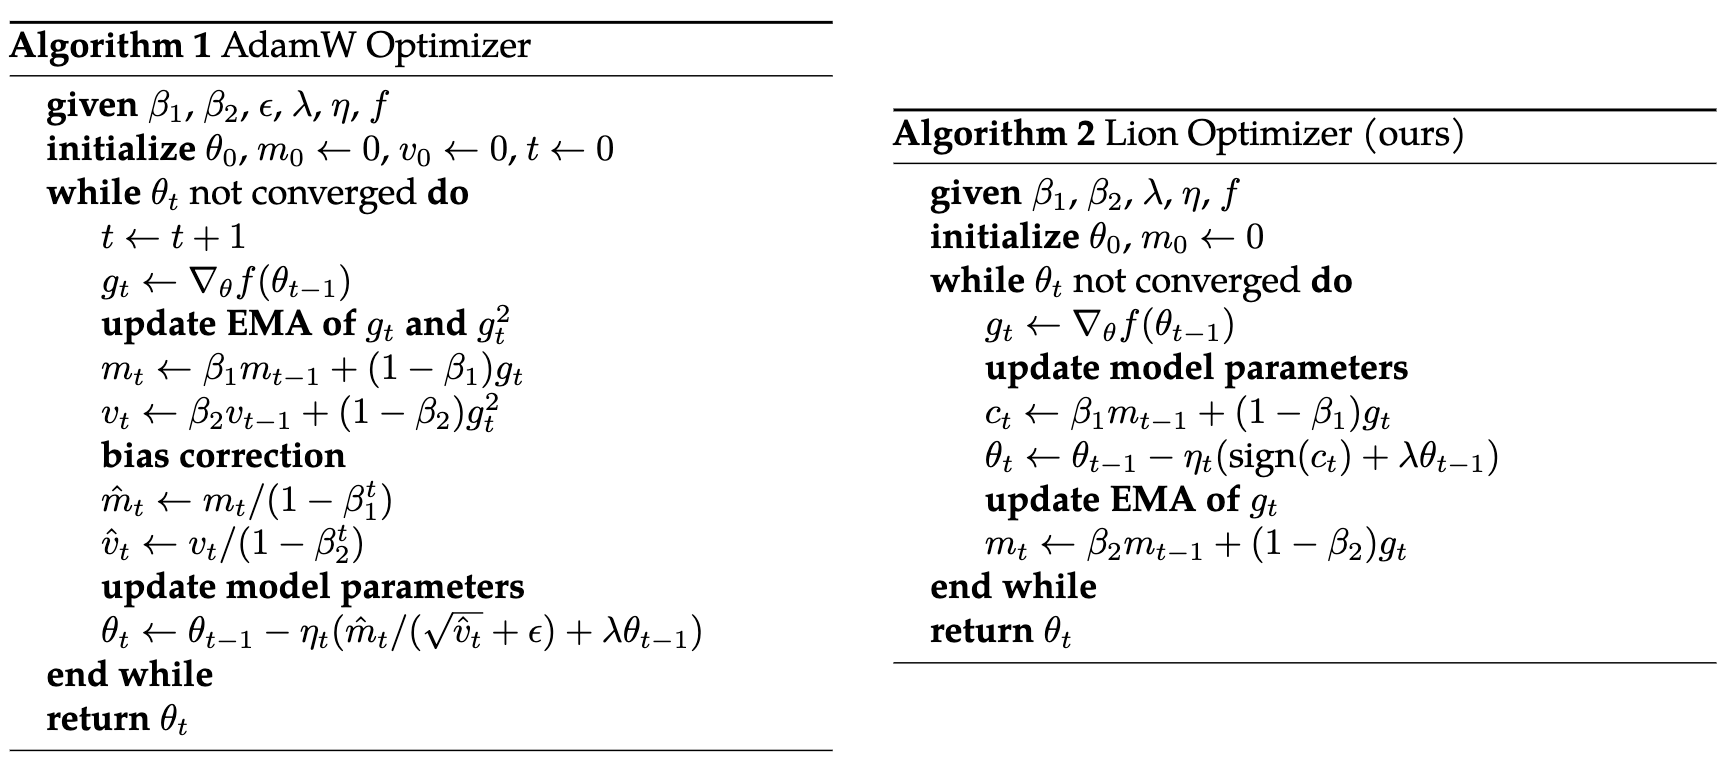
Optimization Algorithms Explained: LION vs. AdamW | AutoML Discovery of ...
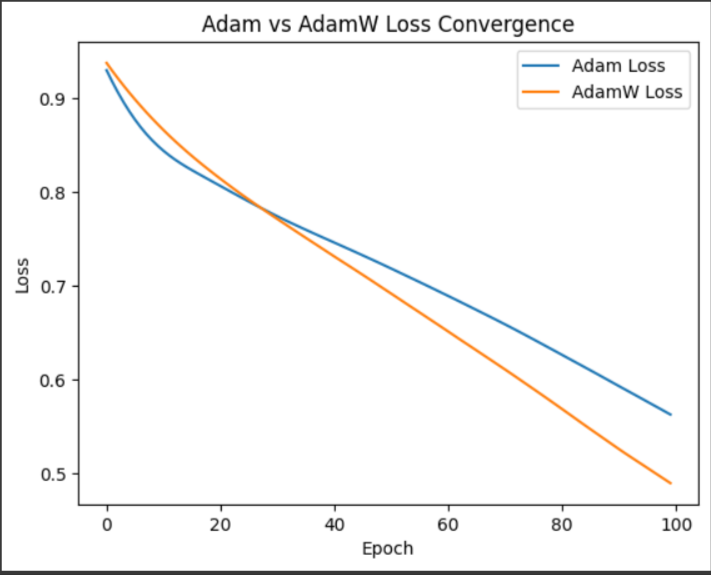
AdamW optimizer gives better loss convergence but poor image generation ...
python - Decay parameter of Adam optimizer in Keras - Stack Overflow
python - How does a decaying learning rate schedule with AdamW ...
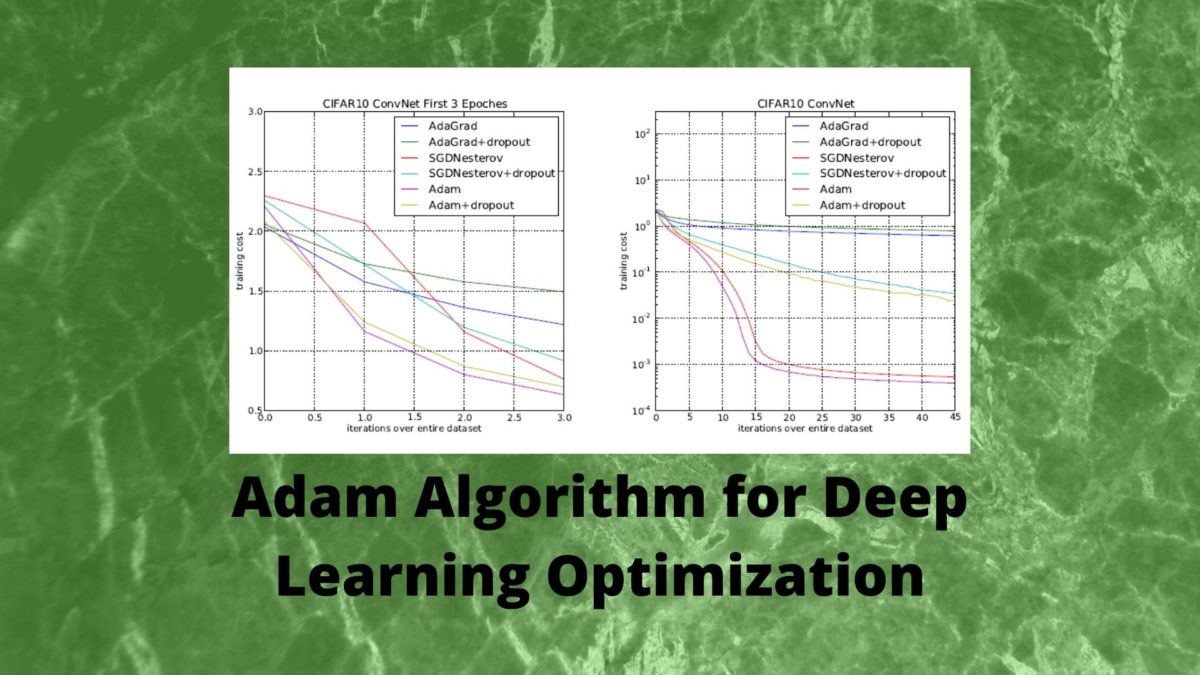
Adam Optimizer: A Quick Introduction – EBRX
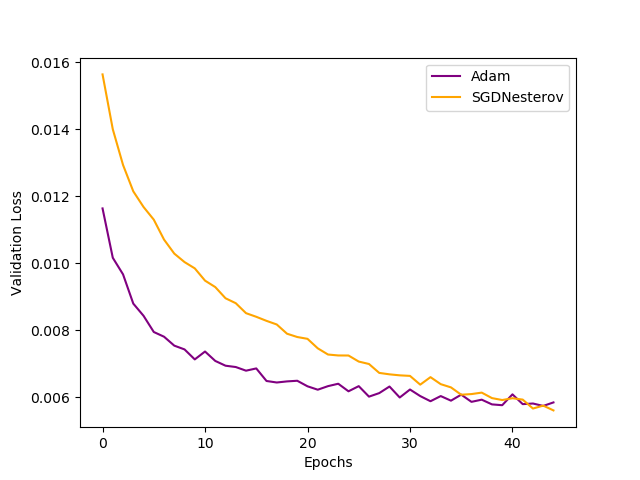
Comparison of Adam and SGD optimizers on training performance of ...
Adam-mini: better performance than AdamW | Ashish Patel 🇮🇳 posted on ...
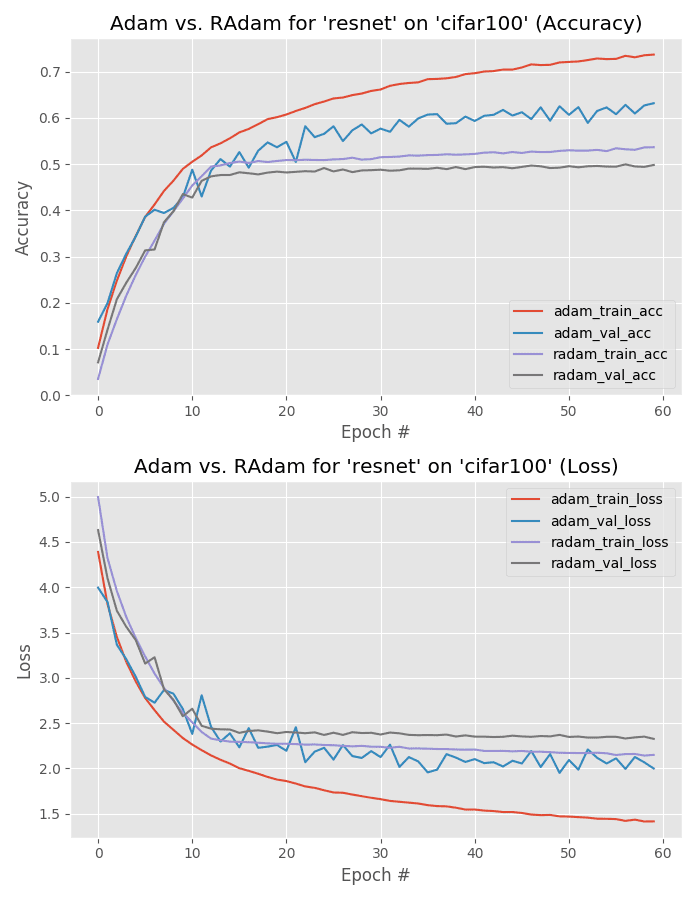
Is Rectified Adam actually *better* than Adam? - PyImageSearch
Optimizer Adam
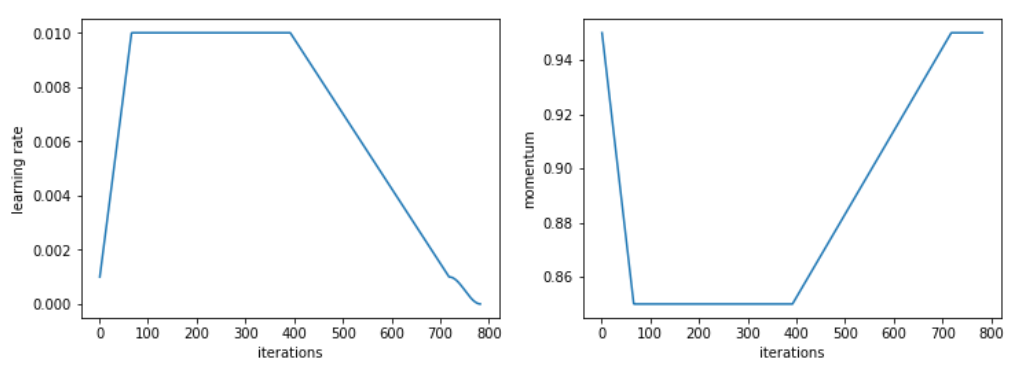
AdamW and Super-convergence is now the fastest way to train neural nets ...
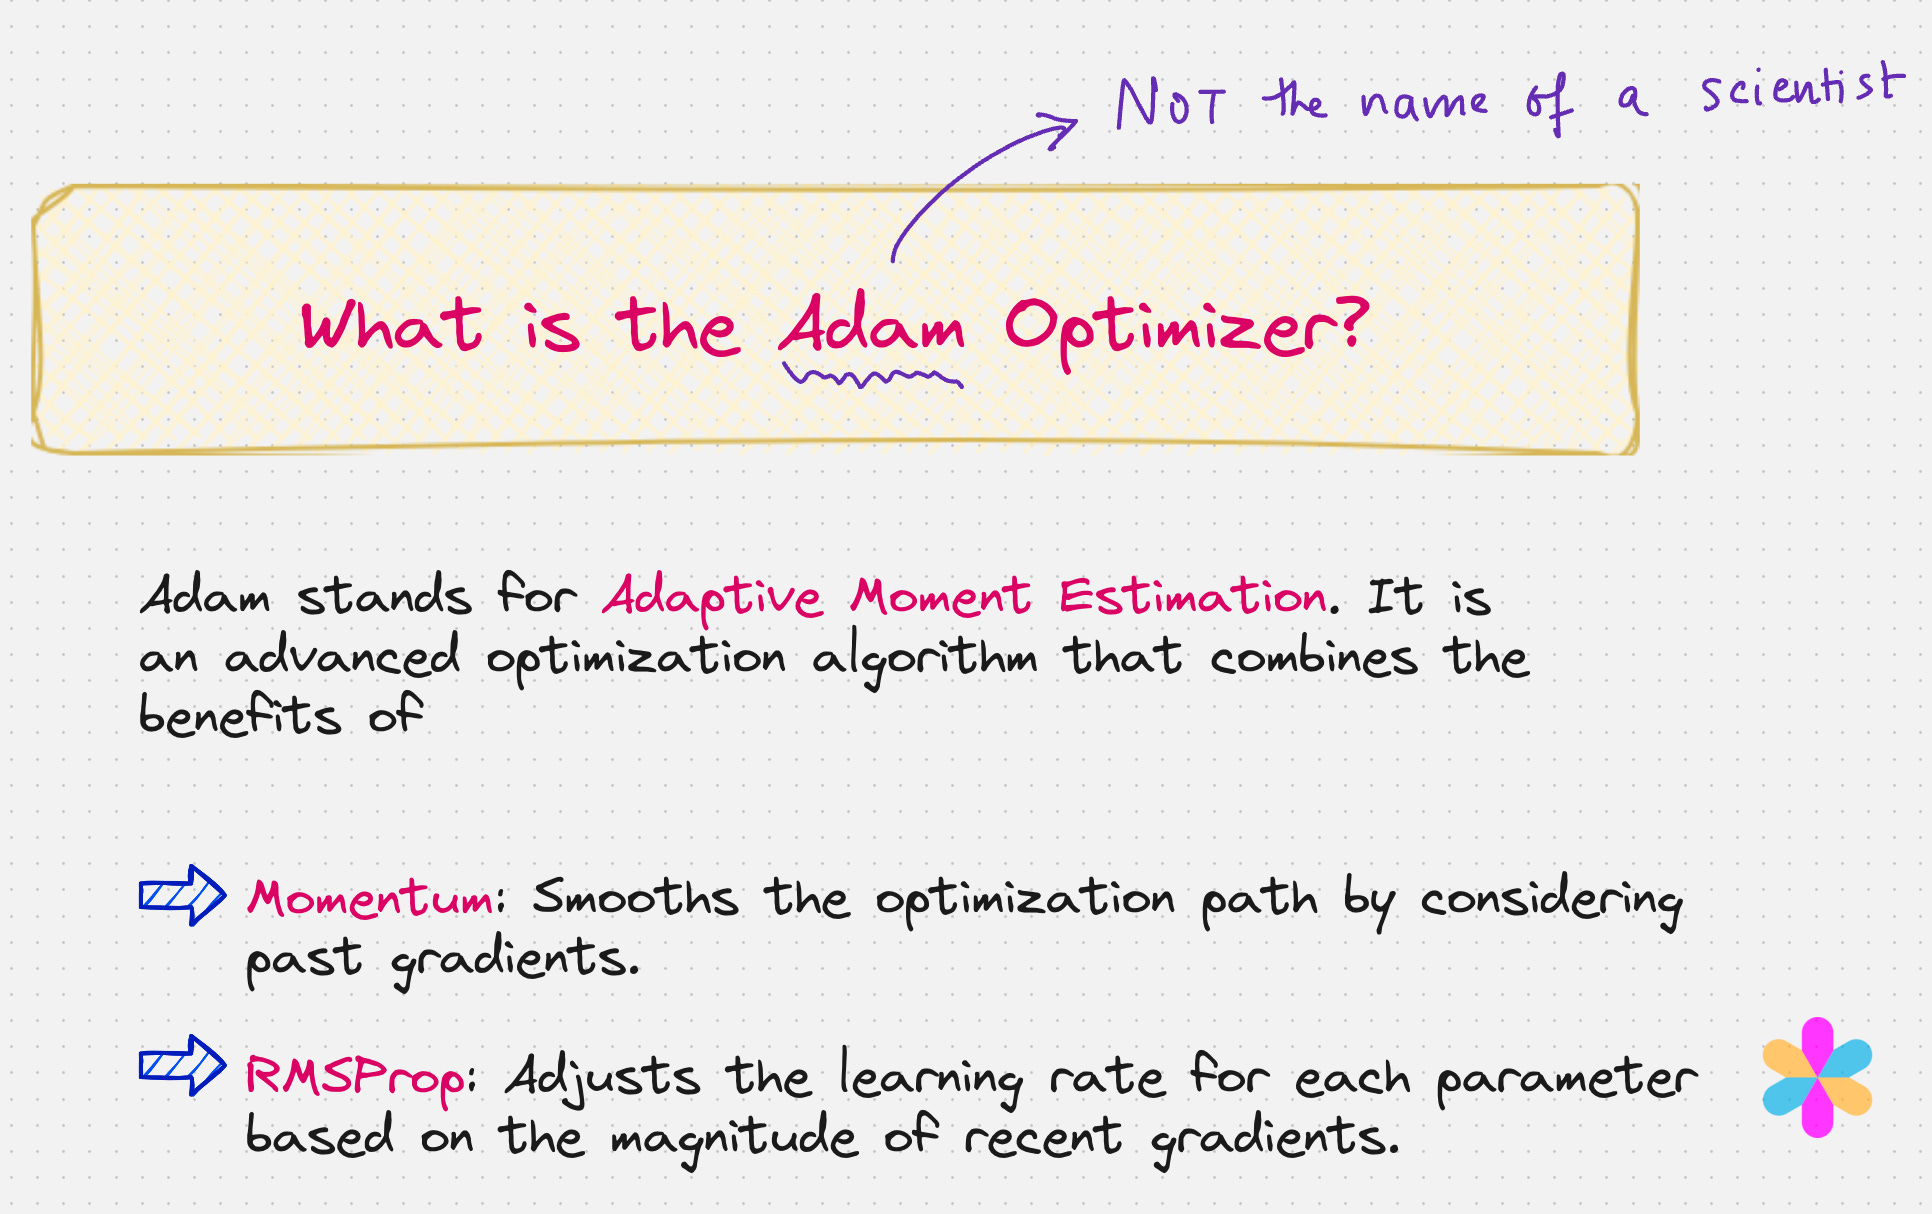
Adam Optimizer Simplified for Beginners in ML
c shows the comparison between different optimizers -Adam, AdamW and ...
(PDF) Mixing ADAM and SGD: a Combined Optimization Method
The Adam Optimizer - Conceptual Introduction
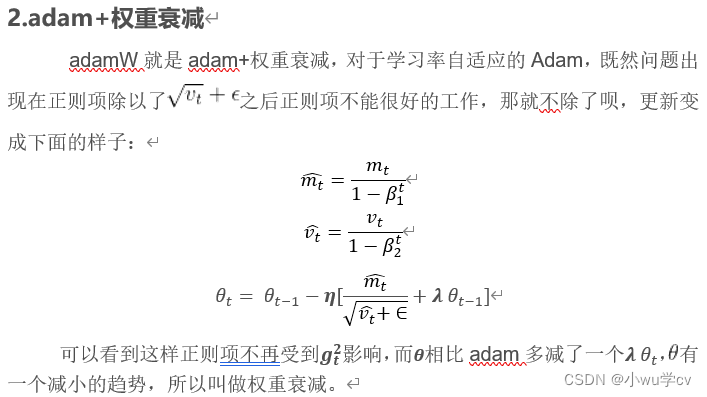
AdamW(Adam 的解耦权重衰减)—— 将权重衰减与参数更新分离,从而更稳定地提升泛化的 Adam 变体 - Zero Math AI
AdamW Optimizer from Scratch in Python - YouTube
Adam Optimizer là gì? A-Z về tối ưu hóa Adam trong học sâu
Adam Deep Learning – Adam Optimization Algorithm – PBCYJ
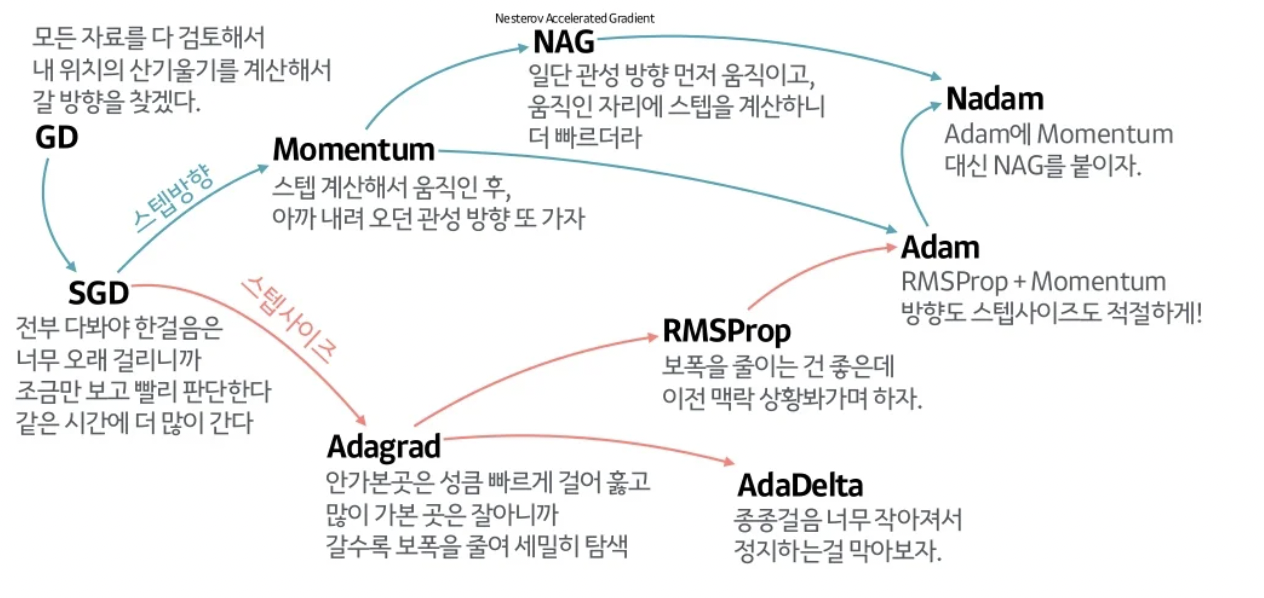
Optimization (3): The Gradient Descent Family from SGD to AdamW · Chen ...
Adam-Mini - New Optimizer - Achieves 50% Higher Throughput than AdamW ...
Tuning Adam Optimizer Parameters in PyTorch - KDnuggets
What is Adam Optimizer? – Quantum™ Ai Labs
Explain Adam and Adamw: Understanding Optimizers - AIML.com
Numerical error v.s. the number of iterations for Adam and SGD ...
optimization - How Adam optimizer influence the learning rate? - Data ...
AdamW for a ResNet56v2 – I – a detailed look at results based on the ...
AdamWにおける改善点をきちんと理解する
AdamW: Decoupled Weight Decay for Neural Networks - Interactive ...
Adam和AdamW - 知乎
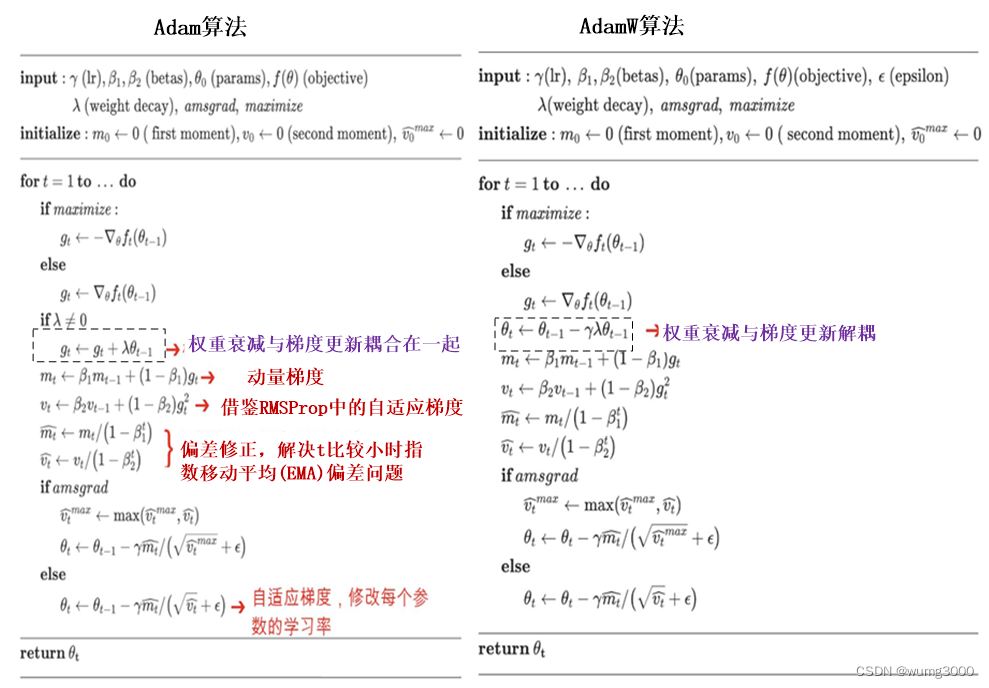
一文告诉你Adam、AdamW、Amsgrad区别和联系 - 知乎
2.困扰Adam优化器多年的问题终于找到了_adamw比adam更加好吗-CSDN博客
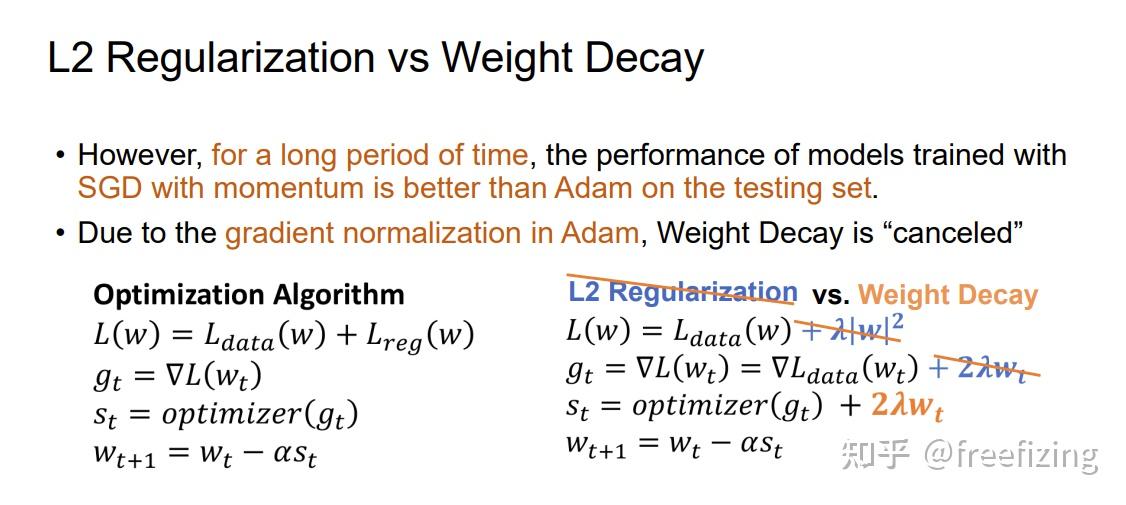
深度学习优化:SGD、Adam与Weight Decay解析-CSDN博客
Vision Transformers | Event Horizon
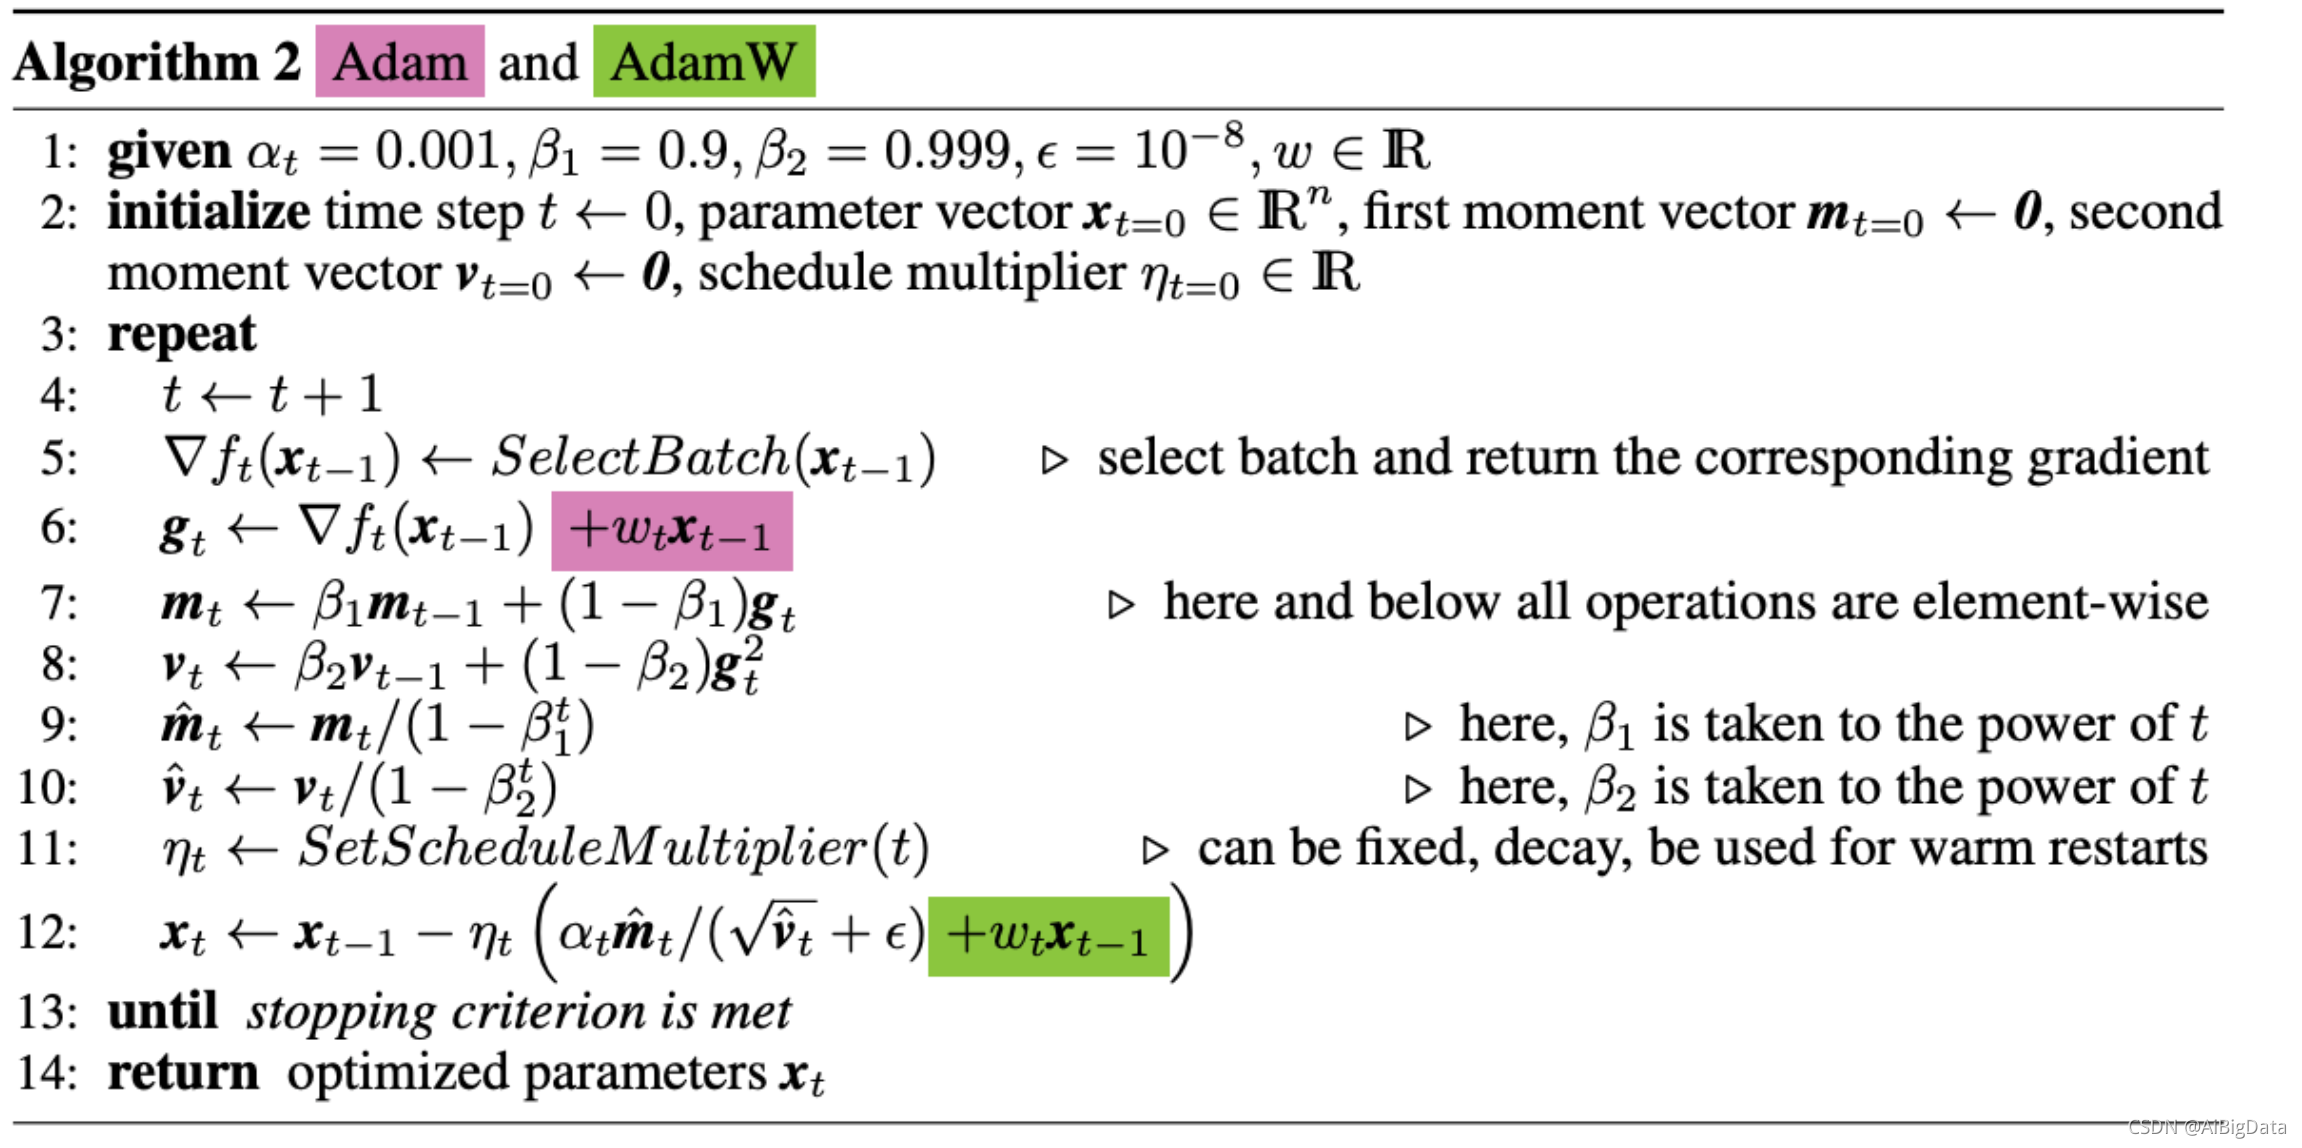
理解AdamW_AiBigData-华为云开发者联盟
深度学习优化新星:AdamW算法解析与实践-CSDN博客
SDG,ADAM,LookAhead,Lion等优化器的对比介绍 - 知乎
当前训练神经网络最快的方式:AdamW优化算法+超级收敛 - 知乎
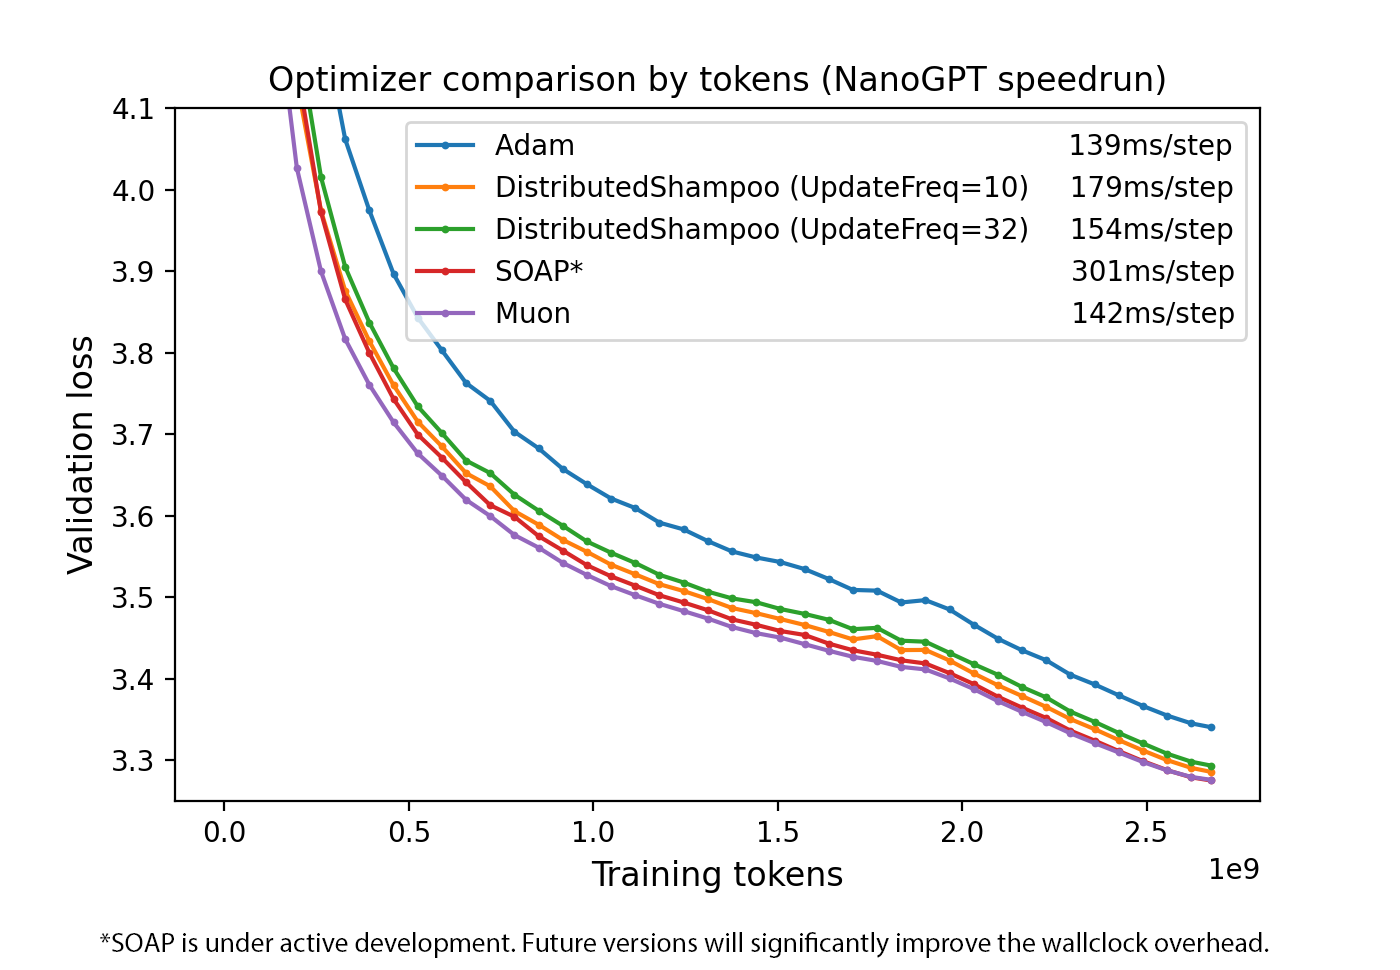
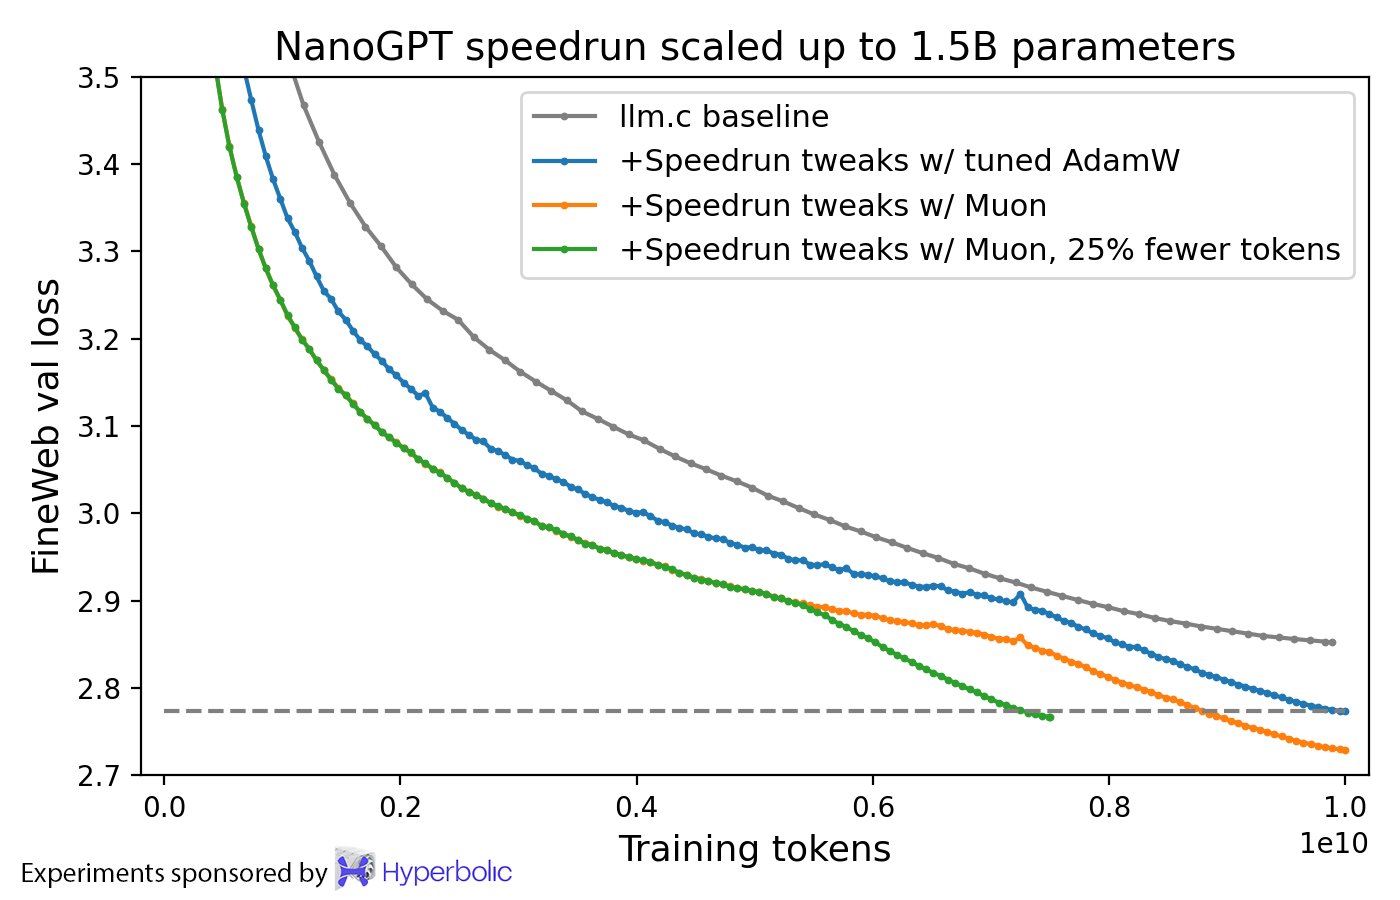
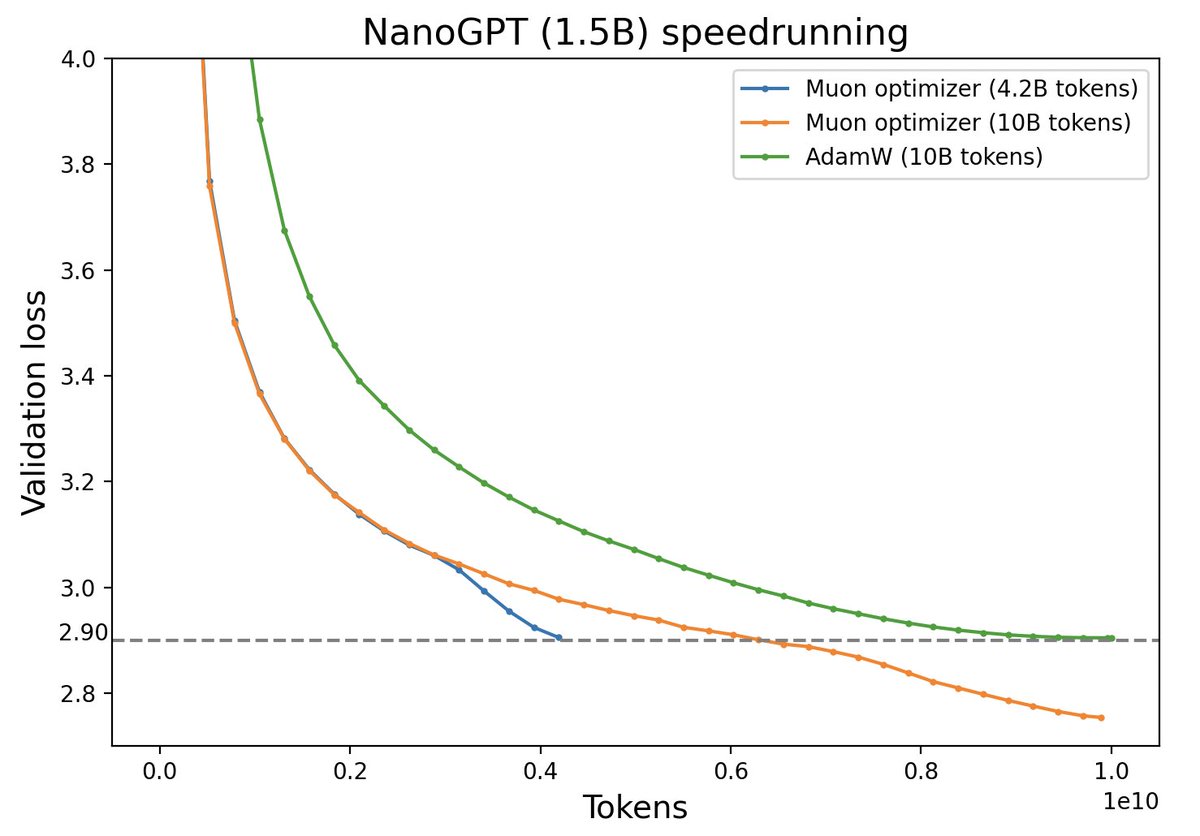
Muon: An optimizer for hidden layers in neural networks | Keller Jordan ...
Compare-and-Contrast-the-Different-Optimization Techniques - AIML.com
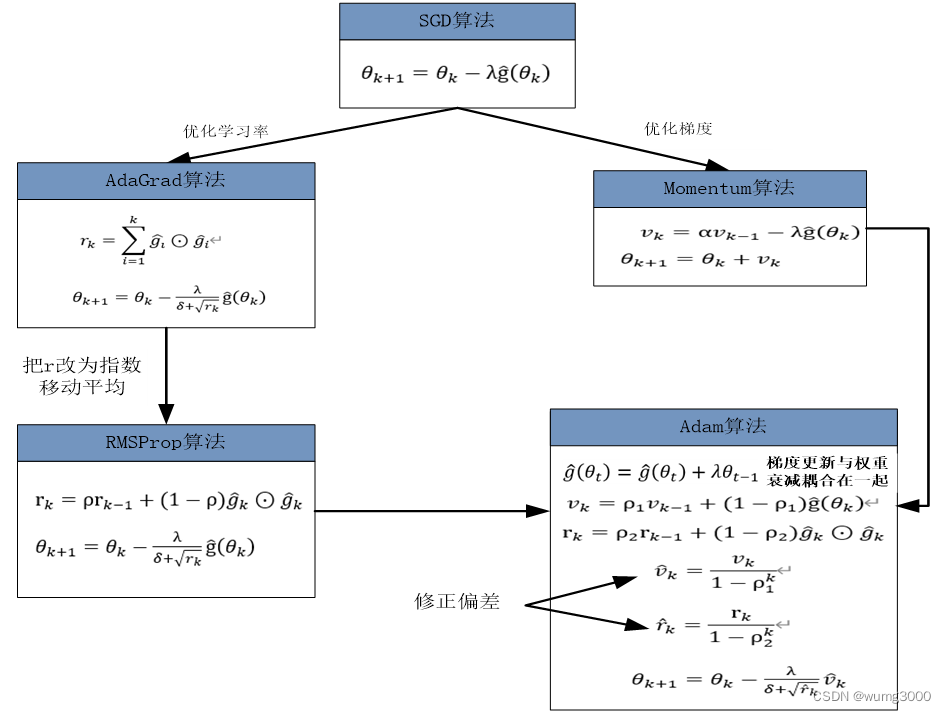
Optimizer优化器发展 从SGD到Adam(W)及其对比 (附Pytorch代码)_adamw优化器-CSDN博客
墨滴社区
SGD,SGDM,Adagrad,RMSProp,Adam,AdamW复习笔记 - 知乎
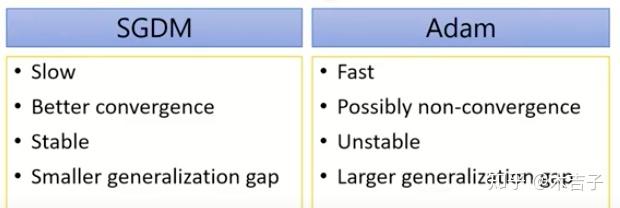
#深入探究# Adam和SGDM优化器的对比_sgd和adam区别-CSDN博客
adamw优化器为什么和大的weight decay的效果好? - 知乎
Combining Optimization Methods Using an Adaptive Meta Optimizer
深度学习各种优化器(SGD/Momentum/RMSProp/Adam/AdamW)与Weight decay详解_详解各种优化器-CSDN博客
包含关键字 hoathinh3d.sh 的文章 - 科学空间|Scientific Spaces
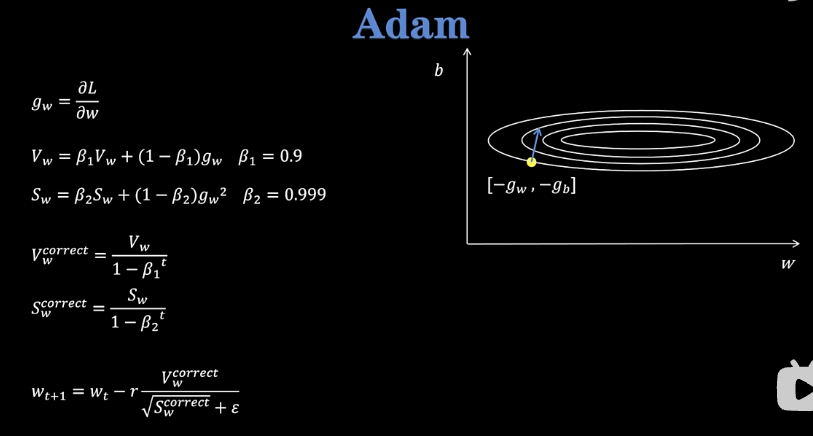
Adam- The most famous ML optimizer from Scratch
AdamW论文解读 - 知乎
Regularization and Optimization - Semt0's Blog
Comparisons of ND optimiser (8), Adam, AdaGrad, AdamW, and RMSprop by ...
十分钟速通优化器原理,通俗易懂(从SGD到AdamW) - 知乎
Unit 6 Exercises - Lightning AI
TrainingArguments optim=adamw_8bit / paged_adamw_8bit (bitsandbytes ...
每天3分钟,彻底弄懂神经网络的优化器(十一)AdamW - 知乎
pytorch中常见优化器的SGD,Adagrad,RMSprop,Adam,AdamW的总结 - 知乎
Optimization - Home
史上最详细的各种优化器对比! - 知乎
Comparisons of ND optimiser (8), Adam, AdaGrad, AdamW, and RMSprop ...
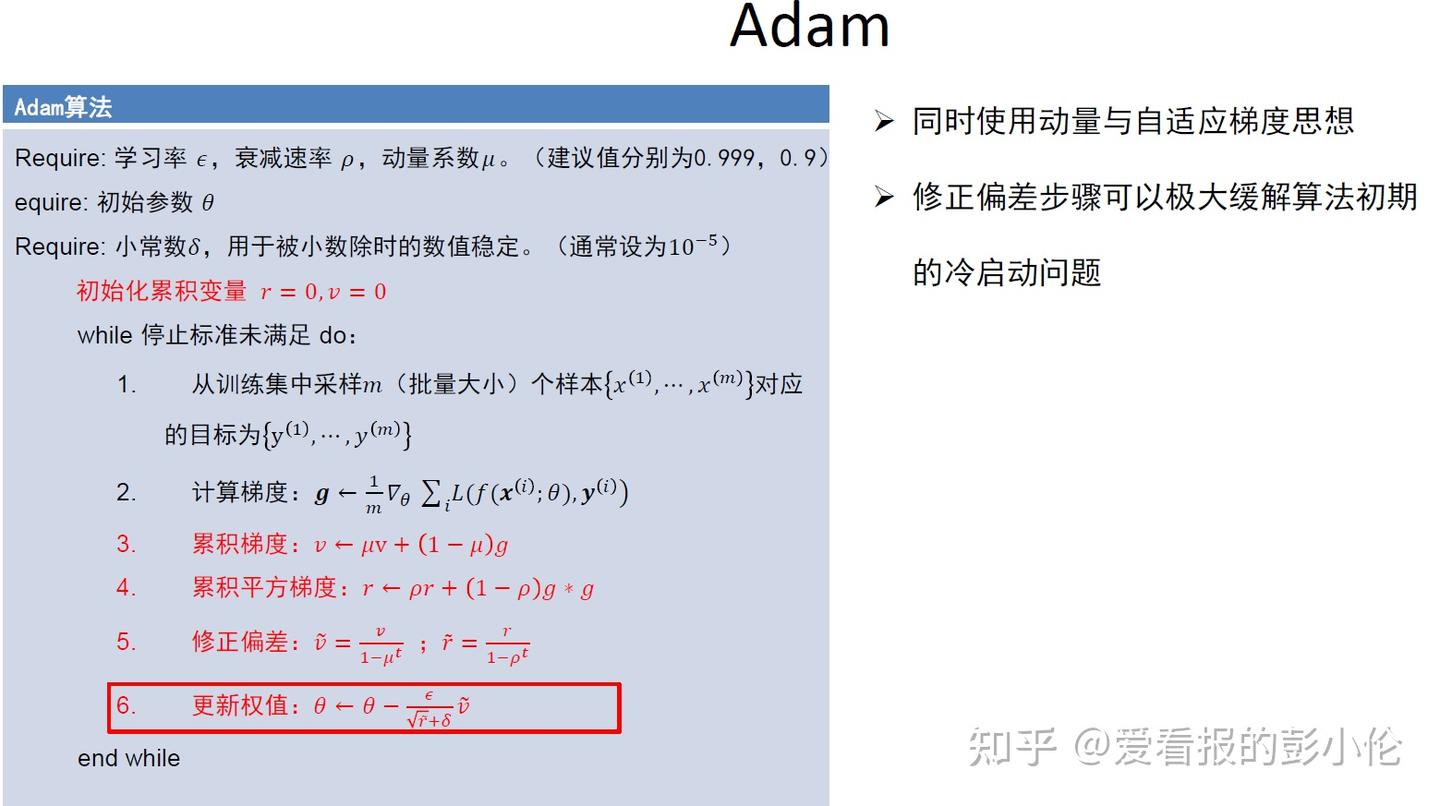
Adam优化器及其变种的原理-CSDN博客
大语言模型高效训练基础知识:优化器AdamW和Adafator_adamw优化器-CSDN博客
【AI知识】常见的优化器及其原理:梯度下降、动量梯度下降、AdaGrad、RMSProp、Adam、AdamW_adamw优化器-CSDN博客
Python | 从零实现10种优化算法并比较_python优化算法-CSDN博客
常用的优化器合集_优化器有哪些-CSDN博客
PyTorch模型训练优化器Adam和AdamW - 知乎
Fantastic Pretraining Optimizers and Where to Find Them | AI Research ...
论文阅读:Decoupled Weight Decay Regularization | 时间溢出的地方
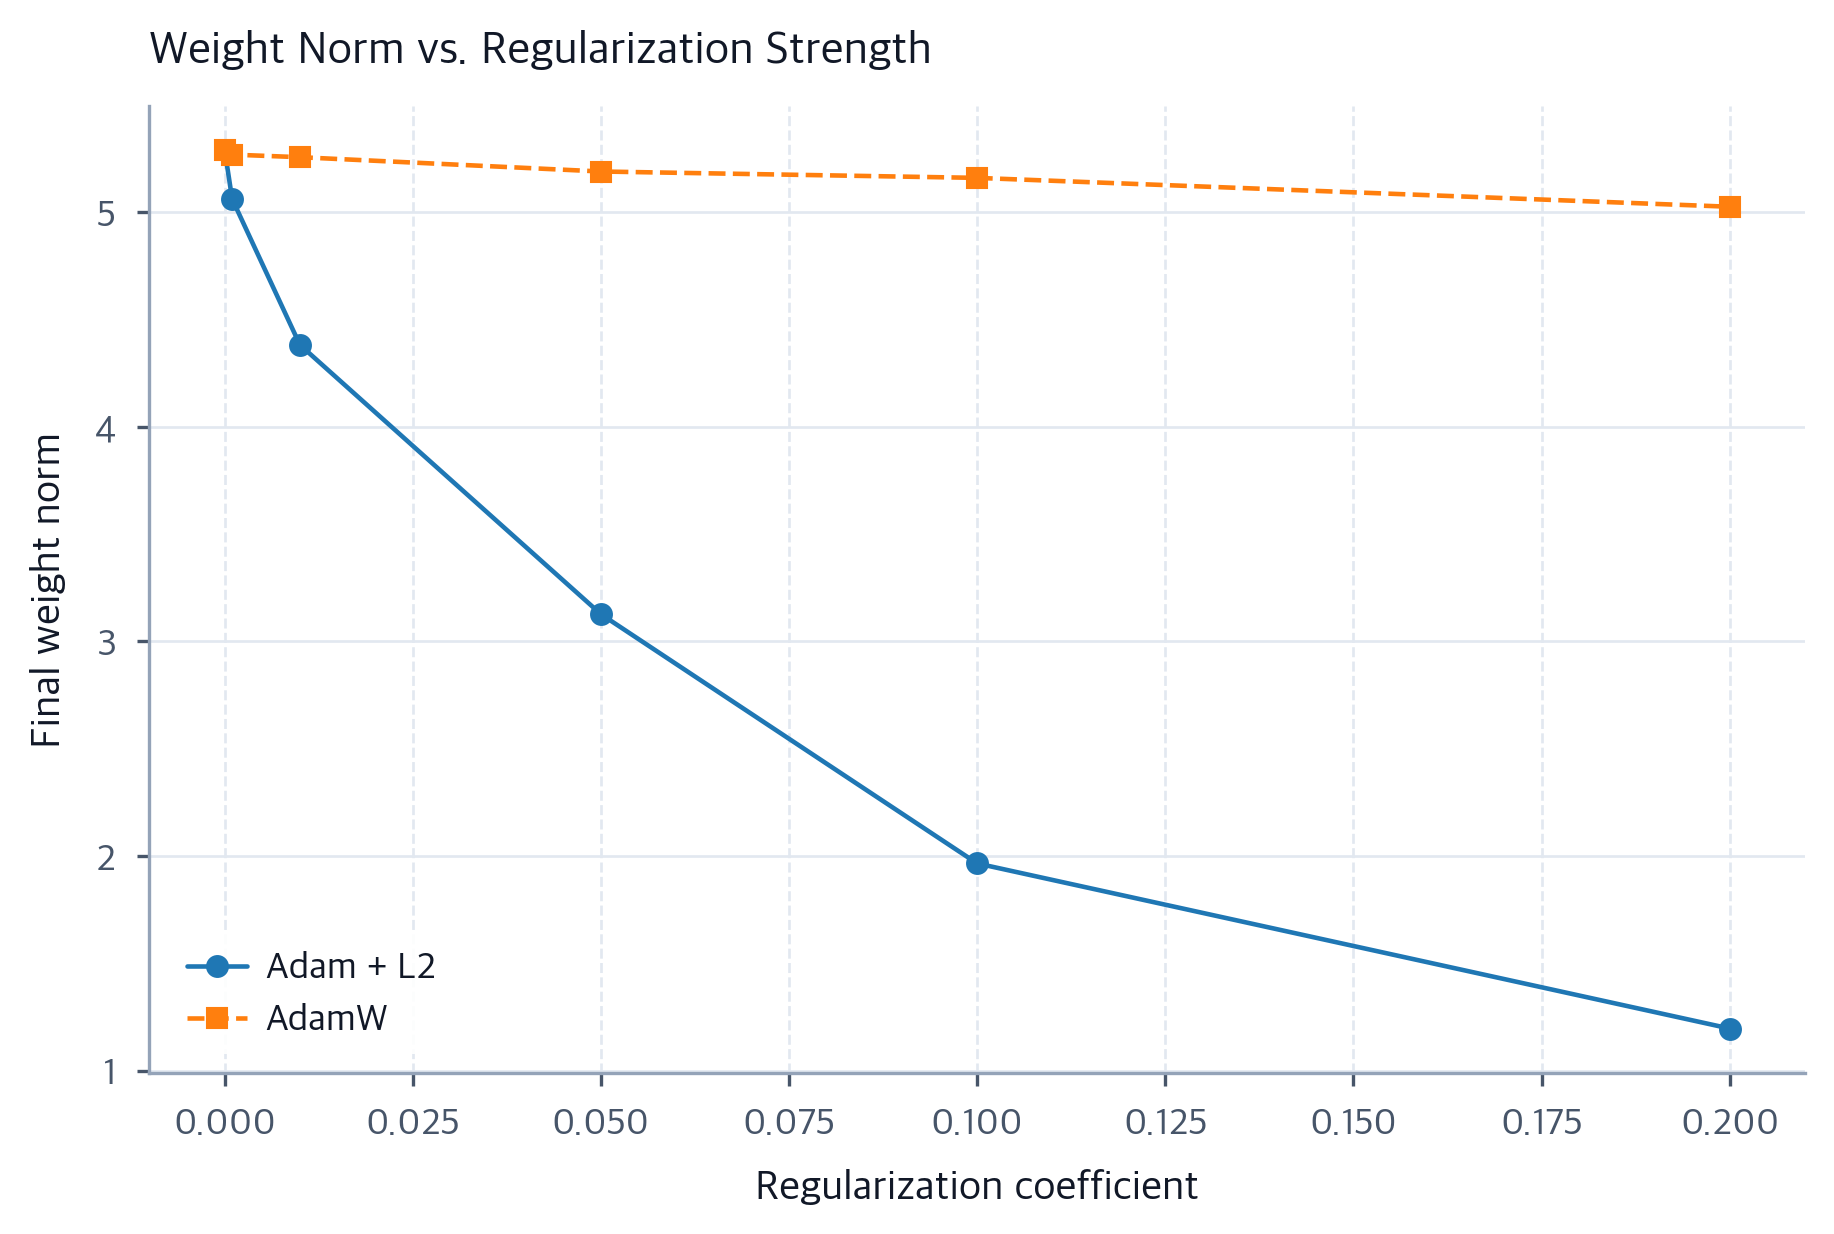
Weight Decay: L2 Regularization, AdamW, and Decoupled Training ...
Adam与AdamW_adamw betas-CSDN博客
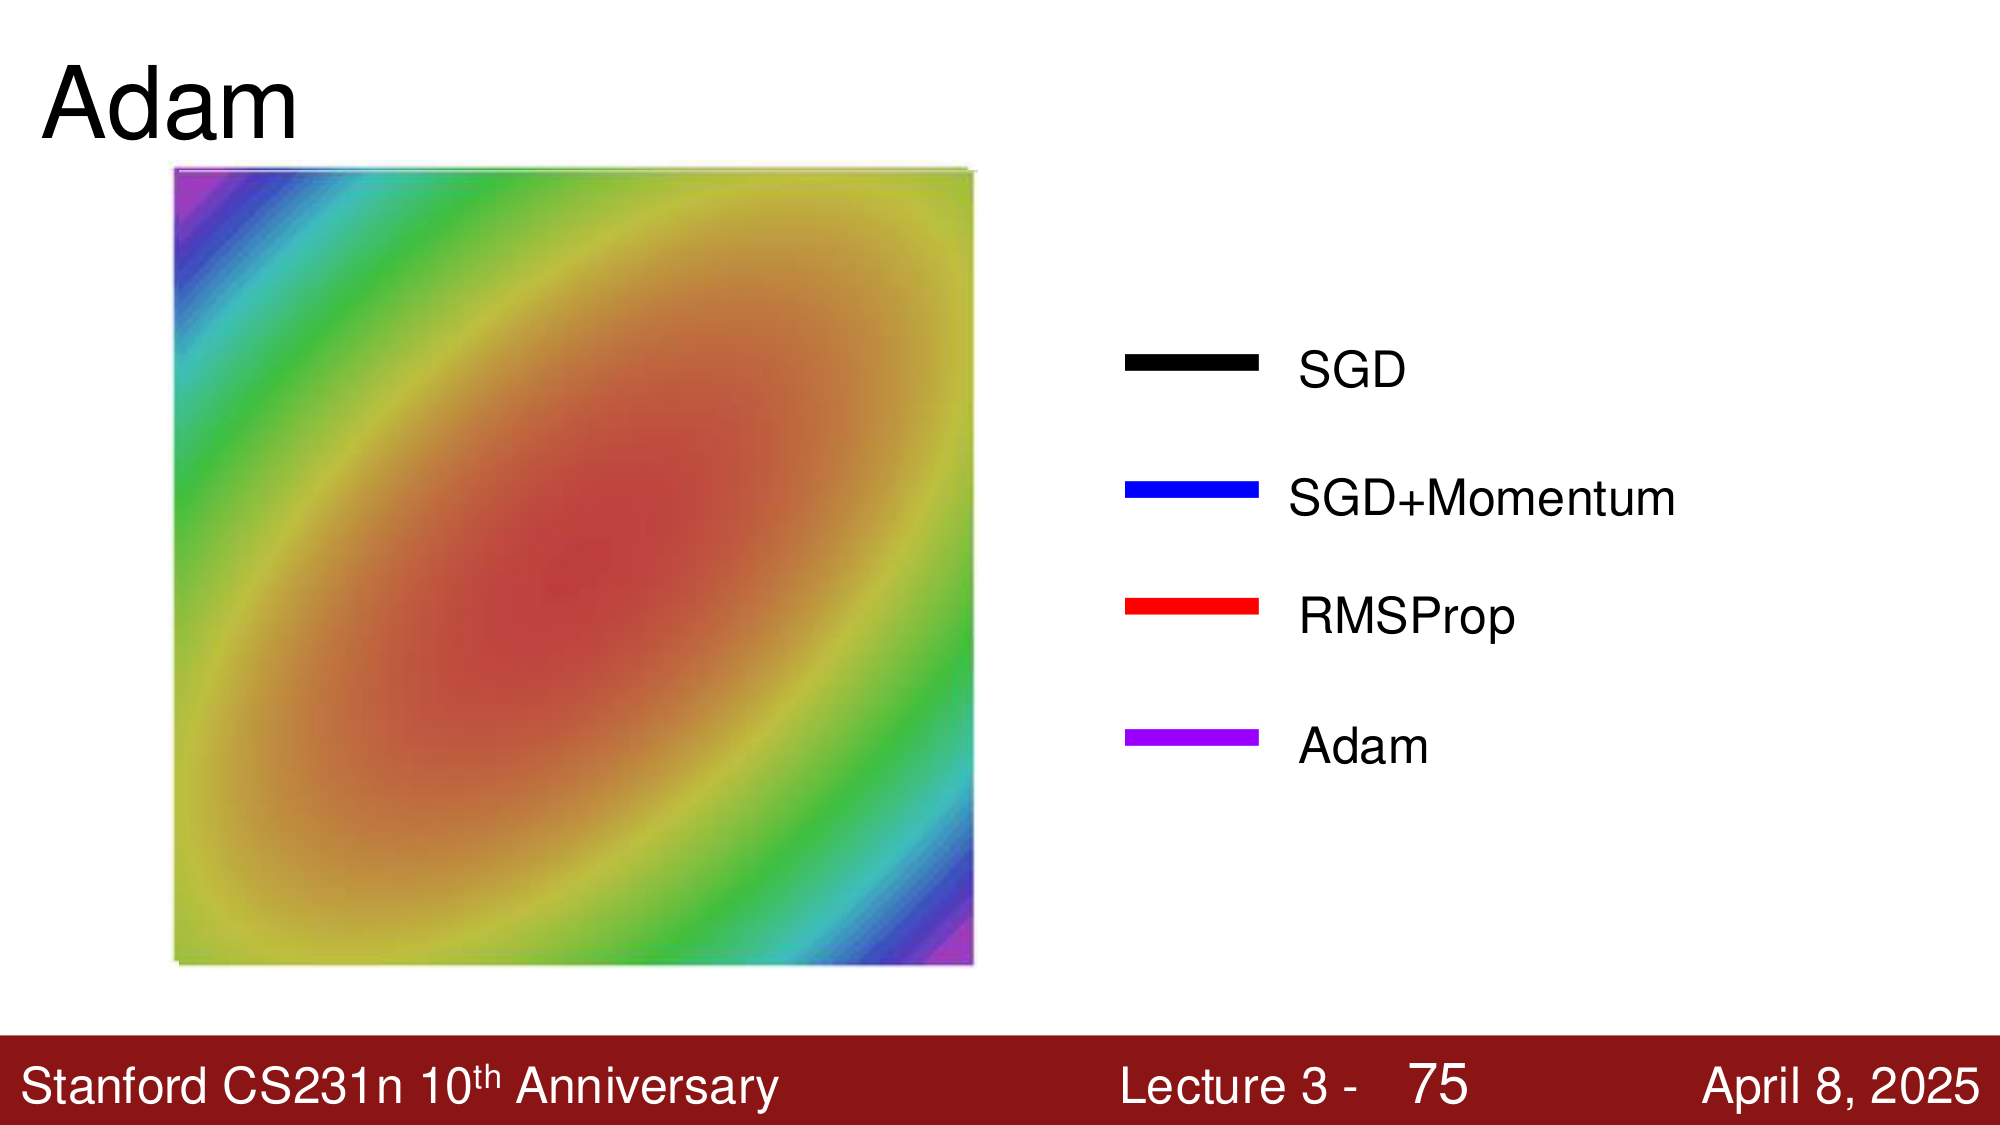
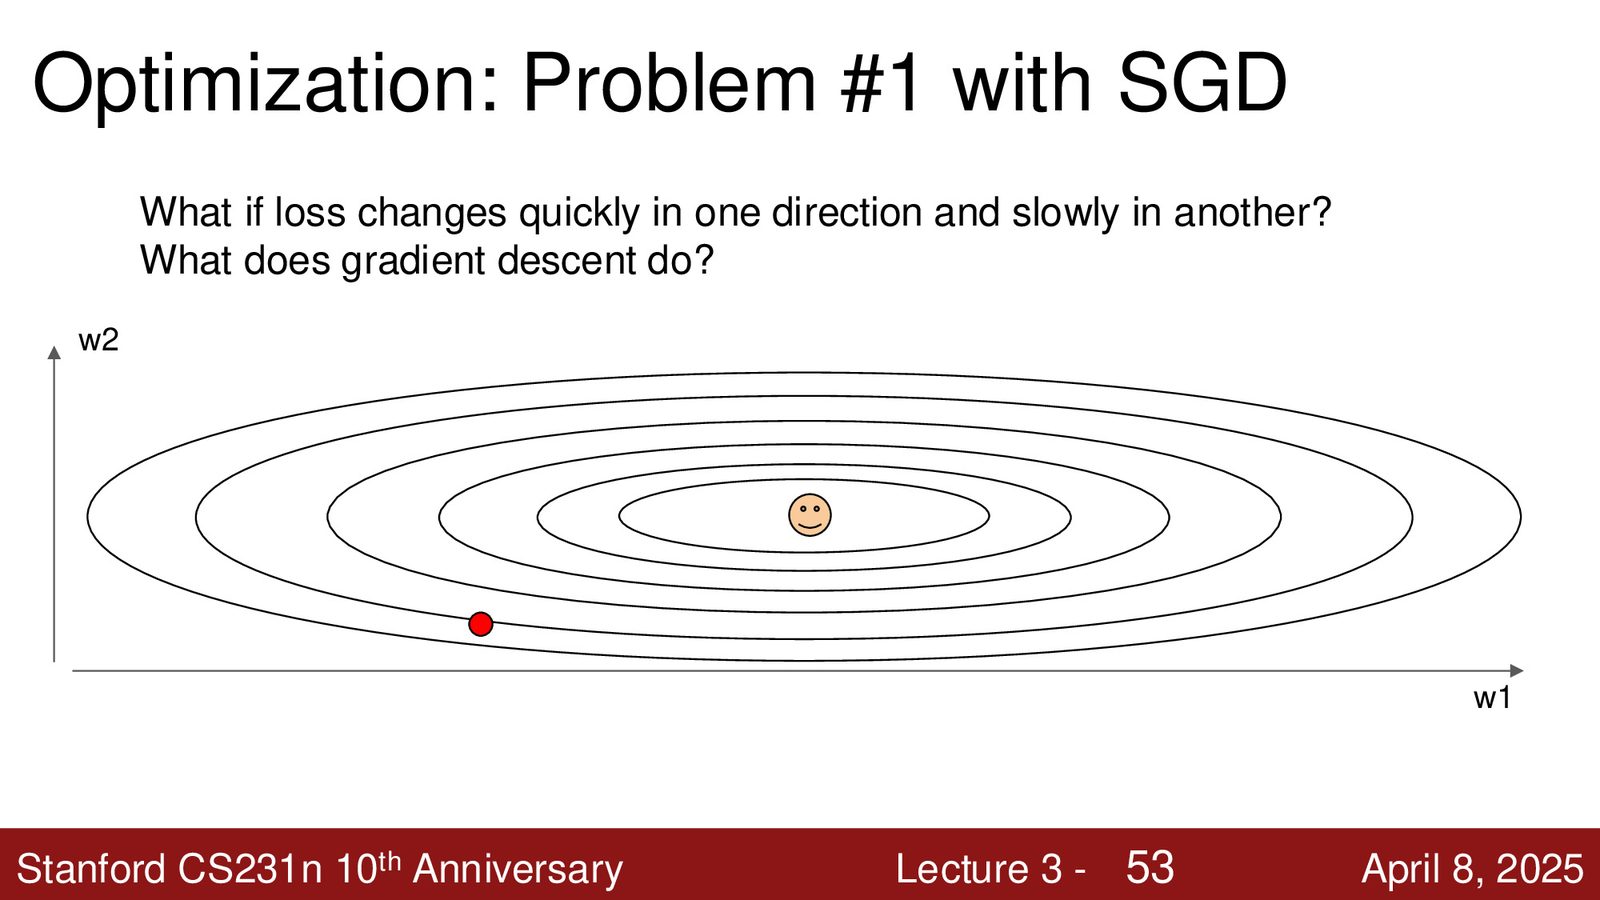
CS231N Lecture 3: Regularization and Optimization - AI Course Notes
From RMSProp to AdamW: The Optimizer Evolution Story | @naskovai
pytorch中如何使用adamW优化器 adam优化器代码_mob6454cc61981e的技术博客_51CTO博客
L12.4 Adam: Combining Adaptive Learning Rates and Momentum - YouTube