Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
Getting Started with Code Benchmarks -- CyBench : r/JavaPerformance
AI Code Review Benchmarks 2025 | Greptile
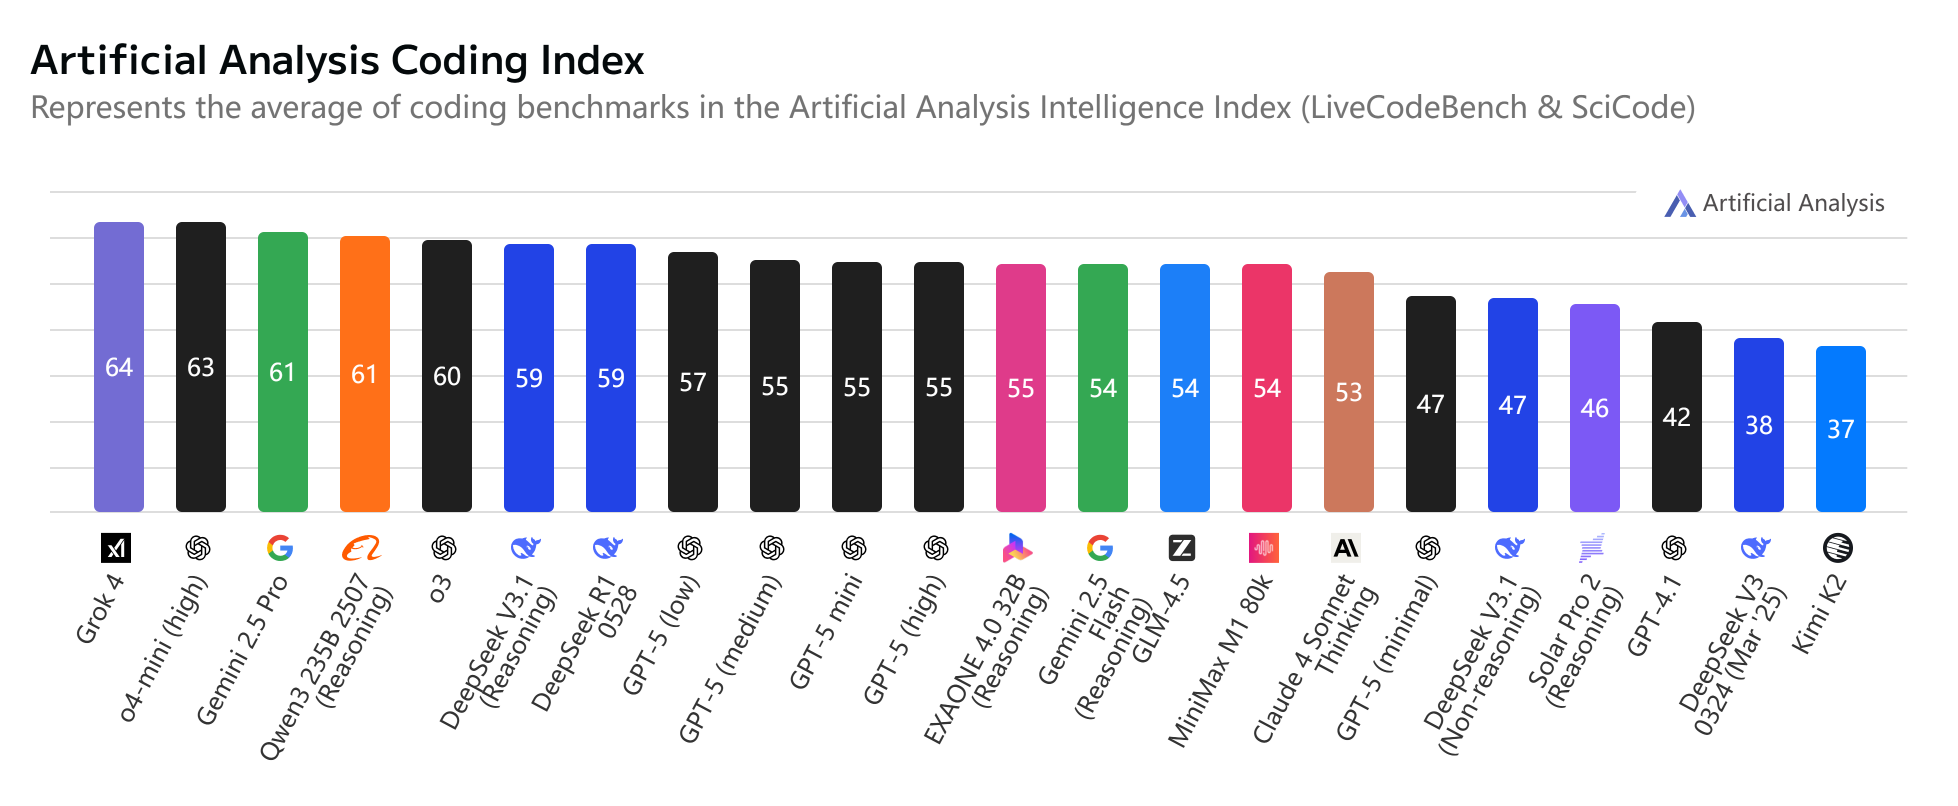
Summary of code benchmarks with experimental data. | Download ...
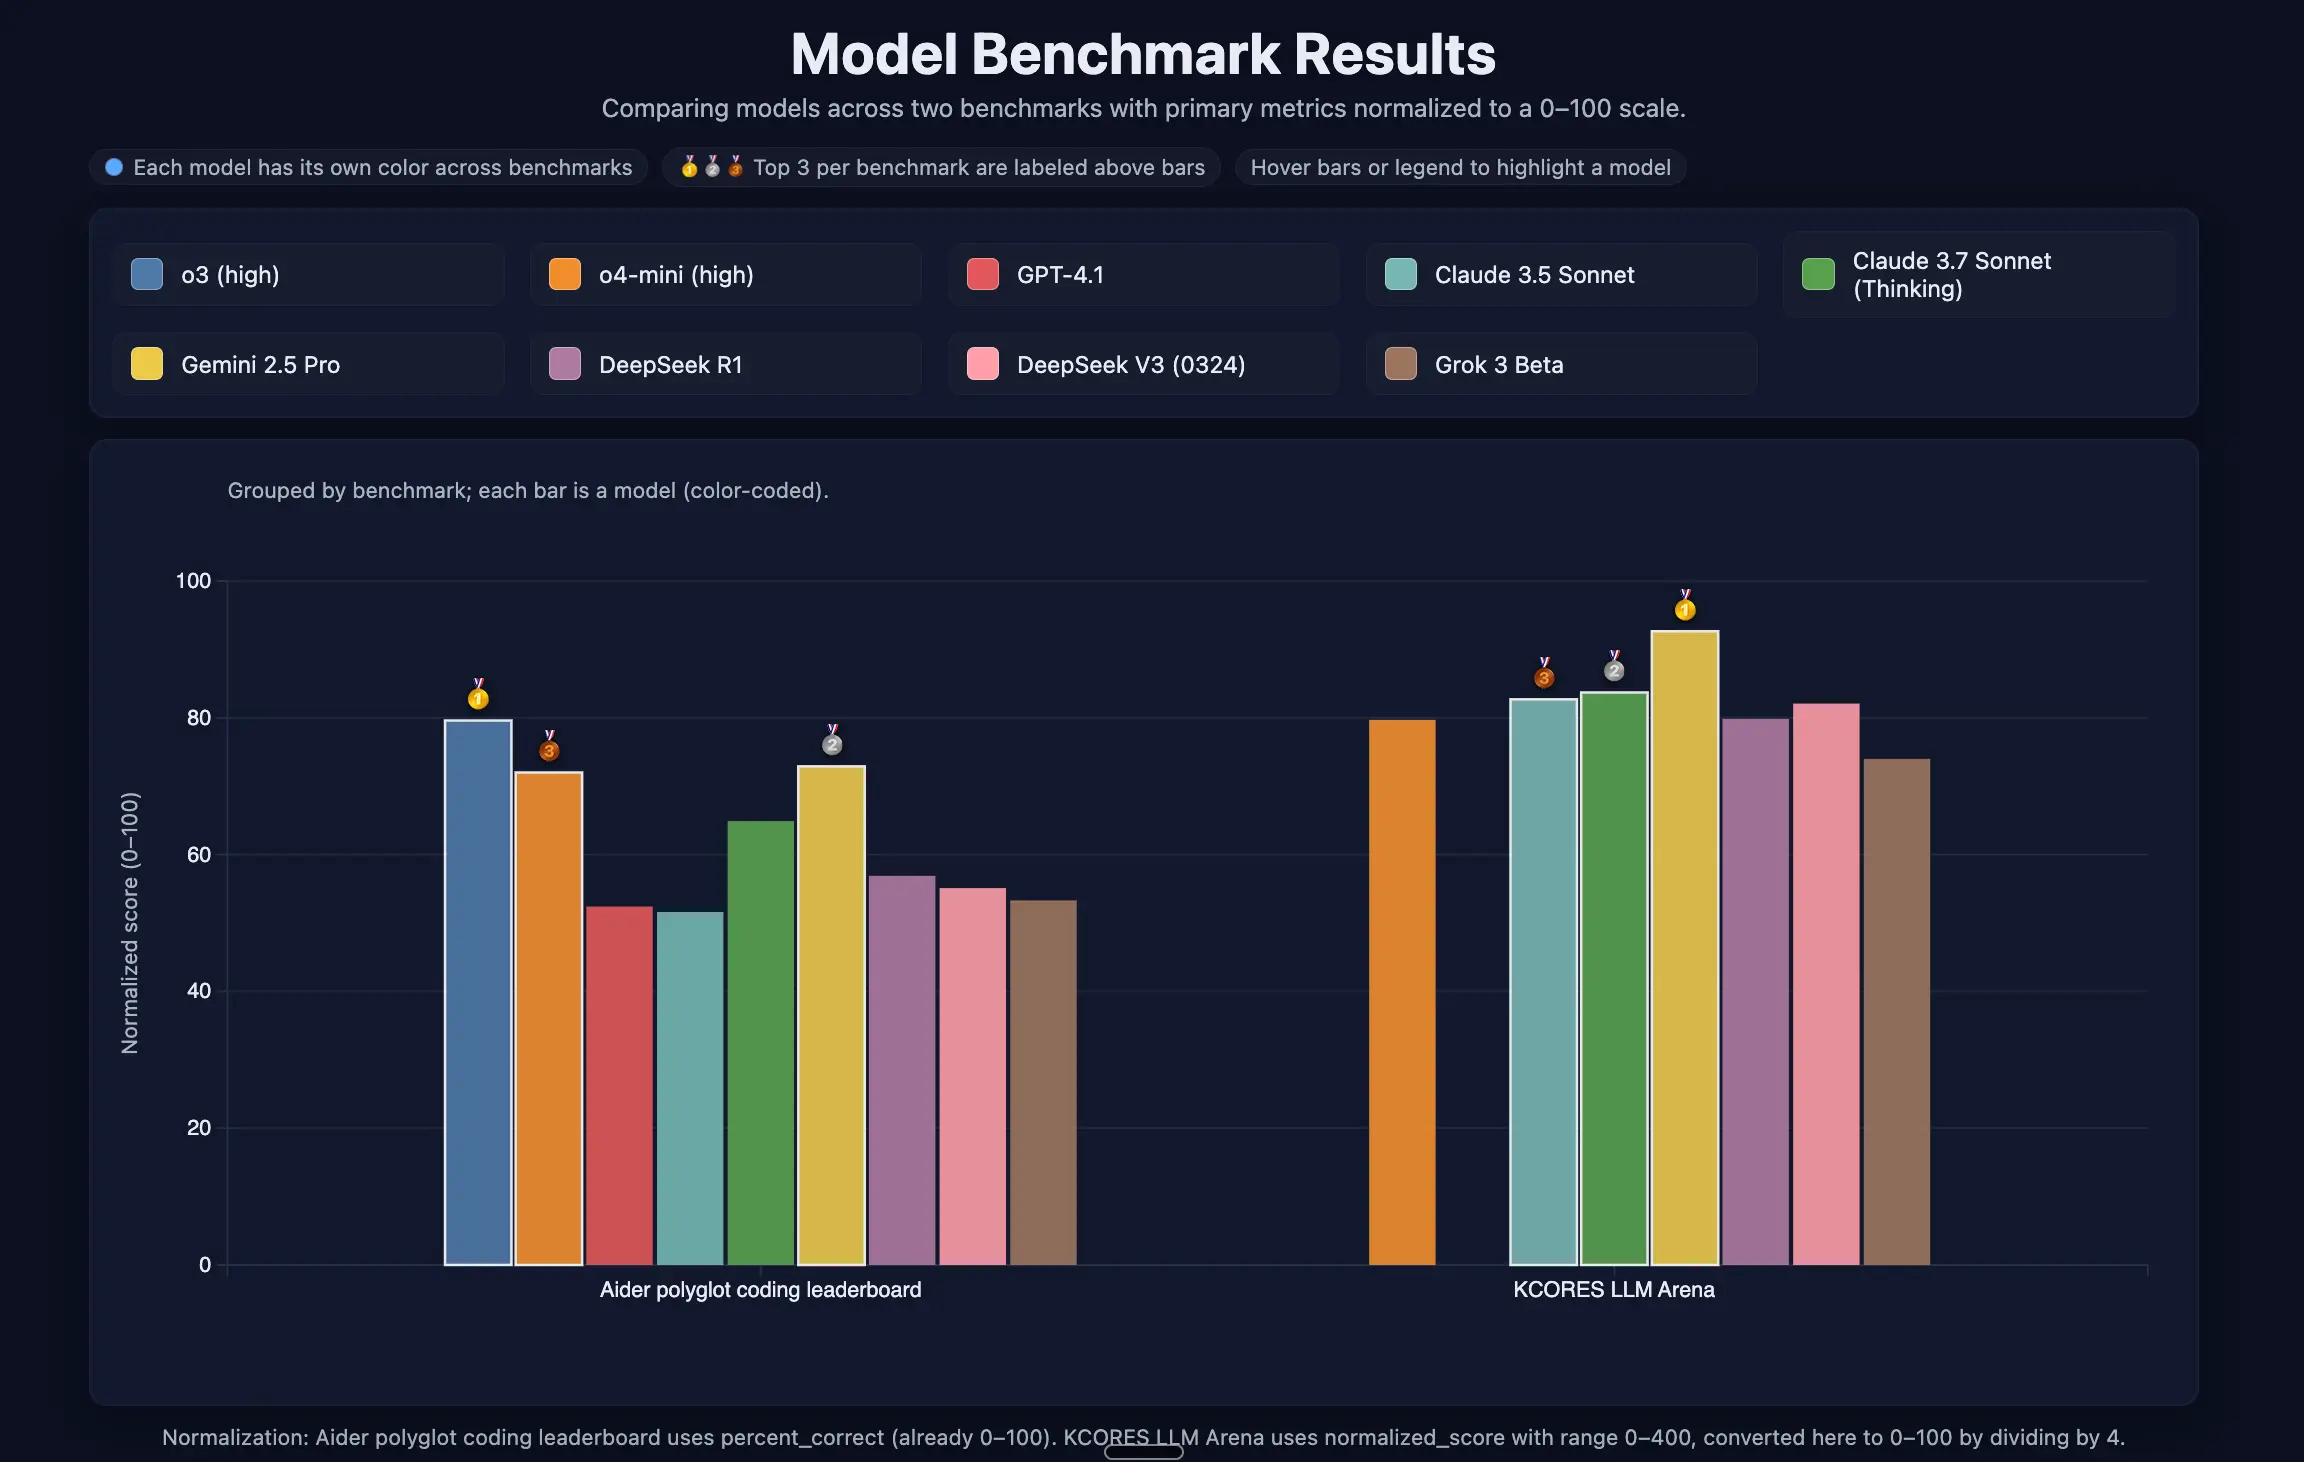
GPT code editing benchmarks | aider
Can code benchmarks save you money? - CyBench : r/JavaPerformance
An introduction to code LLM benchmarks for software engineers ...
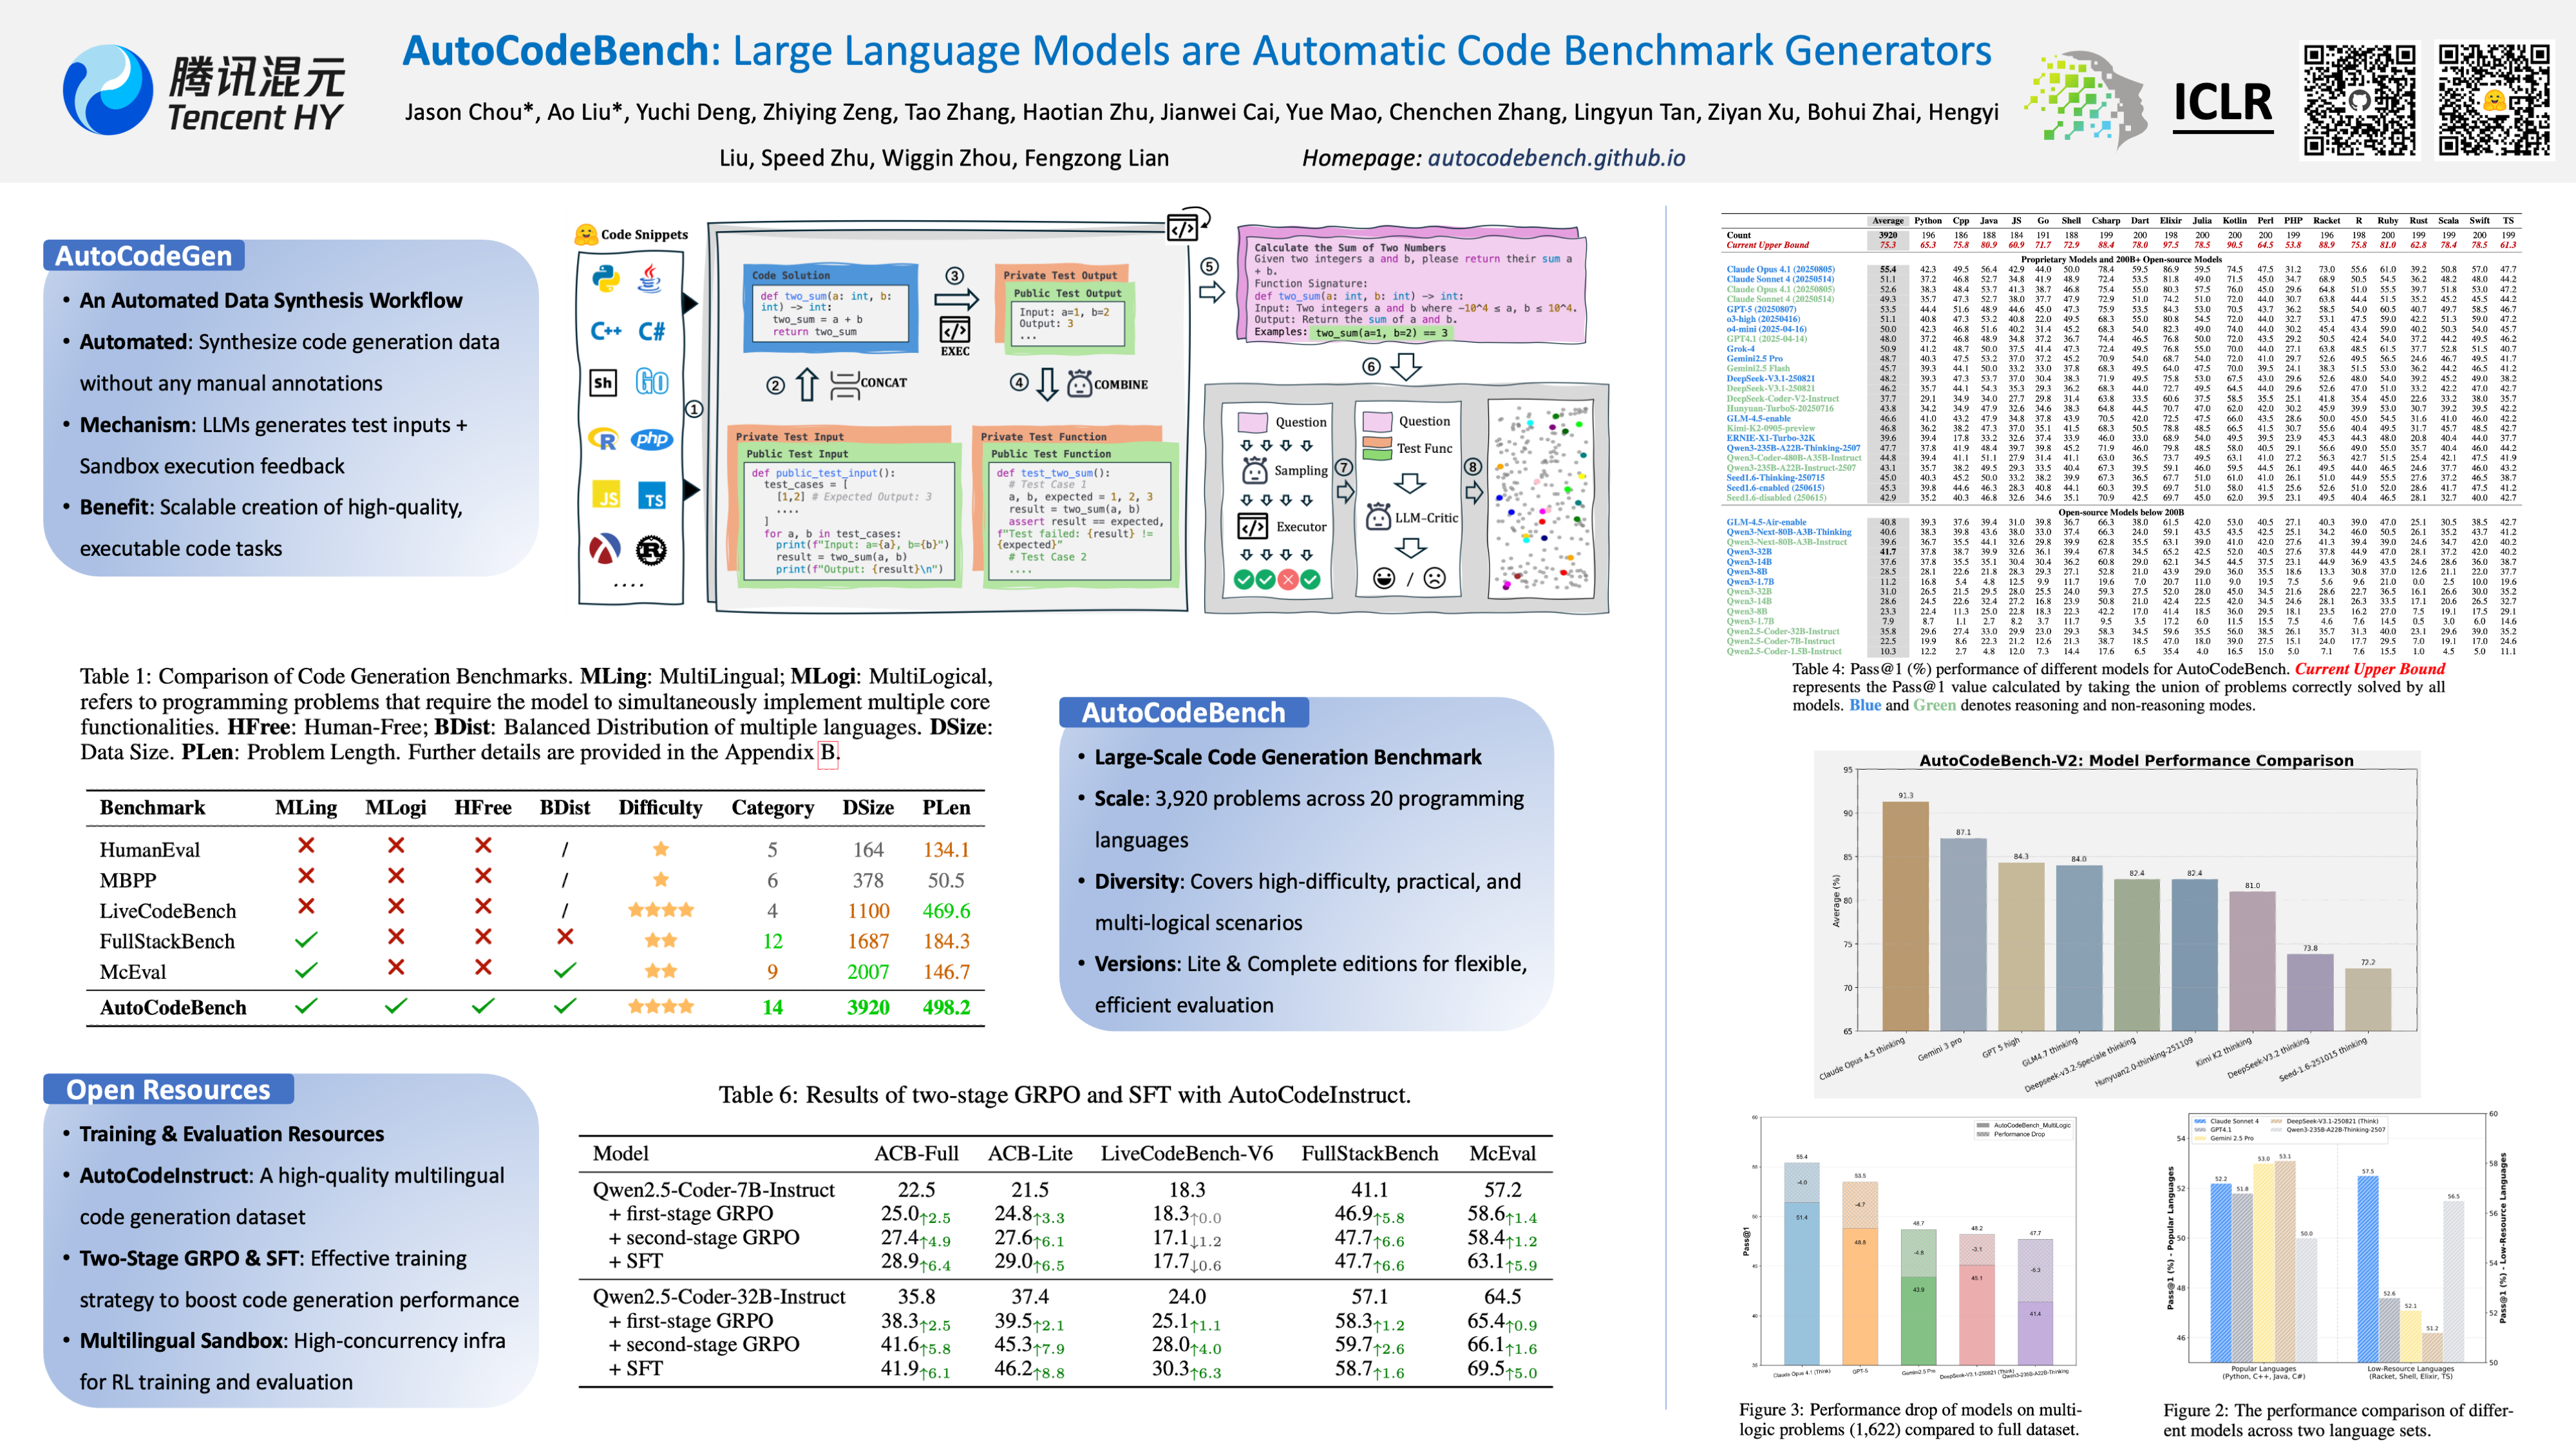
AutoCodeBench: When LLMs Generate Code Benchmarks | Justin Huang
The generated code size for standalone benchmarks based on all three ...
CODE VEIN 2 Benchmarks & PC Performance Analysis
BAILU CODE - AI 智能編程助手
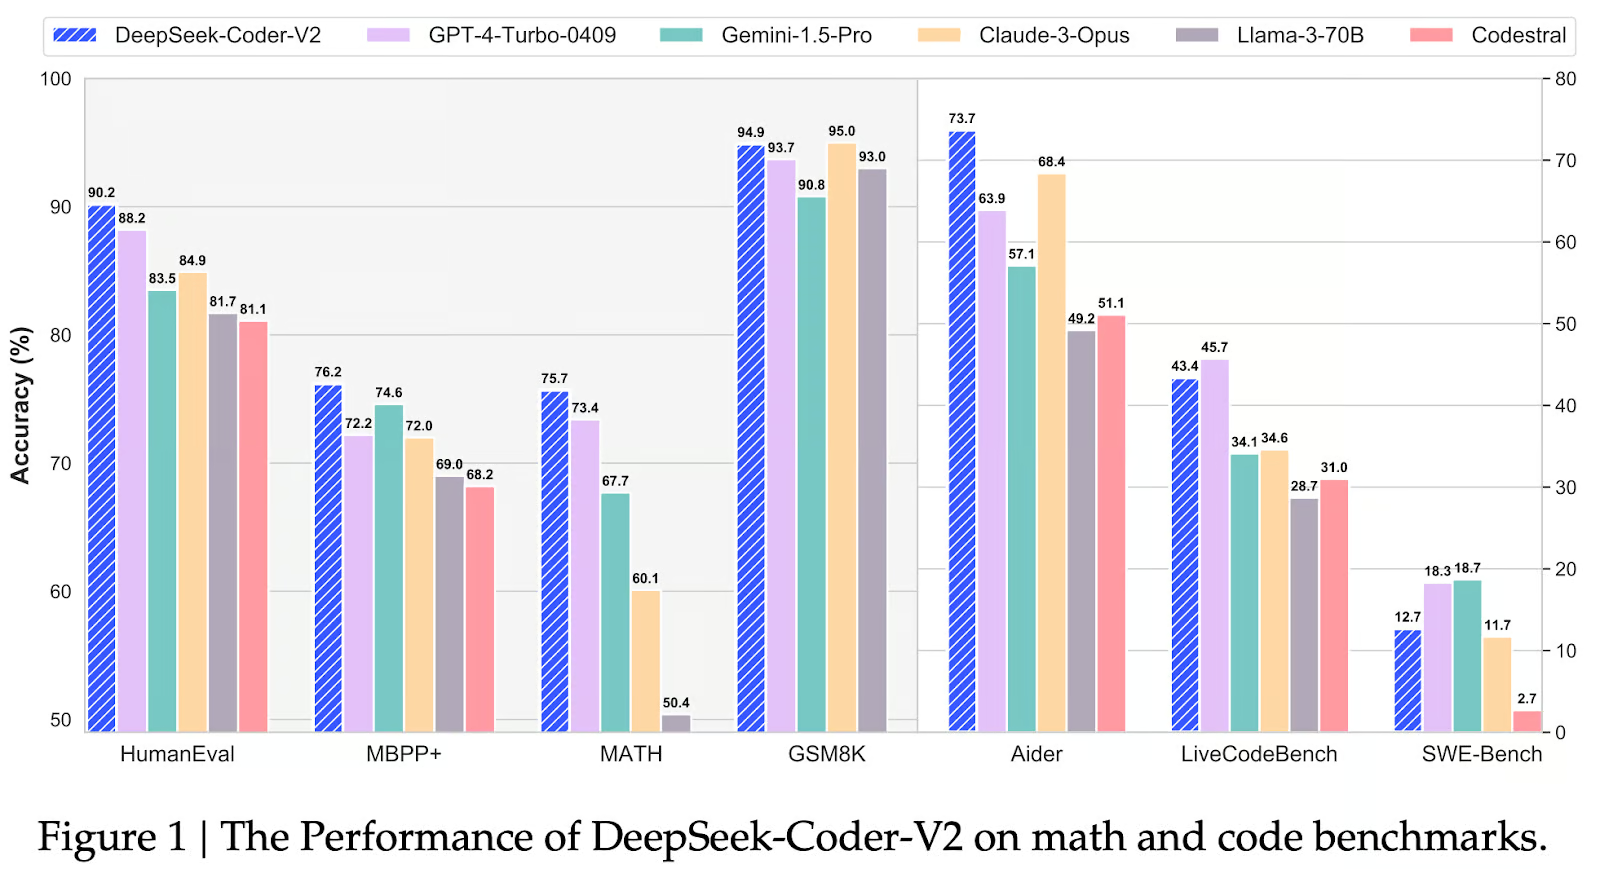
DeepSeek-Coder-V2 Tutorial: Examples, Installation, Benchmarks | DataCamp
AI Code Generation: New DevQualityEval Benchmark Reveals Which LLMs ...
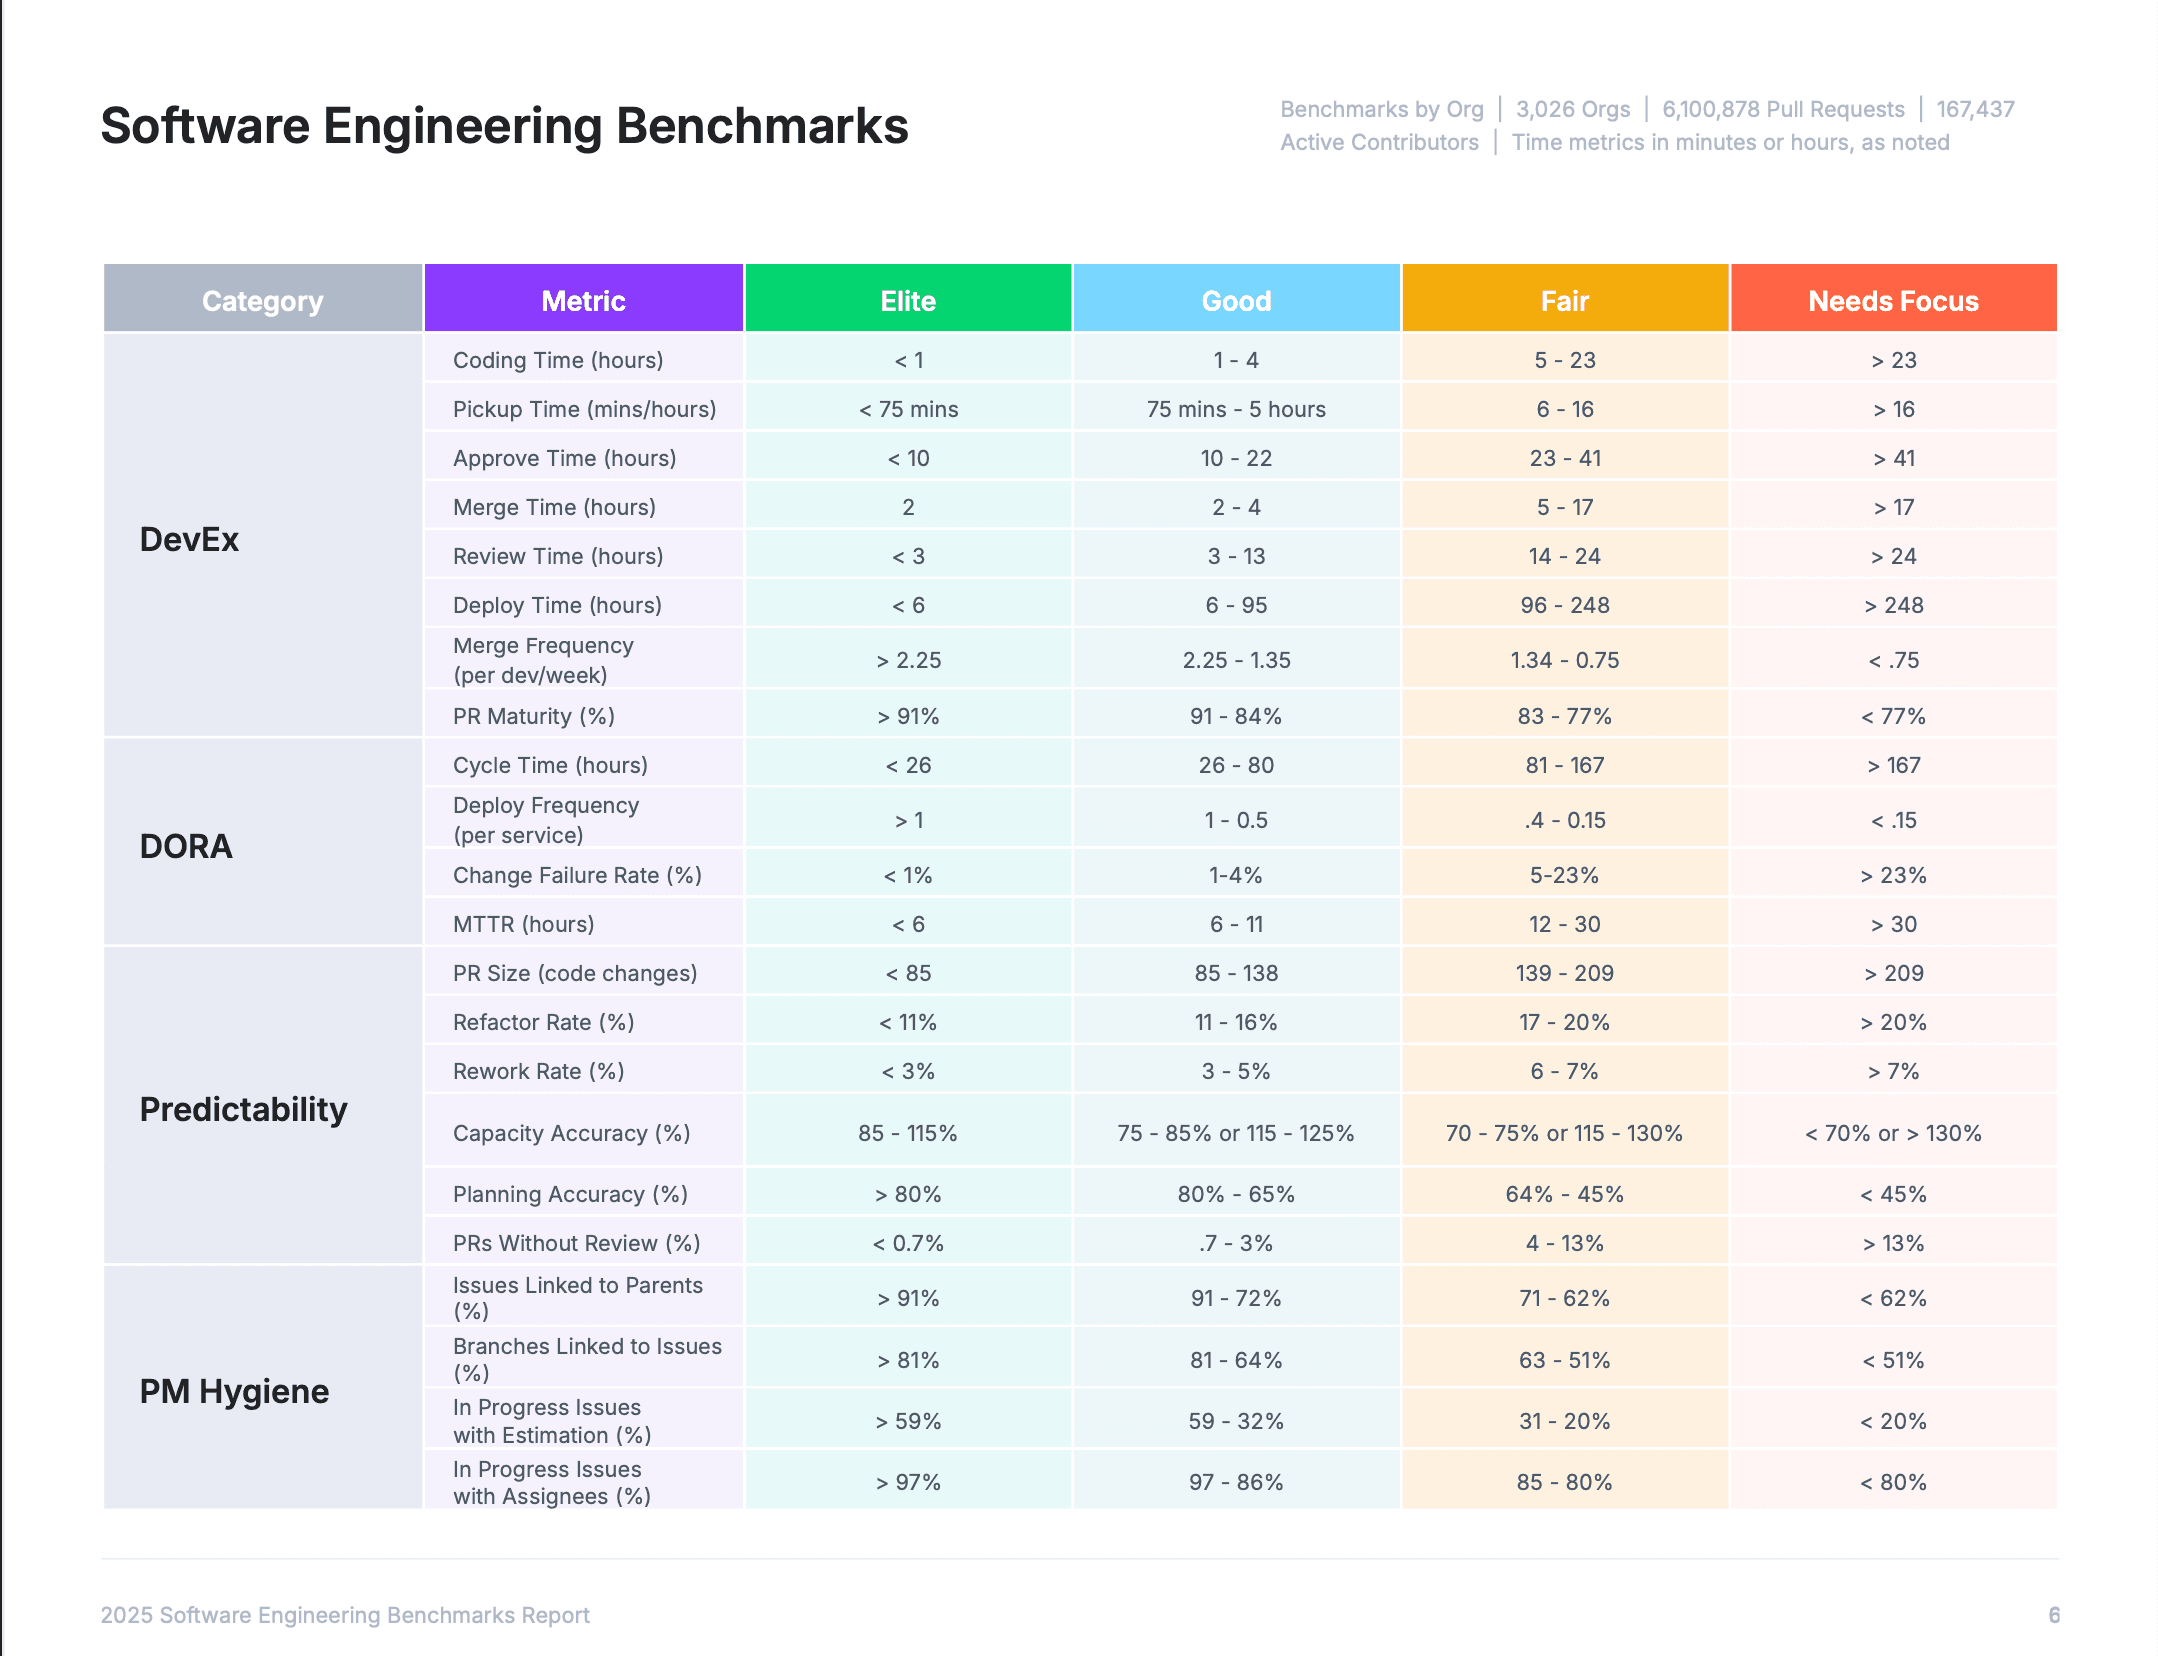
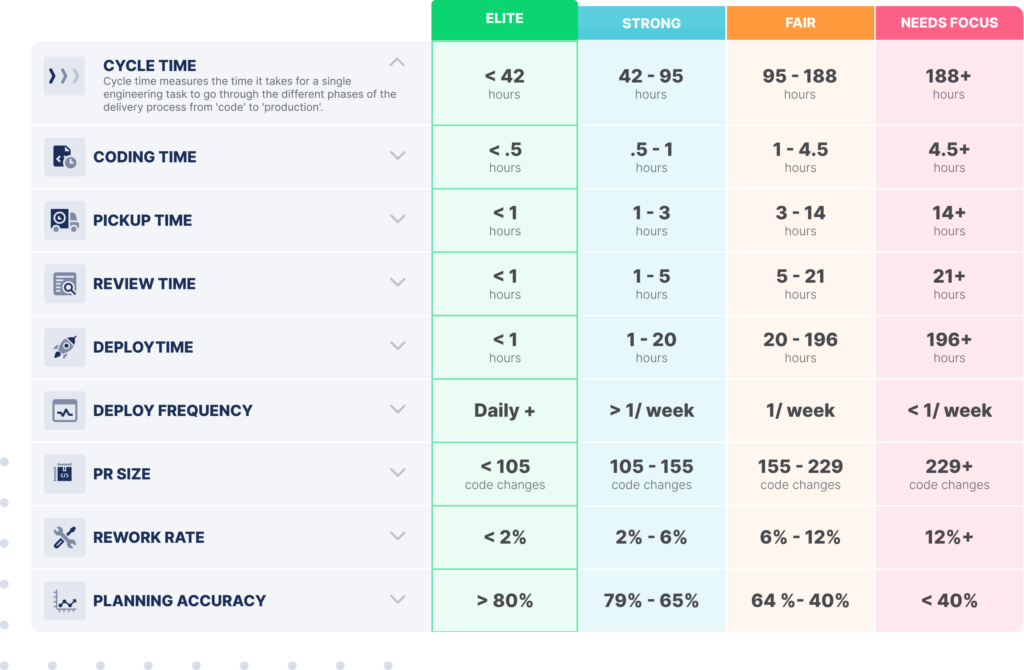
Software development metrics guide: Benchmarks & best practices ...
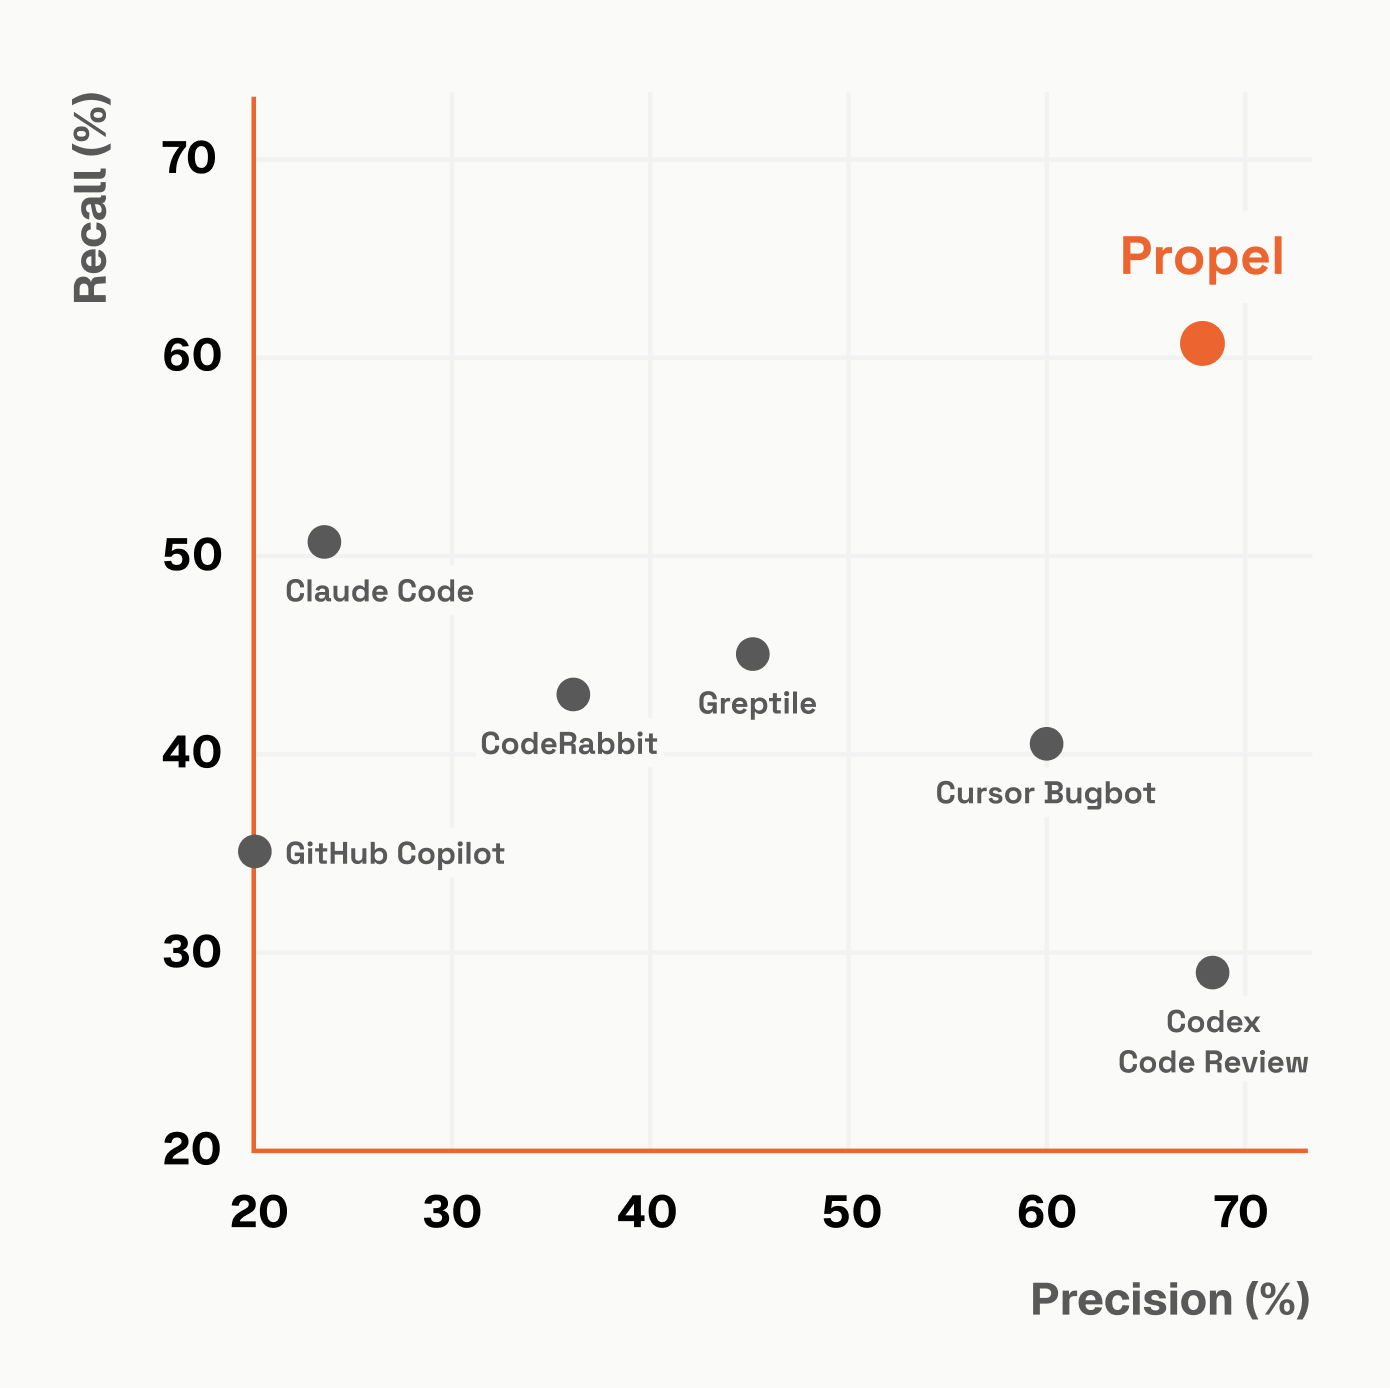
Benchmarking the Best AI Code Review Tool in 2026 - Bito
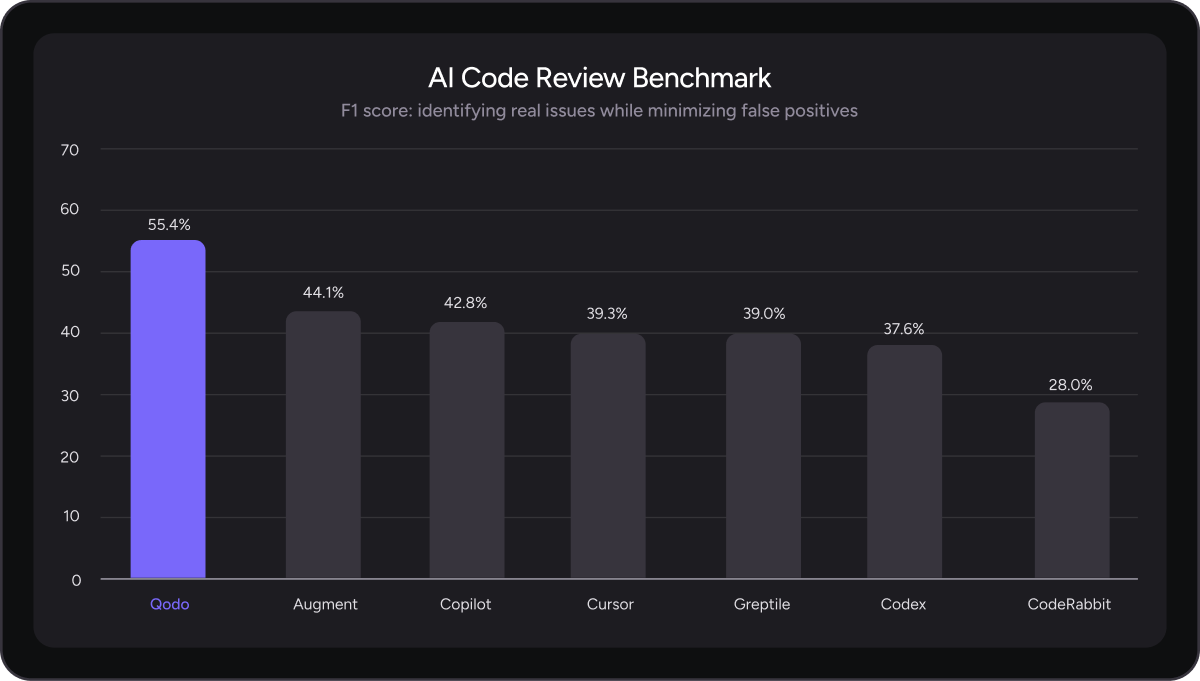
AI Code Review Benchmark
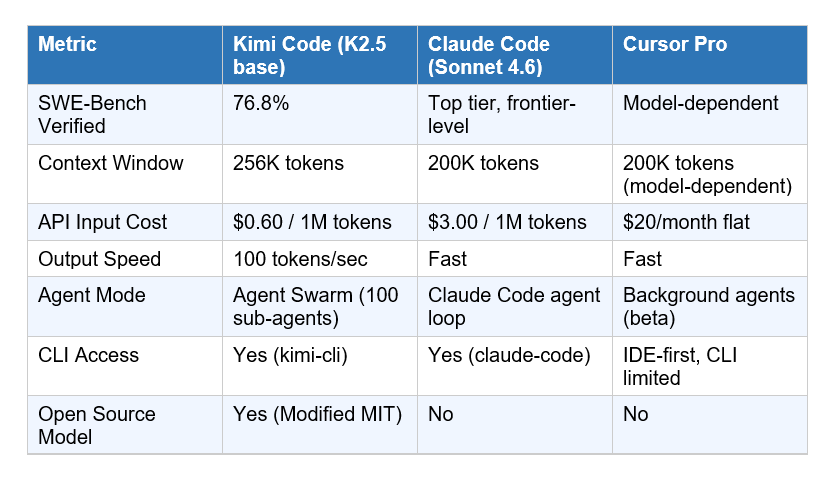
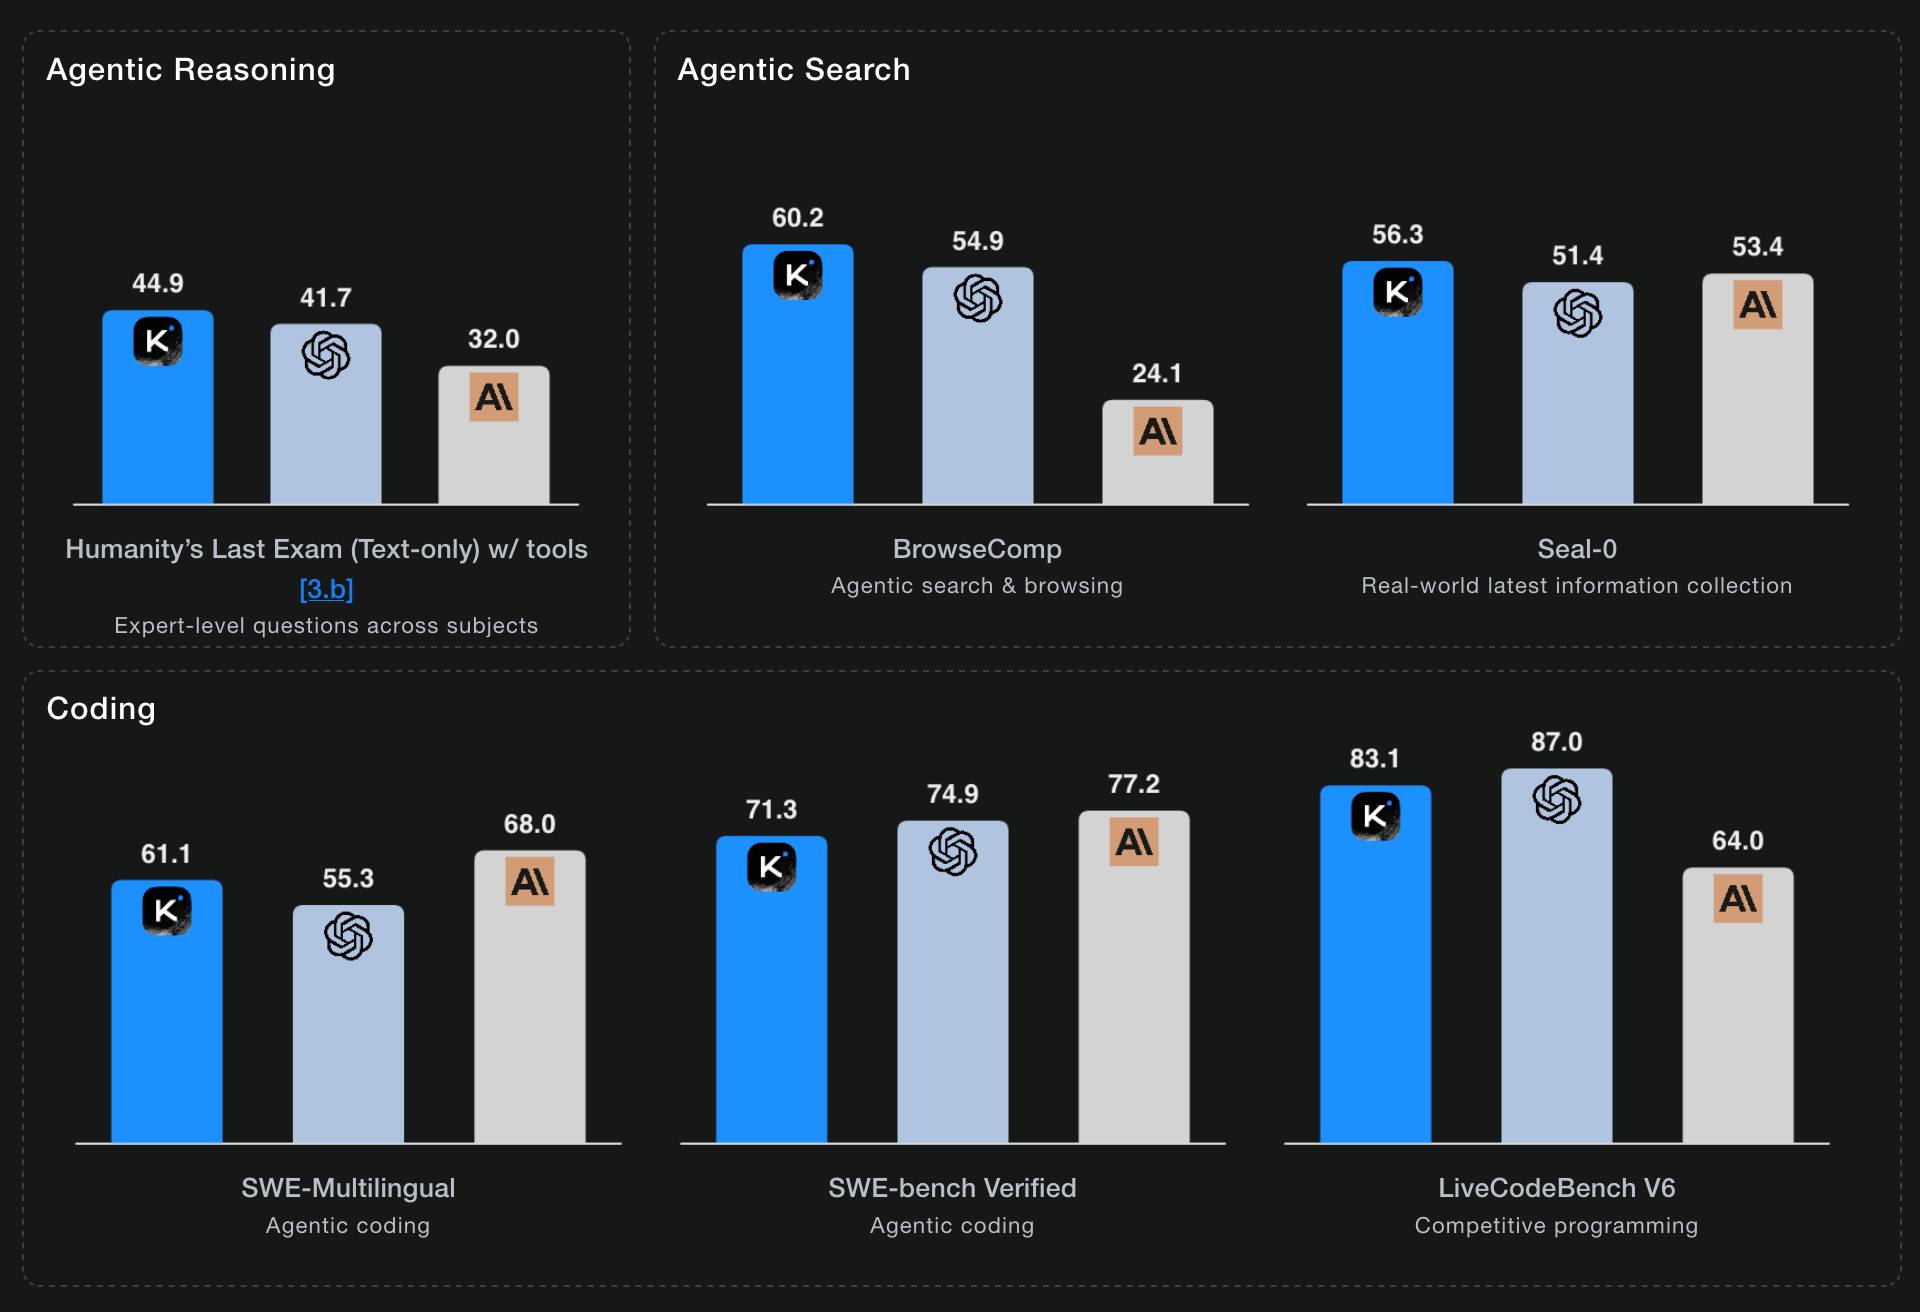
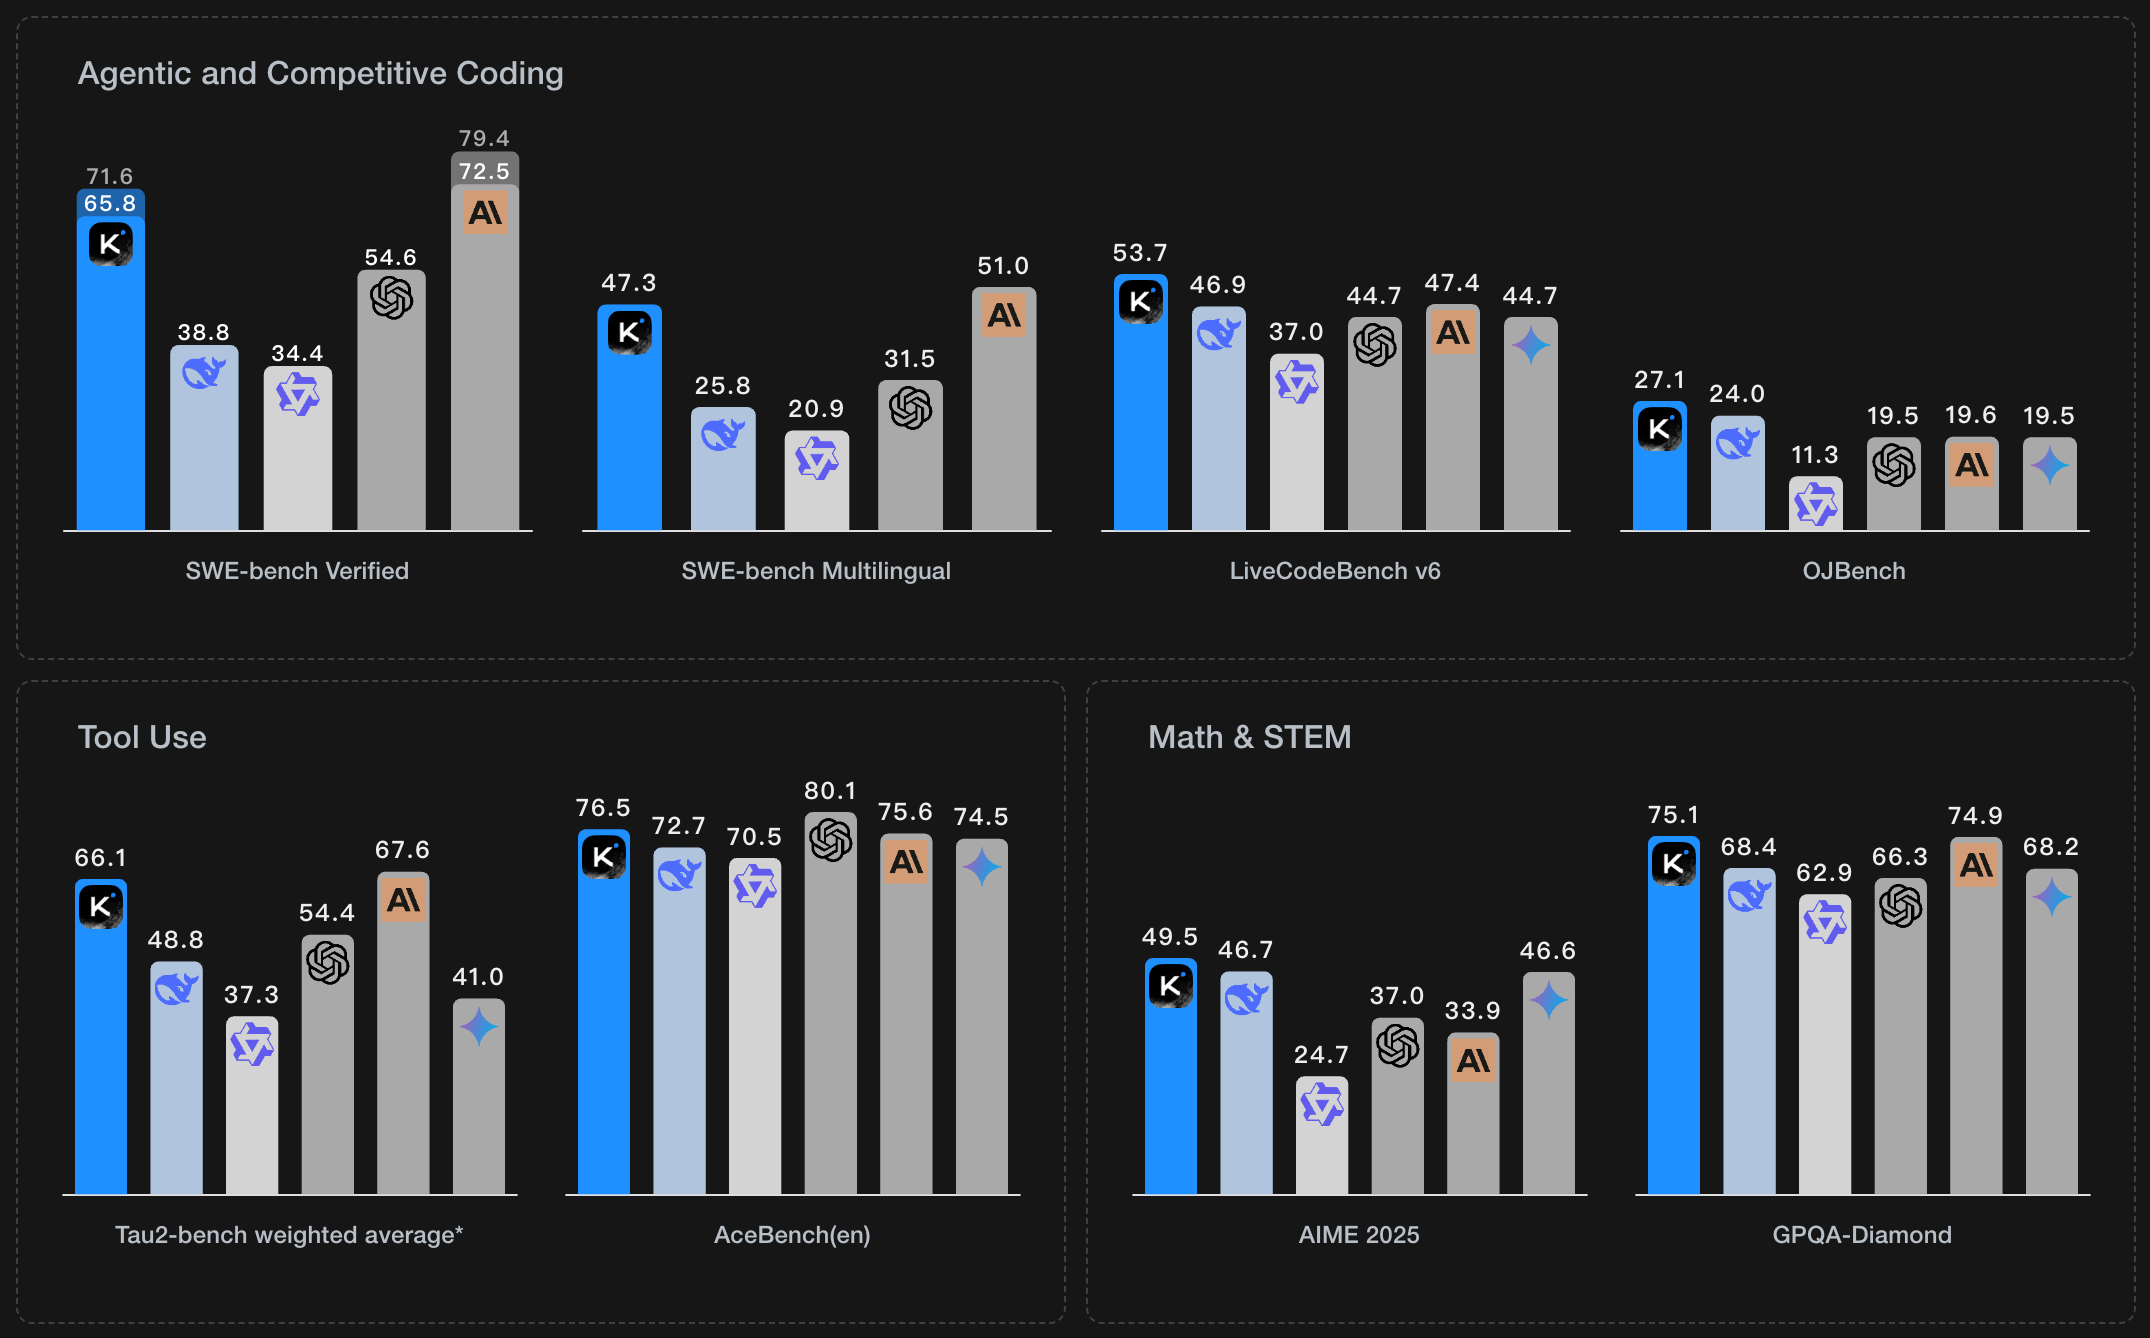
Kimi Code K2.6 Preview: What Developers Need to Know (2026)
Codex vs Claude Code 2025: Performance Comparison Guide
Open AI Codex vs Github Copilot vs Claude | Testing & Benchmarks
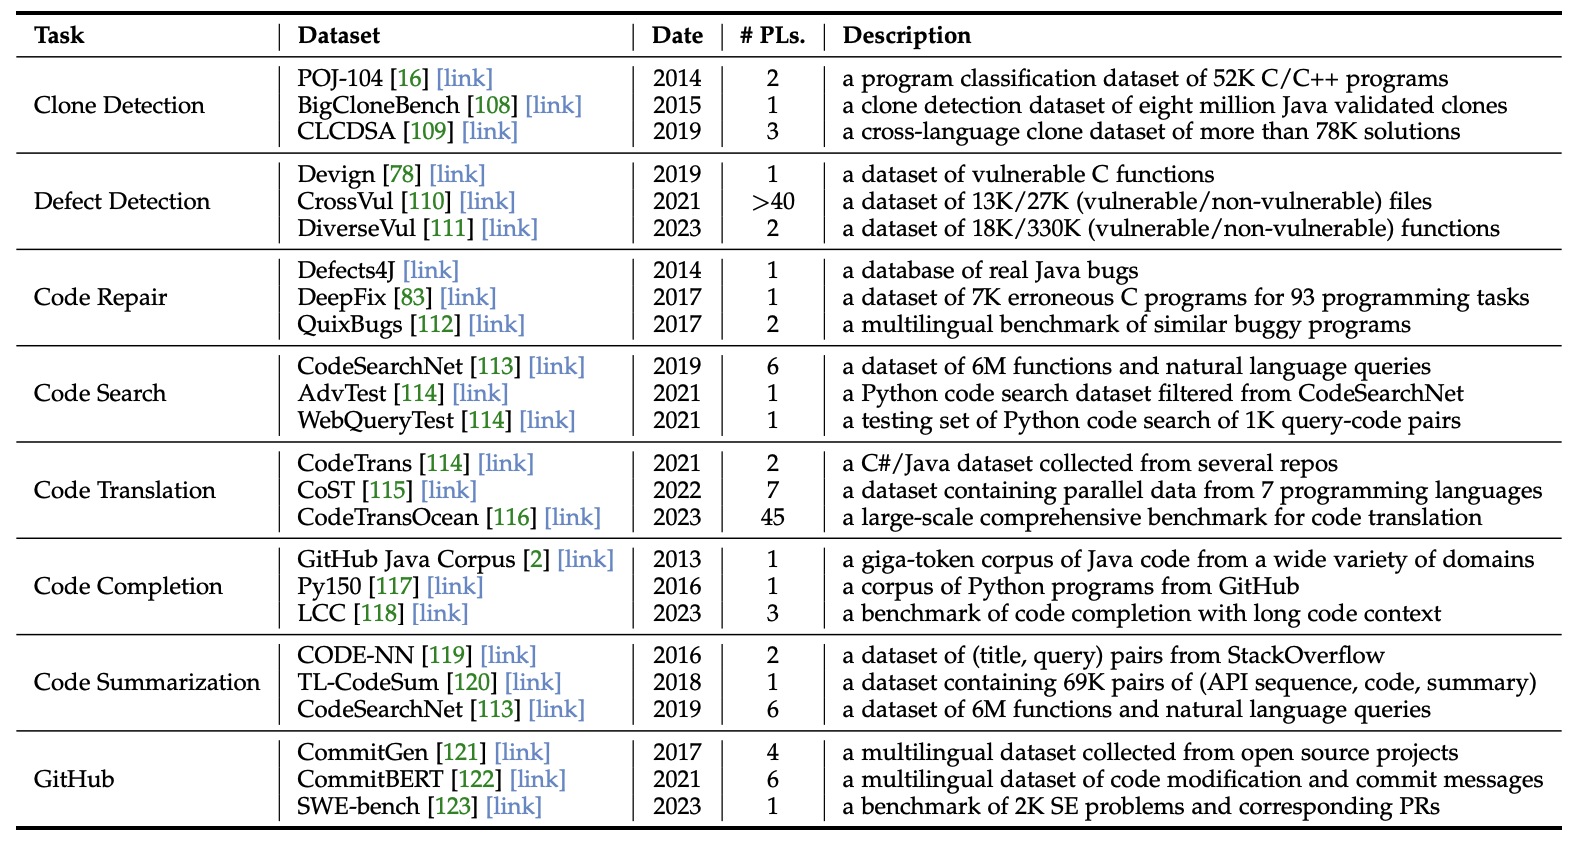
GitHub - tongye98/Awesome-Code-Benchmark: A comprehensive code domain ...
the benchmarks, their size in terms of number of lines of code ...
Best GitHub Code Review Platforms (2026 Snapshot) | Propel Code
GN Mega Charts: CPU Benchmarks & Comparison | GamersNexus
AutoCodeBench: Large Language Models are Automatic Code Benchmark ...
AI-Generated Code Quality Metrics and Statistics for 2026 | Second Talent
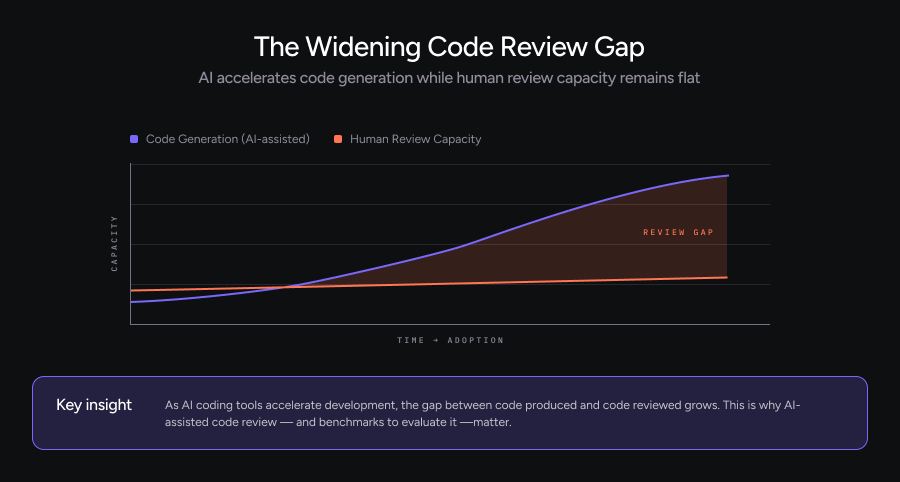
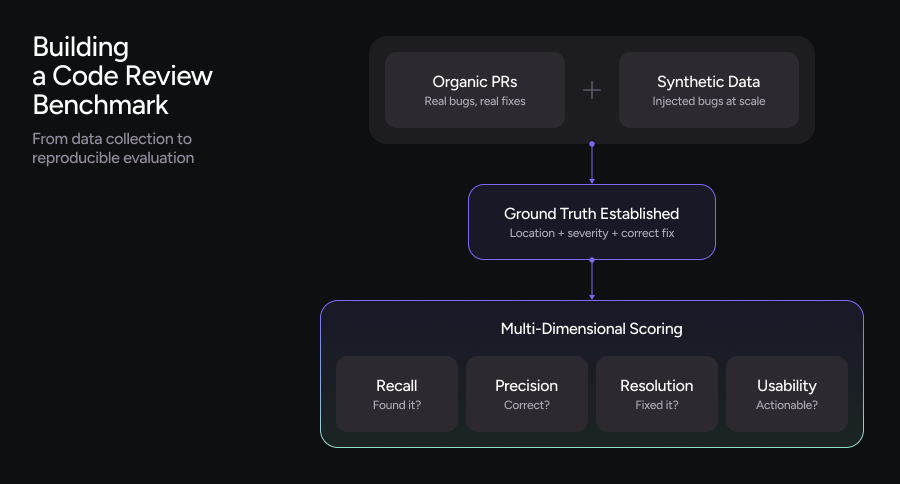
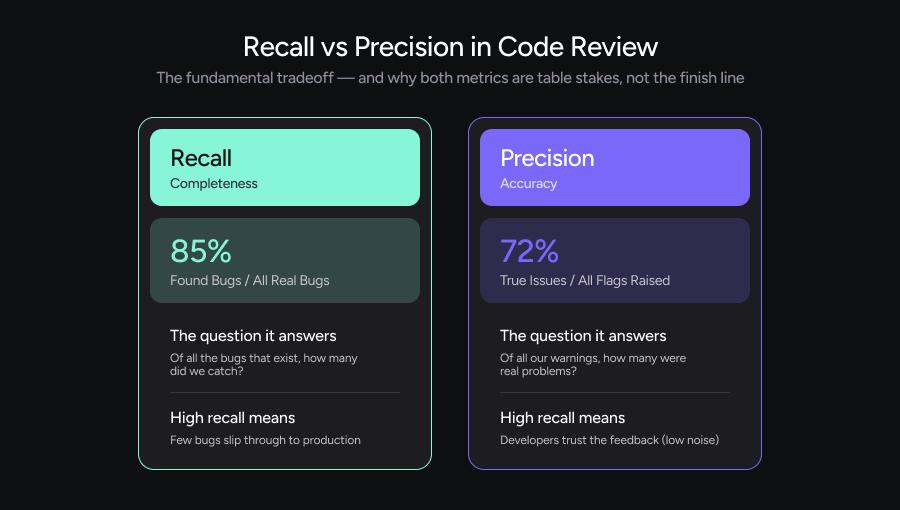
What makes a good code review benchmark for AI tools?
anton on Twitter: "Reran many models on code benchmark, matching or ...
15 LLM coding benchmarks
Benchmarks for Comparing Human and AI Intelligence — LessWrong
10 Best Code Analysis and Code Quality Tools in 2026
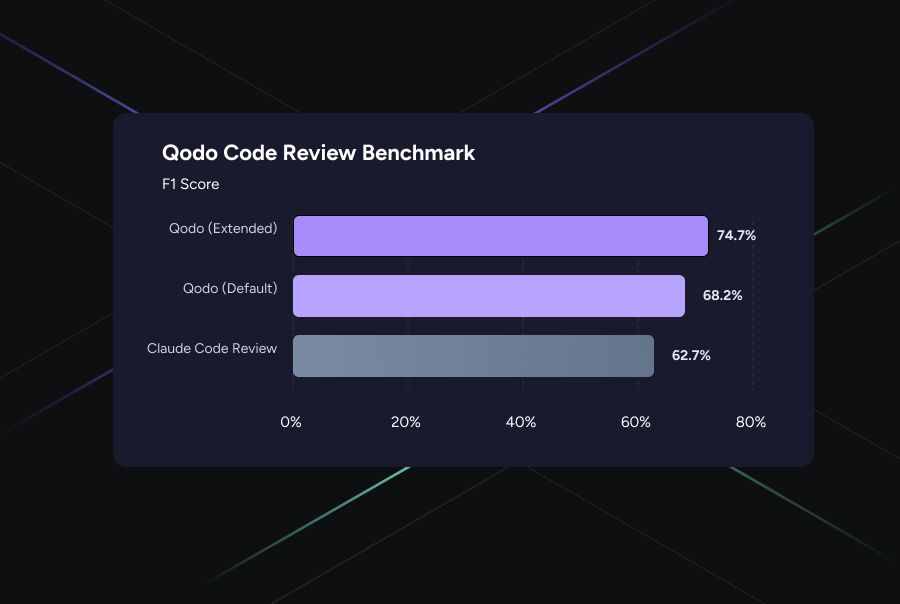
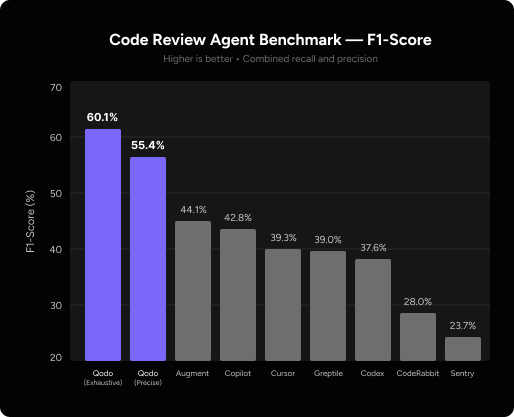
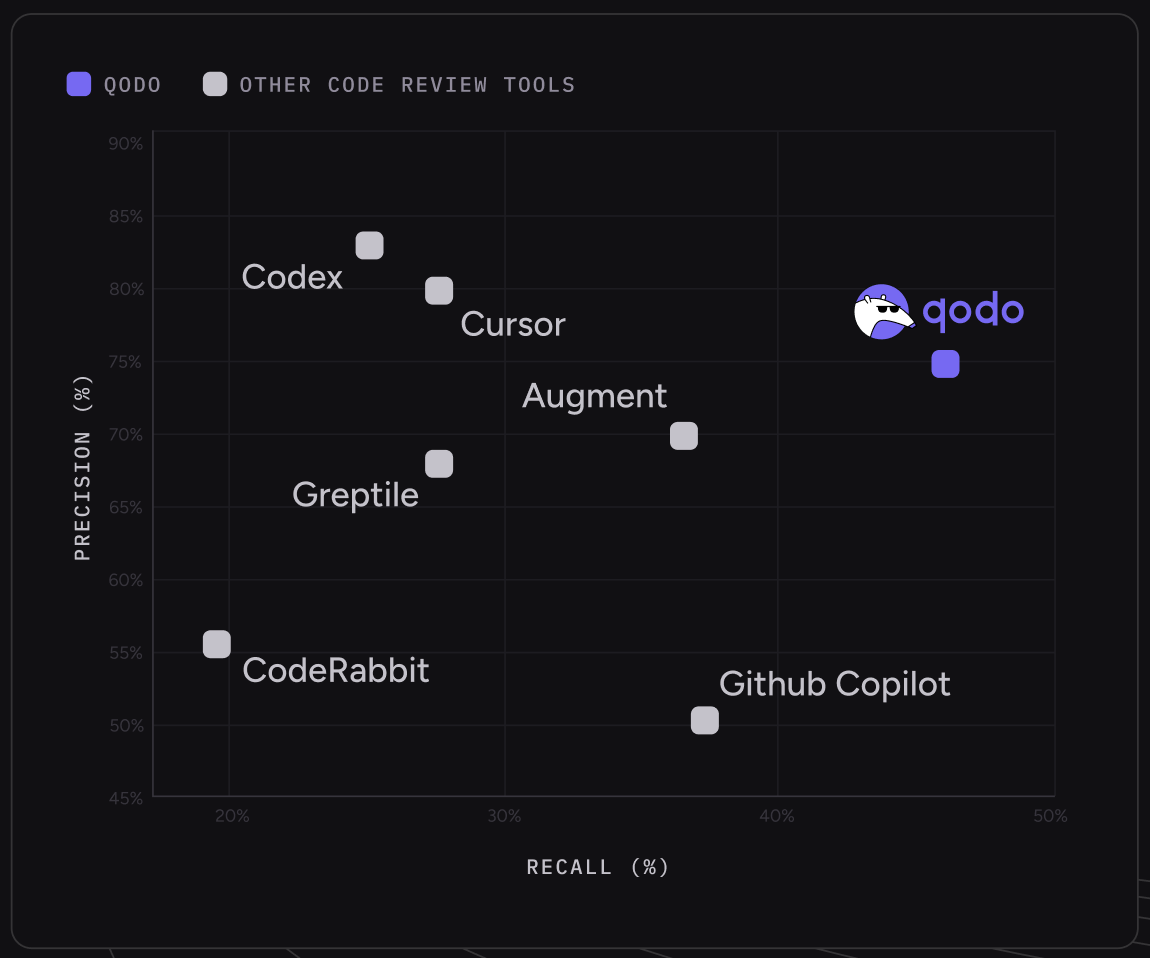
Qodo Outperforms Claude in Code Review Benchmark - Qodo
ICLR Poster AutoCodeBench: Large Language Models are Automatic Code ...
What Is Code Complexity? What It Means and How to Measure It | LinearB Blog
[논문 리뷰] CoCo-Bench: A Comprehensive Code Benchmark For Multi-task Large ...
GitHub - code-bench/codebench: Automated code benchmark solution. · GitHub
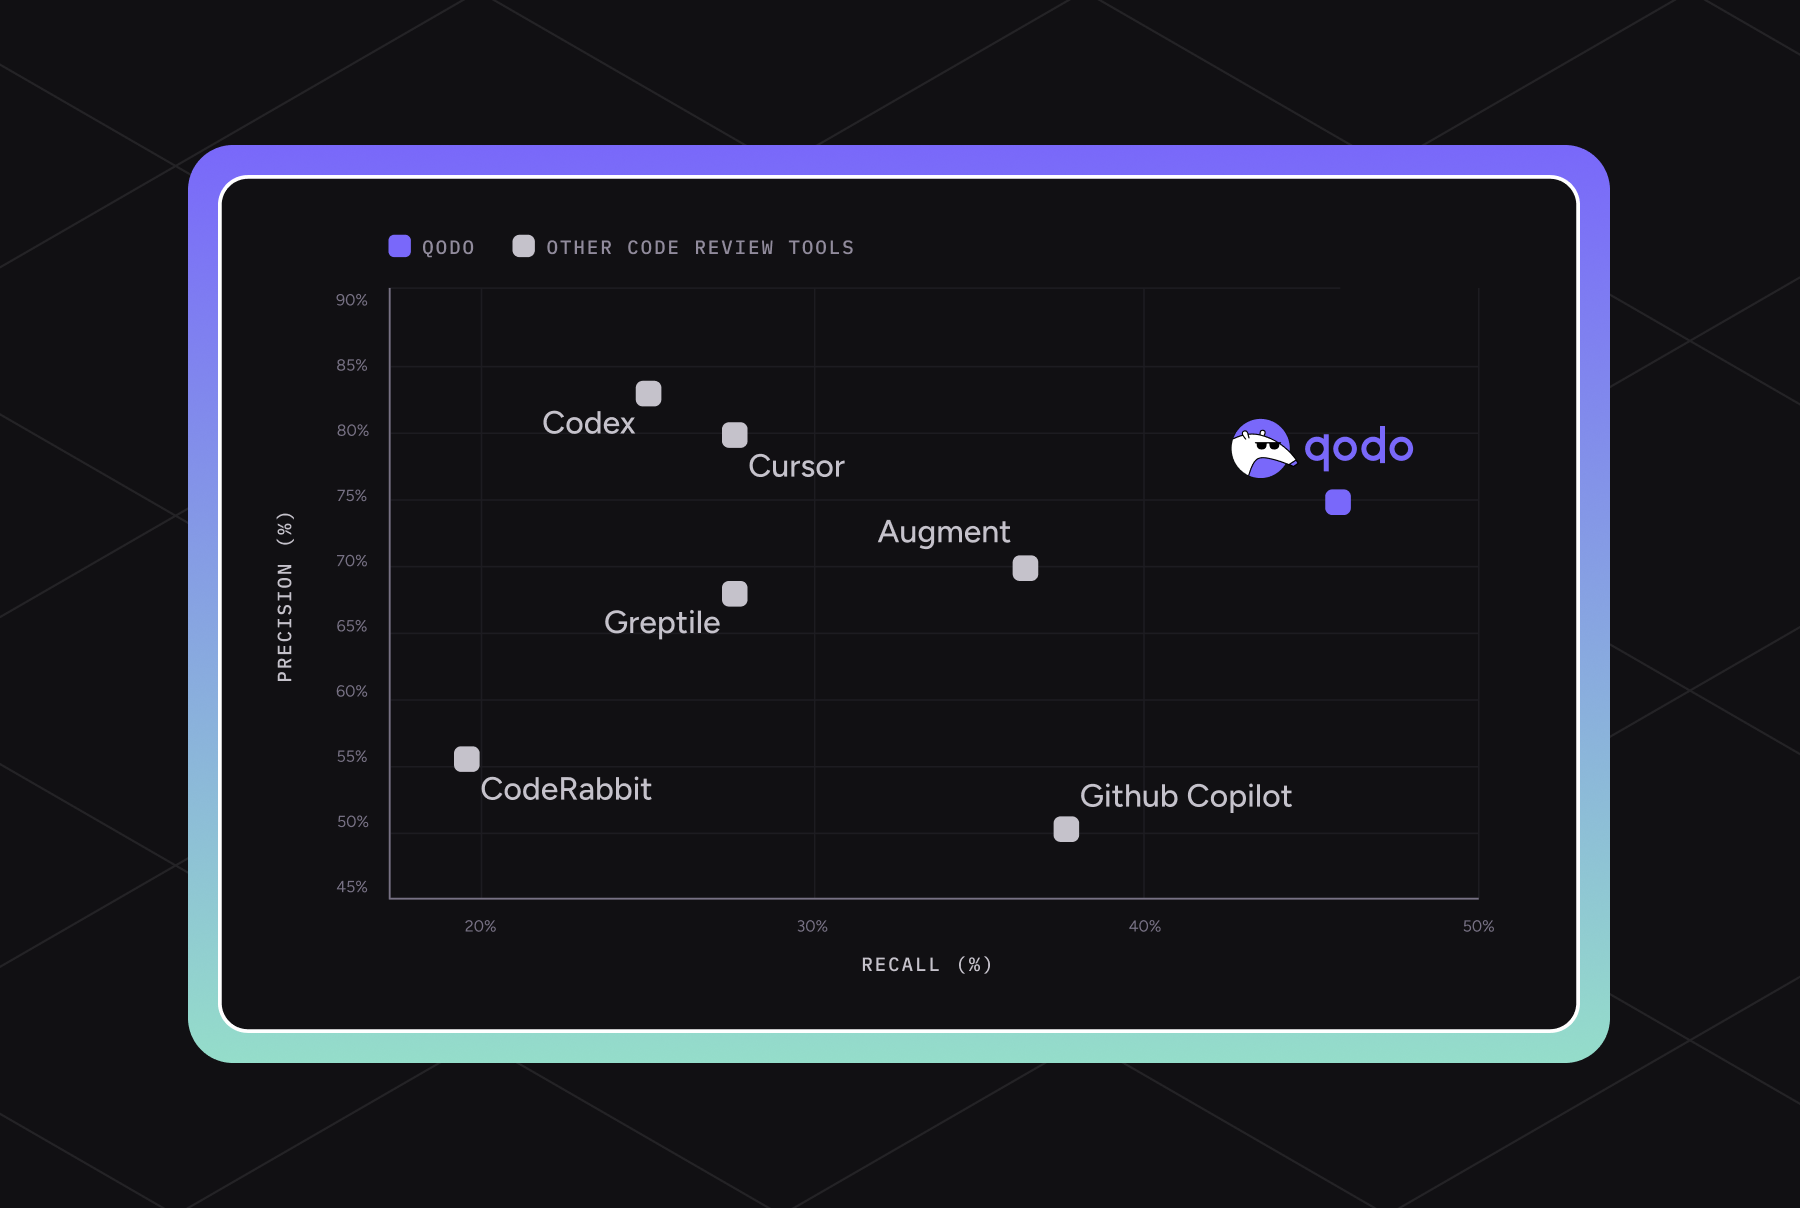
How Qodo Built a Real-World Benchmark for AI Code Review
Claude Code vs Codex en 2026: qué agente de código elegir ahora ...
4th Grade Math 6.6, Compare Fractions Using Benchmarks - Worksheets Library
BigCodeBench: Benchmarking Code Generation with Diverse Function Calls ...
Vibe code benchmark
Repeated "write better code" prompts can make AI-generated code 100x faster
Discussion on "LLM for Coding Benchmarks and Datasets" | Hashnode
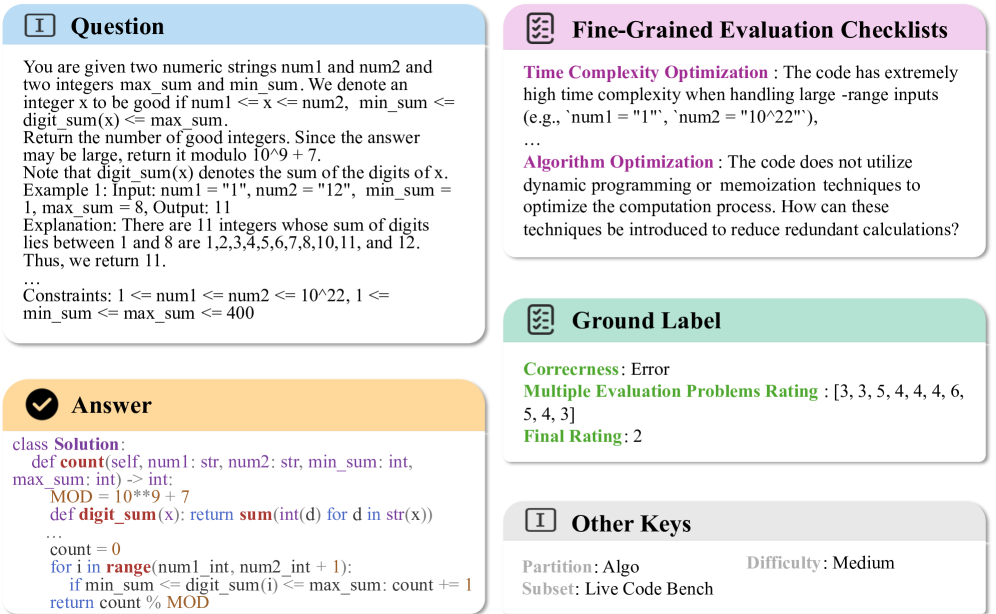
CodeCriticBench: A Holistic Code Critique Benchmark for Large Language ...
Martian Releases Largest Open-Source Benchmark for AI Code Review Agents
How to make time for code benchmarks? - CyBench
AI Code Generation Benchmarks: Accuracy and Speed Tested
The Current State of Infrastructure From Code | Ready, Set, Cloud!
LLM Benchmarks in 2024: Overview, Limits and Model Comparison
Best 11 Code Assessment Tools in 2025
Software Development Life Cycle Perspective: A Survey of Benchmarks for ...
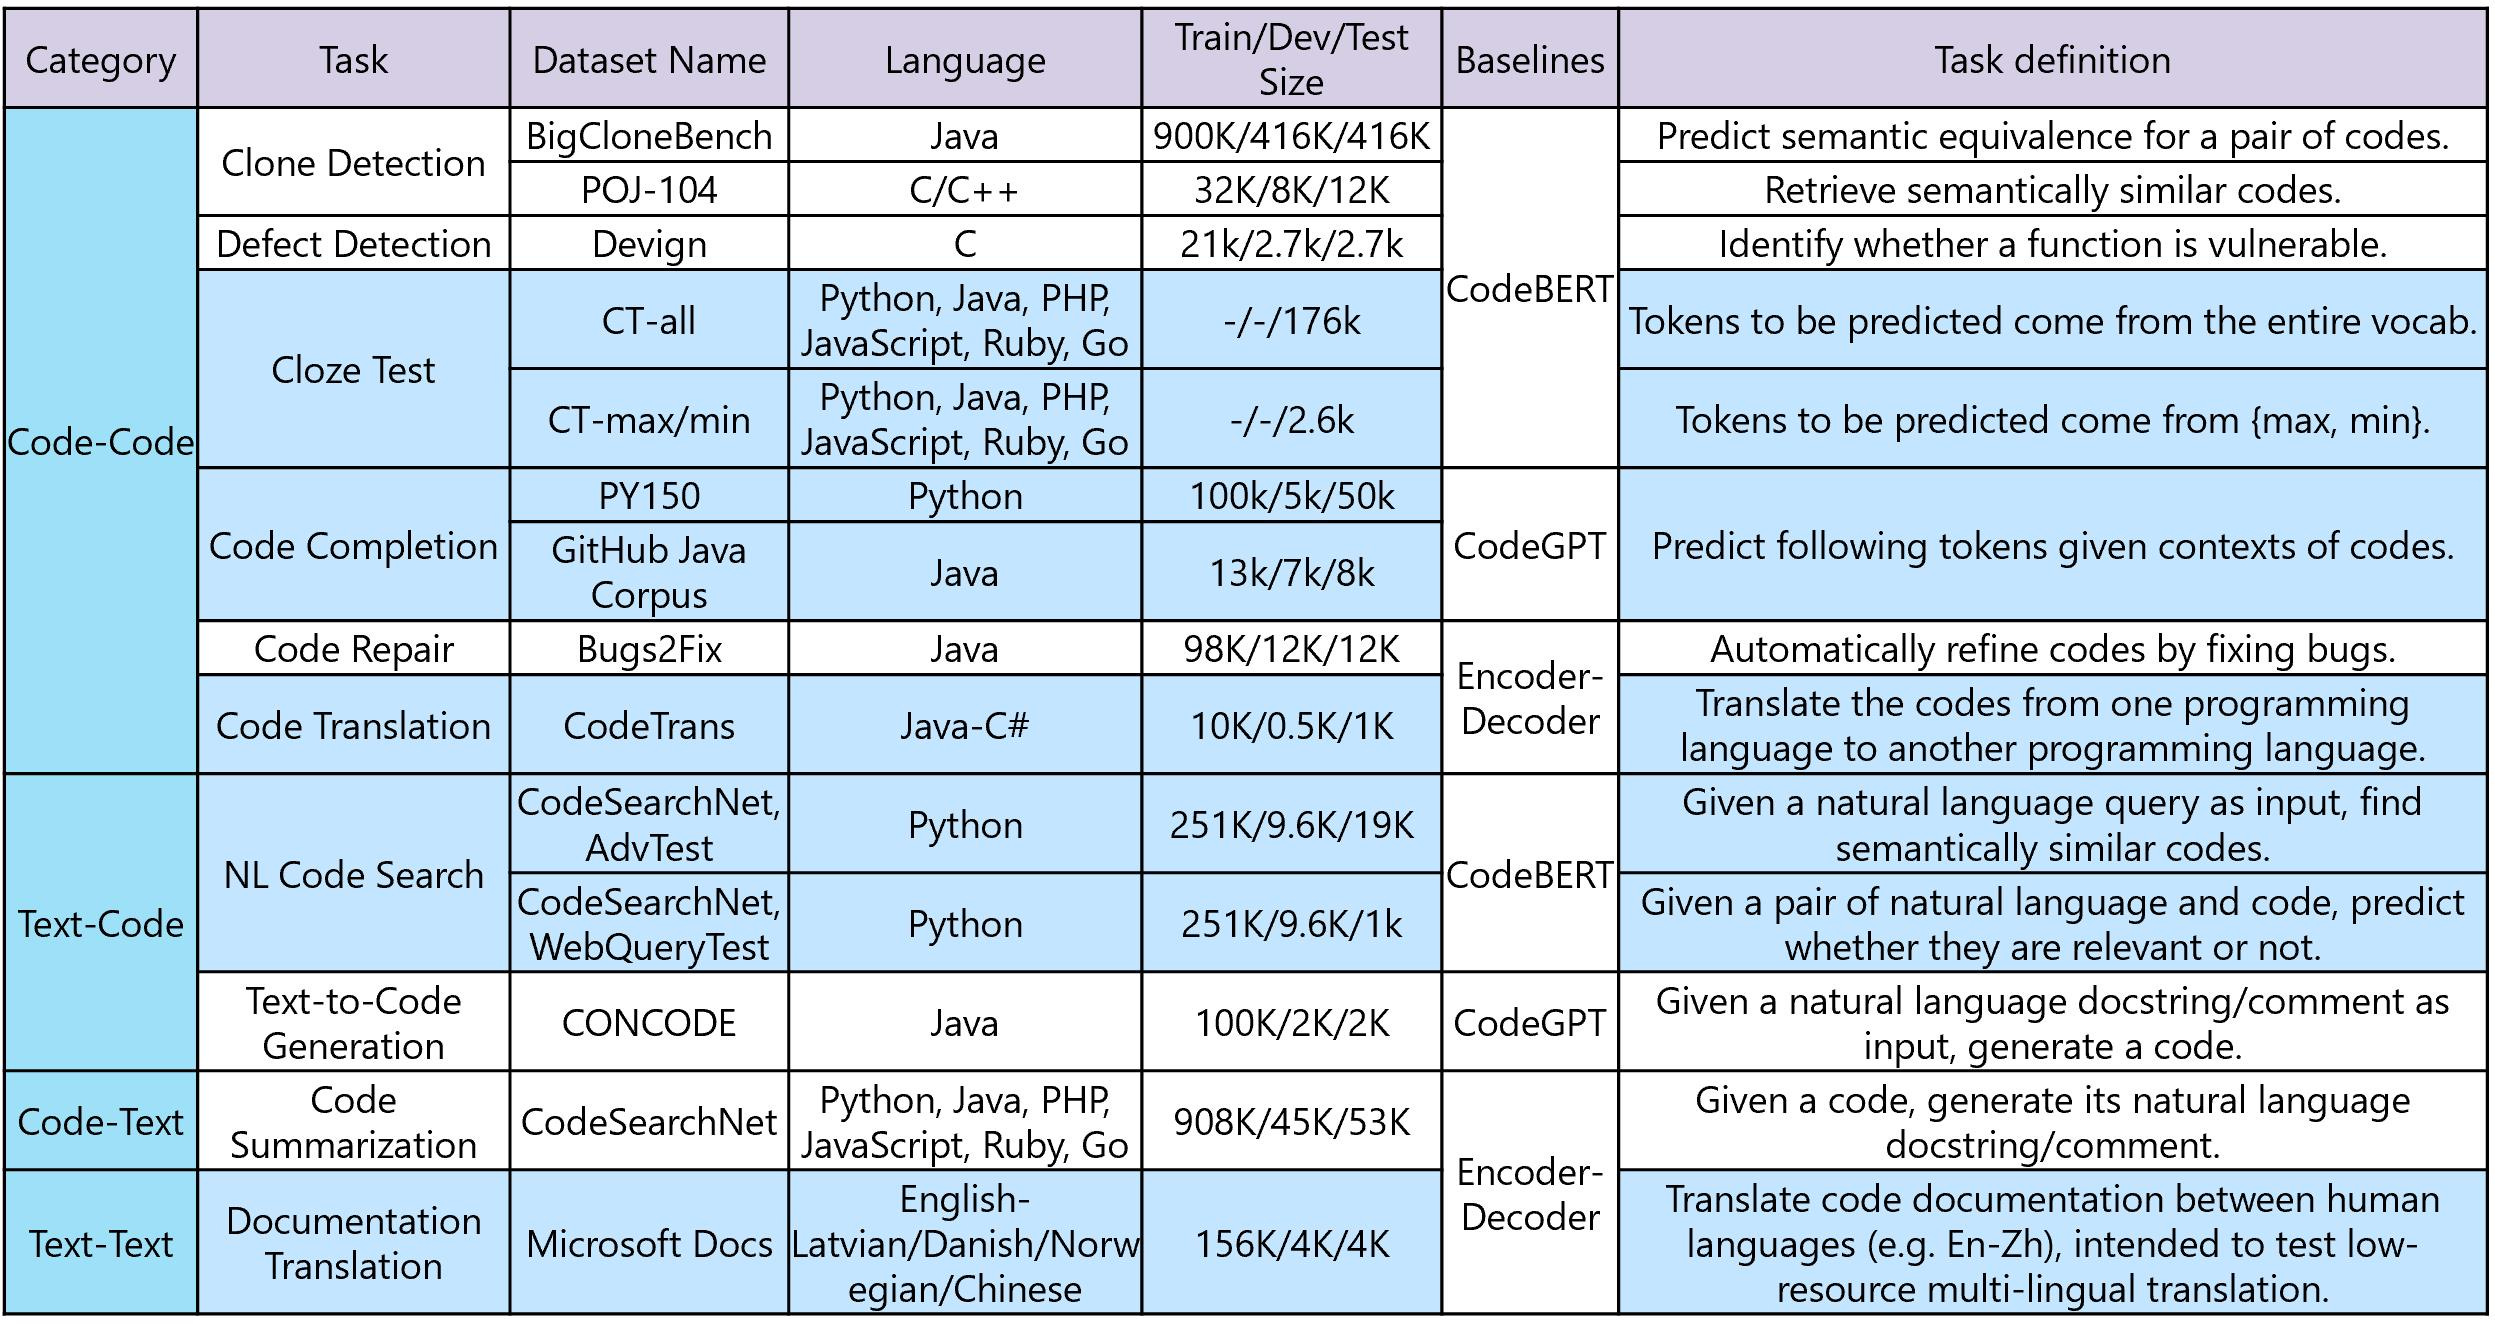
Table 1 from CodeXGLUE: A Machine Learning Benchmark Dataset for Code ...
Programming Language Performance Benchmarks – VJNT
PPT - Compiler-Based Code Partitioning for Intelligent Embedded Disk ...
VeriContest: A Competitive-Programming Benchmark for Verifiable Code ...
Is Your Benchmark (Still) Useful? Dynamic Benchmarking for Code ...
Code benchmark en C# | Néosoft
[Revisión de artículo] Automatic Generation of Benchmarks and Reliable ...
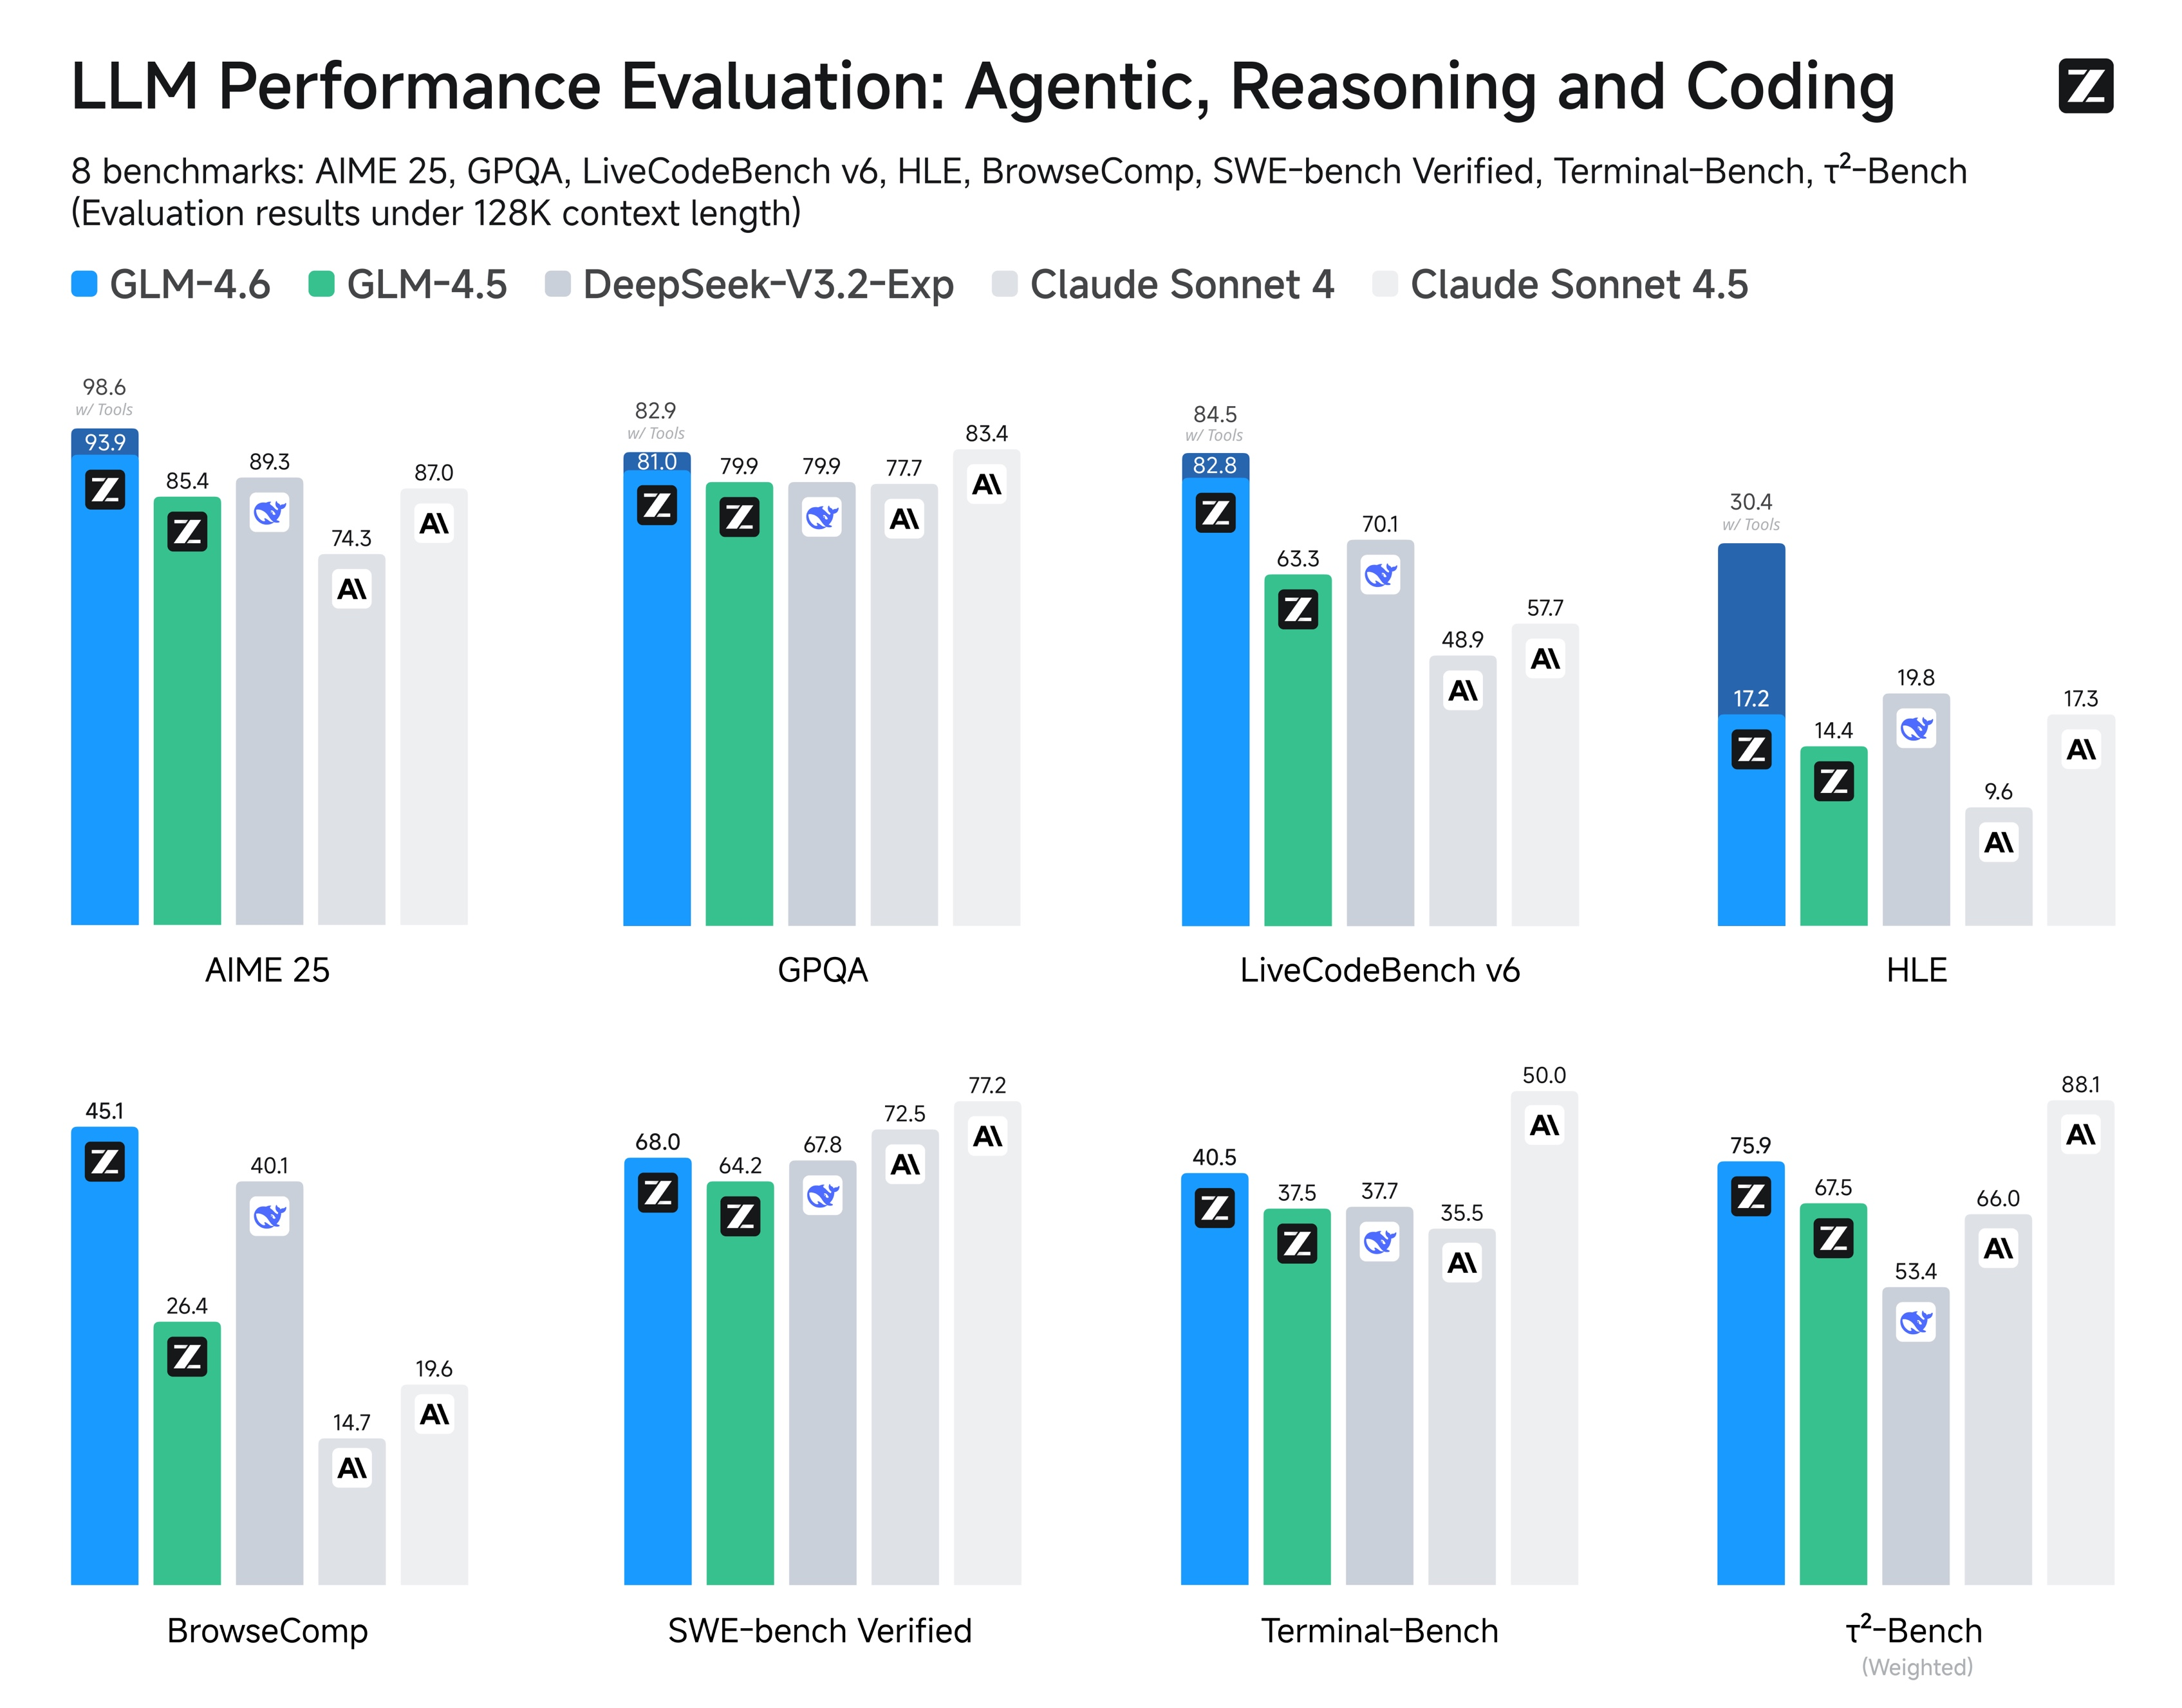
GLM-4.6: Advanced Agentic, Reasoning and Coding Capabilities
NVIDIA Llama Nemotron Ultra Open Model Delivers Groundbreaking ...
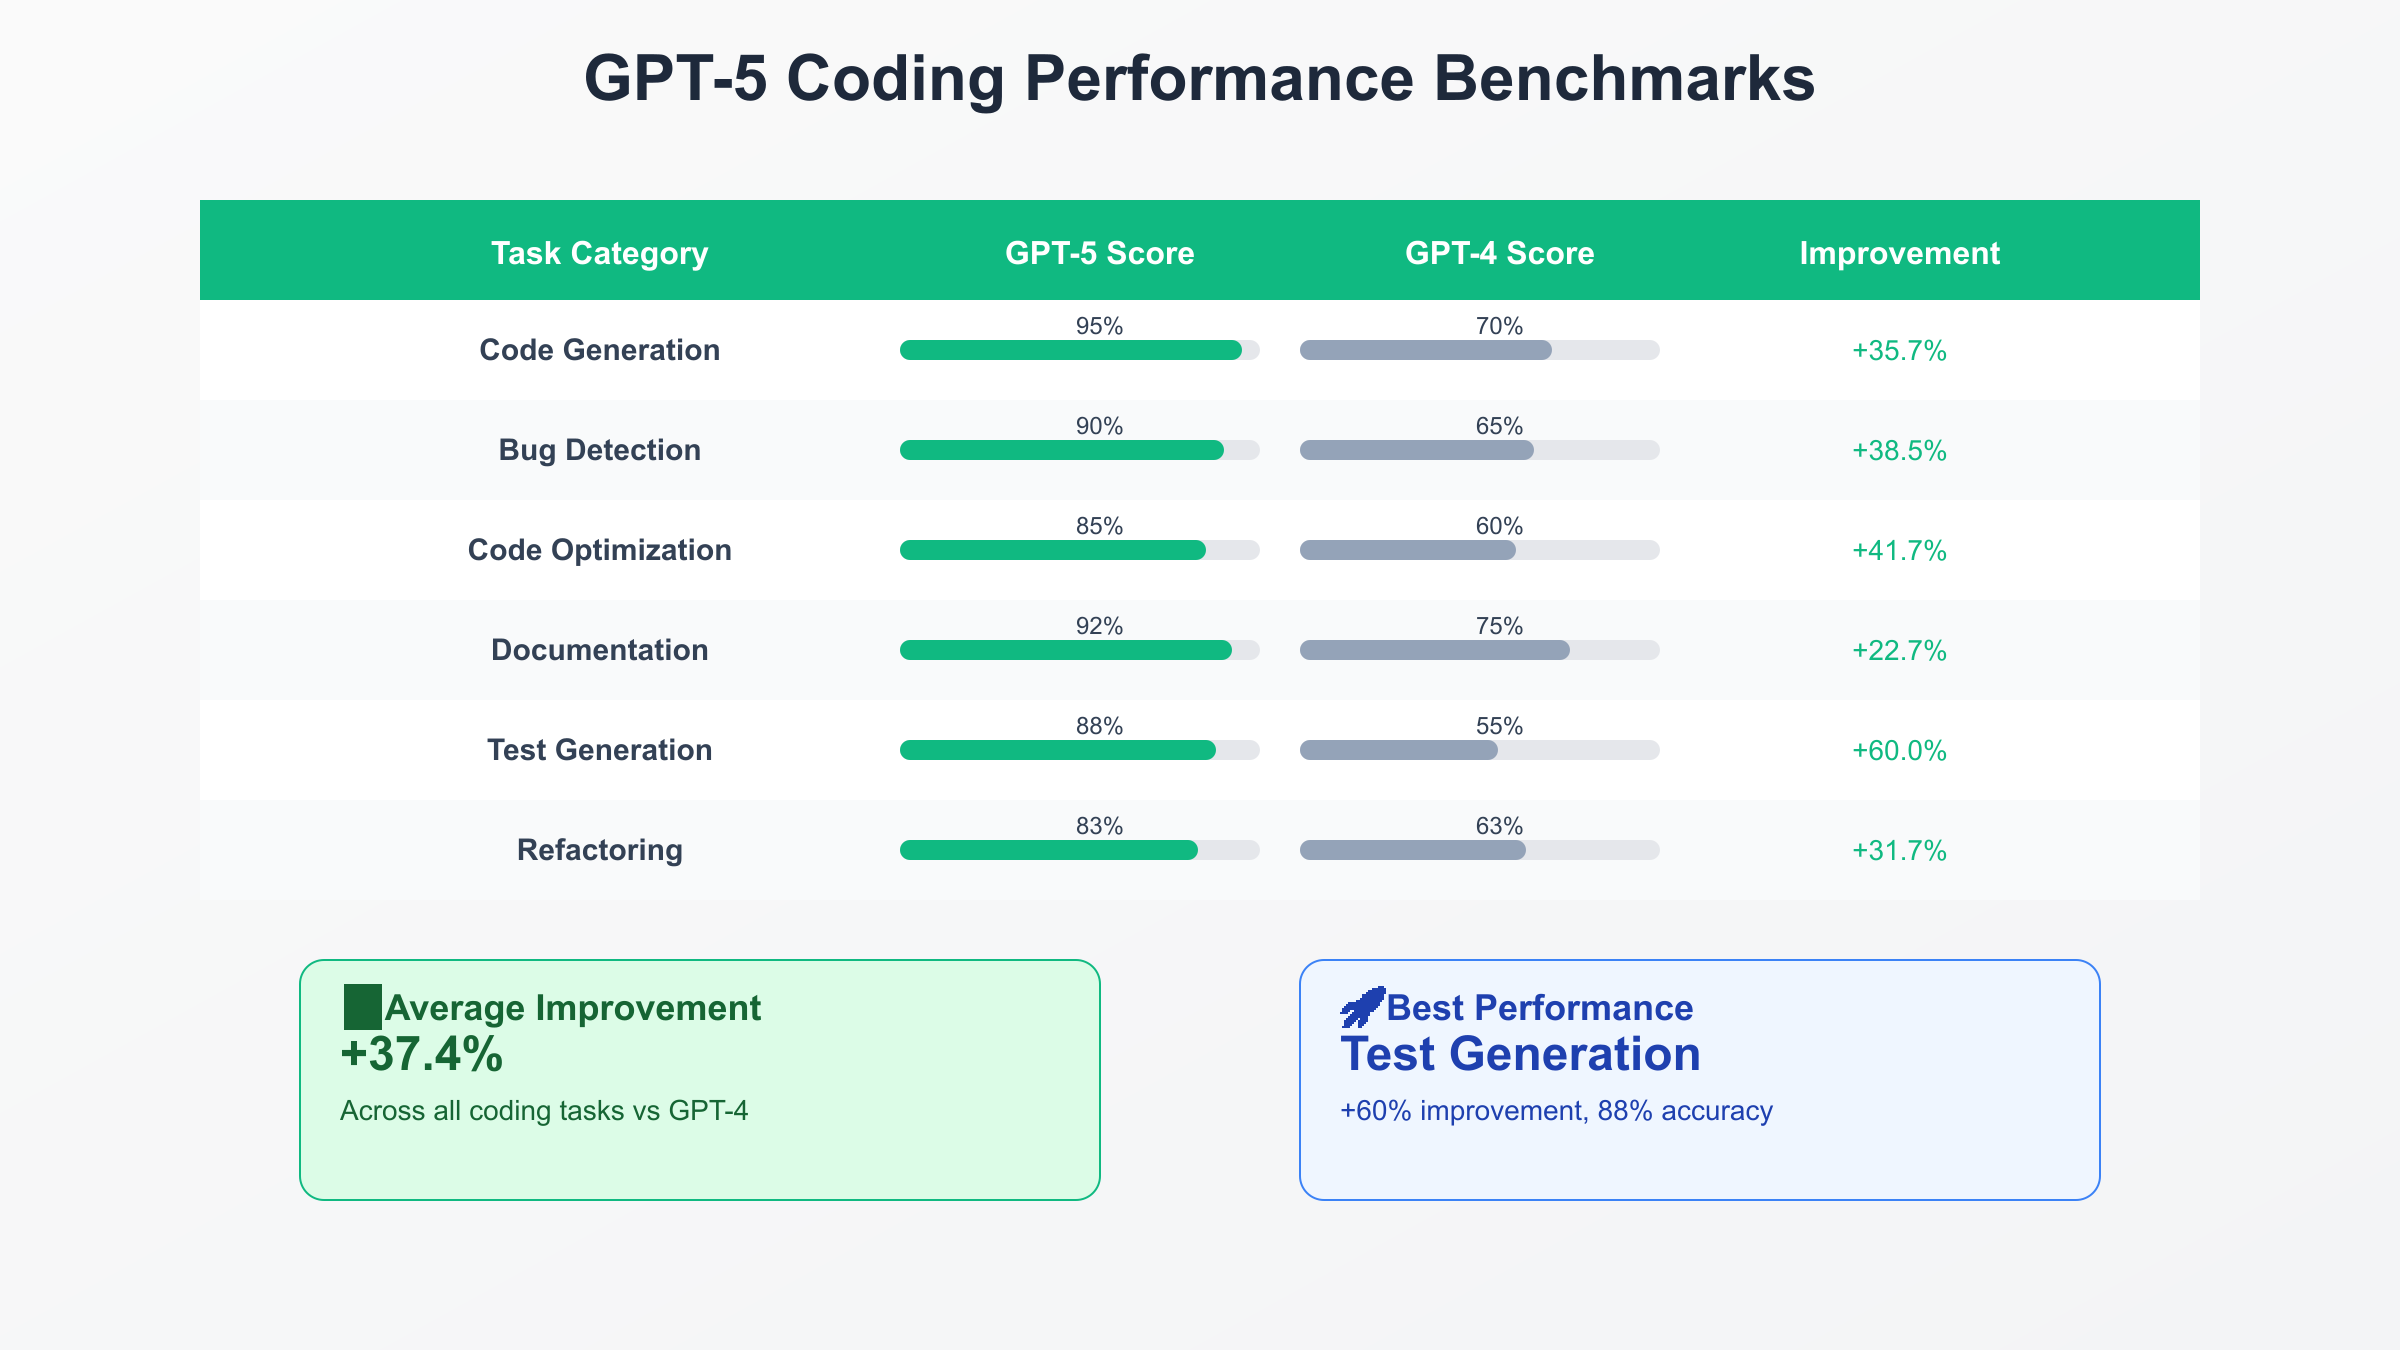
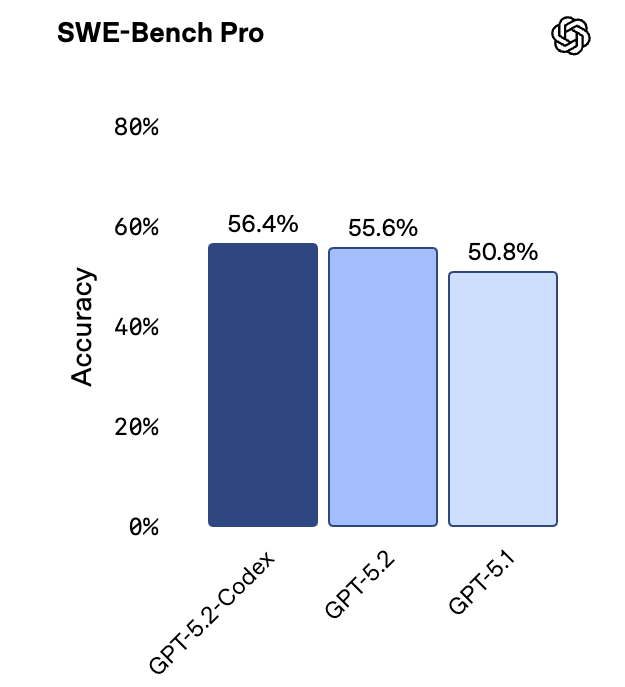
GPT-5 Coding: 74.9% SWE-bench & 88% Aider Performance [August 2025 ...
Claude vs ChatGPT vs Gemini for Coding: Real Benchmark Results
Composer 1 vs Claude 4.5: Coding Speed Benchmark - Skywork
DeepSeek V3.1 Release Overview: Performance, Pricing, and Feature ...
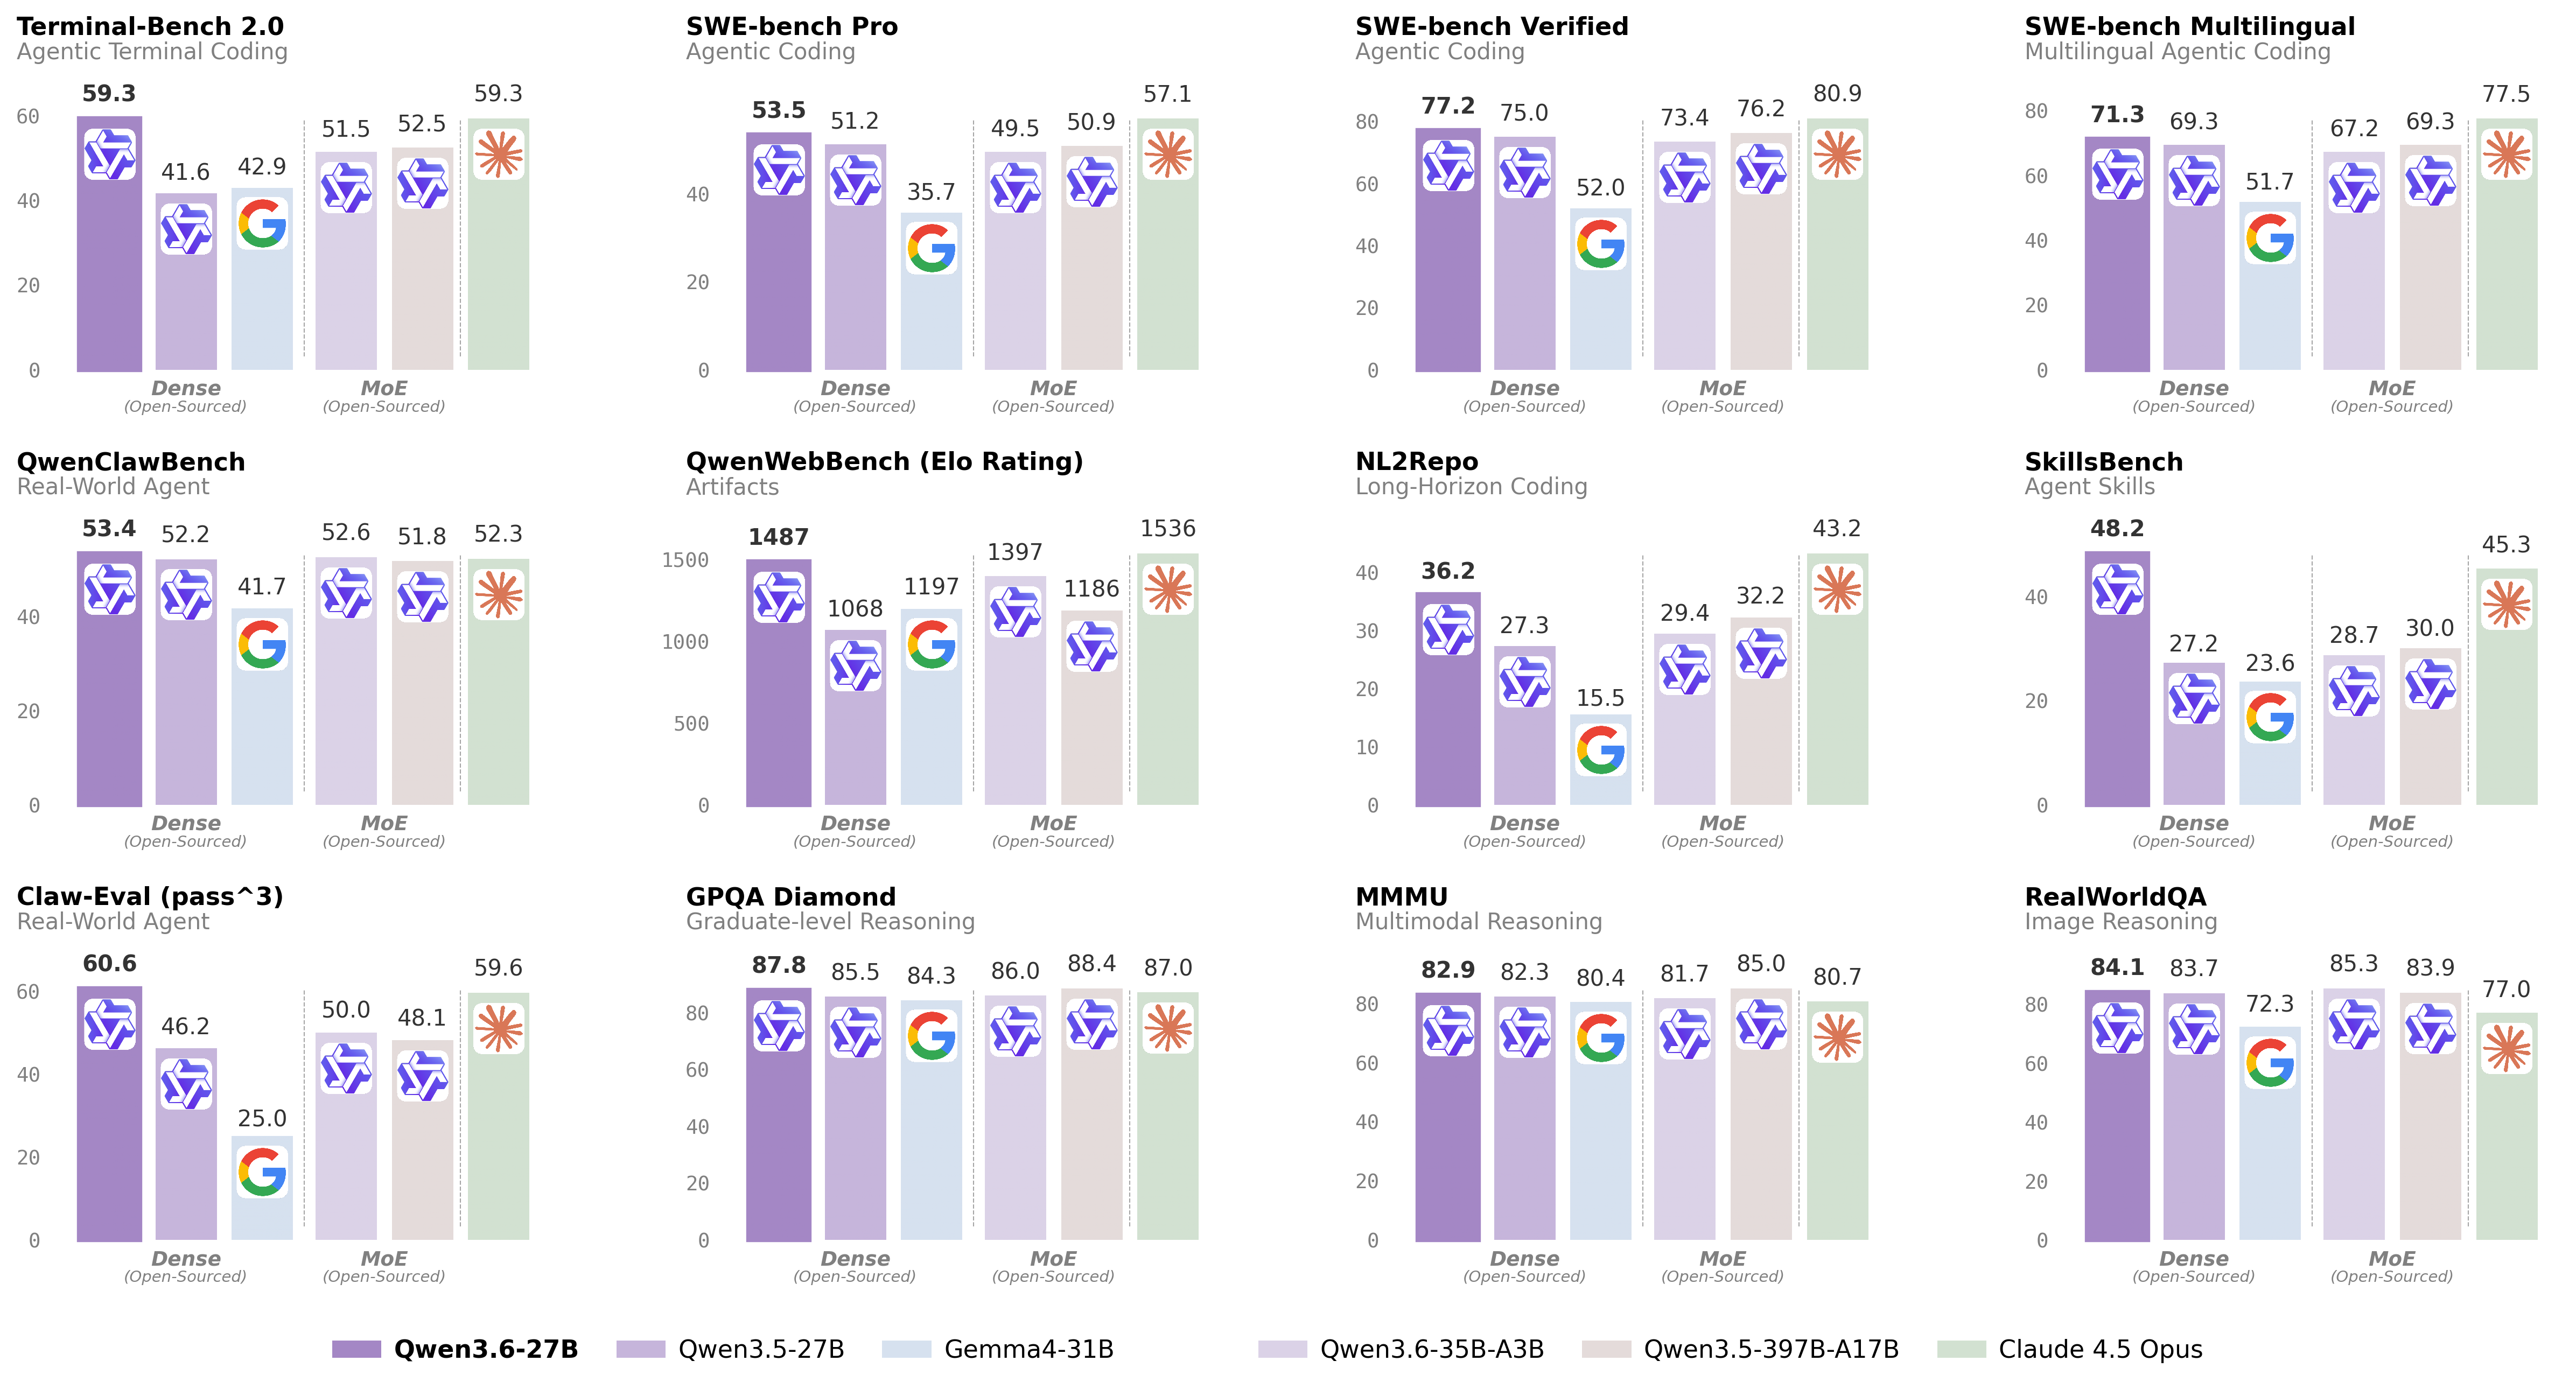
README.md · vrfai/Qwen3.6-27B-FP8 at main
Simon Willison on llm
Decoding 21 LLM Benchmarks: What You Need to Know
GitHub - Tencent-Hunyuan/AutoCodeBenchmark · GitHub
Best LLMs for coding: developer favorites
Kimi K2.6 - Agentic Coding AI | 12-Hour Runs | 300-Agent Swarms
GPT-5 High Reasoning Evaluation: A Major Leap in Coding Performance
Toward Generalizable Evaluation in the LLM Era: A Survey Beyond ...
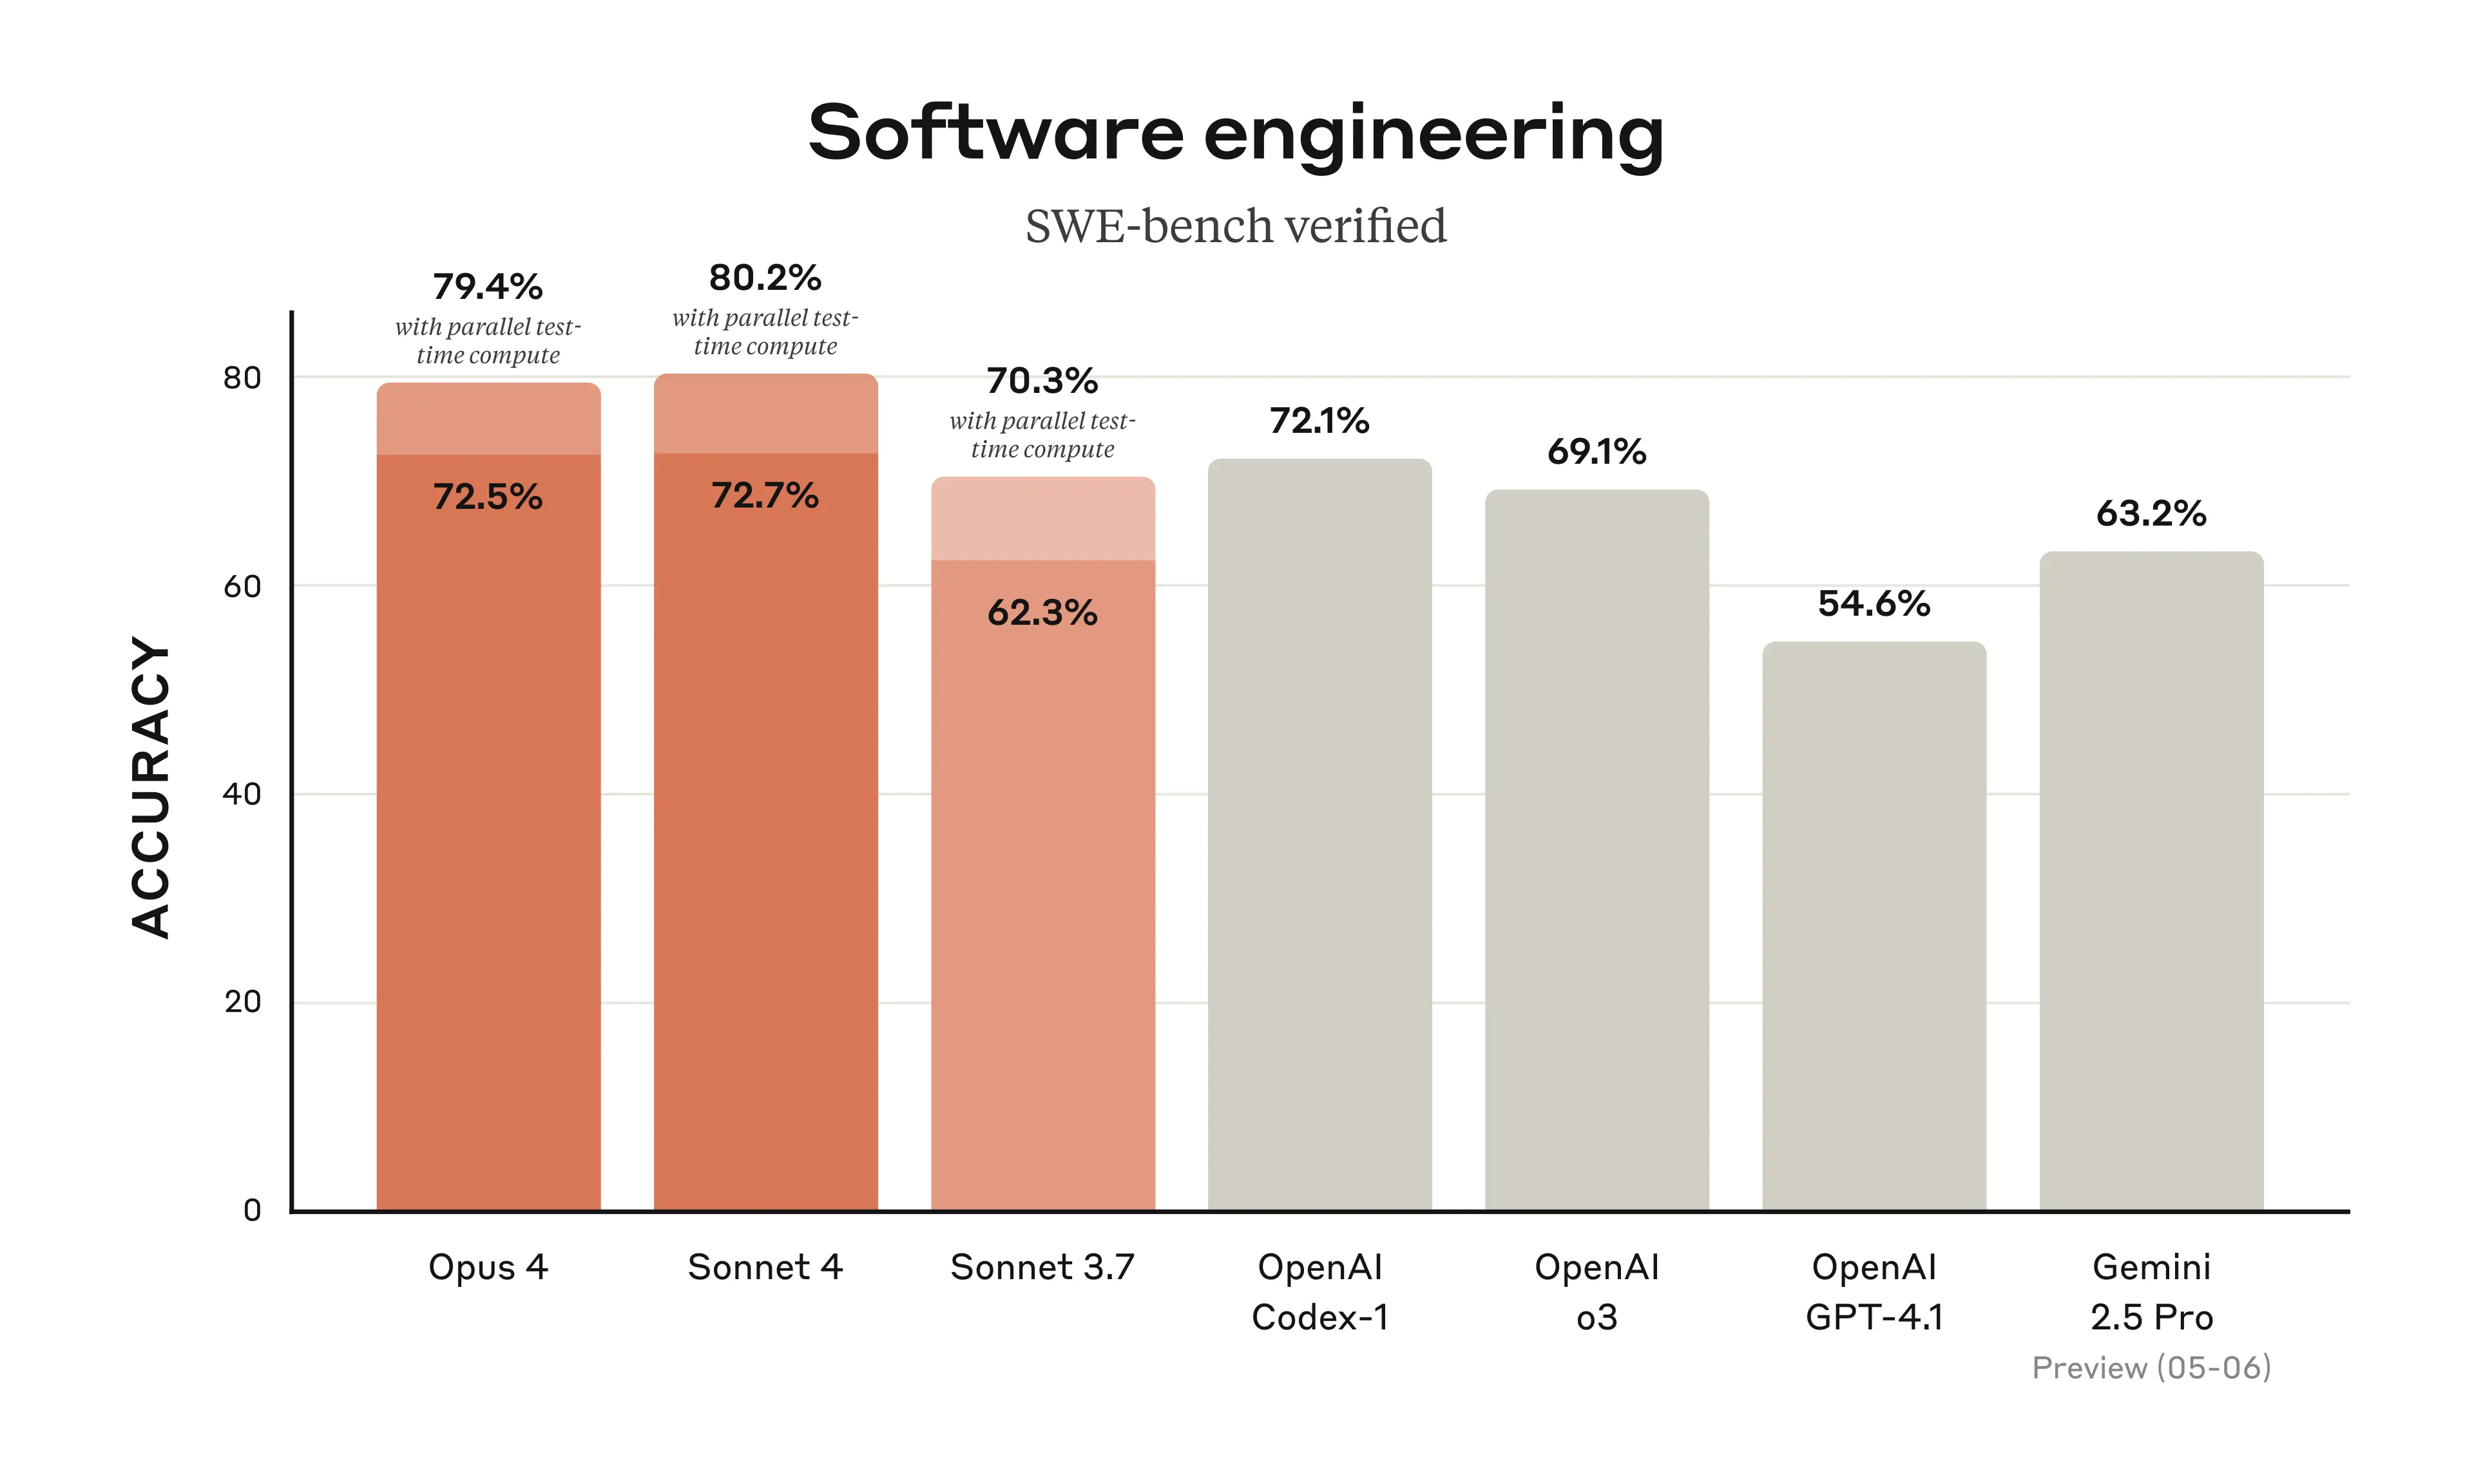
Thread by @AnthropicAI on Thread Reader App – Thread Reader App
Introducing Claude 4 \ Anthropic
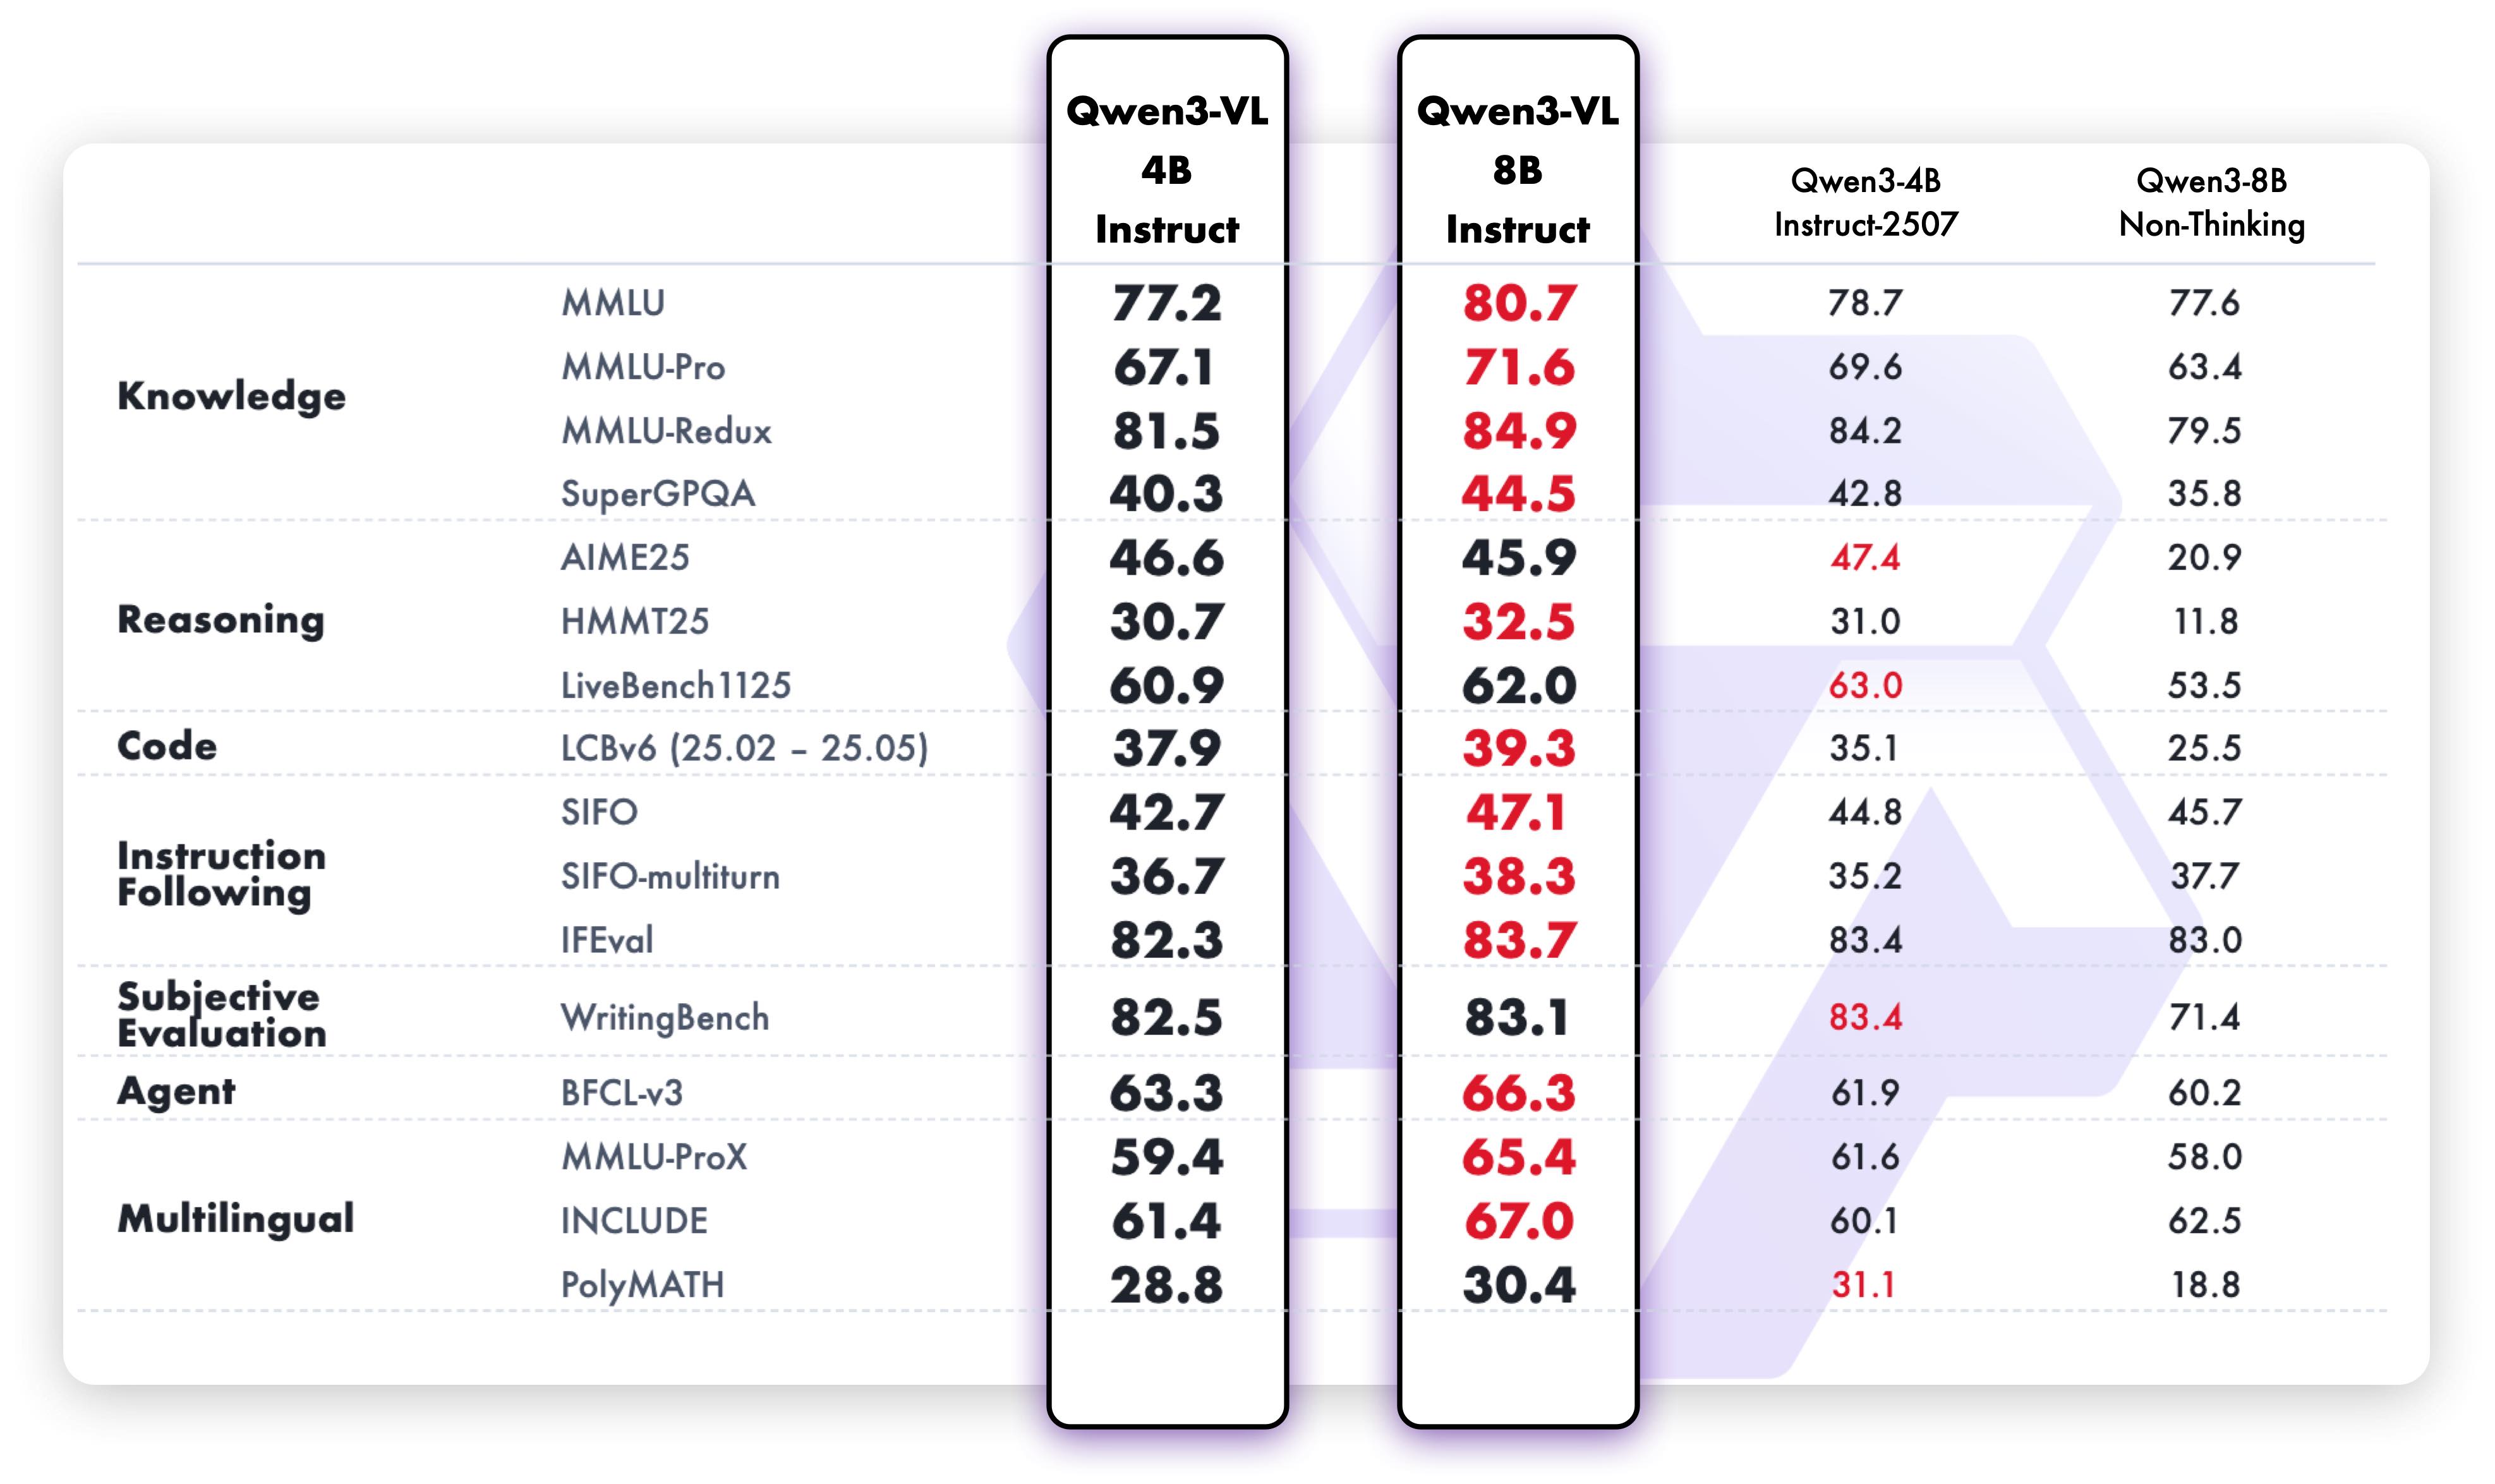
coder3101/Qwen3-VL-4B-Instruct-heretic · Hugging Face
Docs | Benchmark
qwen2.5-coder:1.5b-base
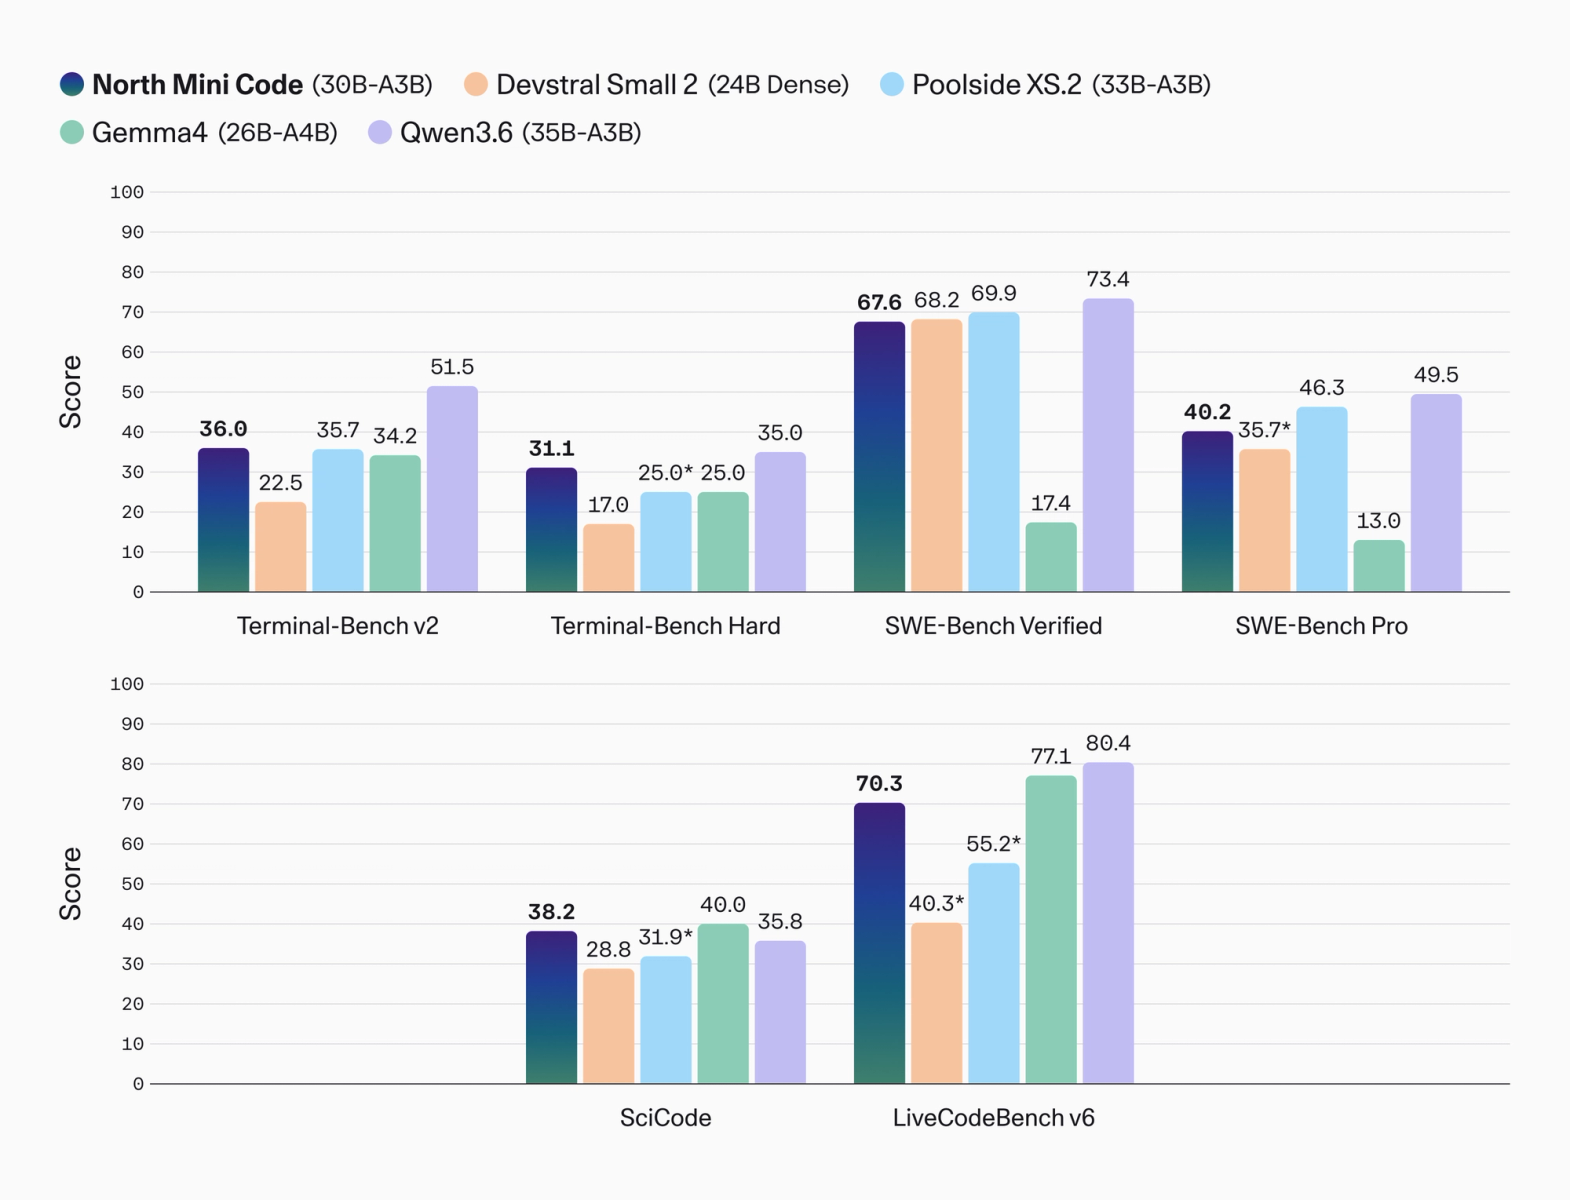
North Mini Code: Agentic Coding for Developers | Cohere
We are not evaluating AI coding agents the way they are actually used ...
NCISurvey
benchmark怎么测试c语言,使用CodeBenchmark对逻辑代码进行并发测试-CSDN博客
Top 10 Benefits of Using Grok-1 Technology
speed comparison of various programming languages, Julia (AOT) is on ...
A Scalable and Extensible Approach to Benchmarking NL2Code for 18 ...
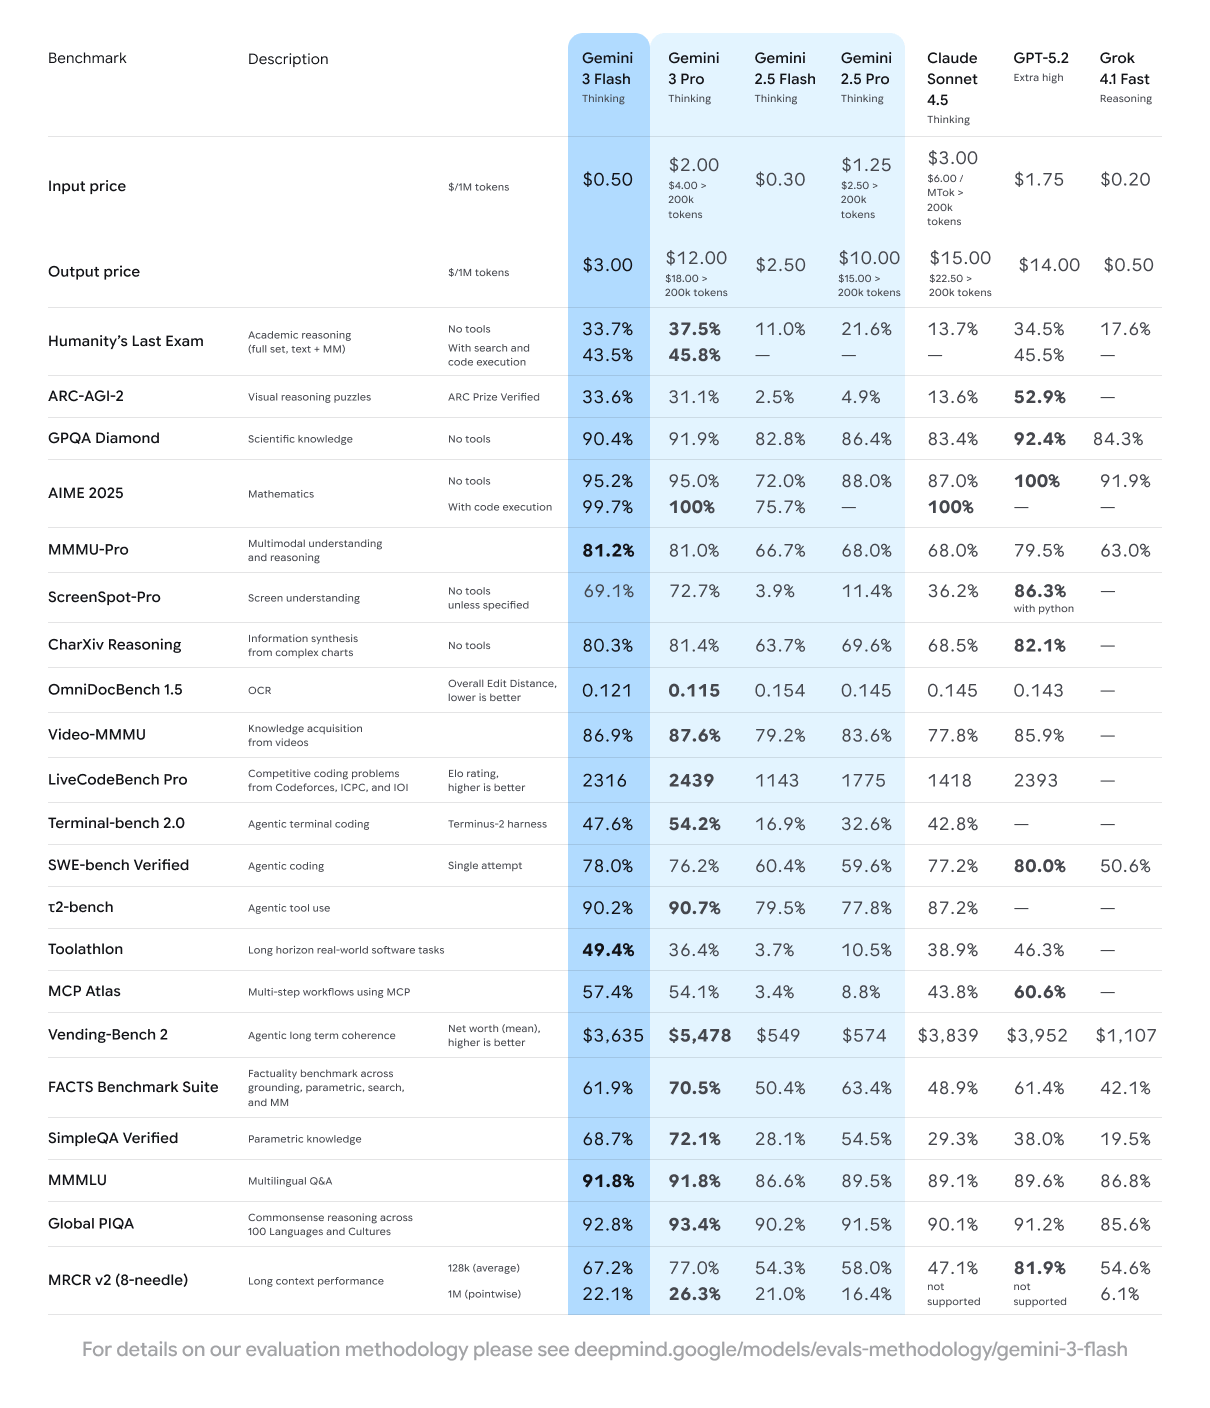
Google's New AI Just Killed the Speed vs. Intelligence Trade-Off ...
The Developer’s Dilemma: GitHub Copilot vs. Cursor — Which AI Coding ...
qwen2.5-coder
Anthropic Releases Claude Opus 4.5, Beats Gemini 3.0 On Coding, Agentic ...
Js Framework Benchmark at Michelle Ma blog
What are LLM Benchmarks?
Announcing UA-Code-Bench: a New Benchmark for Evaluating LLMs on ...
Qwen Researchers Introduce CodeElo: An AI Benchmark Designed to ...
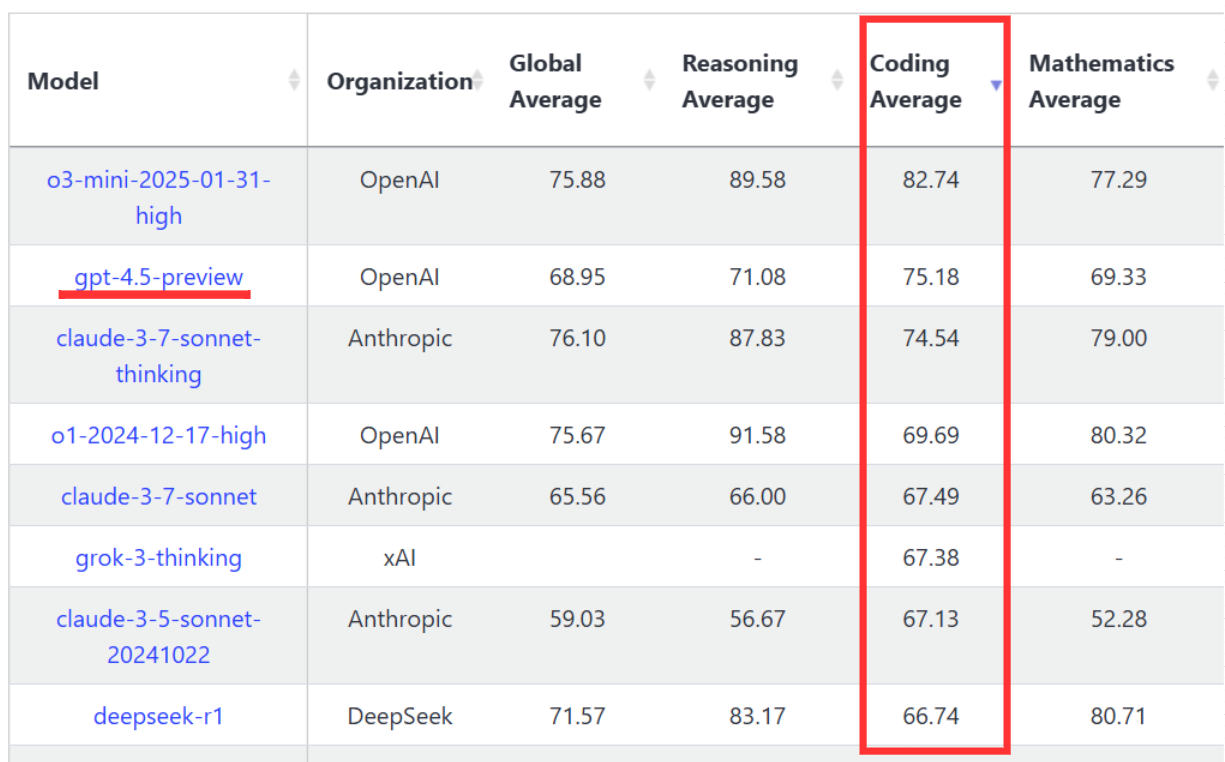
大模型代码编程能力评测排行榜 | DataLearnerAI
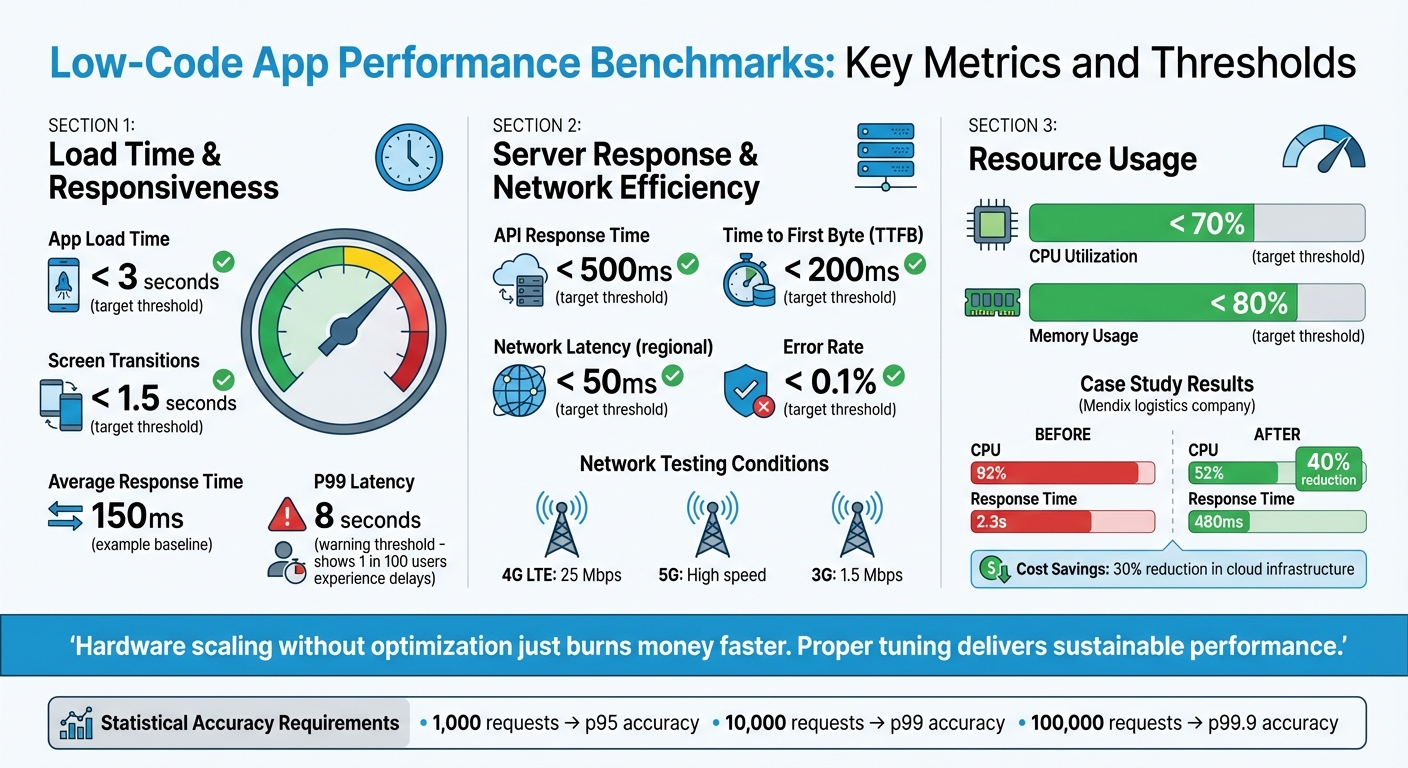
Ultimate Guide to Low-Code Performance Benchmarking
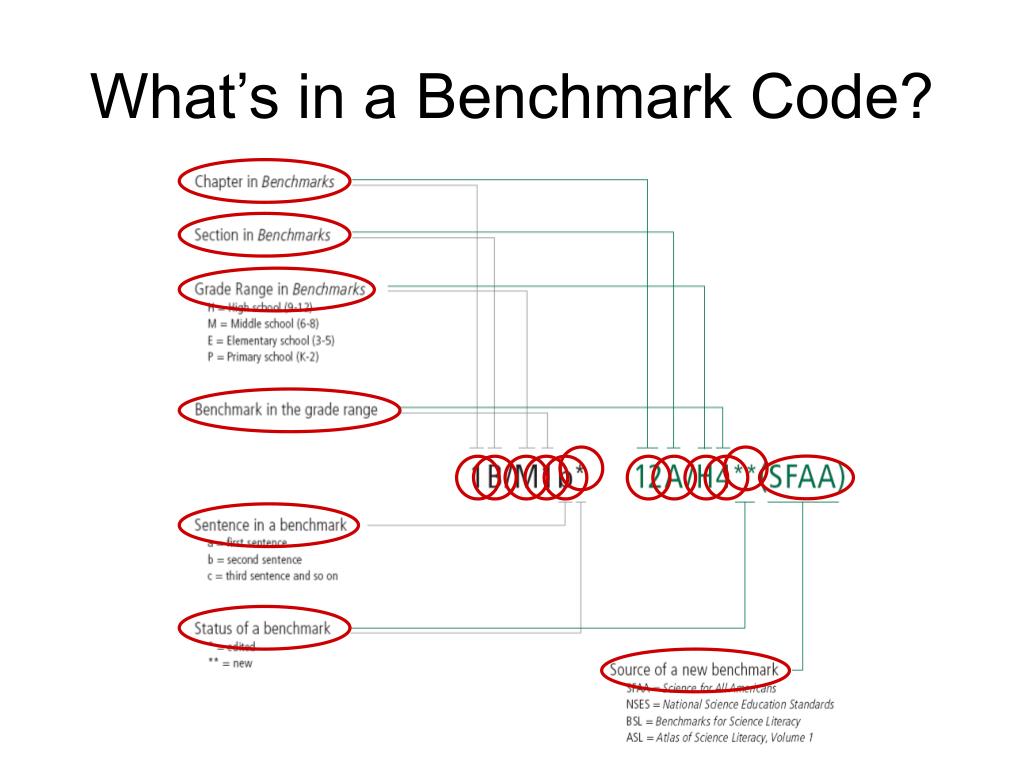
PPT - Atlas of Science Literacy PowerPoint Presentation, free download ...
Coding Productivity Benchmarks: Industry-Wide 2025 Report — AMBCI
Programming Rants: TechEmpower Framework Benchmark Round 14
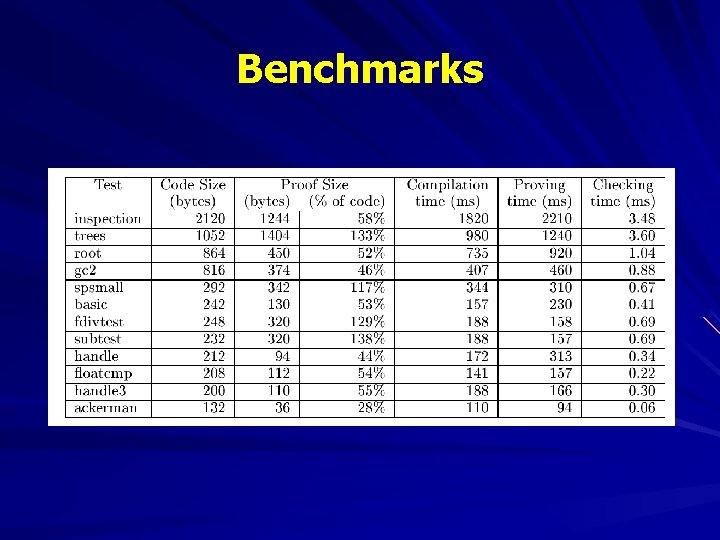
The Design and Implementation of a Certifying Compiler
The most common "Benchmarks and Controls" coding references. | Download ...
Metric Calculating Benchmark: Code-Verifiable Complicate Instruction ...
Deterministic Coding Benchmark - My Results (Codeneedle) - DGX Spark ...
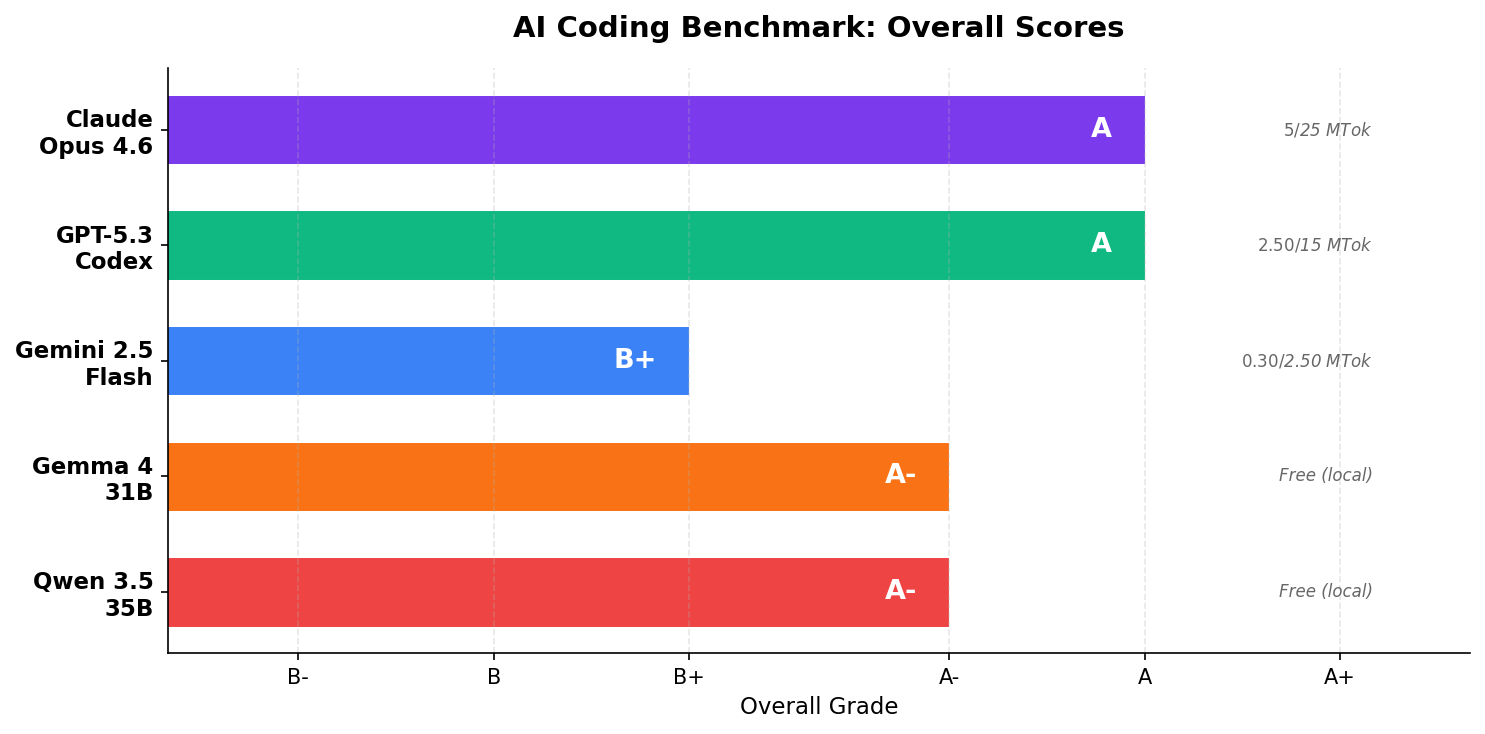
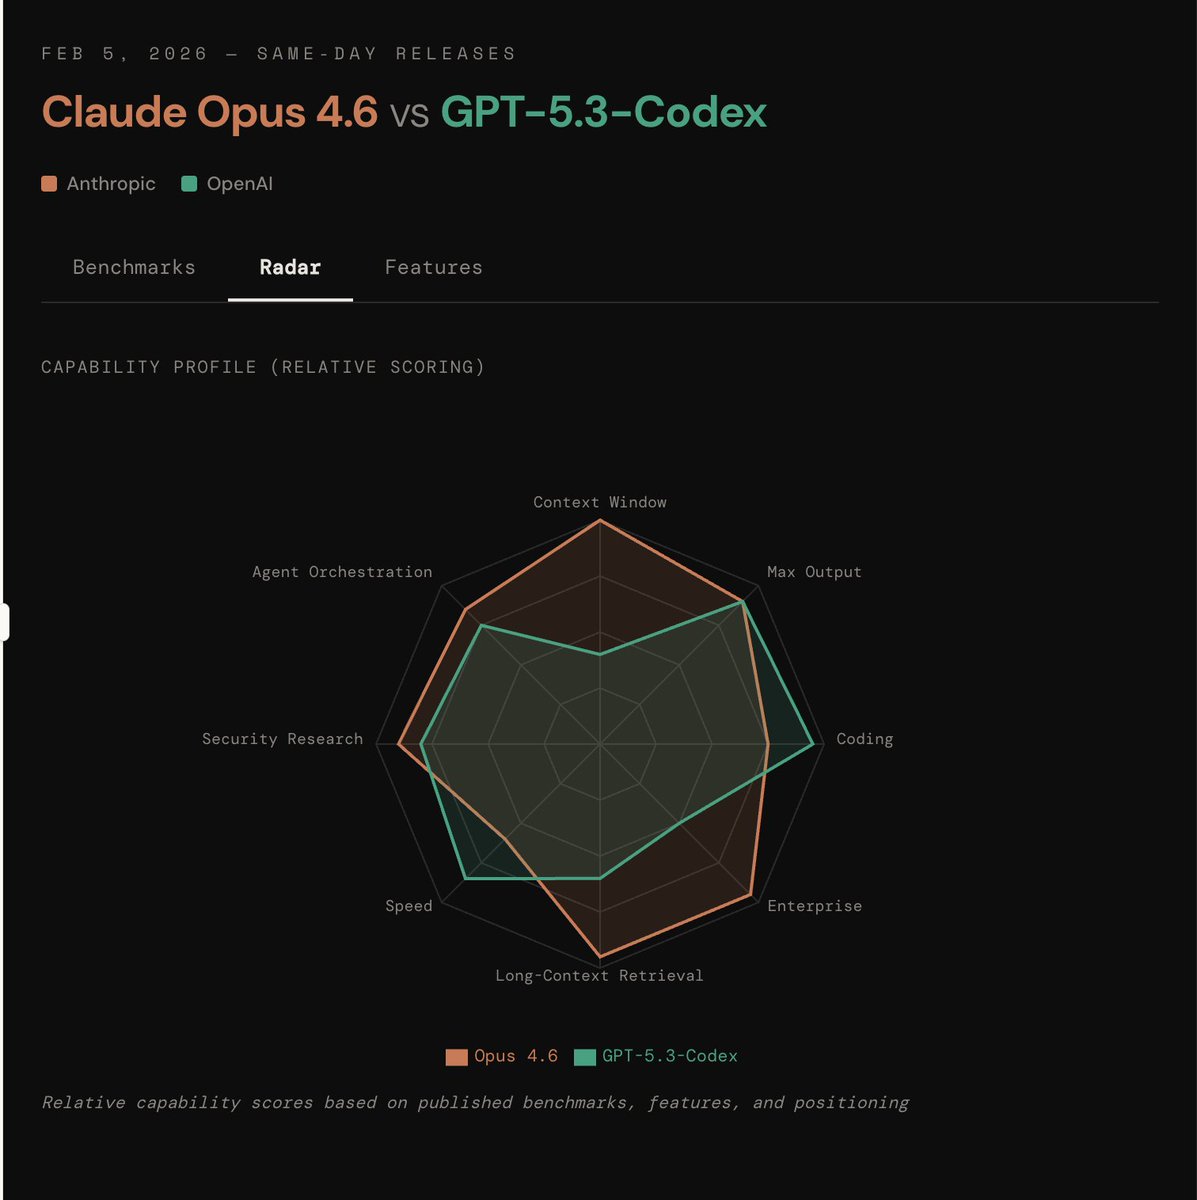
Codex 5.3 vs Opus 4.6 tldr; opus 4.6: + 1M context + enterprise ...
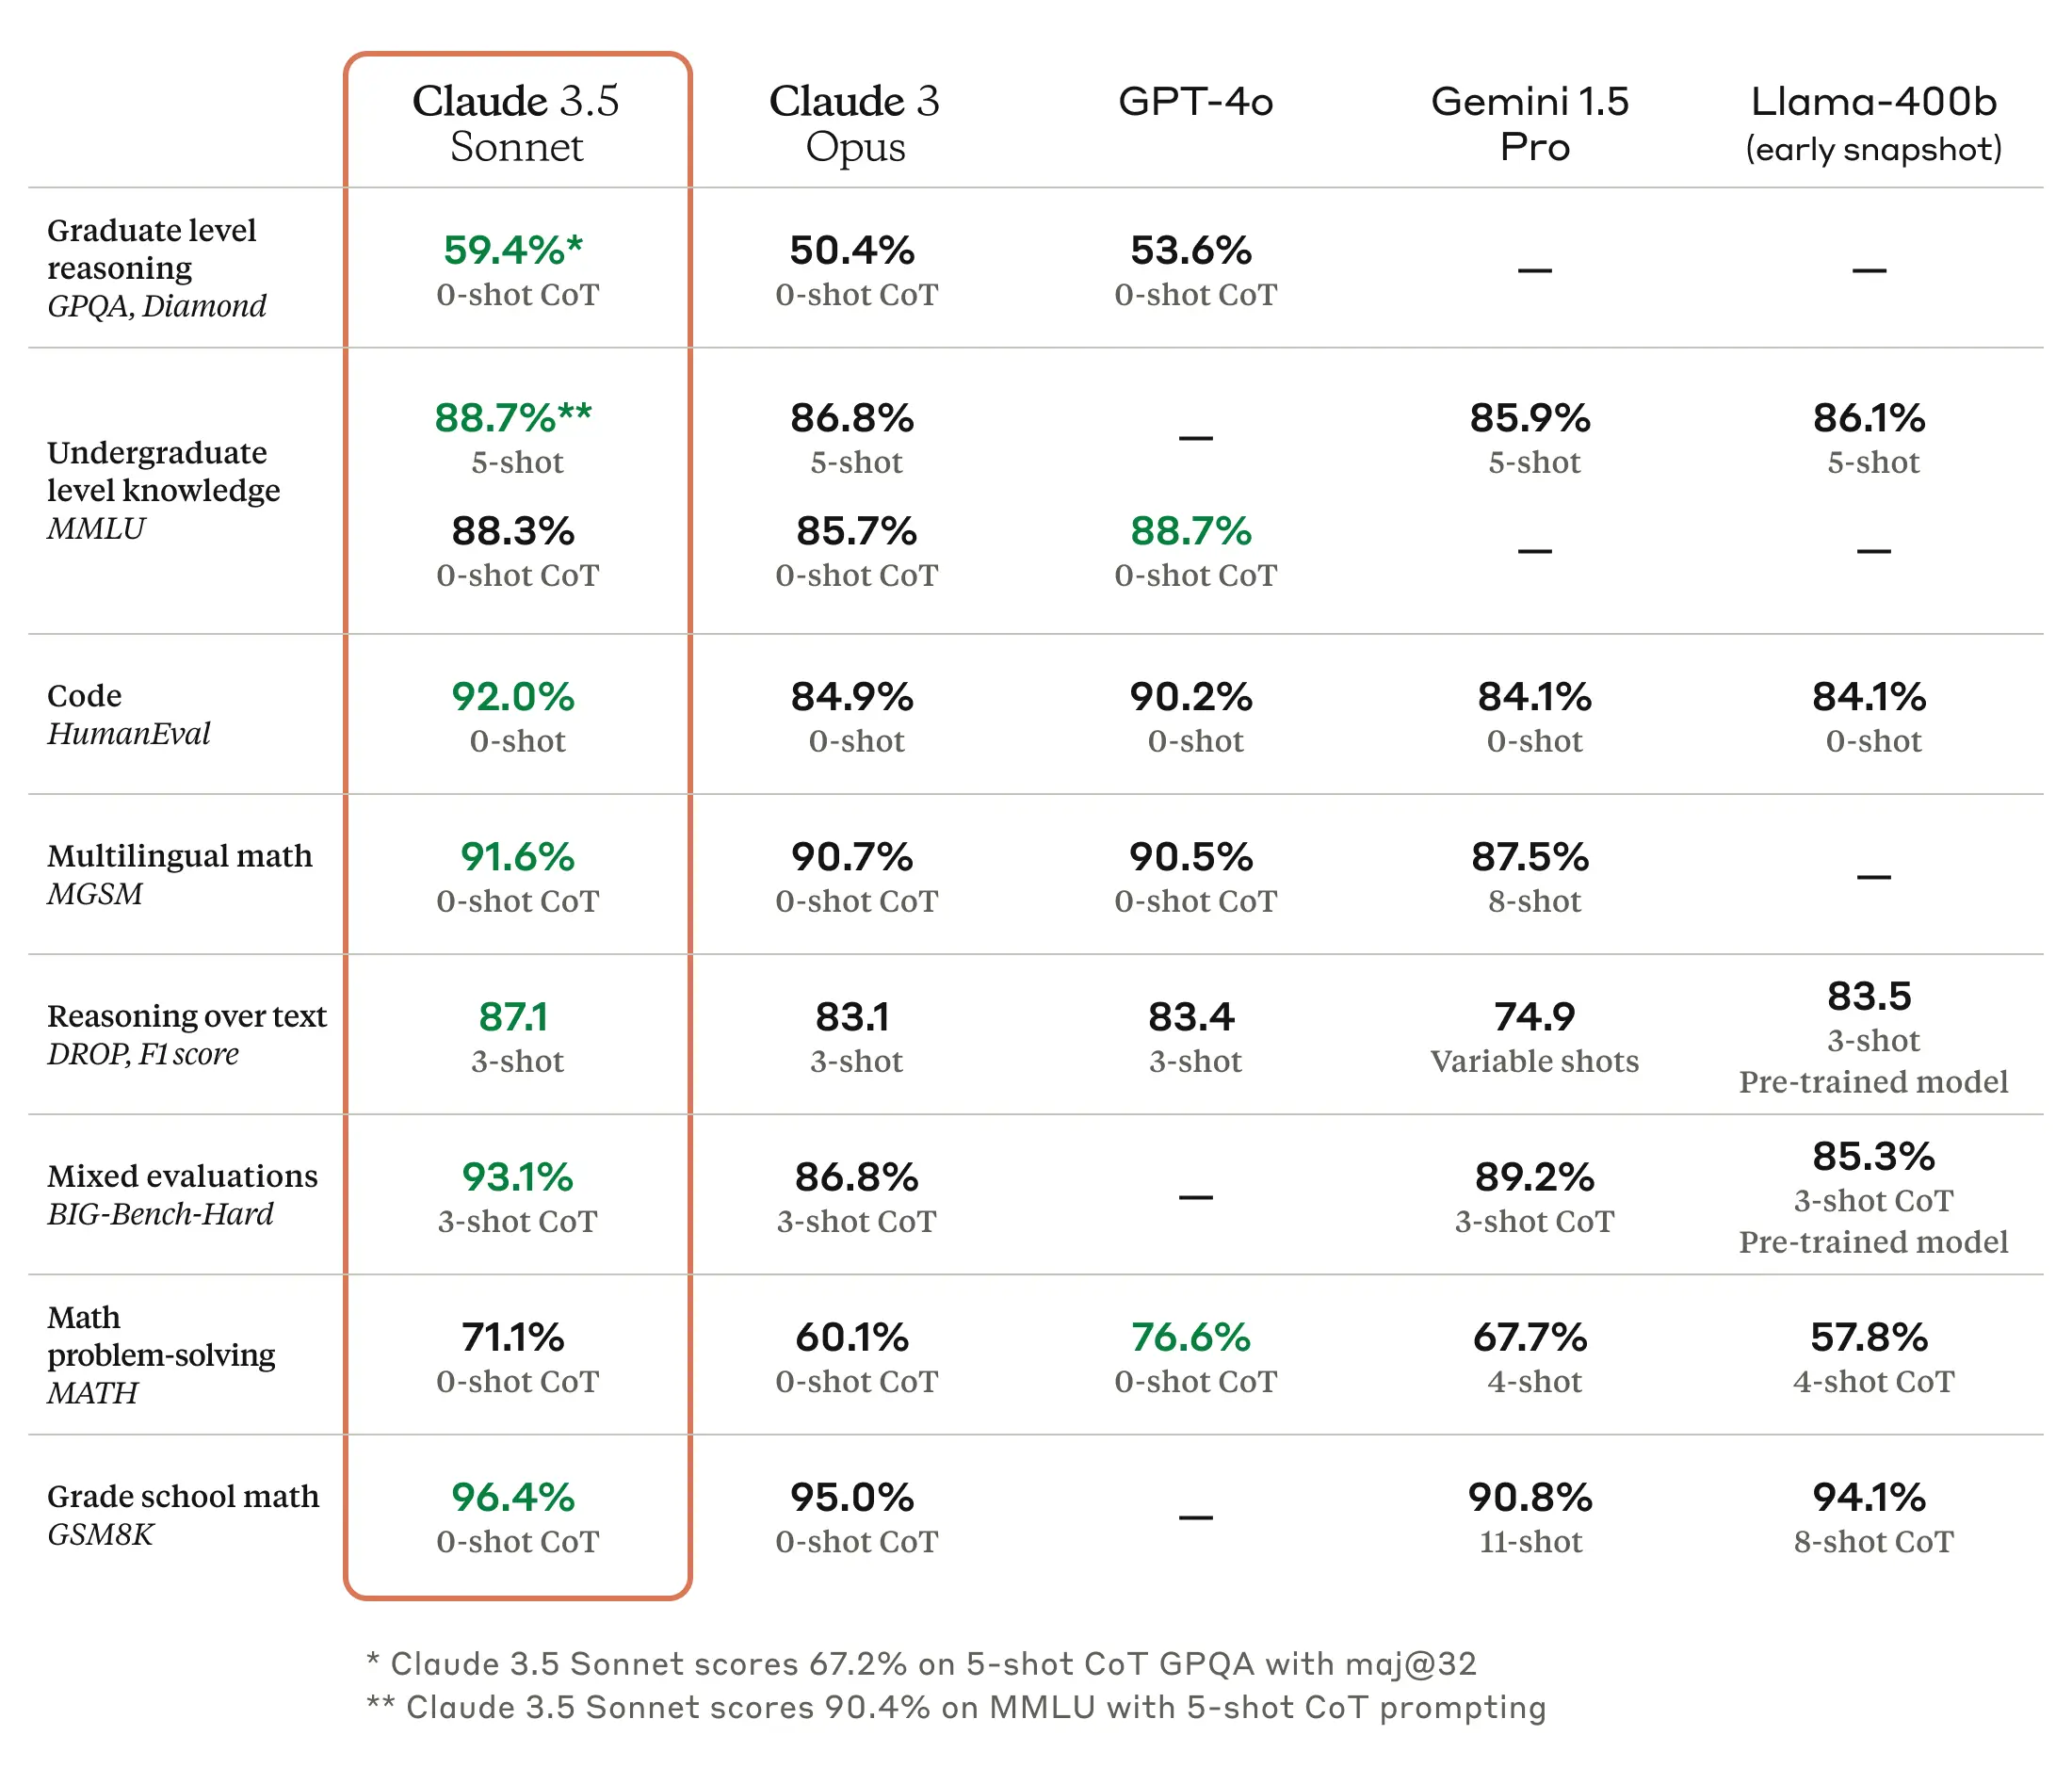
Claude 3.5 sets new AI benchmarks, beating GPT-4o in coding and ...
Barcode Benchmark Index | Dynamsoft Barcode Reader Tutorial
How to Create Your Own Coding Benchmark to Test the Quality of ...
FrontierCode: AI Coding Benchmark Goes Beyond Corre… | StartupHub.ai
unsloth/North-Mini-Code-1.0 · Hugging Face
How to Fix Claude "Error sending code. Double check your phone number ...
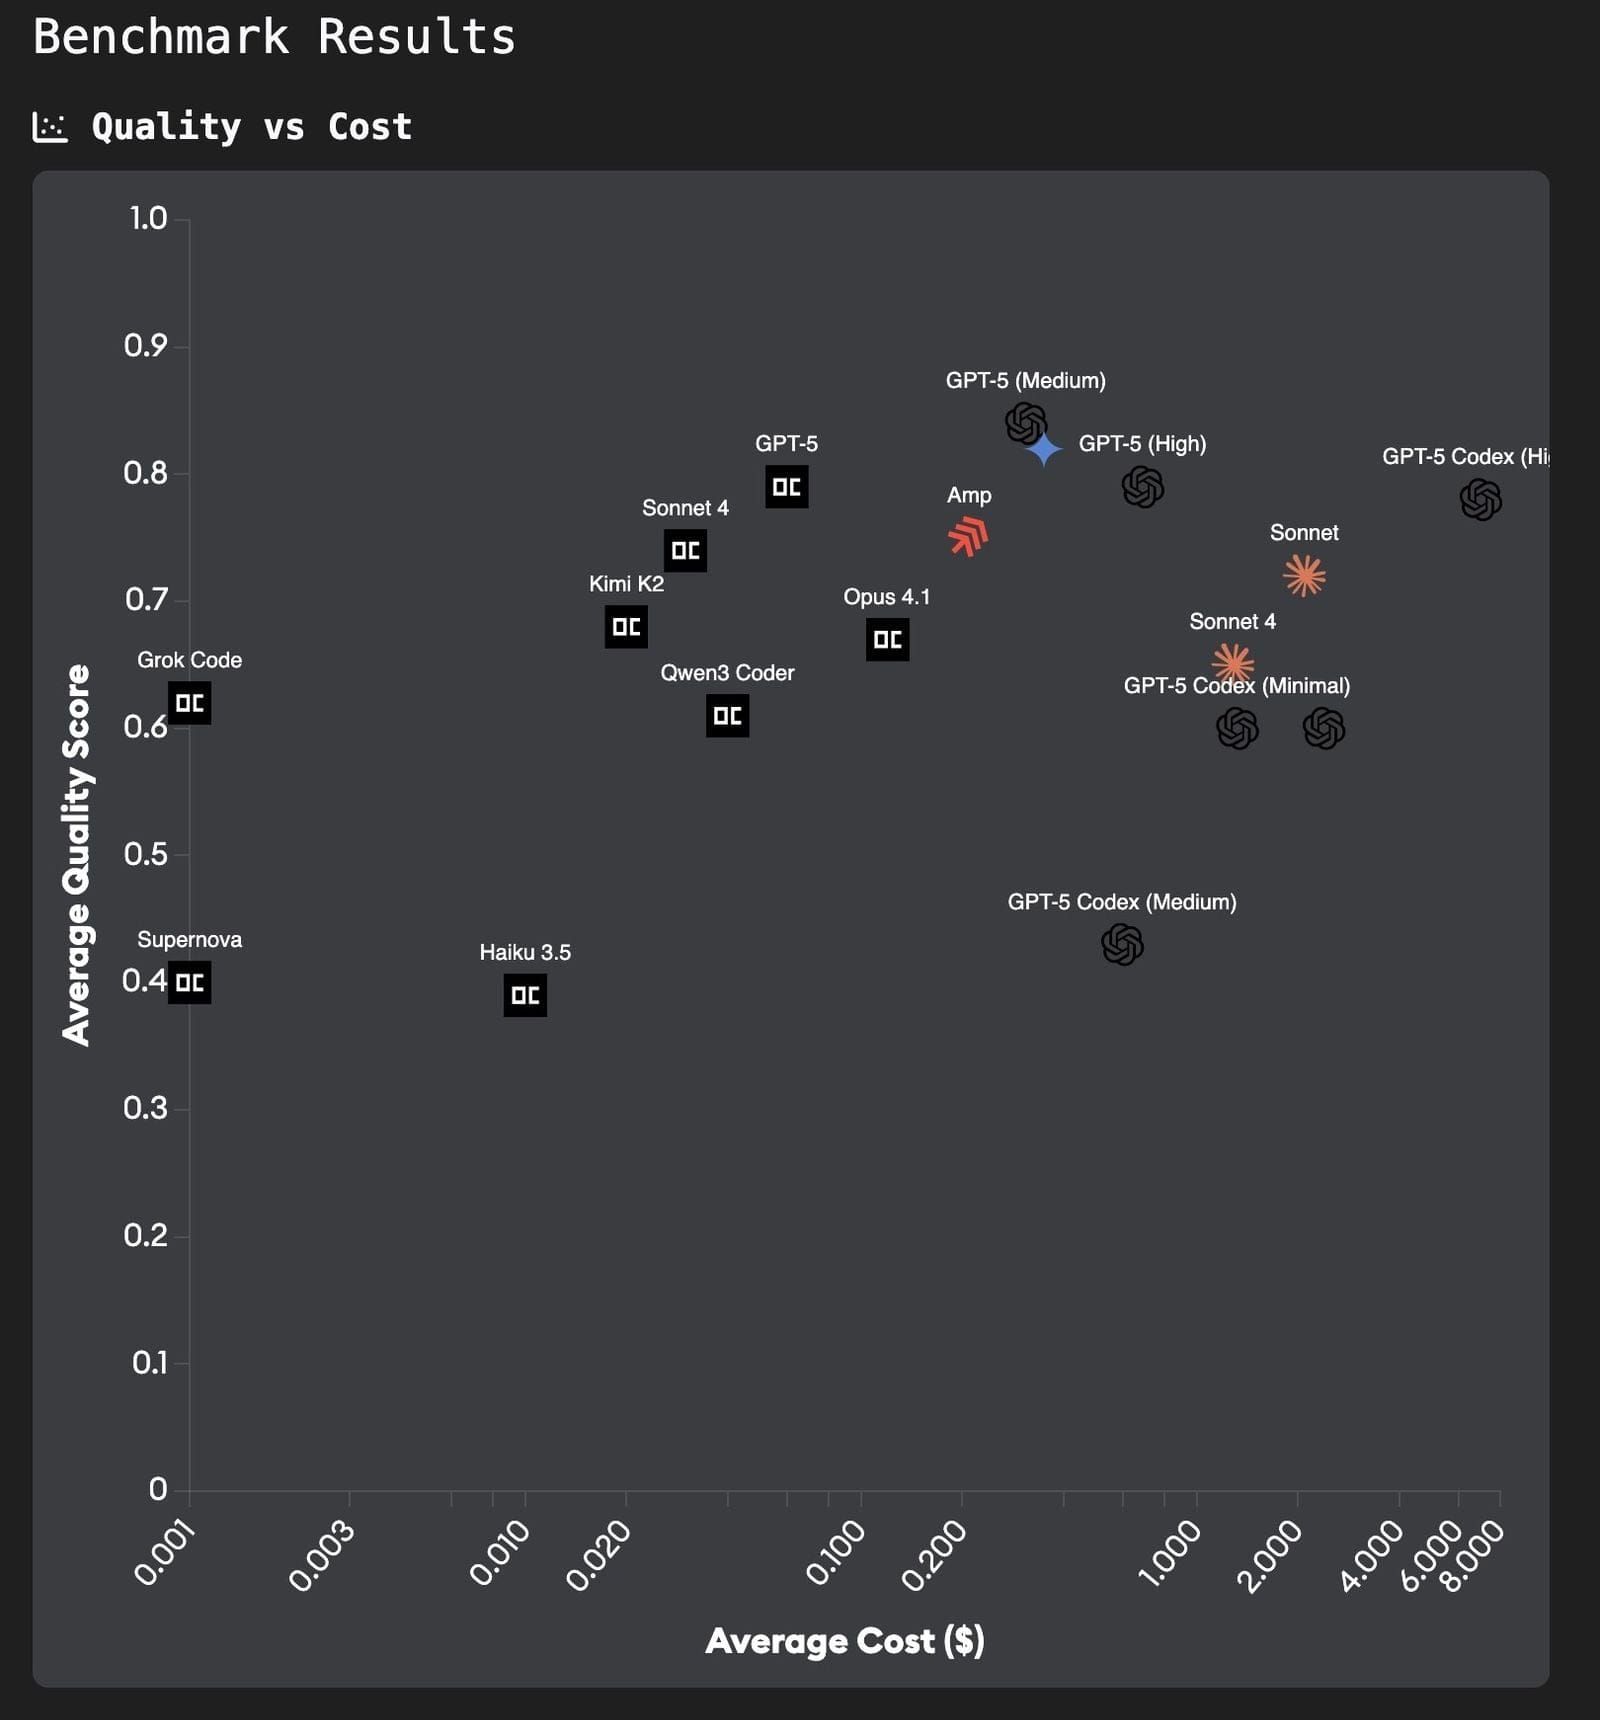
GitHub - grigio/opencode-benchmark-dashboard: Benchmark system for ...
Benchmarking OpenAI Releases New Coding Benchmark SWE Lancer Showing
Comparing benchmark participant with the current participant on ...