Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
CUDA Graph Usage: CUDA Feature Testing
CUDA graph 简述-CSDN博客
Cuda Graph With Object As Model’S Input – MXLQN
Parameterized CUDA Graph Launch in PyTorch: CUDA Graphs Without the ...
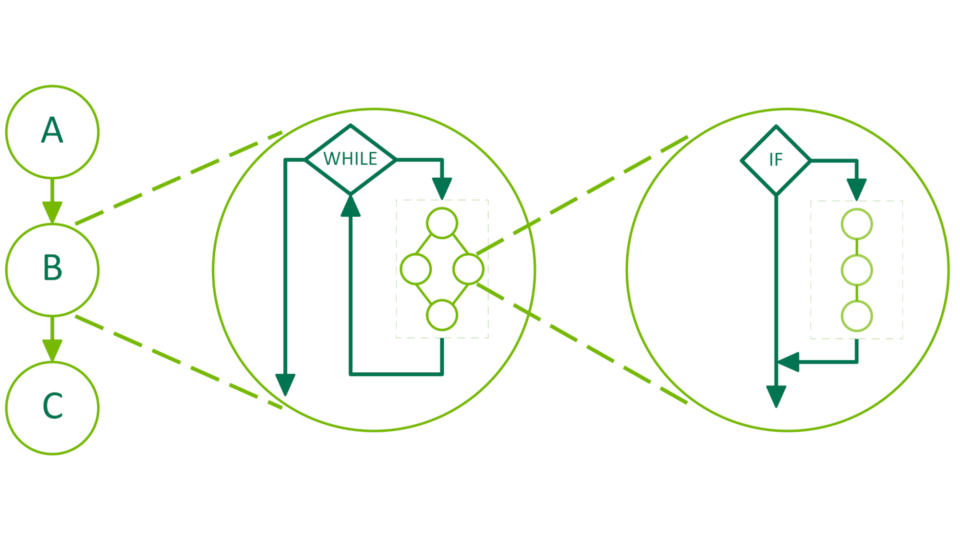
Enabling Dynamic Control Flow in CUDA Graphs with Device Graph Launch ...
CUDA graph 简析-CSDN博客
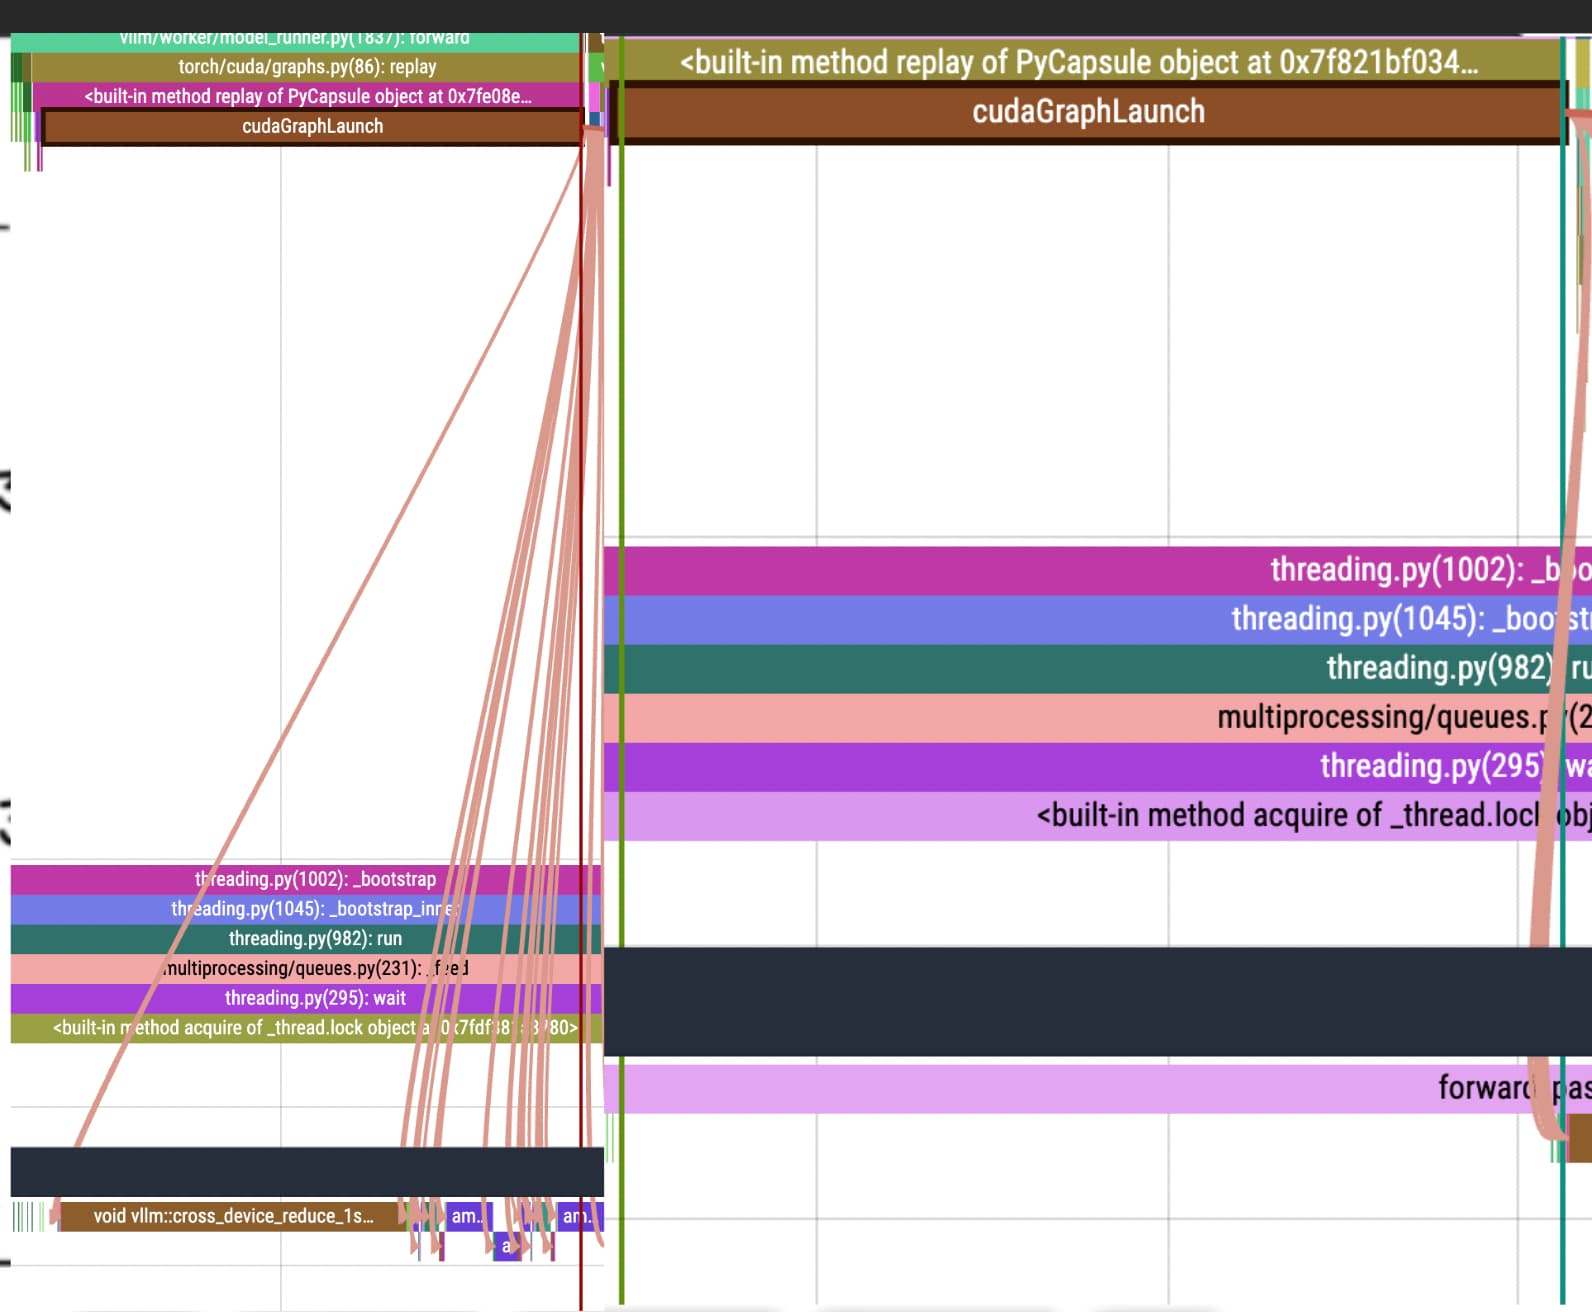
CUDA profile graph comparison for three different configurations ...
How CUDA Graph Works in torch.compile · GPU Notes
CUDA Graph Execution Taking Longer Than Original Kernel Launch Loop ...
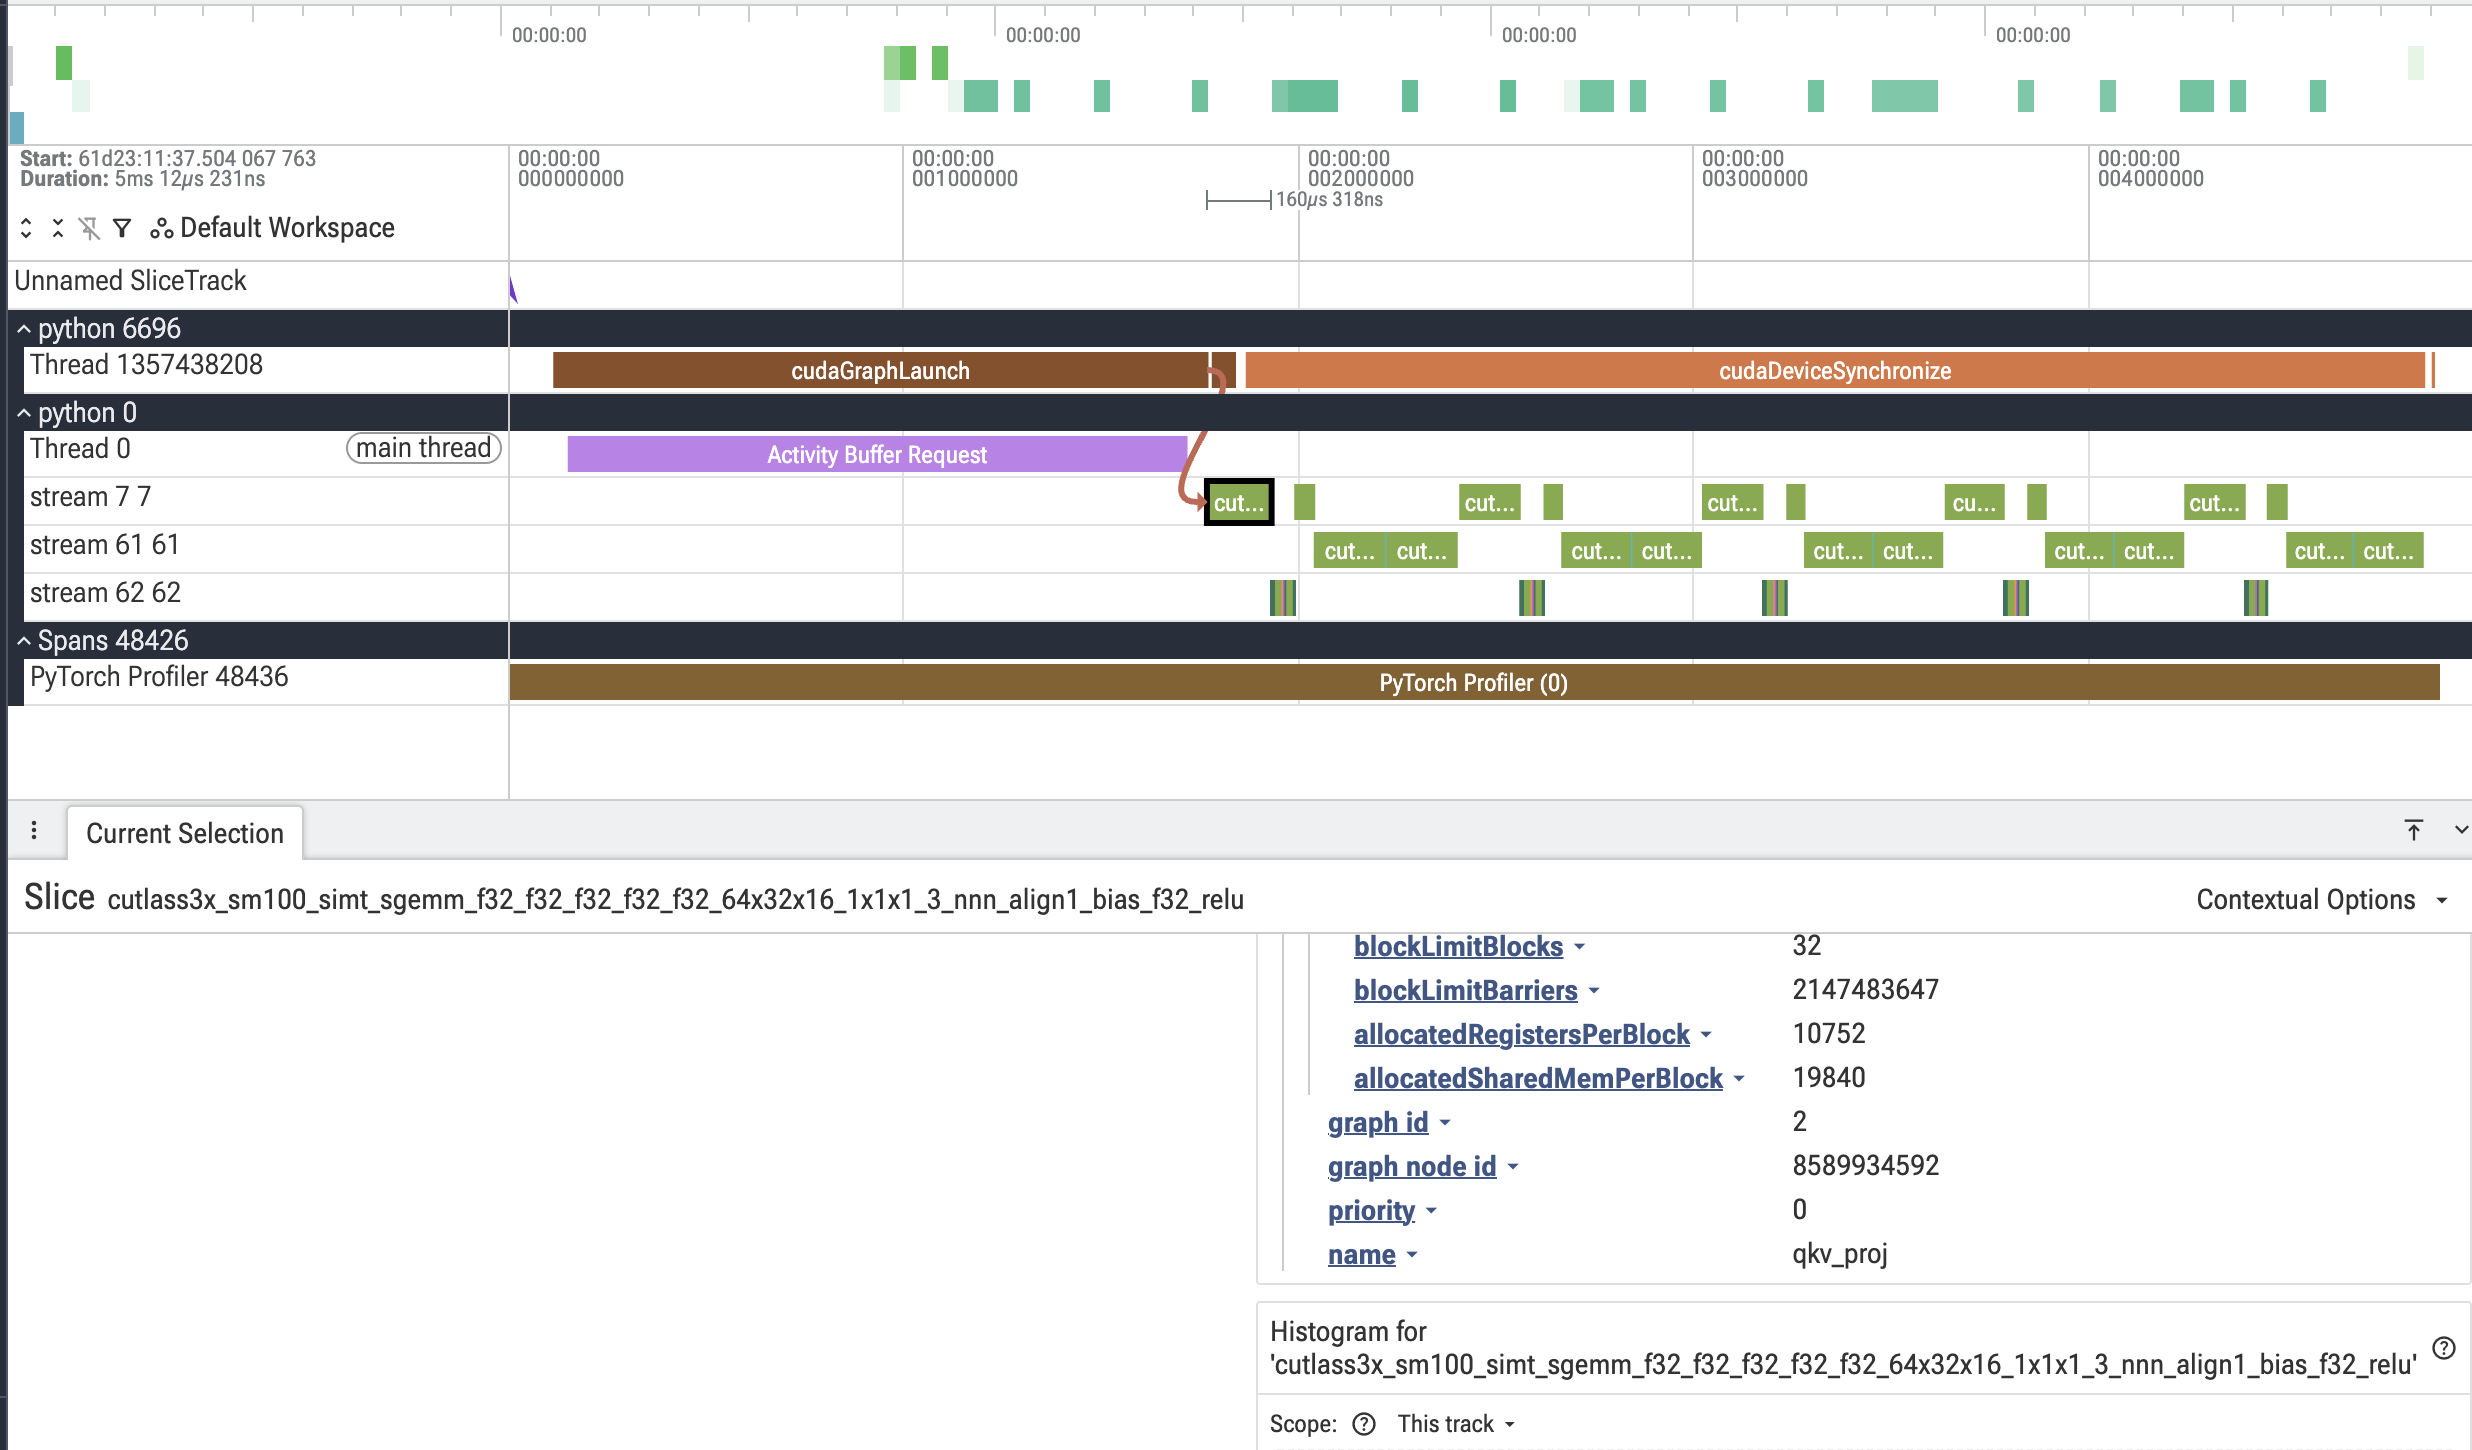
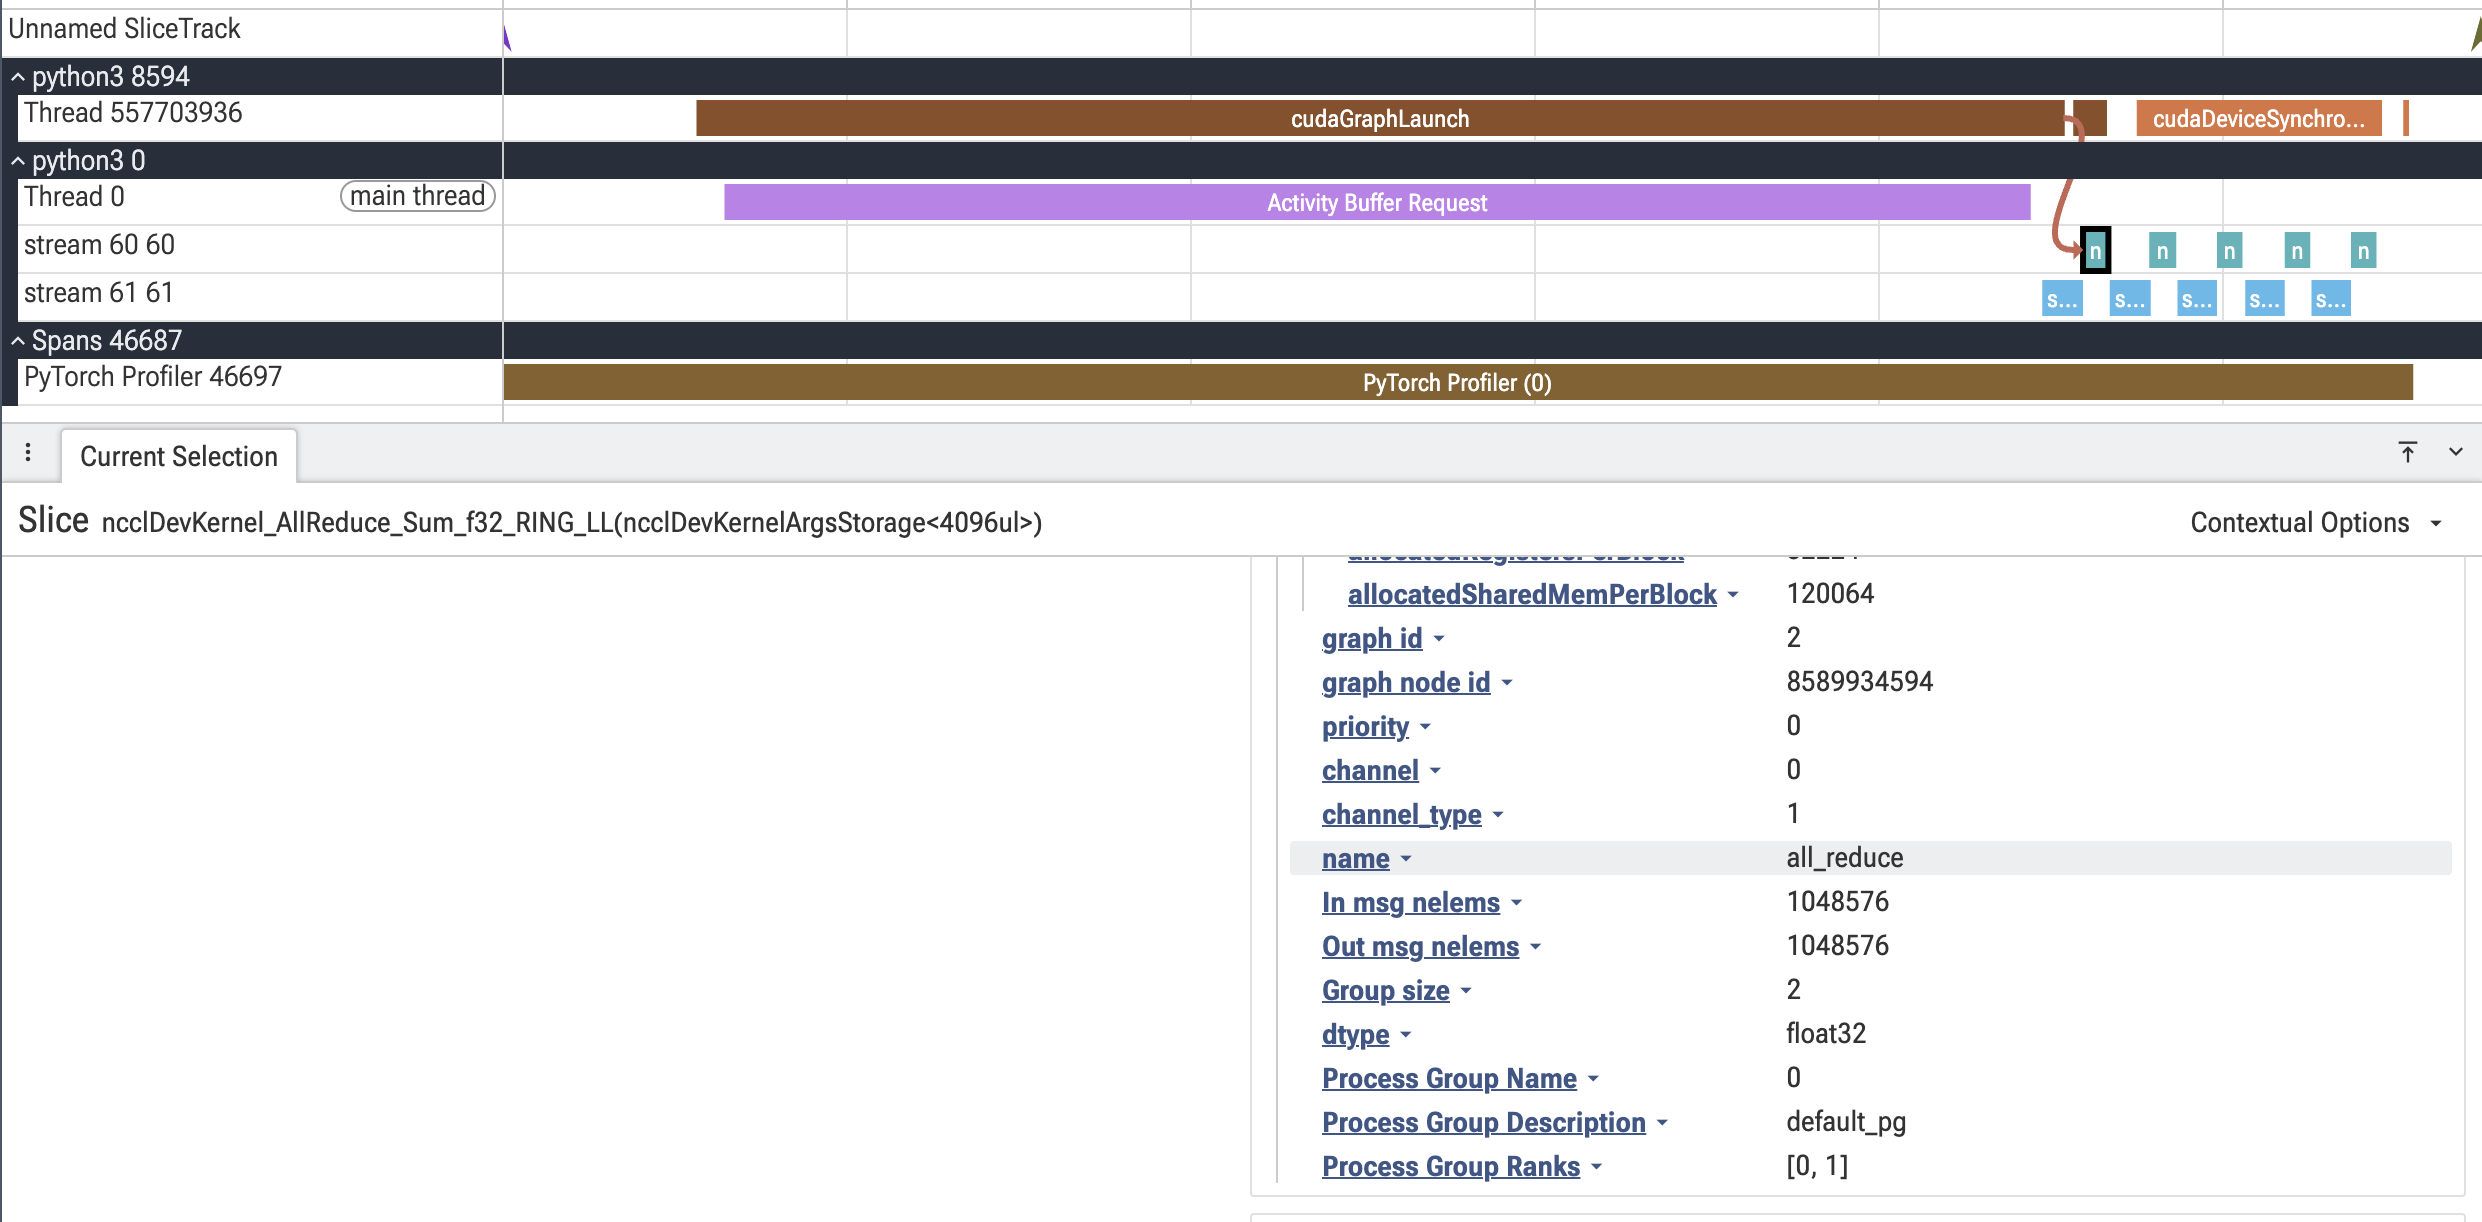
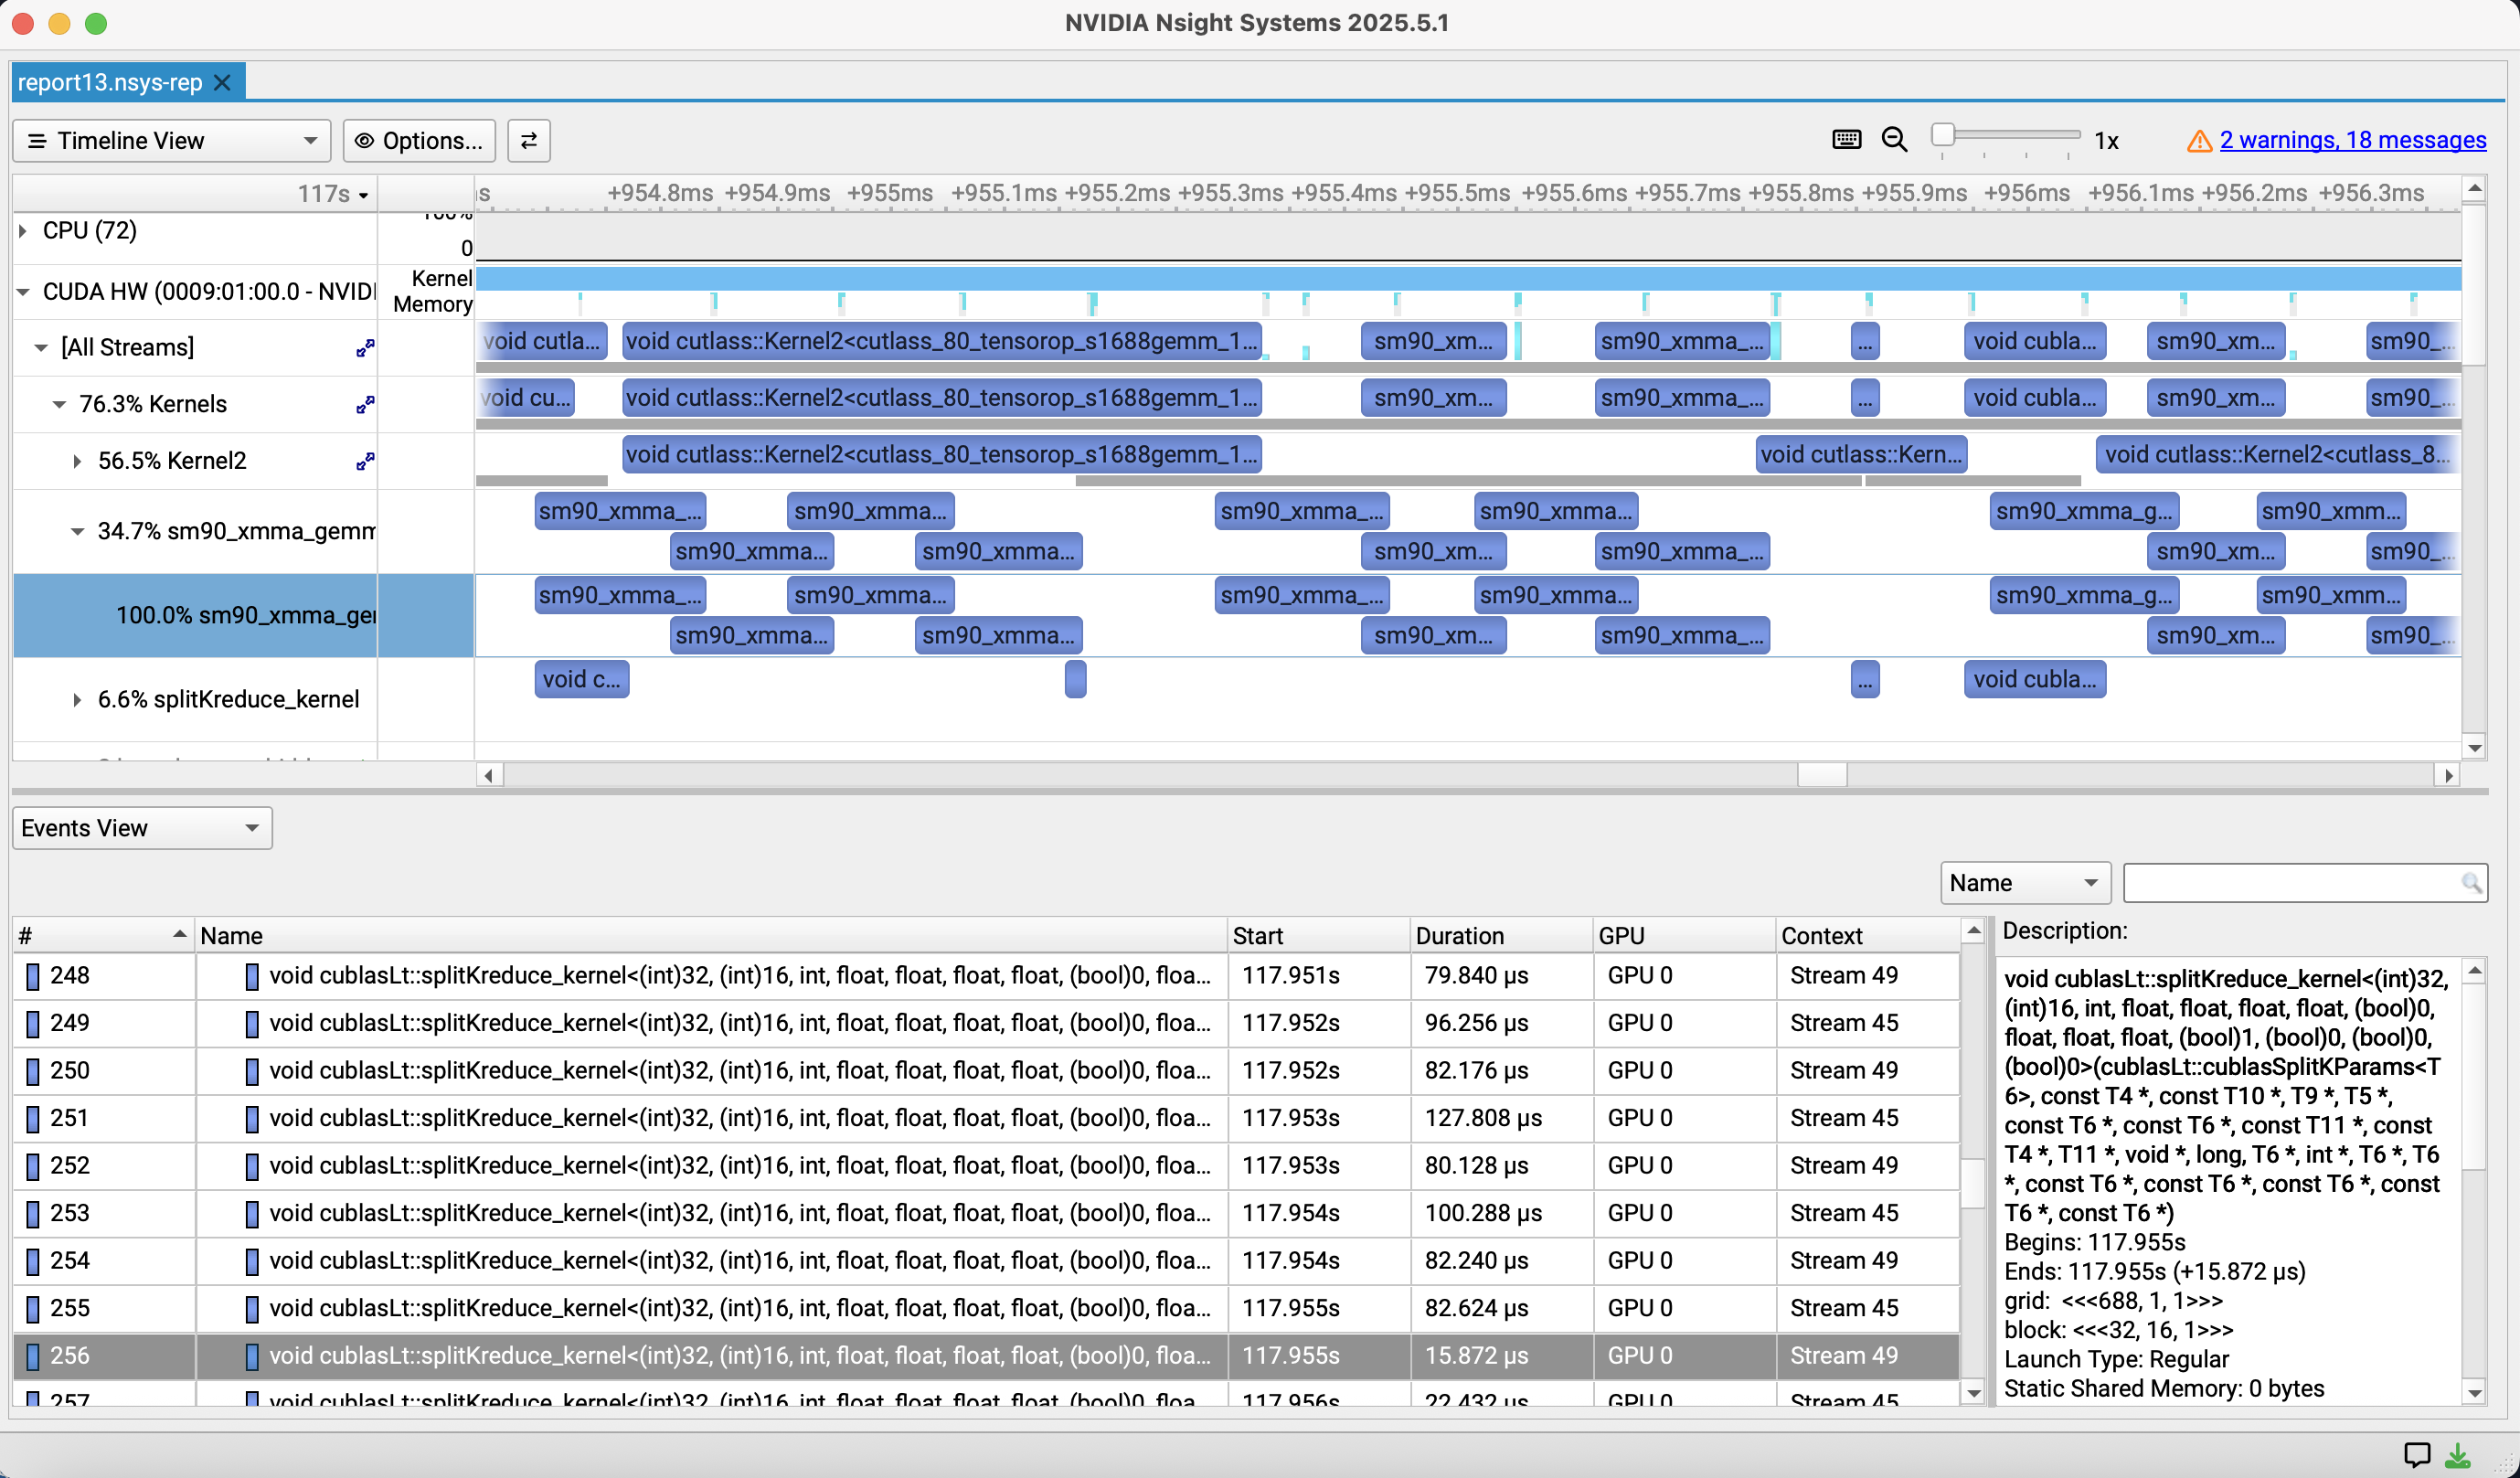
CUDA Graph Kernel Annotations and Profiling — PyTorch Tutorials 2.13.0 ...
CUDA Graph Runners and Decode Perf Cache | deepseek-ai/DeepInfer | DeepWiki
CUDA Graphs - vLLM
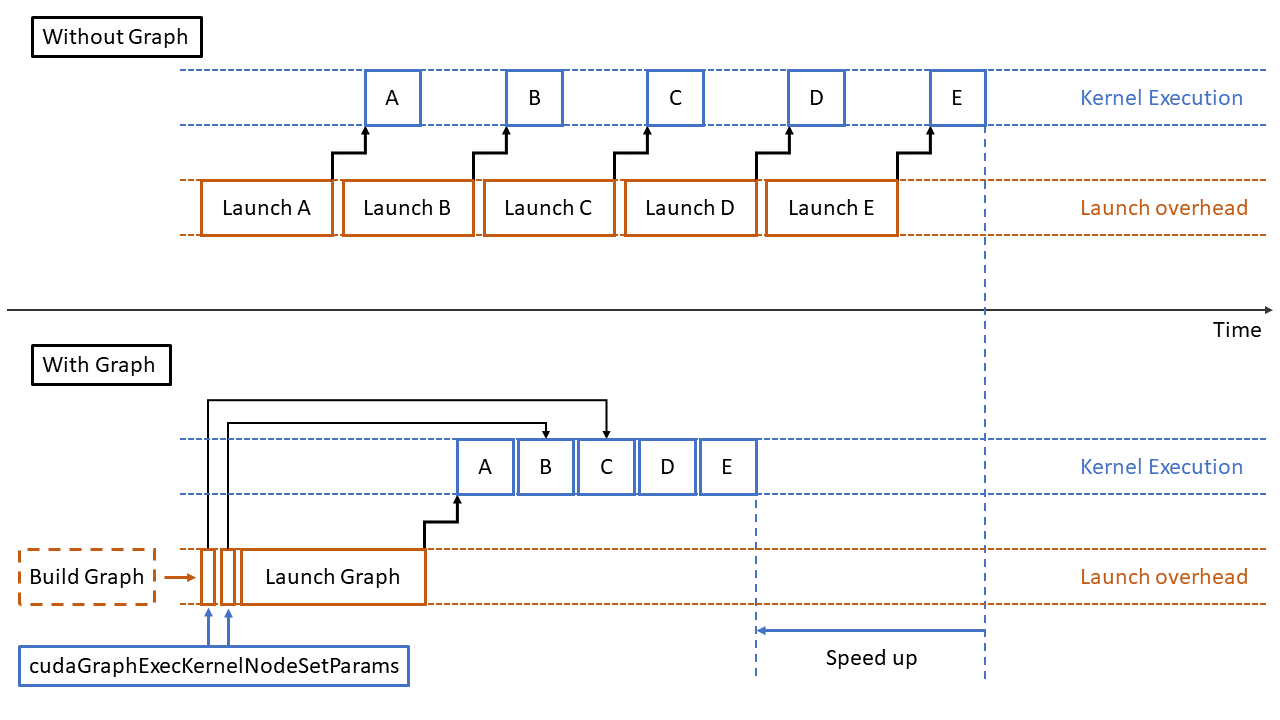
Constructing CUDA Graphs with Dynamic Parameters | NVIDIA Technical Blog
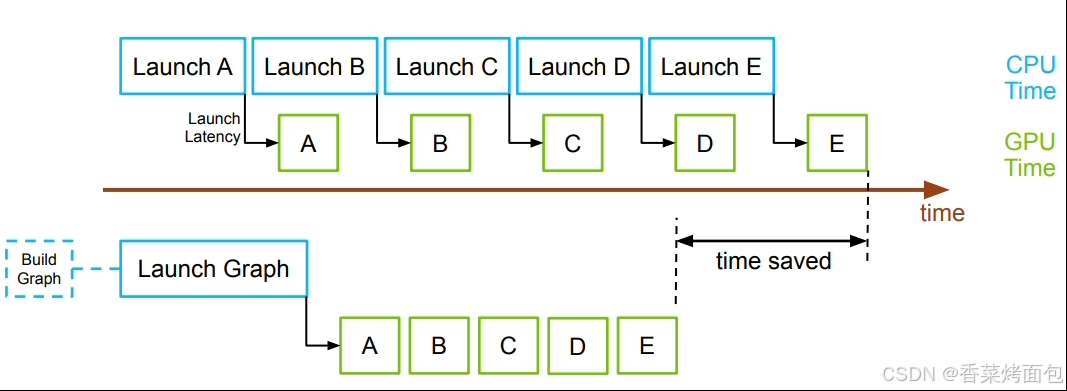
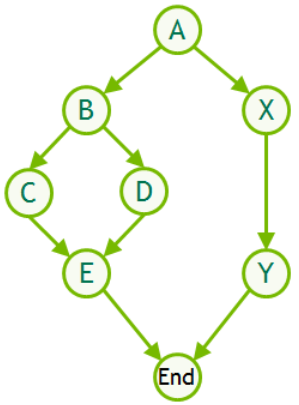
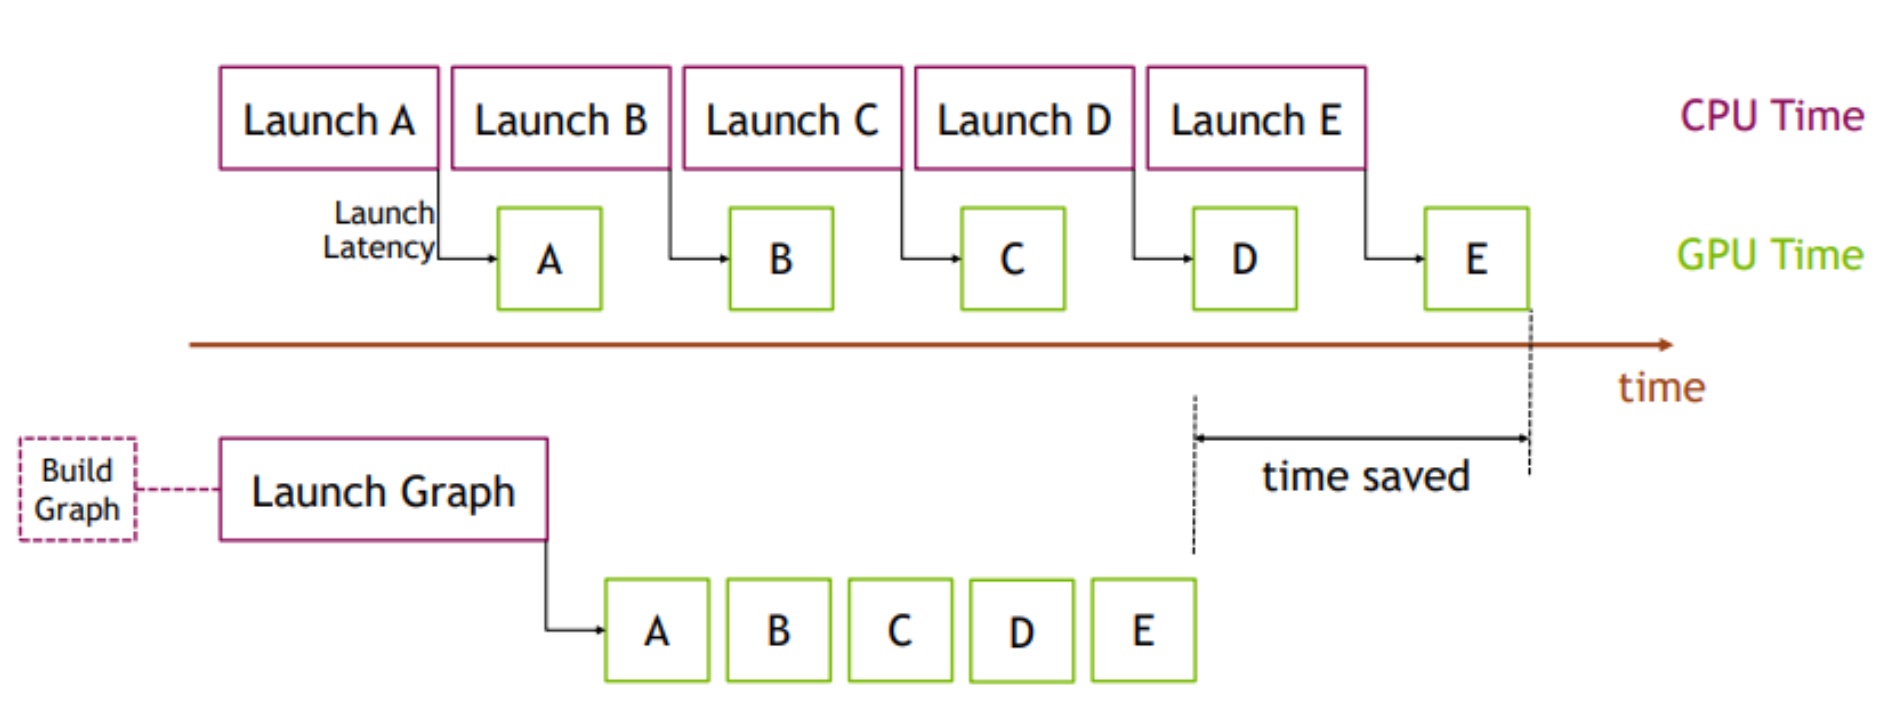
Getting Started with CUDA Graphs | NVIDIA Technical Blog
Revisiting CUDA Graph: Core Mechanisms, Multi-Graph Memory Sharing, and ...
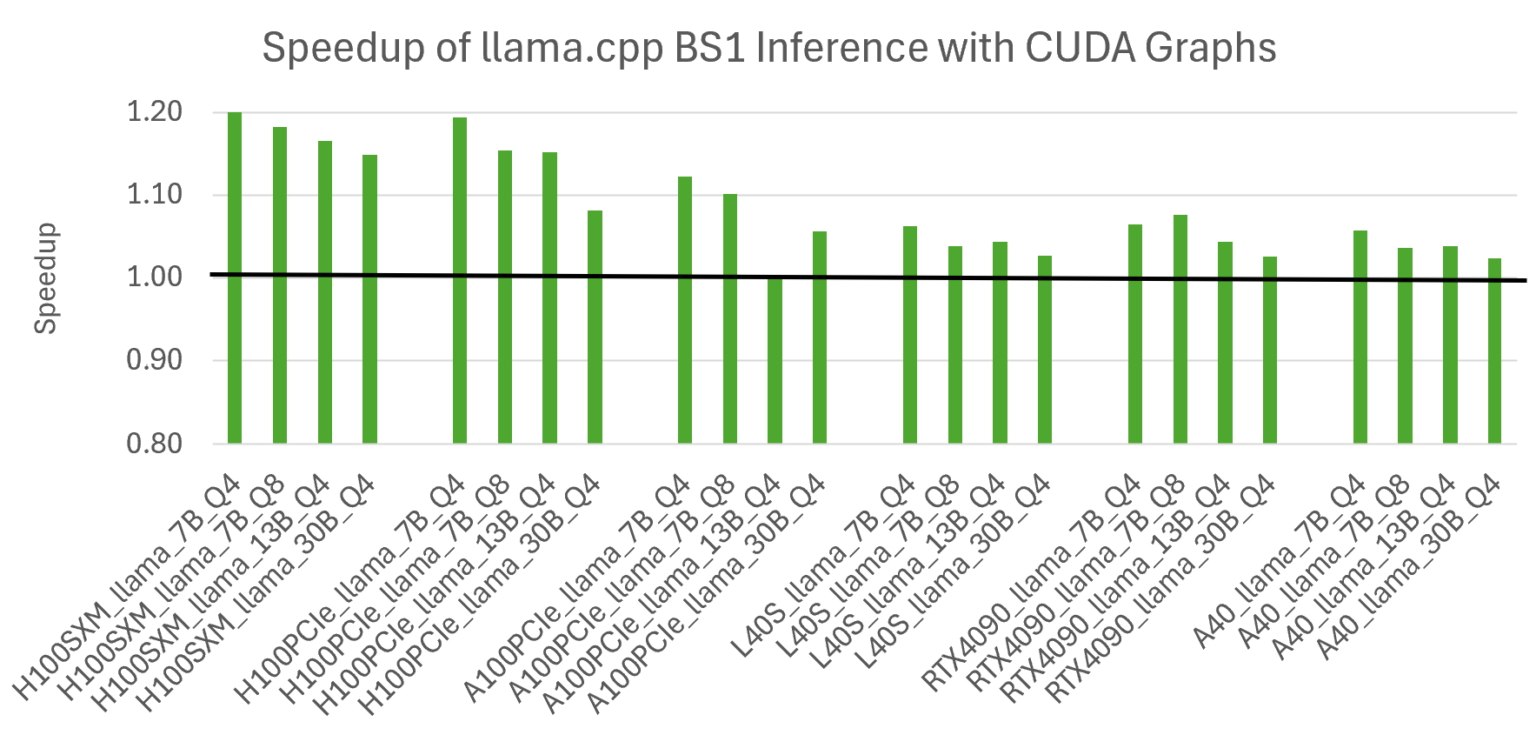
Optimizing llama.cpp AI Inference with CUDA Graphs | NVIDIA Technical Blog
Quantum Mechanics-Enhanced Drug Discovery Using QUELO-G and CUDA Graphs ...
A Guide to CUDA Graphs in GROMACS 2023 | NVIDIA Technical Blog
CUDA Graph优化GPU性能的底层原理分析-开发者社区-阿里云
Nvidia Cuda Core Chart
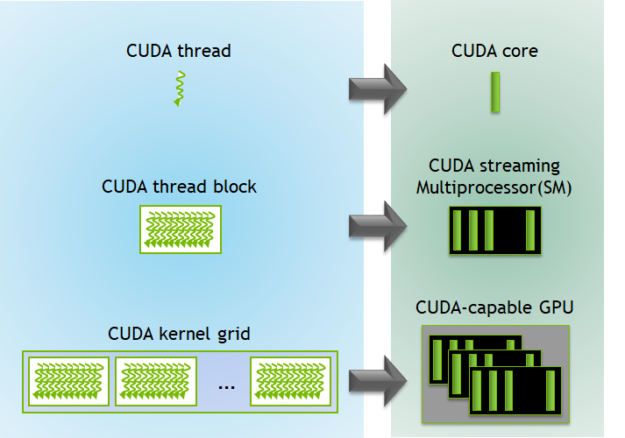
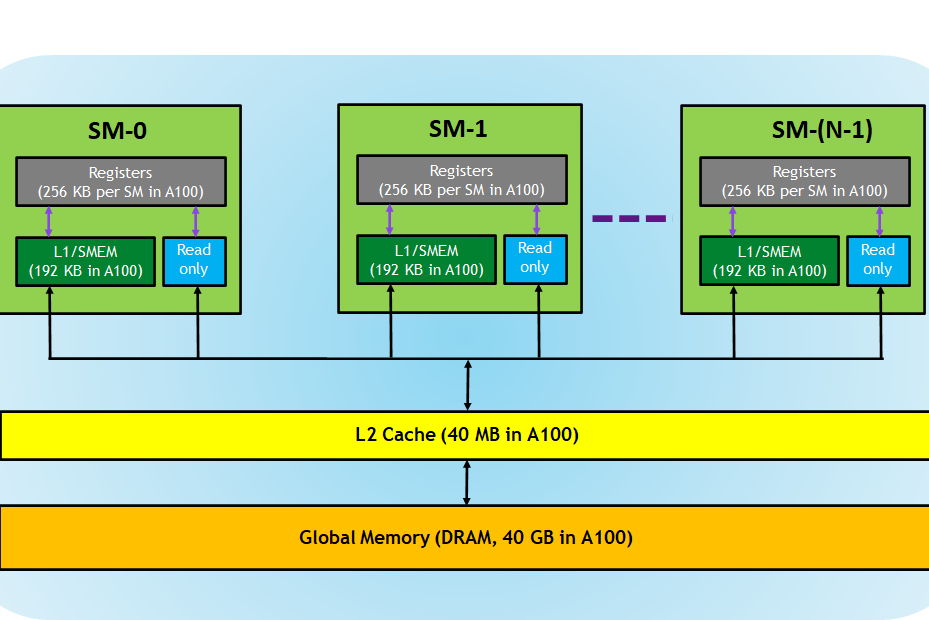
CUDA Refresher: The CUDA Programming Model | NVIDIA Technical Blog
CUDA Graphs学习与实验-CSDN博客
GitHub - fw-ai/llama-cuda-graph-example: Example of applying CUDA ...
Dynamic Control Flow in CUDA Graphs with Conditional Nodes | NVIDIA ...
Reduce time to first kernel when using CUDA graphs - PyTorch Forums
Question about CUDA kernels parallel execution - CUDA Programming and ...
CUDA 12.1 Supports Large Kernel Parameters | NVIDIA Technical Blog
CUDA enables parallel execution of GPU kernels from a C++ main ...
Ch3. CUDA Execution Model
CUDA graph: kernel execution and DtoH/HtoD memcpy not concurrent when ...
The CUDA Execution Model - 谭邵杰的计算机奇妙之旅
CUDA Series: Execution and Graphs | by Dmitrij Tichonov | Medium
Running ONNX GenAI Model on GPU - How to Set Up Driver, CUDA 13, cuDNN ...
Parakeet TDT: CUDA illegal memory access in the CUDA-graph greedy ...
CUDA software optimization reportedly reached 2x in a month with AI ...
Cuda Tensorflow Windows - GitHub Musador13 TensorFlow CUDA Windows ...
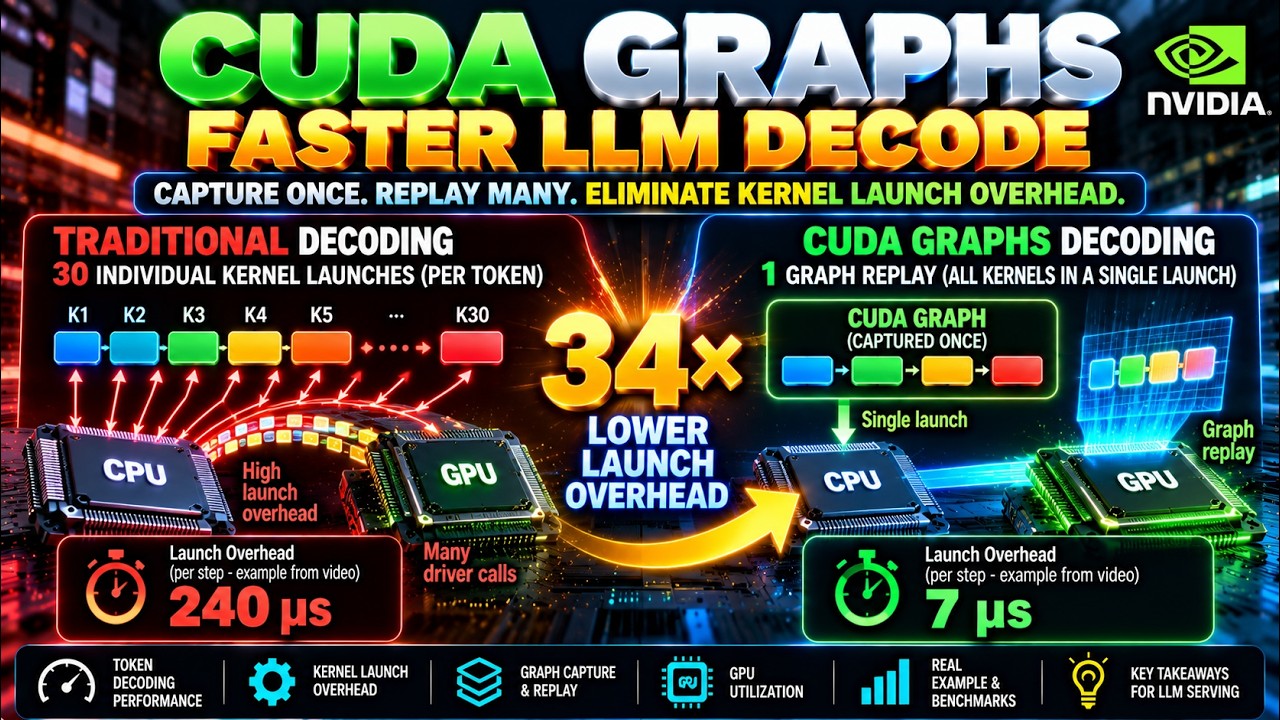
The GPU Isn't Slow, It's Waiting: How CUDA Graphs Fix LLM Decode ...
Tensor RT-LLM and Custom CUDA Kernel Optimization: Maximizing ...
GitHub - Void-LifeStream/dsh-cuda: Run Python on the local CUDA GPU ...
Nvidia Cuda Compatibility Chart Bdiv – NBKomputer
2026 Hot Wheels Case P Super Treasure Hunt STH '70 Plymouth AAR Cuda ...
Hot Wheels '70 Plymouth AAR Cuda Super Treasure Hunt 2026 P Case | eBay
Windows: NVIDIA GPUs run via Vulkan instead of CUDA on 0.40.6 with ...
NVIDIA — GPUs, RTX, CUDA e soluções de IA de alto desempenho | CHIPMAN
Use CUDA P2P / NVLink for multi-GPU layer-split hand-off (dual RTX 2080 ...
CUDA / AI Engineer σε MWDN – Λευκωσία – Κάντε αίτηση τώρα! – Jooble
build(cuda): CUDA preset 未指定架构,实际按 sm_75 编译导致 Ampere 性能失真 · Issue #8 ...
Two tests fail on a CUDA host since #736 / #697: test_nvfp4_experts ...
[Engine] Startup fails on dual RTX 2080 Ti 22GB GPUs due to CUDA weight ...
[Engine] Strata update downloads CUDA engine instead of HIP on Radeon ...
推荐场景GPU优化中CUDA Graph与多流并行的方案对比及选择-开发者社区-阿里云
Answer | GPU Puzzlers
[논문 리뷰] Boosting Performance of Iterative Applications on GPUs: Kernel ...
入局 AI Infra:程序员必须了解的 AI 系统设计与挑战 - 知乎
Accelerating Intra-Node GPU-to-GPU Communication Through Multi-Path ...
Image of slide 58
CUDA: From Correctness to Performance | 北京大学 Linux 俱乐部
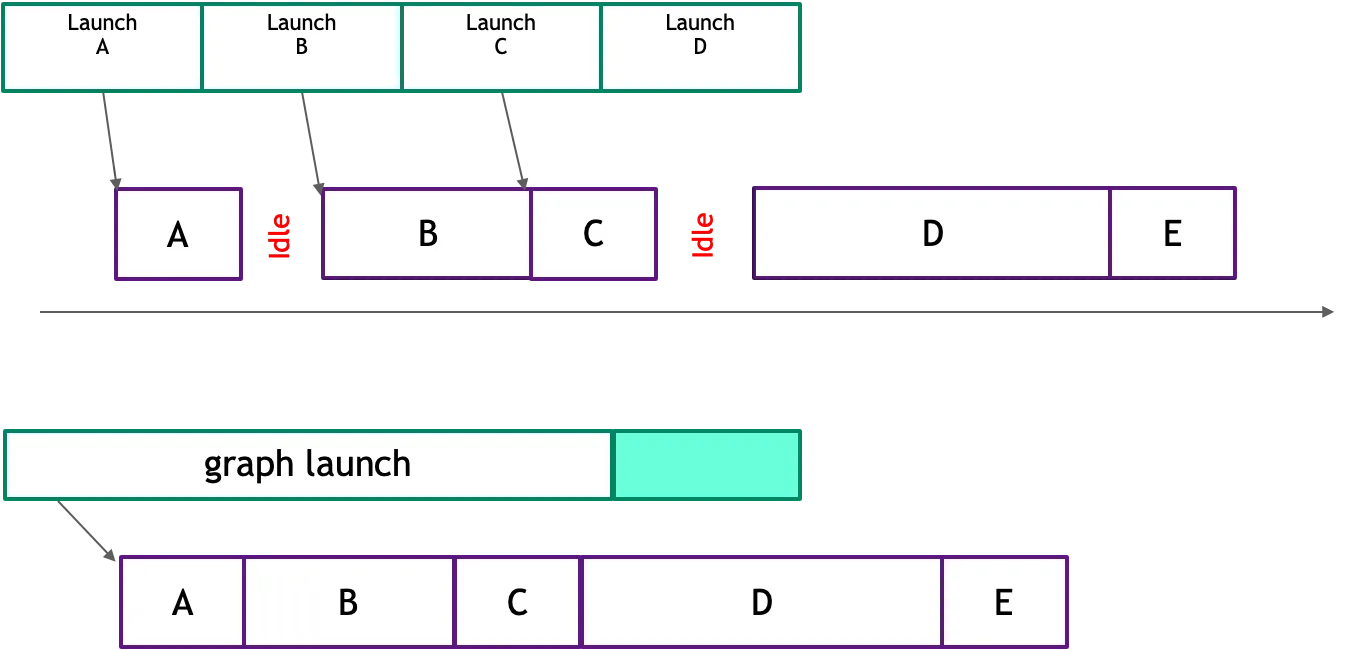
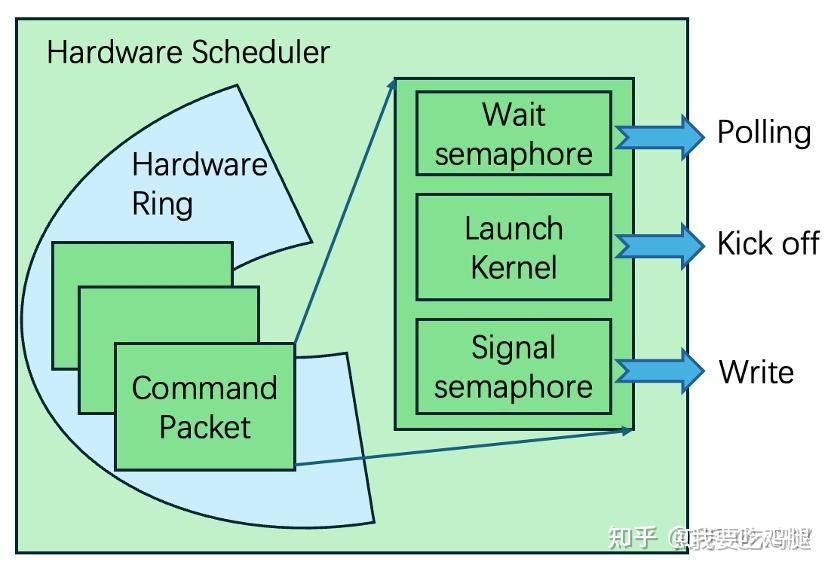
从“芯”到“码”(七): 深度剖析Kernel Launch开销与CUDA Graph的优化之道 - 知乎
【CUDA Training Series】Lecture 1 - 知乎
Modeling and Estimation - 1 | SuperHotDogCat’s Blog
[Bug] --cuda-graph-max-bs-prefill silently rounds down to the nearest ...
mantelmoritz/CorridorKey-ONNX-Graphs · Hugging Face
CUDA-for-AMD-Windows/docs/CUDNN_PHASE1_CHECKLIST.md at main · Speedstu ...
GitHub - cj-yuen/Project1-CUDA-Flocking · GitHub
cuda-examples/.vscode/c_cpp_properties.json at main · yaikeda/cuda ...
Strata/tests/cuda at main · Niko1221/Strata · GitHub
cuTile: integer-to-integer conversions, and arithmetic on generic ...
Cómo hacer un backup de Microsoft Entra ID
Yash Punjabi | alphaXiv
Seagate 3.5" Barracuda 3TB SATA III 6Gbps HDD ST3000DM007 | eBay
spark-pearl-miner/cuda/gemm at main · xXGuilasXx/spark-pearl-miner · GitHub
sglang/.agents/skills/debug-cuda-crash at main · sgl-project/sglang ...
capsulet-mesh-train/python/meshtrain/cuda_adapter.py at main · mohripan ...
Kevin Rooney vs. Anthony Vincent, October 10, 2026 - Tucson Roadrunners ...
vllm-backport/requirements/build/cuda.txt at master · wtdcode/vllm ...
Seagate BarraCuda ST8000DM004 8TB 3.5" SATA HDD 5425RPM 256MB | eBay
Zesty Launches Automated Fractional GPUs, Bringing Automation to NVIDIA ...
Guanaco/src/backend/cuda_backend.c at main · animeshkumarmaitreya ...
Olmo-core/src/olmo_core/kernels/cuda at main · allenai/Olmo-core · GitHub
gpu_ecc_alignment/ecc/ecc_cuda.cpp at main · levyben/gpu_ecc_alignment ...
vllm-plugin-FL/csrc/cuda/weak_ref_tensor.cpp at main · flagos-ai/vllm ...
San Diego Gulls vs San Jose Barracuda | Market | PredictStreet
Anthony Vincent vs. Devin Kaplan, October 23, 2026 - San Jose Barracuda ...
多CUDA Stream随机崩溃?wait_event与record_stream配对解难题-CSDN博客
GitHub - FgsiDev/llama.cpp-bin: Prebuilt llama.cpp binaries with auto ...
bio-nextflow/nextflow_notebooks/containerized_gpu_workflows/torch_cuda ...
Libor Hajek vs. Konnor Smith, October 24, 2026 - San Jose Barracuda vs ...
fix(dft/cuda): isolate UKS final-closure and RSH final-state scientific ...
CUDA/Qwen3.8: share W4A8 prompt quantization across projections ...
torch.histc returns wrong bins or errors for constant float32 inputs ...
Barracuda - Локации и карта - Palia
[RFC][Muse-Glimmer-30B][CUDA/ROCm] ROADMAP · Issue #501 · RL-Align/RL ...
Eclipse Howeruler Rau – 40 | #8 Daylight Chart | SW Shore Game ...
Use device-side assertions (CUDA_KERNEL_ASSERT2) in user-reachable ...
PccAI/third_party/nndistance/src/my_lib_cuda.cpp at main ...
Fix `expose_all_gpus_to_cuda_driver` crash when CUDA_VISIBLE_DEVICES is ...
CUDA_ERROR_ILLEGAL_ADDRESS from cuModuleLoadData (tilelang) at first ...
BARRACUDA, s.r.o. – tržby 50 tis. € – IČO 52110141
GitHub - Wallawalla47/Infernix: C++/CUDA single-GPU inference engine ...