Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
PPD: Prefill-Decode Disaggregation for Multi-turn LLM Serving · Zongze Li
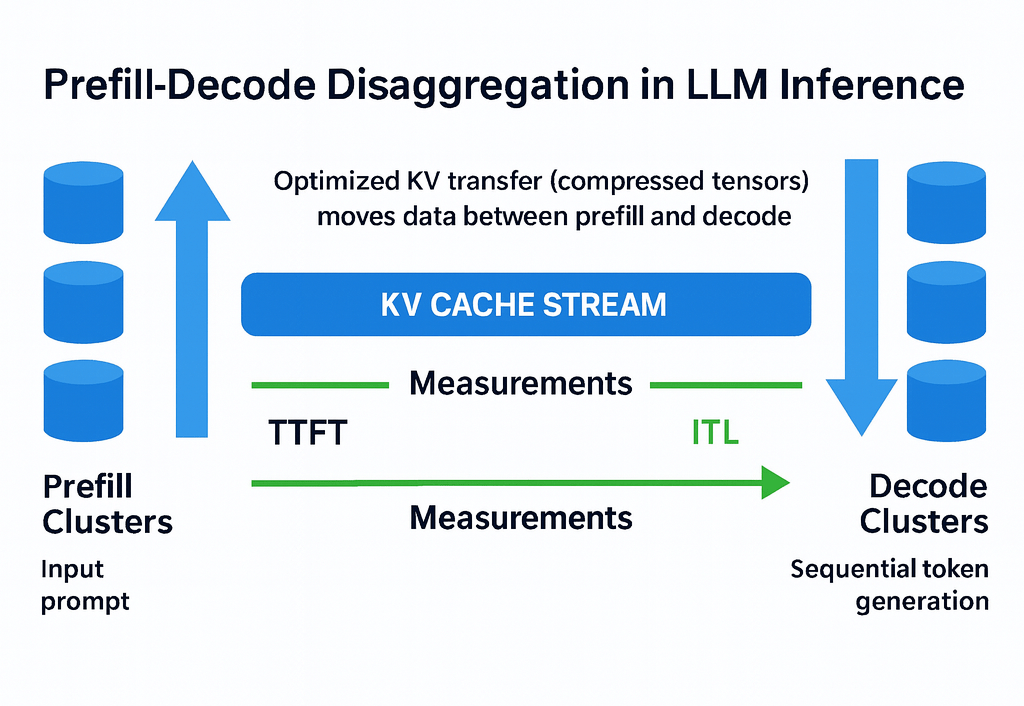
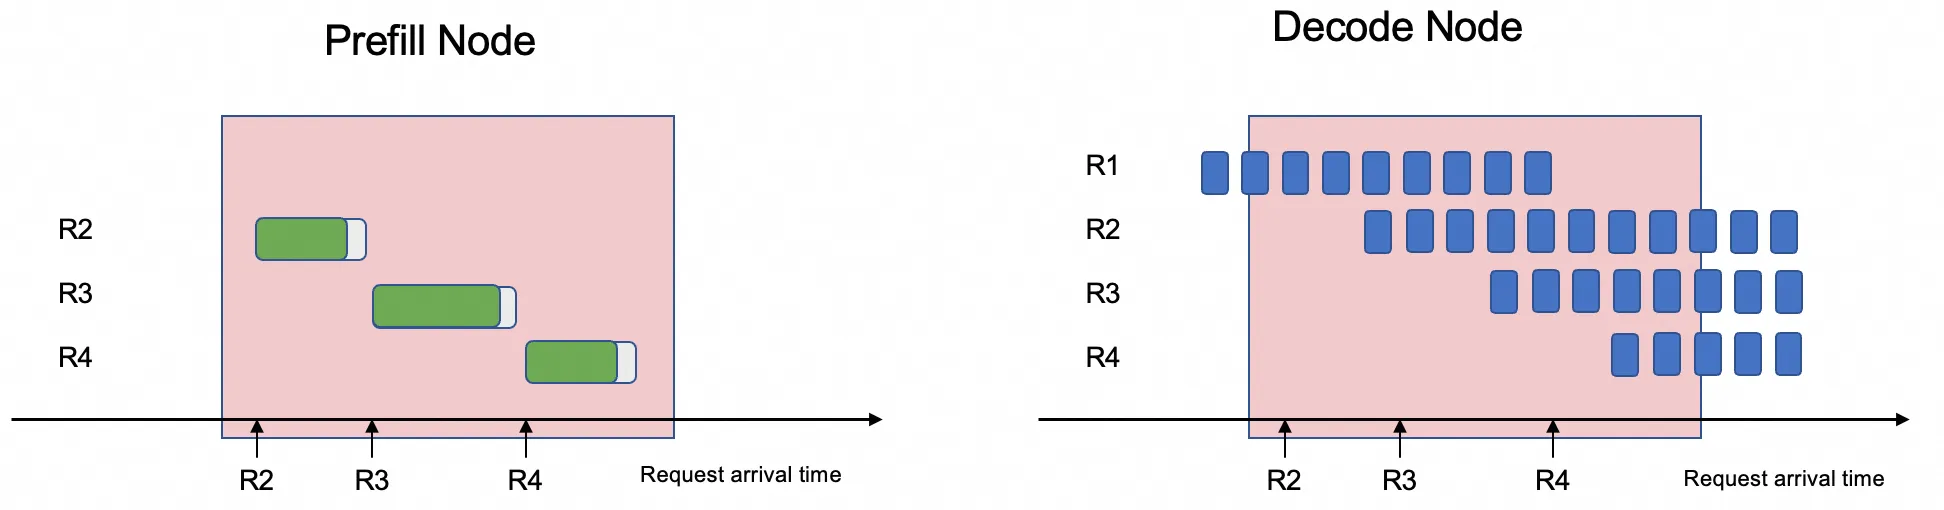
Understanding the Prefill-decode Disaggregation in LLM Inference ...
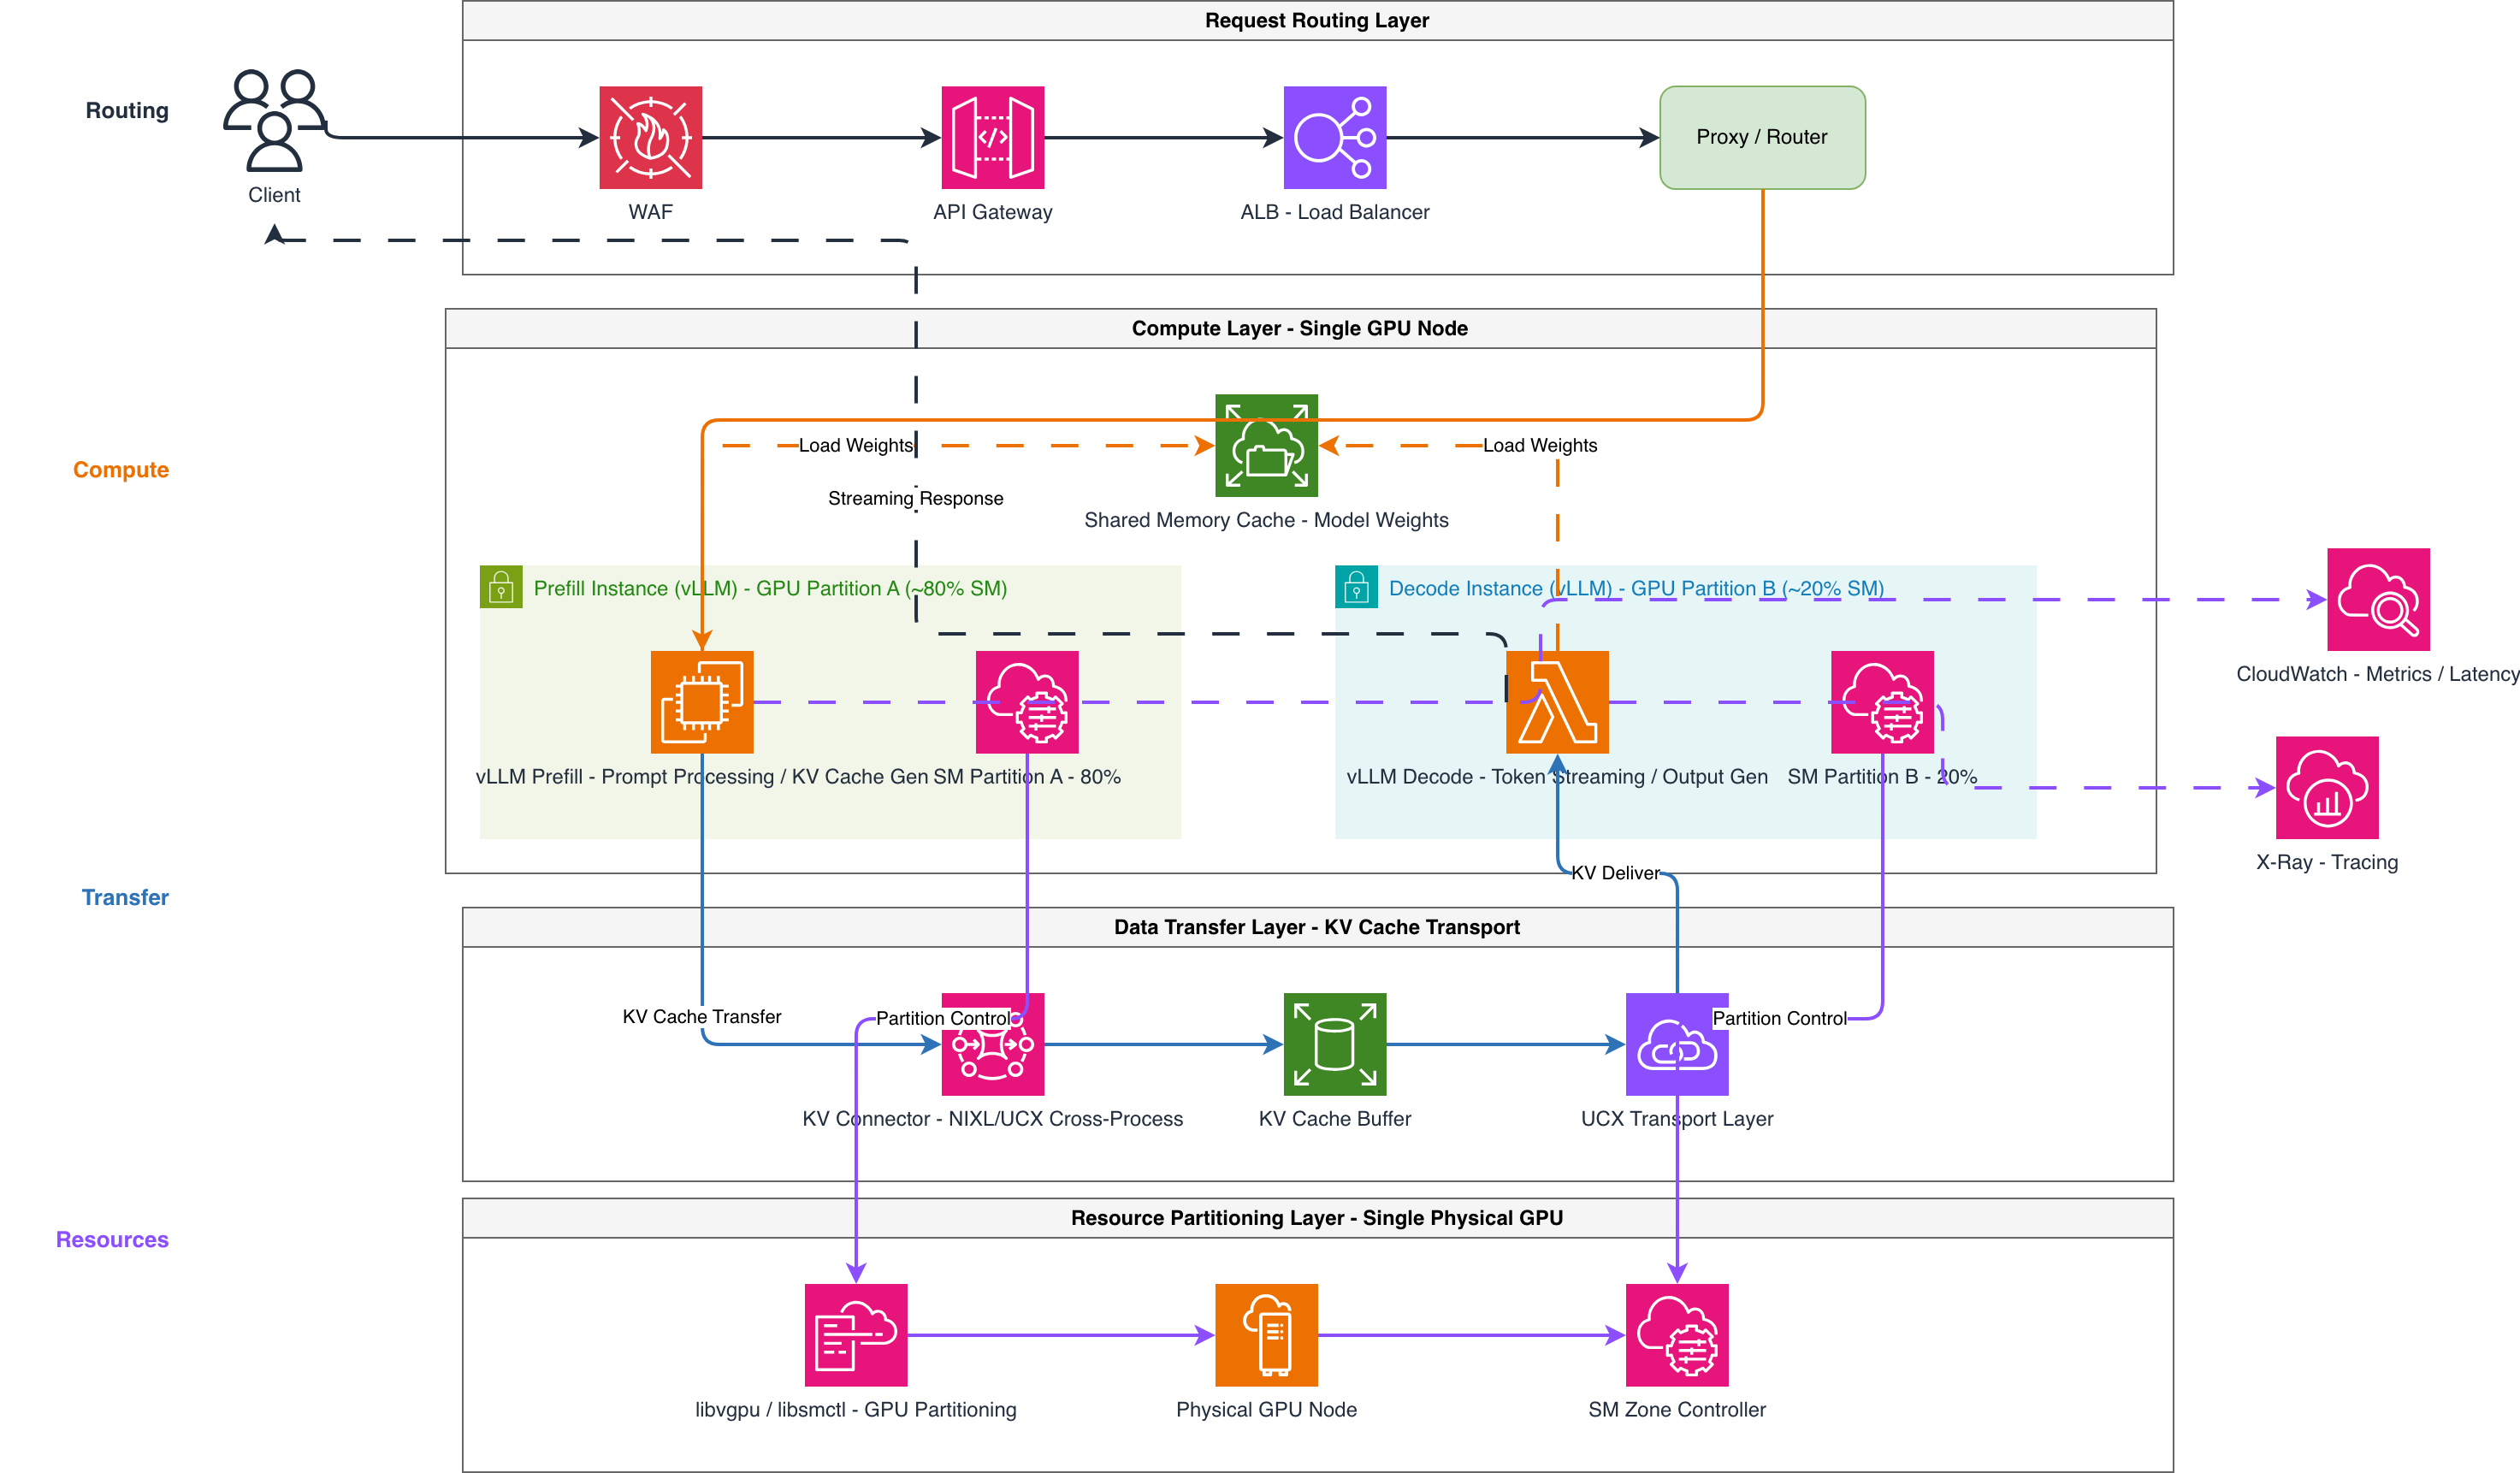
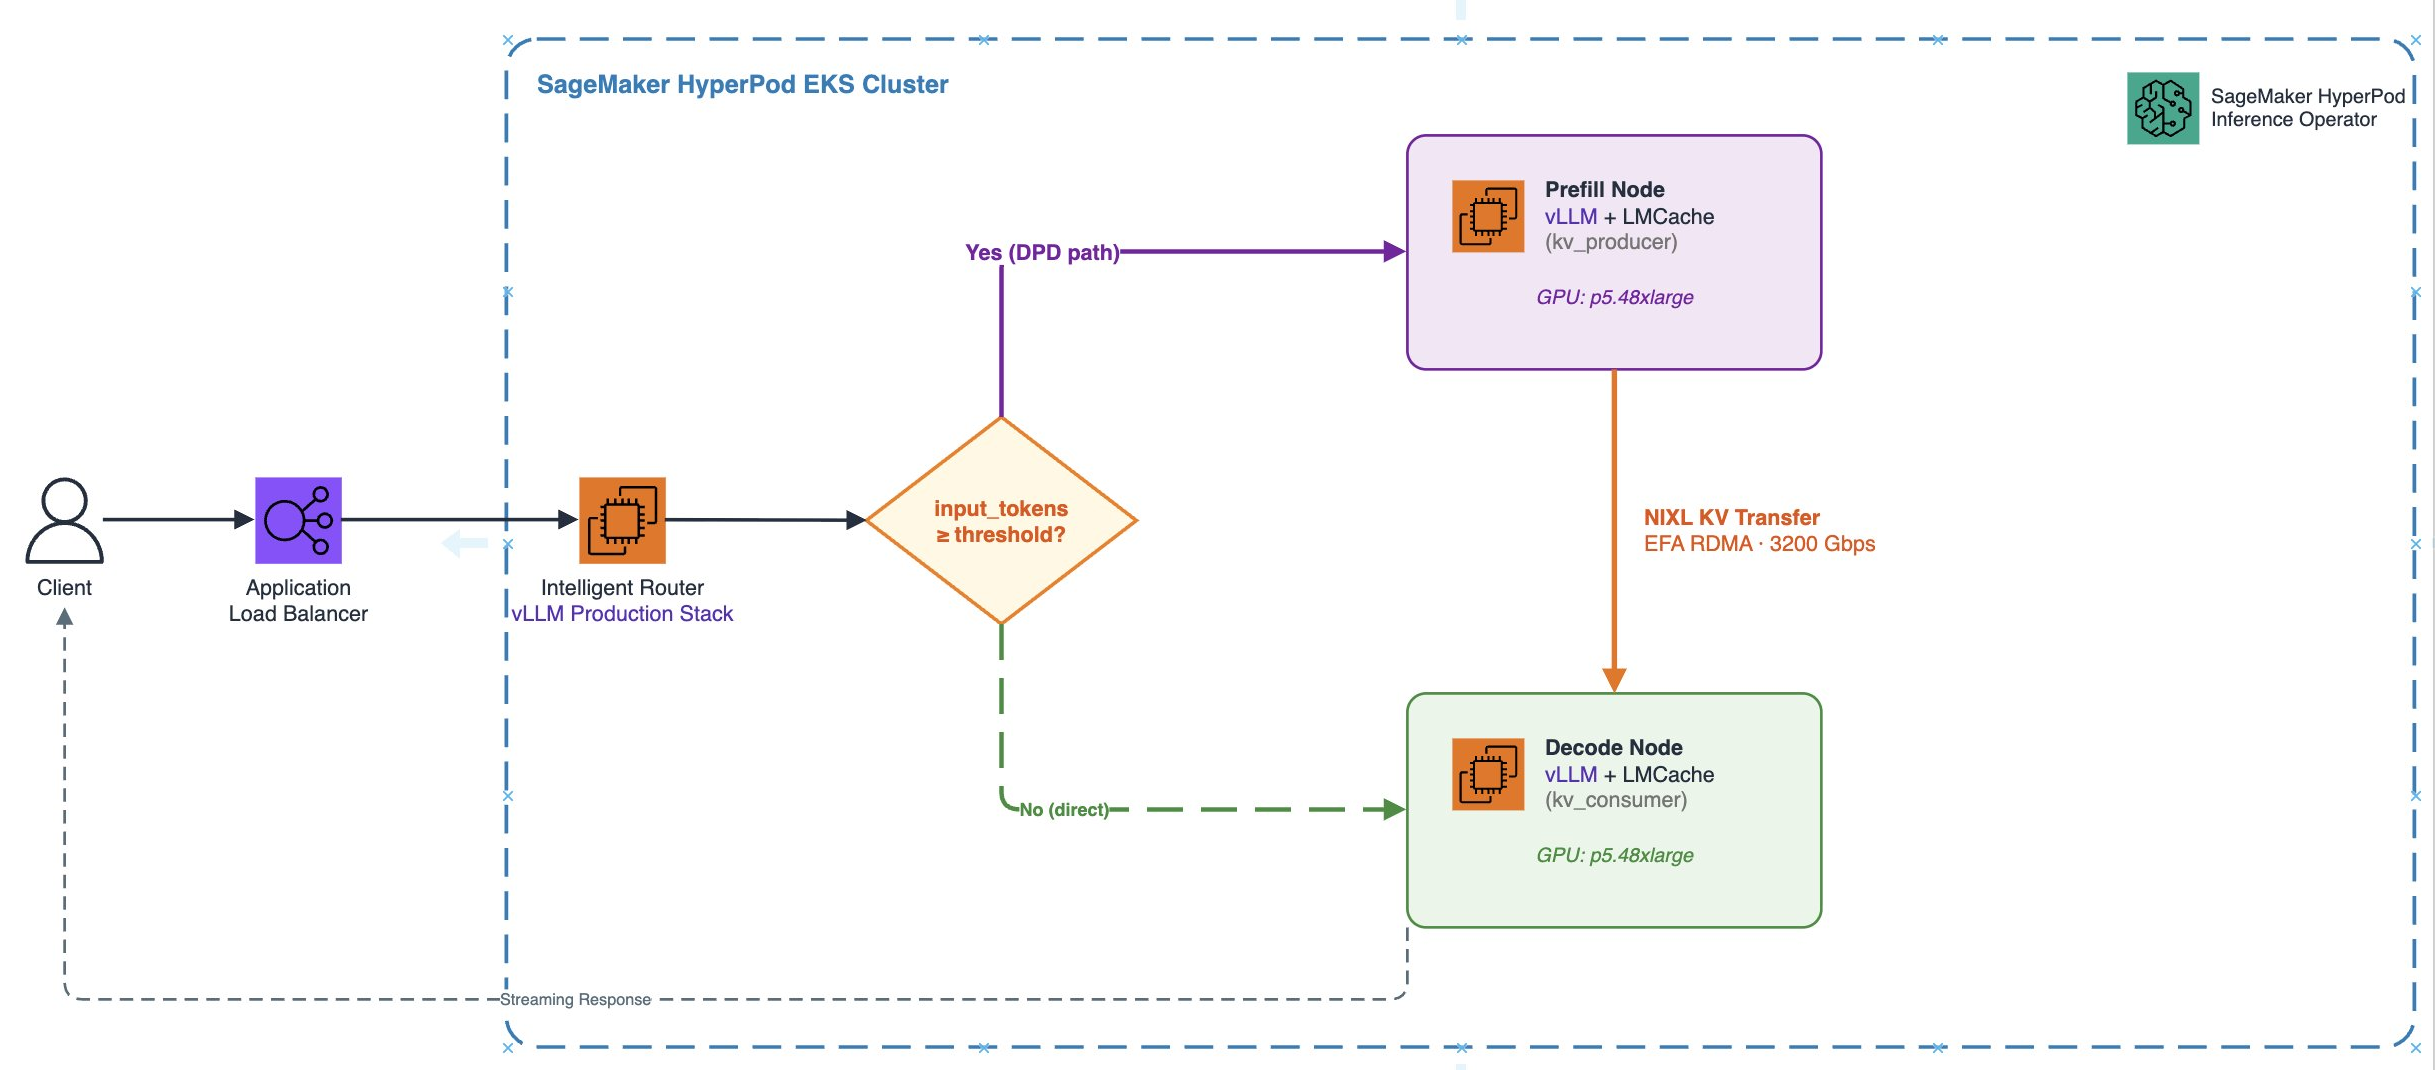
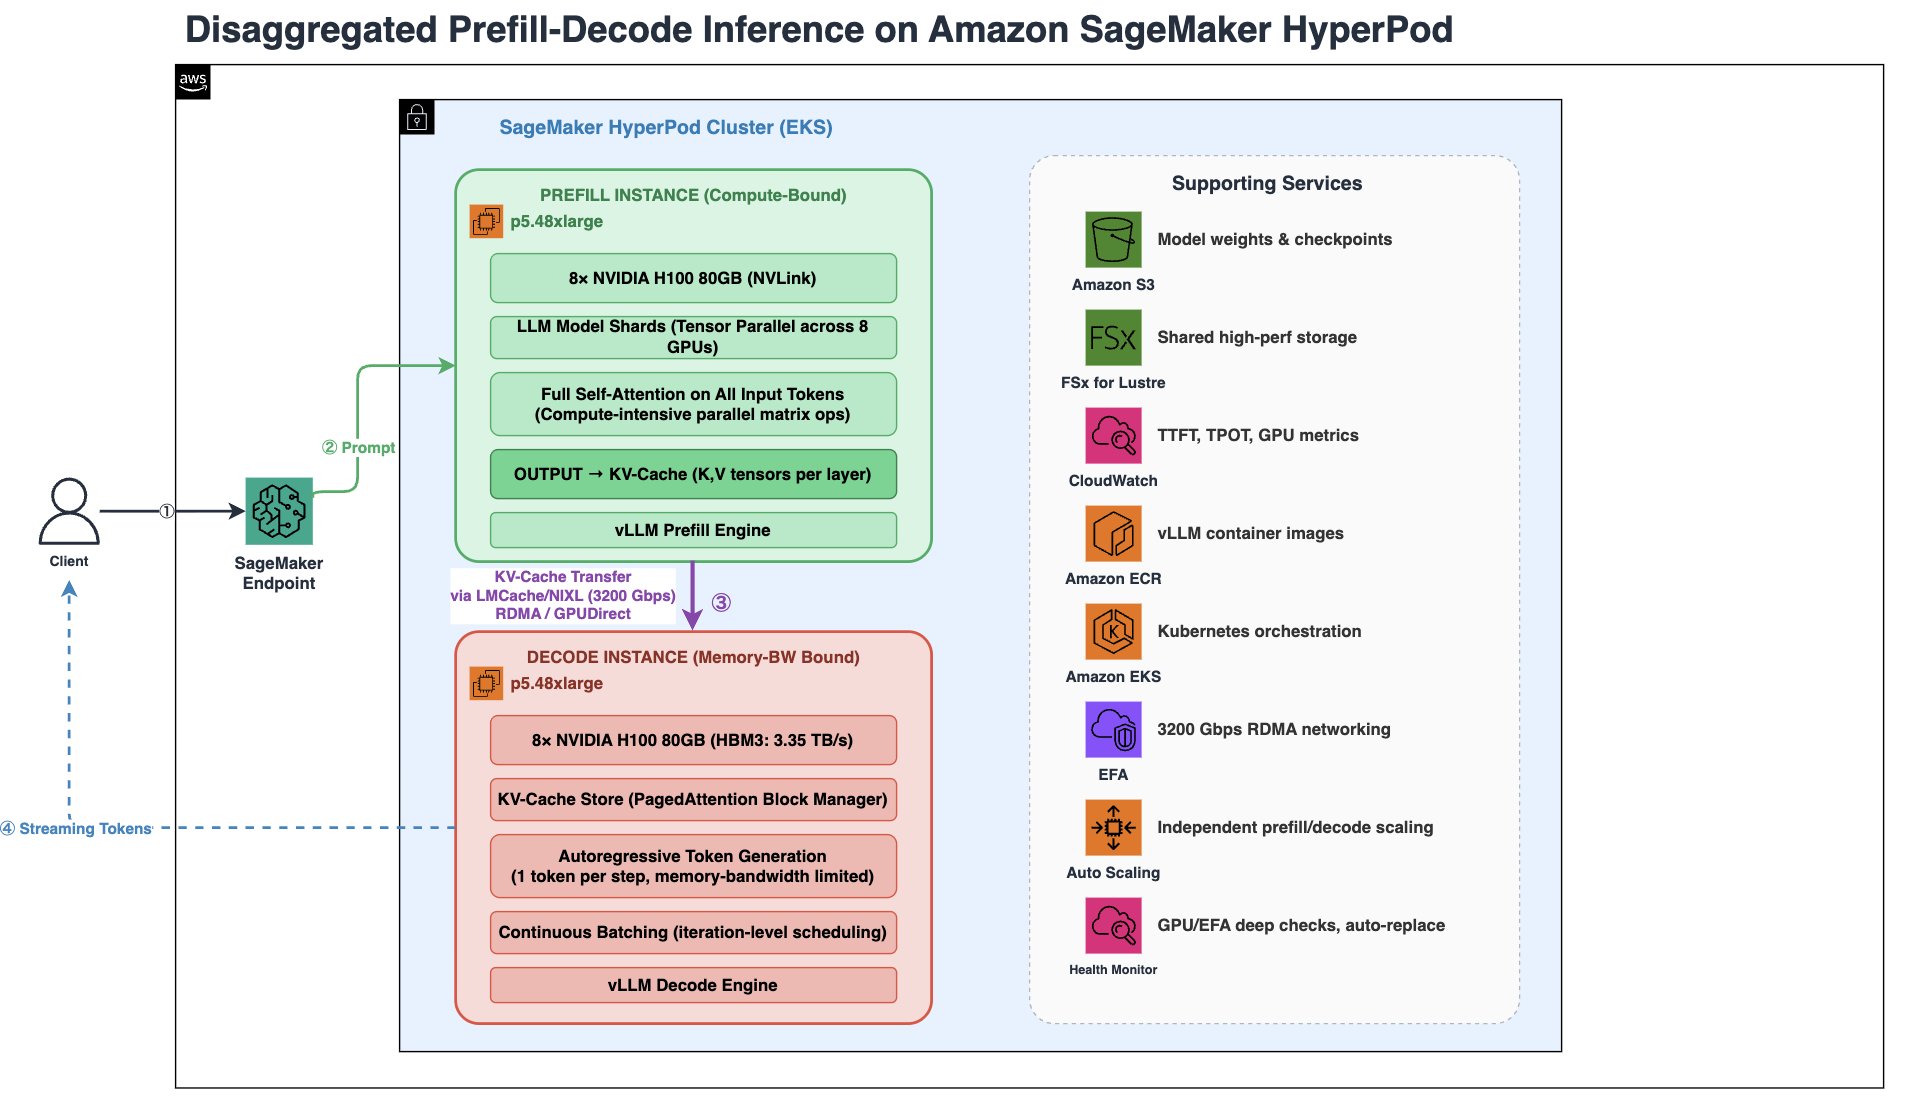
GPU Prefill-Decode Disaggregation — AWS LLM Diagram
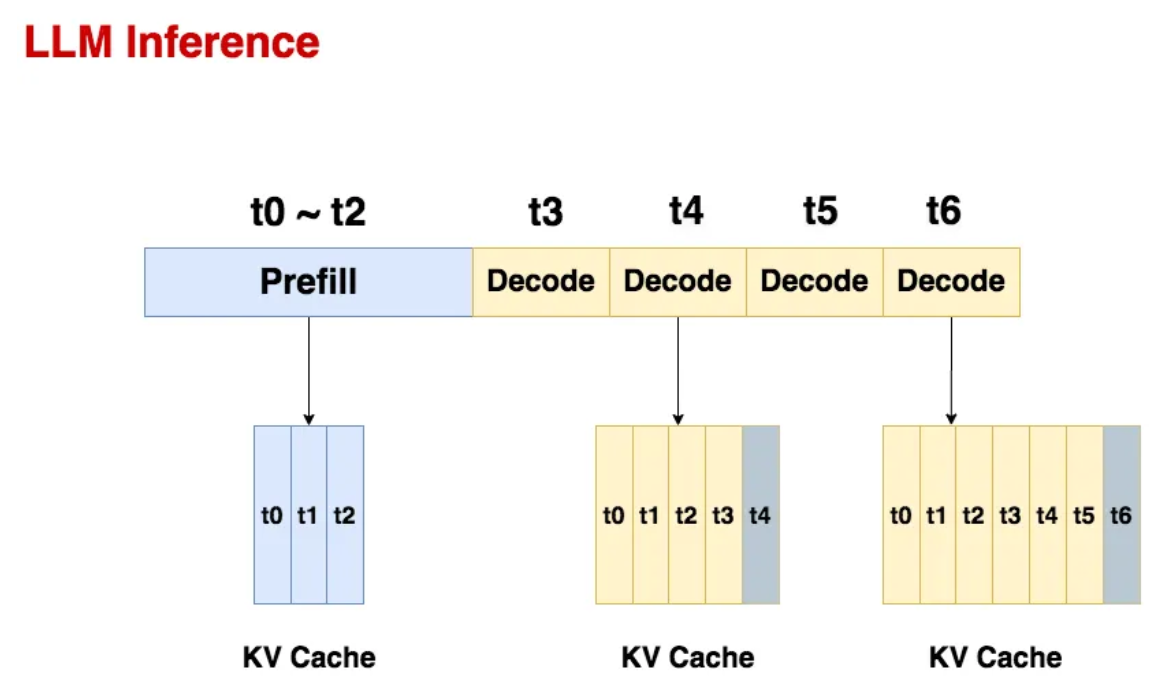
LLM Inference Reading 01 - Prefill Decode Disaggregation - YouTube
Not All Prefills Are Equal: PPD Disaggregation for Multi-turn LLM Serving
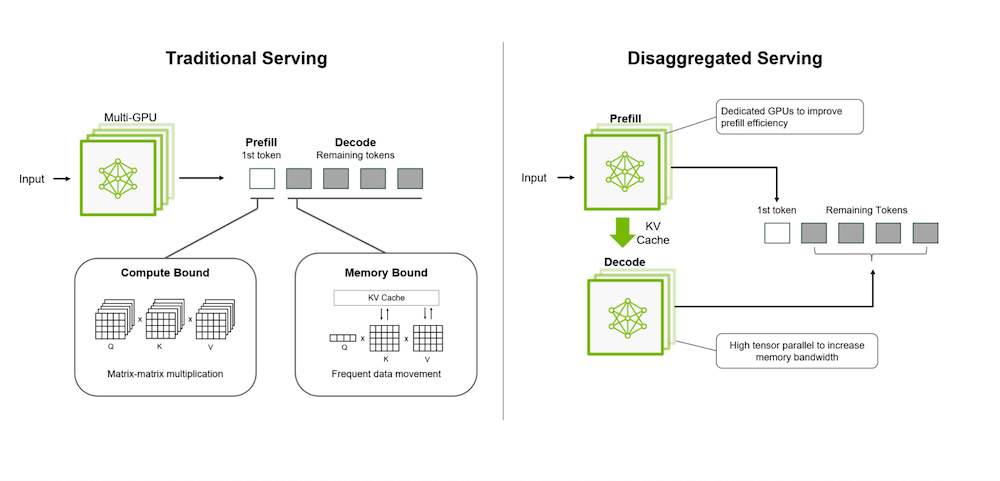
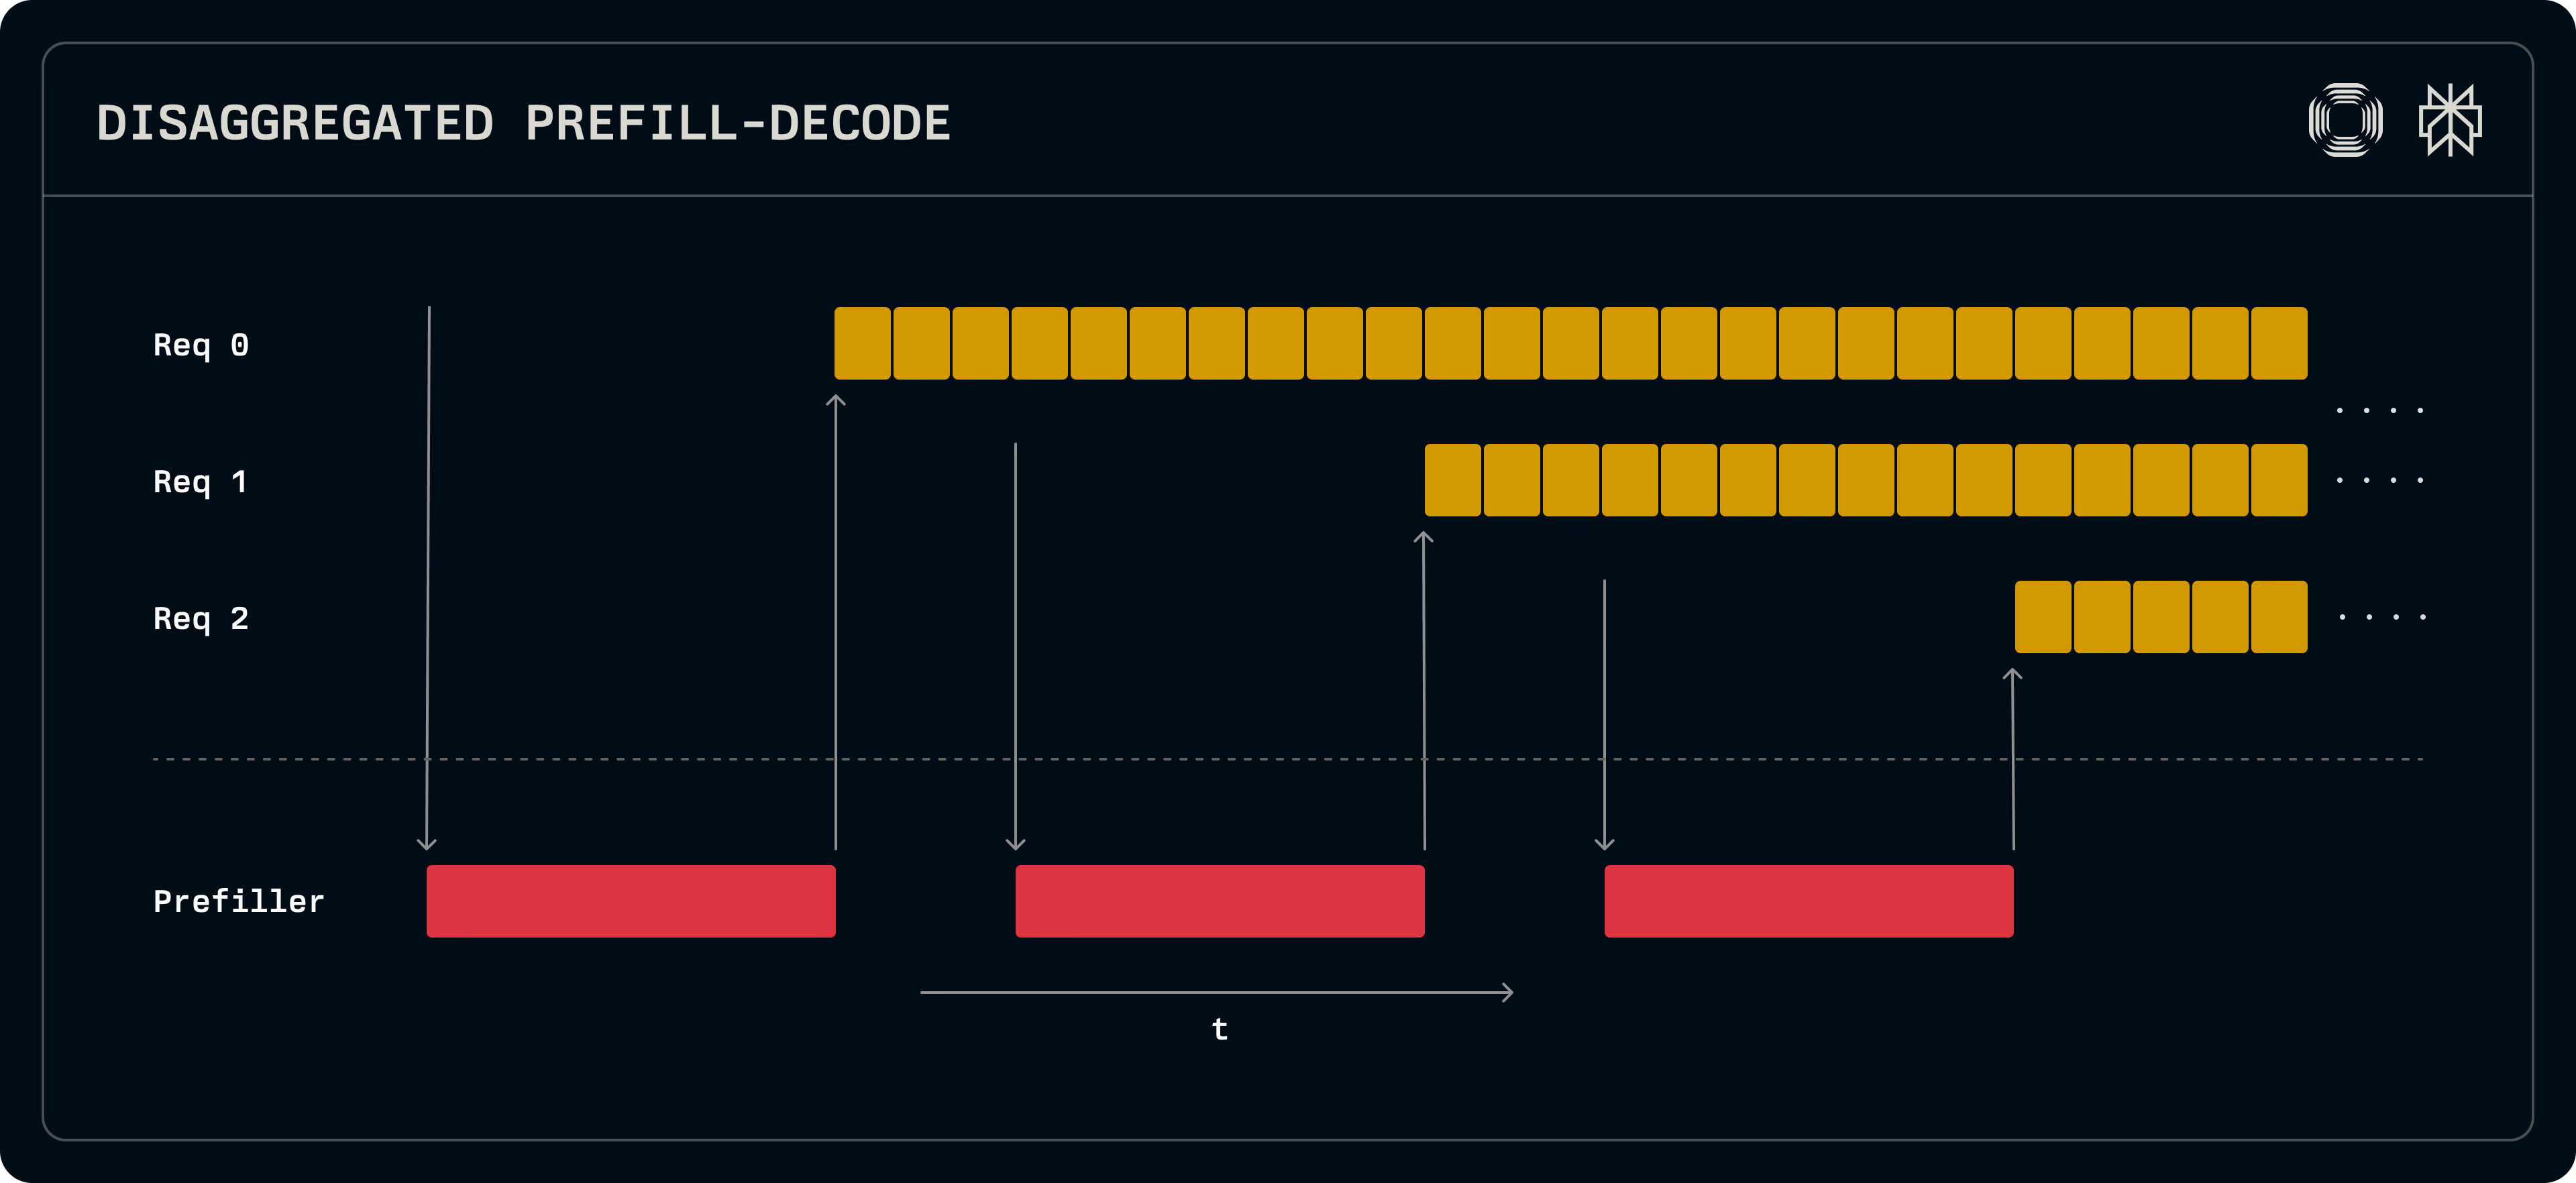
Prefill-decode disaggregation | LLM Inference Handbook
nanoPD: From-Scratch Prefill/Decode Disaggregation Engine for LLM ...
GPU Prefill-Decode Disaggregation — AWS LLM Inference Diagram
Prefill-Decode Disaggregation on GPU Cloud: Split LLM Inference for 2x ...
Aikipedia: Prefill–Decode Disaggregation – Champaign Magazine
Microserving:让Disaggregated LLM Serving可编程 - 知乎
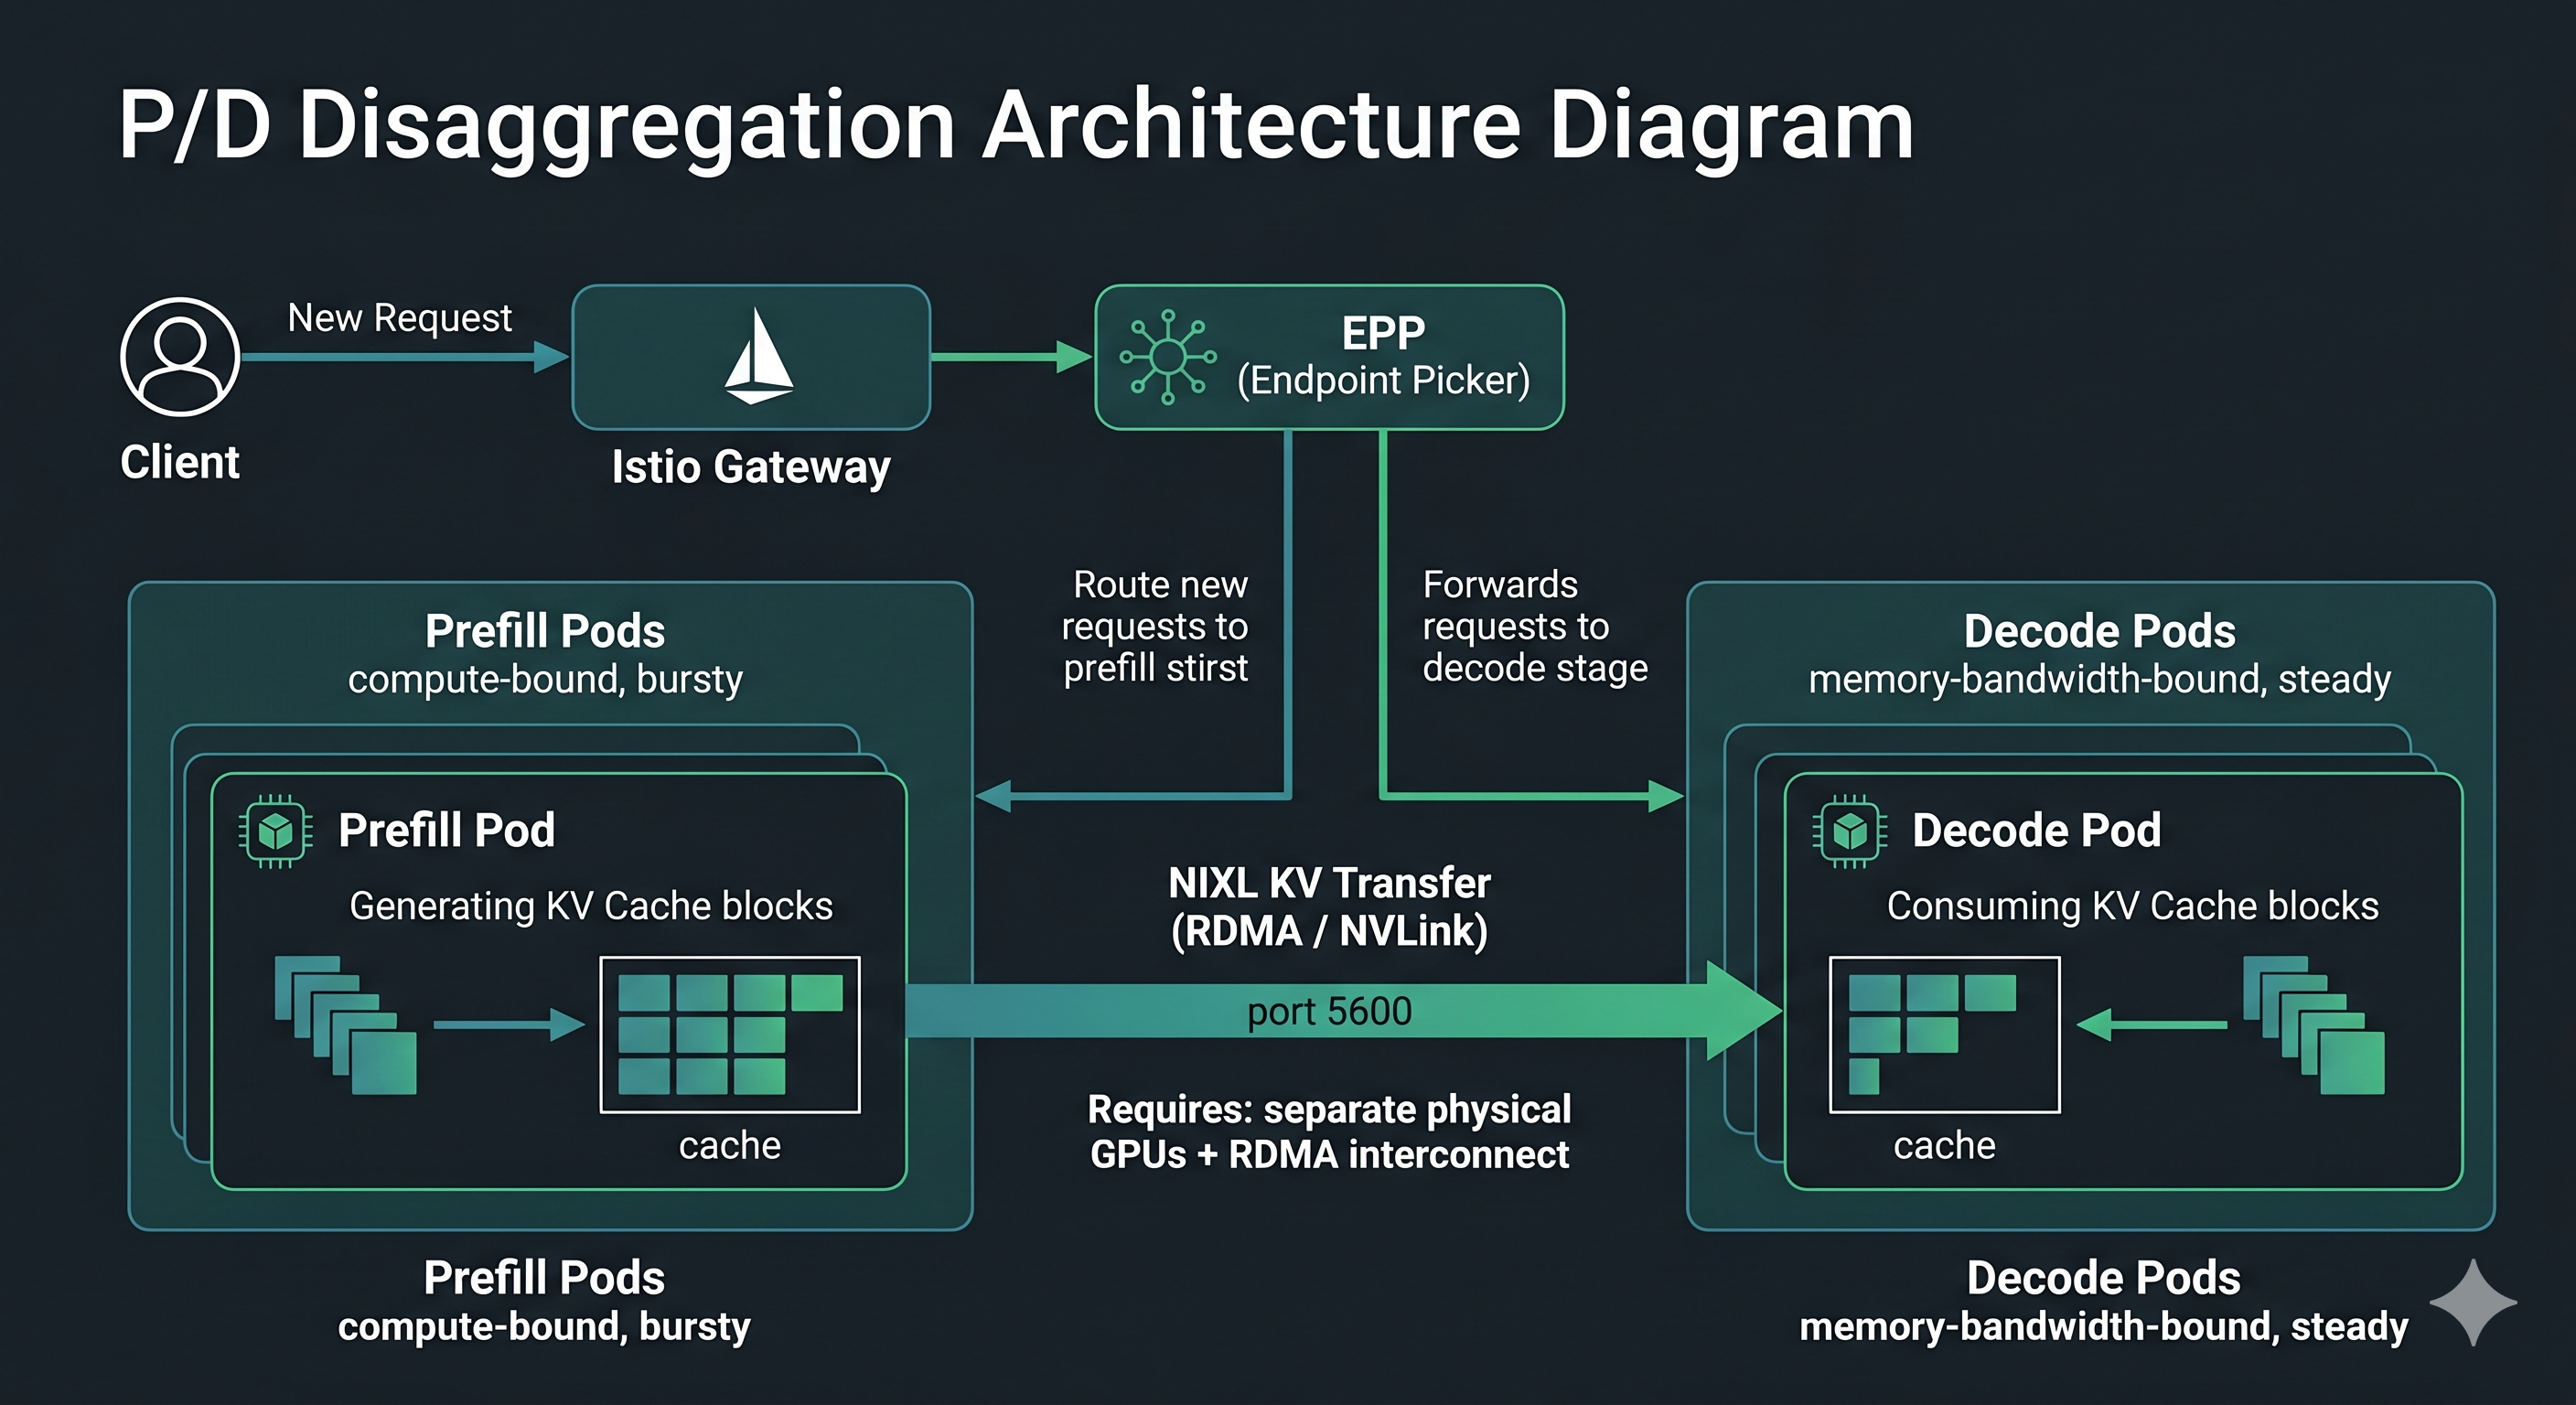
Deploying Disaggregated LLM Inference Workloads on Kubernetes | NVIDIA ...
LLM Inference Optimization Techniques
Review of PD-Disaggregation in LLM Serving
A Use Case of Disaggregated Architecture for LLM Serving: Mooncake | by ...
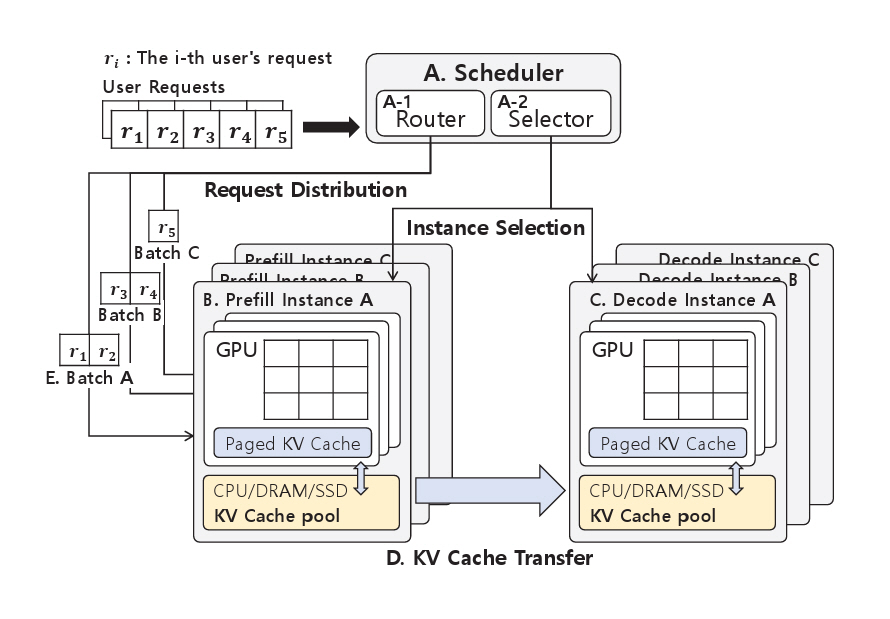
A Dynamic PD-Disaggregation Architecture for Maximizing Goodput in LLM ...
LLM 추론 성능 향상을 위한 Disaggregated Prefill 기술 동향
Throughput is Not All You Need: Maximizing Goodput in LLM Serving using ...
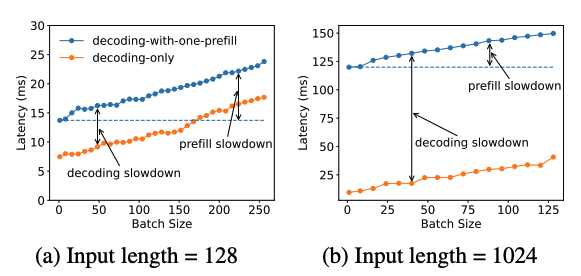
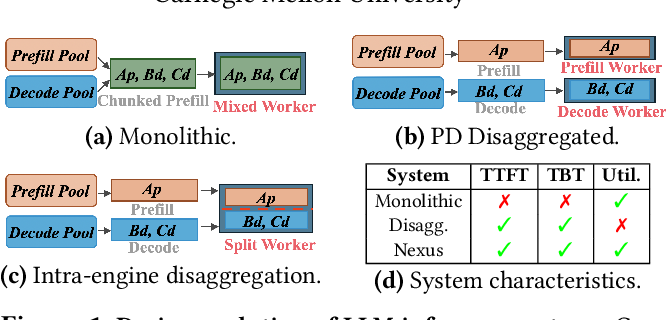
Paper page - Nexus:Proactive Intra-GPU Disaggregation of Prefill and ...
Splitting LLM inference across different hardware platforms | Gimlet Blog
llm-d on Amazon EKS で Prefill/Decode Disaggregation 検証環境を構築する
[论文评述] Efficiently Serving Large Multimodal Models Using EPD Disaggregation
From Attention to Disaggregation: Tracing the Evolution of LLM ...
A Practical Guide to LLM Inference at Scale
Disaggregated prefill and decode for LLM inference on SageMaker ...
Disaggregation in Large Language Models: the Next Evolution in AI ...
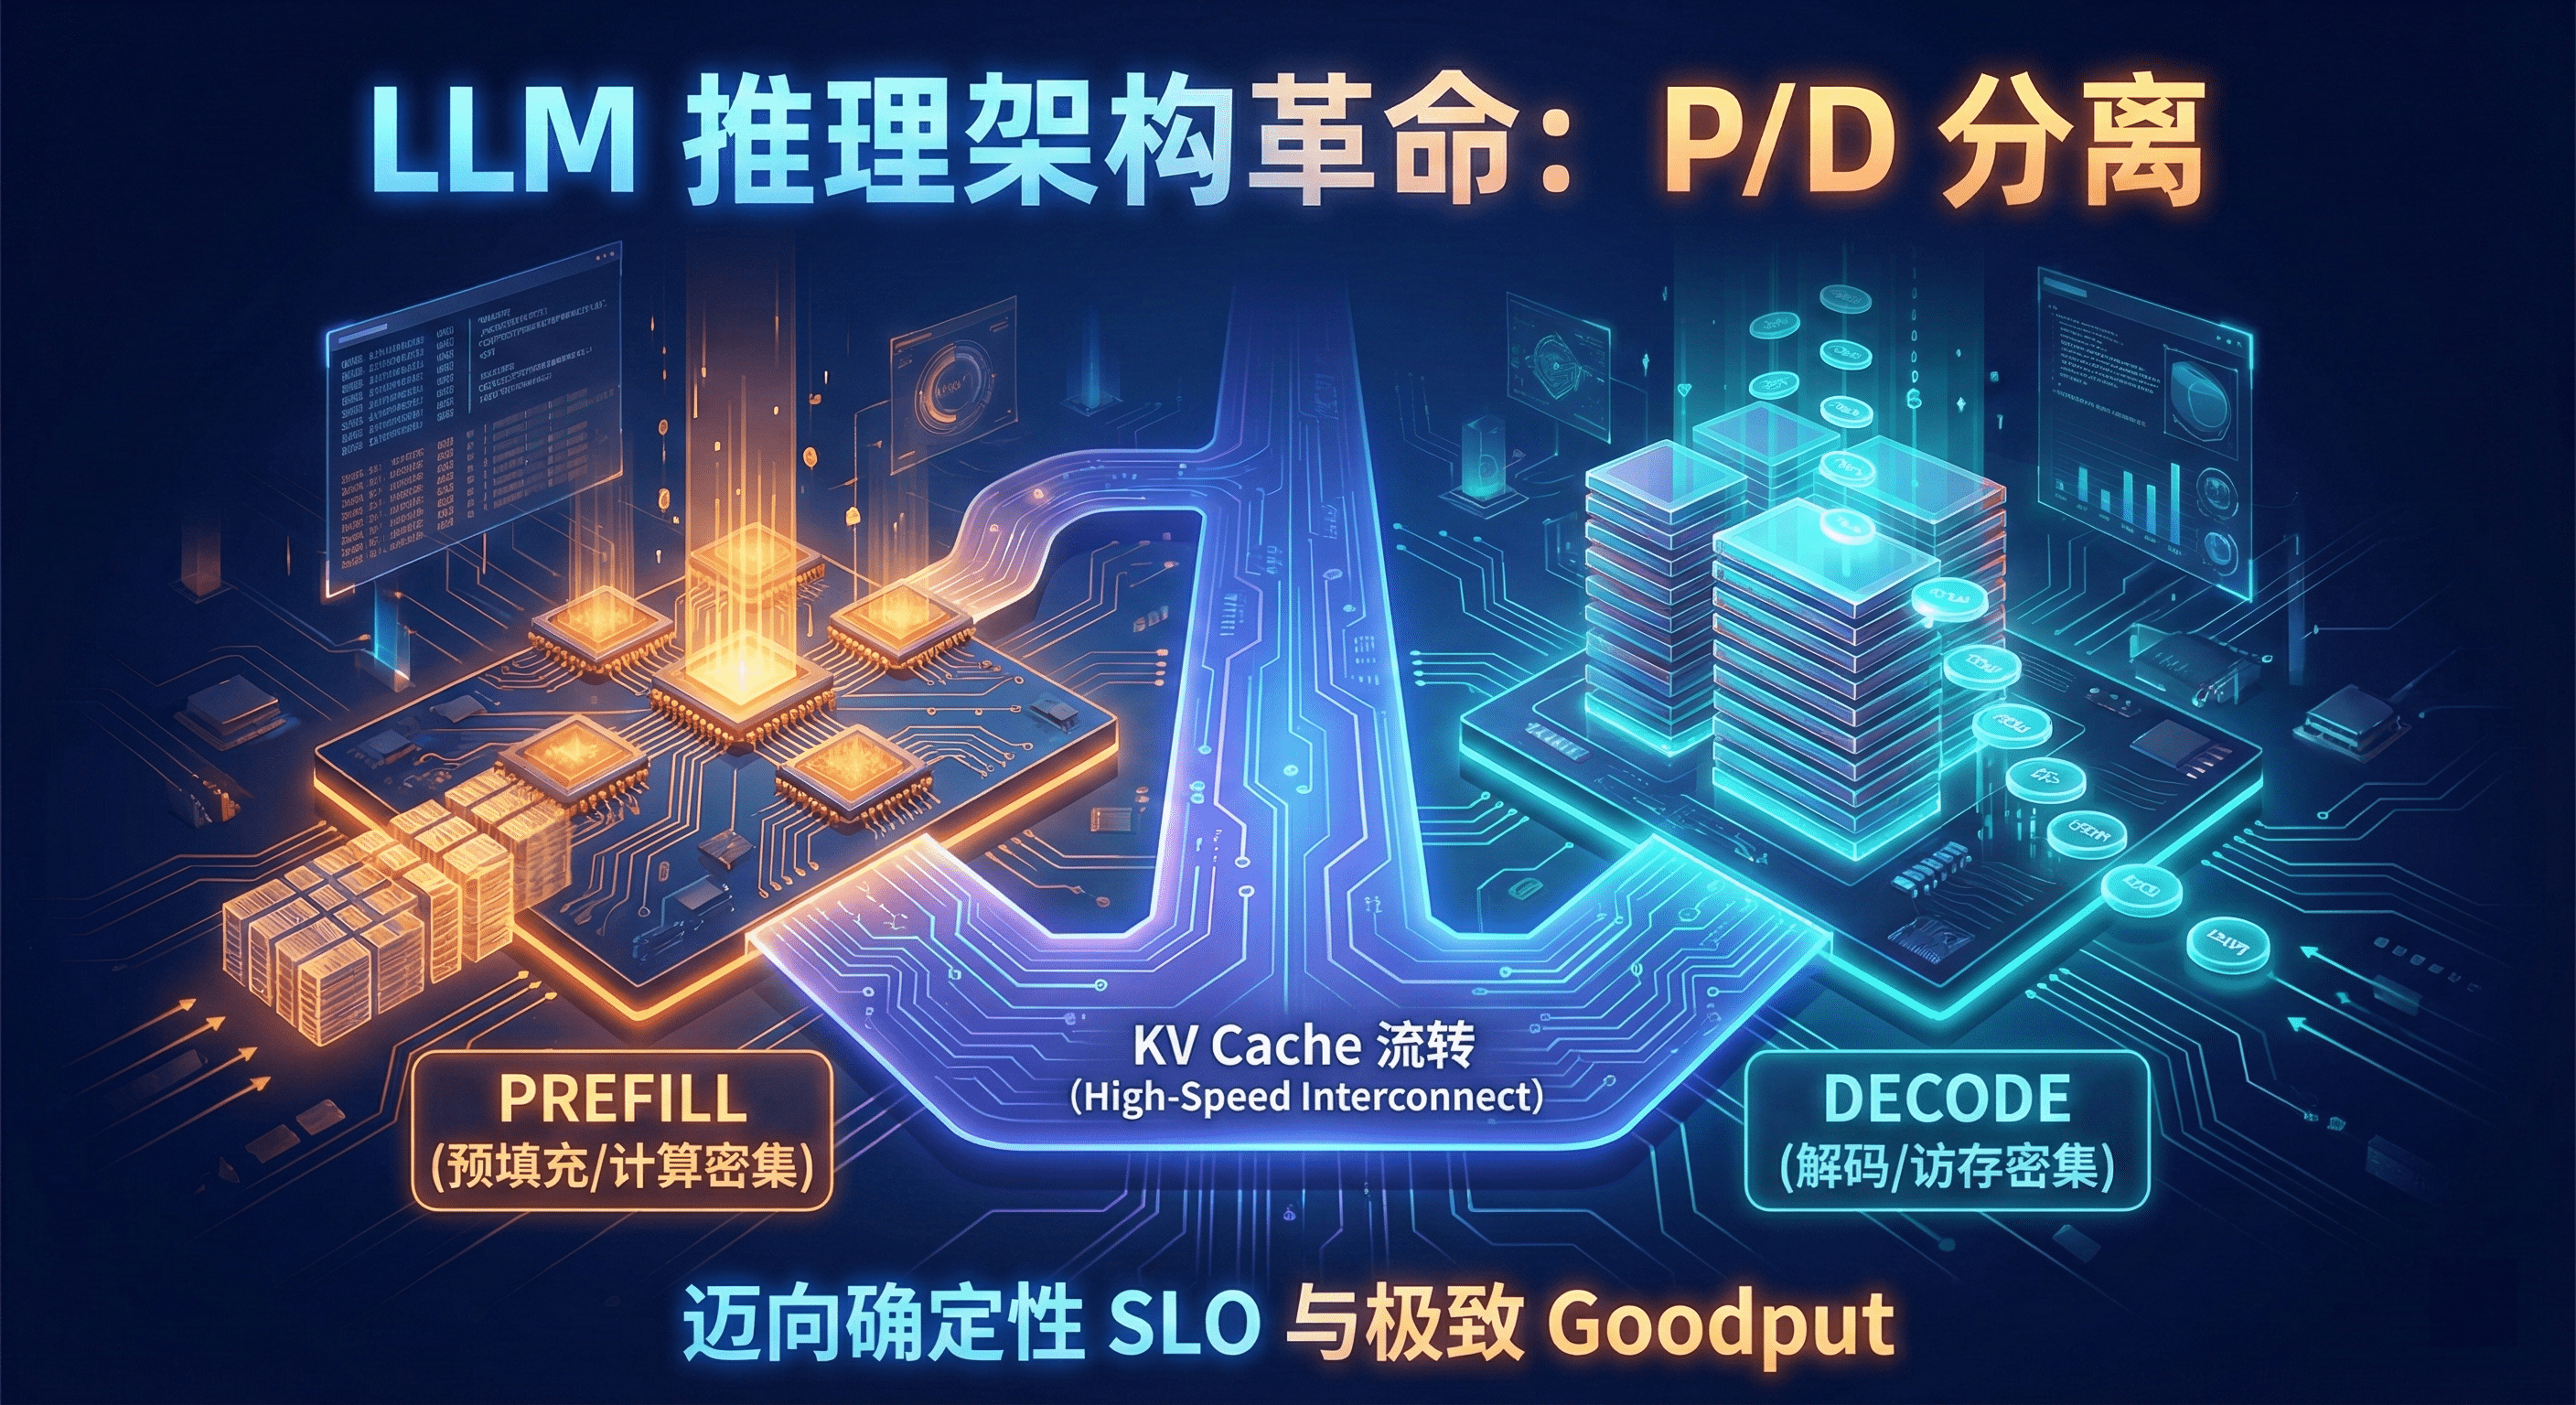
LLM 推理架构的存算分离革命:P/D 分离技术深度解析
Figure 1 from Nexus:Proactive Intra-GPU Disaggregation of Prefill and ...
Method for aggregating unstructured data using LLM
PPD: Not All Prefills Are Equal -- PPD Disaggregation for Multi-turn ...
[논문 리뷰] Mooncake: A KVCache-centric Disaggregated Architecture for LLM ...
[논문 리뷰] Efficient Multi-round LLM Inference over Disaggregated Serving
LLM Inference on H800: A Disaggregated Architecture Guide | LLM ...
Deploy a Dynamo inference service with PD disaggregation - Container ...
LLM Disaggregated Serving怎麼落地?Dynamo、NIXL、Router與條件式P/D
论文分享:Inference without Interference: Disaggregate LLM Inference for ...
P/D Disaggregation on a Single GPU — What the Architecture Actually ...
Unpacking LLM Inference: Why Disaggregated Architecture is getting ...
LLM Serving有效吞吐量的最大化实现 - 智源社区
Prefill-Decode Disaggregation: The Architecture Shift Redefining LLM ...
MemServe: Context Caching for Disaggregated LLM Serving with Elastic ...
Cache-aware prefill–decode disaggregation (CPD) for up to 40% faster ...
Disaggregated Serving in TensorRT LLM — TensorRT LLM
Arrow: Adaptive Scheduling Mechanisms for Disaggregated LLM Inference ...
Prefill-Decode Disaggregation and Parallelism | bentoml/llm-inference ...
Accelerating LLM Inference: Decoupling Prefill and Decode (PD ...
Unlocking MoE Efficiency: How MegaScale-Infer Slashes LLM Serving Costs ...
Prefill/Decode Disaggregation | llm-d/llm-d | DeepWiki
[논문 리뷰] Theoretically Optimal Attention/FFN Ratios in Disaggregated LLM ...
[논문 리뷰] A Dynamic PD-Disaggregation Architecture for Maximizing Goodput ...
DOPD: A Dynamic PD-Disaggregation Architecture for Maximizing Goodput ...
The Evolution of the Inference Stack for LLMs — jeromemassot-ai
Disaggregated Inference: 18 Months Later | Hao AI Lab @ UCSD
PD分离定制化芯片 (arXiv 2025):SPAD: Specialized Prefill and Decode Hardware ...
Introduction to distributed inference with llm-d | Red Hat Developer
打造高性能大模型推理平台之Prefill、Decode分离系列(一):微软新作SplitWise,通过将PD分离提高GPU的利用率哆啦不是梦 ...
Technologies | Atomic Loops
This AI Paper from ByteDance Introduces MegaScale-Infer: A ...
Understanding disaggregated GenAI model serving with llm-d | Canonical
Figure 1 from SLO-Aware Compute Resource Allocation for Prefill-Decode ...
LLM大模型系列(十):深度解析 Prefill-Decode 分离式部署架构_prefill和decode-CSDN博客
[论文评述] SPAD: Specialized Prefill and Decode Hardware for Disaggregated ...
[论文评述] Trinity: Disaggregating Vector Search from Prefill-Decode ...
さくらインターネットの道下さんの記事、かなり網羅的にLLM Inferenceについてまとめられており、オススメです。 Chunked ...
[논문 리뷰] TD-Pipe: Temporally-Disaggregated Pipeline Parallelism ...
传统ML推理 vs LLM推理:为什么大模型需要专属高性能推理引擎?-CSDN博客
vLLM PD分离方案浅析 - 知乎
vLLM Large Scale Serving: DeepSeek @ 2.2k tok/s/H200 with Wide-EP ...
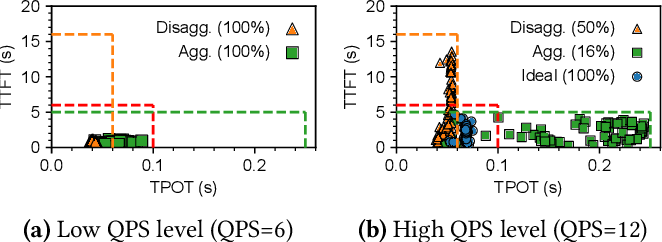
(PDF) Prefill-Decode Aggregation or Disaggregation? Unifying Both for ...
llm-d/guides/pd-disaggregation/scheduler at main · llm-d/llm-d · GitHub
I Think, Therefore I Diffuse: Enabling Multimodal In-Context Reasoning ...
Figure 2 from SLO-Aware Compute Resource Allocation for Prefill-Decode ...
Parallellogramformet Bygning Basic Terminologies Large Language Models
DistTrain: Addressing Model and Data Heterogeneity with Disaggregated ...
xLLM Technical Report
[论文评述] Disaggregated Prefill and Decoding Inference System for Large ...
[Literature Review] SplitZip: Ultra Fast Lossless KV Compression for ...
Introducing Disaggregated Inference on AWS powered by llm-d ...
谈一谈LLM在推荐域的一些理解_recommendation as language processing (rlp): a uni-CSDN博客
[논문 리뷰] PrefillShare: A Shared Prefill Module for KV Reuse in Multi-LLM ...
LoongServe 论文解读:prefill/decode 分离、弹性并行、零 KV Cache 迁移开销 - 知乎
What Disaggregated Data means for LCAs, Eco-Design & DPP - Peftrust ...
[论文评述] Taming the Chaos: Coordinated Autoscaling for Heterogeneous and ...
DPDisc: From Factoid Questions to Data Product Requests for Open-World ...
Figure 2 from Prefill-Decode Aggregation or Disaggregation? Unifying ...
LLM大模型系列(十):深度解析 Prefill-Decode 分离式部署架构_mob64ca14095513的技术博客_51CTO博客
GPUs and Transformers: Understanding Inference and Its Optimizations