Showing 119 of 119on this page. Filters & sort apply to loaded results; URL updates for sharing.119 of 119 on this page
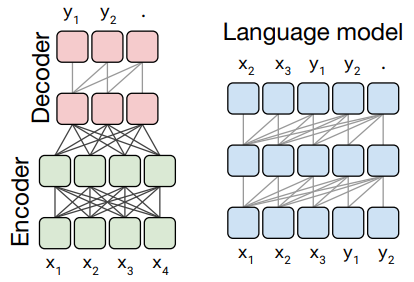
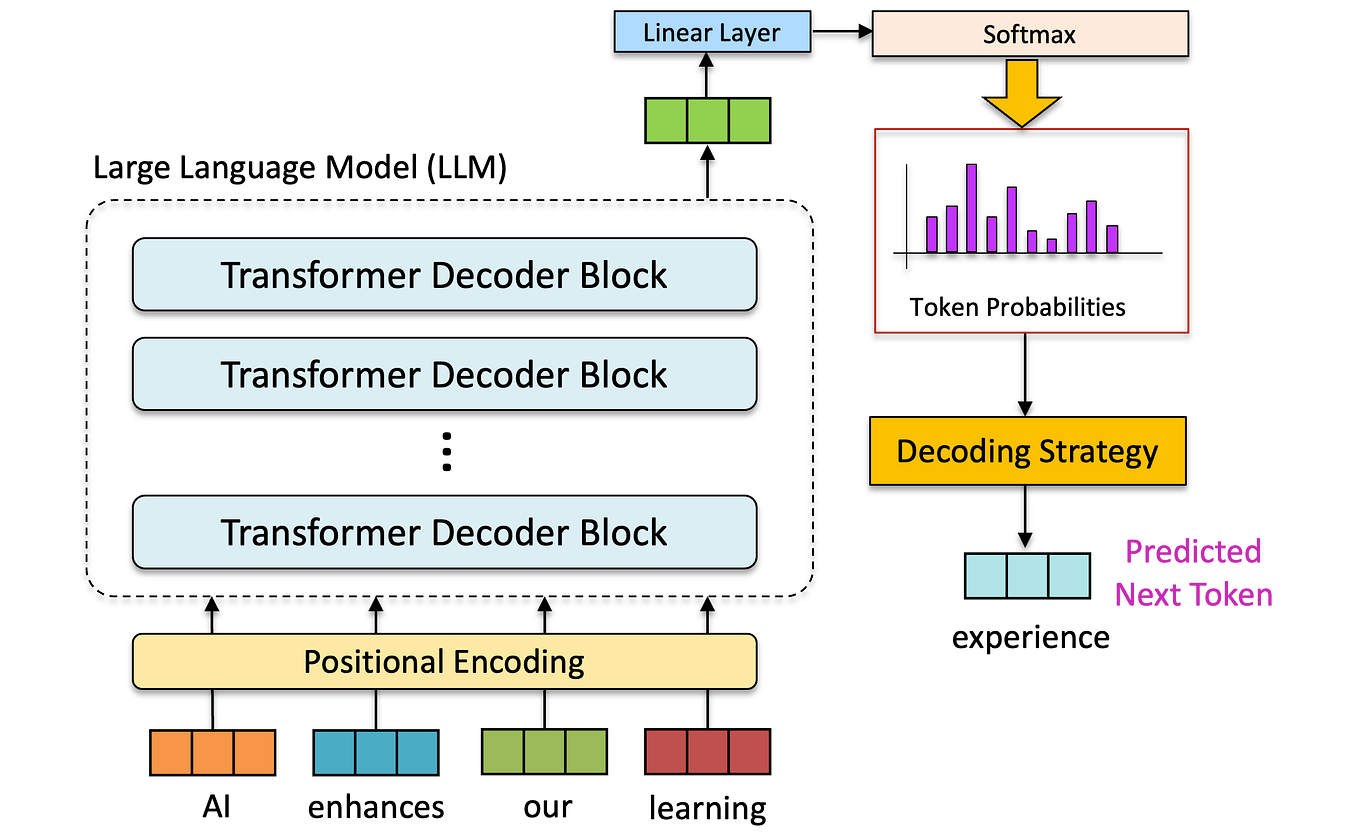
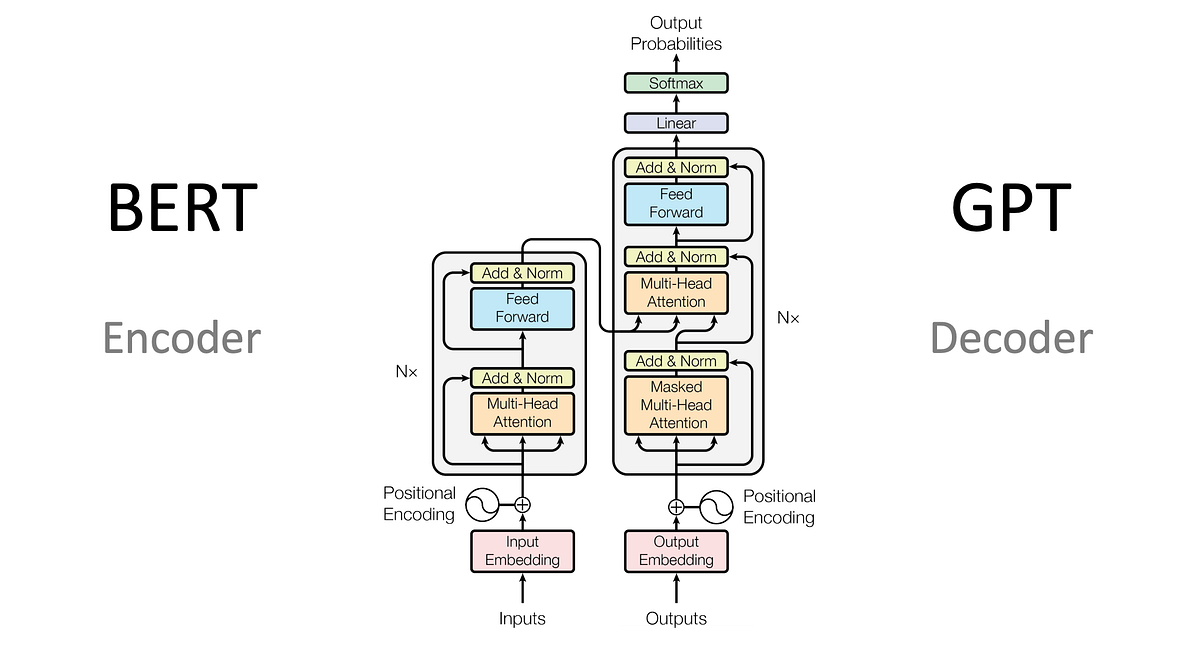
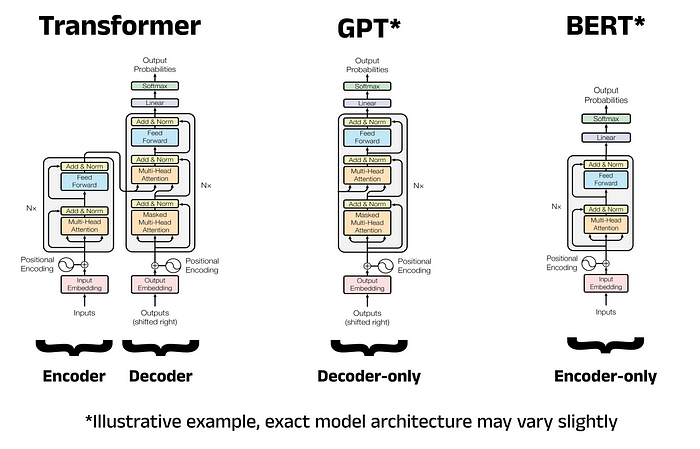
Discovering LLM Structures: Decoder-only, Encoder-only, or Decoder ...
Getting an LLM running is only the opening act. As traffic grows ...
LLM Foundations: Constructing and Training Decoder-Only Transformers ...
Mastering LLM Techniques: Training – GIXtools
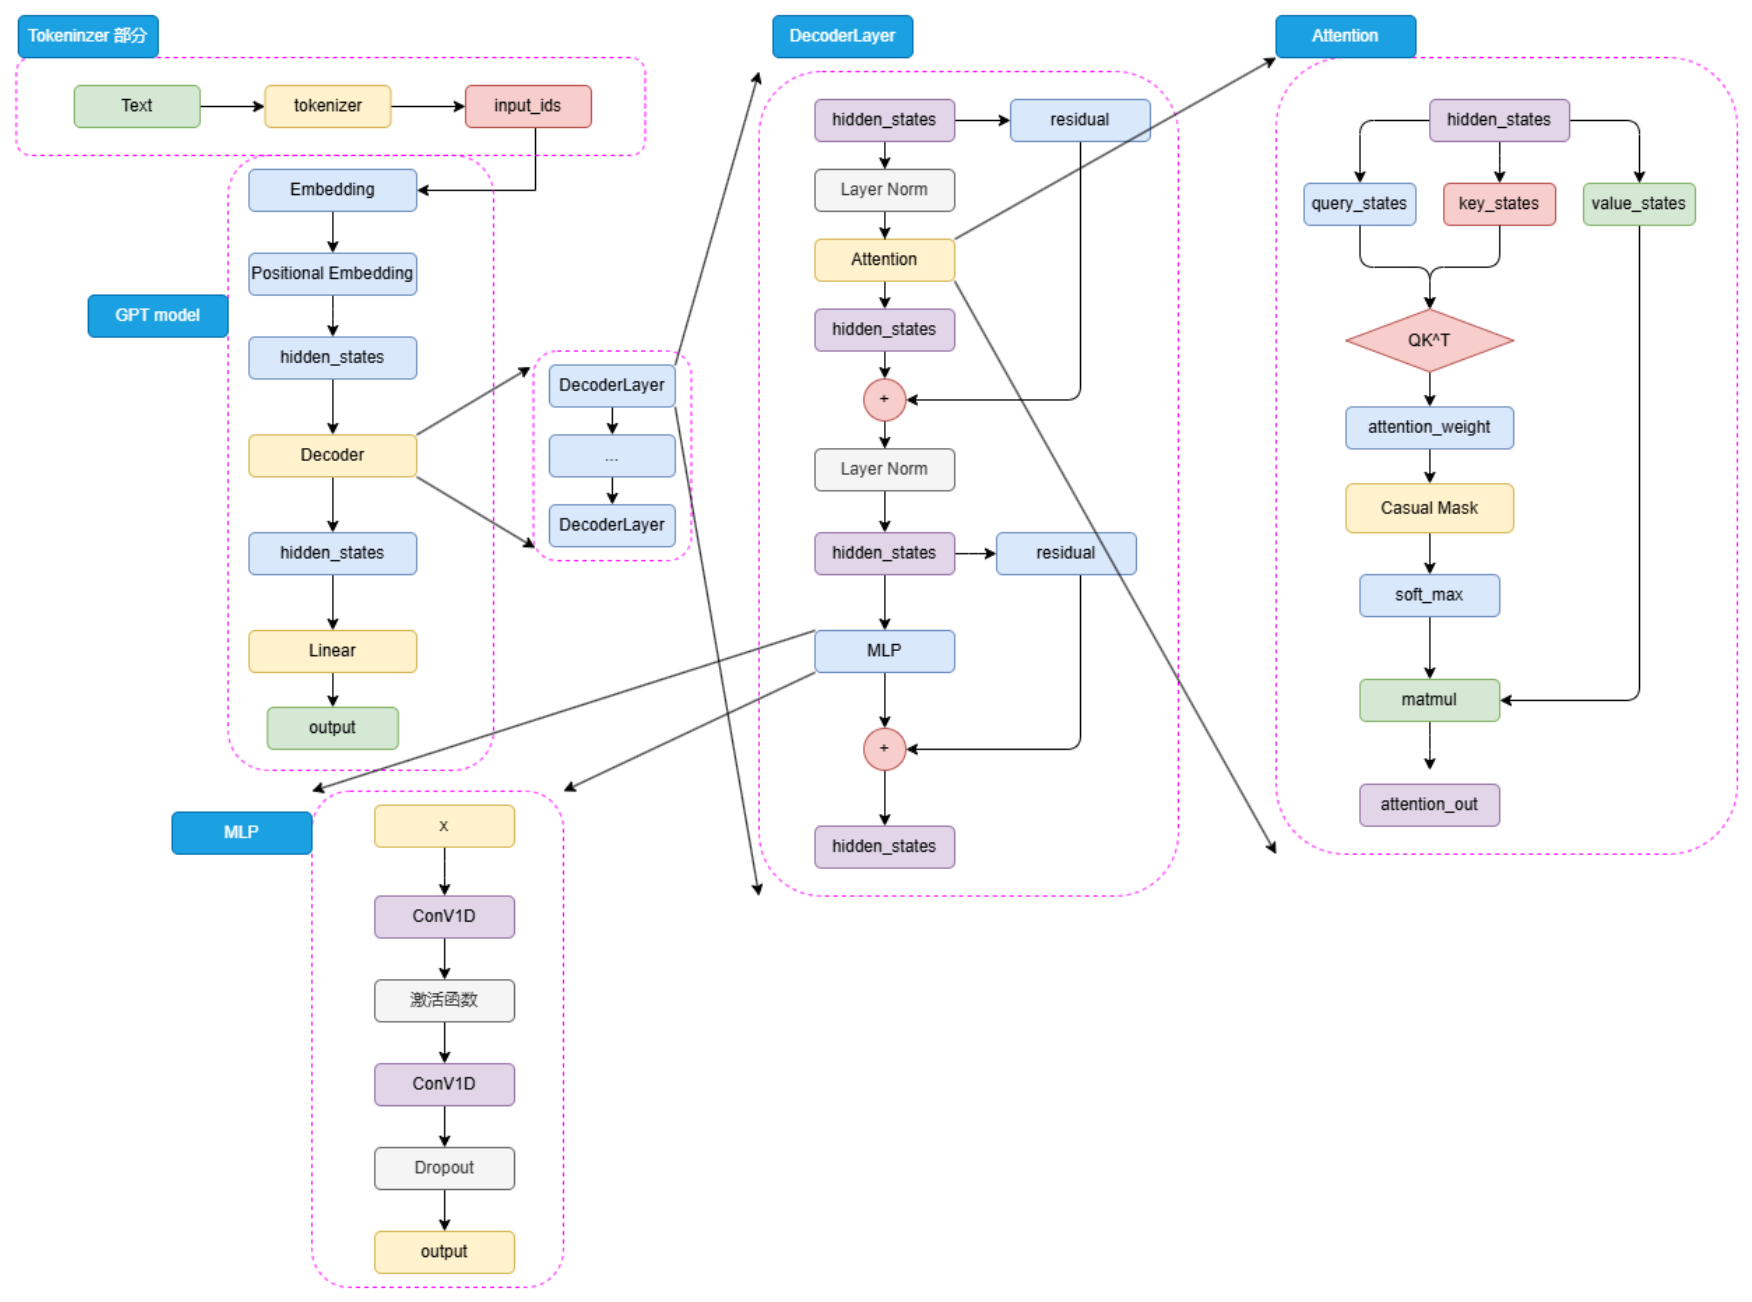
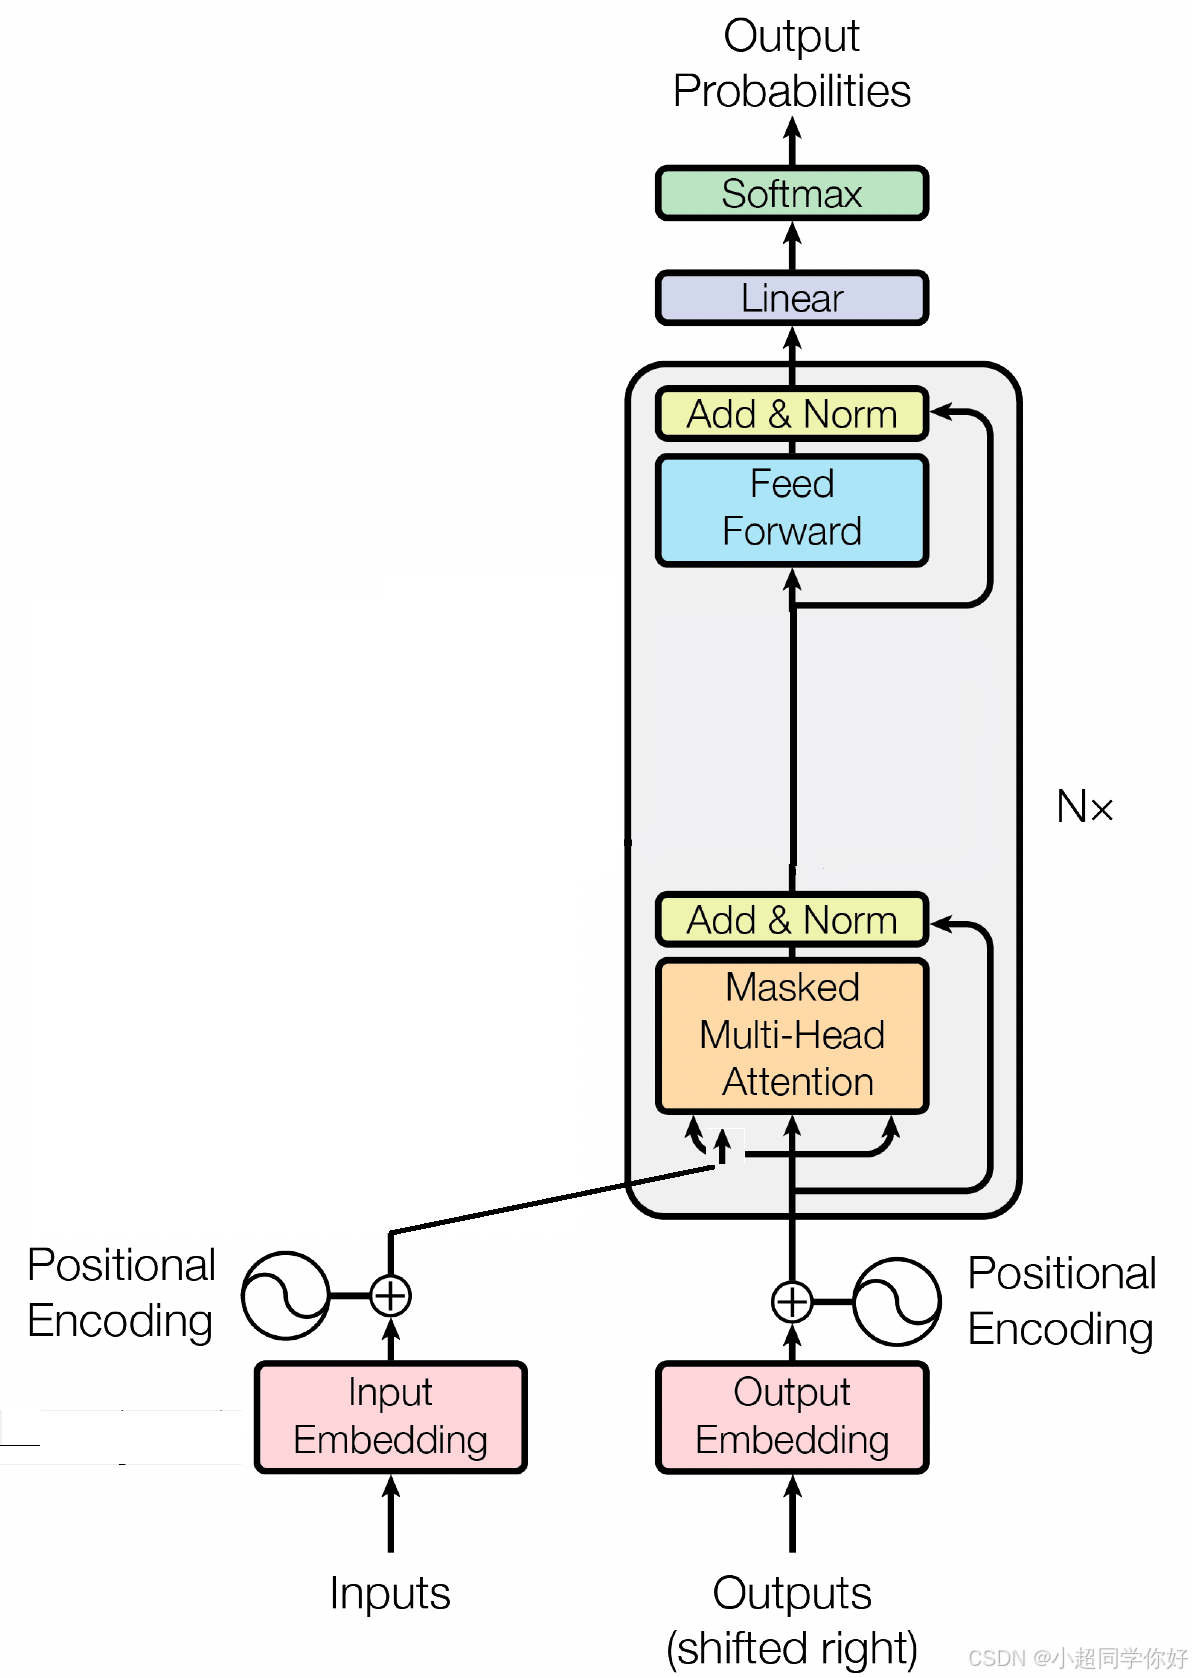
从 GPT 到 LLaMA:解密 LLM 的核心架构——Decoder-Only 模型_decoder only架构图-CSDN博客
Why decoder-only? LLM架构的演化之路_为什么 decoder only-CSDN博客
LLM Architecture: Possible Model Configurations in 2026 | Label Your Data
LLM Architecture Explained: Exploring the Heart of Automation
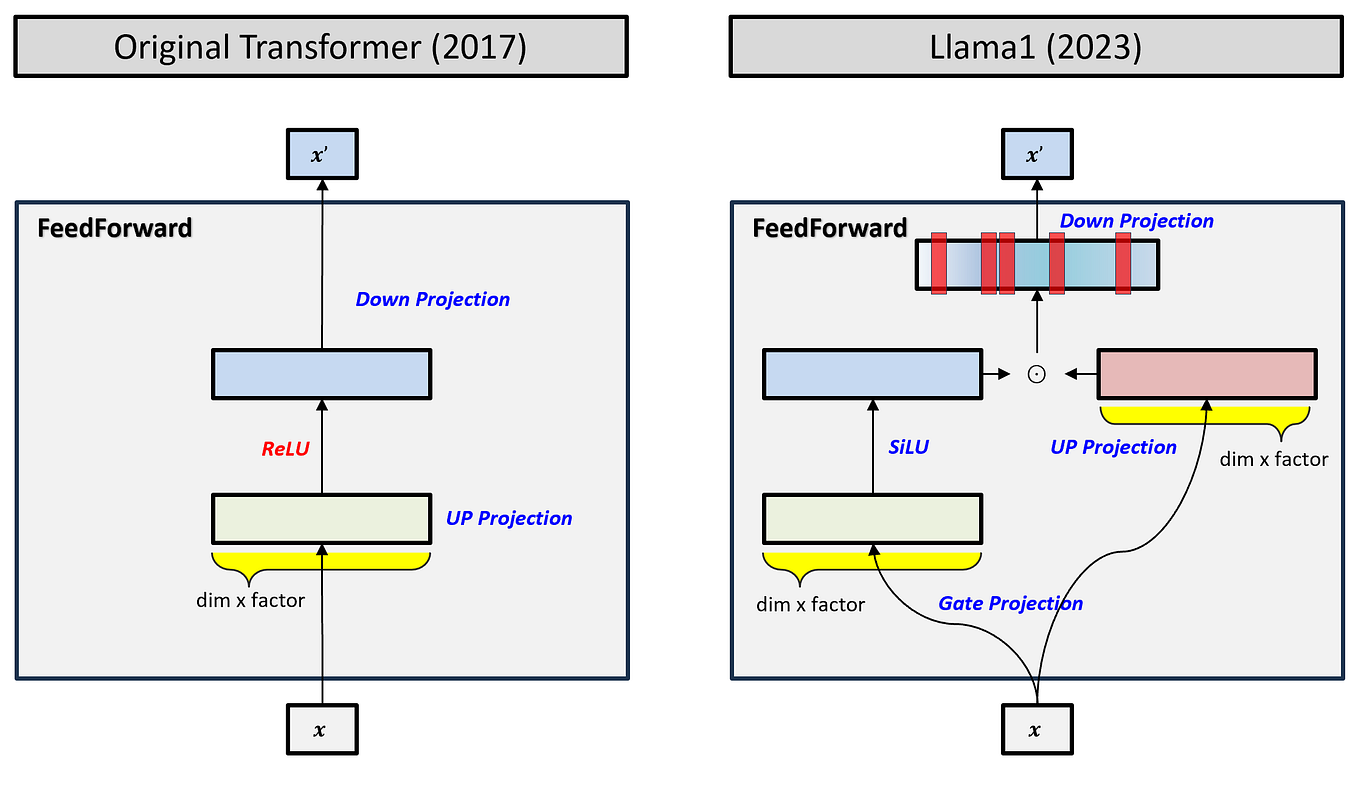
Tweaking the Transformer: LLaMa. Open sourced successor to the Decoder ...
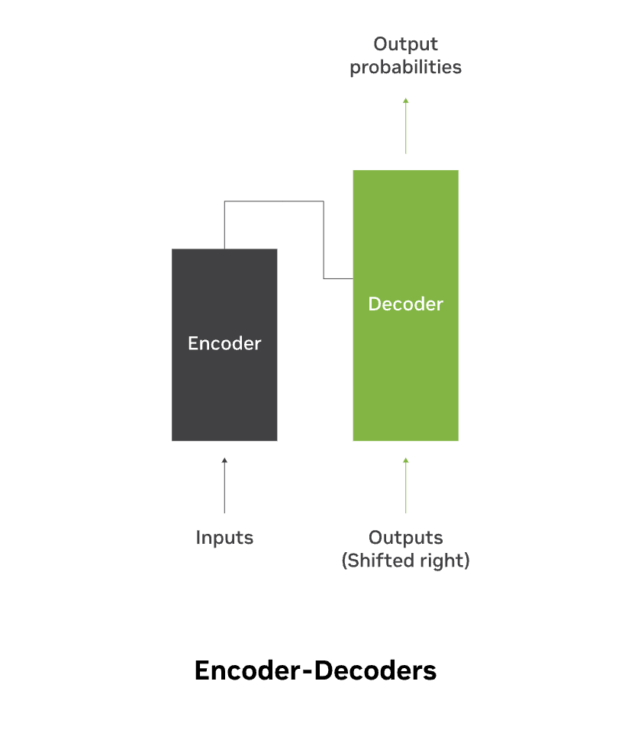
Decoder-Only vs. Encoder–Decoder: What’s the Difference in LLM ...
为什么现代 LLM 都用 Decoder-only:从推理效率说起 - 知乎
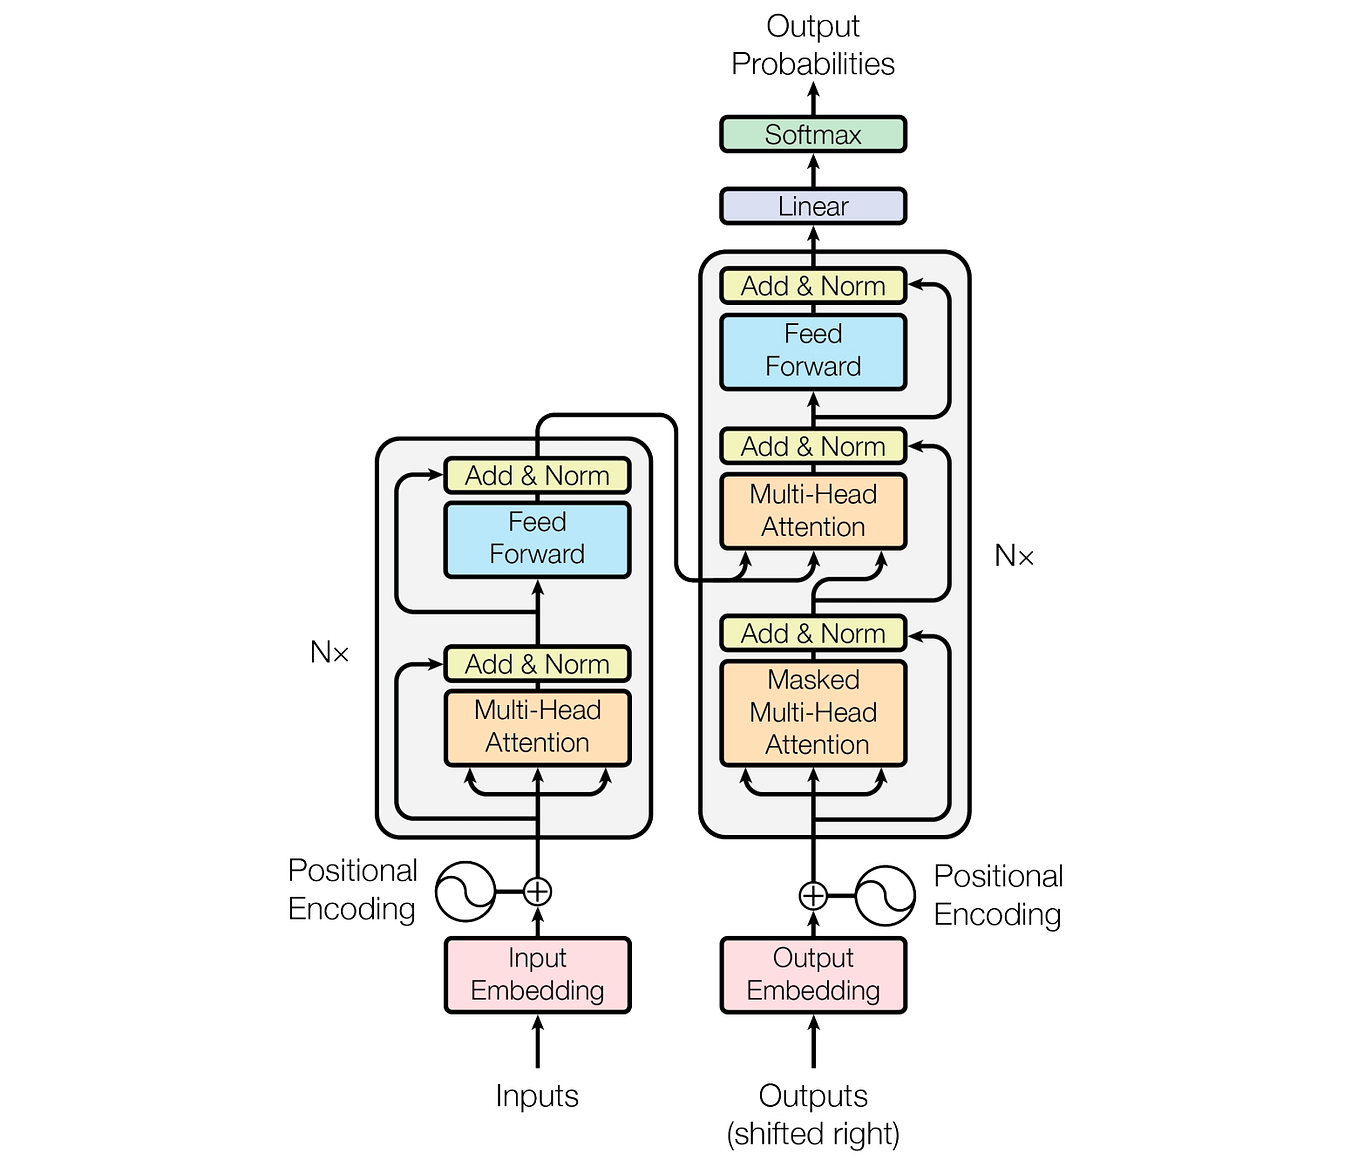
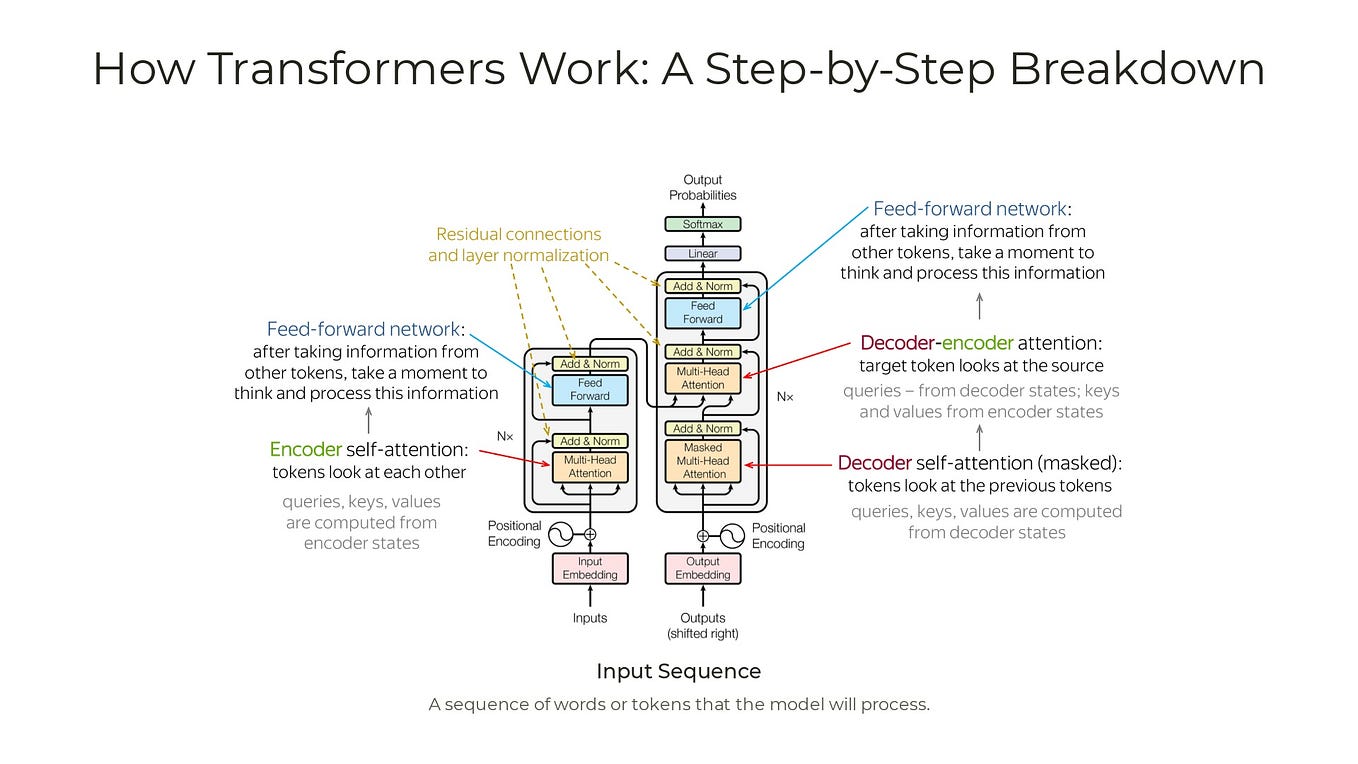
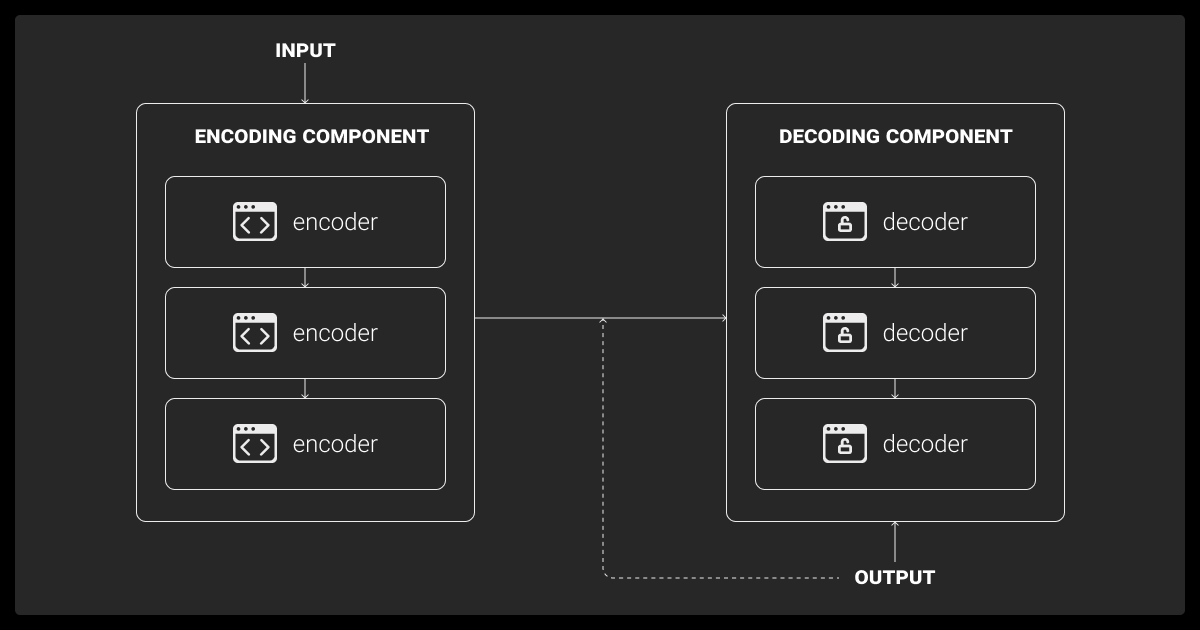
LLM Architectures Explained: Encoder-Decoder Architecture (Part 4) | by ...
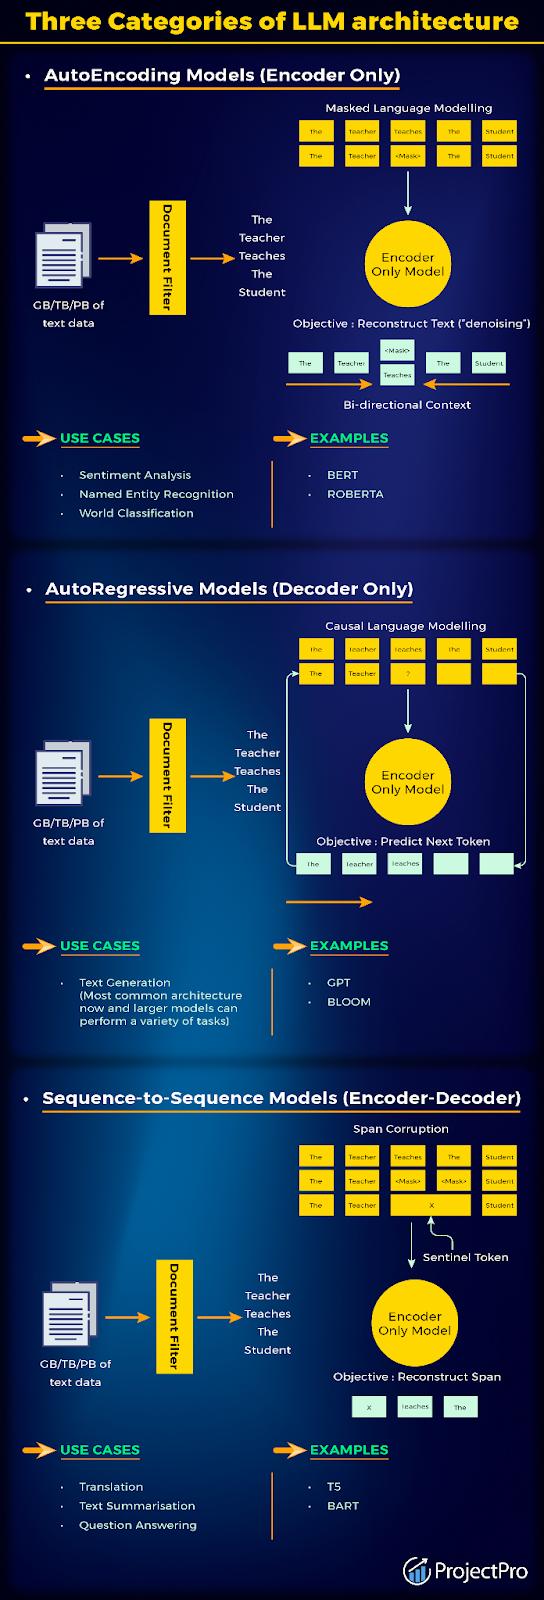
LLM Types: Decoder-Only, Encoder-Decoder, and Encoder-Only Models ...
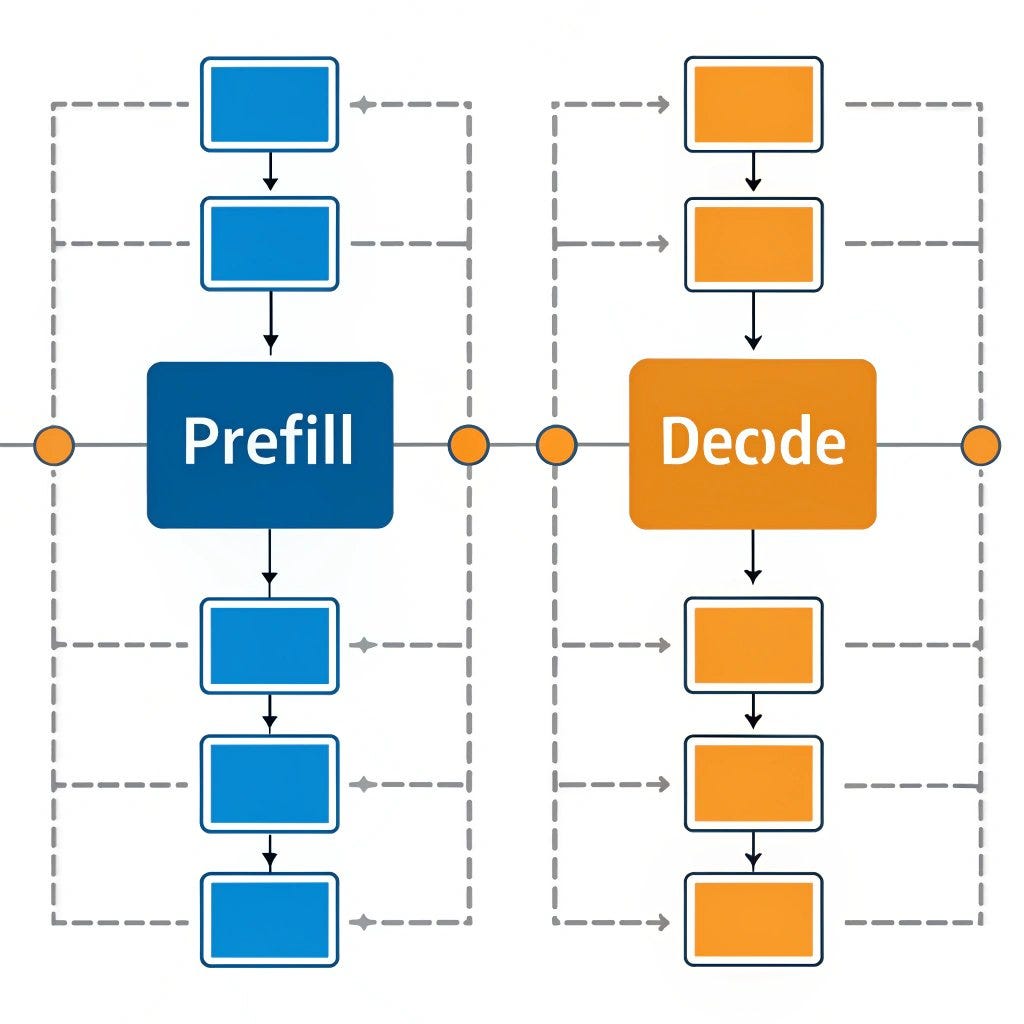
AVB on X: "A 35+ minute visual essay about LLM inferencing, prefill vs ...
Train LLM From Scratch: Pure PyTorch Pipeline From Pile to GRPO ...
AsymFlow: Enabling Long-Context LLM Serving via CPU-GPU Prefill-Decode ...
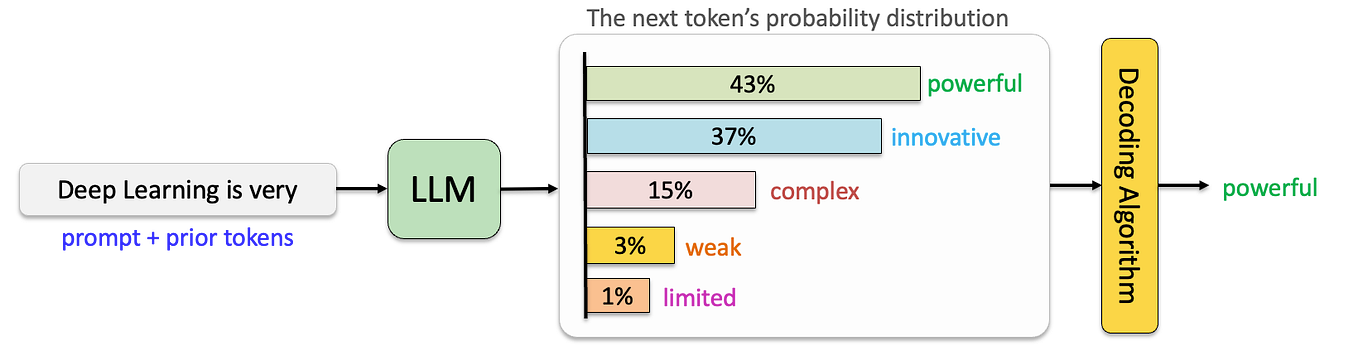
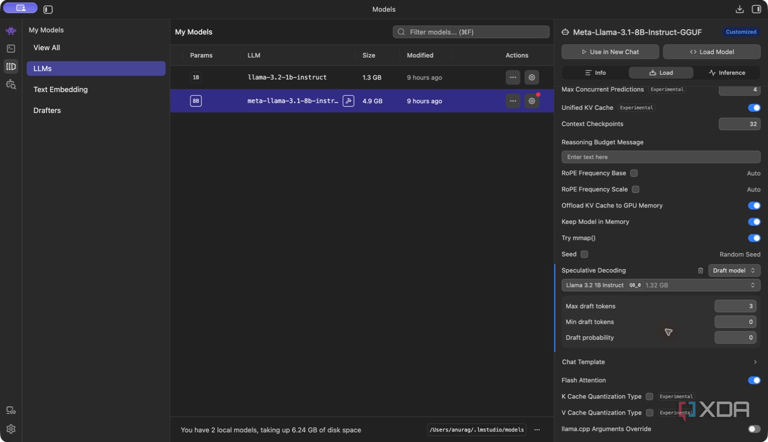
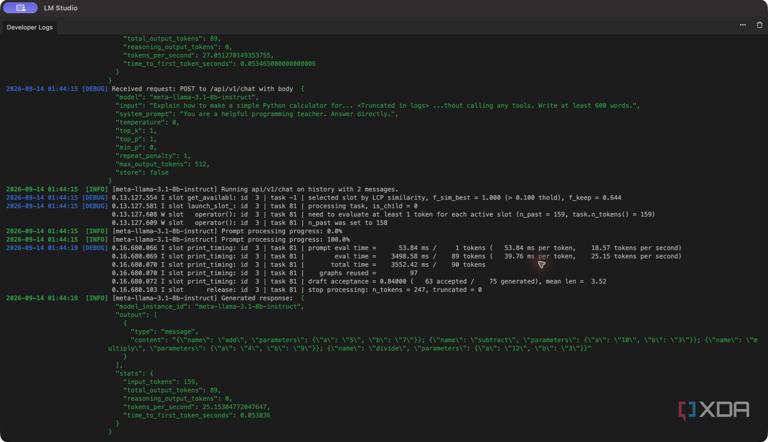
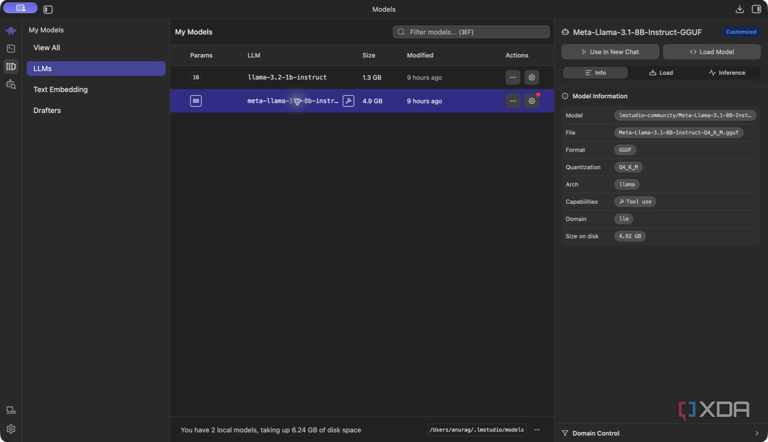
I used speculative decoding to make my local LLM feel instant, and now ...
[GDGoC LLM 스터디] 미니 GPT를 100배 키우고 맥북 GPU로 학습시켜 봤어요
What Is a Transformer? The Architecture Behind Every Modern LLM (2026 ...
Best Open Source LLM Models for 16GB VRAM in 2026 — Tested… | Pactentia
WAQ-LLM: Optimizing Multi-Instance LLM Deployment via Workload-Aware ...
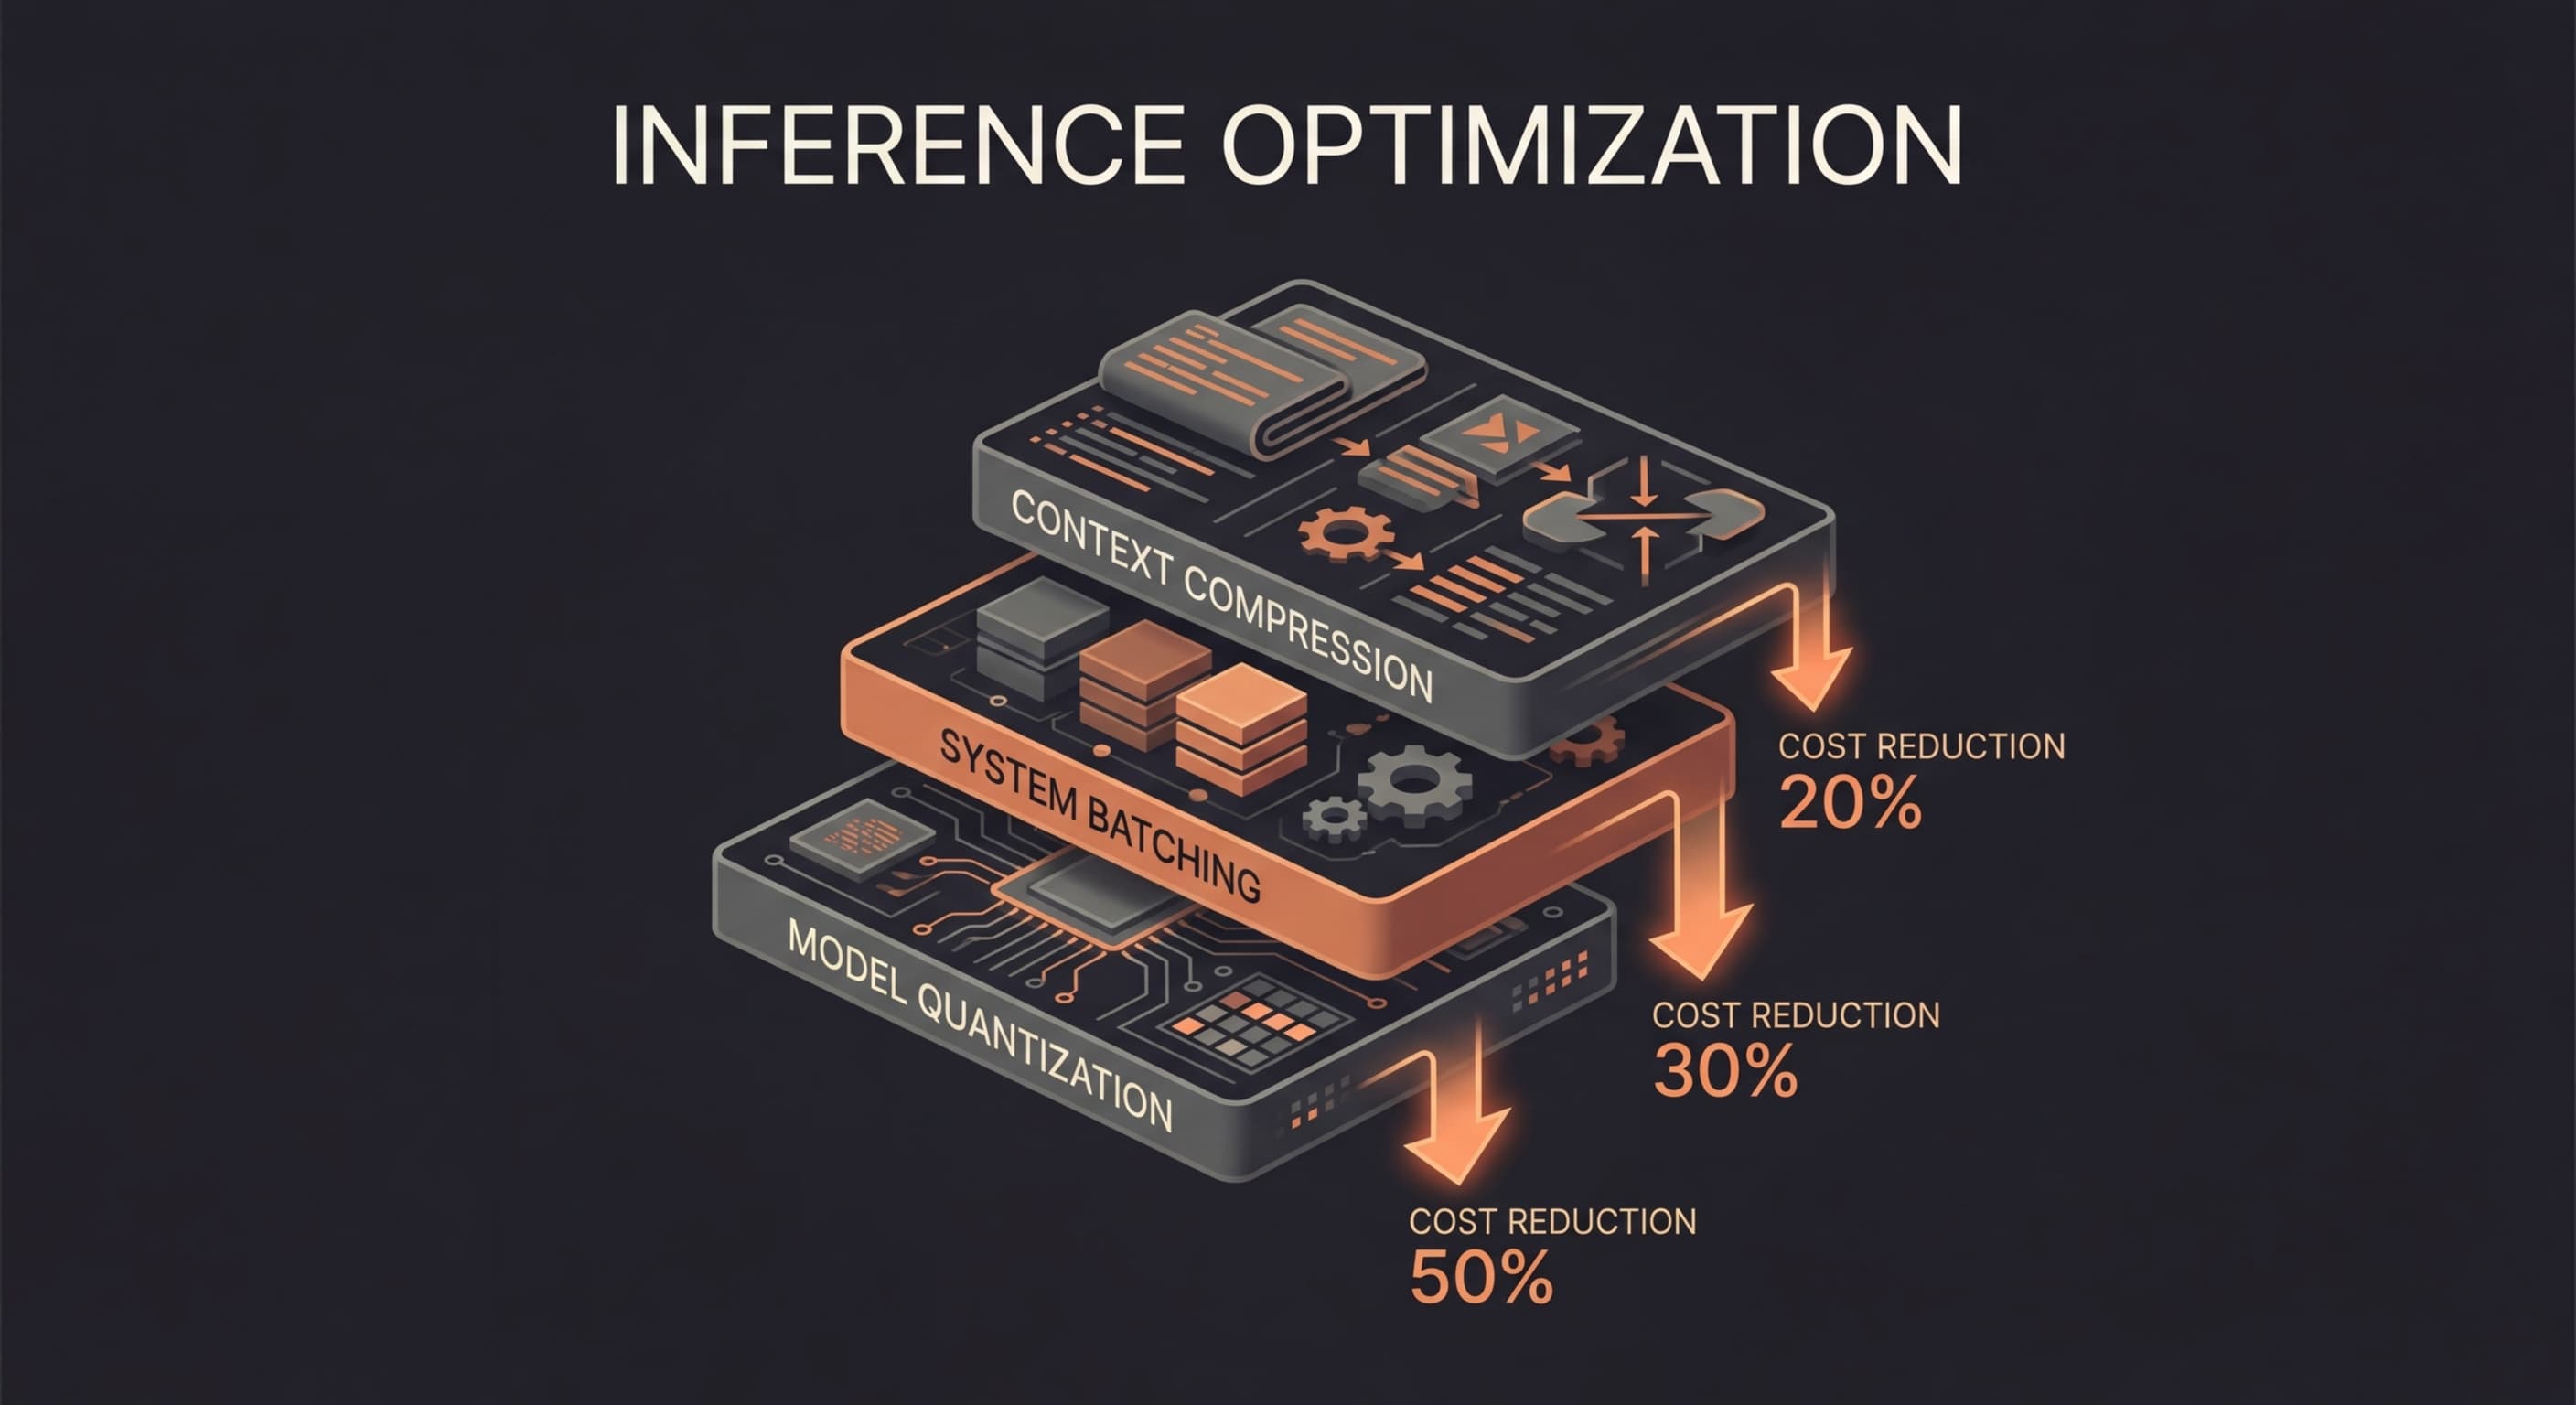
LLM Inference Optimization: Cut Cost & Latency at Every Layer (2026 ...
Local LLM inference speed in 2026: what we've measured · llm-speed
I tried running the rumored local LLM inference engine "Splash" on a ...
Reliably Structuring LLM Output with JSON Schema and Tool Use|AutoIncome
The '42x speedup' in llama.cpp was only about draft generation. Testing ...
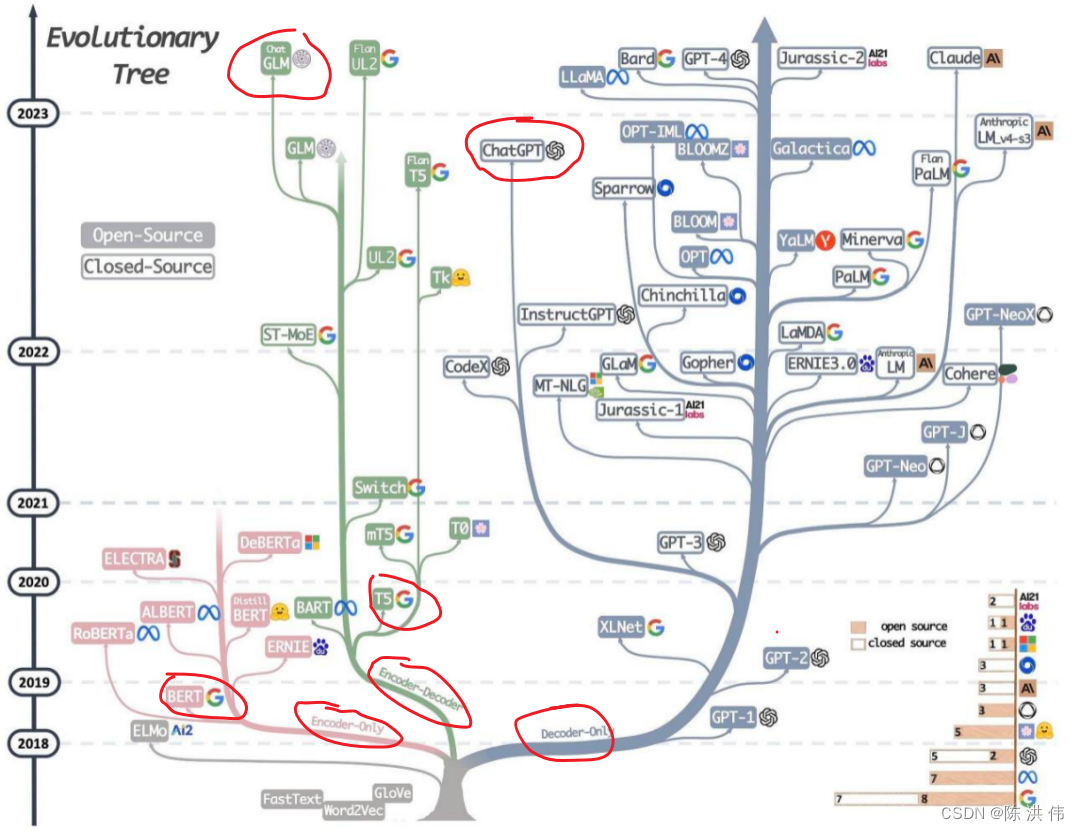
The History of Open-Source LLMs: Early Days (Part One)
Decoder-Only Transformers: The Workhorse of Generative LLMs
GitHub - logic-OT/Decoder-Only-LLM: This repository features a custom ...
Decoder-only Transformer-based Large Language Model (LLM) - GM-RKB
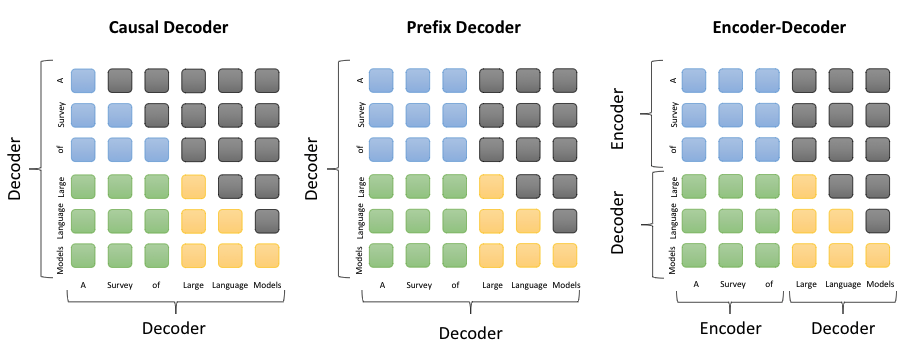
LLM的3种架构:Encoder-only、Decoder-only、encode-decode - 知乎
Considerations on Encoder-Only and Decoder-Only Language Models | by ...
Biomedical LLMs (1): Intro | JX's log
Medium
Why are most LLMs decoder-only?. Dive into the rabbit hole of recent ...
深入理解大模型(LLMs)的内部原理(二):decoder-only transformers - 知乎
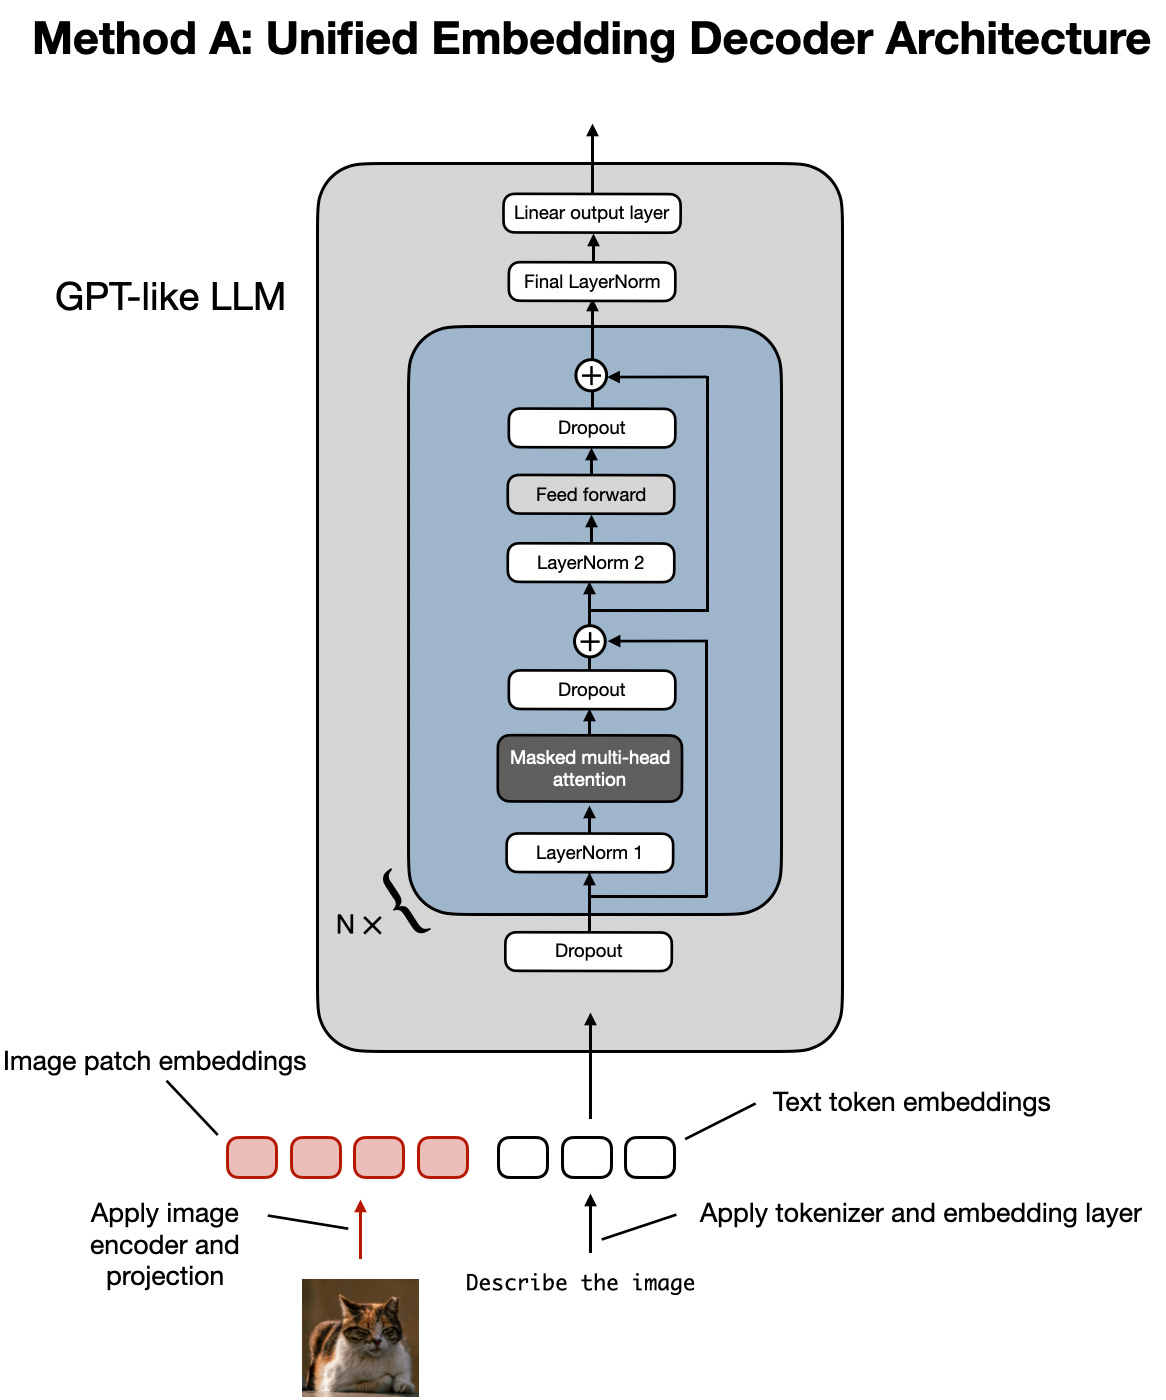
Understanding Multimodal LLMs - by Sebastian Raschka, PhD
What is AI what is LMM and why it is amazing for the IoT | Cloud Studio ...
Understanding the Encoder-Decoder Architecture in Machine Learning | by ...
从Transformer到LLM:为什么为什么“decoder-only”这句话不够 - 知乎
为什么大多数LLM只使用Decoder-Only结构? - 知乎
为什么现在的LLM都是Decoder only的架构? - 知乎
大模型LLM架构--Decoder-Only、Encoder-Only、Encoder-Decoder_decoder only-CSDN博客
面试官问我:LLM为何都用Decoder only架构? - 知乎
Decoder-only LLM输入输出流程学习 - 知乎
为什么现在的LLM都是Decoder-only的架构?_decoder-only 下三角矩阵-CSDN博客
LLM面试_为什么常用Decoder Only结构_哔哩哔哩_bilibili
从零开始的LLM 13.LLM模型及训练 | Hexo
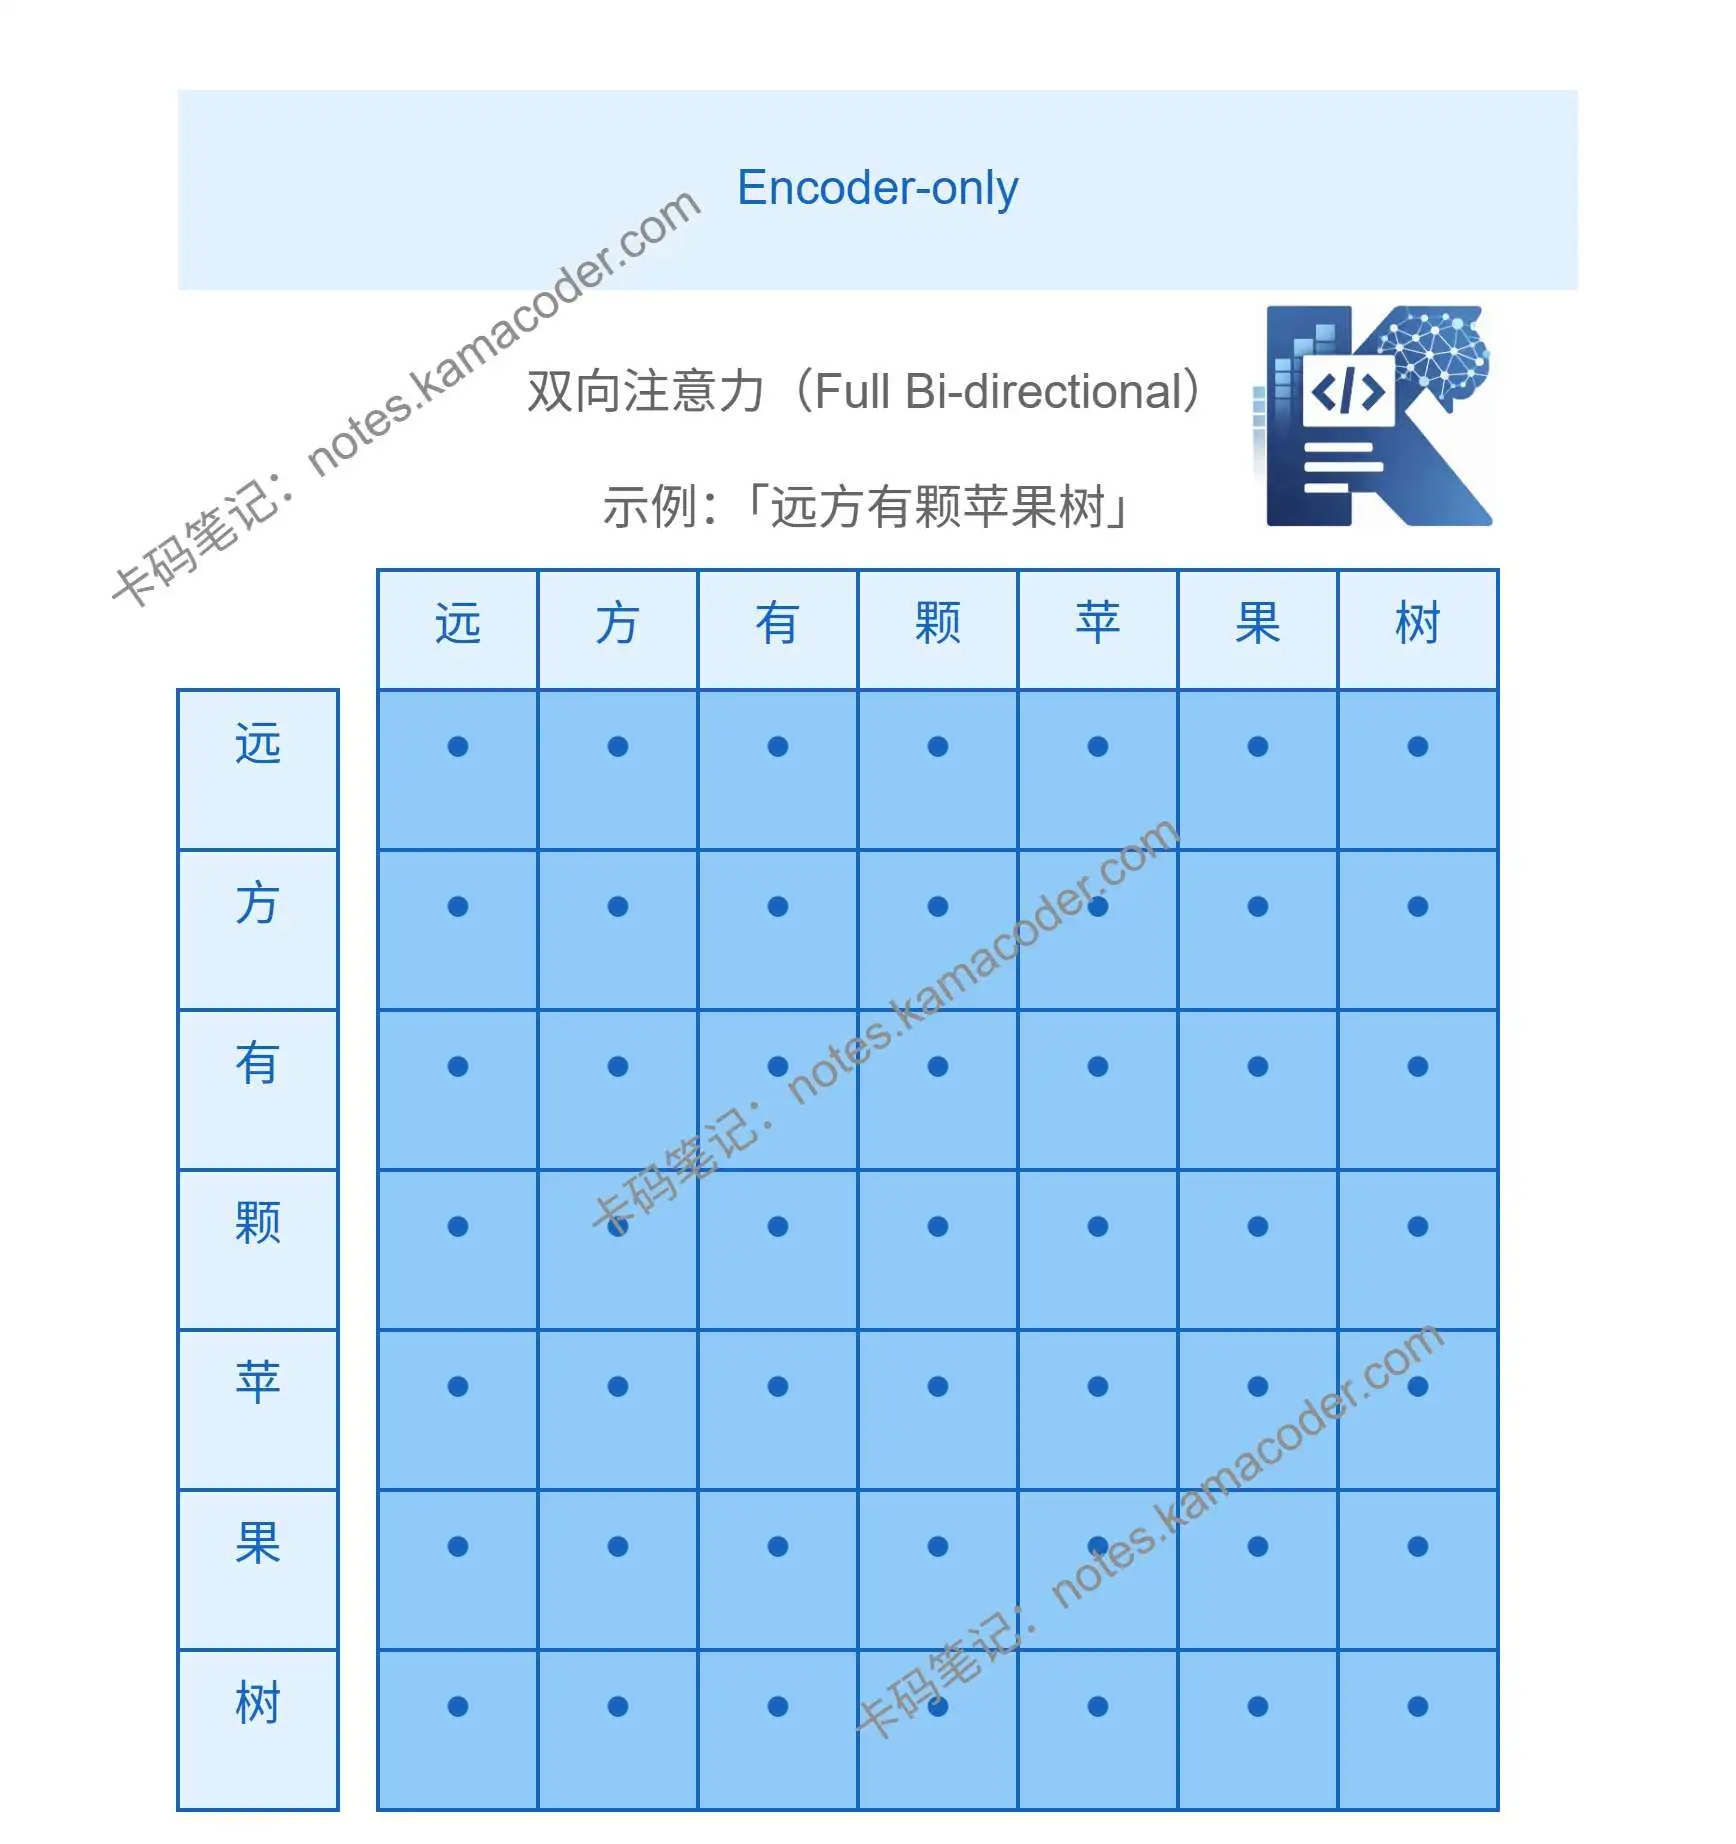
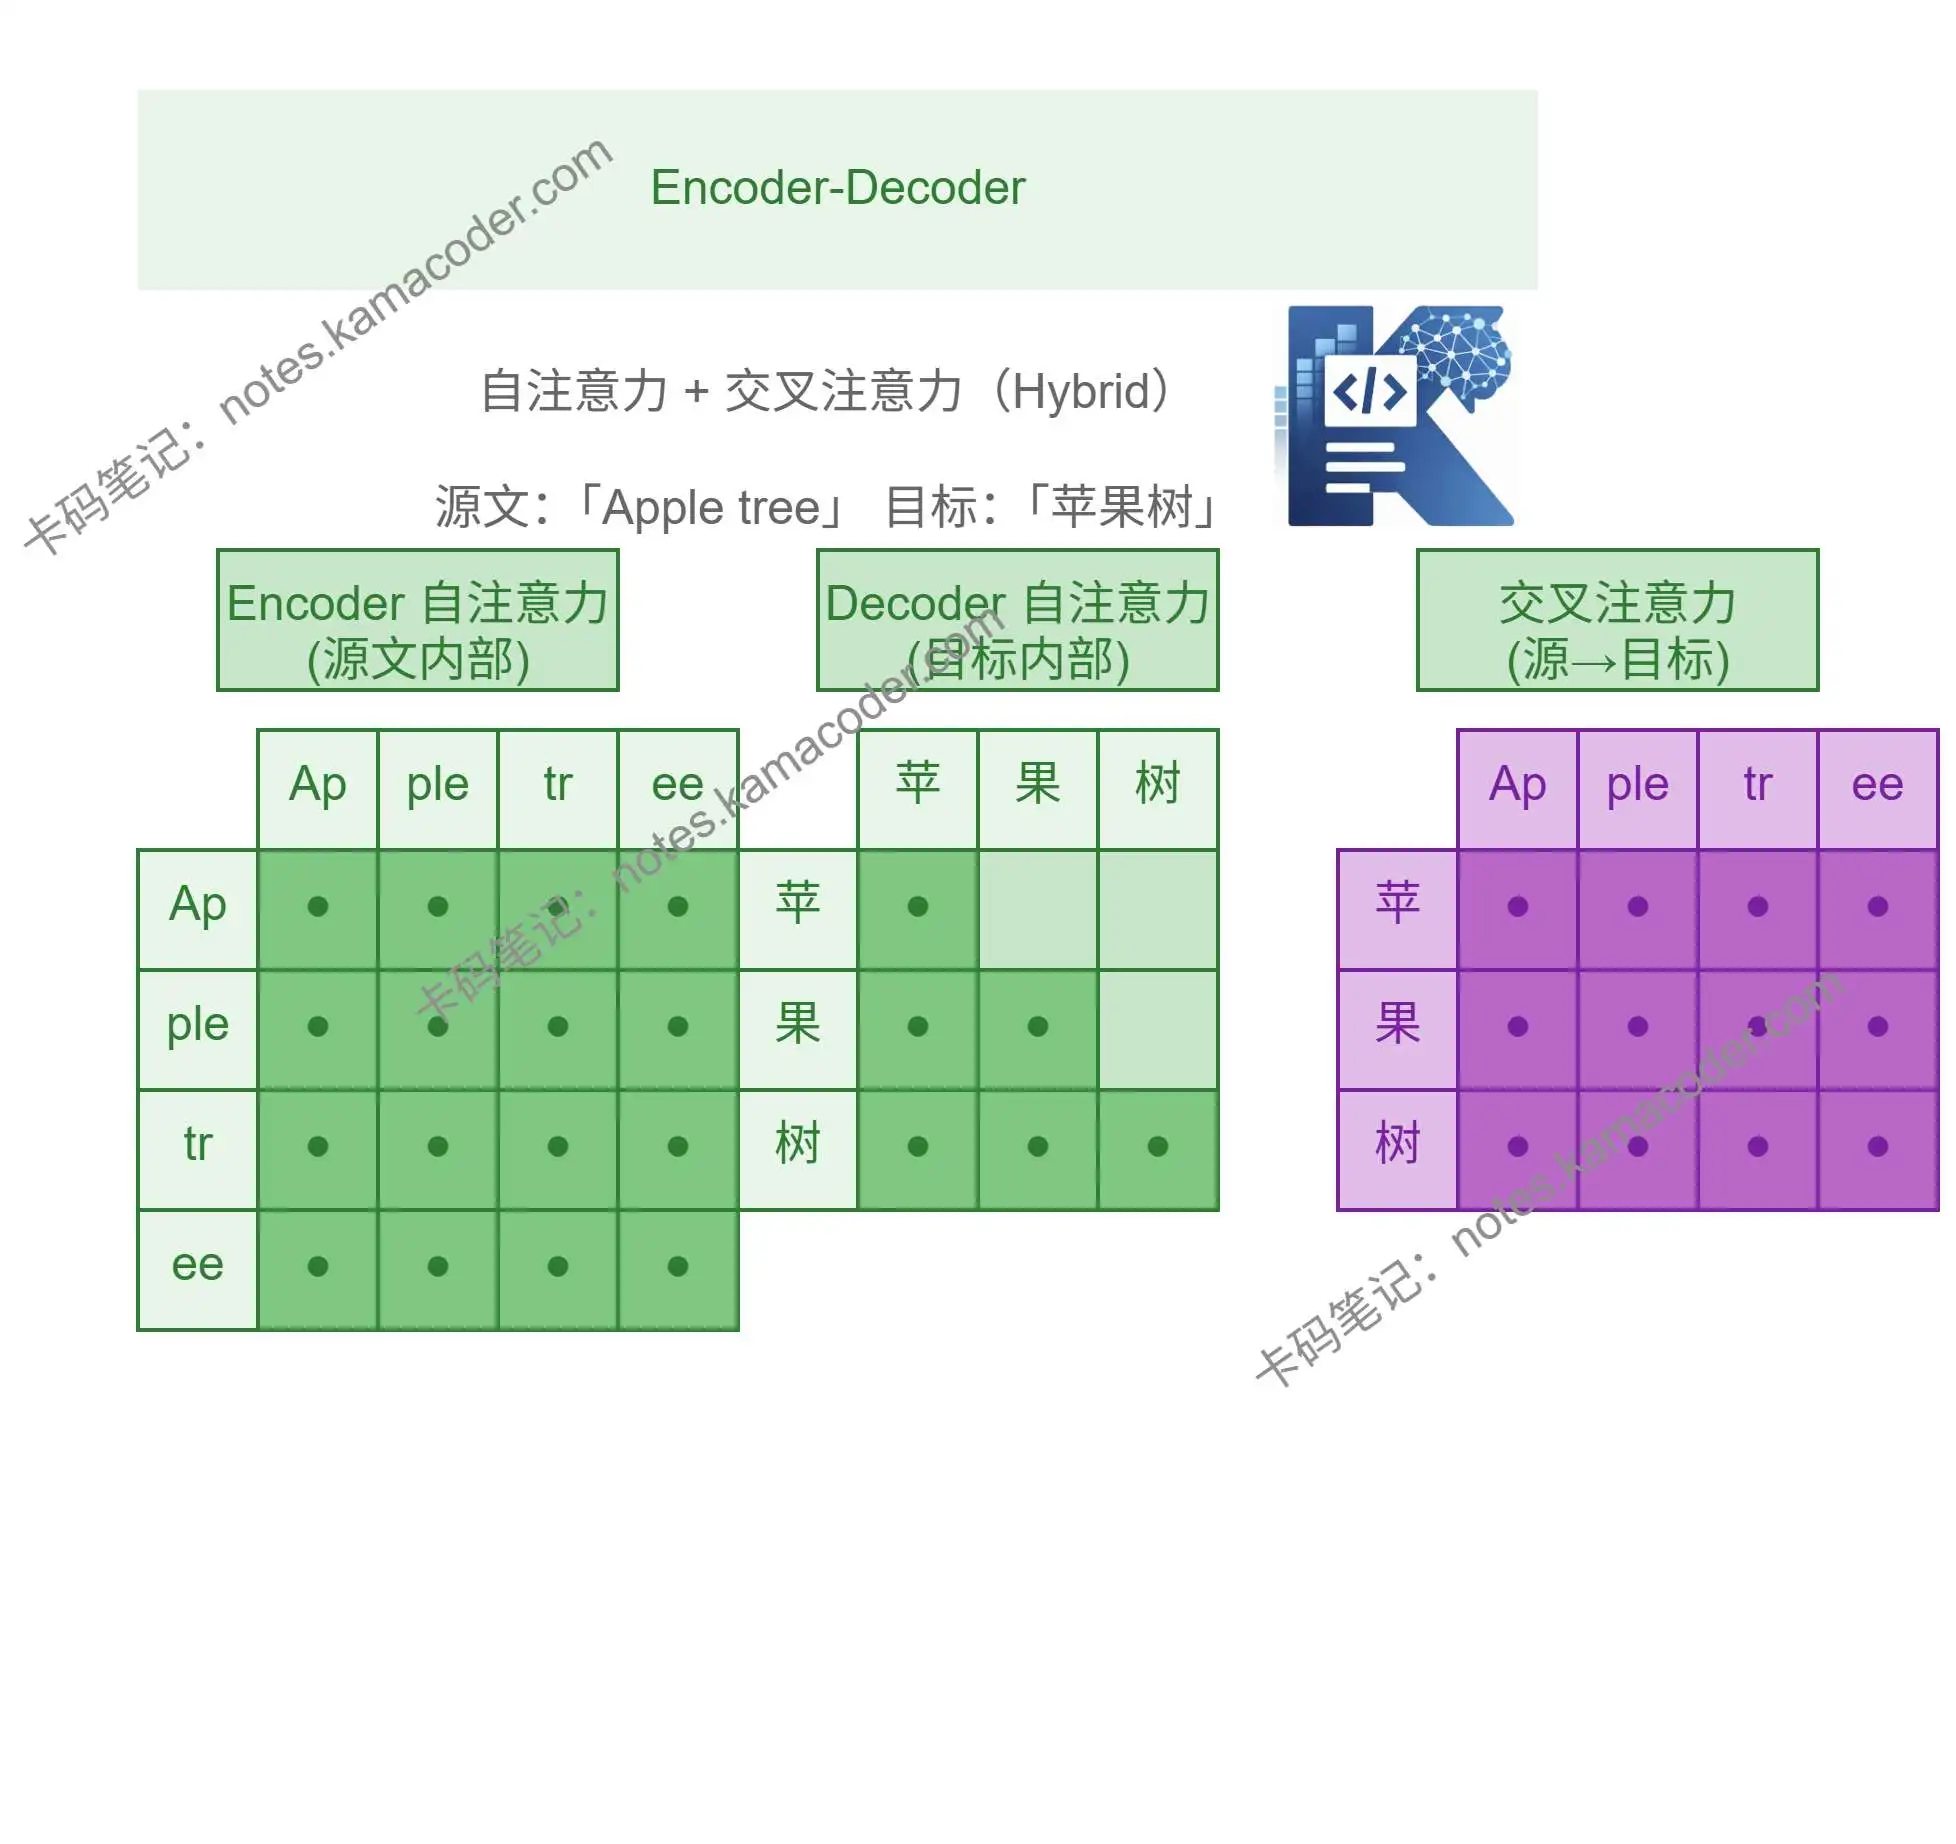
Encoder-only、Decoder-only、Encoder-Decoder三种架构详解与对比 | 卡码笔记|程序员面试题库,Java ...
OpenAI's first custom chip "Jalapeño" reportedly beats Nvidia's ...
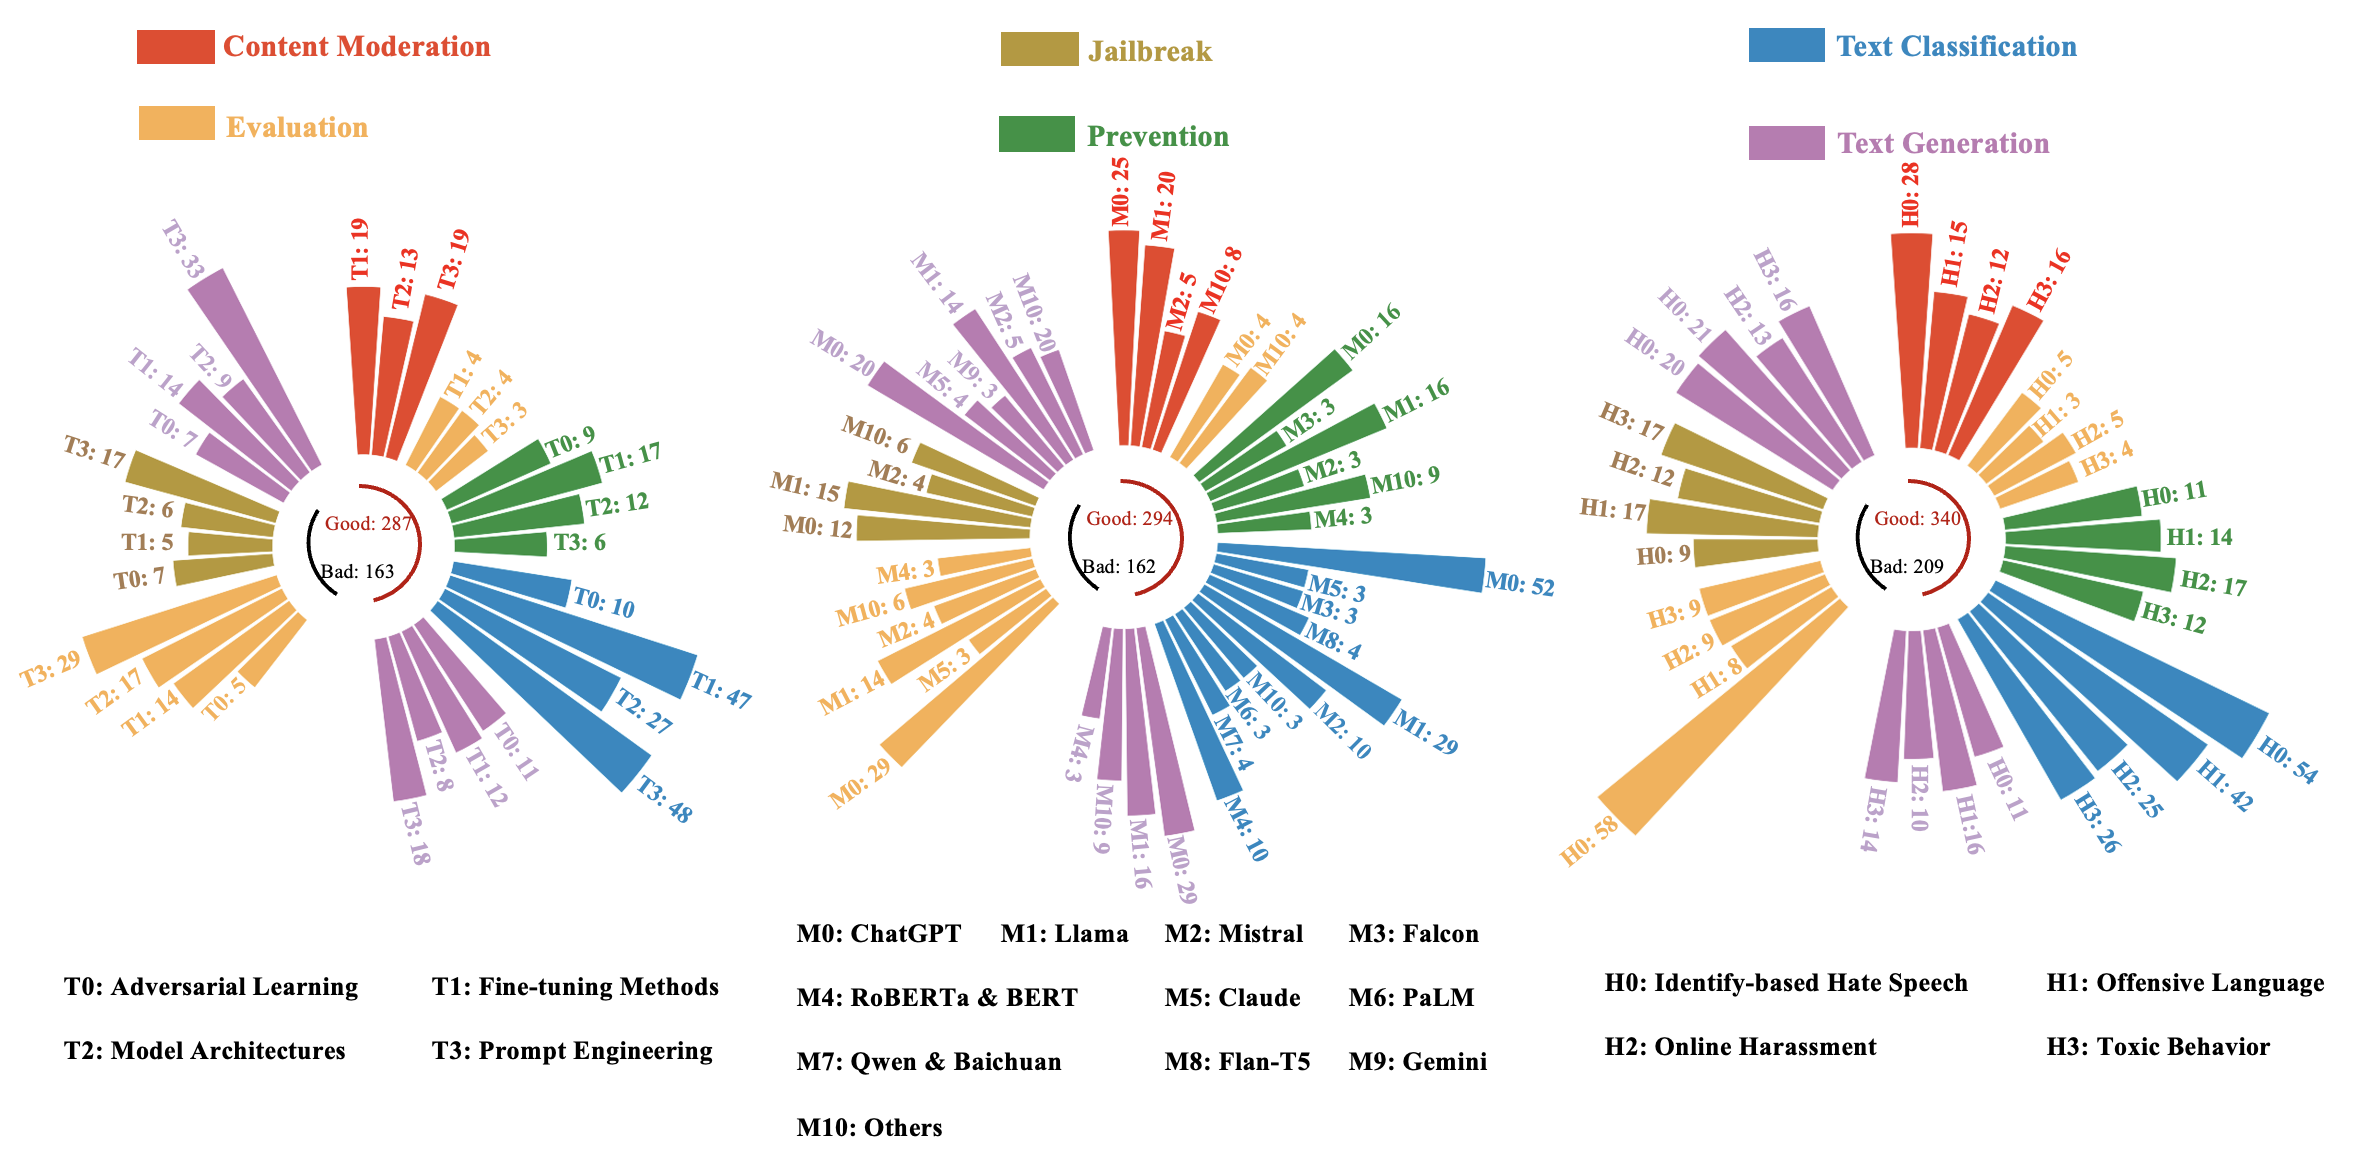
Guardians and Offenders: A Survey on Harmful Content Generation and ...
[ROM][UNOFFICIAL][10] LineageOS 17.1 for Amazon Fire HD8 7/6th gen ...
《Happy-LLM》项目正式发布,一起快乐学习大模型!-CSDN博客
Agentic AI / Generative AI – NVIDIA Technical Blog
Transformer 14. DeepSeekMoE 架构解析:与 LLaMA 以及 Transformer 架构对比-CSDN博客
Granite 4.1 LLMs: IBM Training Details | Neura Market
这个预训练不简单!BLIP:统一视觉-语言理解和生成任务_mob64ca140dc73b的技术博客_51CTO博客
First Known LLM-Powered Malware From APT28 Hackers Integrates AI ...
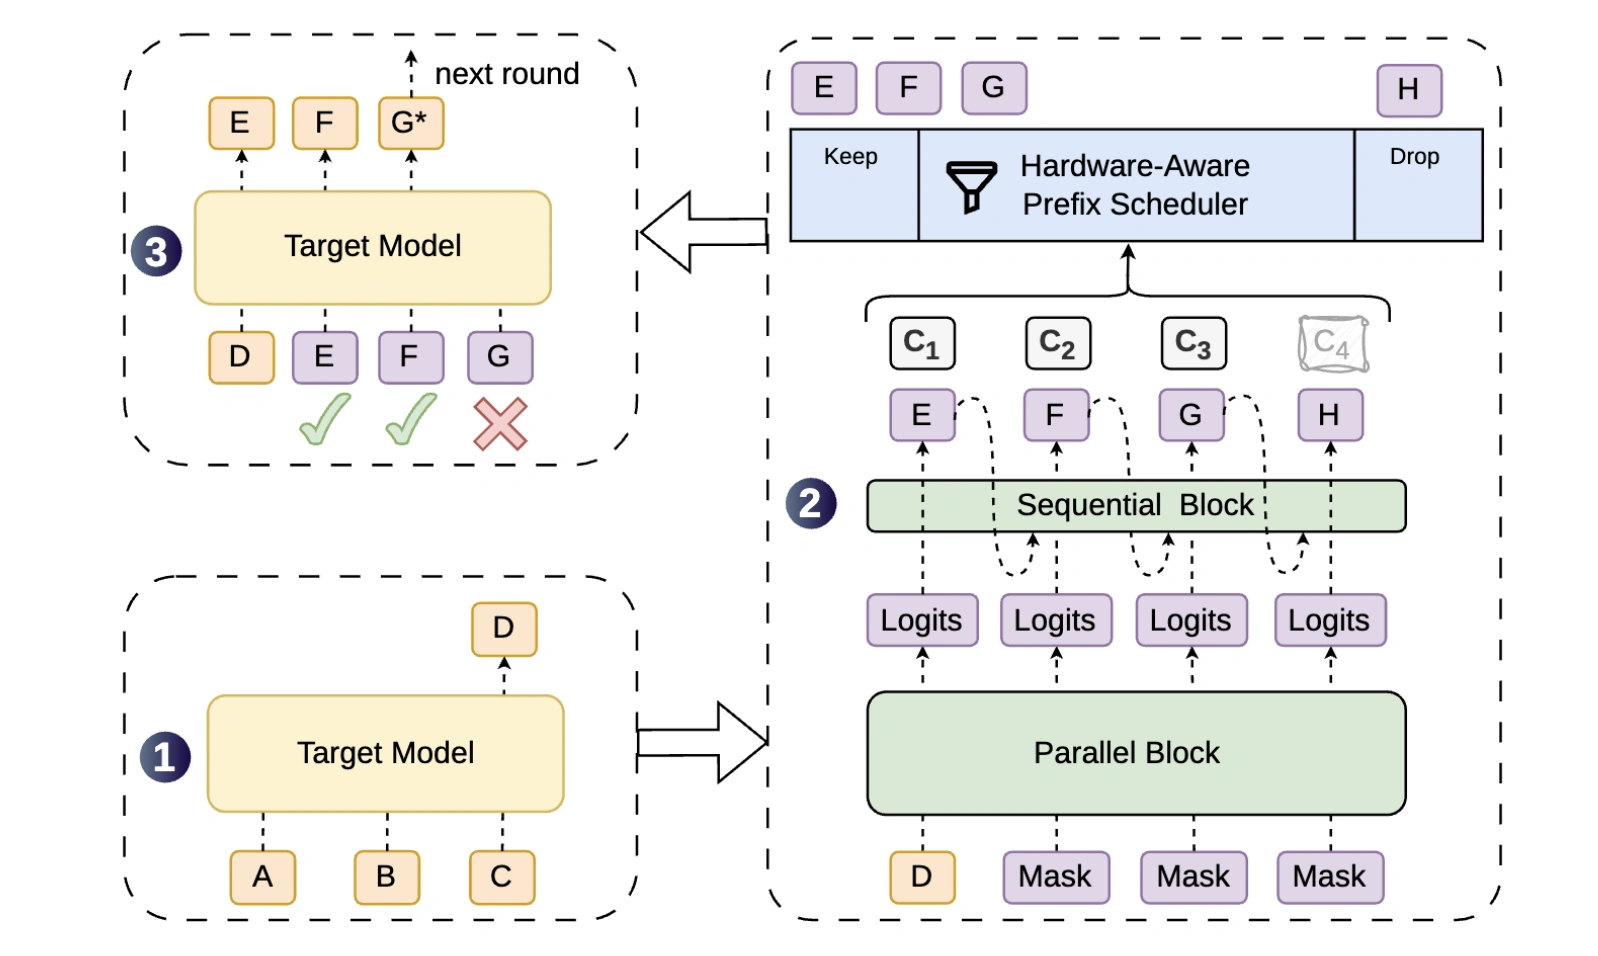
Speculative Decoding Setup: 13 Steps, 90 Min [2026]
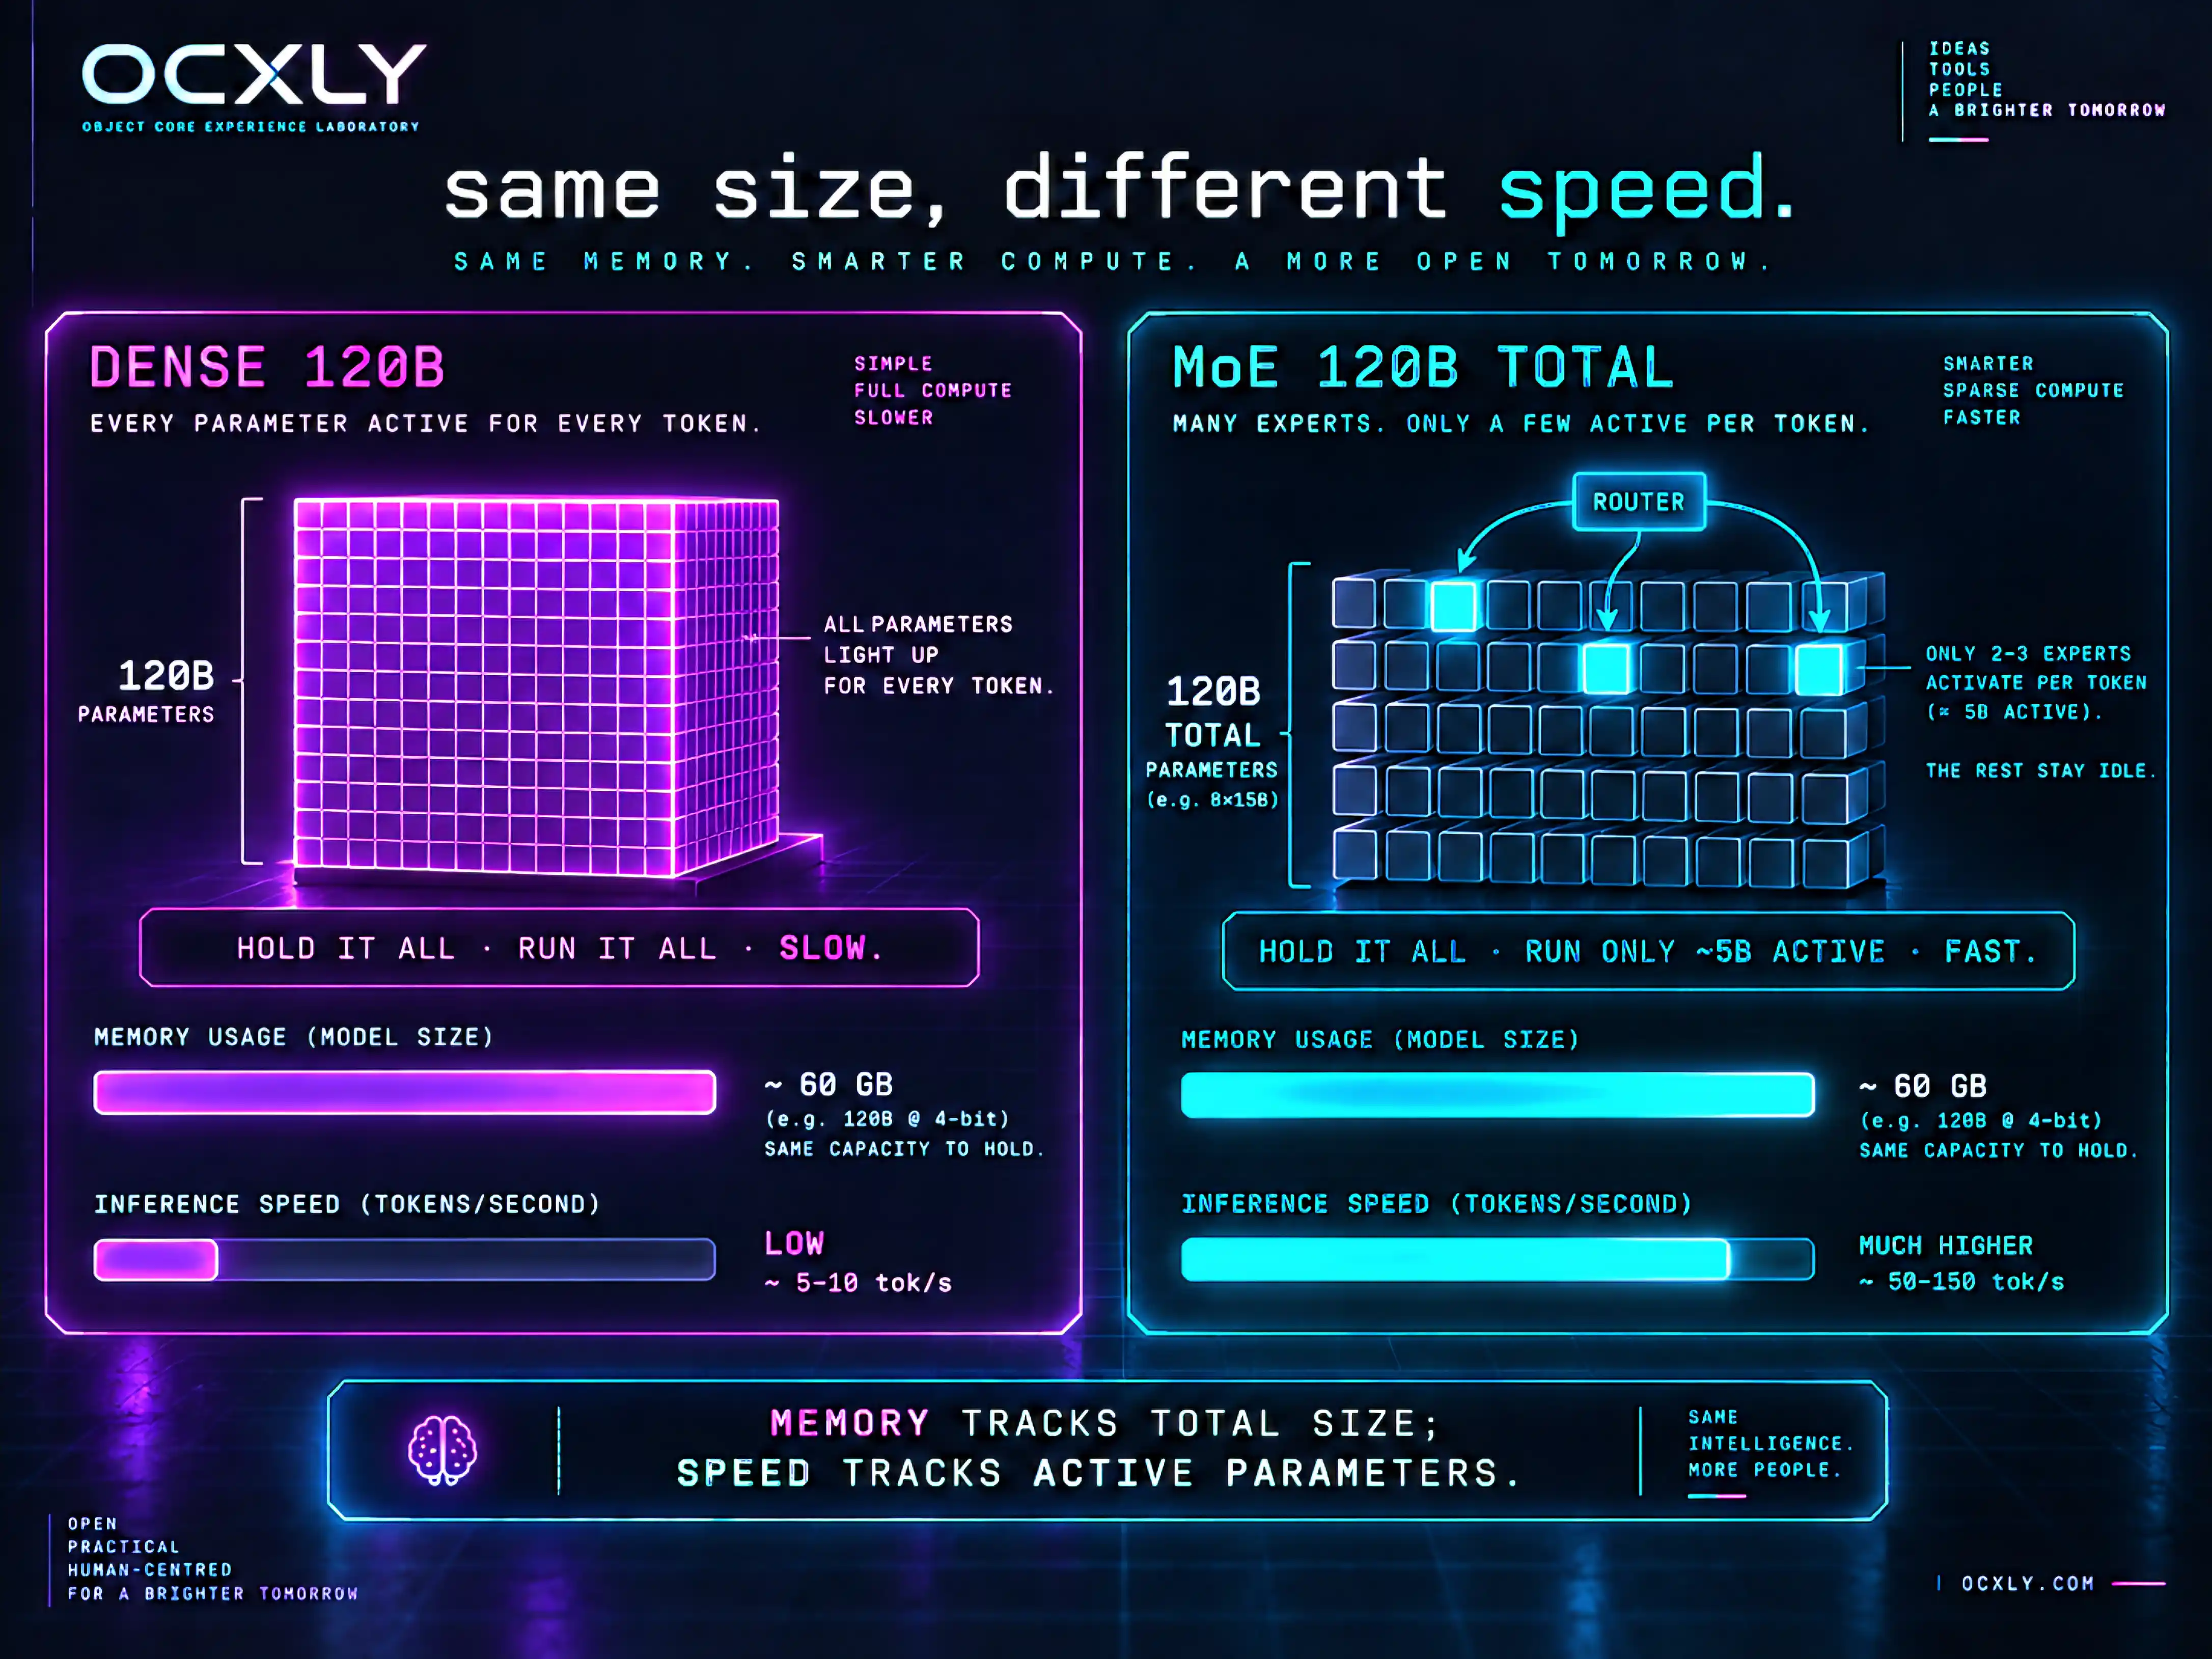
What It Takes to Run Local LLMs in 2026 | OCXLY
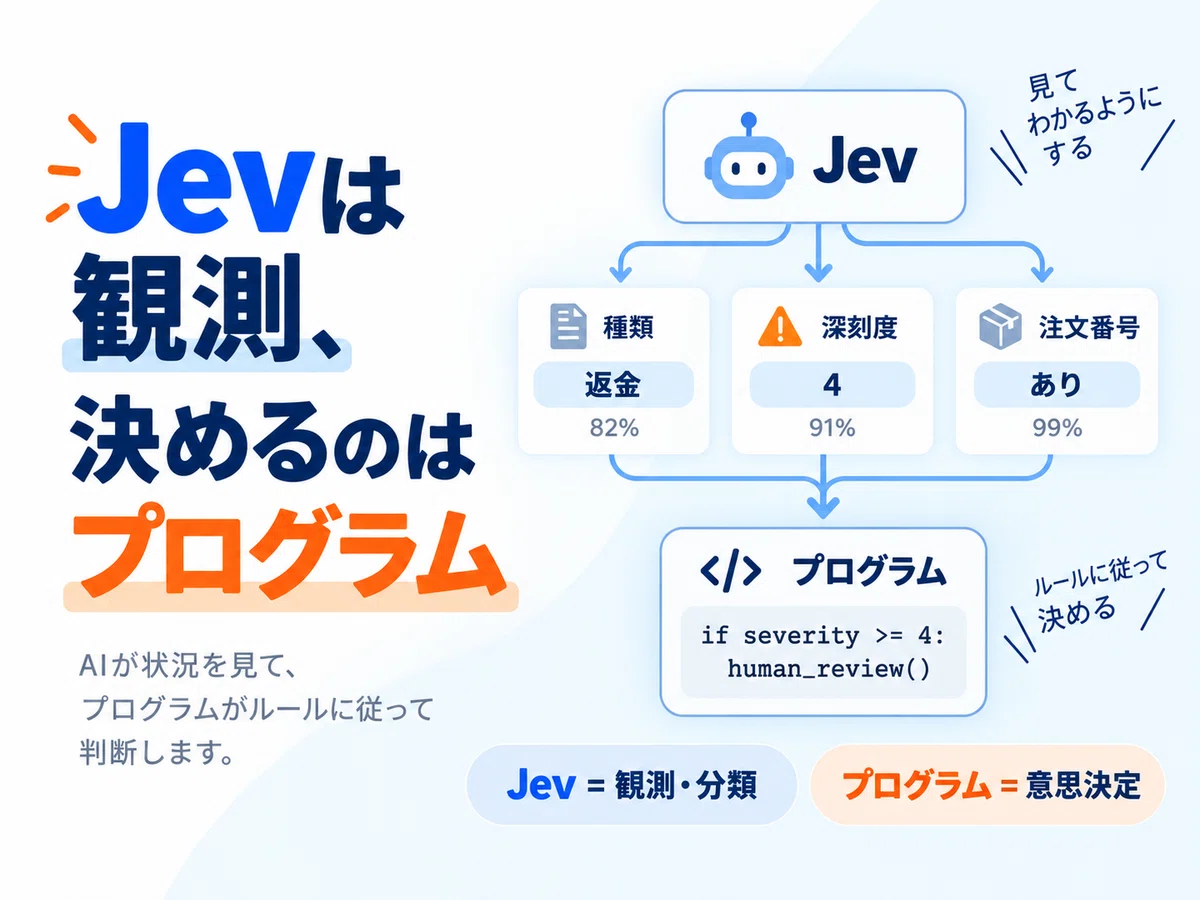
Decoding Jev, the AI that doesn't write text, from official ...
Speculative Decoding - vLLM
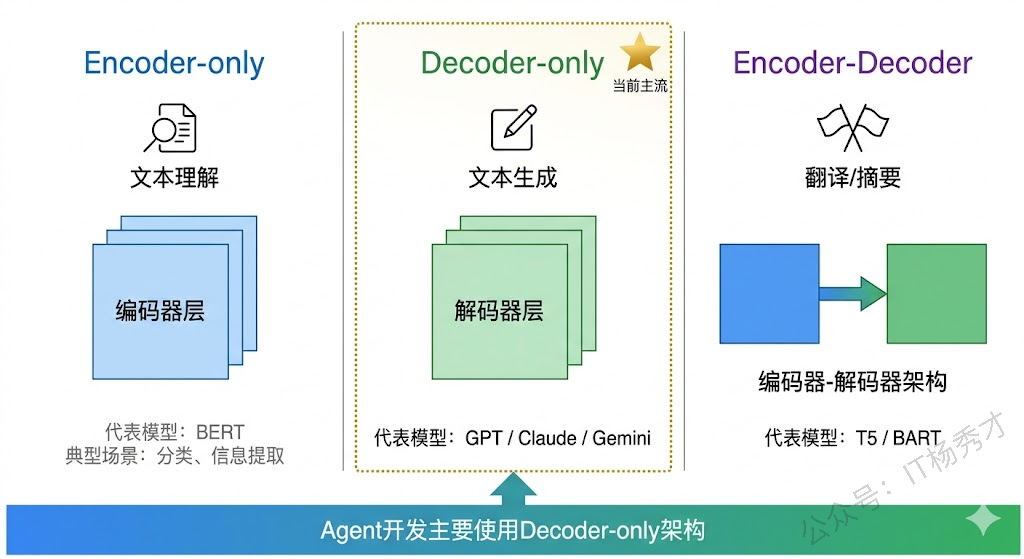
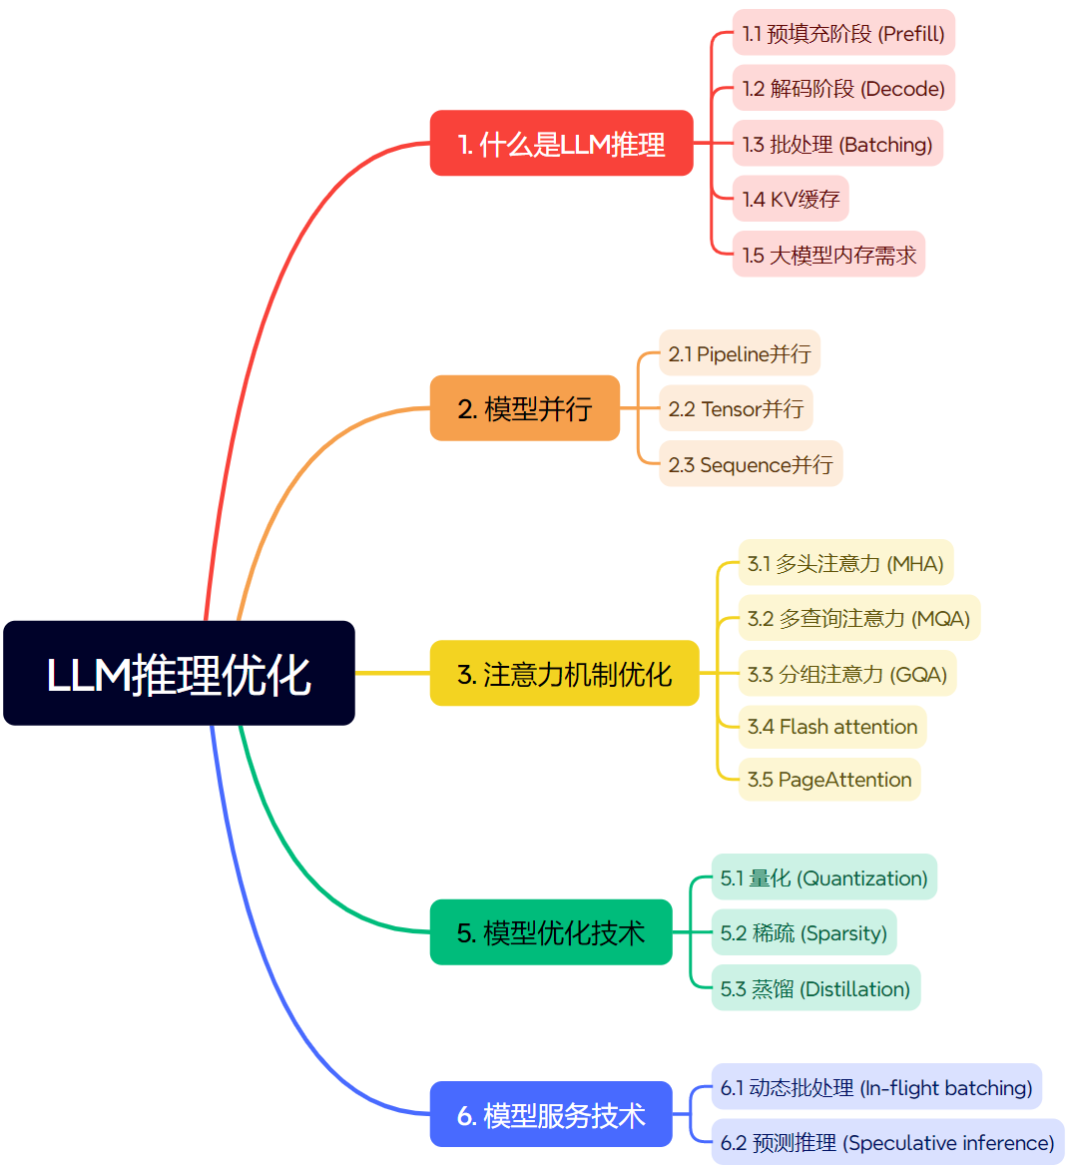
1. 大模型概述与发展历程 | 秀才的进阶之路
万字长文!LLM推理优化从入门到精通,收藏这篇就够了!-CSDN博客
Jeff joins JevBench with a reported No. 9 ranking · Digg
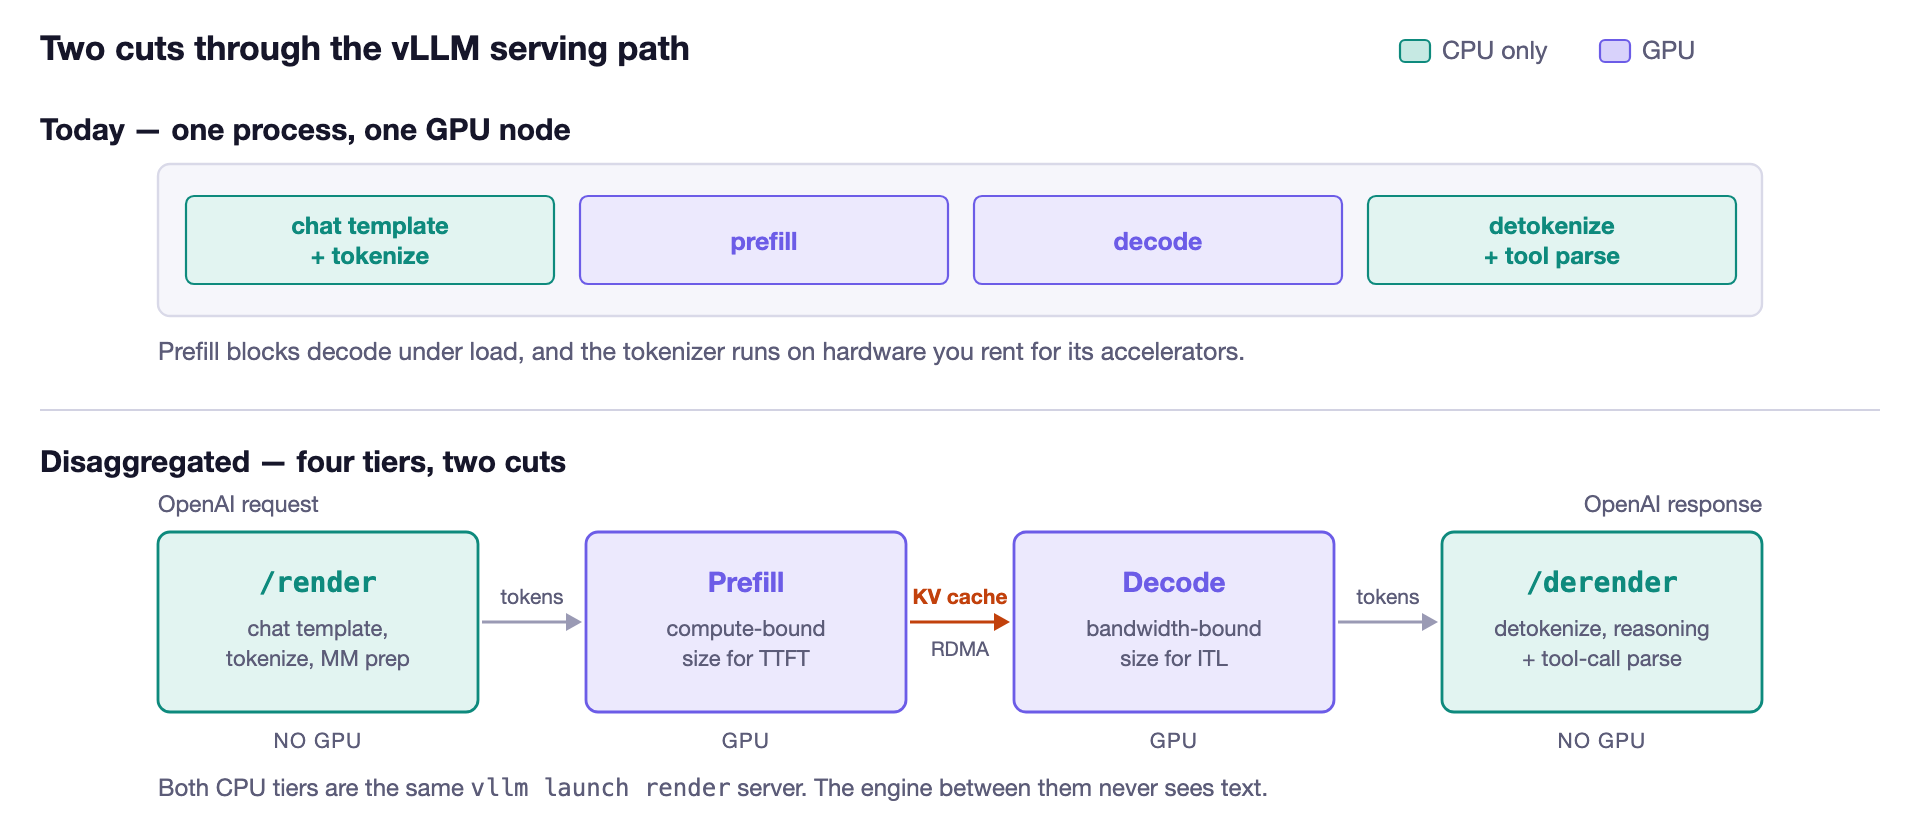
Taking vLLM Apart: A Practical Guide to Disaggregated Serving | vLLM Blog
AI sentiment is turning sour as employee reviews reveal growing ...
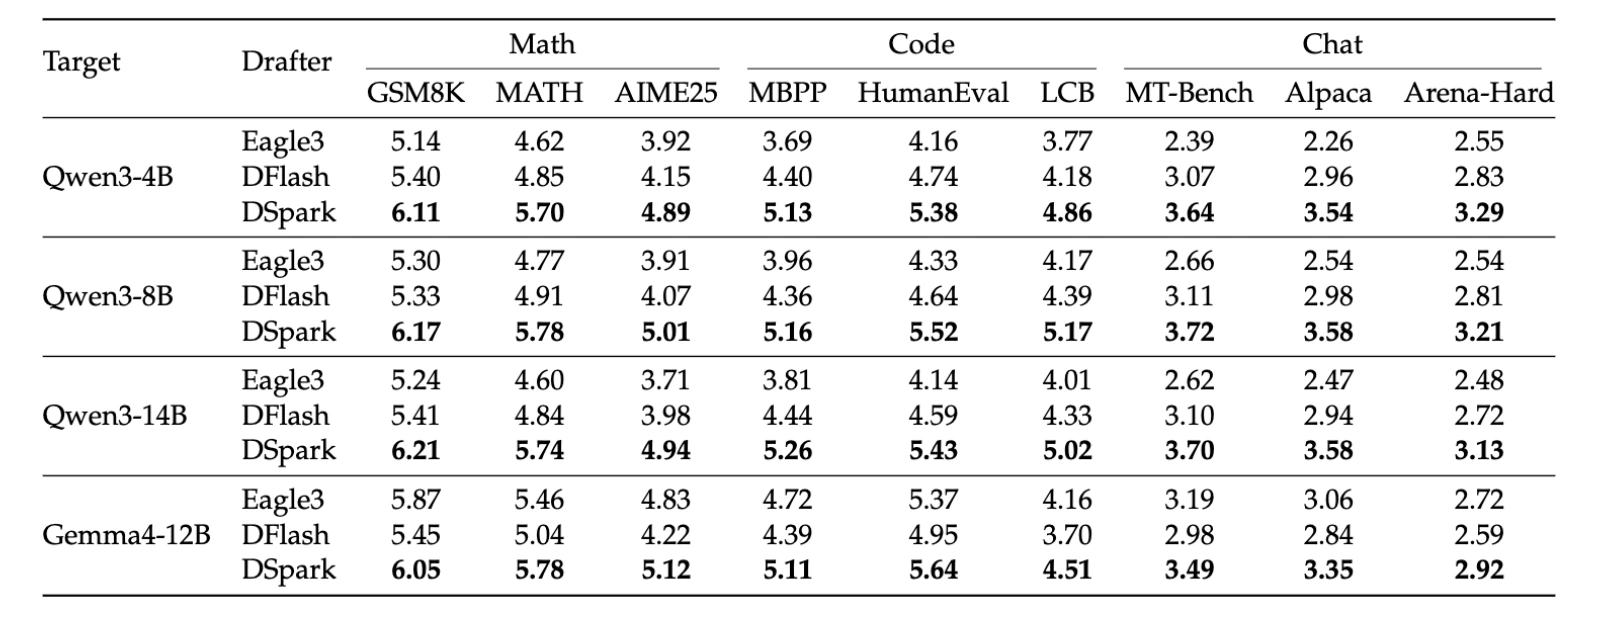
DeepSeek DSpark: Speculative Decoding for 400% Faster LLMs
2026春招必备:大模型面试“八股”干货,小白程序员速收藏!-CSDN博客
M4 MacBook Air vs. M5 MacBook Pro: Decoding Apple's Laptop Dichotomy ...
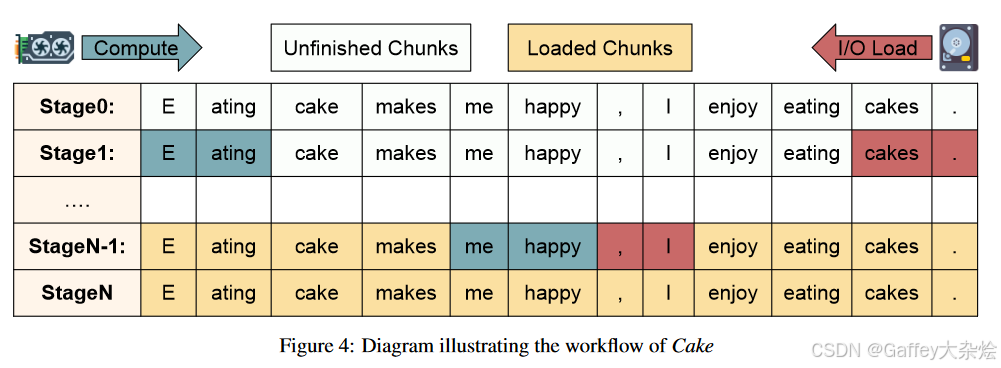
Cake:双向并行KV 缓存,加速LLM推理_大模型 磁盘缓存-CSDN博客
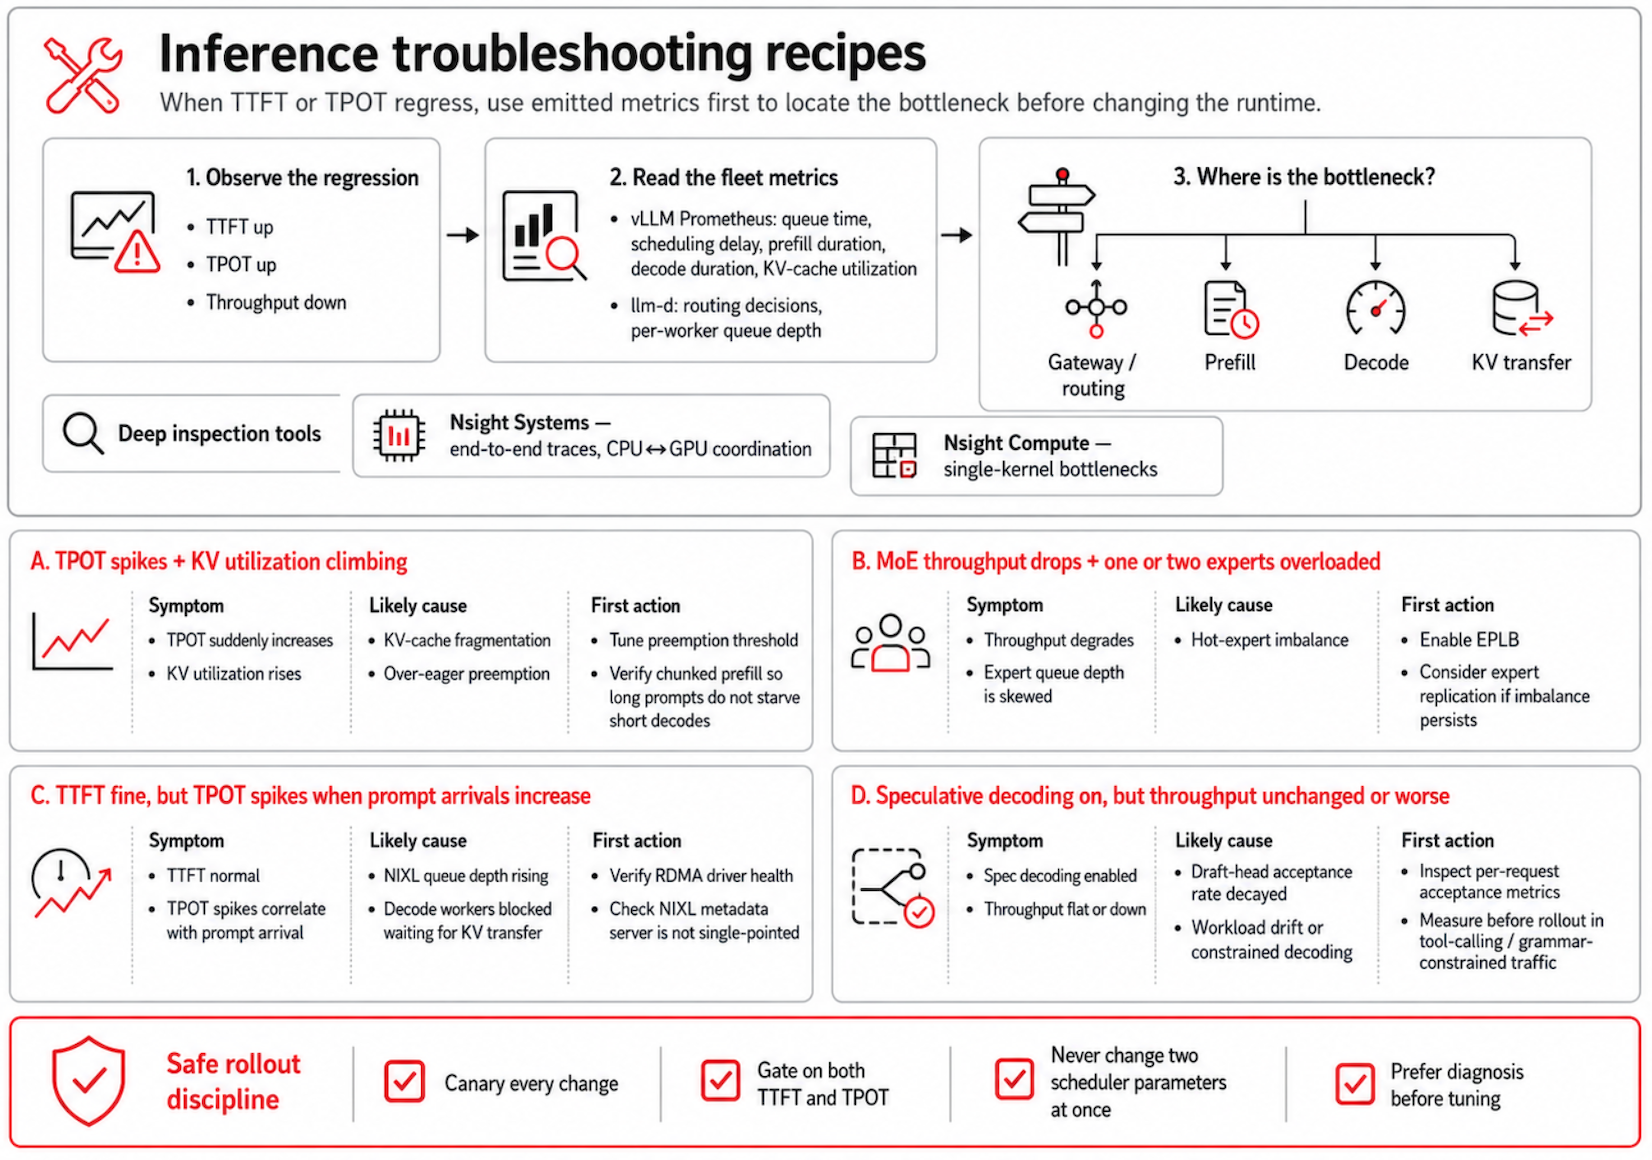
Deploying distributed AI inference: Blueprints & troubleshooting | Red ...
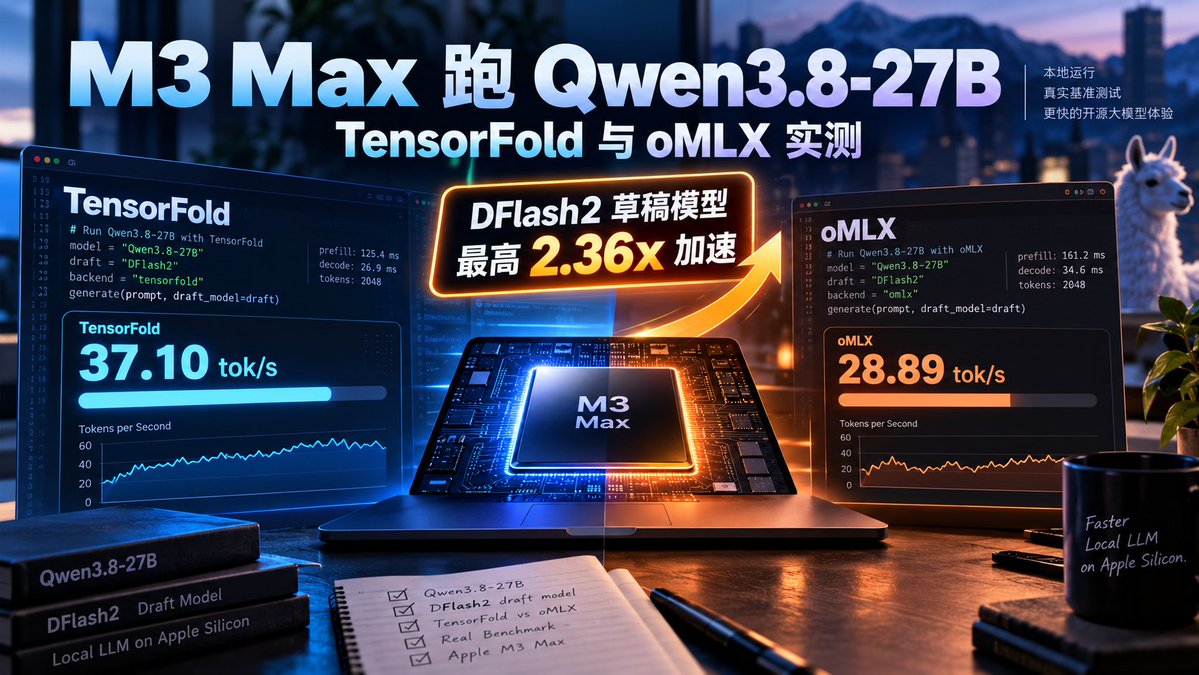
米柒说 on X: "M3 Max 跑Qwen3.8-27B,草稿模型能加速多少?TensorFold 与 oMLX 实测 https://t ...