Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
[论文评述] DreamDDP: Accelerating Data Parallel Distributed LLM Training ...
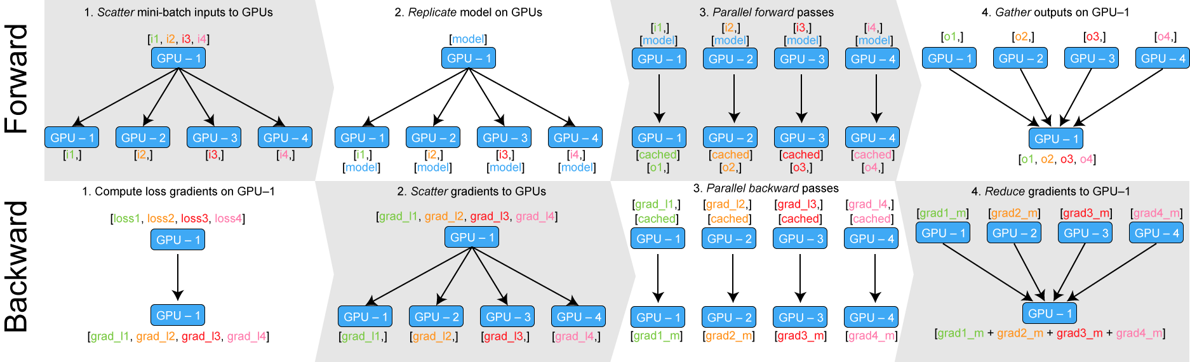
Distributed data parallel training using Pytorch on AWS – Telesens
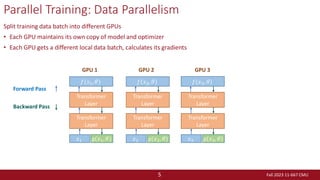
Data Parallelism: Scaling LLM Training Through Parallel Processing
Research Topics in Distributed and Parallel Training for LLM | S-Logix
Distributed Data Parallel Model Training in PyTorch - YouTube
Exploring Distributed Data Parallel (DDP) Training on Consumer GPUs - Salad
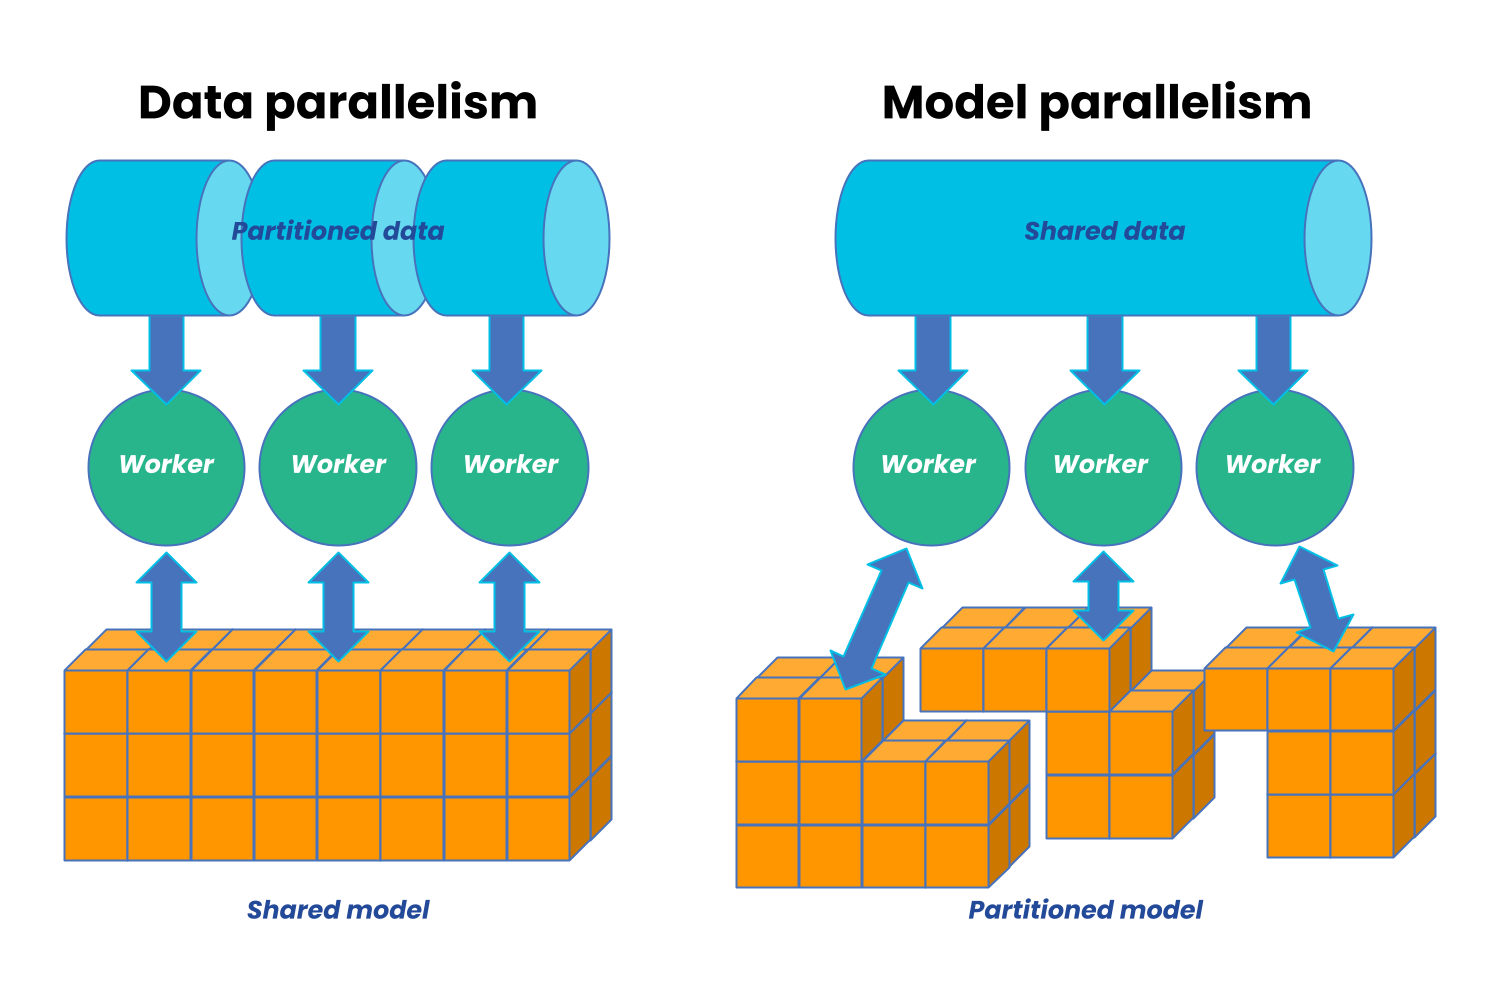
Distributed Parallel Training: Data Parallelism and Model Parallelism ...
How DDP works || Distributed Data Parallel || Quick explained - YouTube
Scaling Up LLM Pretraining: Parallel Training | PDF
Data parallelism in a typical distributed training scheme, where í µí± ...
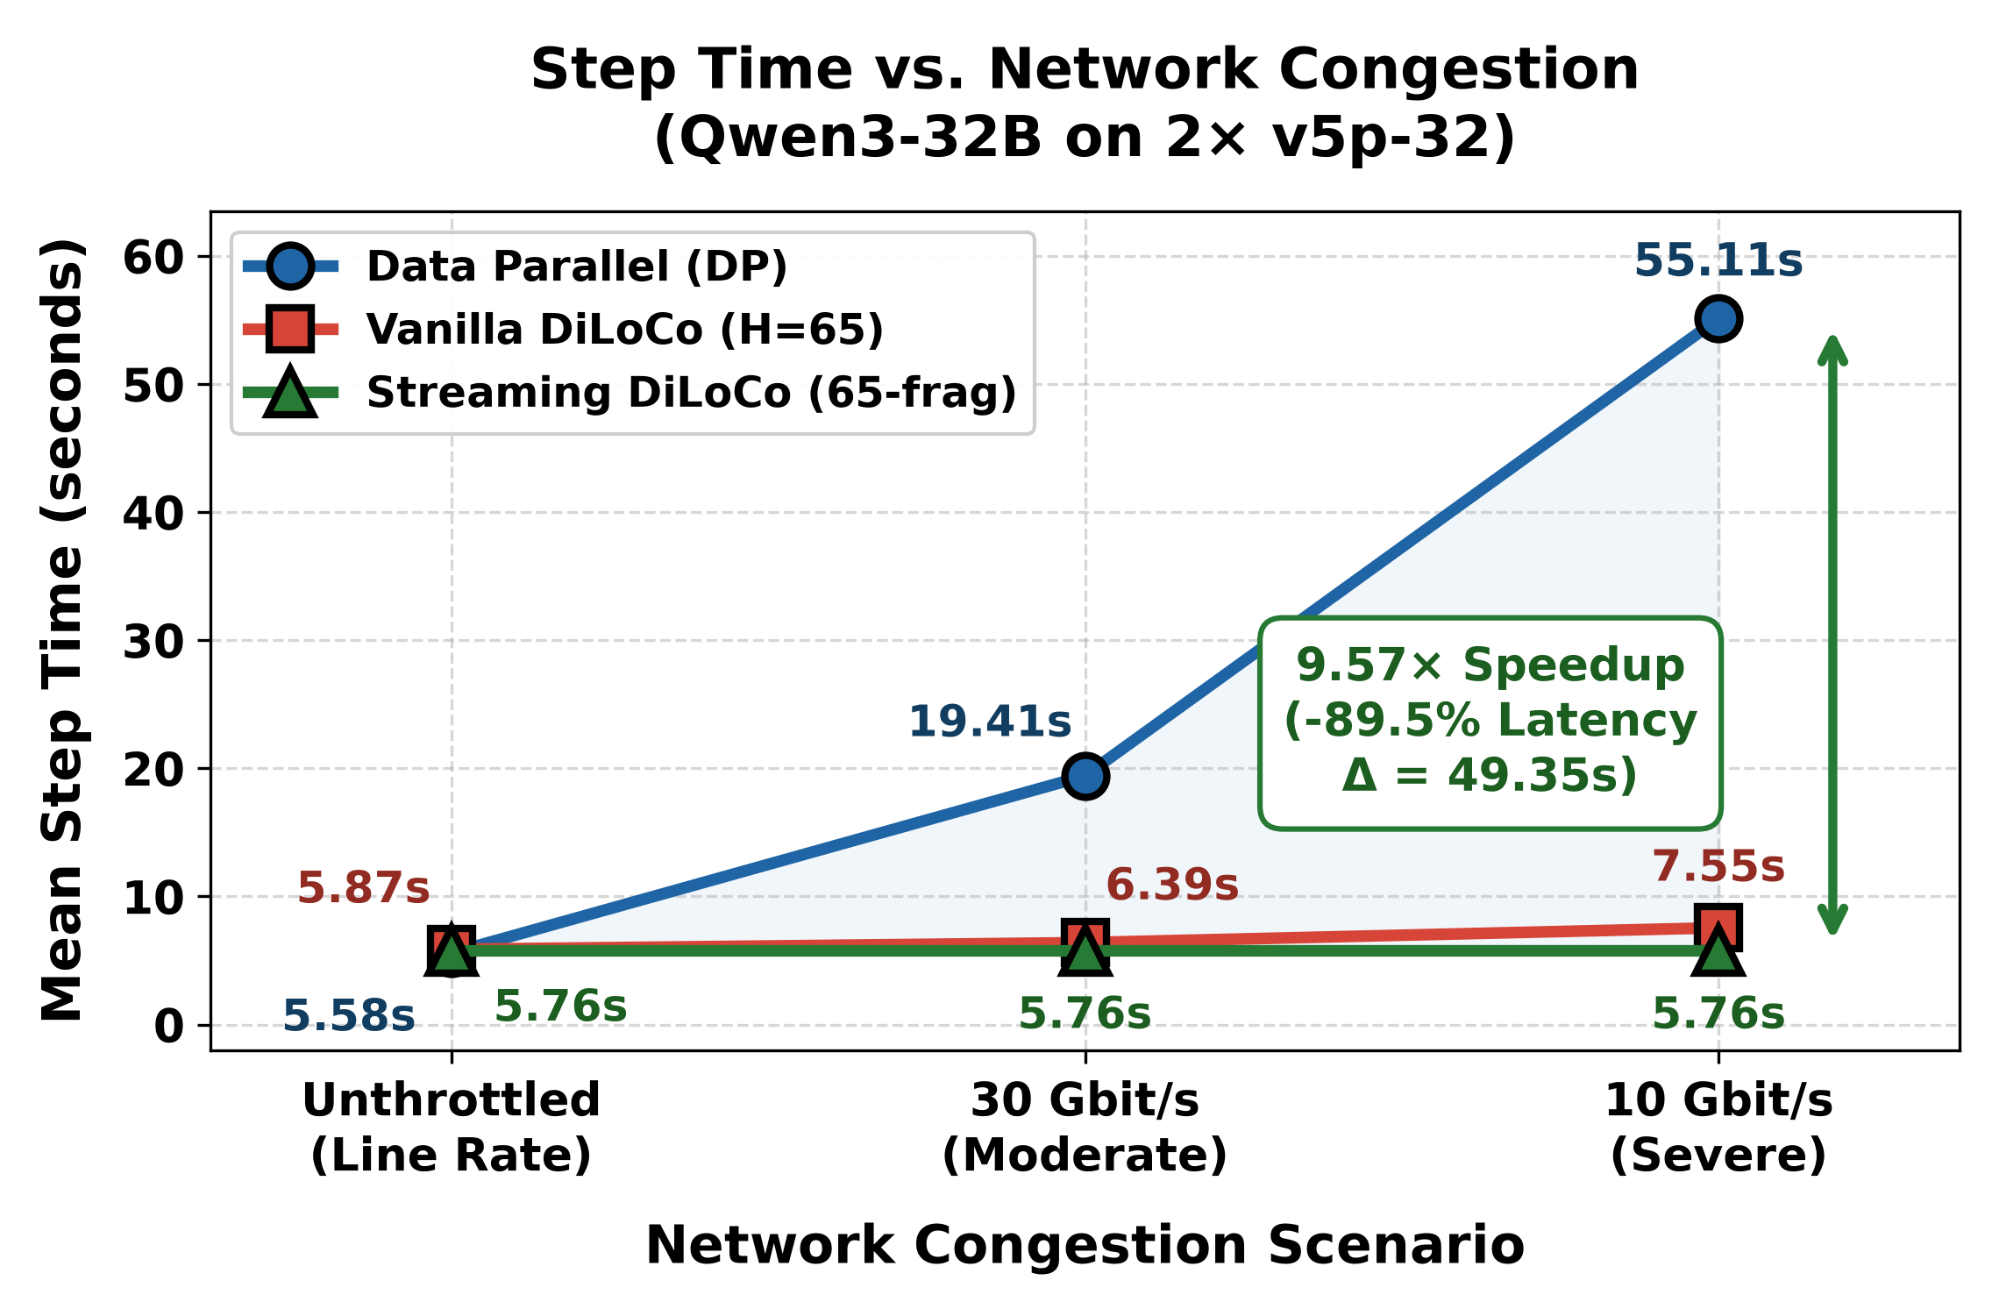
Distributed LLM Training Across Metros: Streaming DiLoCo in MaxText ...
Infra for Distributed Model Training of LLM: Part One— Parallel ...
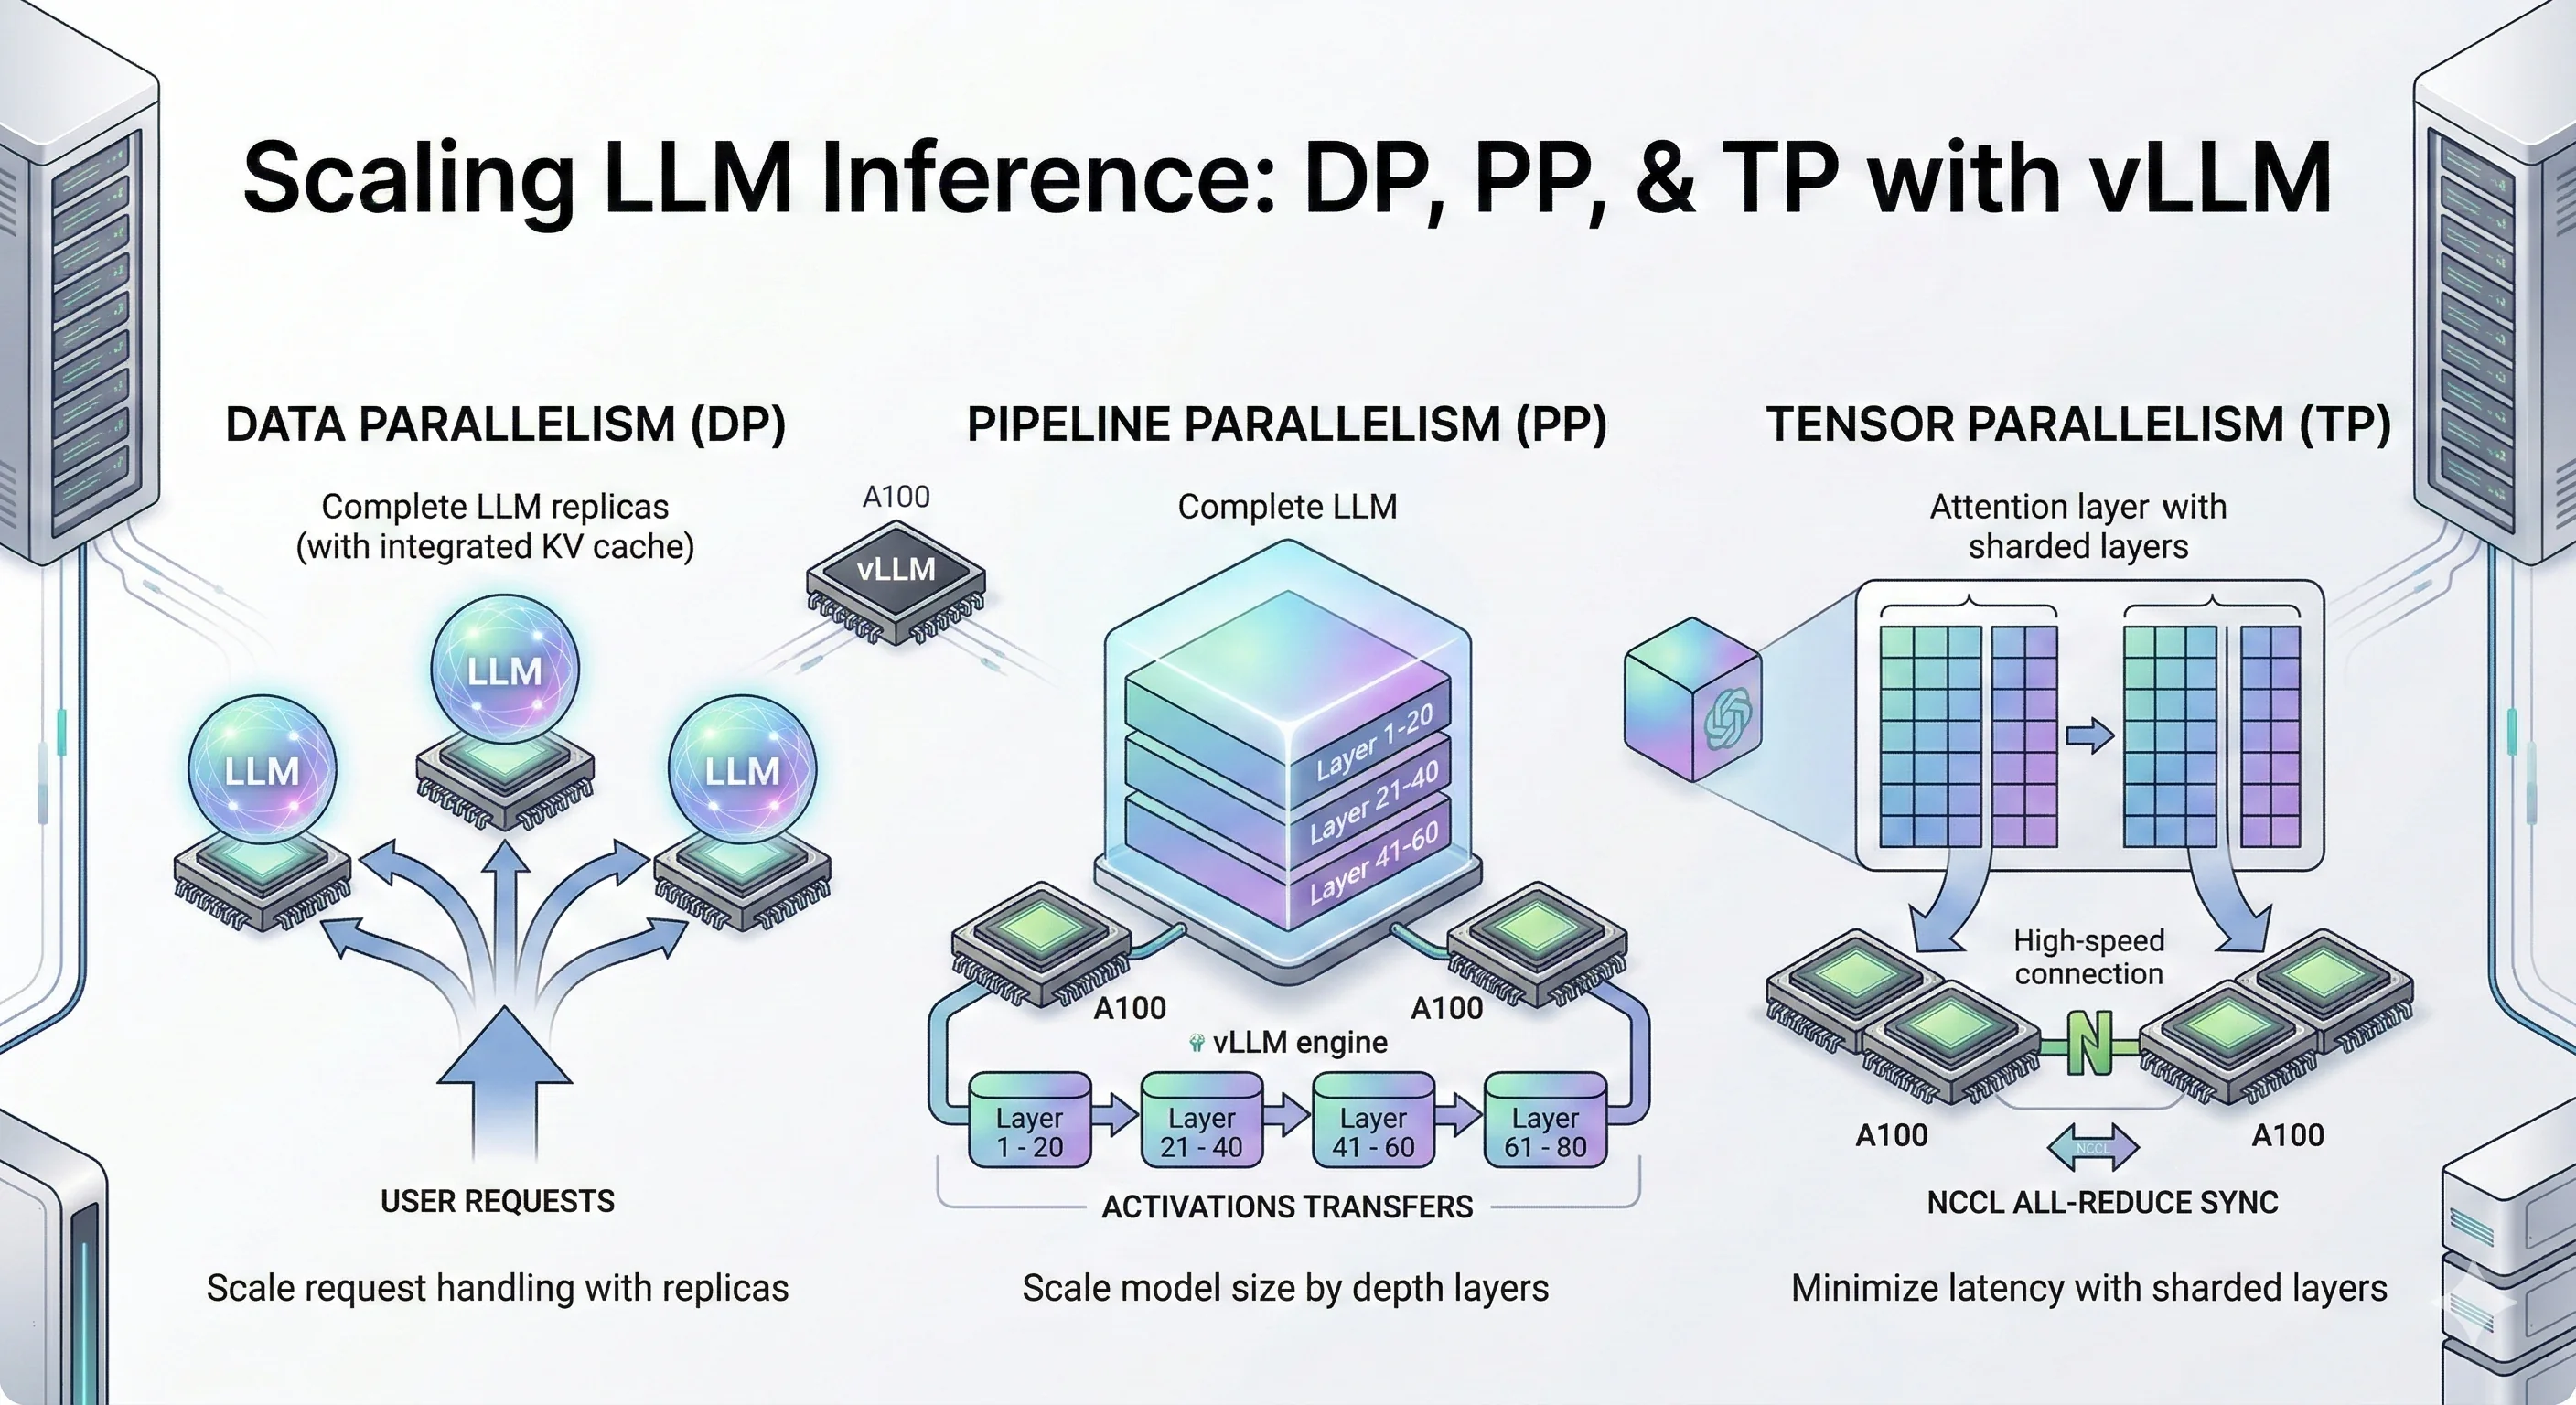
LLM Inference: Data Parallel, Model Parallel, and Pipeline Parallel ...
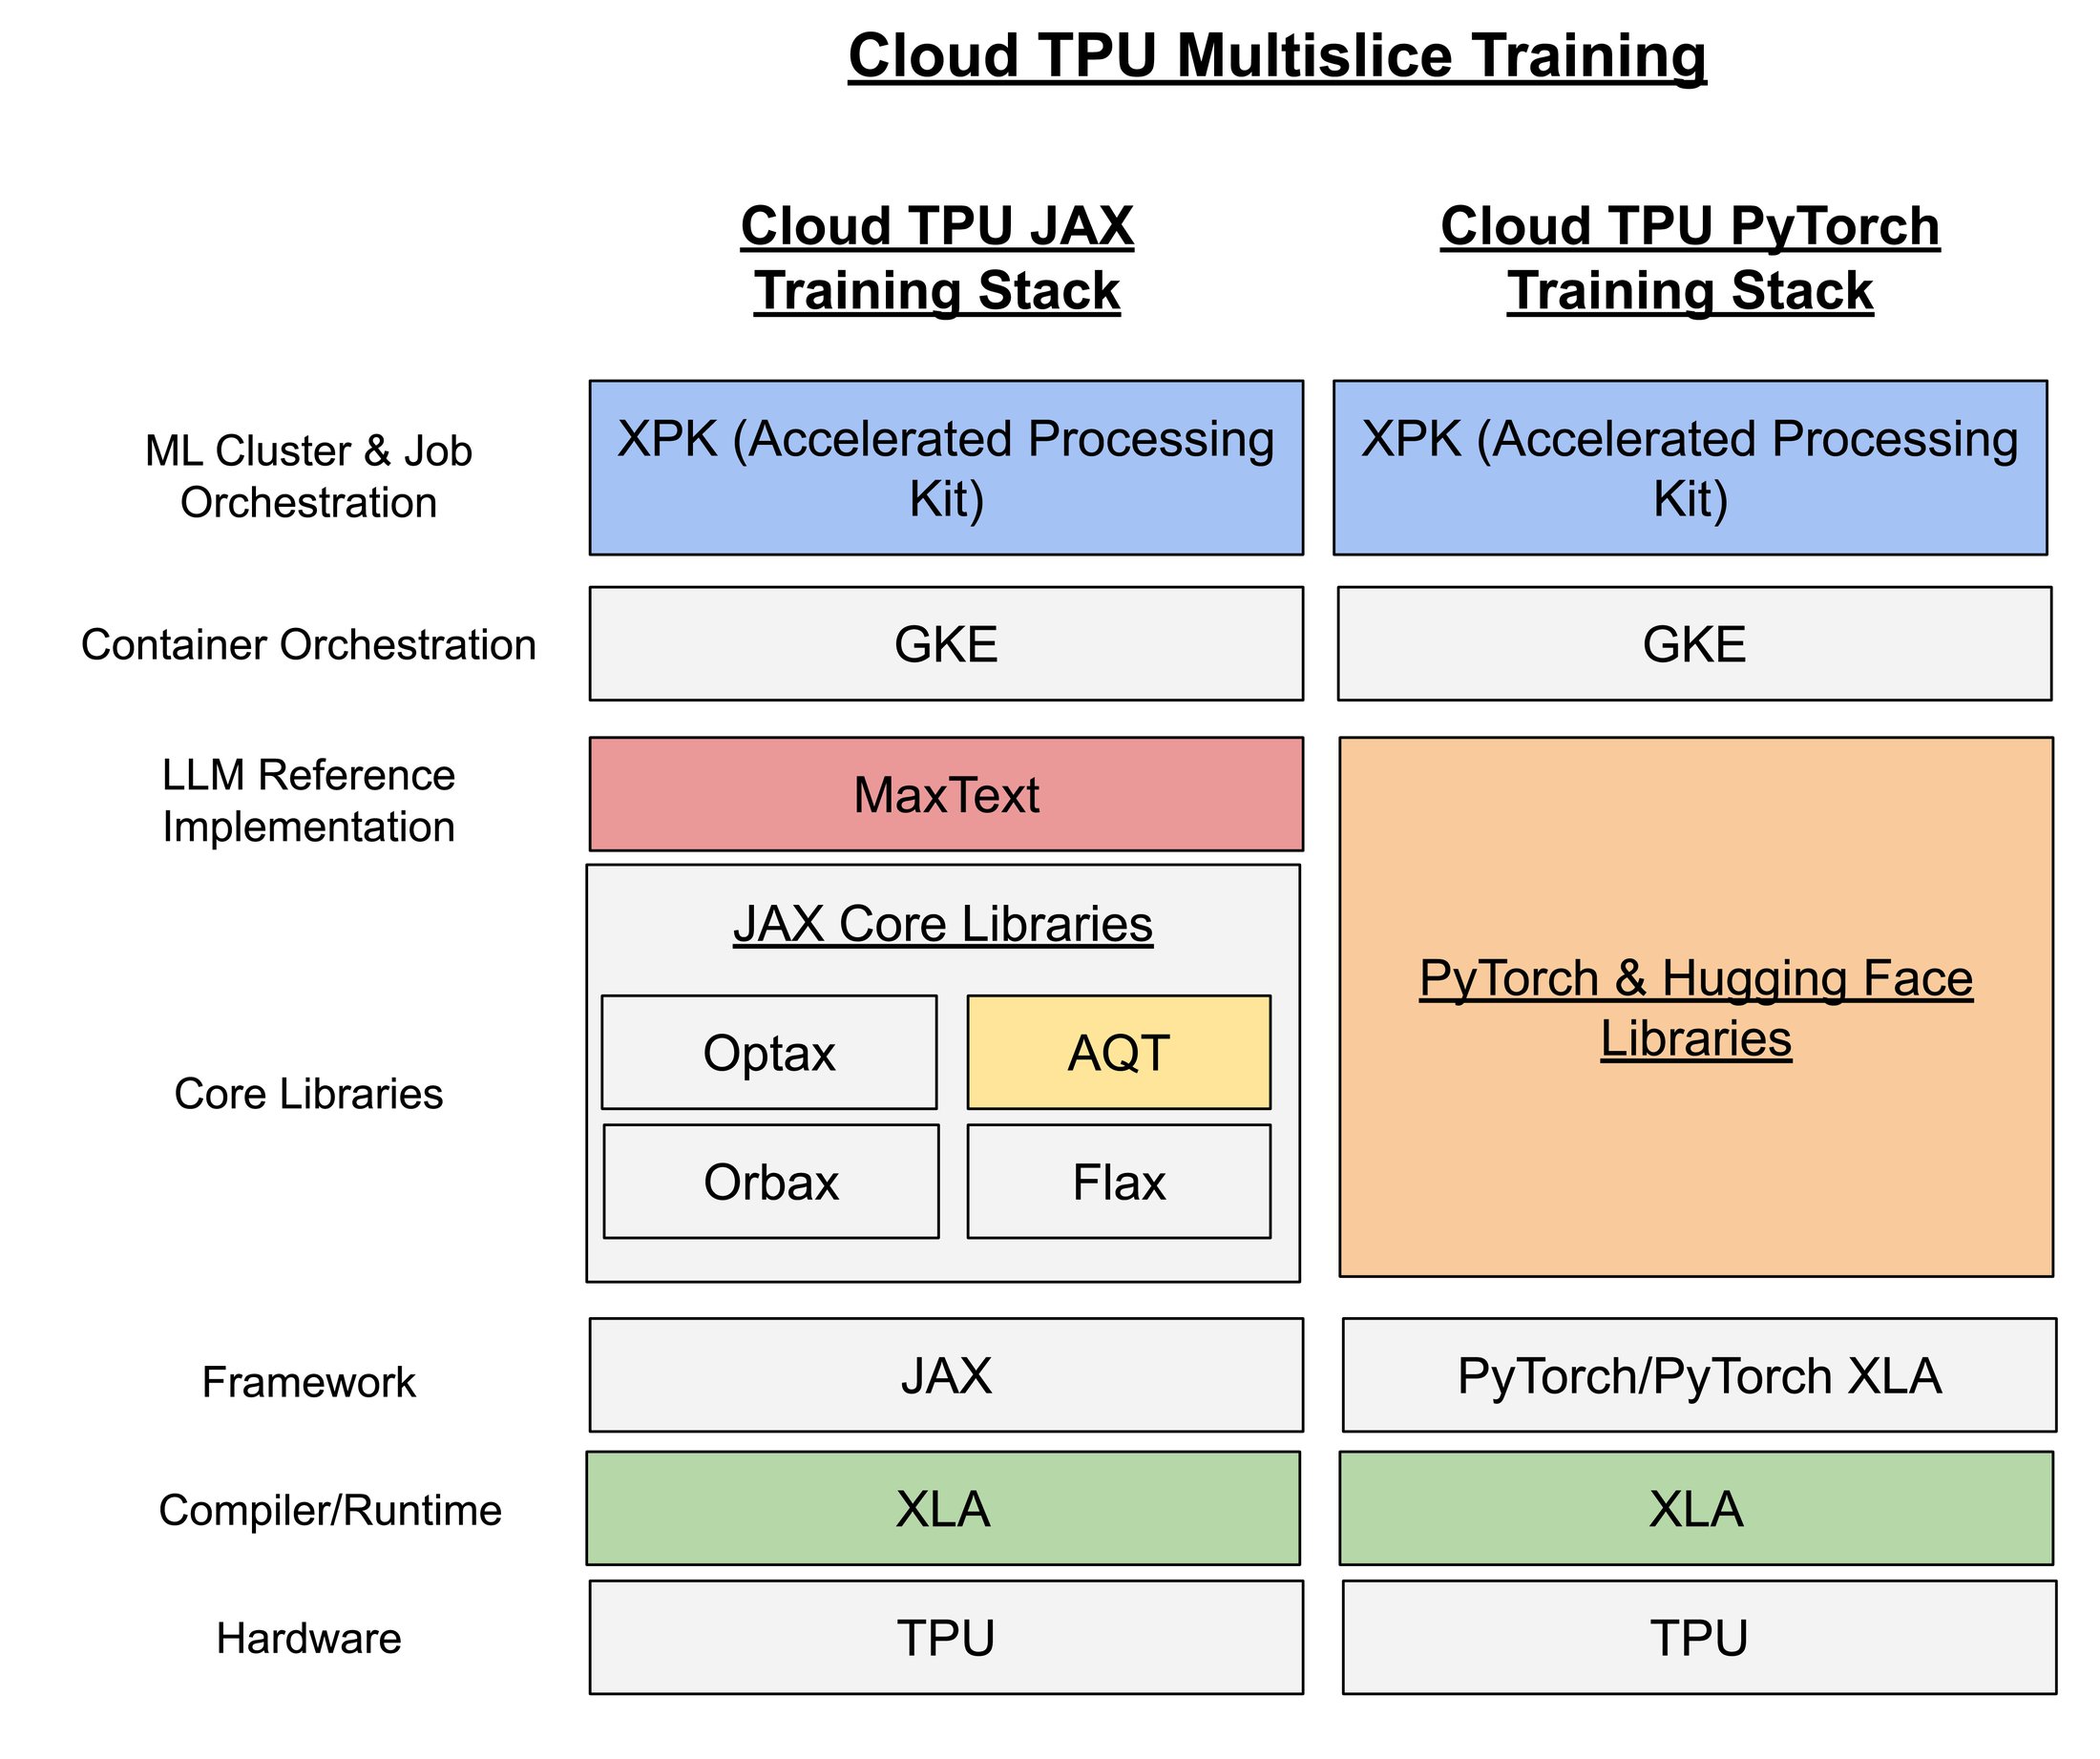
the world’s largest distributed LLM training job on TPU v5e | Google ...
Distributed Data Parallel: Speed Up LLM Fine-Tuning on Multiple GPUs ...
Read Think Practice: Data parallel and model parallel distributed ...
Introducing the LLM distributed training simulator | Epoch AI
LLM Training Framework: Tools, Models & Data
Fundamentals of Lustre Distributed Storage Supporting LLM Training
Data-Parallel Distributed Training of Deep Learning Models
Accelerating AI: Implementing Multi-GPU Distributed Training for ...
M30 - Distributed Training - DTU-MLOps
LLM Training Parallelism: A Practical Guide to Choosing the Right Strategy
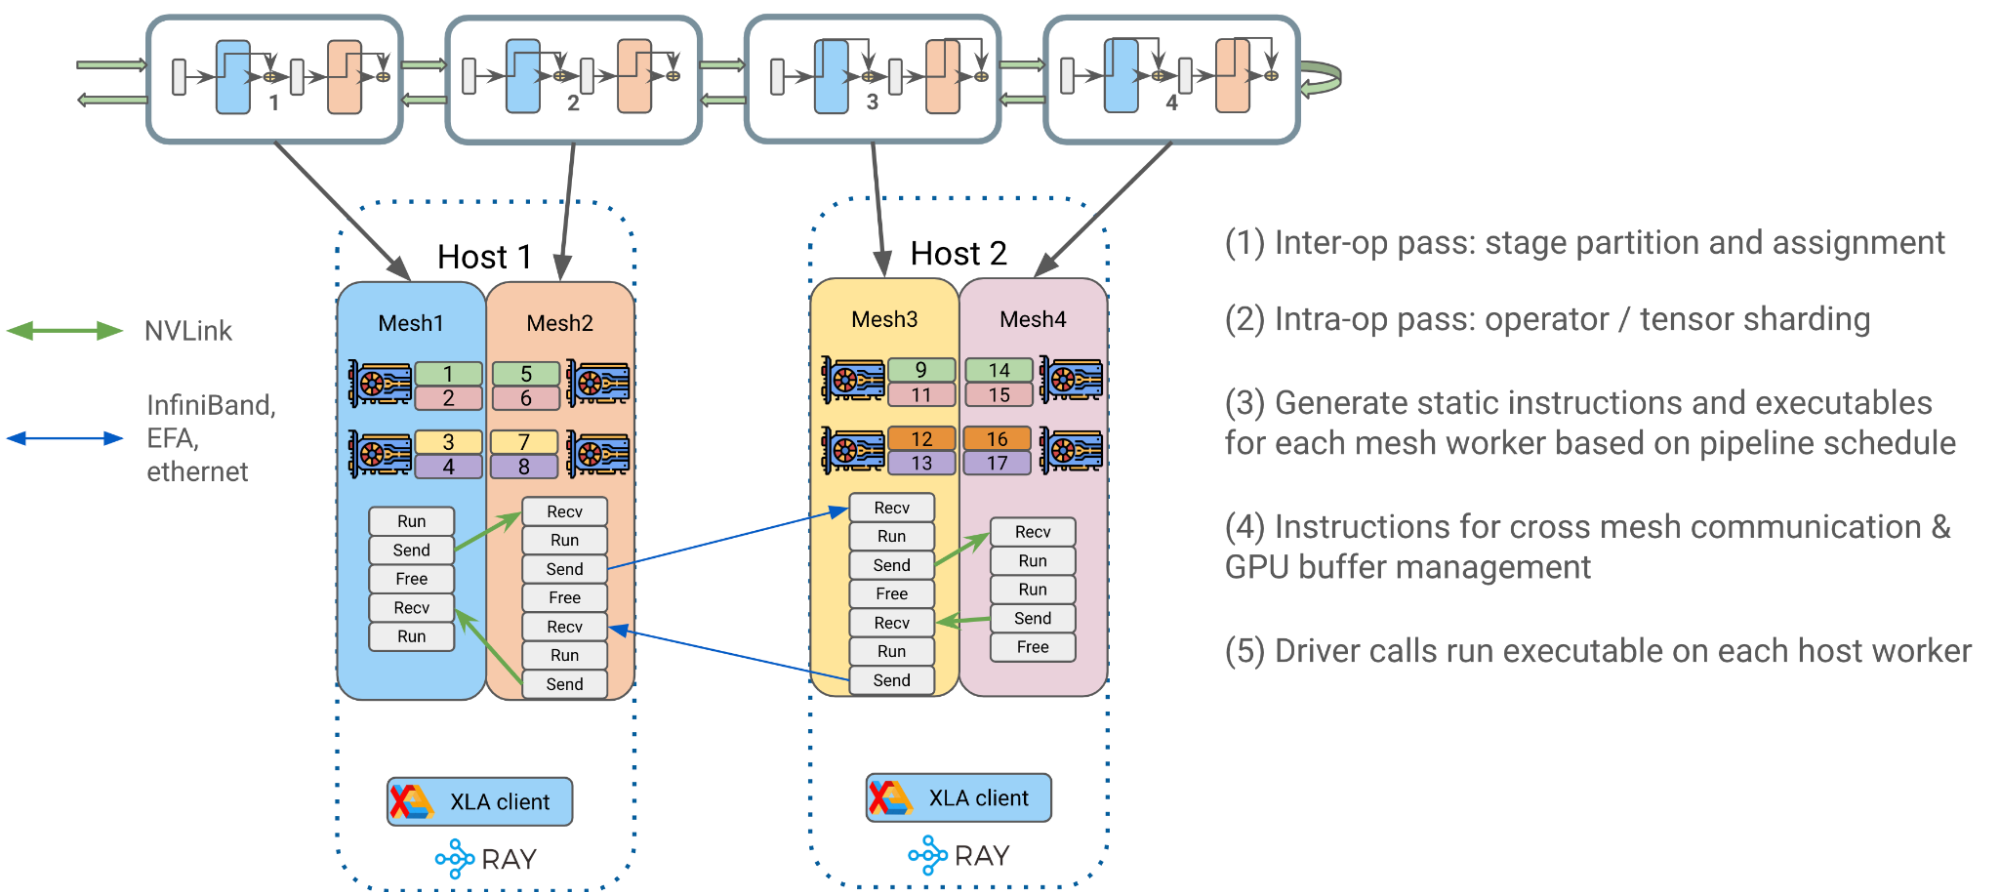
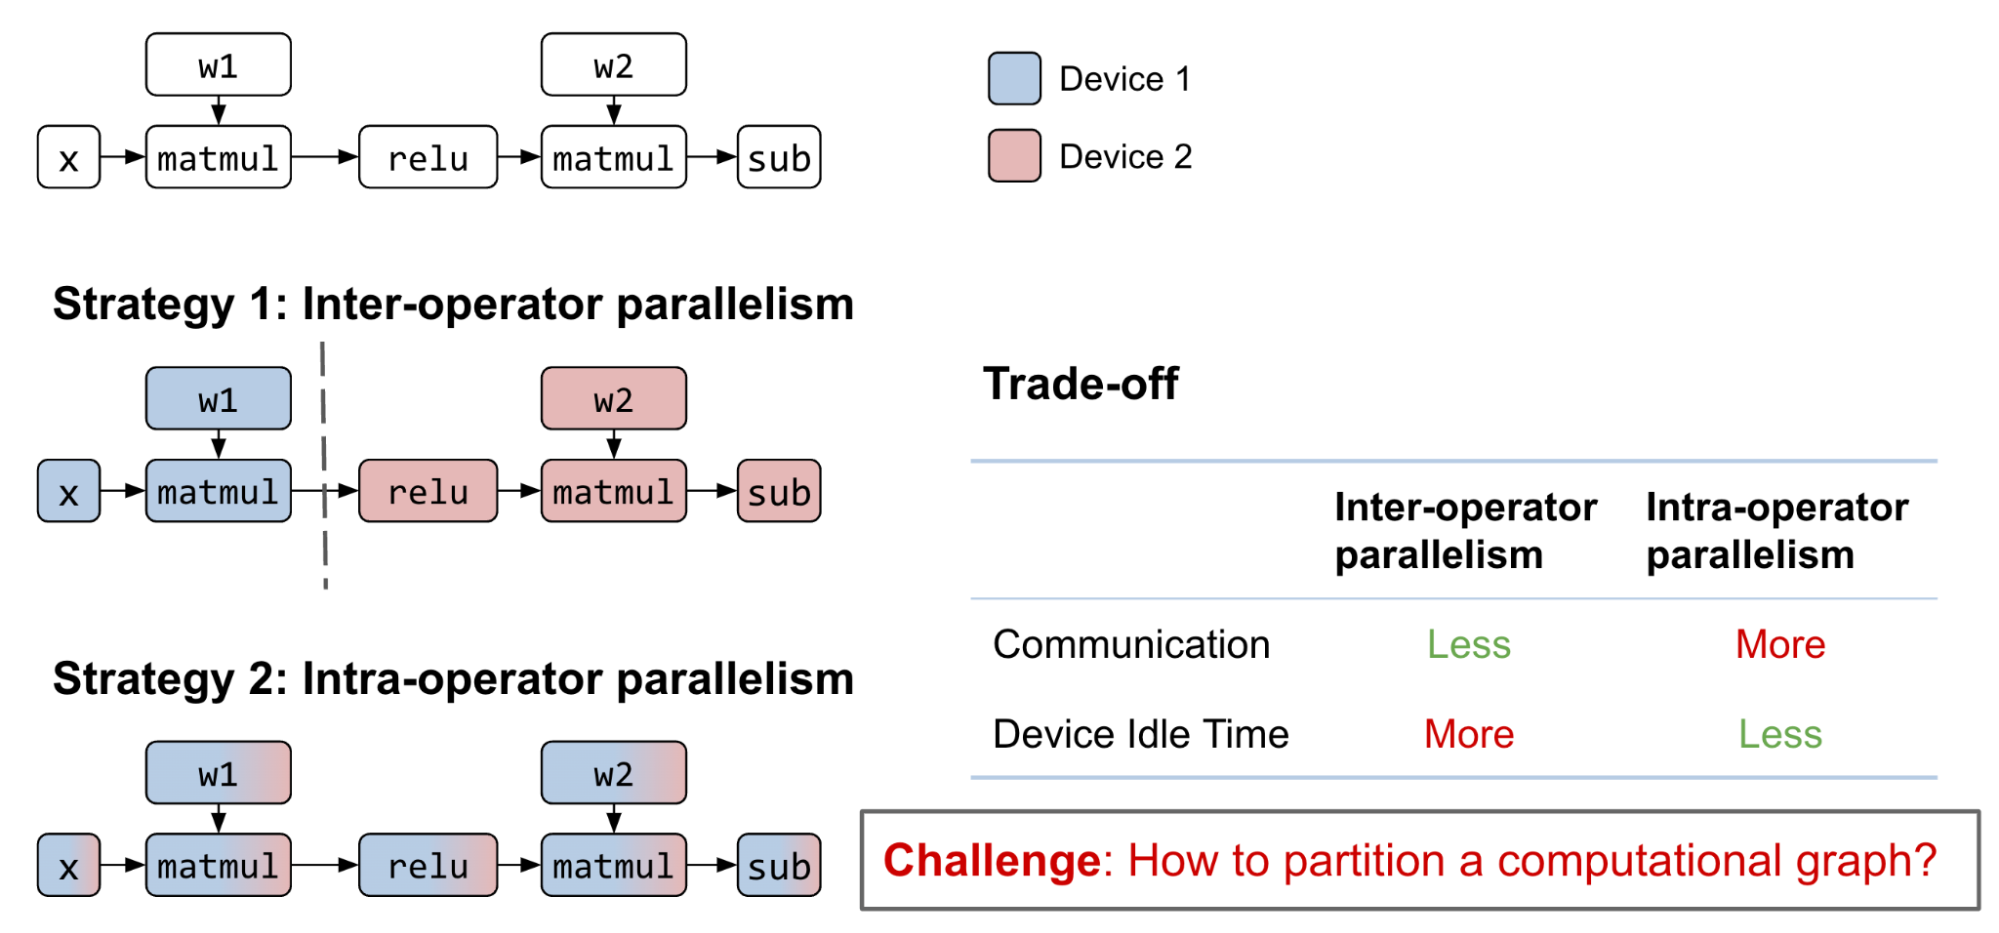
High-Performance LLM Training at 1000 GPU Scale With Alpa & Ray
Distributed Deep Learning training: Model and Data Parallelism in ...
Training LLMs - A Lazy Data Science Guide
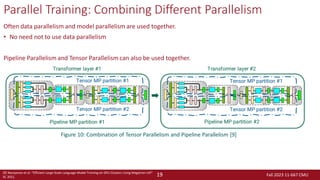
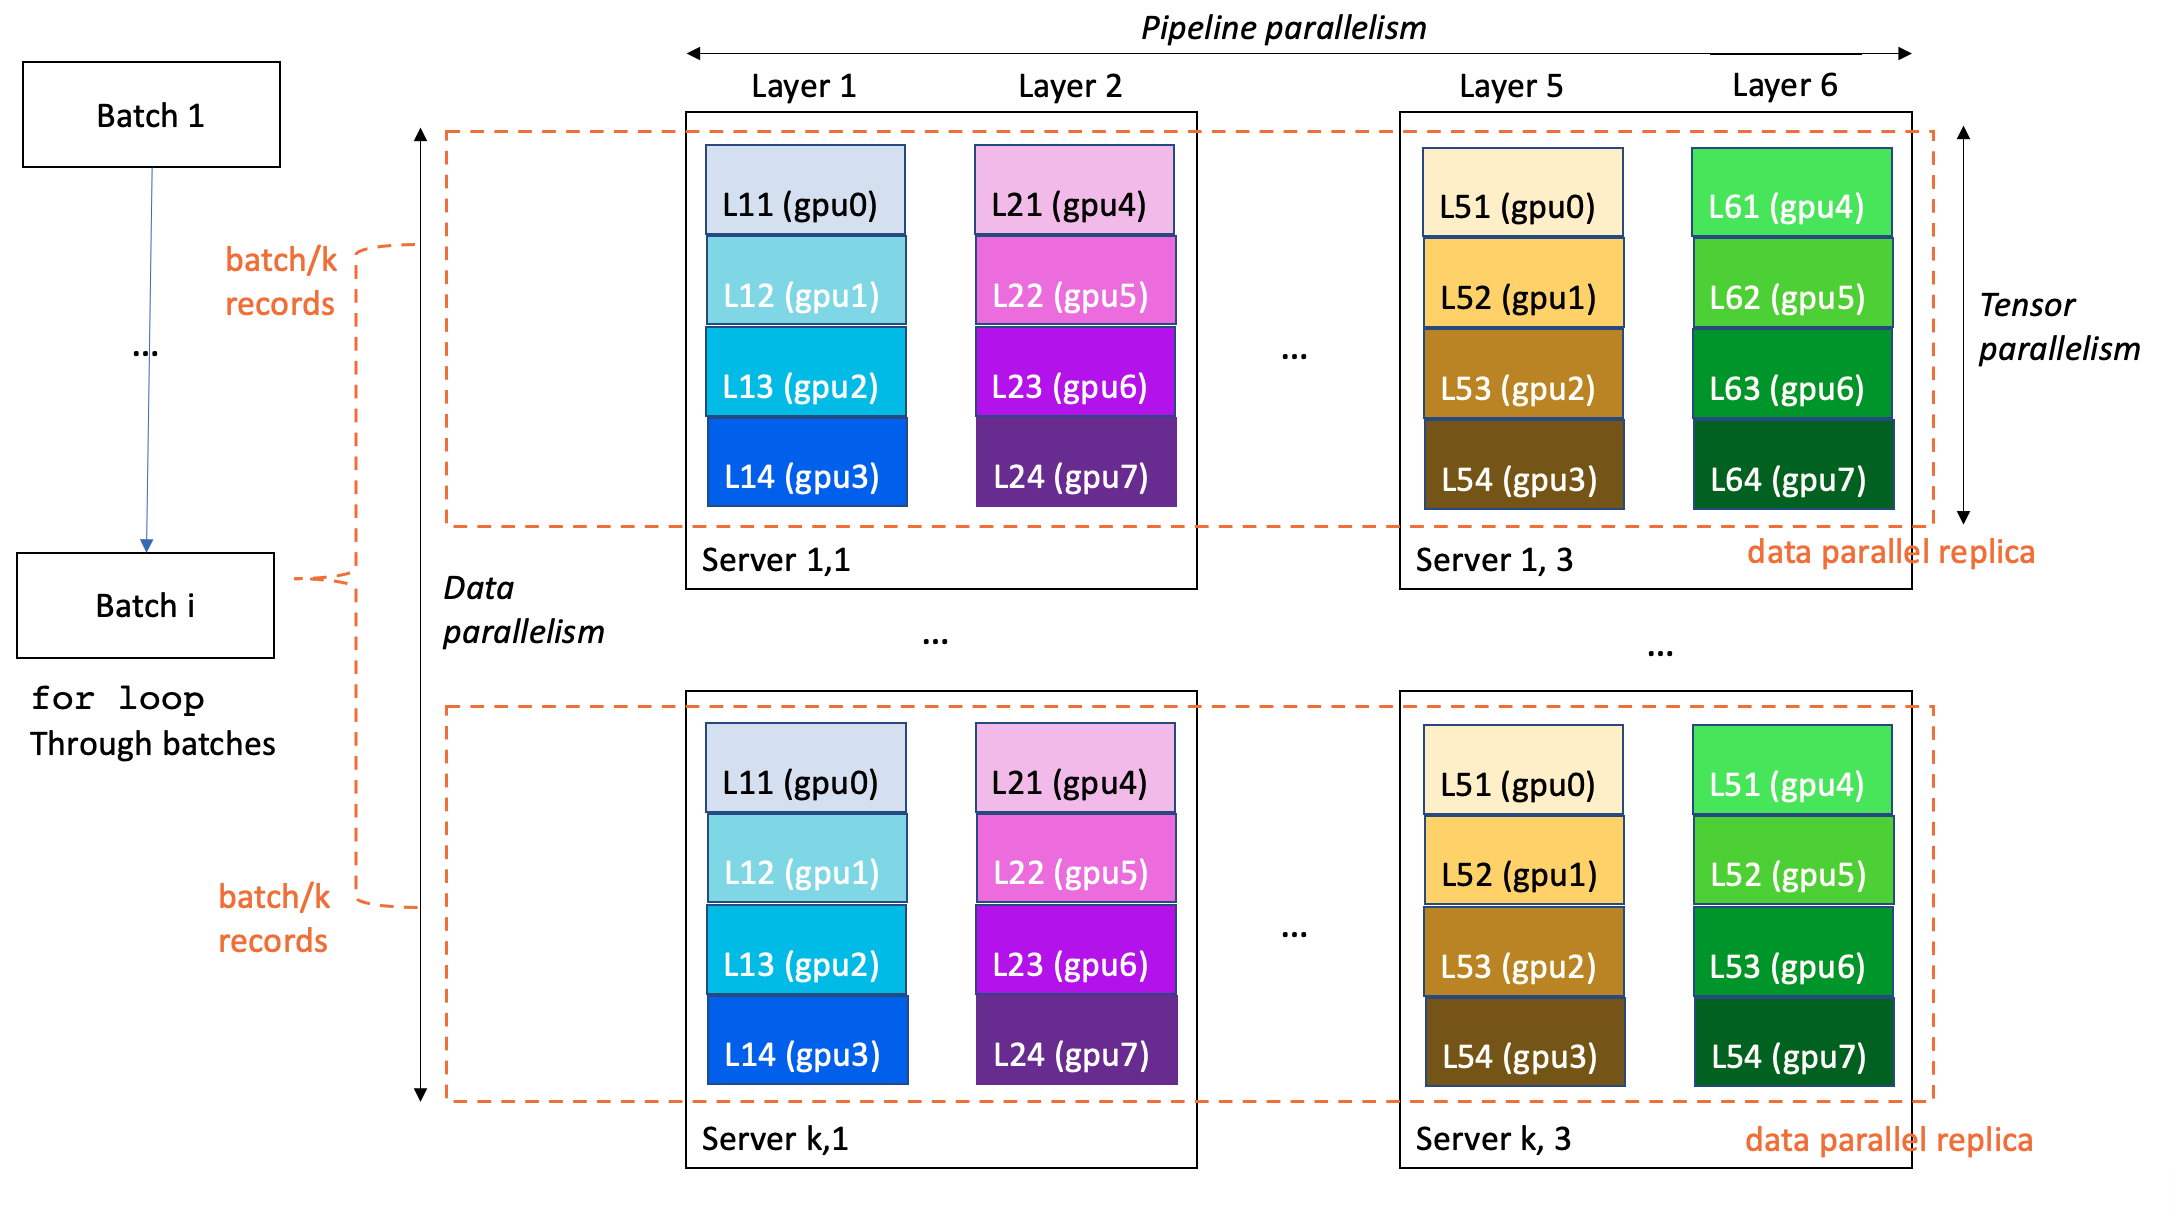
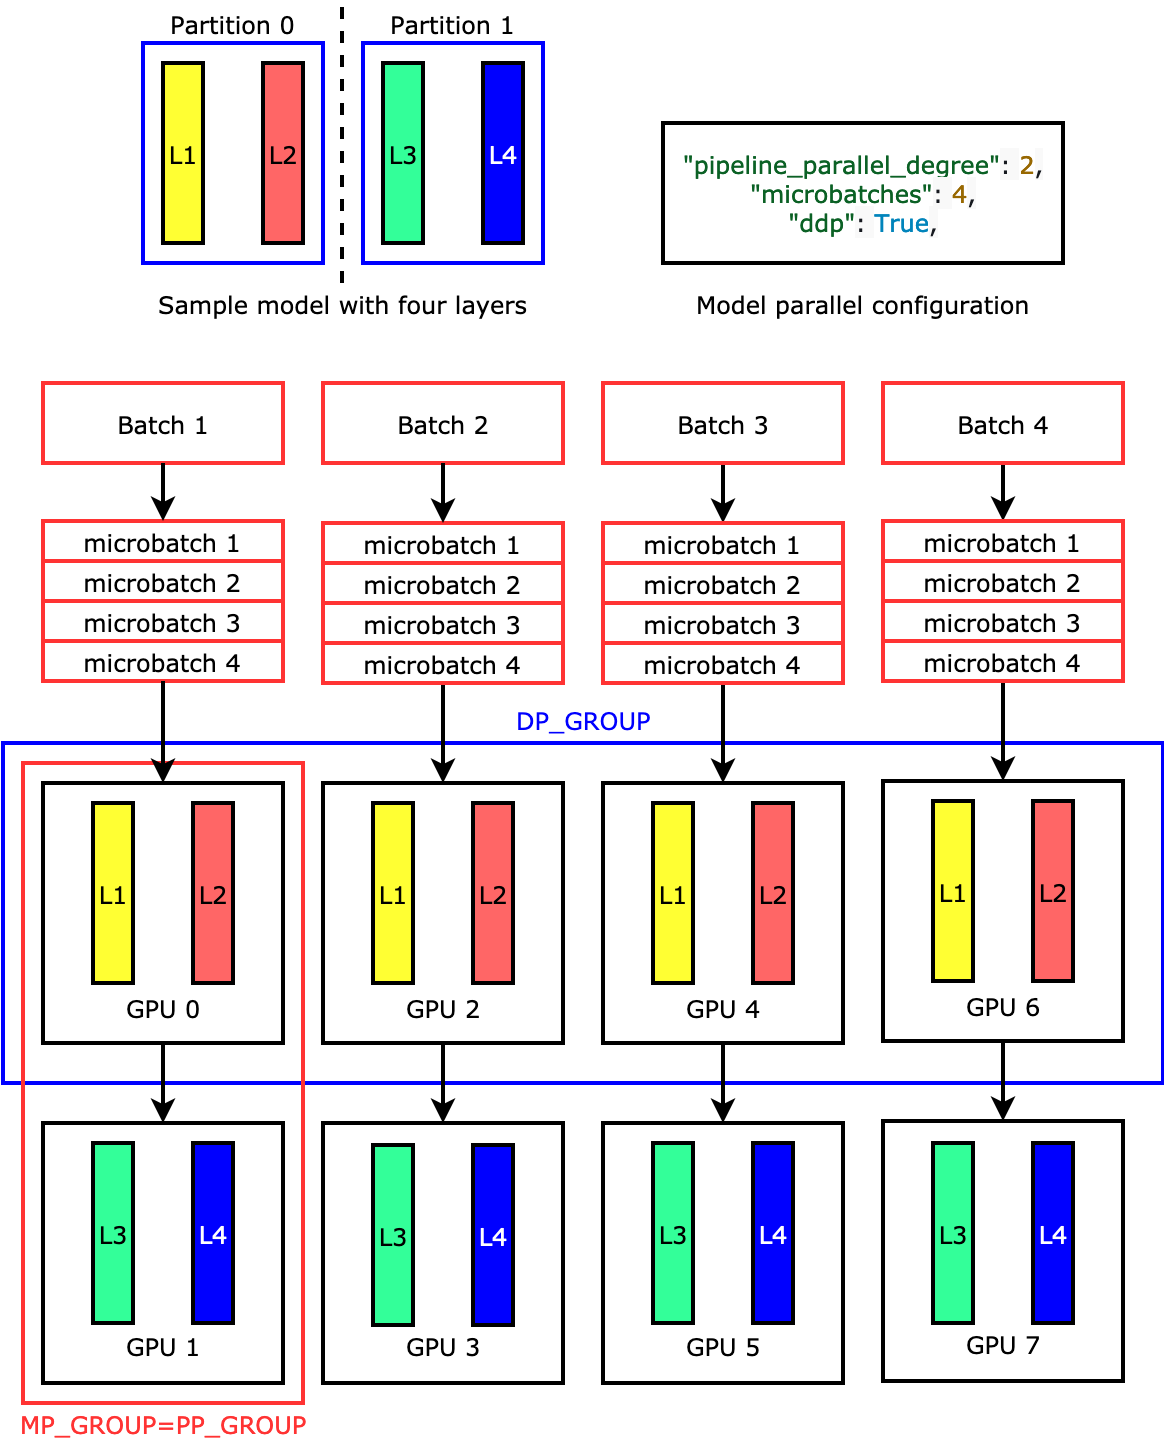
Example distributed training configuration with 3D parallelism, with 2 ...
Efficiently Scale LLM Training Across a Large GPU Cluster with Alpa and ...
gLLM: Global Balanced Pipeline Parallelism System for Distributed LLM ...
LLM in the Parallel Learning Framework. | Download Scientific Diagram
Distributed Training for LLMs - Best Generative AI & Machine Learning ...
Evolution of Distributed Training in Deep Neural Networks | Lazy Loaded ...
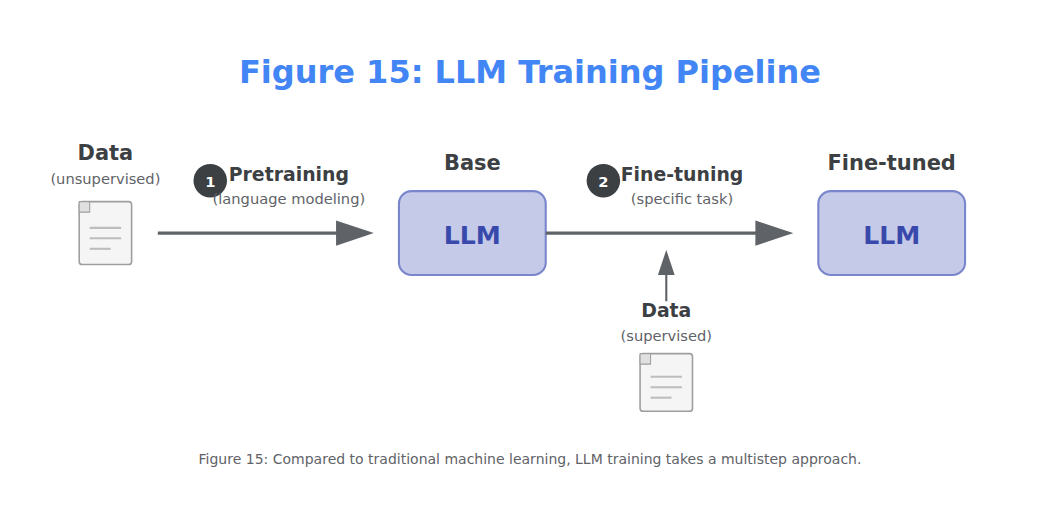
LLM Training Pipeline Overview | AI Tutorial | Next Electronics
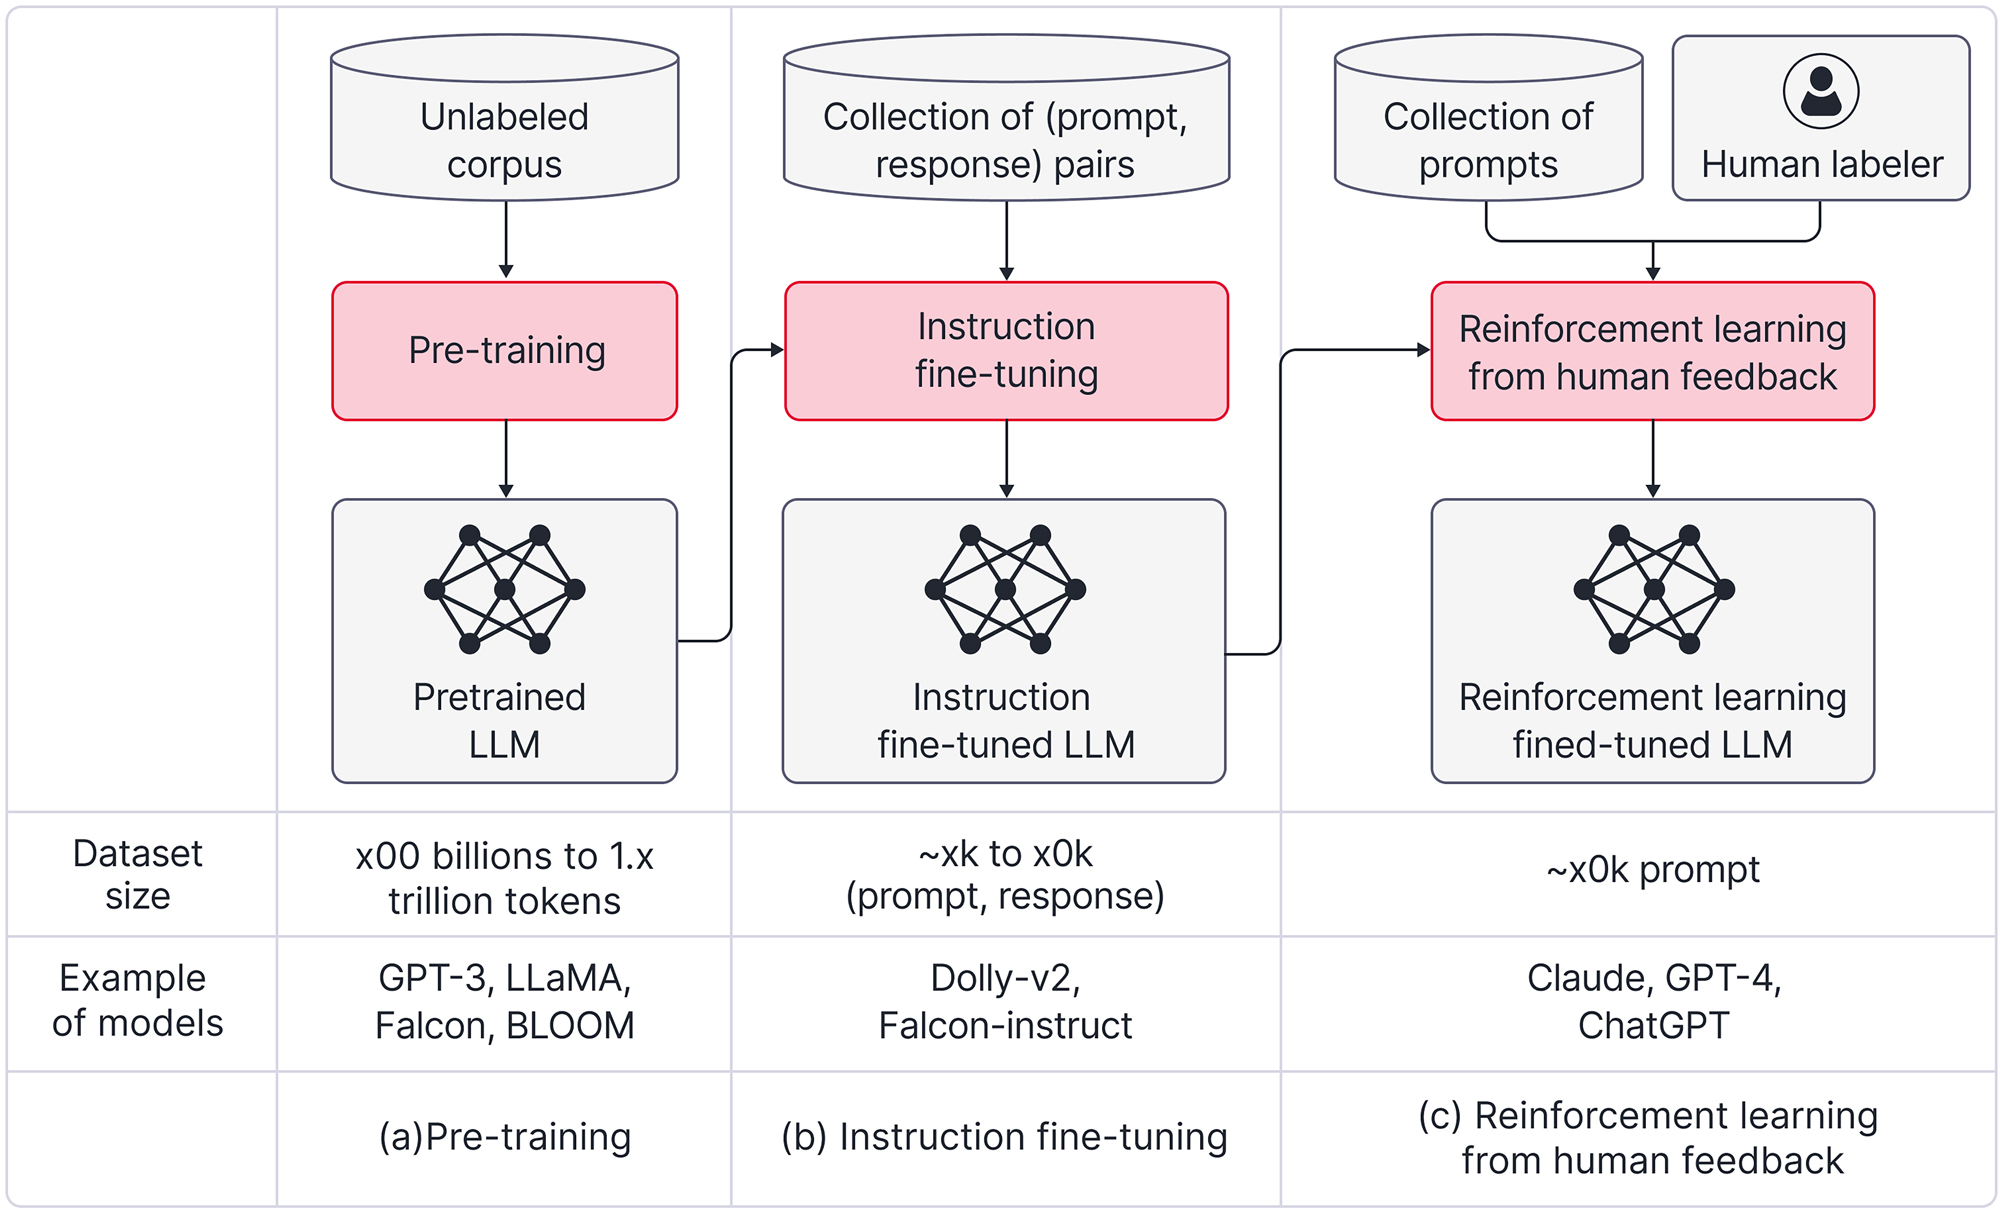
Different ways of training LLMs | Towards Data Science
Distributed Training · Apache SINGA
[2401.09796] A FAST, PERFORMANT, SECURE DISTRIBUTED TRAINING FRAMEWORK ...
LLMs 44. Distributed Training of Large Language Models (LLMs) | PracHub ...
Pipeline-Parallelism: Distributed Training via Model Partitioning
Parallel LLM Integration for Scalable AI Systems | Chappidi S posted on ...
LLM training overview
PARD: Accelerating LLM Inference with Low-Cost PARallel Draft Model ...
LLM x DATA - by Ashish IBM - Ashish’s Substack
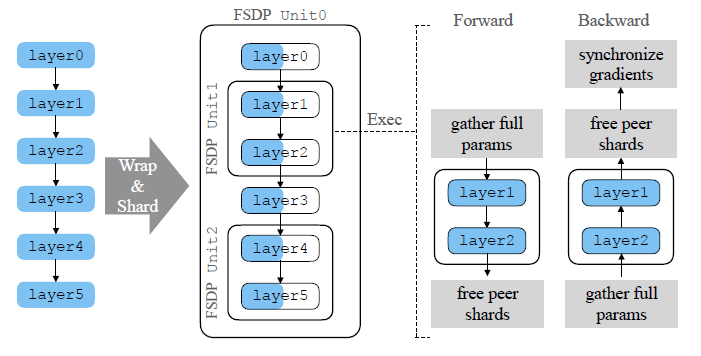
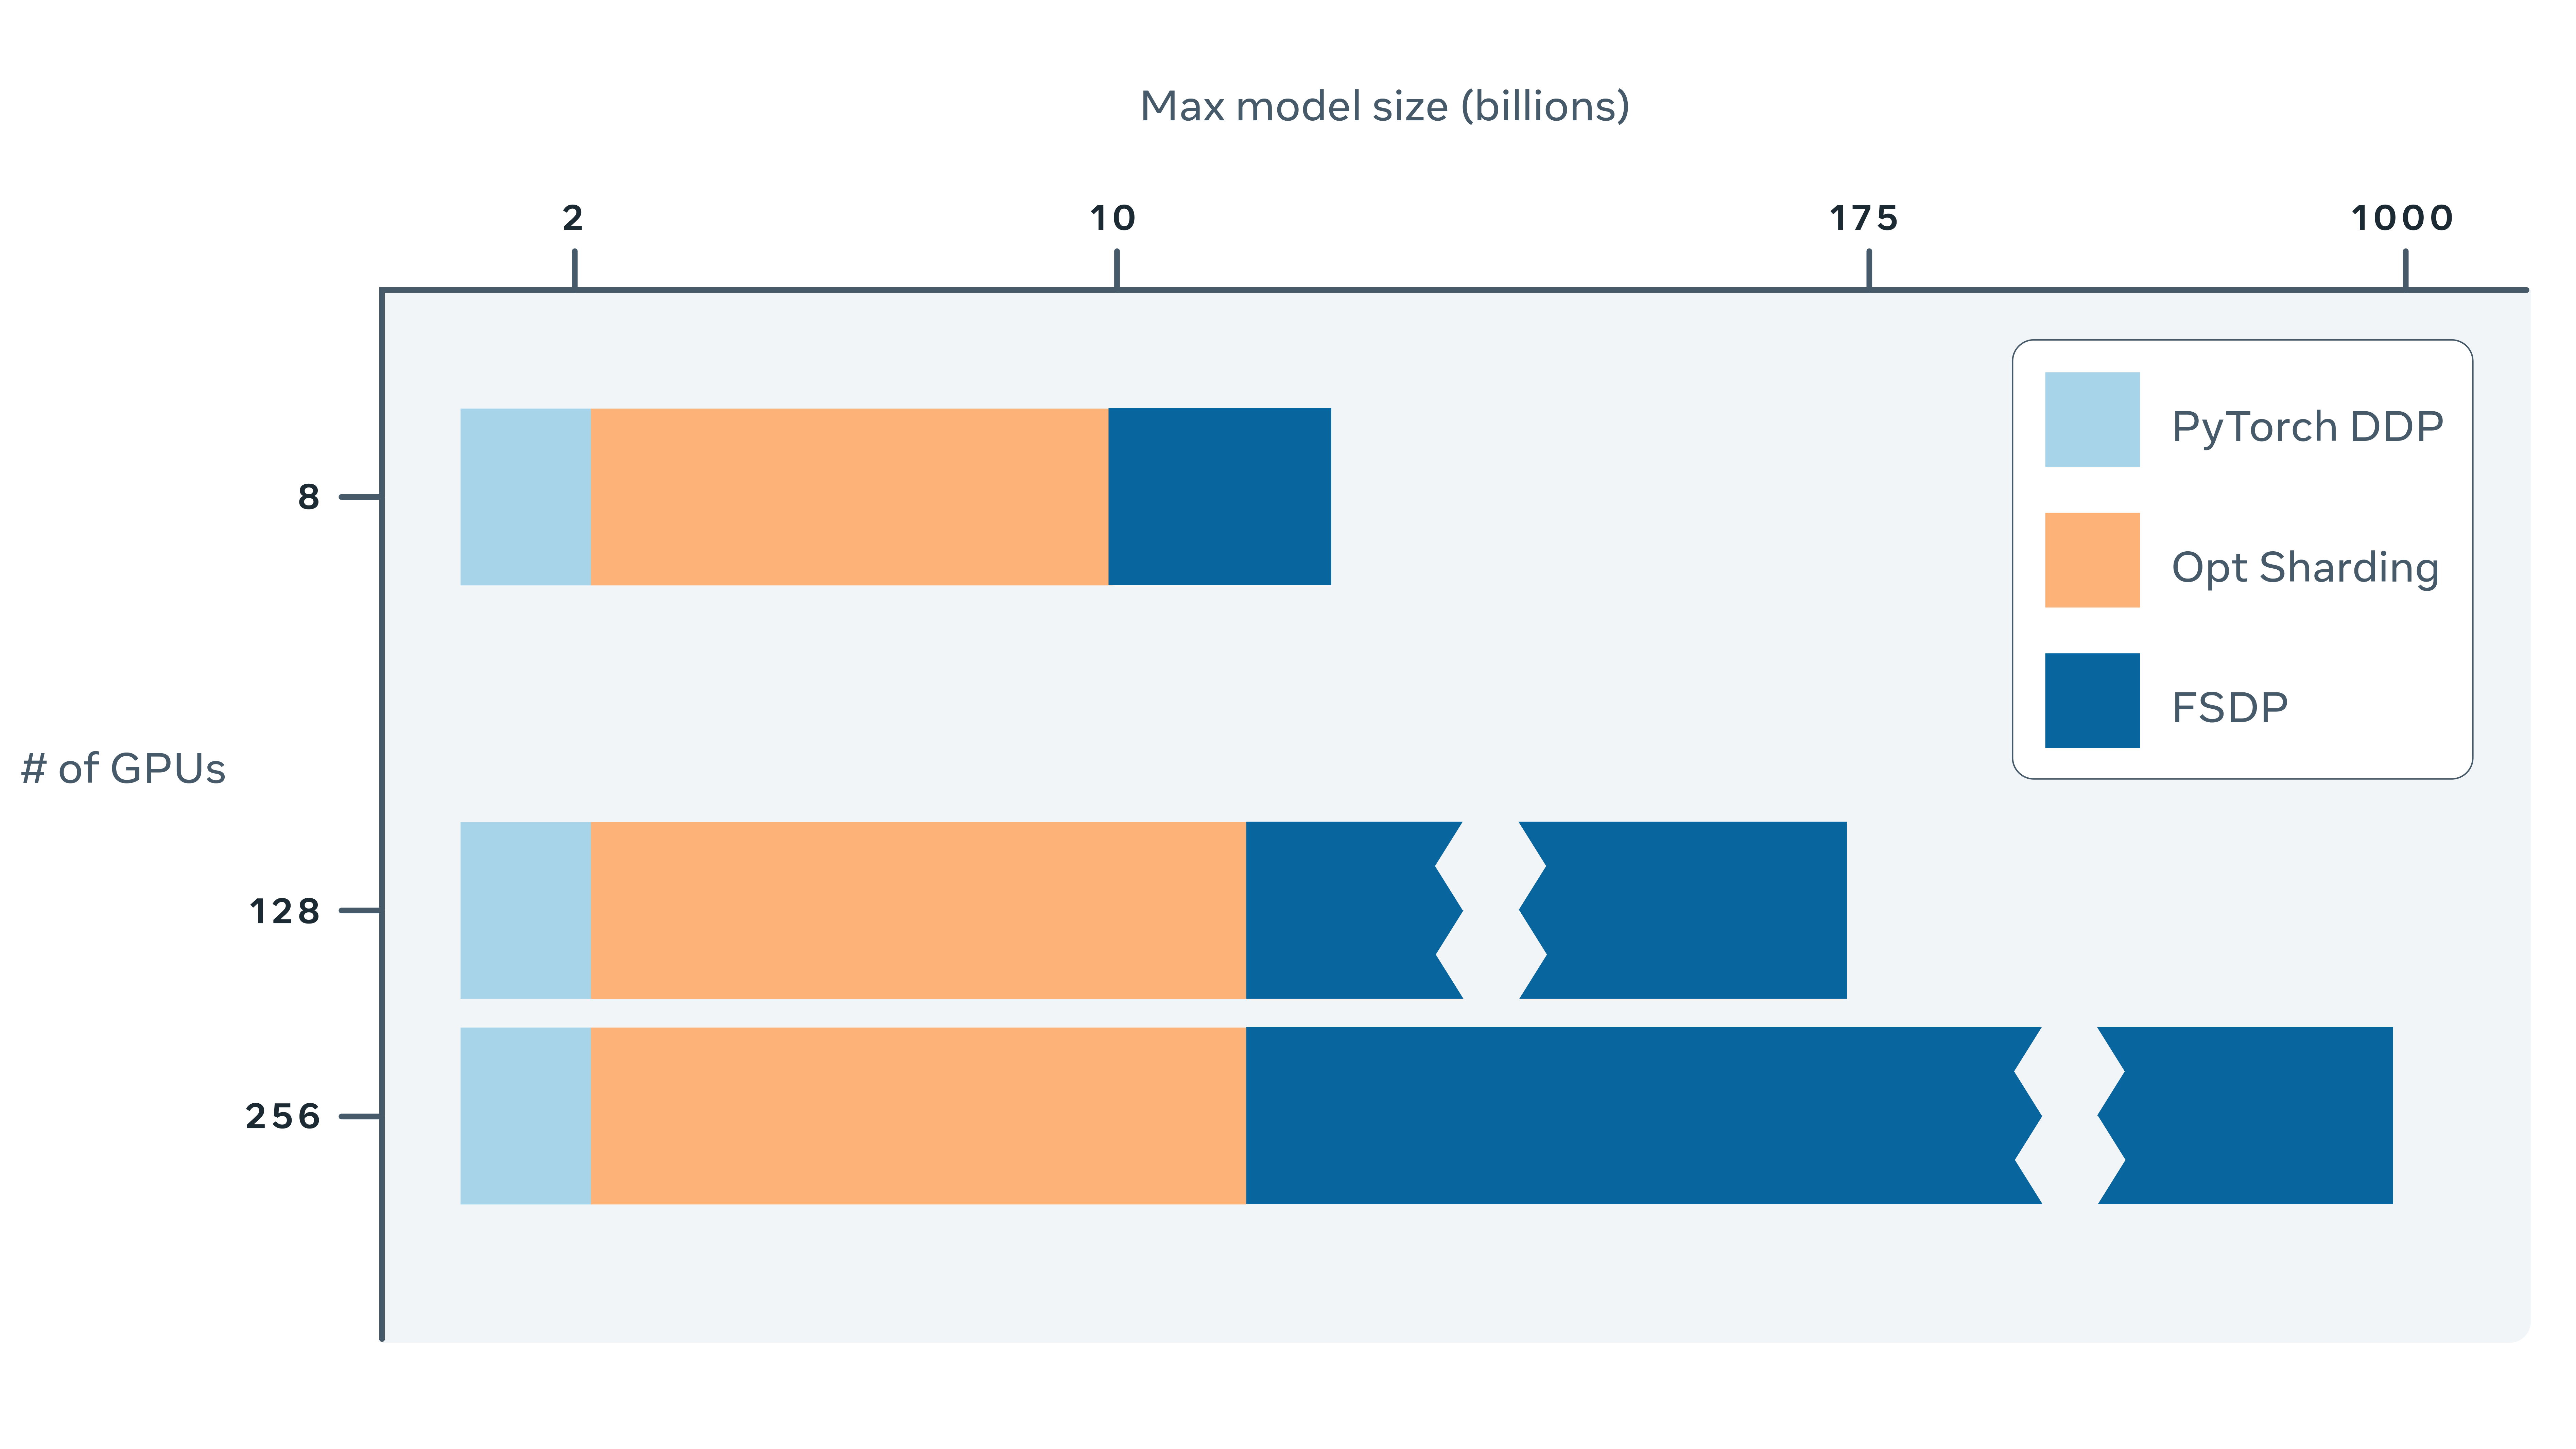
Fully Sharded Data Parallel: faster AI training with fewer GPUs ...
[论文评述] Efficient Code LLM Training via Distribution-Consistent and ...
Gradient Blog: Intro to Distributed LLM Training, Part 1: Orchestration ...
The Logistics of Large-Scale Training: Distributed Training and the ...
Diversity-Aware Self-Paced Data Selection for LLM Fine-Tuning, 2026
[논문 리뷰] Mechanistic Data Attribution: Tracing the Training Origins of ...
(4/6) AI in Multiple GPUs: Grad Accum & Data Parallelism – Lorenzo ...
Training large language models on Amazon SageMaker: Best practices ...
What Is Distributed Training?
[2401.02038] Understanding LLMs: A Comprehensive Overview from Training ...
Top Five Tips and Tricks for LLM Fine-Tuning and Inference
Distributed Machine Learning – Part 2 Architecture – Studytrails
Pytorch Data Parallelism | Datumorphism | L Ma
Intro Distributed Deep Learning | Xiandong
[논문 리뷰] Bandwidth-Aware and Cost-Efficient Pipeline Parallel Scheduling ...
LLM Benchmark Comparison Dashboard | Simulations4All
3 Techniques to Train An LLM Using Another LLM
How to Train an LLM: 2025 Workflow Guide | Label Your Data
CTCCL: Cost-Efficient Joint Device-Network Load Balancing for LLM ...
Data Quality Is All You Need? | Shashank Shekhar
GitHub - anyscale/e2e-llm-workflows: Fine-tune an LLM to perform batch ...
Bandwidth-Aware and Cost-Efficient Pipeline Parallel Scheduling in Geo ...
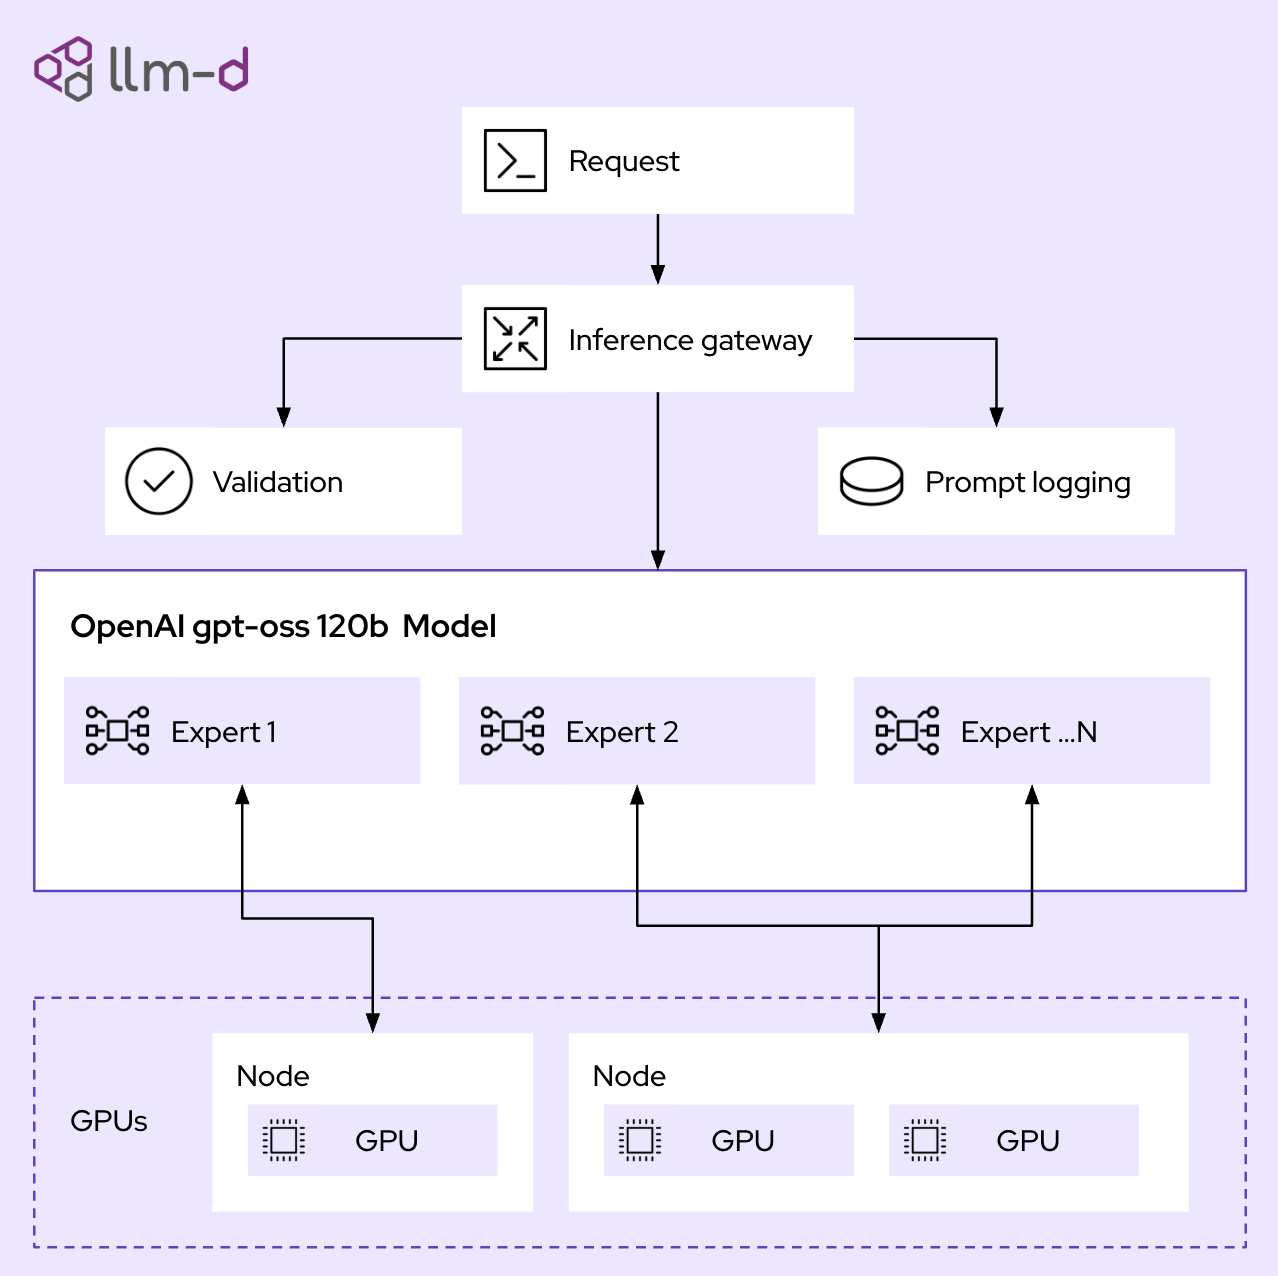
Introduction to distributed inference with llm-d | Red Hat Developer
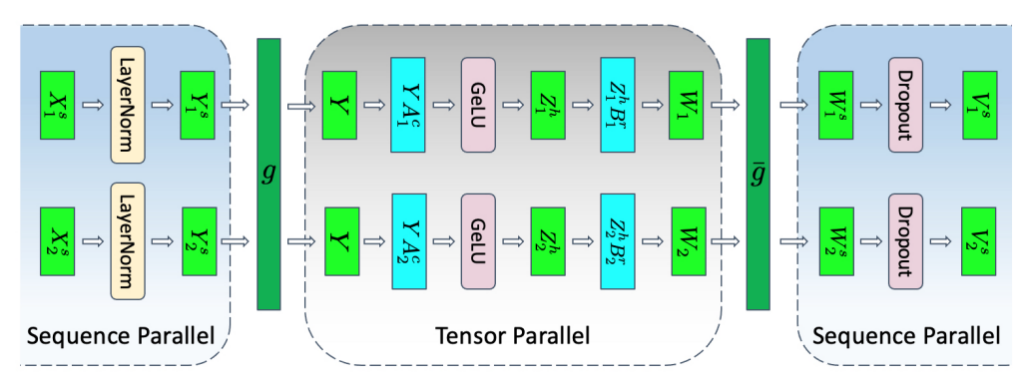
使用 Alpa 和 Ray 在大型 GPU 集群中高效扩展 LLM 训练 - NVIDIA 技术博客
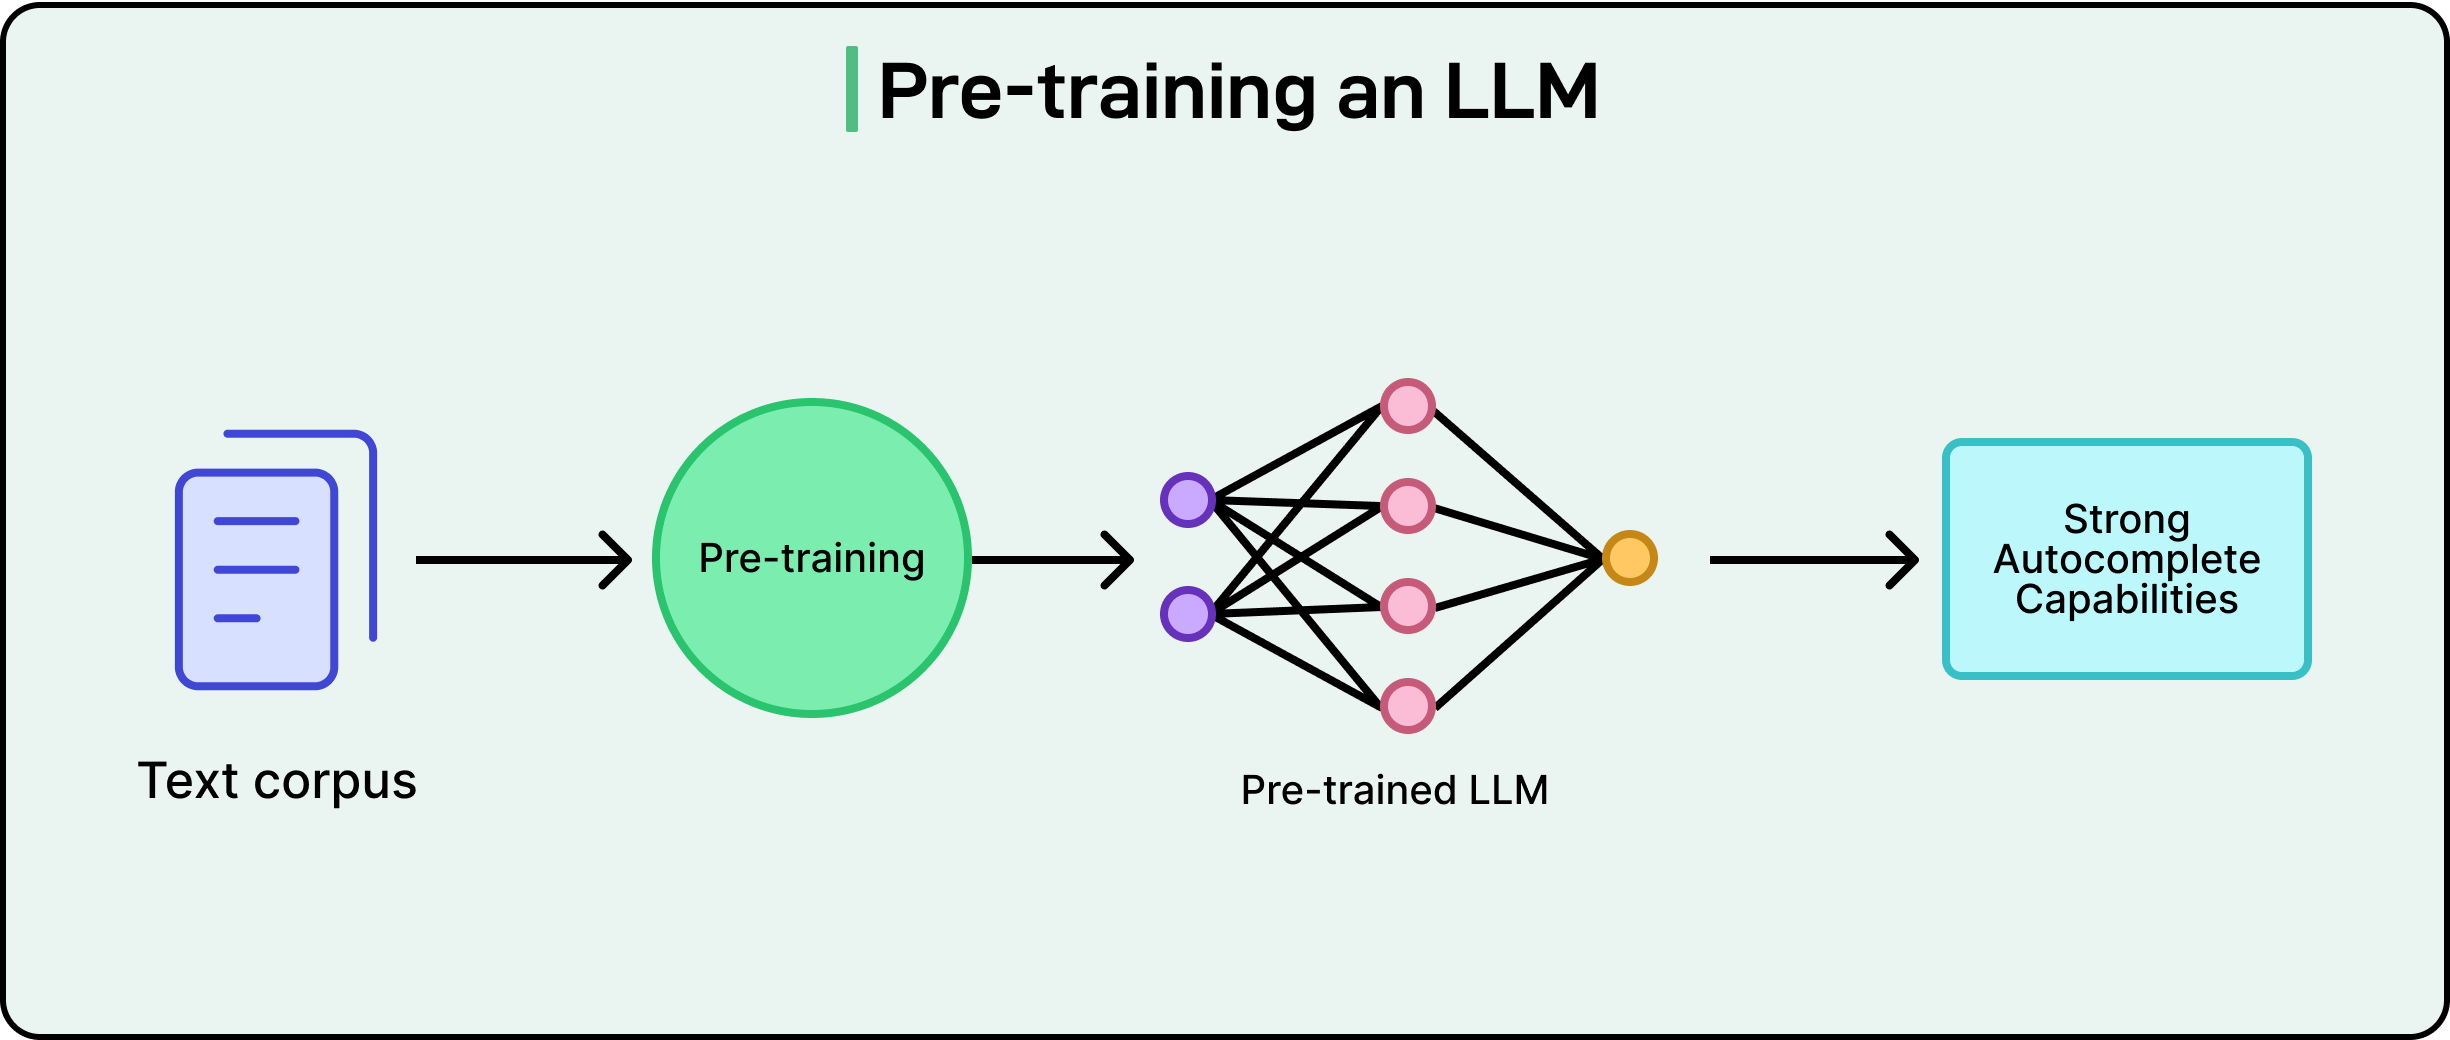
A Comprehensive Guide to LLM Pretraining
Outshift | Training LLMs: An efficient GPU traffic routing mechanism ...
[2402.06682] Private Knowledge Sharing in Distributed Learning: A Survey
Mastering LLM Techniques: Inference Optimization | NVIDIA Technical Blog
How to Train an LLM on Your Own Data: Beginner’s Guide | Heavybit
How LLMs Learn from the Internet: The Training Process
The Open LLM Leaderboard is Closing - by Donato Riccio
The backbone of large language models: understanding training datasets
Essential Practices for Building Robust LLM Pipelines
Enhanced MoE Parallelism, Open-source MoE Model Training Can Be 9 Times ...
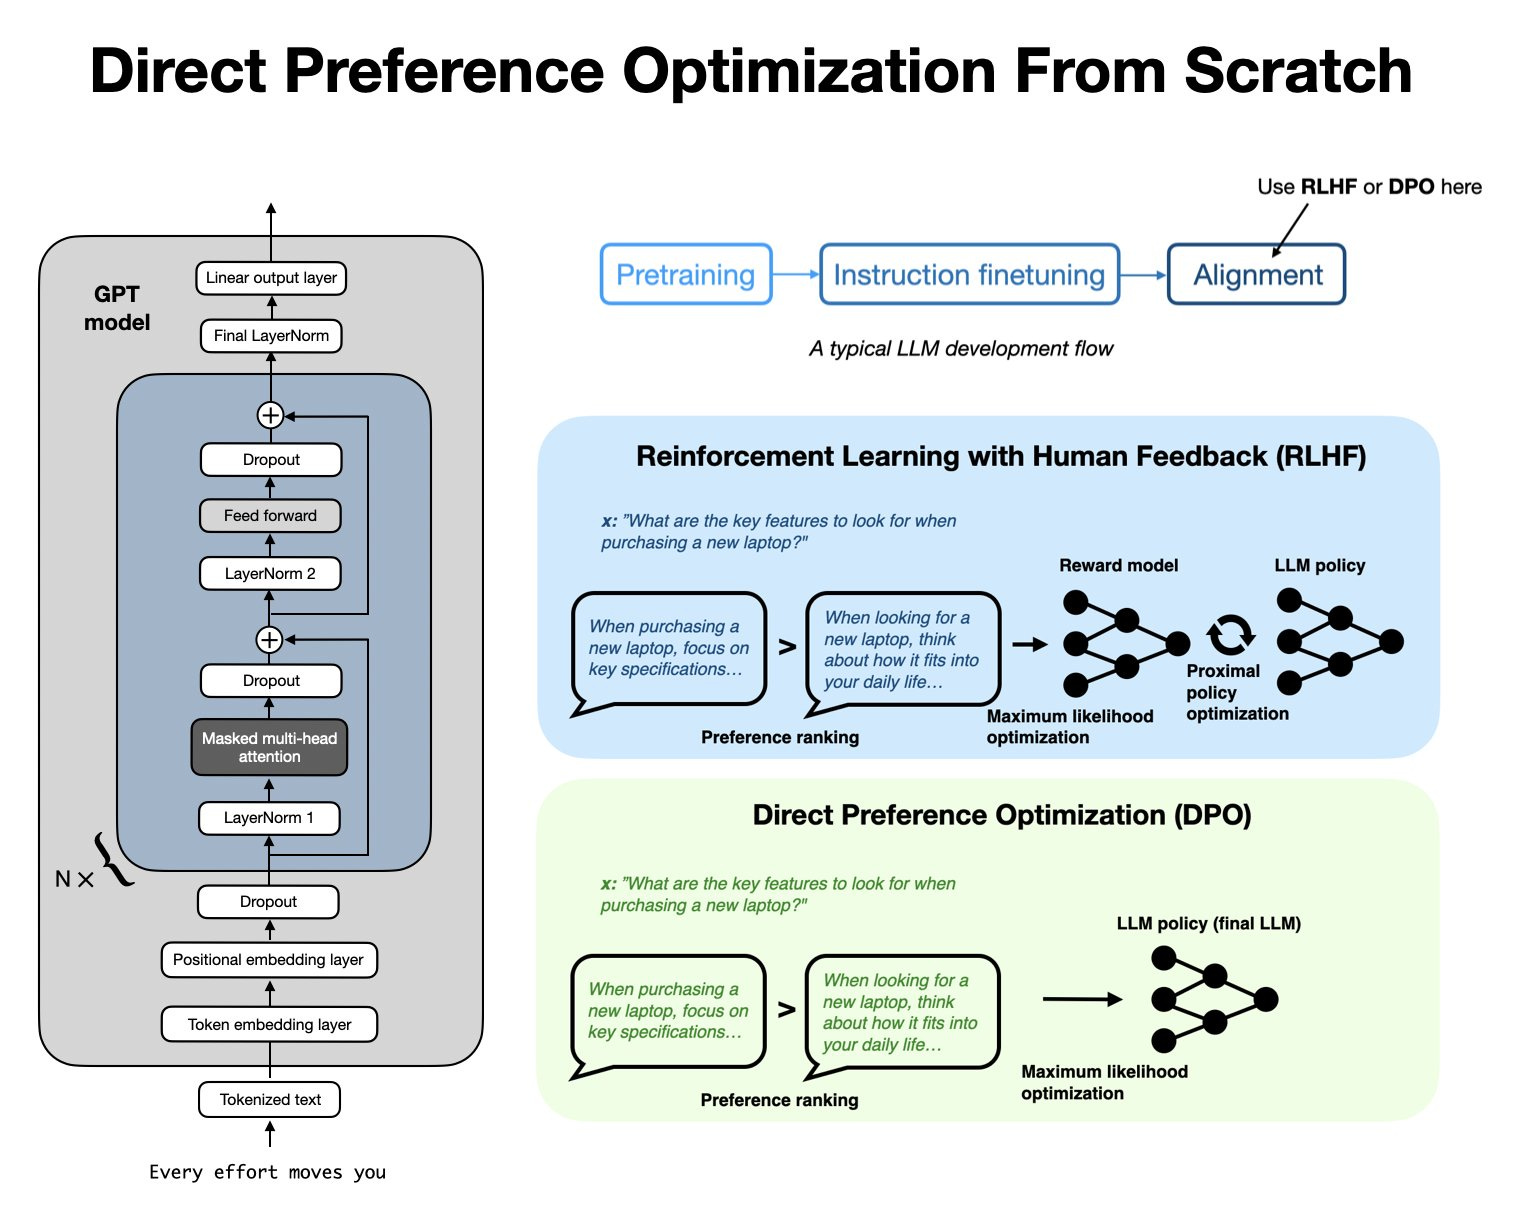
New LLM Pre-training and Post-training Paradigms
Open-Sourced Training Datasets for Large Language Models (LLMs)
An Overview of LLM Pre-Training
Navigating LLM Deployment: Tips, Tricks, and Techniques - InfoQ
Expert Parallelism and Mixed Parallelism Strategies in vLLM | Jarvis ...
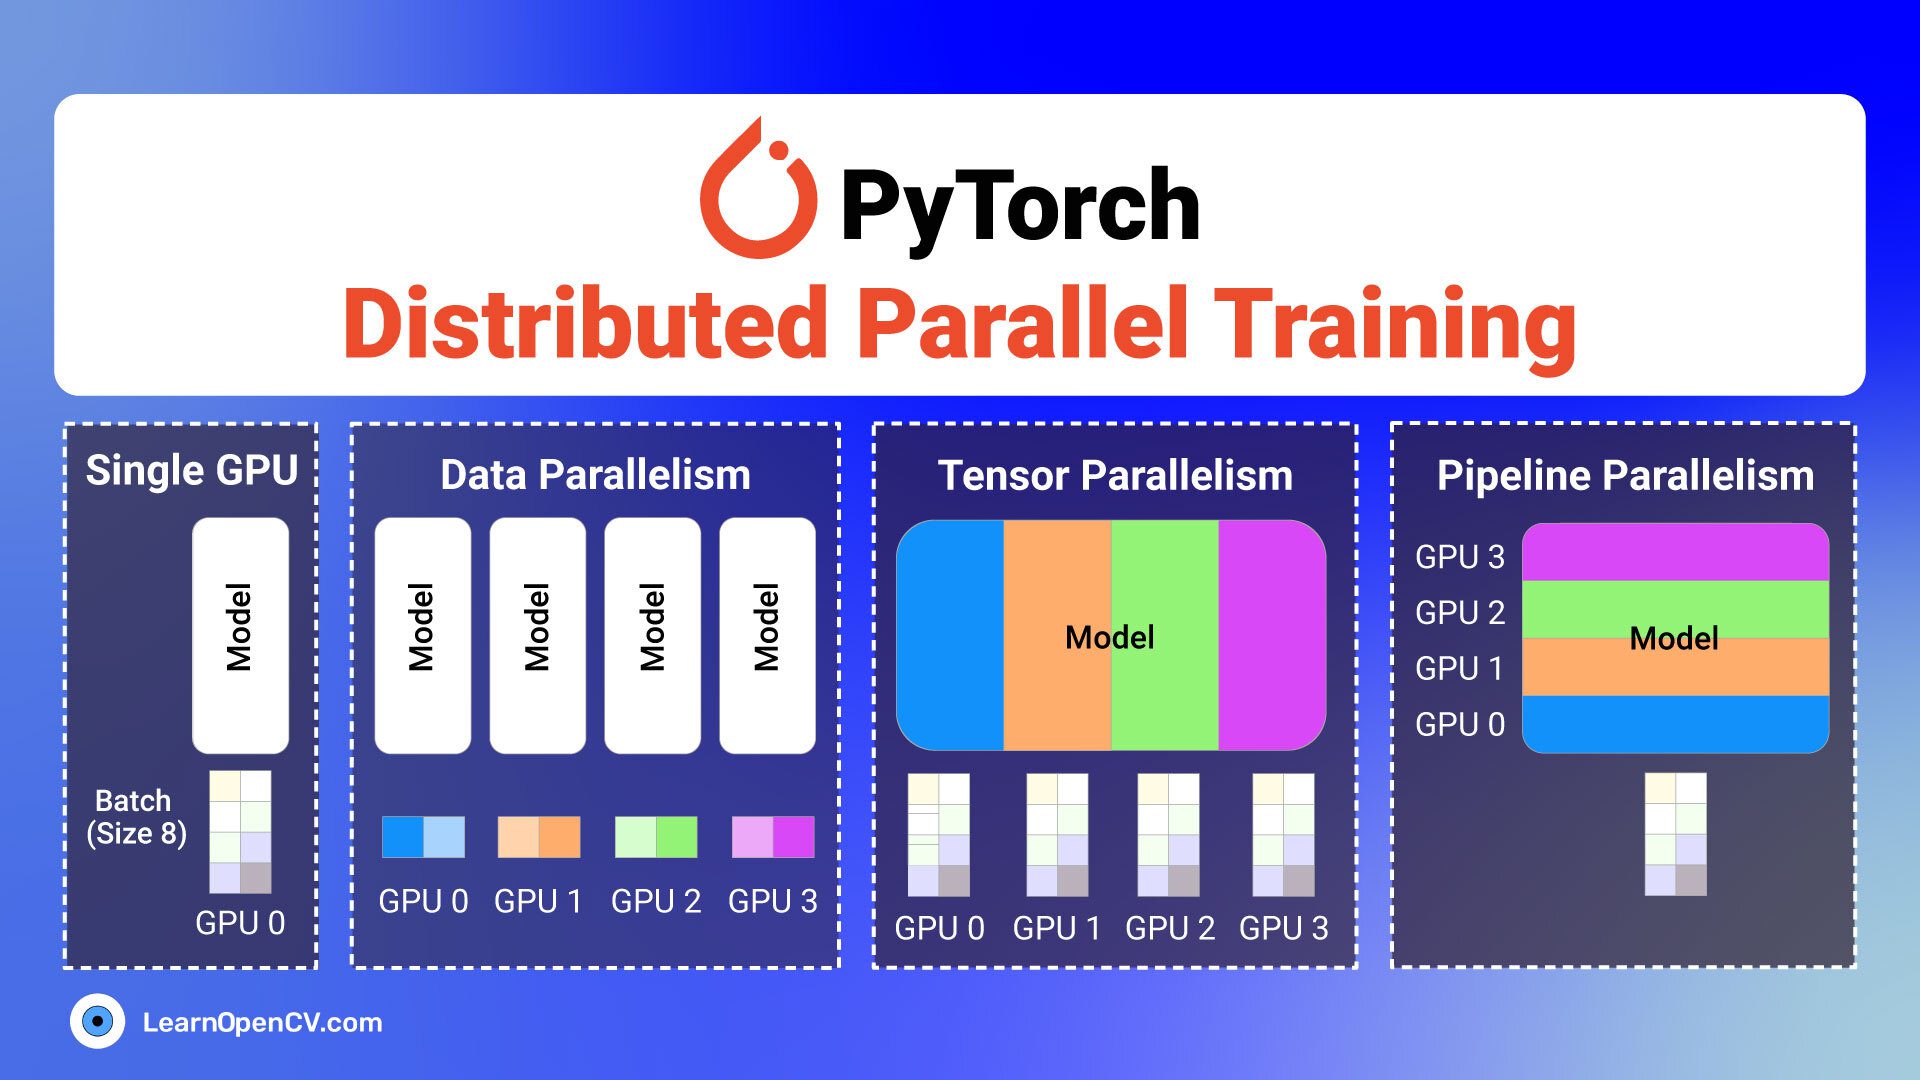
torch | LearnOpenCV
Medium
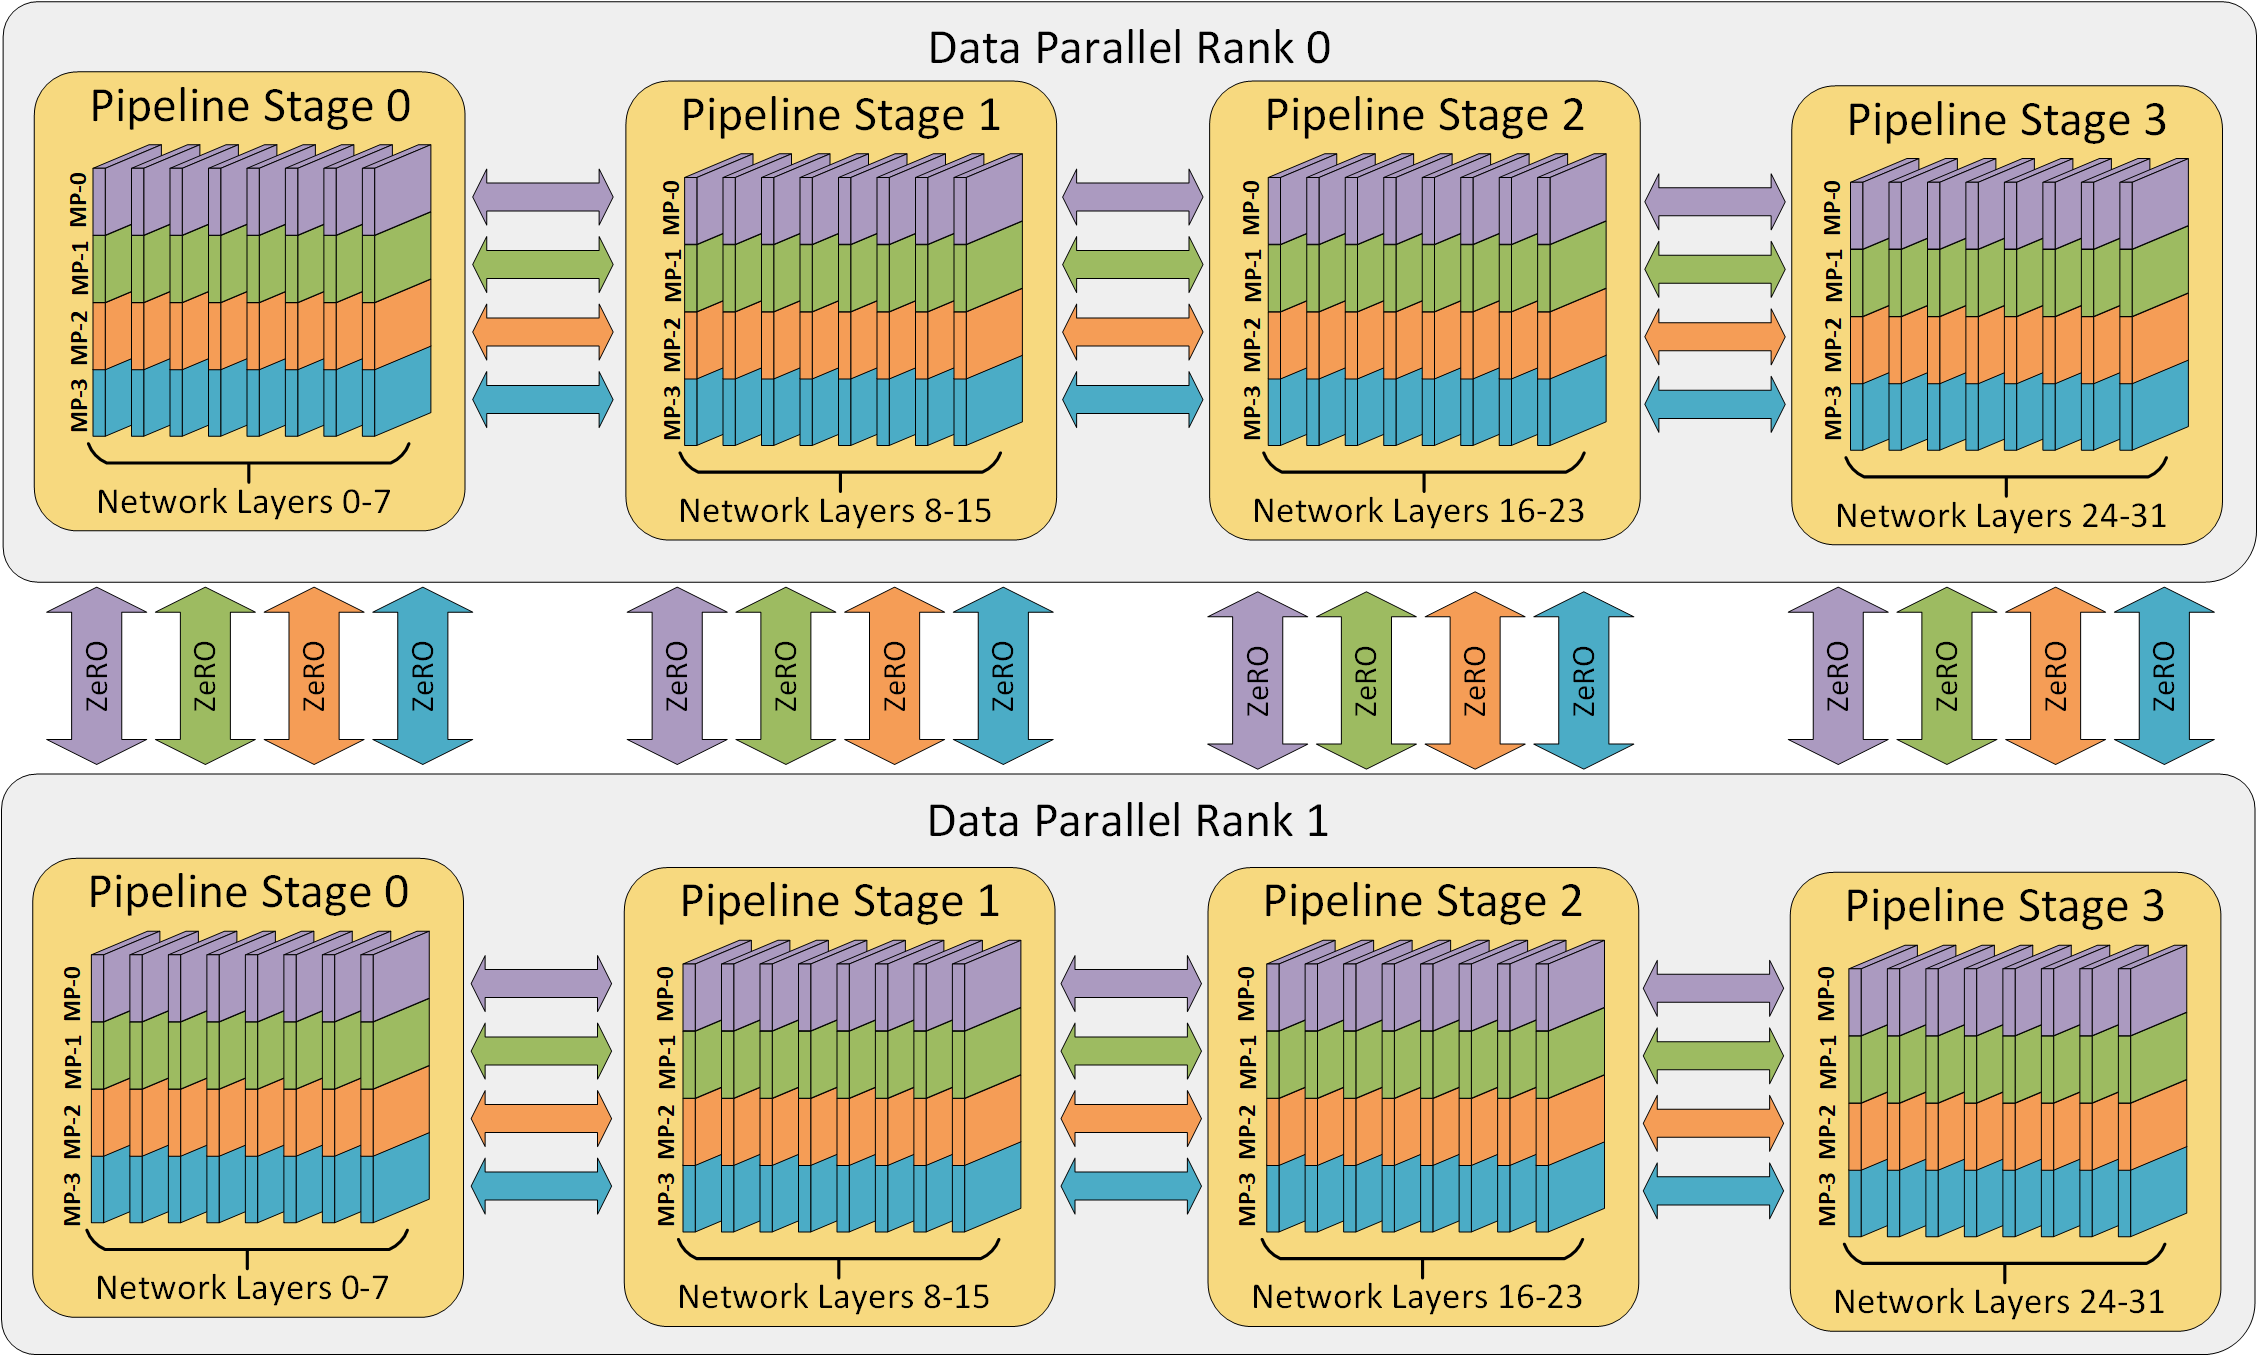
Pipeline Parallelism - DeepSpeed
A walkthrough to tune LLMs with Ray Clusters in the on-premise K8S ...
LLM_log #001: Understanding Large Language Models: From Word Counting ...
A Hacker's Guide to LLMs · Ibrahim Sowunmi
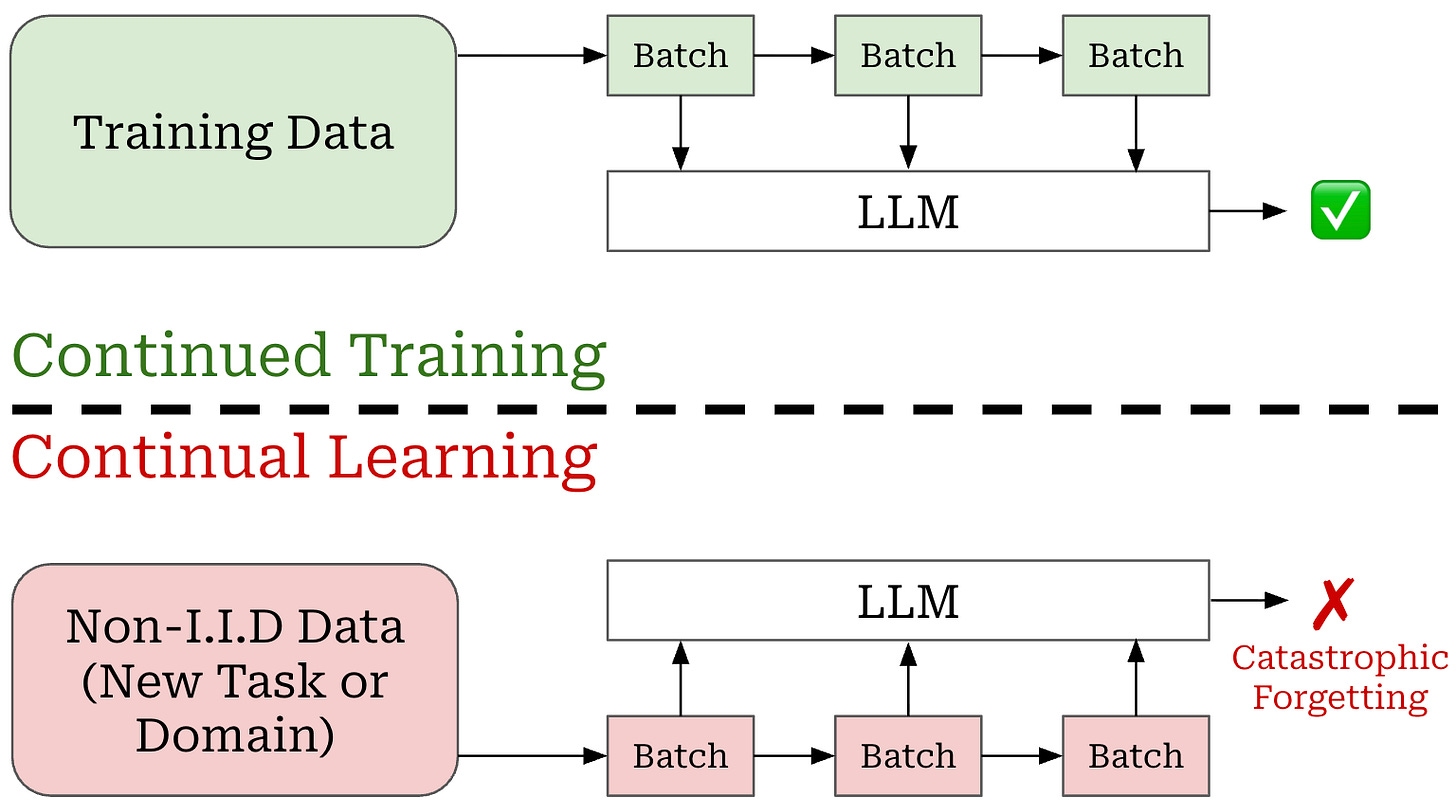
Continual Learning with RL for LLMs
Introduction to Model Parallelism - Amazon SageMaker AI
Anyscale
分布式训练
Transformer-Based Resource and Stage-Aware Scheduling for Model ...
现代LLM基本技术整理_llama prefill-CSDN博客
LLMをゼロから事前学習する | speed1313 Blog
(PDF) CBA: Communication-Bound-Aware Cross-Domain Resource Assignment ...
Maximizing Business Potential with Large Language Models (LLMs)