Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
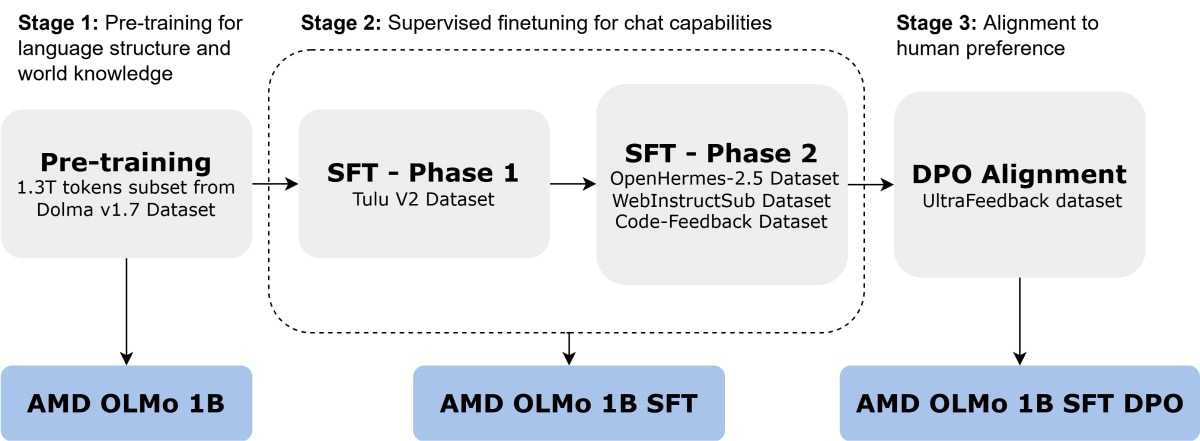
Introducing the First AMD 1B Language Models: AMD OLMo - Edge AI and ...
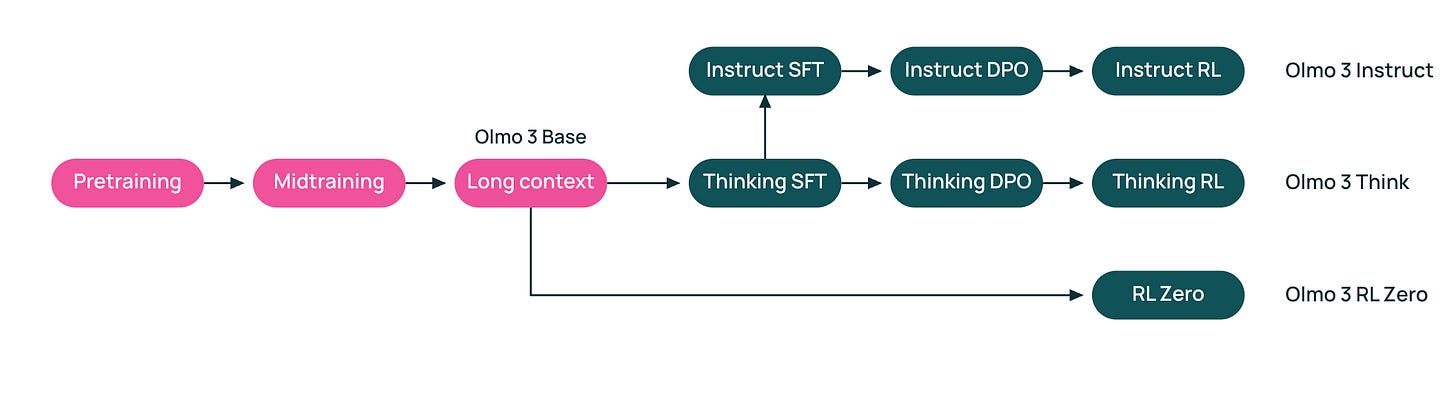
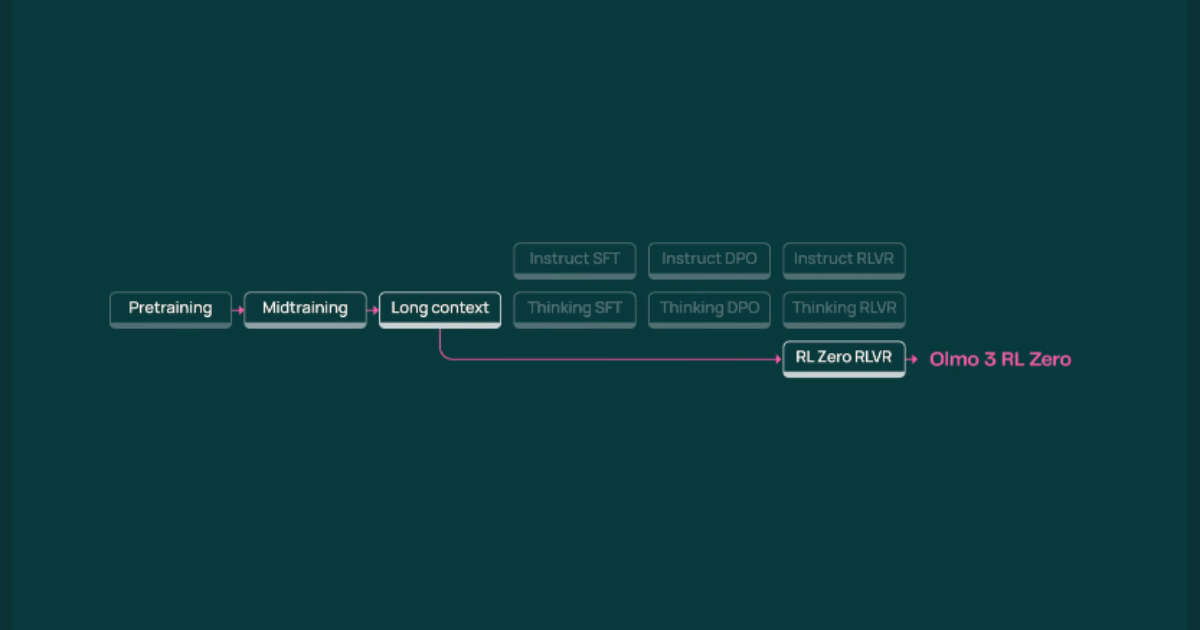
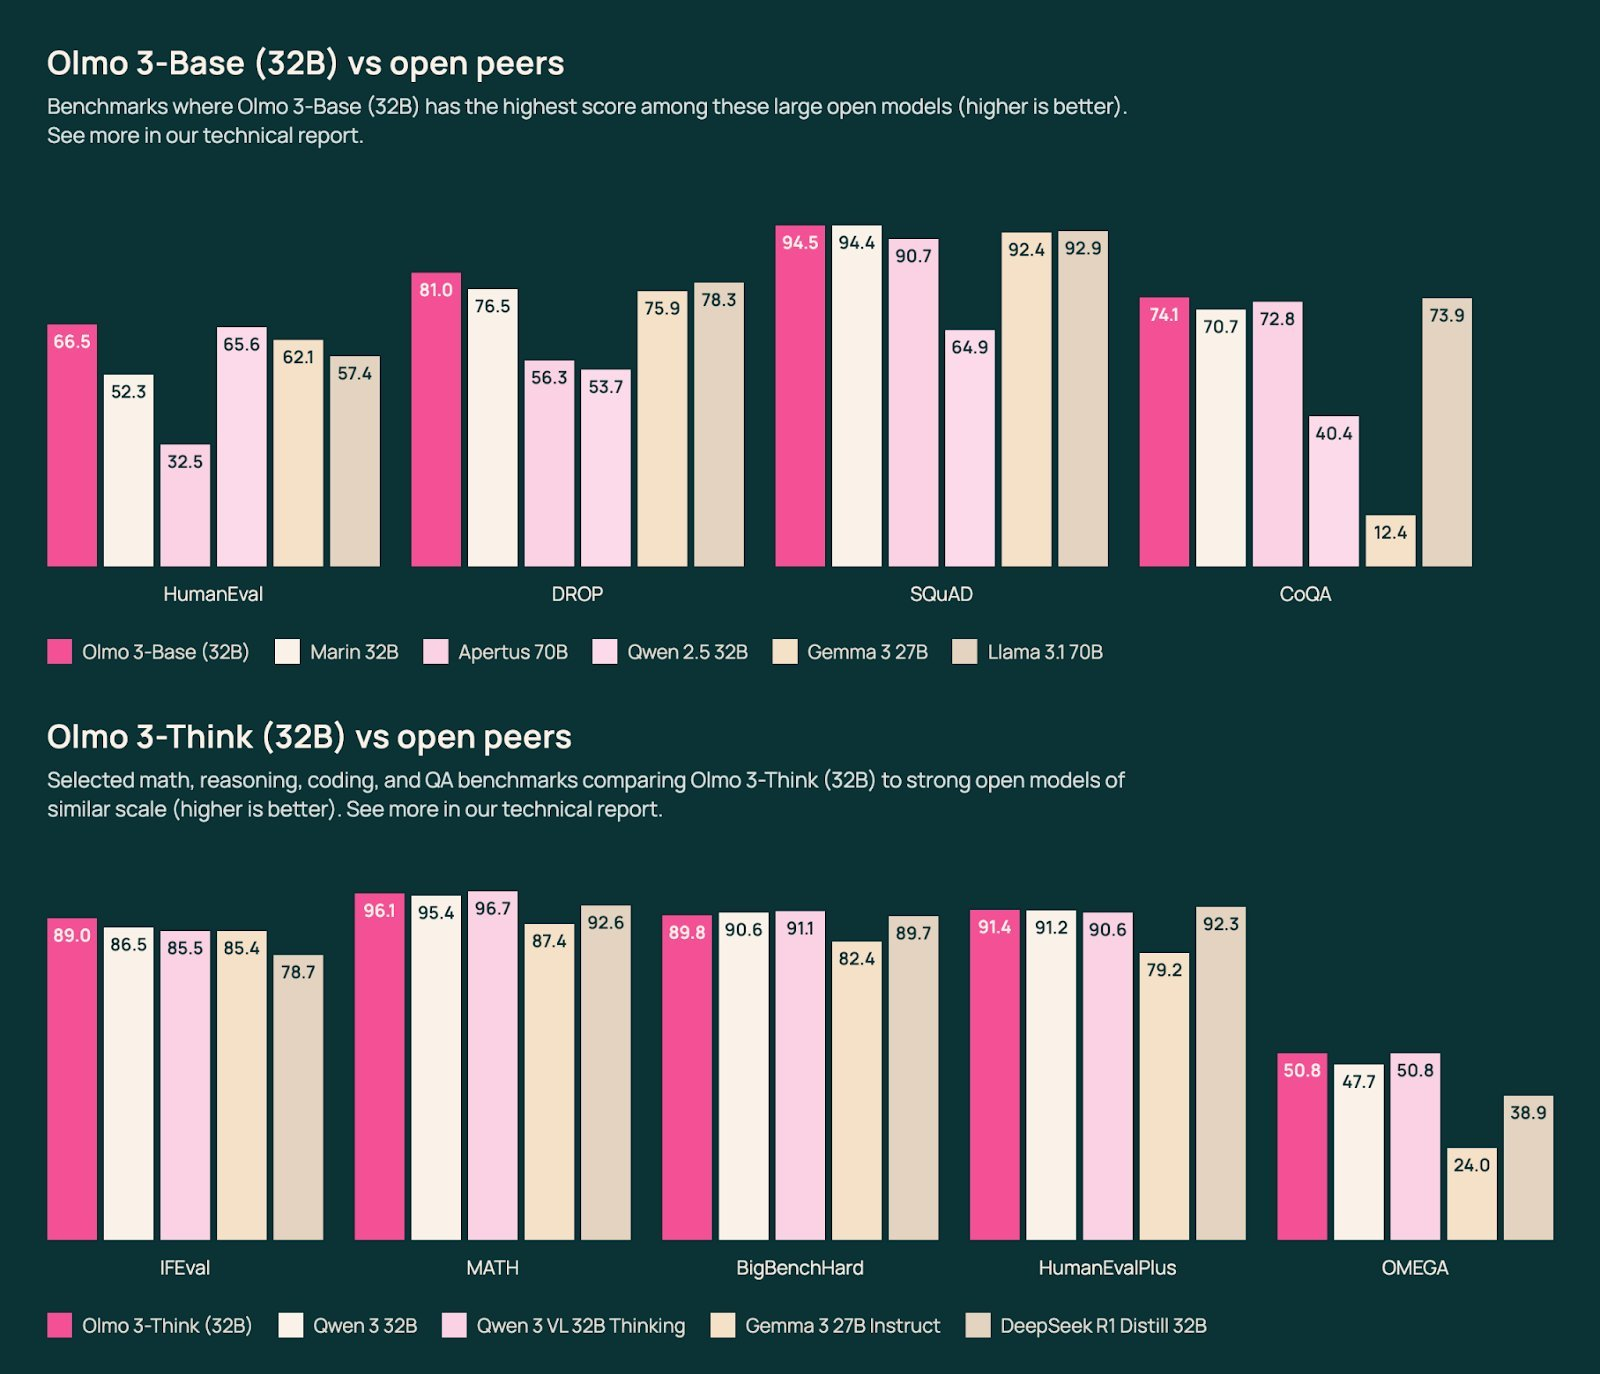
Olmo 3 and the Open LLM Renaissance
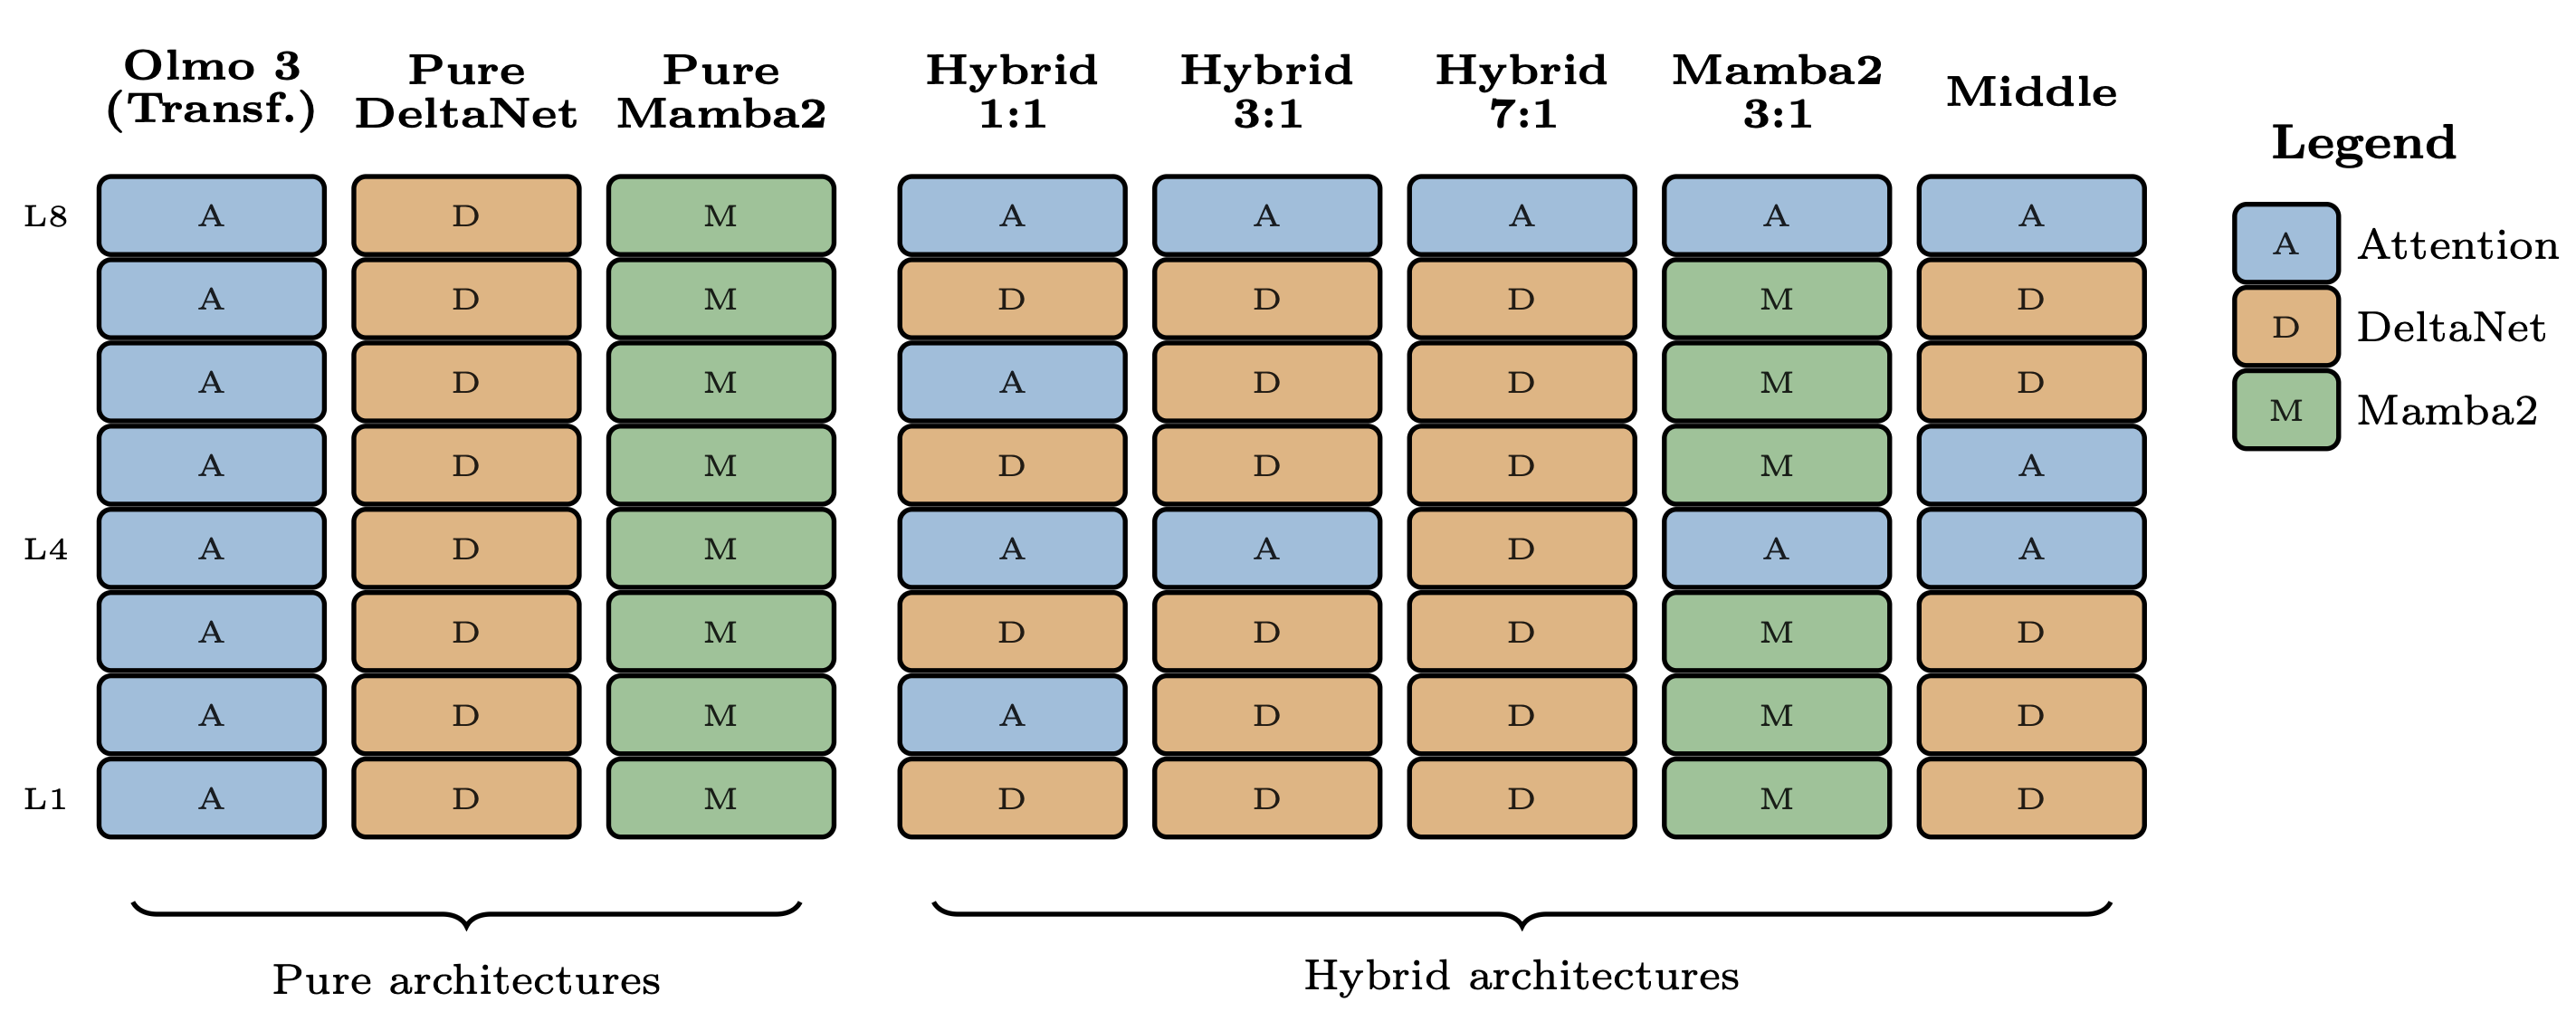
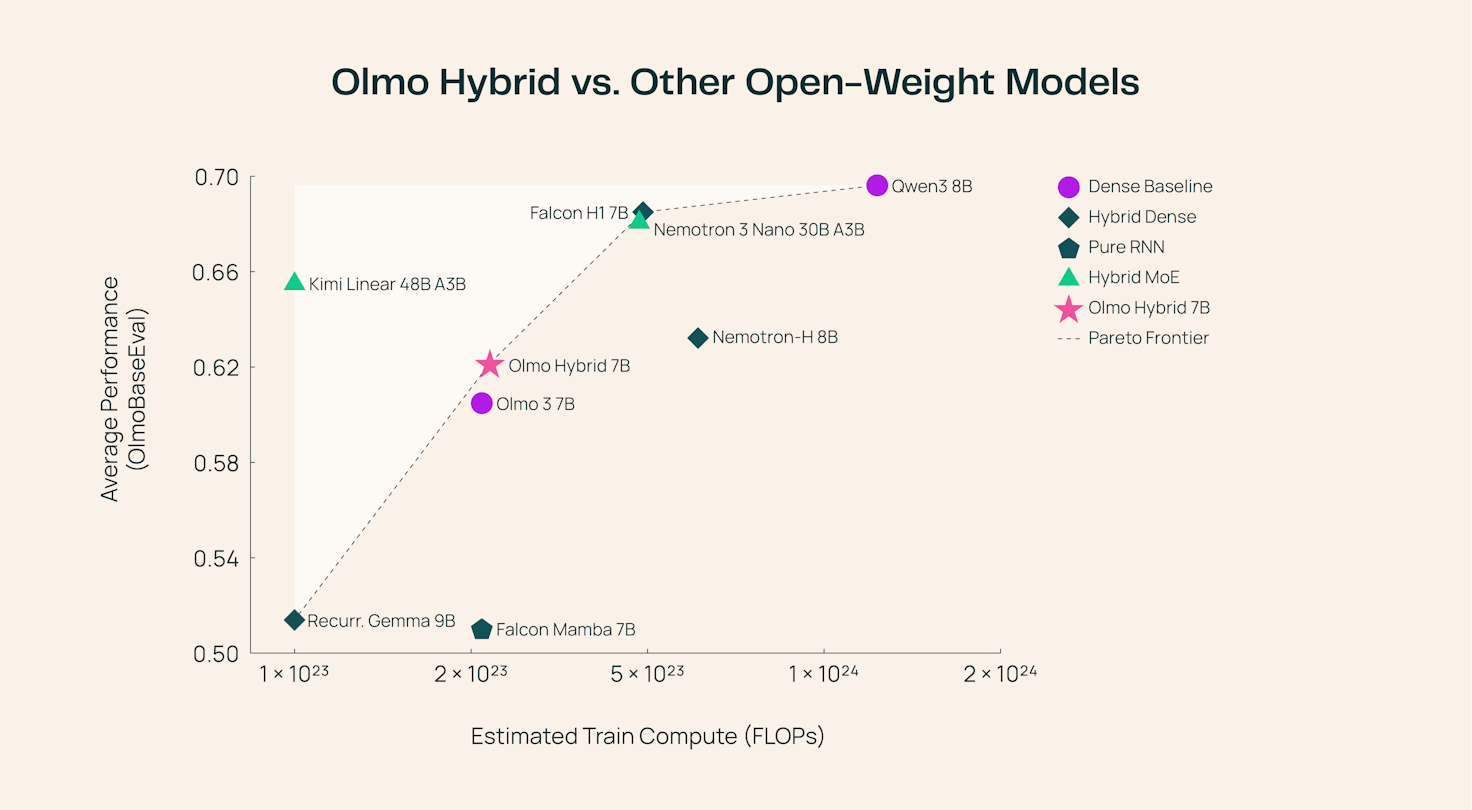
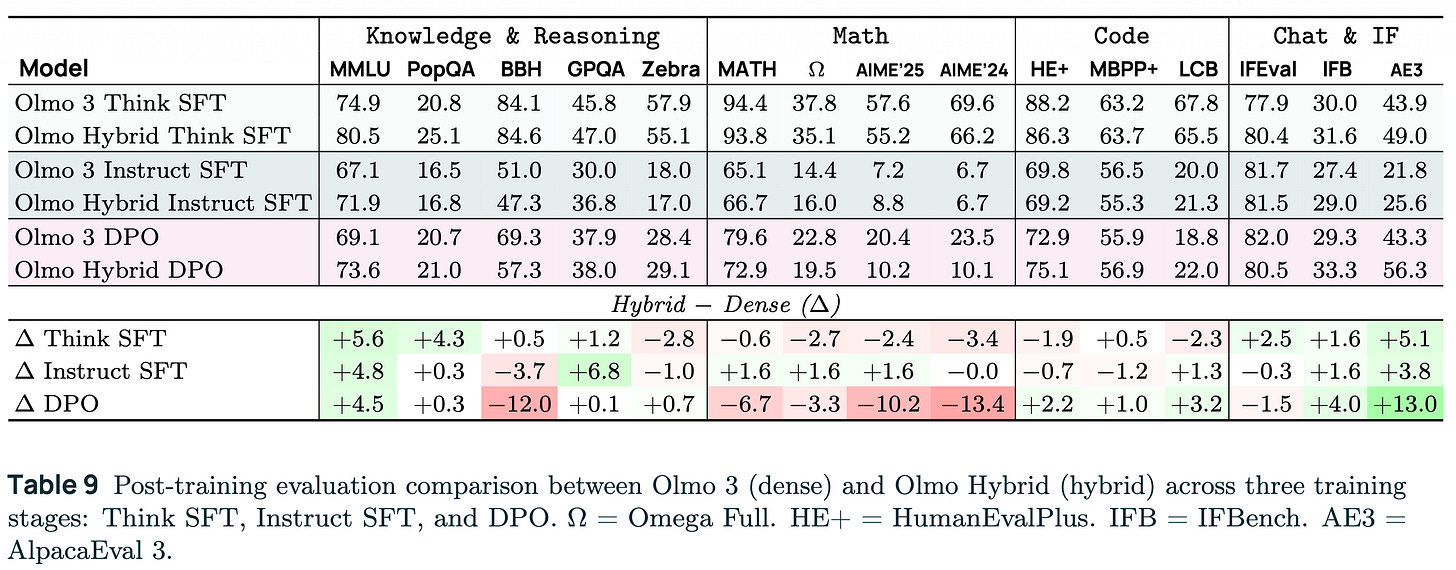
Olmo Hybrid and future LLM architectures
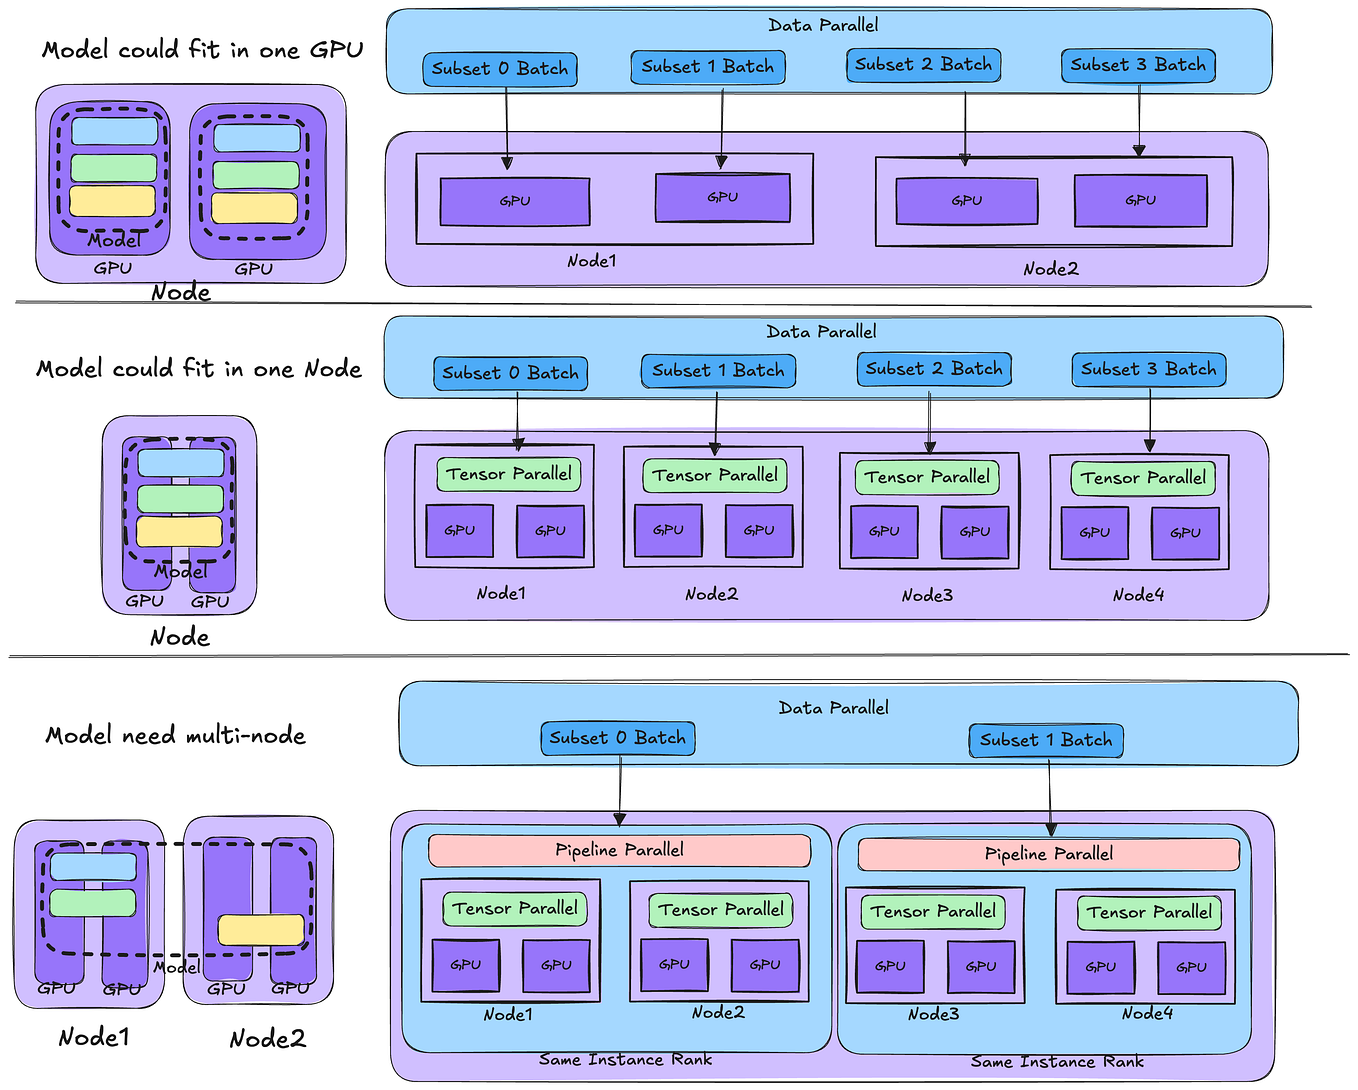
Simple explanation of Distributed Training | by 성연우 | Jan, 2025 | Medium
LLMs 44. Distributed Training of Large Language Models (LLMs) | PracHub ...
What Is Olmo 3? A Deep Dive into the Fully Open-Source LLM | MDP Group
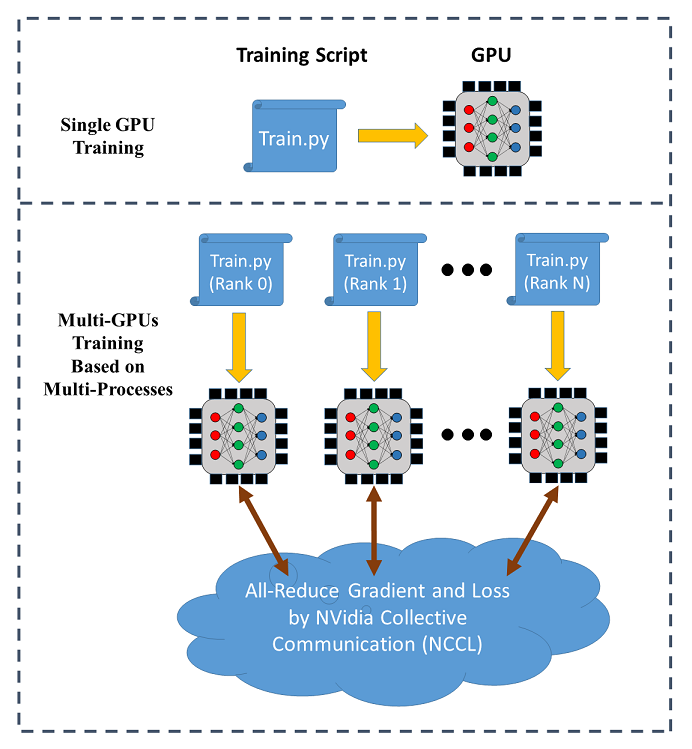
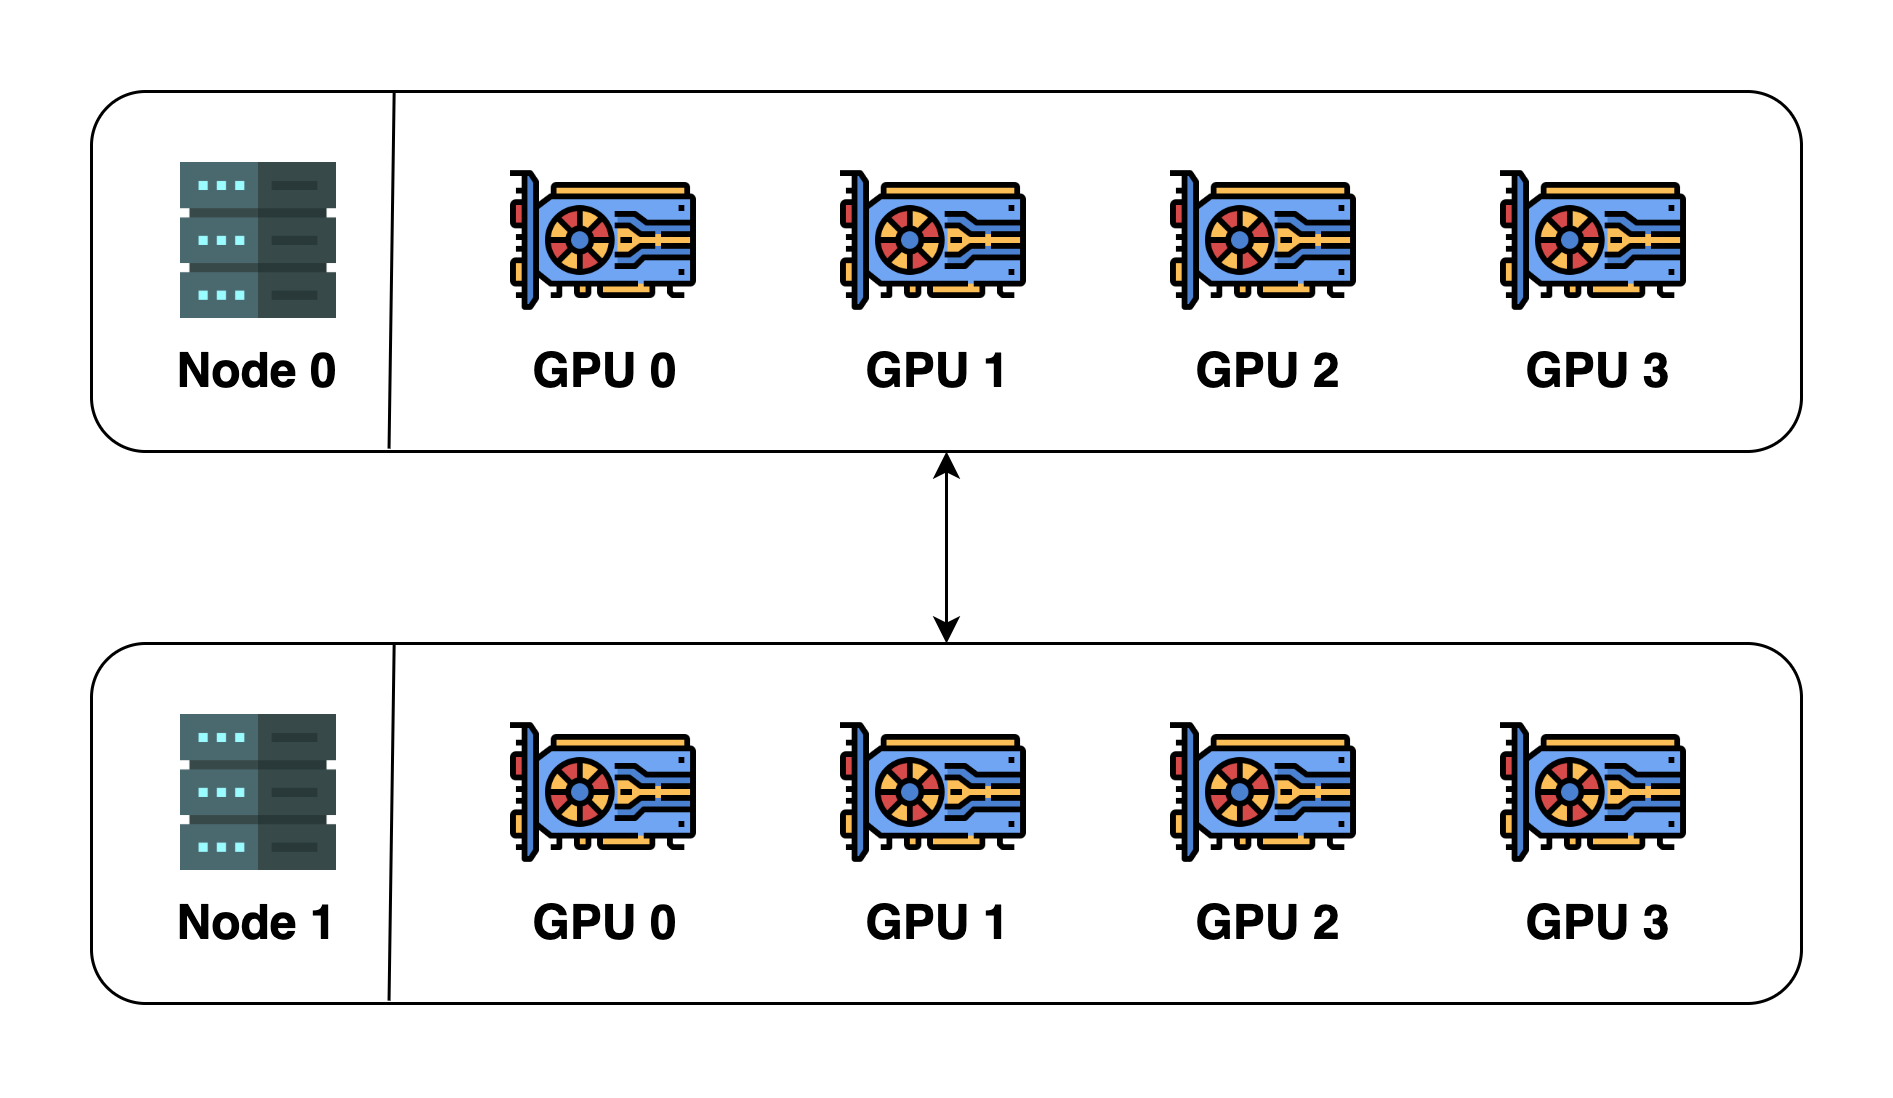
Accelerating AI: Implementing Multi-GPU Distributed Training for ...
Introducing Olmo Hybrid: Combining transformers and linear RNNs for ...
Distributed Training: How to train Large Language Models (LLM ...
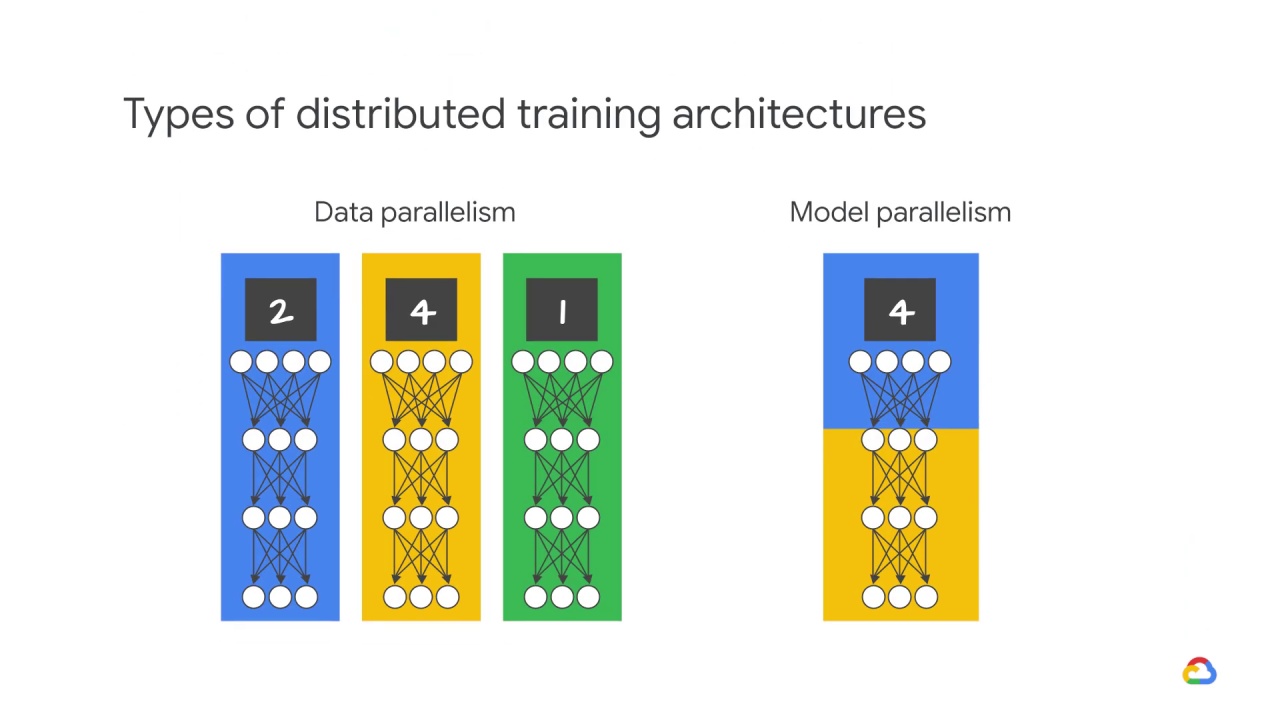
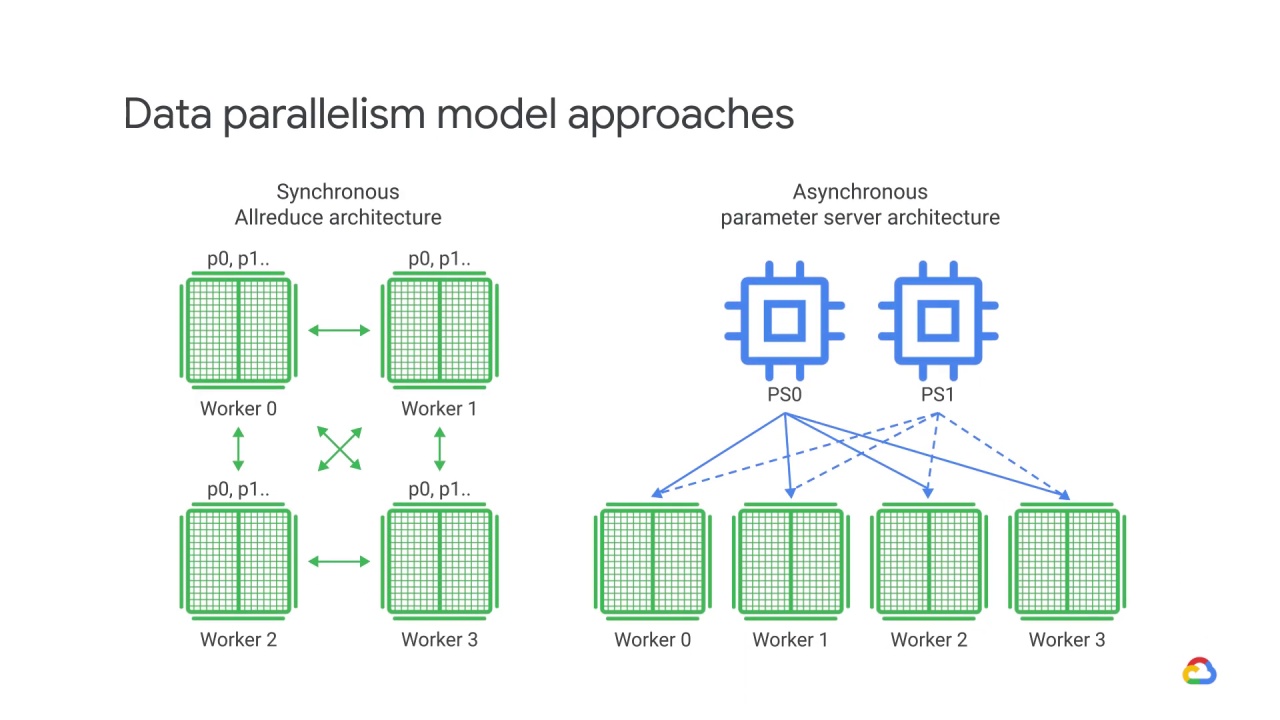
Distributed training architectures — Eduardo Avelar
What Is Distributed Training?
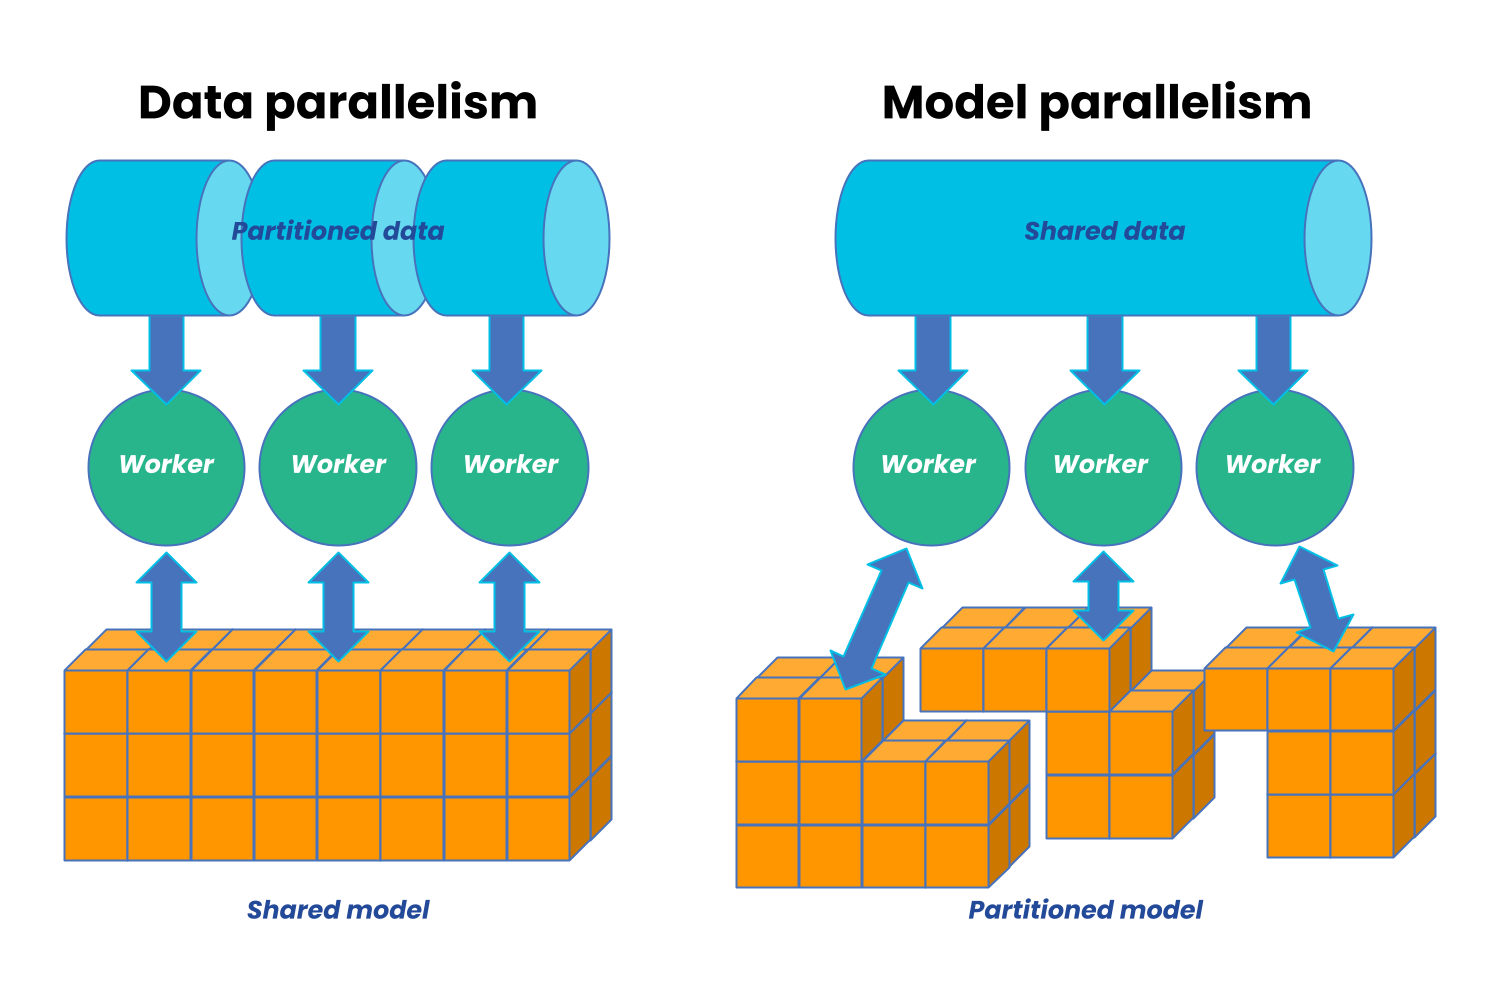
Distributed Deep Learning training: Model and Data Parallelism in ...
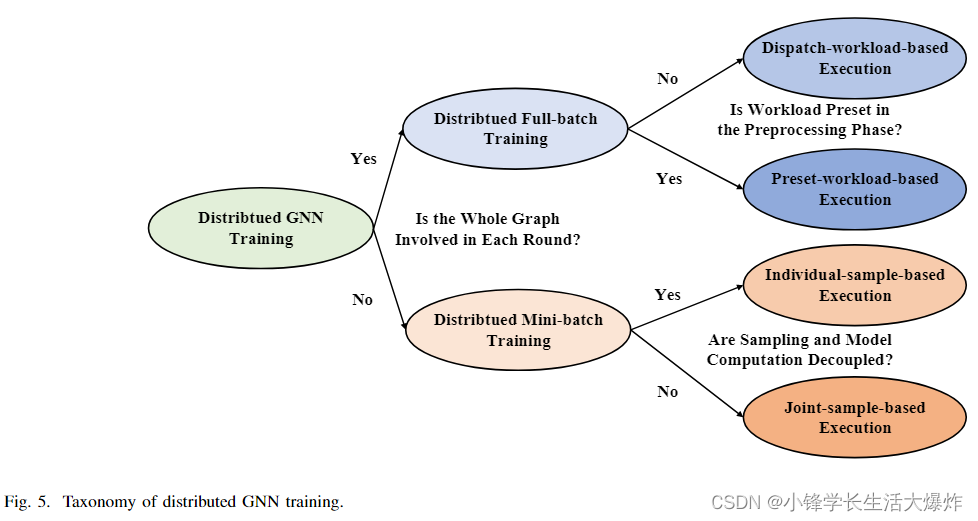
【阅读】A Comprehensive Survey on Distributed Training of Graph Neural ...
Distributed Training · Apache SINGA
Distributed Training Process. | Download Scientific Diagram
Olmo 3: America’s truly open reasoning models
Distributed training environment. | Download Scientific Diagram
Olmo 3 Release Provides Full Transparency into Model Development and ...
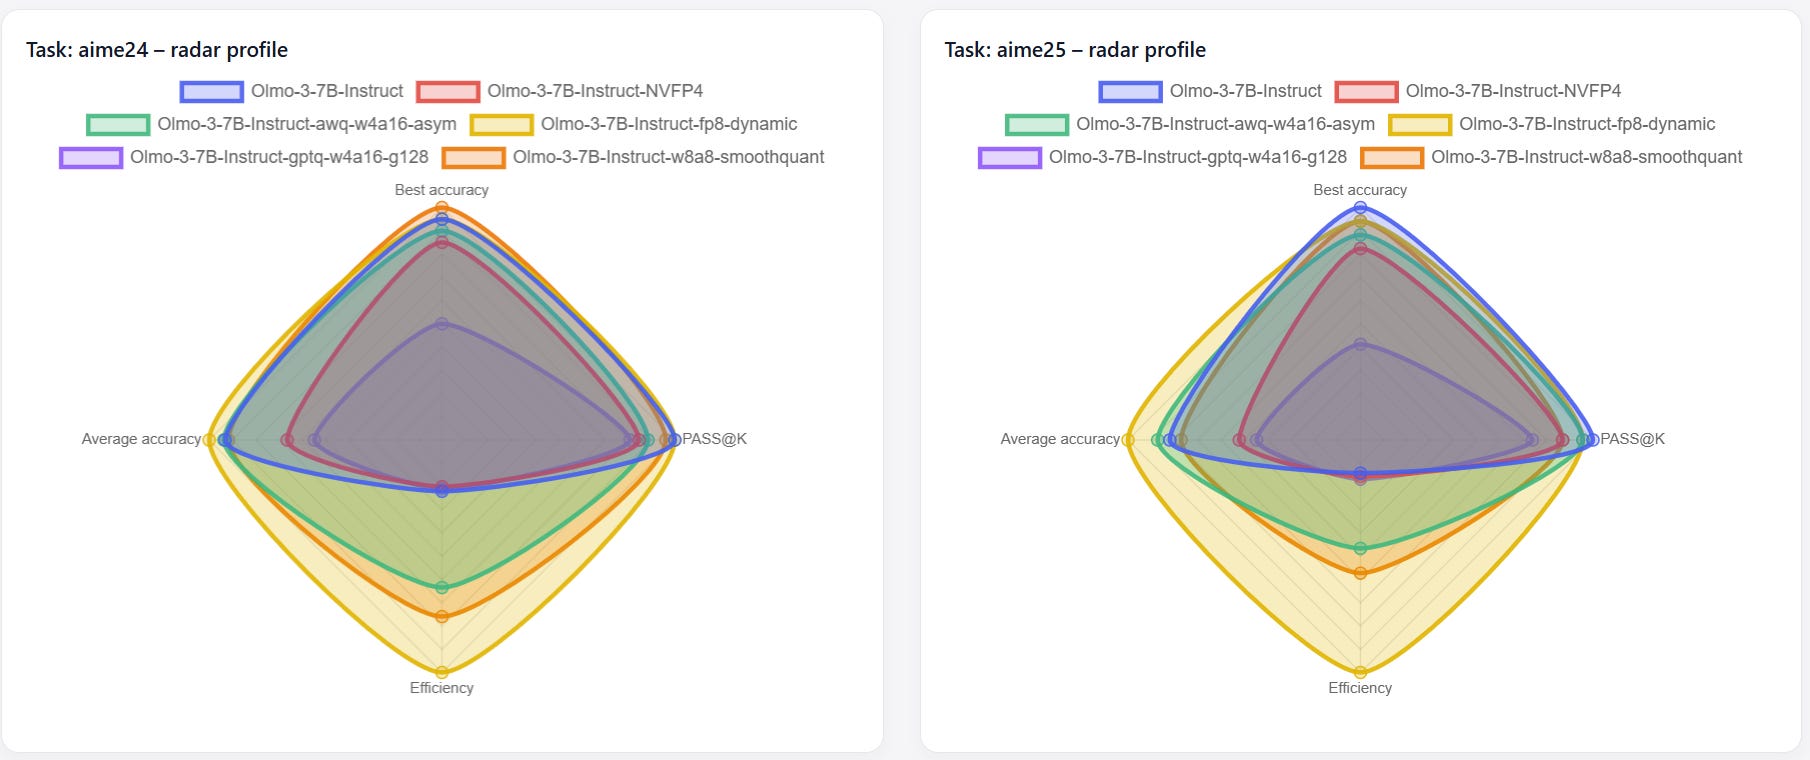
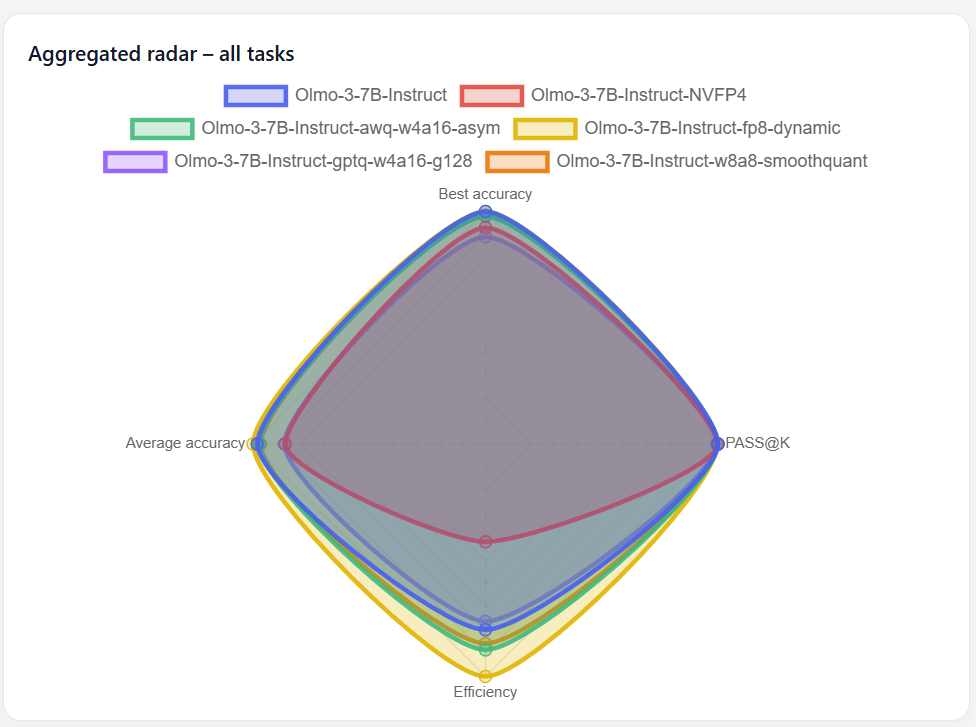
Quantizing Olmo 3: Most Efficient and Accurate Formats
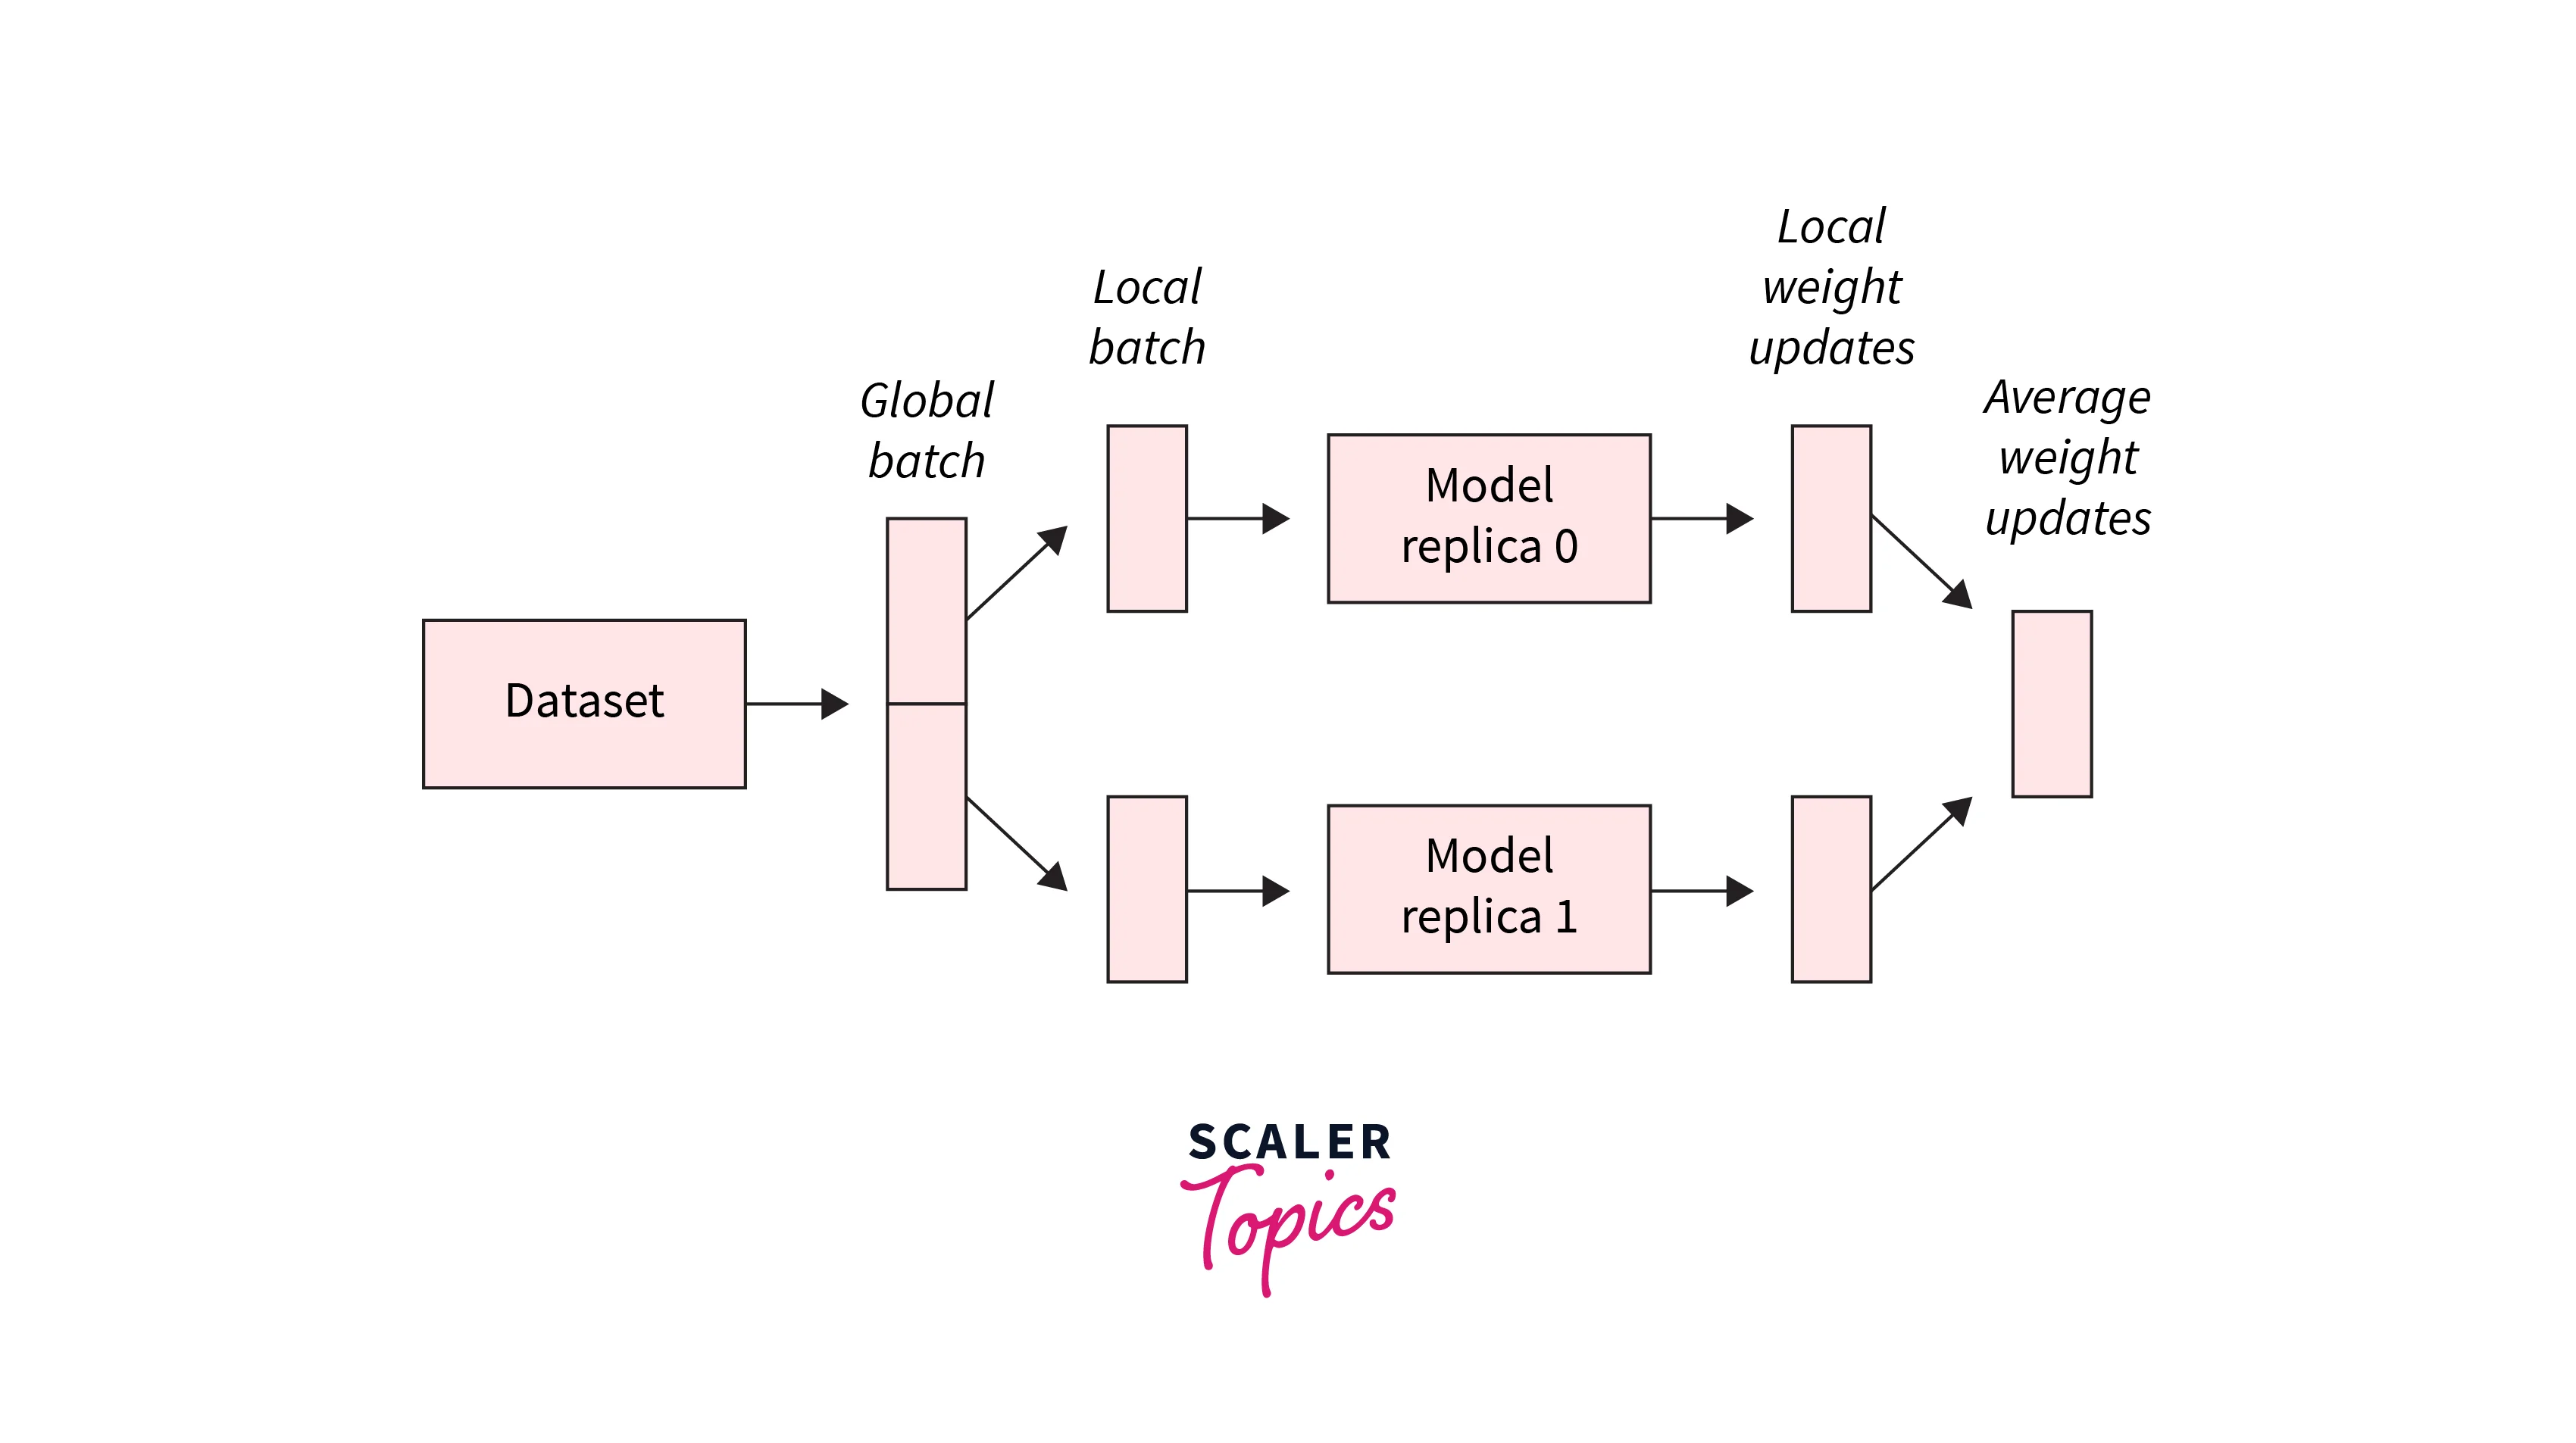
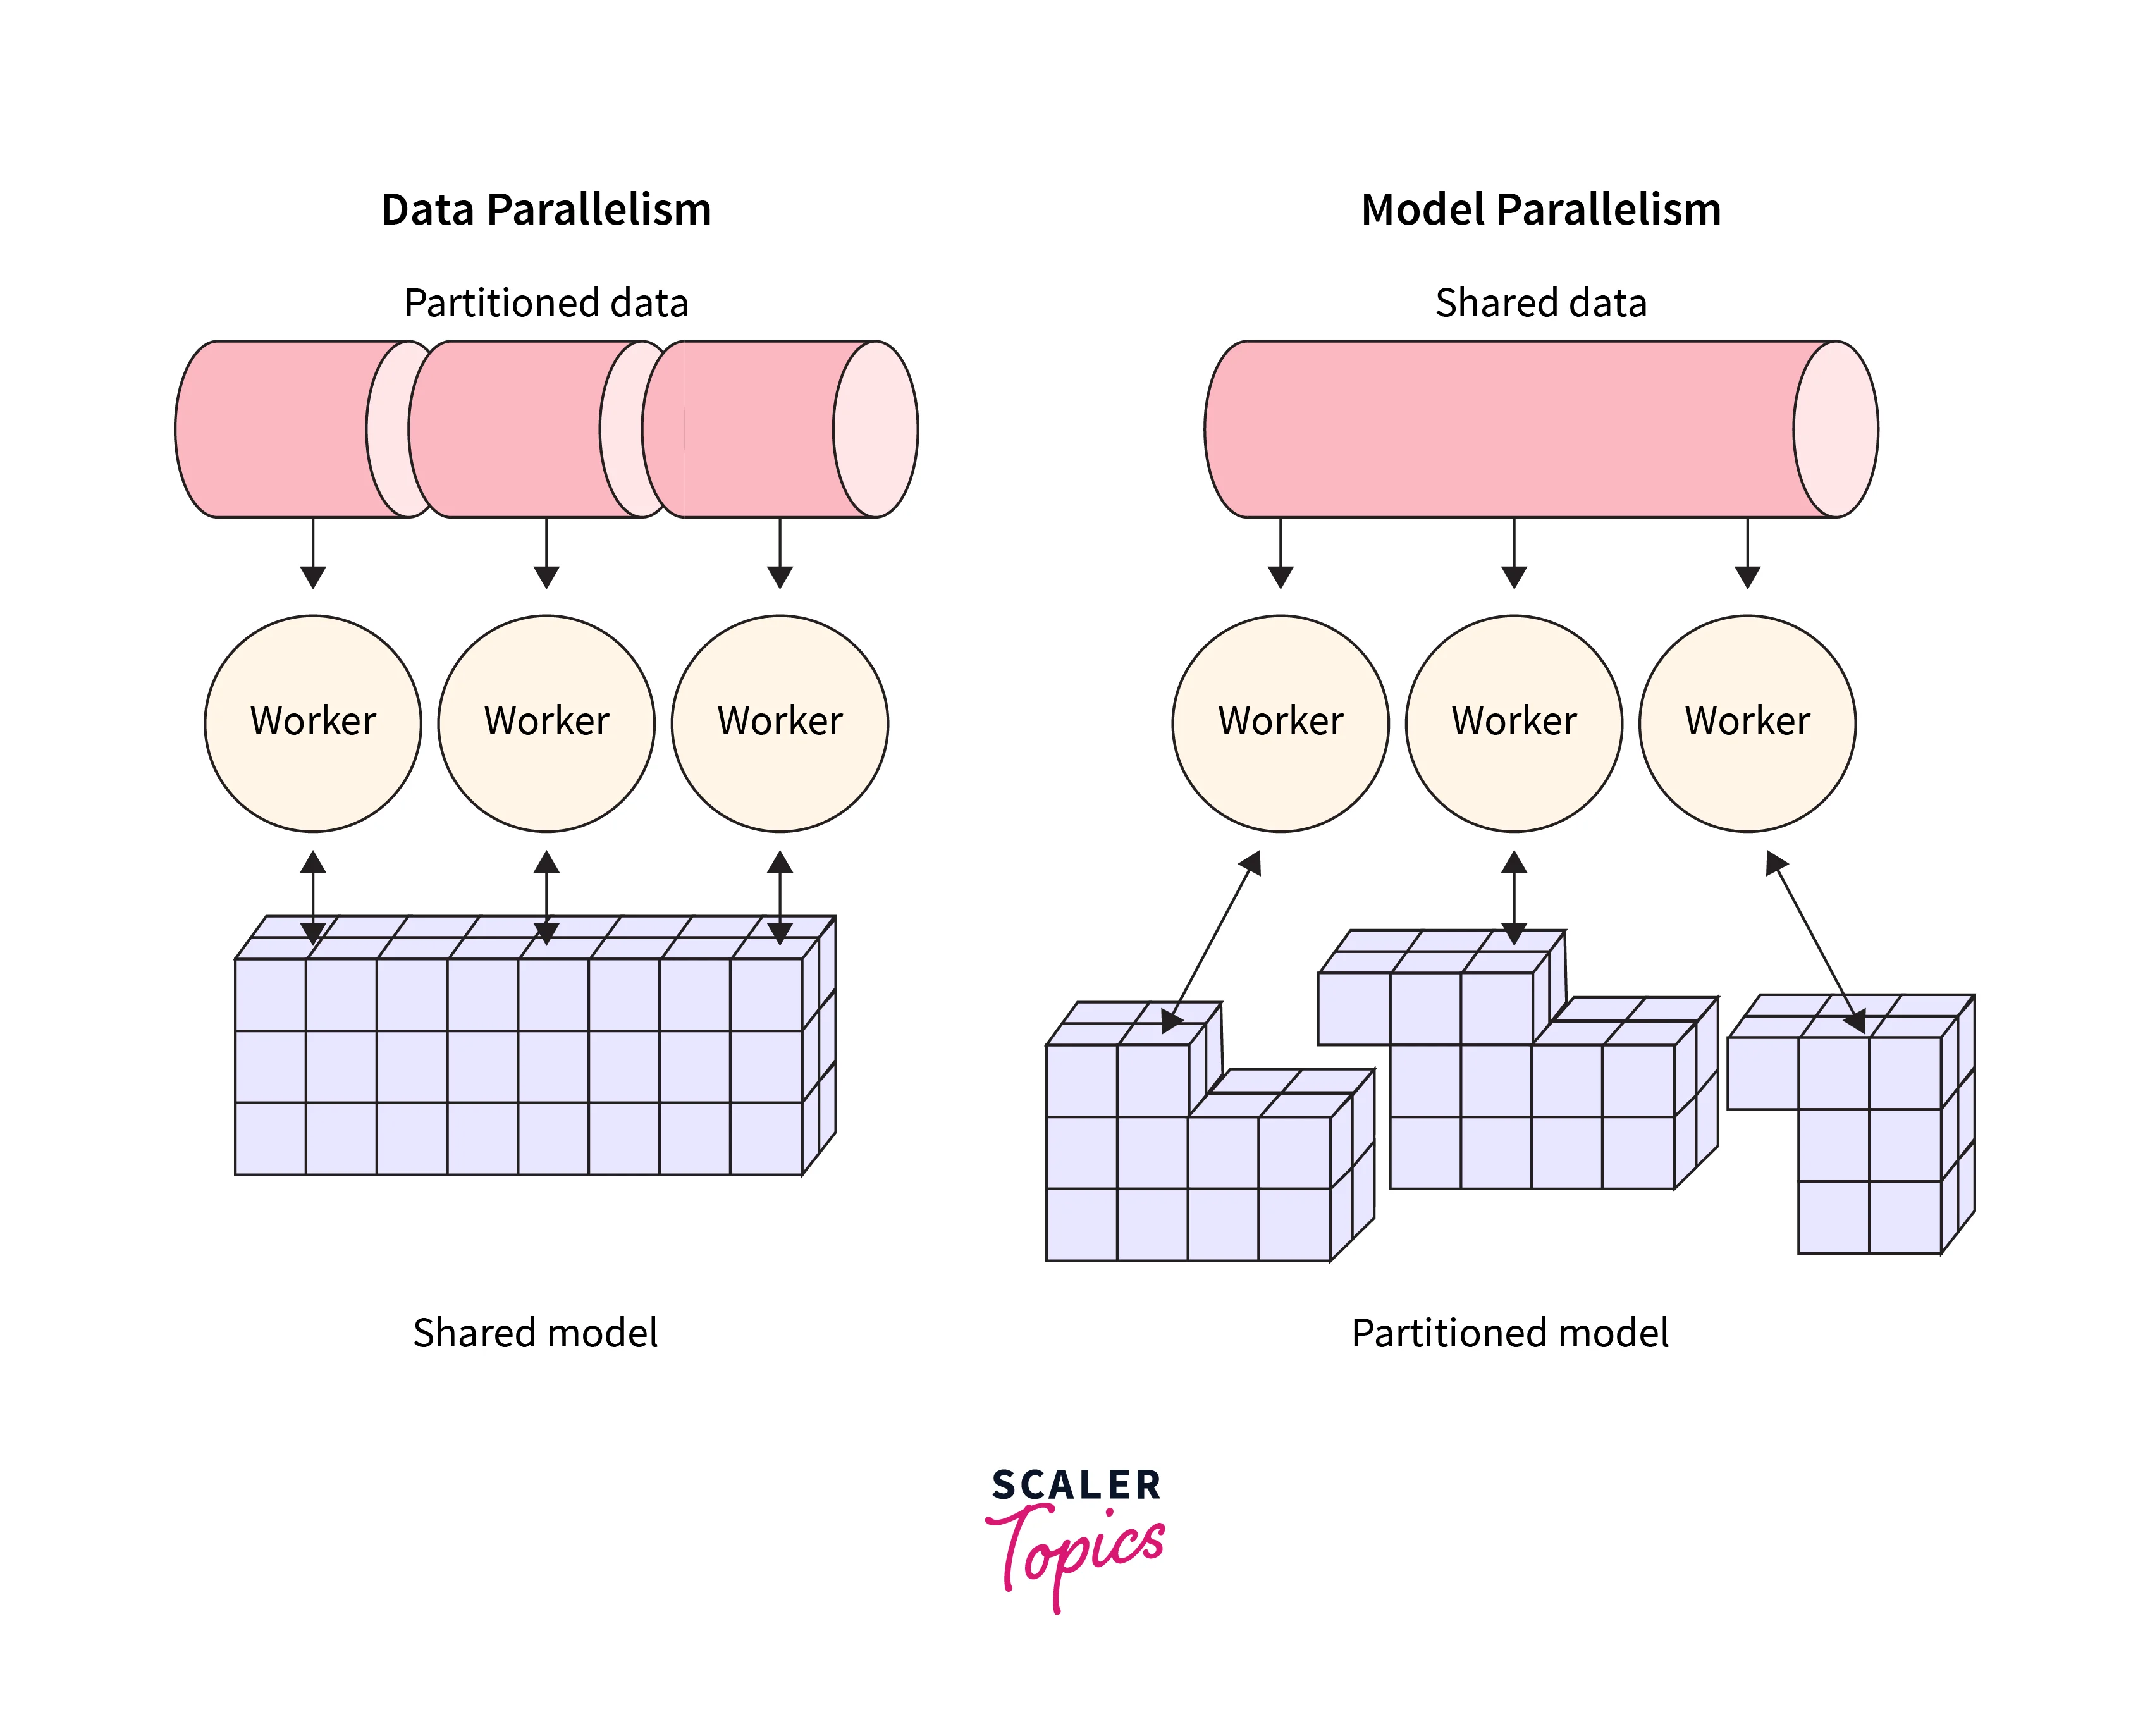
Distributed Training for Standard Training Loops in Keras - Scaler Topics
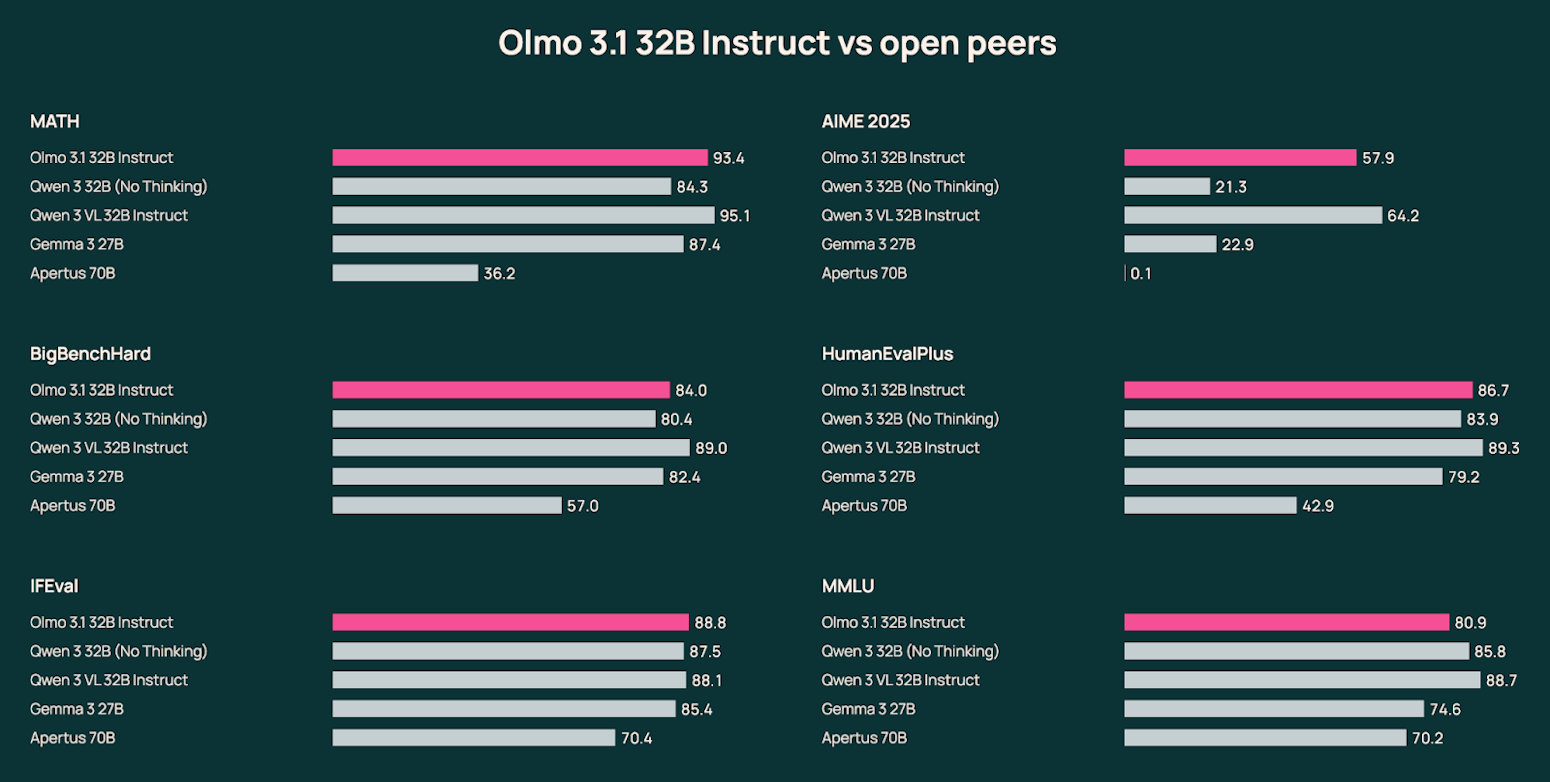
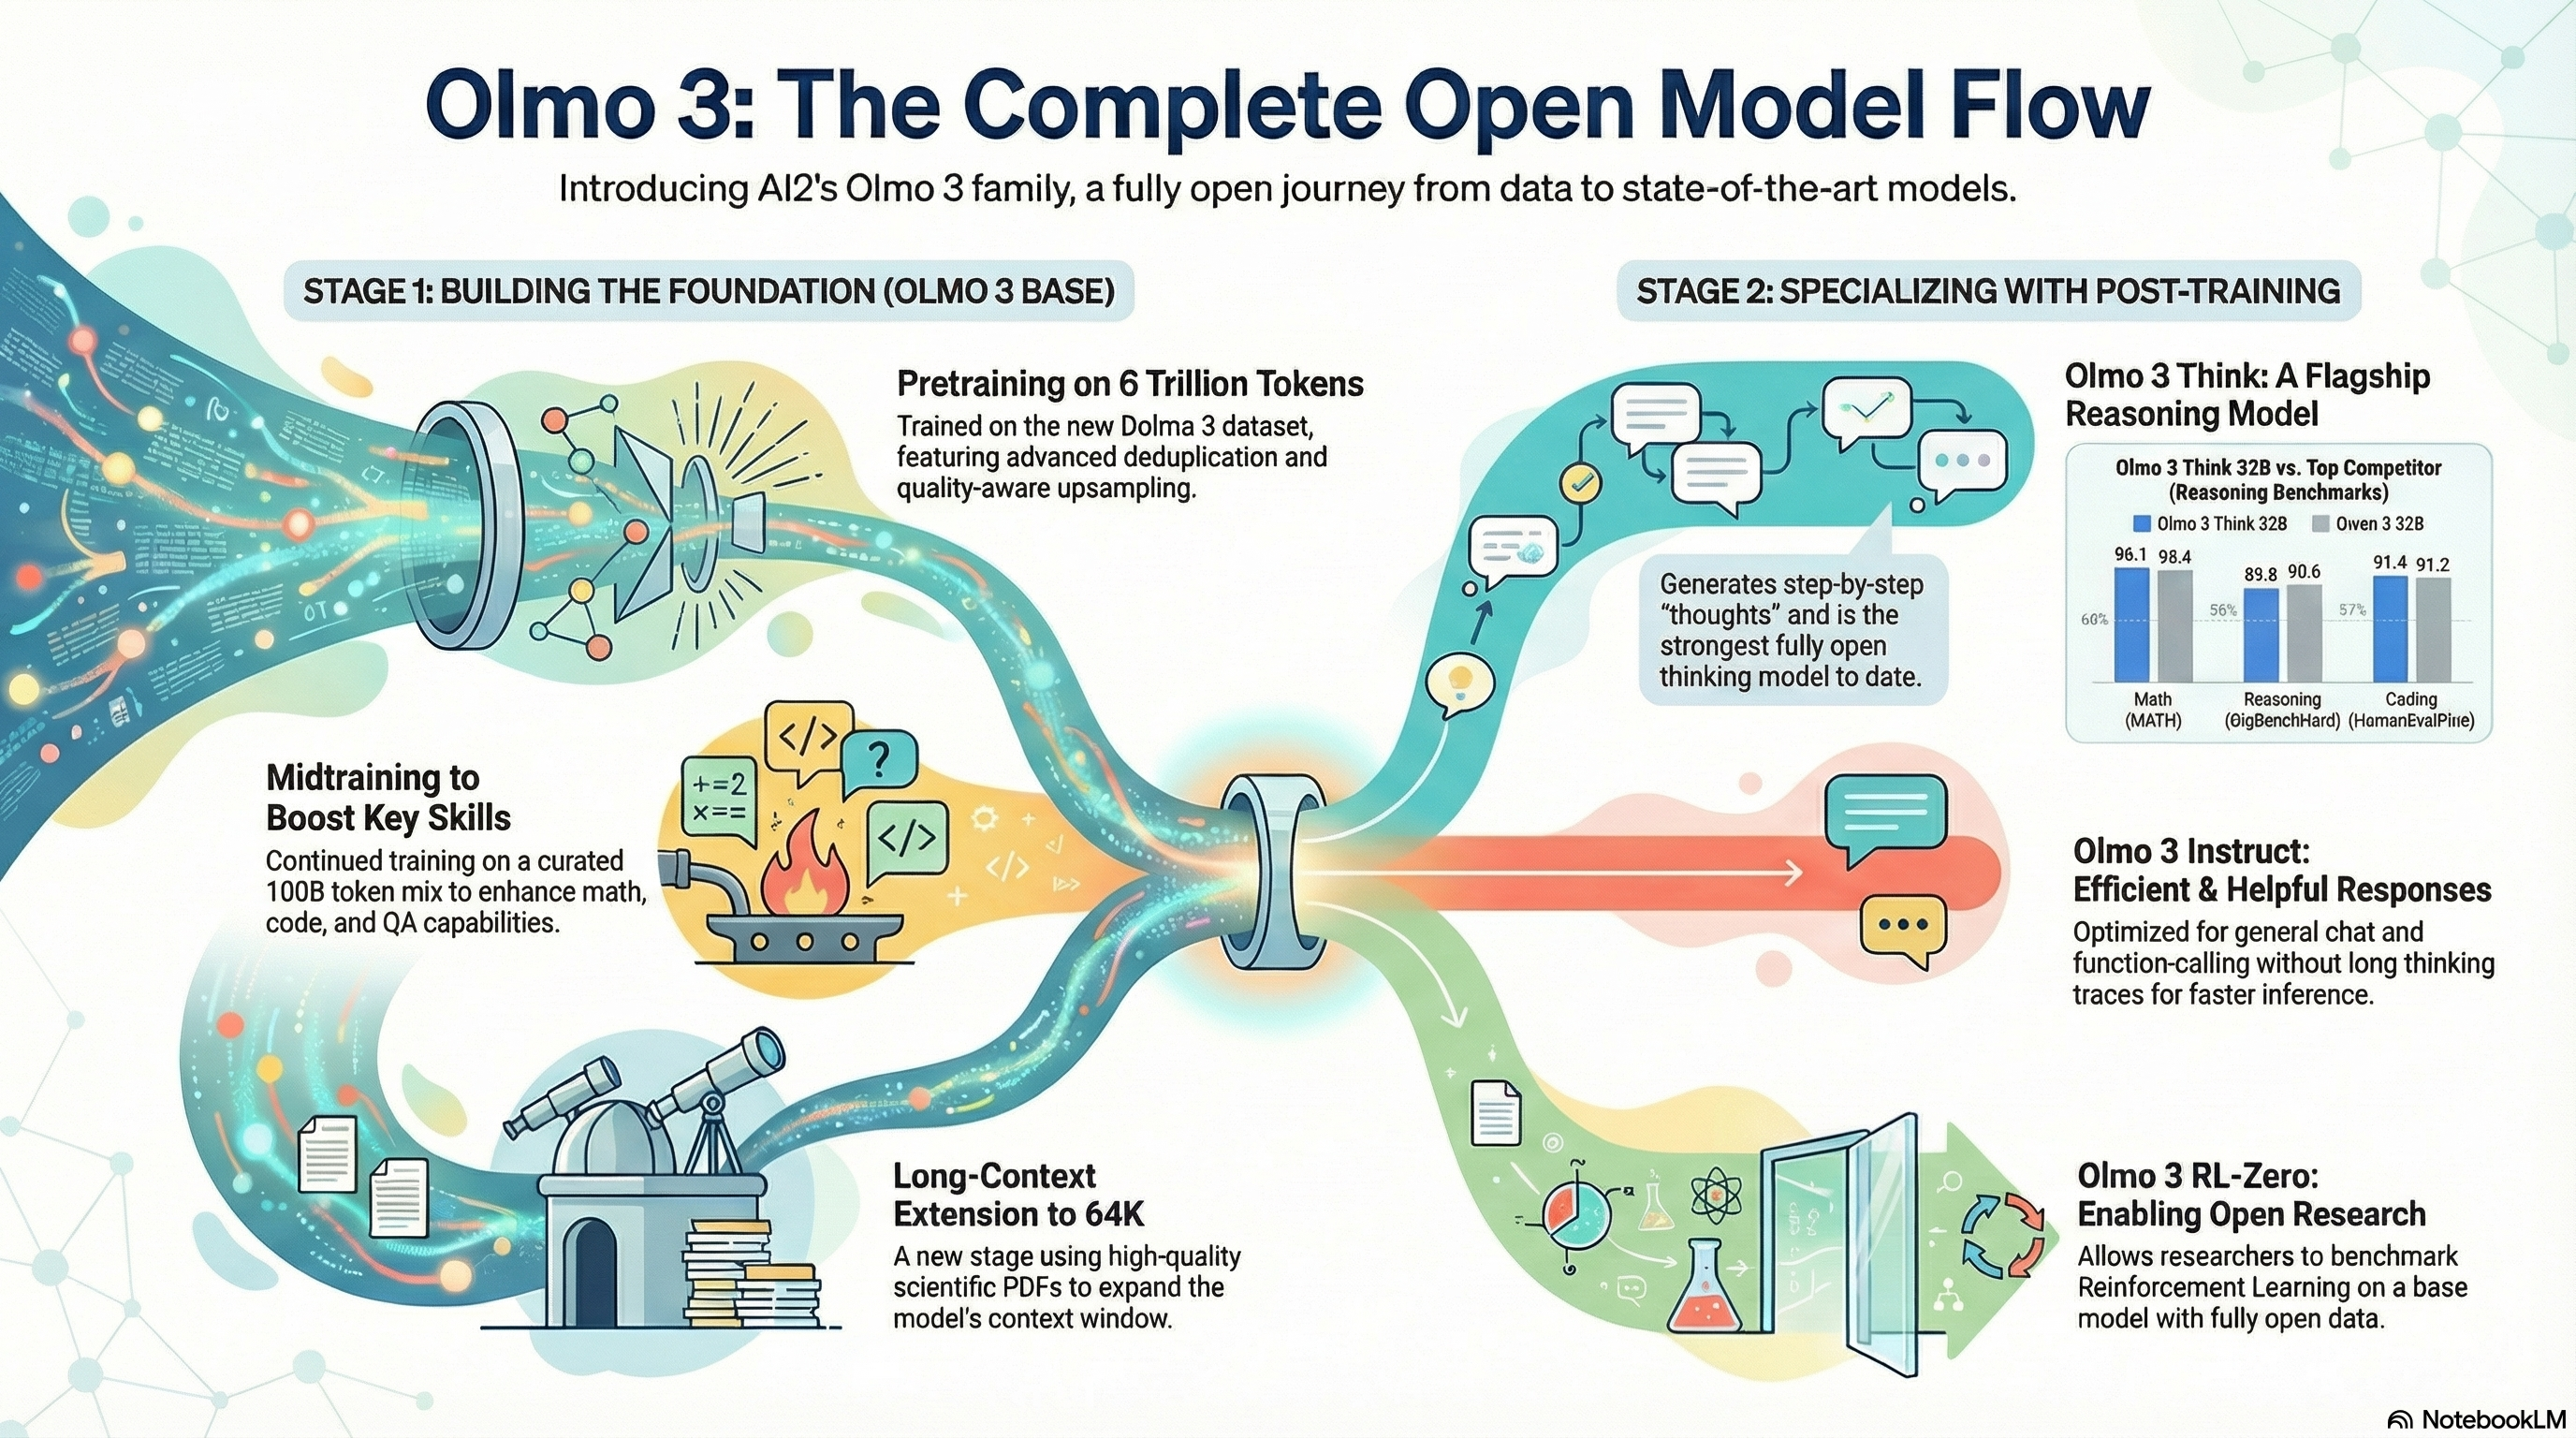
Olmo 3: Charting a path through the model flow to lead open-source AI | Ai2
DeepSeek Engram × OLMo-core: Distributed Implementation
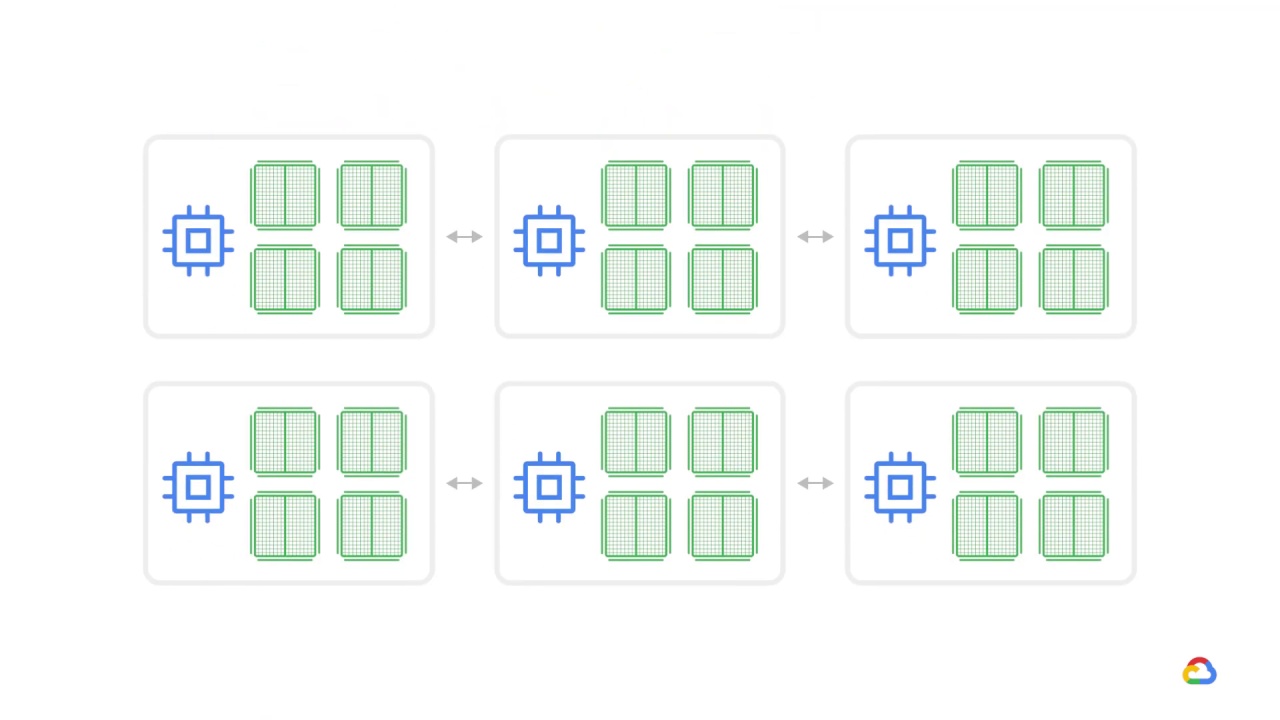
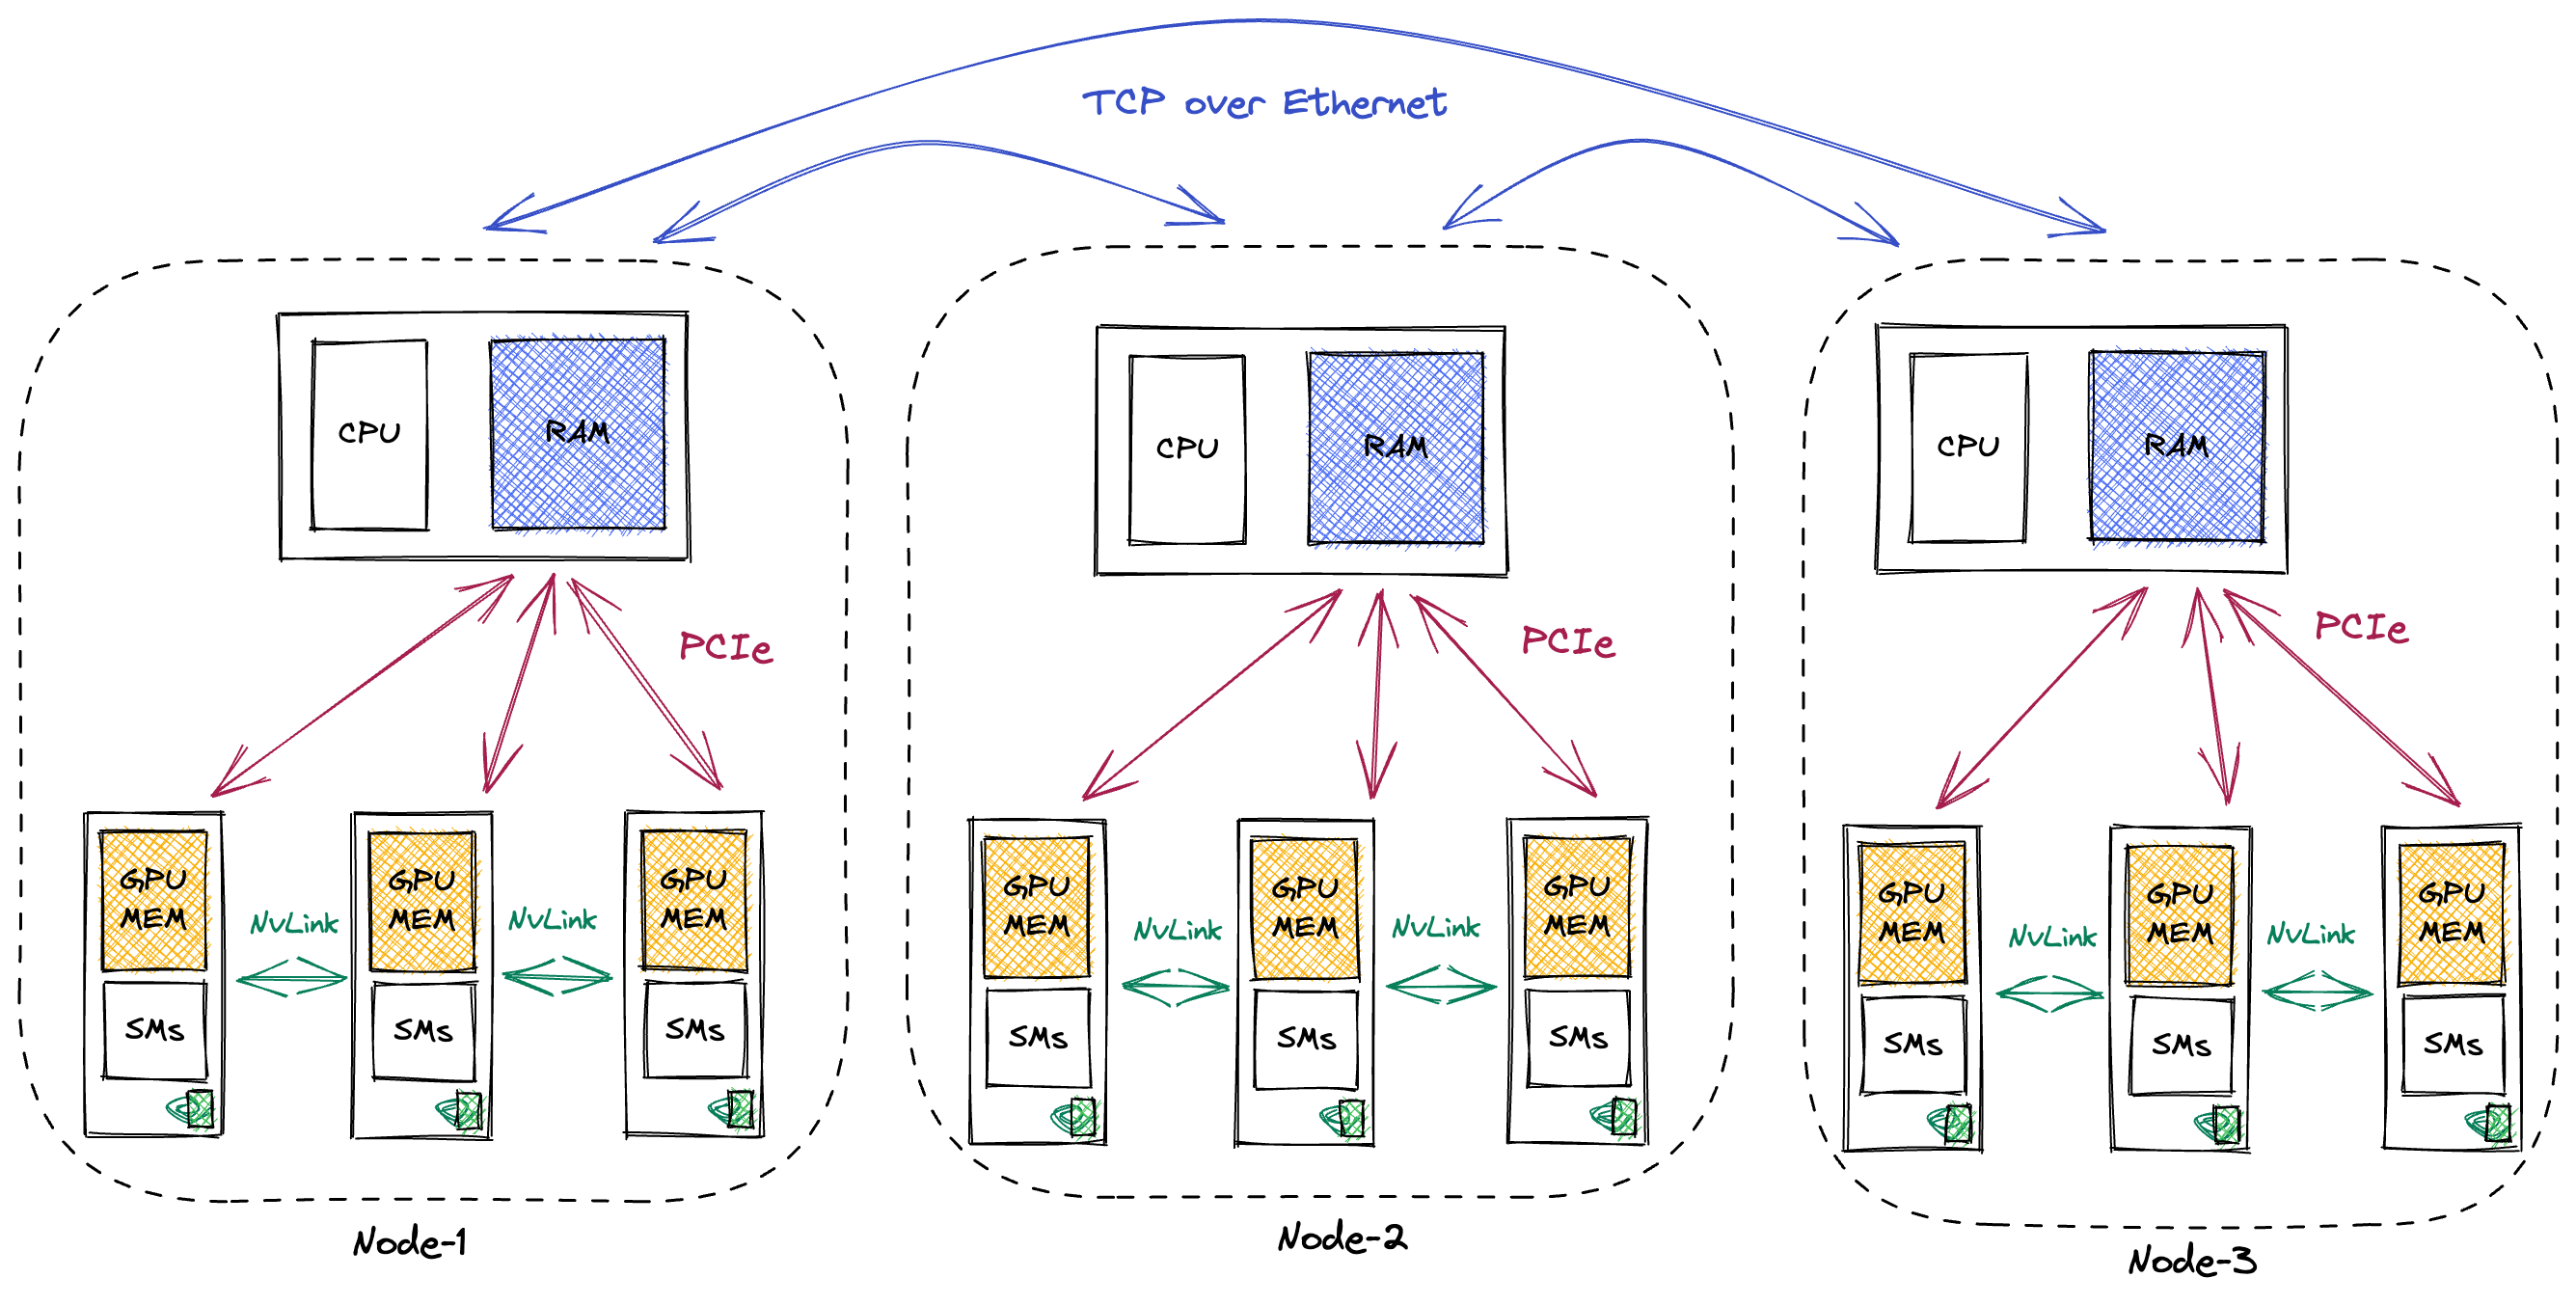
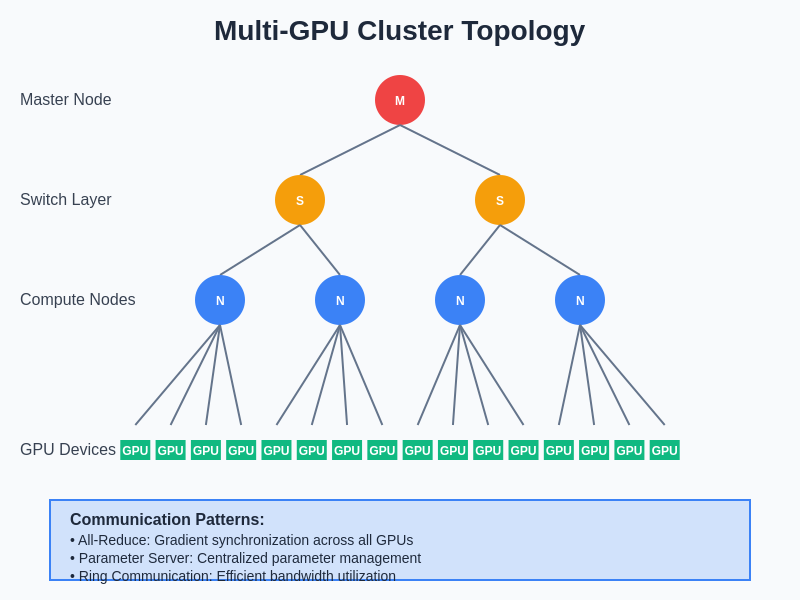
Infra for Distributed Model Training of LLM: Part TWO — Topology Design ...
[논문 리뷰] A Distributed Training Architecture For Combinatorial Optimization
Look who's back! Dani Olmo rejoins the squad in training.🔥💙 ️ #barce ...
Introduction to Distributed Training in Deep Learning - Scaler Topics
Introducing the LLM distributed training simulator | Epoch AI
Pretraining A Large Language Model using Distributed GPUs: A Memory ...
Overview of our distributed training framework. There are two types of ...
最开放的 LLM 模型 OLMo 的模型、训练、 FineTune 与其它 - 知乎
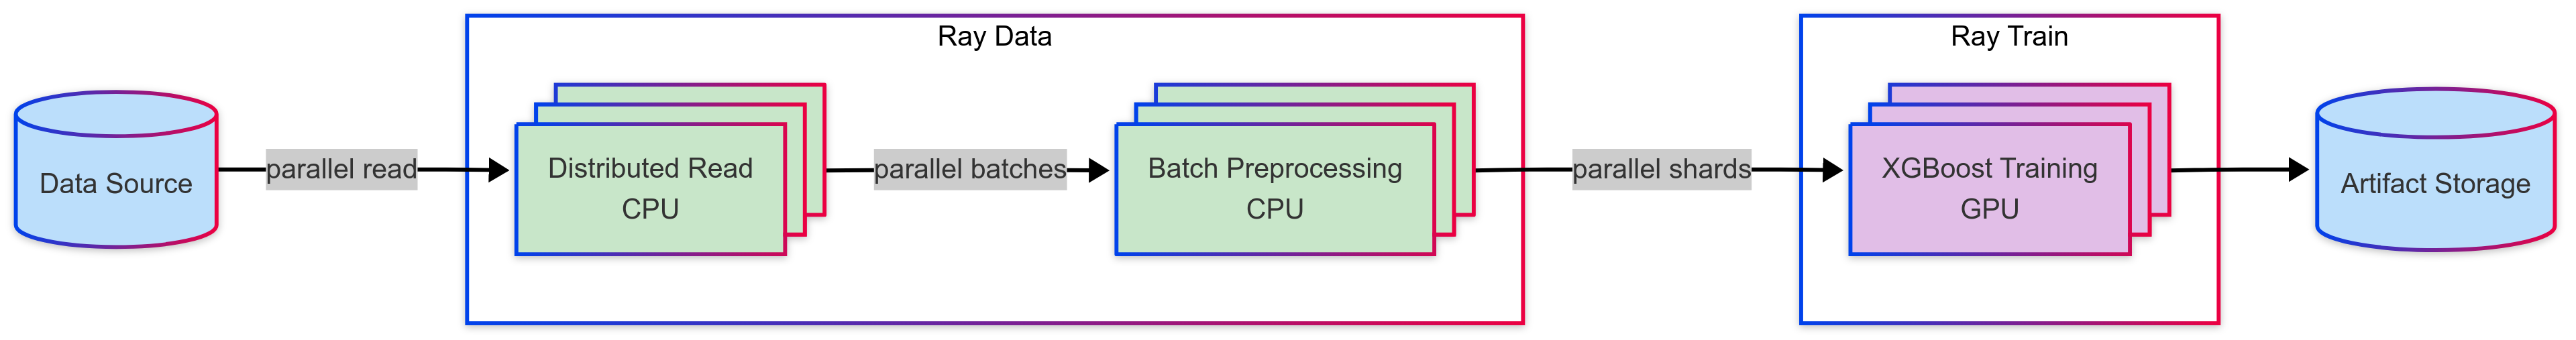
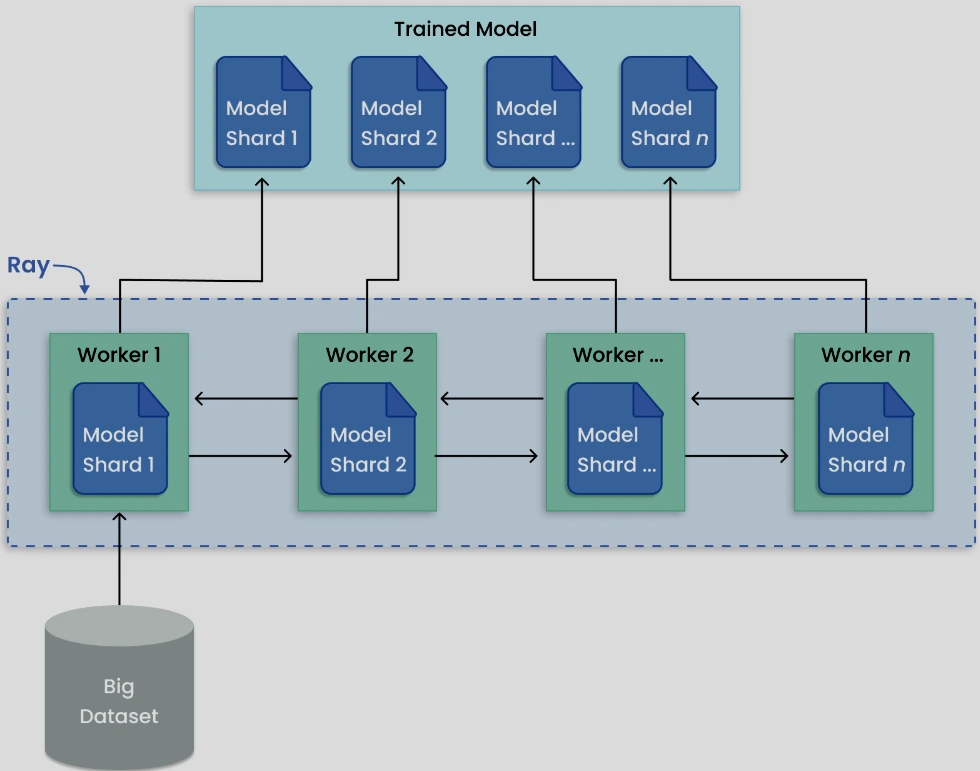
Distributed training of an XGBoost model — Ray 2.51.1
Olmo 3 Post-training - a allenai Collection
Distributed Training For Graph Networks — part 2 -what and why of ...
Pipeline-Parallelism: Distributed Training via Model Partitioning
Distributed Training Machine Learning – ZFBE
Olmo 3 Pre-training - a allenai Collection
Olmo 3 - LLMトレーニングに関する豊富な洞察
Olmo 3:开源训练过程 - 汇智网
Everything you need to know about Distributed training and its often ...
Distributed Training | Colossal-AI
TRAINING OLE FOR PROCESS CONTROL OPC AND DISTRIBUTED COMPONENT OBJECT ...
Olmo 3 Release Provides Full Transparency Into Model Development and ...
Distributed Deep Learning: Training Method for Large-Scale Model ...
Distributed Training Architectures for Next-Generation LLMs
[논문 리뷰] HETHUB: A Distributed Training System with Heterogeneous ...
The procedure of distributed training CNN via | Download Scientific Diagram
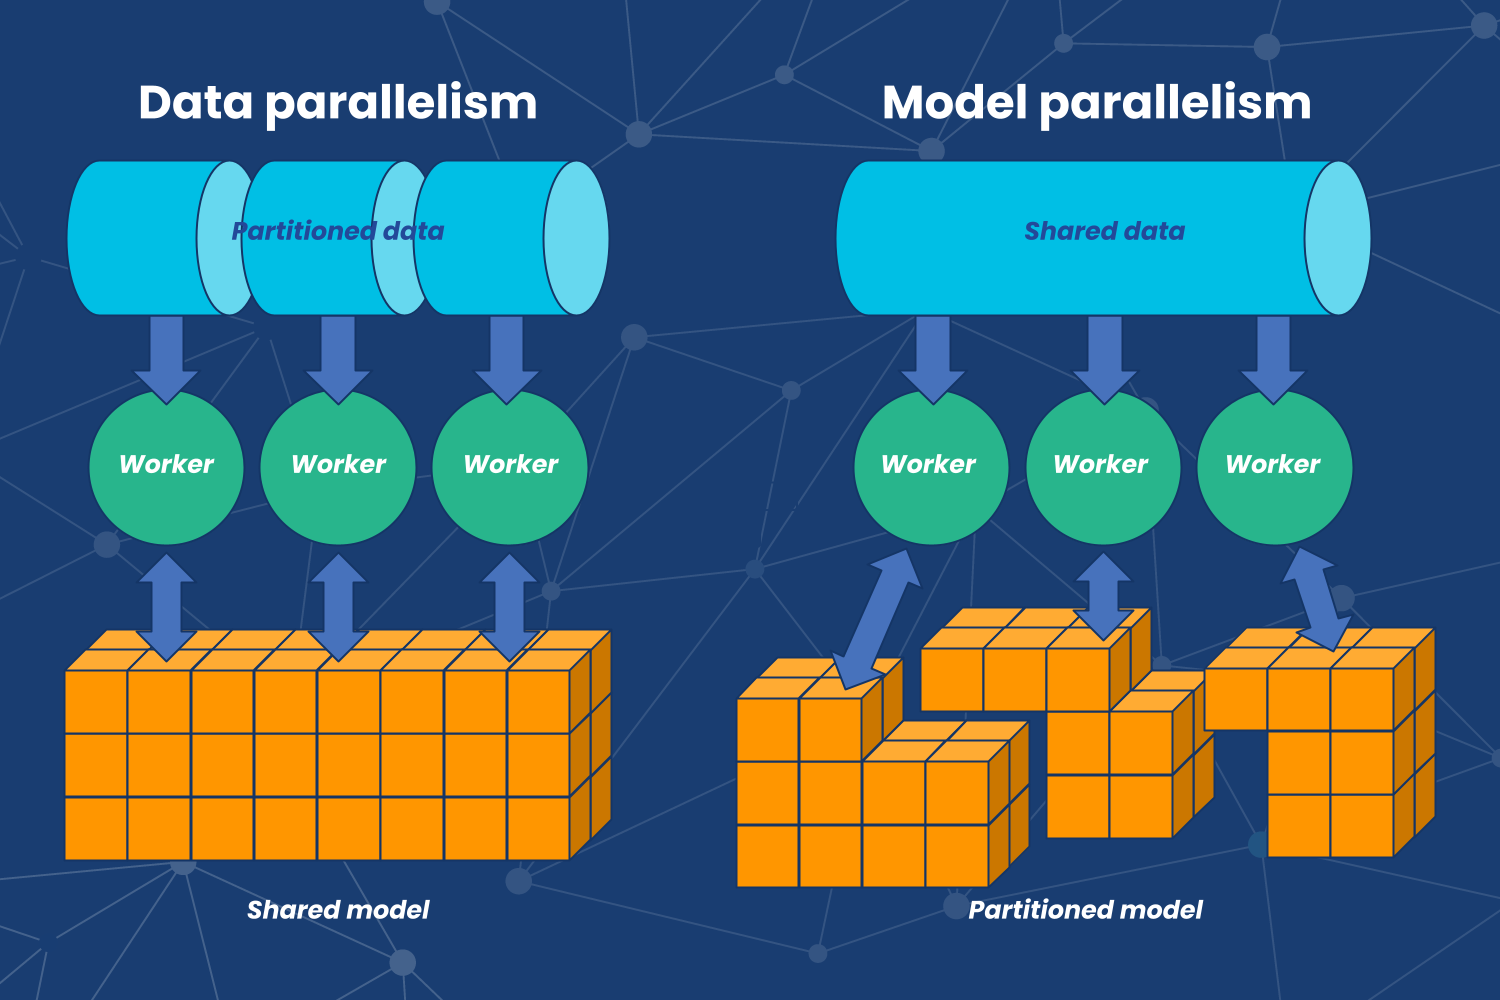
Distributed Parallel Training: Data Parallelism and Model Parallelism ...
DistributedEstimator: Distributed Training of Quantum Neural Networks ...
Schematics of the distributed training approach presented in Subsection ...
English for Professionals - Distributed Training
Dani Olmo situation overshadowing Barcelona’s bid for Spanish Super Cup ...
👨👩👧👦 Distributed Training - Composer
Understanding Distributed Training (1) : What is Distributed Training ...
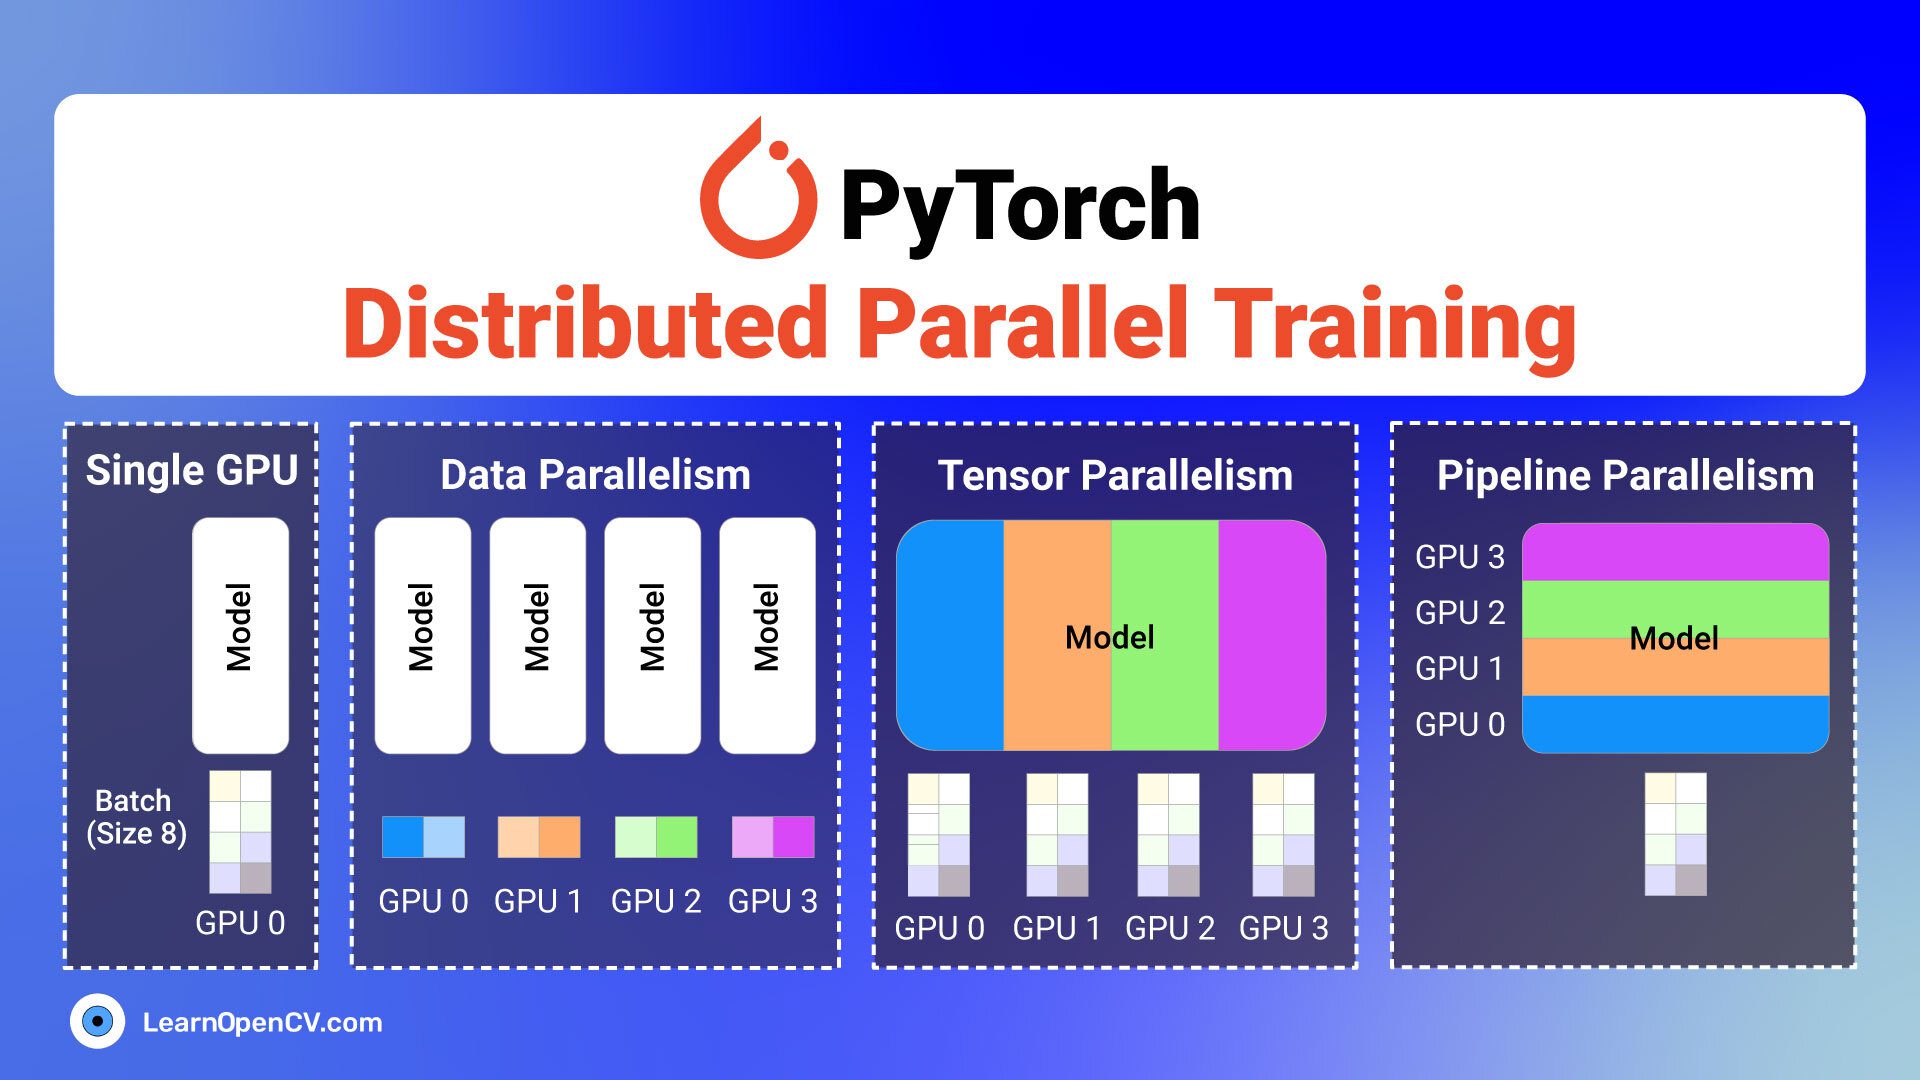
Advanced AI & Machine Learning: Distributed Training PyTorch
OLMo 2 32B: First fully open model to outperform GPT 3.5 and GPT 4o ...
Scaling Deep Learning with Distributed Training: Data Parallelism to ...
LLM Model: Olmo 2 32B by Allen Institute for AI | Deepranking.ai
Overview of Popular Distributed Training Techniques for Large Models ...
OLMo 2:全开放语言模型的技术突破与实践_olmo2-CSDN博客
OLMo 2: Fully Open-Source Foundation Model
Olmo from Ai2
Dani Olmo gives verdict on Barcelona and Real Madrid transfer windows
olmo 3
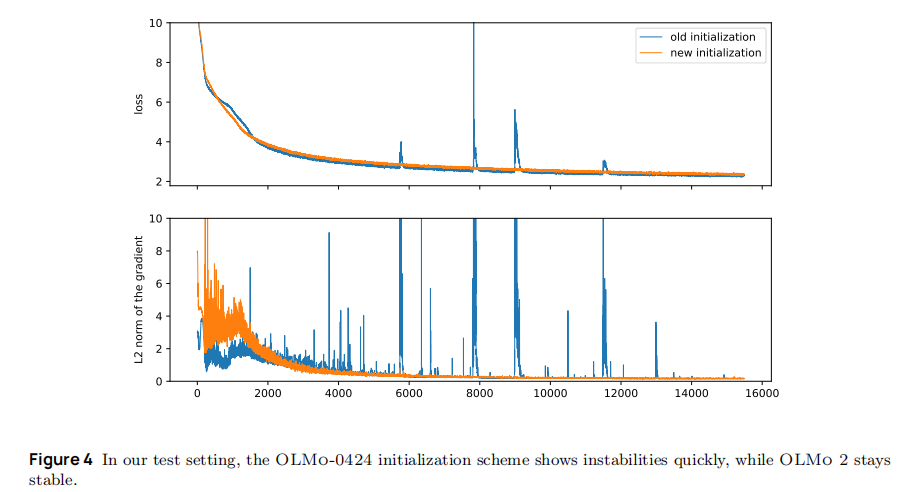
Investigating pretraining dynamics and stability with OLMo checkpoints ...
PyTorch Distributed Data Parallel (DDP) Training in Kaggle
Distributed AI Training: Multi-GPU Cluster Setup and Optimization
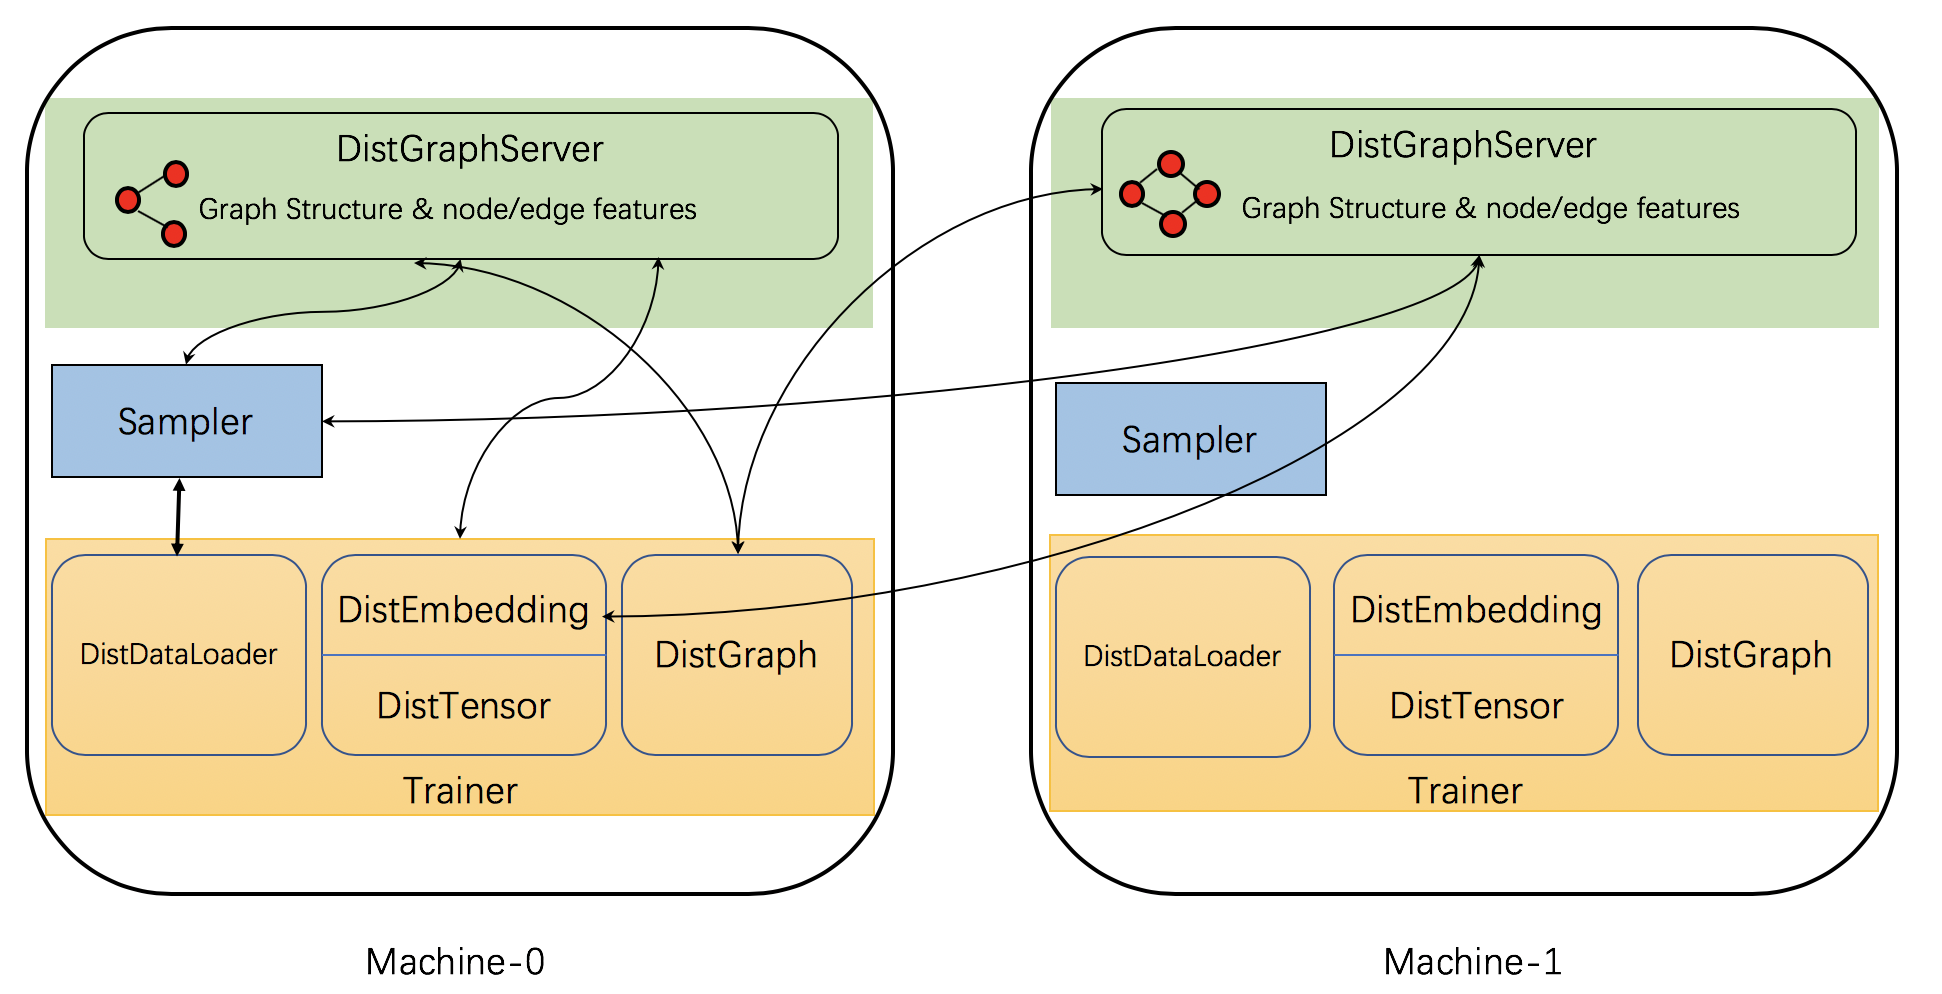
Chapter 7: Distributed Training — DGL 2.0.0 documentation
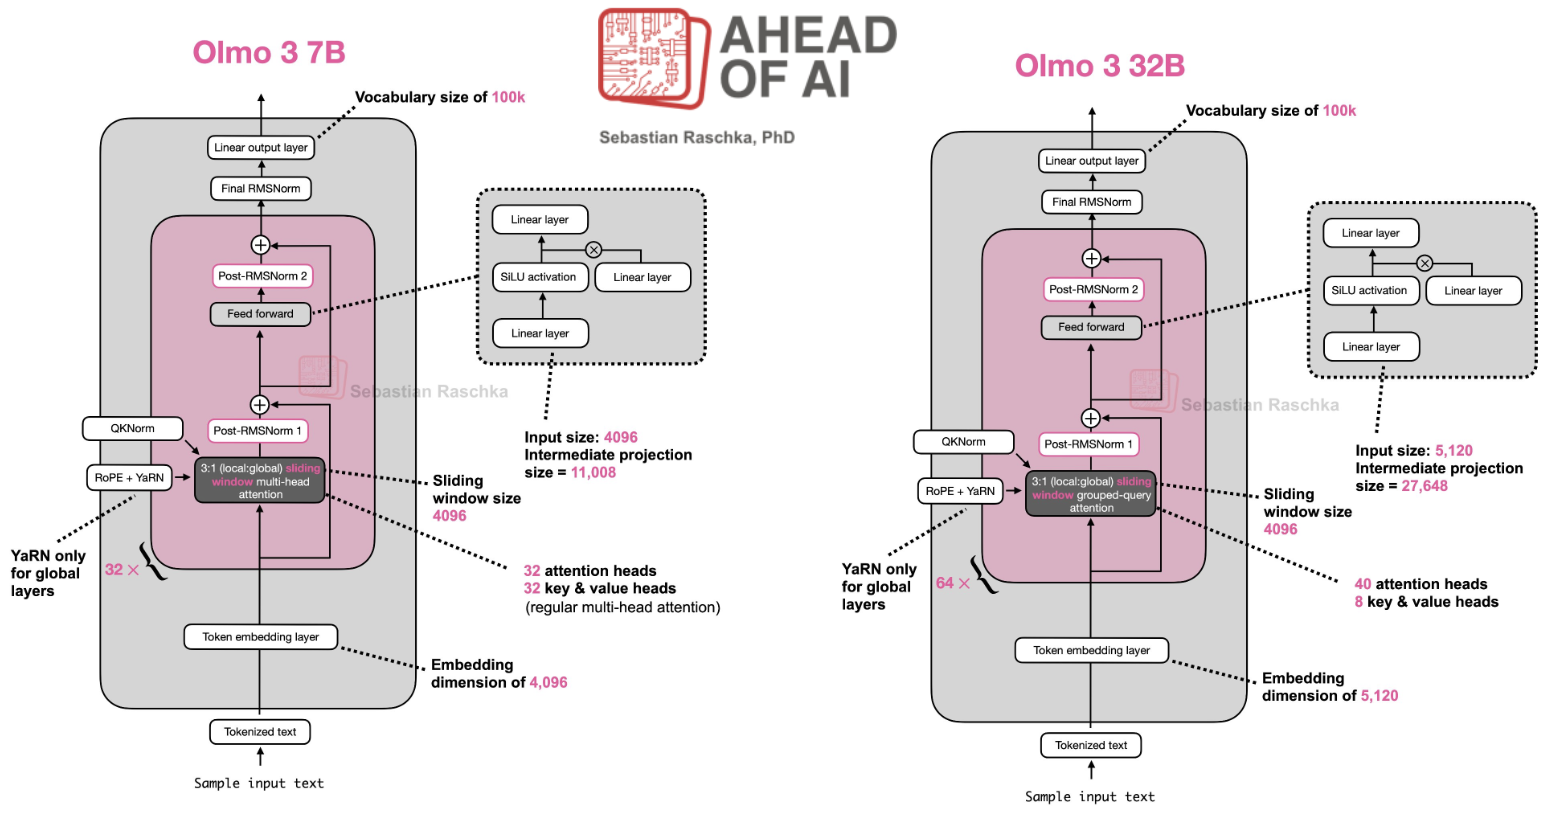
LLM Architecture Gallery | Sebastian Raschka, PhD
读代码0:OLMo3全详解 - 从OLMo 3 Tech Report开始 - 知乎
Olmo3 Open Reasoning Llm – Monir Moniruzzaman – Data Scientist, Problem ...
Guide to Ray for Scalable AI and Machine Learning Applications
GitHub - dingirsu/OLMo-pretraining: Modeling, training, eval, and ...
Sharpness-Aware Pretraining Mitigates Catastrophic Forgetting
LLM 後訓練入門 – PyTorch - PyTorch 框架
Medium
OlmoLogic: Boosting Reasoning via RLVR with Inductive Logic Programming
LLM-Training und Inferenz — Ray 2.53.0
Sparse Attention Post-Training for Mechanistic Interpretability
LLMs-from-scratch/ch05/13_olmo3/README.md at main · rasbt/LLMs-from ...
Dani Olmo's entourage 'pessimistic' about registration in time for ...
Training phase: Overview of the procedure for calculating the training ...
Don't (Just) Train For Performance - AR Forum Blog
开源大模型Olmo 3全解析:从架构到训练的完整指南_olmo-3-CSDN博客
Why AI Model Training Takes So Long
Where does output diversity collapse in post-training?
LLM (ML) Job Interviews - Resources • Mimansa Jaiswal
Reinforcement Learning | RLHF and Post-Training Book by Nathan Lambert
Probe-Based Data Attribution: Discovering and Mitigating Undesirable ...
【LLM】OLMo:又一完全开源的LLM - 知乎
AI2 and OLMo: The Only Lab Where You Can Check the Training Data
6 Self–Hosted & Local LLMs | Budibase
Traces of Social Competence in Large Language Models
PAJAMA: Codifying the Judge | Huang, Qiu, Sala
(ICLR 2025)OLMoE用更少资源超越DeepSeek-16B,开源AI迎来新纪元-OLMoE: Open Mixture-of ...
𝗢𝗟𝗠𝗼 𝟯 - A very detailed, up-to-date report on the latest best ...
14 Top Open Source LLMs For Research and Commercial Use
STRIDE: Training Data Attribution via Sparse Recovery from Subset ...