Showing 114 of 114on this page. Filters & sort apply to loaded results; URL updates for sharing.114 of 114 on this page
[FSDP] FSDP produces different gradient norms vs DDP, and w/ grad norm ...
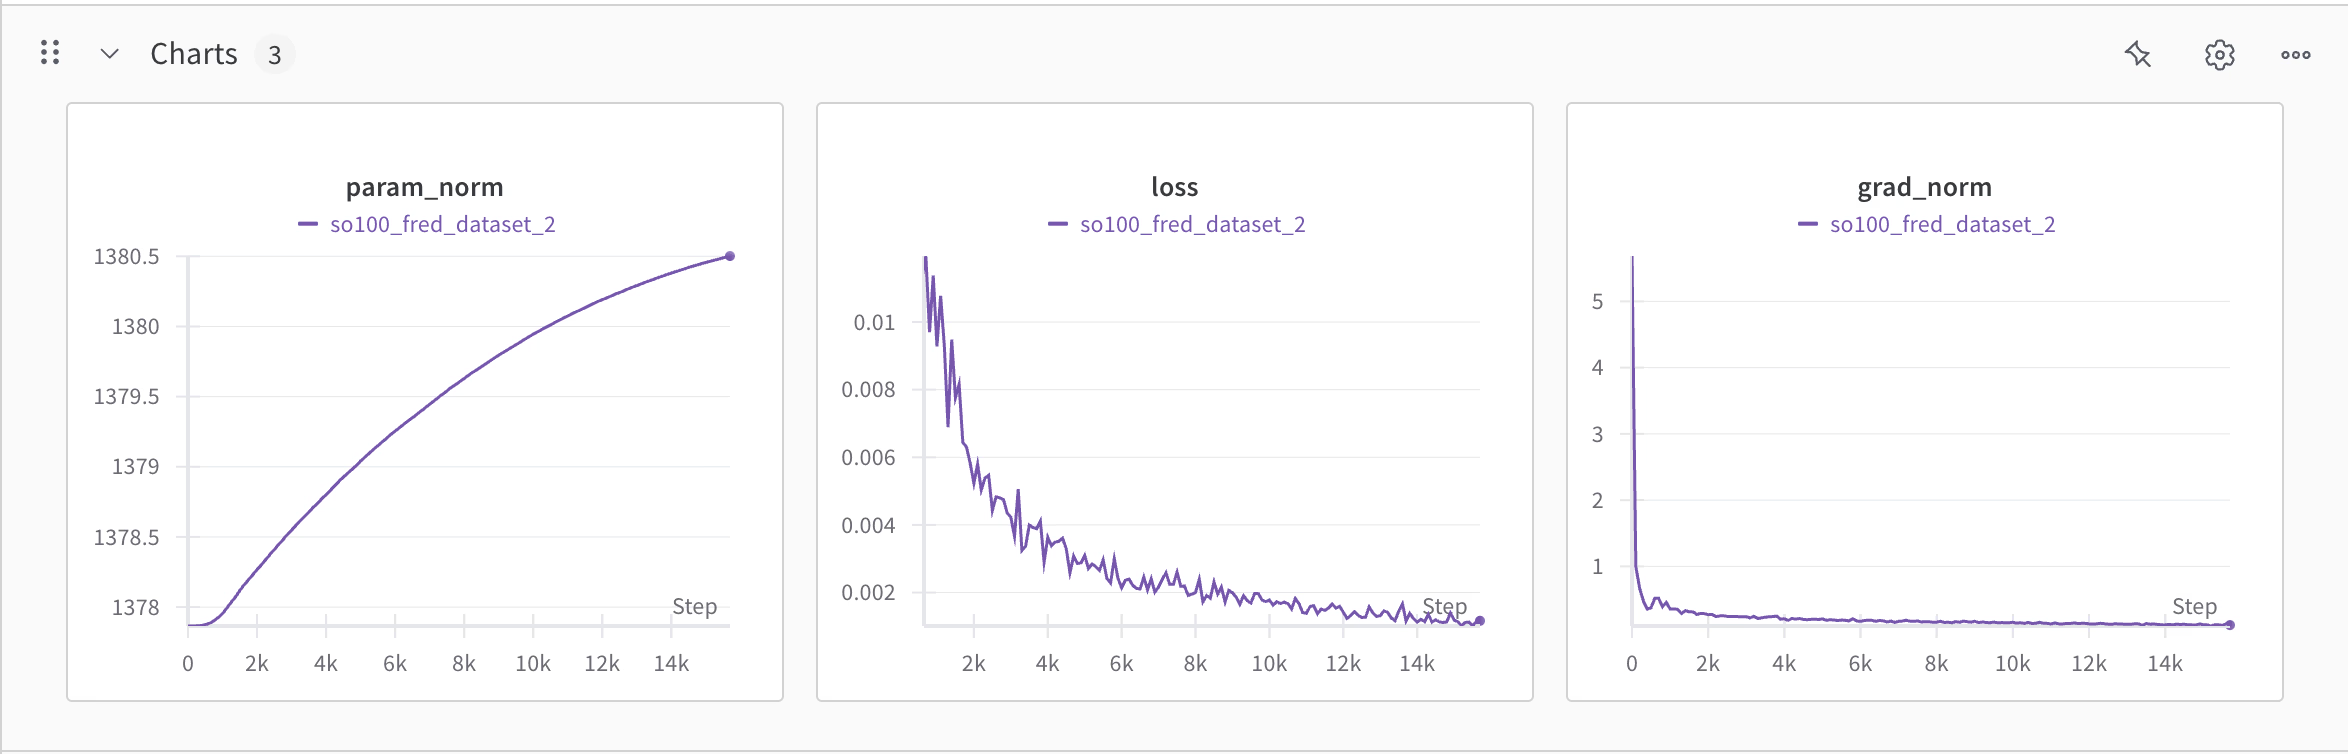
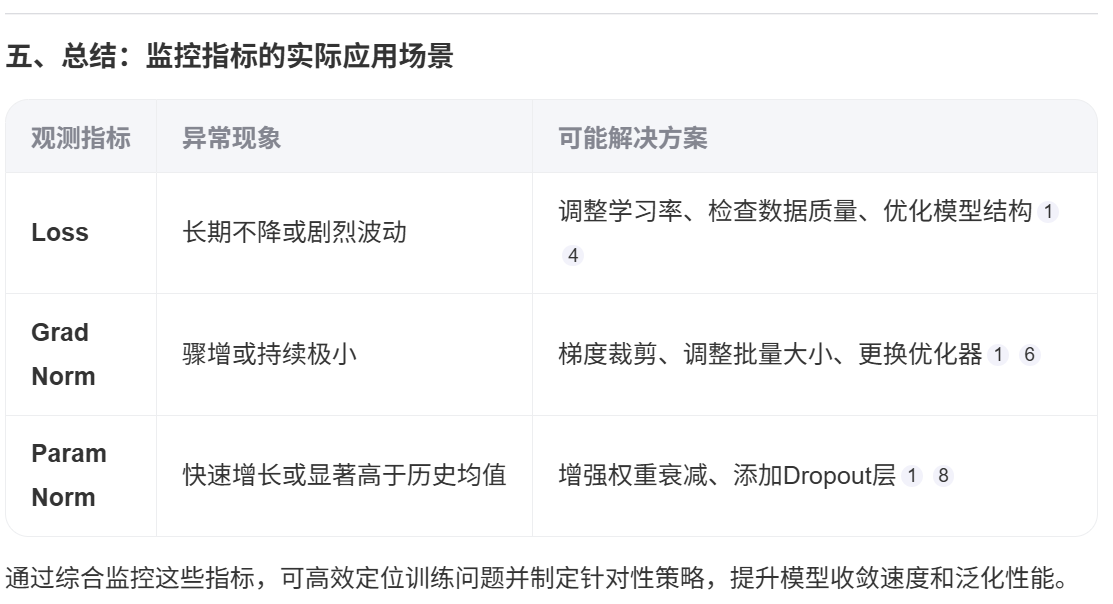
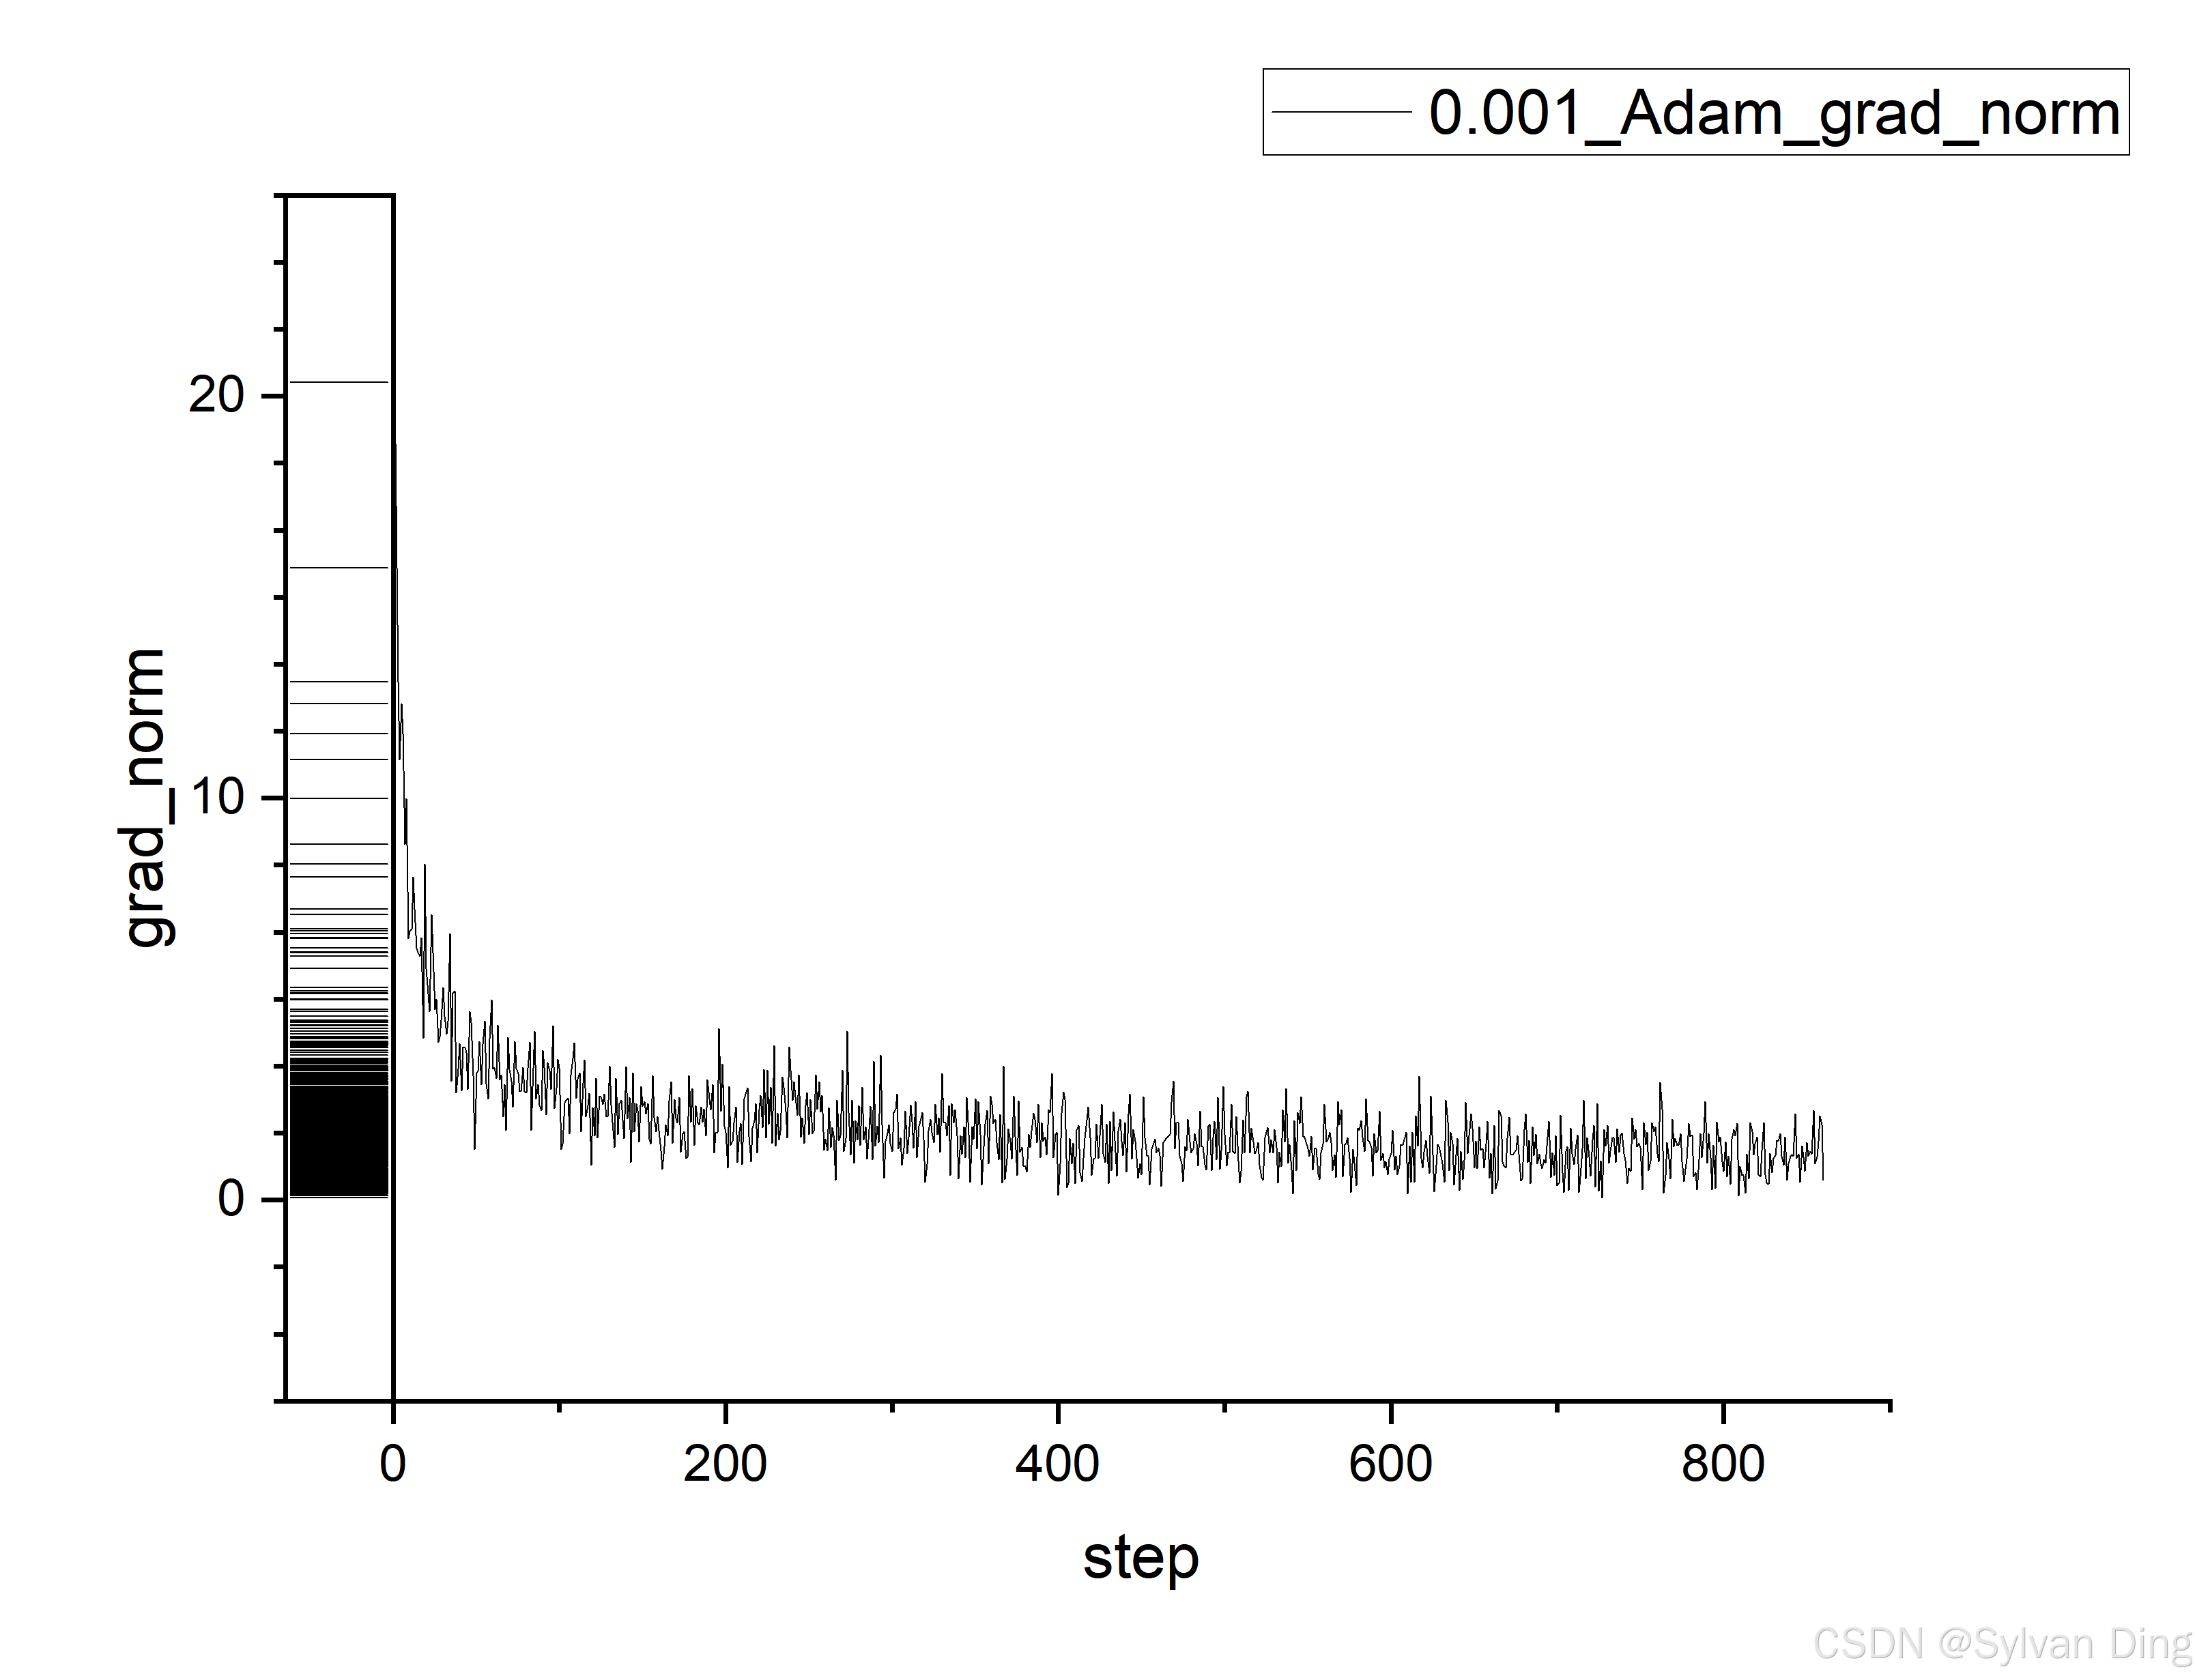
深度神经网络训练过程中的观测值 —— param norm, loss, grad norm - Angry_Panda - 博客园
neural networks - What does it mean when the global gradient norm keeps ...
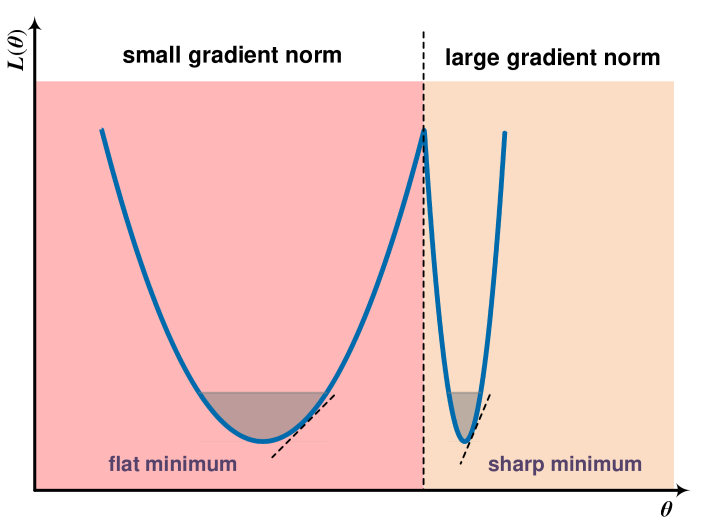
Image and Gradient Norm
[2202.03599] Penalizing Gradient Norm for Efficiently Improving ...
Illustration of the gradient norm for ScaleGrad and MLE. T-N denotes ...
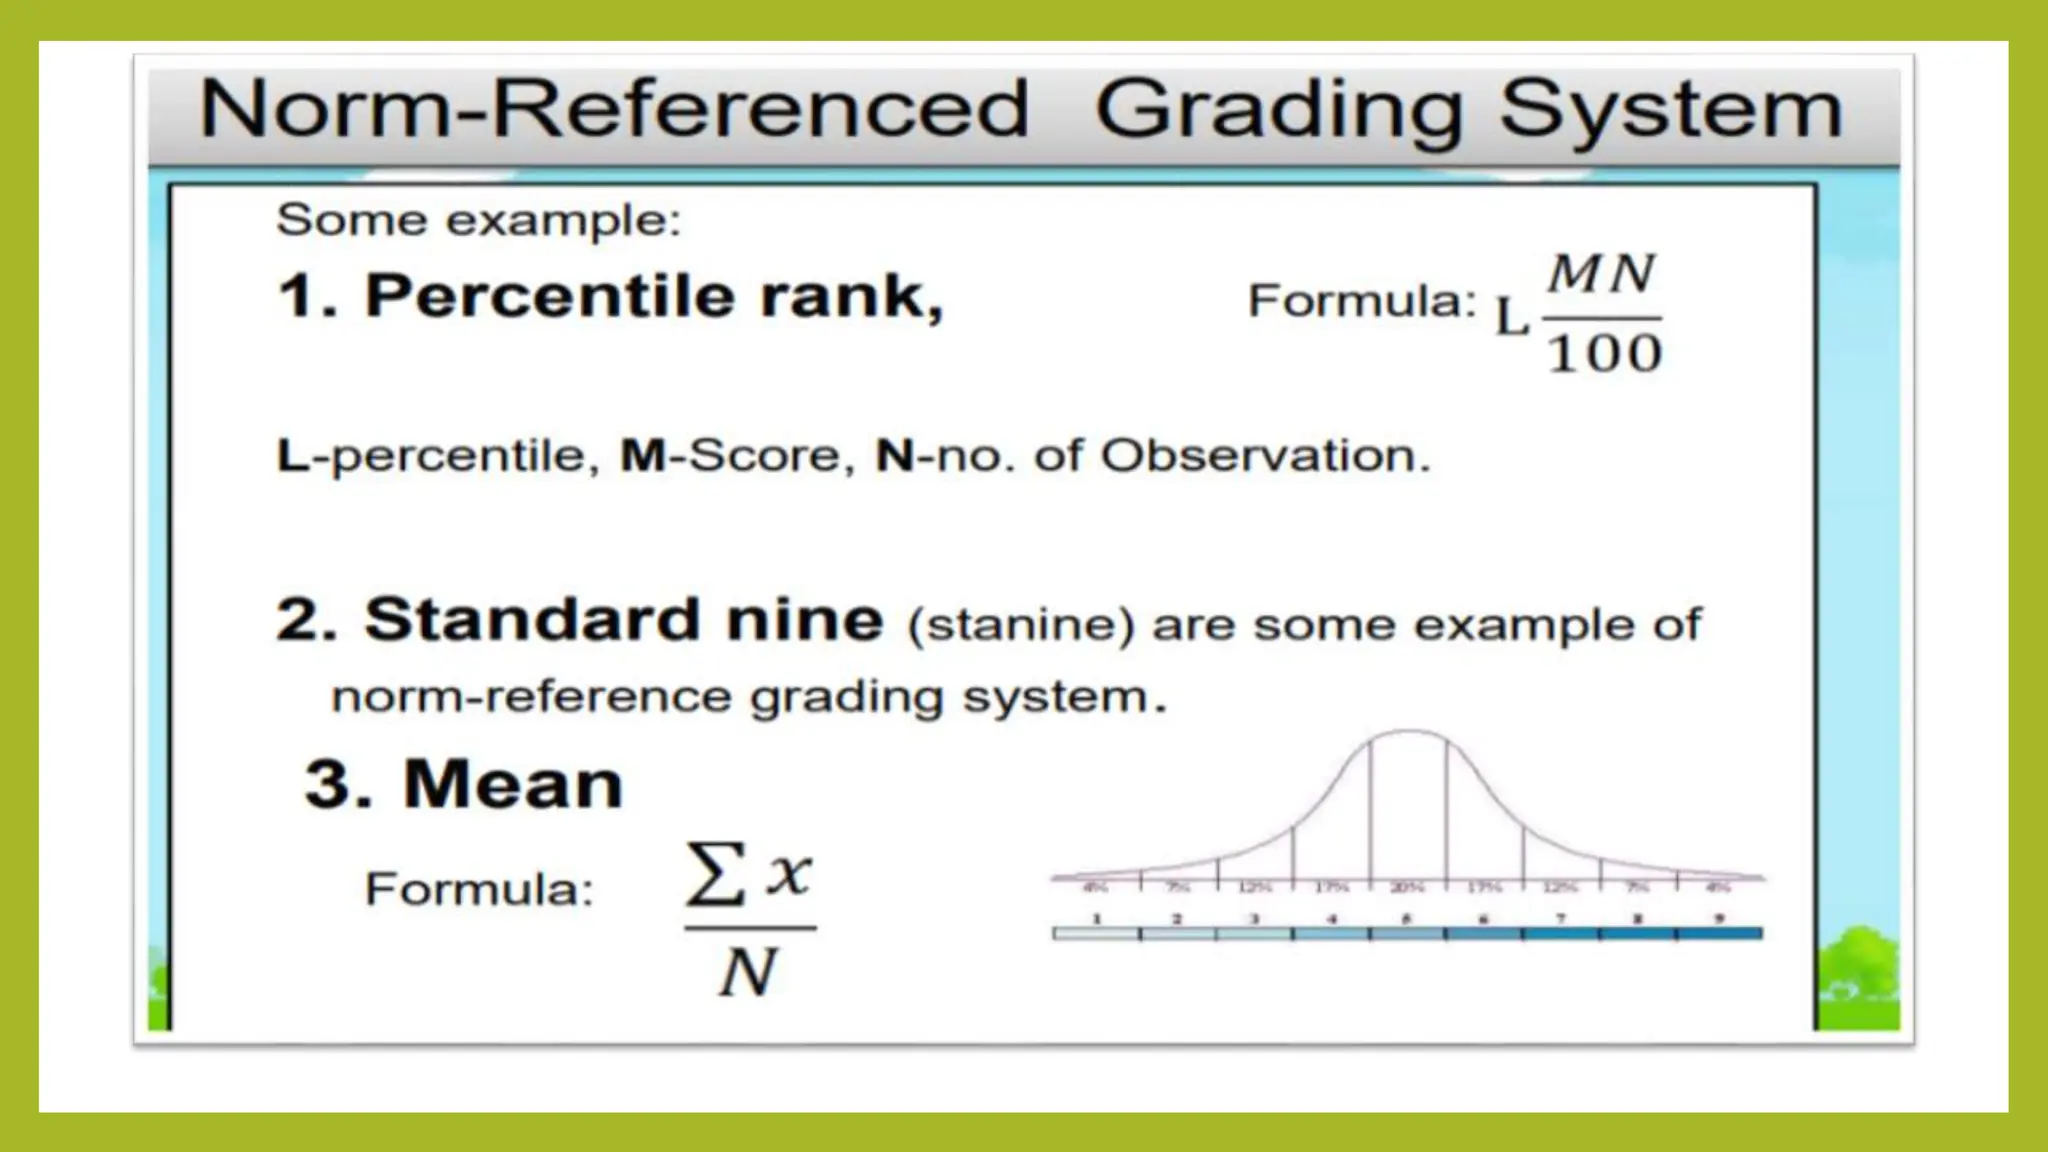
Criterion-Referenced Grading and Norm Grading system | PPTX
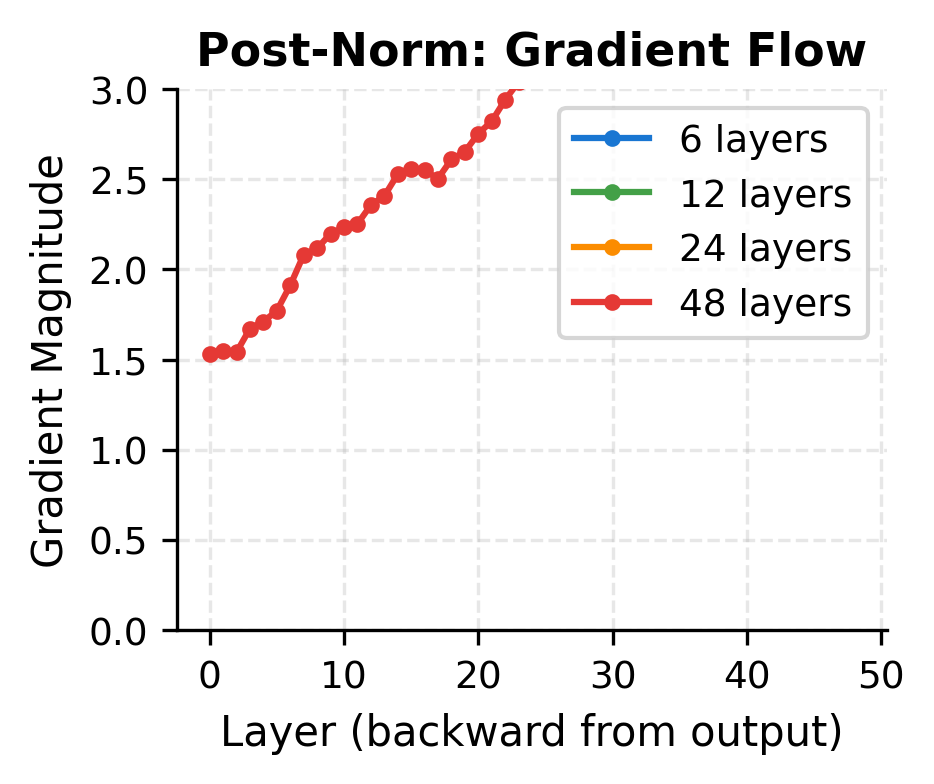
The global norm of gradients when using POSTNORM or PRENORM, and with ...
The gradient norm and the noise - autograd - PyTorch Forums
Gradient norm of the three last convolution layers with the ...
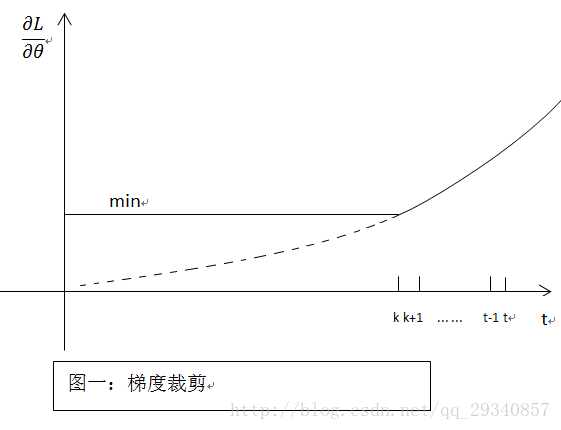
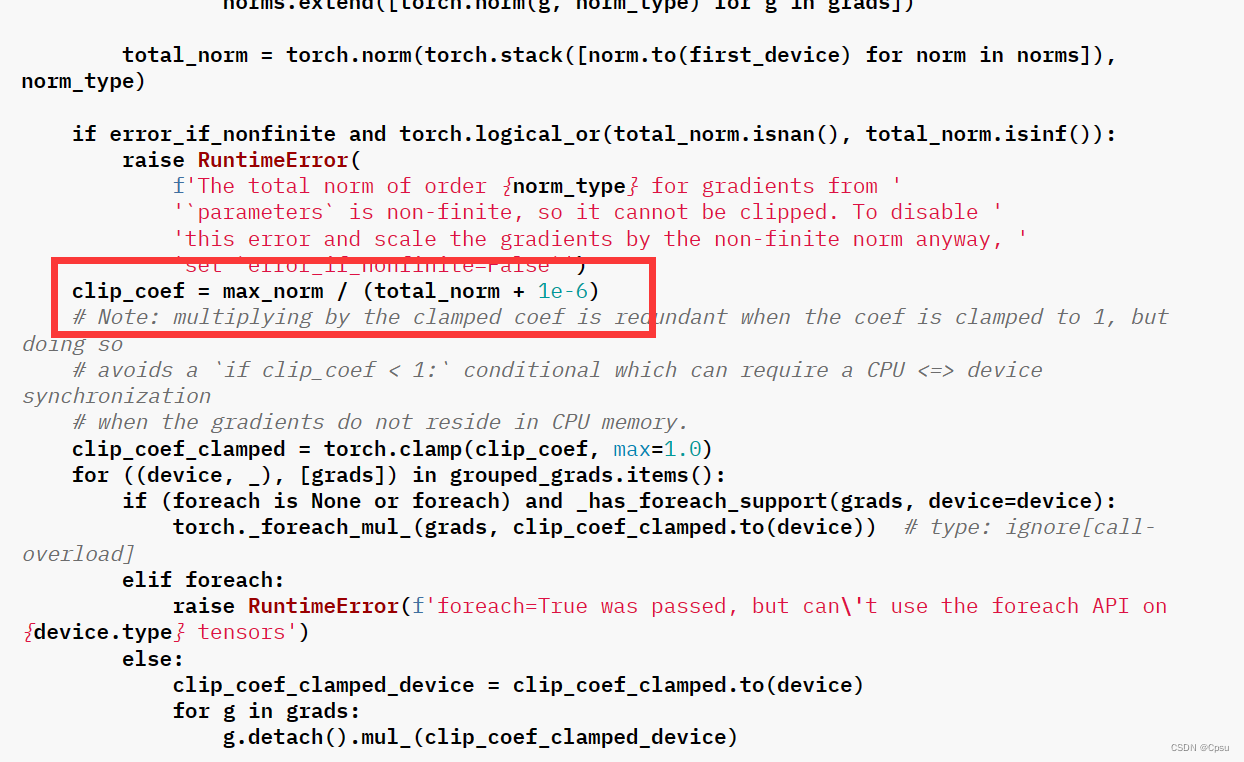
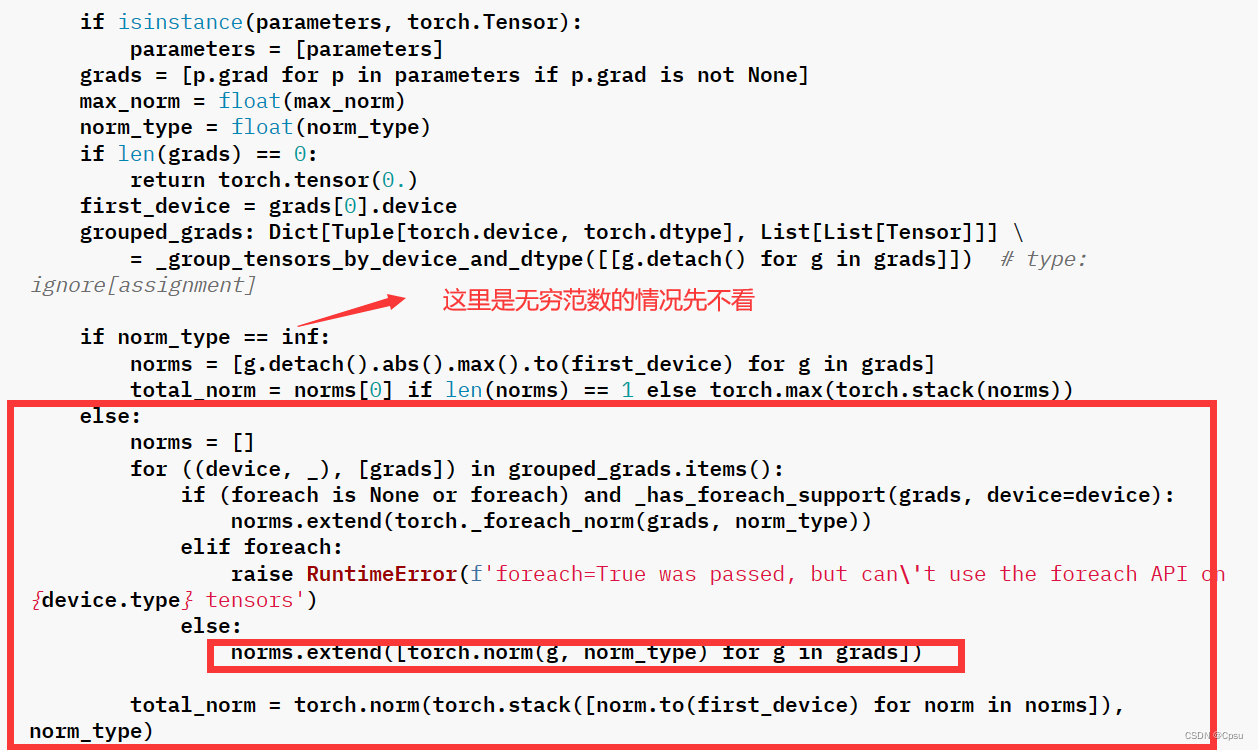
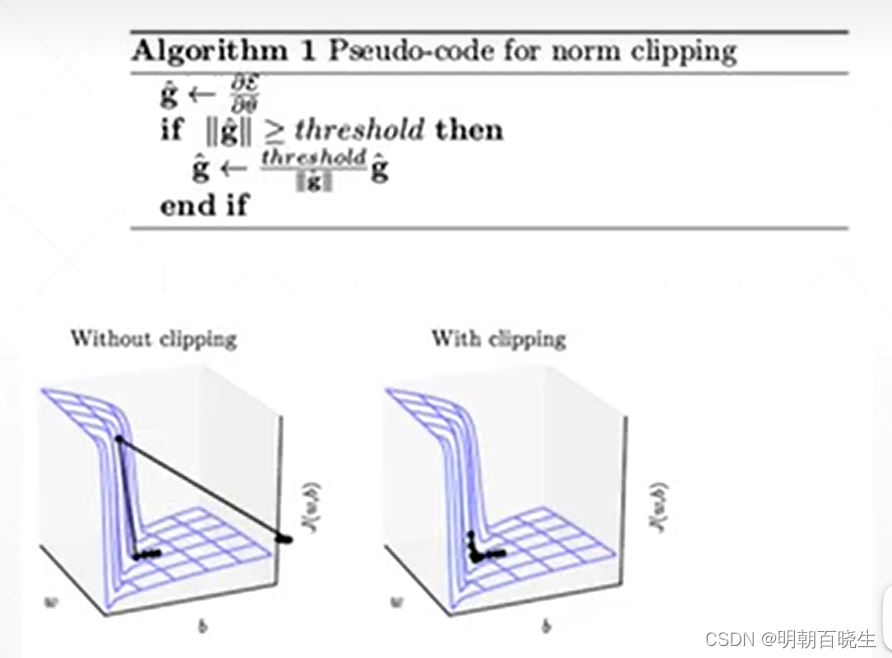
梯度裁剪:torch.nn.utils.clip_grad_norm_详解_clip grad norm-CSDN博客
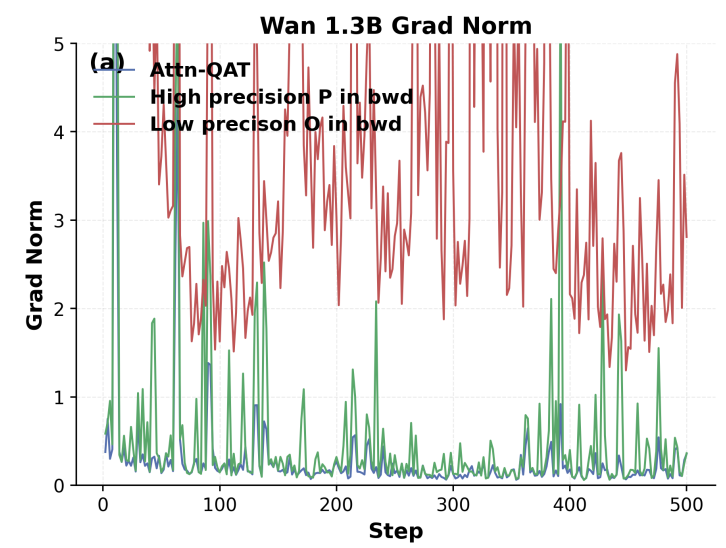
Attn-QAT: Making 4-Bit Attention Actually Work | Hao AI Lab @ UCSD
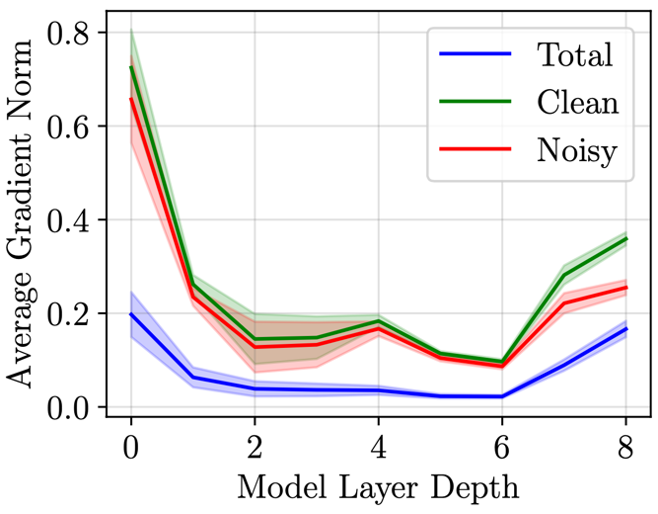
Collaboratively Learning Federated Models from Noisy Decentralized Data
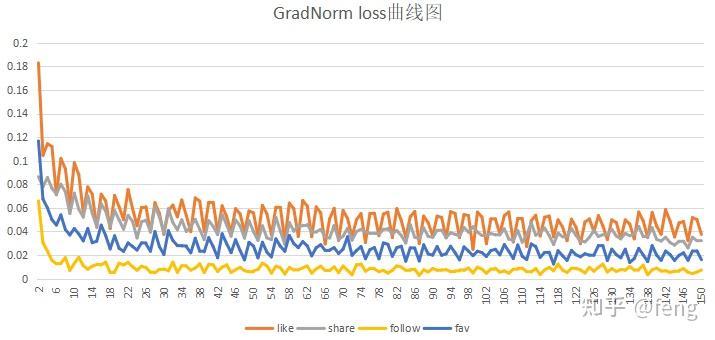
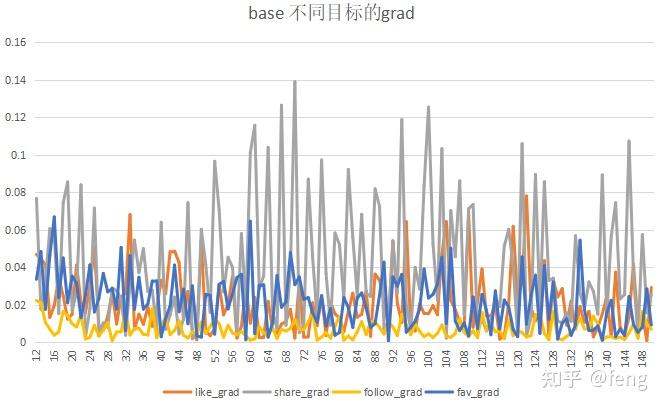
多目标loss优化在开源数据实验一(uncertainty weight、GradNorm) - 知乎
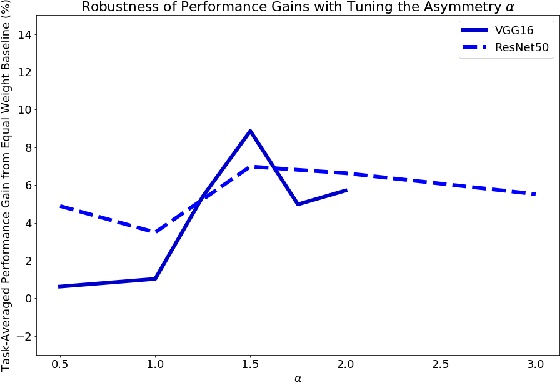
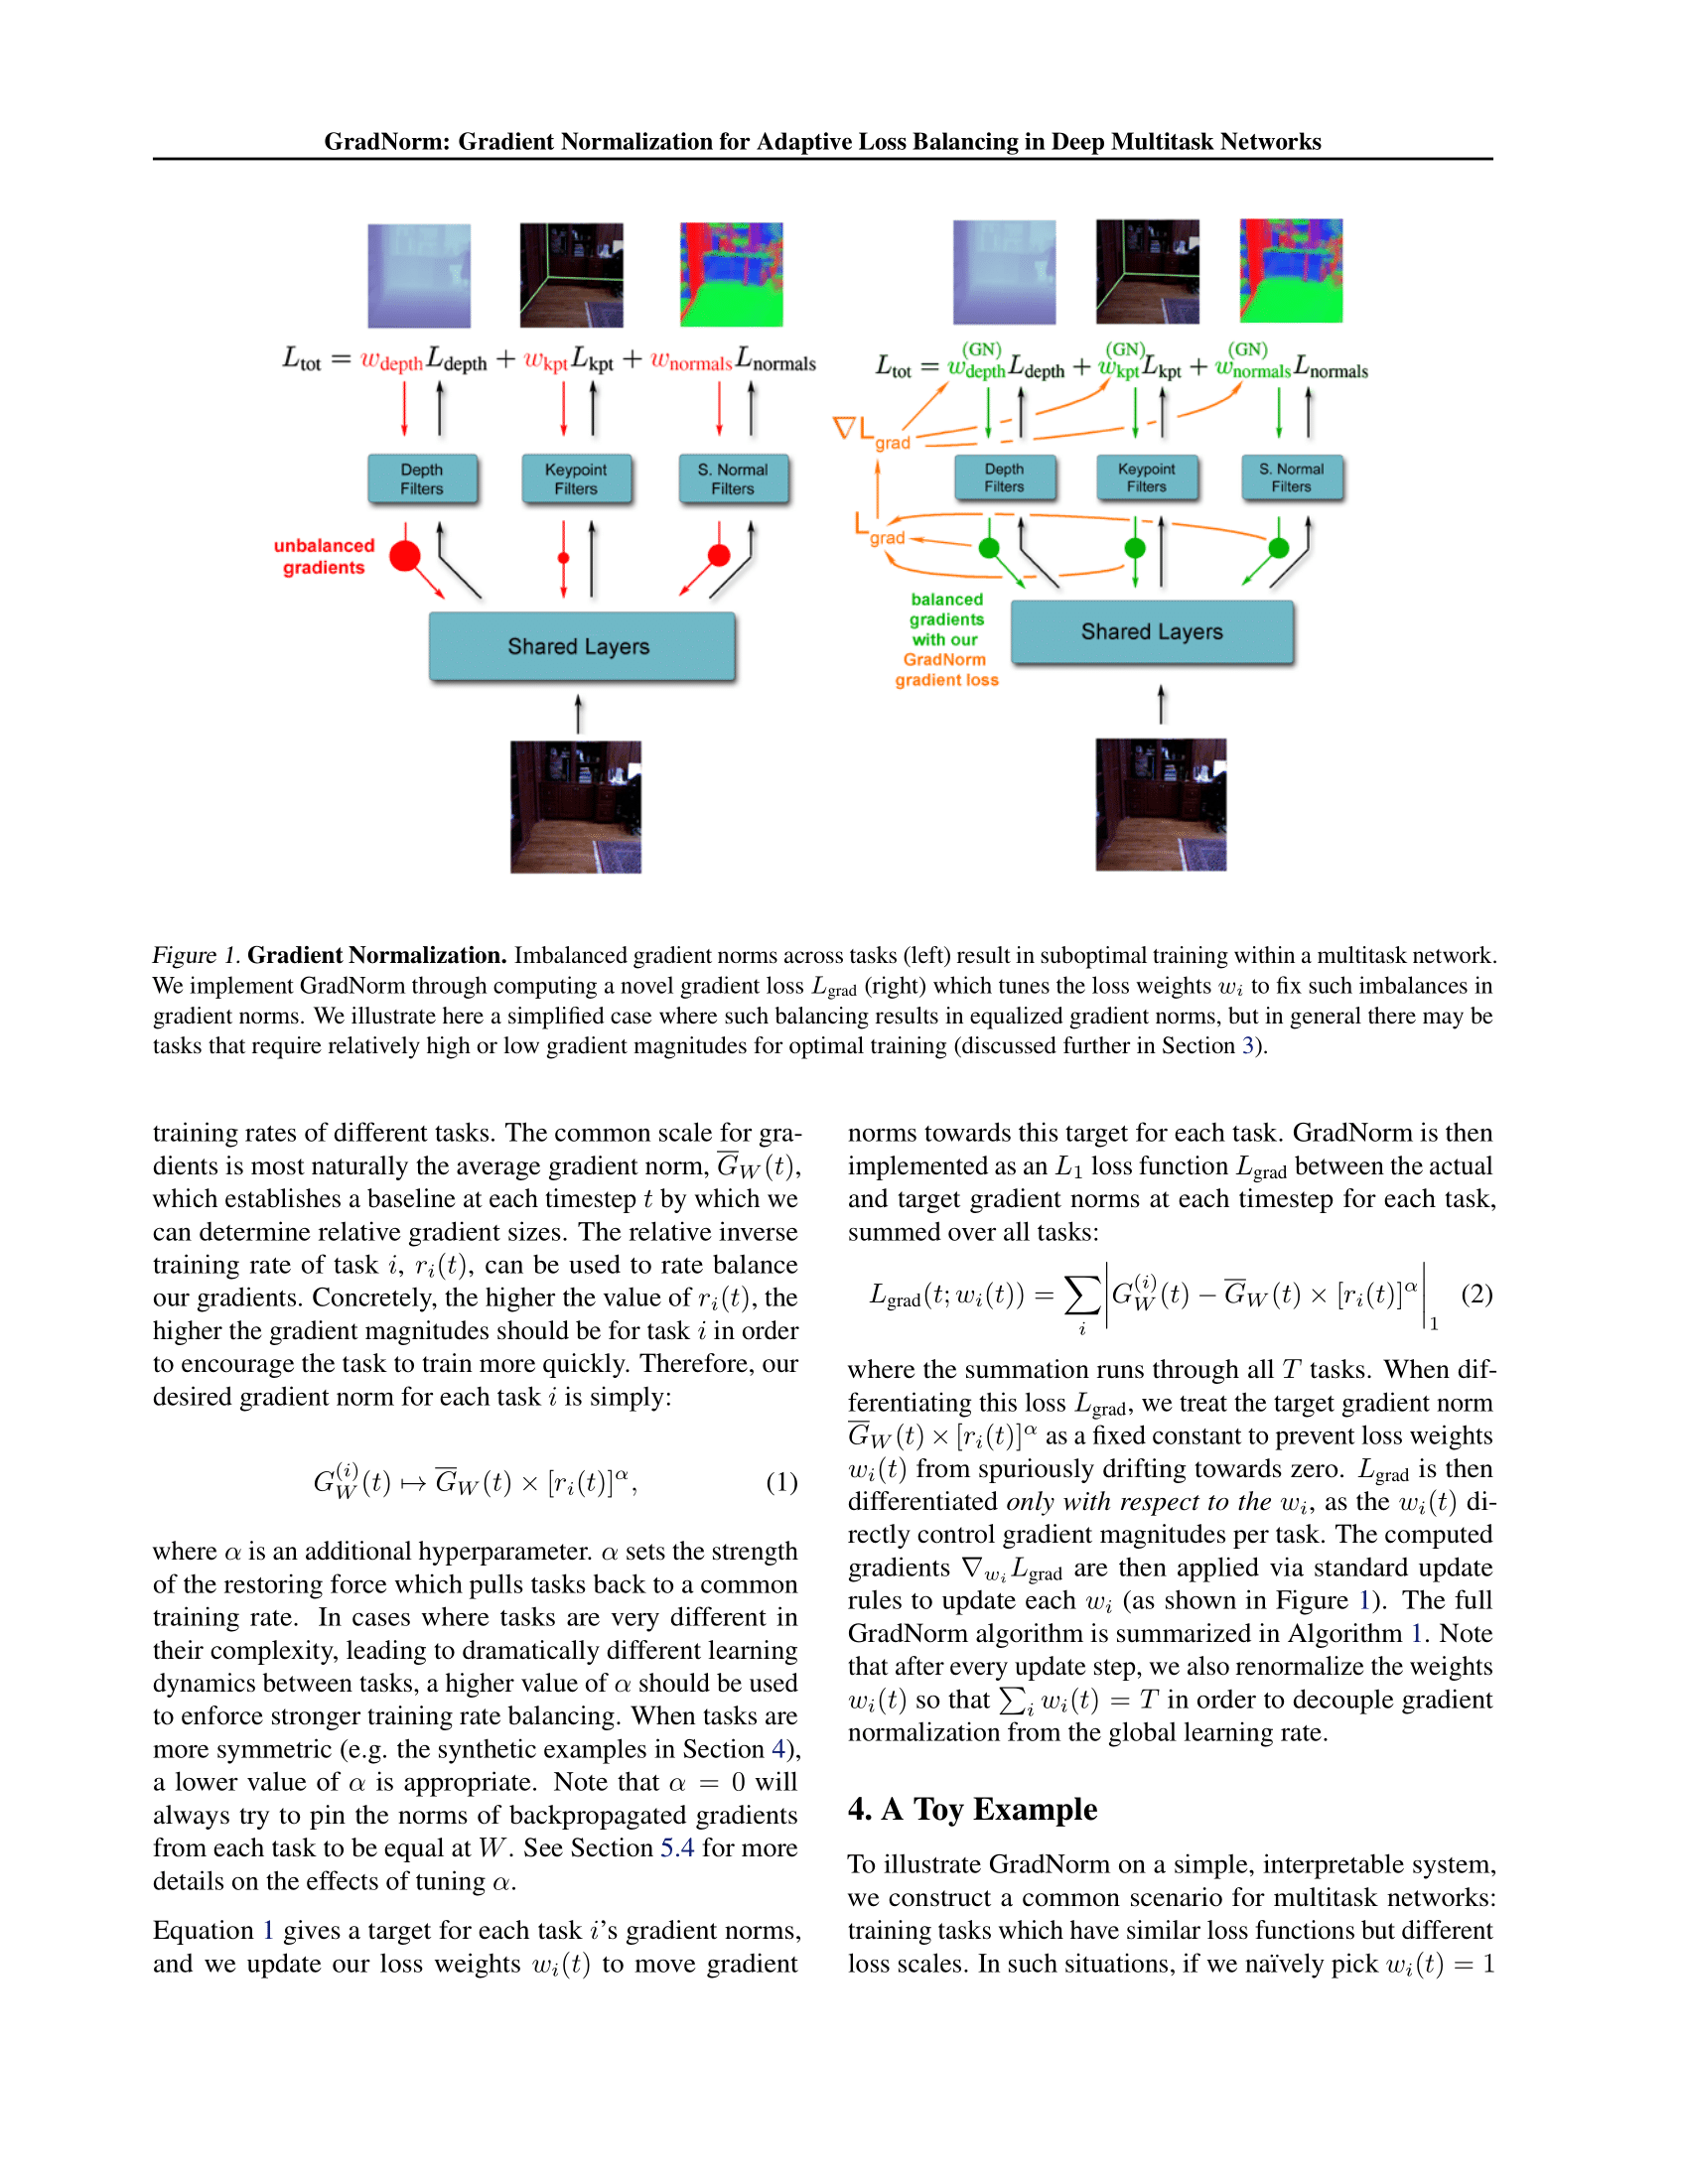
GradNorm: Gradient Normalization for Adaptive Loss Balancing in Deep ...
grad_norm(梯度范数)是什么?_grad norm-CSDN博客
技术实现 | 多目标优化及应用_多目标优化实例-CSDN博客
Working with the metric | mbank documentation
L2-norms of gradients increasing during training of deep neural network ...
Writing an LLM from scratch, part 32j -- Interventions: trying to train ...
[1711.02257] GradNorm: Gradient Normalization for Adaptive Loss ...
Learning GRPO: Experiments and Insights from Fine-Tuning an LLM
李宏毅2023机器学习作业HW05解析和代码分享 - 知乎
大模型微调实战:通过 LoRA 微调修改模型自我认知 - 探索云原生 - 博客园
Multi-Task Learning:GradNorm - 知乎
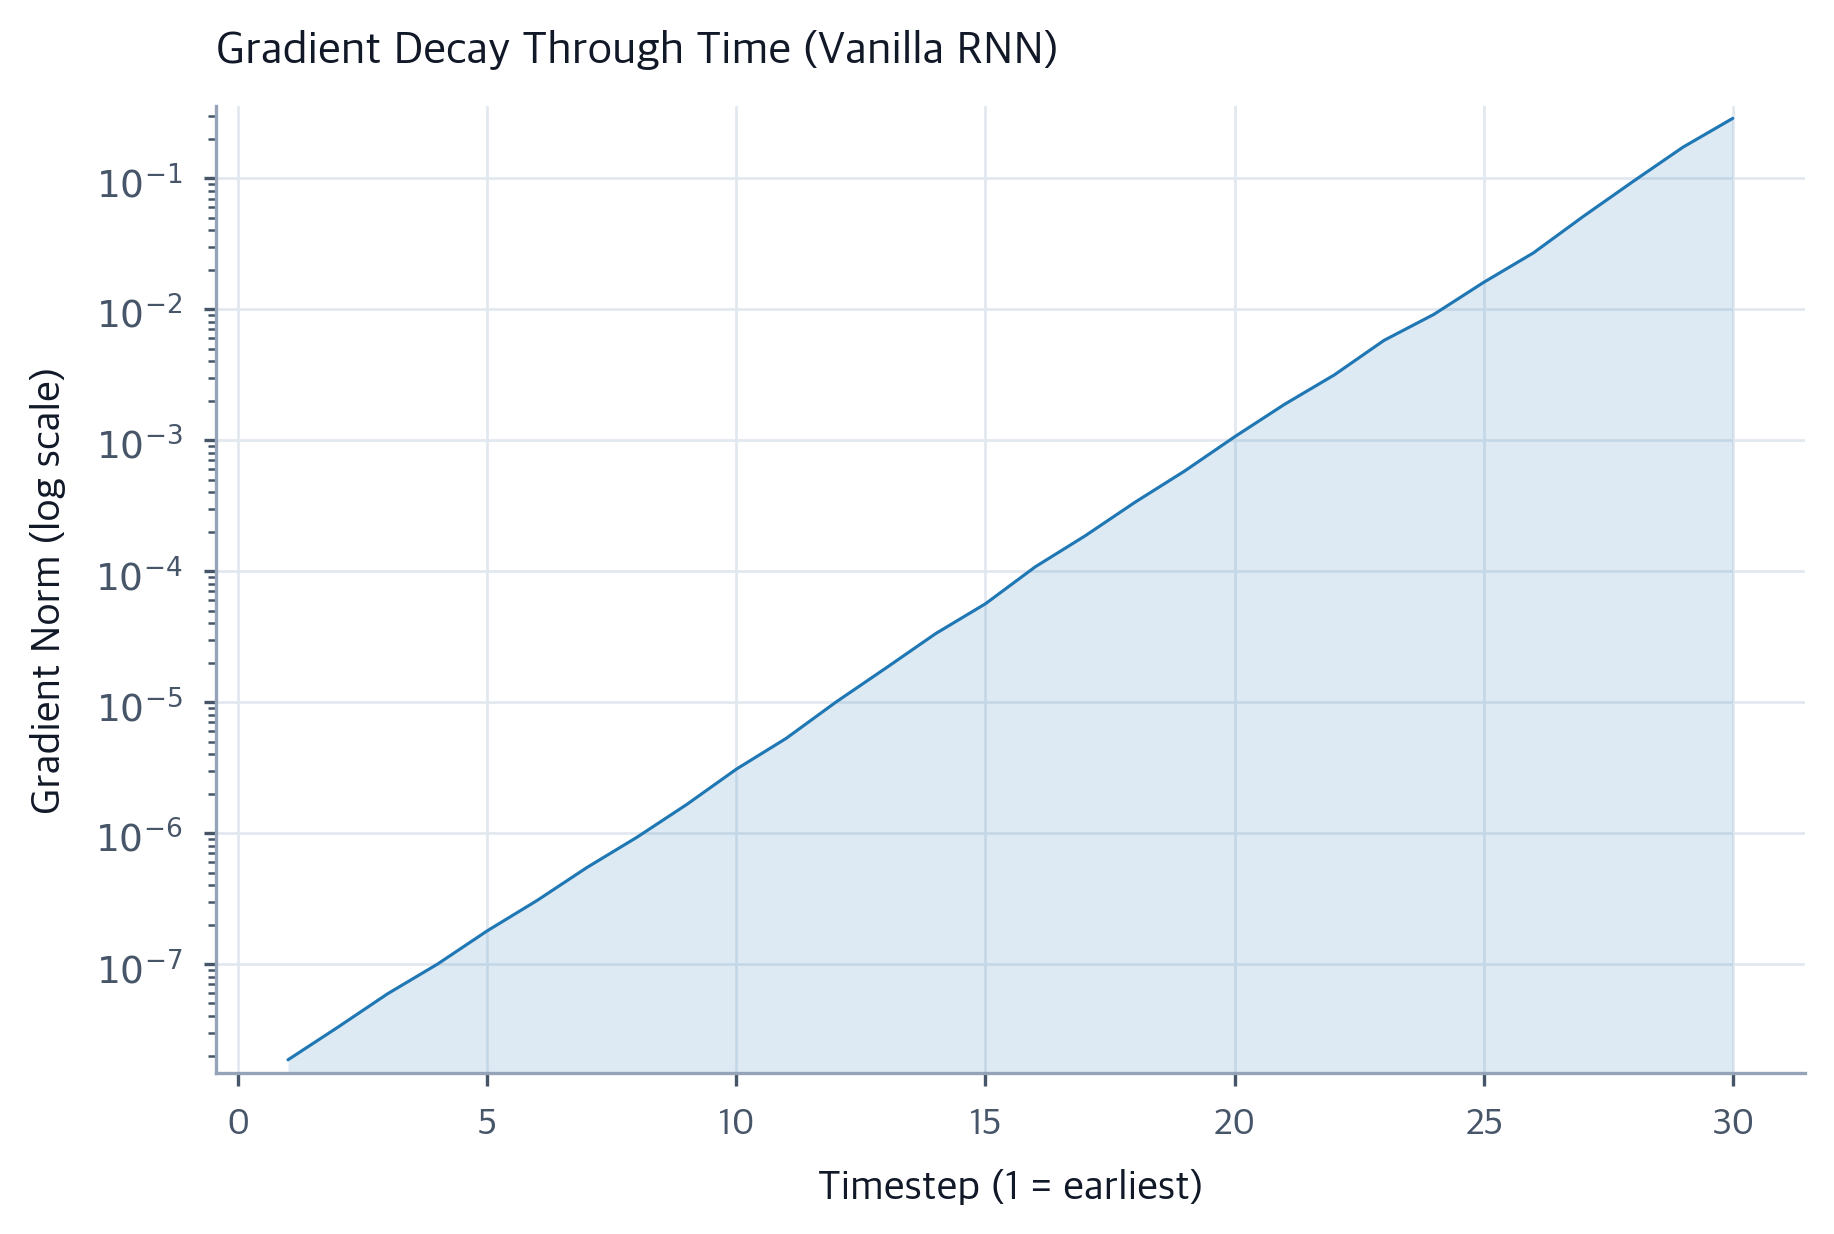
Backpropagation Through Time: RNN Training Algorithm - Interactive ...
动态调整多任务学习:GradNorm算法详解-CSDN博客
(PDF) GradNorm: Gradient Normalization for Adaptive Loss Balancing in ...
Supplementary Material
梯度裁剪(Clipping Gradient):torch.nn.utils.clip_grad_norm - Shaw_喆宇 - 博客园
Pre-Norm vs Post-Norm: Choosing Layer Normalization Placement for ...
Dual-Balancing for Multi-Task Learning | AI Research Paper Details
Can Neural Network Memorization Be Localized?
Gradient Evolution | David Weissteiner
MaxRL: Maximum Likelihood Reinforcement Learning
Revisiting Auxiliary Losses for Conditional Depth Routing: An Empirical ...
GitHub - brianlan/complex-grad-norm: a much more complex case using ...
在多任务学习中应用GradNorm实现自适应损失均衡与训练优化-开发者社区-阿里云
Vanishing Gradients: Why RNNs Fail on Long Sequences - Interactive ...
将蛋白质语言模型扩展到千亿参数,深度解读百图生科、清华xTrimoPGLM模型-腾讯云开发者社区-腾讯云
[2311.07772] In-context Learning and Gradient Descent Revisited
Screening Is Enough
(2017) Training very deep networks with Batchnorm – Rohan Varma ...
Demystifying Gradients | Yuan (Emily) Xue
torch.nn.utils.clip_grad_norm__clipgrad-CSDN博客
Training Stability: Loss Spikes, Gradient Norms & Debugging ...
torch.nn.utils.clip_grad_norm_() - 梦想家肾小球 - 博客园
pytorch梯度裁剪_pytorch梯度剪裁-CSDN博客
GPT-2 复现笔记 | Glerium's Blog
大模型训练 Learning rate warmup, cosine decay and gradient clipping - 技术栈
Writing an LLM from scratch, part 32k -- Interventions: training a ...
[AI] 파인튜닝으로 만드는 나만의 아이폰 고객센터 #3
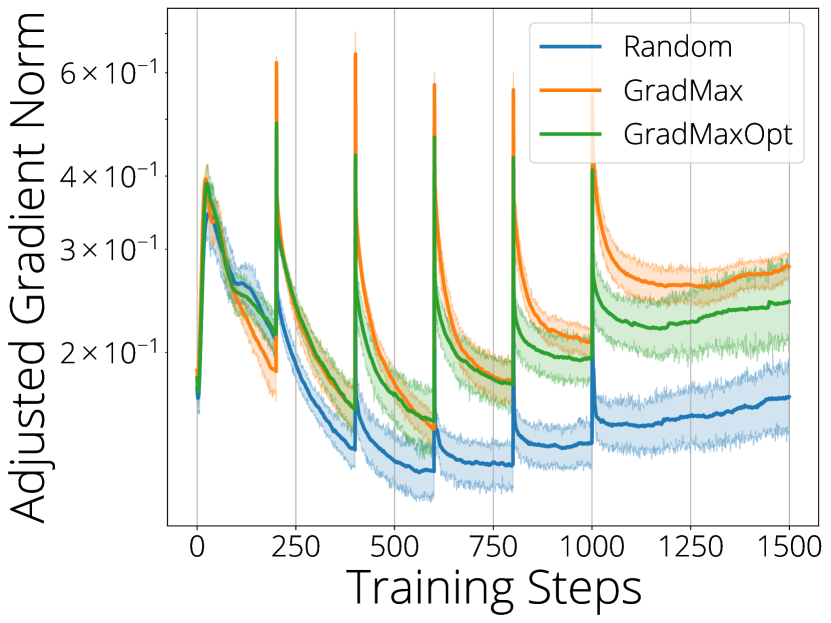
[2201.05125] GradMax: Growing Neural Networks using Gradient Information
Figure 7 from GradNorm: Gradient Normalization for Adaptive Loss ...
what is the key difference between SimpleGradNormalizer and ...
【Pytorch】梯度裁剪——torch.nn.utils.clip_grad_norm_的原理及计算过程-CSDN博客
Towards Certified Unlearning for Deep Neural Networks
Asymmetric On-Policy Distillation: Bridging Exploitation and Imitation ...
【Pytorch】梯度裁剪——torch.nn.utils.clip_grad_norm_的原理及计算过程
centerpoint训练过程 - 知乎
PyTorch Lightning实战 - 训练 MNIST 数据集
Torch.Nn.Utils.Weight_Norm — Pytorch 2.2 Documentation – FFPKG
Optimizing Recurrent Neural Networks: A Study on Gradient Normalization ...
微调Qwen2大模型开发中药方剂生成智能体-开发者社区-阿里云
torch.nn.utils.clip_grad_norm_: bad GPU utilization due to GPU-data ...
[PyTorch][chapter 45][RNN_2]_np.random.randint(3.size=1)-CSDN博客
What Is the Gradient Norm? | Baeldung on Computer Science
Gated Normalization Removal and Scale Anchoring in Pre-Norm Transformers
DiaBlo: Diagonal Blocks Are Sufficient For Finetuning
cs330 - lecture2 multi task learning
Embedding微调-对齐下游检索 – Lcf Blogs
Demystifying Data Organization for Enhanced LLM Training
5. Filtering - Digital Image Processing Notes
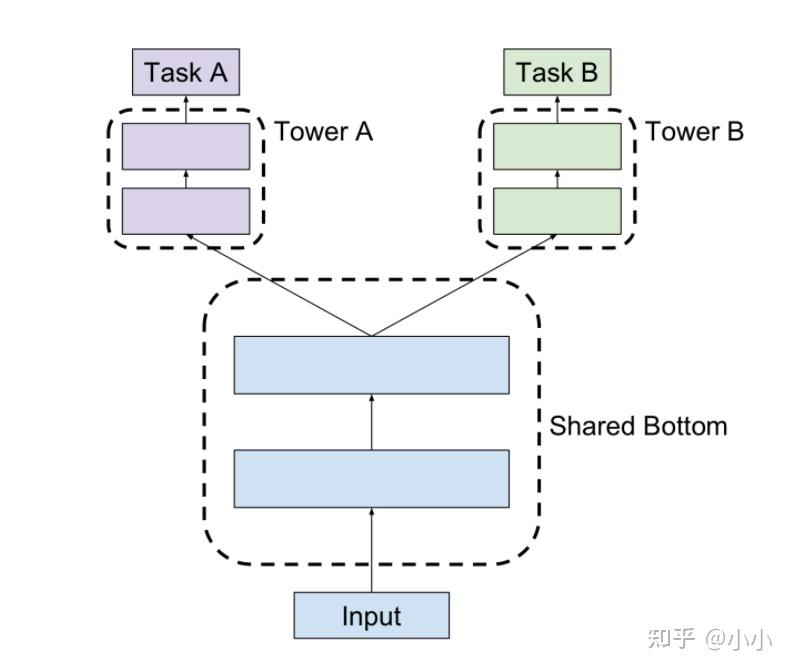
多任务学习(三)硬参数共享 - 知乎
How to choose between clip_grad_norm and BatchNorm2d - PyTorch Forums
模型训练分析-1:Loss以及Grad Norm分析
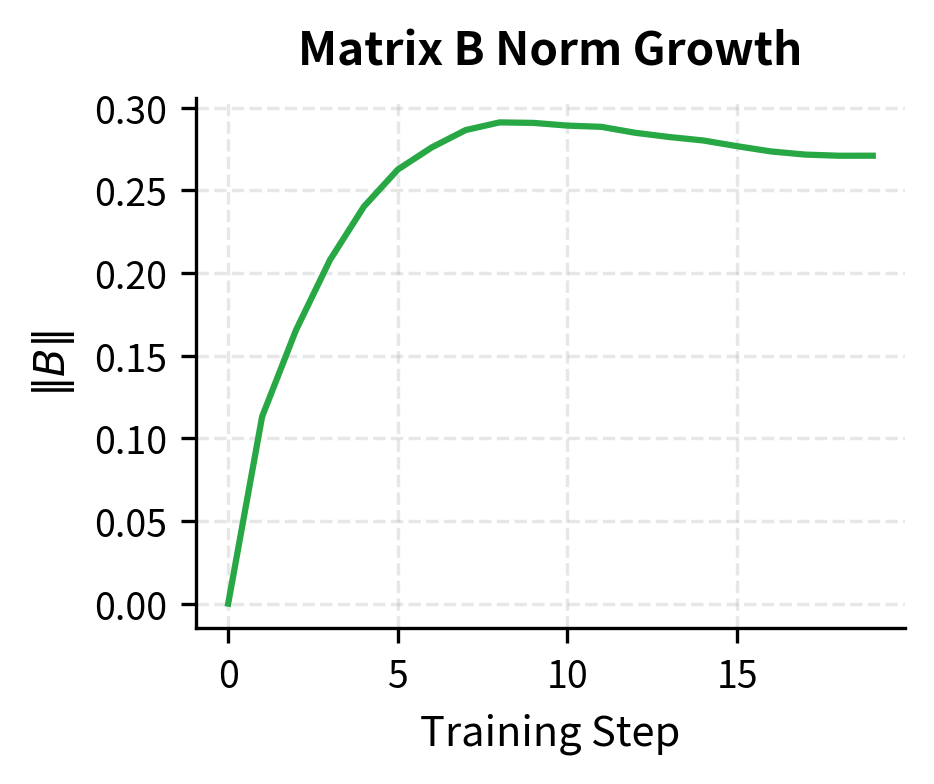
LoRA Mathematics: Low-Rank Adaptation Formulas & Gradients ...
Differentiating Powers of x | AQA GCSE Further Maths Revision Notes 2020
The critic gradient norms in the logarithmic scale during the training ...
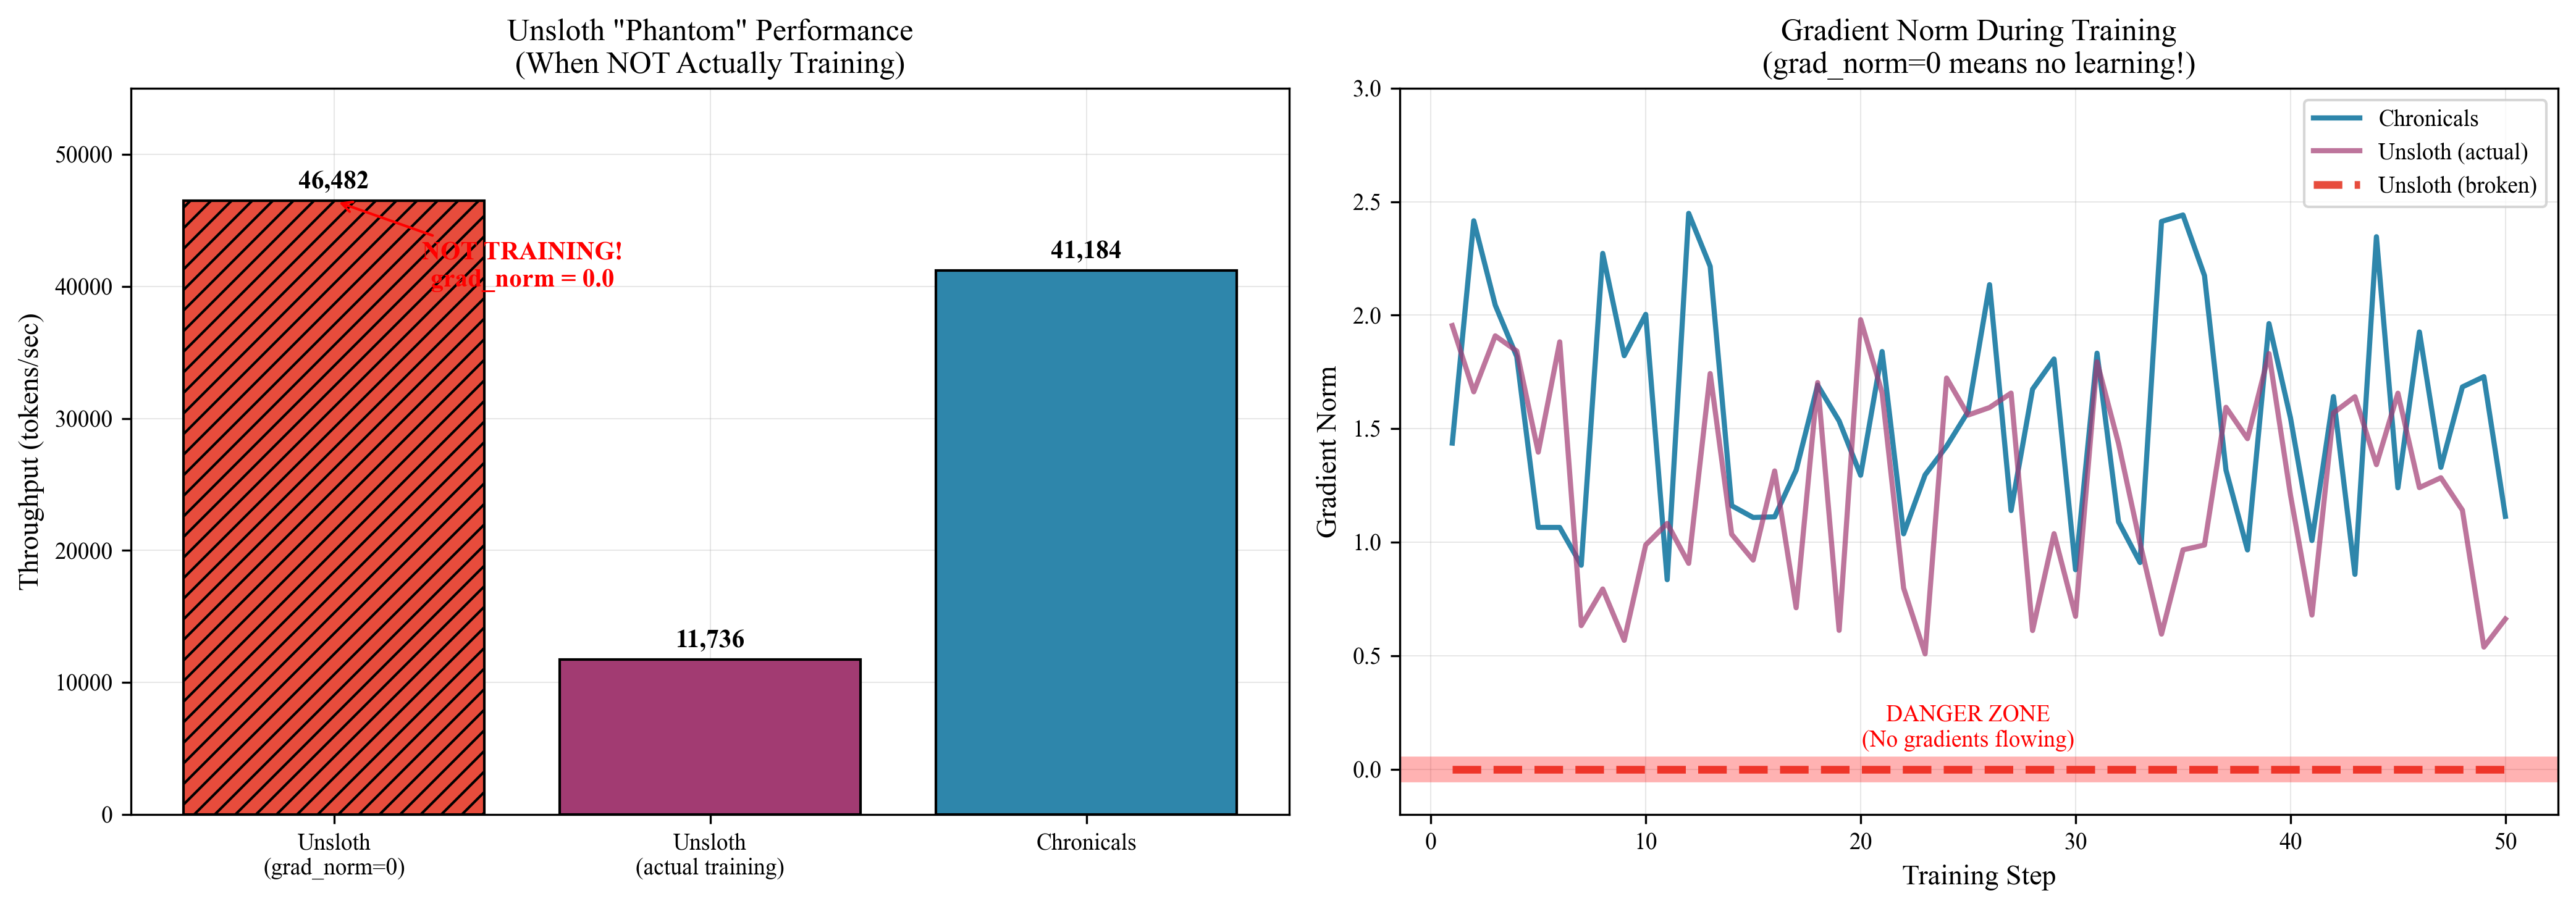
GitHub - Ajwebdevs/Chronicals: High-Performance LLM Fine-Tuning ...