Showing 115 of 115on this page. Filters & sort apply to loaded results; URL updates for sharing.115 of 115 on this page
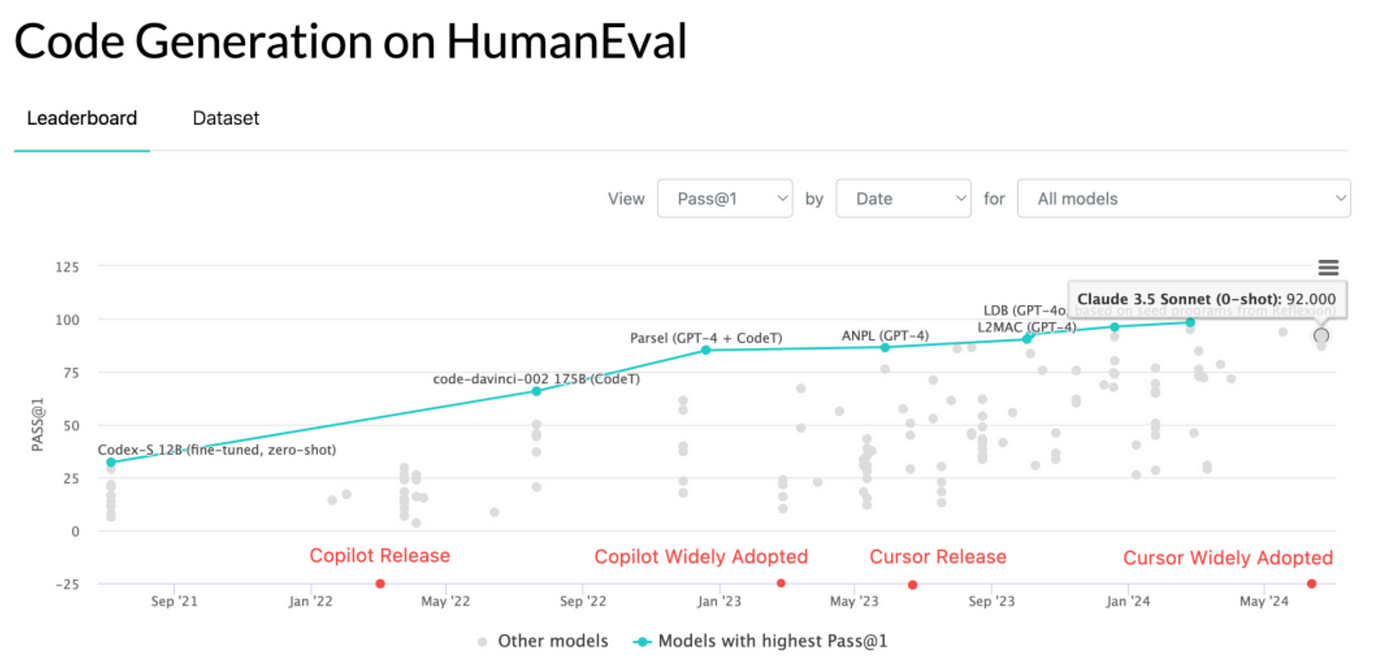
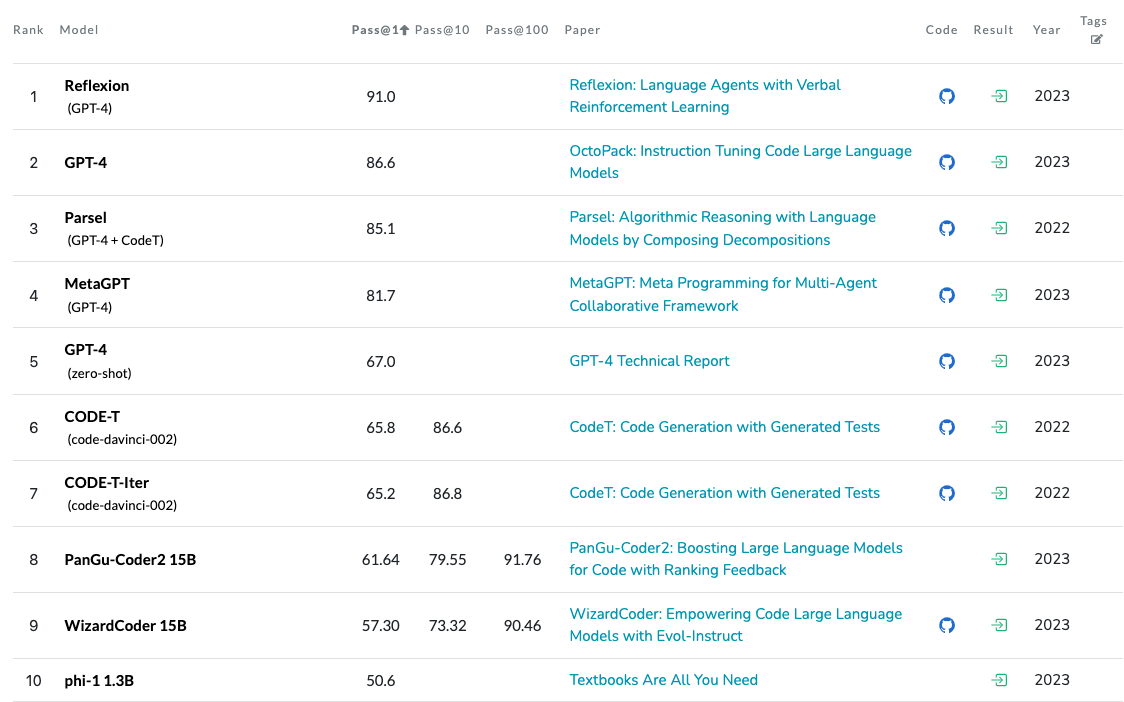
LLMs sorted by Python Eval score. HumanEval for Python, Pass@1.
CodeLlama Python 13B: HumanEval 43.3%, VRAM & Local Guide 2026 | Local ...
Comparative Analysis of AI Models for Python Code Generation: A ...
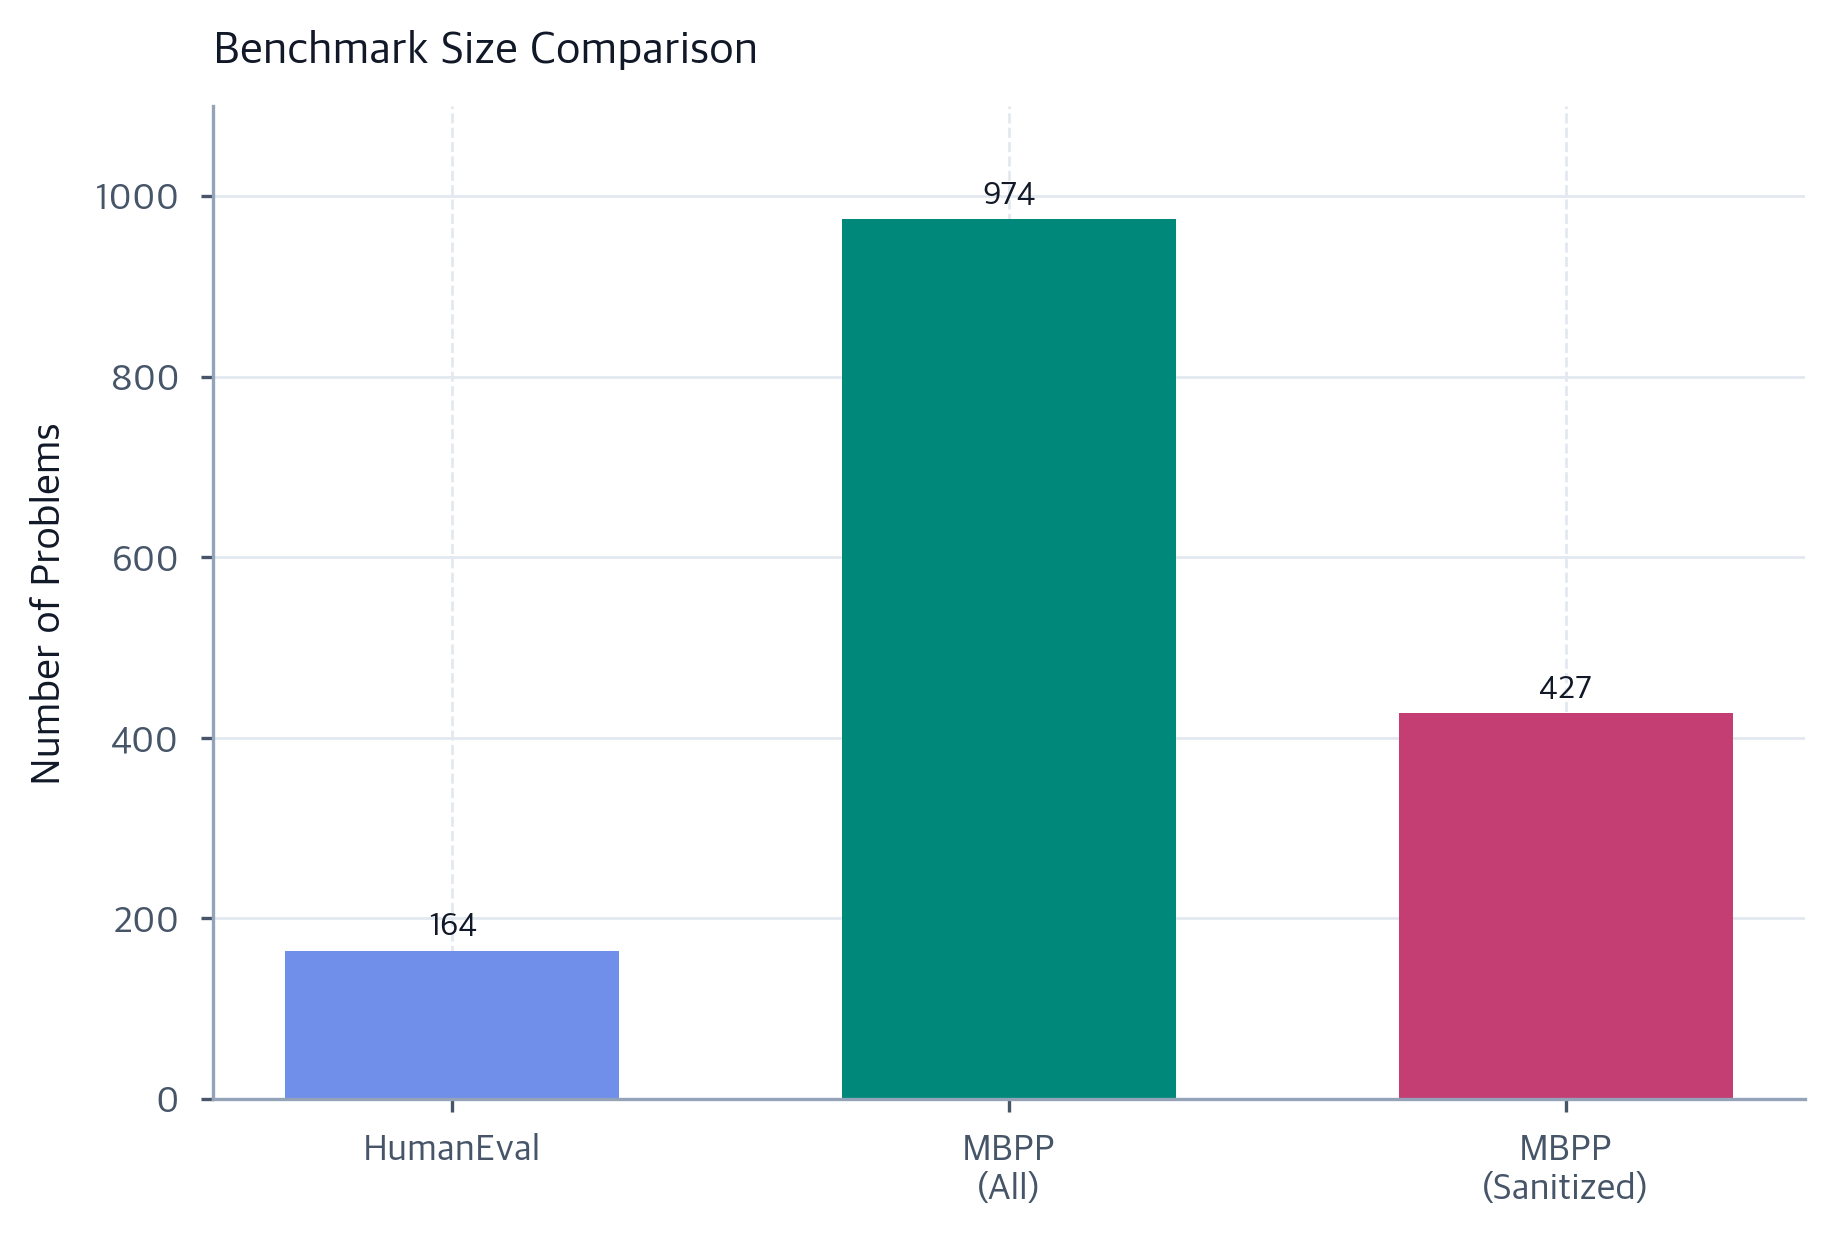
MBPP: Mostly Basic Python Programming Benchmark Guide - Interactive ...
From HumanEval to SWE-bench | Rui Zheng
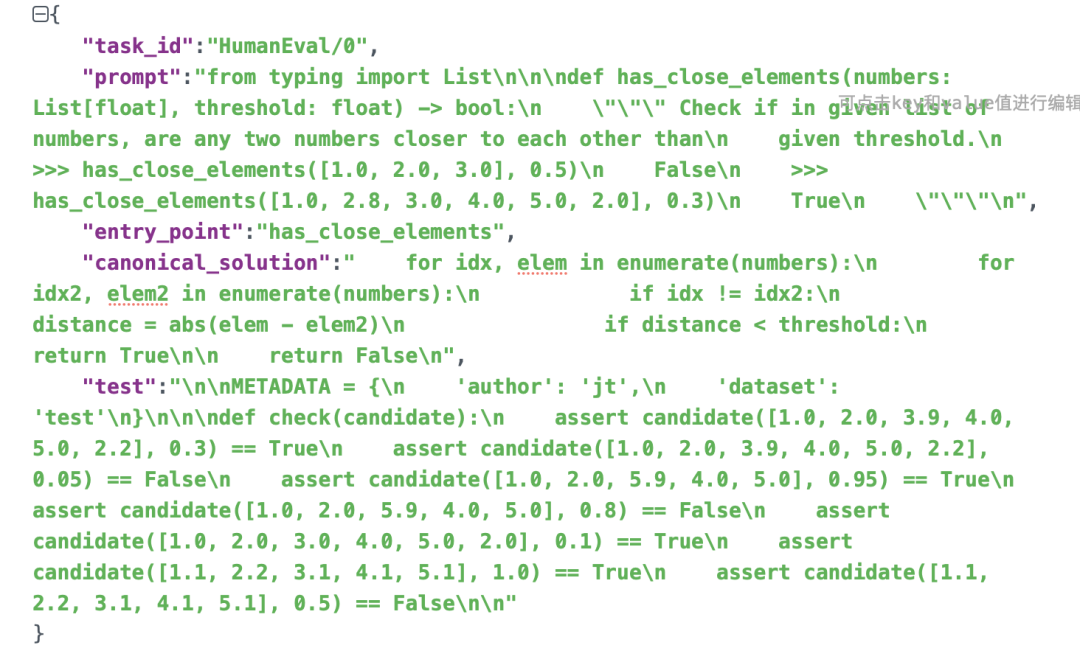
HumanEval - 知乎
(PDF) Comparative Analysis of AI Models for Python Code Generation: A ...
HumanEval Dataset | openai/human-eval | DeepWiki
BigCodeBench: 继 HumanEval 之后的新一代代码生成测试基准HumanEval 是一个用于评估大型语 - 掘金
HumanEval vs. LiveCodeBench: Why the Future of Code Generation Needs a ...
HumanEval showcase 1 illustrating failure case under deadcode insertion ...
HumanEval Benchmark: Evaluating LLM Code Generation Capability
HumanEval Dataset — AaaS Knowledge Index
HumanEval performance of a 350M model on different training sets ...
codefuse-ai/CodeExercise-Python-27k · Similar to humaneval
A visualization of the origin of tokens in an example T=1 HumanEval ...
HumanEval - LLM Benchmark
HumanEval - AI Benchmark Explained | DemandSphere
Humaneval Benchmark: Humaneval Leaderboard – BTIINZ
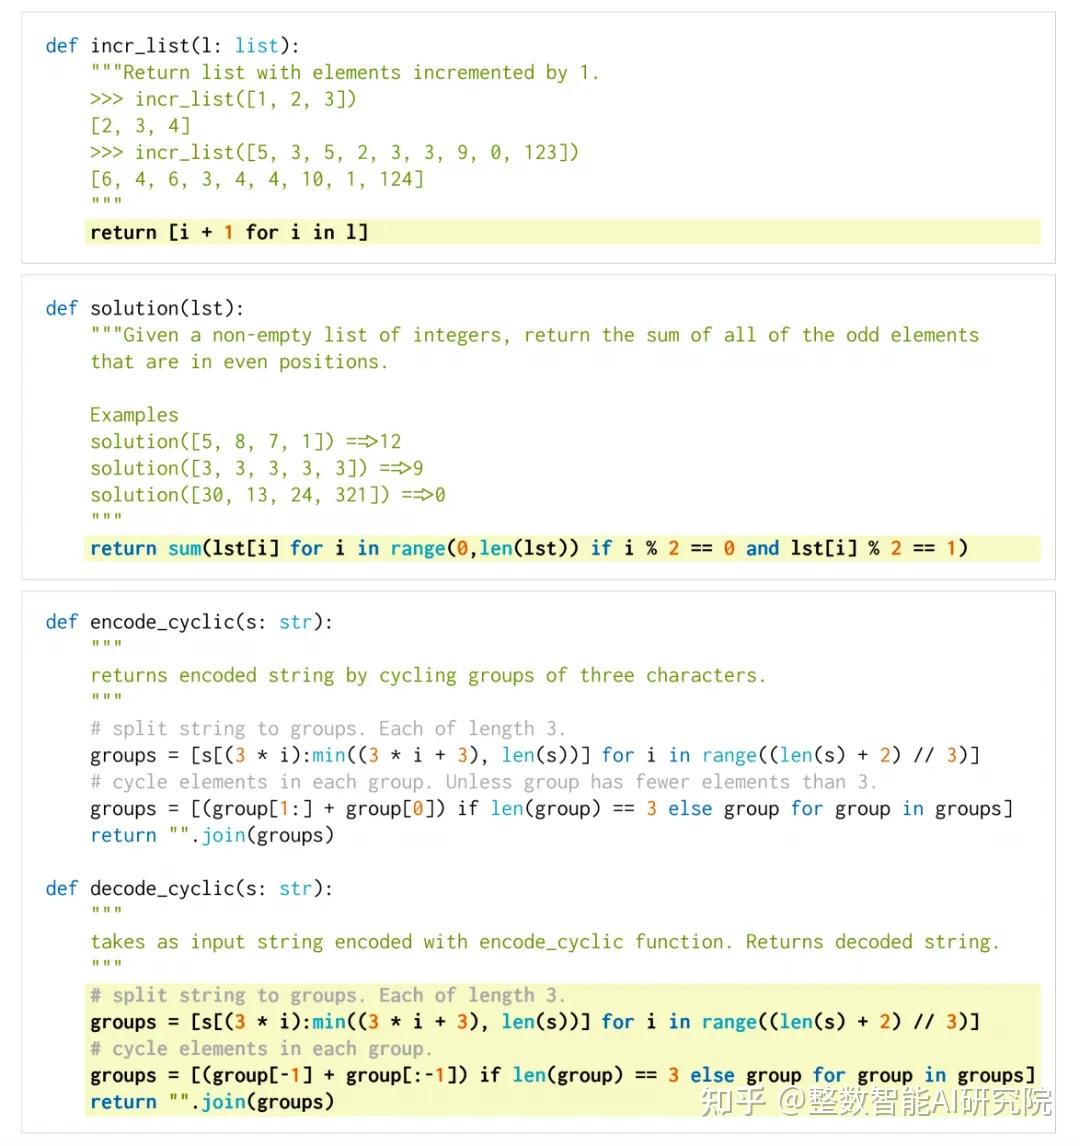
HumanEval 评测分析 - 知乎
HumanEval Benchmark: What It Tells You About Coding Agents | Blaxel Blog
Comparing HumanEval vs. EvalPlus - YouTube
LLM code gen
Mistral AI Launches Codestral Mamba 7B: A Revolutionary Code LLM ...
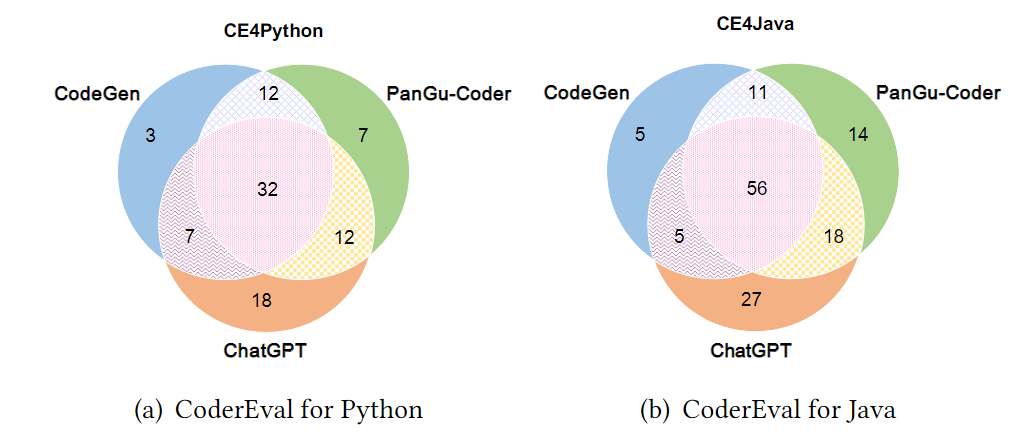
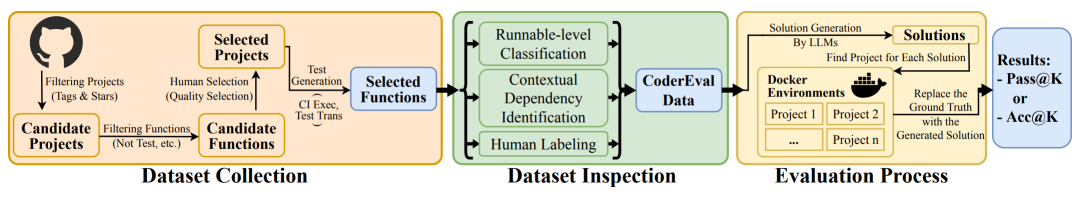
从HumanEval到CoderEval: 你的代码生成模型真的work吗? - 华为云开发者联盟 - 博客园
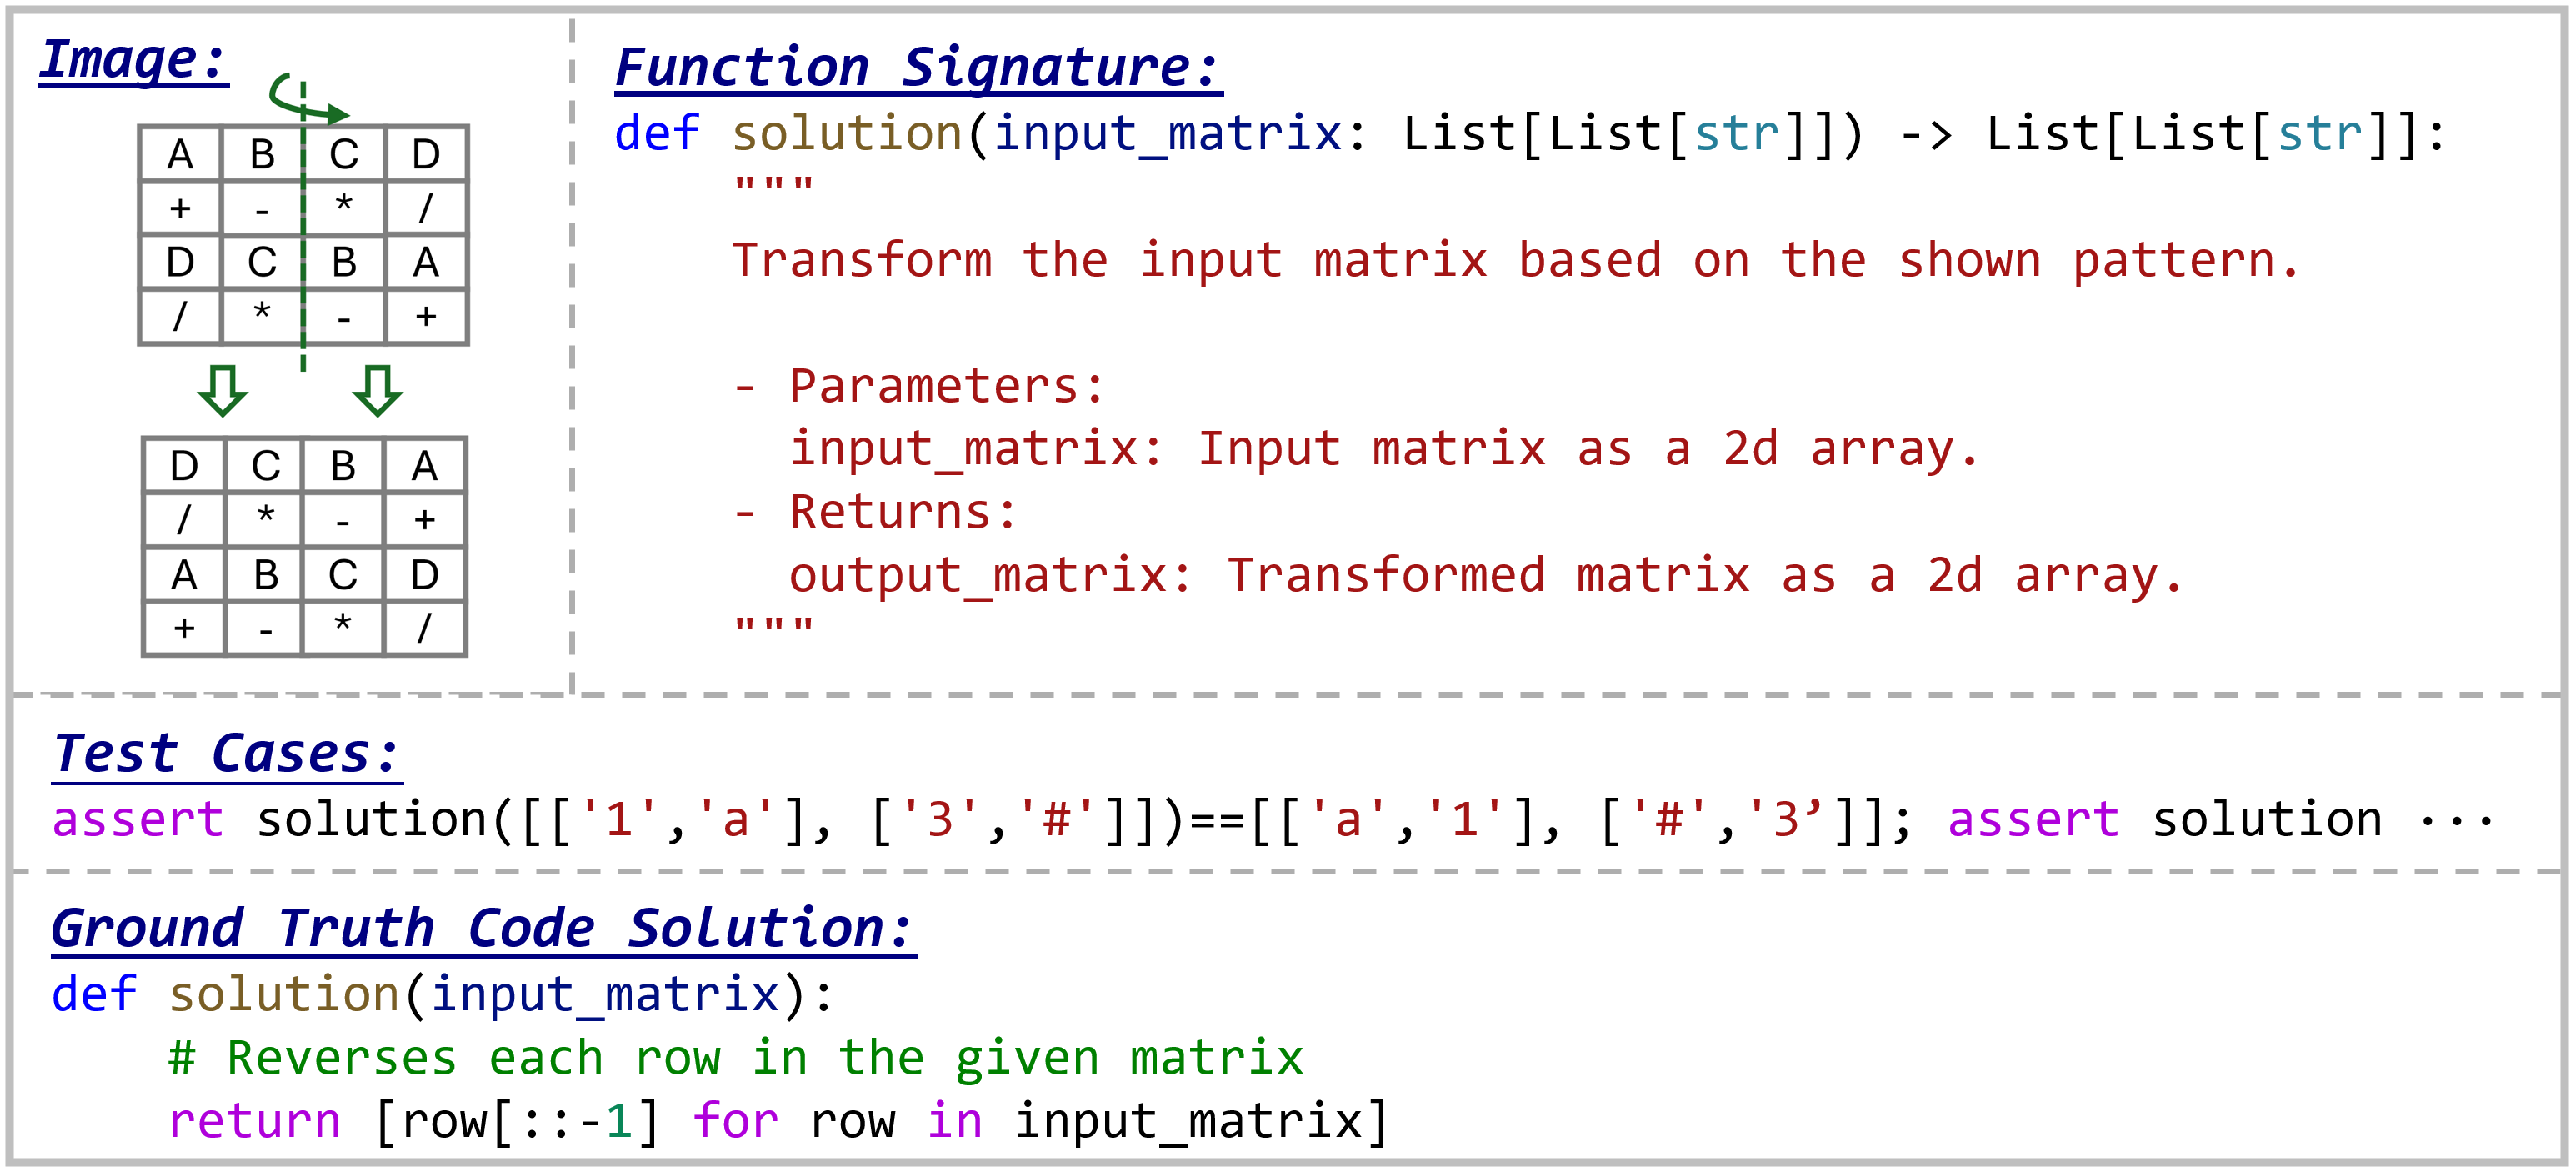
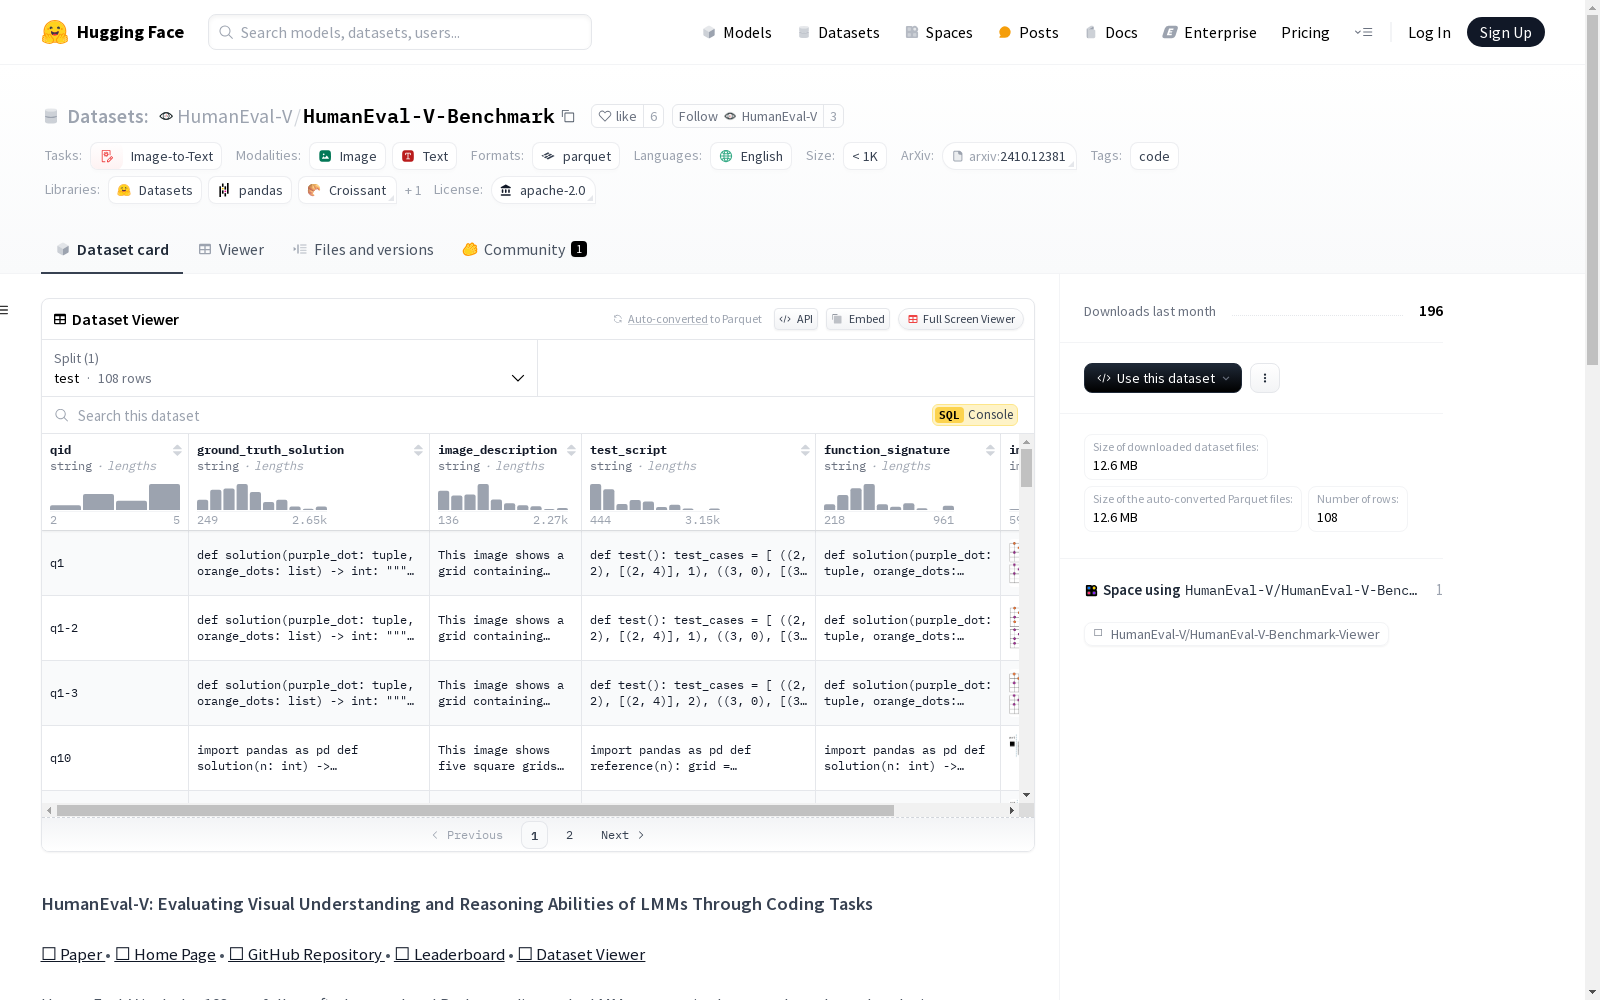
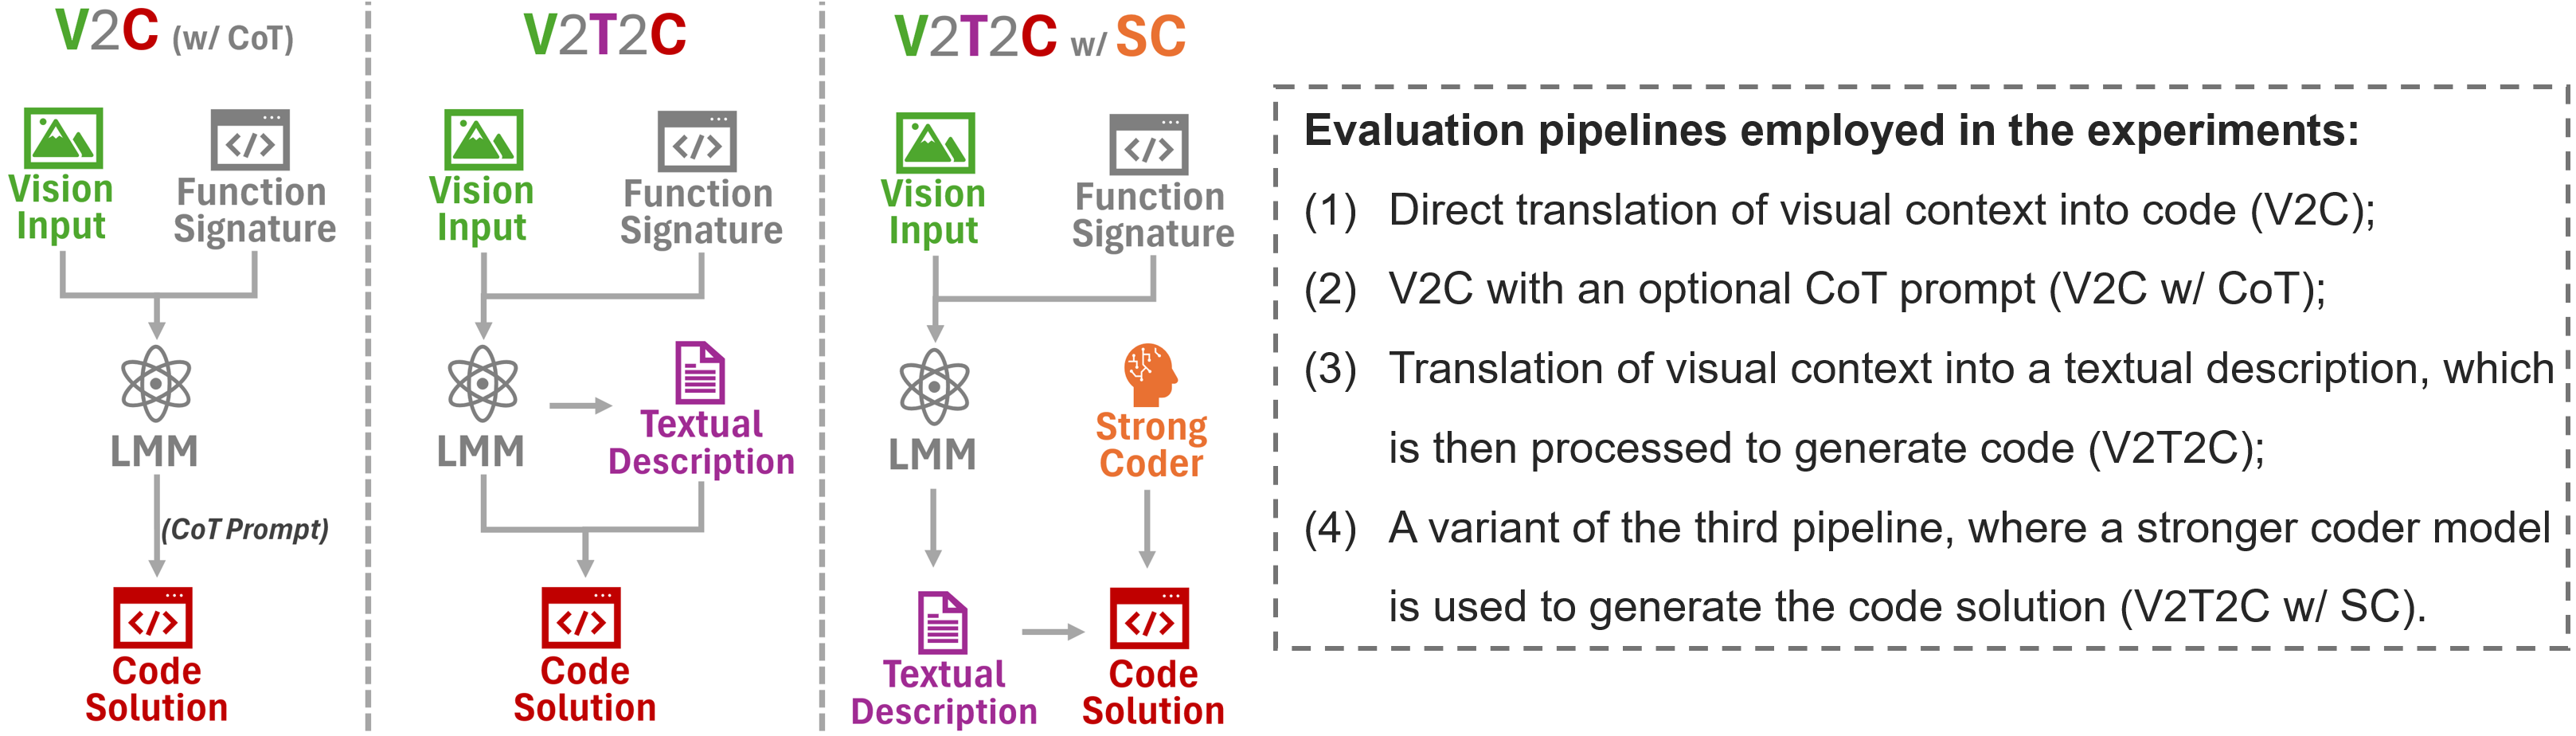
HumanEval-V
模型Evaluation|文本大语言模型评估体系:从能力维度到方法论 - 知乎
openai/openai_humaneval|代码生成数据集|Python编程数据集
How to Interpret HumanEval: Can this AI Actually Code?
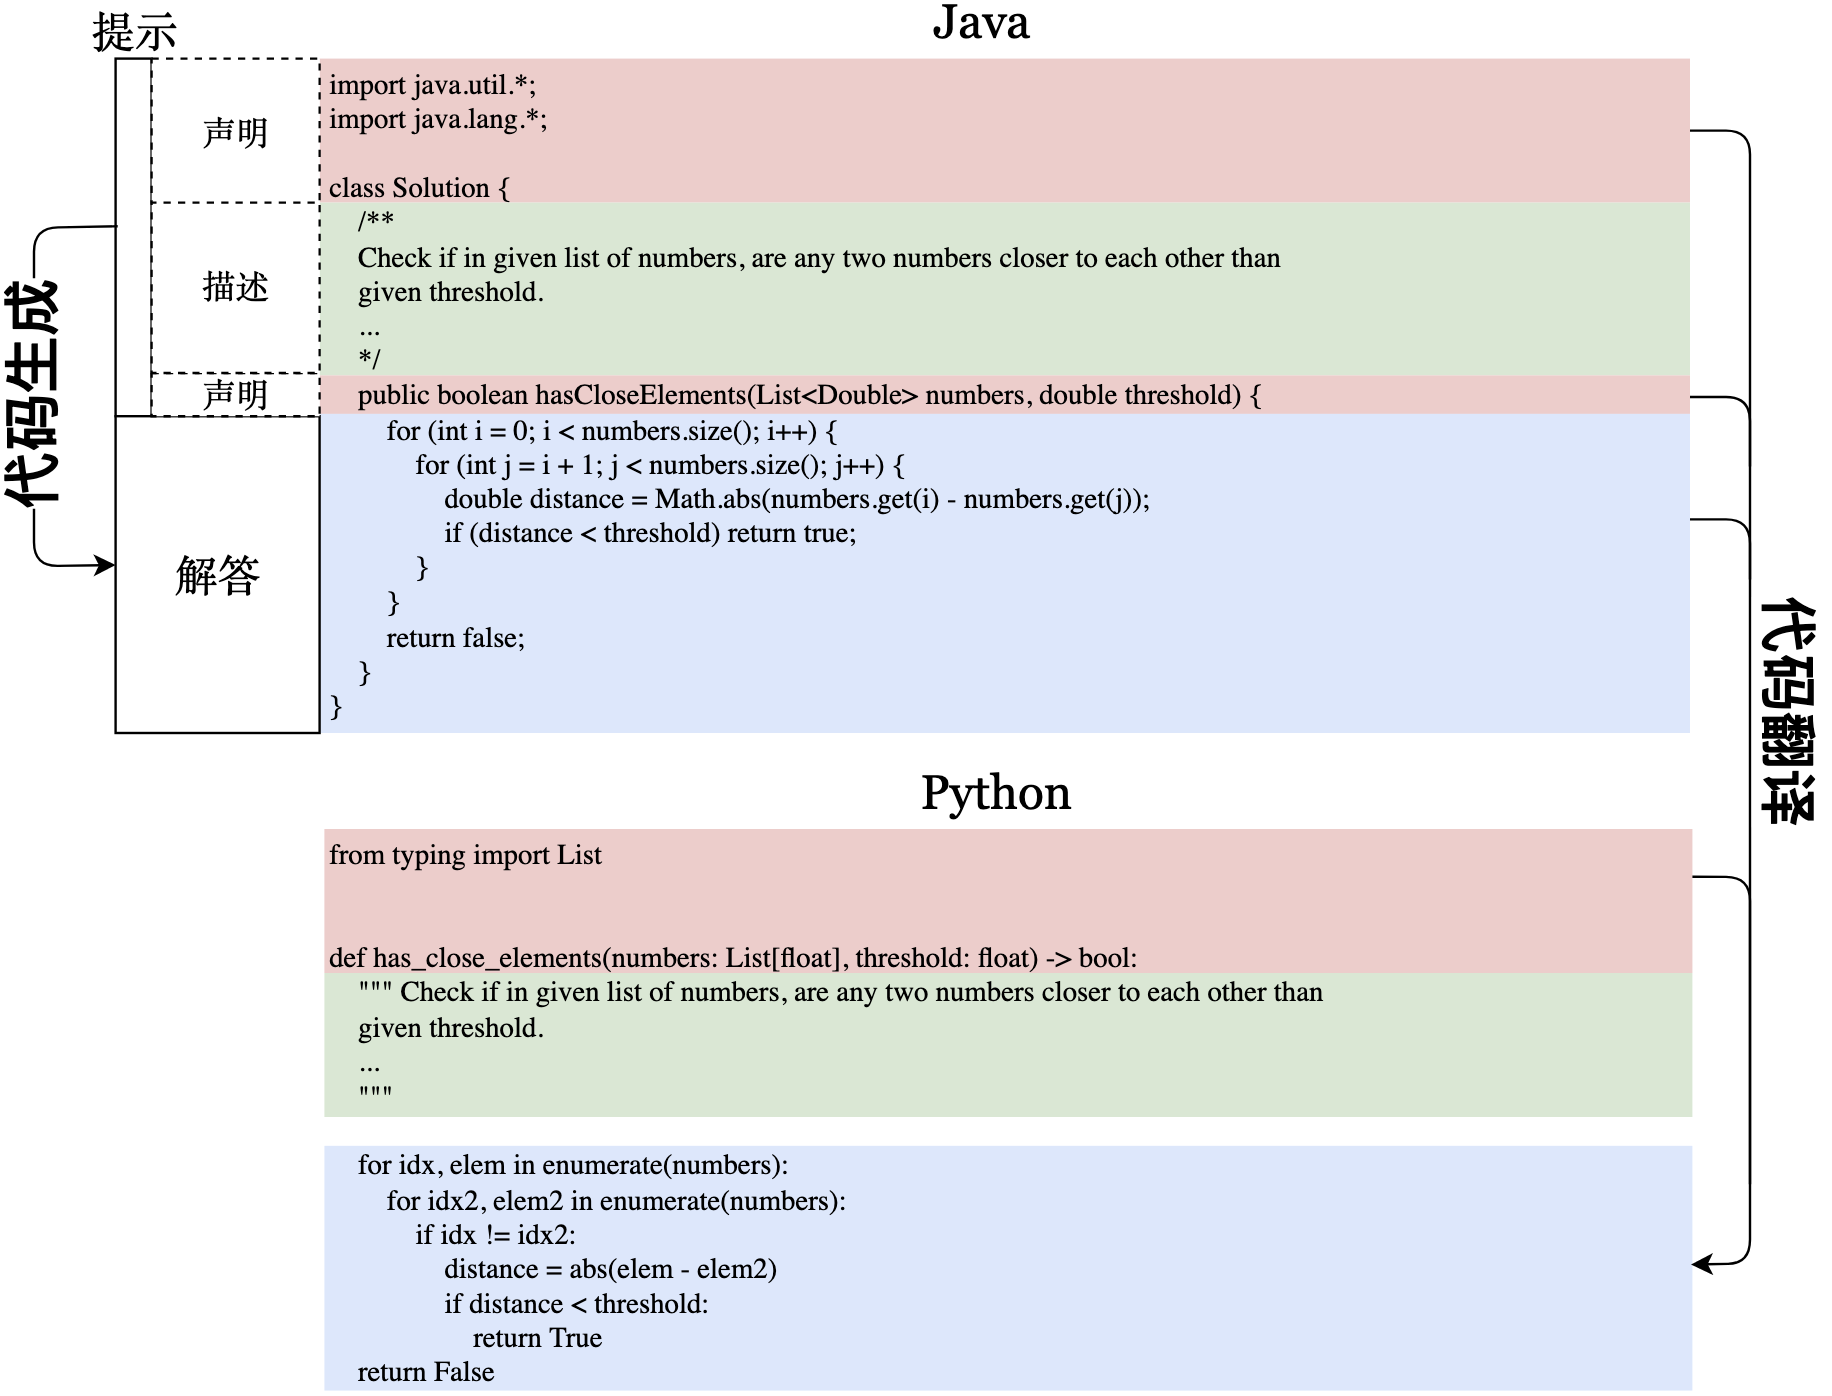
【论文】智源CodeGeeX + HumanEval评测集_humanevalx-CSDN博客
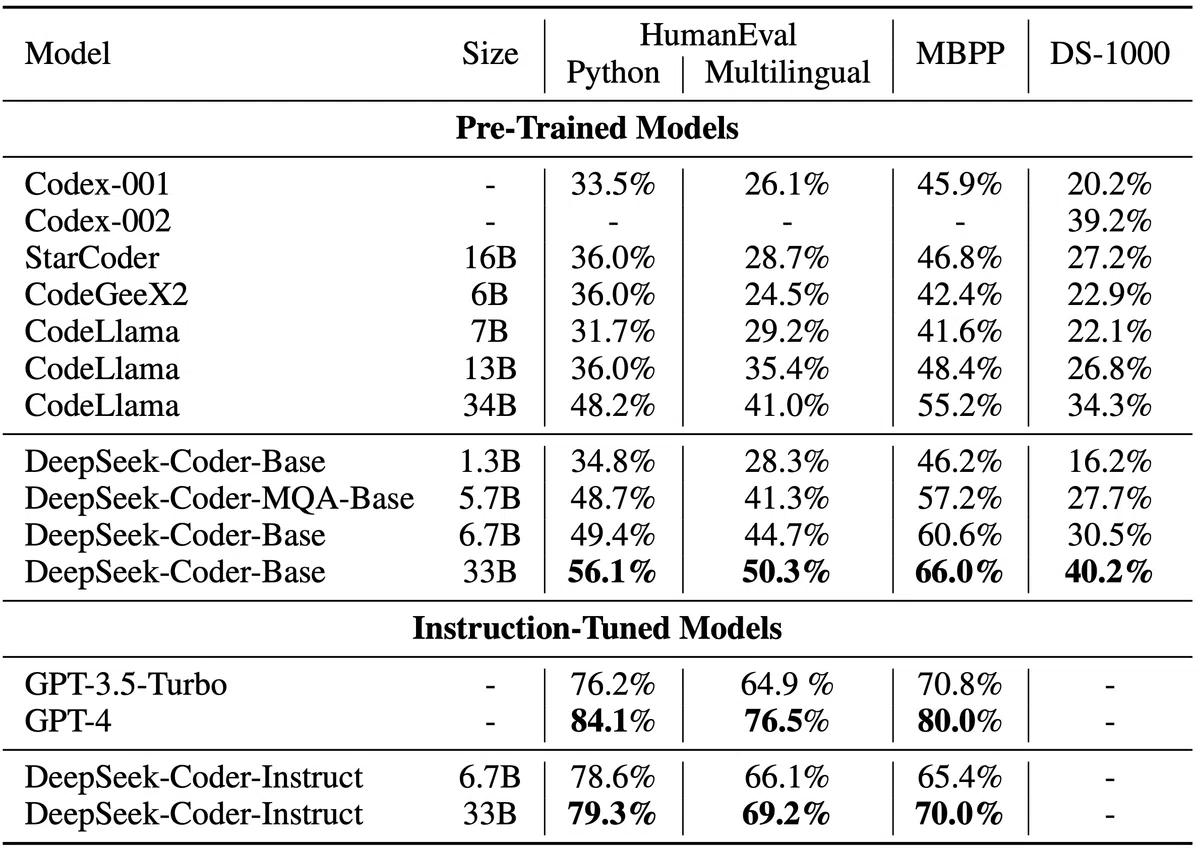
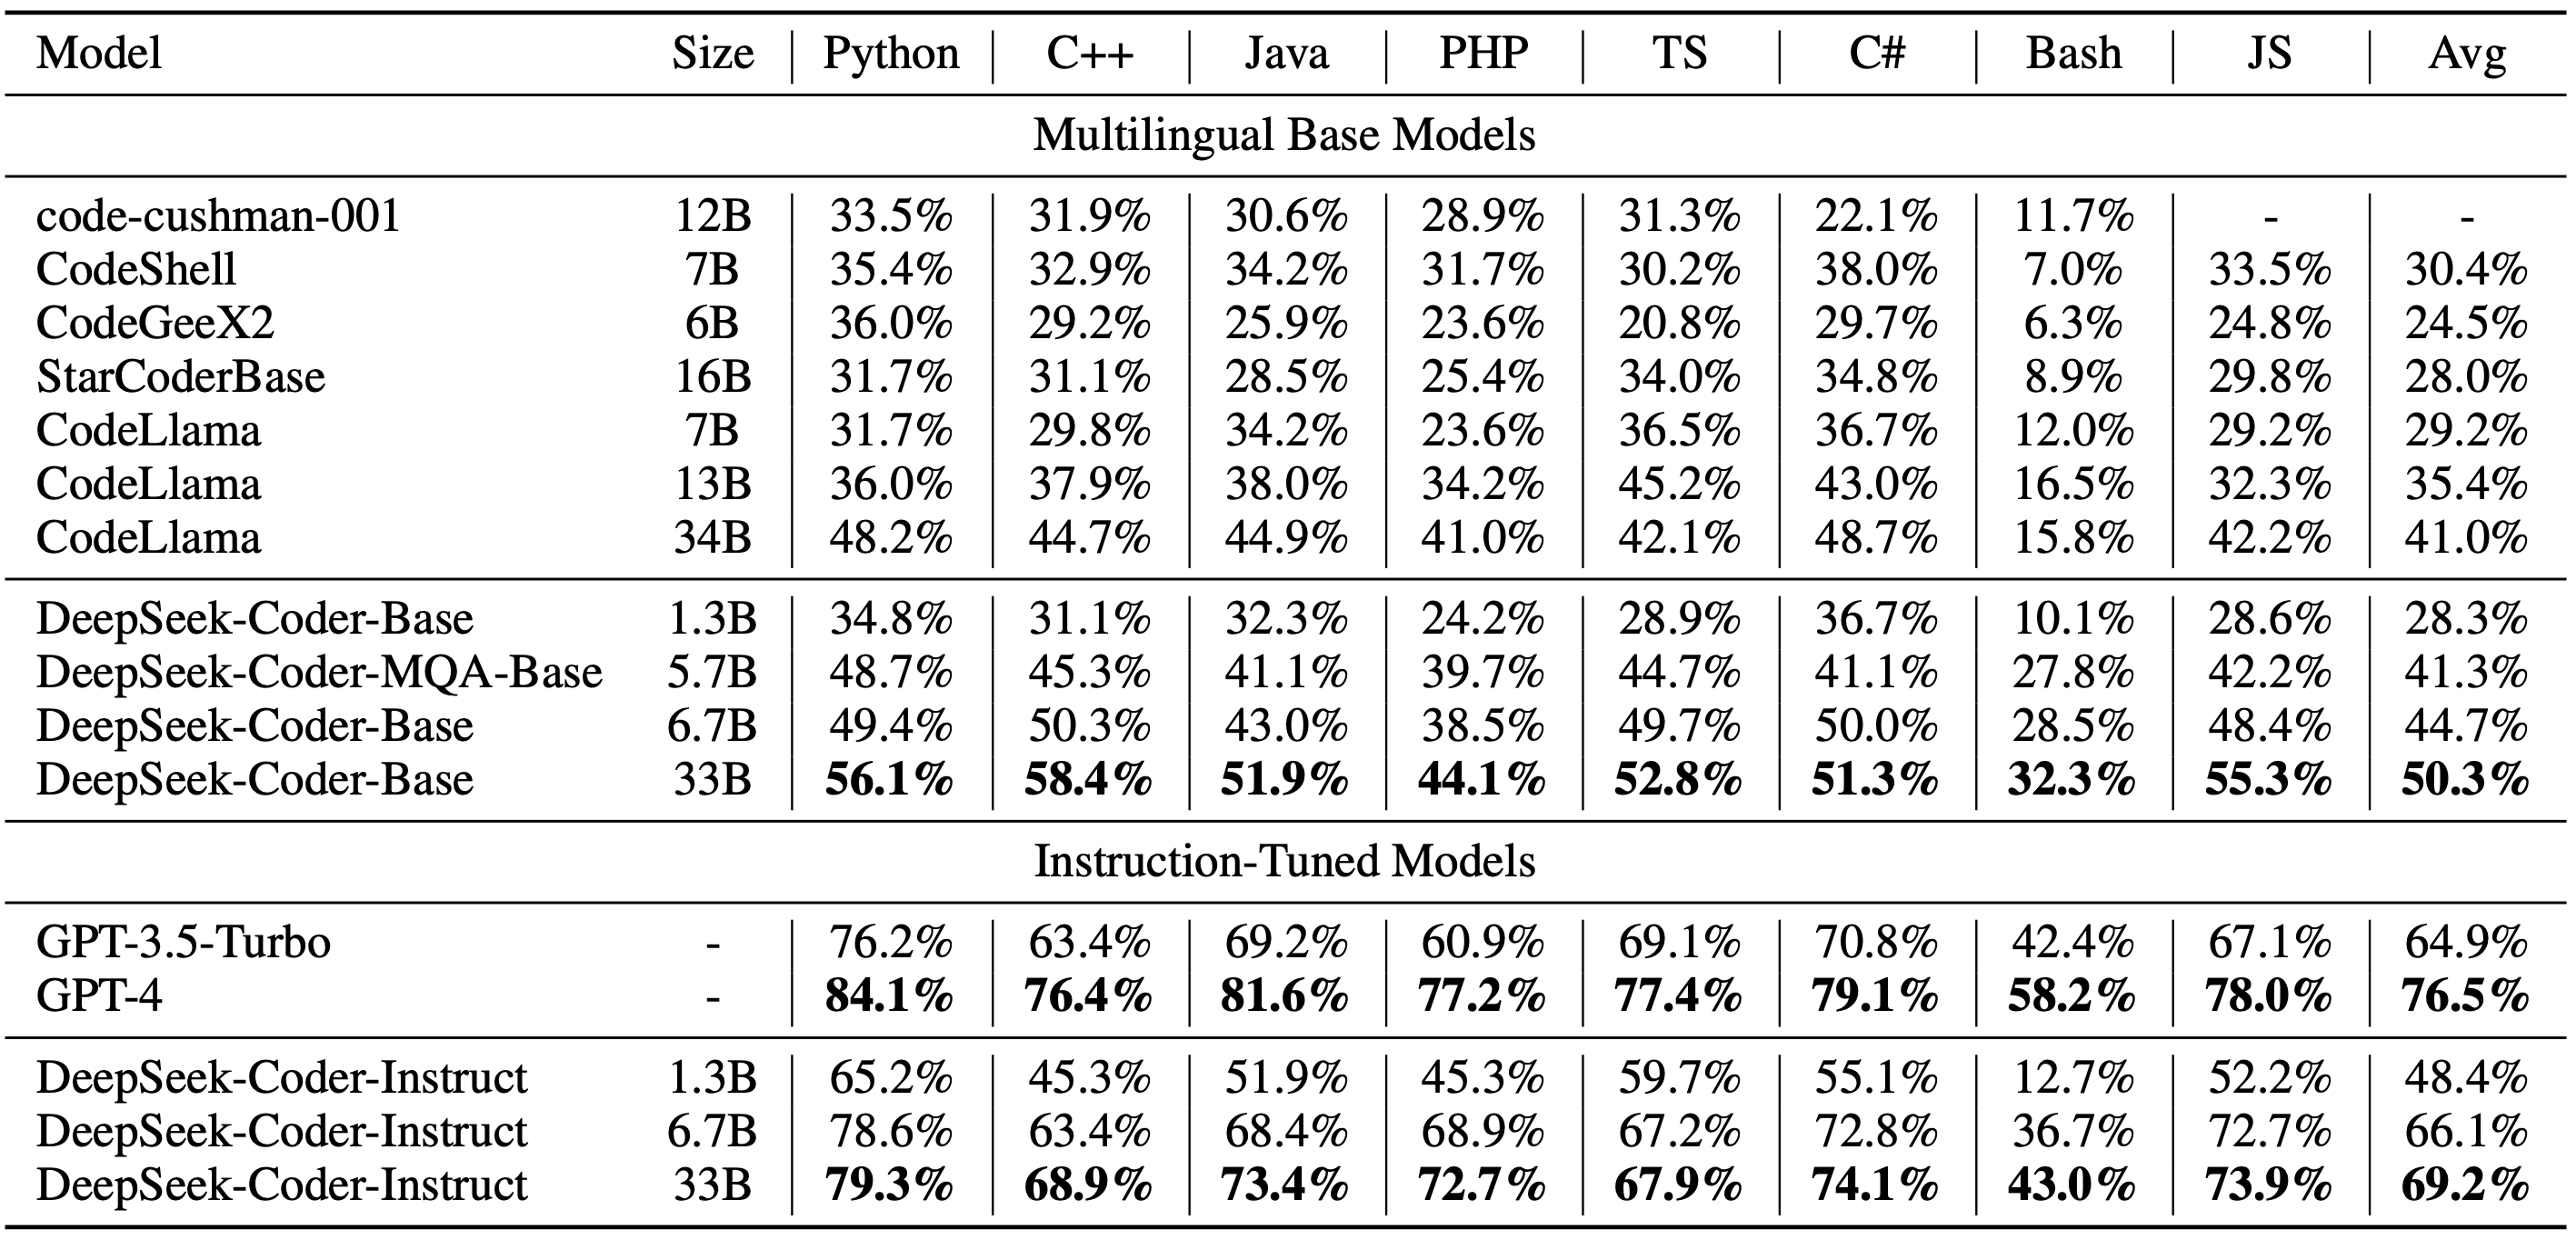
DeepSeek Coder 技術ドキュメント|LeN|文系AIアドバイザー
DeepSeek Coder
CodeGeeX: 多语言代码生成模型
Alex J Type | Future Trainee Solicitor @ Milbank LLP
andy-yang/humaneval-rephraser-python-7b · Hugging Face
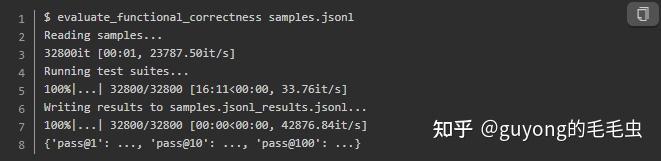
HumanEval是如何进行代码评估的:从数据构成、评估逻辑到pass@k指标计算 - 智源社区
How to use LLMs effectively - About Objects
Optimize and deploy LLMs for production with OpenShift AI | Red Hat ...
rubricreward/HumanEval-XL-Python · Datasets at Hugging Face
xin1997/humaneval-x-python_all_only_input · Datasets at Hugging Face
HumanEval: A Benchmark for Evaluating LLM Code Generation Capabilities ...
LLM benchmark
HumanEval-X-腾讯云开发者社区-腾讯云
帮你写代码的大模型CodeGeeX!-CSDN博客
大代码模型排行榜 - Smolagents
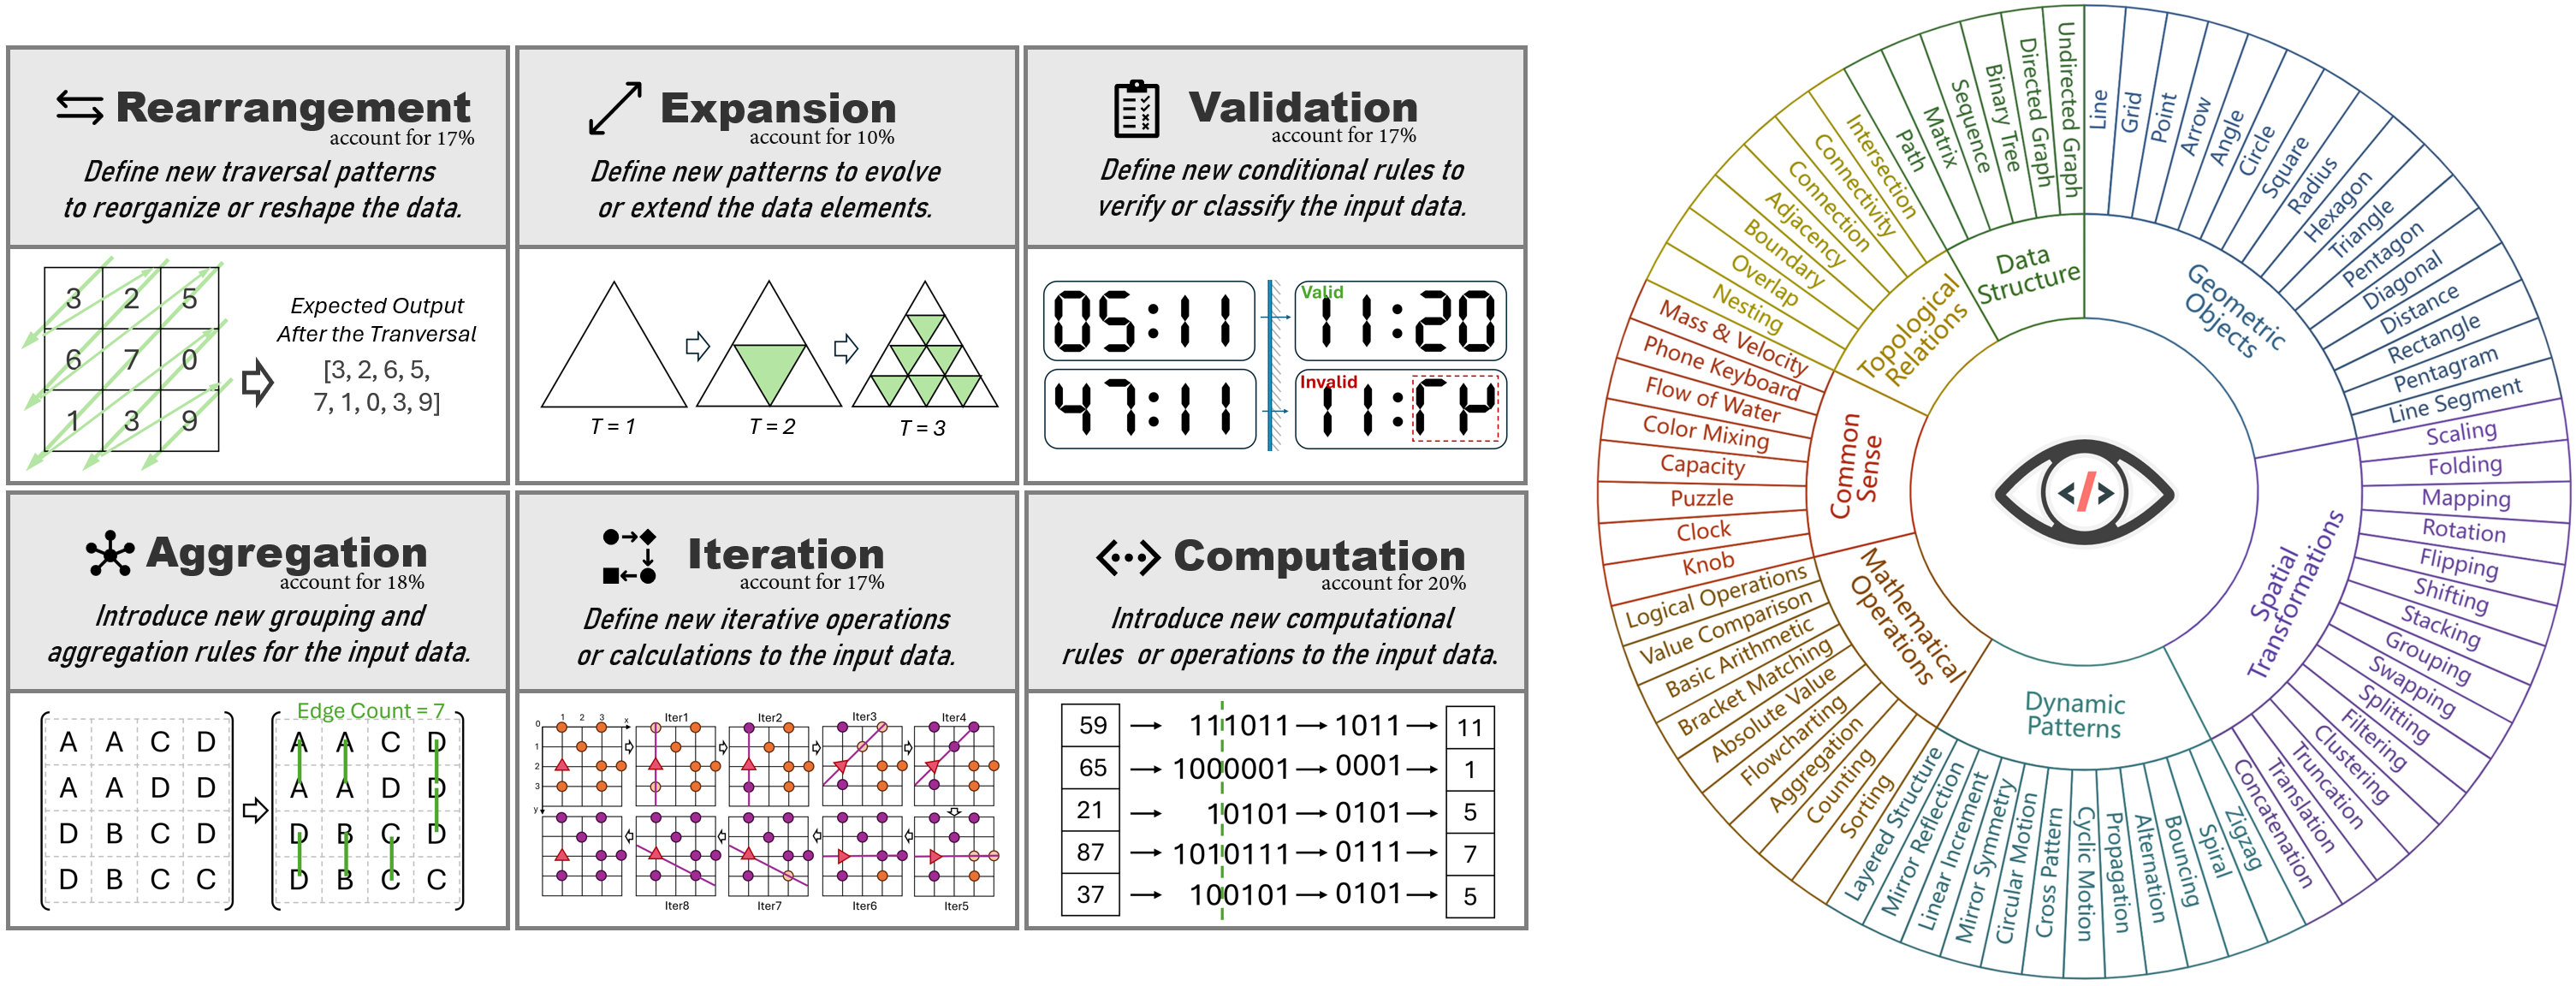
HumanEval-V-Benchmark|模型评估数据集|视觉理解数据集
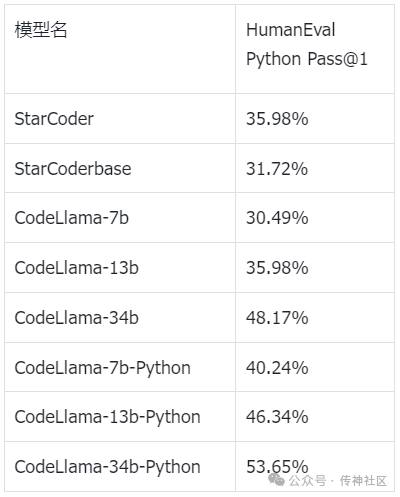
发布一天,Code Llama代码能力突飞猛进,微调版HumanEval得分超GPT-4
GitHub - brandaobrandisborges/openai-human-eval: Code for the paper ...
解密代码模型StarCoder & CodeLlama - 智源社区
CodeGeeX: A Pre-Trained Model for Code Generation with Multilingual ...
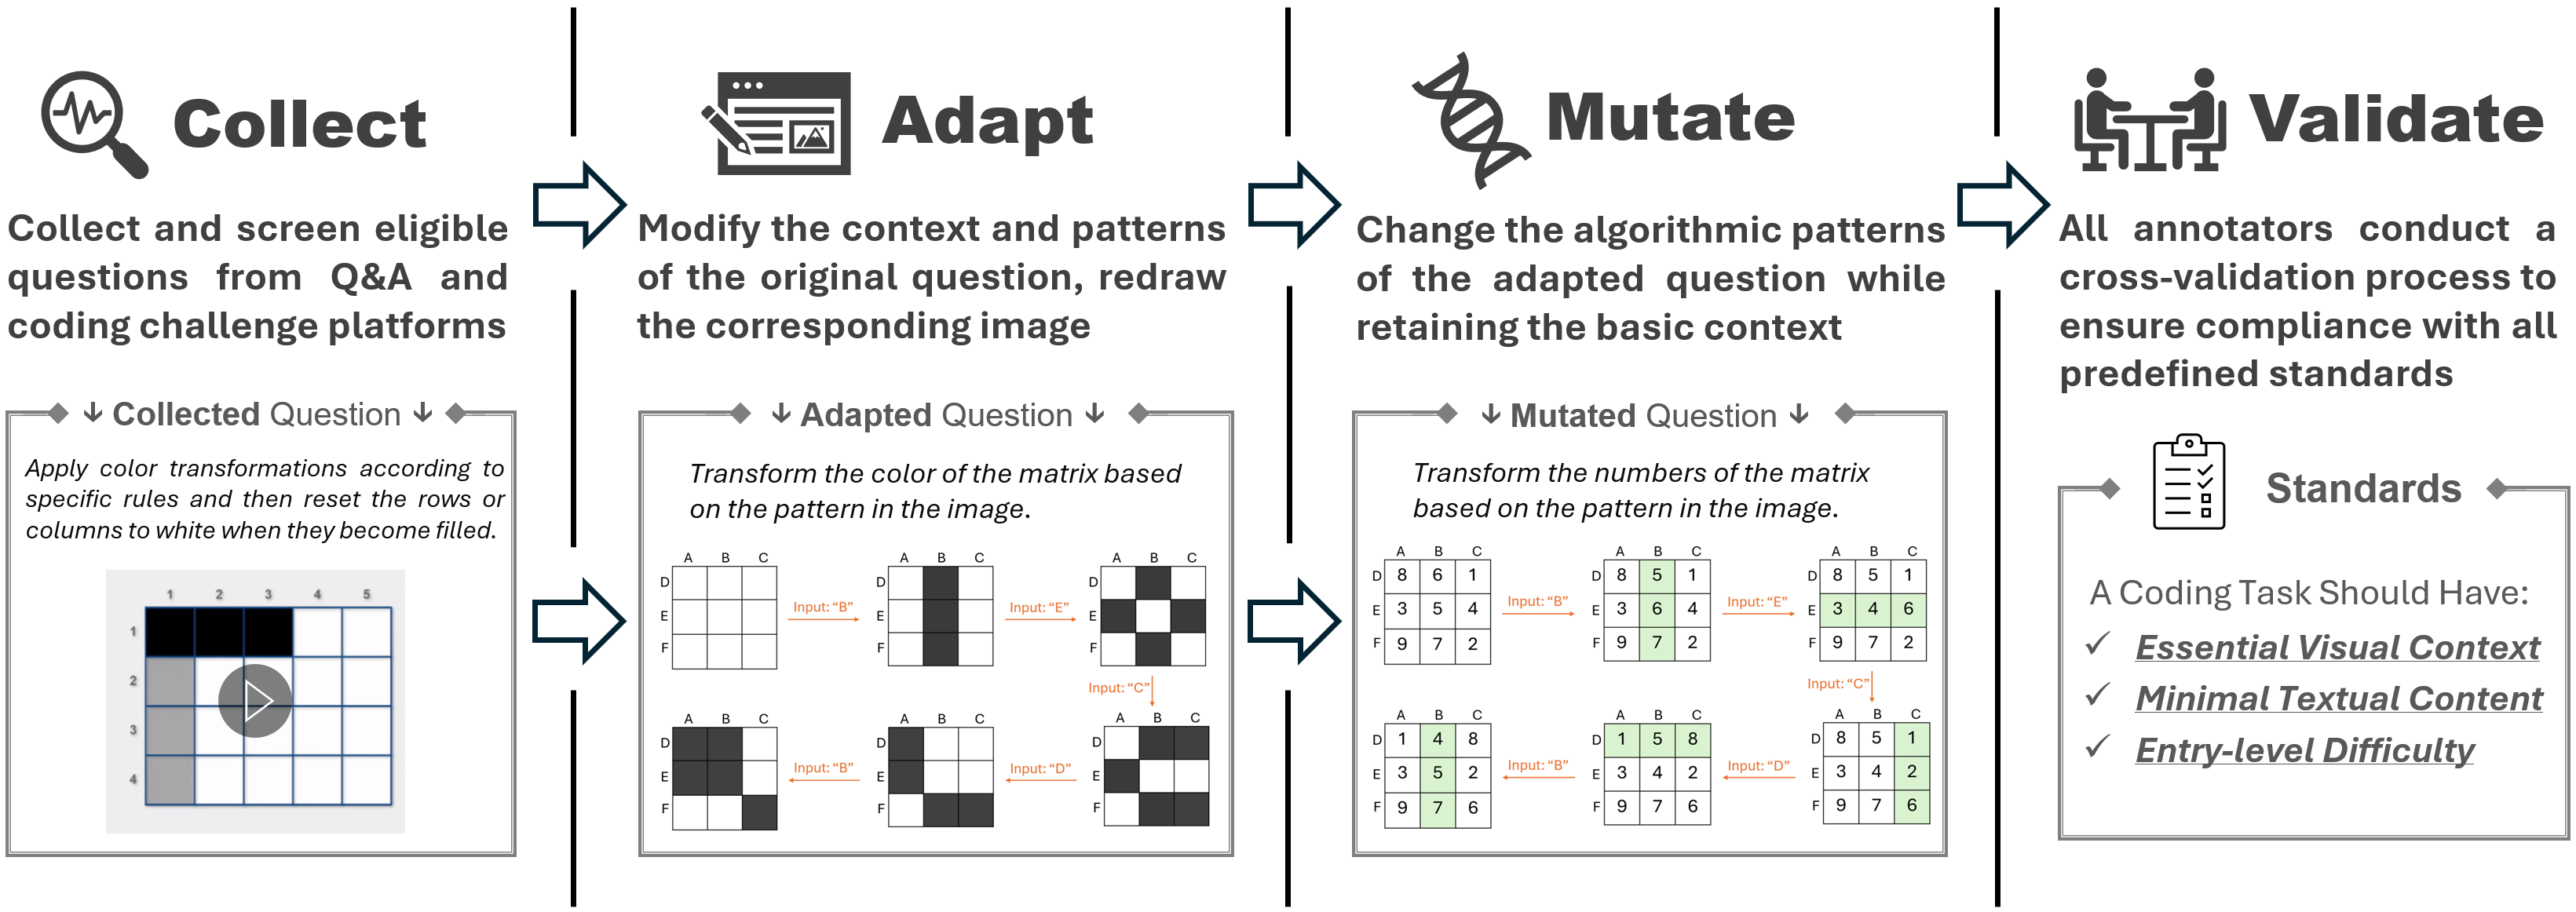
HumanEval-V: Evaluating Visual Understanding and Reasoning Abilities of ...
从HumanEval到CoderEval: 你的代码生成模型真的work吗? - 知乎
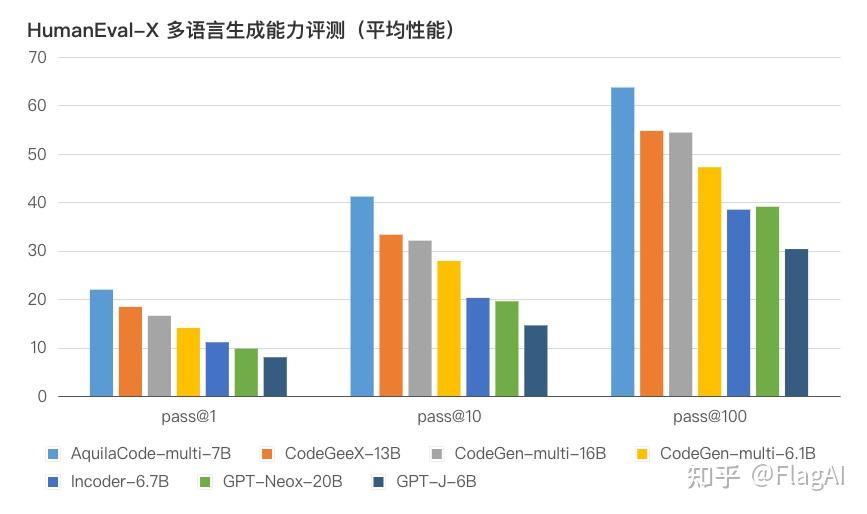
悟道·天鹰 AquilaCode升级多语言代码生成,多项指标领先,开源可商用 - 知乎
LLM Agents - Miguel's Blog
TheBloke/WizardCoder-Python-34B-V1.0-GGUF · This model looks insanely ...
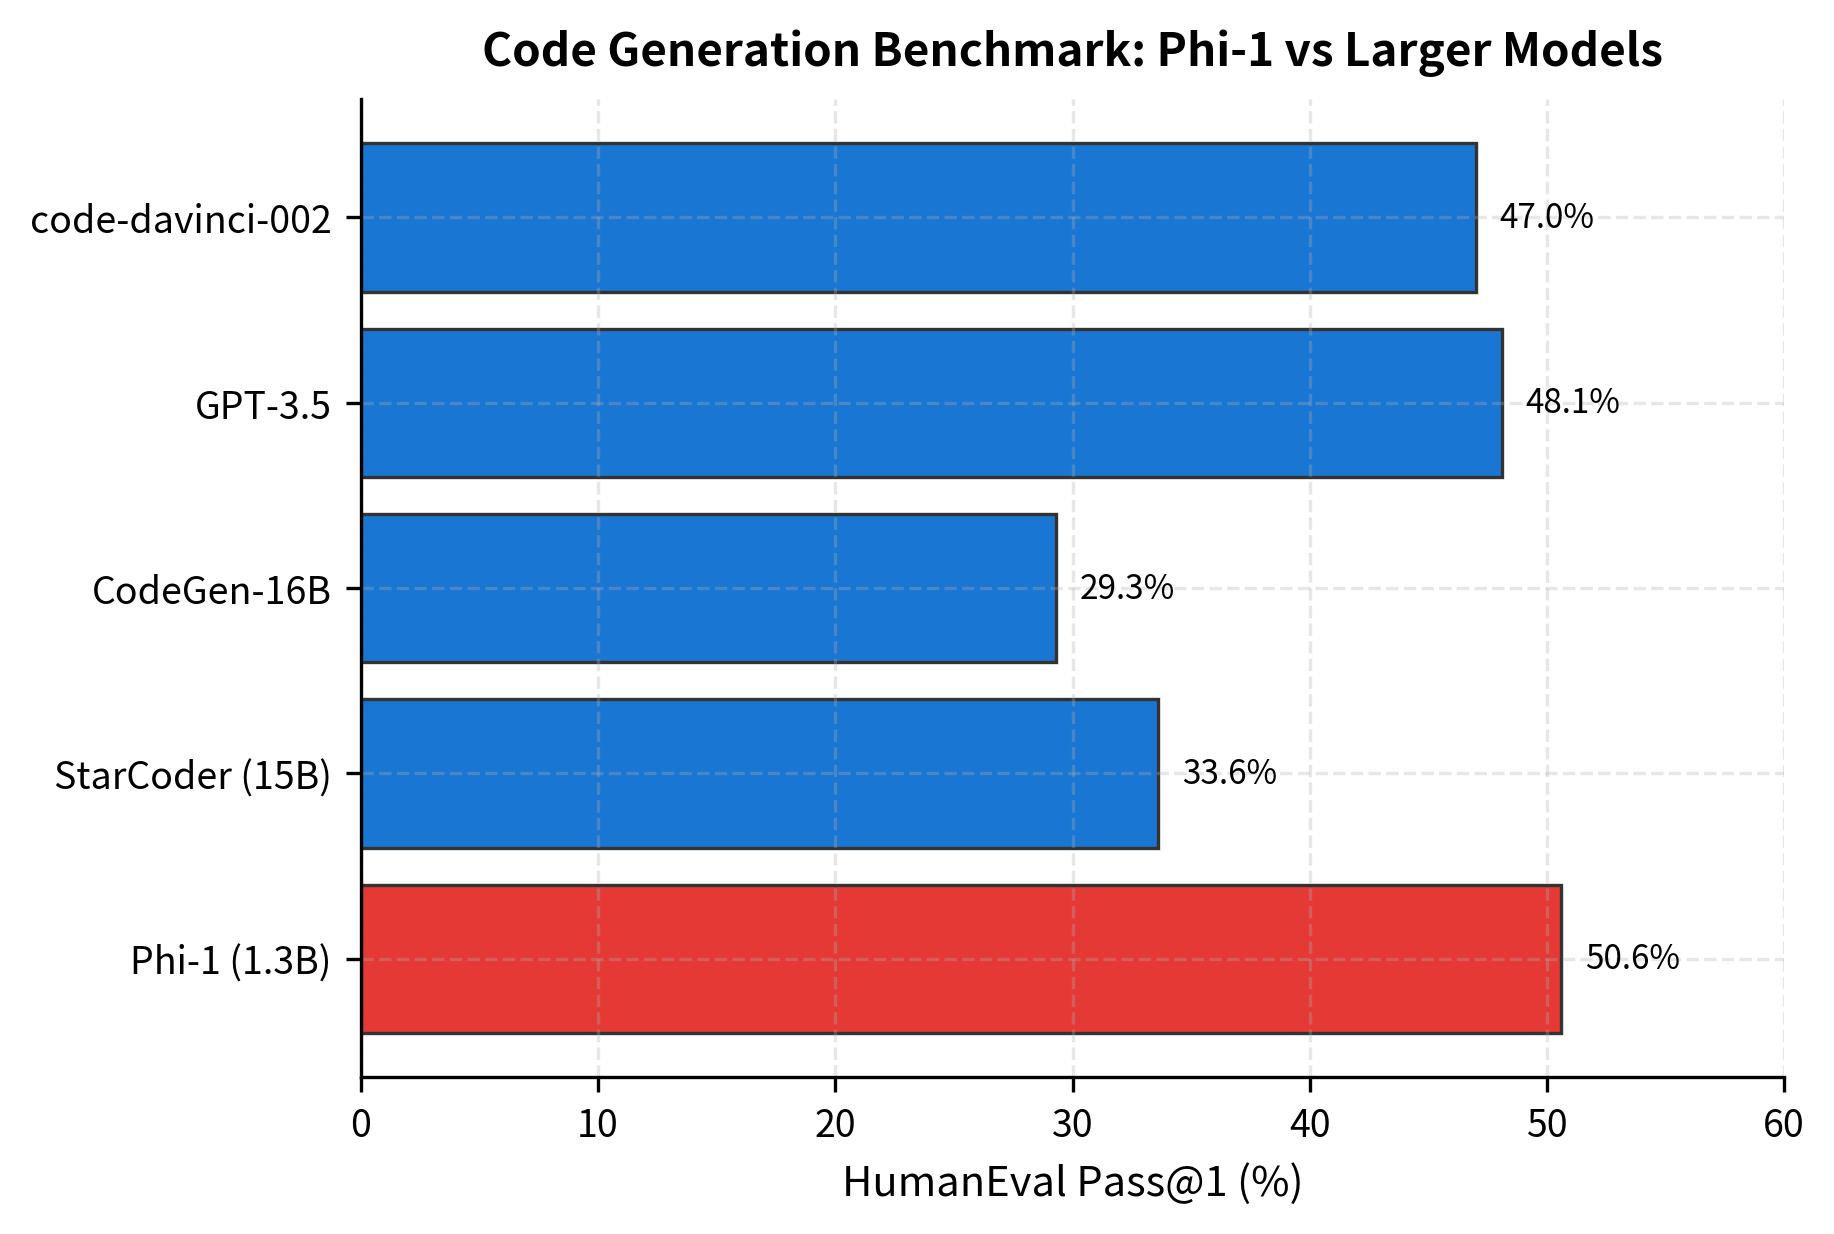
Phi Models: How Data Quality Beats Model Scale - Interactive | Michael ...
Mistral announces Codestral, its first programming focused AI model ...
On the Uncertainty of Large Language Model-Based Multi-Agent Systems
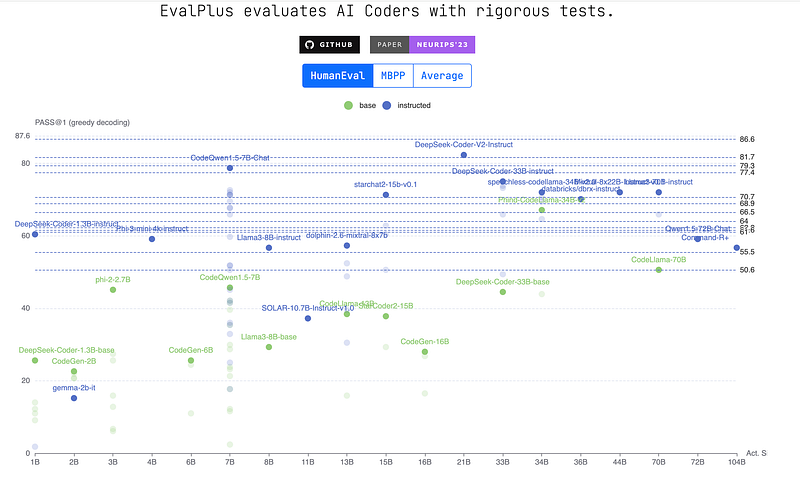
LLM评测一:HumanEval+ - 知乎
CodeGenCrusaders
Evaluation & Datasets — State of Open Source AI Book
Paper page - HumanEval-V: Evaluating Visual Understanding and Reasoning ...
HumanEval.org - AI Performaces, Human Evaluations
End-to-End Secure Evaluation of Code Generation Models | Databricks Blog
HumanEval-X Dataset - Papersgraph
HumanEval: Code Generation | openai/simple-evals | DeepWiki
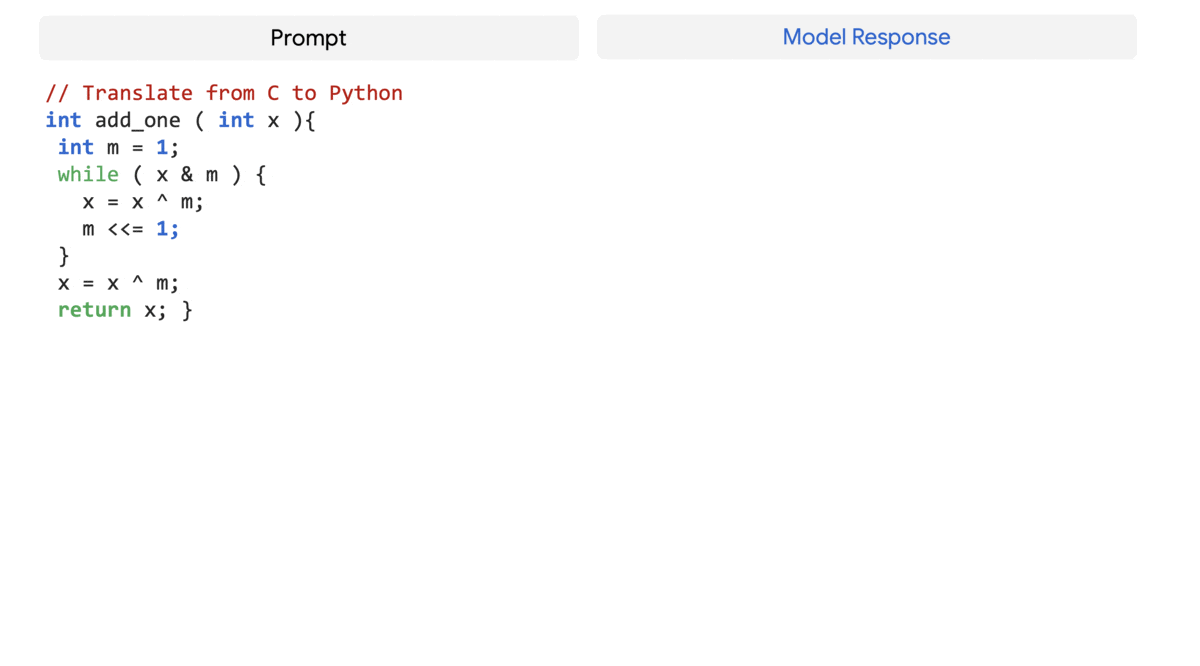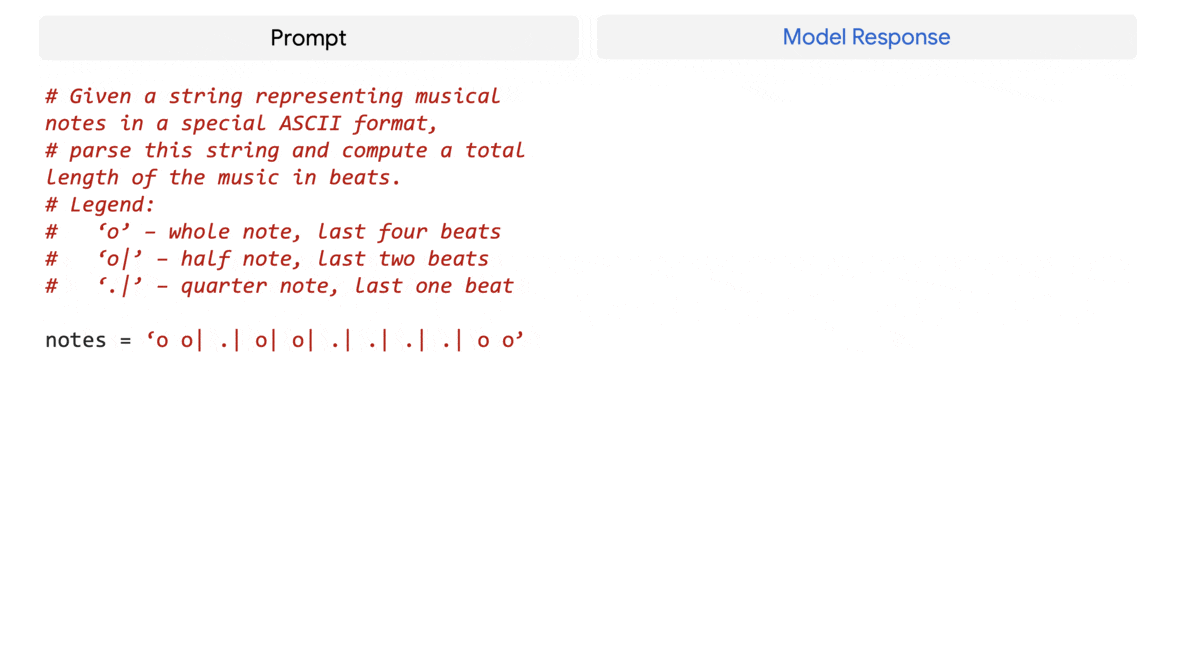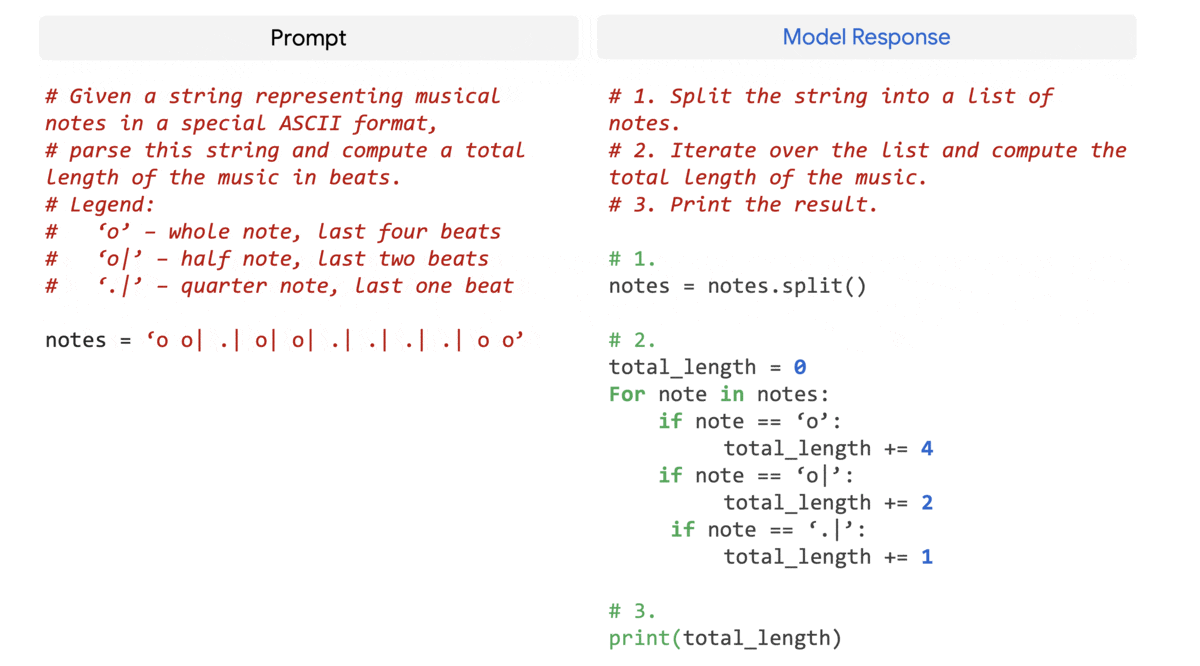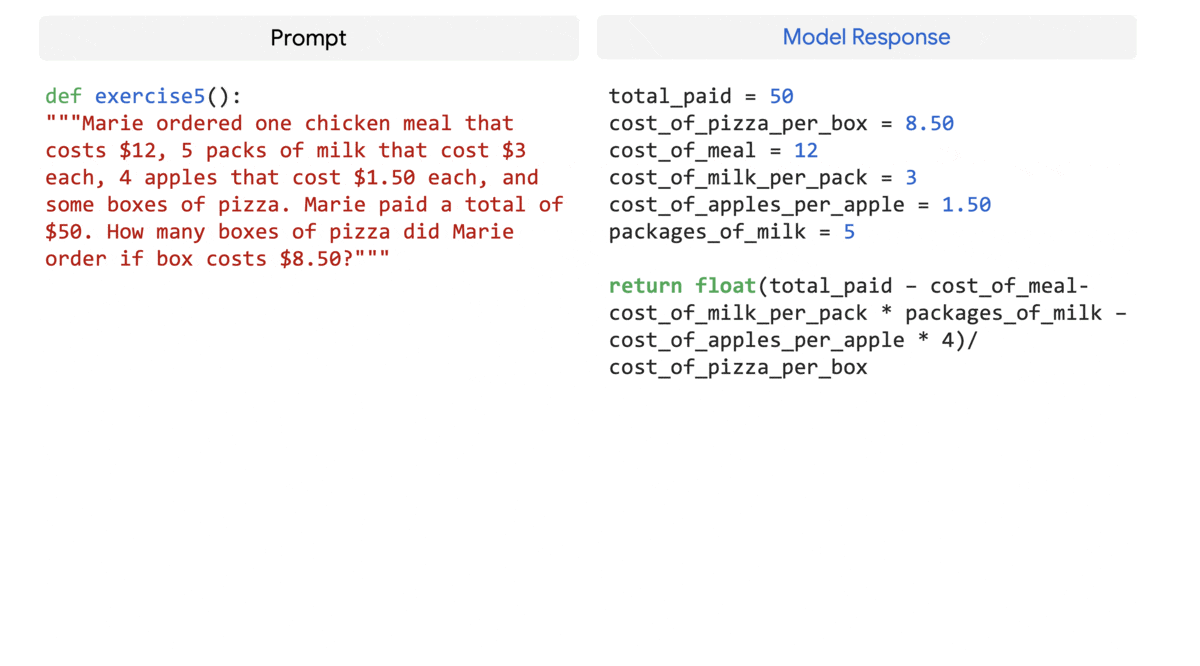
Examples from the PaLM-Coder 540B model. (top left) GSM8K-Python ...
Training Language Models with Textbook-Quality Synthetic Data | Towards ...
10 Best Solutions for Testing Conversational AI Systems
清华系「自然语言编程神器」上新!支持100+种编程语言,效率upup_腾讯新闻
论文笔记:InCoder: A Generative Model for Code Infilling and Synthesis - 掘金
GitHub - HumanEval-V/HumanEval-V-Benchmark: A Lightweight Visual ...
Code Survey | 📚 plmblog
GitHub - evalplus/humanevalplus_release: Release repository for ...
LLM Benchmark Scores: MMLU, HumanEval, GSM8K by Model | LumiChats
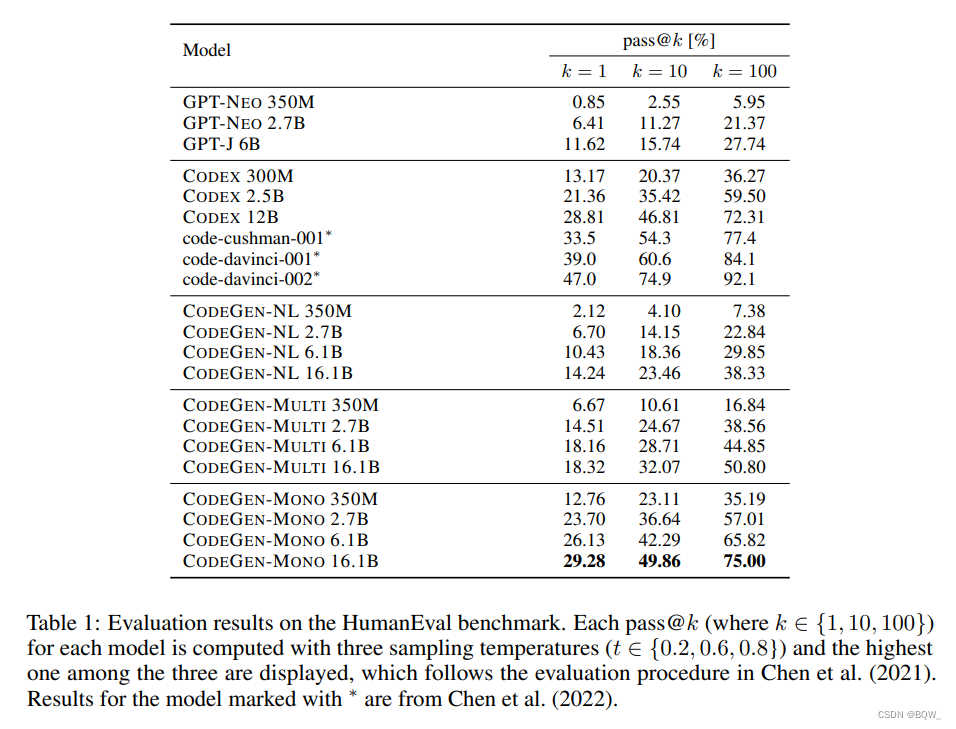
【自然语言处理】【大模型】CodeGen:一个用于多轮程序合成的代码大语言模型_codegen codegee-CSDN博客
从HumanEval到CoderEval: 你的代码生成模型真的work吗?_开源代码生成模型-CSDN博客
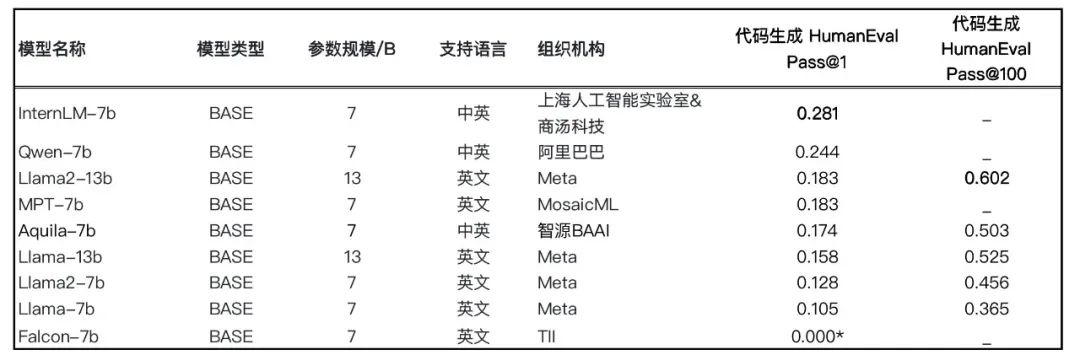
FlagEval 8月榜单:新增通义千问、Llama2等多个模型评测,新增基座模型代码生成能力评测-CSDN博客
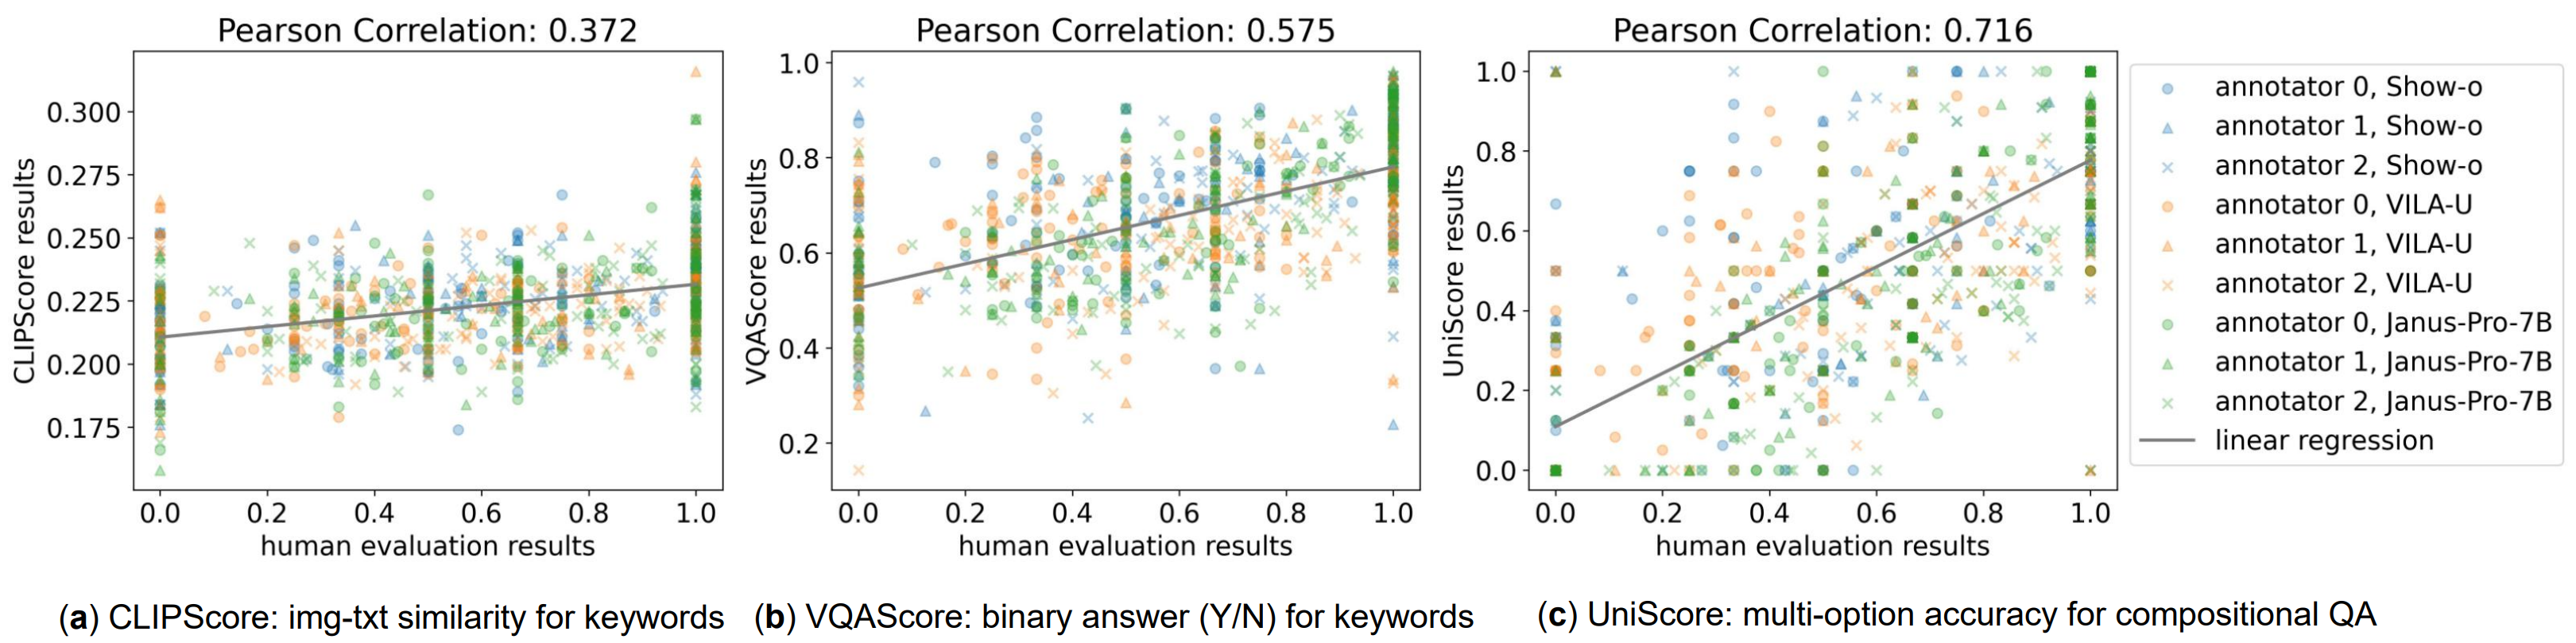
UniEval | UniEval: Unified Holistic Evaluation for Unified Multimodal ...
[2501.09316] SOP-Agent: Empower General Purpose AI Agent with Domain ...
human-eval/human_eval/__init__.py at master · openai/human-eval · GitHub
(PDF) CodeGeeX: A Pre-Trained Model for Code Generation with ...
Guide to AI Benchmarks: MMLU, HumanEval, and More Explained
RealHumanEval: A Web Interface to Measure the Ability of LLMs to Assist ...
구글, 5400억 매개변수 초대형 언어 모델 ‘PaLM’ 공개
GenAI Management Consultants & Anthropic’s Jump
[2303.17568] CodeGeeX: A Pre-Trained Model for Code Generation with ...
AI Coding at a Crossroads: Disposable Code Editors, Flawed Benchmarks ...
Building and Training Large Language Models for Code – Quantum™ Ai Labs
Model performance on MultiPL-HumanEval by language frequency and ...
How I built my own Copilot on VSCode for FREE?
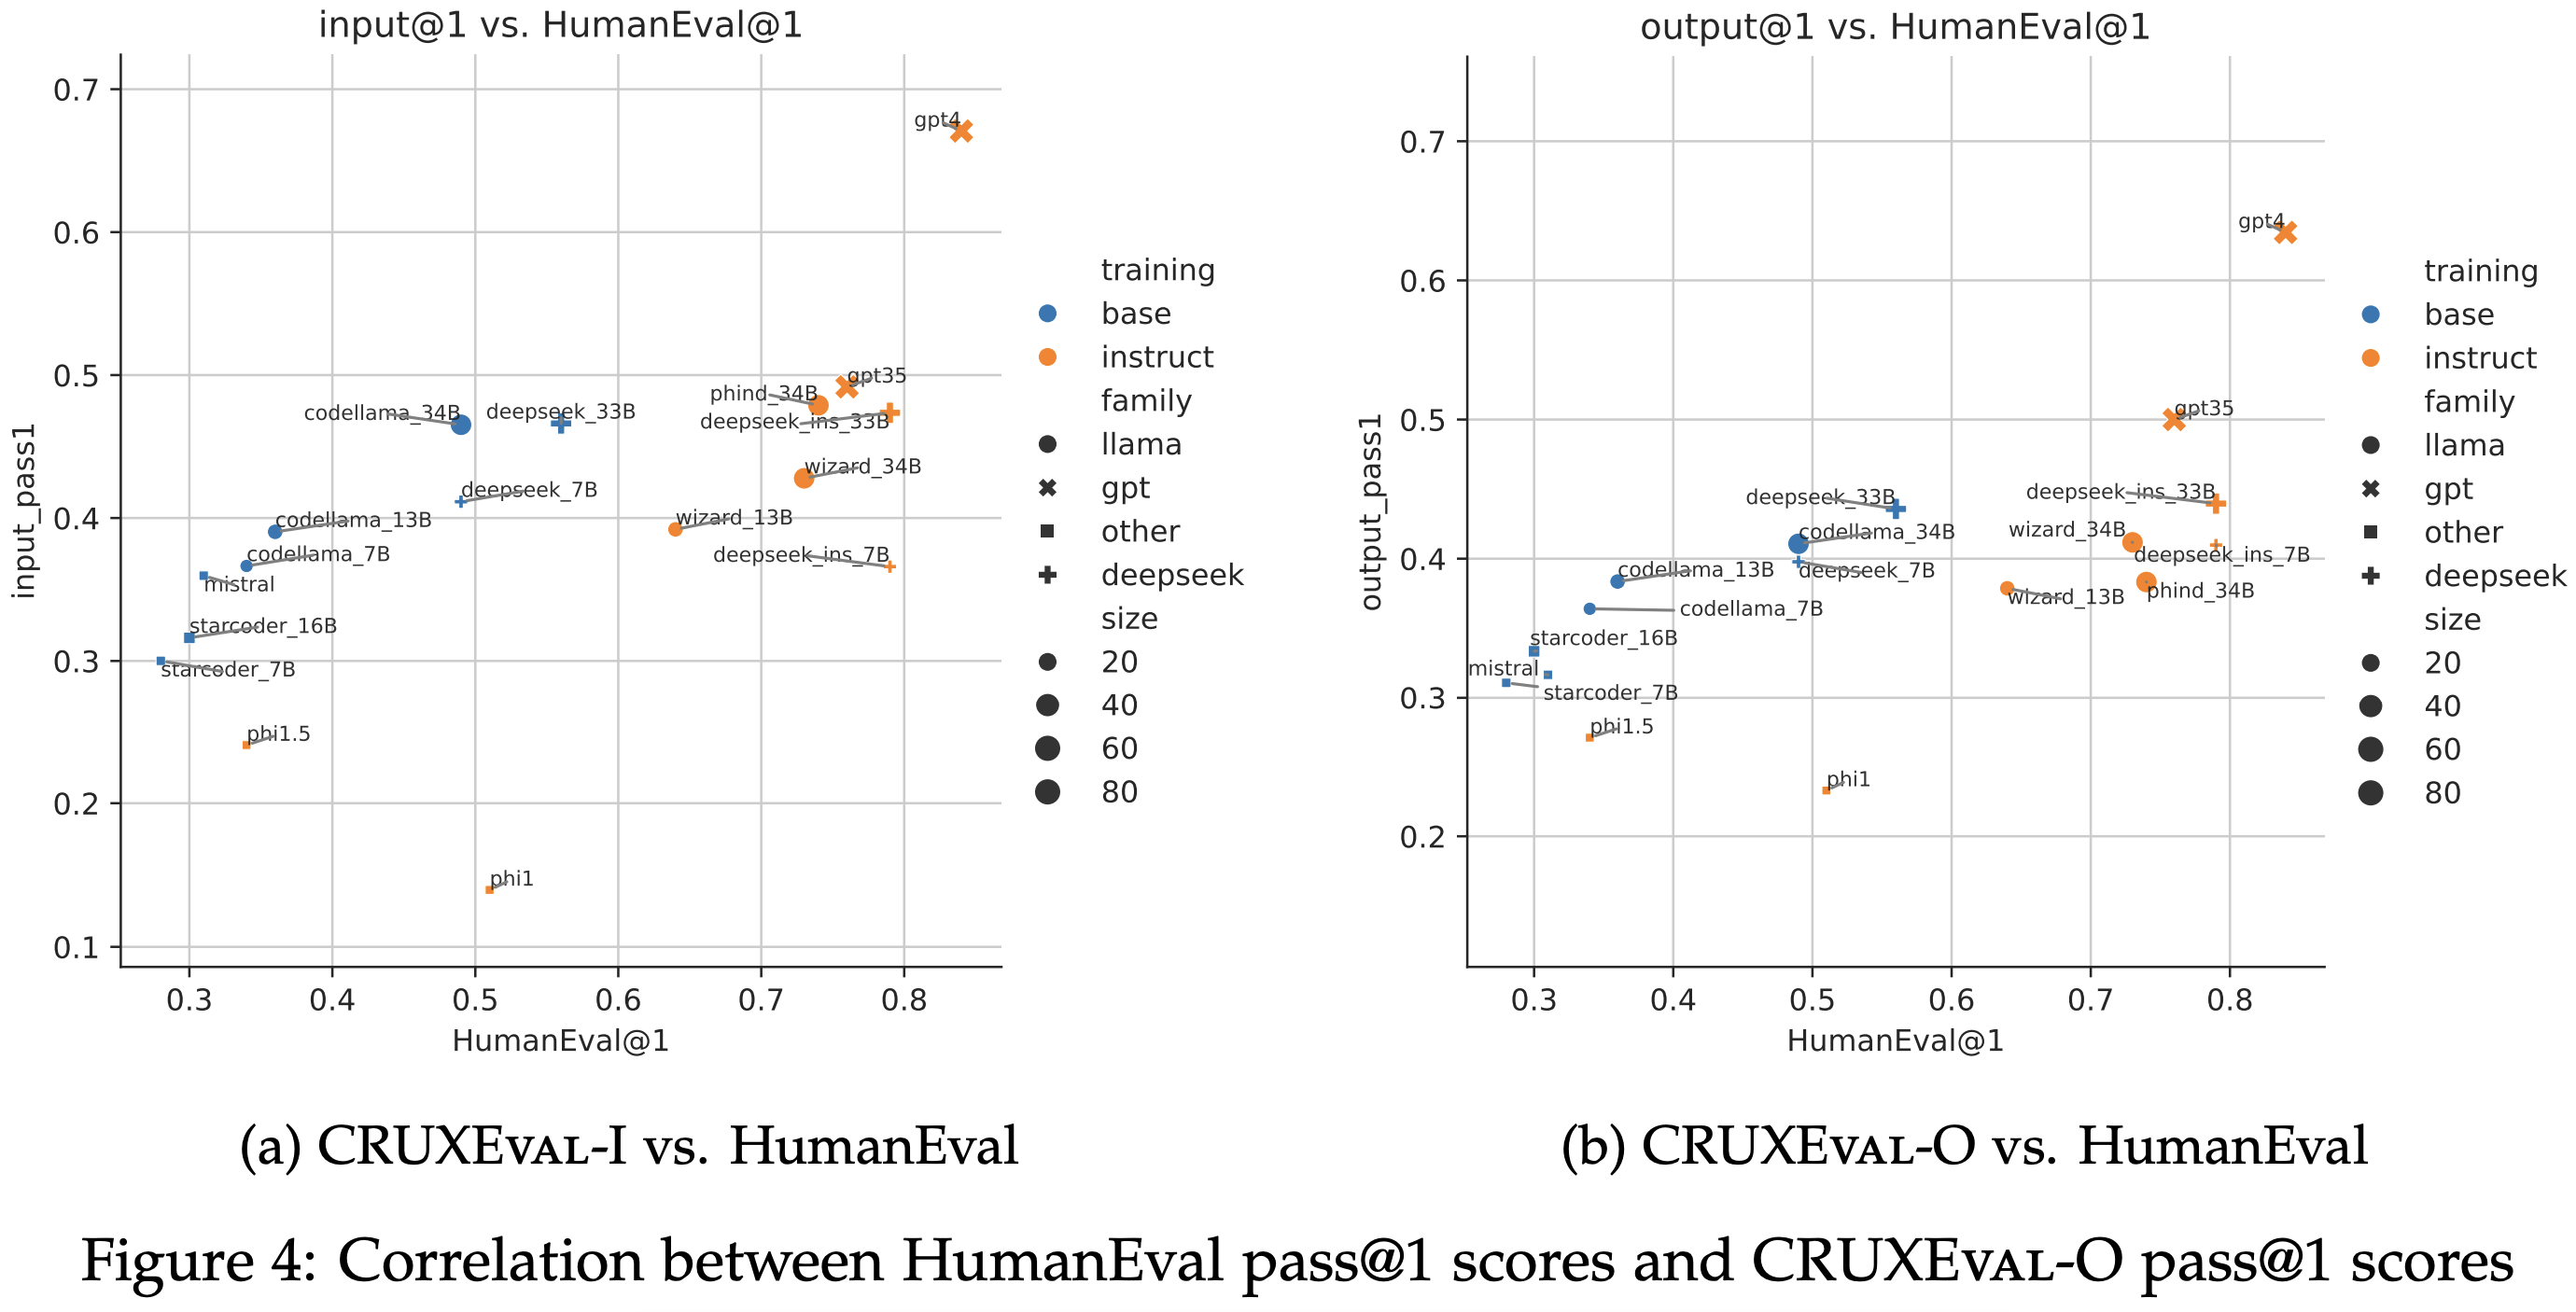
CRUXEval: Code Reasoning, Understanding, and Execution Evaluation
悟道·天鹰 AquilaCode升级多语言代码生成,多项指标领先,开源可商用开源“文本-代码”生成模型AquilaCod - 掘金
qwen2.5-coder:1.5b
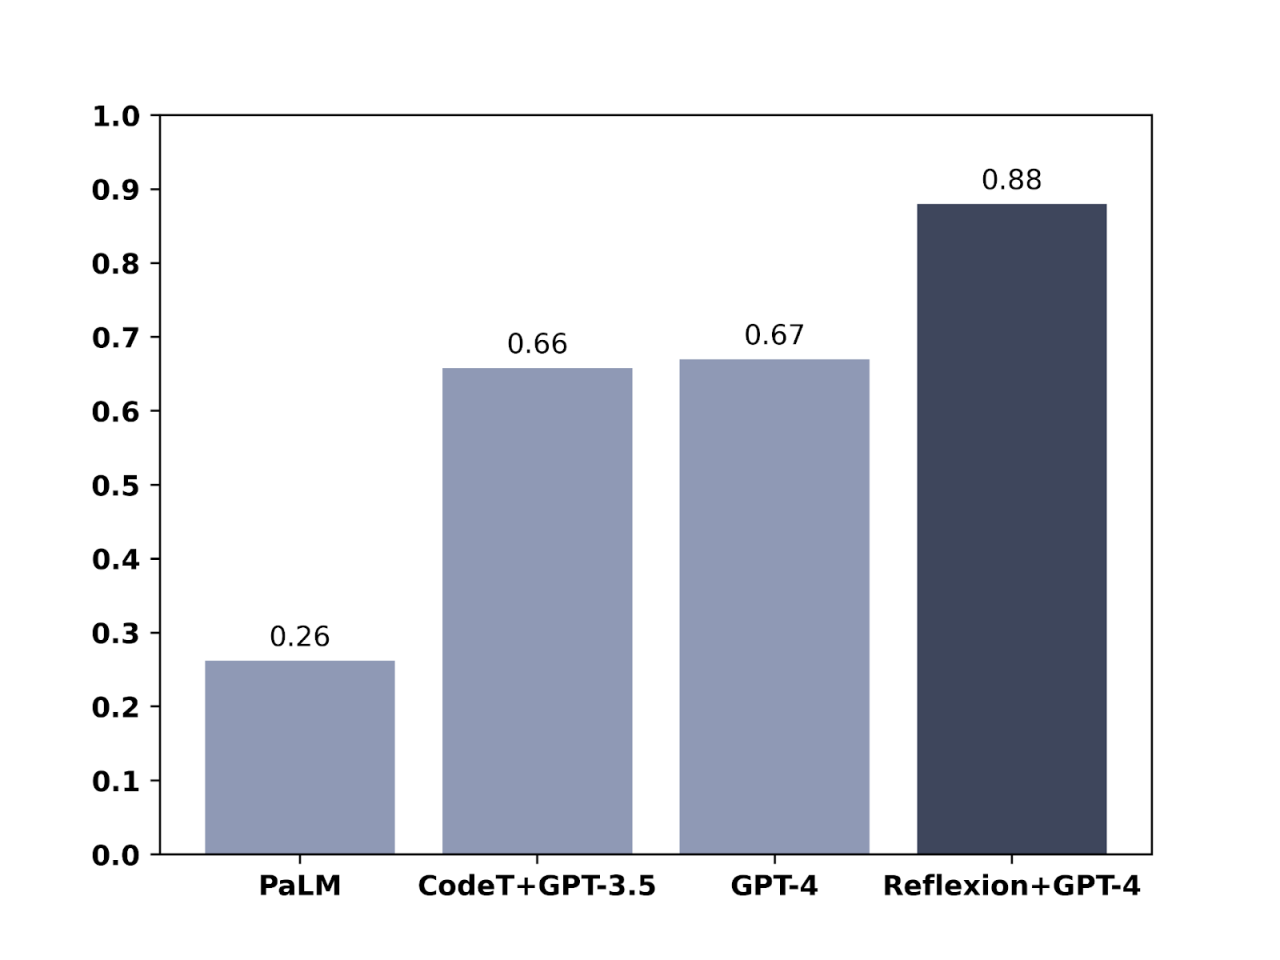
GPT-4 becomes 30% more accurate when asked to critique itself - Kowatek ...
Codestral - Mistral AI推出的代码生成模型,支持80+编程语言 | AI工具集