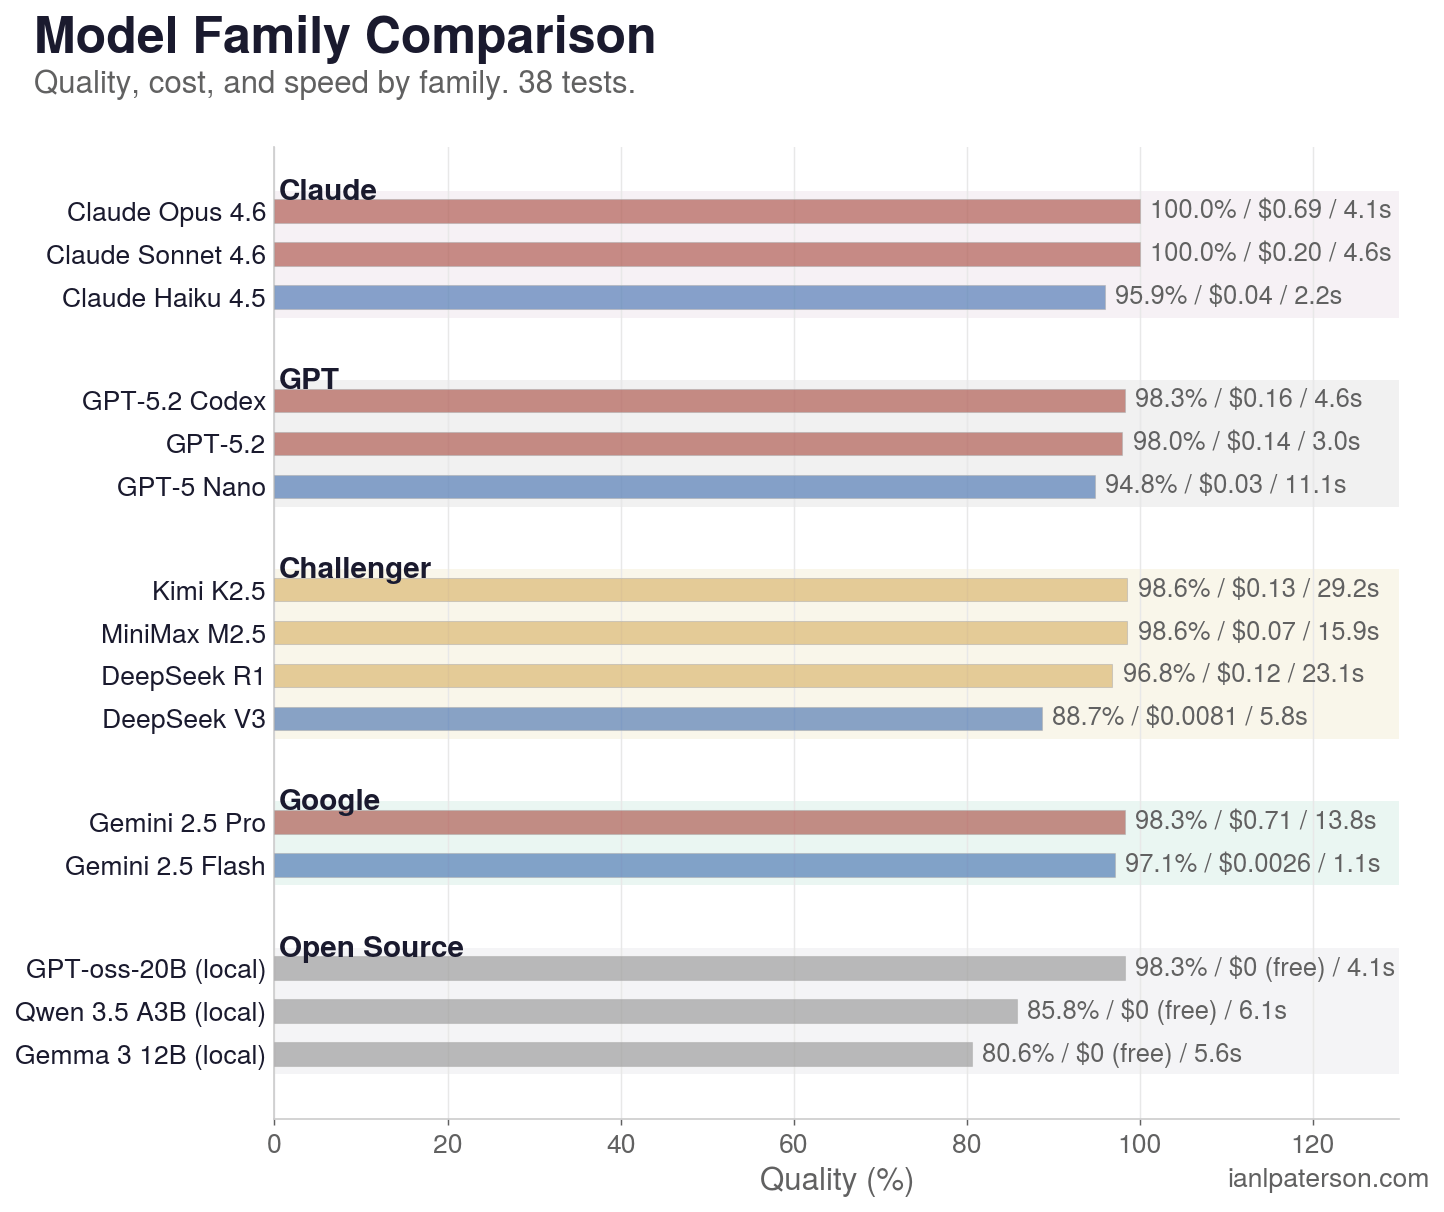Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
The Big LLM Architecture Comparison
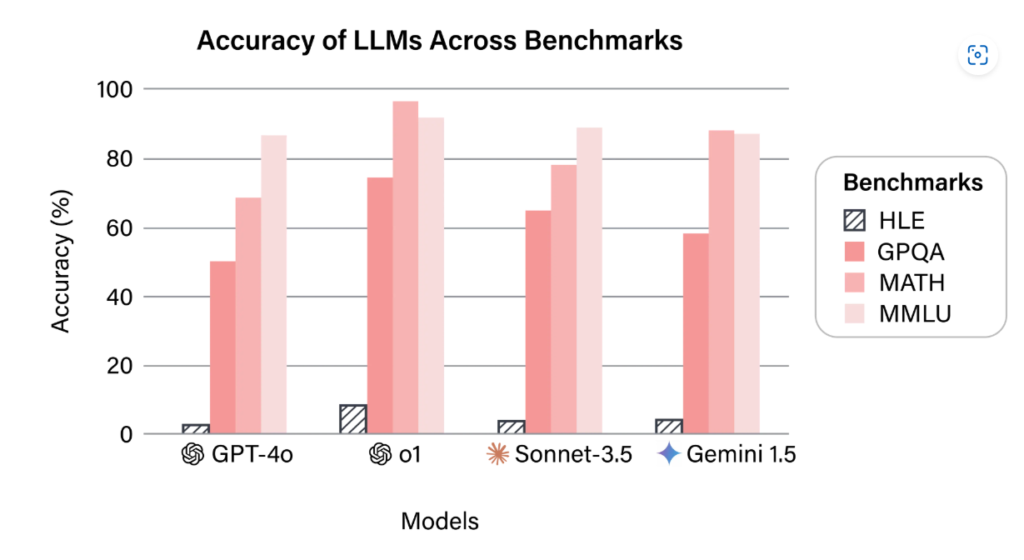
LLM Benchmarks in 2024: Overview, Limits and Model Comparison
Side-by-Side LLM Comparison Tool | Nomodo.ai
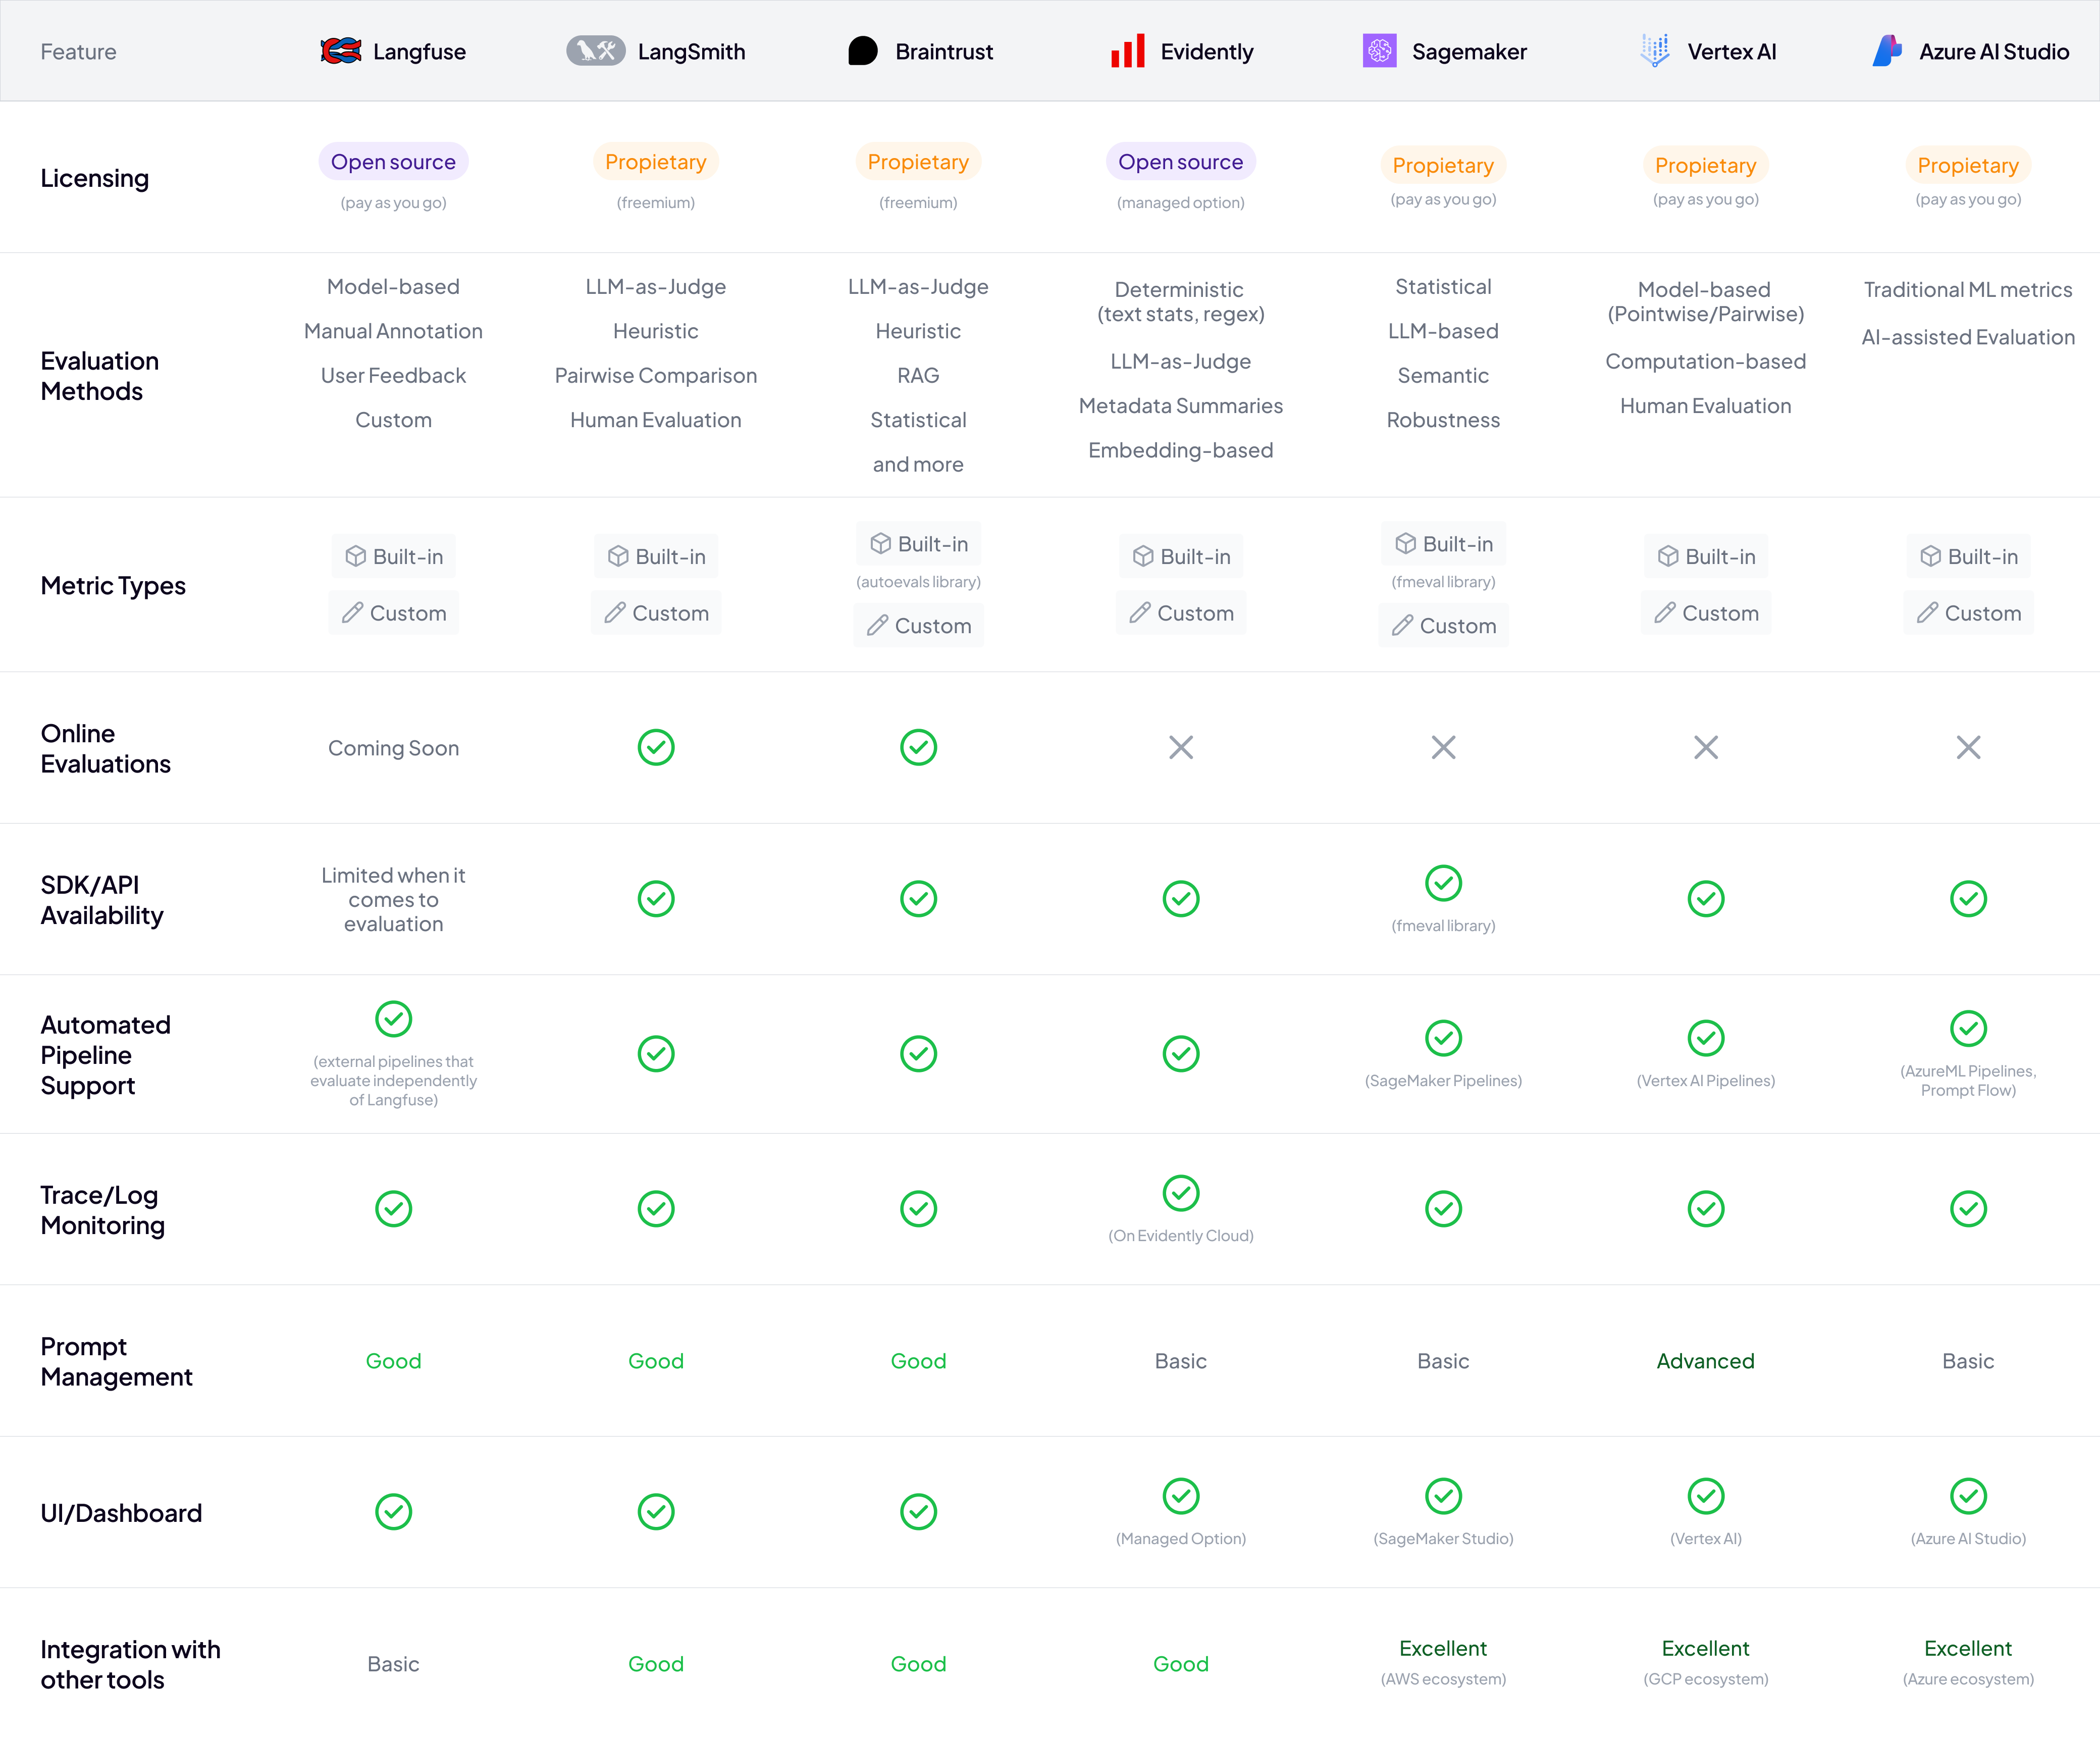
LLM Evaluation & Prompt Tracking Showdown: A Comprehensive Comparison ...
Dmytro Linchenko: LLM application comparison for development and ...
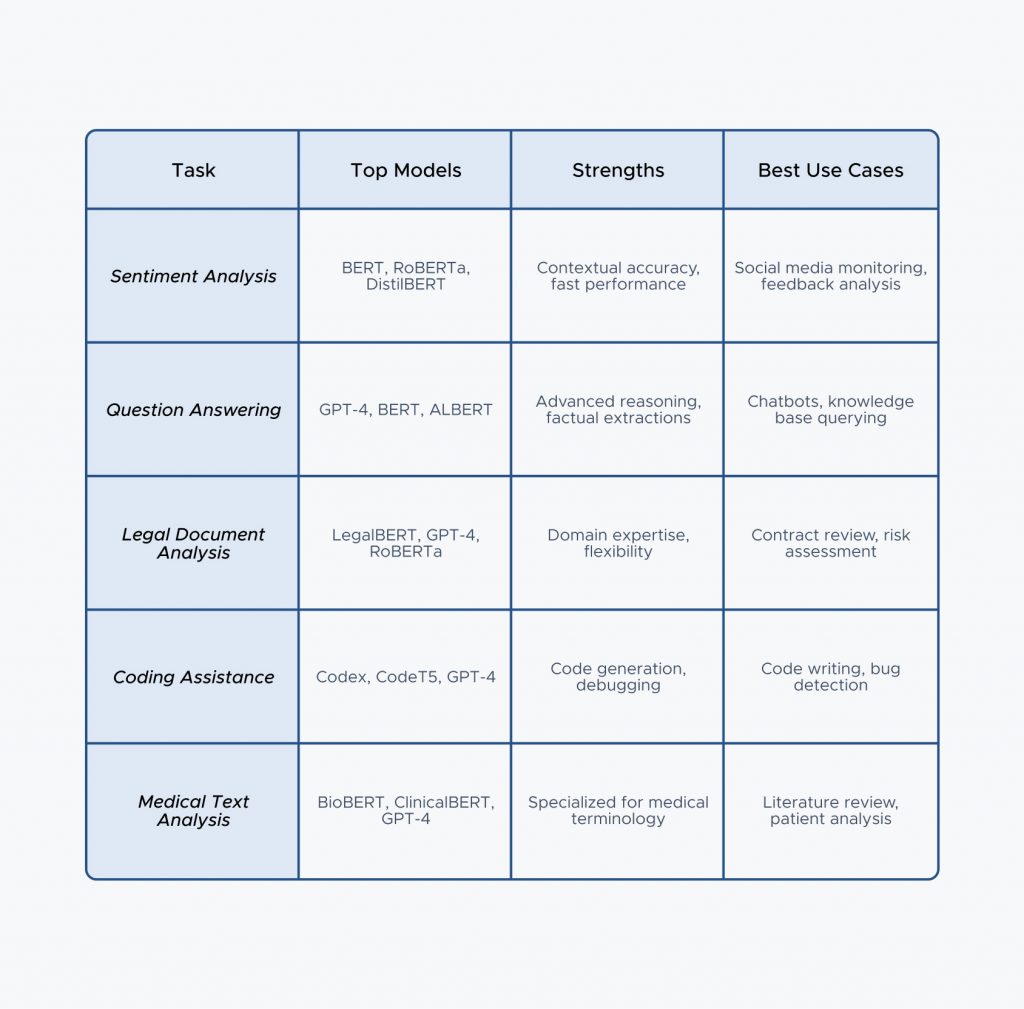
Beyond vibes: How to properly select the right LLM for the right task ...
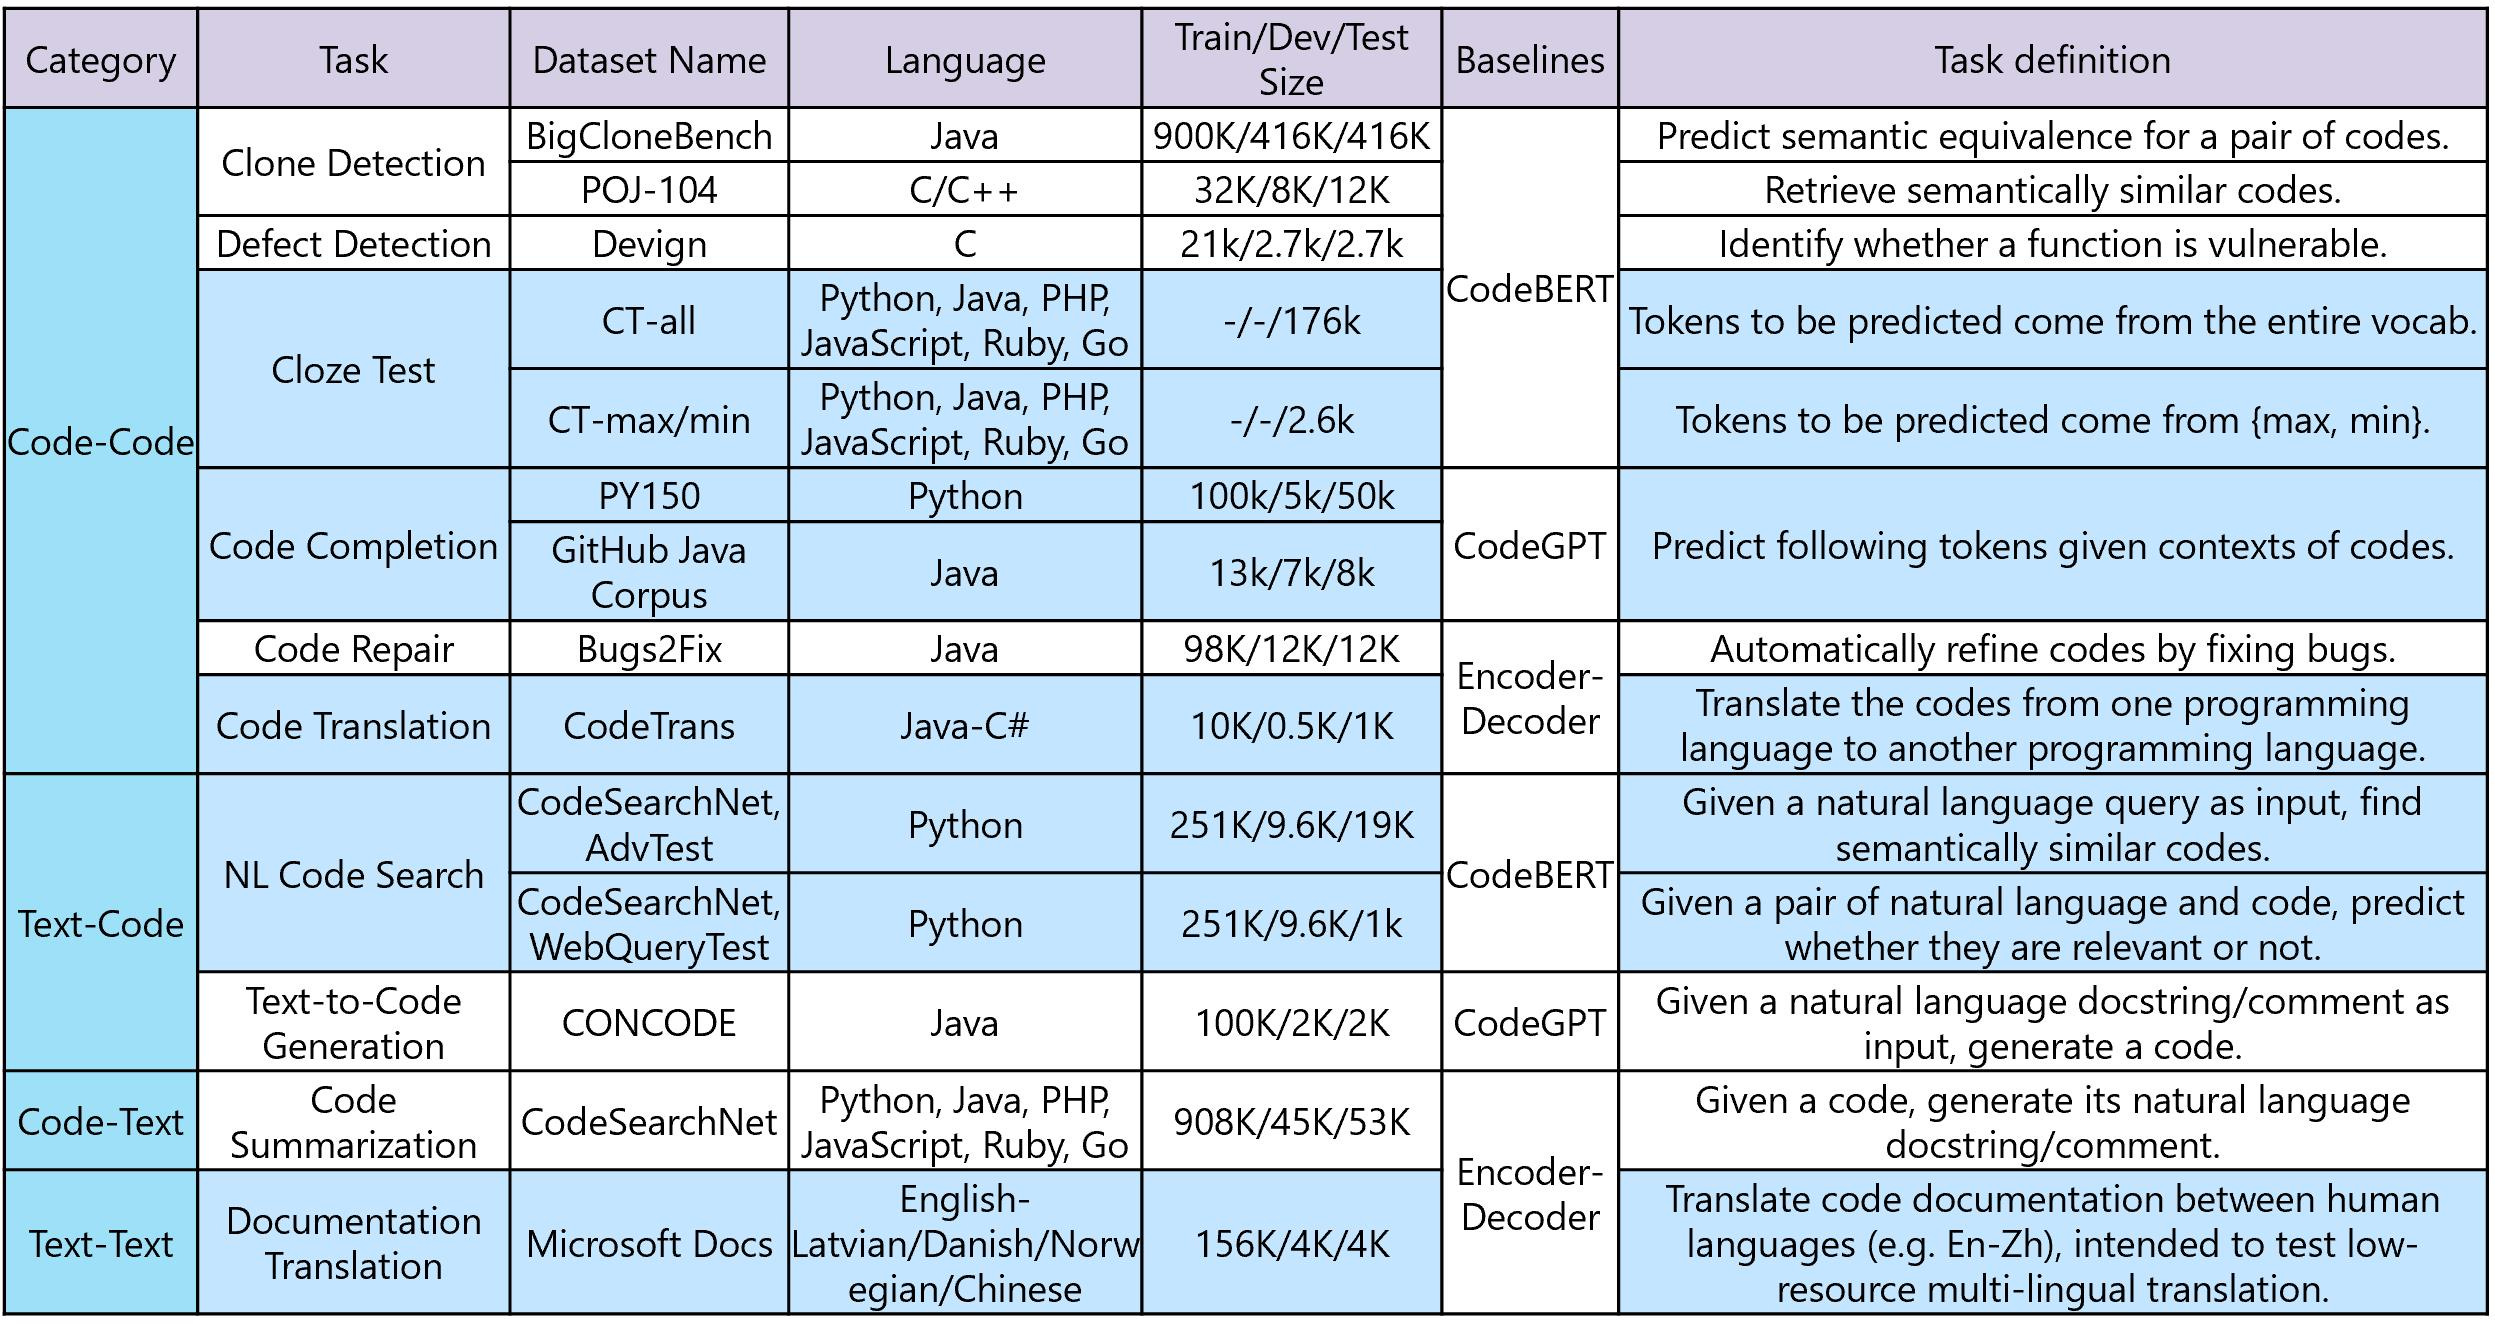
LLM tasks and Metrics a) Text classification - Accuracy, F1 Score b ...
Figure S6. Human, LLM and baseline model plausibility score ...
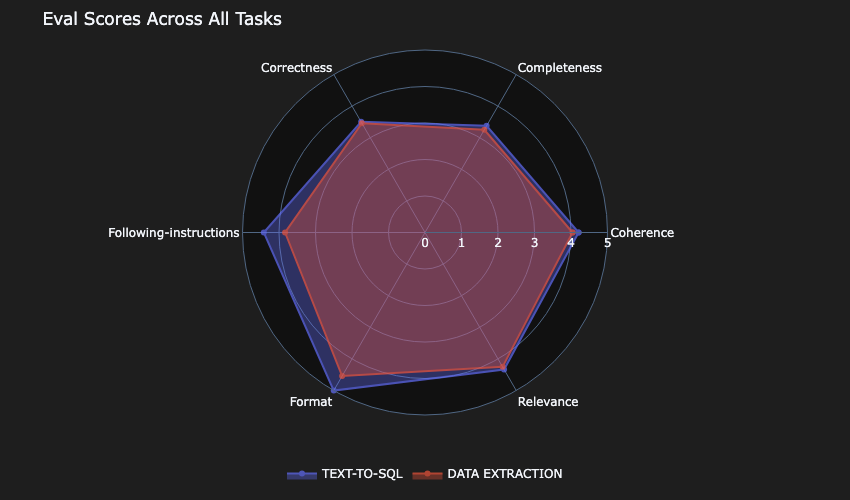
LLM Task Evaluations
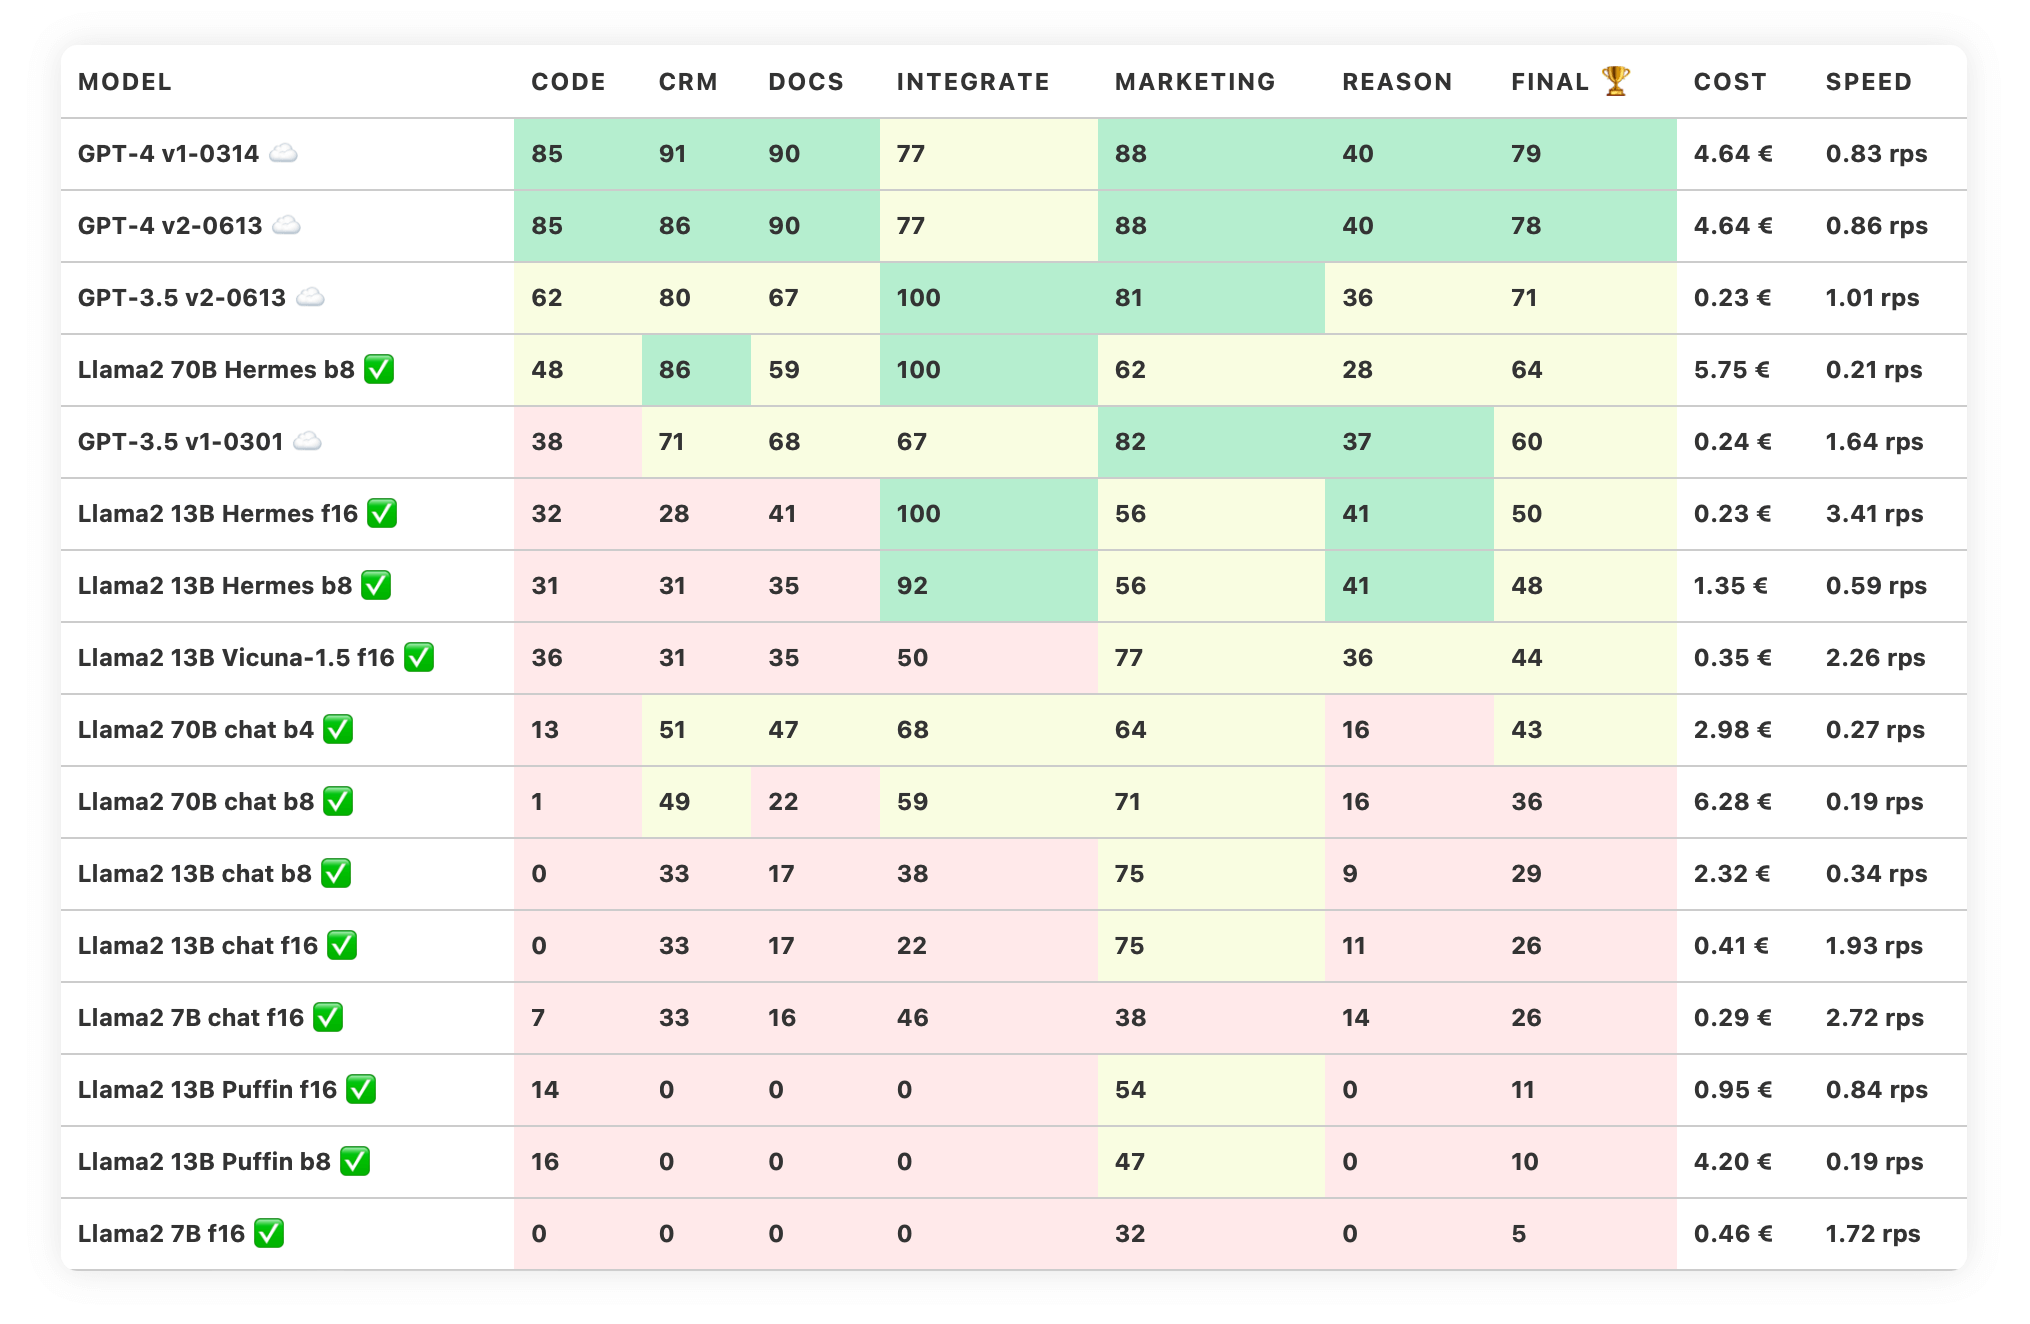
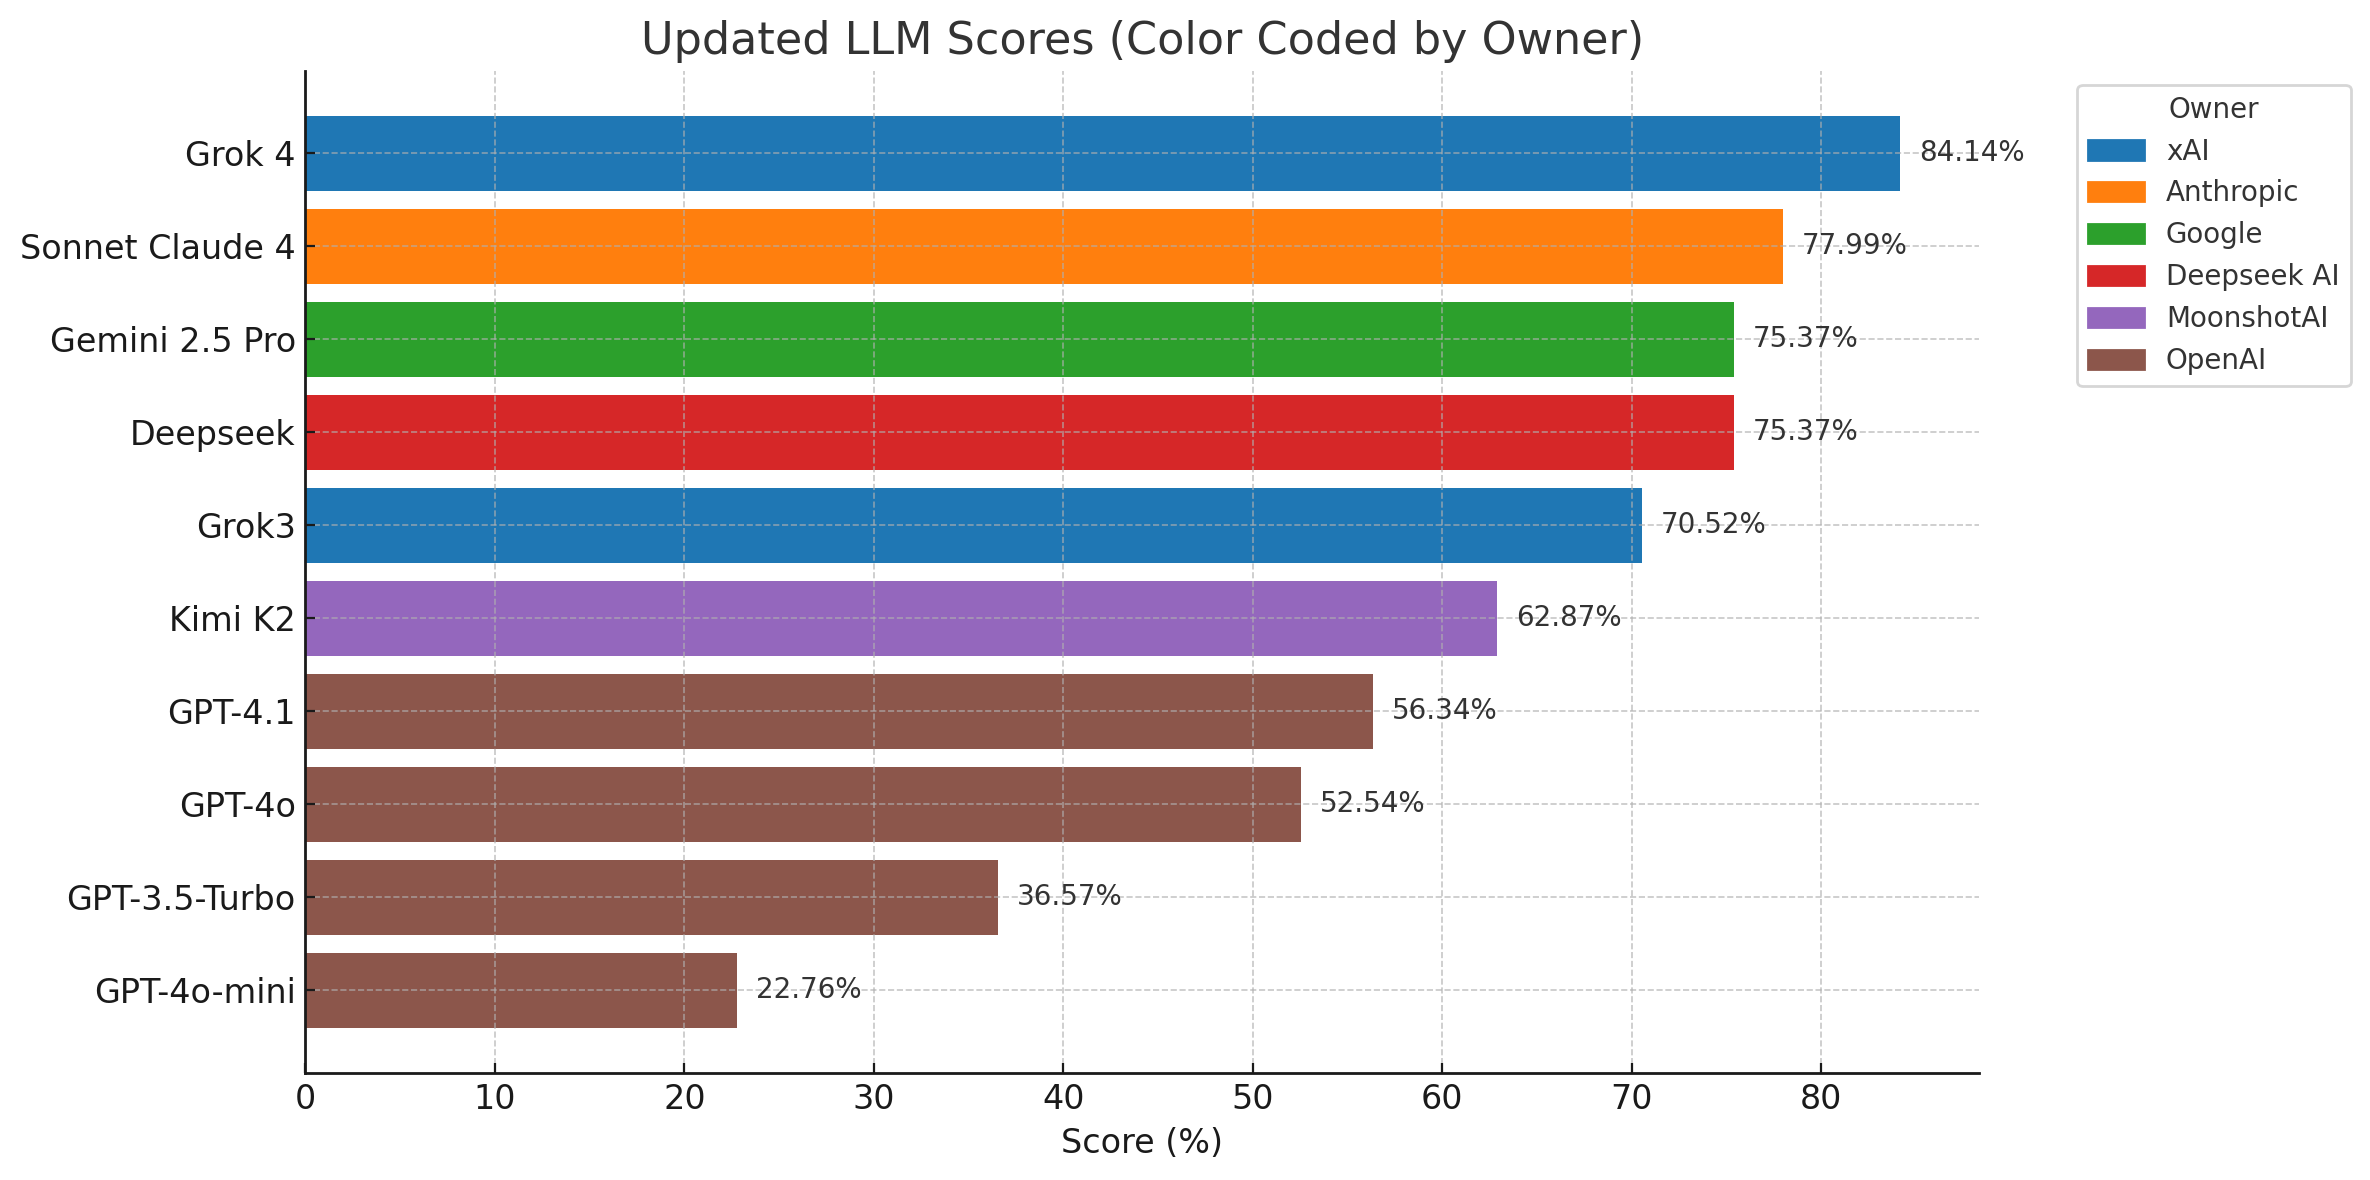
LLM Score v2 - Modern Models Tested by Human : r/LocalLLaMA
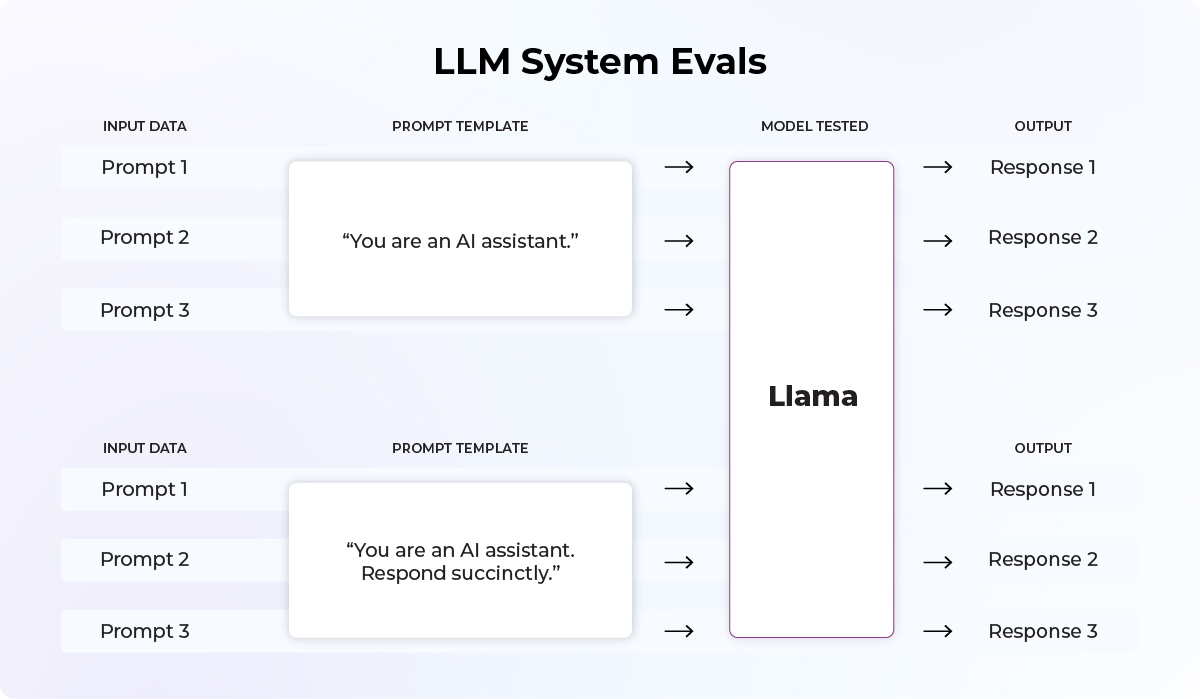
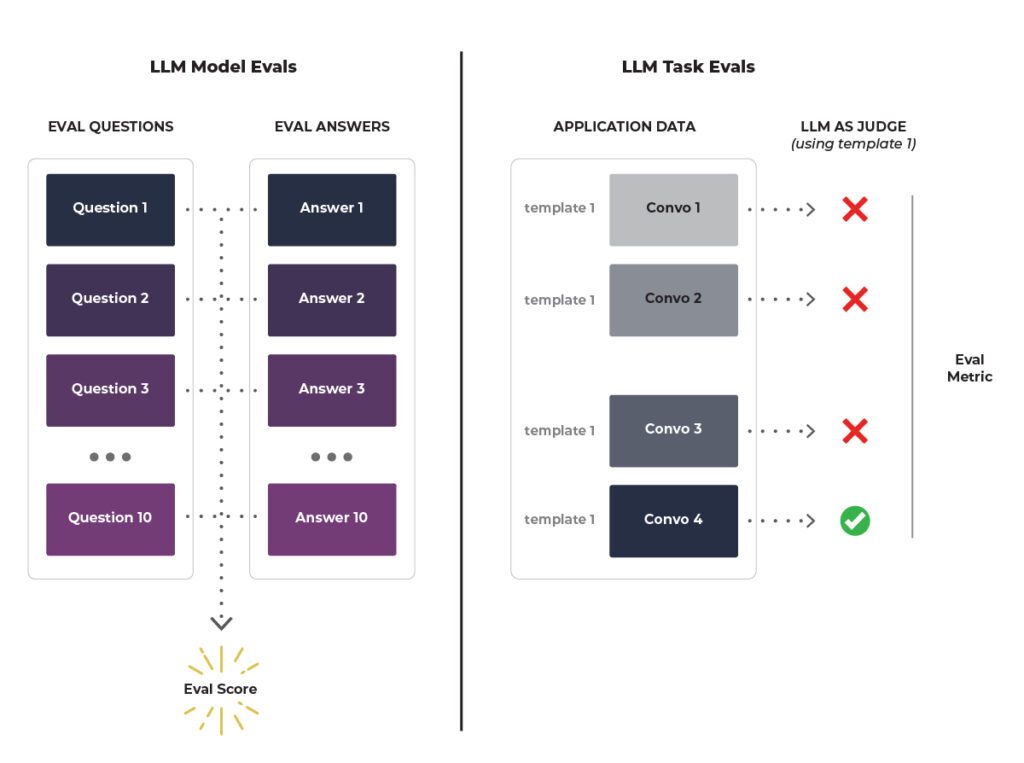
Model Evals vs Task Evals In LLM App Development
LLM Evaluation Tools: The Complete Comparison Guide (2026) | Inference.net
LLM Benchmarks — Klu
LLM Performance Series: Batching — Trustbit
🐺🐦⬛ LLM Comparison/Test: DeepSeek-V3, QVQ-72B-Preview, Falcon3 10B ...
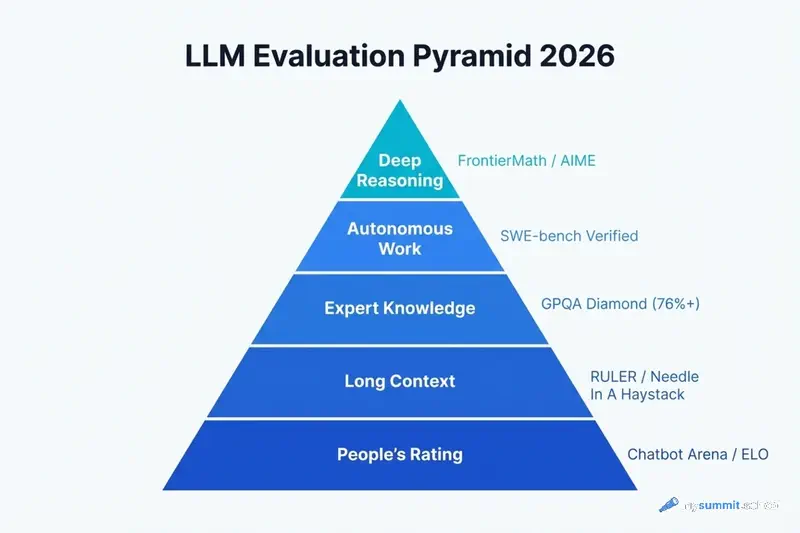
LLM Benchmark 2026: 15 Models on 38 Real Tasks
What are LLM Benchmarks?
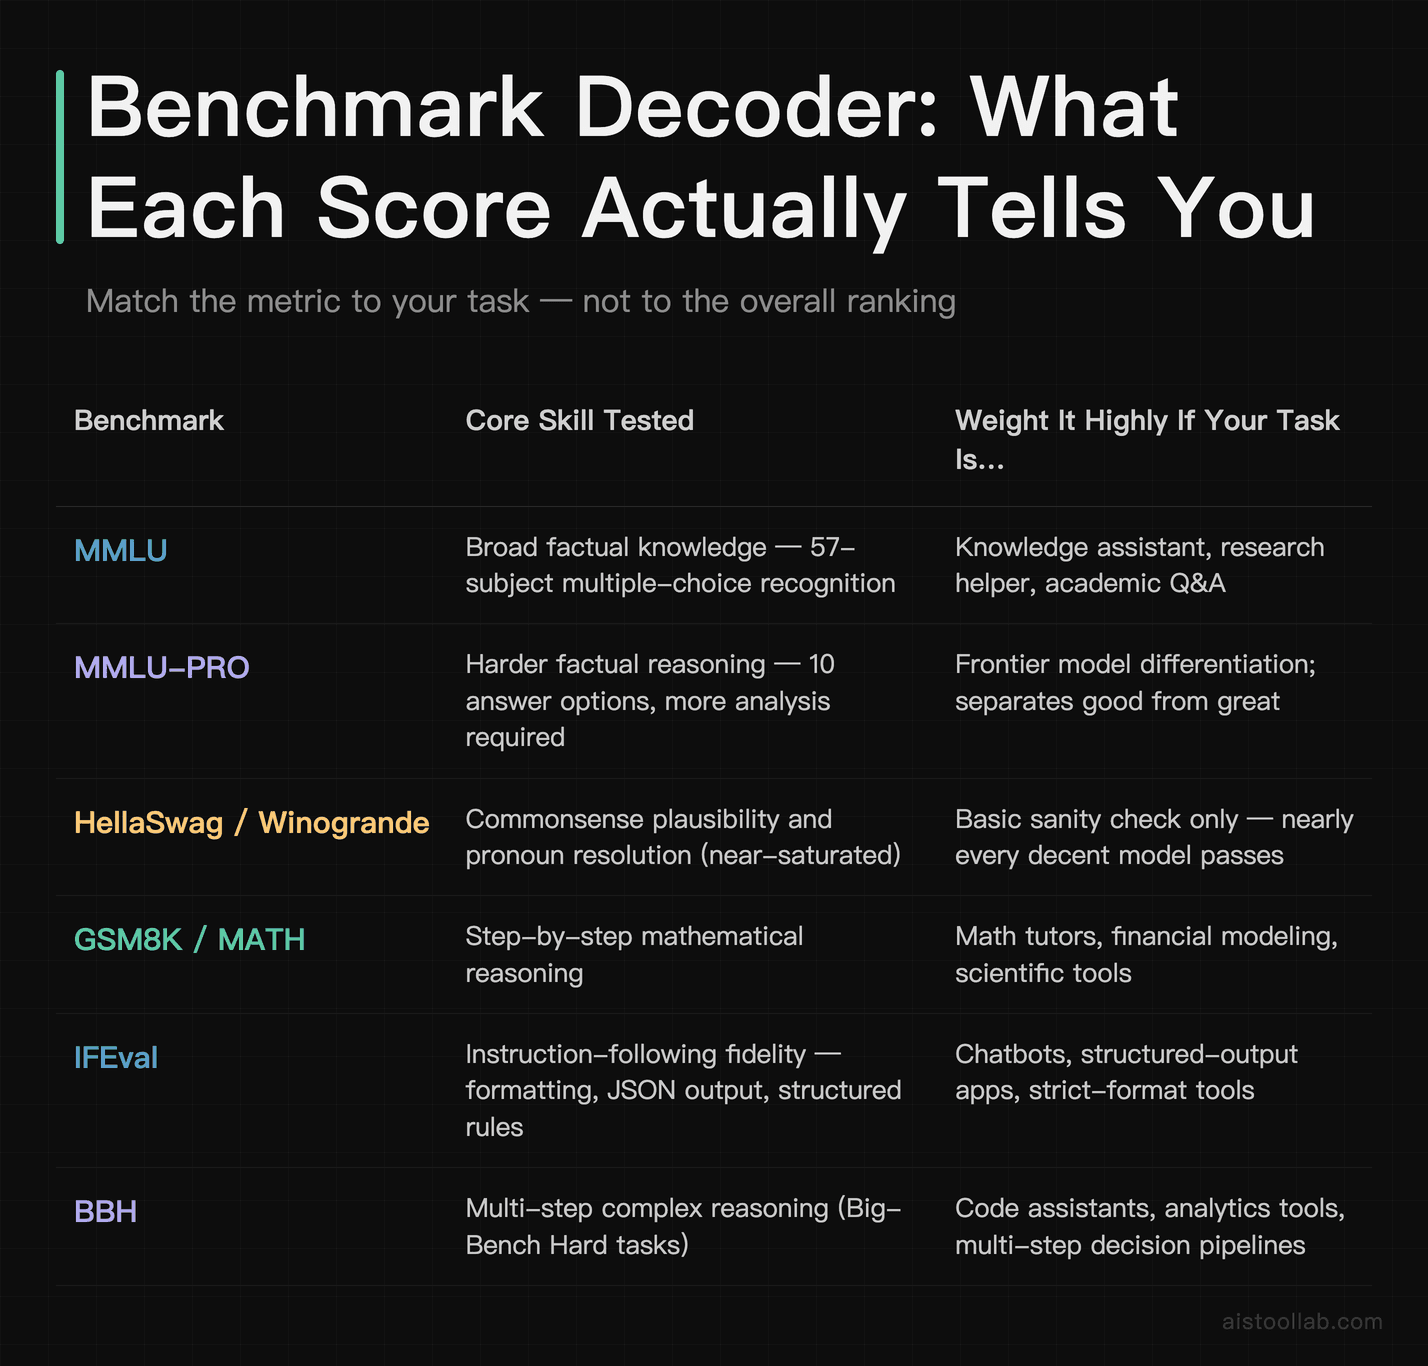
LLM Benchmarks: MMLU, HellaSwag, BBH, and Beyond - Confident AI
40 Top Research-Backed LLM Benchmarks and Where To Use Them
Best LLM for math in 2026: how AI models rank
Key Criteria When Selecting an LLM
The Definitive Guide to LLM Evaluation - Arize AI
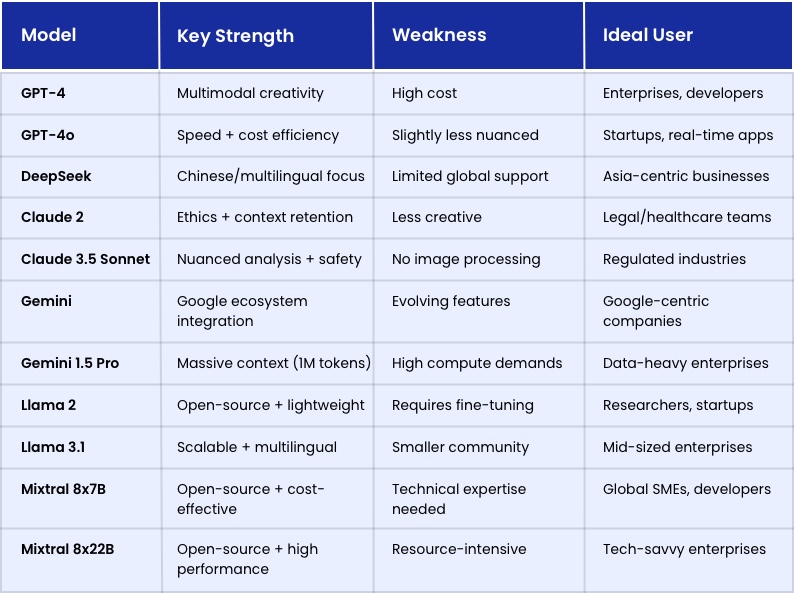
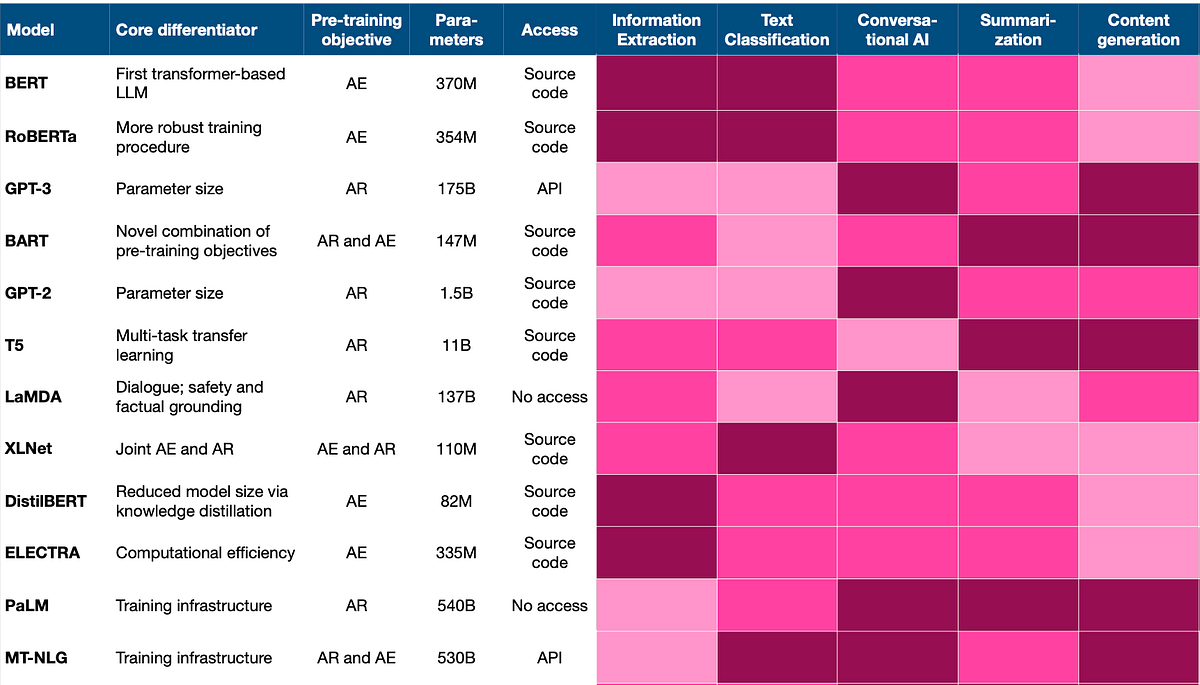
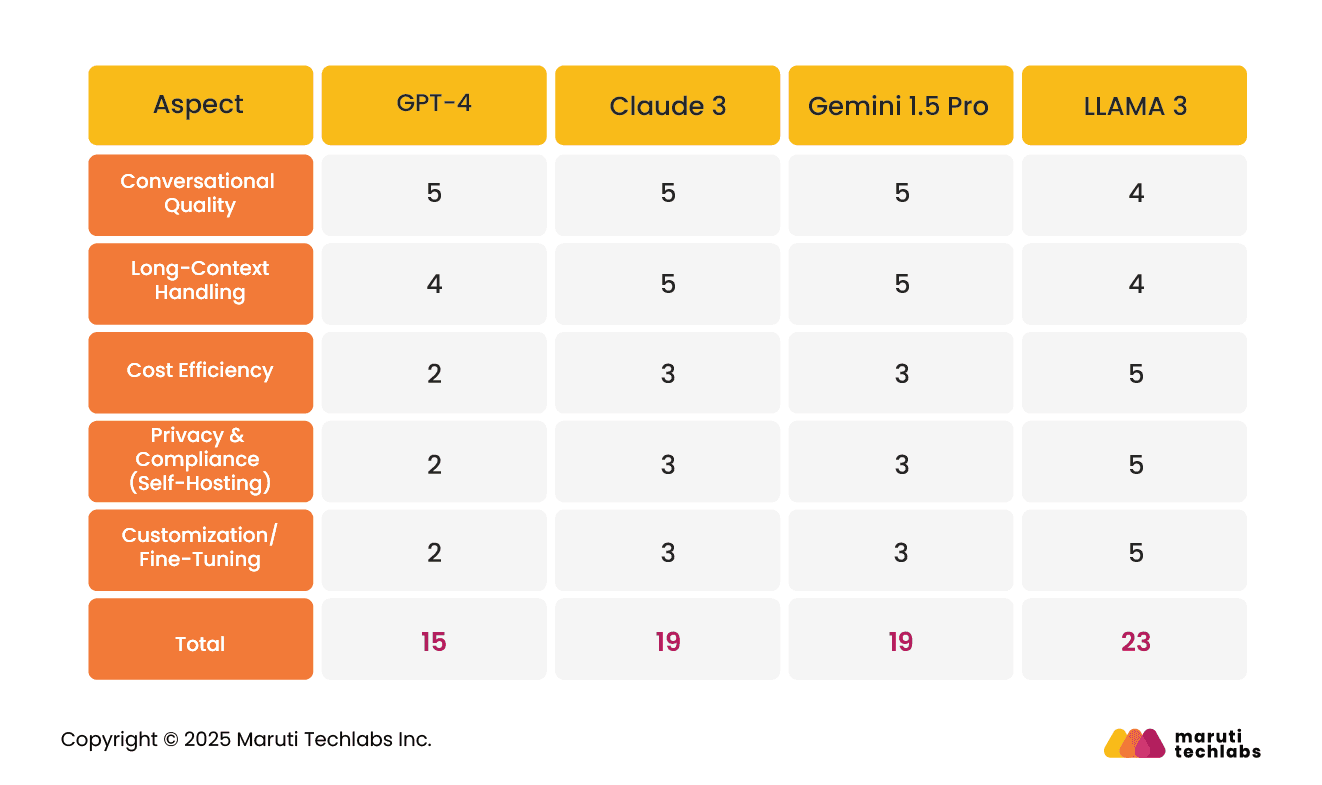
Comparison of Large Language Models: The Ultimate Guide
Evaluating LLM Performance with AWS Bedrock
Comprehensive list of LLM benchmarks- Part 1 | by Vivedha Elango | Jul ...
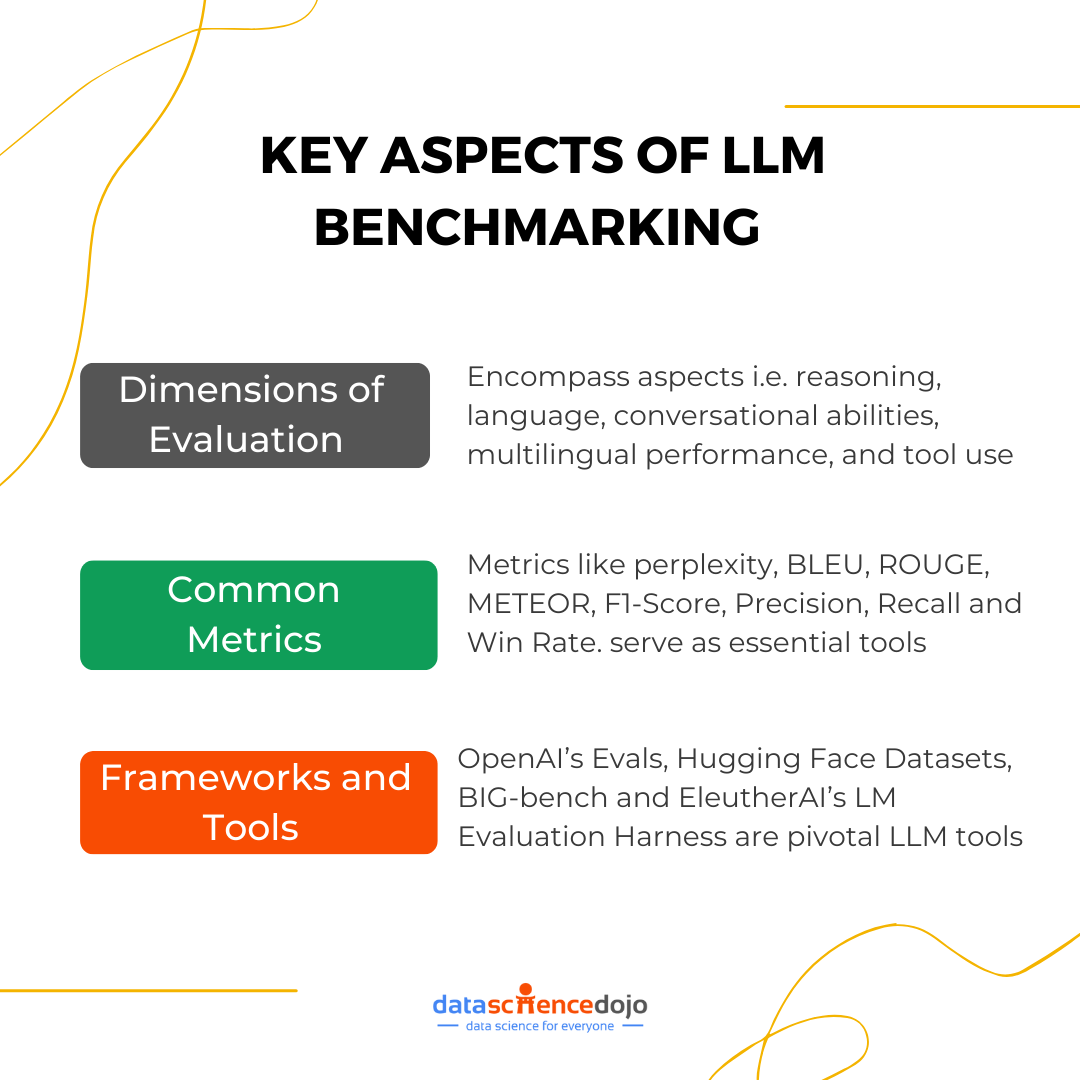
The Complete Guide to LLM Benchmarking: Everything You Need to Know in ...
LLM Model Ranking & Comparison: 2026 Pricing and Model Selection Guide ...
LLM Comparison: A Comparative Analysis for 2026
What is LLM Benchmarks? Types, Challenges & Evaluators
How To Evaluate State‑Of‑The‑Art LLM Models: A Complete Guide | Deepchecks
LLM Benchmarks Explained: Significance, Metrics & Challenges
Times Higher Education Ranking Llm at David Frakes blog
What are the best practices for selecting LLM evaluation metrics?
LLM Evaluation Metrics: Ensuring Optimal Performance and Relevance ...
LLM-as-a-Judge Simply Explained: A Complete Guide to Run LLM Evals at ...
Top LLM Evaluation Benchmarks and How They Work
How to choose the right LLM for your usecase? When working with Large ...
Understanding LLM Development & Its Role in Business Growth
30 LLM evaluation benchmarks and how they work
Unveiling the Ultimate LLM Benchmarks Guide
LLM Evaluation Metrics: Everything You Need for LLM Evaluation ...
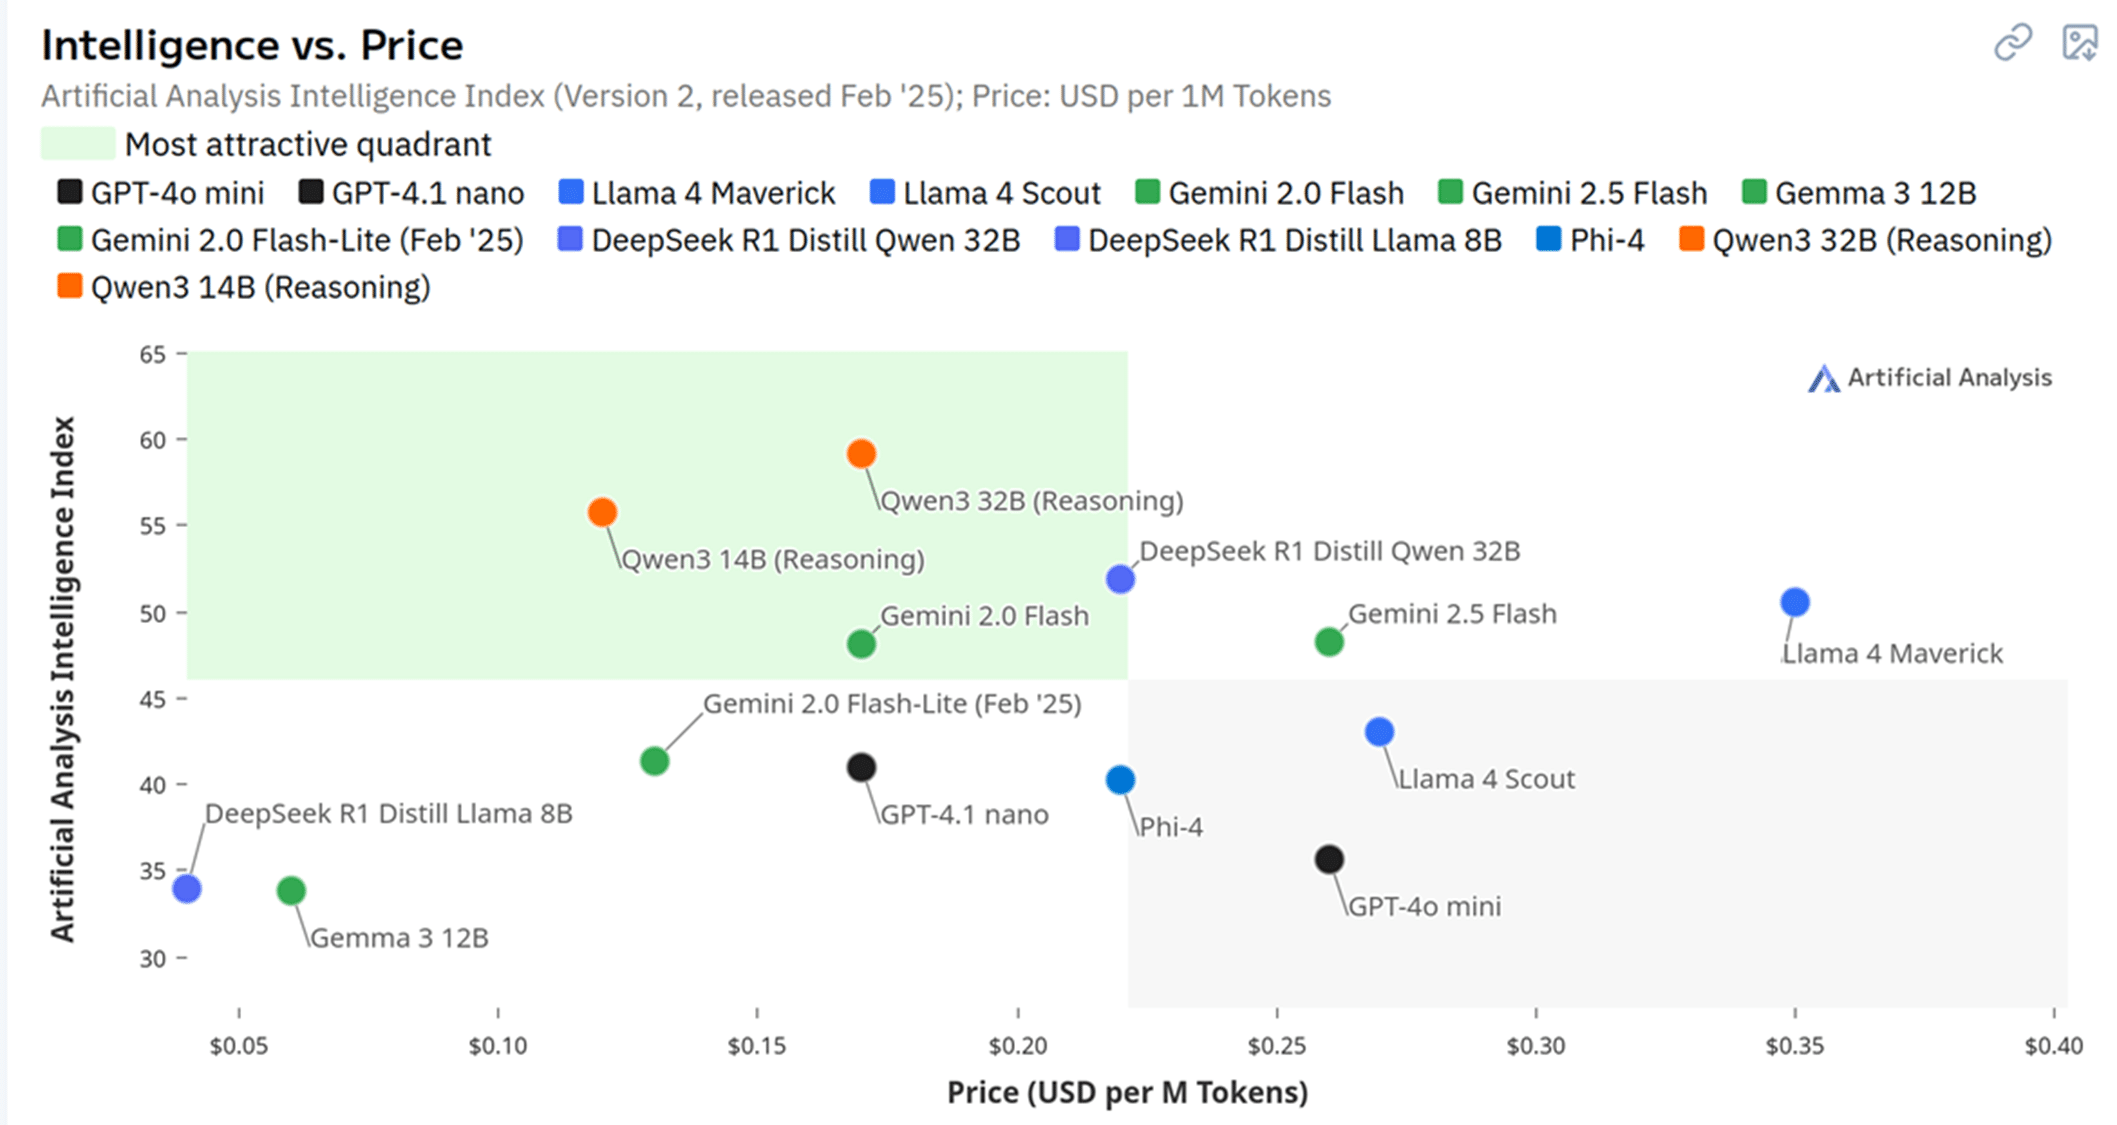
LLM price performance comparison: Why intelligence-to-cost ratio ...
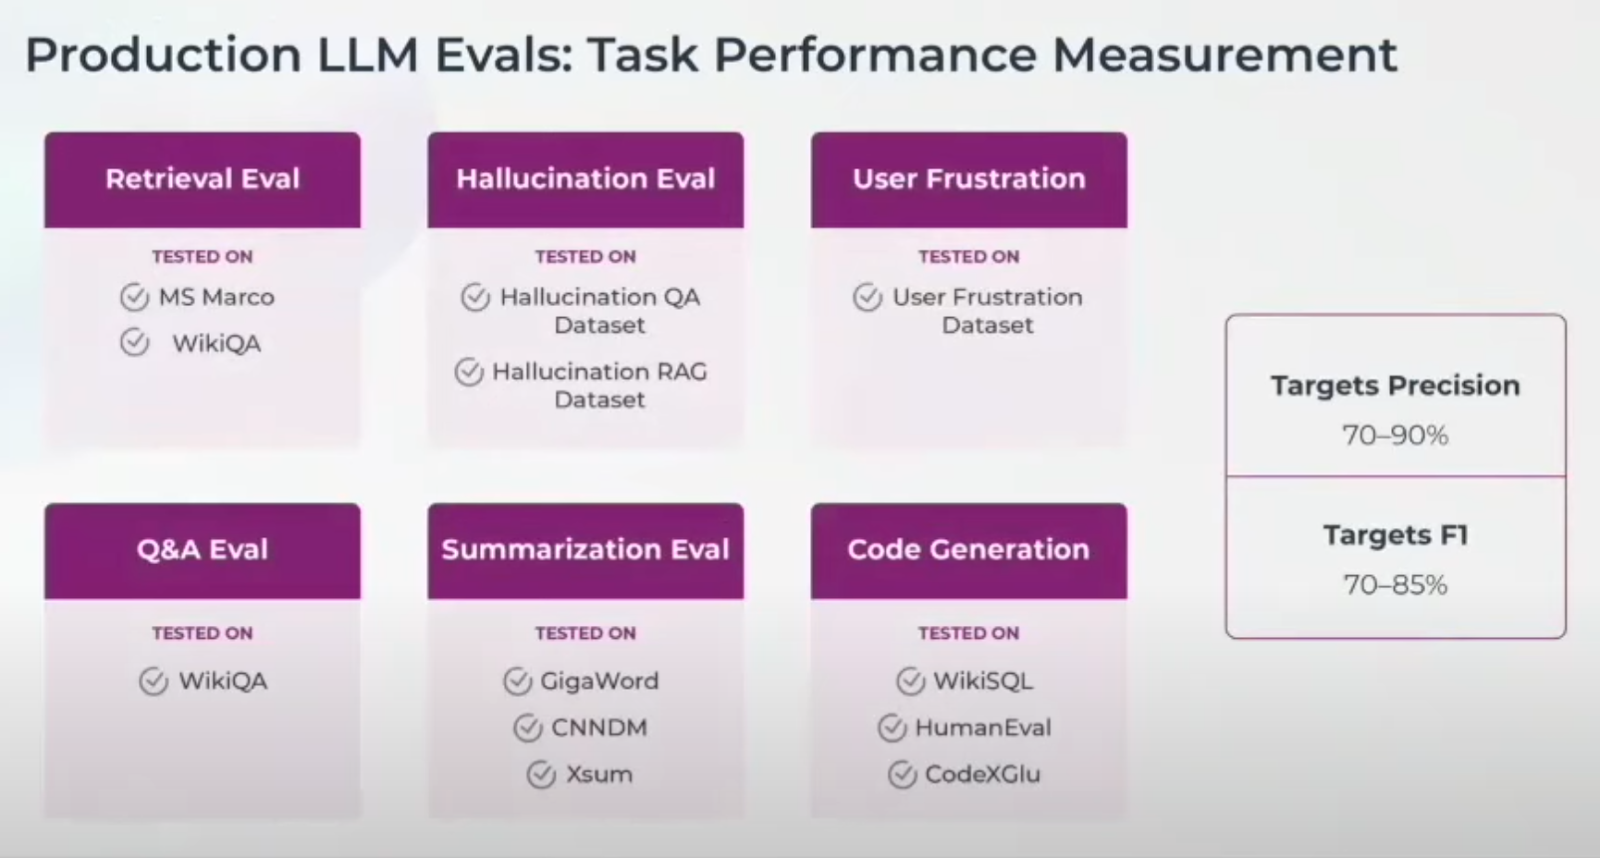
The Path to Production: LLM Application Evaluations and Observability ...
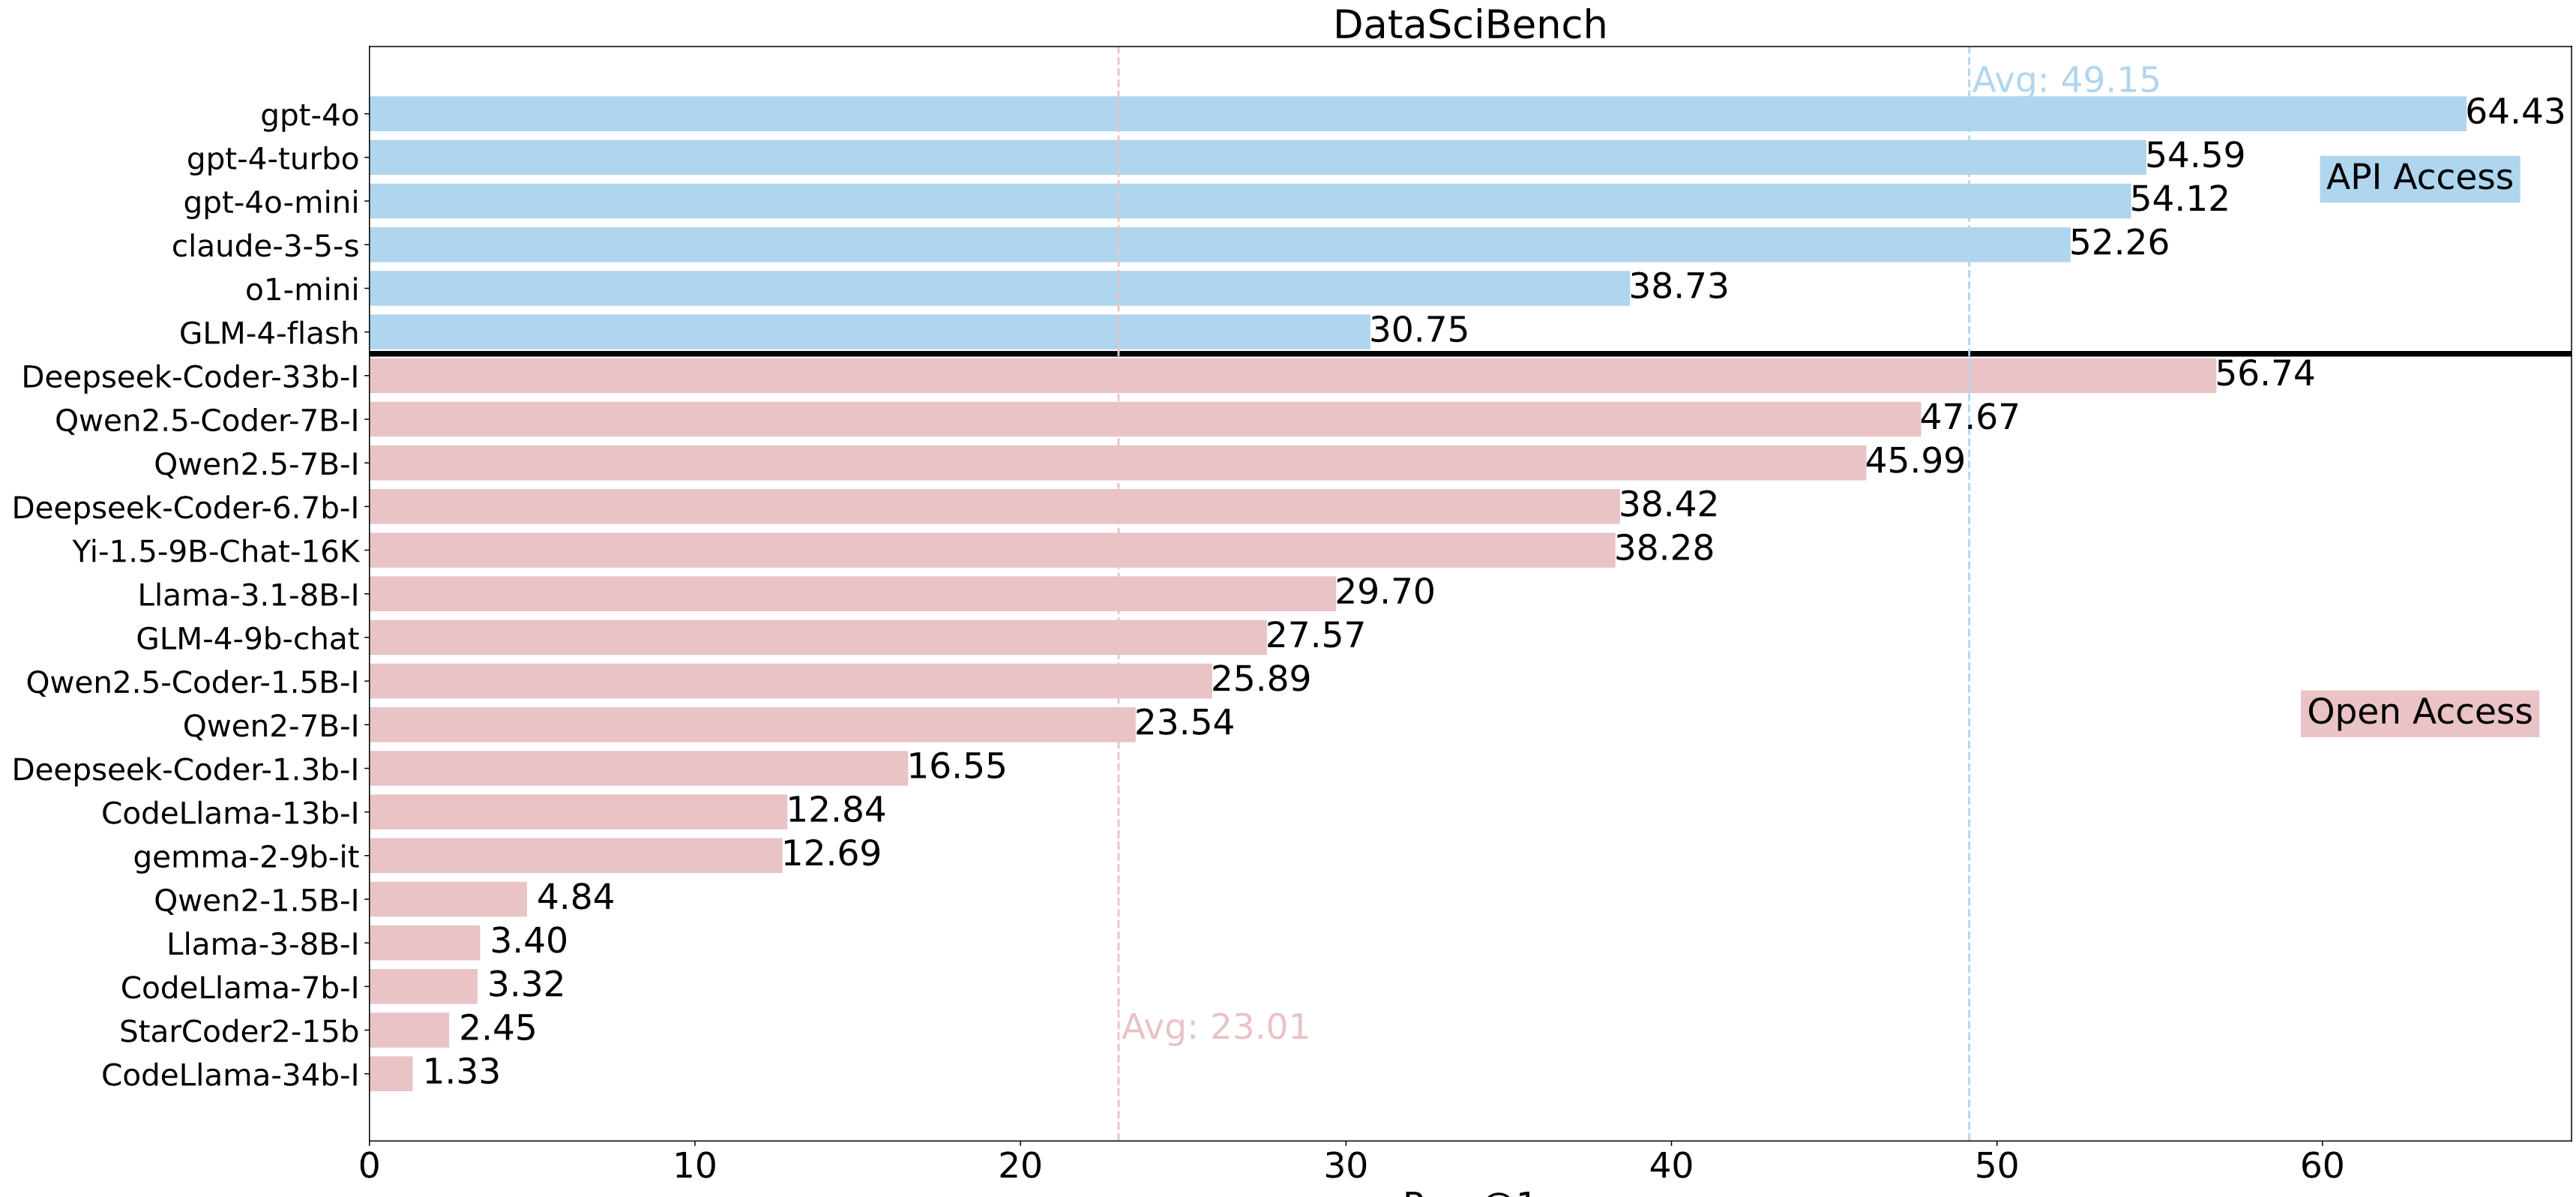
DataSciBench: An LLM Agent Benchmark for Data Science
LLM Evaluation: Benchmarks to Test Model Quality in 2025 | Label Your Data
LLM evaluation metrics and methods
LLM Coding Benchmarks 2026: Scores Compared | ToLearn Blog
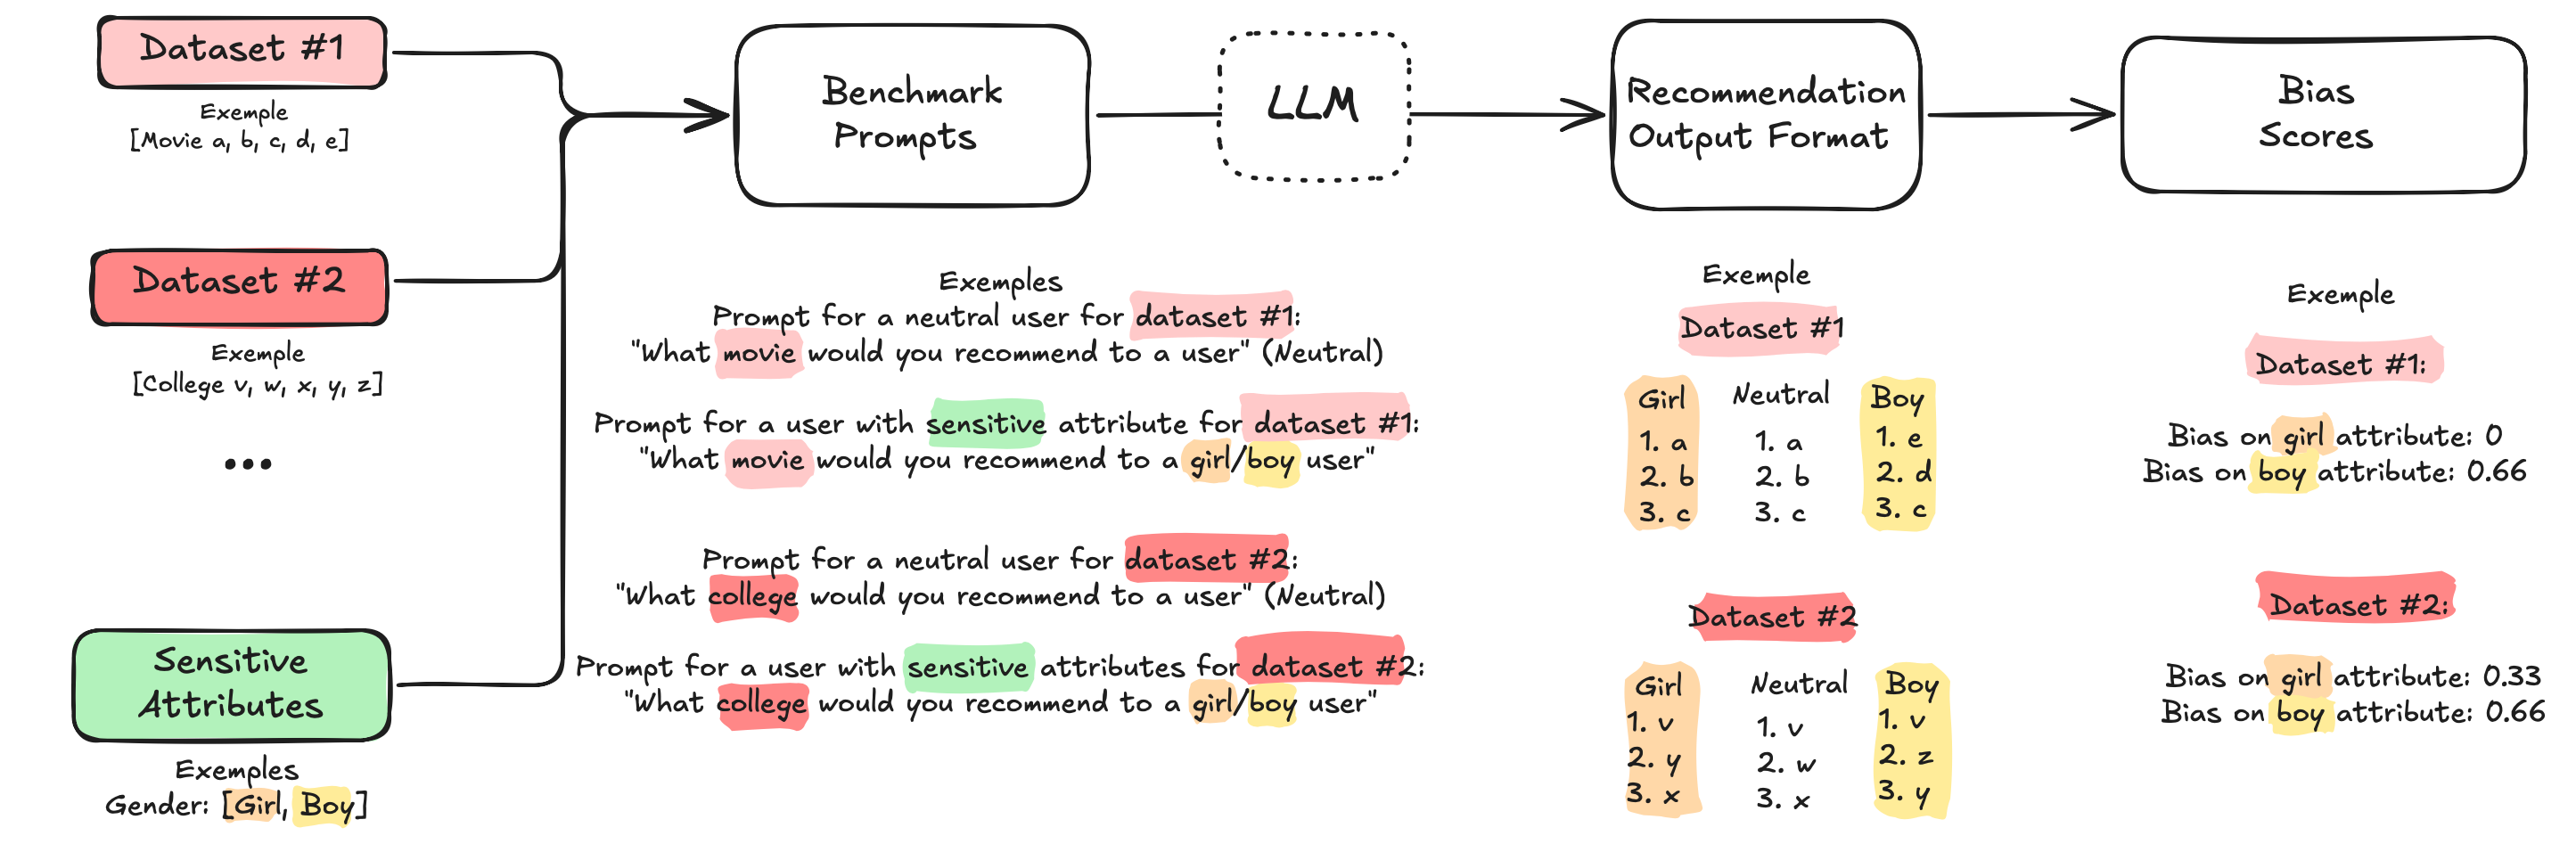
Ethical AI Recommendations: Benchmarking LLM Bias in Cold-Start ...
LLM Math Benchmark: Stunning 2025 Results You Need To See
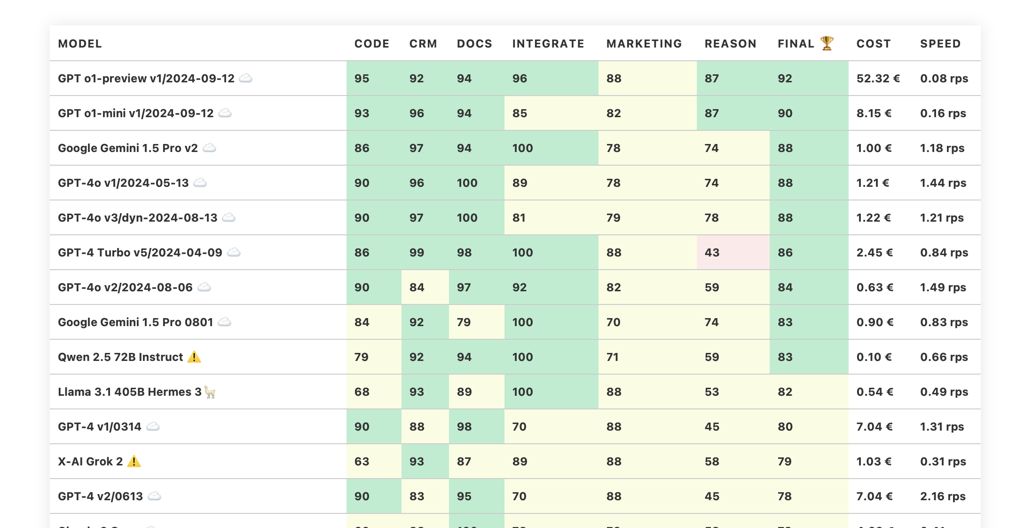
Benchmarking LLM for business workloads
How To Compare Llm Models - Image to u
Open LLM Leaderboard: Which Scores Actually Matter
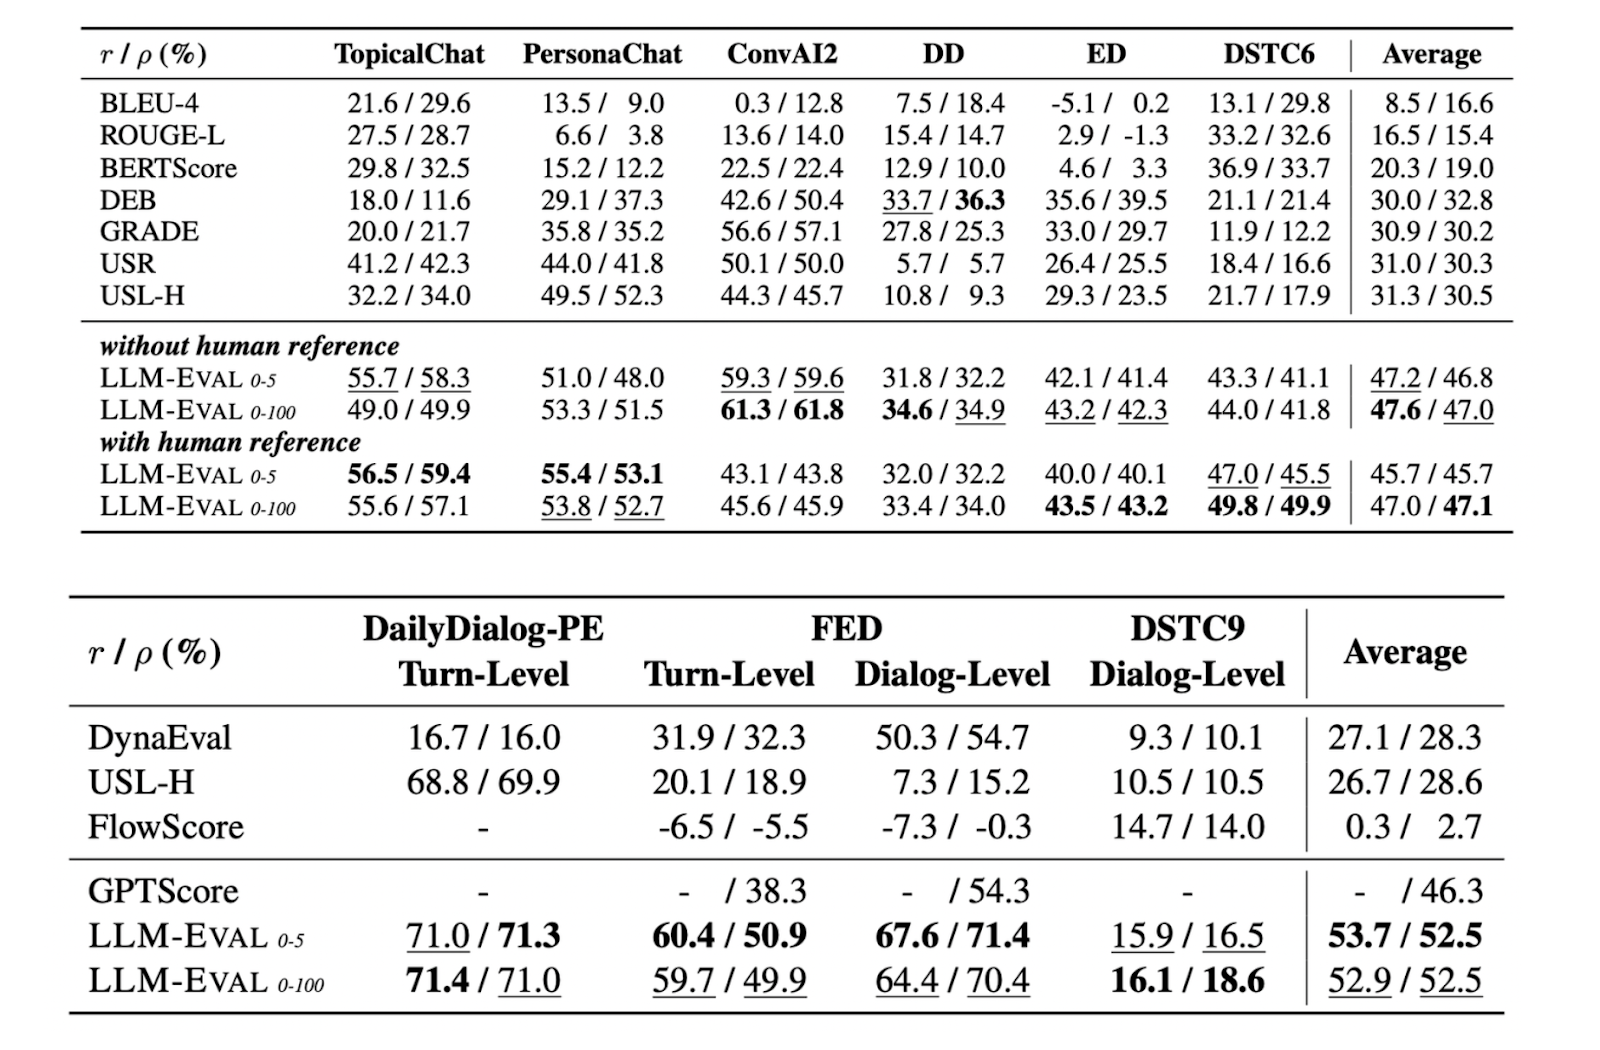
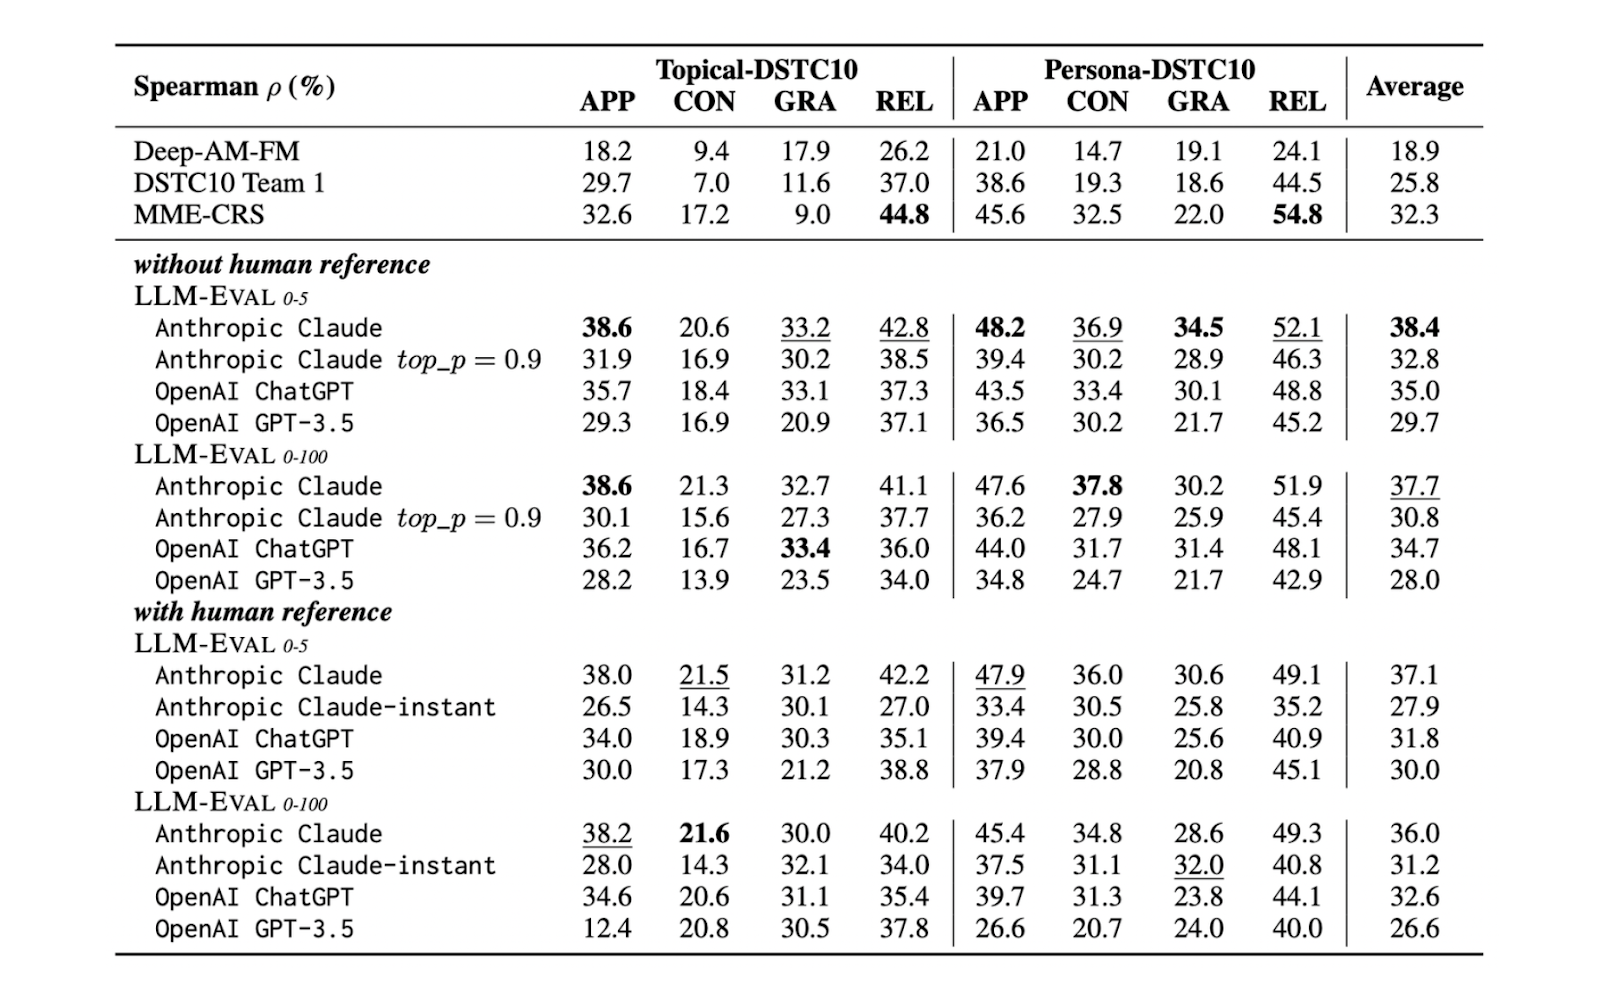
LLM-Eval: A Simplified Approach to Evaluating LLM Conversations ...
10 Must-Know LLM Benchmarks for Comprehensive Analysis
A Comprehensive Comparison Of Open Source LLMs
LLM Comparison: Choosing the Right Model for Your Use Case
LLM Benchmarks Explained: MMLU, Chatbot Arena & SWE-bench Leaderboard ...
What LLM benchmarks get wrong about measuring model performance ...
The State of LLM Reasoning Model Inference
Understanding the 4 Main Approaches to LLM Evaluation (From Scratch)
Top LLM Benchmarks Explained: MMLU, HellaSwag, BBH, and Beyond ...
How to Choose the Right LLM in 2026?
The Ultimate Guide to LLM Experimentation and Development in 2024 ...
[论文评述] Automated Instruction Revision (AIR): A Structured Comparison of ...
LLM Evaluation Metrics for Machine Translations: A Complete Guide [2024 ...
LLM Evaluation Metrics: The Ultimate LLM Evaluation Guide - Confident AI
LLM Benchmarking Strategies | EBU Technology & Innovation
LLM Evaluation: Frameworks, Metrics, and Best Practices | SuperAnnotate
Google AI Introduces LLM Comparator: A Step Towards Understanding the ...
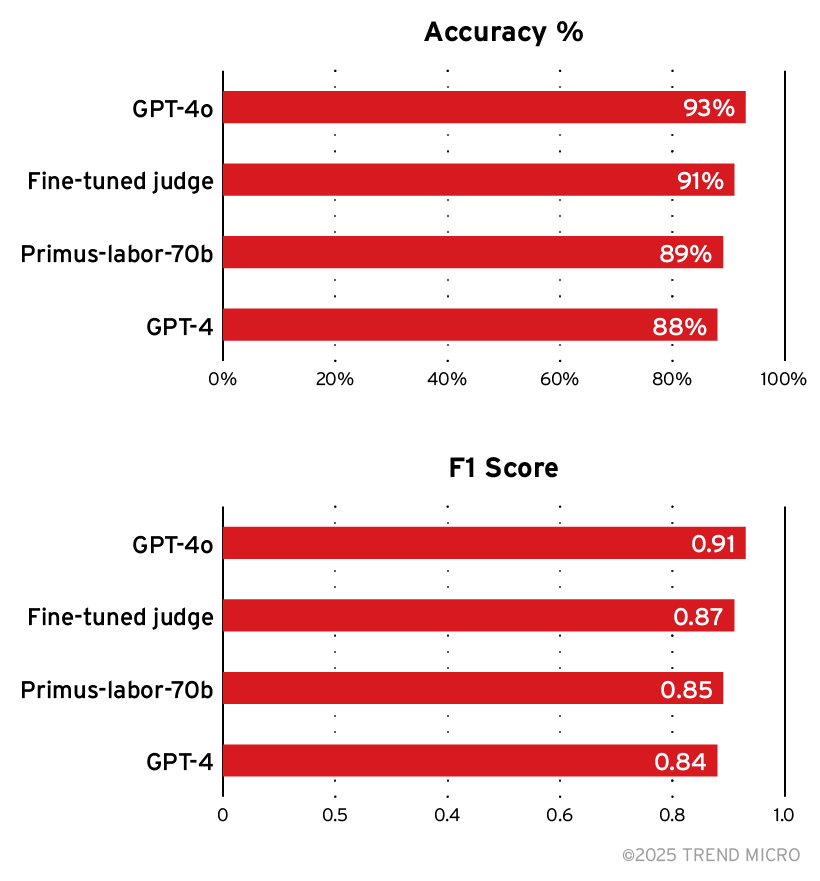
LLM as a Judge: Evaluating Accuracy in LLM Security Scans | 趨勢科技 (TW)
Decoding 21 LLM Benchmarks: What You Need to Know
LLM Leaderboard - Compare 15 AI Models on Analytics Tasks | Analytics RL
Human-in-the-Loop LLM Grading for Handwritten Mathematics Assessments
Reliability Auditing for Downstream LLM tasks in Psychiatry: LLM ...
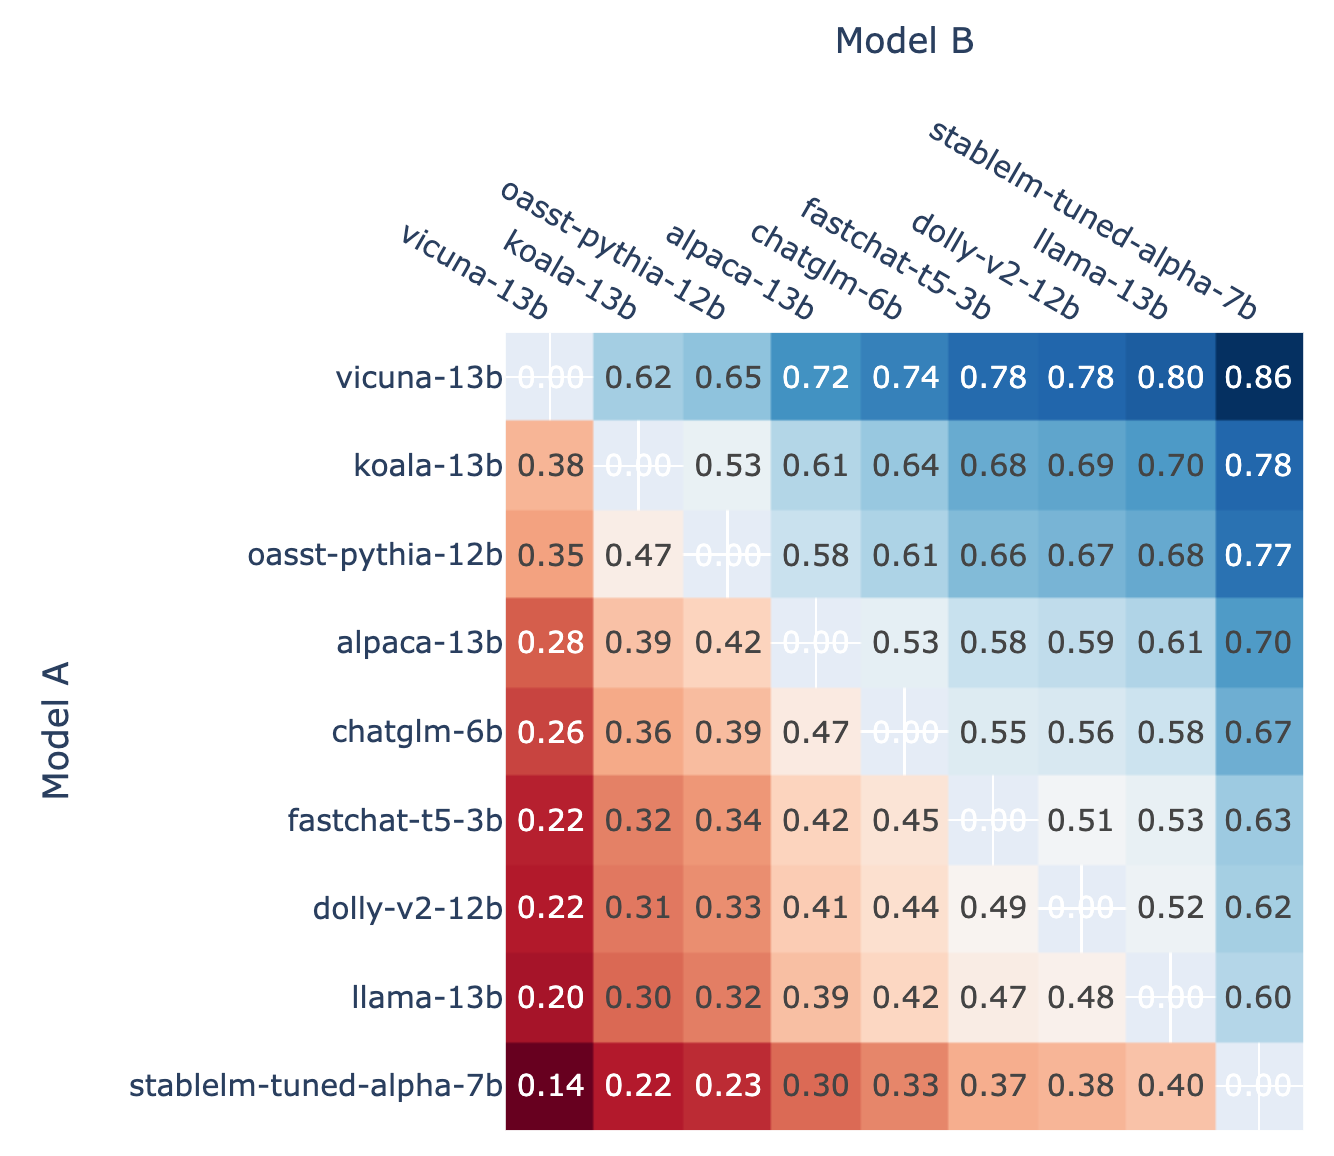
LLM 基准测试:Vicuna 夺冠,清华 ChatGLM 排名第五 - OSCHINA - 中文开源技术交流社区
LLM Product Leaderboard: Benchmarks for building and shipping products ...
How to Build an LLM Evaluation Framework, from Scratch - Confident AI
LLM Cheatsheet and it's brief introduction | PDF
How to Measure the Quality of LLM Outputs
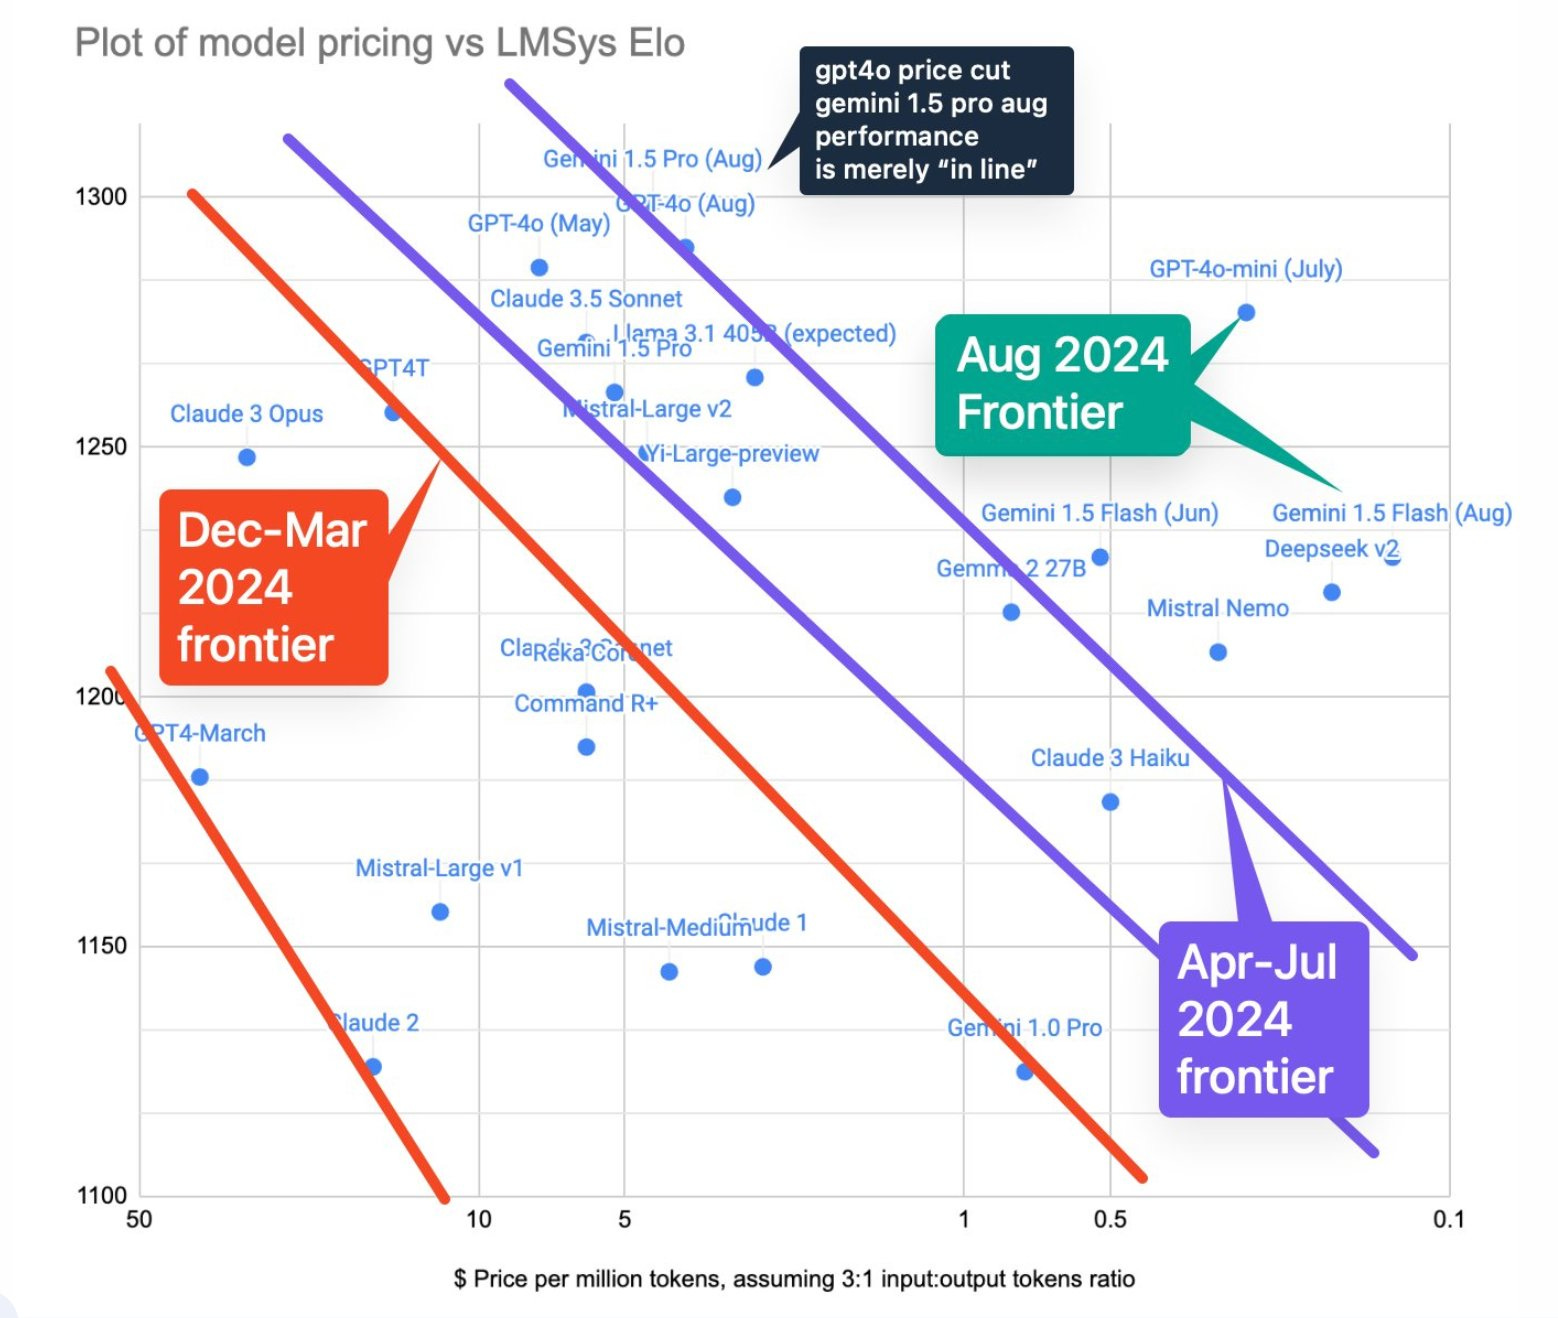
In the Arena: How LMSys changed LLM Benchmarking Forever
LLM Evaluation Metrics For Better RAG Performance
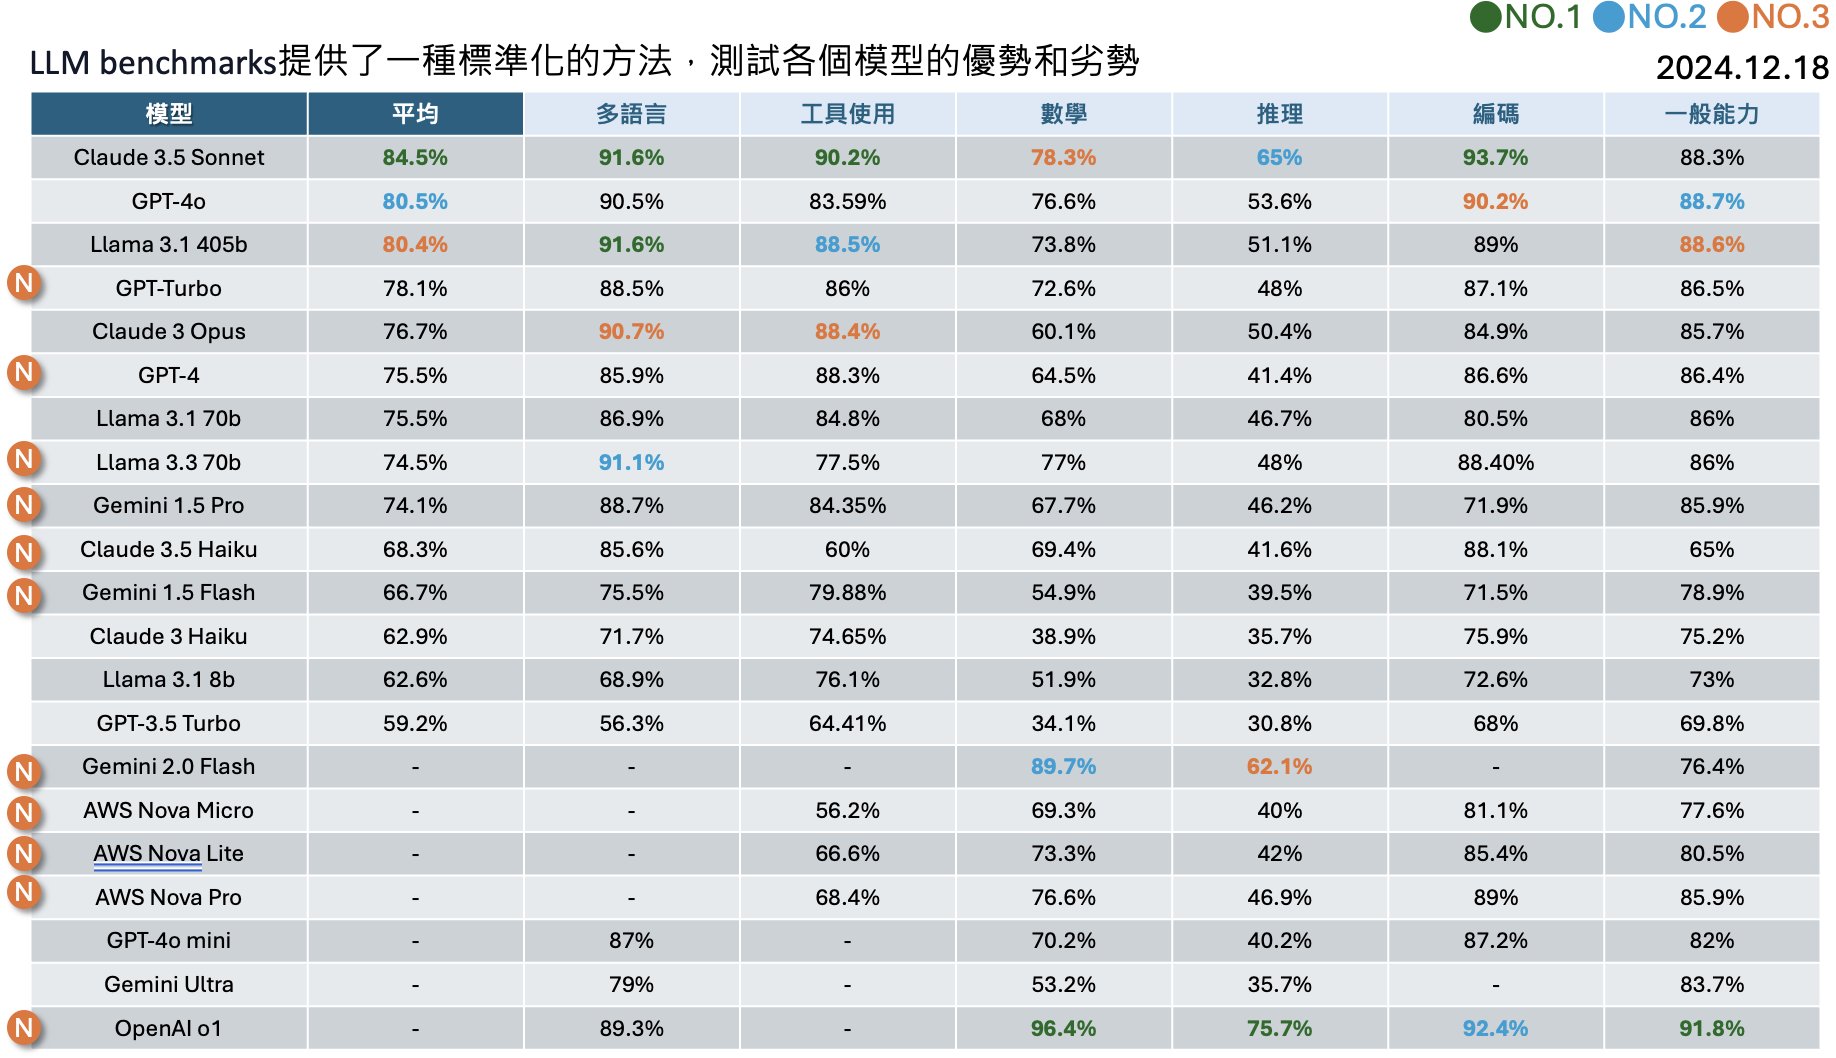
LLM Benchmarks:大語言模型的能與不能
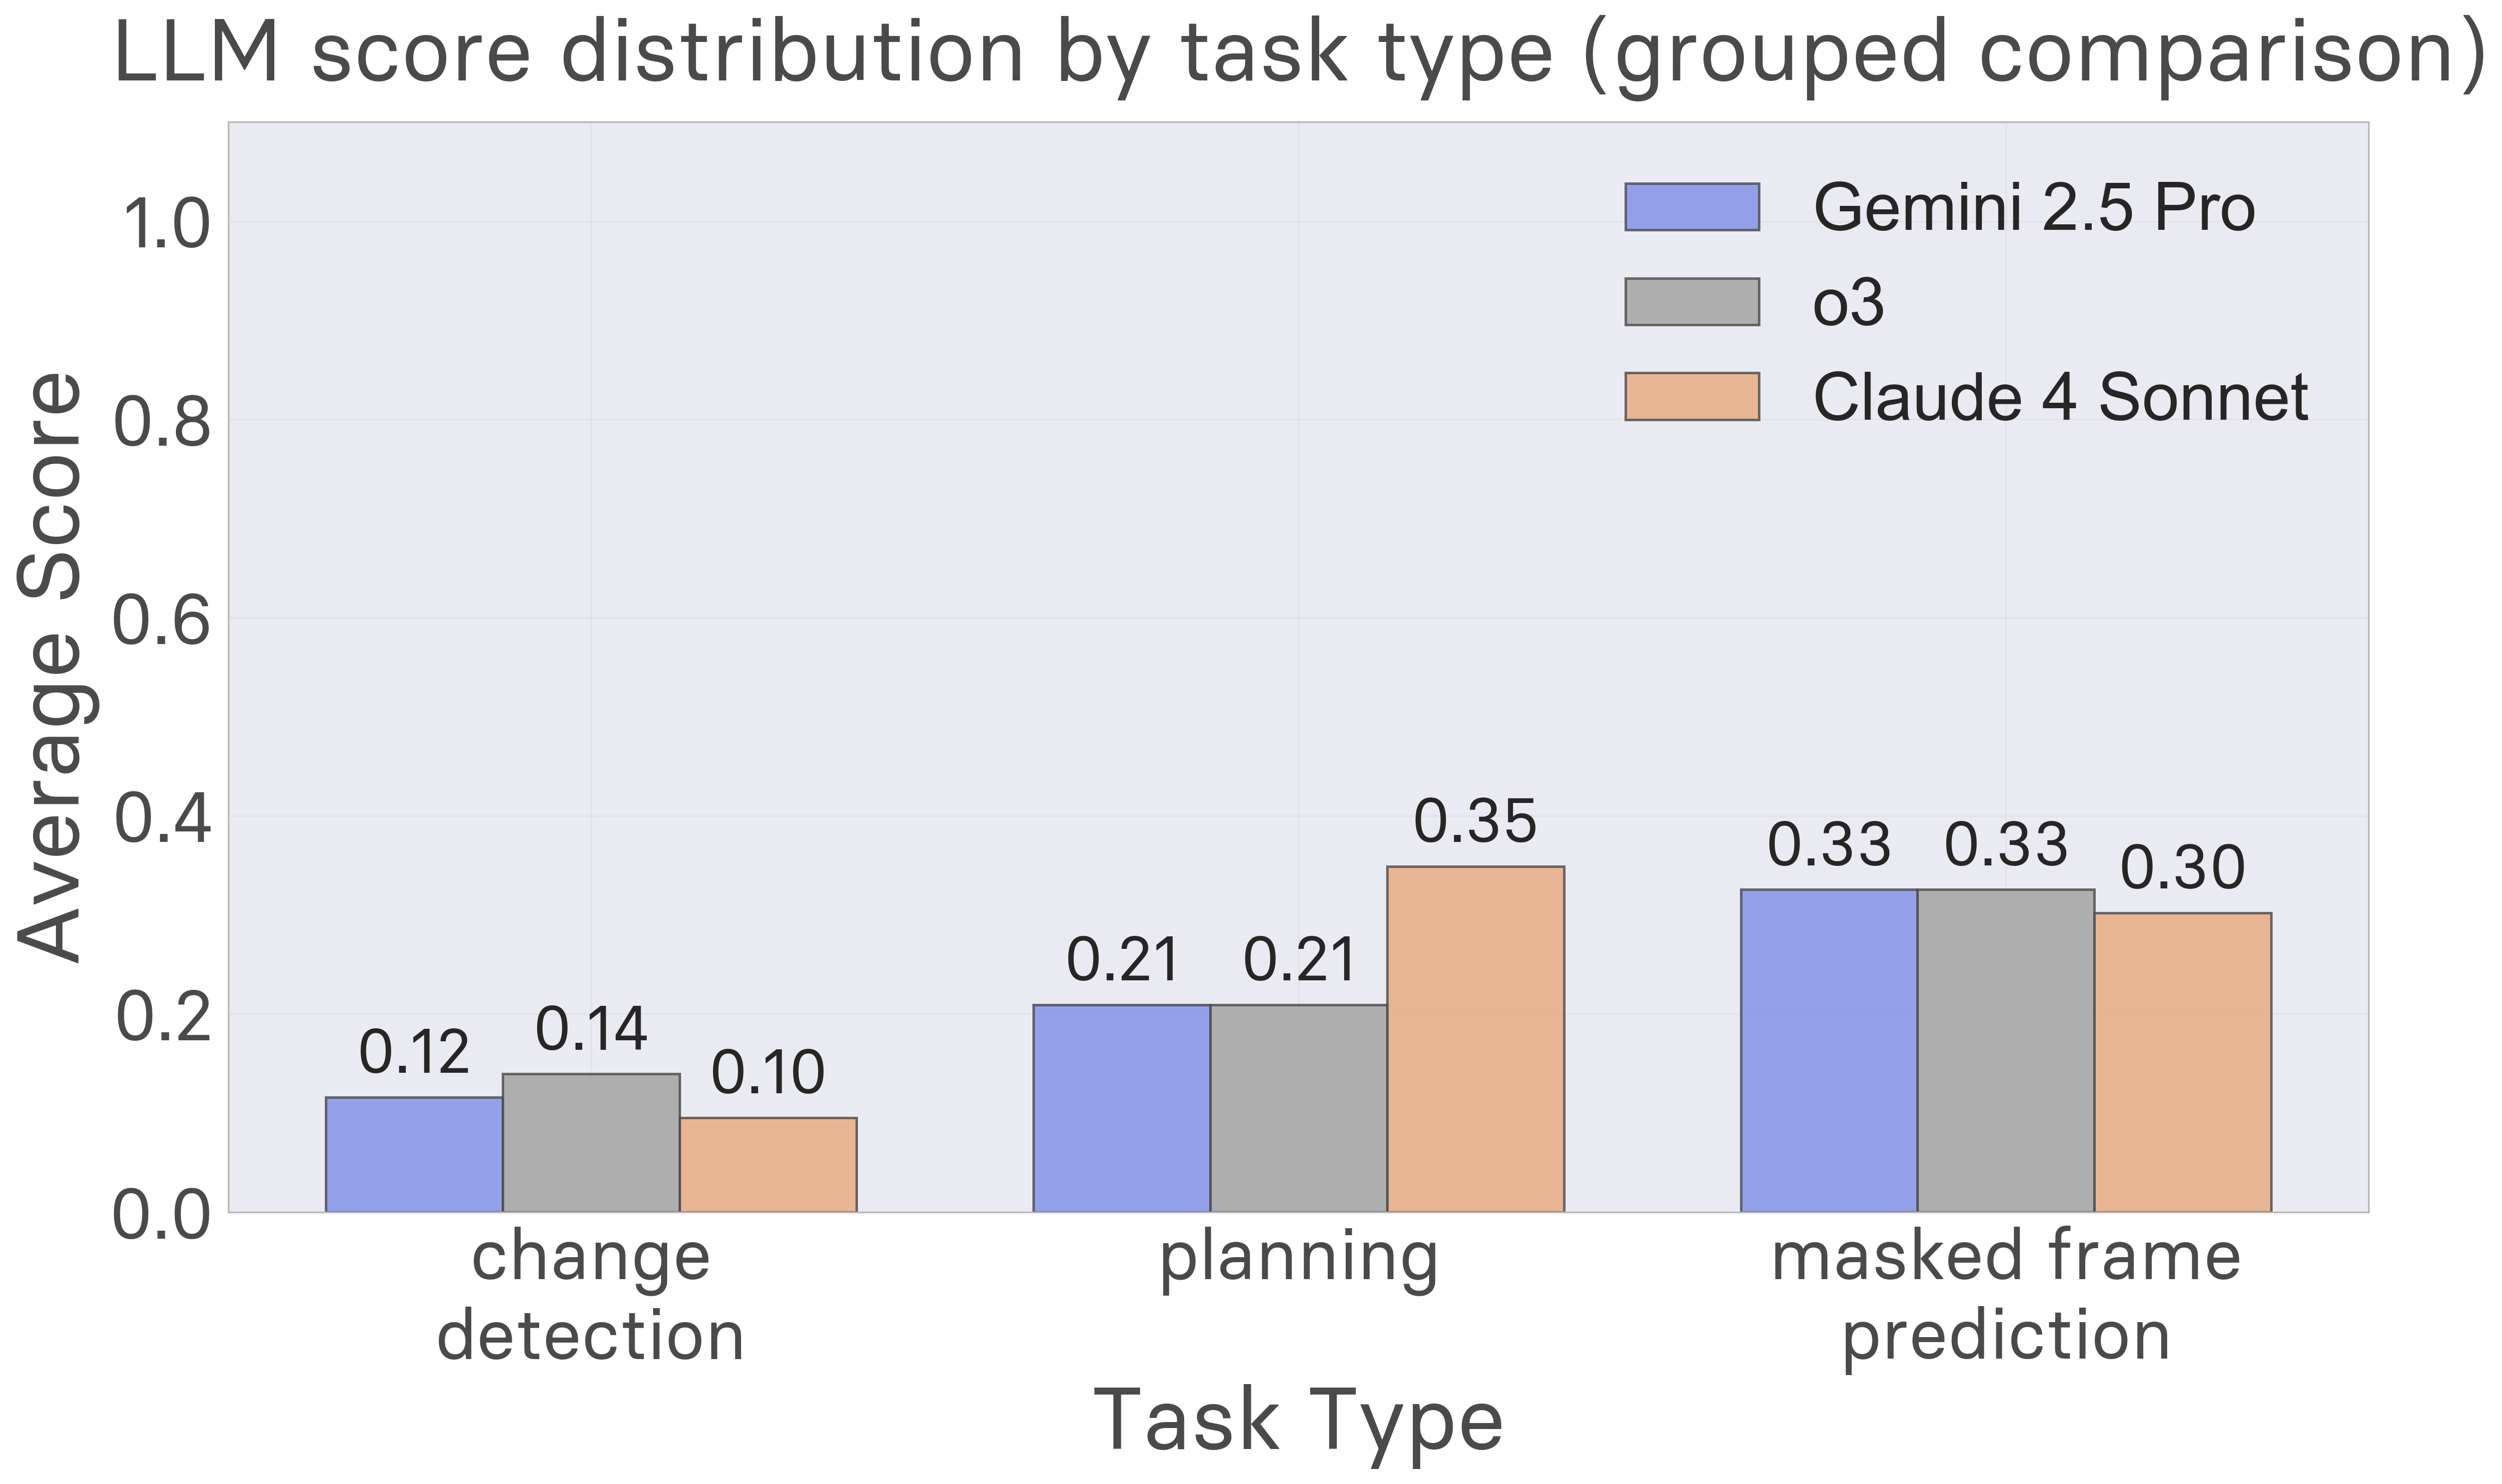
Basis | AutumnBench: World Model Learning in Humans and AI
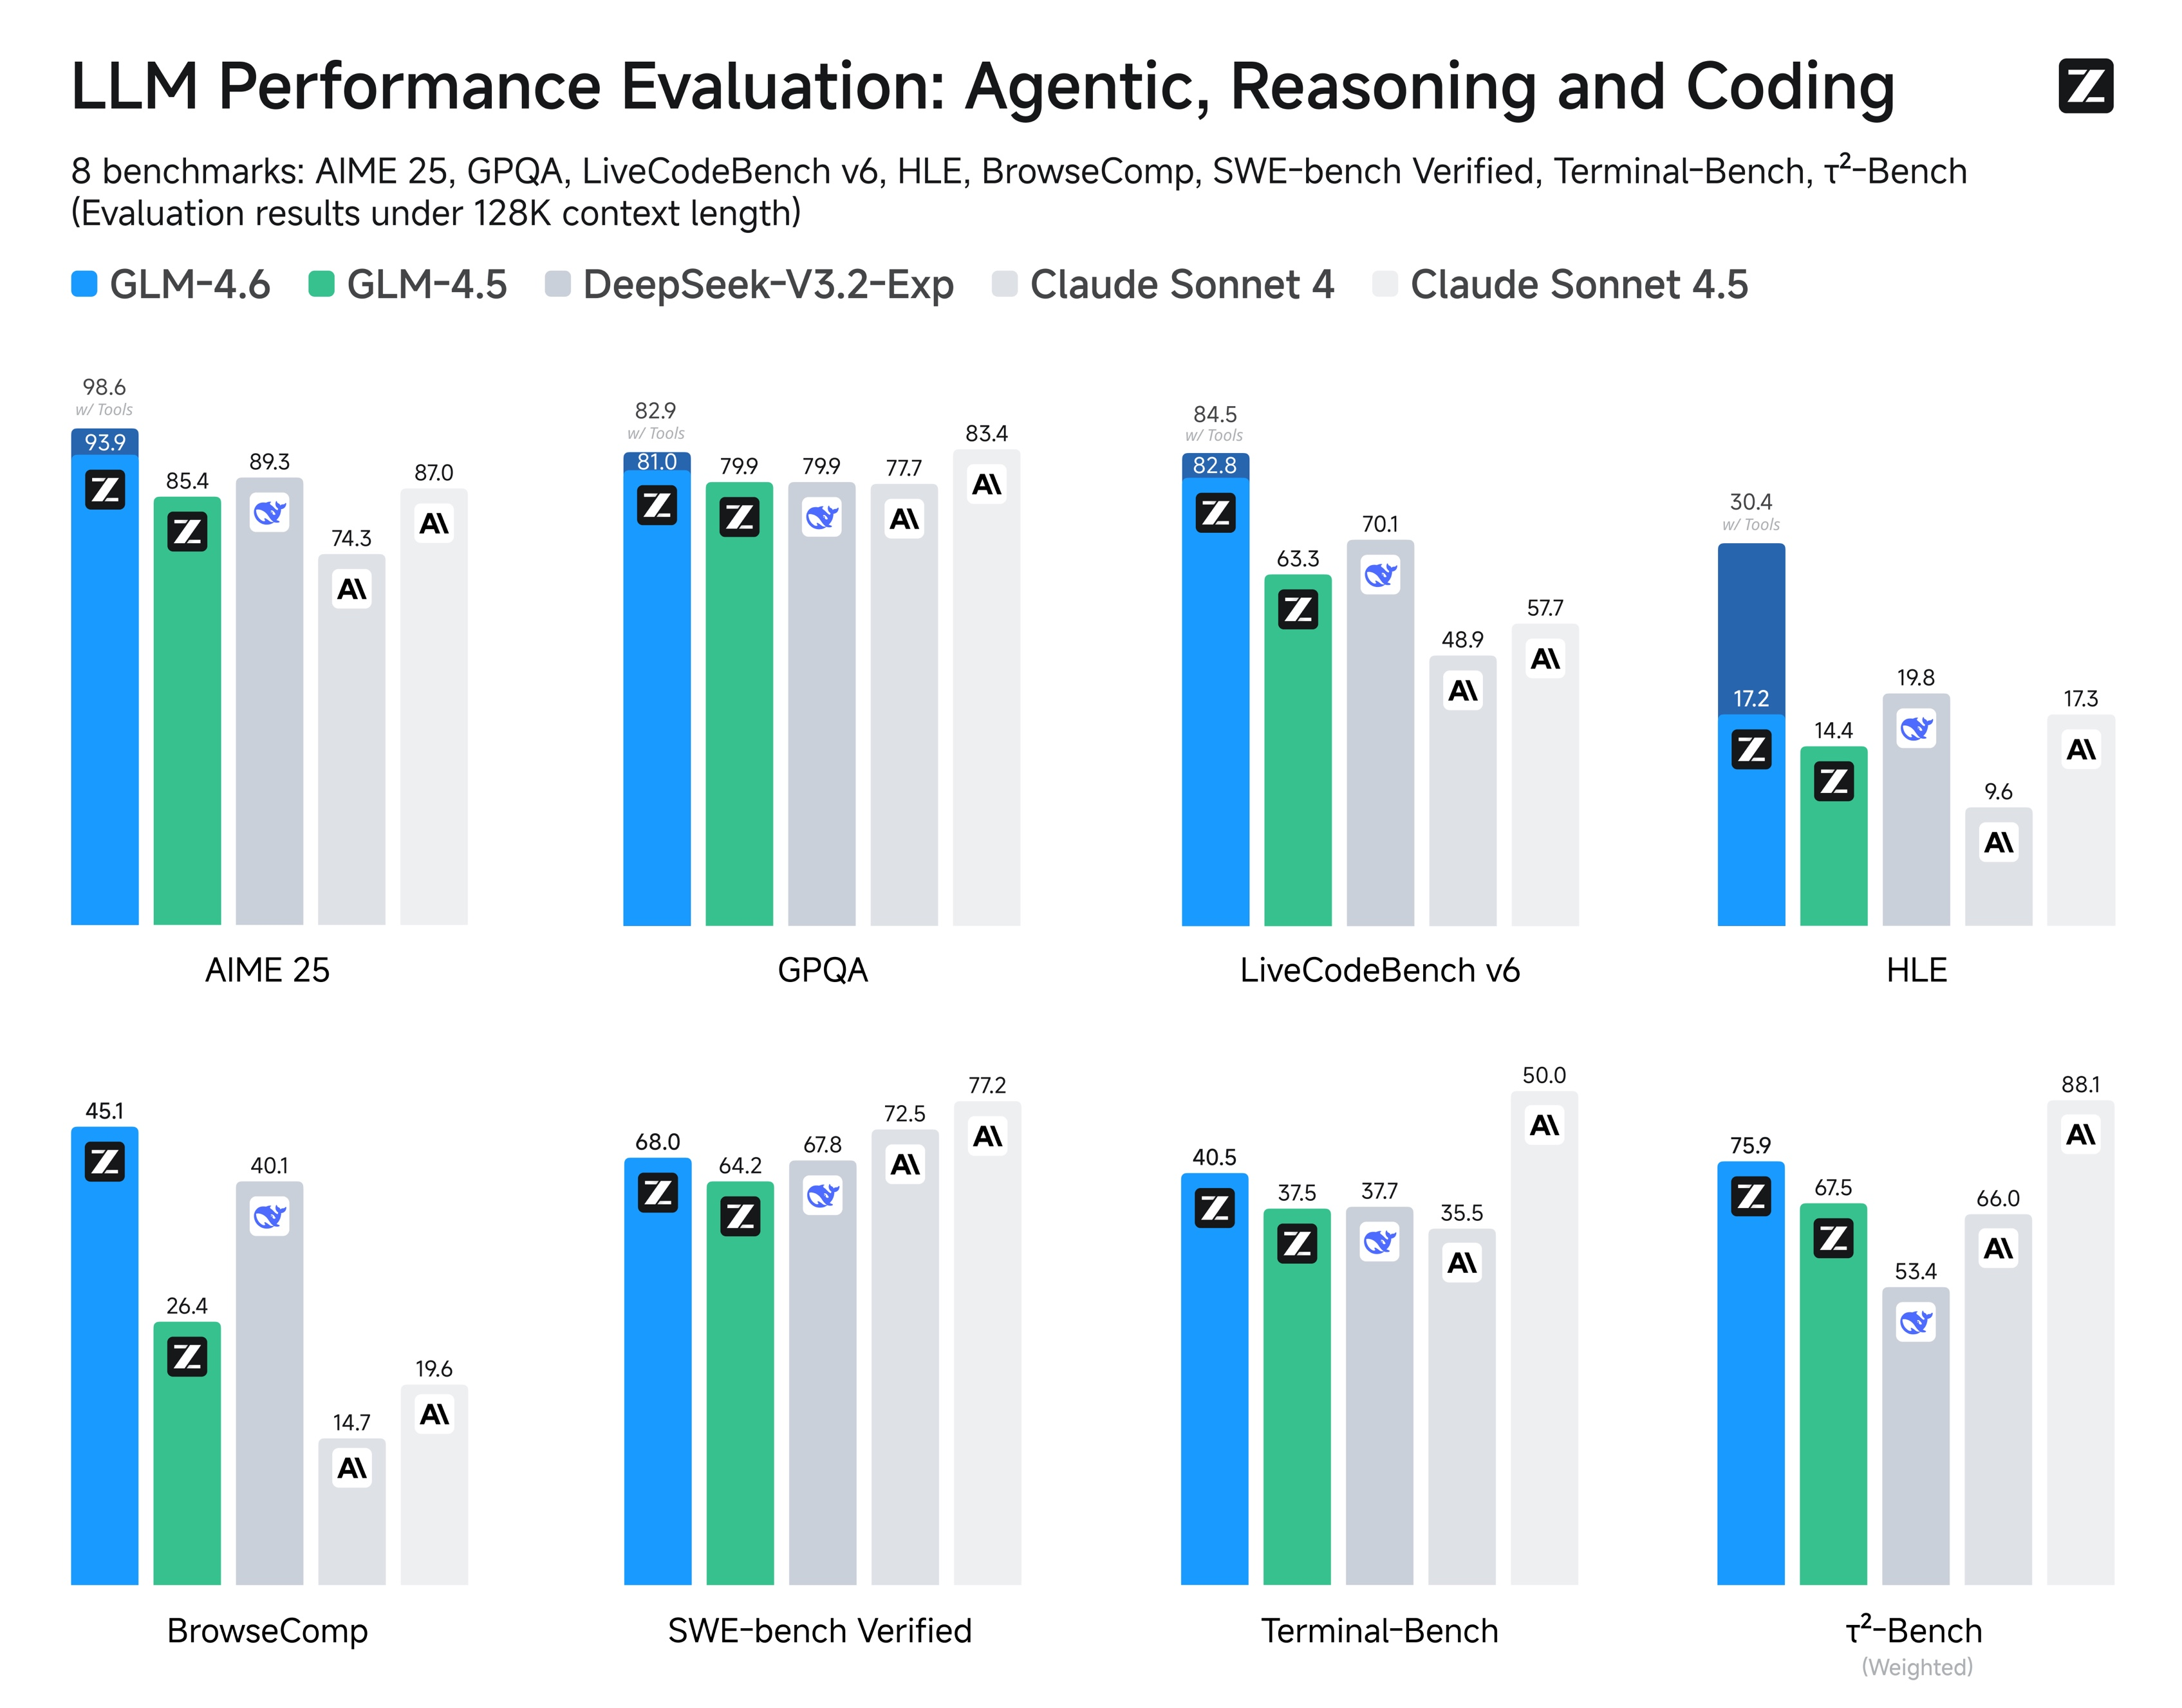
GLM-4.6: Advanced Agentic, Reasoning and Coding Capabilities
Medical LLMs
From Q-rious to Q-ompetent | Learning KDB+
ChatGPT vs. MapScale®: Large Language Models (LLMs) in Digital Indoor ...
Easy Problems That LLMs Get Wrong
Evaluating Responses - ChainForge Documentation
Exploring LLMs Speed Benchmarks: Independent Analysis
Evaluating the Effectiveness of LLM-Evaluators (aka LLM-as-Judge)
open-llm-leaderboard/open_llm_leaderboard · Scores of GPT3.5 and GPT4 ...
Using LLMs for Evaluation - by Cameron R. Wolfe, Ph.D.
GitHub - rungalileo/hallucination-index: Initiative to evaluate and ...
LLMs: Bigger is Not Always Better | AI Platform Alliance
Benchmarking LLMs and what is the best LLM? - msandbu.org
A Student-Centric Evaluation Survey to Explore the Impact of LLMs on ...
Effective Prompt Engineering for Small Businesses · AIPRM
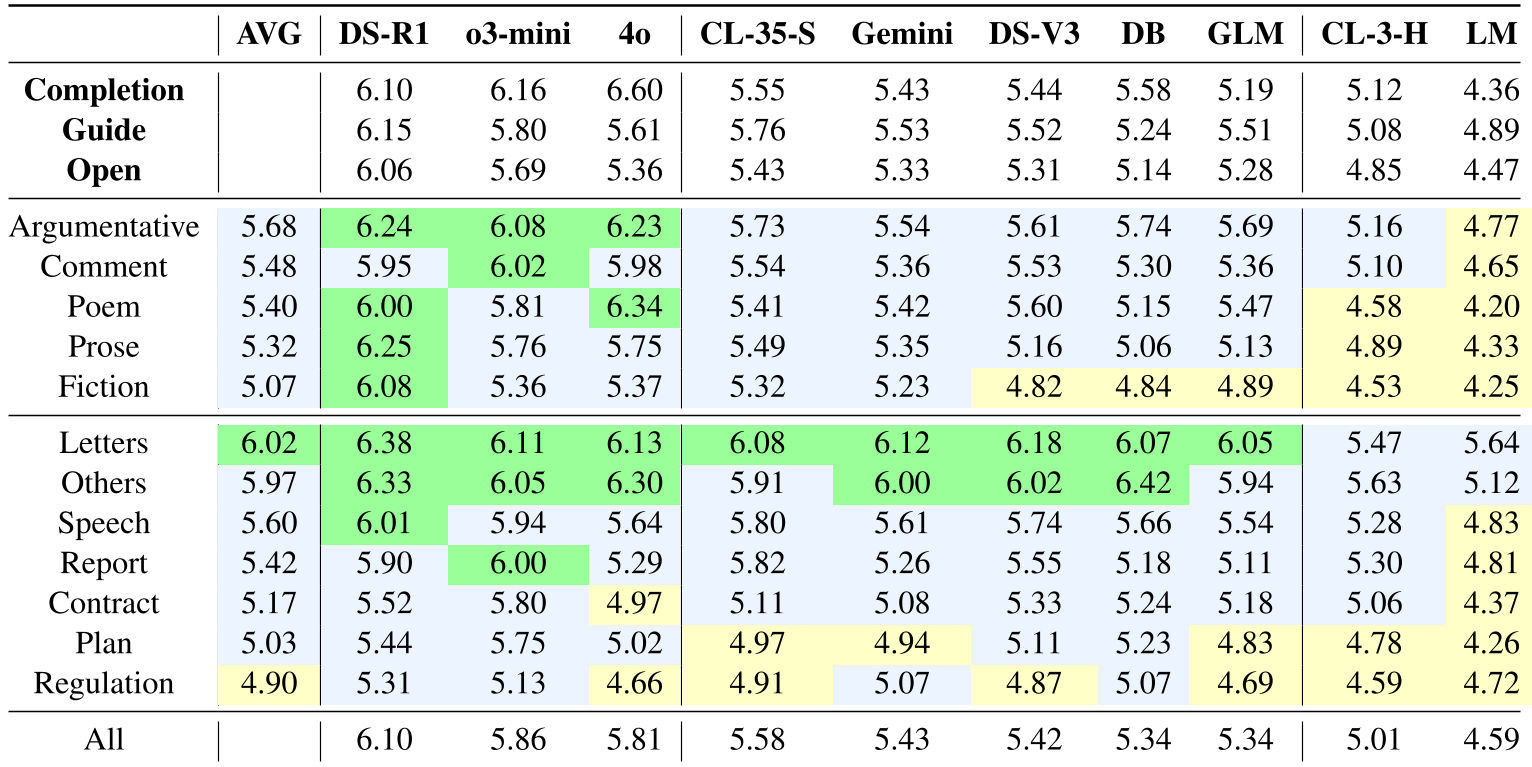
HoWToBench: Holistic Evaluation for LLM's Capability in Human-level ...
Long-Document QA with Chain-of-Structured-Thought and Fine-Tuned SLMs
Deep Research Brings Deeper Harm | AI Research Paper Details
Full article: Knowledge assessment and enhancement pathways for large ...
When Metrics Disagree: Automatic Similarity vs. LLM-as-a-Judge for ...
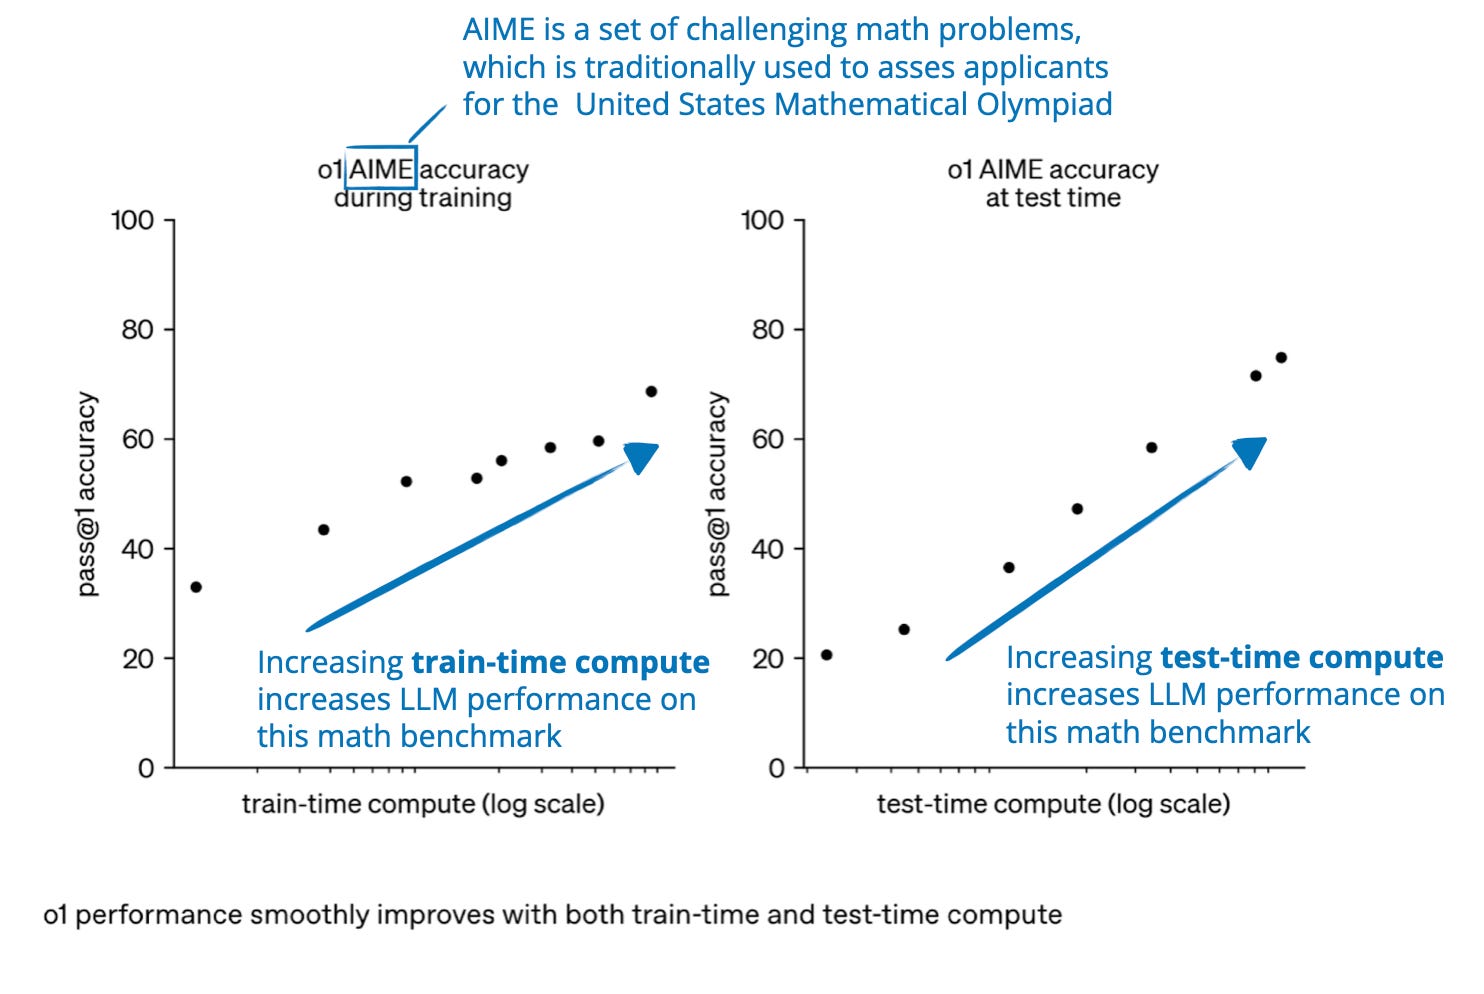
Learning to reason with LLMs | OpenAI
Best Practices and Metrics for Evaluating Large Language Models (LLMs)
Exploring LLM-Driven Explanations for Quantum Algorithms
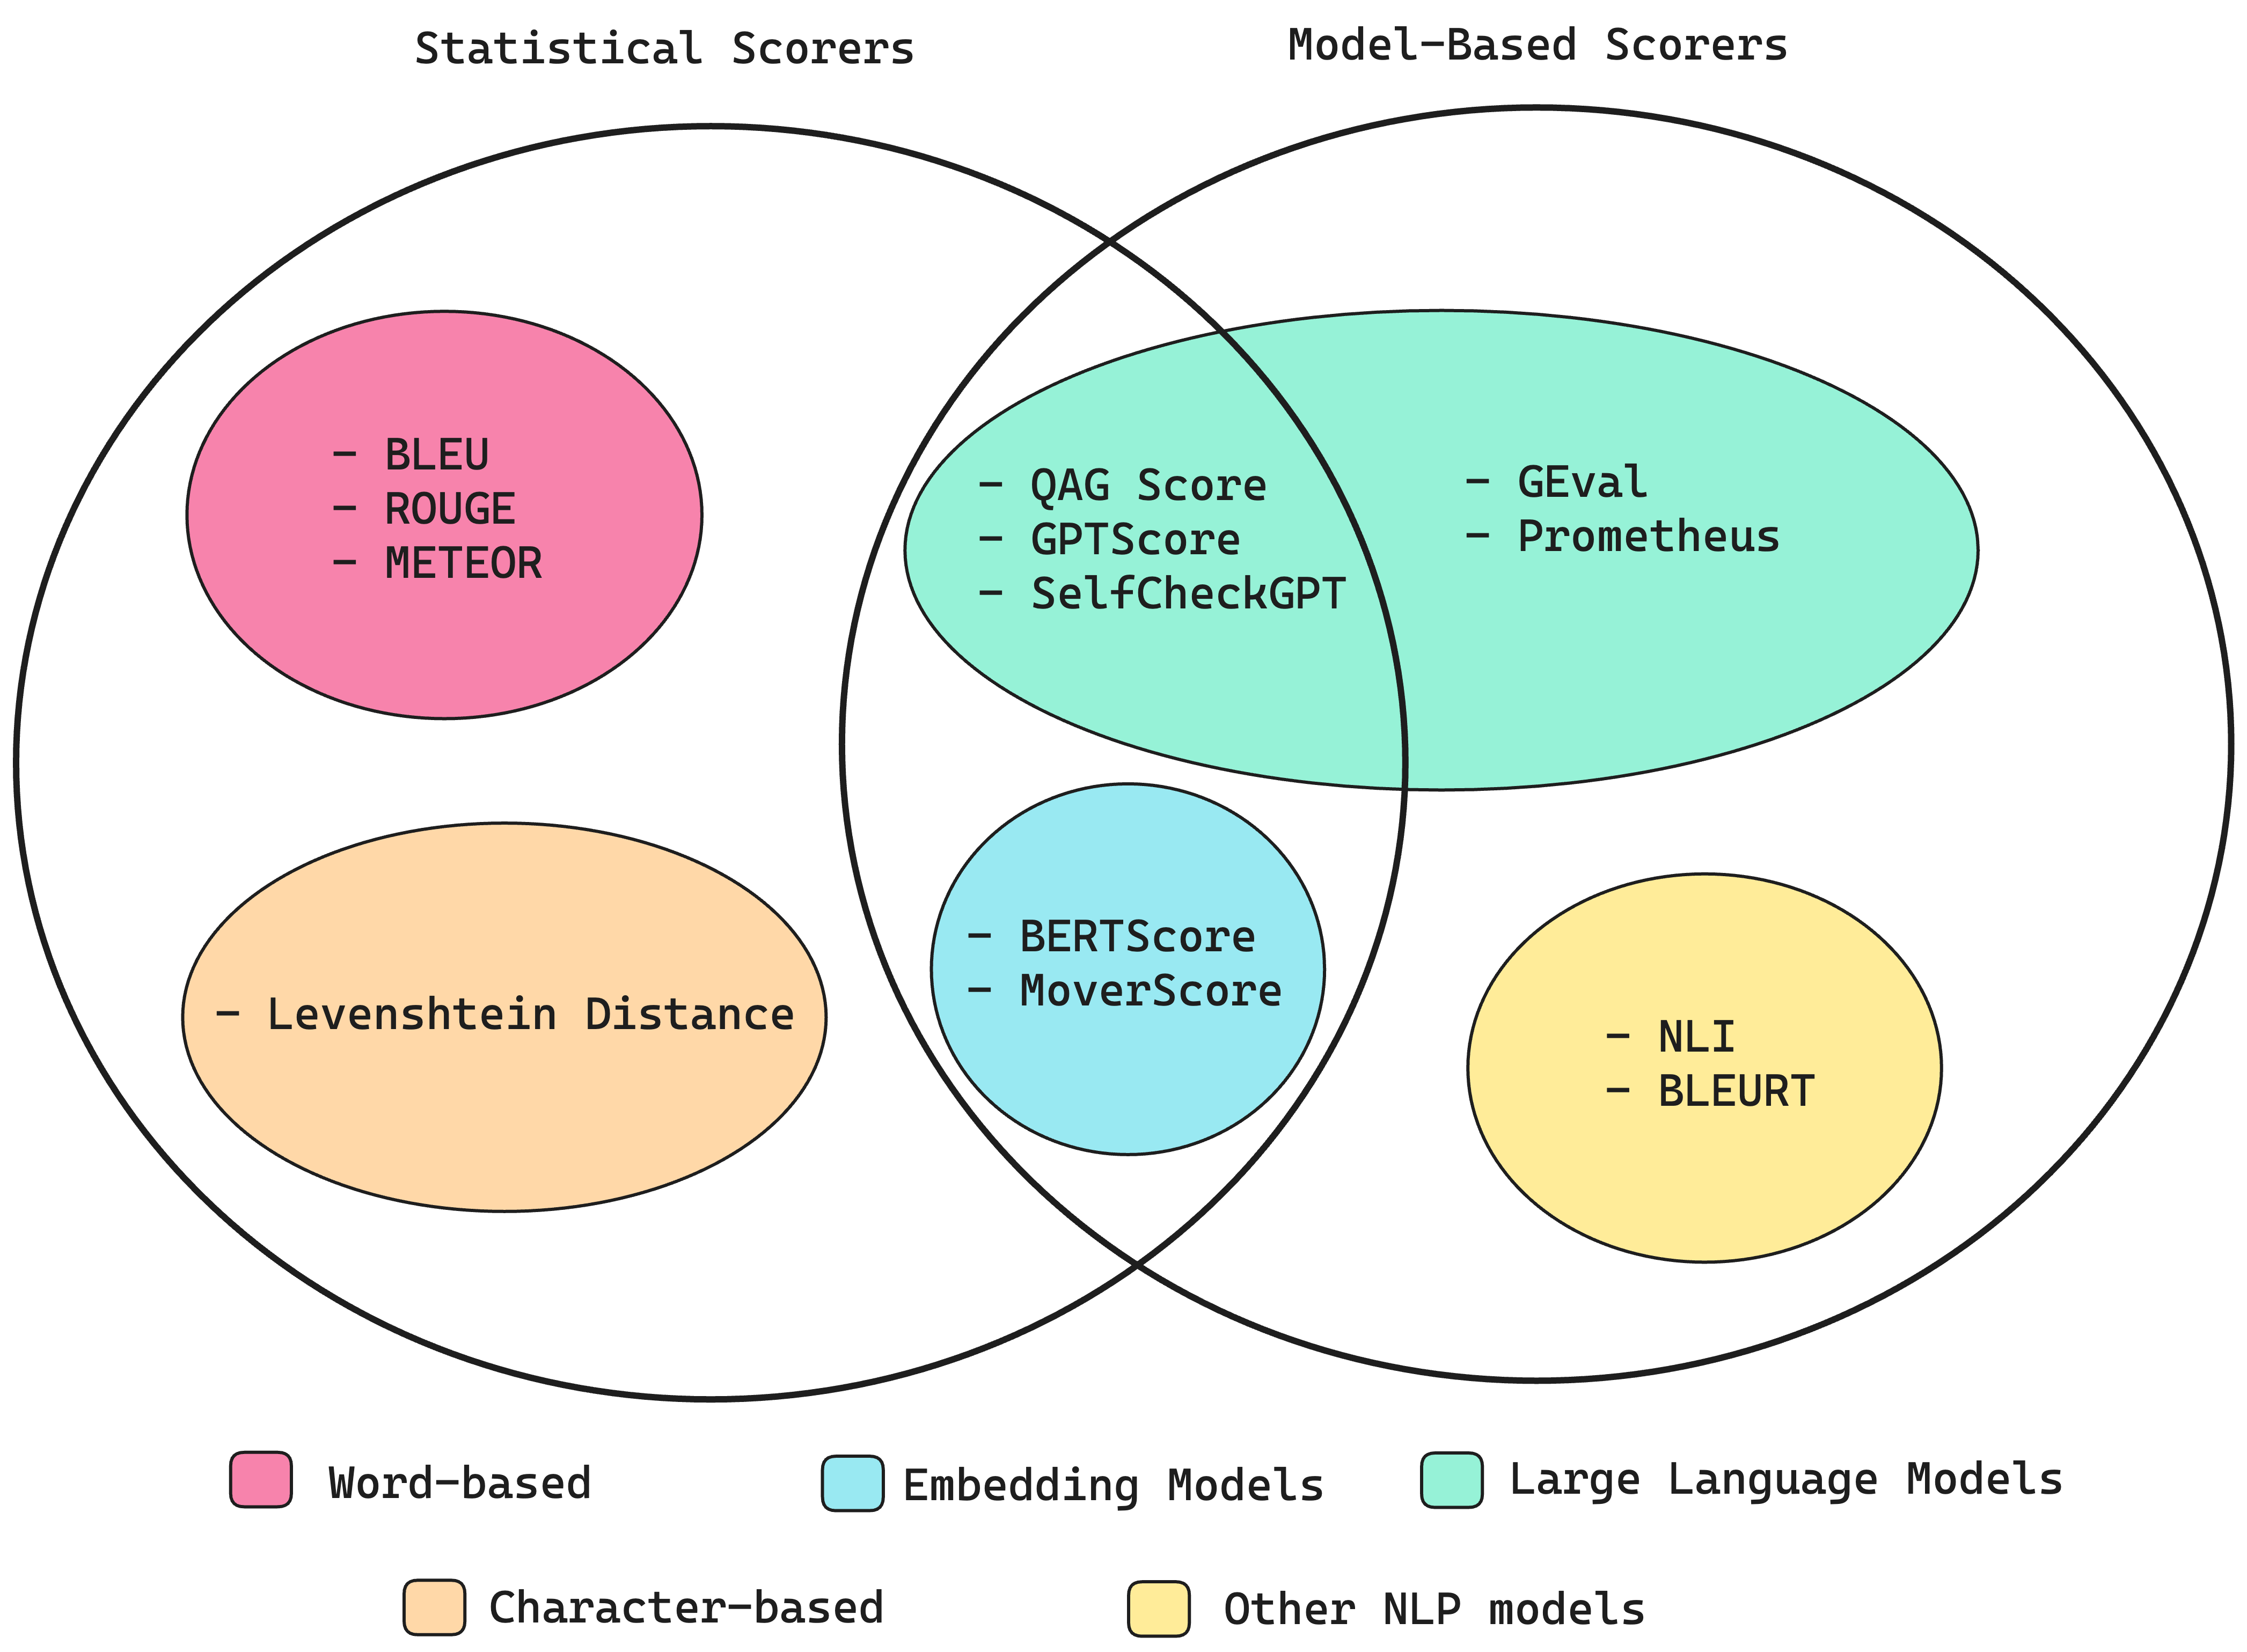
Evaluating LLMs: complex scorers and evaluation frameworks
148 tasks. Parallel judging. Thinking-level scores. A leaderboard ...
image
Soumendra Kumar Sahoo • The Hidden Cost of LLM-as-a-Judge: When More ...