Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
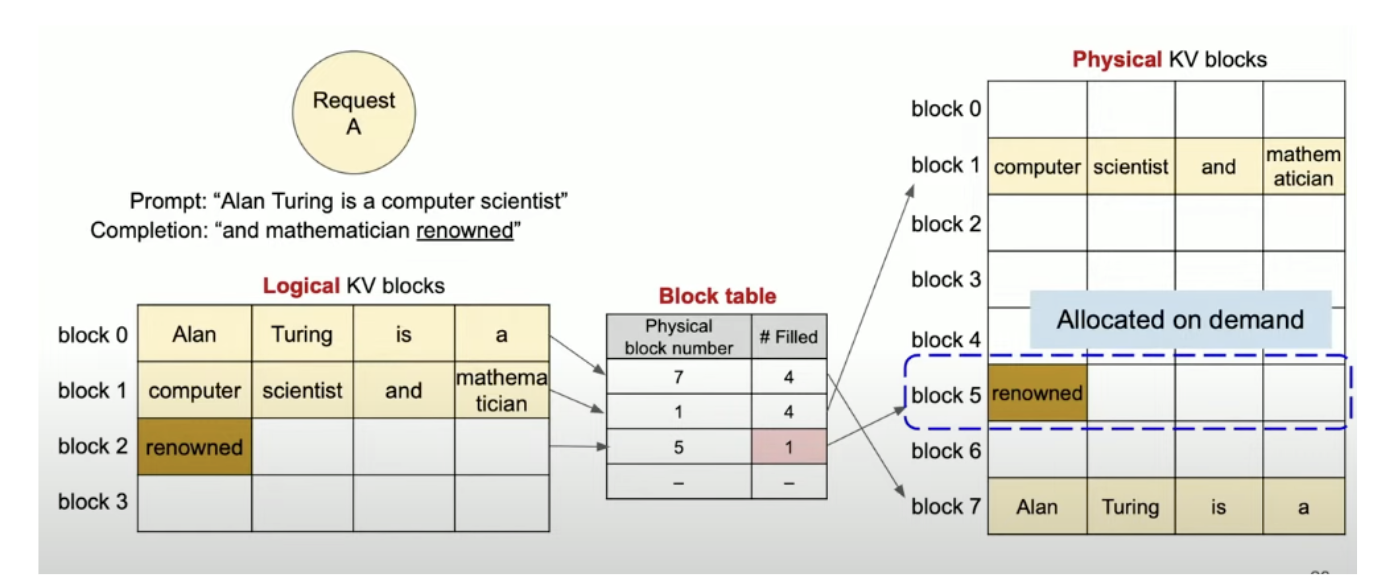
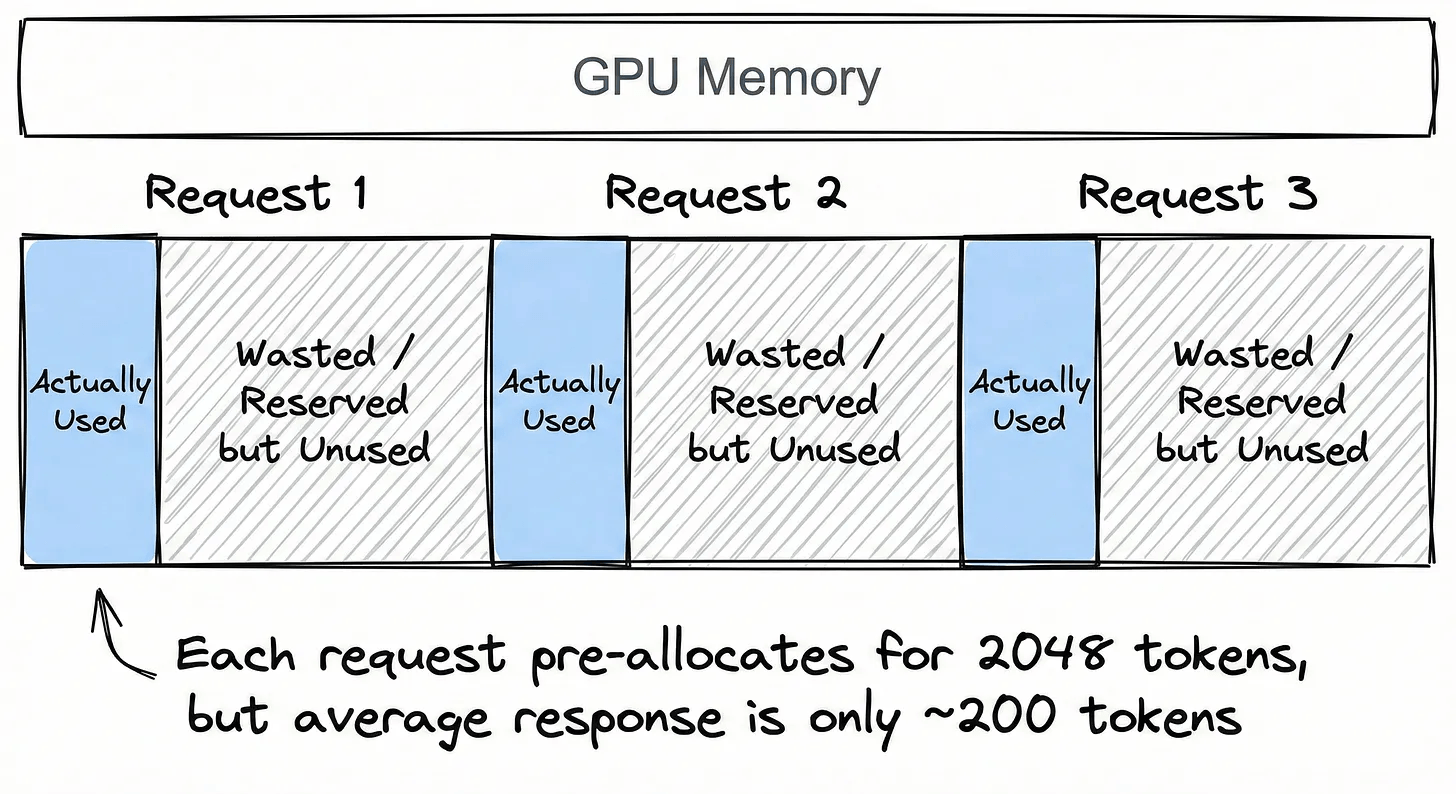
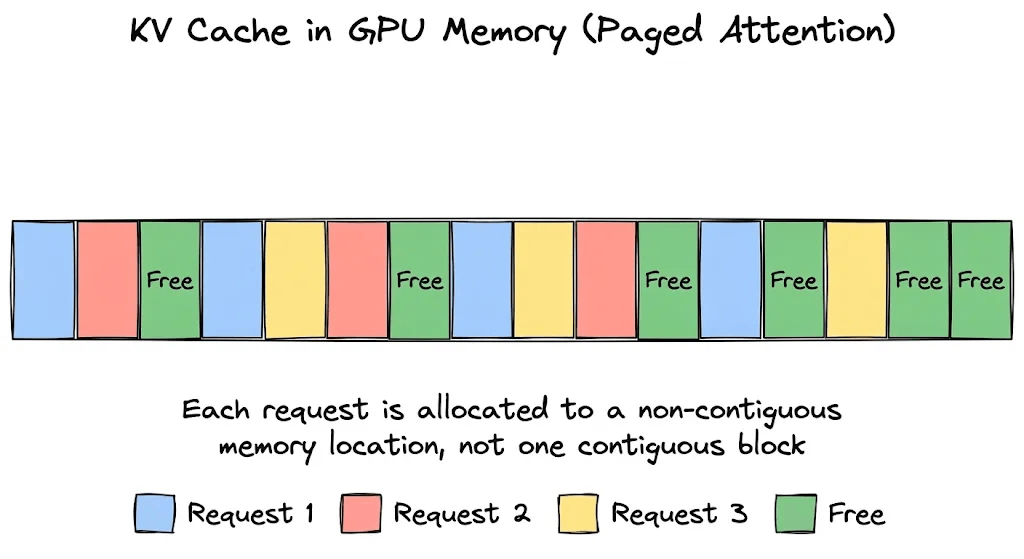
How PagedAttention resolves memory waste of LLM systems | Red Hat Developer
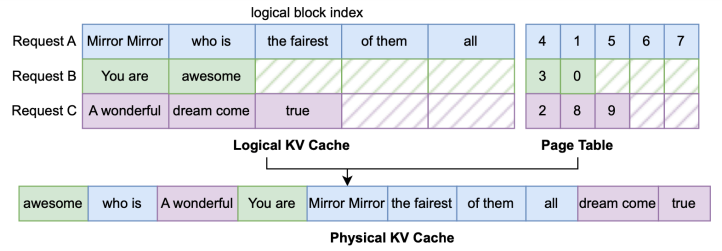
PagedAttention | PagedAttention Architecture Explained | LLM ...
Optimizing LLM Deployment: vLLM PagedAttention and the Future of ...
VLLM: Using PagedAttention To Optimize LLM Inference and Serving ...
LLM Jargons Explained: Part 5 - PagedAttention Explained - YouTube
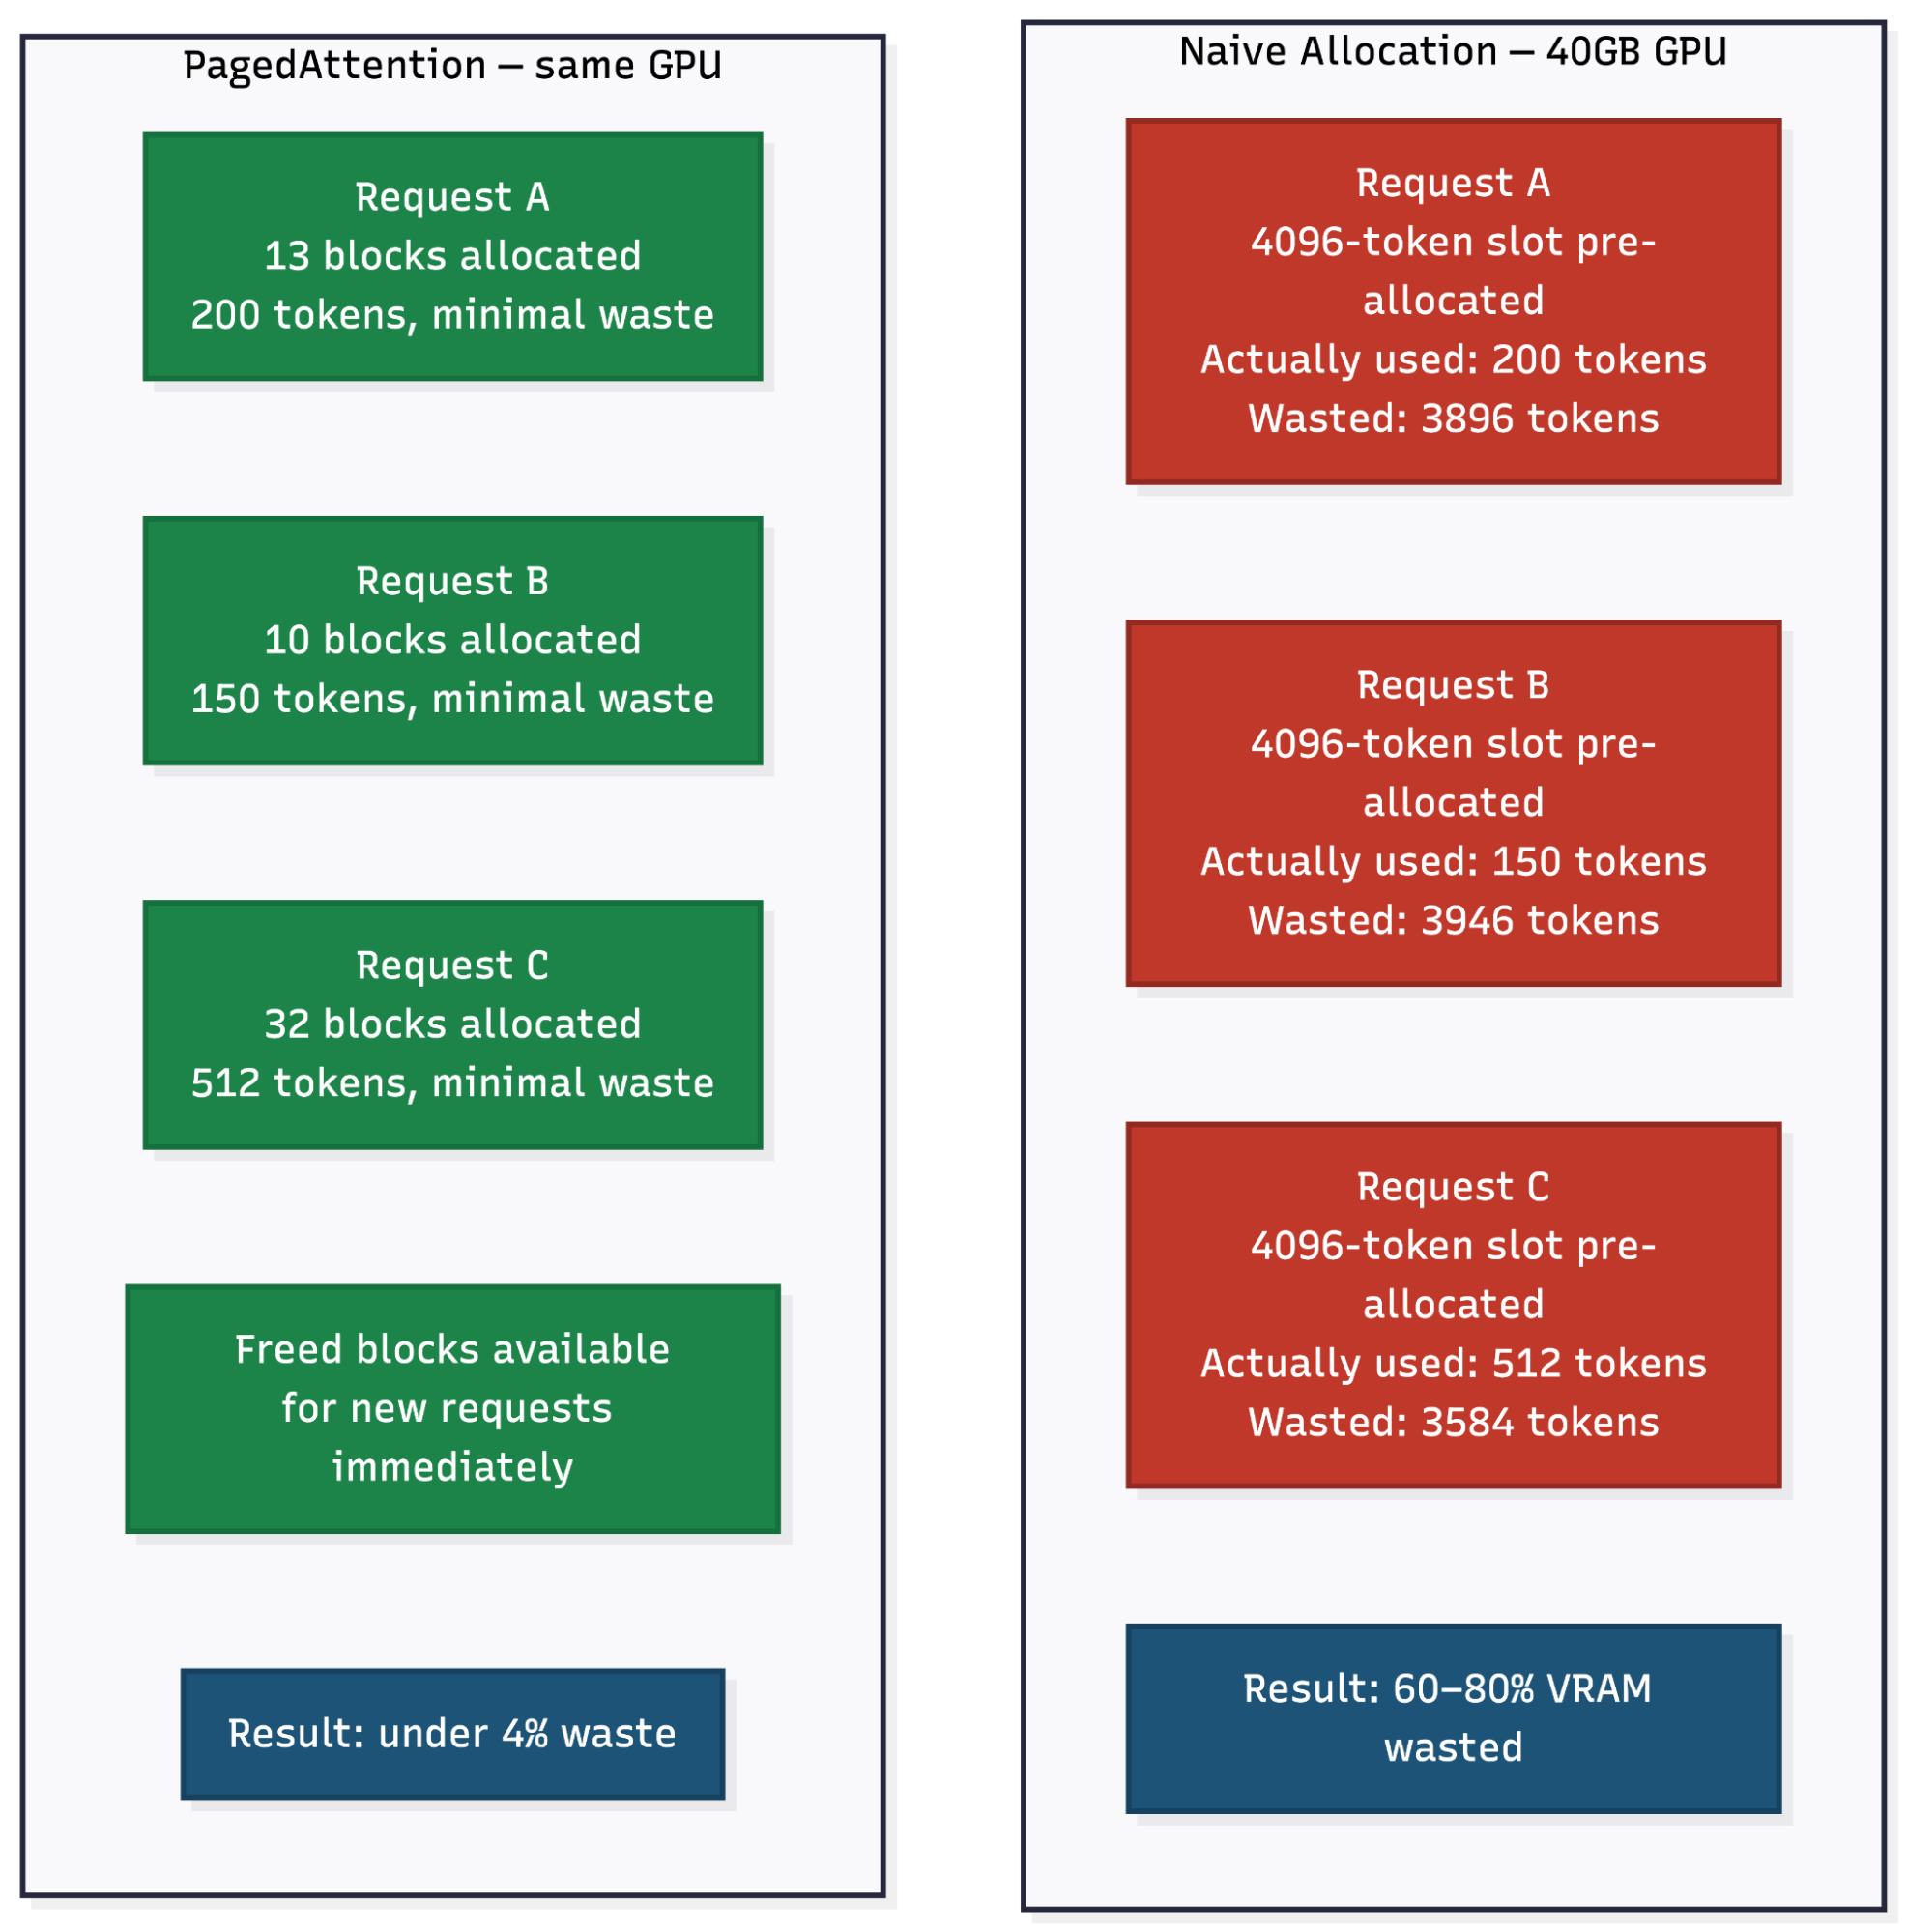
What is PagedAttention — and what it changed in LLM serving. | Nuqta
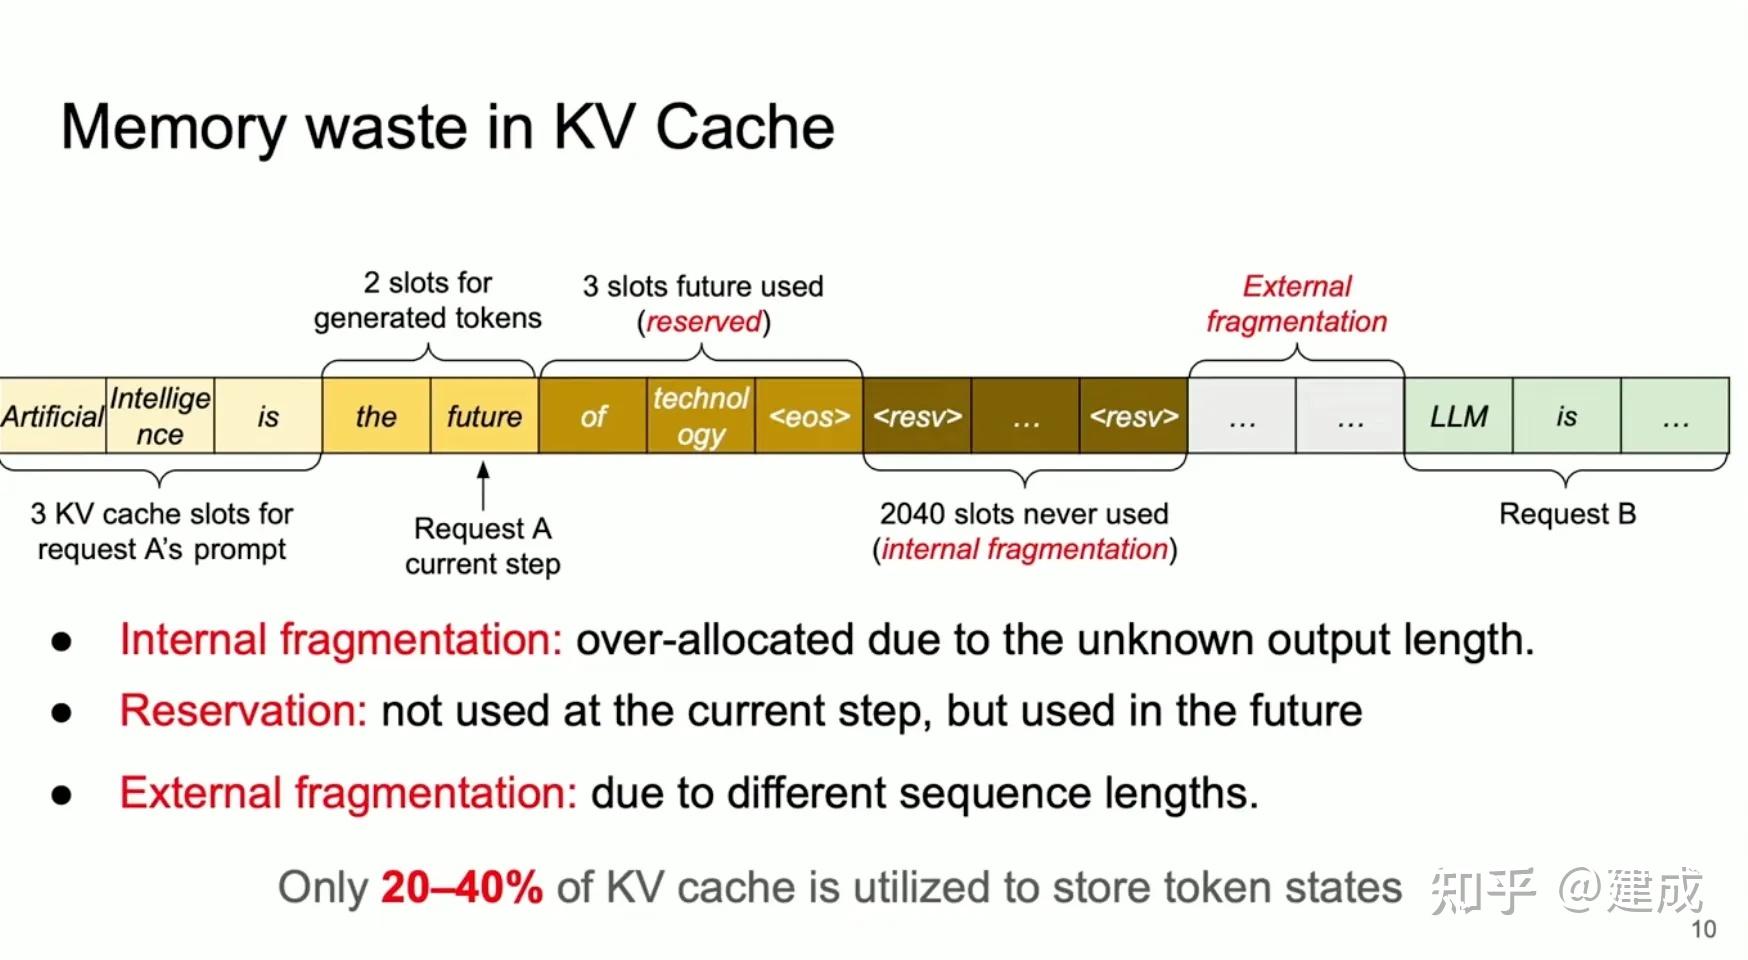
vLLM & PagedAttention 论文深度解读(一)—— LLM 服务现状与优化思路 - 知乎
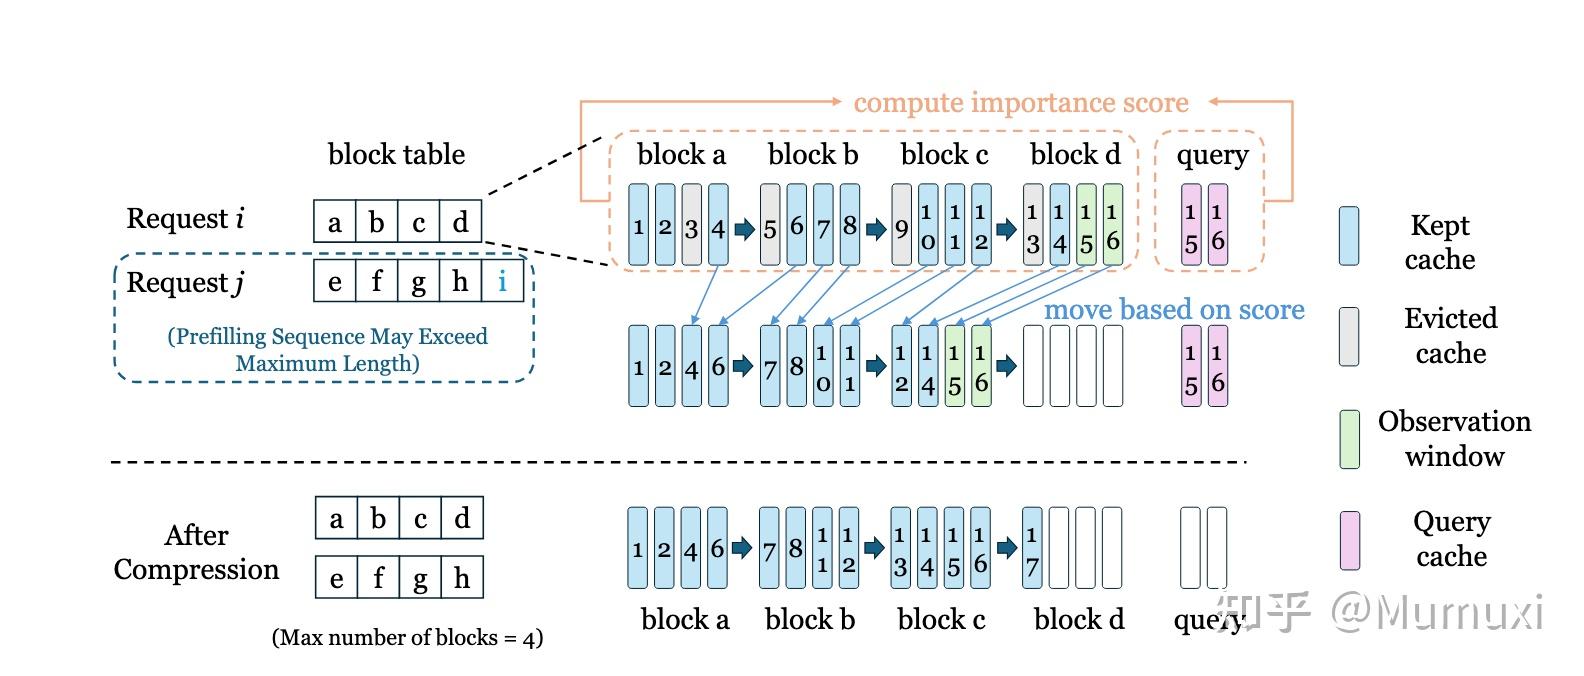
Zipage引擎: 结合 KV cache 驱逐和 PagedAttention 维持 LLM 推理的高并发 - 知乎
Fast LLM Serving with vLLM and PagedAttention - YouTube
ما هو PagedAttention وما الذي غيّره في عالم الـ LLM Serving. | نُقطة
Top 3 LLM frameworks that you should know
A Guide to LLM Inference (Part 2): Attention Optimisation – Stephen Carmody
Introduction to vLLM and PagedAttention | Runpod Blog
Premium Vector | How attention mechanism powers transformer and llm for ...
LLM 推理的 Attention 计算和 KV Cache 优化:PagedAttention、vAttention 等_paged ...
How I think about LLM prompt engineering
PagedAttention 深度解析 - 知乎
LLM Inference from First Principles: Tokenization, KV Cache, and ...
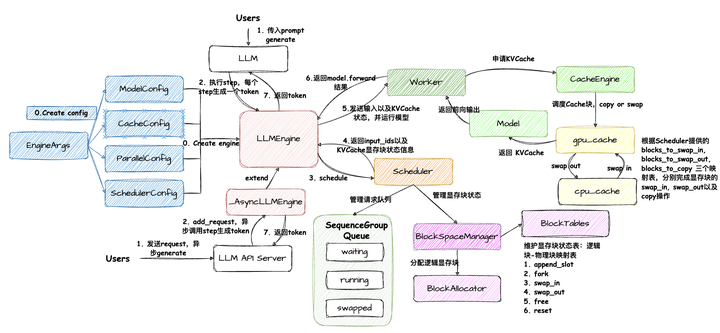
vllm 优化之 PagedAttention 源码解读 - Zhang
LLM and hardware - LLM Workshop
How To Deploy LLM Applications - by Damien Benveniste
Paper page - Squeezed Attention: Accelerating Long Context Length LLM ...
LLM 推理的 Attention 计算和 KV Cache 优化:PagedAttention、vAttention 等-AI.x-AIGC ...
Efficient Memory Management For LLM Model Serving With Paged Attention ...
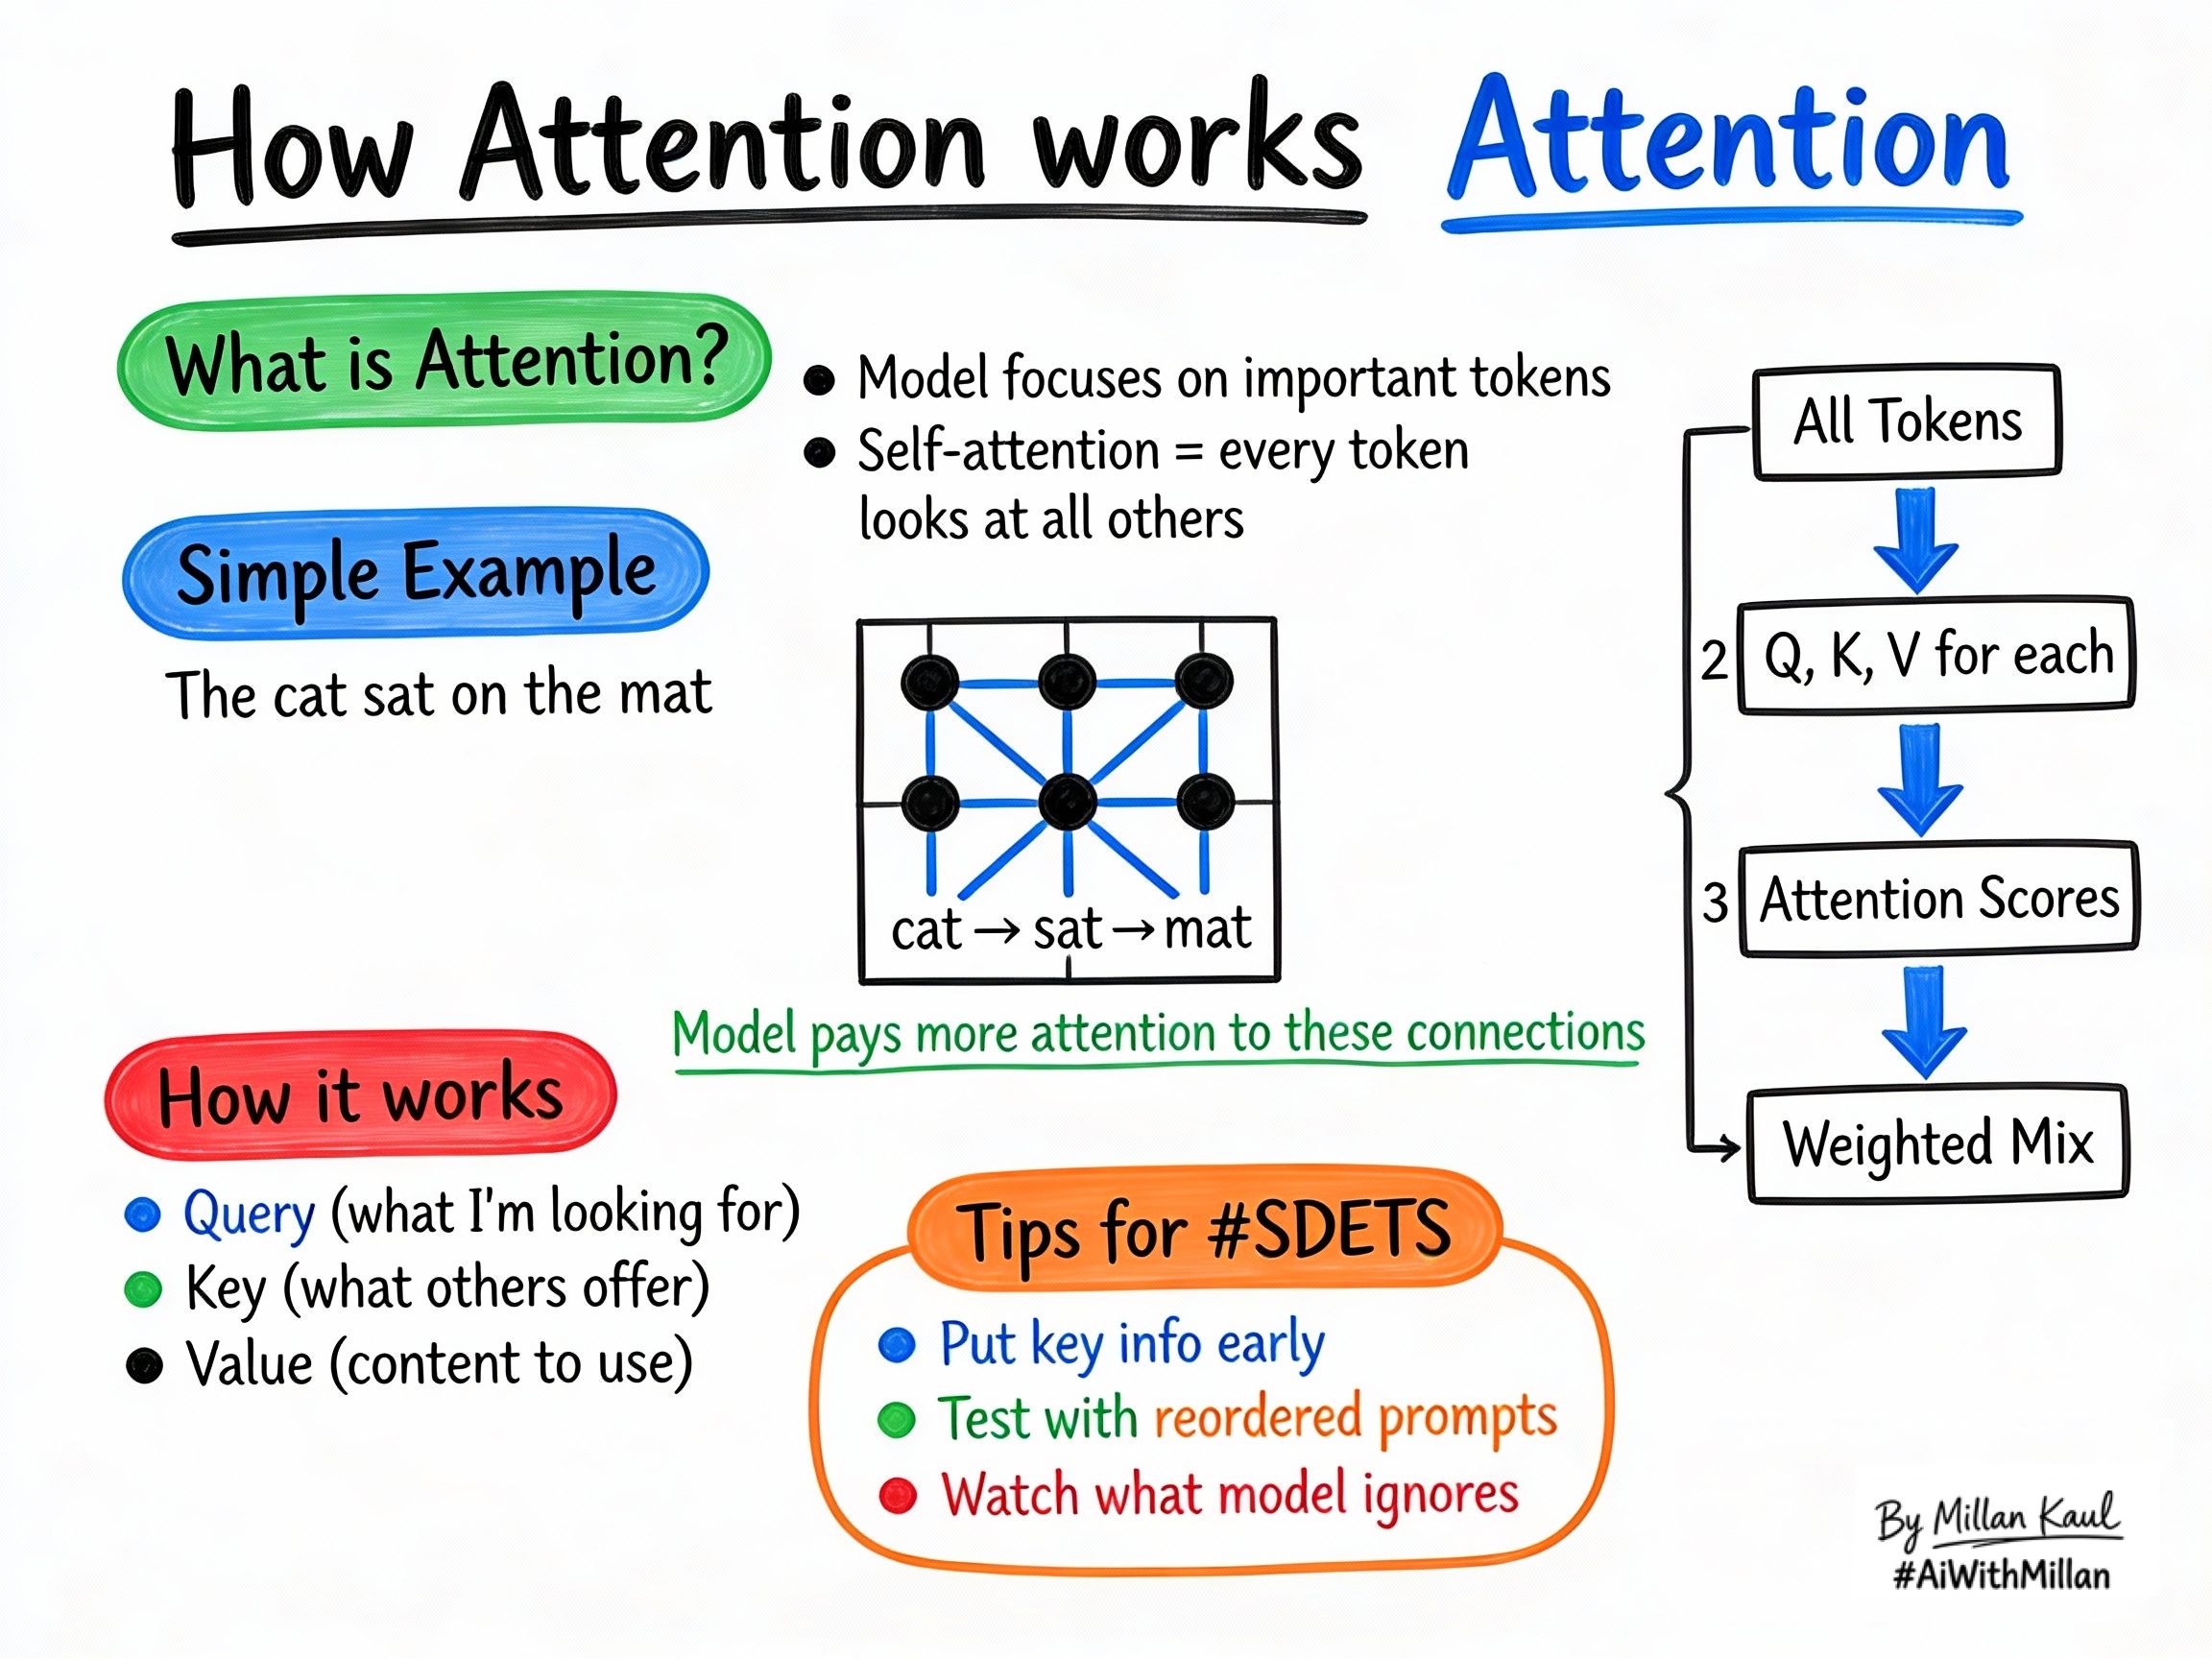
Understanding LLM attention is tough. Read below how it works. The ...
LLM 优化技术(2)——paged_attention 原理_pagedattention-CSDN博客
Attention Mechanism in LLM TRansformers | PDF
PagedAttention: Solving LLM KV Cache Memory Fragmentation - Interactive ...
PagedAttention - MLOps Dictionary | Hopsworks
[NLP] LLM 서빙을 위한 VLLM 이란? | BambooStreet
LLM outputs | Structured LLM outputs
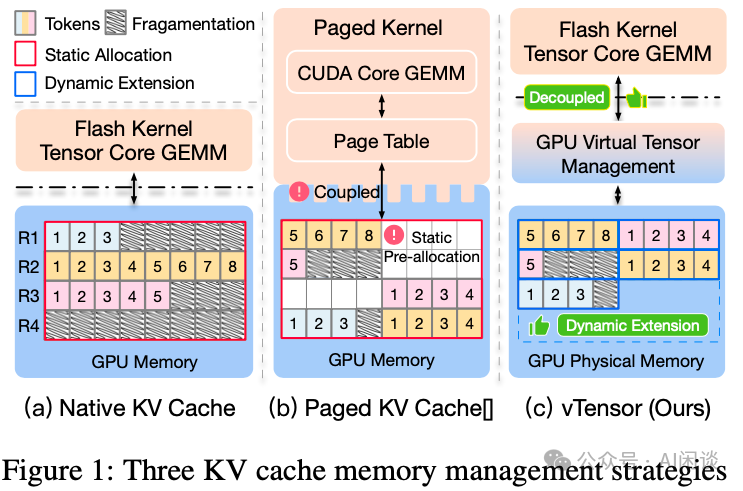
vAttention:用于在没有Paged Attention的情况下Serving LLM - 知乎
PagedAttention: Efficient LLM Serving with Memory Optimization | dypsis ...
vLLM PagedAttention Production Serving Optimization and Inference ...
Efficient AI Lecture 13: LLM Deployment Techniques The lecture helped ...
vLLM PagedAttention: LLM 추론 처리량의 혁신 | GeekNews
Что такое FlashAttention и PagedAttention: ускорение инференса LLM в ...
Deep-dive into the deployment of an on-premise low-privileged LLM
Paper page - Attention Mechanisms Perspective: Exploring LLM Processing ...
Mechanistic Interpretability: Peeking Inside an LLM | Towards Data Science
Paged Attention in LLMs, visually explained: (how and why it works)
Paged Attention in LLMs (Daily Dose of Data Science) | Flux YoanDev
Paged Attention in LLMs - by Avi Chawla
What are Private LLMs? Running Large Language Models Privately ...
vLLM과 PagedAttention: 대규모 언어 모델 서빙의 메모리 최적화 및 시스템 아키텍처 : 네이버 블로그
Understanding Attention Mechanisms in LLMs
LLM_log #005: Implementing Attention Mechanisms — From Simplified Self ...
深入浅出,一文理解LLM的推理流程_chunked prefill-CSDN博客
全新注意力算法PagedAttention:LLM吞吐量提高2-4倍,模型越大效果越好 - CV技术指南(公众号) - 博客园
Data - 💡 Making long-context AI practical: Why Paged Attention matters ...
图解主流大语言模型的技术原理细节 - 知乎
vLLM框架原理——PagedAttention - 知乎
What is PagedAttention? - Hopsworks
Attention优化:Flash Attn和Paged Attn,MQA以及GQA - 知乎
Paged Attention from First Principles: A View Inside vLLM | Hamza's Blog
LLM优化技术——Paged Attention-CSDN博客
63 LLM(大语言模型)部署加速方法 - PagedAttention篇 | PDF
vLLM and PagedAttention: A Comprehensive Overview | by Abonia ...
What is Flash Attention?. Improved Attention Mechanism for LLMs | by ...
LLM(十七):从 FlashAttention 到 PagedAttention, 如何进一步优化 Attention 性能 - 知乎
Understanding KV Cache and Paged Attention in LLMs: A Deep Dive into ...
Chapter 3: Coding Attention Mechanisms — LLMs from Scratch
LLM推論高速化手法が推論結果に 与える影響の分析 | offline-benchmark – Weights & Biases
Part 2 — Memory Is the Real Bottleneck: How Paged Attention Powers the ...
Efficient Memory Management for Large Language Model Serving with ...
vAttention:用于在没有Paged Attention的情况下Serving LLM-腾讯云开发者社区-腾讯云
Как ускорить LLM-генерацию текста в 20 раз на больших наборах данных / Хабр
GPU memory requirements for serving Large Language Models | UnfoldAI
大模型推理加速与KV Cache(三):Paged Attention - 知乎
FlashAttention & Paged Attention: GPU Sorcery for Blazing-Fast ...
Medium
LLM推理优化技术综述:KVCache、PageAttention、FlashAttention、MQA、GQA_page attention ...
Understanding Attention: Standard Attention vs flash Attention | by ...
vLLM은 왜 빠른가?: Paged-Attention
Attention Mechanism: How LLMs Decide ‘What Matters Most’ | Quality With ...
Paged Attention in LLMs
Paper page - Efficient Memory Management for Large Language Model ...
Core Optimisations in LLMs: Paged Attention, Mixture of Experts, and ...
A Primer on Understanding Attention Mechanisms in LLMs | by Phaneendra ...
vAttention: Dynamic Memory Management for Serving LLMs without ...
PagedAttention(vLLM):更快地推理你的GPT生成式大模型改变了我们在各个行业中应用人工智能的方式。然而 - 掘金
The Attention Mechanism in Deep Learning — An Example | by George Ginis ...
LLM前沿技术跟踪:PagedAttention升级版vAttention - 知乎
Details Attention Mechanism for LLM’s | by Md. Golam Mostofa | Medium
2.2 Understanding the Attention Mechanism in Large Language Models ...
【论文学习】理解LLM中的KV Cache和Paged Attention:深入探讨高效推理 - 知乎
[2309.06180] Efficient Memory Management for Large Language Model ...
At the Intersection of LLMs and Kernels - Research Roundup
Understanding and Coding Self-Attention, Multi-Head Attention, Causal ...
Explained: Attention Mechanism in AI | by XQ | The Research Nest | Medium
[논문 리뷰] Efficient Memory Management for Large Language Model Serving ...
Understanding Large Language Models – A Transformative Reading List ...
Paged Attention - vLLM
FlexAttention Part II: FlexAttention for Inference – PyTorch
PagedAttention--大模型推理服务框架vLLM要点简析 (中) - 知乎
Paper page - Kascade: A Practical Sparse Attention Method for Long ...