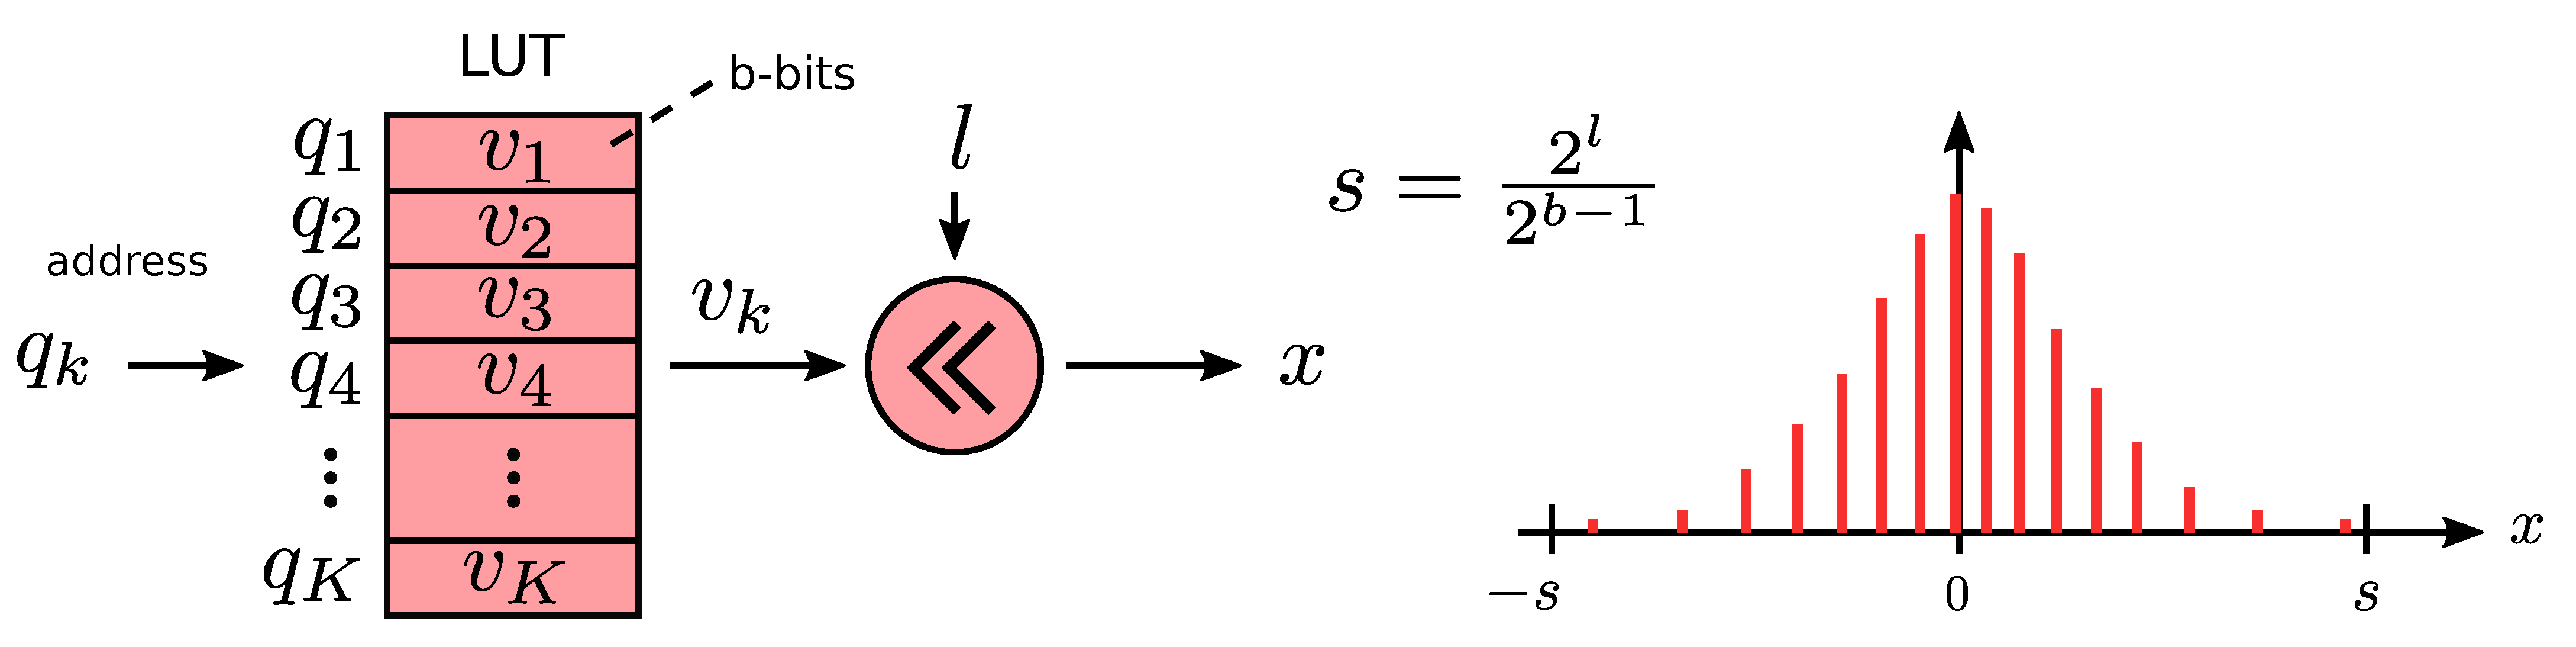Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
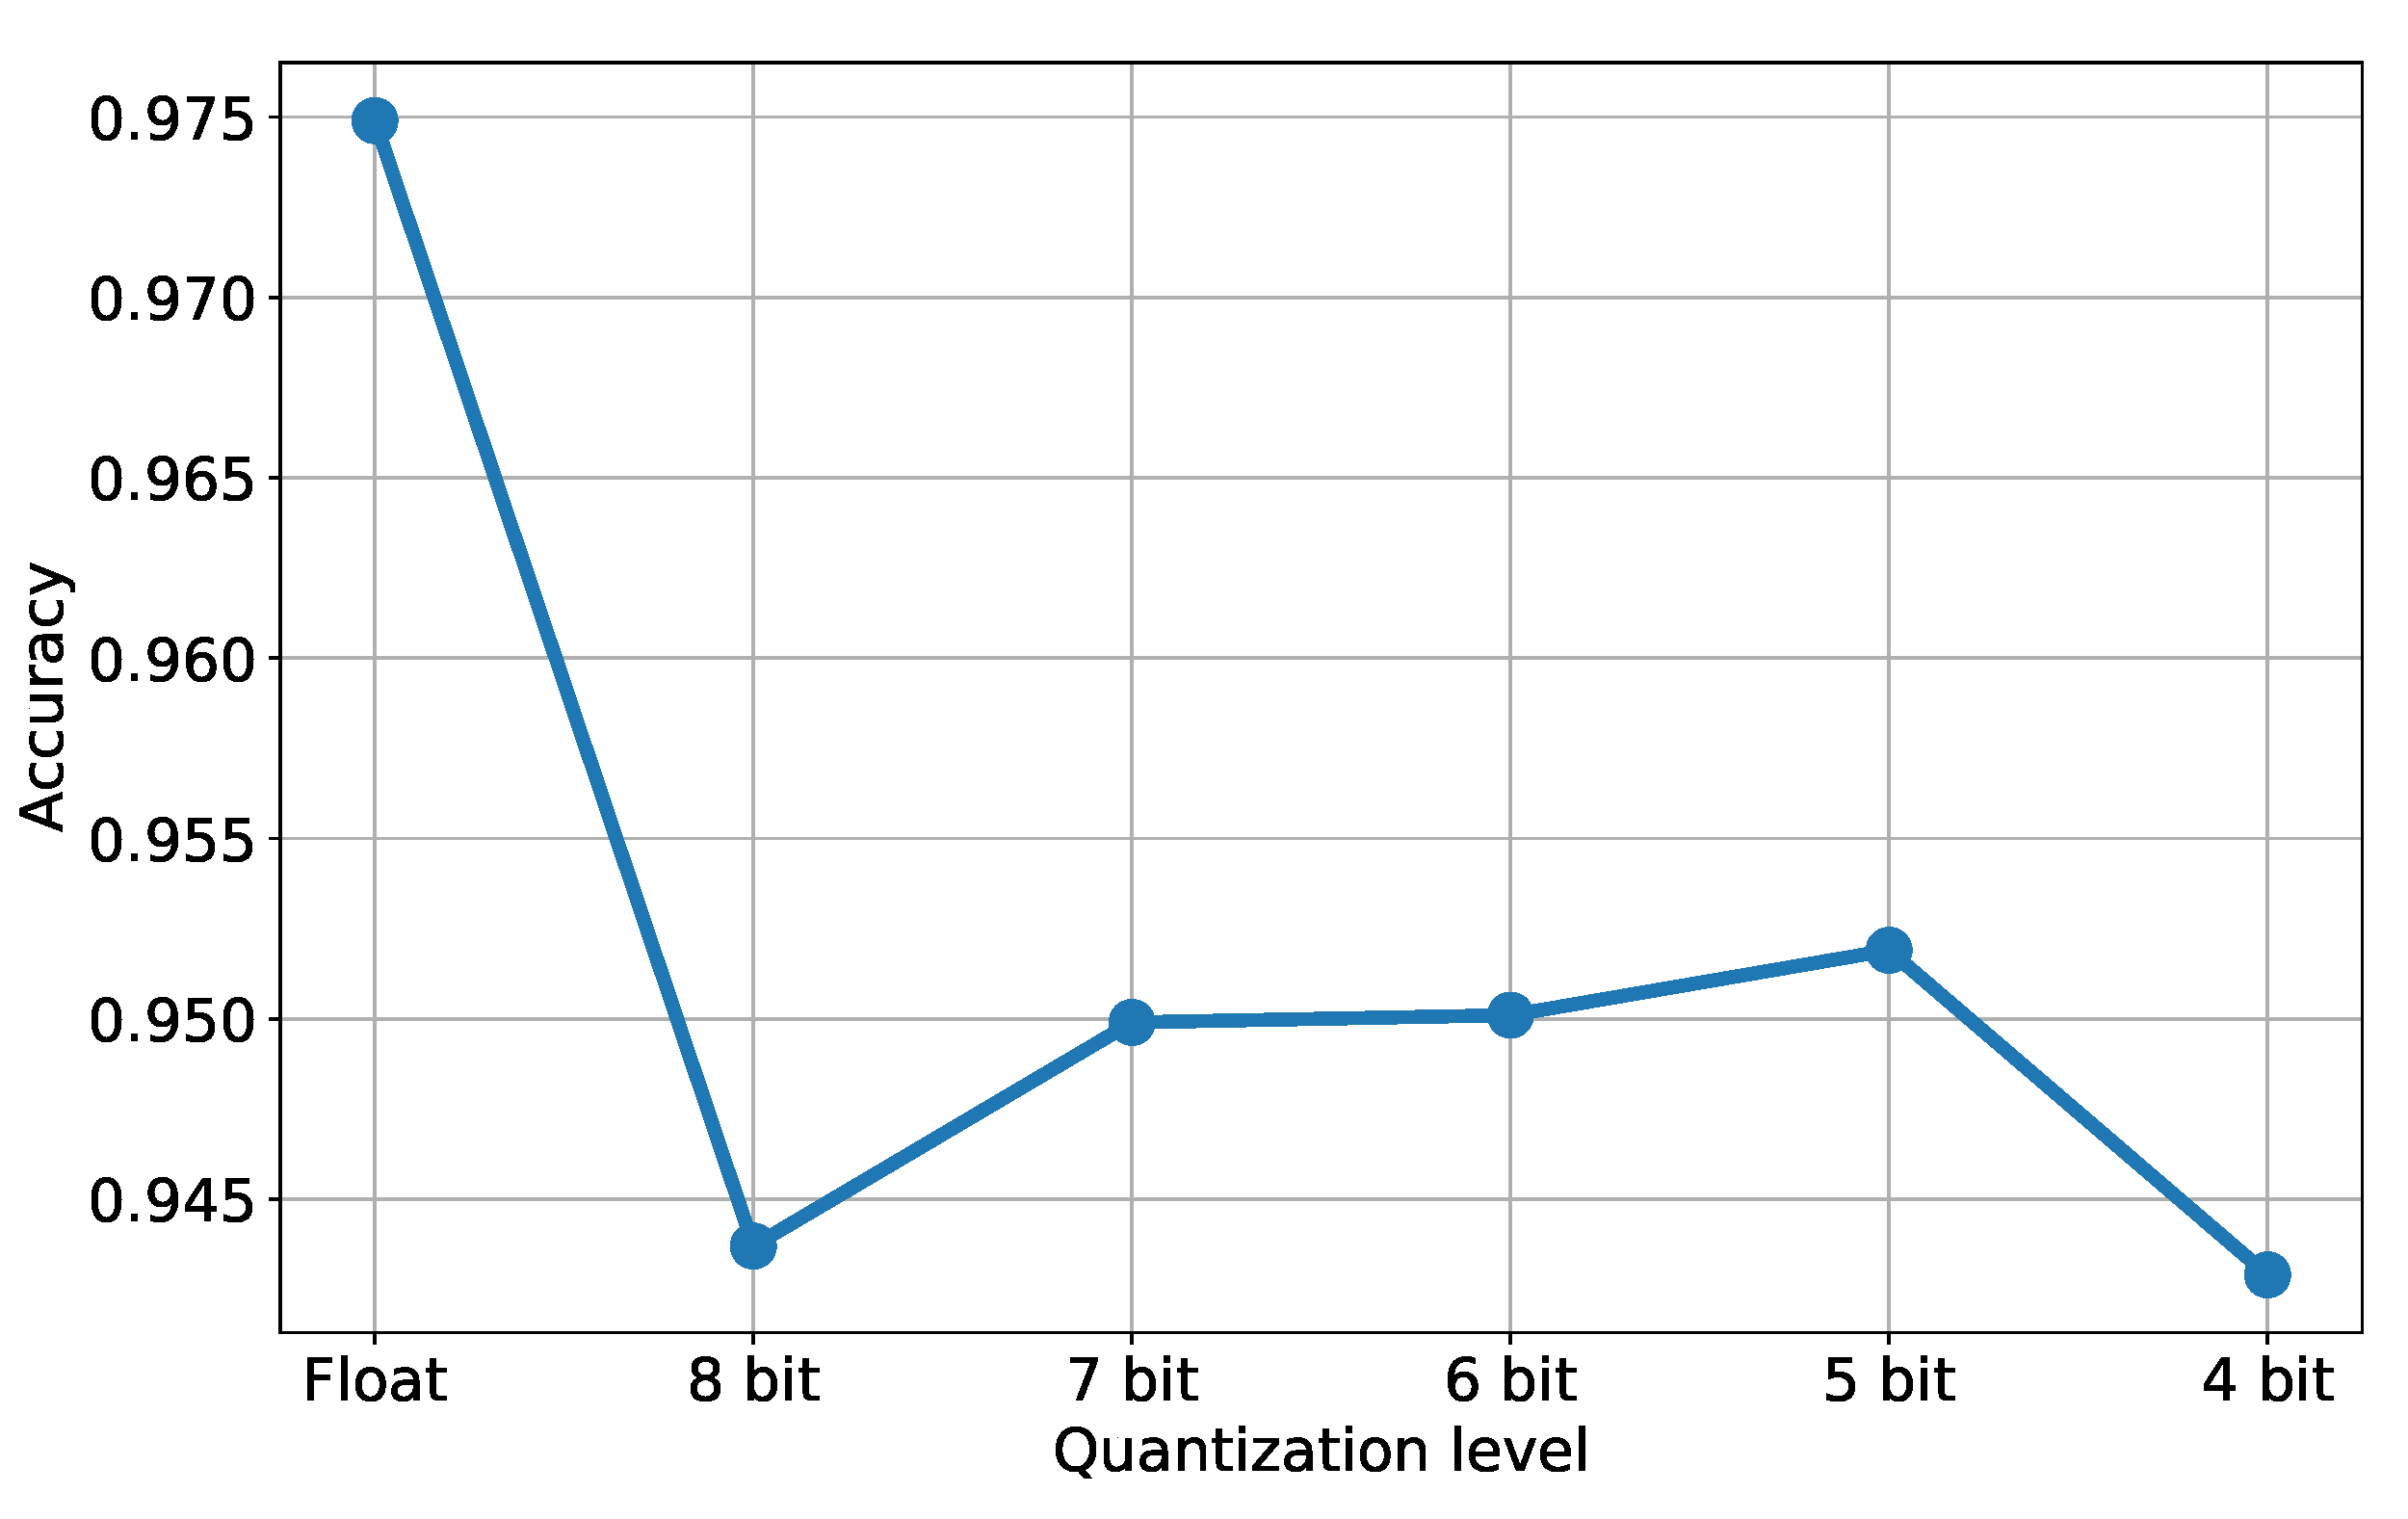
Quantization Bits at Amanda Okane blog
SR versus number of quantization bits of phase shifter with SNR=15dB ...
Codebook entries versus number of quantization bits on G (7, 1 ...
Estimated number of quantization bits for the received signals ...
The achievable ergodic secrecy rates versus quantization bits ...
Sum rate loss versus the number b of quantization bits for different ...
A comparison between the number of quantization bits vs. MSE and ...
Performance loss versus number of quantization bits with N = 32 and M ...
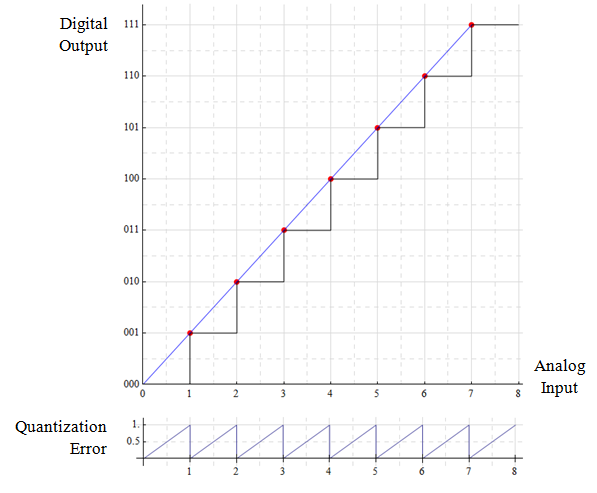
ADC Wiggles to Bits 8.2 Quantization – Dave McGlone
Uniform midriser quantizer with B = 2 quantization bits. | Download ...
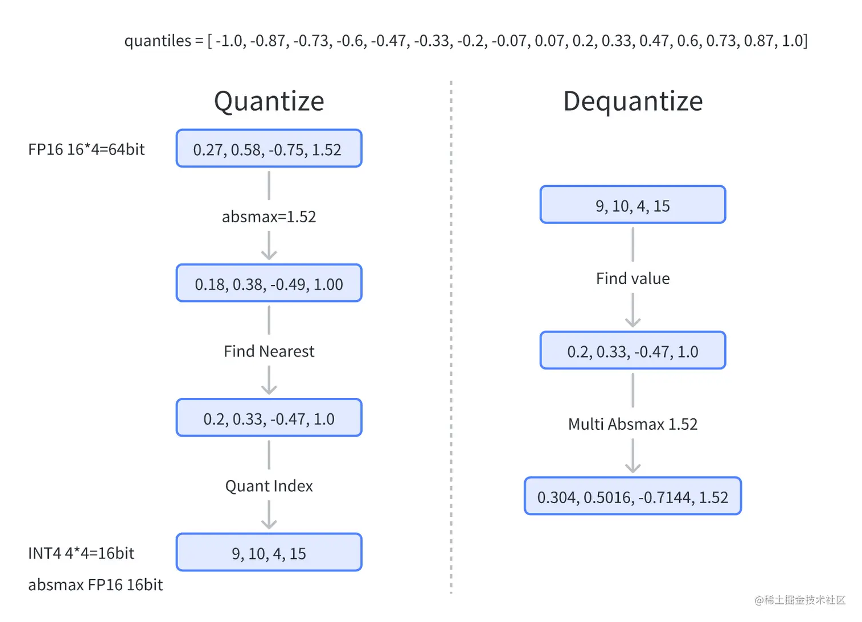
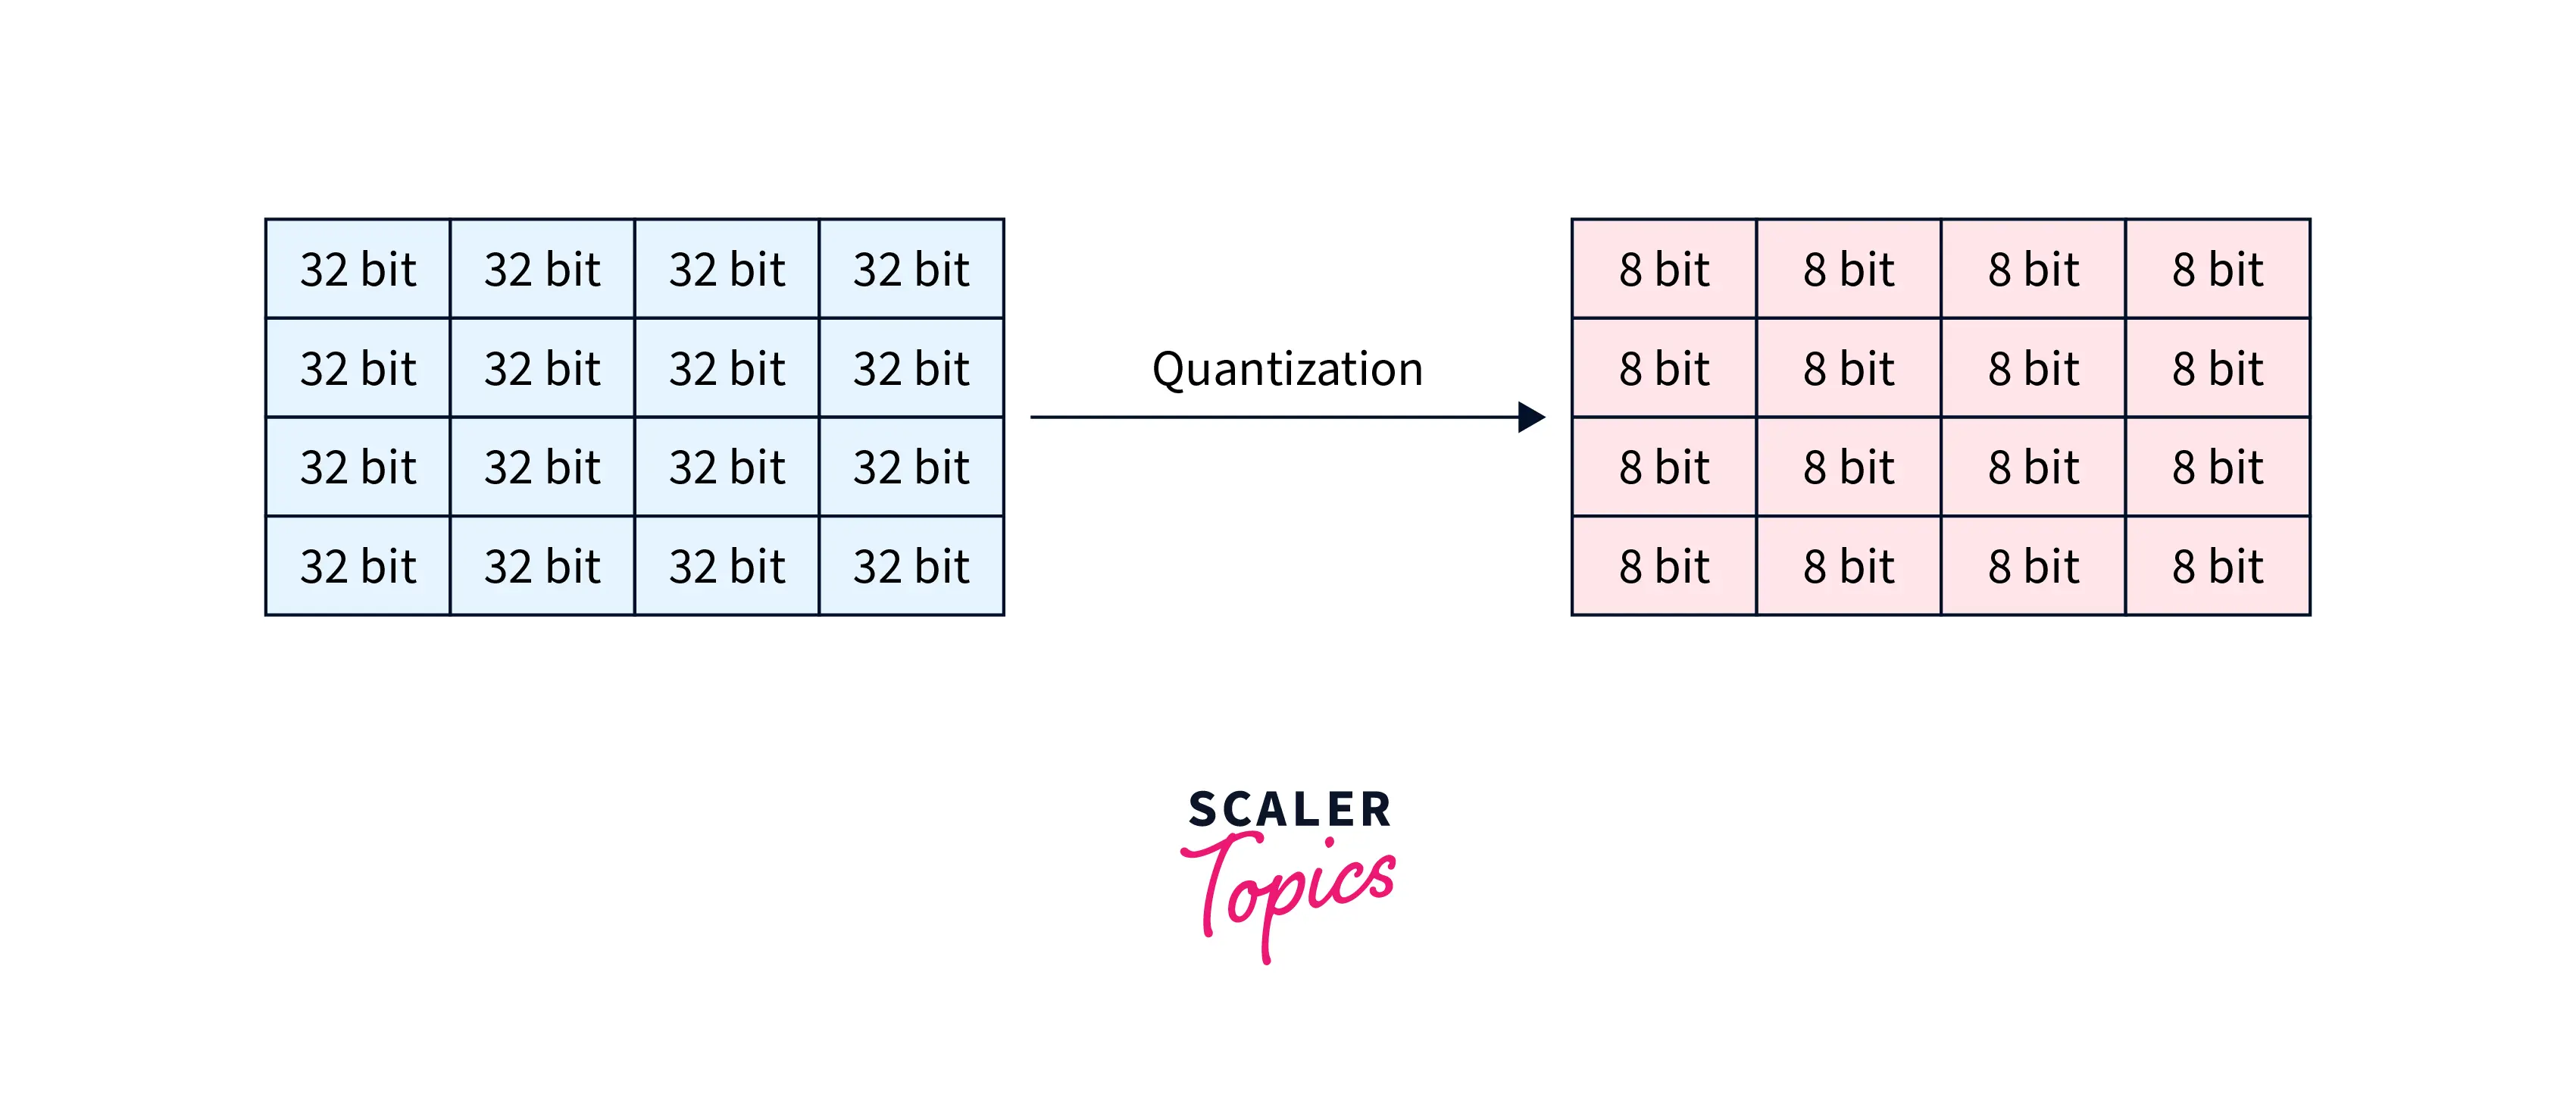
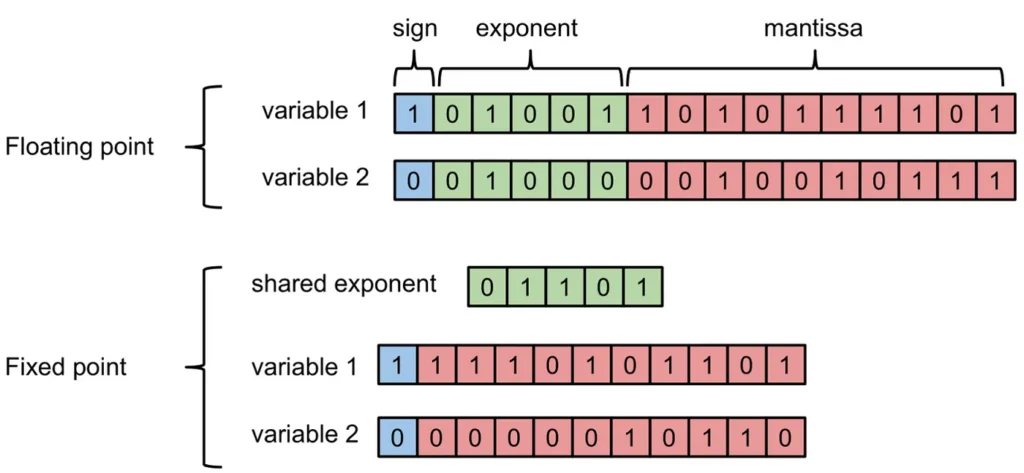
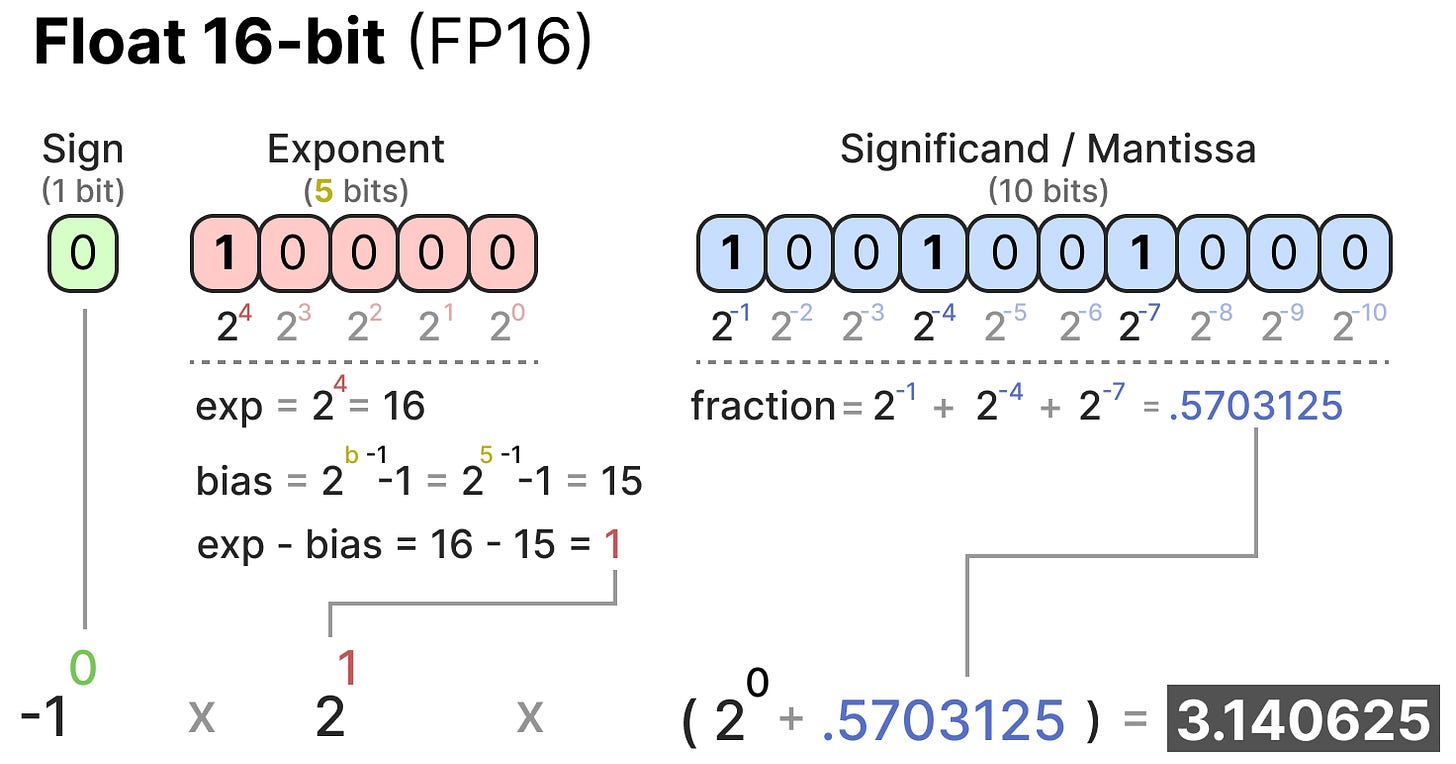
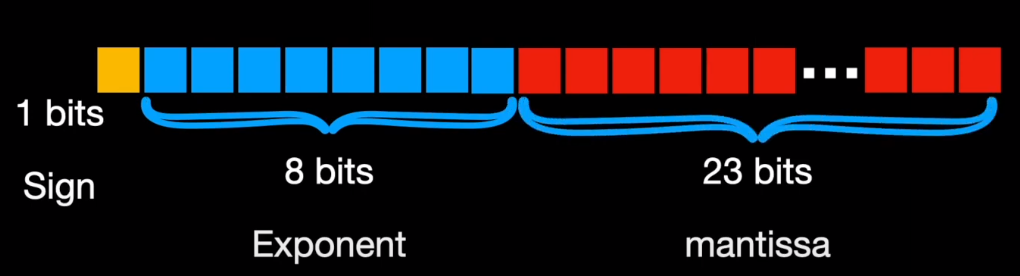
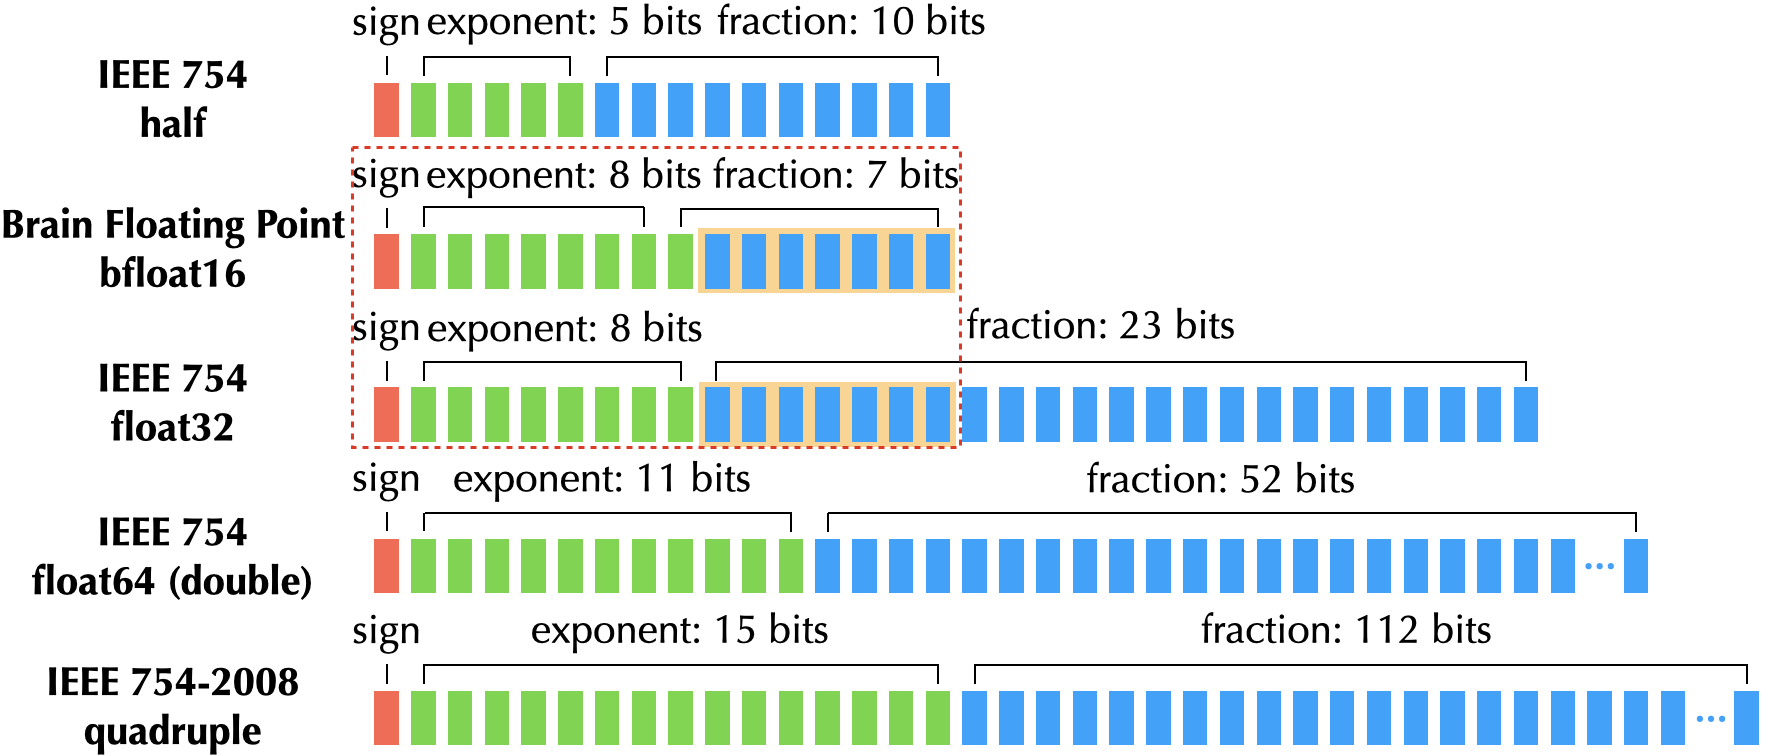
4-bit LLM training and Primer on Precision, data types & Quantization
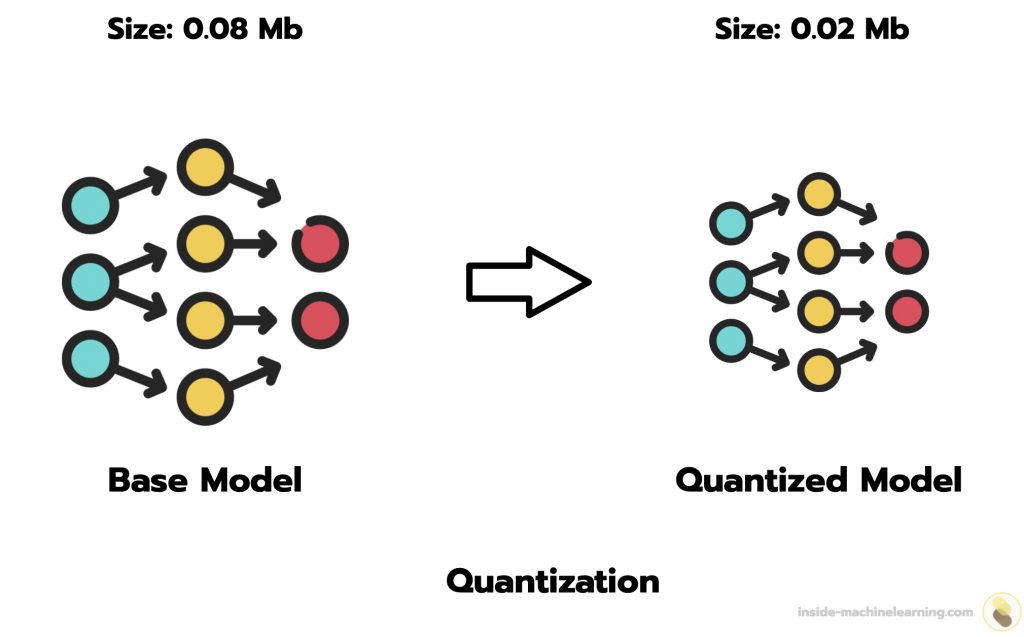
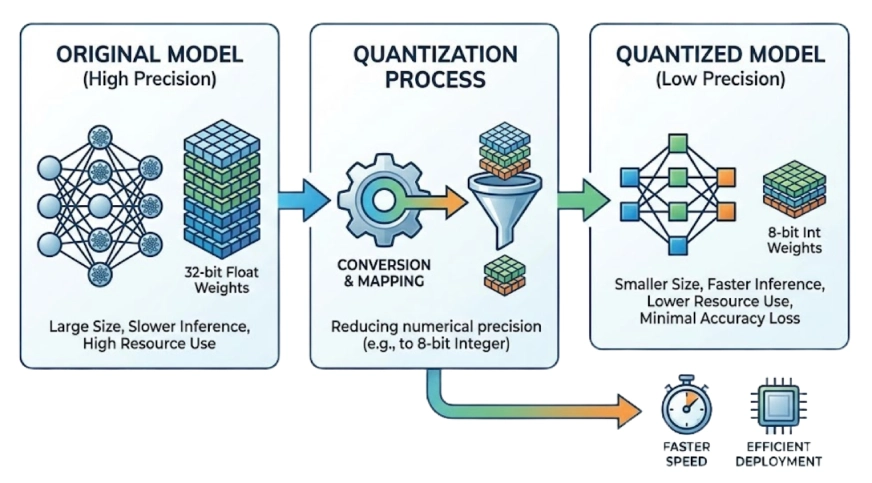
Mastering Generative AI with Model Quantization
Honey, I shrunk the LLM! A beginner’s guide to quantization | News For ...
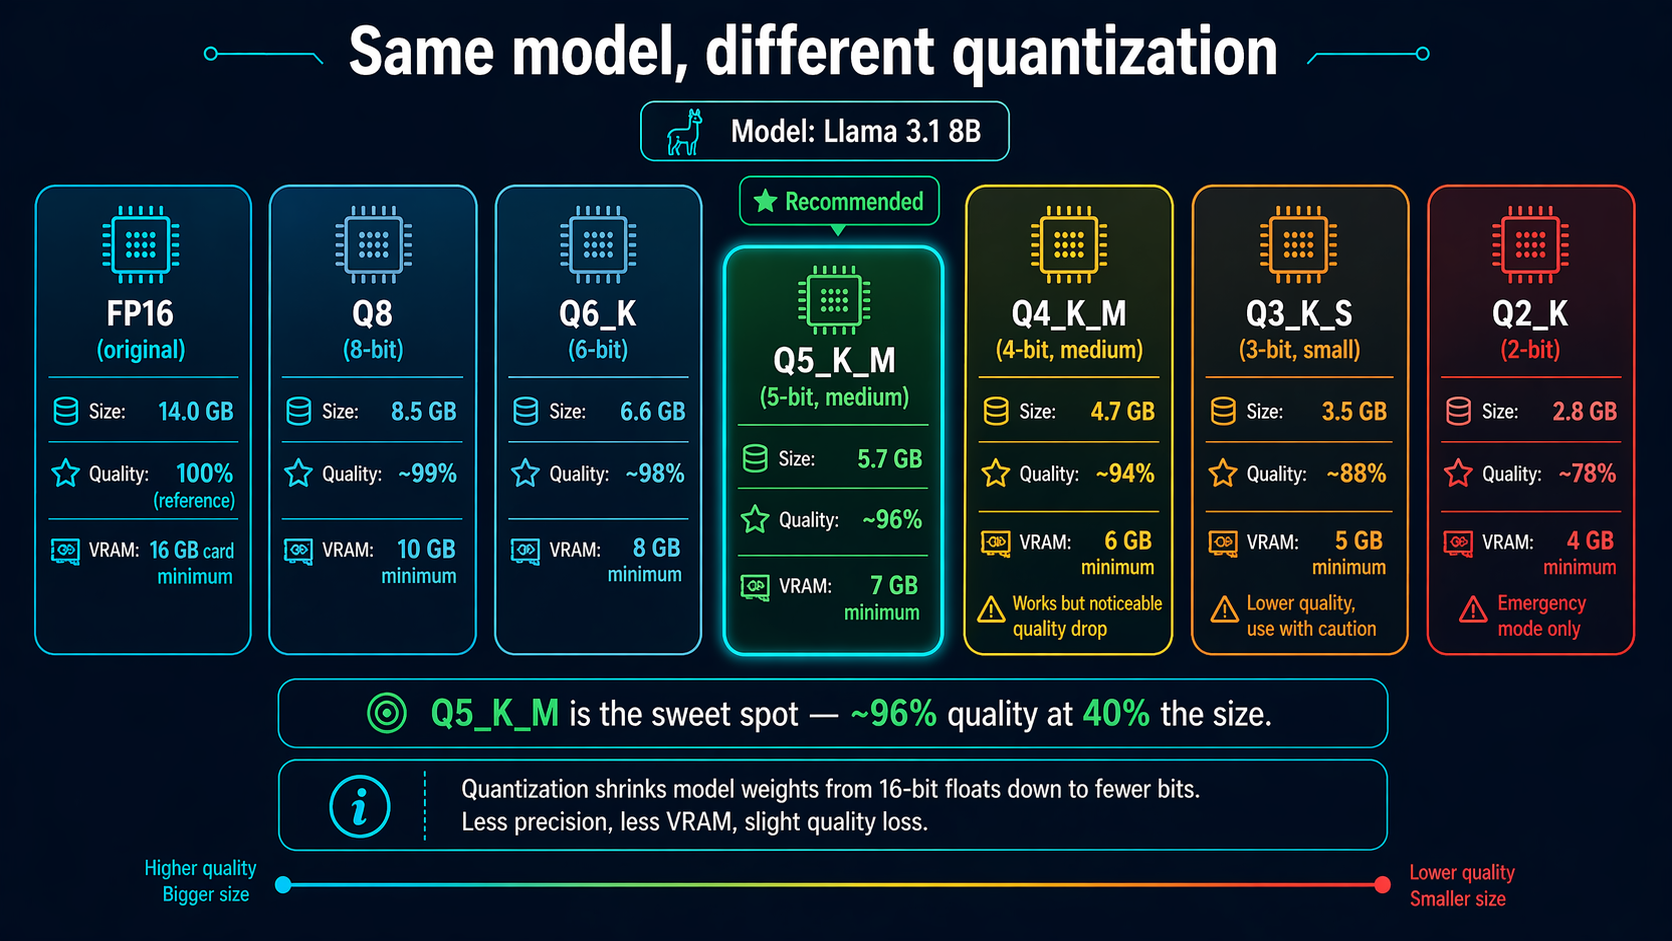
LLM Quantization 2026: Q2 vs Q4 vs Q5 vs Q8 (K_M, K_S & IQ Explained ...
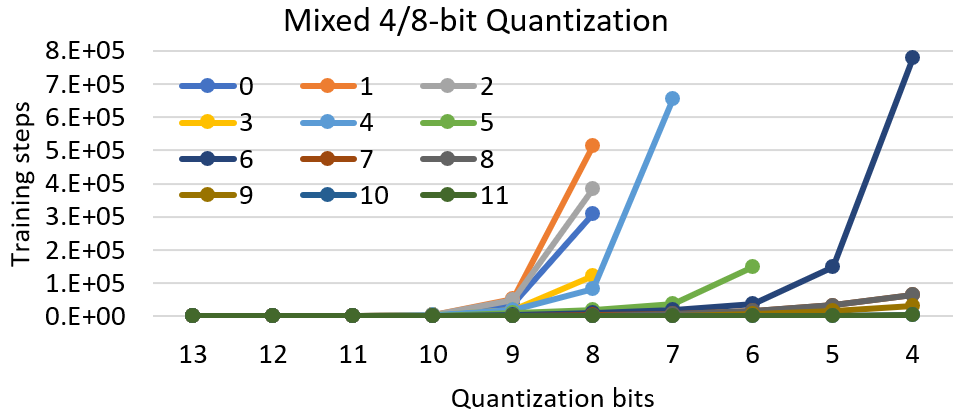
Mixture-of-Quantization: A novel quantization approach for reducing ...
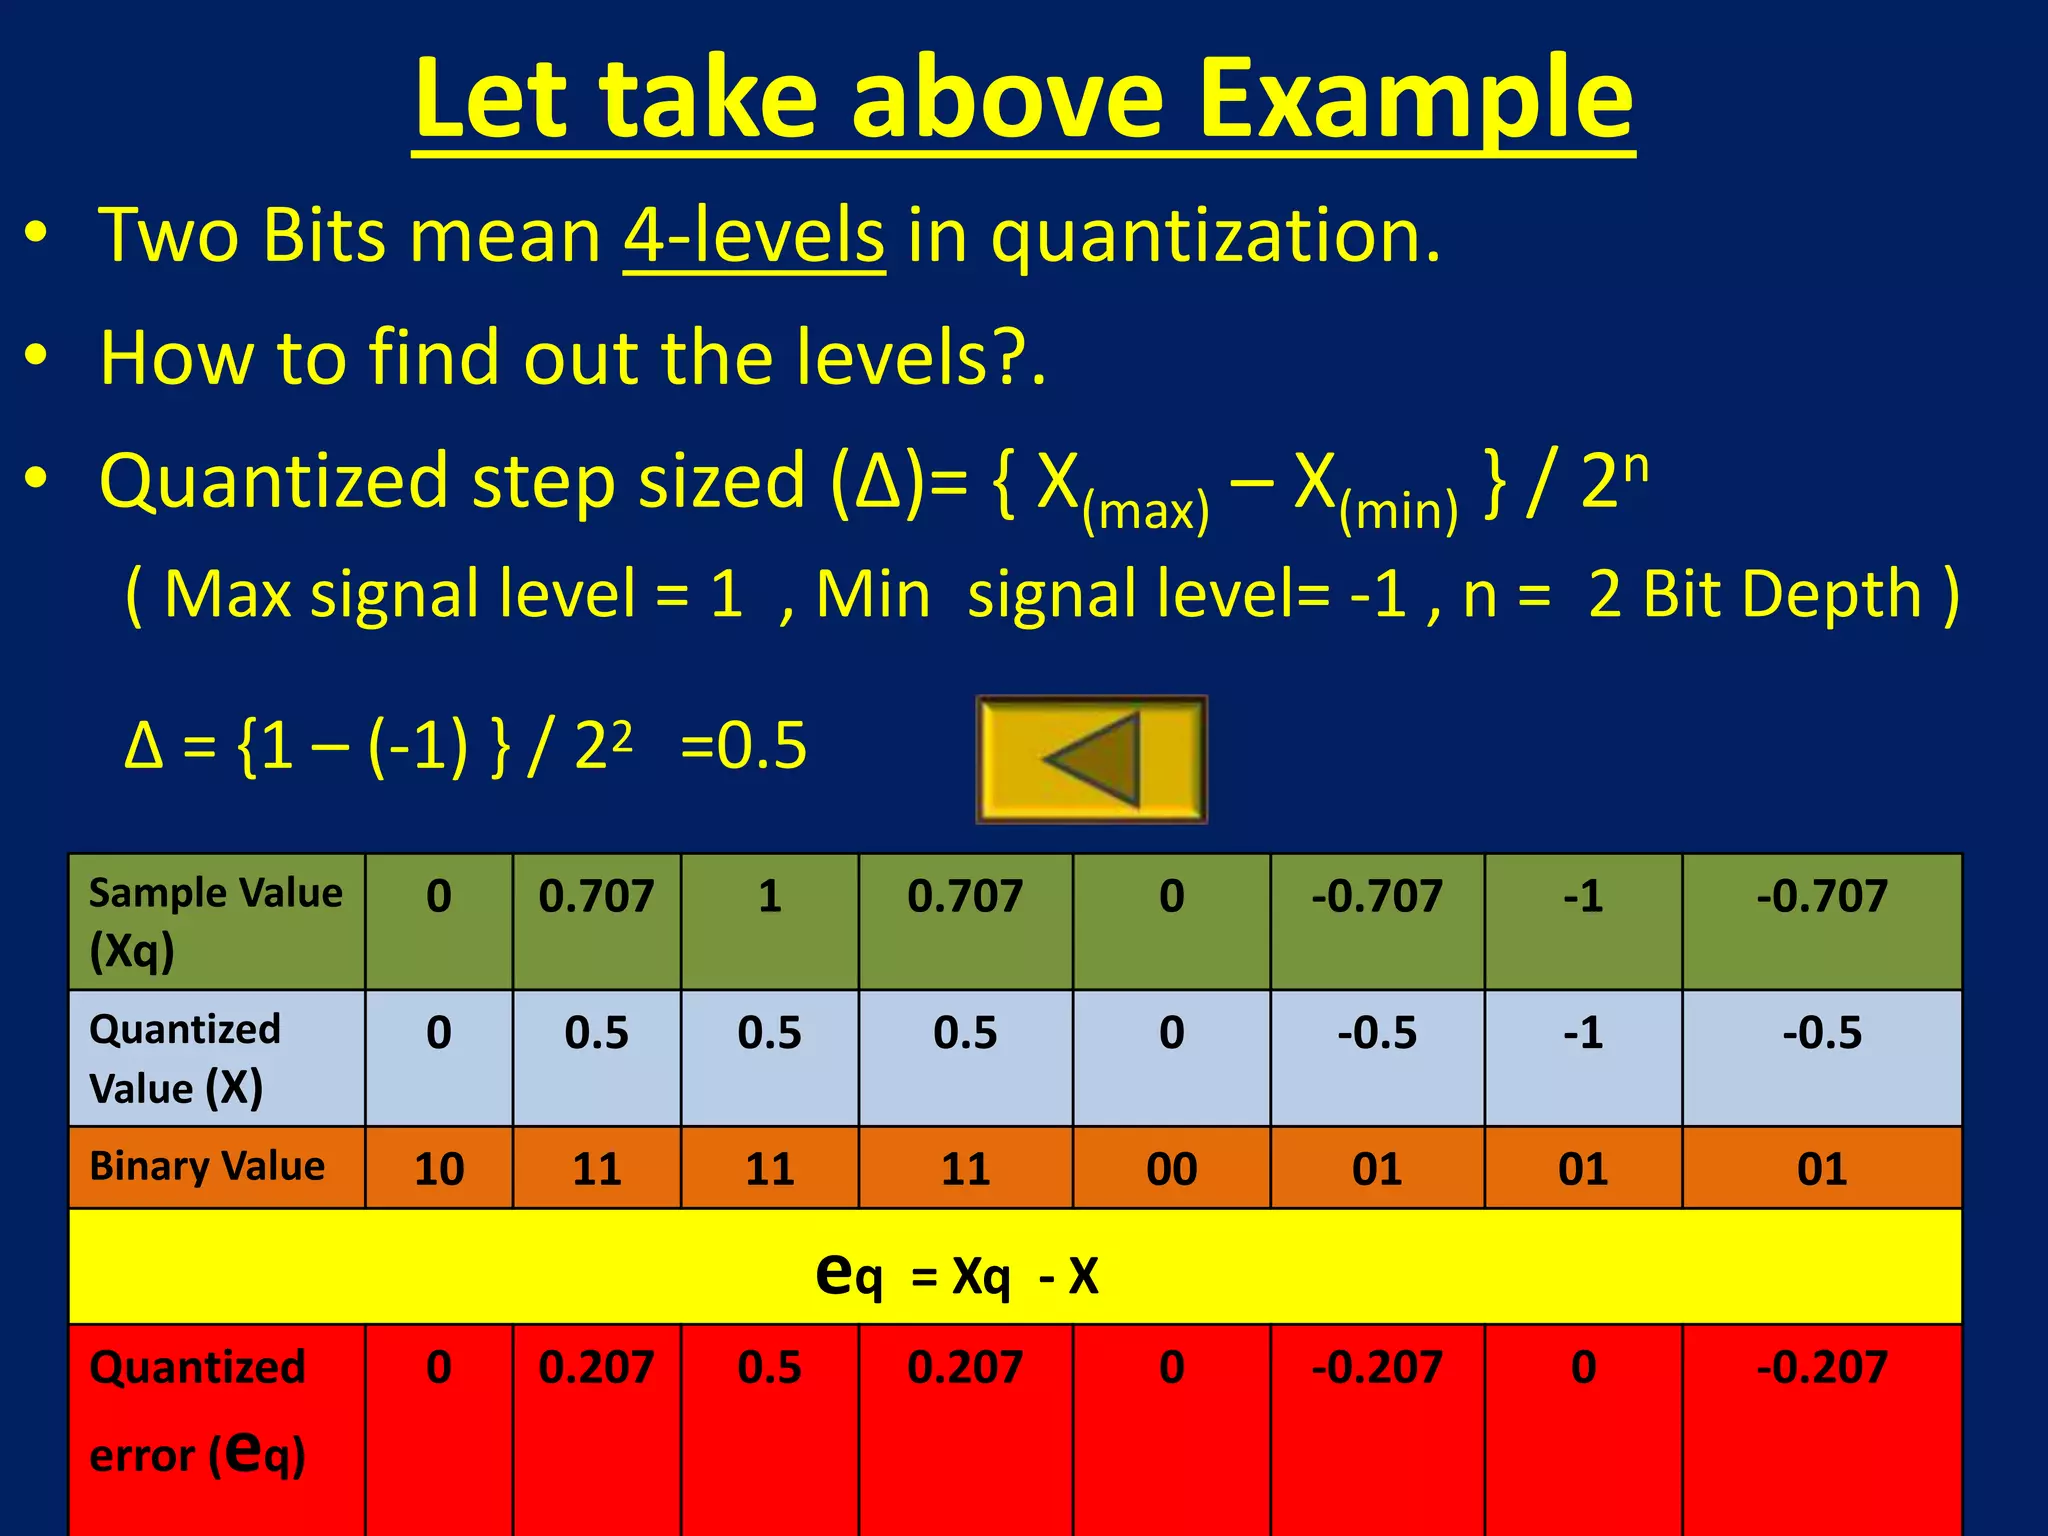
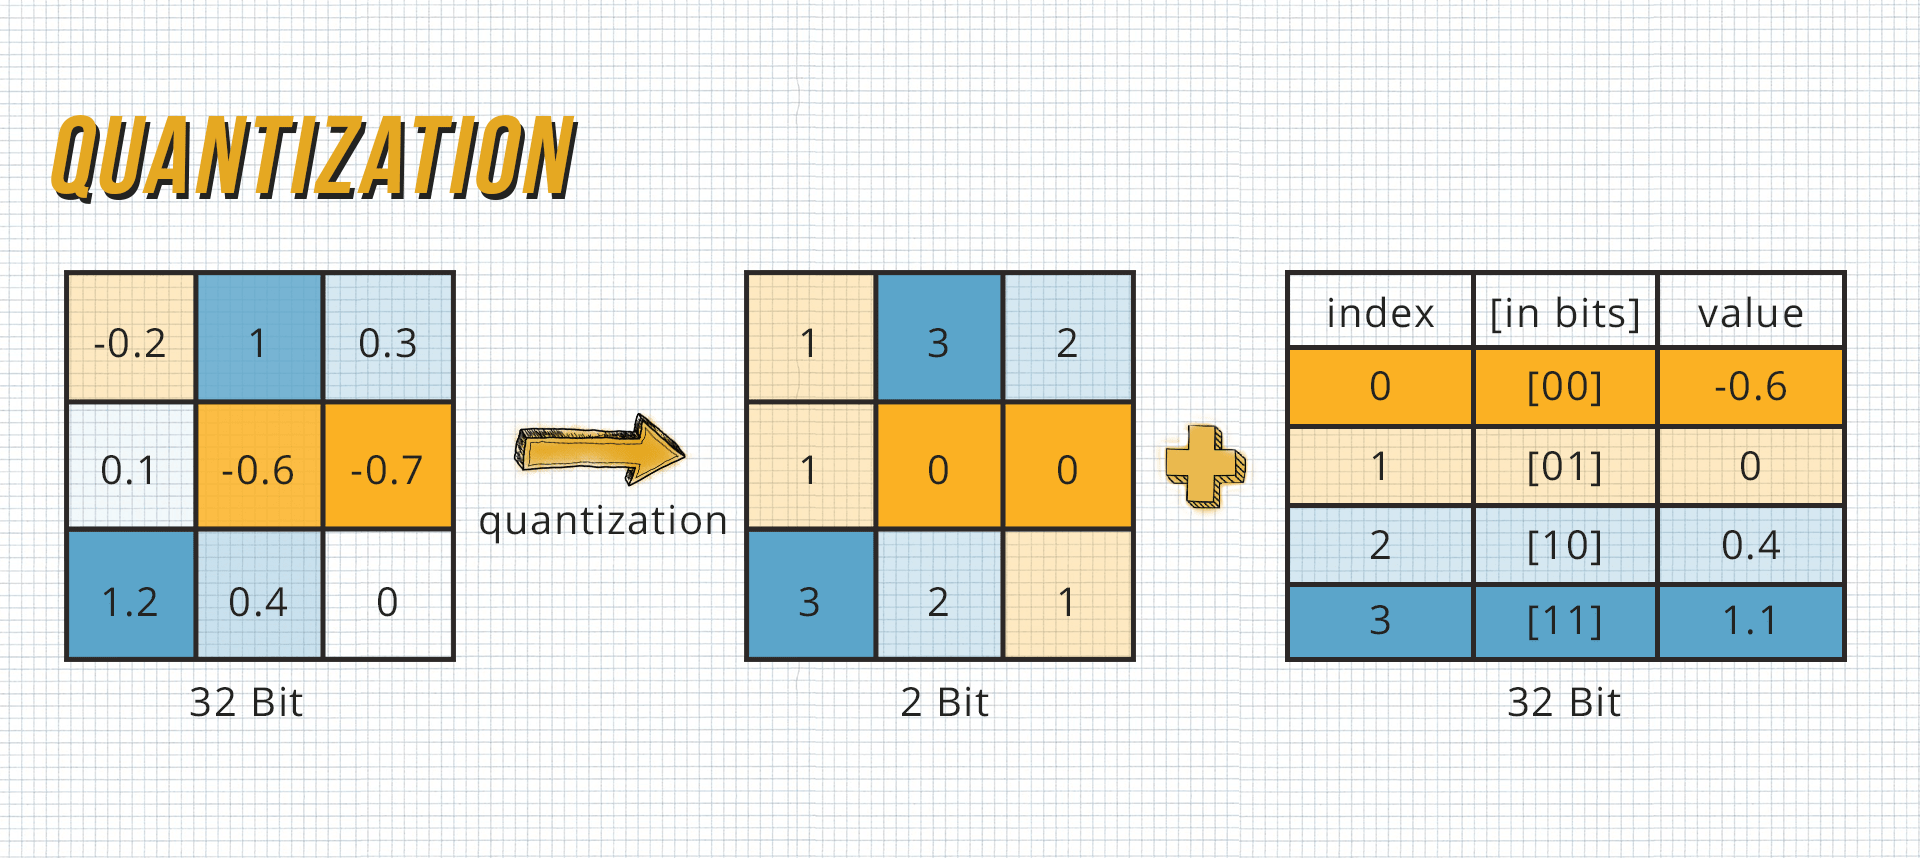
Quantization | PPTX
Quantization - Qdrant
What is Quantization and how to use it with TensorFlow
Understanding Model Quantization in Large Language Models | DigitalOcean
A Hands-On Walkthrough on Model Quantization - Medoid AI
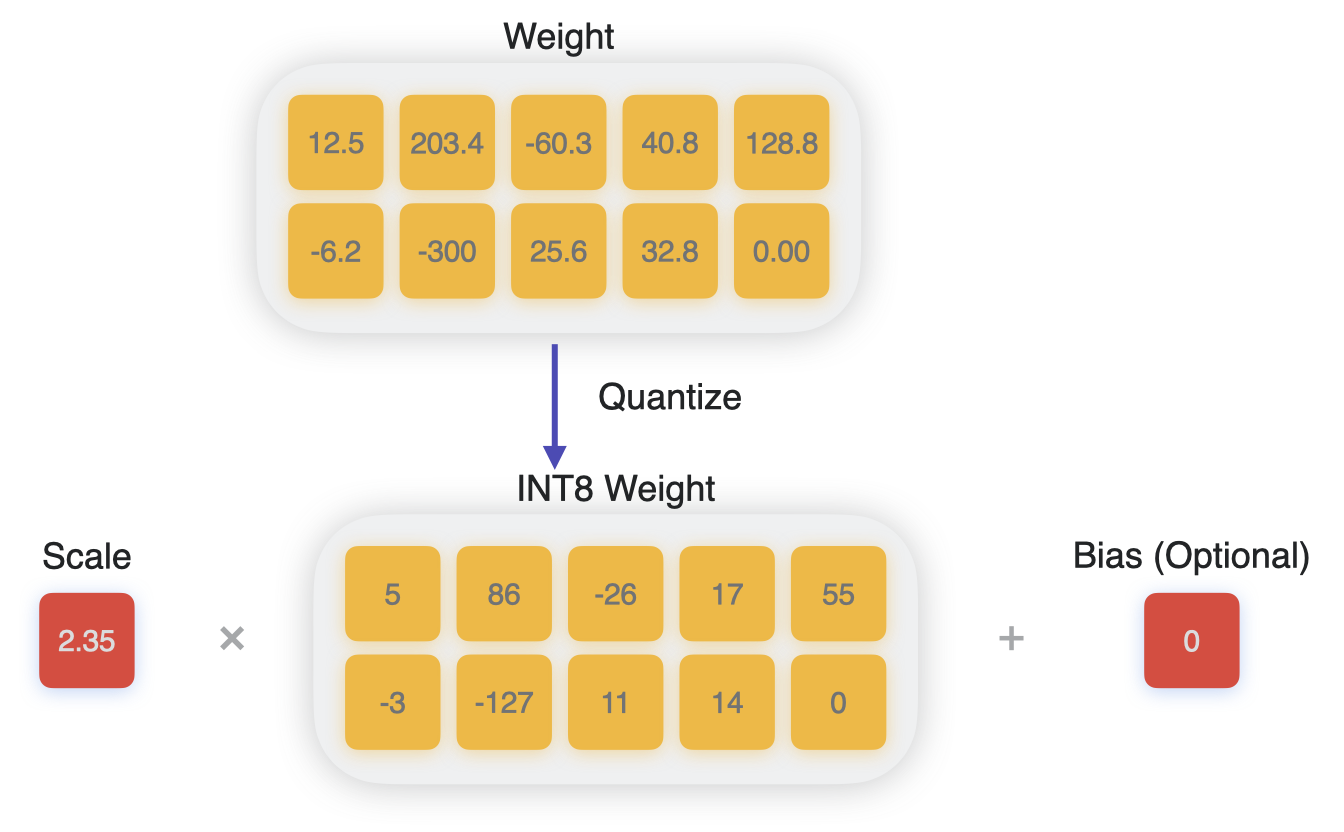
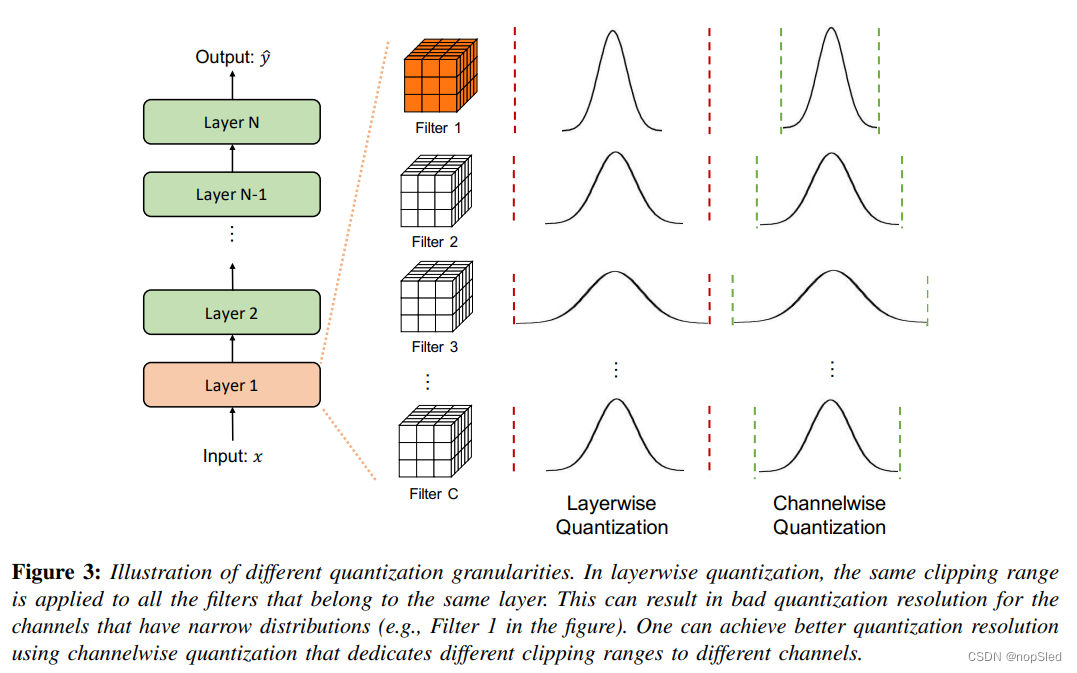
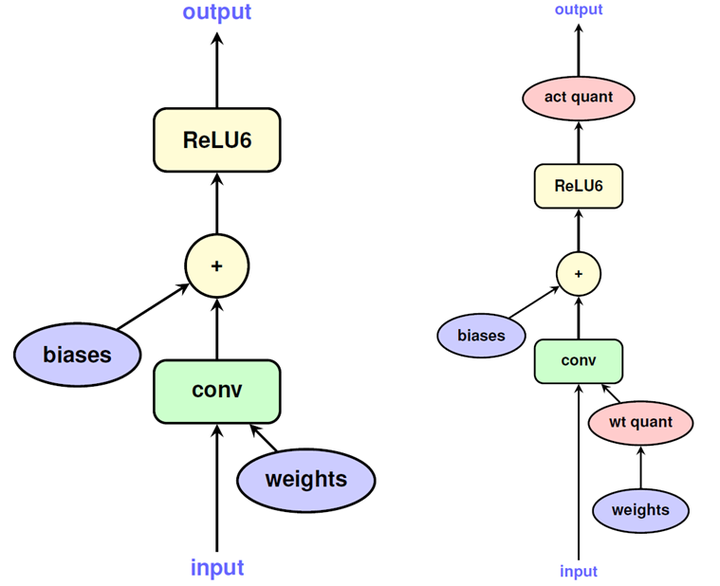
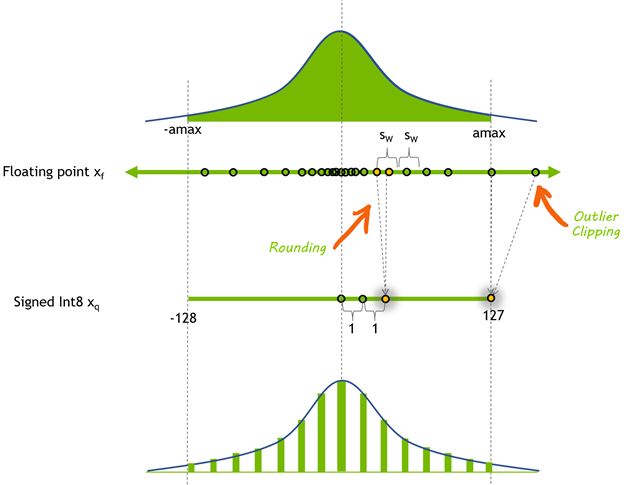
Scale Quantization : A White Paper on Neural Network Quantization – NUUWI
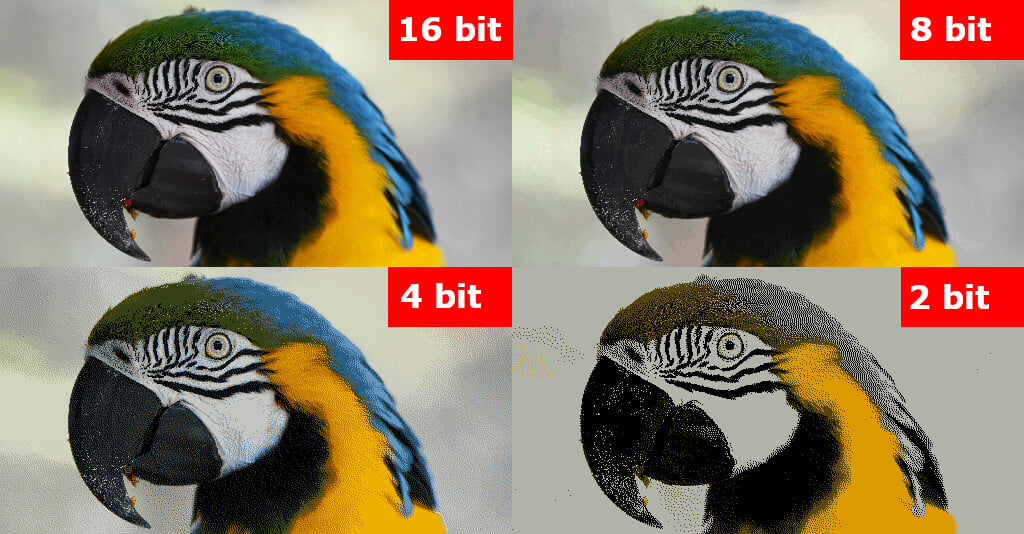
Samples of original image, 1-bit quantization X¹, 2-bit quantization ...
Quantization of unsigned data to 3-bit or 4-bit (α = 1.0) using three ...
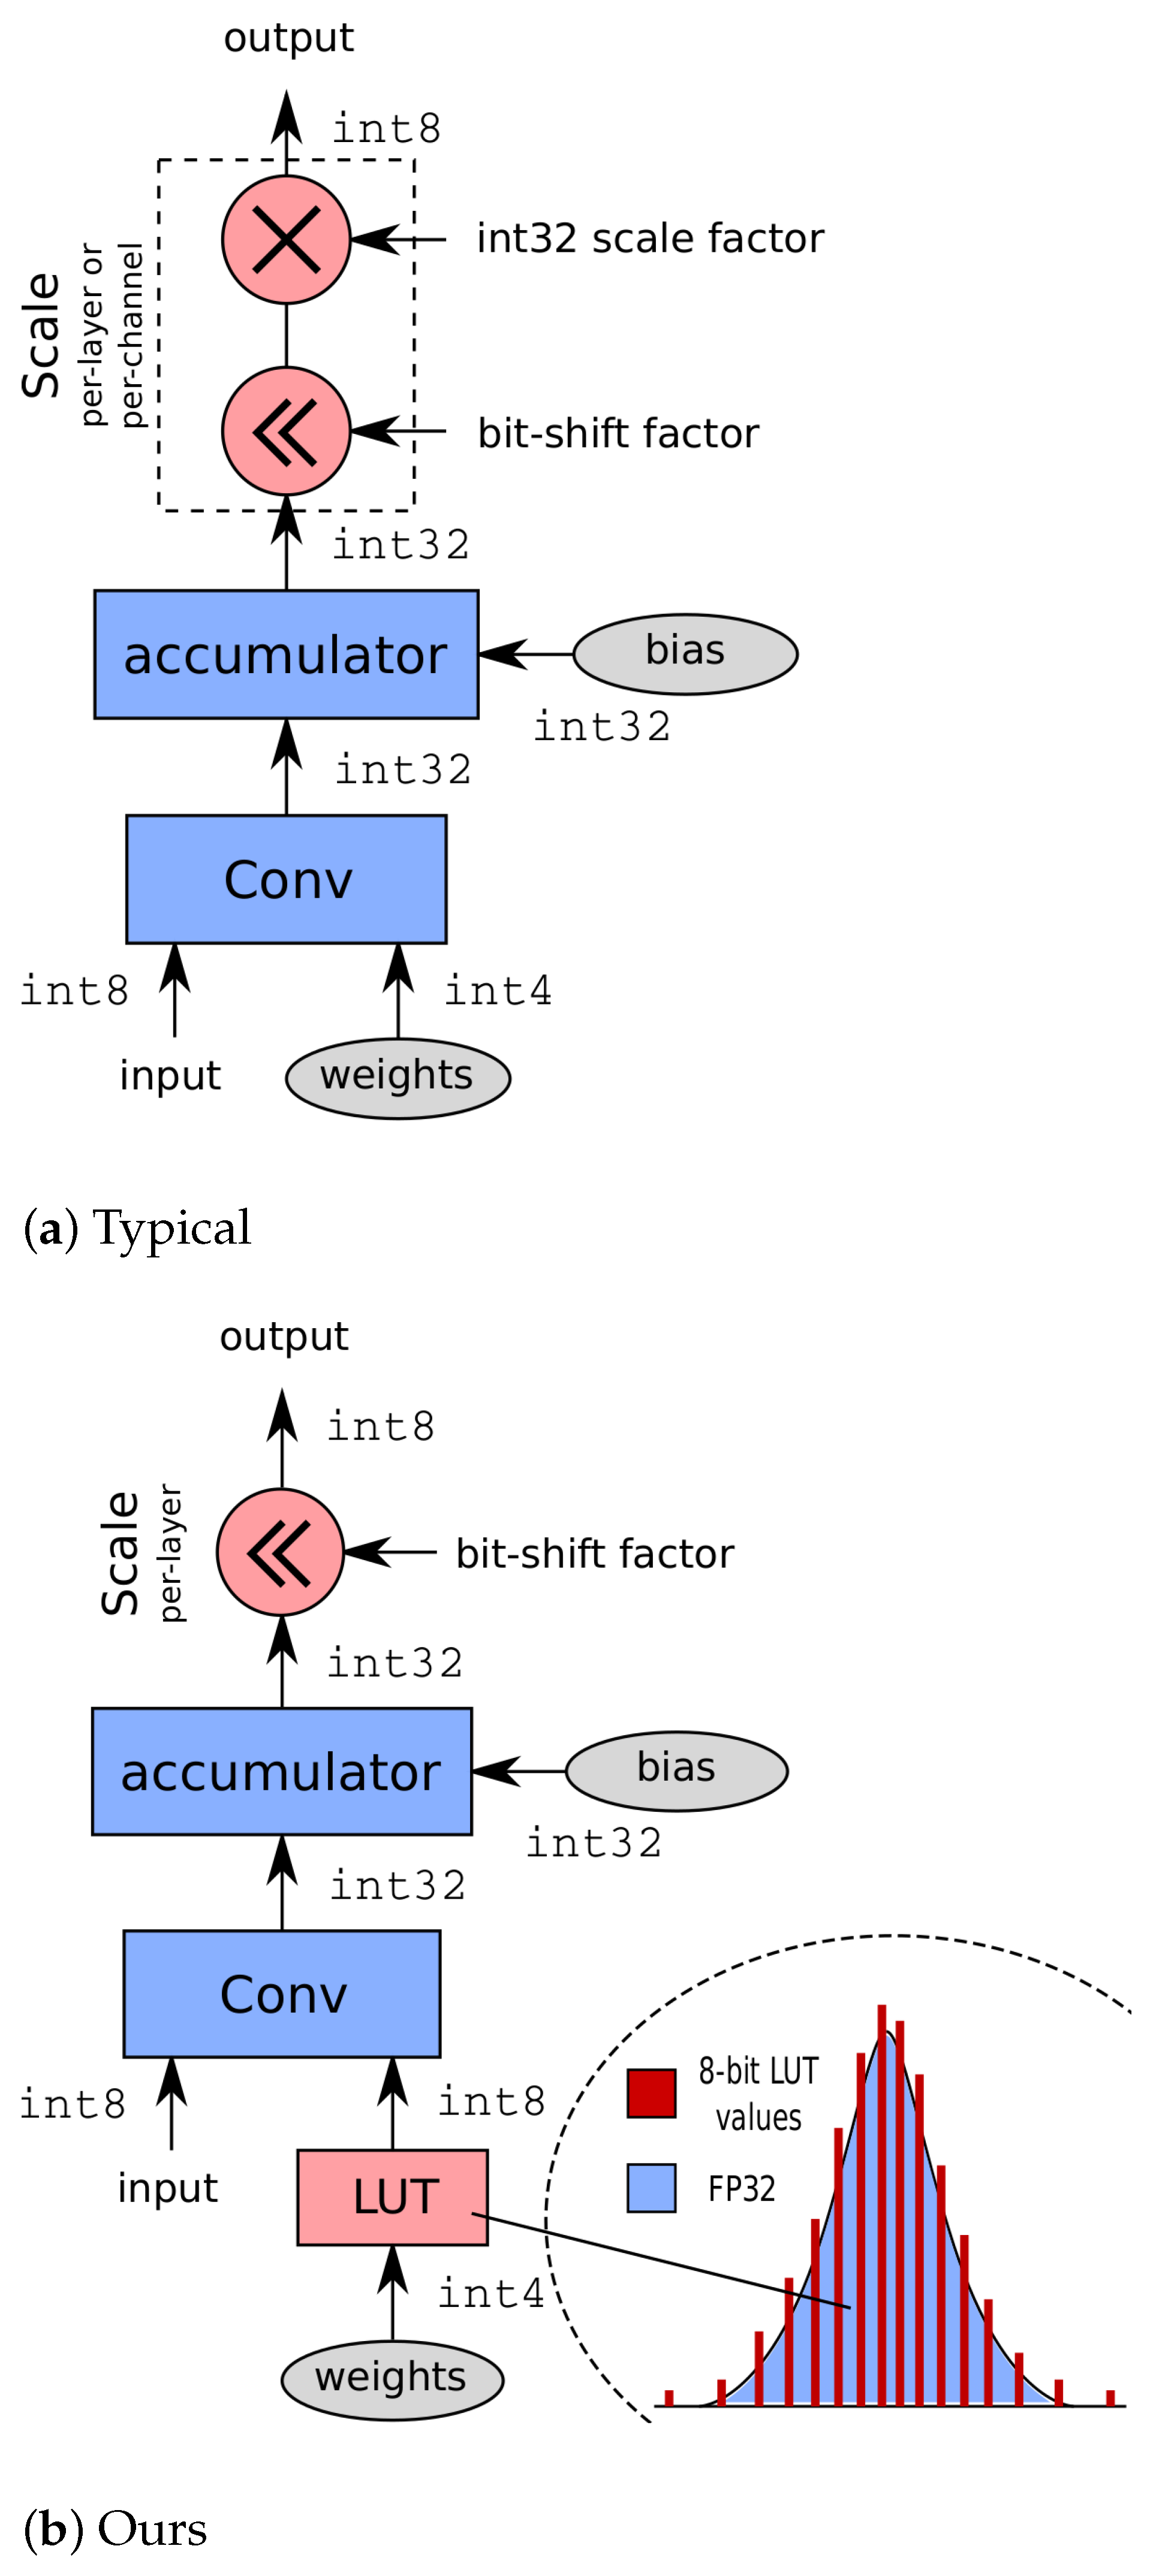
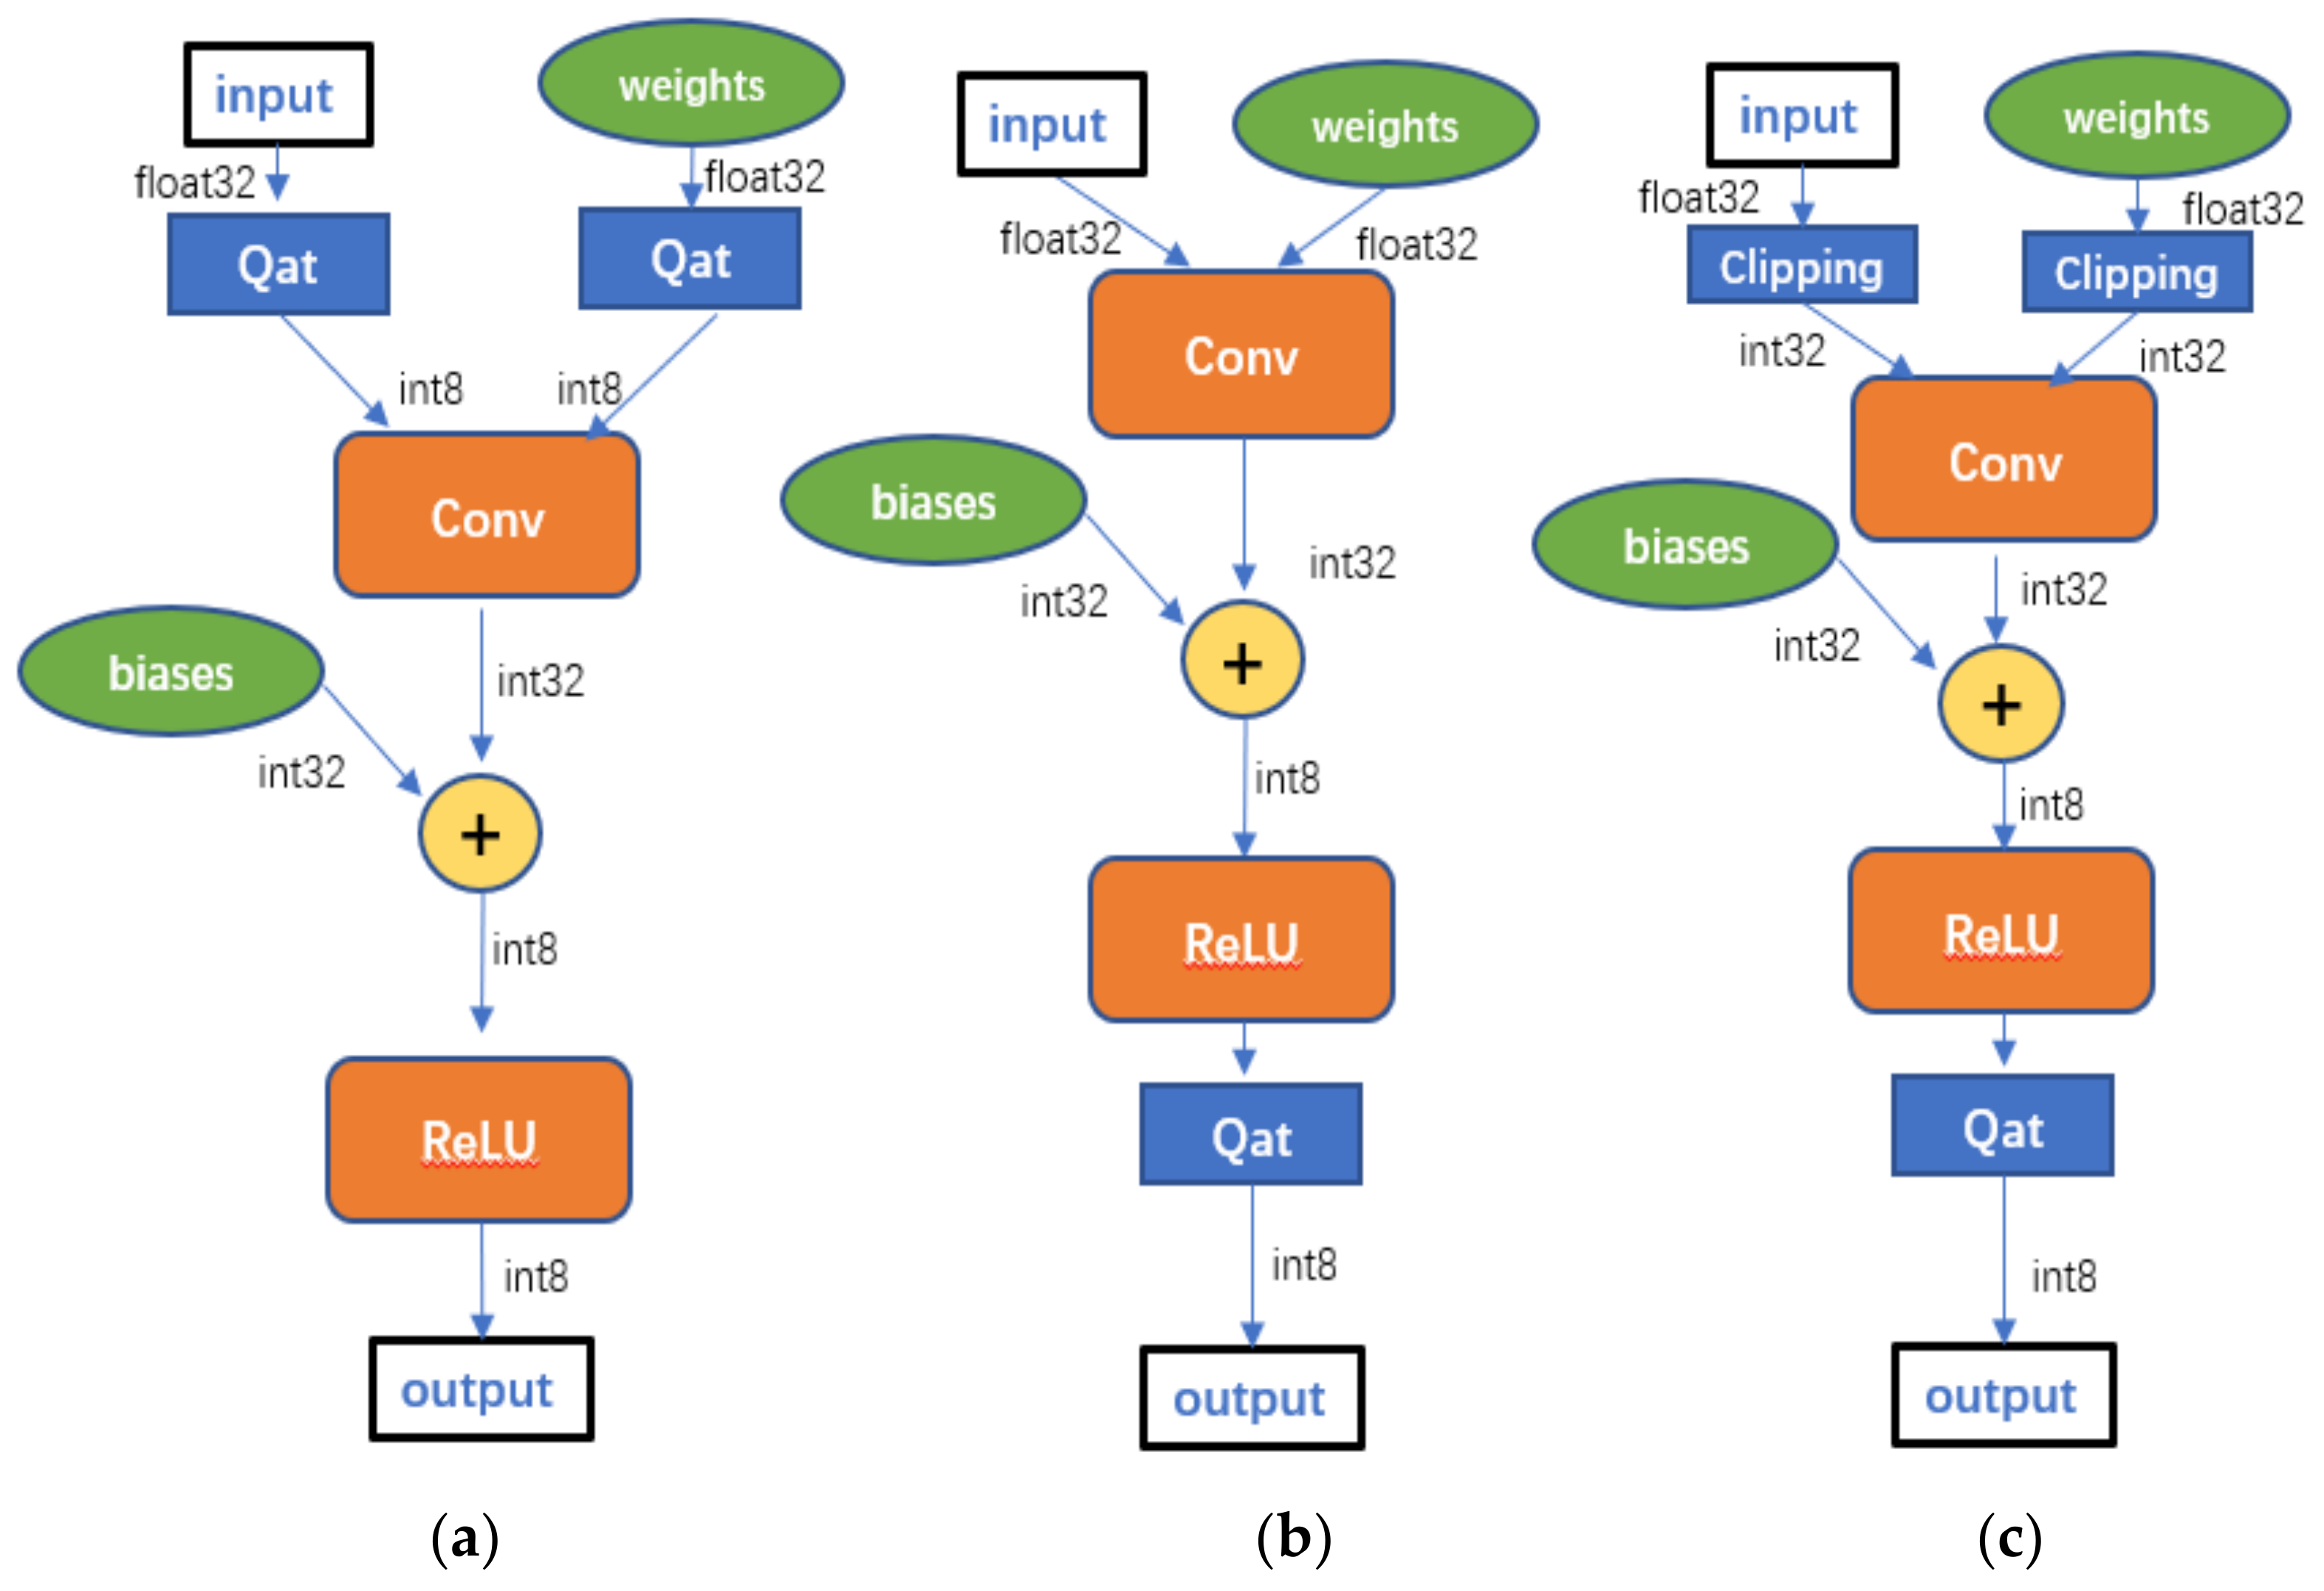
Integer-Only CNNs with 4 Bit Weights and Bit-Shift Quantization Scales ...
enhancement: Add 4-bit quantization / inference support · Issue #181 ...
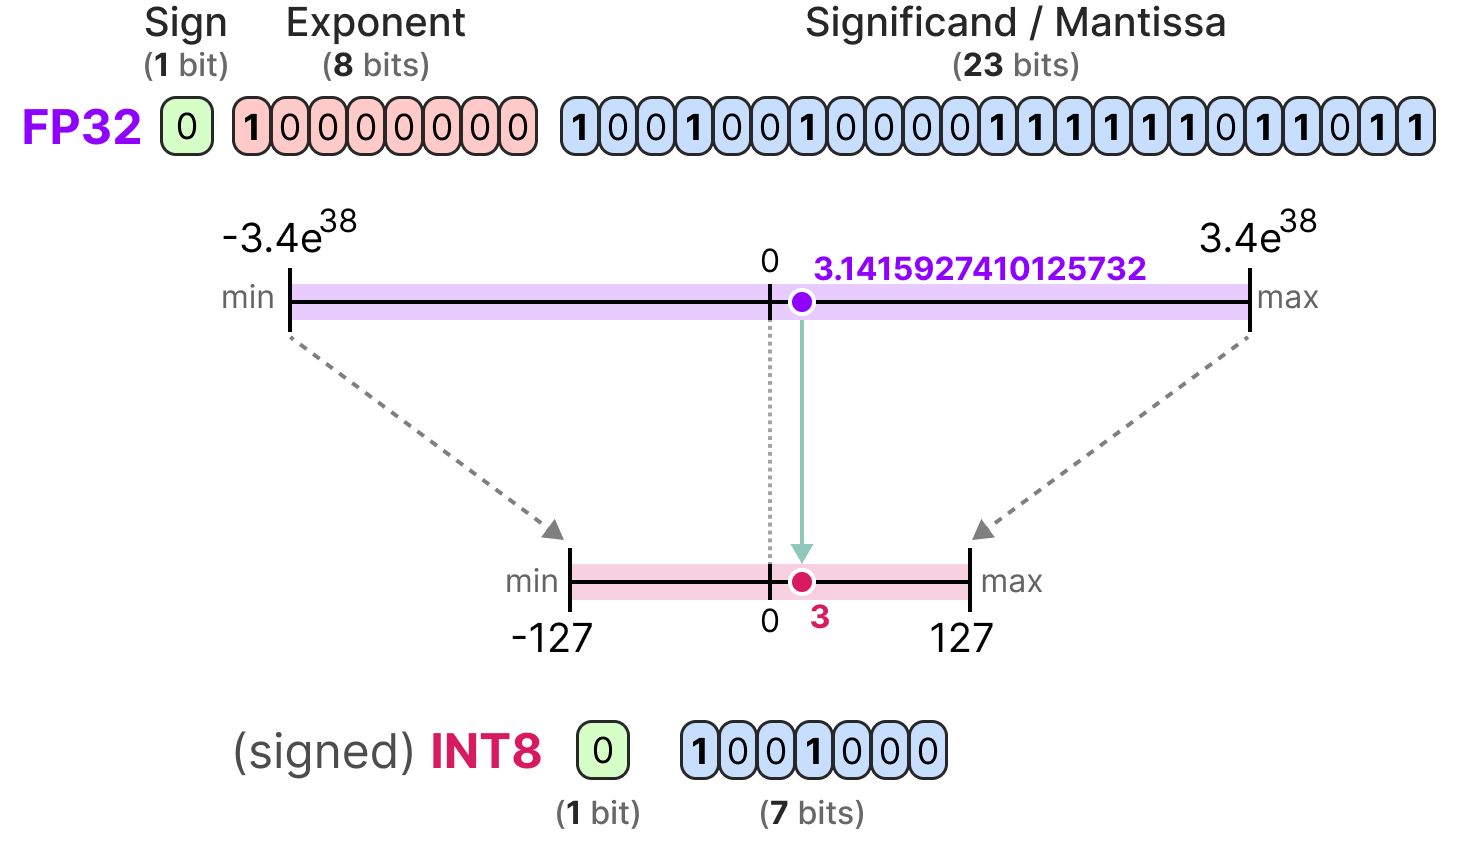
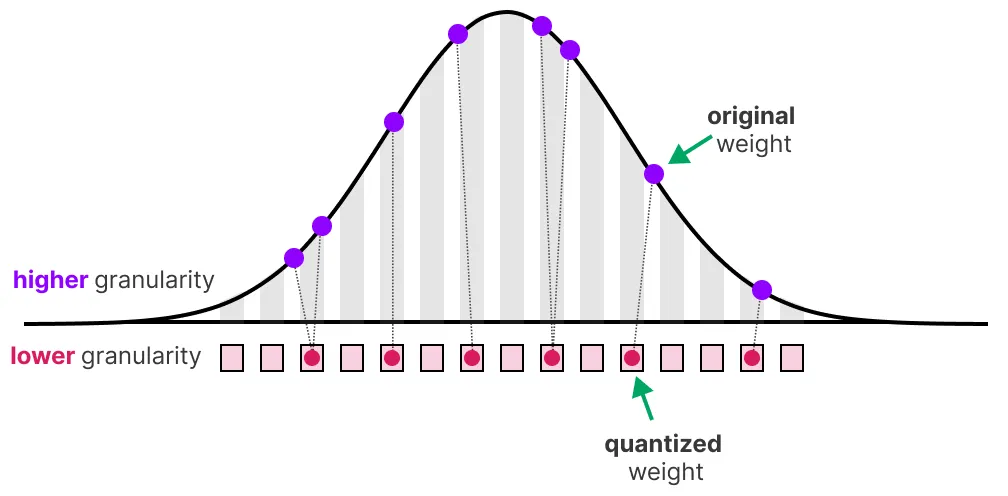
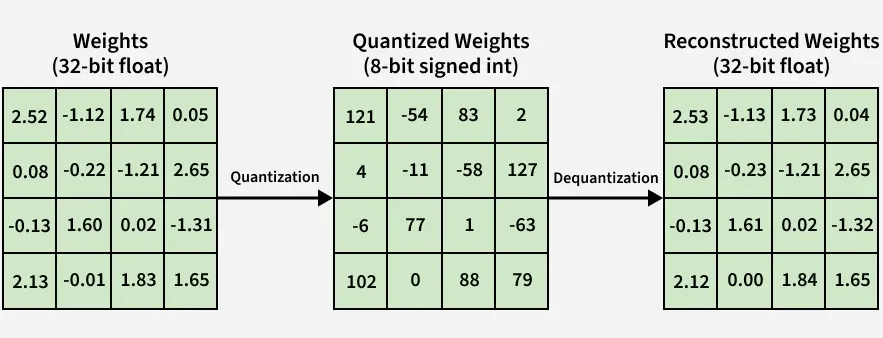
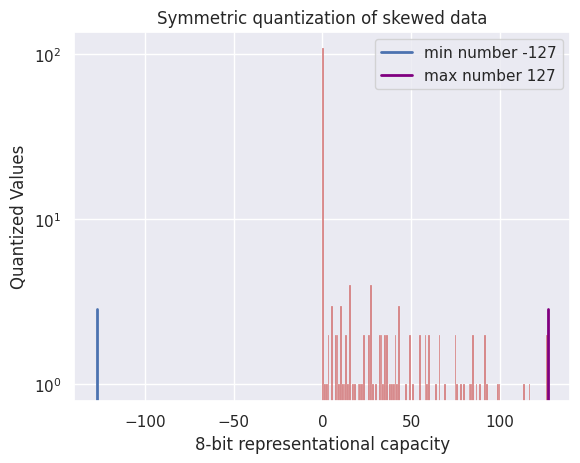
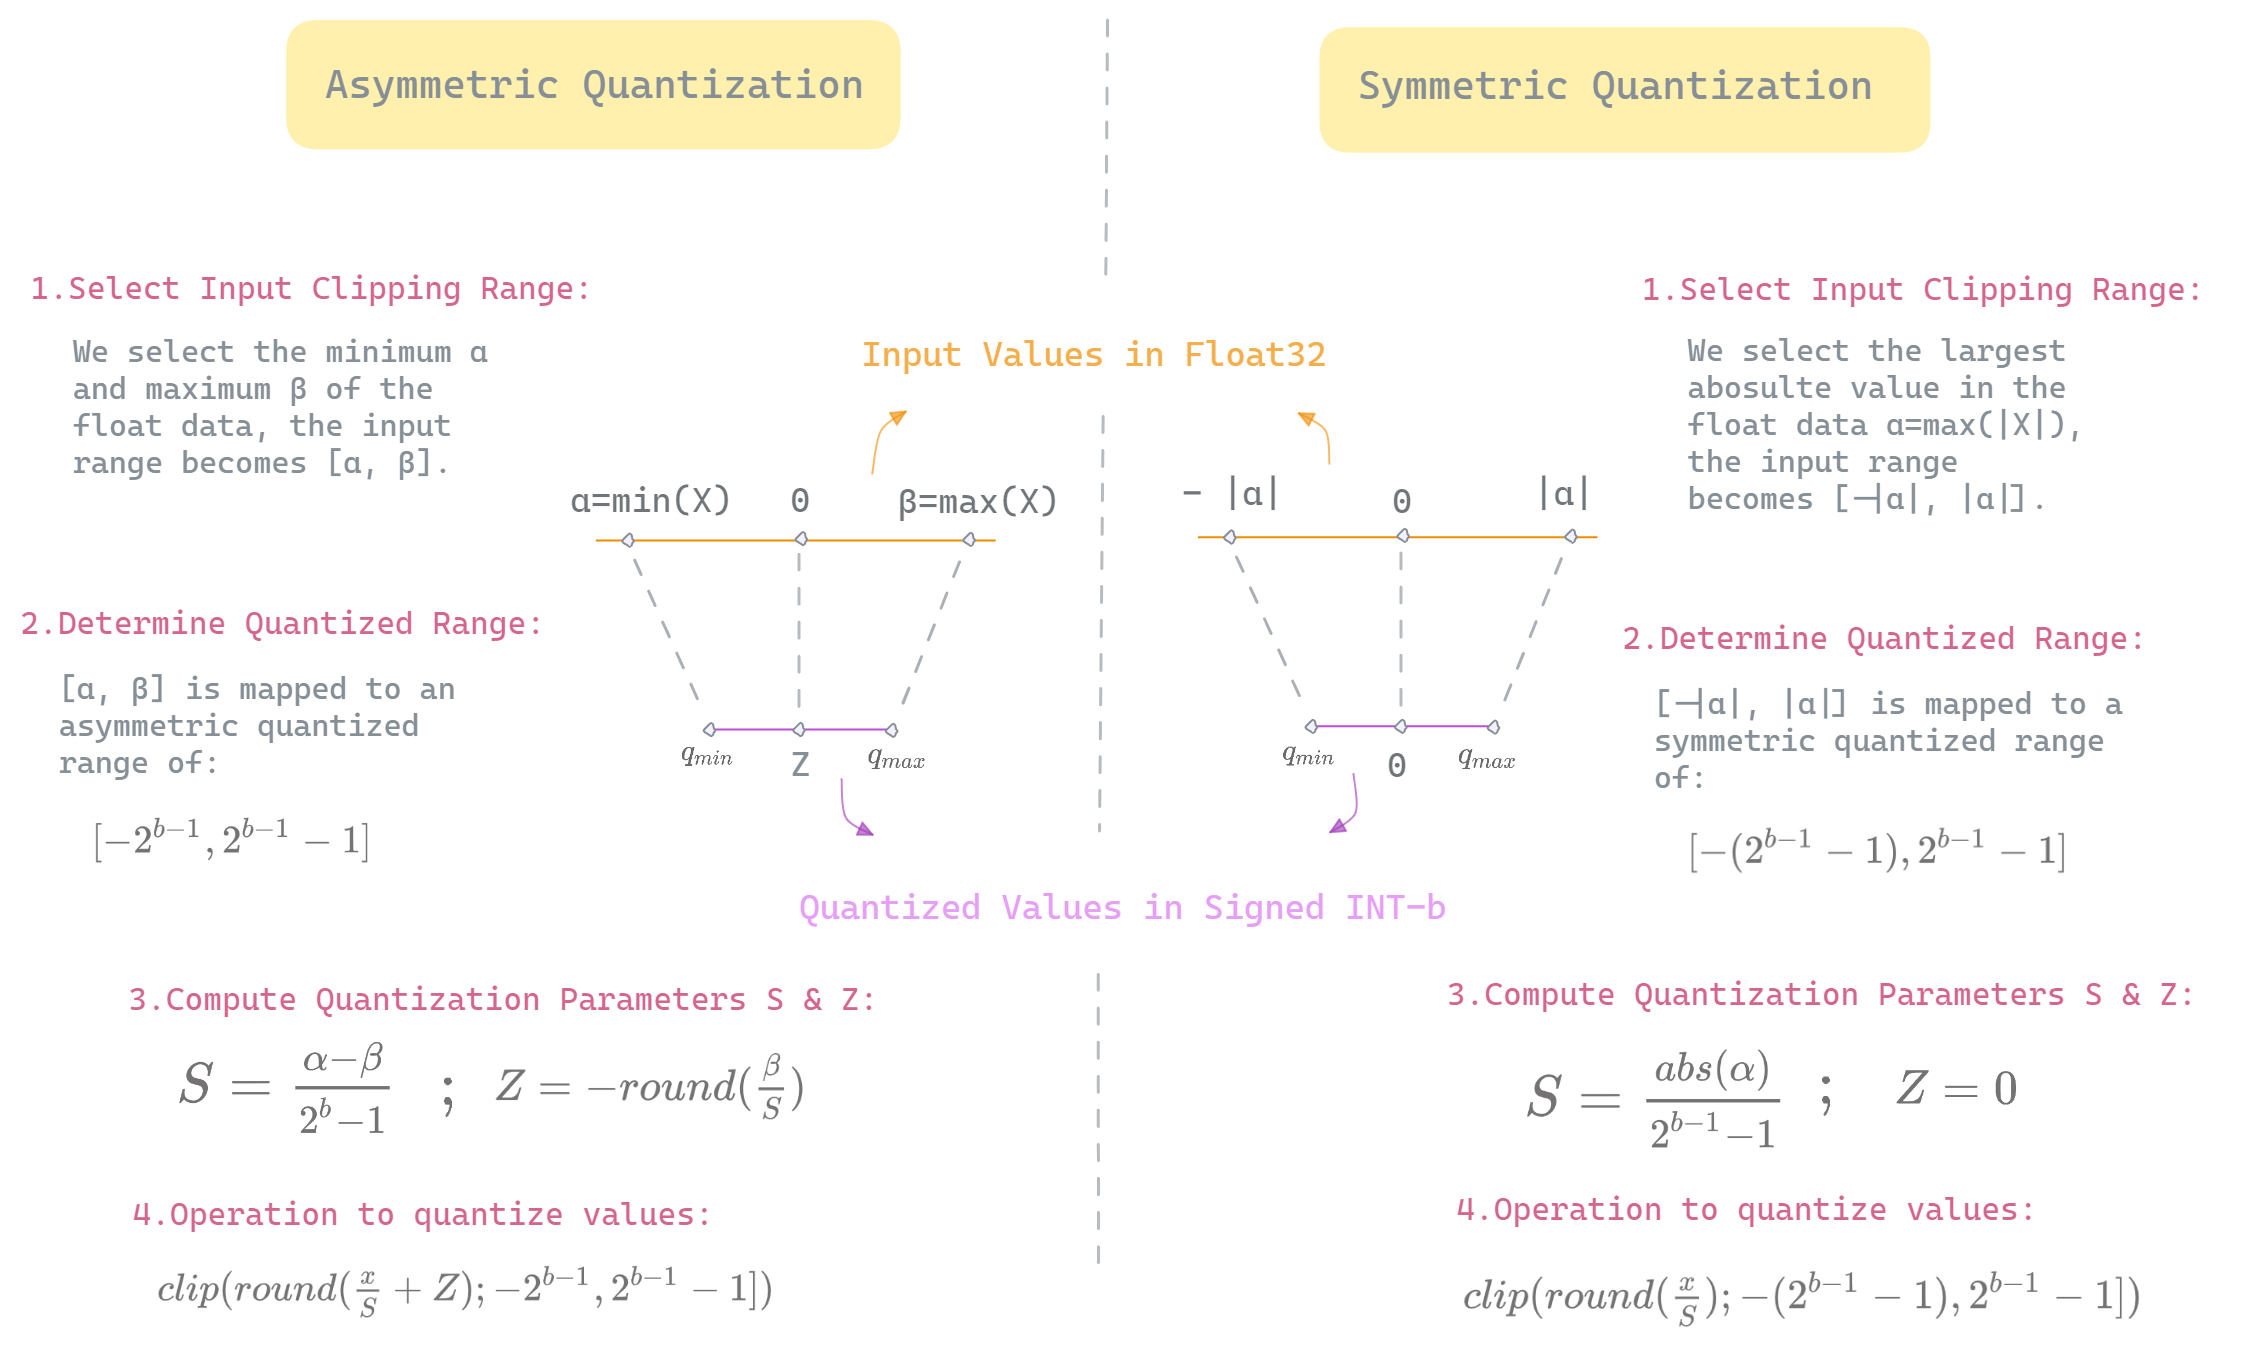
A Visual Guide to Quantization - by Maarten Grootendorst
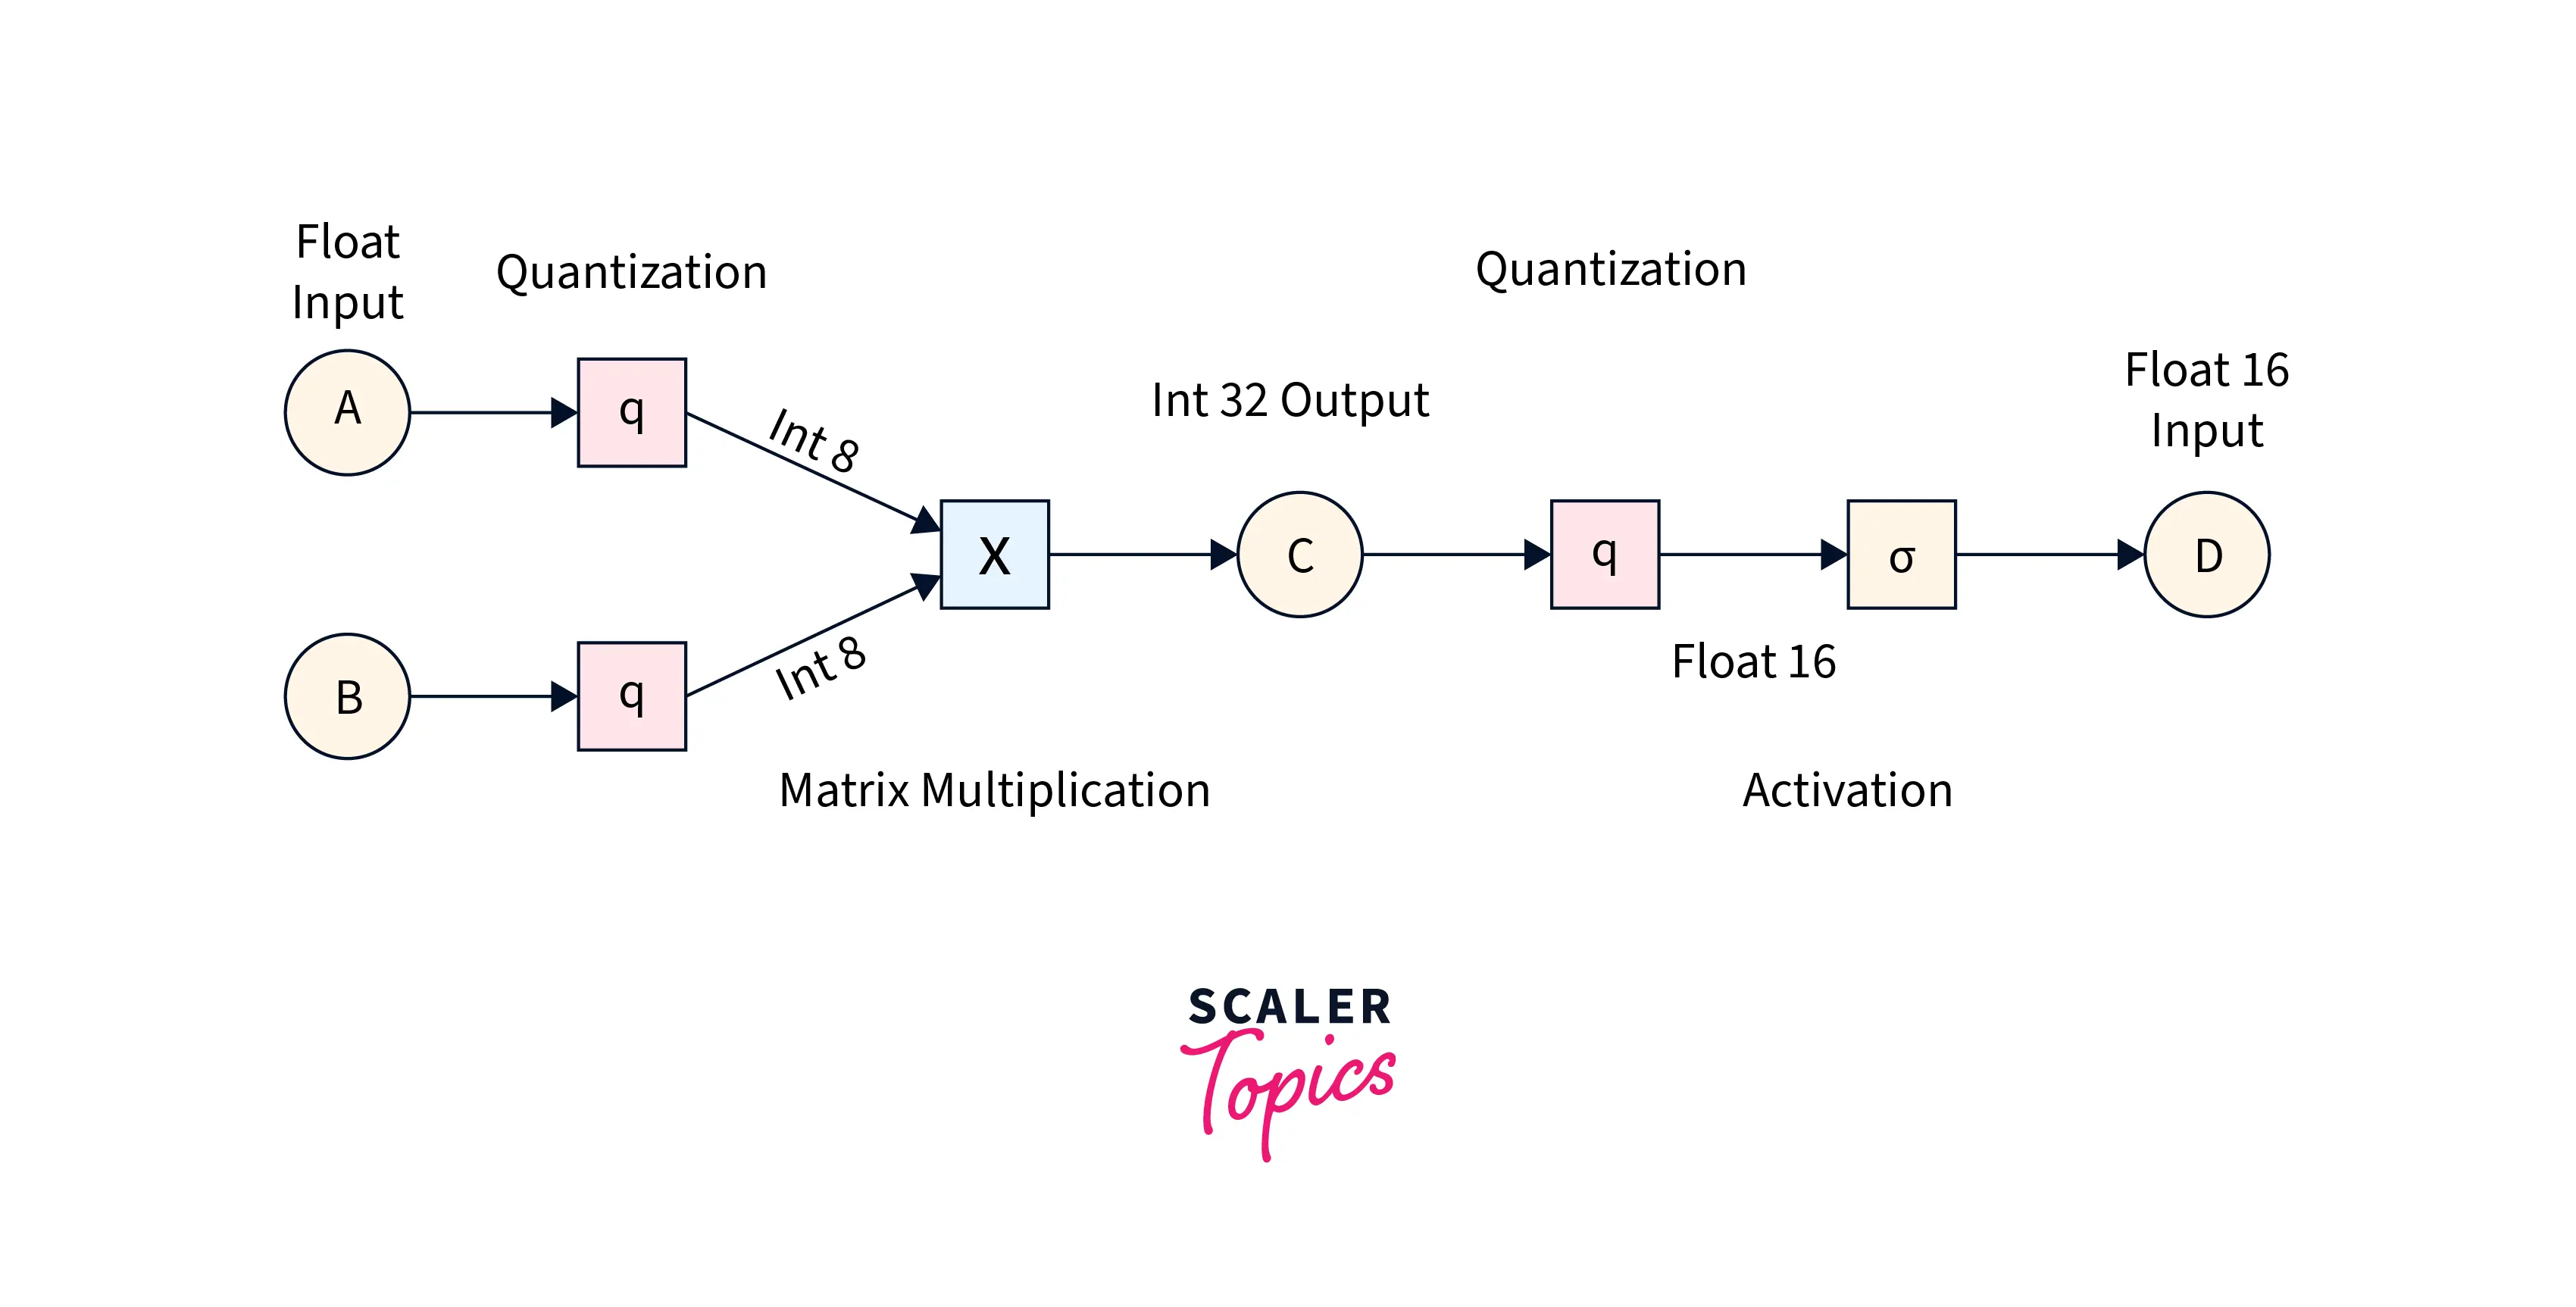
8-Bit Quantization and TensorFlow Lite: Speeding up mobile inference ...
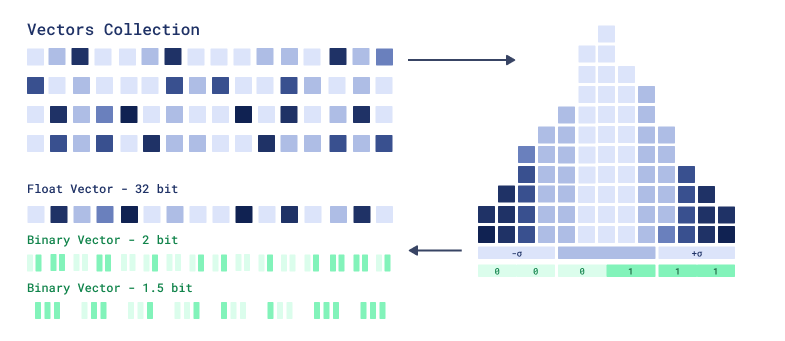
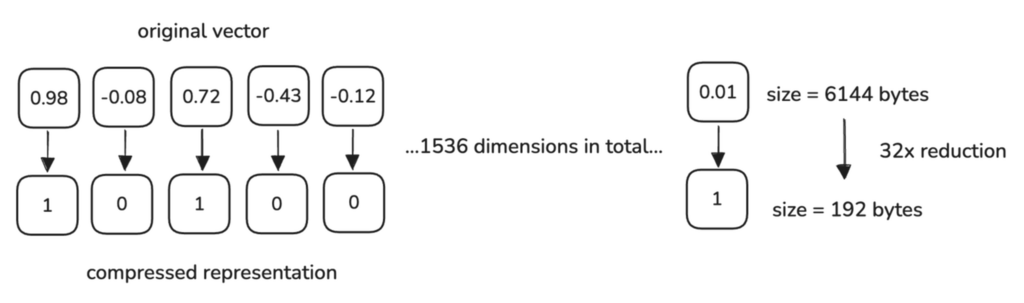
Exploring Binary Quantization in Vector Databases
Mastering QLoRa : A Deep Dive into 4-Bit Quantization and LoRa ...
Quantization — Cours Deep Learning
What is Quantization - GeeksforGeeks
Advances to low-bit quantization enable LLMs on edge devices ...
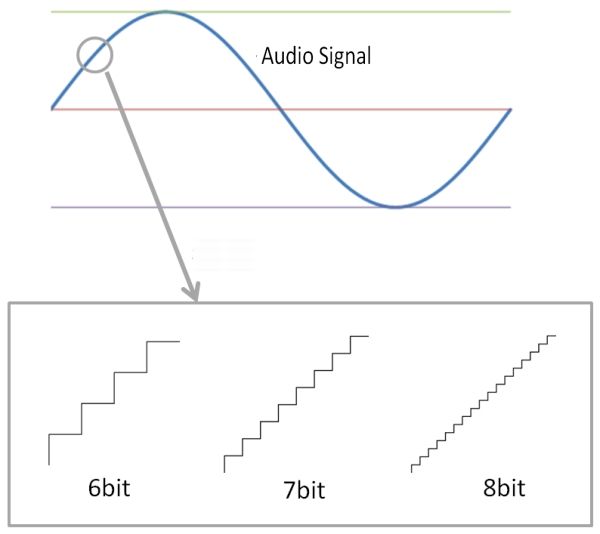
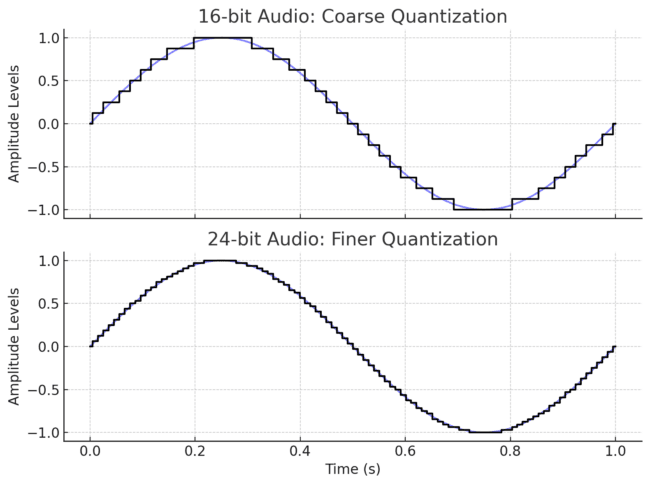
How many bits are your ears? What is the difference in sound quality ...
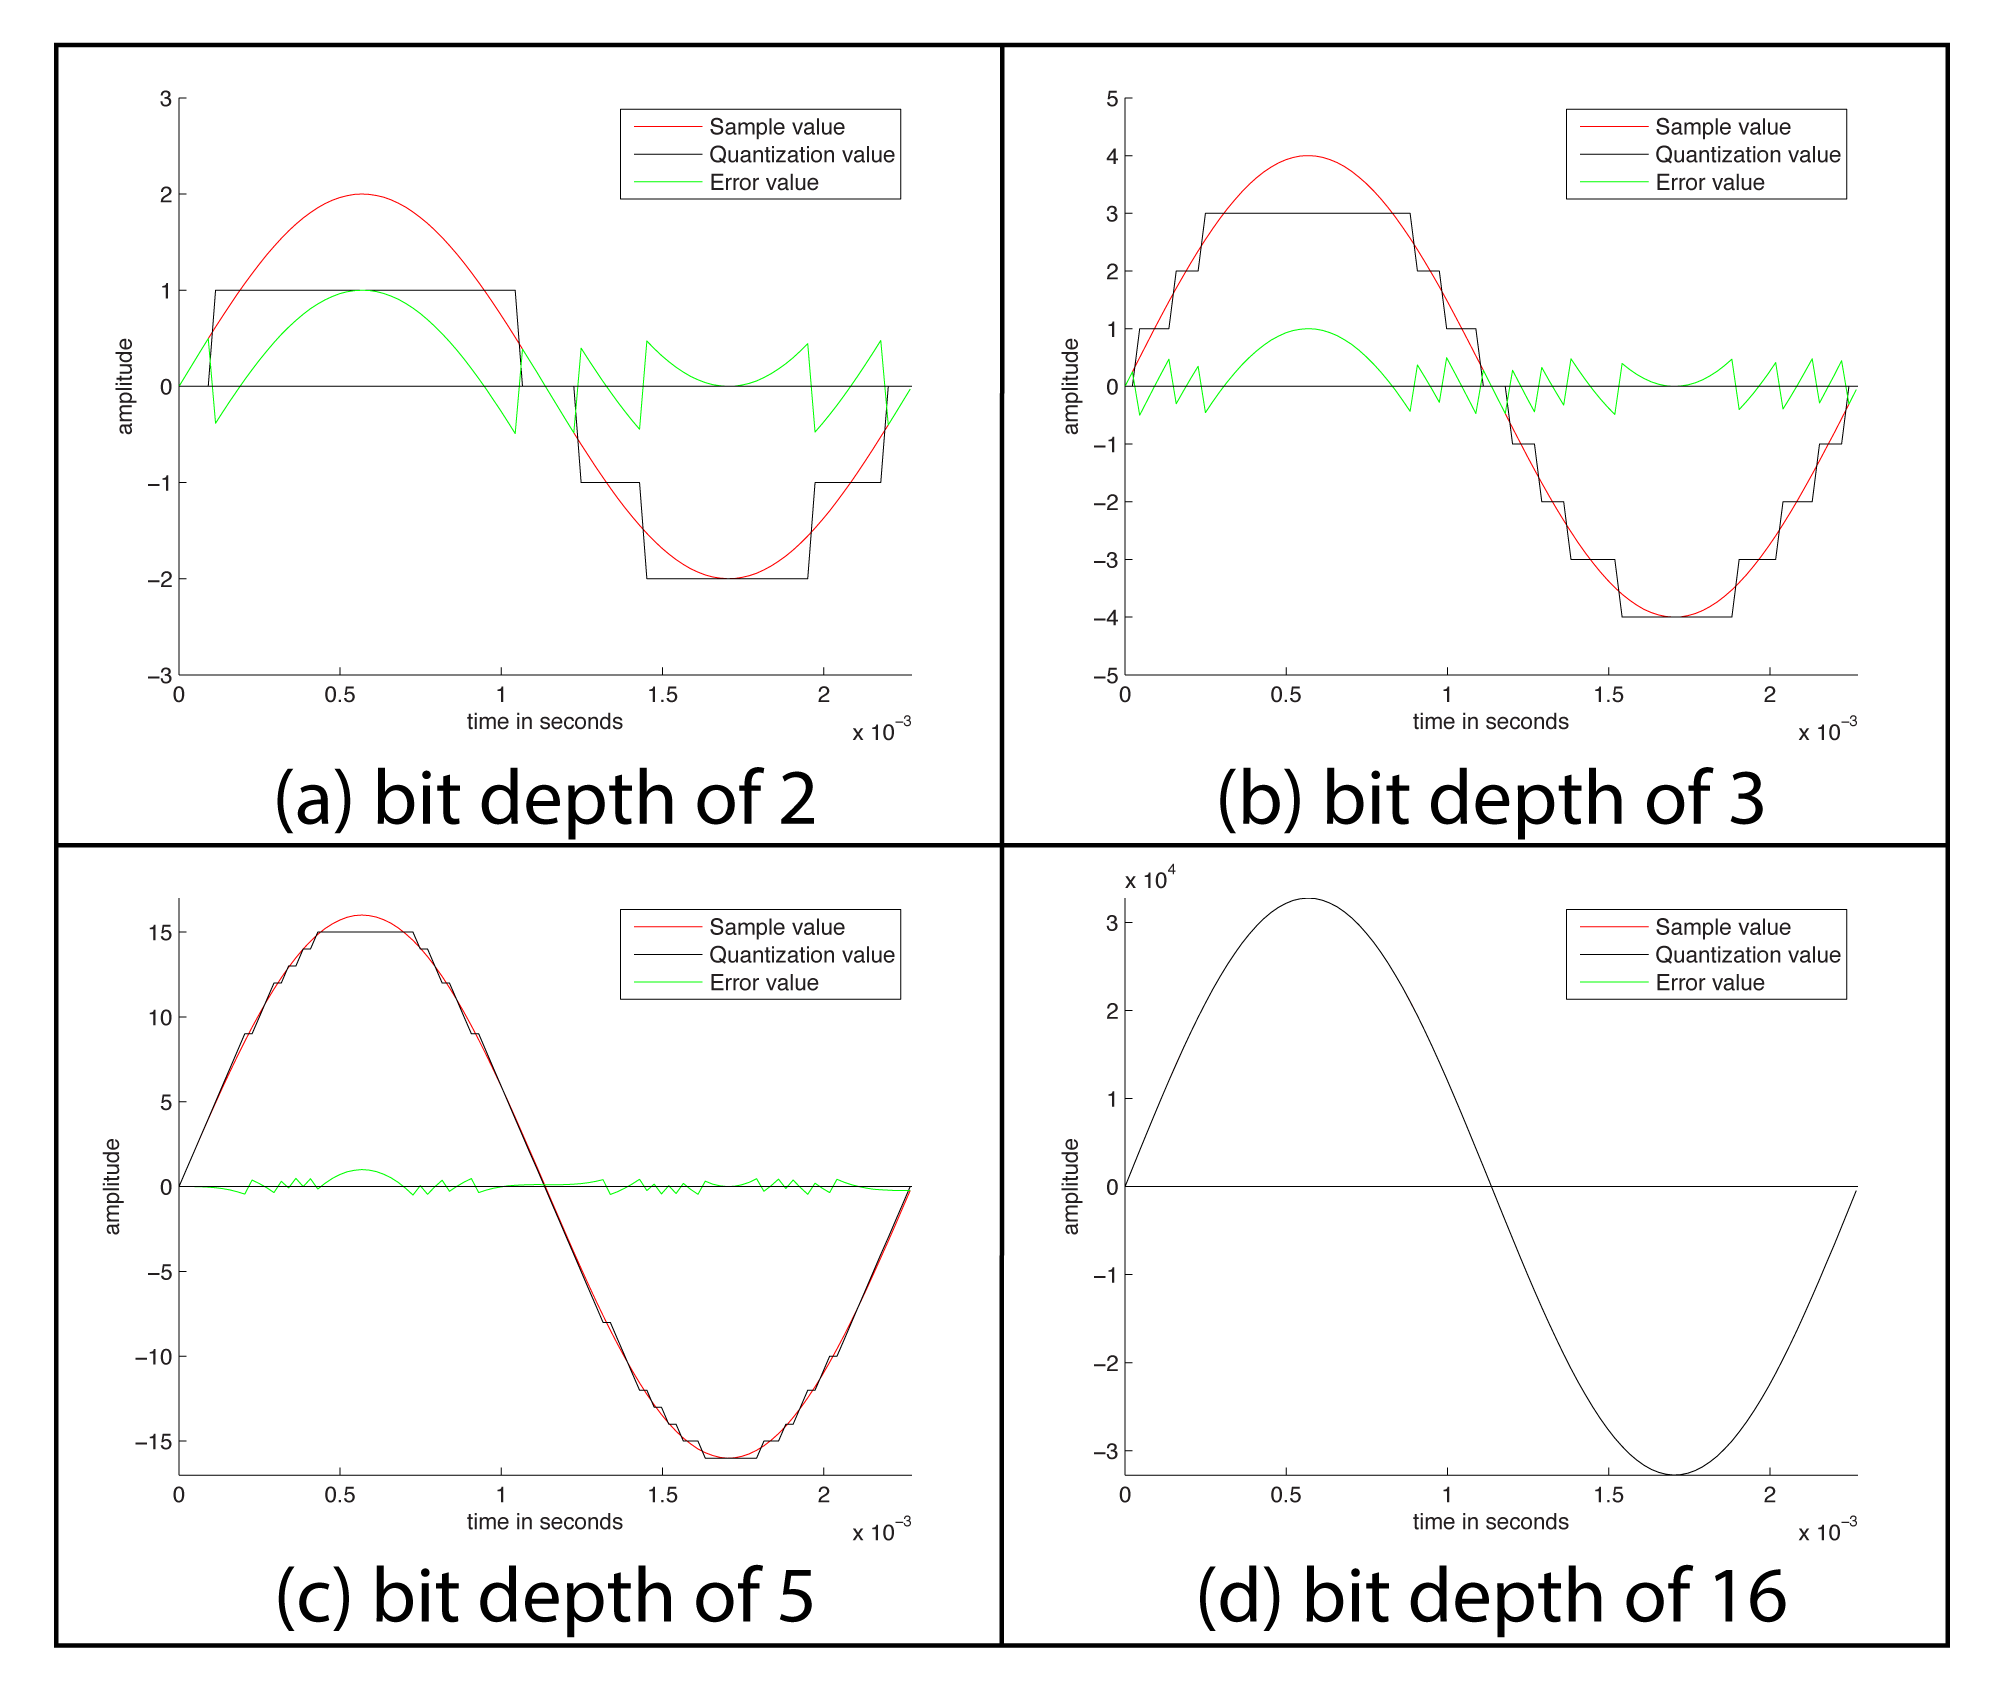
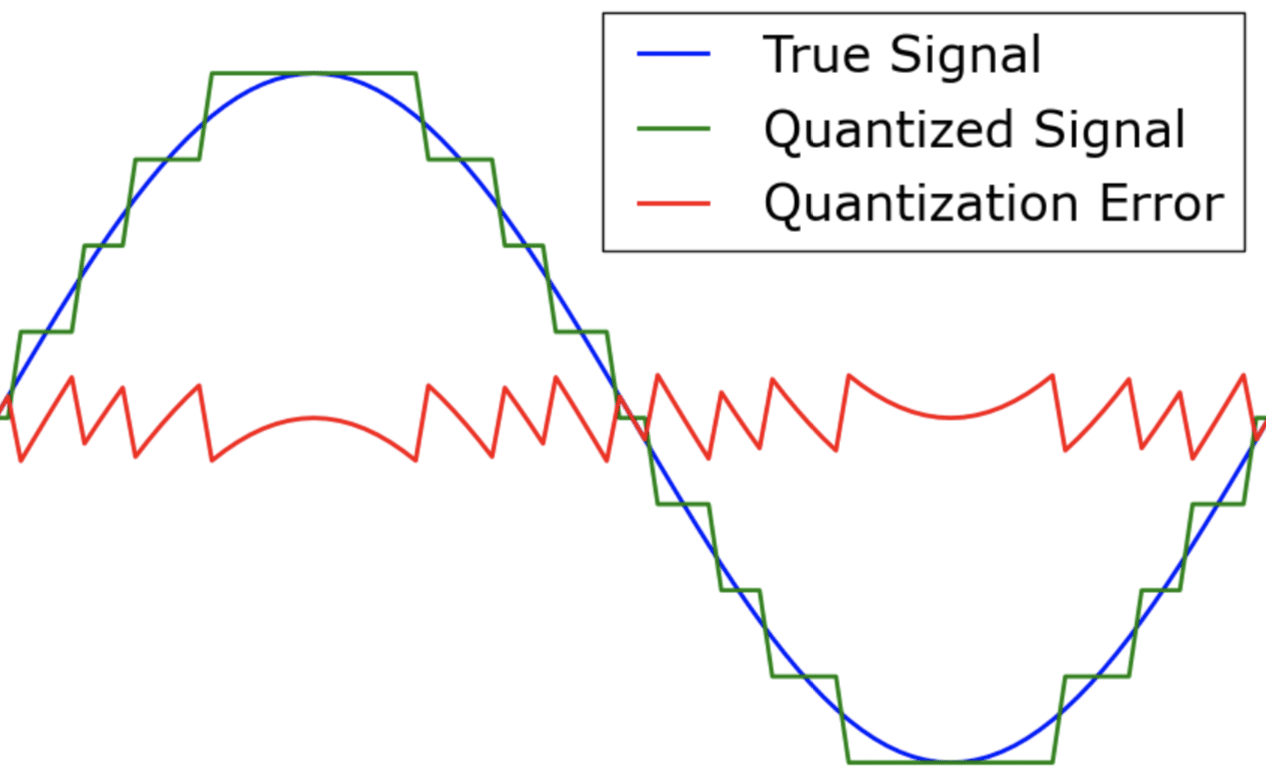
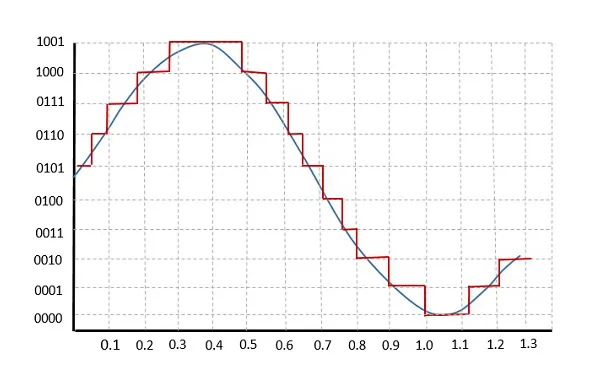
(Color online) Quantization of a sinusoidal signal and the ...
Bit-Weight Adjustment for Bridging Uniform and Non-Uniform Quantization ...
PPT - Introduction to Quantization in Signal Processing PowerPoint ...
ButterflyQuant: Ultra-low-bit LLM Quantization through Learnable ...
The workflow of determining the quantization bit width. m i t is the ...
Which Quantization Method is Right for You? (GPTQ vs. GGUF vs. AWQ)
Neural Network Quantization Paper – ZMIF
One Bit Quantization Technology - fltech - Technology Blog of Fujitsu ...
Model Quantization in Deep Learning
[論文レビュー] Mixed-Precision Graph Neural Quantization for Low Bit Large ...
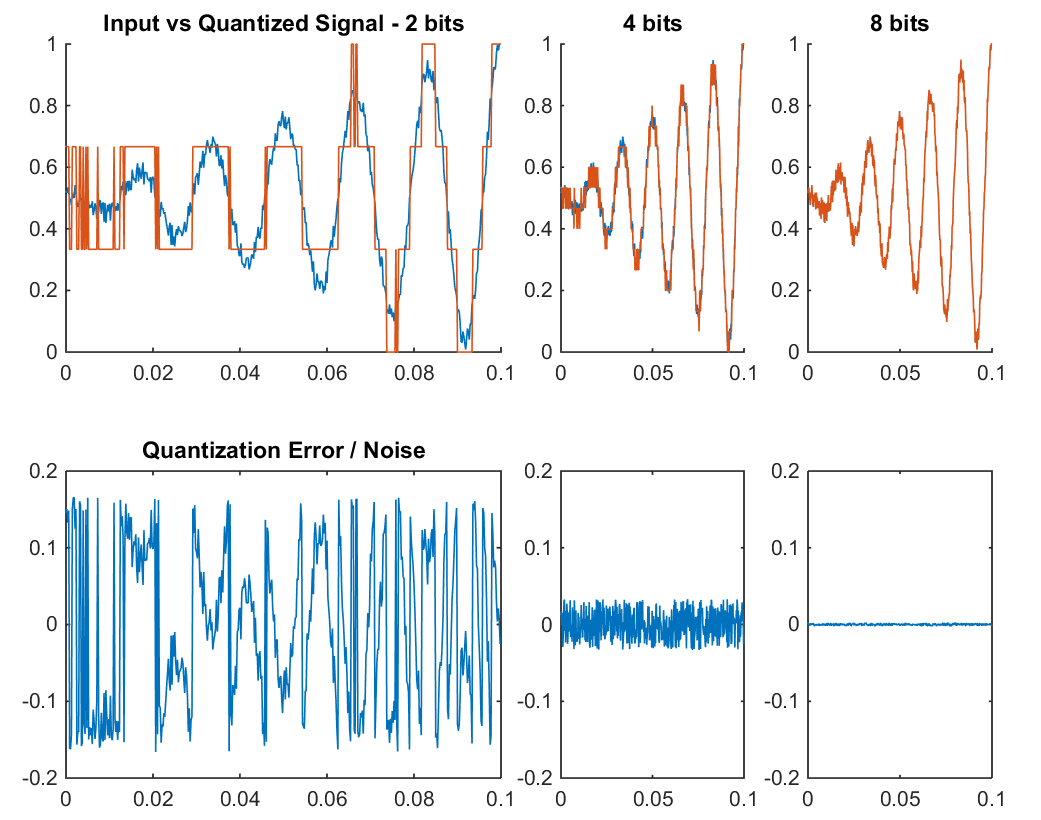
Trade-off between the quantization bit and SNR | Download Scientific ...
Quantization Overview — Guide to Core ML Tools
How to optimize large deep learning models using quantization
A Survey of Quantization Methods for Efficient Neural Network Inference ...
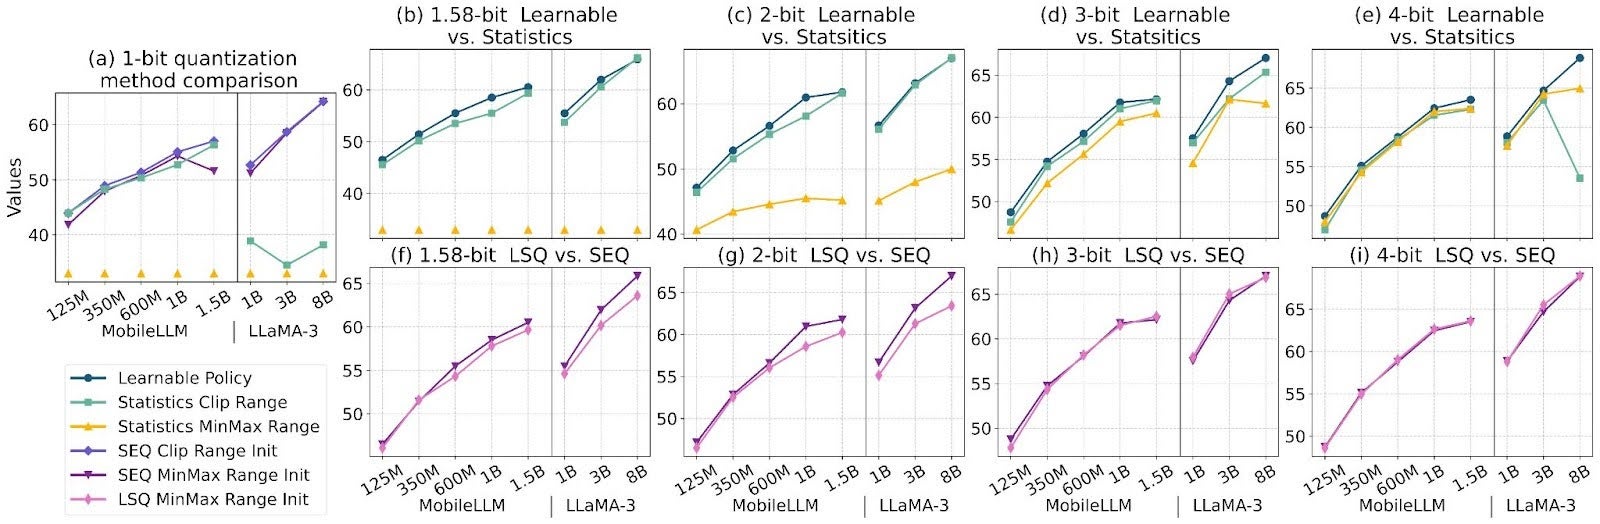
ParetoQ: Scaling Laws in Extremely Low-bit LLM Quantization – PyTorch
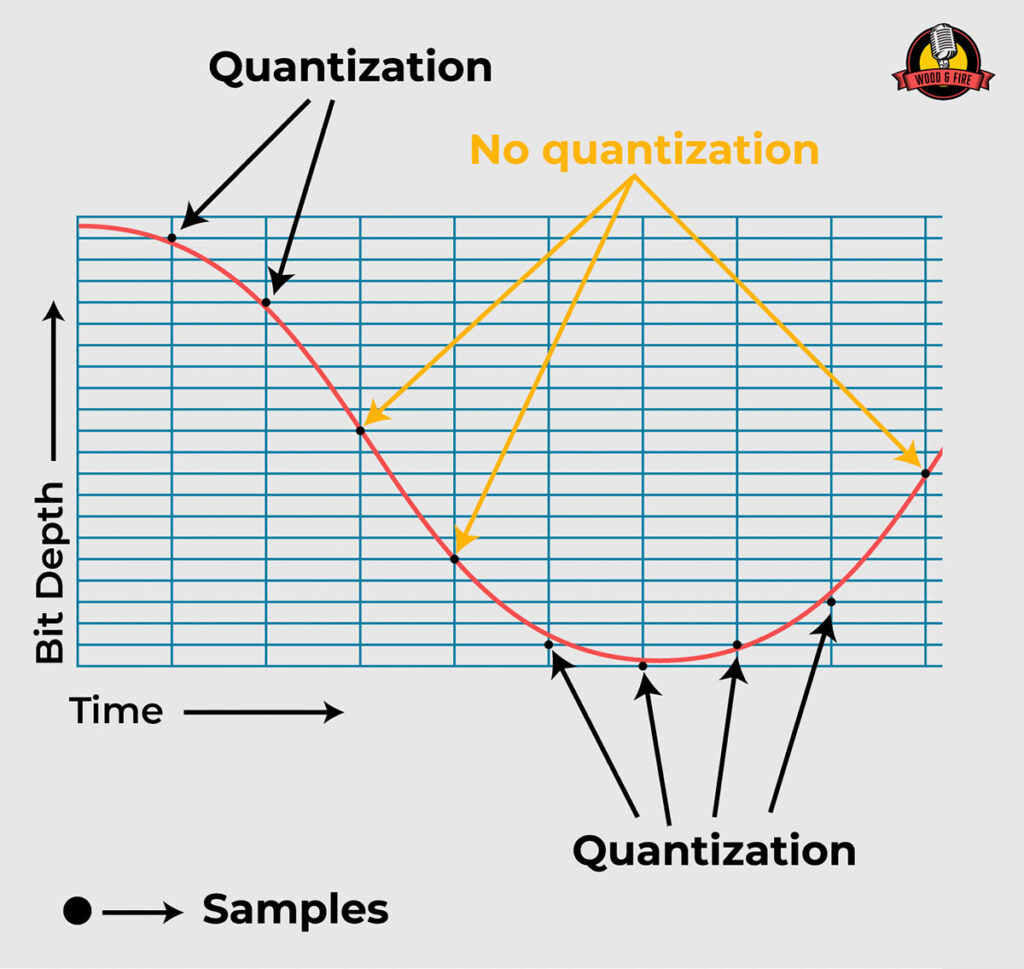
What Is Quantization In Analog To Digital Conversion at Henry Numbers blog
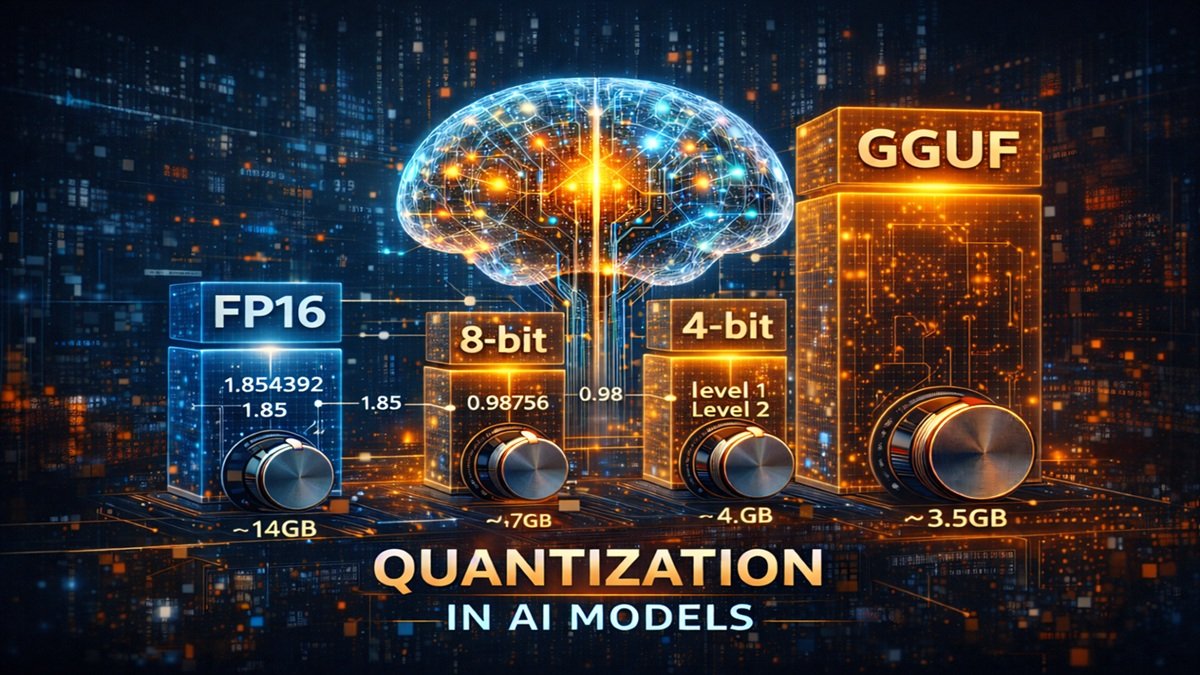
Quantization in AI Models (4-bit, 8-bit, GGUF) — A Clear Detailed Guide ...
Neural Network Activation Quantization with Bitwise Information ...
We compare different ways to achieve 4-bit quantization using three ...
LLM Quantization Methods: GPTQ, AWQ, GGUF - Cast AI
8-Bit Optimizers Via Block-Wise Quantization - 知乎
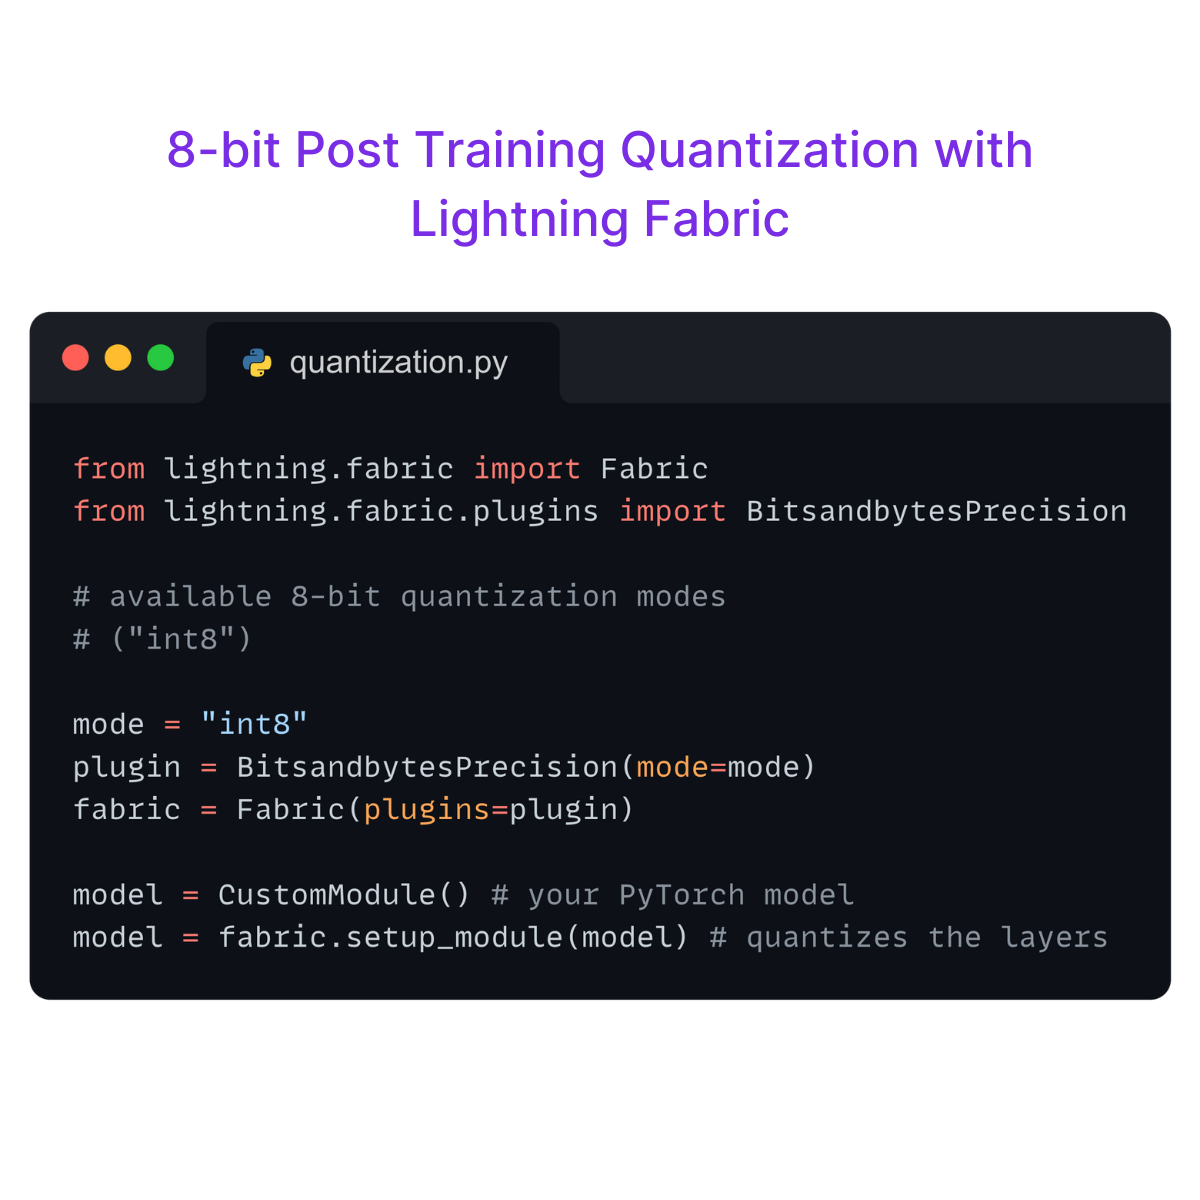
What is Quantization - Lightning AI
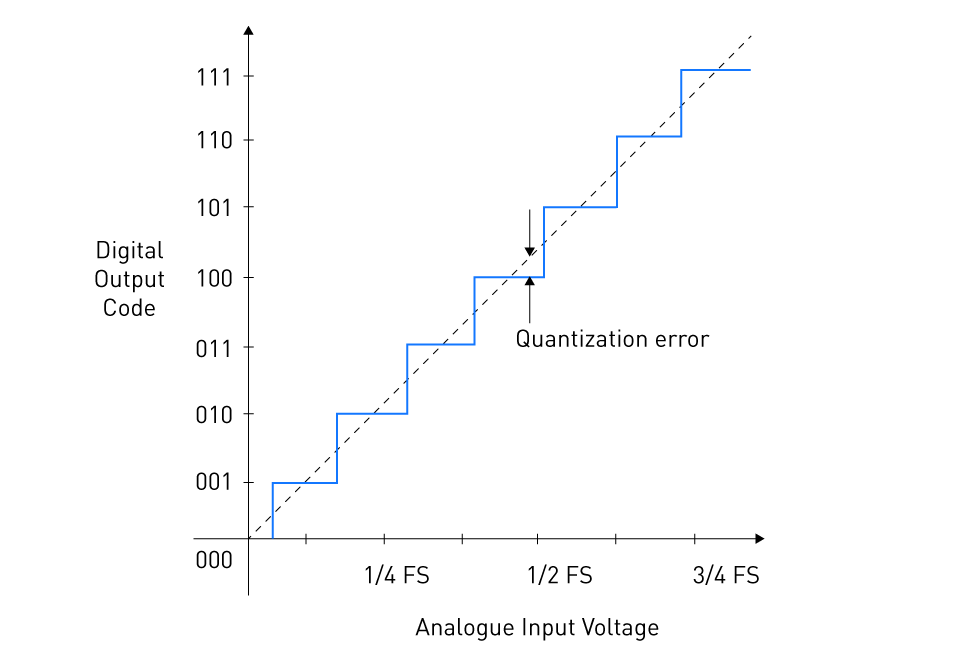
Example of an ADC quantization function for 3-bit quantizer. | Download ...
Quantization Algorithm Overview | MindSpore Golden Stick master ...
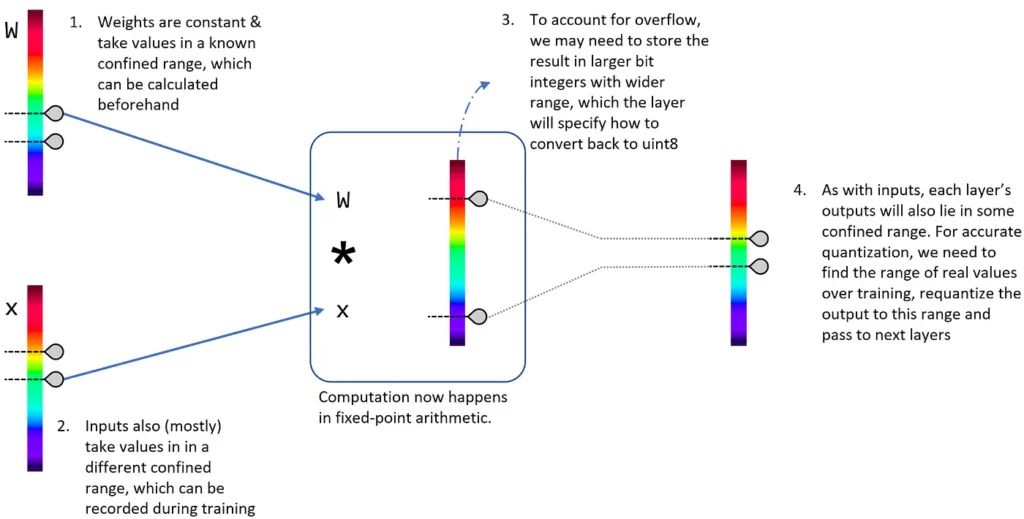
[21.06] A White Paper on Neural Network Quantization
LLMs for your iPhone: Whole-Tensor 4 Bit Quantization
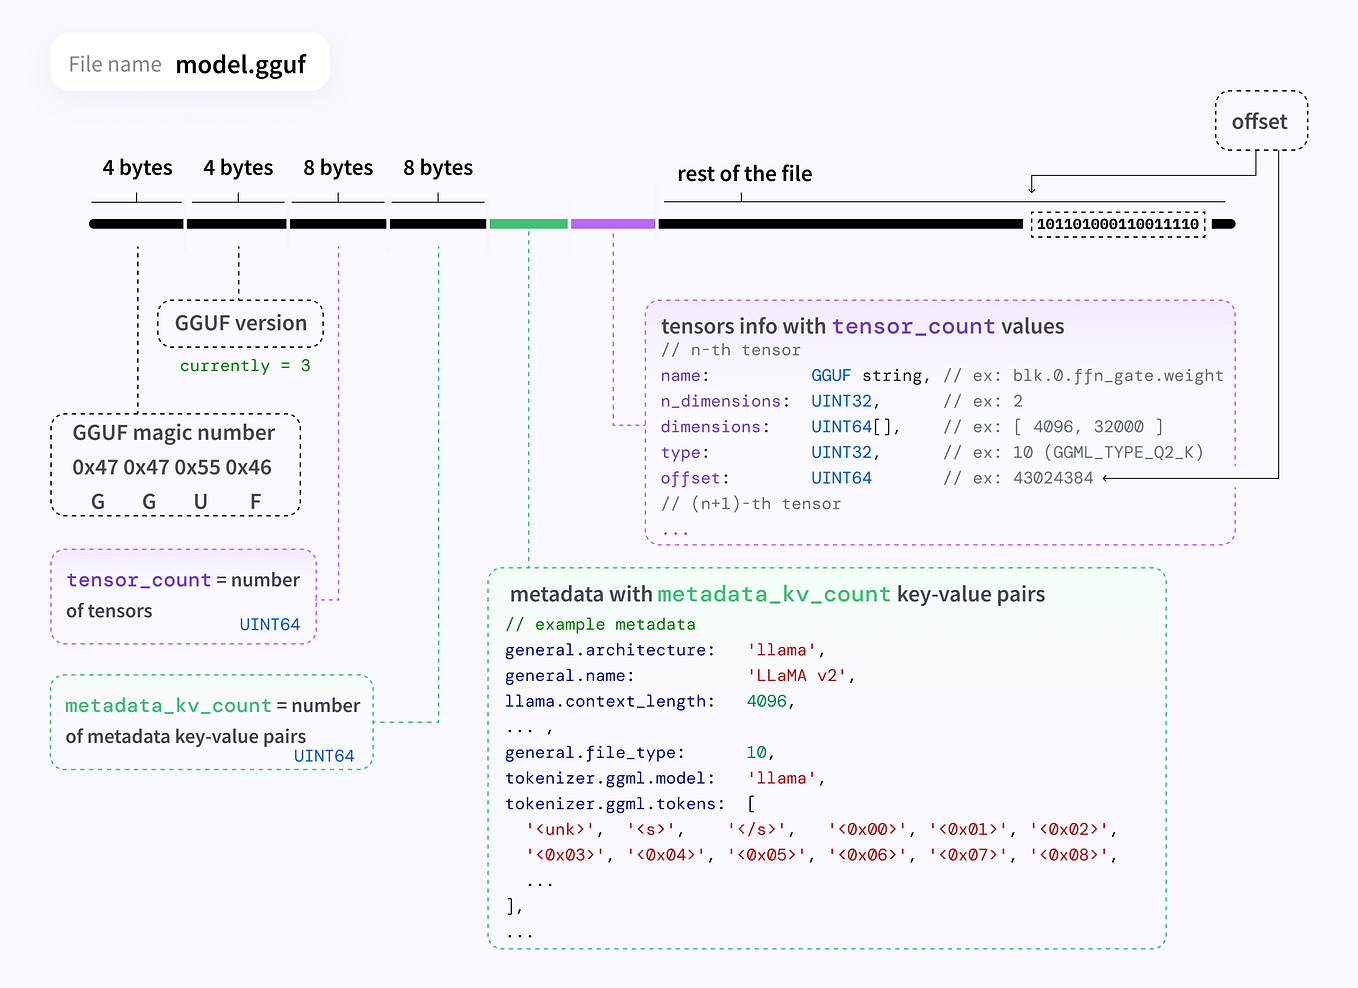
Quantization tech of LLMs-GGUF. We can use GGUF to offload any layer of ...
4-bit LLM Quantization with GPTQ - Origins AI
🧠 Quantization Explained with PyTorch: Smarter, Smaller, and Faster AI ...
KIVI: A Plug-and-Play 2-bit KV Cache Quantization Algorithm without the ...
工程实现 |加速神经网络推理之 8bit Quantization (模型量化压缩) - 知乎
14. Quantization — ECE 386
Low-bit Model Quantization for Deep Neural Networks: A Survey | AI ...
Neural Network Quantization Research Review - Fritz ai
Understanding AI/LLM Quantisation Through Interactive Visualisations ...
Chapter 5 – Digital Sound & Music
Simple and Foolproof ways to Shrink, Compress, and Accelerate your Deep ...
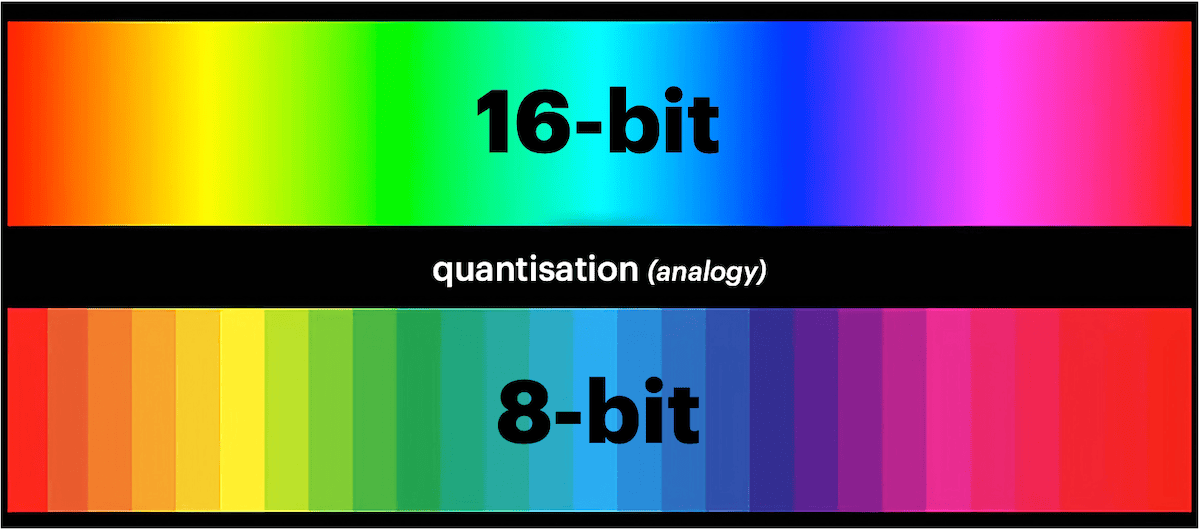
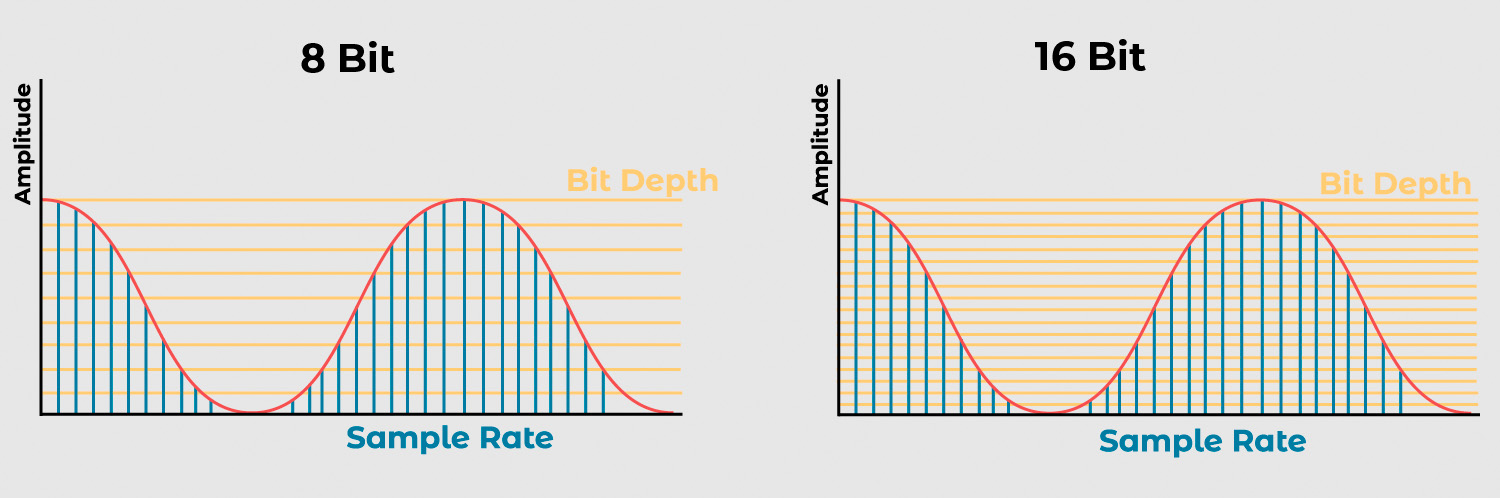
Bit-depth explained: Everything you need to know - SoundGuys
A/D and D/A Converters Guide for Quality Audio Recordings
模型量化1-概述1:量化的过程就是选取合适量化参数(scale factor,zero point,clipping value)以及数据映射 ...
Advances in the Neural Network Quantization: A Comprehensive Review | MDPI
Fl Studio Tutorials: Sampling Rate, Bit Depth, And Dithering – OQDBRI
Bit Depth 101: The Ultimate Guide To Understanding Bit Depth
GPU memory requirements for serving Large Language Models | UnfoldAI
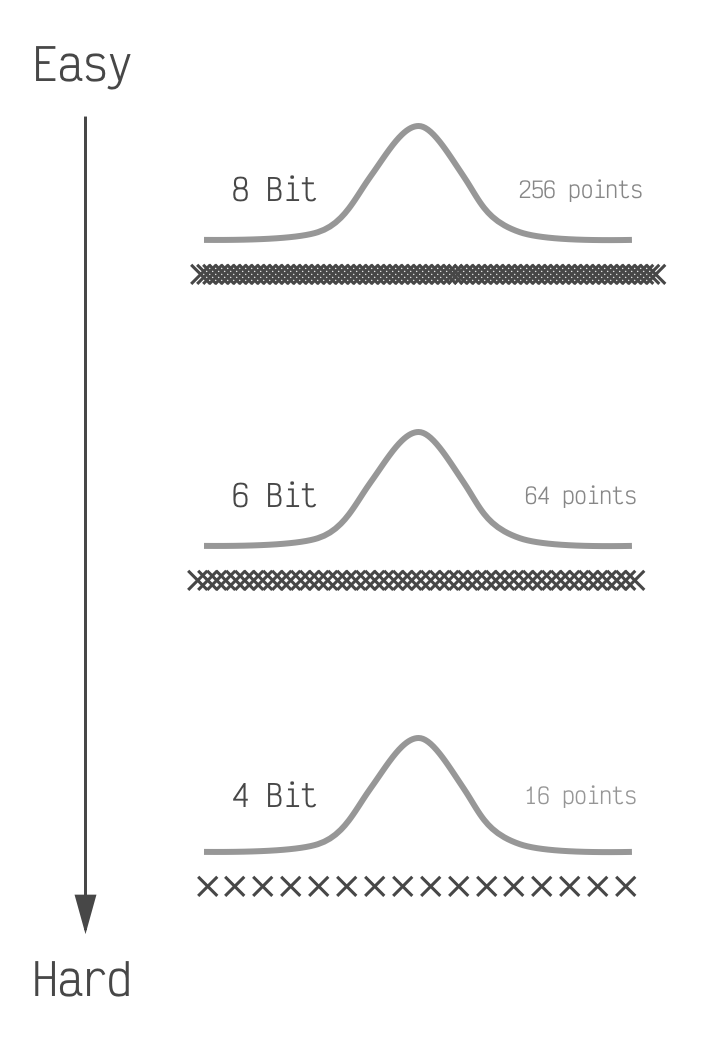
LLM Bit-Rates & Quantization: 32 vs 16 vs 8 vs 4 (what changes, what ...
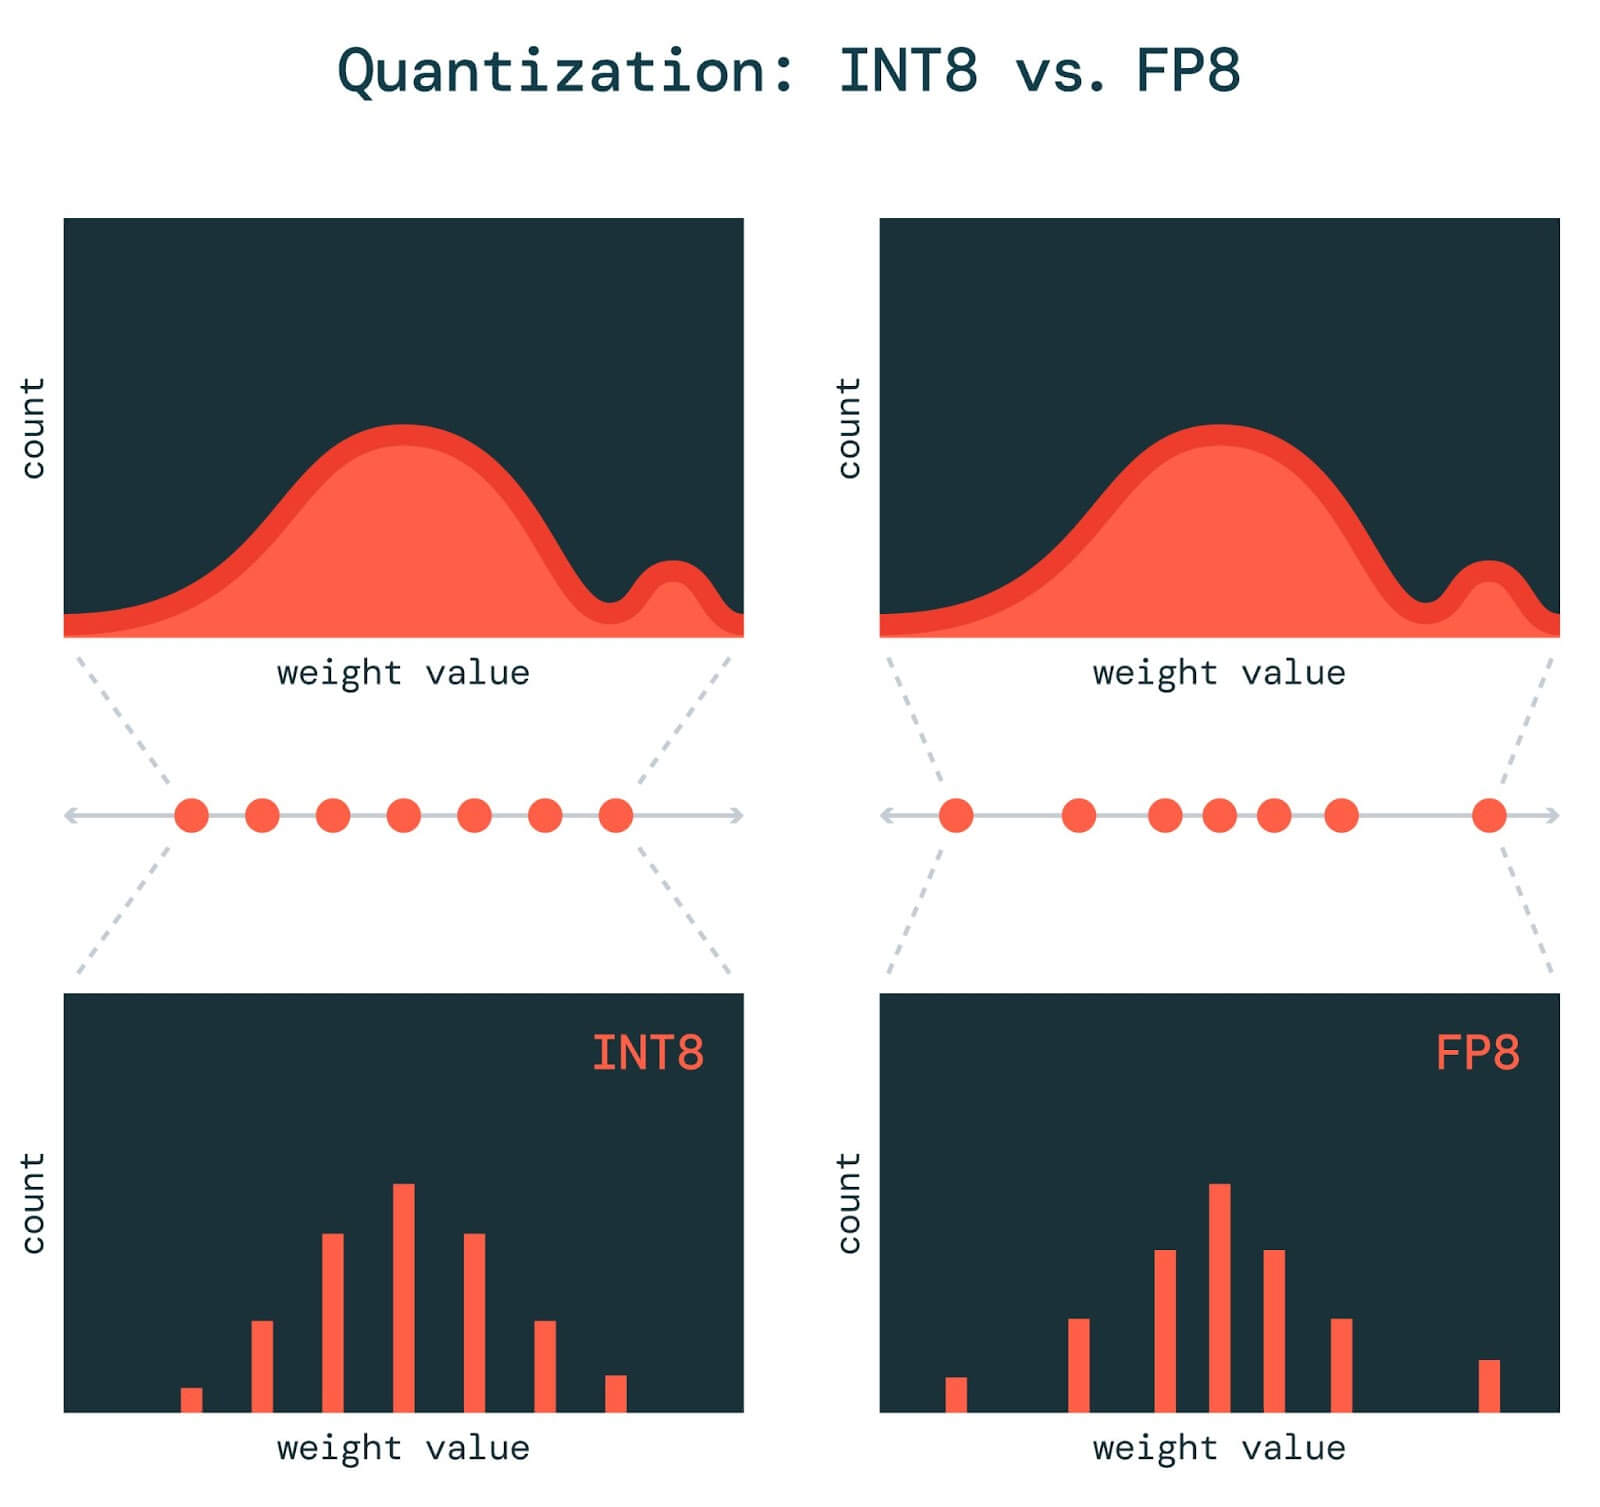
[论文评述] INT v.s. FP: A Comprehensive Study of Fine-Grained Low-bit ...
What is Vector Quantization? - Qdrant
Localization performance vs. number of measurements with different ...
Downsize your AI model while maintaining performance
Serving Quantized LLMs on NVIDIA H100 Tensor Core GPUs | Databricks
BER vs. SNR of different schemes for 16-QAM modulation and R = 5 ...
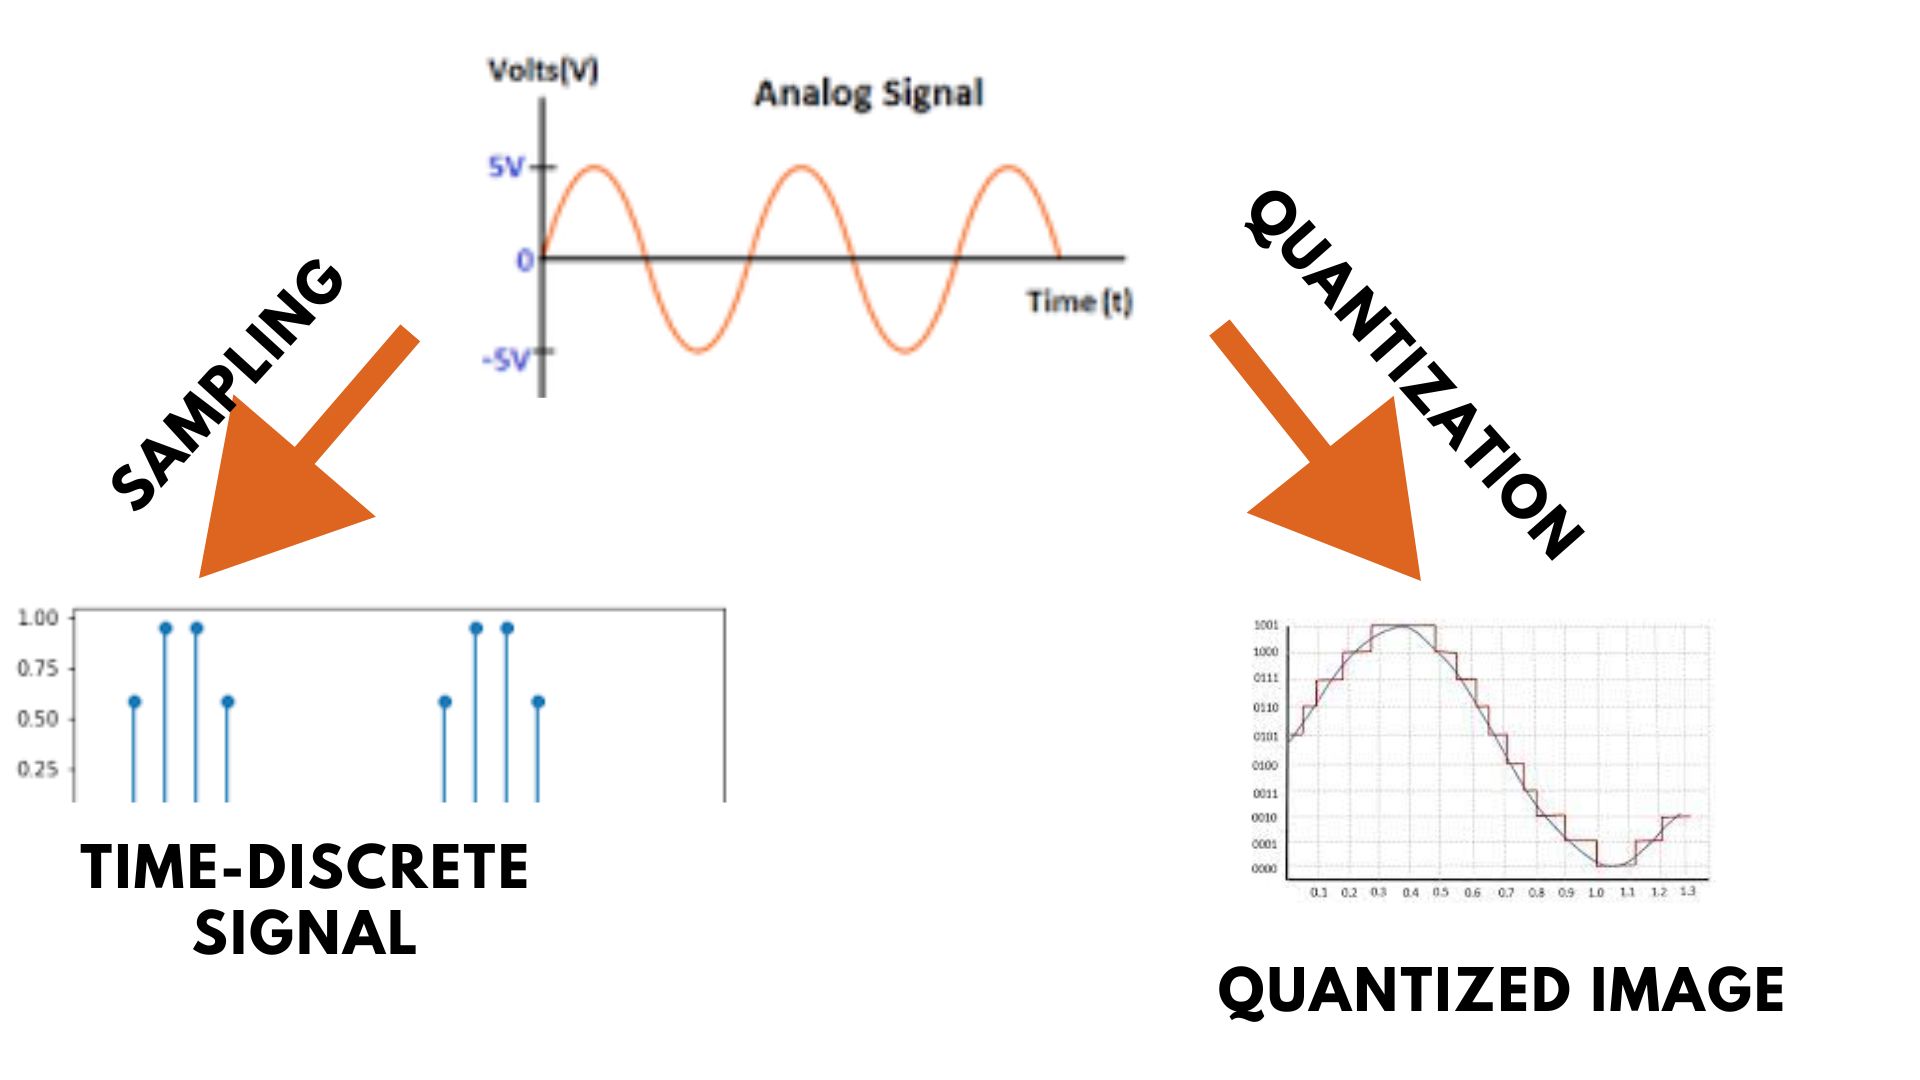
Fundamental Concepts: Sampling, Quantization, and Encoding
quantization-大模型权重量化简介-CSDN博客
any4: Learned 4-bit Numeric Representation for LLMs | AI Research Paper ...
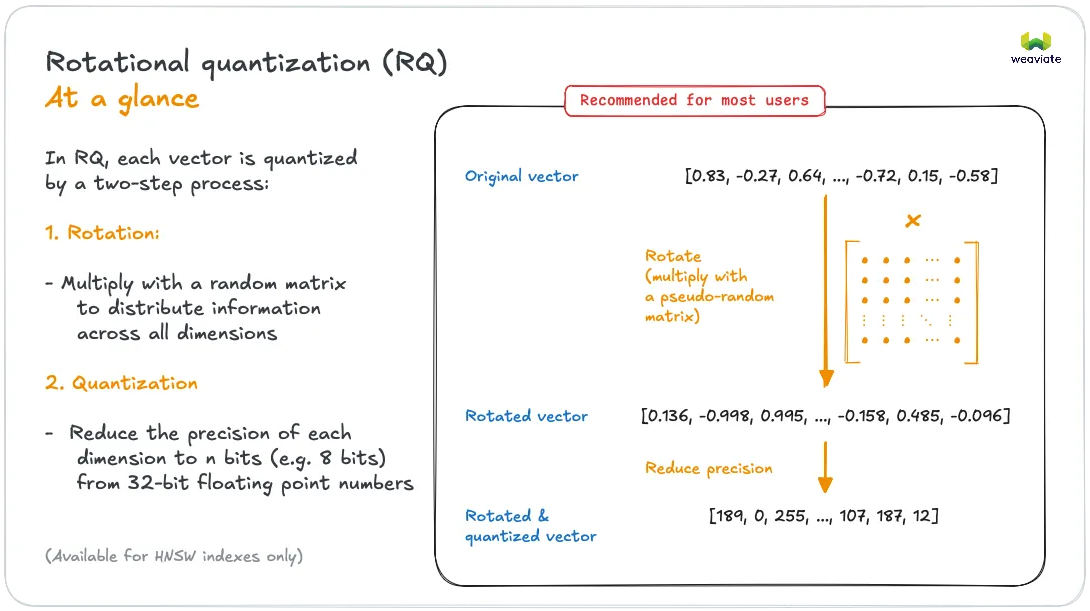
8-bit Rotational Quantization: How to Improve the Speed-Quality ...
Optimizing Data Flow in Binary Neural Networks
The NMSE of channel estimator versus the pilot power with different ...
Quantization-Aware NN Layers with High-throughput FPGA Implementation ...
Quantization, A Core Technology for Building ‘Lightweight’ AI Models
[논문 리뷰] Layer-Wise Quantization: A Pragmatic and Effective Method for ...
Ithy - Quantizing Large Language Models for Low VRAM
Abtastrate (Sampling Rate) & Bit Depth einfach erklärt
What is Quantization? Definition, Types & Examples Techopedia
Use quantized data types | Taichi Docs
What is Model Optimization? A Quick Guide
Tối Ưu Hóa Mô Hình Ngôn Ngữ Lớn với Quantization: Giảm Tải GPU Hiệu Quả ...
Model Quantization: Run Large AI Models on Limited Hardware
Guide to Audio Quality: Sample Rate, Bit Depth, and Bit Rate Explained