Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
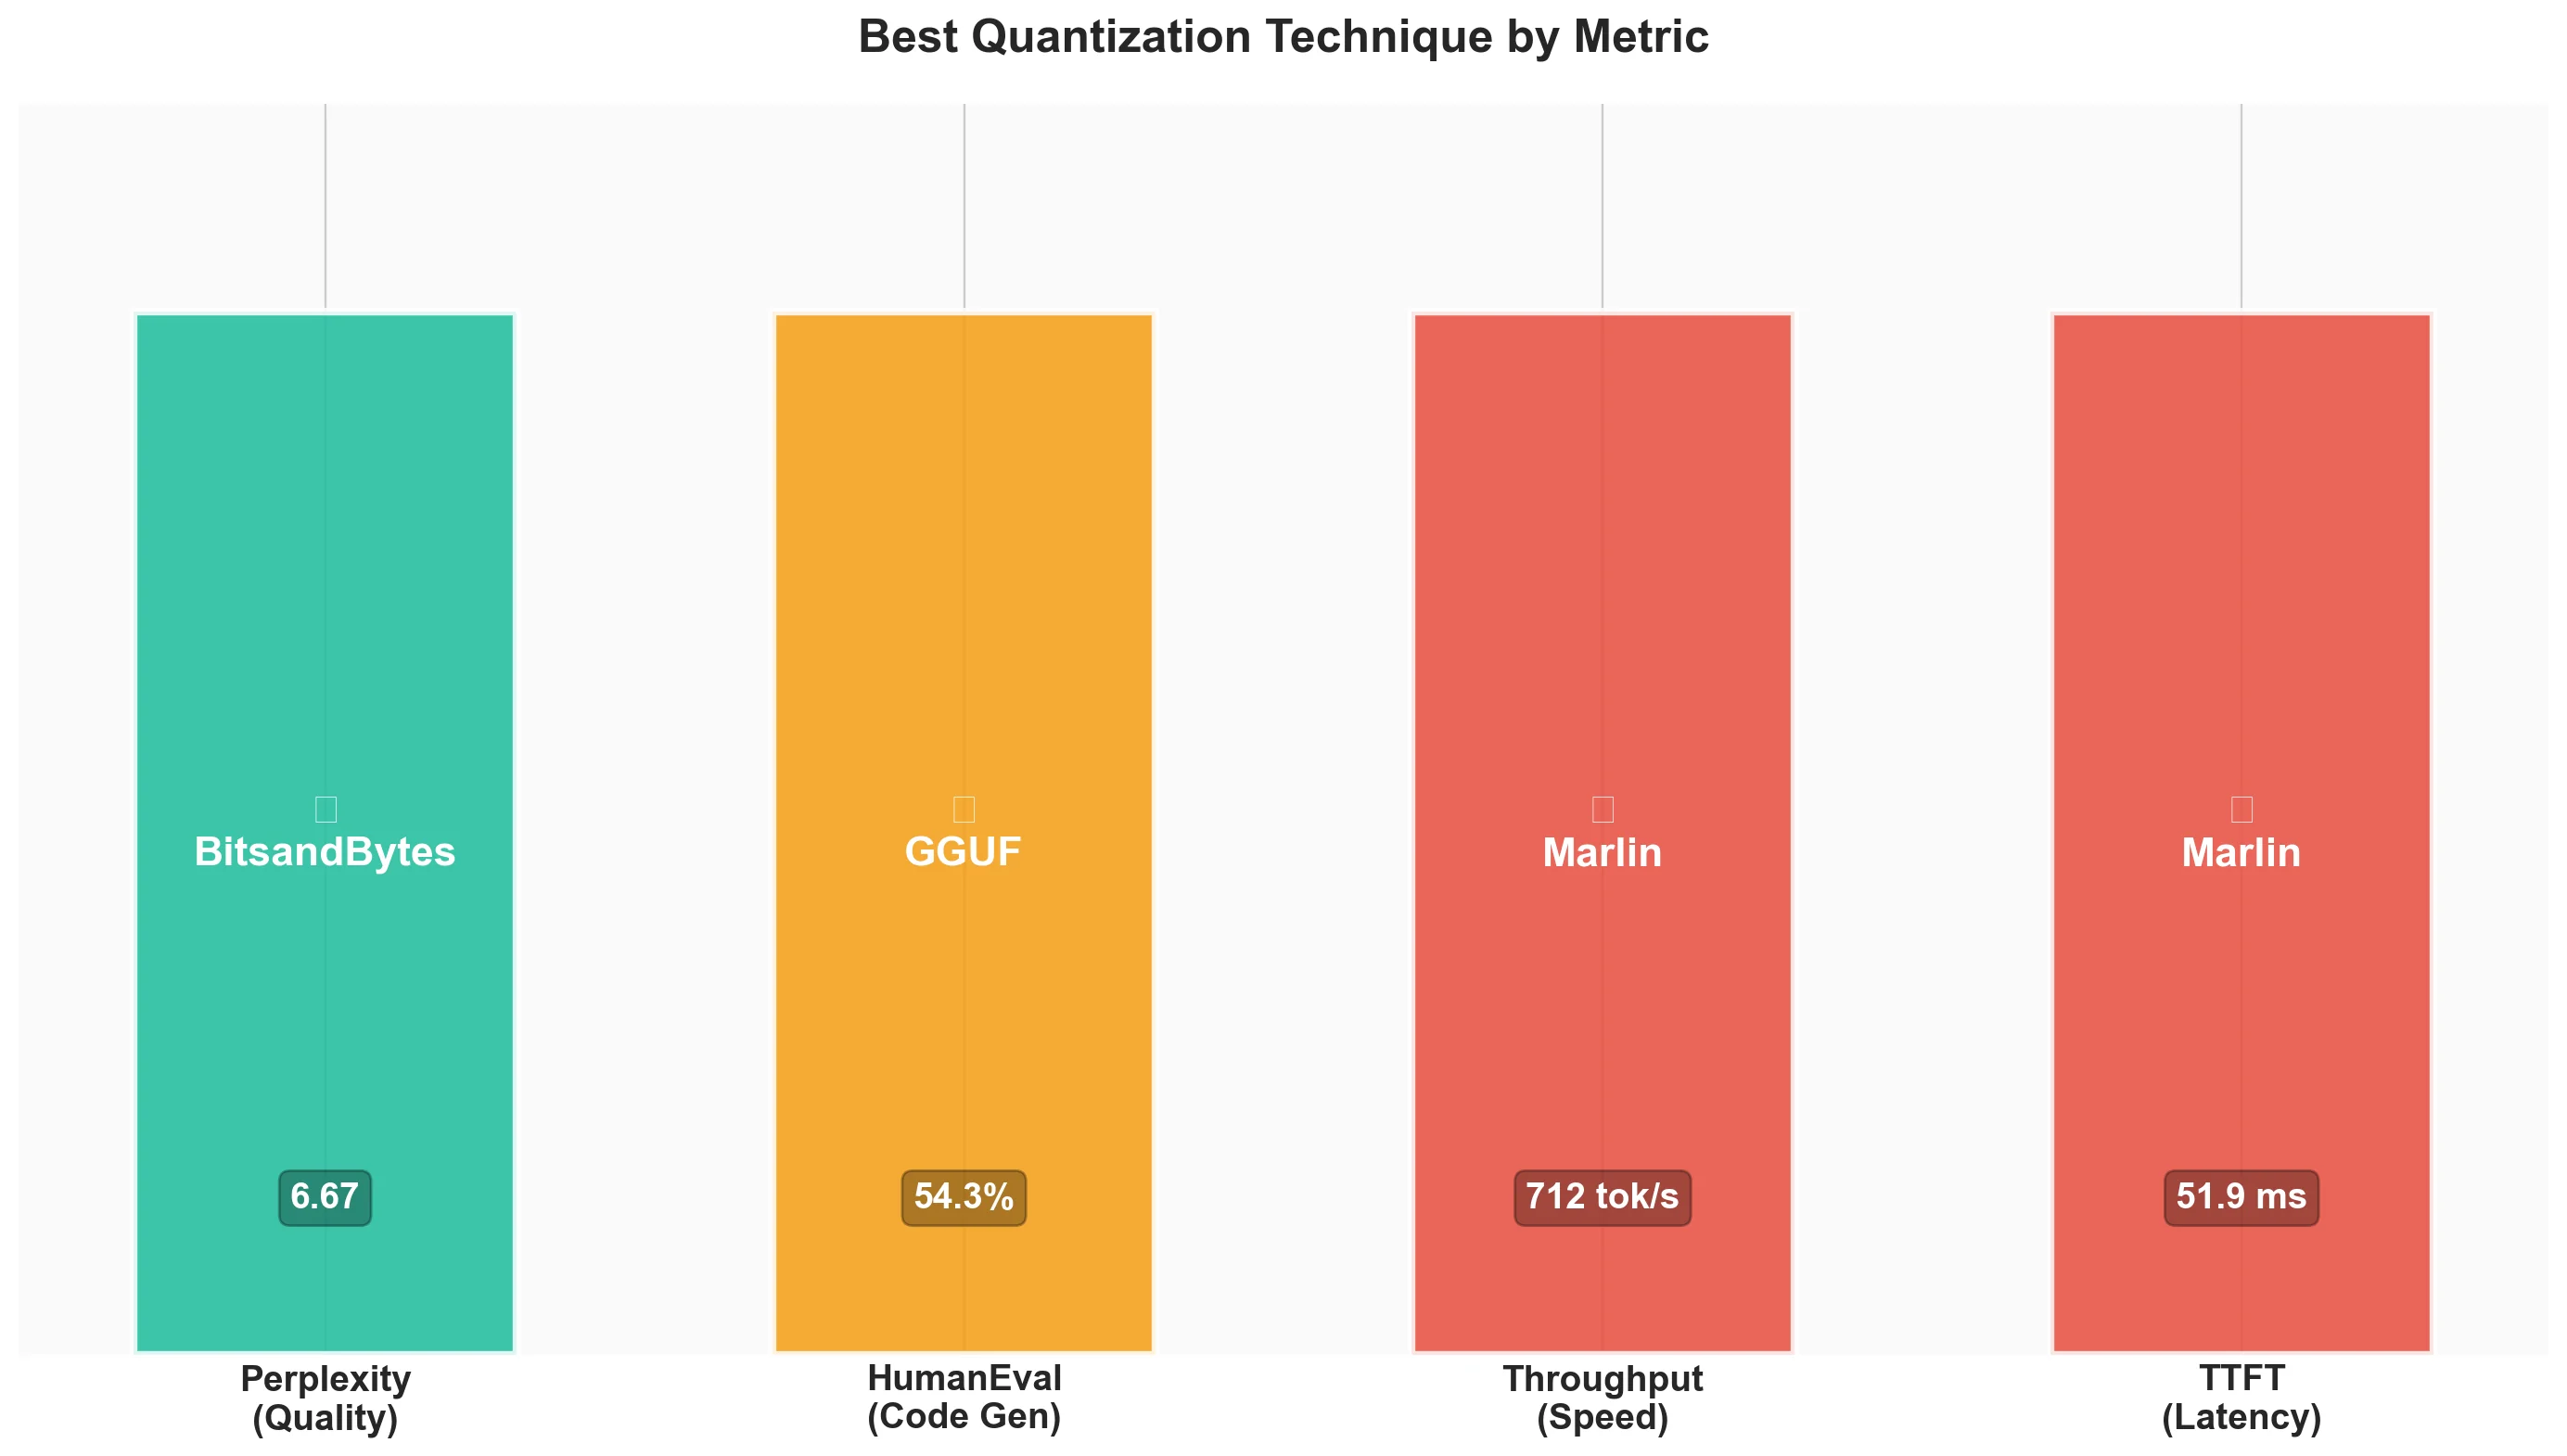
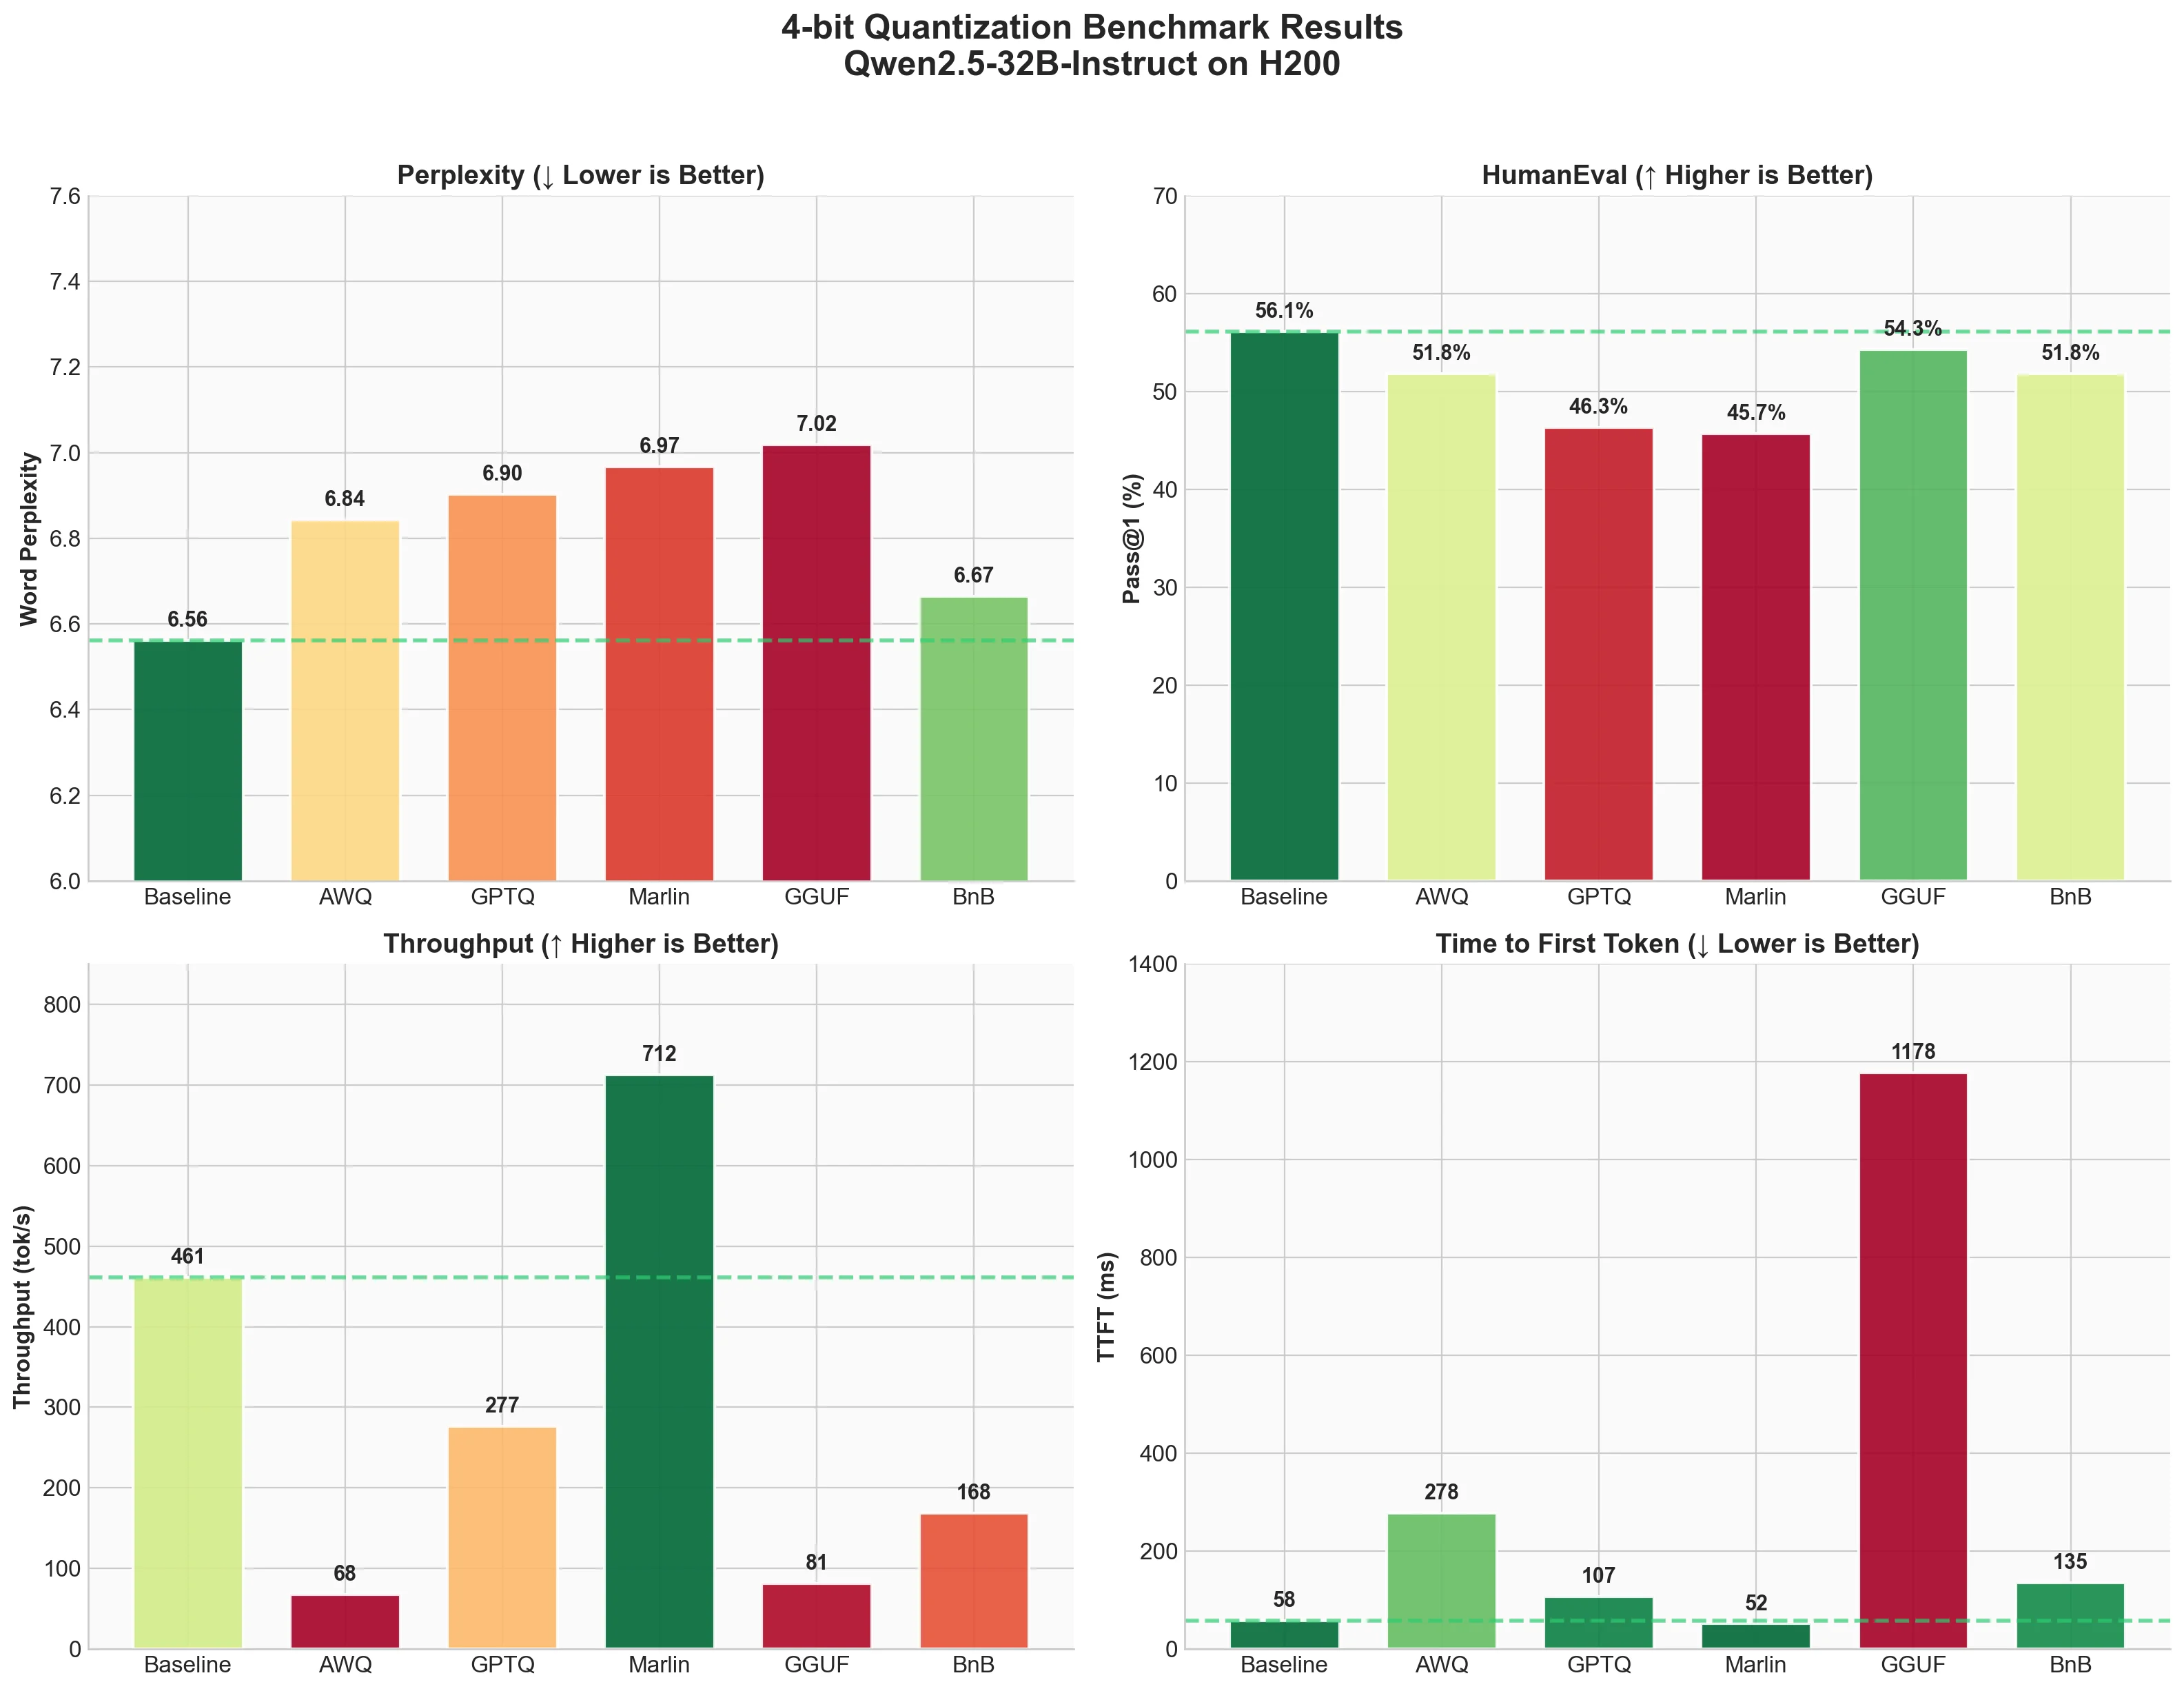
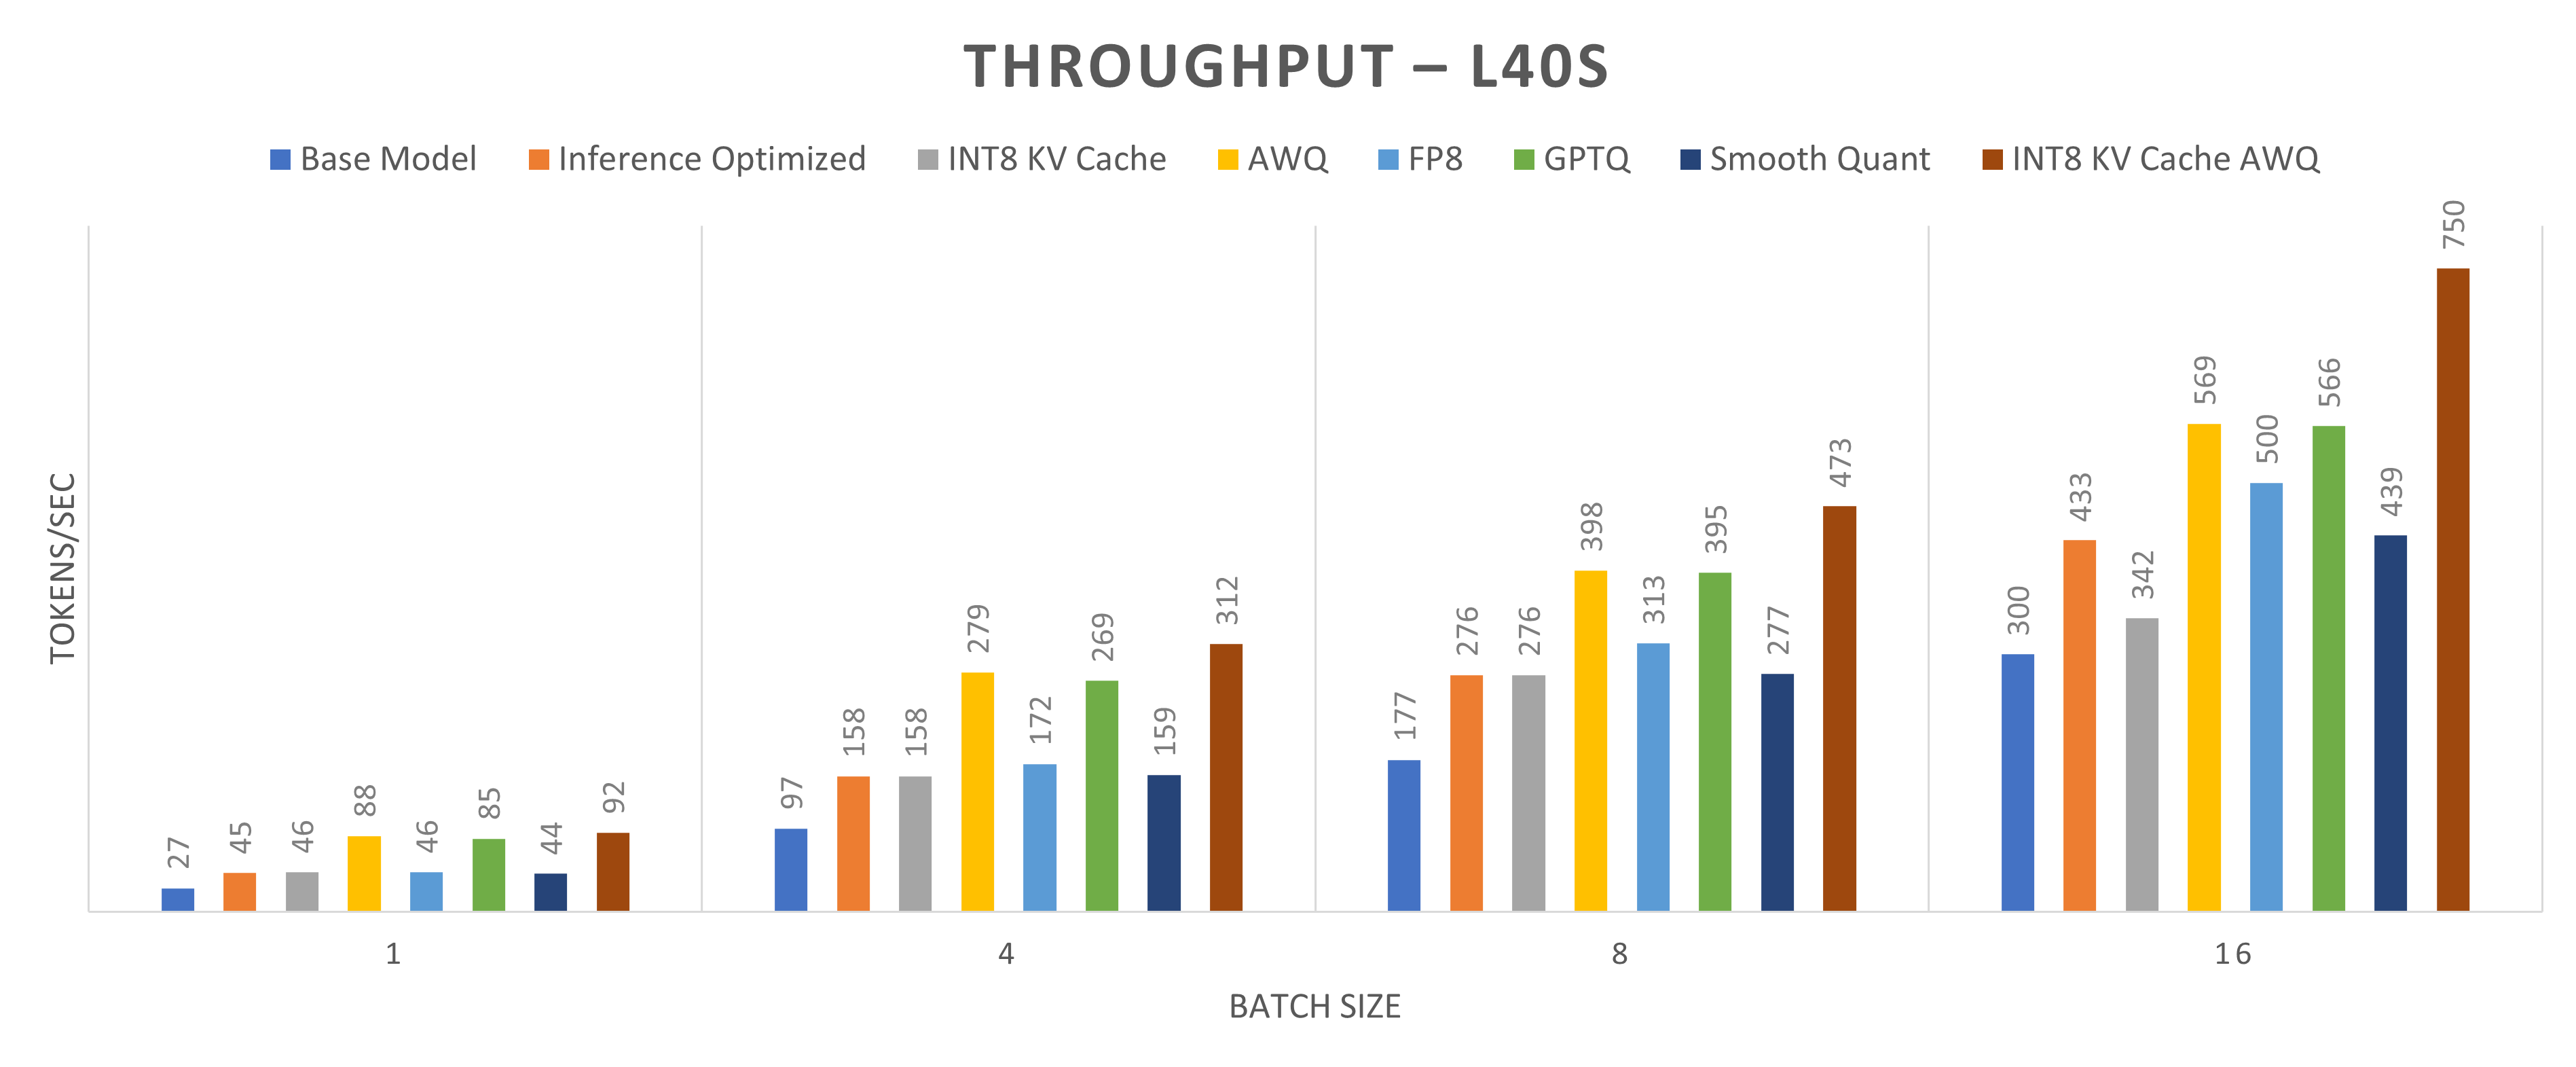
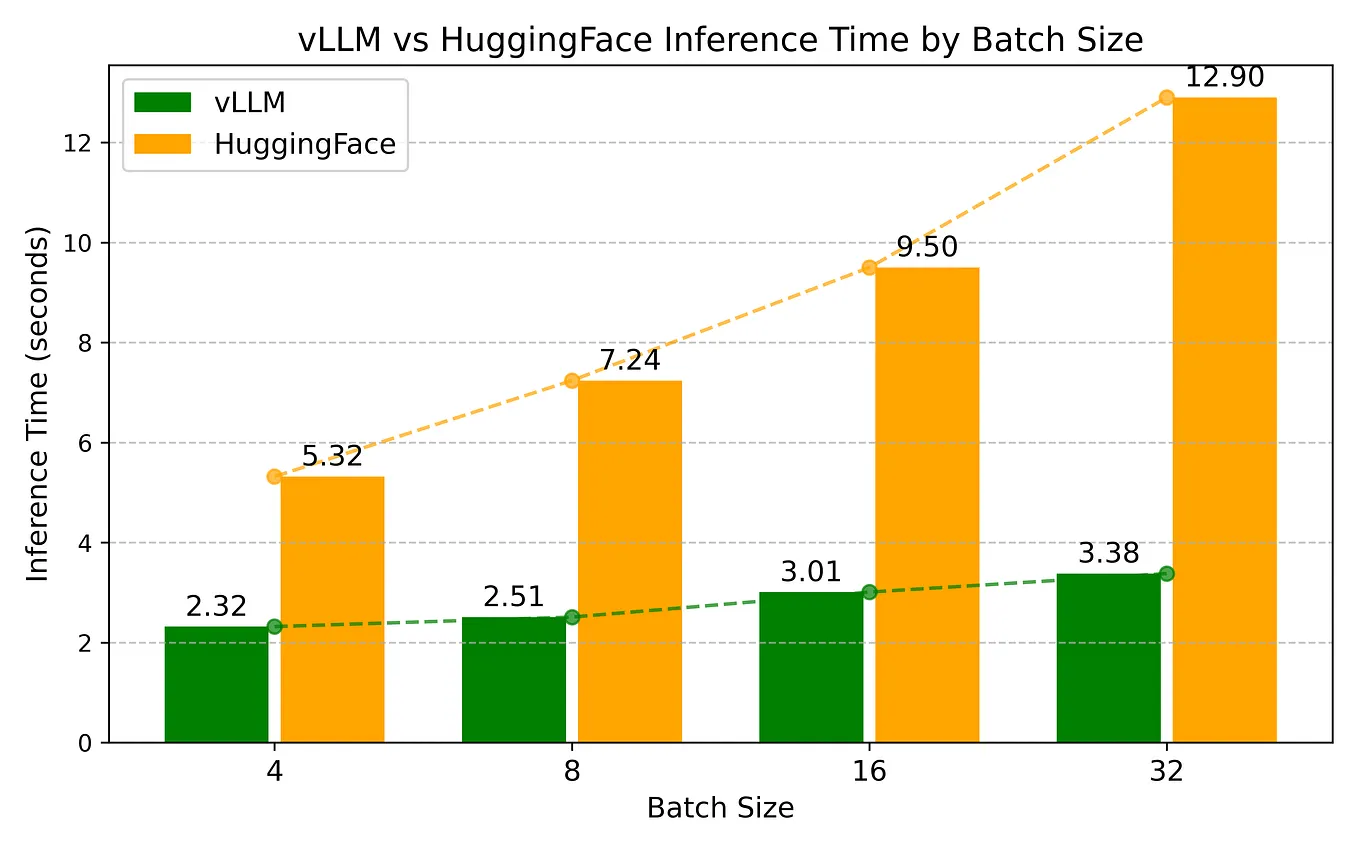
The Complete Guide to LLM Quantization with vLLM: Benchmarks & Best ...
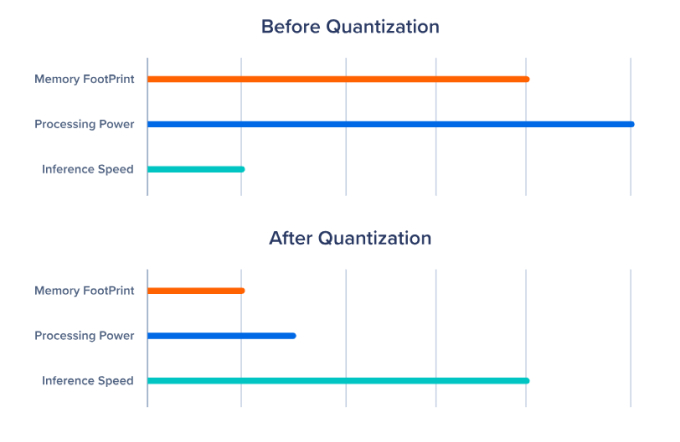
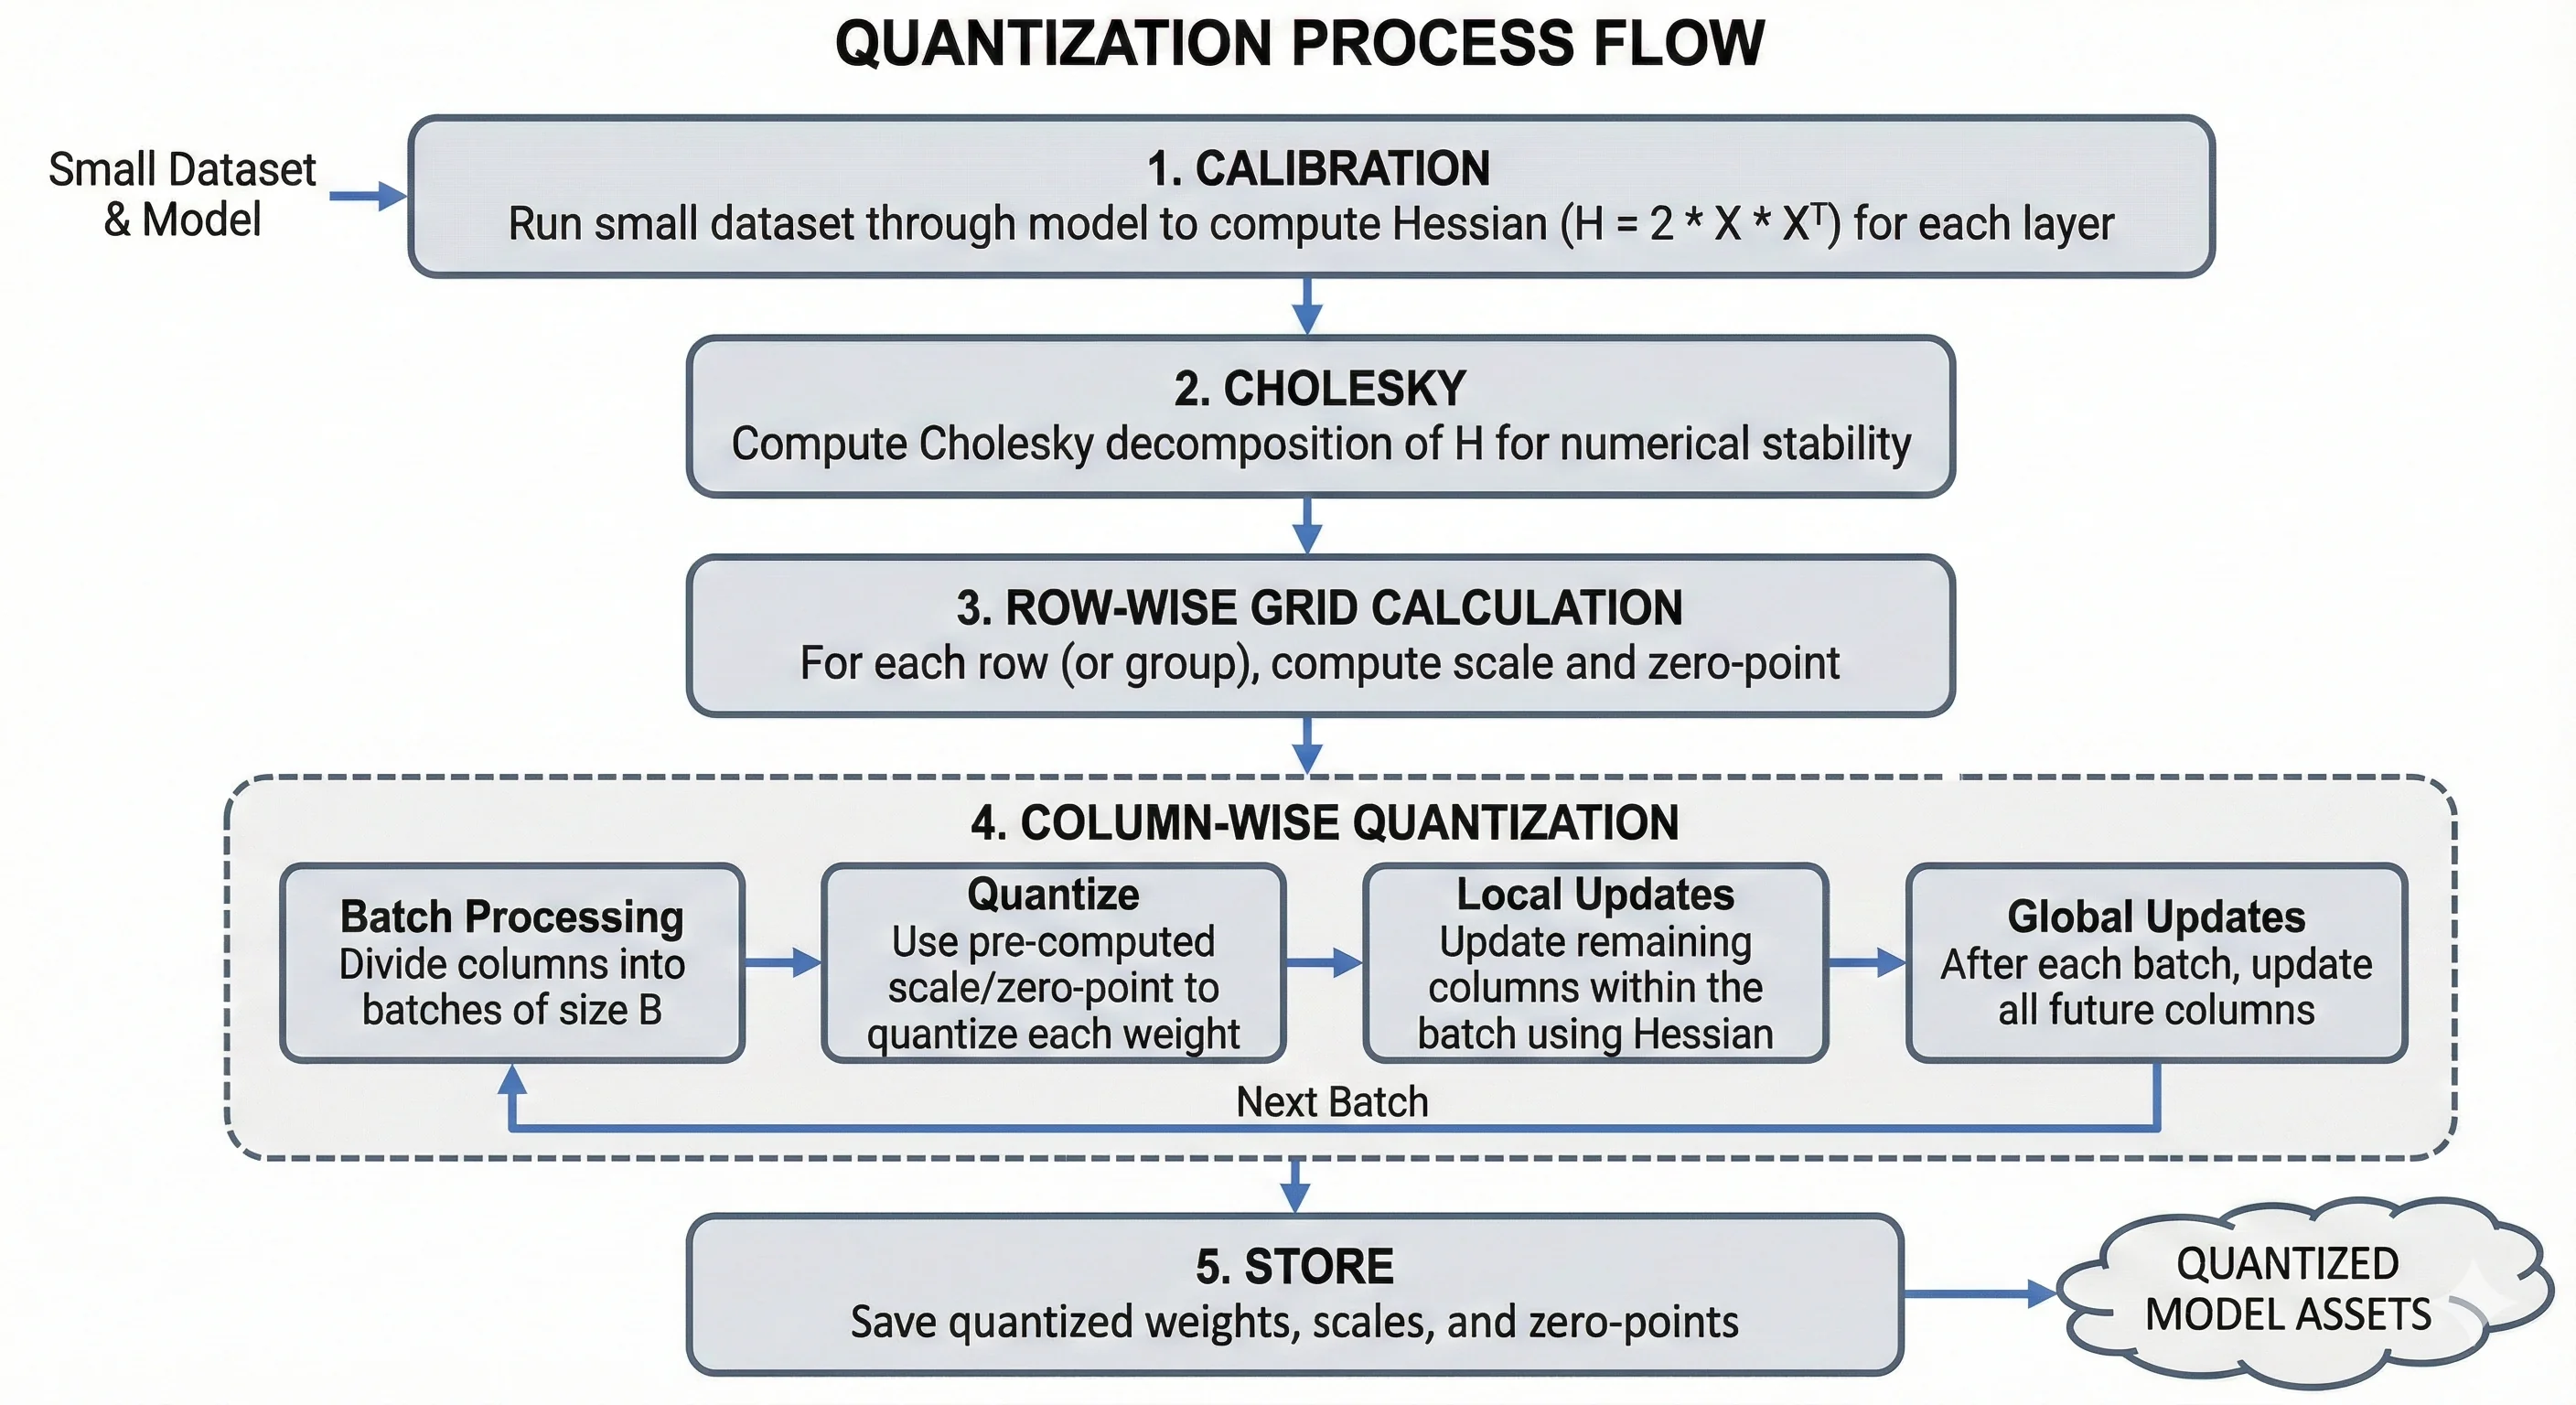
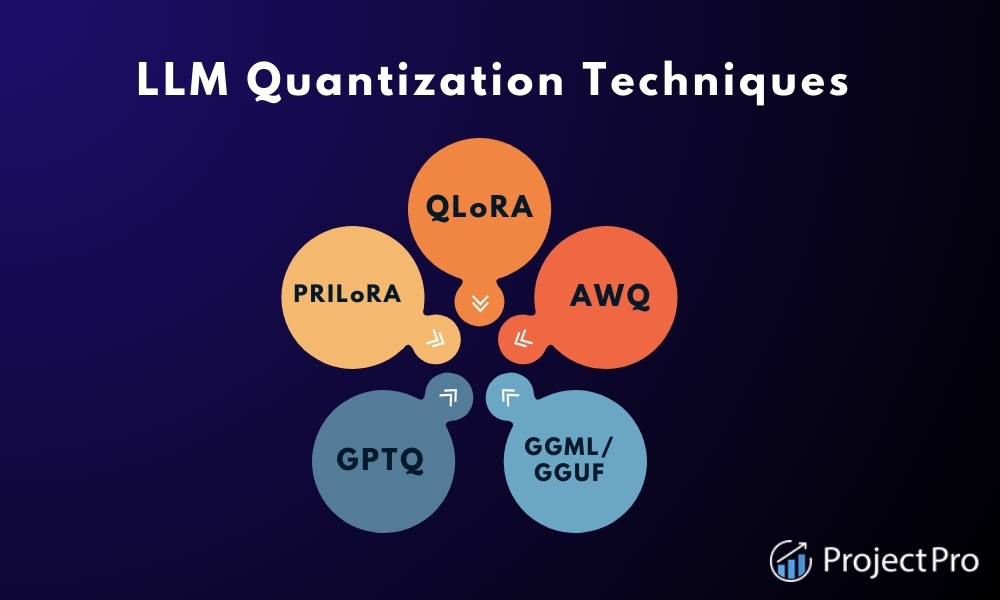
LLM Quantization Methods: GPTQ, AWQ, GGUF - Cast AI
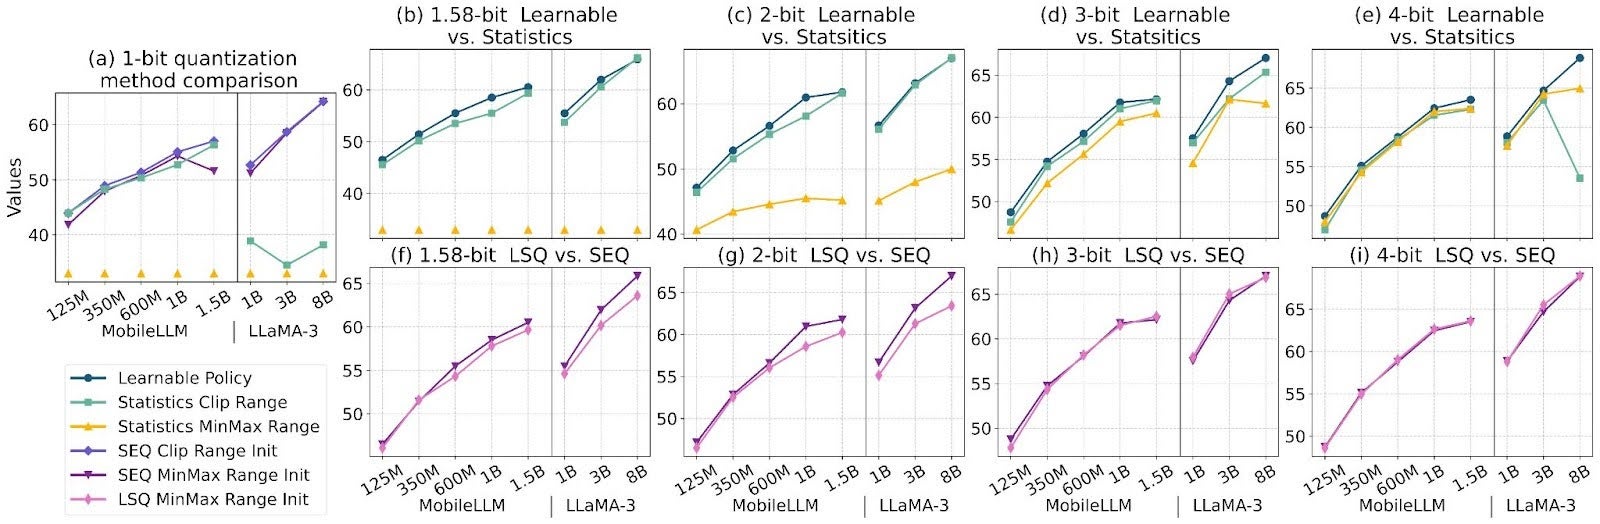
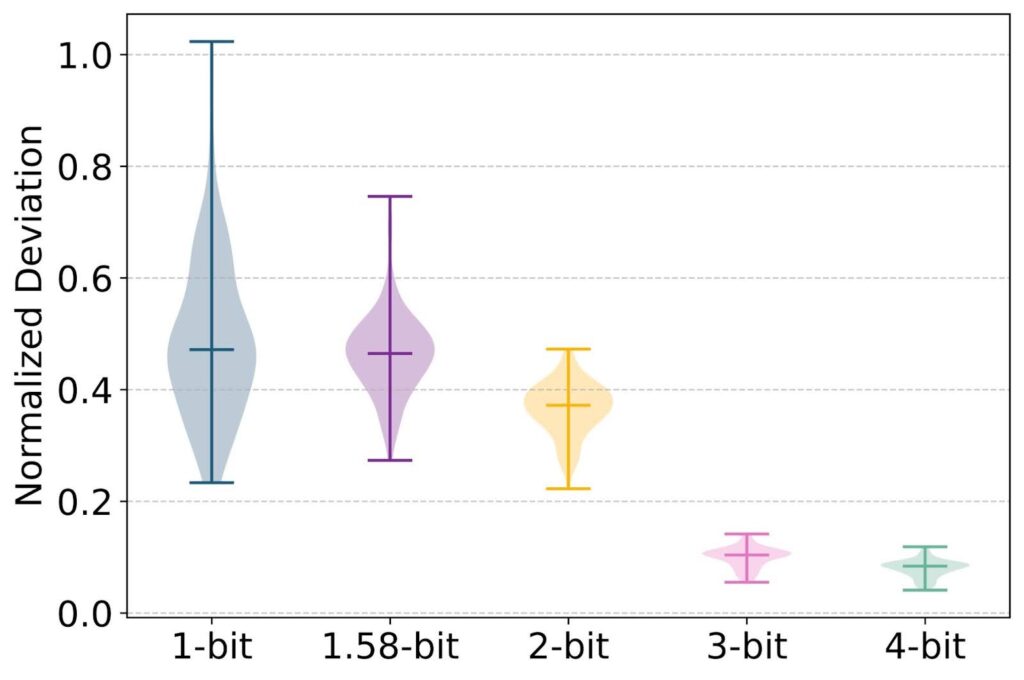
ParetoQ: Scaling Laws in Extremely Low-bit LLM Quantization – PyTorch
LLM Quantization Benchmark: 4 Users vs 47 | Cem Dilmegani posted on the ...
Top LLM Quantization Methods and Their Impact on Model Quality
Improving LLM Inference Speeds on CPUs with Model Quantization | by ...
Democratizing LLMs: 4-bit Quantization for Optimal LLM Inference ...
LLM Quantization Explainer — Quality vs Memory vs Speed | Simulations4All
Unlocking LLM Performance: Advanced Quantization Techniques on Dell ...
The Ultimate Handbook for LLM Quantization | Towards Data Science
Free Video: LLM Quantization Performance Testing - Ollama and LM Studio ...
A Comprehensive Guide on LLM Quantization and Use Cases
4-bit LLM training and Primer on Precision, data types & Quantization
The Complete Guide to LLM Quantization | LocalLLM.in
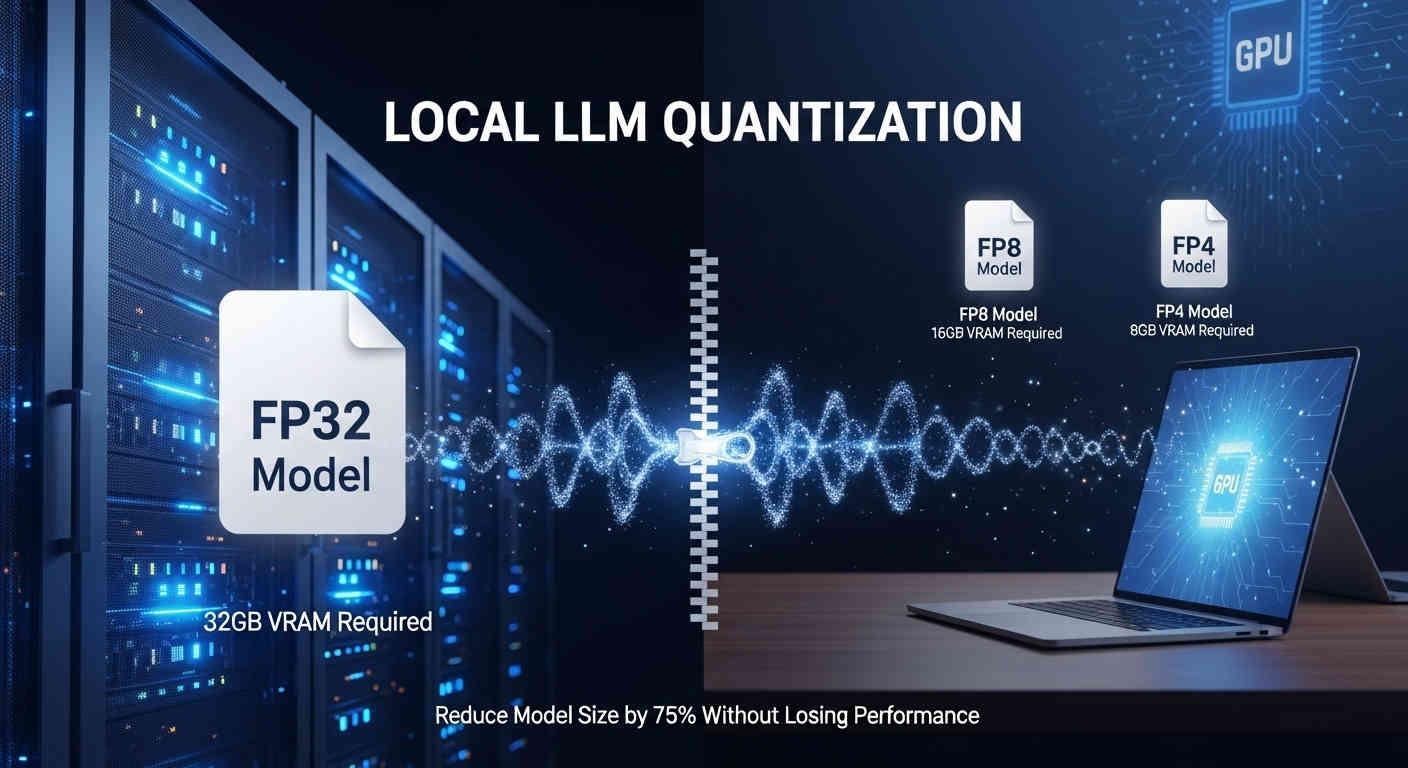
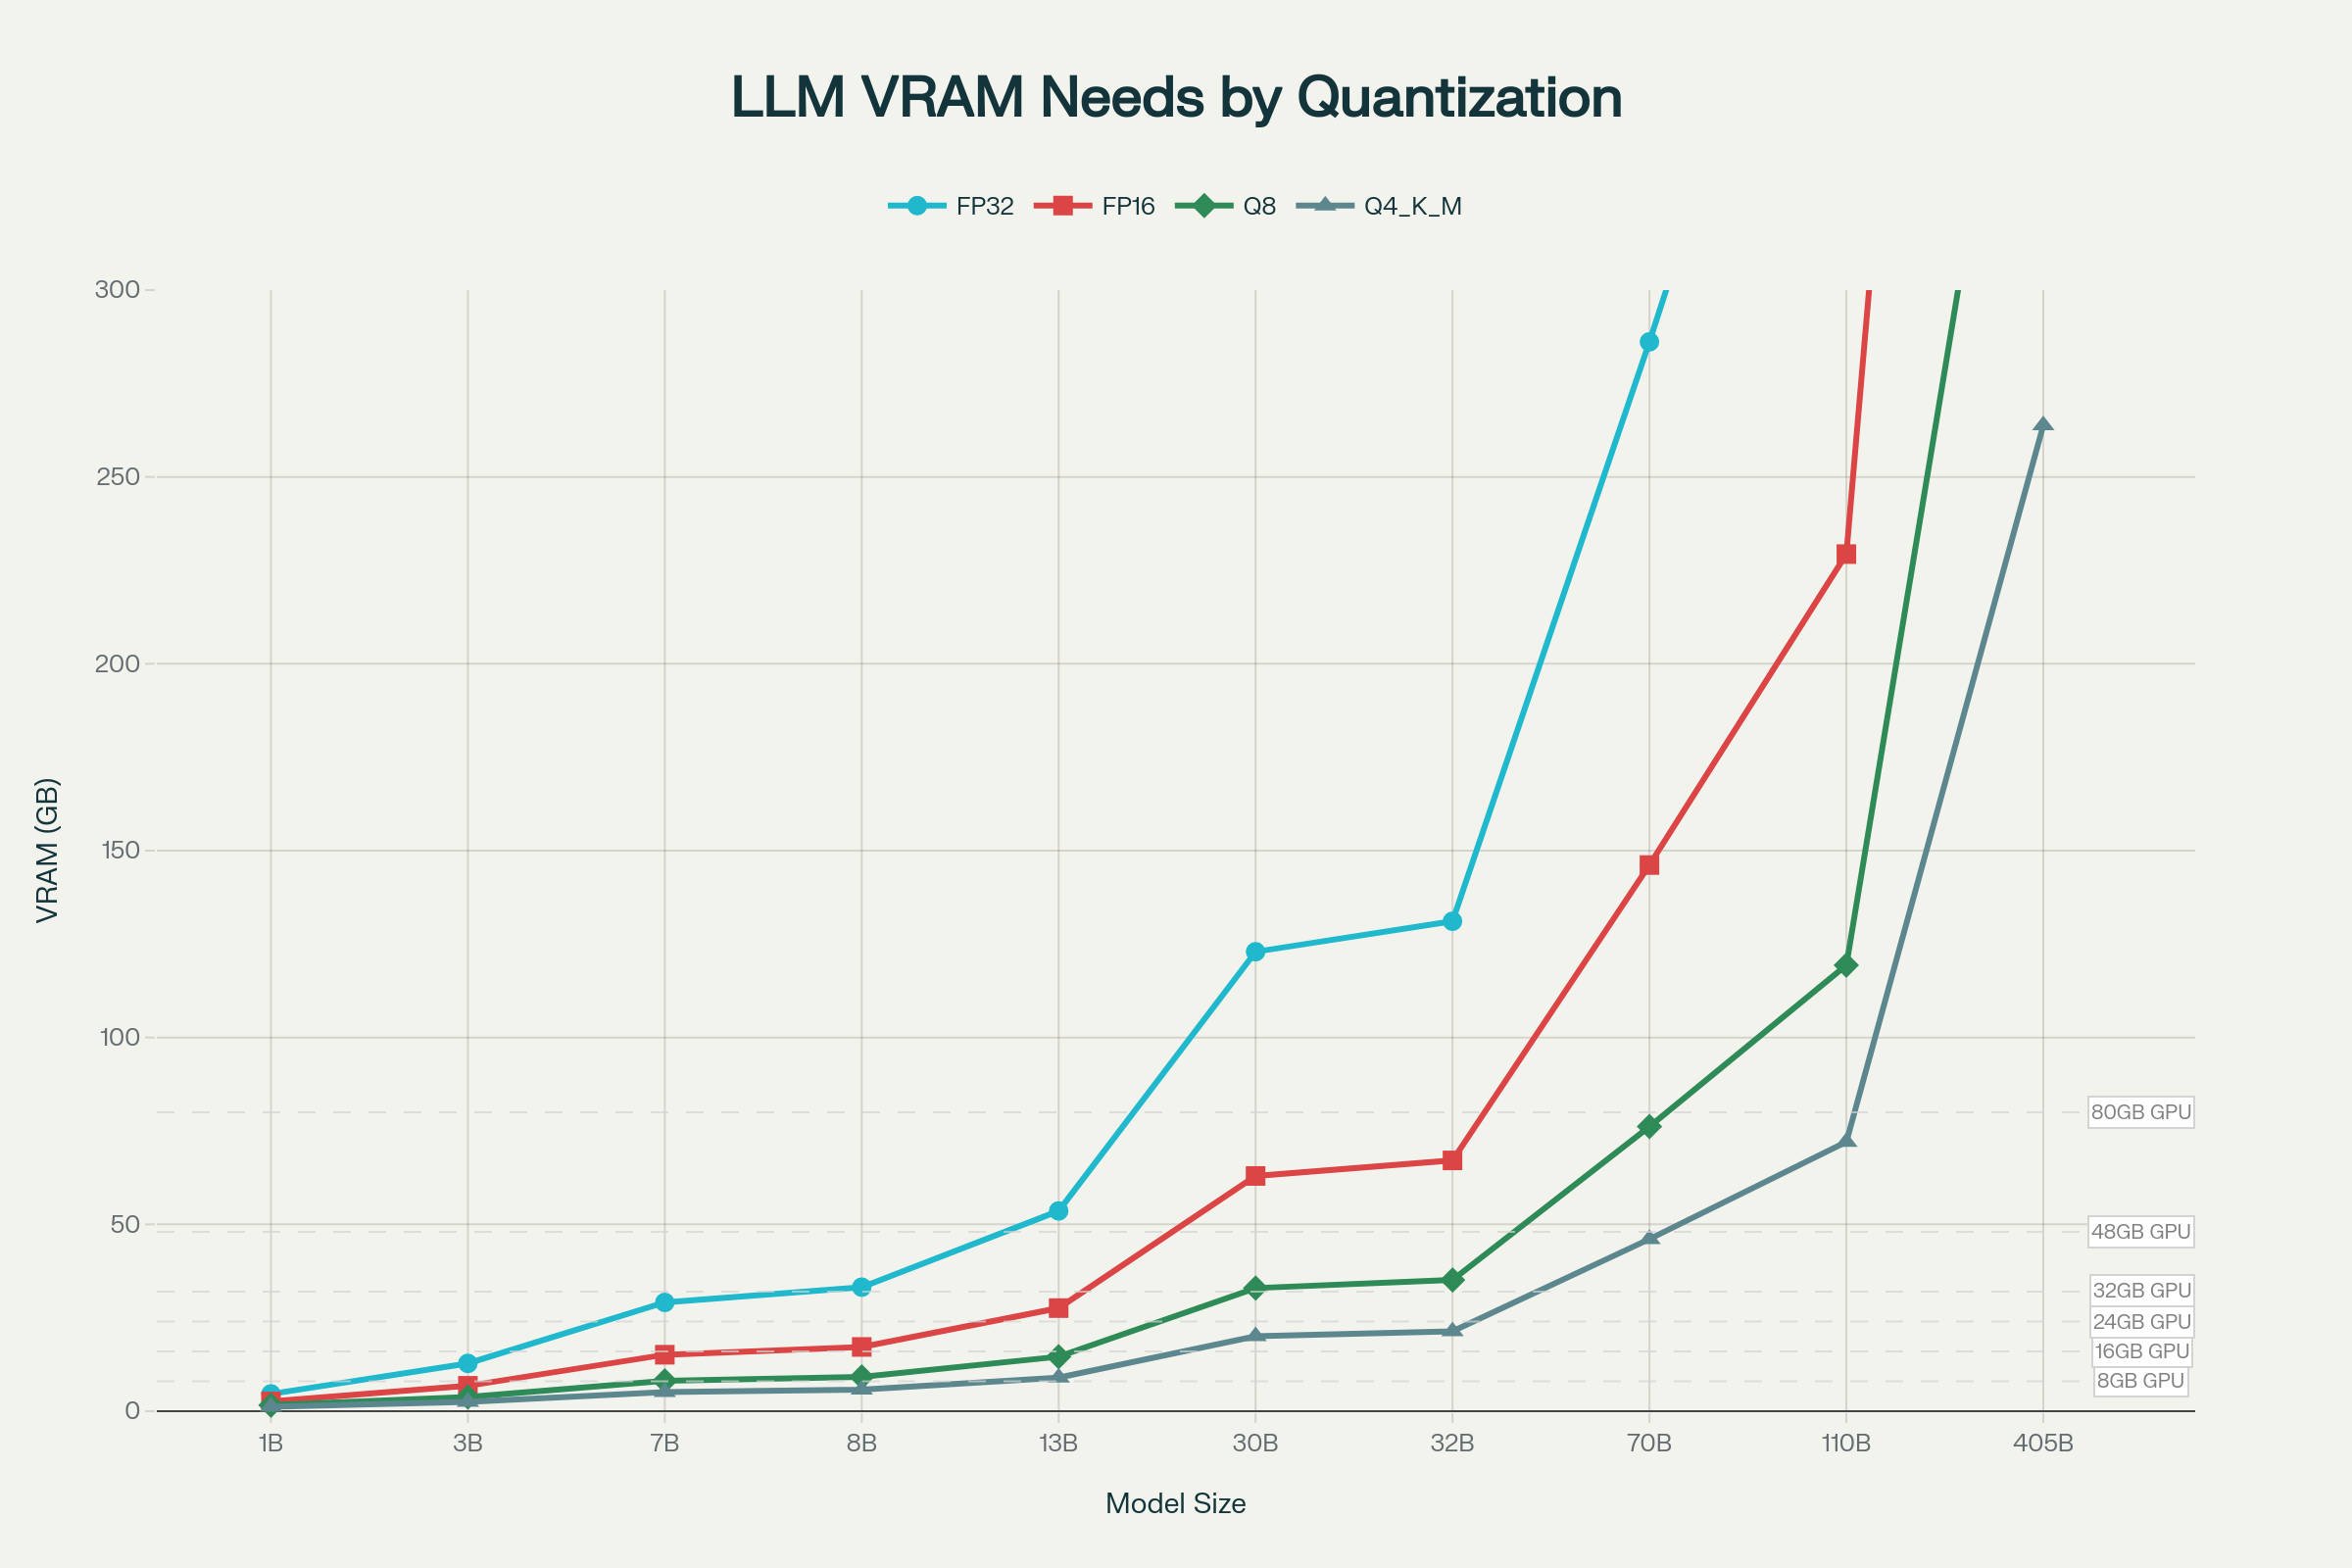
The Great AI Compression: How LLM Quantization Solves the VRAM Bottleneck
How to benchmark and optimize LLM inference performance (for data ...
LLM Quantization Comparison
[PDF] LLM-MQ: Mixed-precision Quantization for Efficient LLM Deployment ...
Quantization is very critical LLM performance to lower cost/memory ...
Comparing LLM Quantization Toolkit Results
Practical Guide to LLM Quantization Methods - Cast AI
Medmarks v0.1, a new LLM benchmark suite of medical tasks
LLM Quantization in Production :: Aaron Mekonnen — Ideas and projects
"ResQ: Efficient LLM Quantization with Low Rank Residuals" | Utkarsh ...
Figure 9 from SpinQuant: LLM quantization with learned rotations ...
LLM Quantization Made Easy: Essential Tips for Success
LLM inference optimization: Model Quantization and Distillation - YouTube
AI LLM 모델별 성능 benchmark 비교 사이트 추천 (ChatGPT, Grok3, Claude, Gemini 등 ...
[PDF] DecDEC: A Systems Approach to Advancing Low-Bit LLM Quantization ...
[Literature Review] Quantization Meets Reasoning: Exploring LLM Low-Bit ...
An Introduction to LLM Quantization - TextMine
[vLLM — Quantization] AWQ: Activation-aware Weight Quantization for LLM ...
What is LLM Quantization Understanding Its Importance and Techniques
The Best GPUs for Local LLM Inference in 2025 | LocalLLM.in
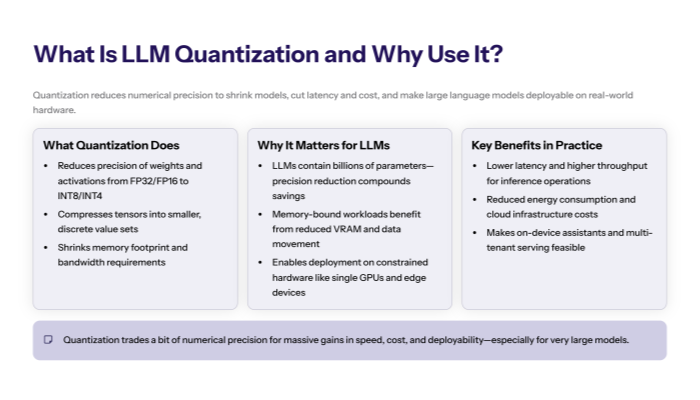
Quantization in LLMs: Why Does It Matter?
Intel Releases a Low-bit Quantized Open LLM Leaderboard for Evaluating ...
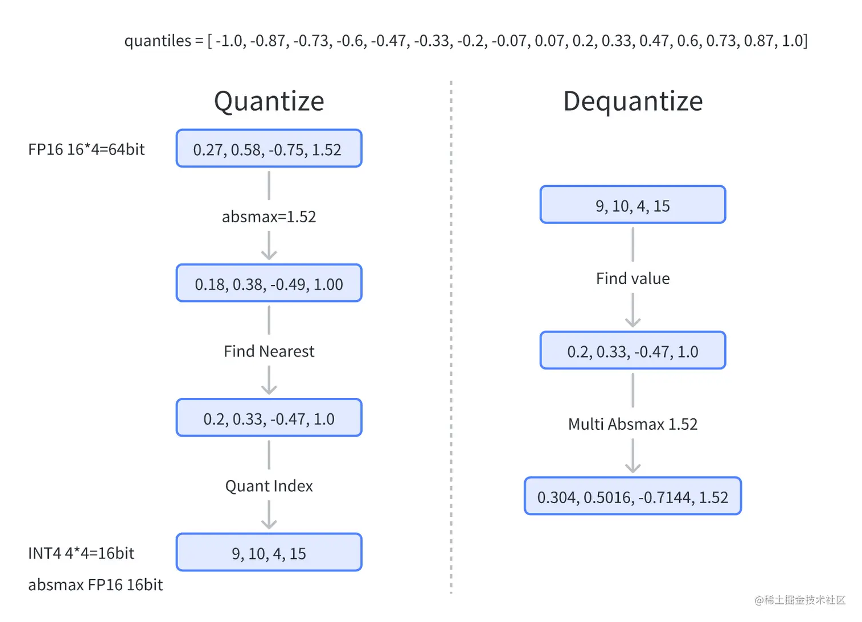
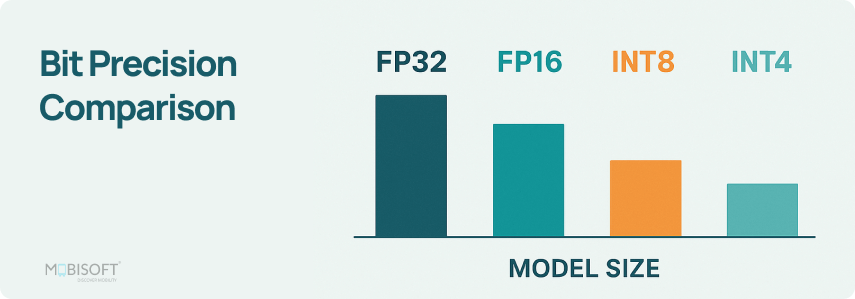
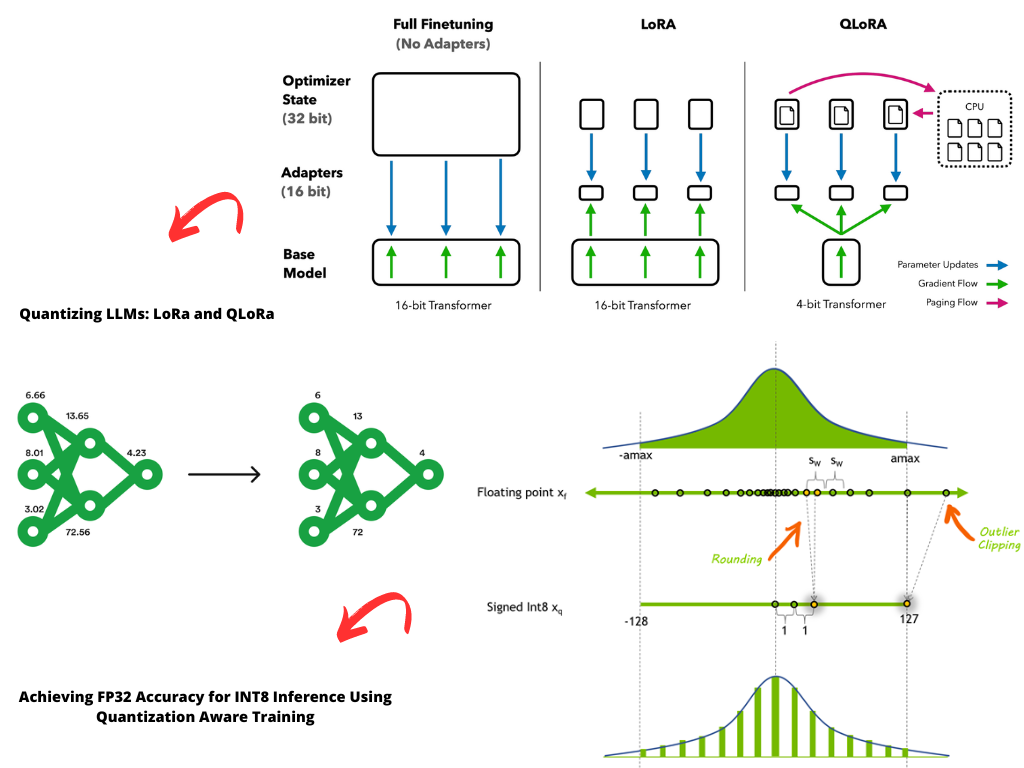
A Deep Dive into LLM Quantization: FP32, BF16, INT8, NF4 & QLoRA | by ...
LLM Compression Techniques to Build Faster and Cheaper LLMs
What is Quantization in LLM? A Complete Guide to Optimizing AI
The Big LLM Architecture Comparison
LLM-QBench: A Benchmark Towards the Best Practice for Post-training ...
40 Top Research-Backed LLM Benchmarks and Where To Use Them
Quantum LLM Benchmarks
LLM Benchmarks Guide: Meaning, Types, Trends & Future
The Complete Guide to LLM Benchmarking: Everything You Need to Know in ...
LLM Quantization-Build and Optimize AI Models Efficiently
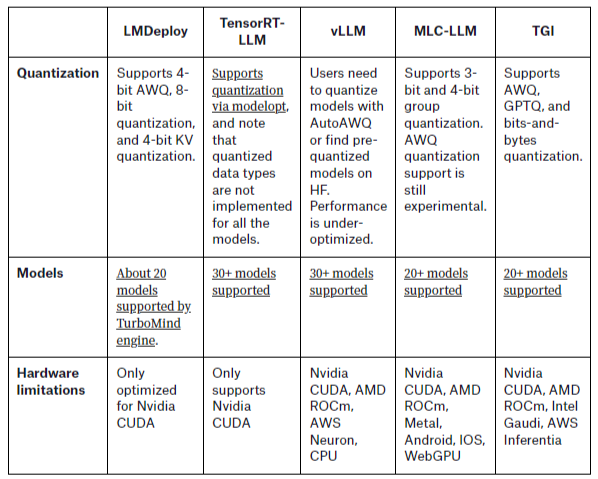
A Comprehensive Study by BentoML on Benchmarking LLM Inference Backends ...
LLM Benchmarks in 2024: Overview, Limits and Model Comparison
LLM Quantization: Making models faster and smaller | MatterAI Blog
Evaluating the Generalization Ability of Quantized LLMs: Benchmark ...
Post-Training Quantization of LLMs with NVIDIA NeMo and NVIDIA TensorRT ...
Comprehensive list of LLM benchmarks- Part 1 | by Vivedha Elango | Jul ...
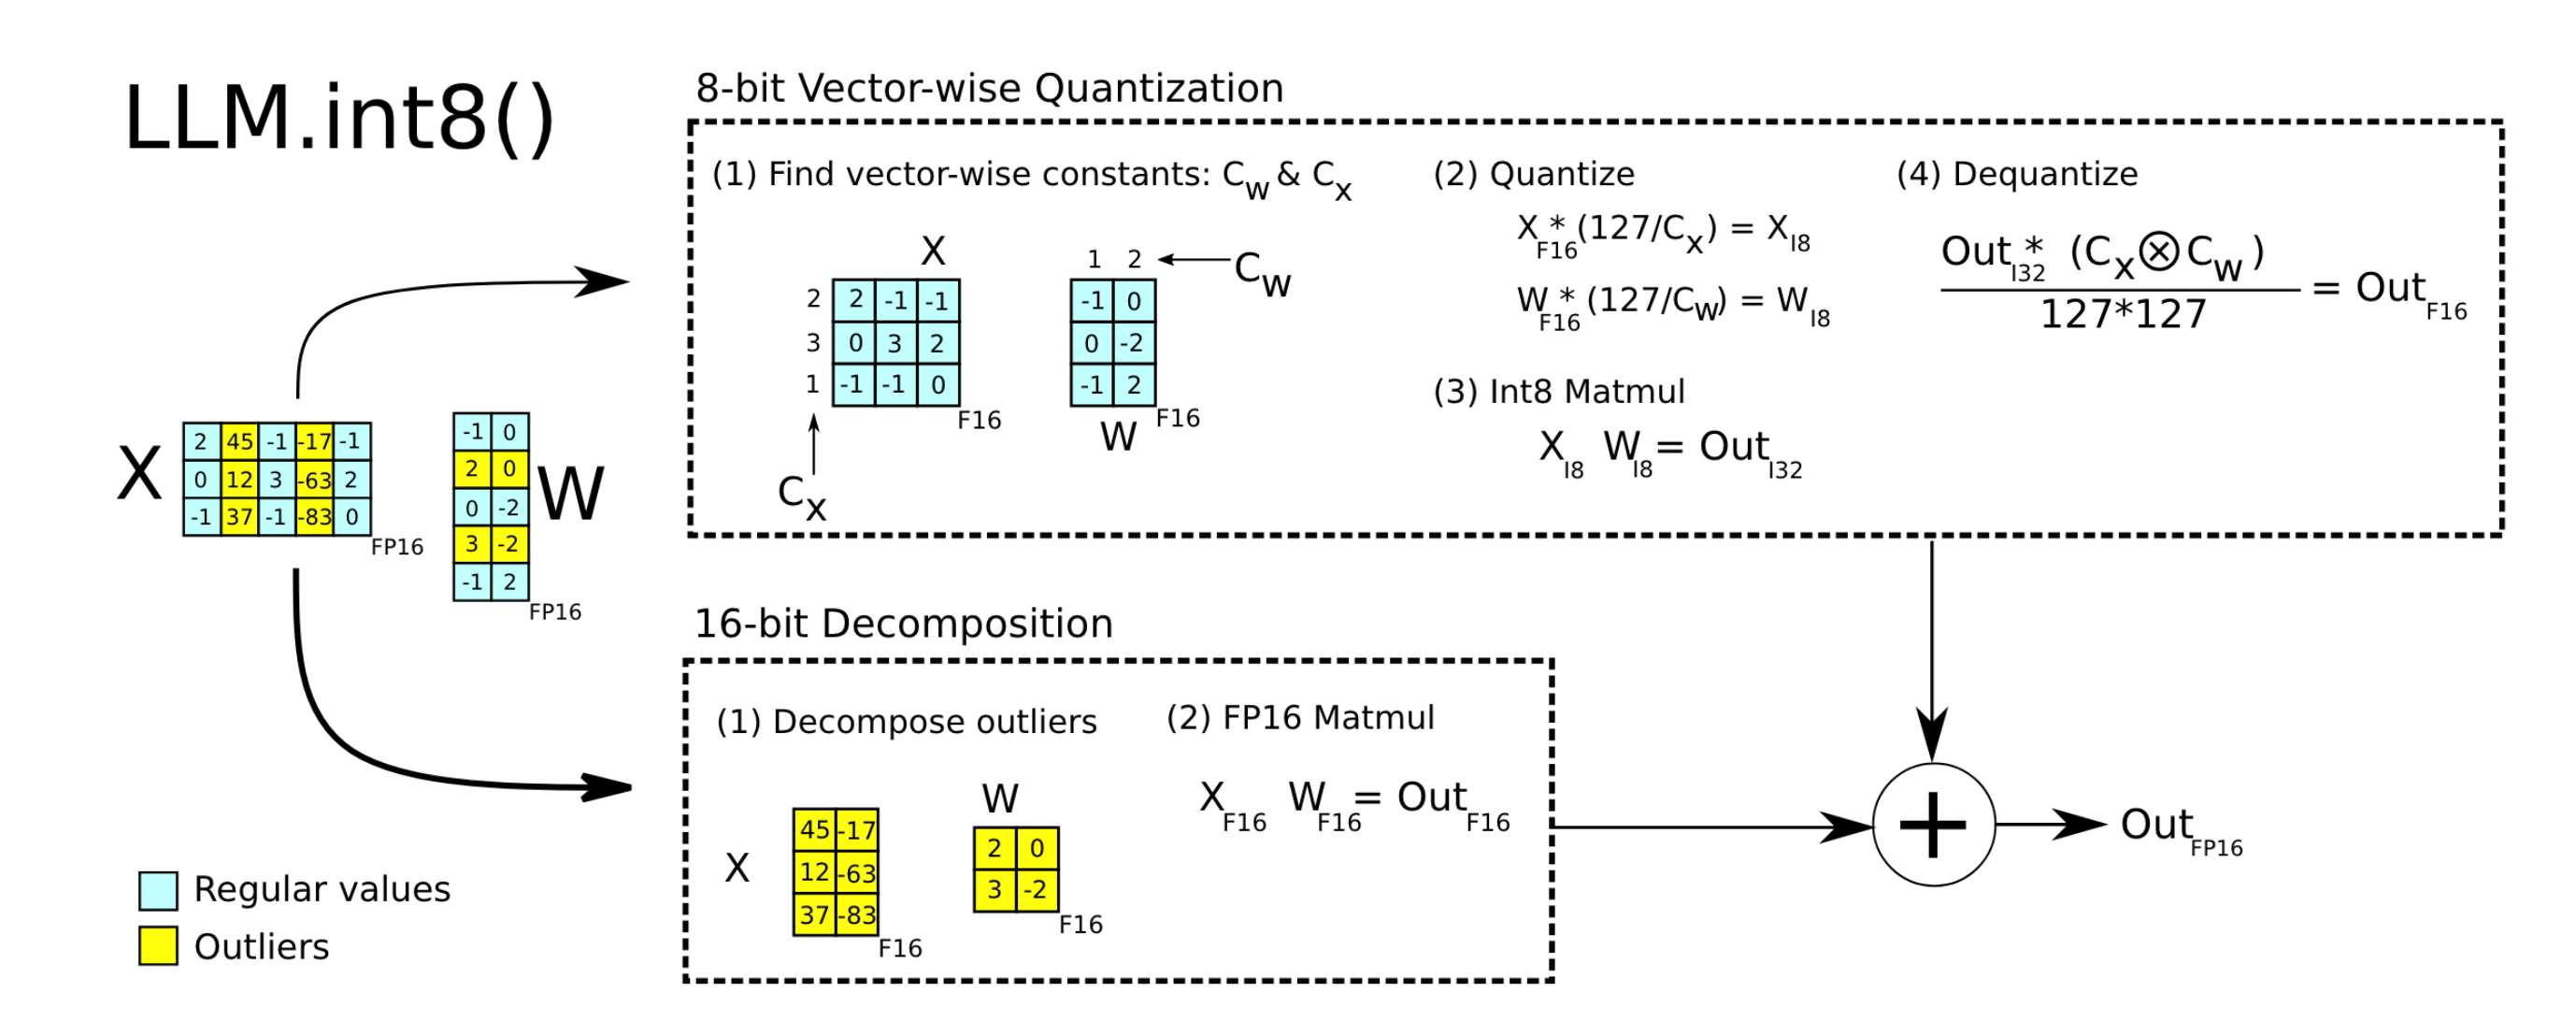
How Quantization Works: From a Matrix Multiplication Perspective ...
How to Maximize the Accuracy of LLM Models in 2025
LLM Benchmarks | SpacetimeDB
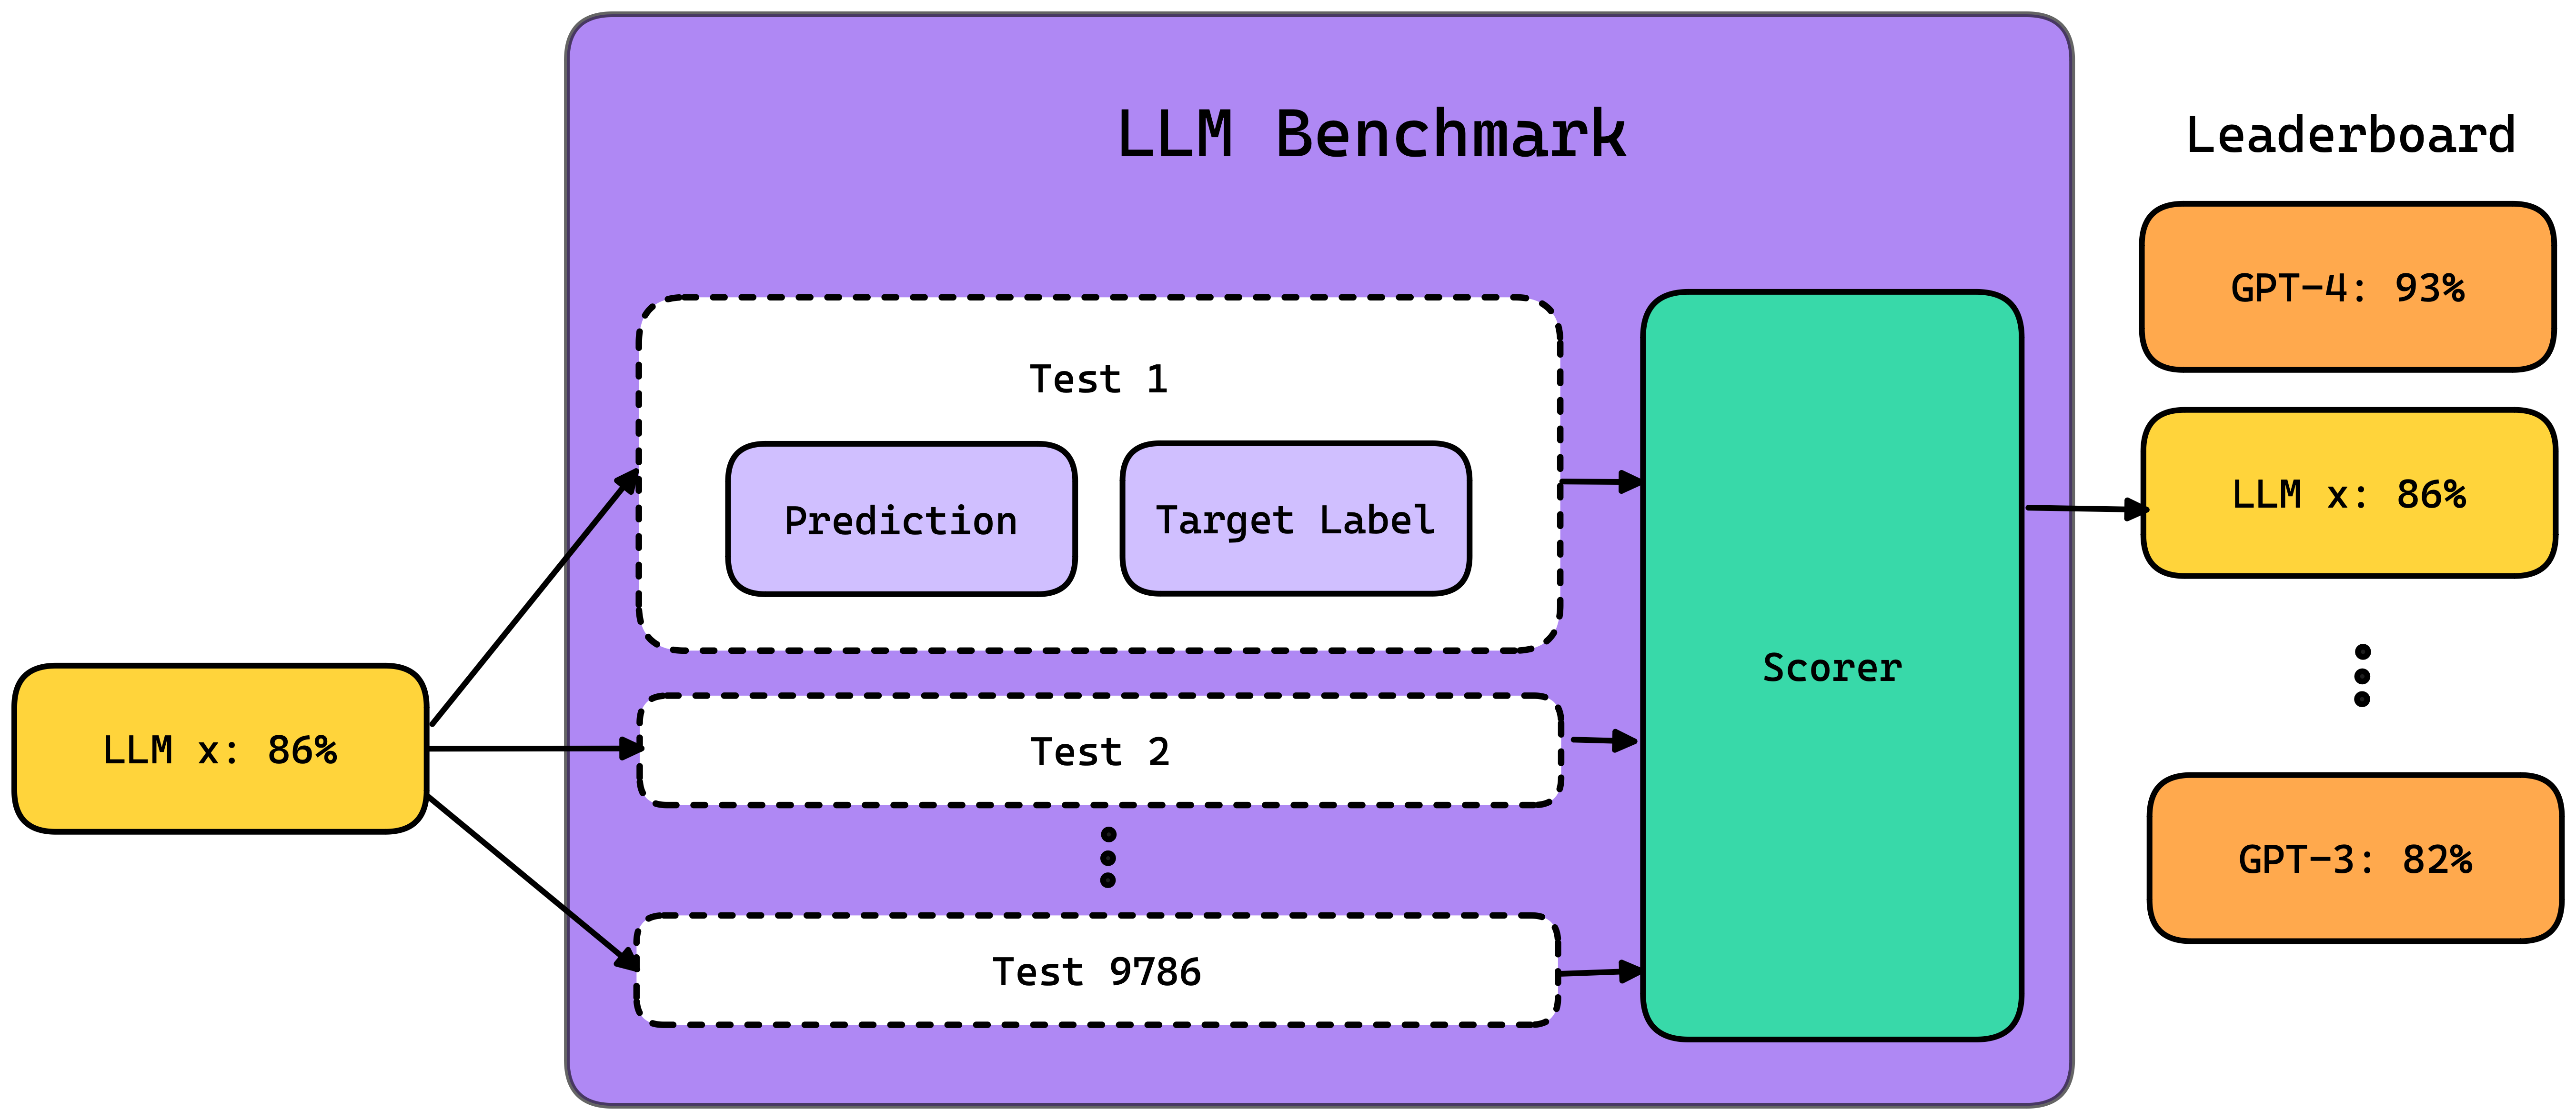
What are LLM Benchmarks?
LLM Benchmarks: MMLU, HellaSwag, BBH, and Beyond - Confident AI
What is LLM quantization? - YouTube
Low-Bit Quantization Favors Undertrained LLMs
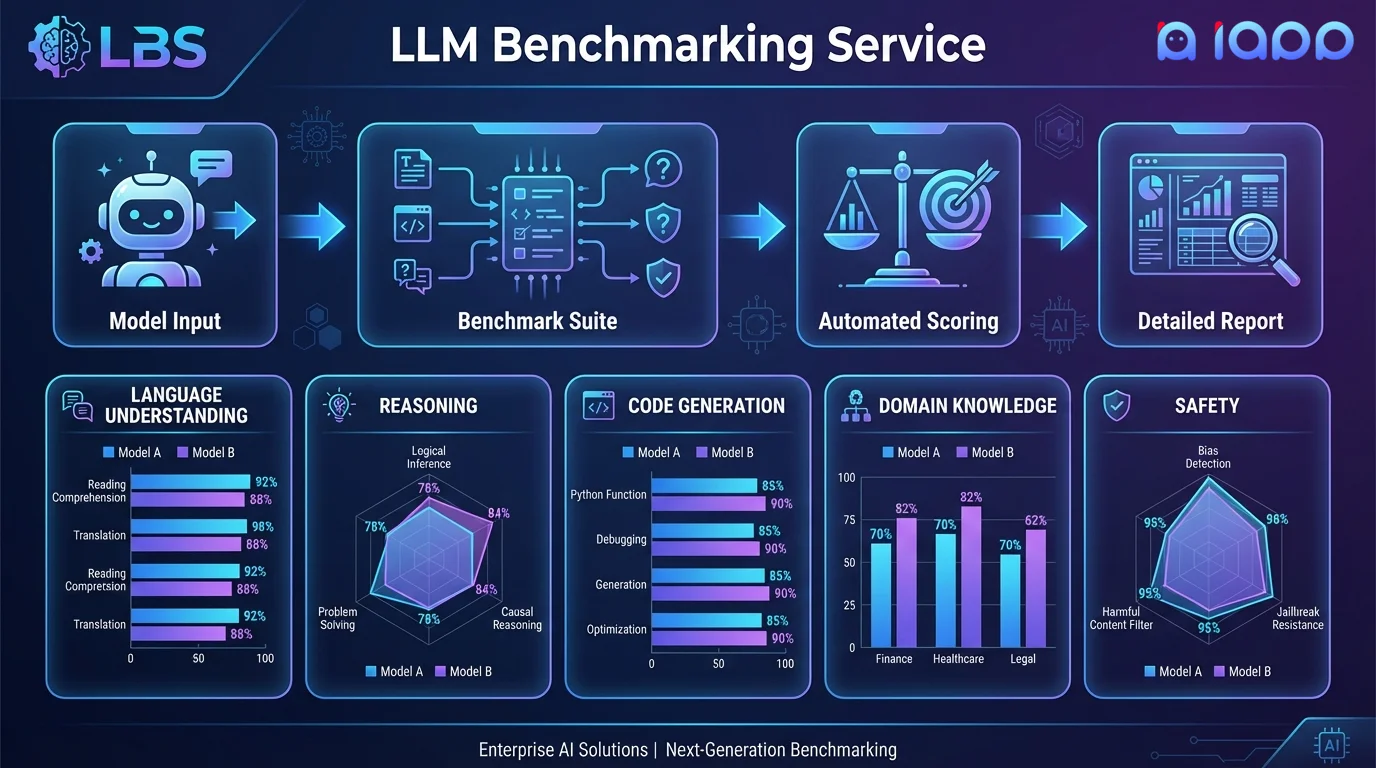
LLM Benchmarking Service - Comprehensive Model Evaluation | iApp ...
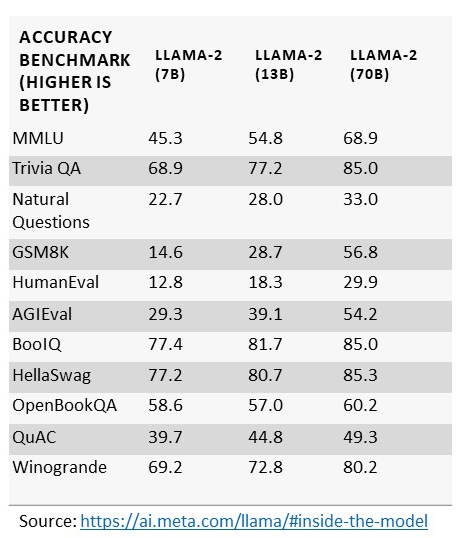
LLM Model Size: Comparison Chart & Performance Guide in 2025 | Label ...
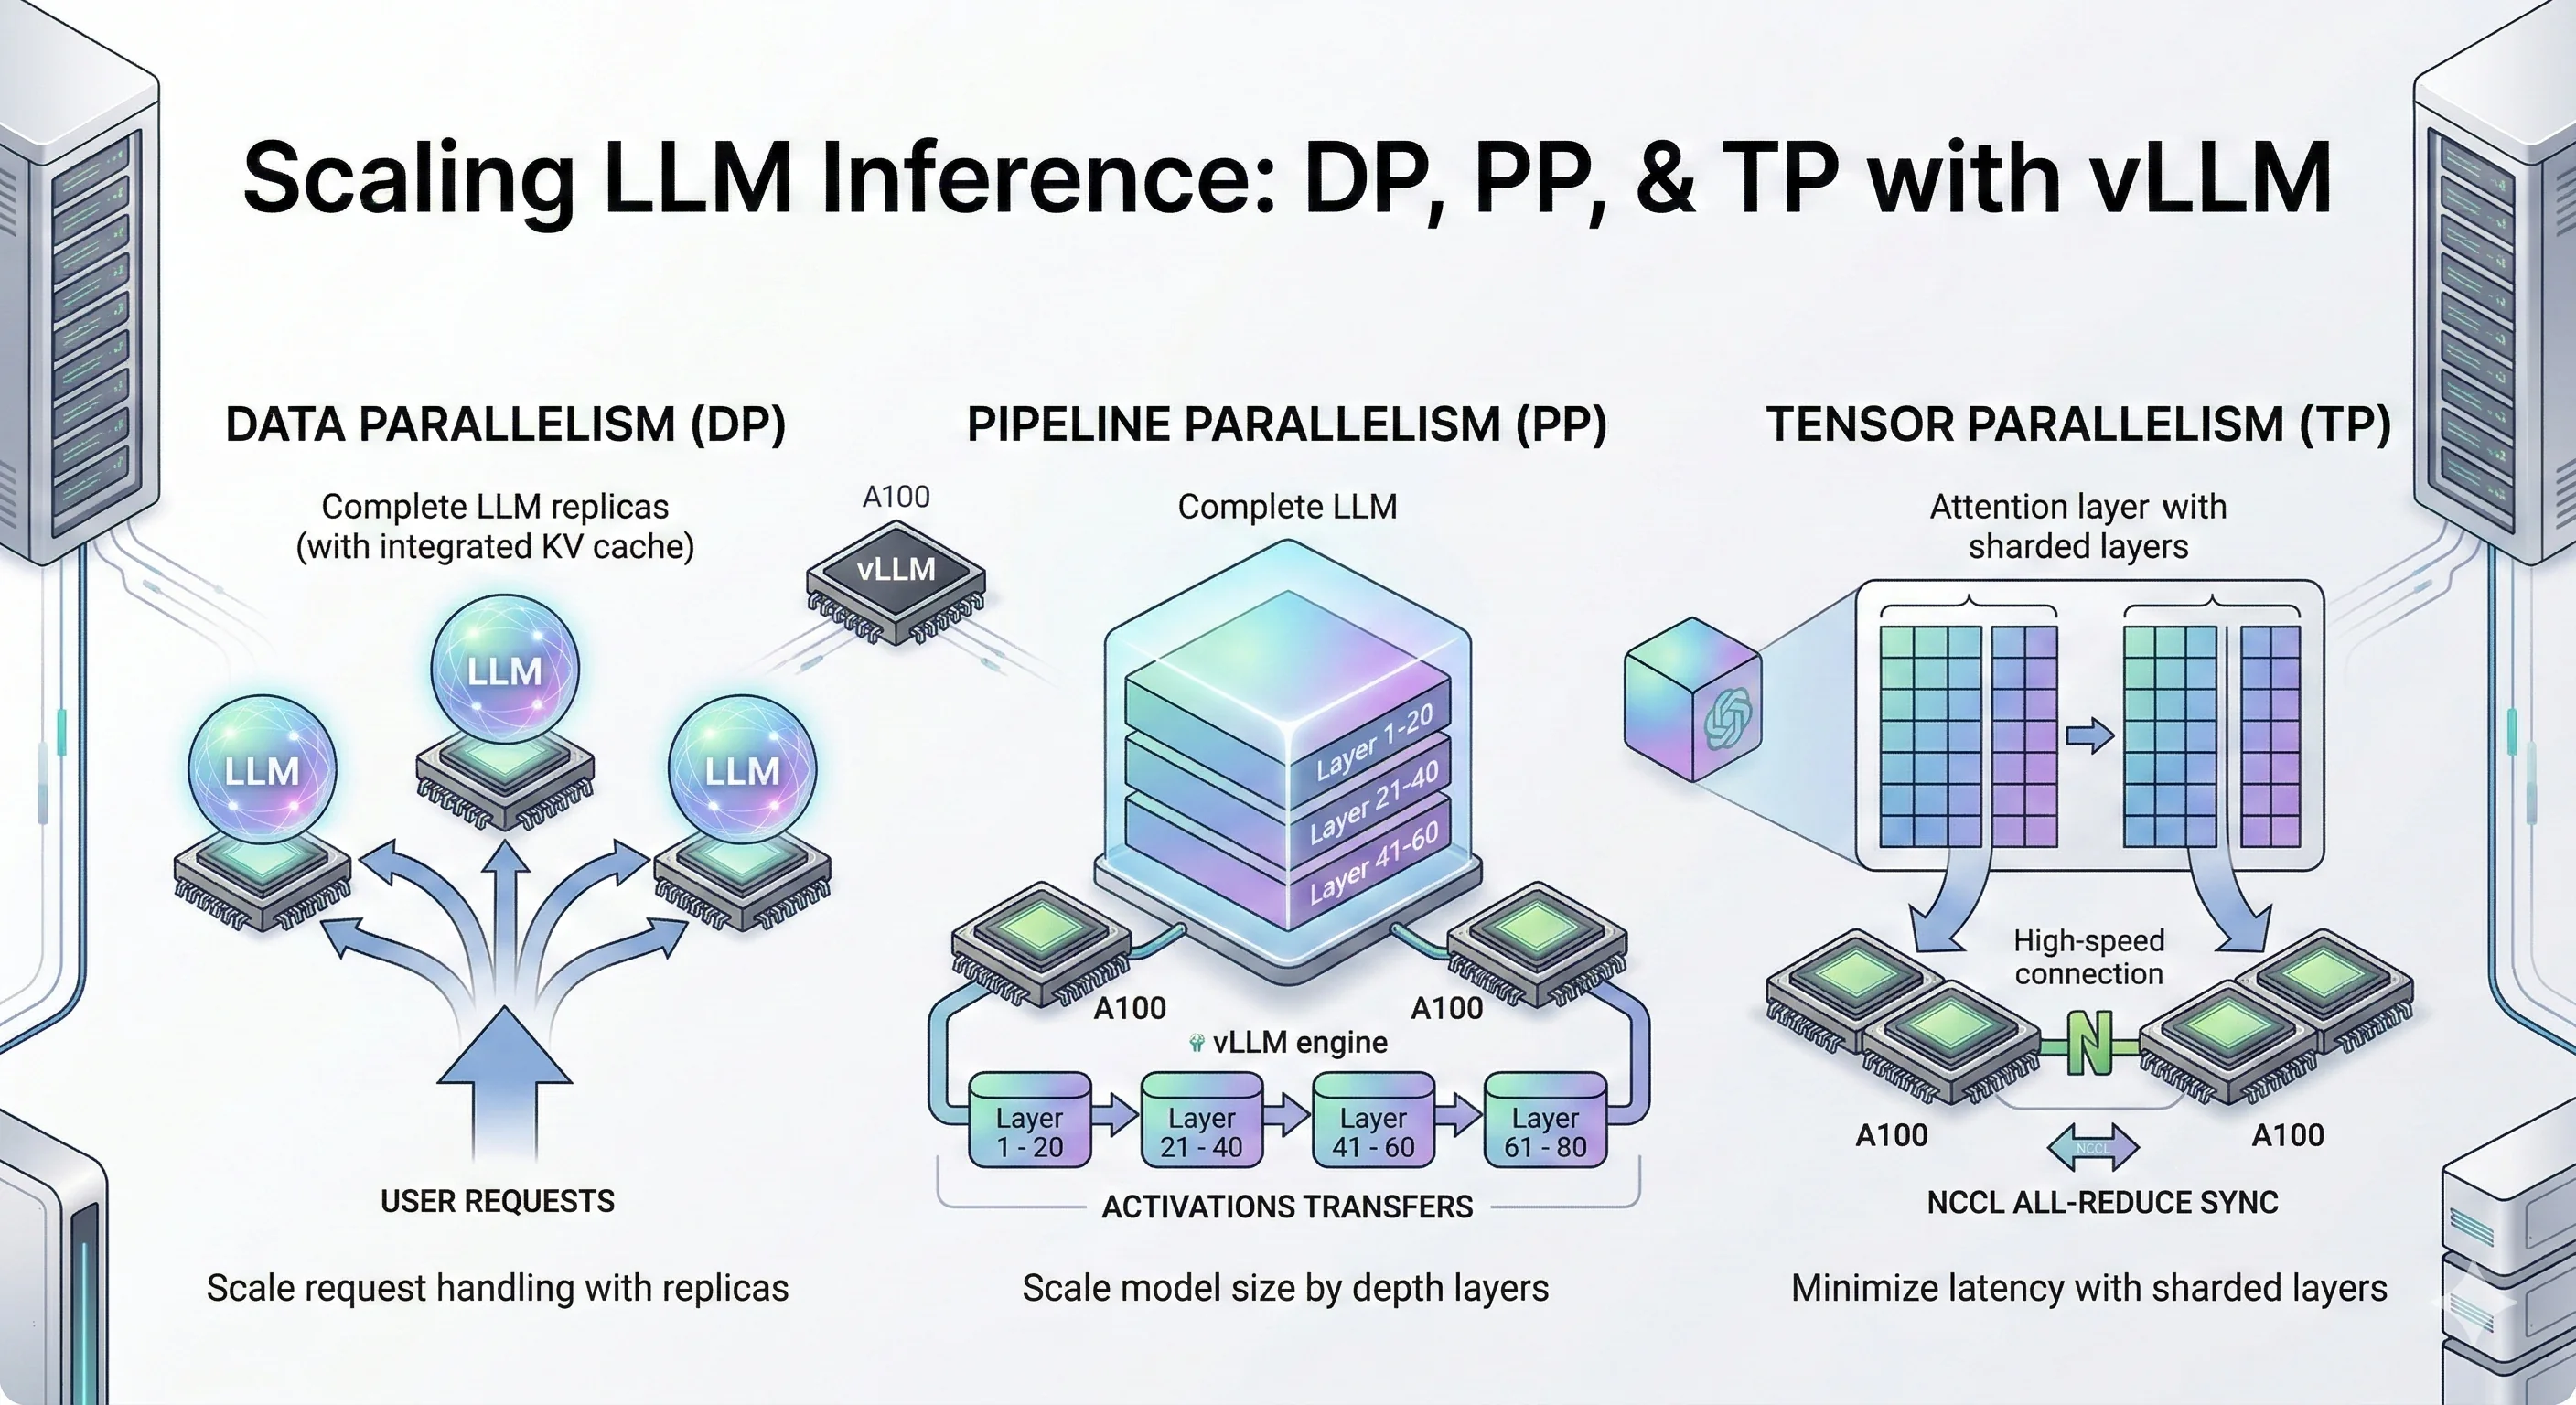
Scaling LLM inference with Ray and vLLM
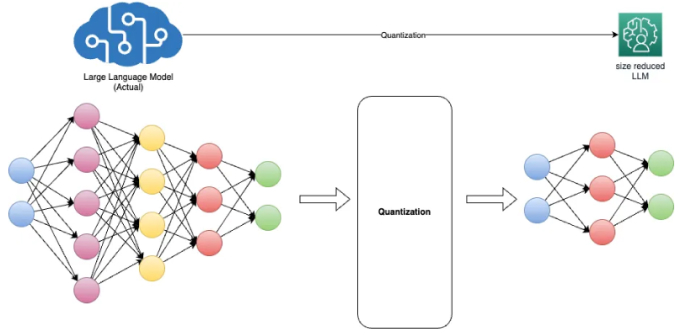
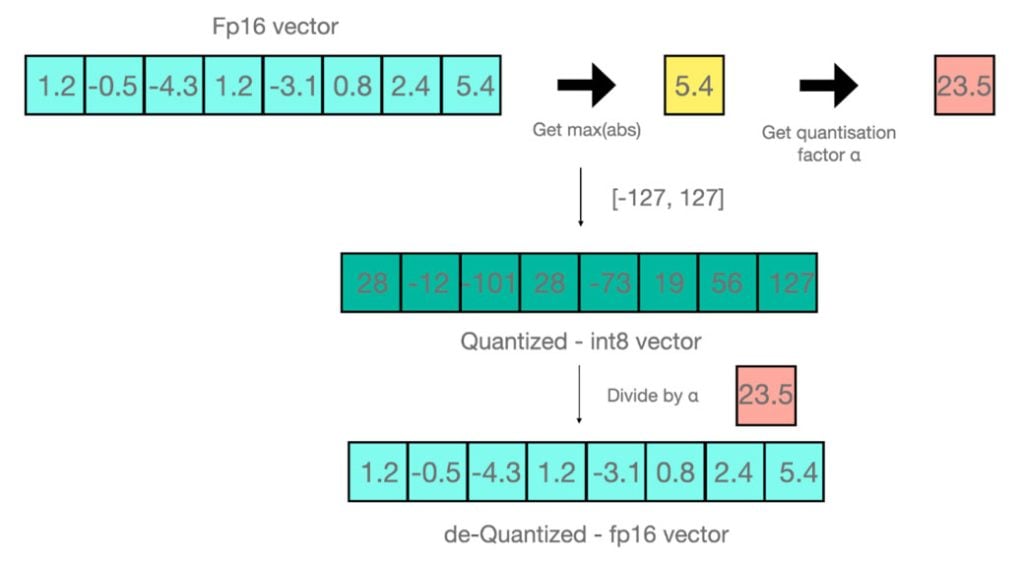
Understanding LLM Quantization. With the surge in applications using ...
Binary Quantization For LLMs Through Dynamic Grouping | AI Research ...
Llm-Qbench: A Benchmark Towards The Best Practice For Post-Training ...
What is LLM Quantization? How Does It Work & Types
Comparing the Giants: A Look at LLM Performance Benchmarks
New every month: The LLM Leaderboard shows the best Large Language ...
Unveiling the Ultimate LLM Benchmarks Guide
You Had One Job: Per-Task Quantization Using LLMs' Hidden ...
LLM Benchmarks Explained: Significance, Metrics & Challenges
Understanding Quantization in Large Language Models | by ...
Toward Efficient LLM Inference: A Quantitative Evaluation of ...
LLM Benchmarks Explained: Significance, Metrics & Challenges ...
What Is Llm Benchmarks Types Challenges Evaluators – forHairstyles ...
Quantization - MIT HAN Lab
Mastering LLM Techniques: Inference Optimization – GIXtools
Honey, I shrunk the LLM! A beginner's guide to quantization • The Register
Faster and More Efficient 4-bit quantized LLM Model Inference | by ...
Benchmarking Quantized LLMs: What Works Best for Real Tasks?
Medium
How to run LLMs on CPU-based systems | UnfoldAI
LLMs: Bigger is Not Always Better | AI Platform Alliance
I-LLM: Efficient Integer-Only Inference for Fully-Quantized Low-Bit ...
[Literature Review] VQ-LLM: High-performance Code Generation for Vector ...
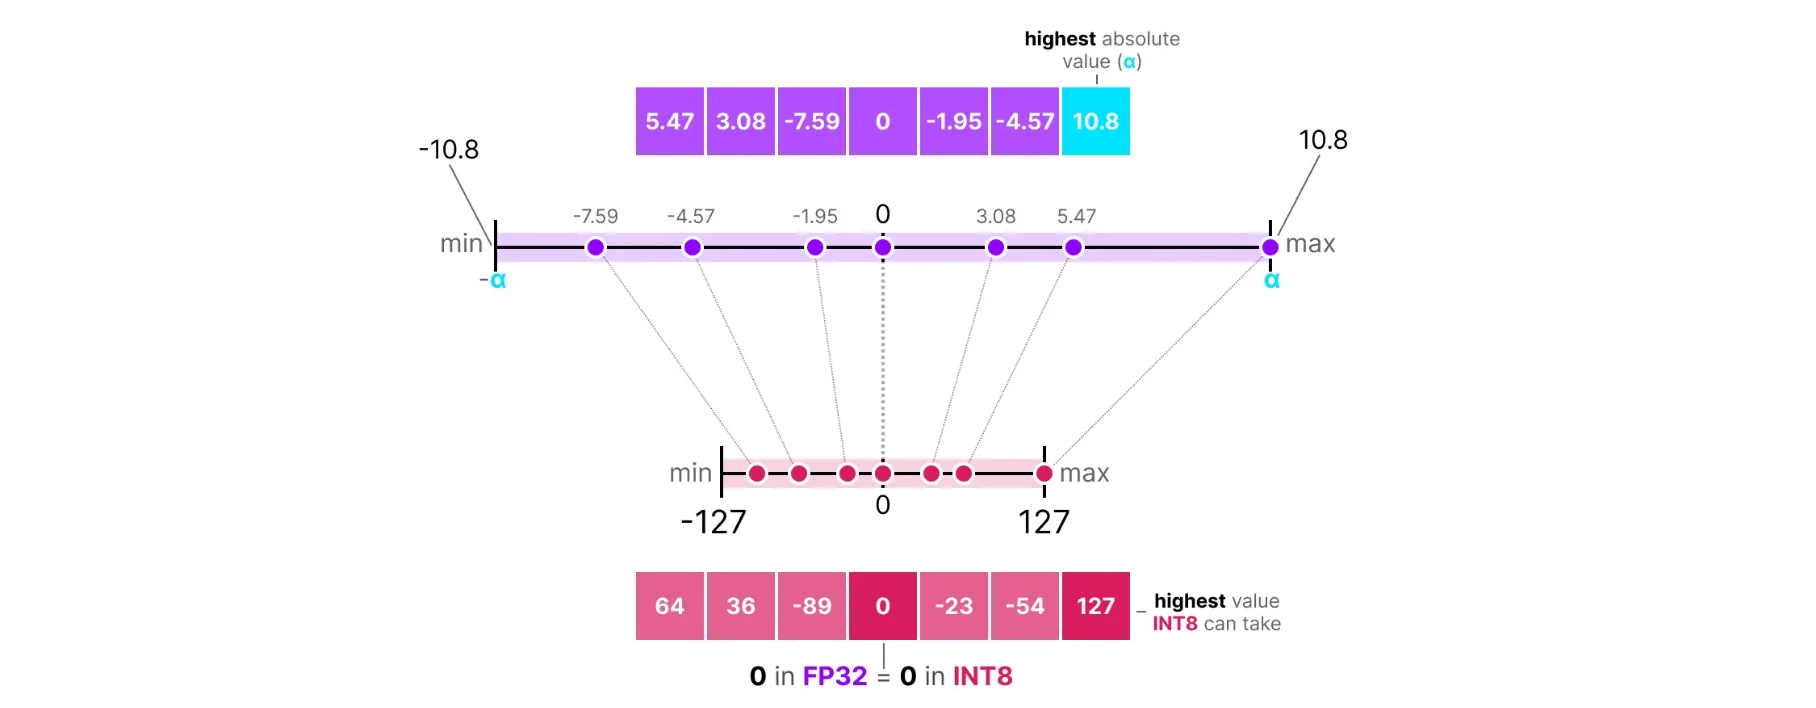
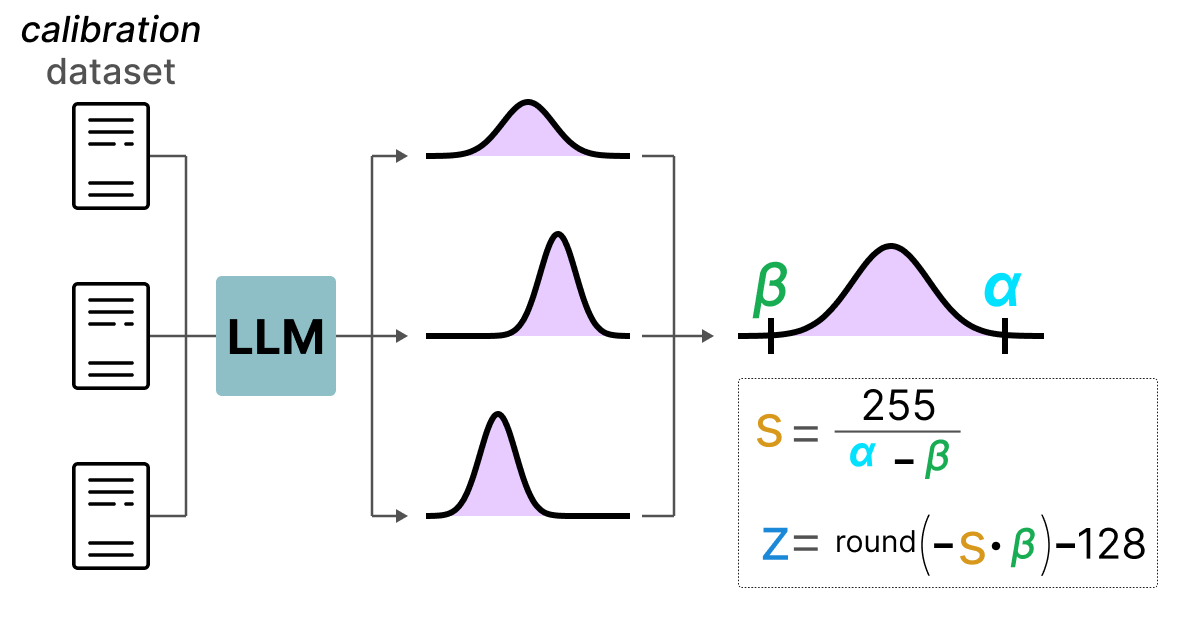
LLMs之Quantization:LLM中量化技术的可视化指南之量化技术的简介、常用数据类型、校准权重和激活值的量化方法(PTQ/QAT ...
What are Quantized LLMs?
Maximizing Business Potential with Large Language Models (LLMs)
大模型入门指南 - Quantization:小白也能看懂的“模型量化”全解析_大模型量化-CSDN博客
How to Run Quantized AI Models on Precision Workstations | Dell
[논문 리뷰] Through a Compressed Lens: Investigating the Impact of ...
Quantization: bài toán dịch thuật 70 năm tuổi mà mọi AI engineer đều ...
长文本(Long LLM) benchmarks 2023(时间顺序) - 知乎
Custom build on-premise Large Language Model — Fine-tuning models on ...
Serving Quantized LLMs on NVIDIA H100 Tensor Core GPUs | Databricks Blog
[论文评述] ABQ-LLM: Arbitrary-Bit Quantized Inference Acceleration for ...