Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
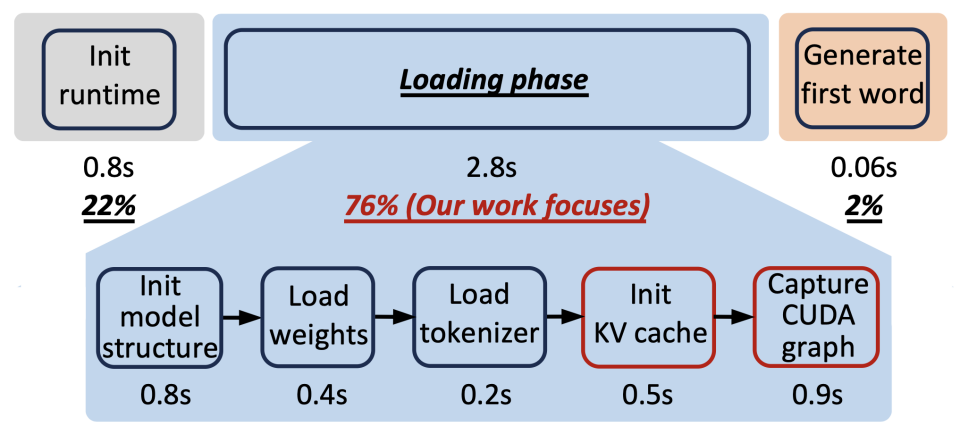
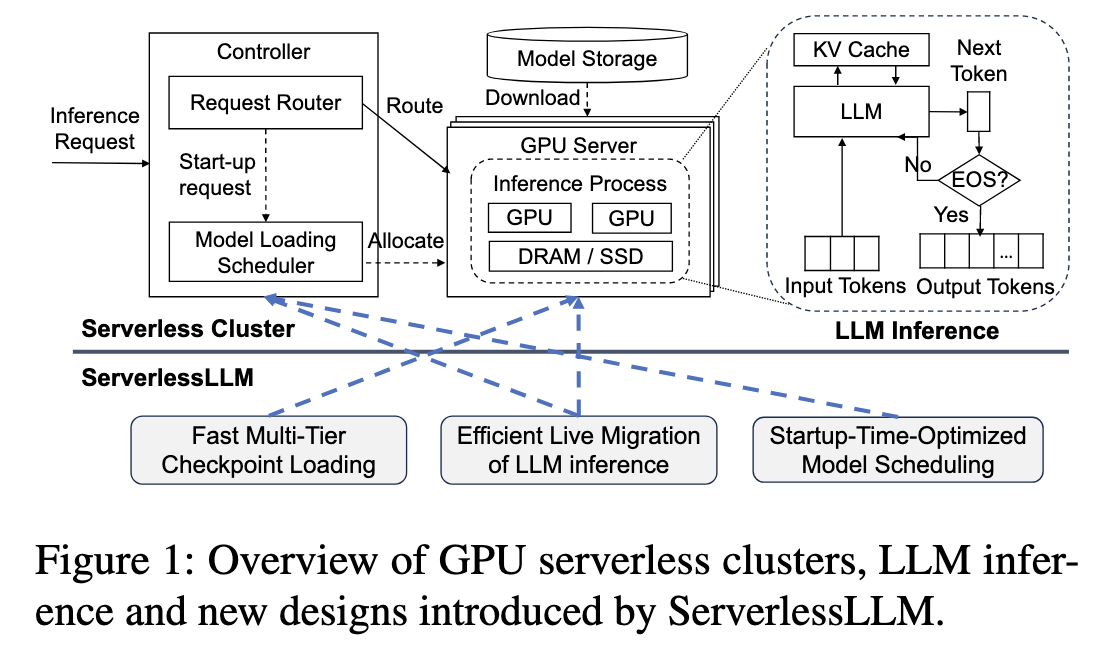
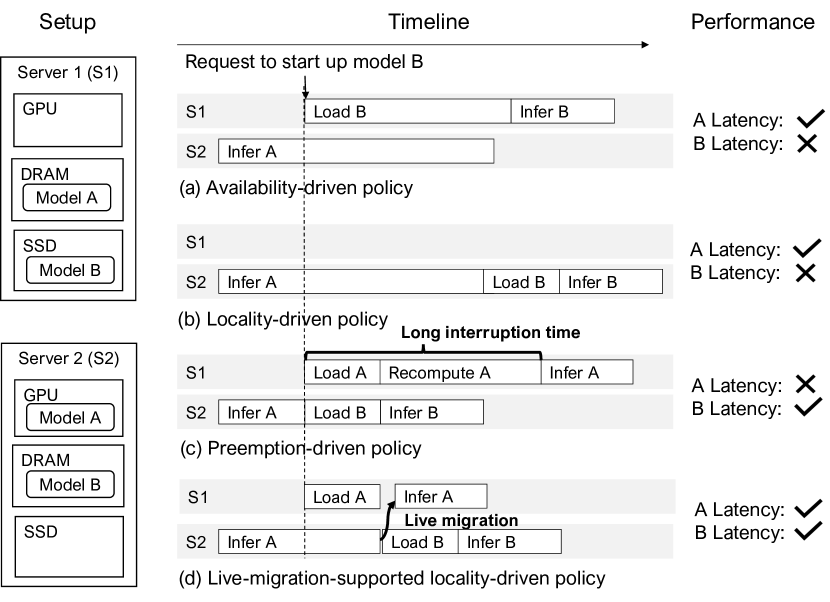
Figure 1 from Towards Resource-Efficient Serverless LLM Inference with ...
Serverless AI Deployment: Scale LLM Inference with Knative
Deploy LLM Inference Using Vast.ai Serverless
Scaling LLM Workloads with Serverless Batch Inference on Databricks ...
LLM inference on serverless solution - Runpod
【论文分享】| Medusa: Accelerating Serverless LLM Inference with ...
(PDF) Enabling Efficient Serverless Inference Serving for LLM (Large ...
HF Serverless LLM Inference API Status - a Hugging Face Space by woodmastr
Medusa: Optimizing Serverless LLM Inference | PDF | Pointer (Computer ...
Towards Scalable Serverless LLM Inference Systems
Scale Your AI Models with Serverless LLM Inference Platforms
Maximizing Efficiency: How Serverless Solutions Enhance LLM Inference ...
The Future of Serverless Inference for Large Language Models — AI ...
ServerlessLLM Locality-Enhanced Serverless Inference for Large Language ...
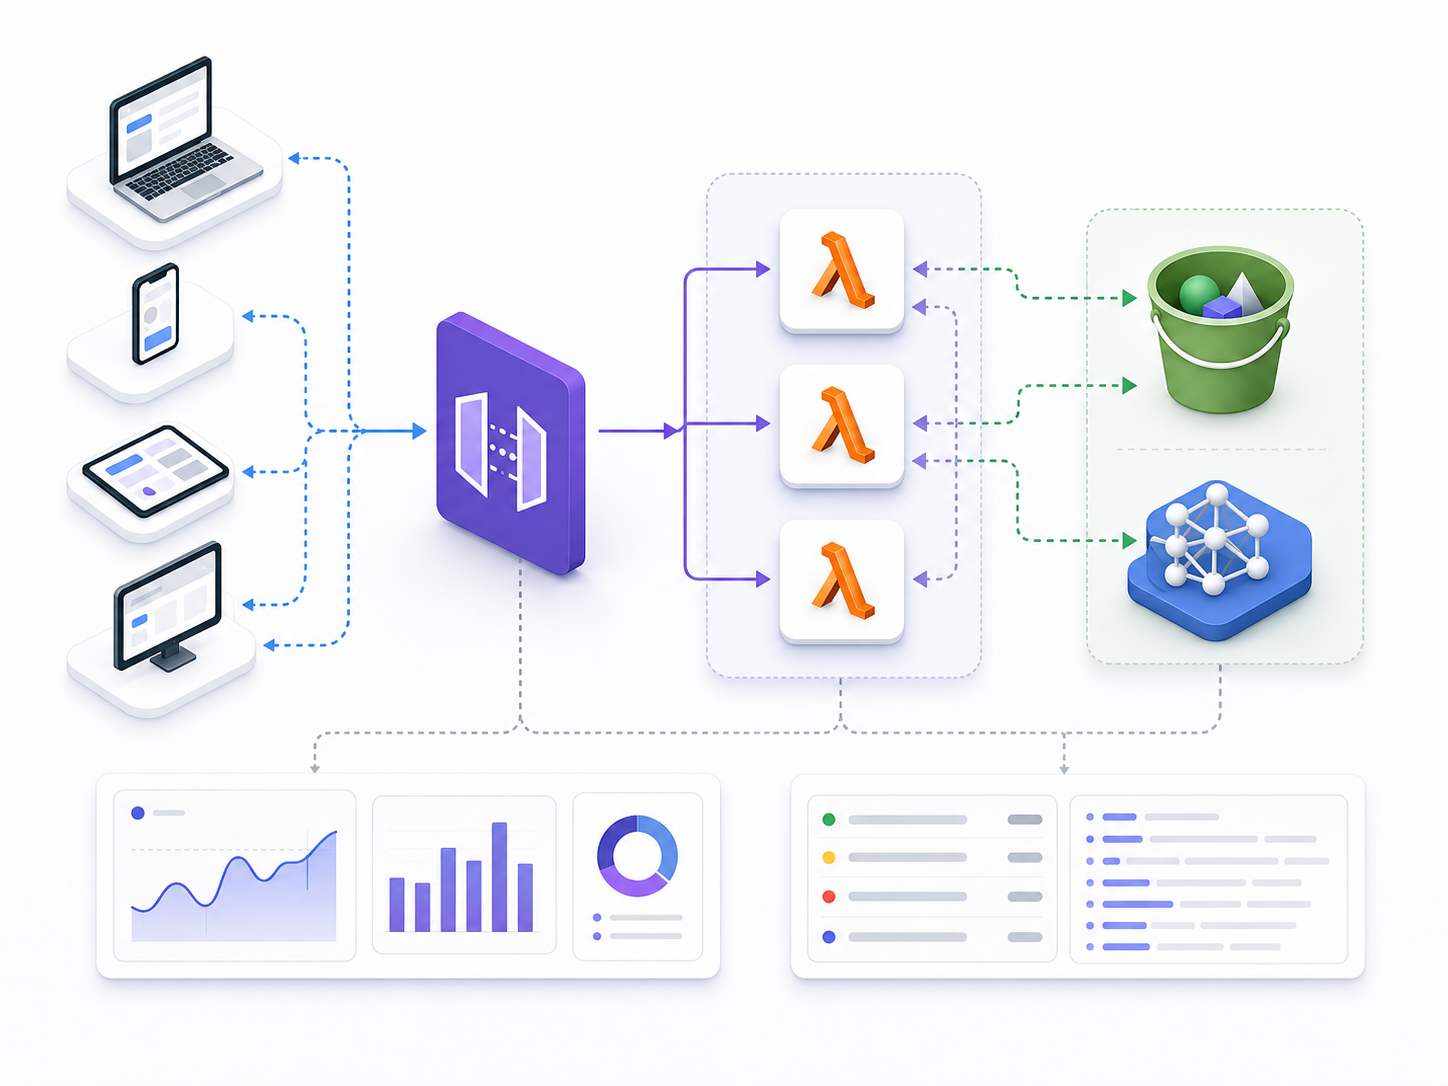
Serverless ML on AWS: How I Cut Inference Costs by 99% with Lambda & ONNX
Deploy models with Amazon SageMaker Serverless Inference - Amazon ...
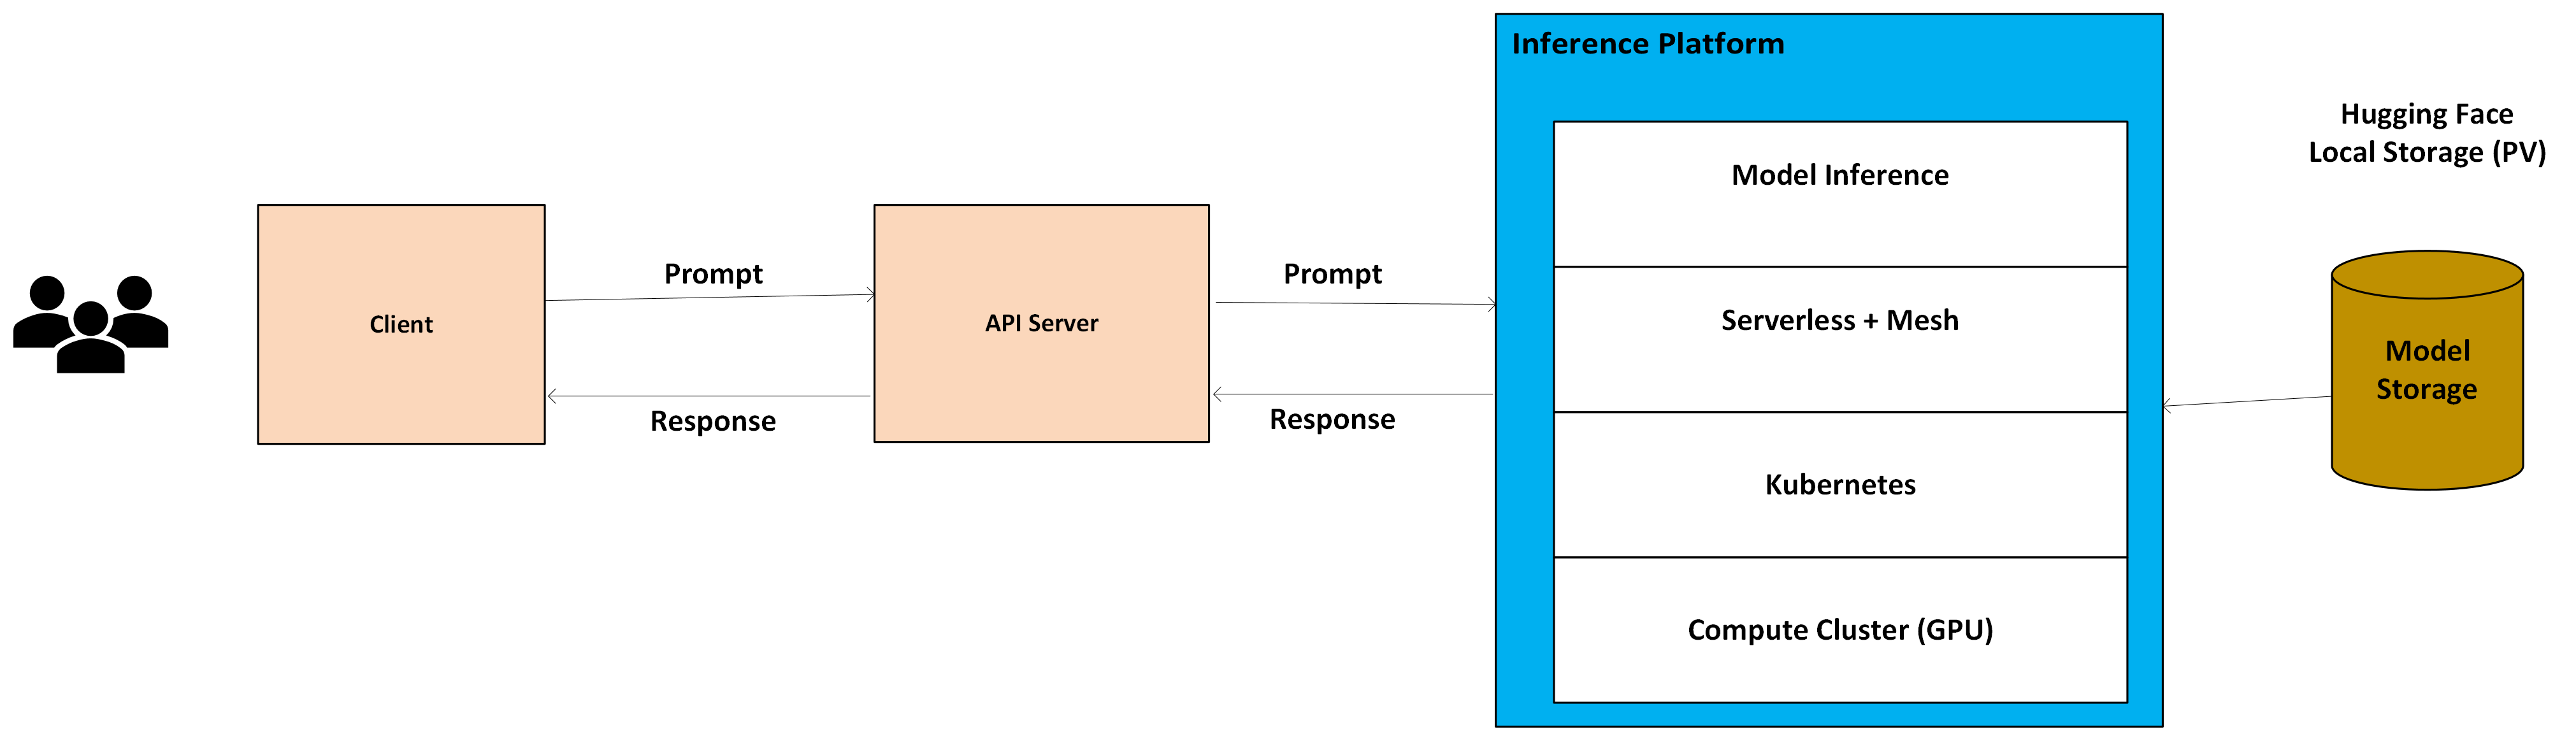
Serverless Machine Learning Model Inference on Kubernetes with KServe.pdf
Serverless Inference with Together AI
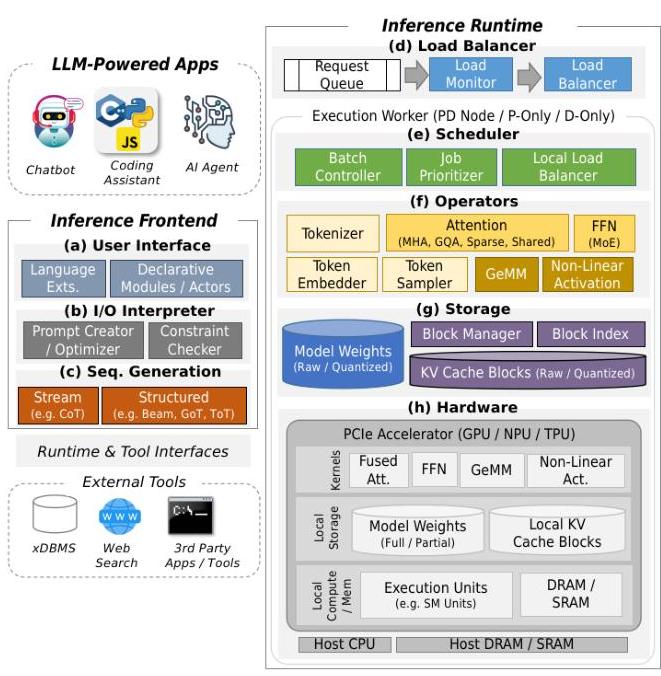
A Survey of LLM Inference Systems | alphaXiv
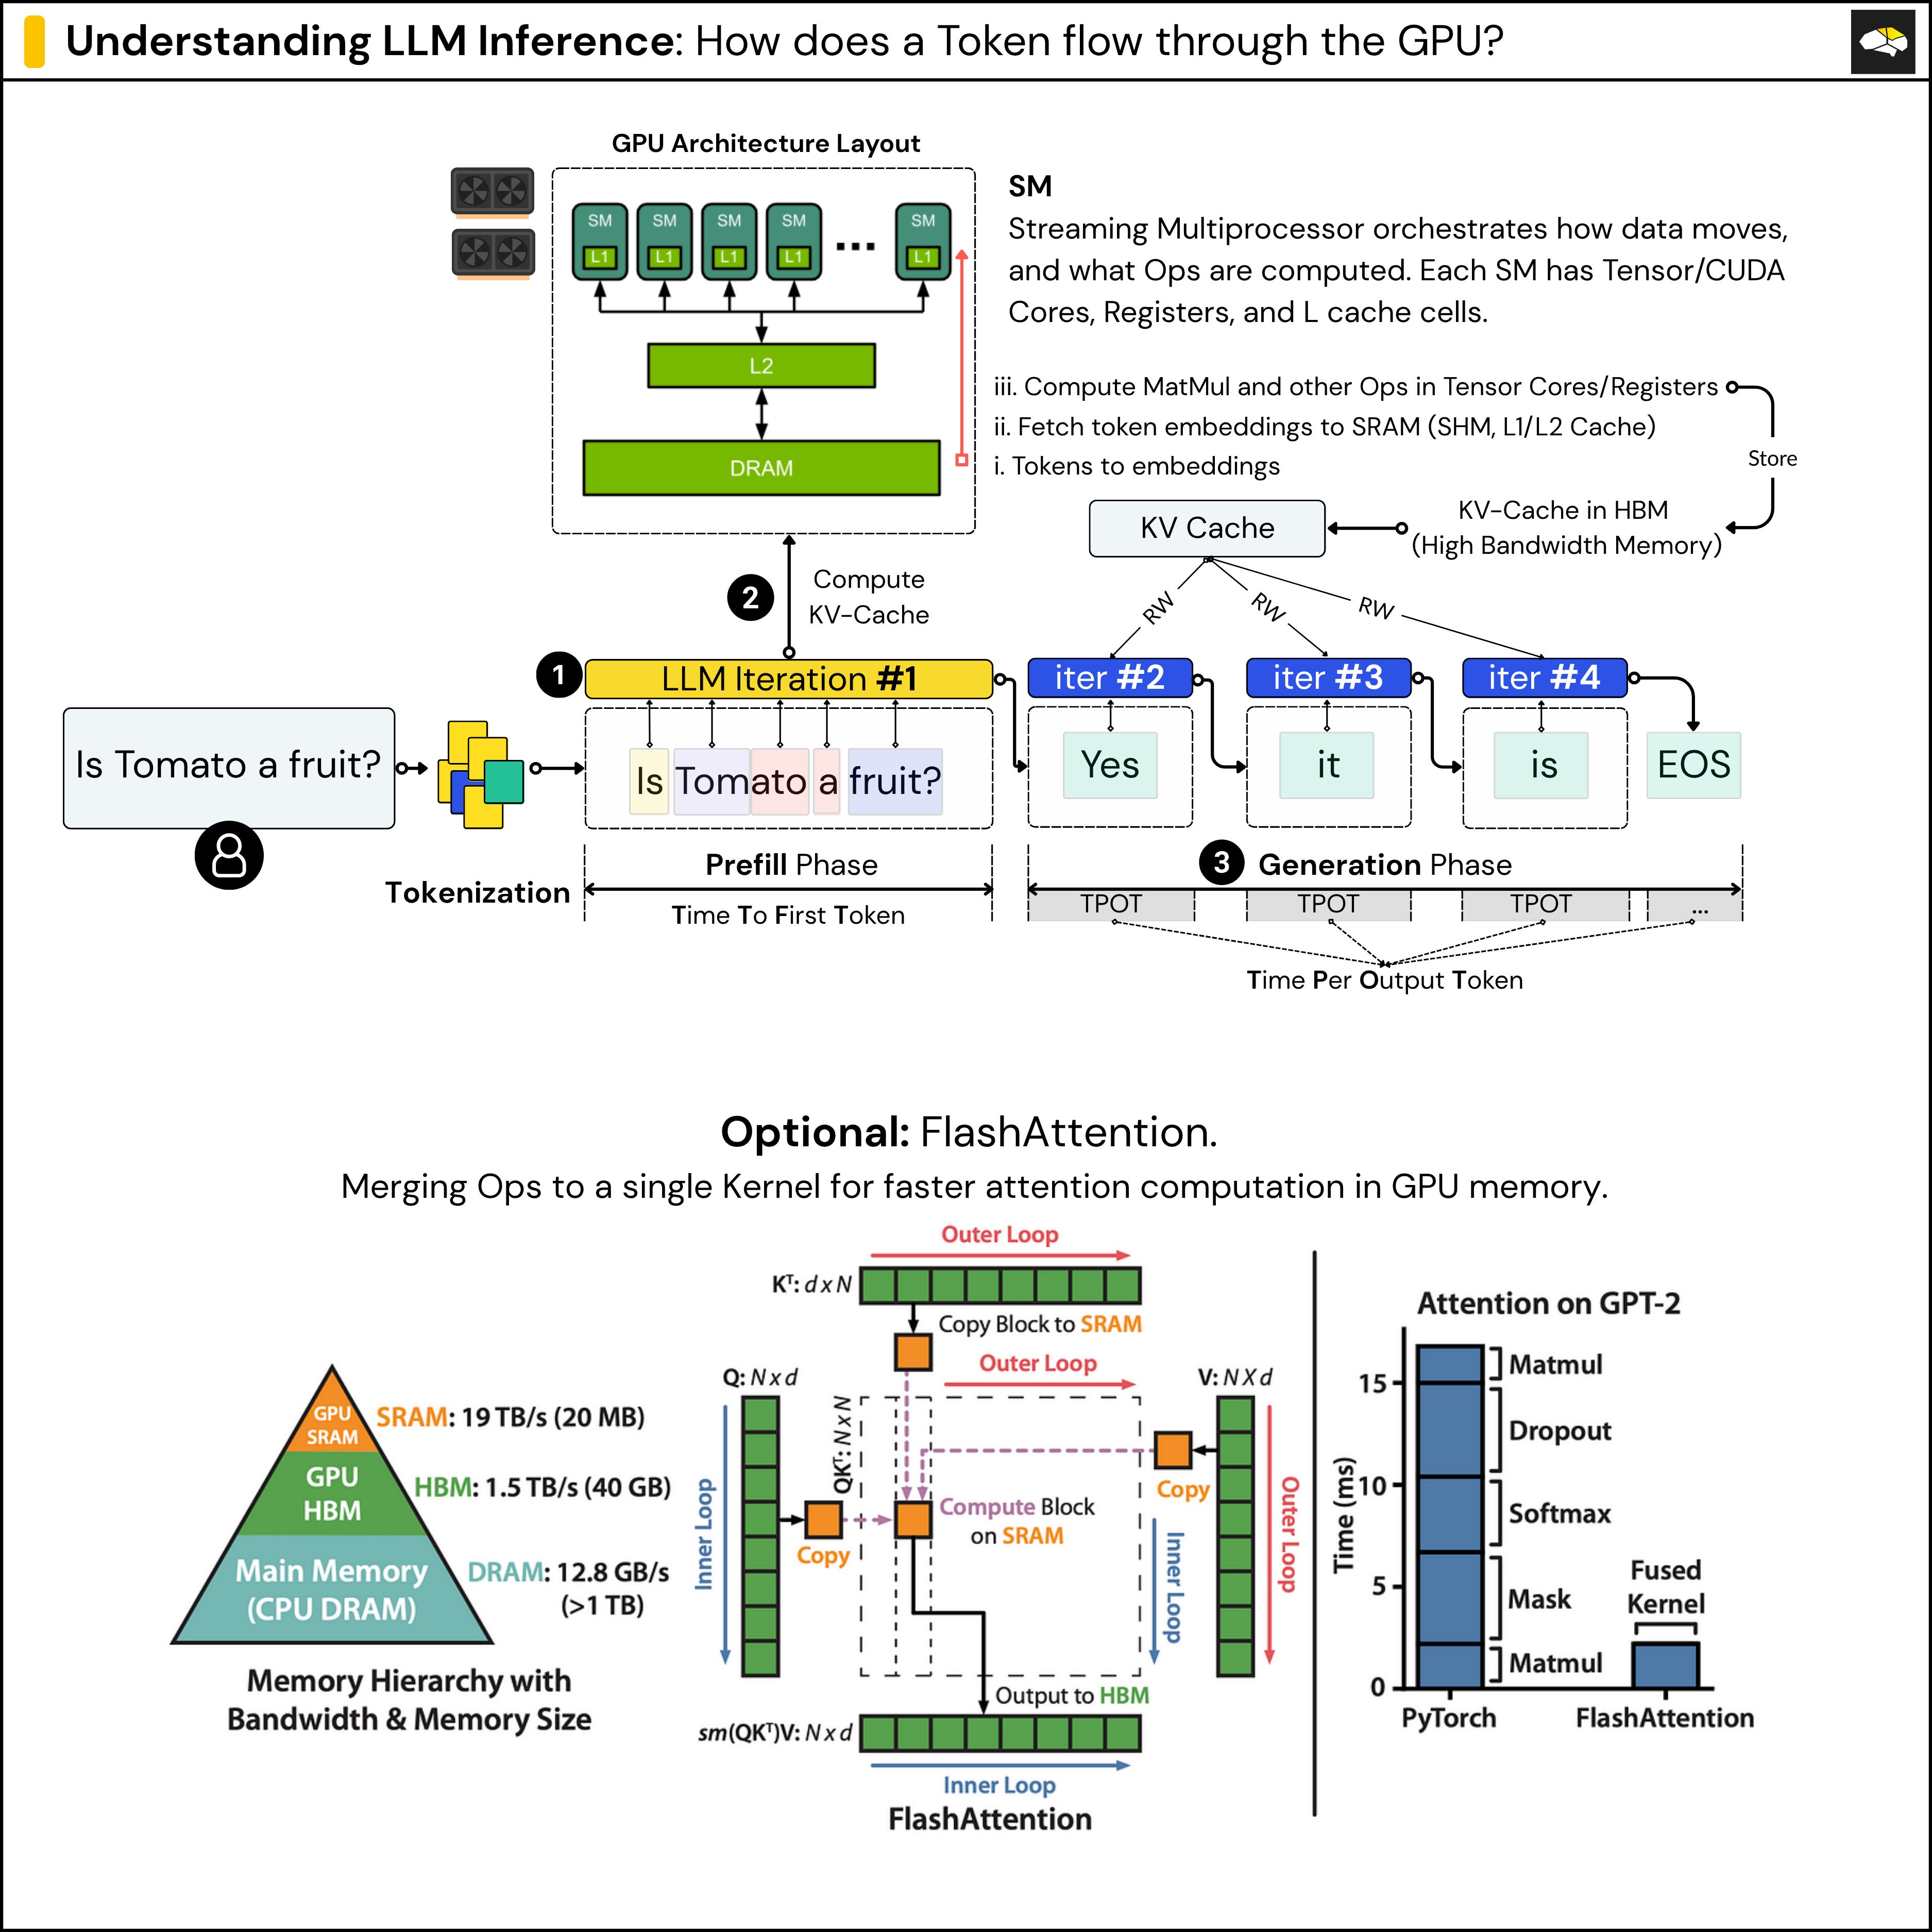
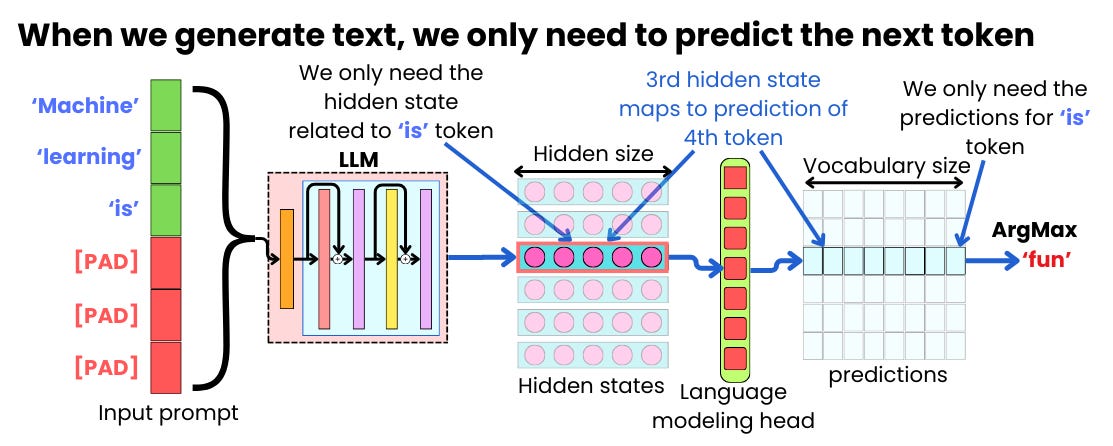
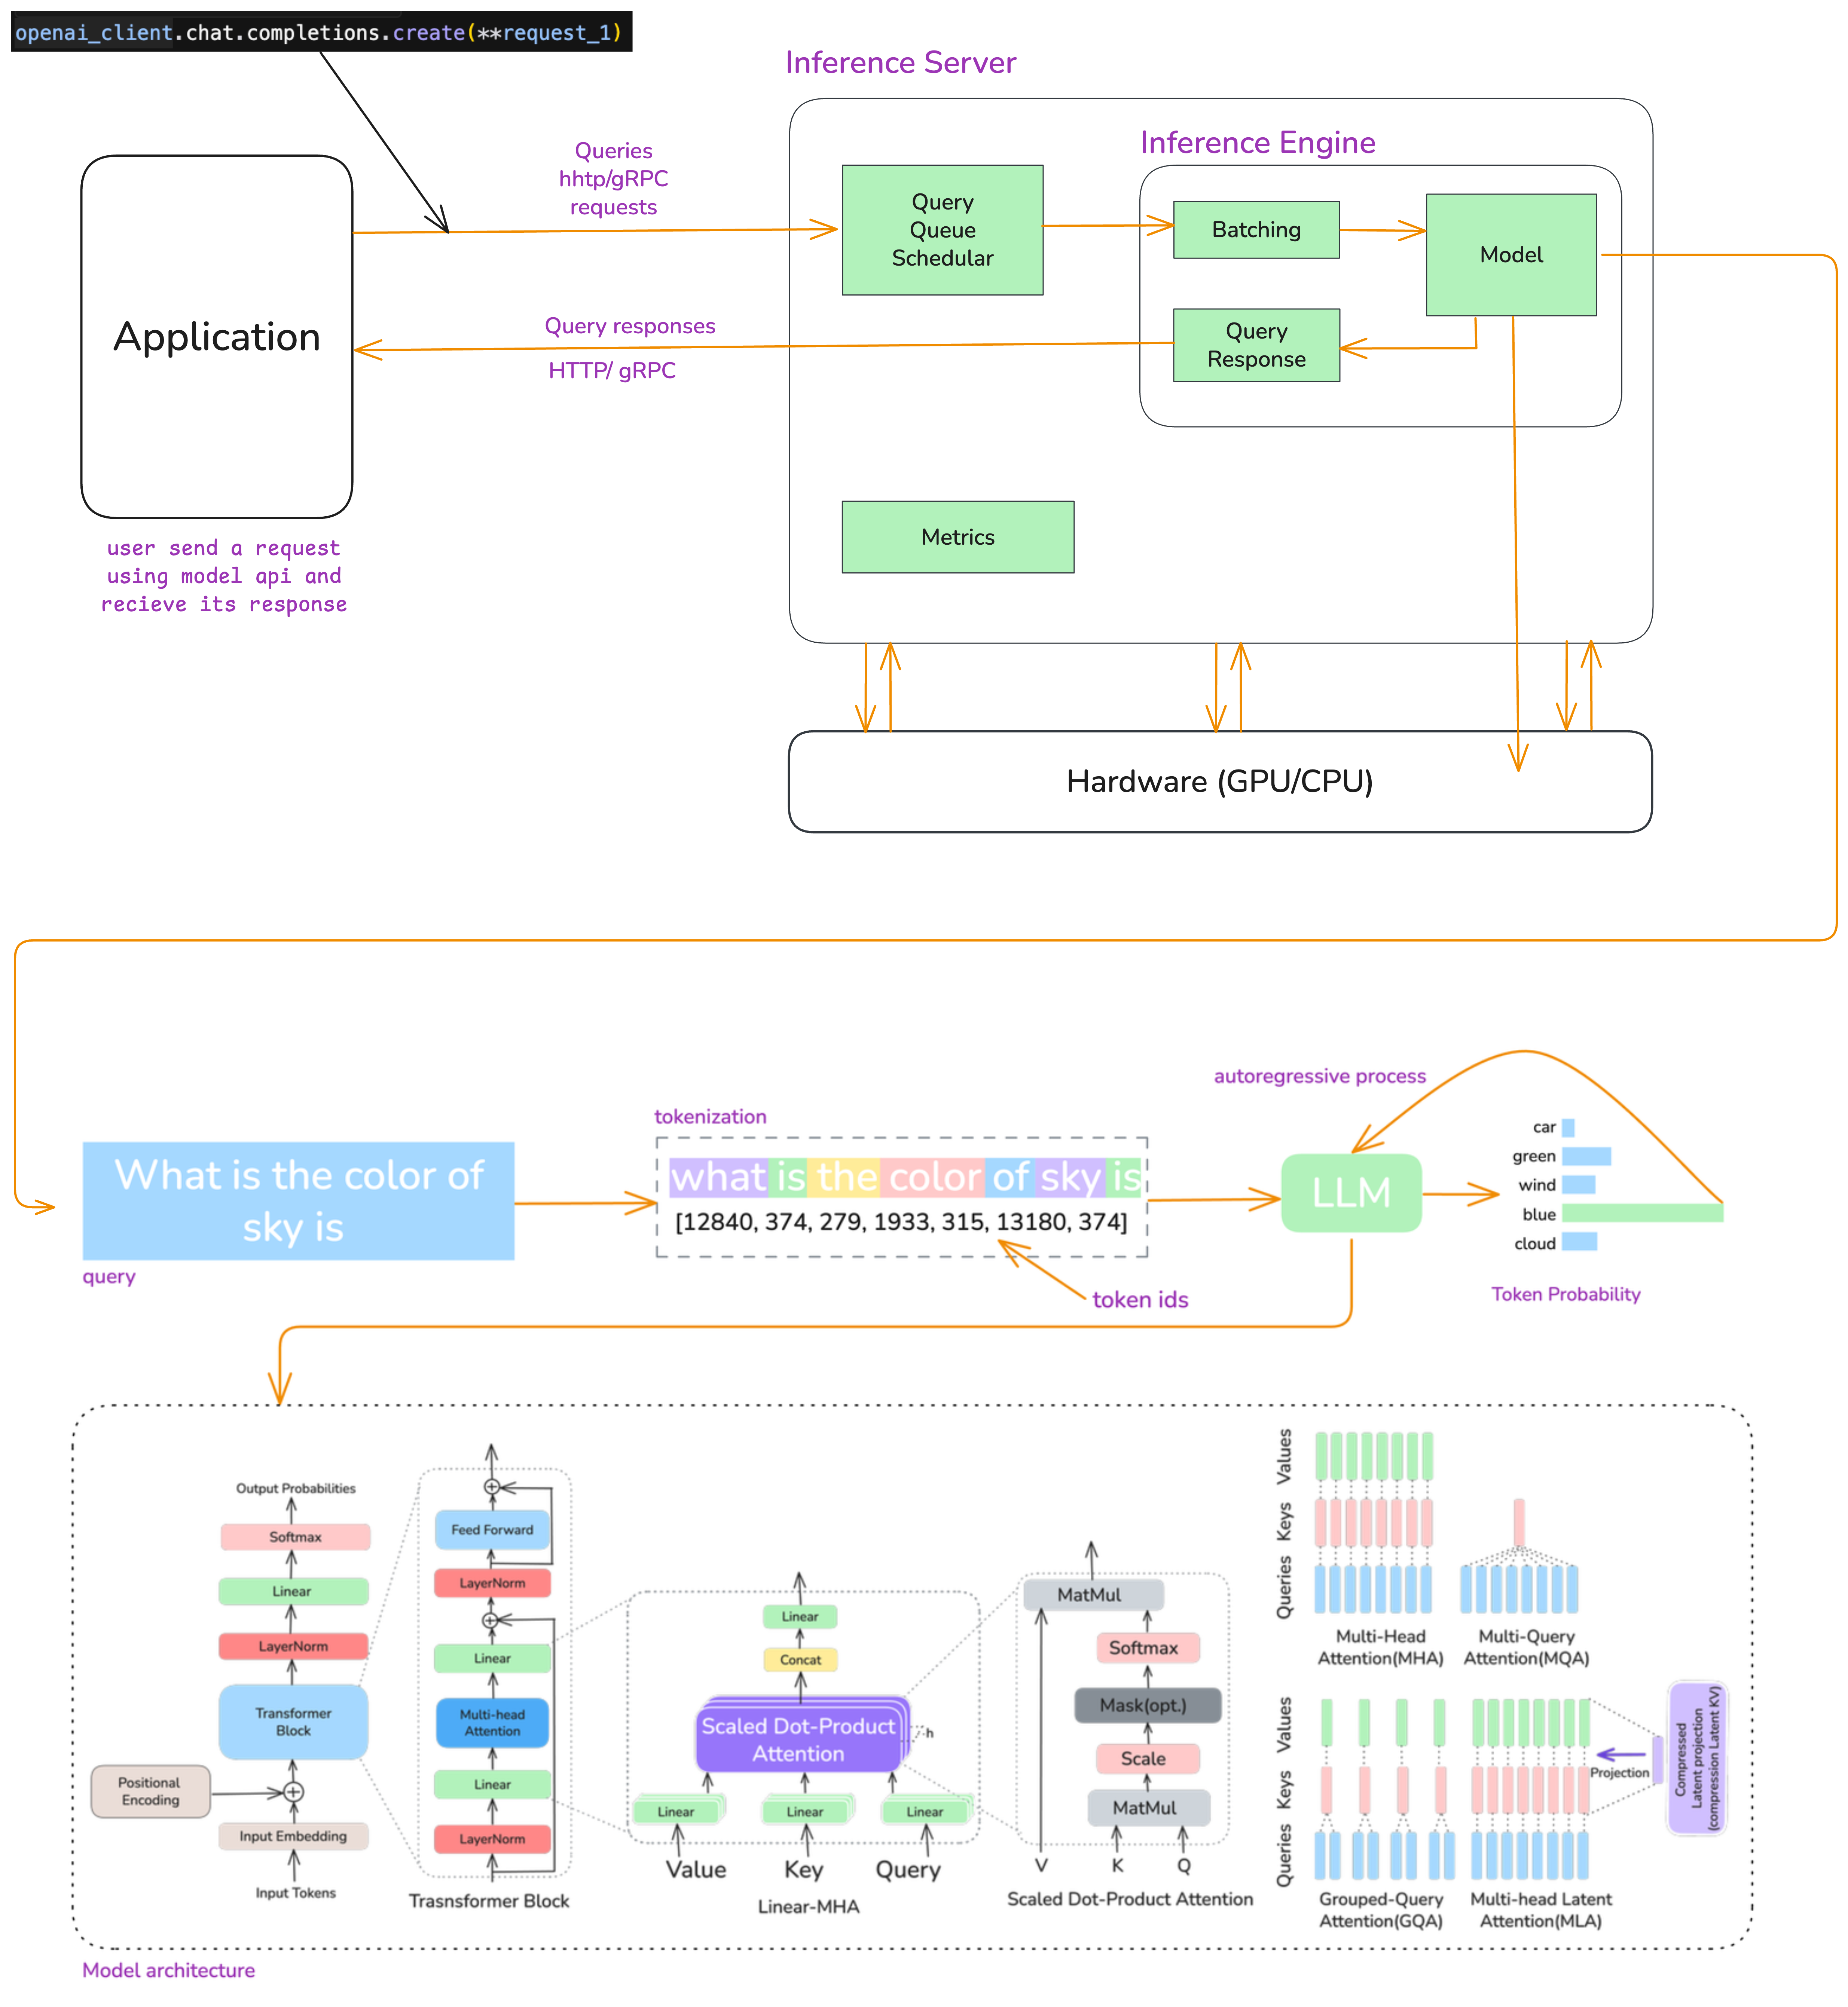
Understanding LLM Inference - by Alex Razvant
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
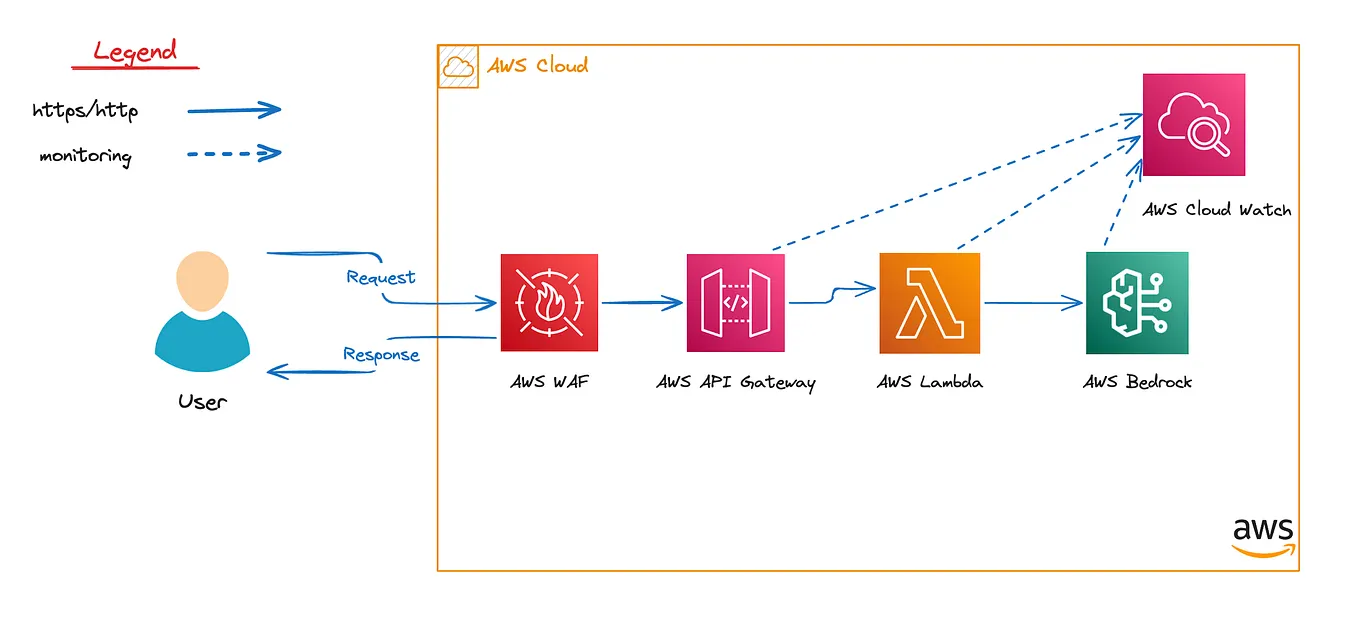
Serverless LLM on AWS » klichx.dev
[2401.14351] ServerlessLLM: Locality-Enhanced Serverless Inference for ...
Introducing Serverless Batch Inference | Databricks Blog
Serverless vs. Dedicated LLM Deployments: A Cost-Benefit Analysis
Discussion on "Serverless LLM Inference vs Self-Hosted LLM: A Practical ...
Serverless GPU Inference for LLMs
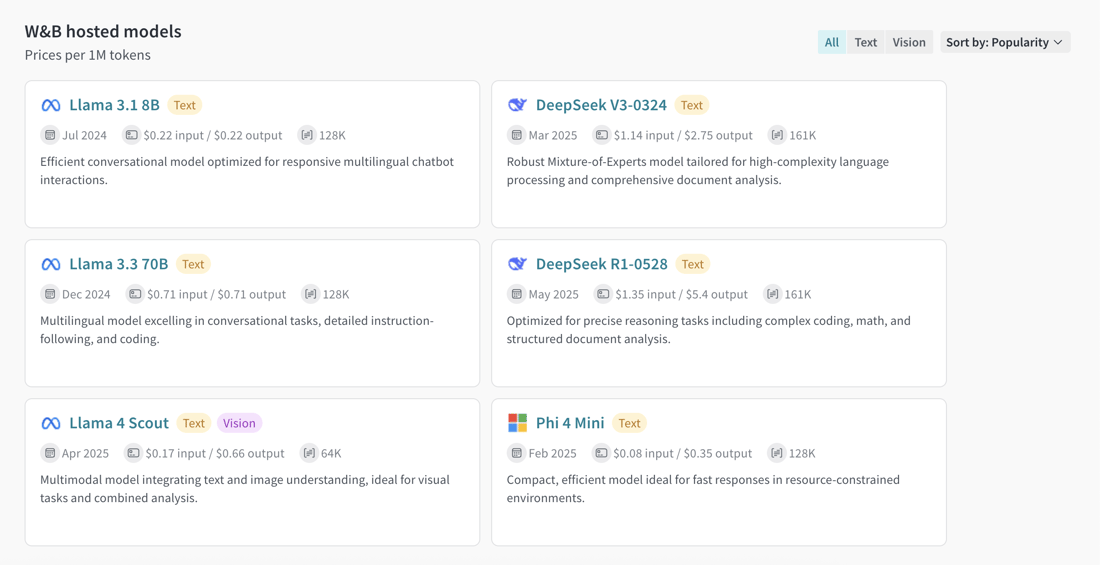
Serverless Inference - Weights & Biases Documentation
Serverless LLM Inference: Enabling Elastic Sharing on Heterogeneous ...
Pure serverless machine learning inference with AWS Lambda and Layers
Accelerate Deep Learning and LLM Inference with Apache Spark in the ...
Serverless LLM Inference: The Real Cost of AWS Bedrock vs. GCP Vertex ...
ServerlessLoRA: Minimizing Latency and Cost in Serverless Inference for ...
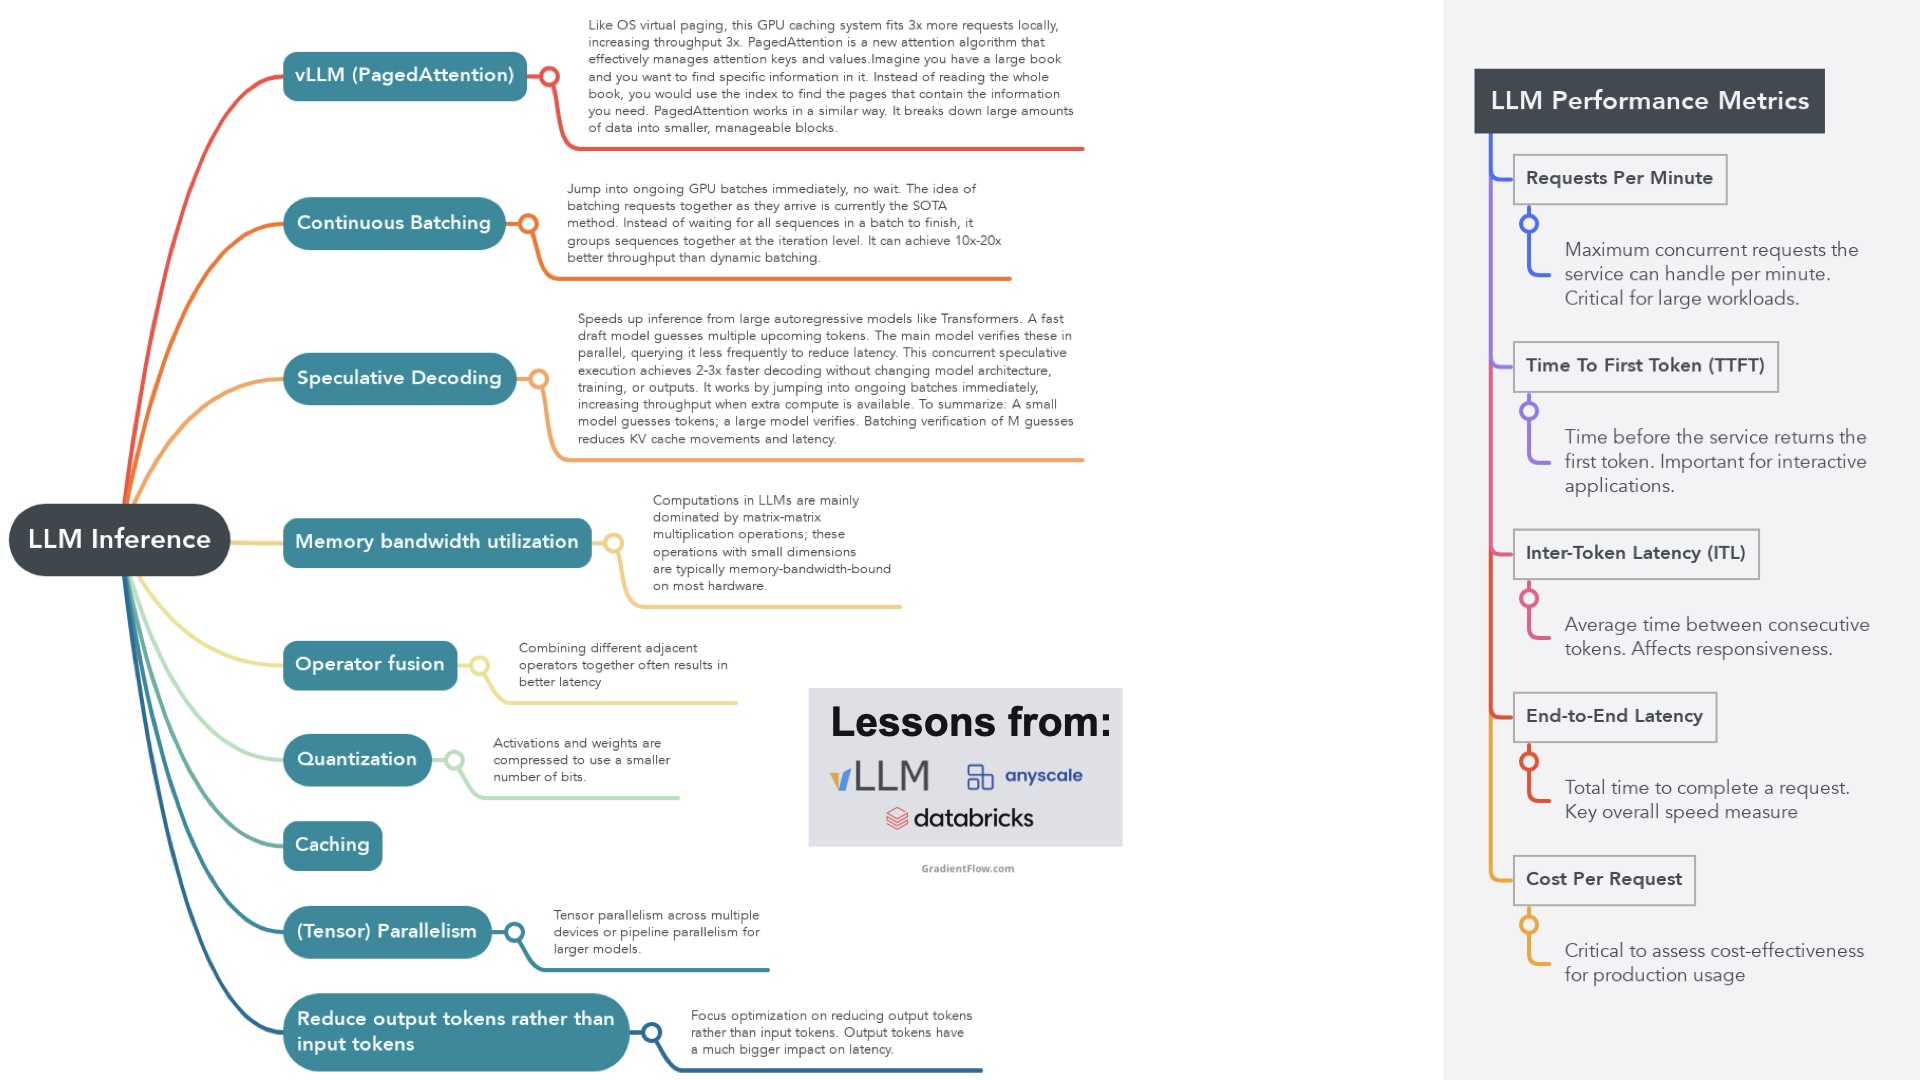
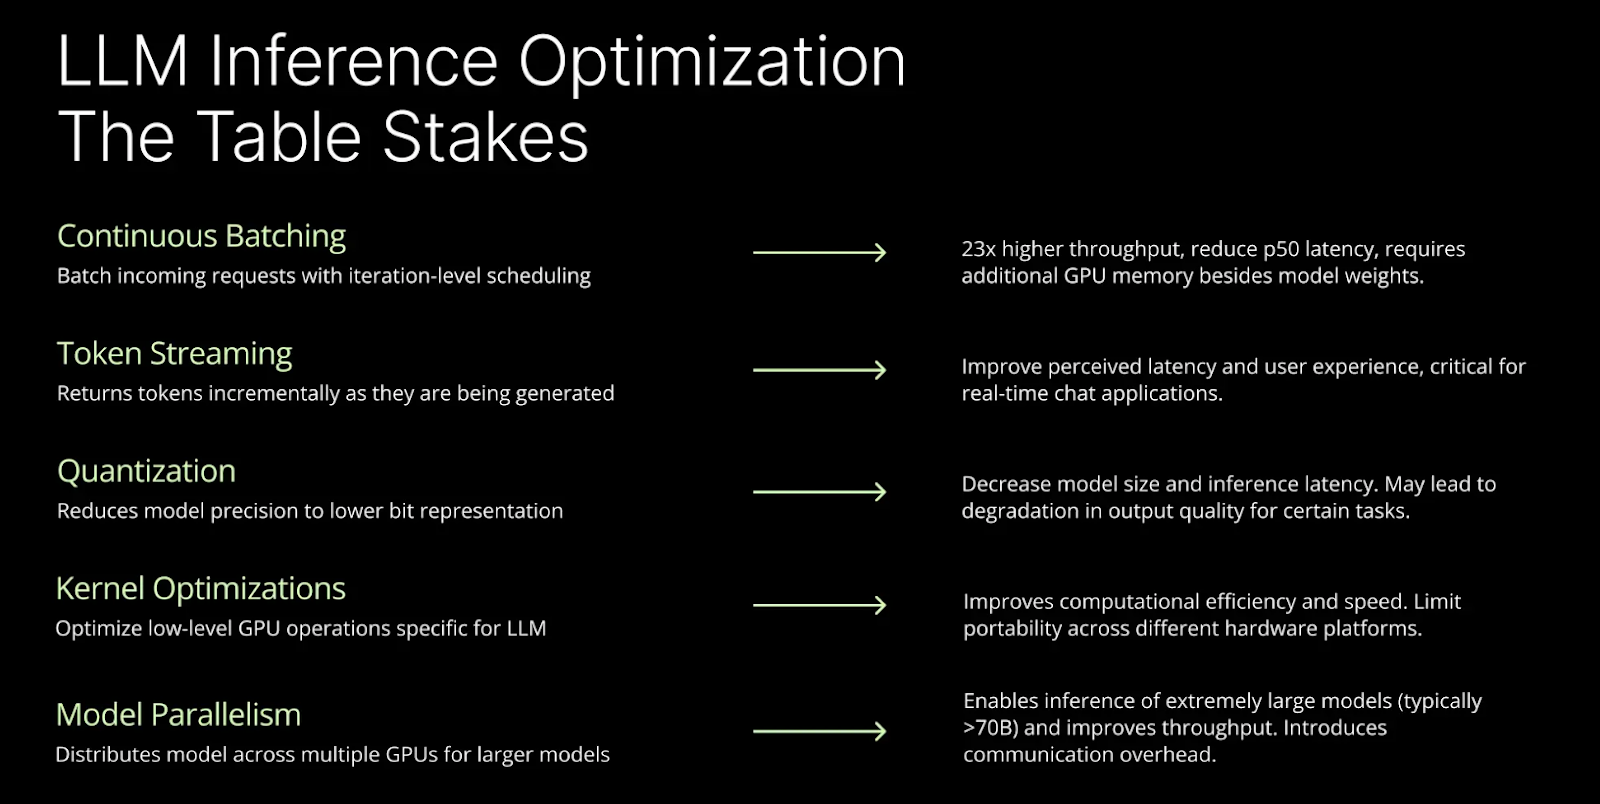
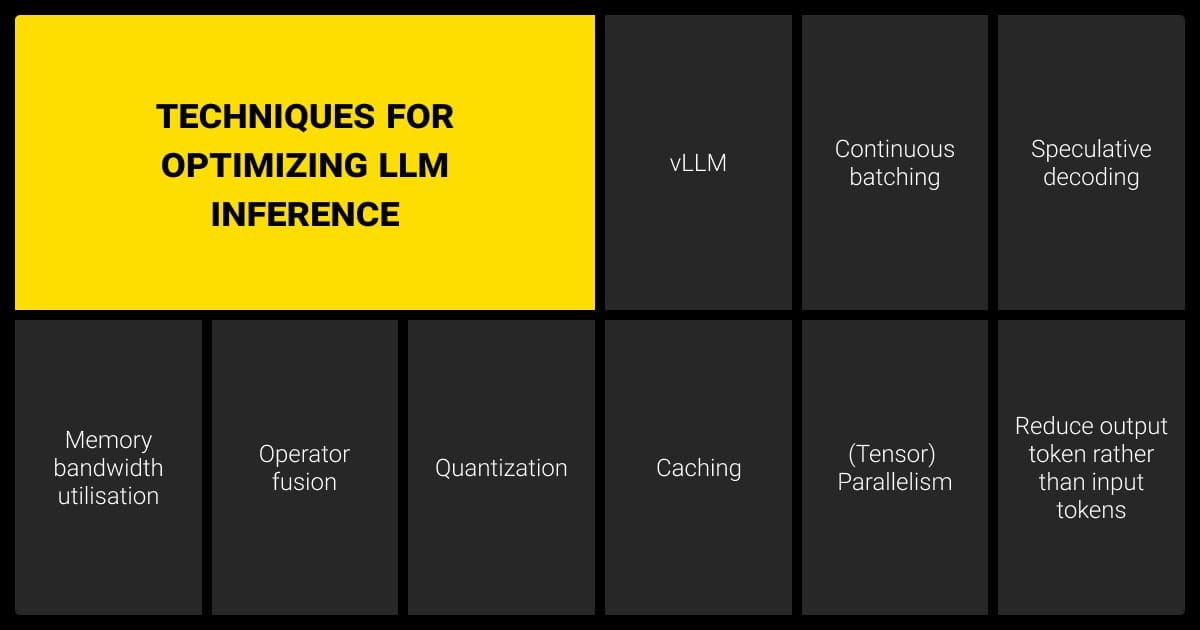
LLM Inference Optimization Overview - From Data to System Architecture ...
LLM Inference - Hw-Sw Optimizations
Can Serverless AI Inference Optimize Model Training? - SlideShare ...
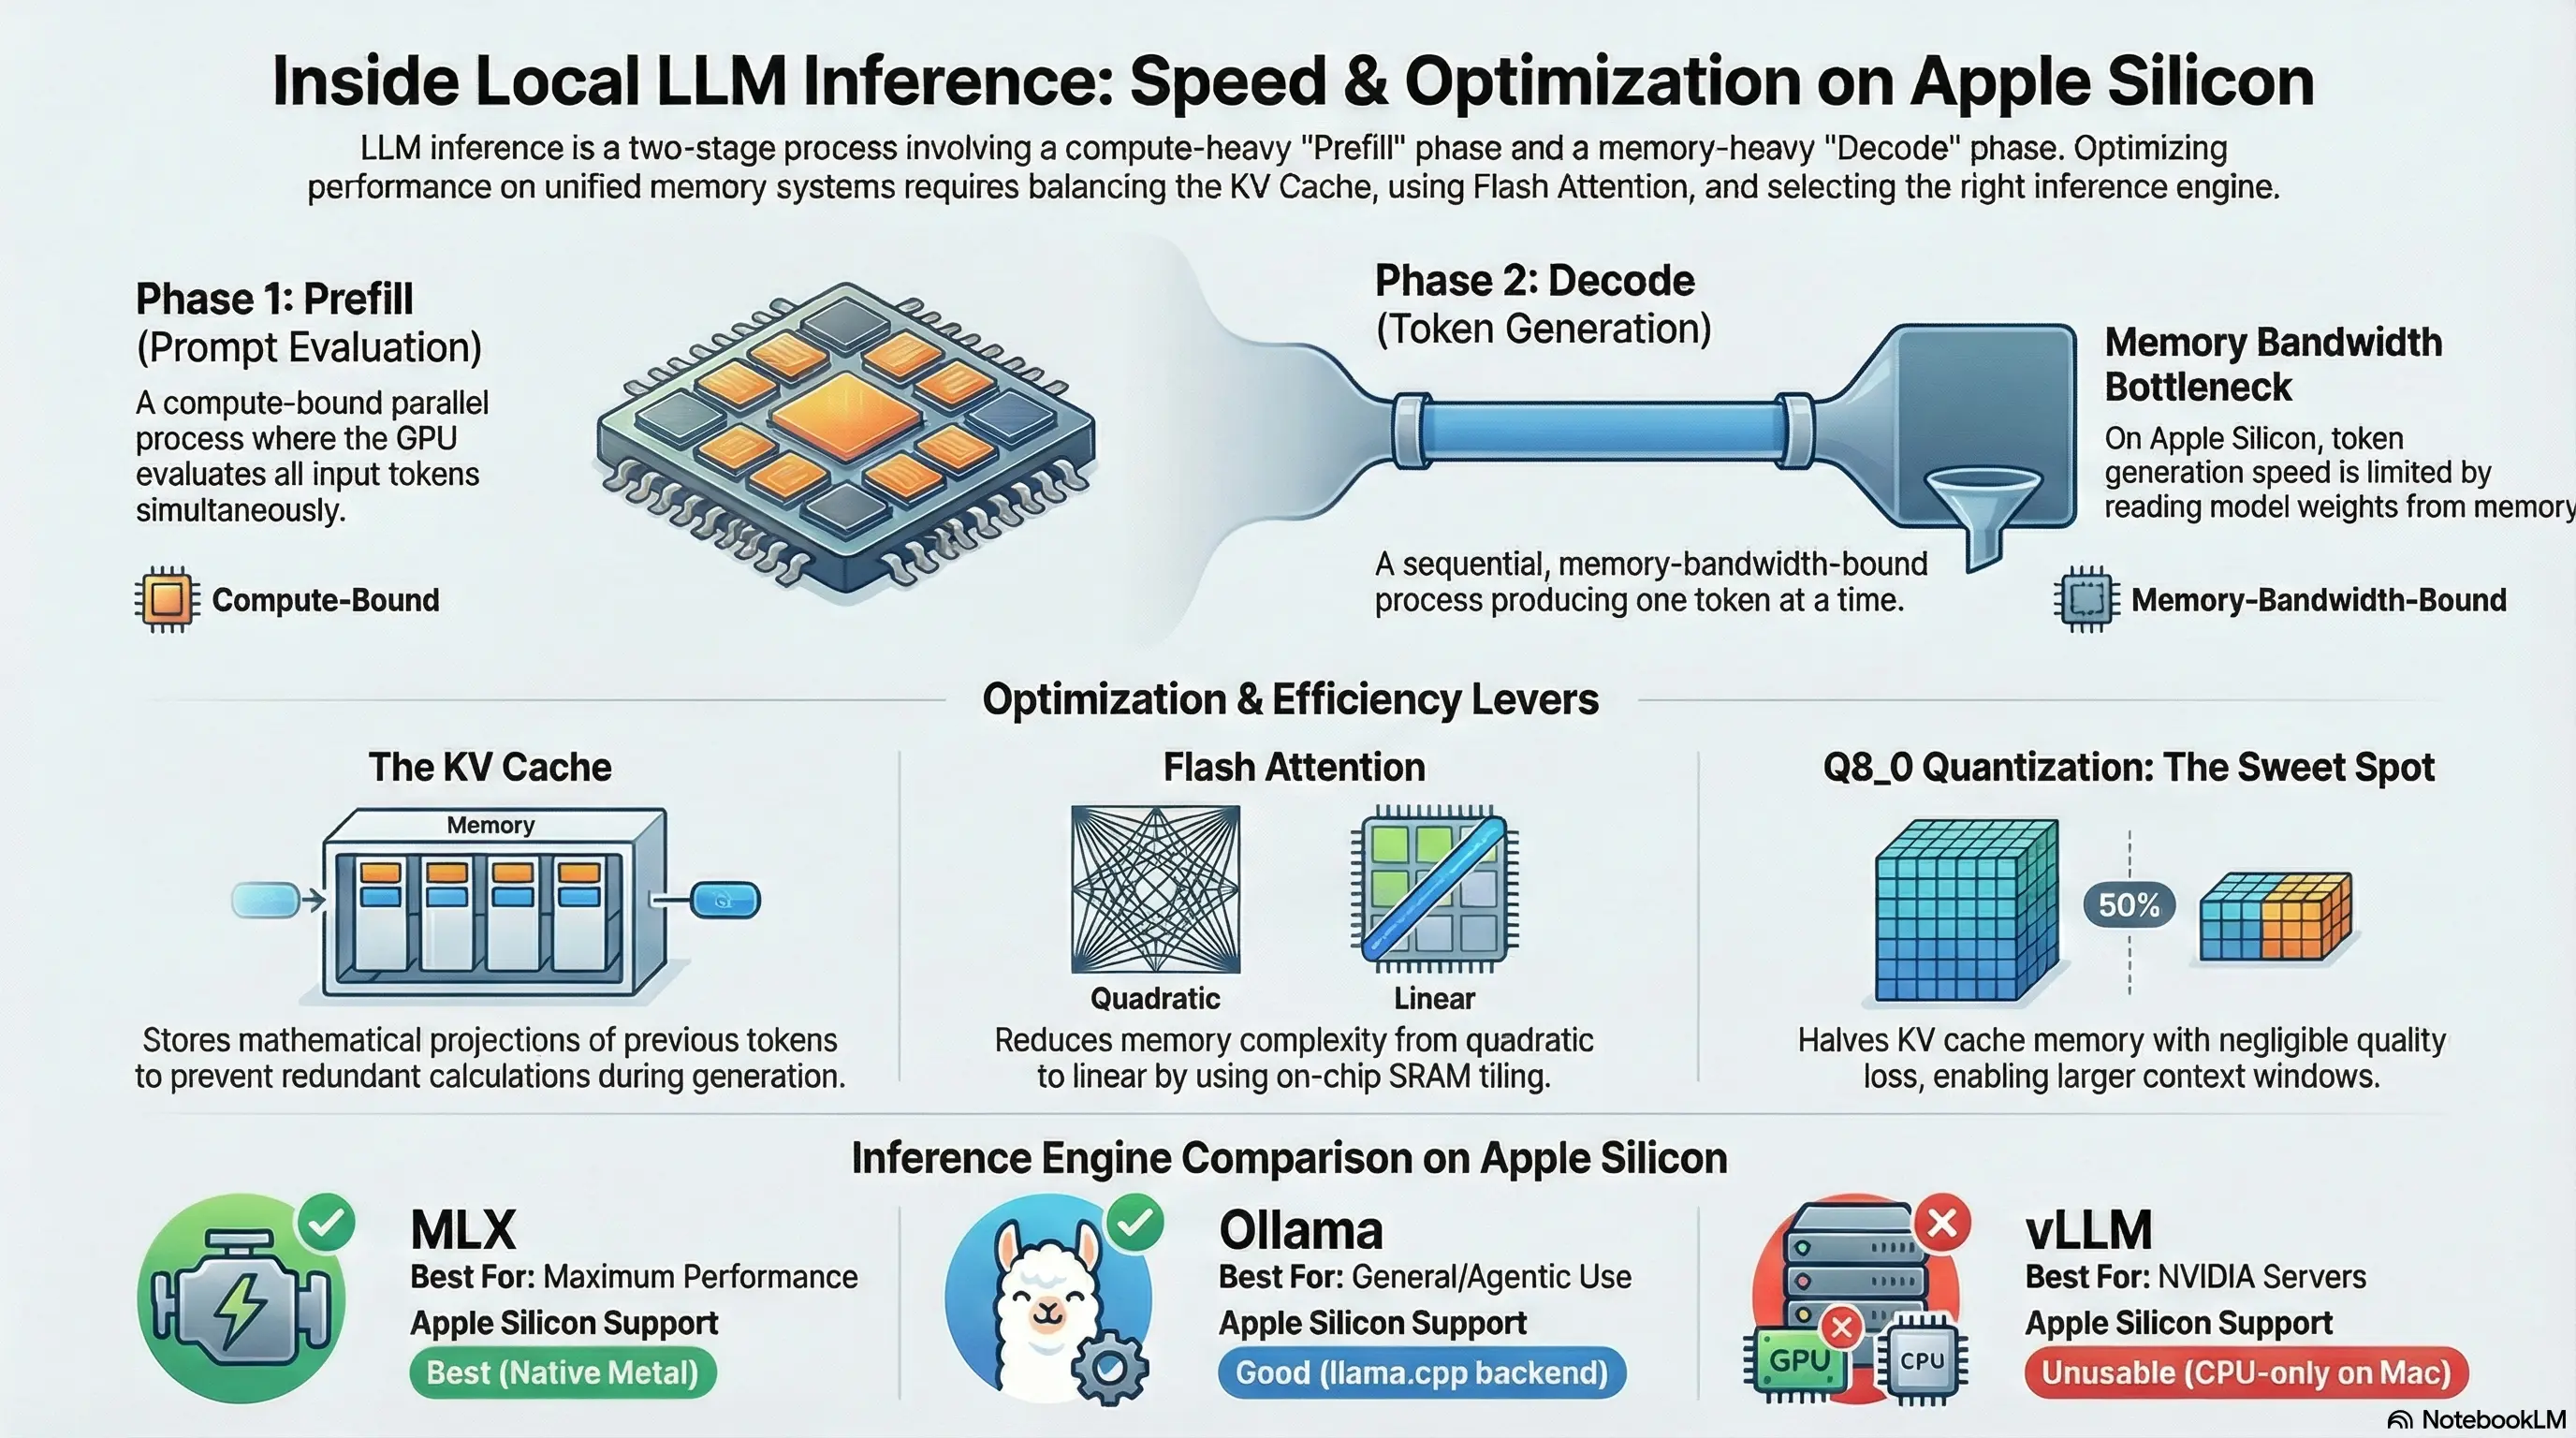
LLM Inference Internals: KV Cache, Flash Attention, and Optimizing for ...
Machine learning inference at scale using AWS serverless – MACHINE LEARNING
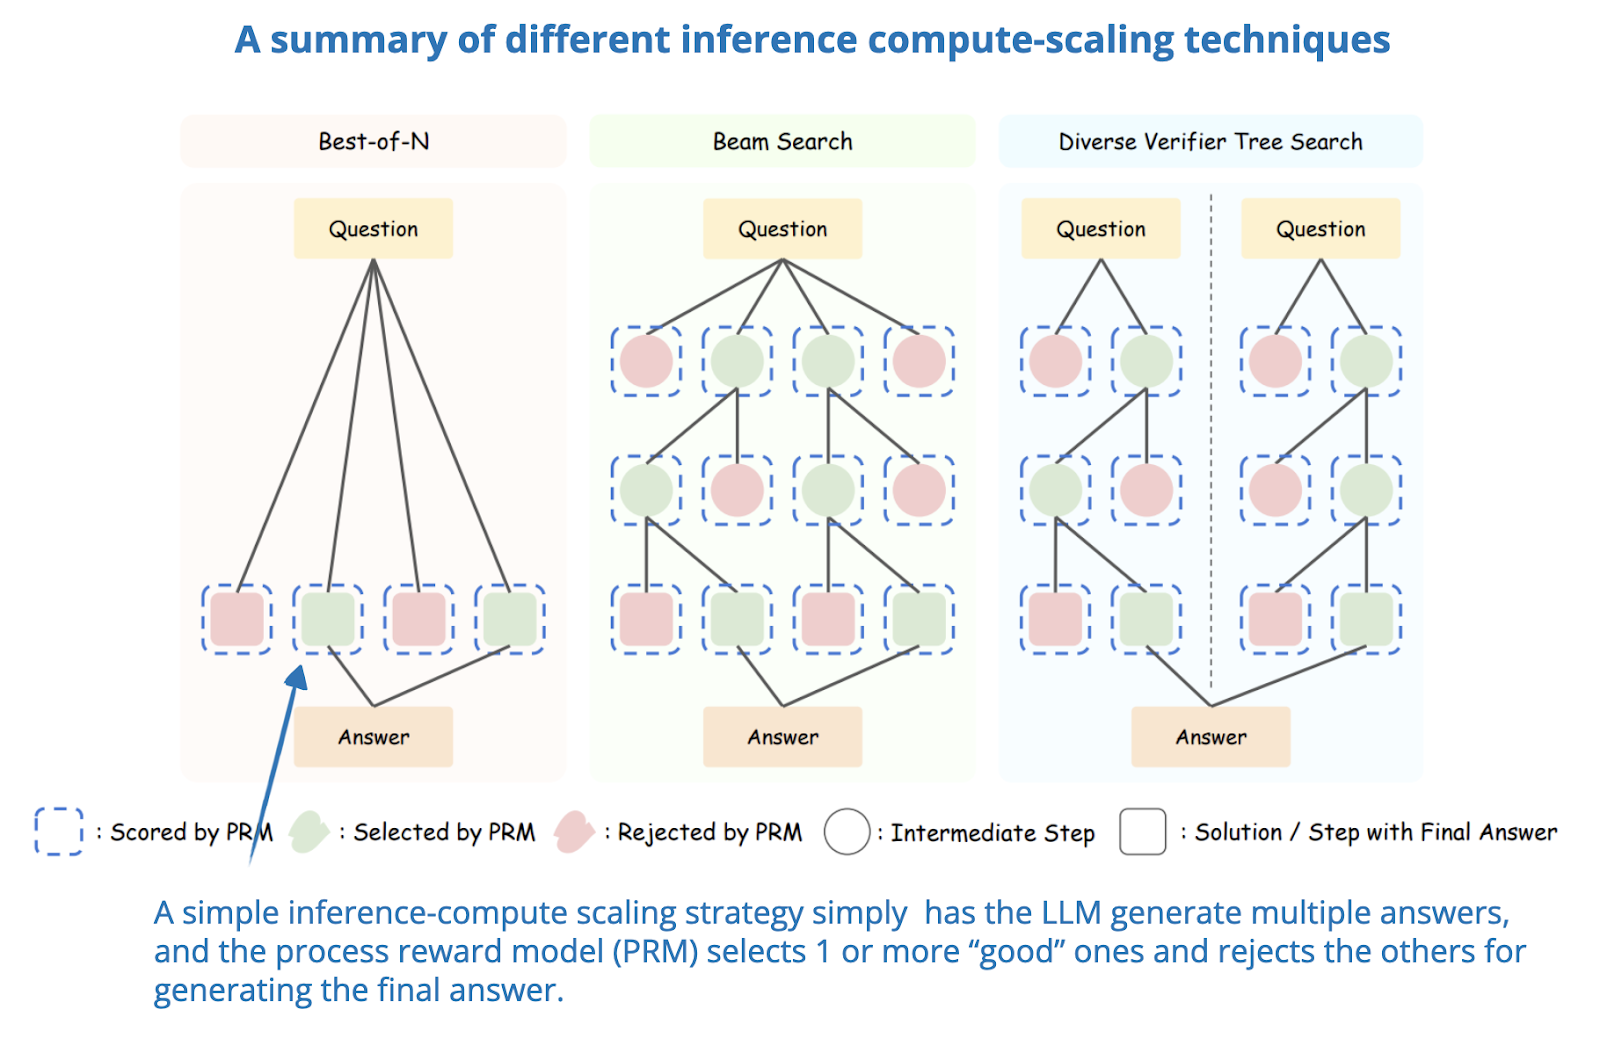
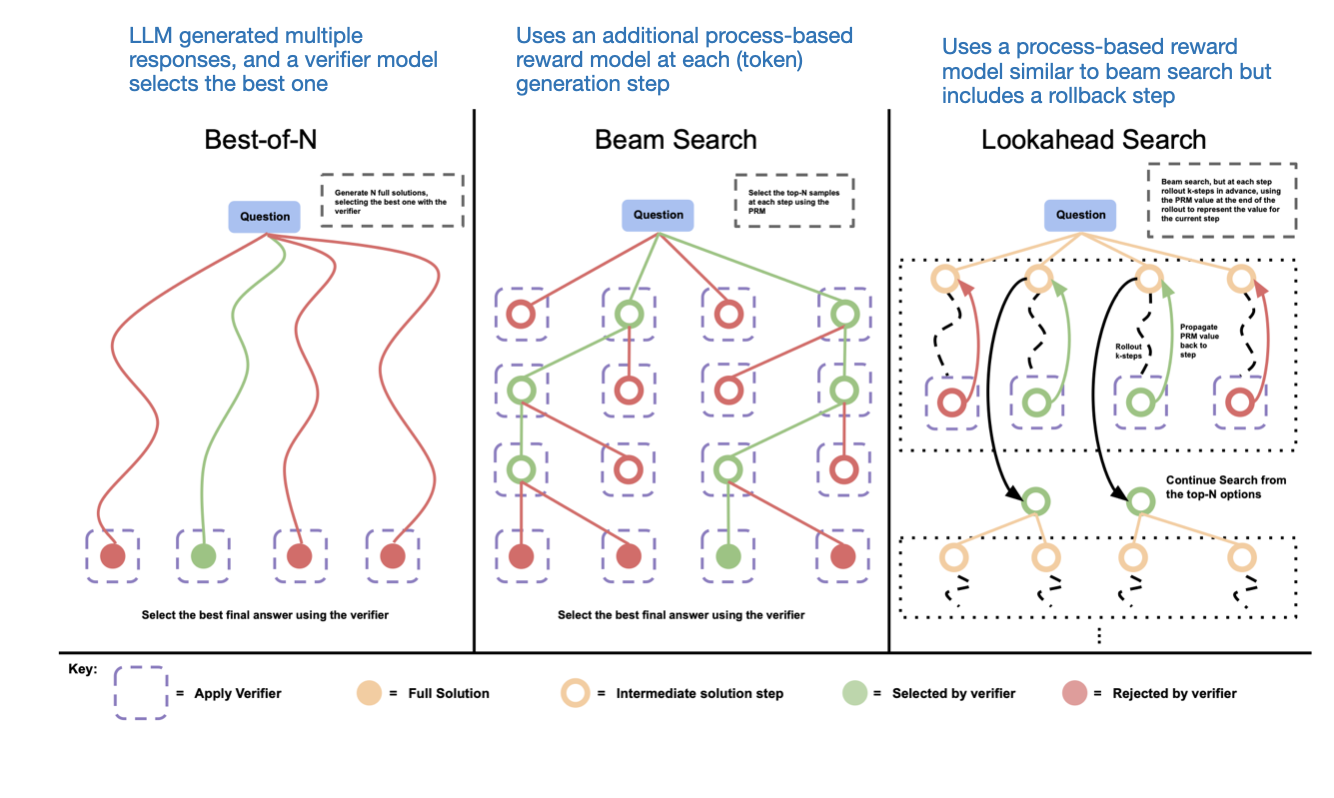
The State of LLM Reasoning Model Inference
Figure 4 from Optimizing Inference Serving on Serverless Platforms ...
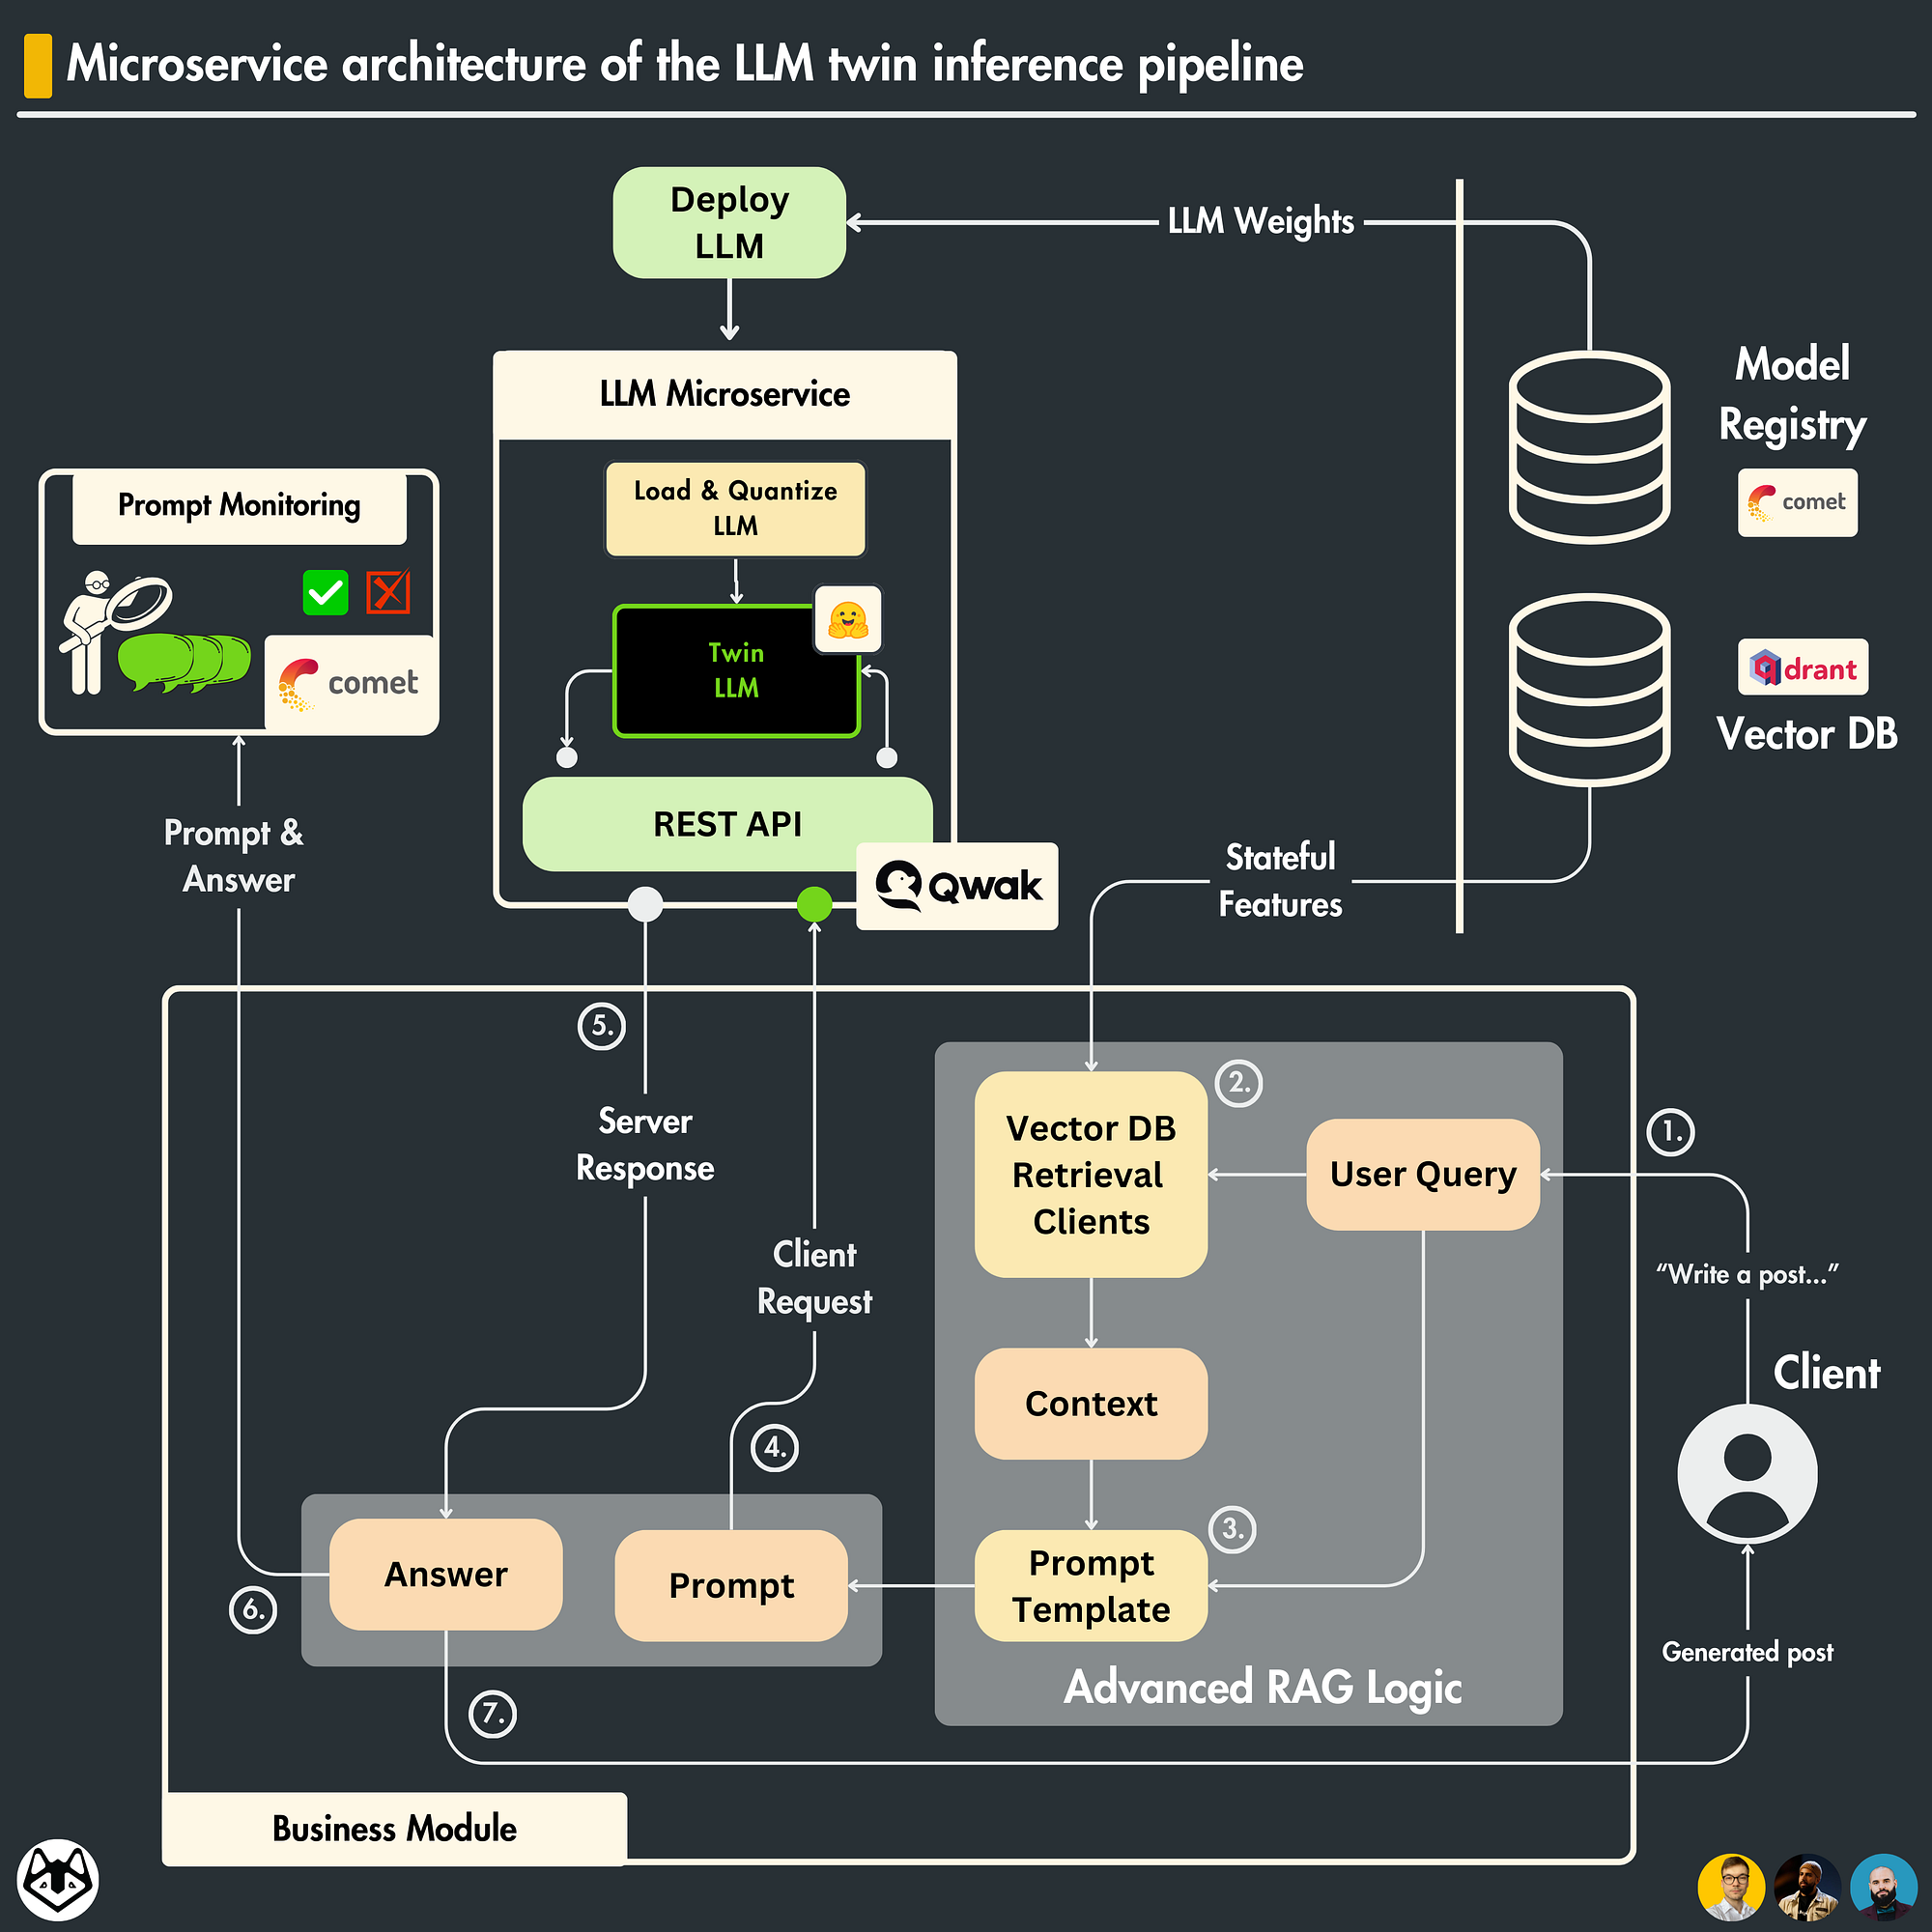
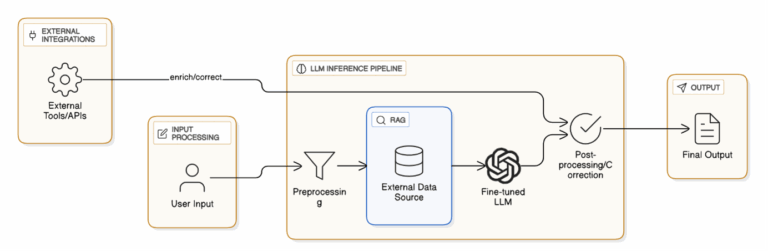
The LLM Inference Pipeline: From Text to Embeddings and the Power of RAG
How to Architect Scalable LLM & RAG Inference Pipelines
Serverless vs. Dedicated AI Inference | Choosing the Right Friendli ...
What serverless inference options are available on Cyfuture?
Serverless Inference là gì? Cách triển khai AI không cần server
[论文评述] A First Look at Bugs in LLM Inference Engines
Deploying Serverless AI Inference on AMD GPU Clusters — ROCm Blogs
A Practical Guide to LLM Inference at Scale
Serverless Inference Providers Compared [2025] | by Arseny Yankovski ...
Fireworks AI Alternatives 2026: Best Replacements for Serverless LLM ...
How to Scale LLM Inference - by Damien Benveniste
Illustration of the proposed method. (a) LLM inference comprises two ...
Conference Talks Talk: Serverless Machine Learning Inference with ...
Serverless LLM Scheduling with QStash and OpenRouter | Upstash Blog
Inference Platform: The Missing Layer in On-Prem LLM Deployments
Taming the LLM Using AI Inference - Architecture & Governance Magazine
LLM Inference Servers Compared - vLLM, SGLang, llama.cpp and Ollama ...
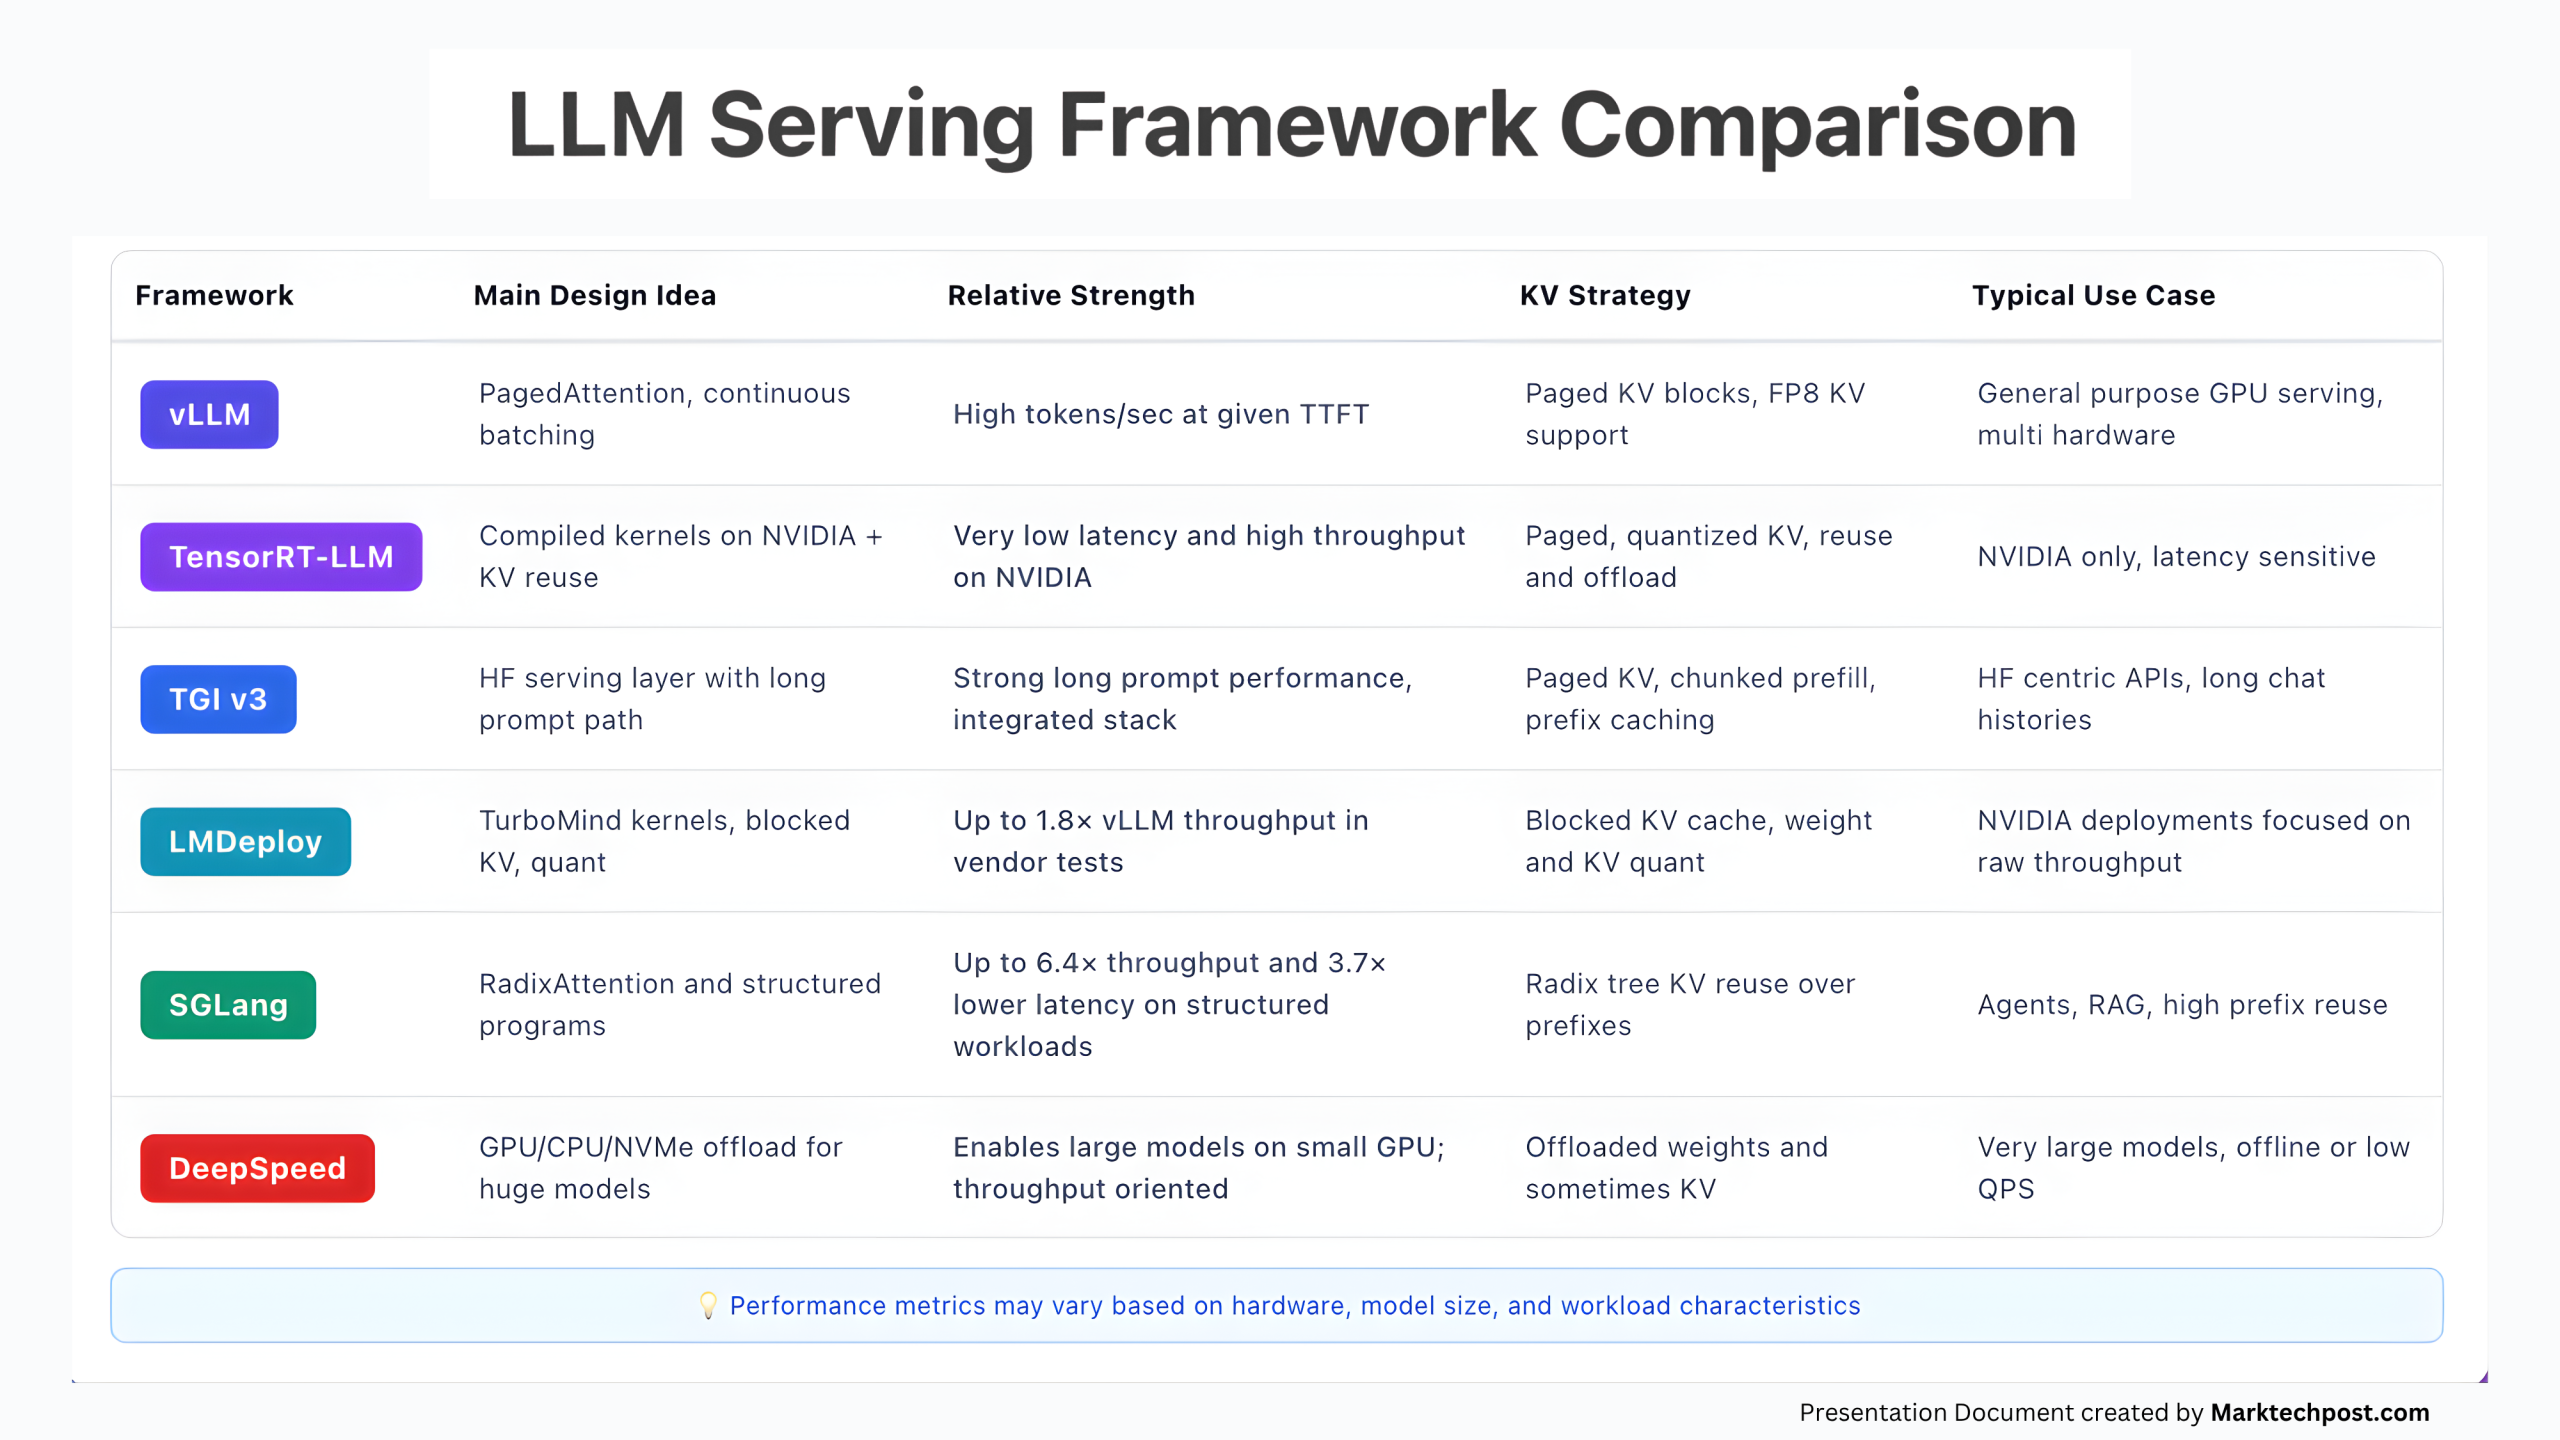
Comparing the Top 6 Inference Runtimes for LLM Serving in 2025 ...
Serverless Inference with the DigitalOcean Gradient Platform | DigitalOcean
Serverless Inference | Together AI
How to Build LLM Inference Pipelines for Enterprise Apps
Level Up Your Development: A Beginner’s Guide to Serverless LLM Apps ...
Serverless Inference For LLMs Market Research Report 2033
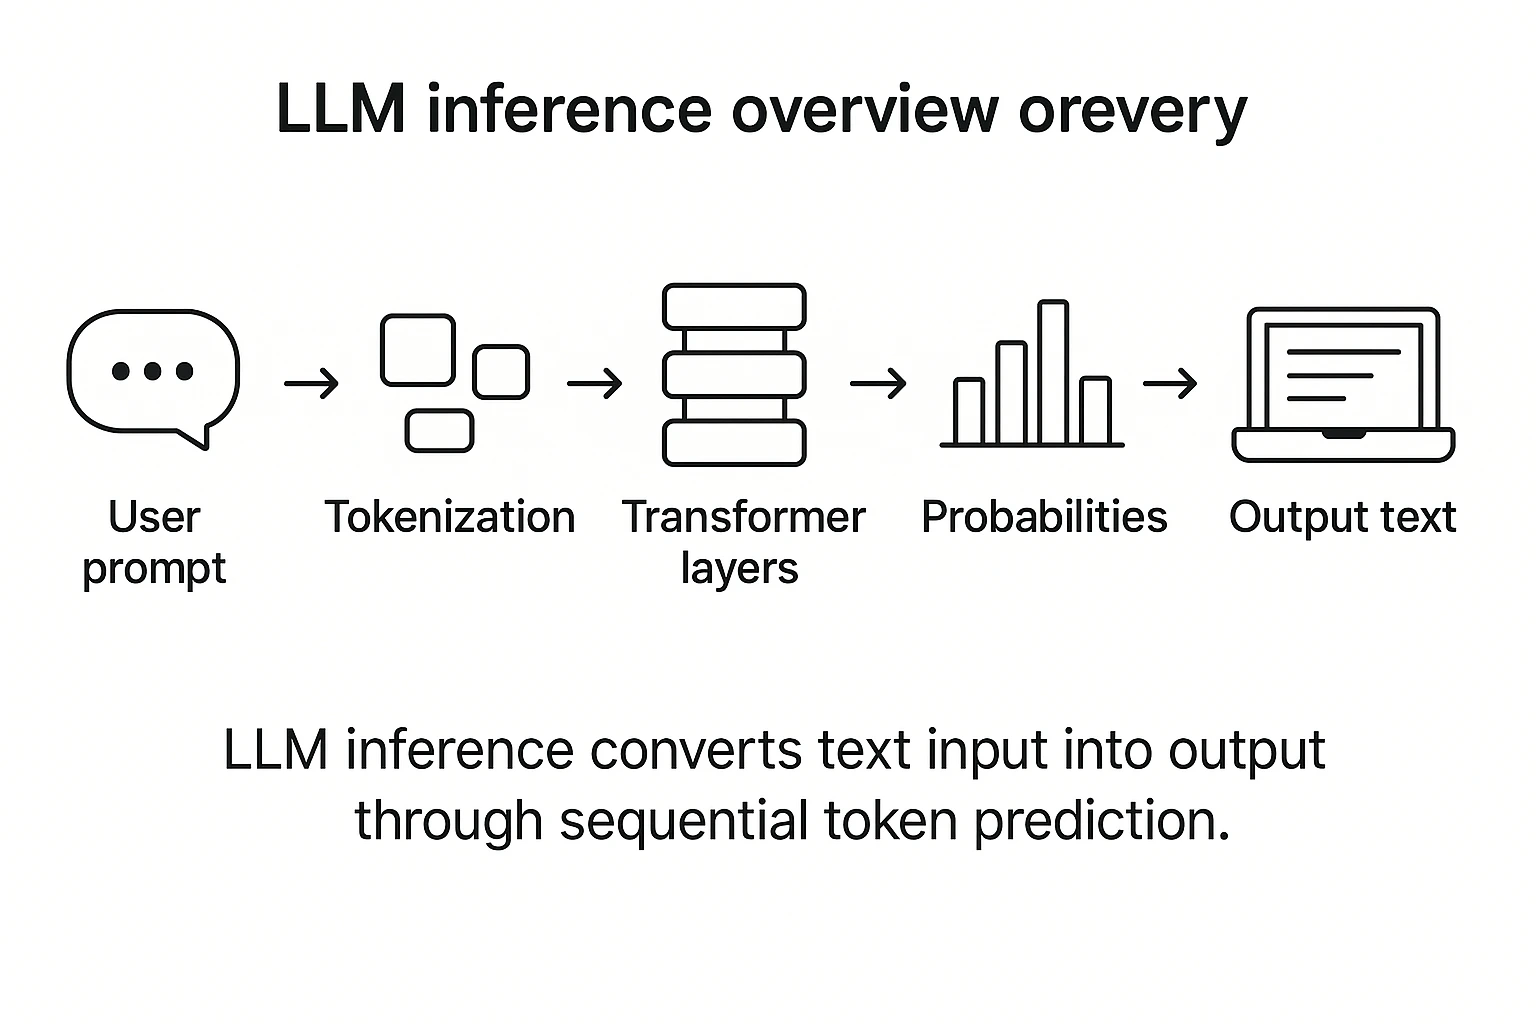
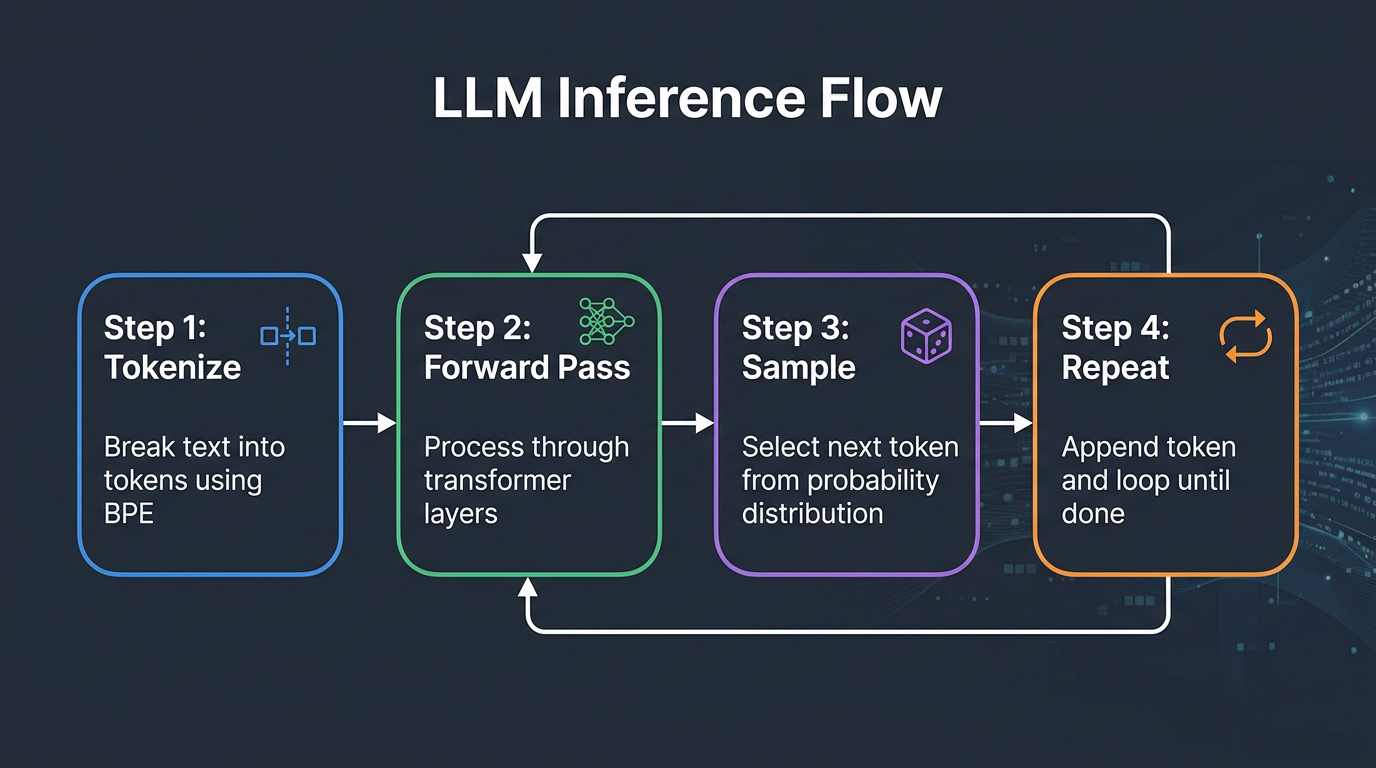
LLM Inference Explained for Developers — How AI Models Generate Text
ServerlessLLM: Locality-Enhanced Serverless Inference for Large ...
LLM Inference Basics — From Prompt to Response | tutorialQ
Serverless LLM Hosting - Featherless.ai
Serverless GPUs for AI, Machine Learning (ML) Inference | Inferless
Figure 3 from Optimizing Inference Serving on Serverless Platforms ...
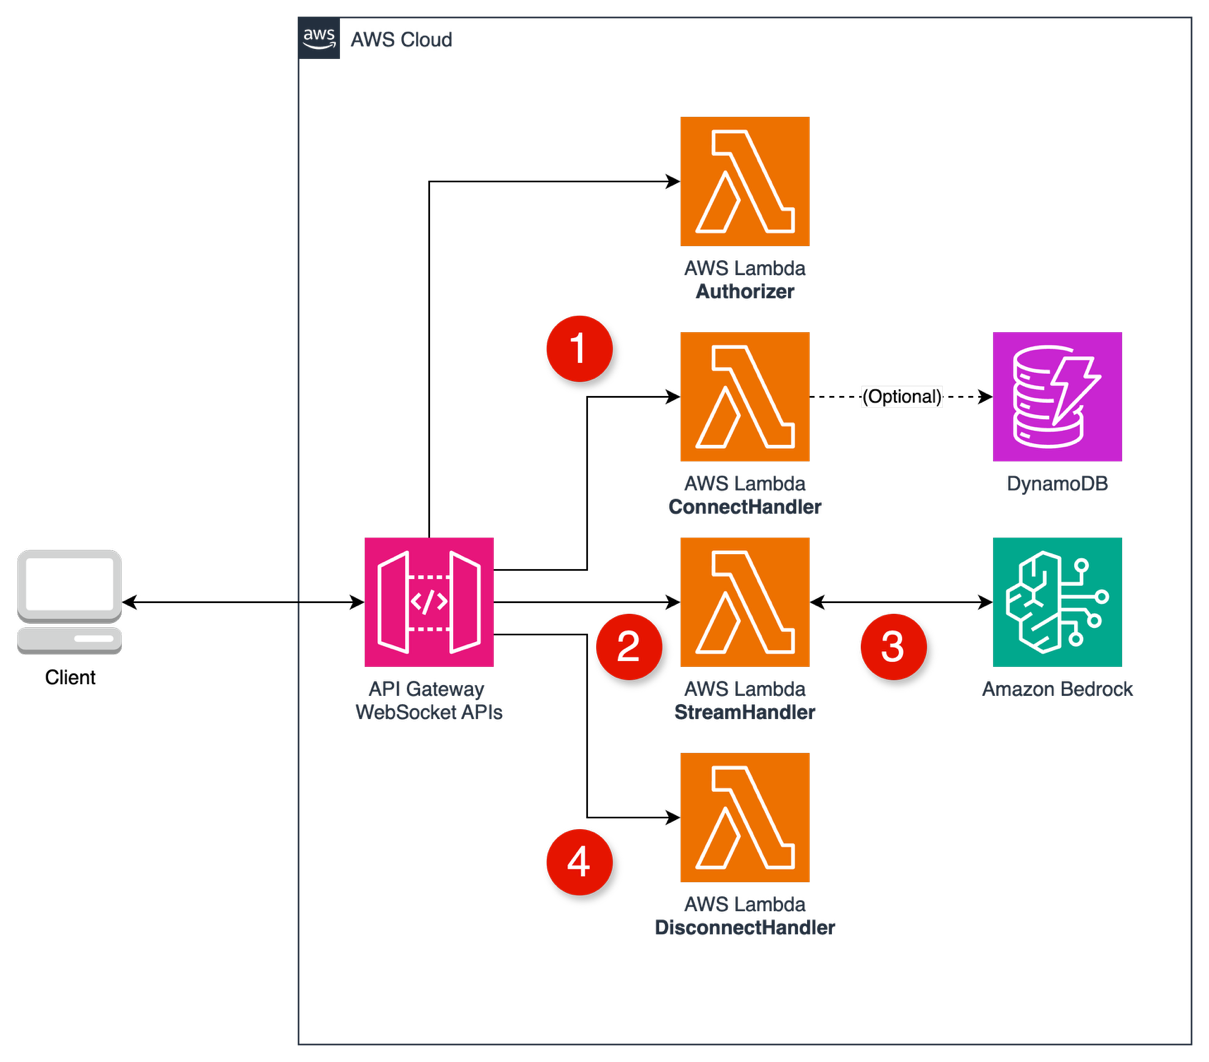
Serverless strategies for streaming LLM responses - Global Intelligence ...
LLM Inference Hardware: Emerging from Nvidia's Shadow
Deploy a serverless ML inference endpoint of large language models ...
Introducing the first purely serverless solution for fine-tuned LLMs ...
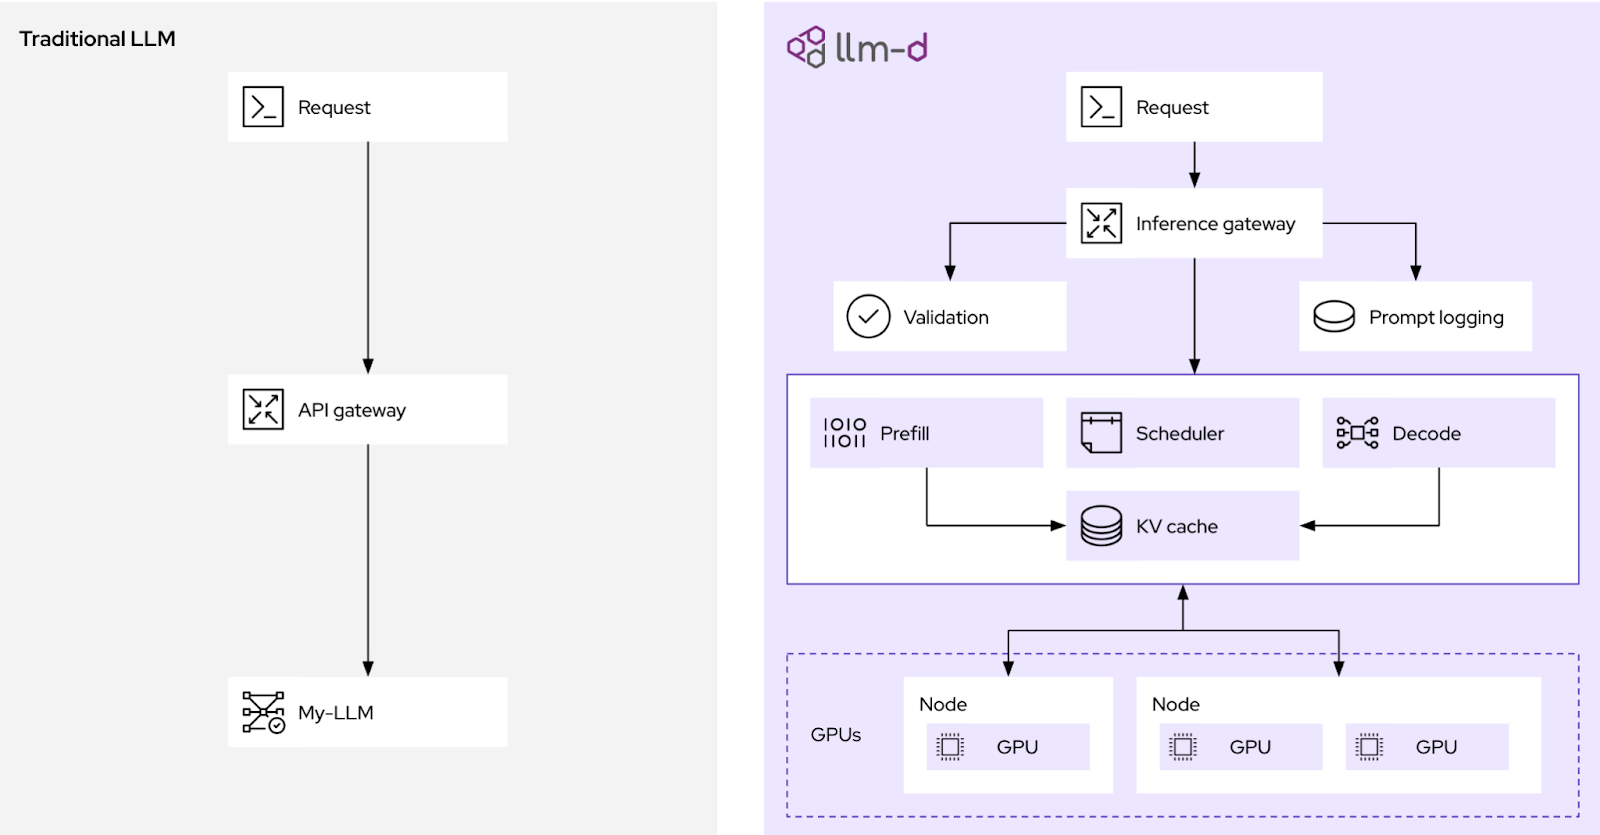
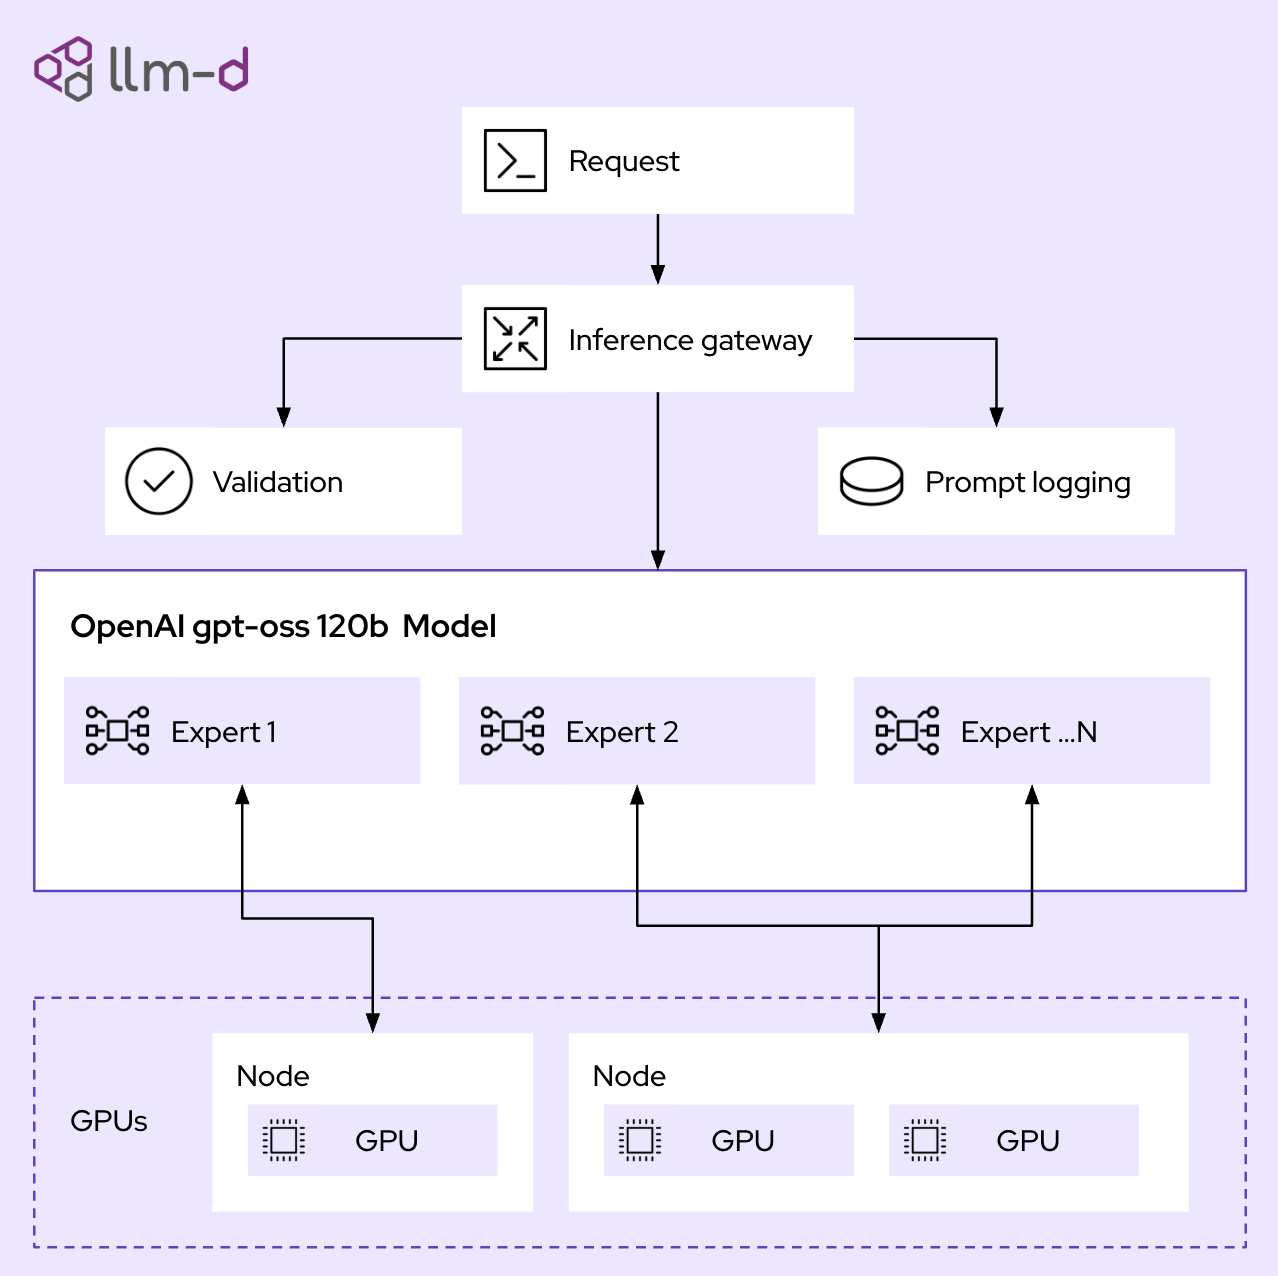
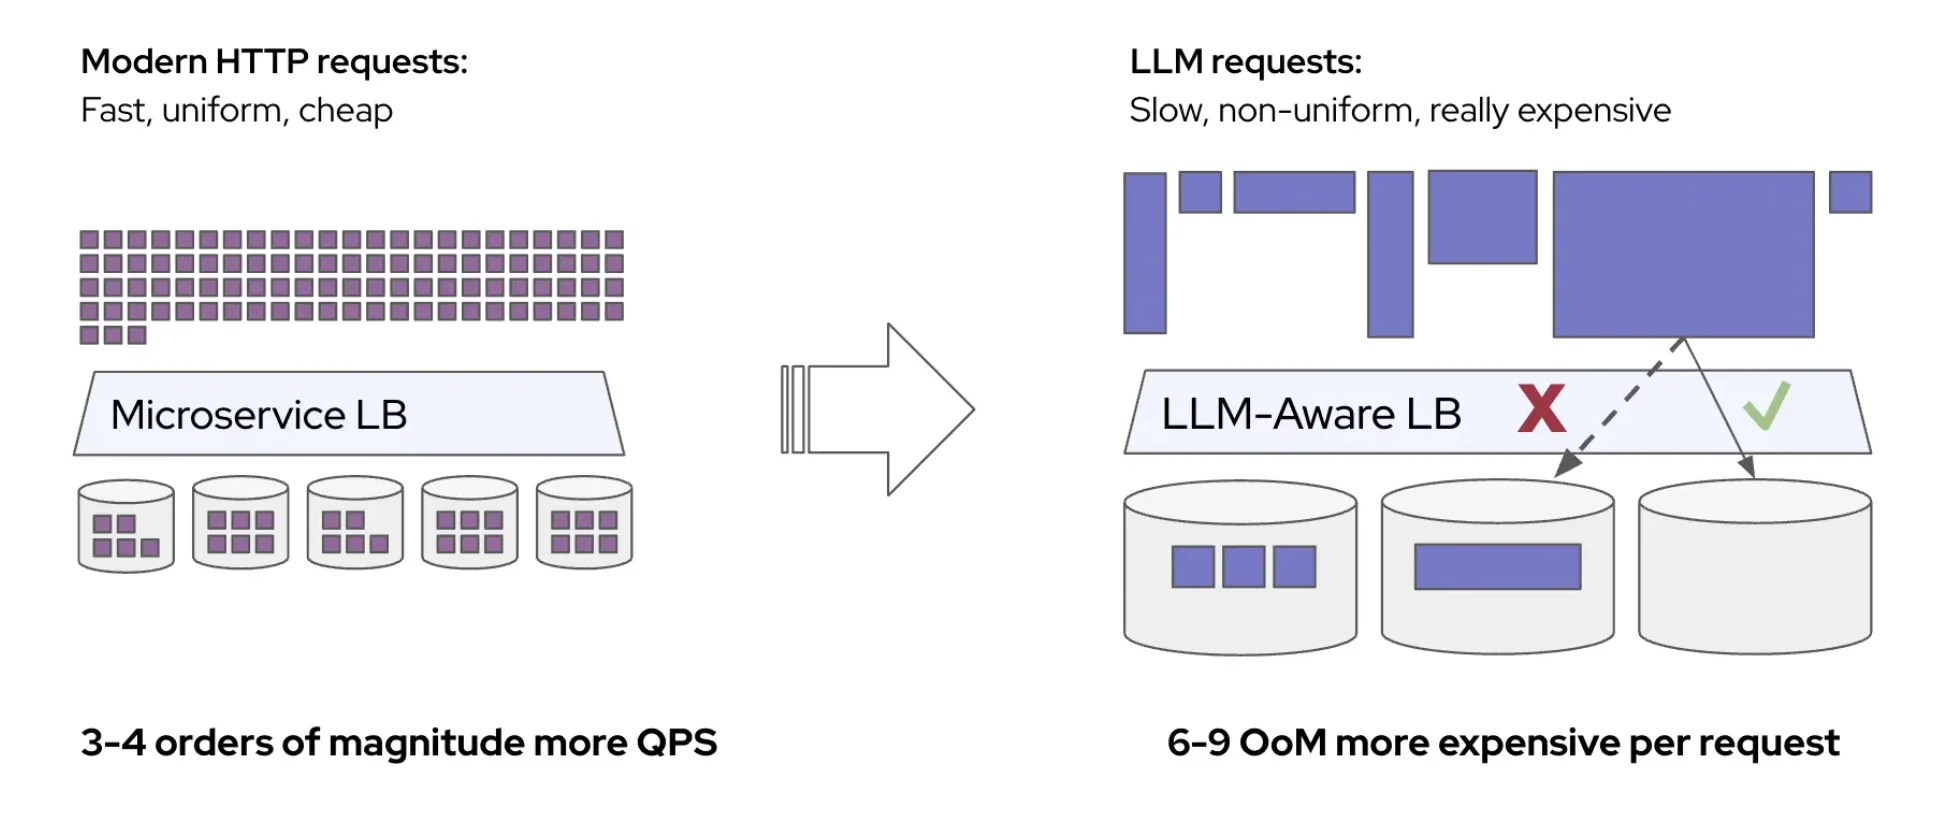
Introduction to distributed inference with llm-d | Red Hat Developer
Optimizing AI Performance: A Guide to Efficient LLM Deployment
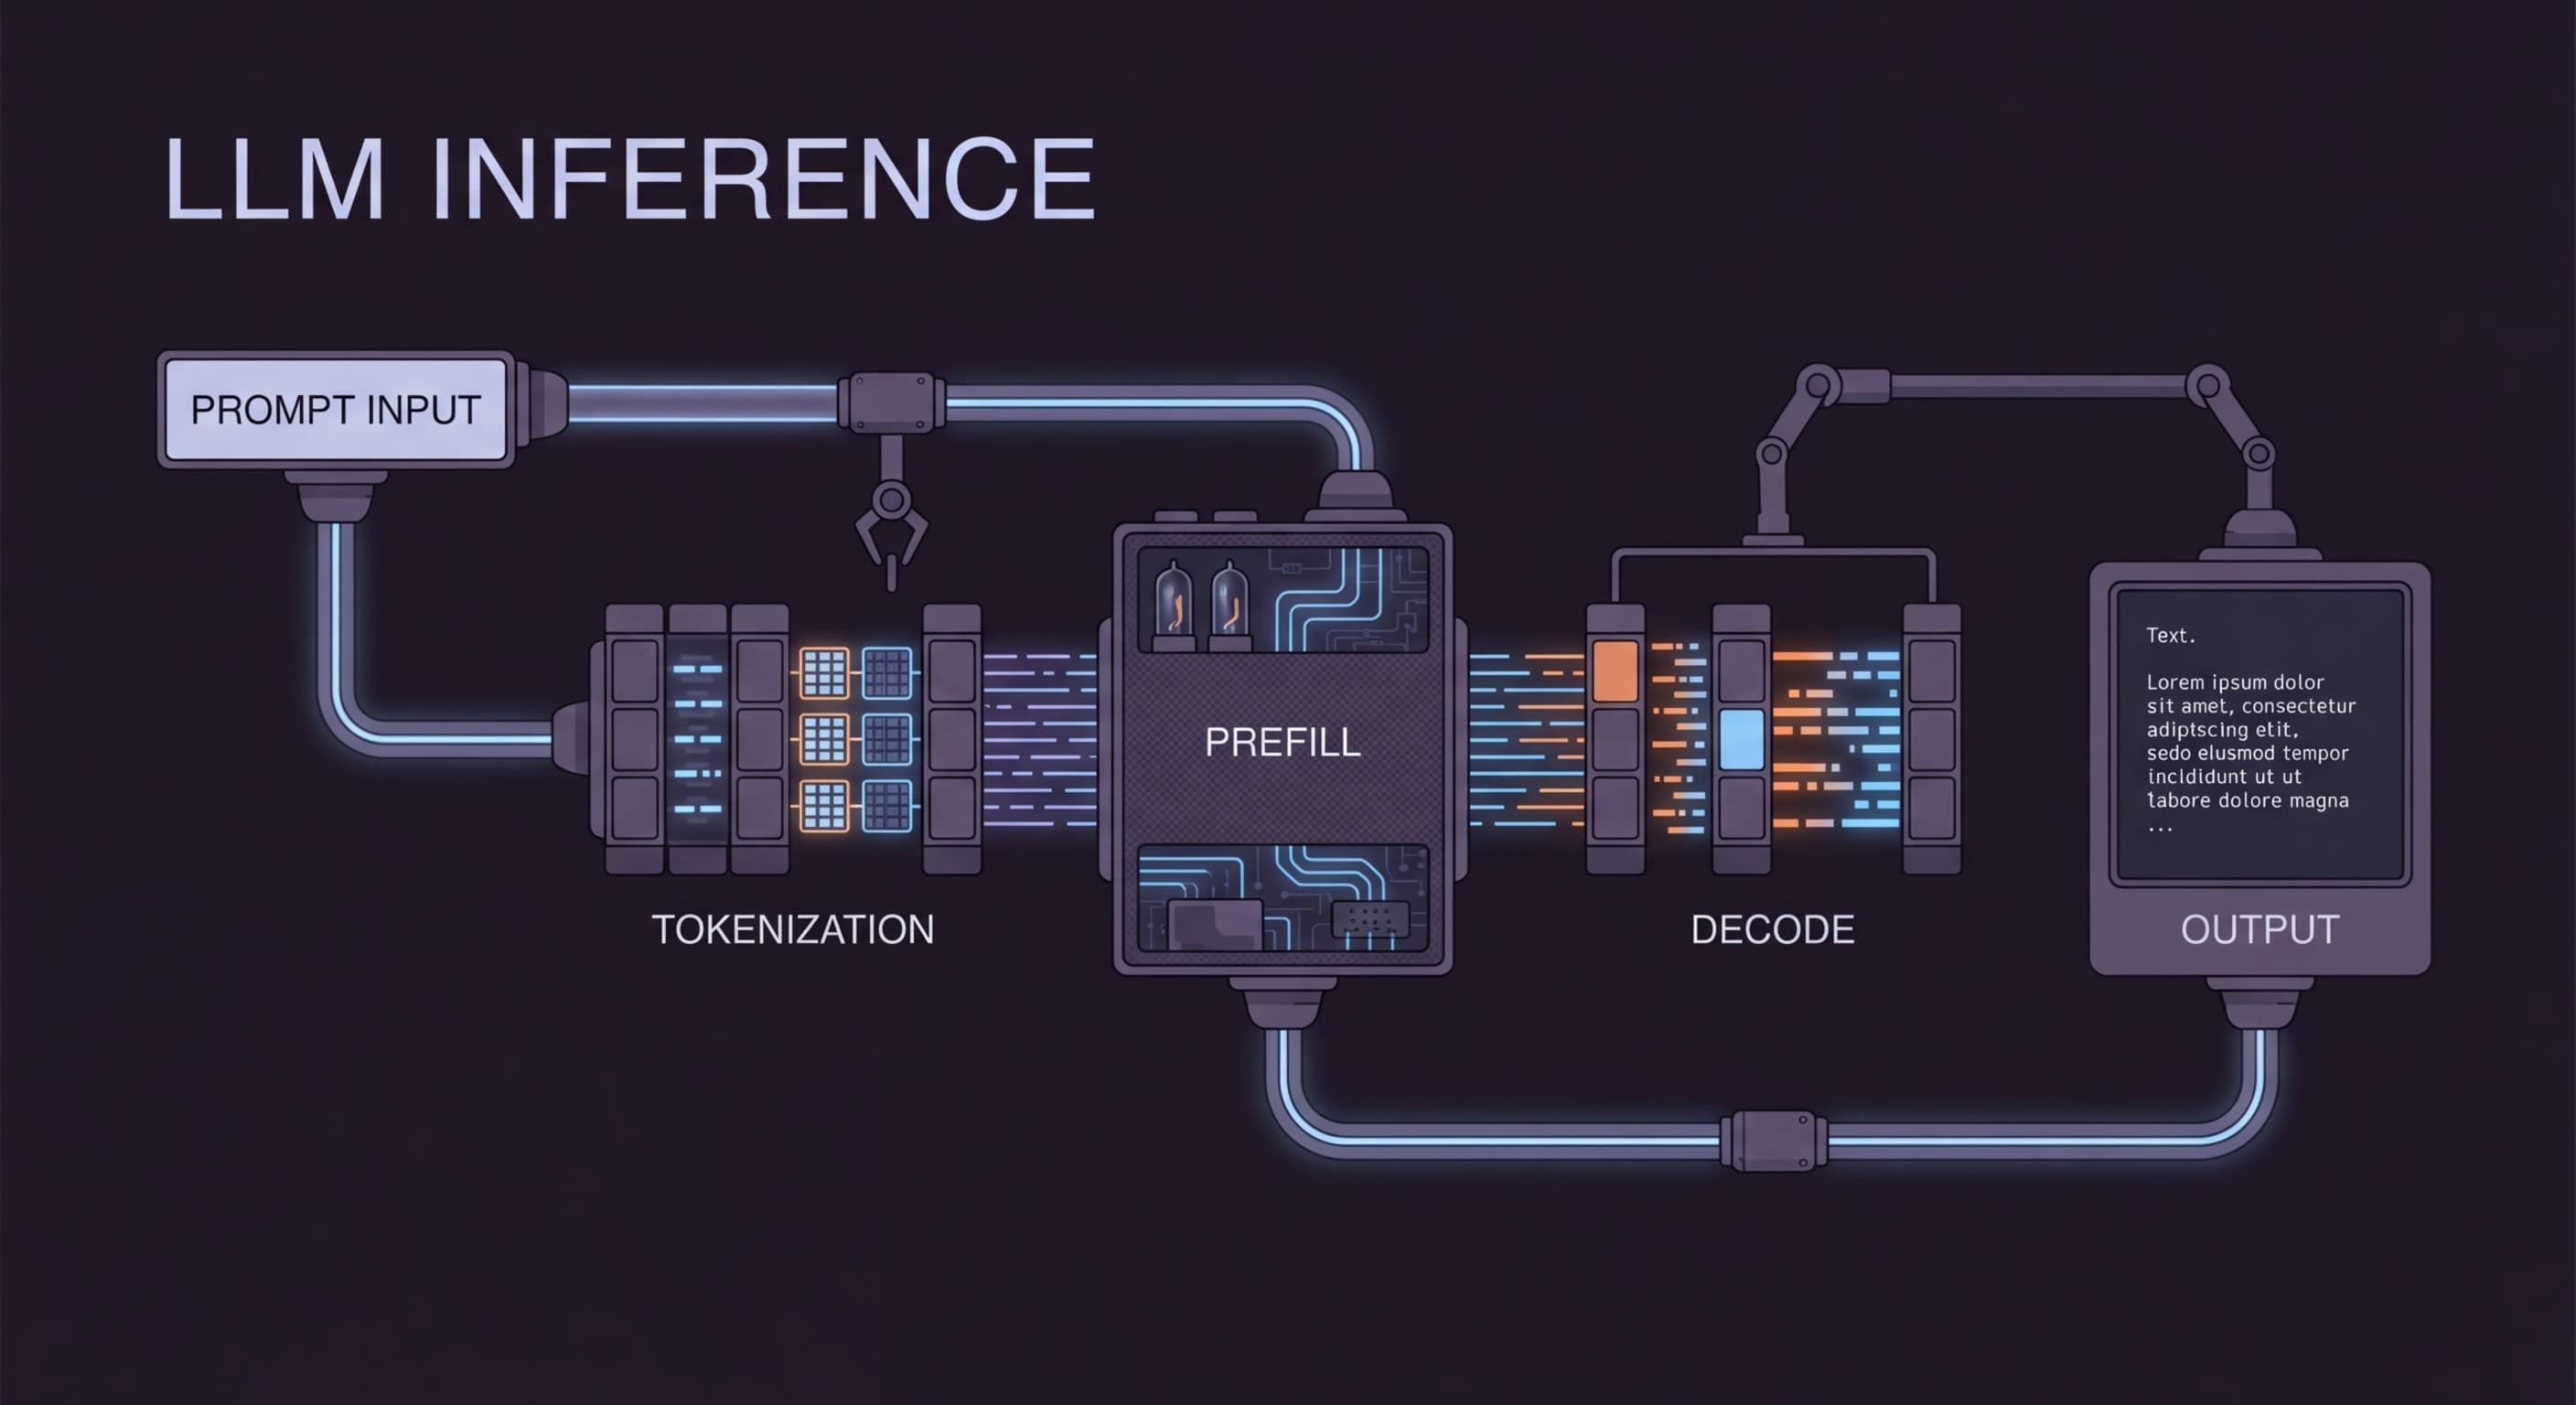
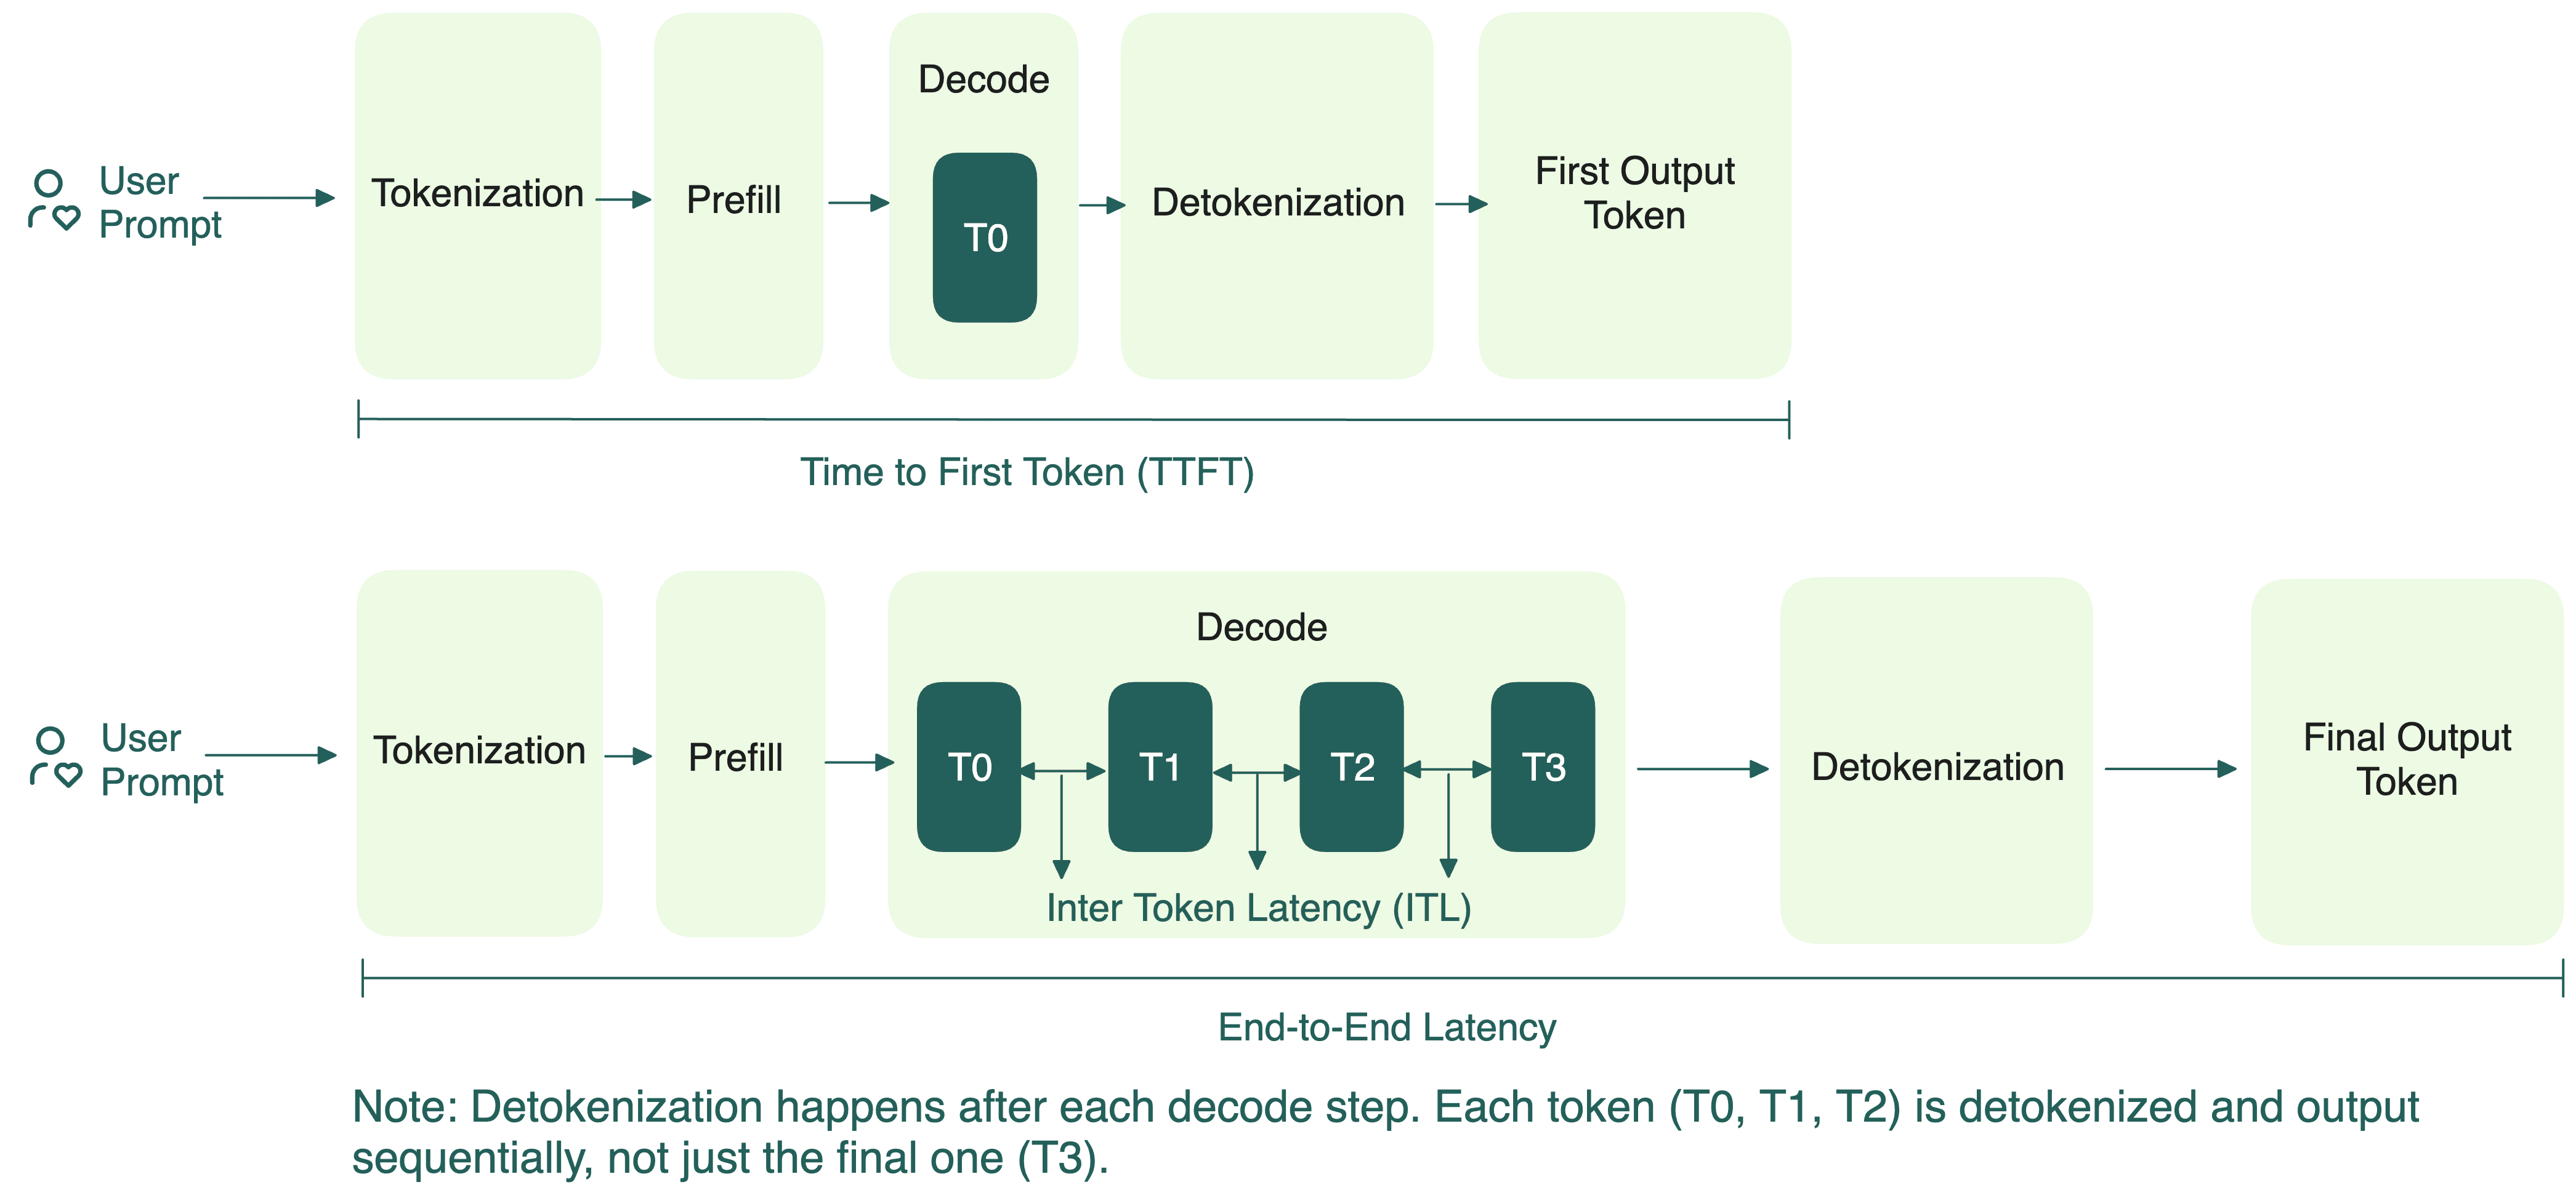
LLM Inference: Prefill, Decode, KV Cache & Cost Guide (2026) | Morph
What Is LLM Inference? Process, Latency & Examples Explained (2026)
Serverless Land
Figure 1 from INFless: a native serverless system for low-latency, high ...
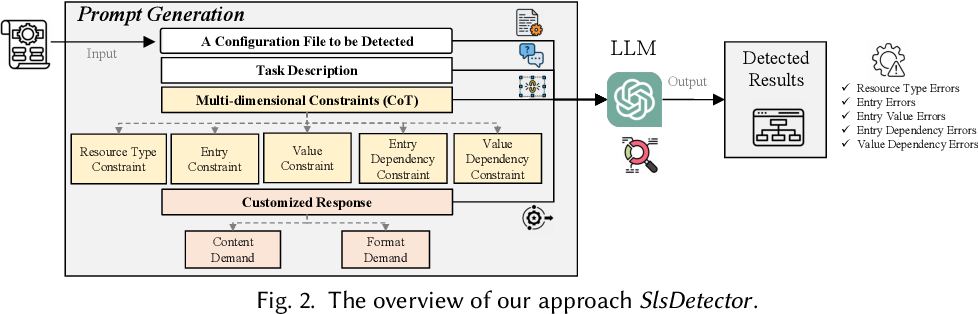
Figure 2 from LLM-Based Misconfiguration Detection for AWS Serverless ...
What is Serverless Inference?
Serverless Inference: A Smarter Way to Scale AI Workloads | The AI Journal
What is a serverless GPU? Benefits, use cases, how it works
Serverles ML; What is Serverless Machine Learning
Serverless Inference: Conquering the 5-Second Cold Start — AI ...
Table 2 from LLM-Based Misconfiguration Detection for AWS Serverless ...
[논문 리뷰] Predictive-LoRA: A Proactive and Fragmentation-Aware Serverless ...
Building Smarter Search: Vector Search on AWS OpenSearch Serverless ...
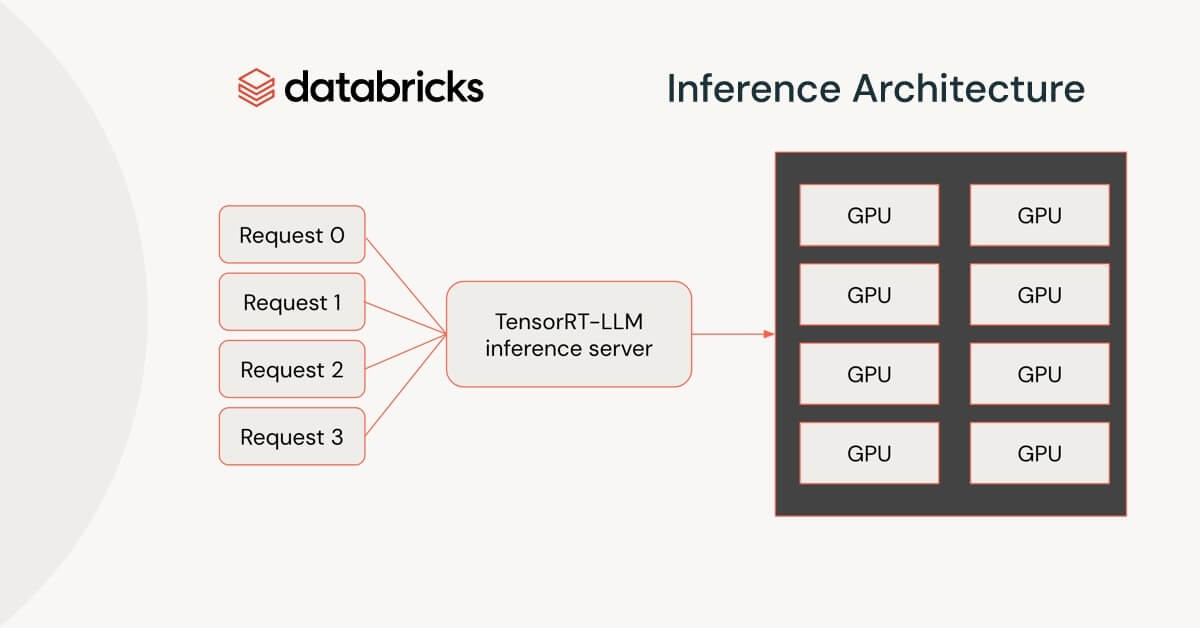
Integrating NVIDIA TensorRT-LLM with the Databricks Inference Stack ...
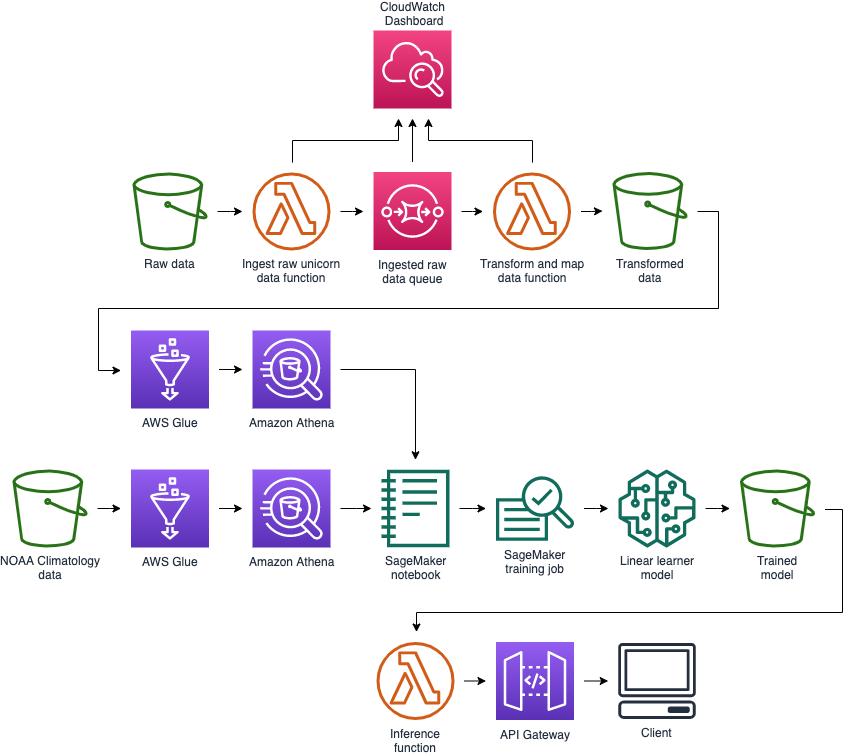
Deploying machine learning models with serverless templates | AWS ...
Serving Inference for LLMs: A Case Study | CoreWeave
Streamlining AI Inference Performance and Deployment with NVIDIA ...
Optimizing Inference Engines: One Api To Rule Them All – AJPII
The Hitchhikers Guide to LLM Agent
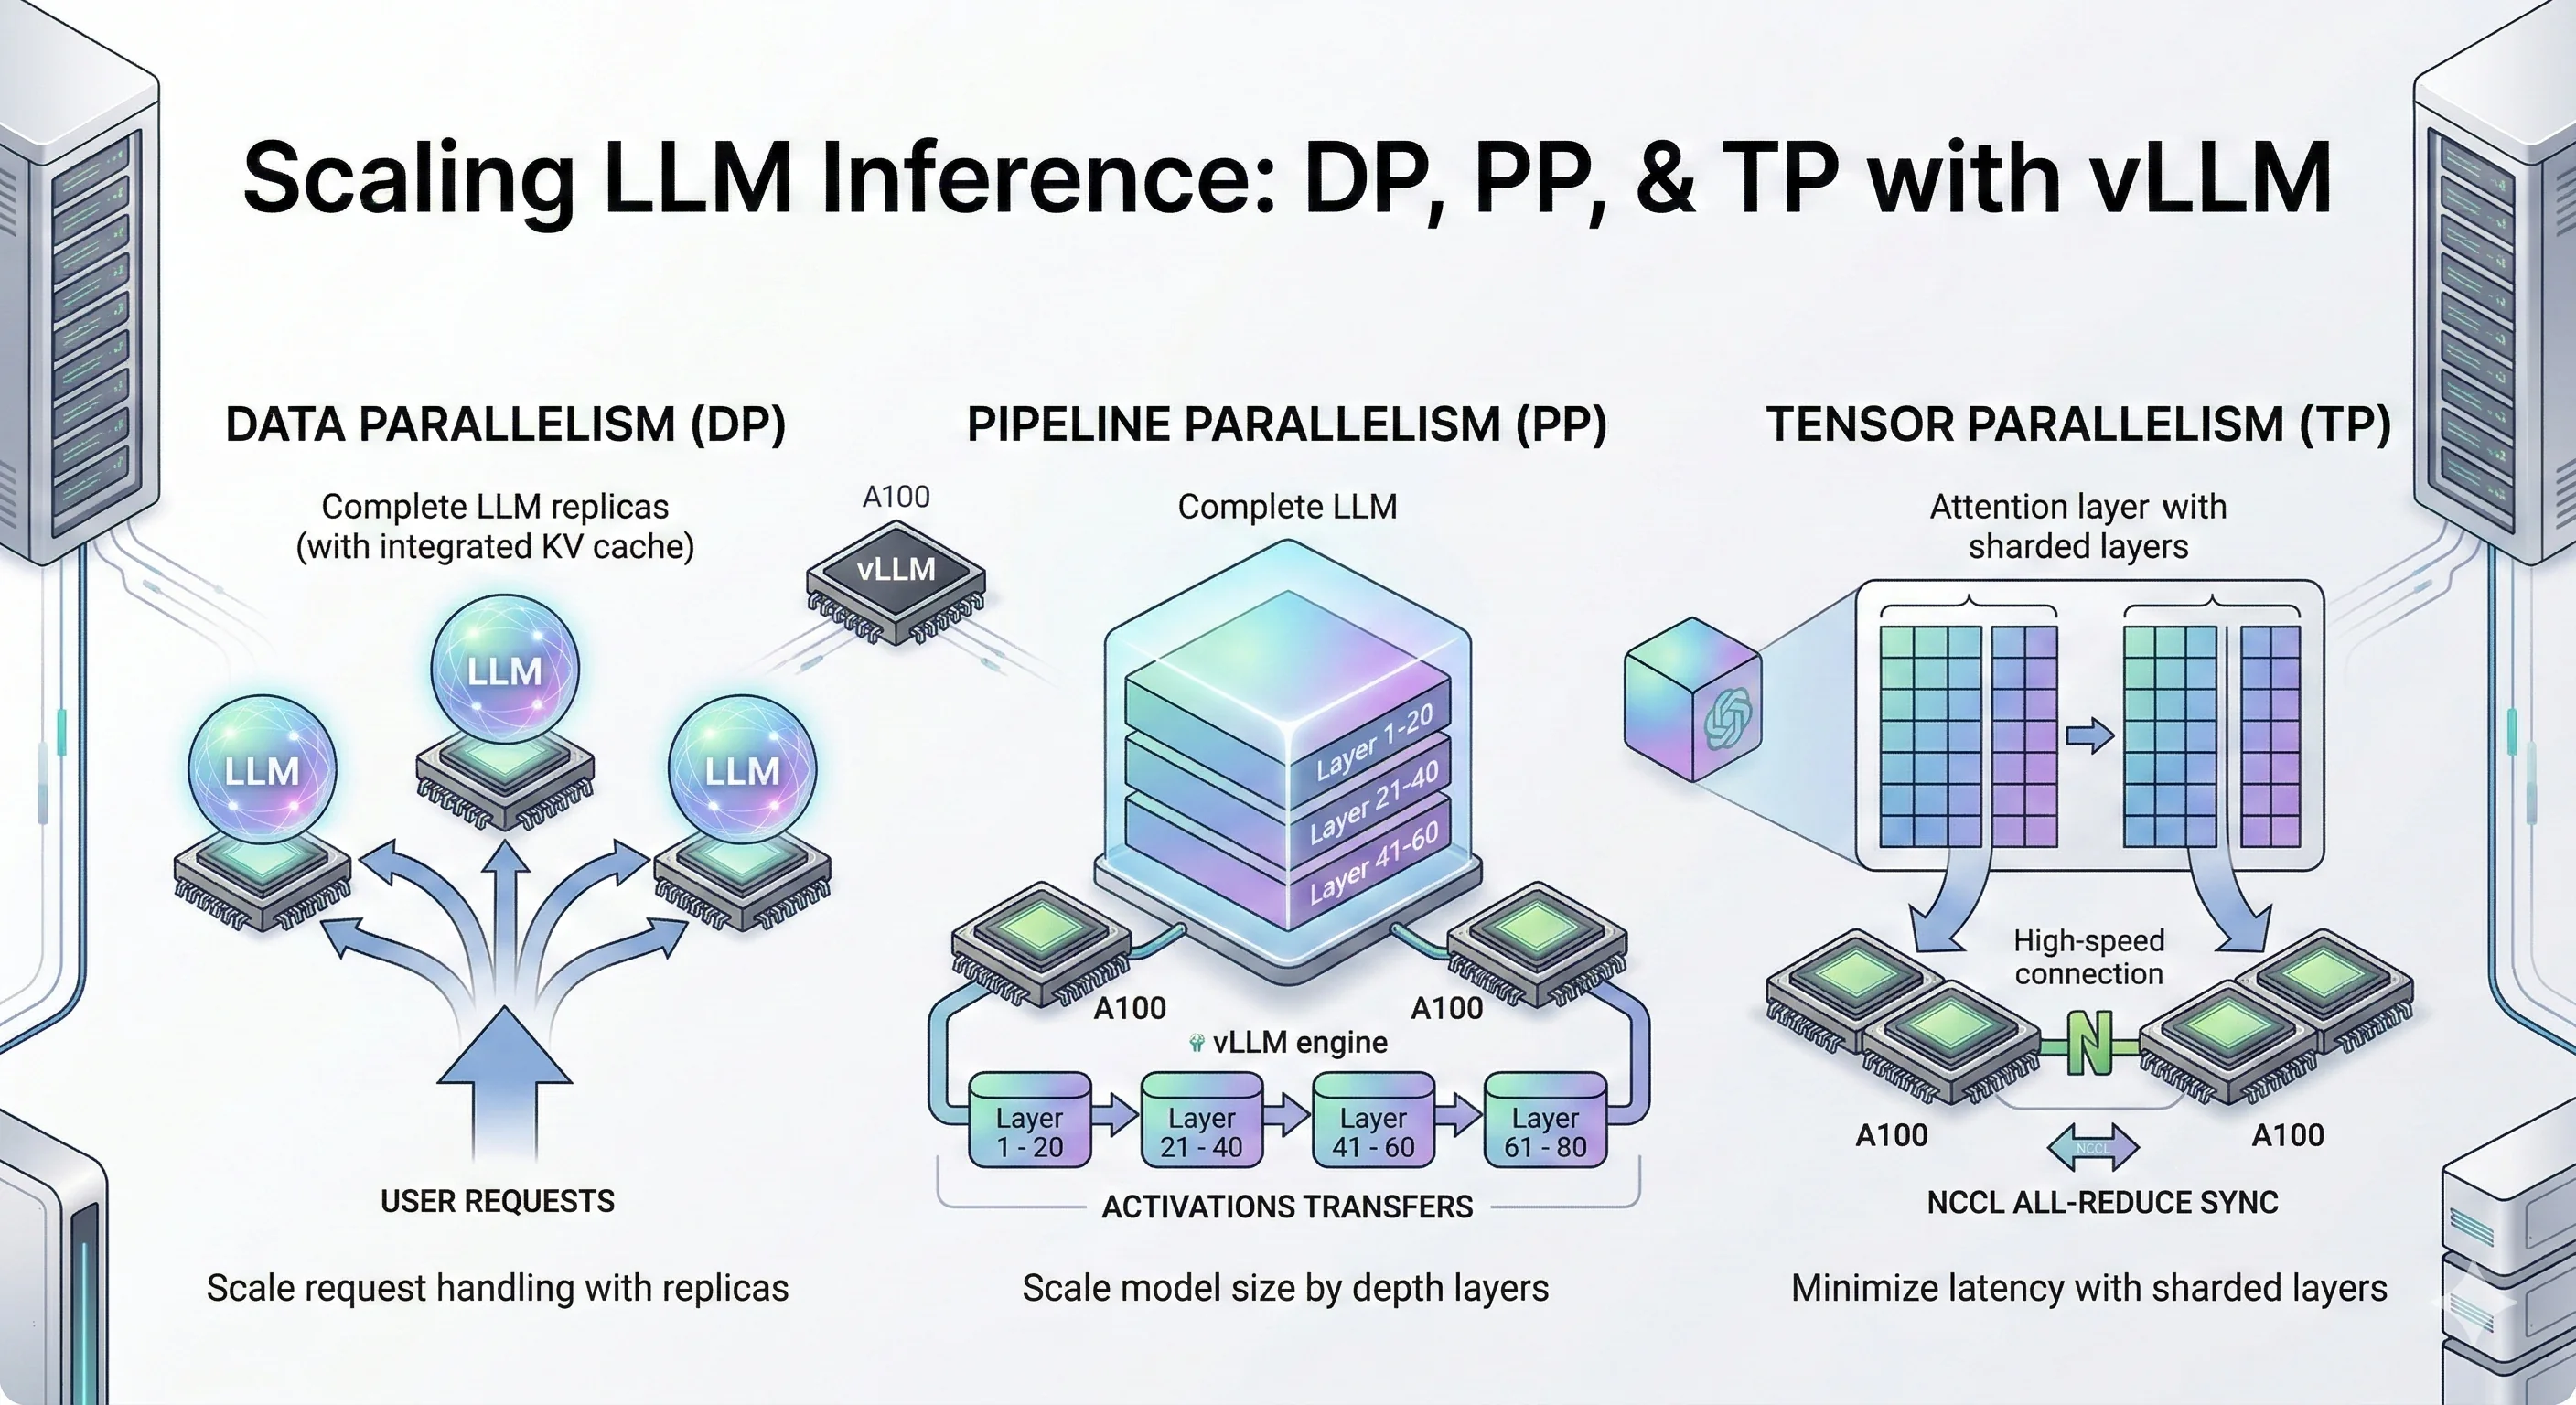
The Shift to Distributed LLM Inference: 3 Key Technologies Breaking ...
Guide to Self-hosting LLM Systems - Zilliz blog
17 Pros and Cons of Serverless Architecture for Modern Apps | Inference.net
Figure 1 from LLM-Based Misconfiguration Detection for AWS Serverless ...
Unpacking LLM Inference: Why Disaggregated Architecture is getting ...
LLM Inference: Techniques for Optimized Deployment in 2026 | Label Your ...
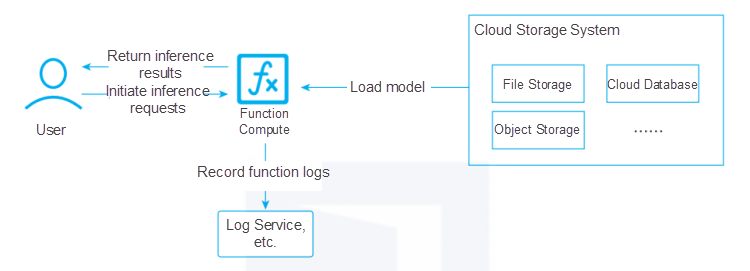
Six Application Scenarios of Serverless Architecture - Alibaba Cloud ...
GitHub - OpenCSGs/llm-inference: llm-inference is a platform for ...
[논문 리뷰] Scalable and Cost-Efficient ML Inference: Parallel Batch ...
Blog | llm-d
Training gets all the attention. | Mary Newhauser
How LLMs Actually Work: A Product Manager's Mental Model | Akash Deep
How Should You Learn AWS? | by Linh Ha | Mar, 2026 | Medium
关于LLM和Serverless的过去,现在和未来 - 知乎