Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
OpenCode Agent Switch System Prompt Cache
Adding an LLM System Prompt document
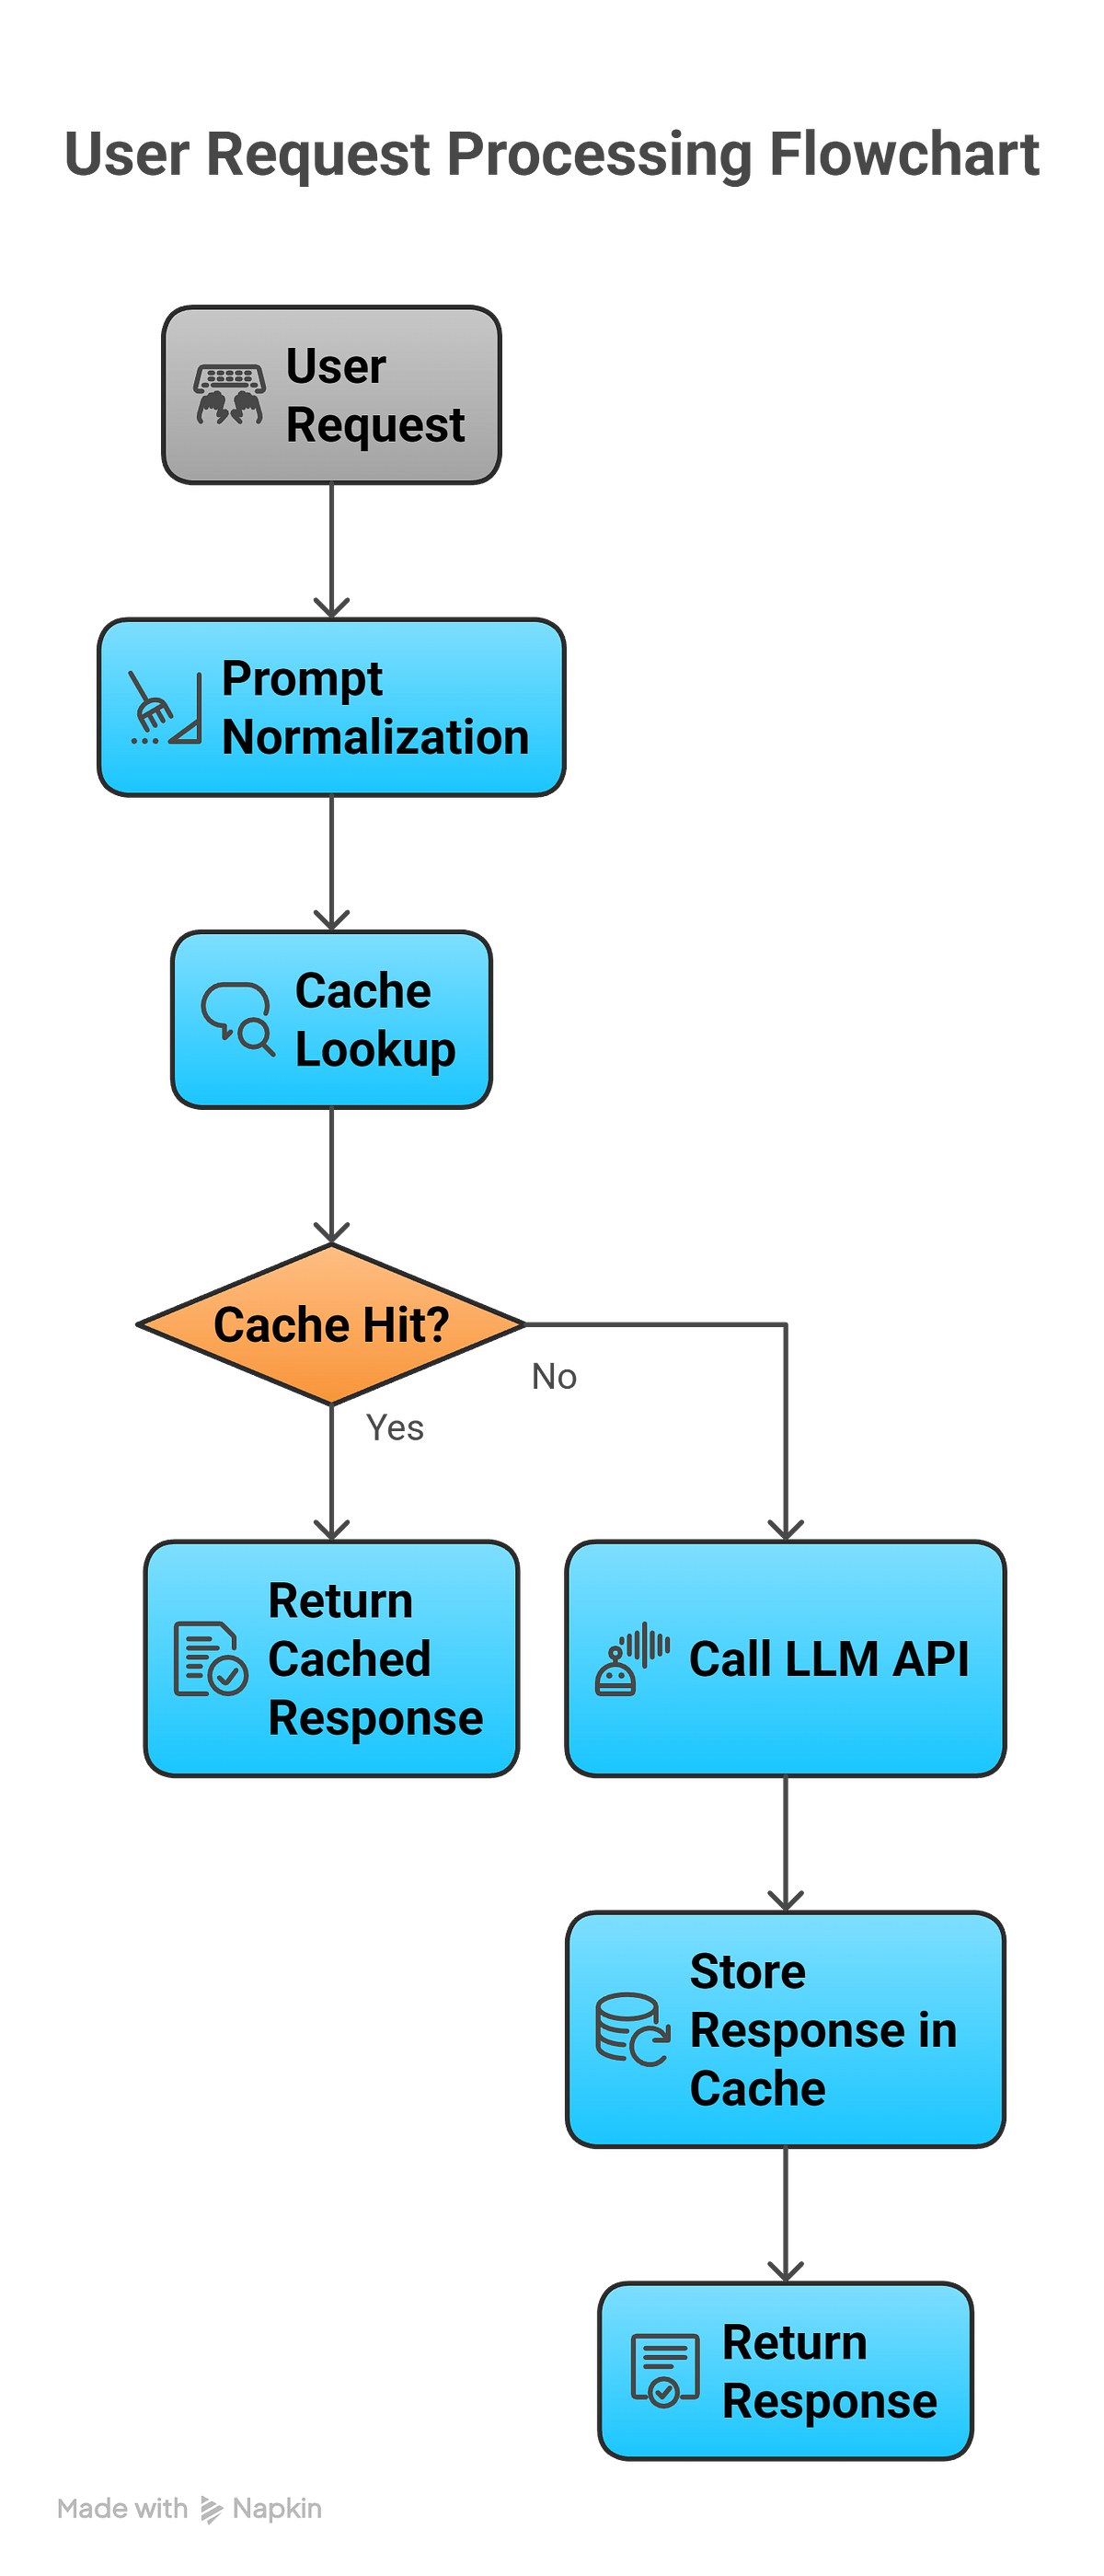
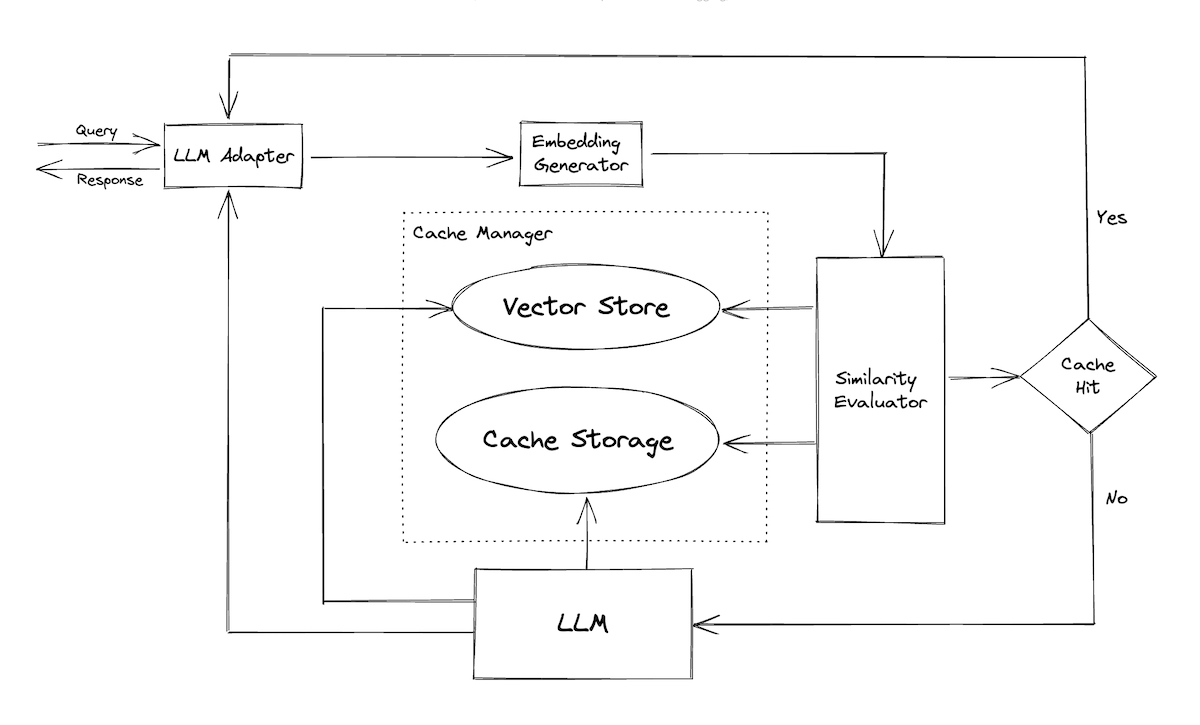
RAG-Enhanced Prompt Processor: Smarter LLM Queries with Cache by Suhaan ...
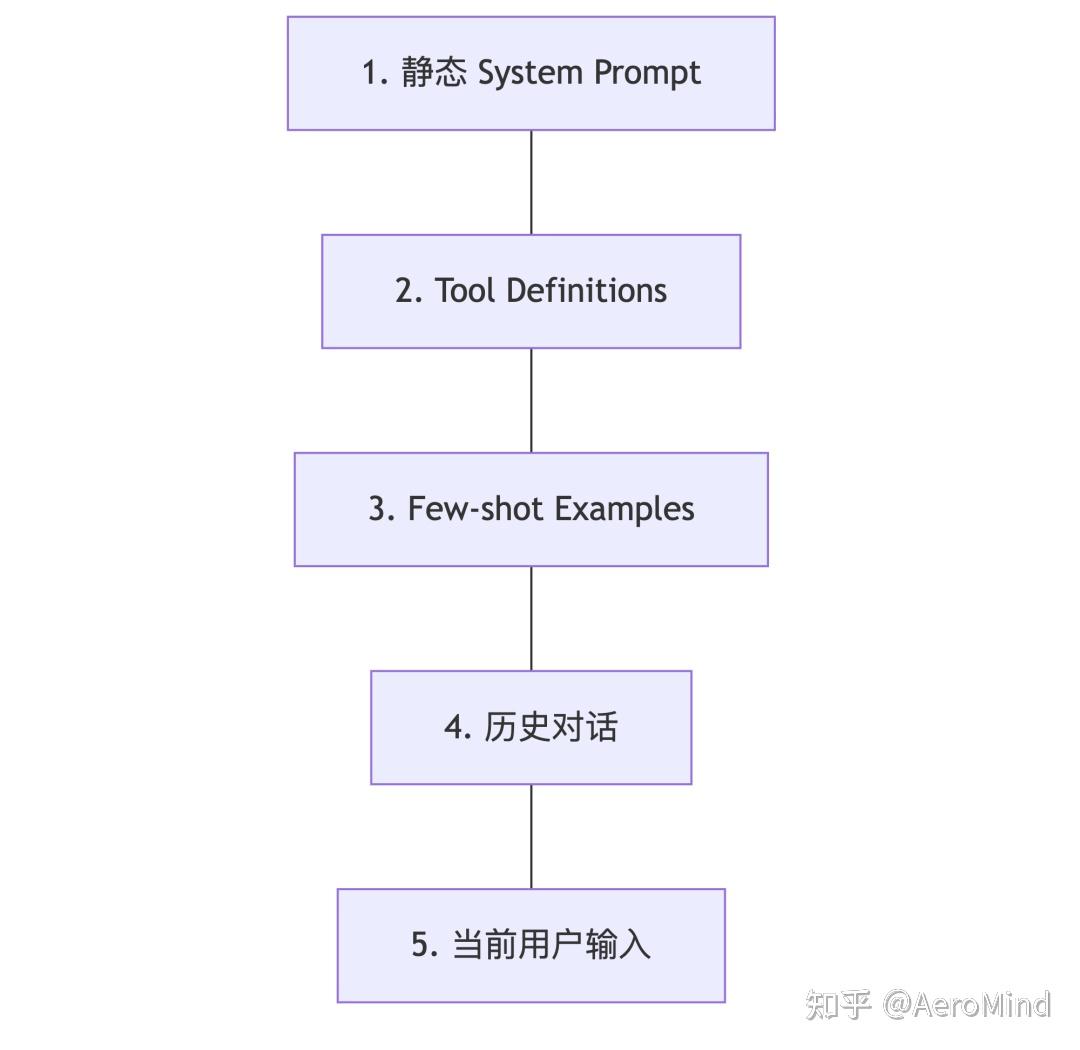
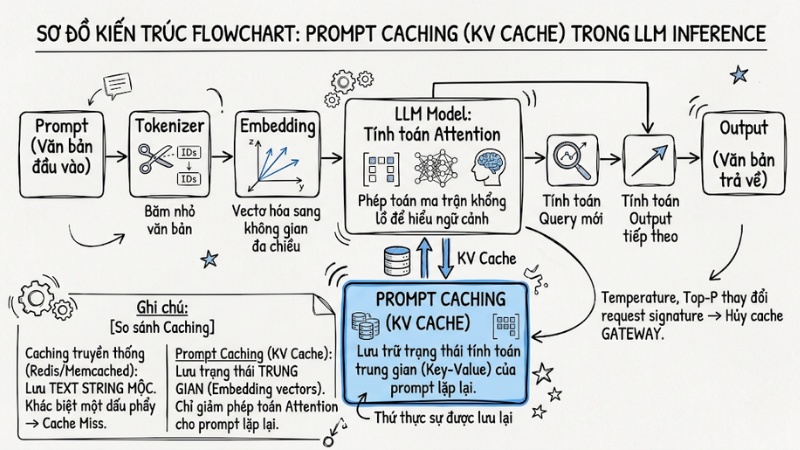
LLM Prompt Cache 深度解析:从 KV Cache 原理到大规模推理架构 - 知乎
LLM - User Prompt与System Prompt原理、方法与实战_llm prompt system user-CSDN博客
What Is an LLM System Prompt and How Does It Work?
LLM System Prompt Leakage: Prevention Strategies | Cobalt
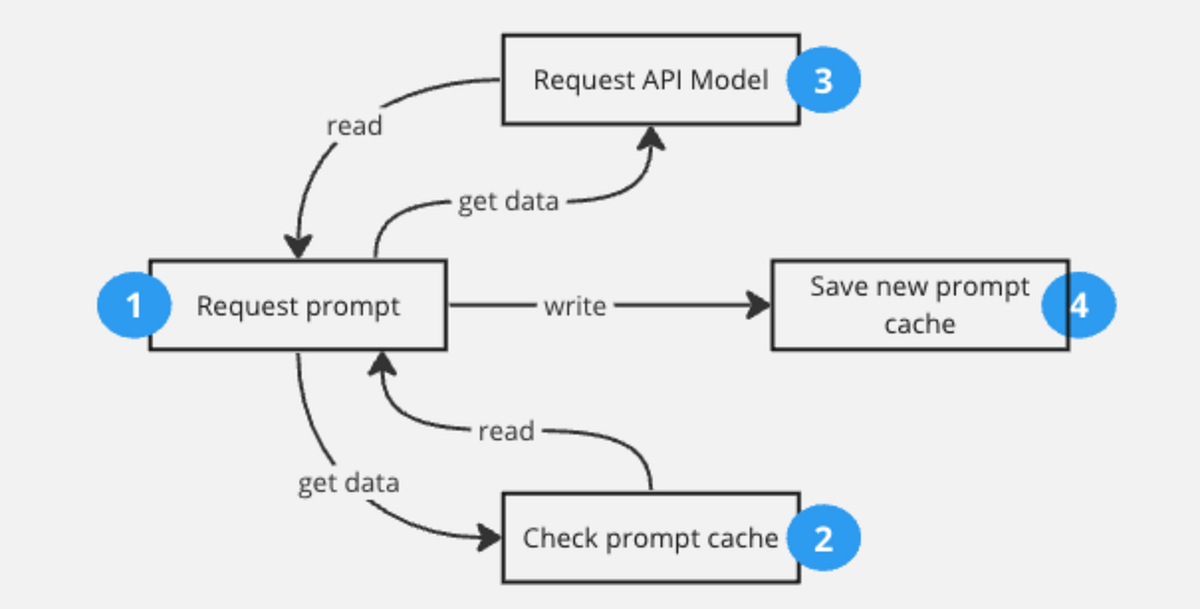
Abordagens de cache de prompt para as aplicações que utilizam LLM | by ...
Prompt Caching in LLM Systems
PromptMule Prompt Cache LLMs – Numino Labs
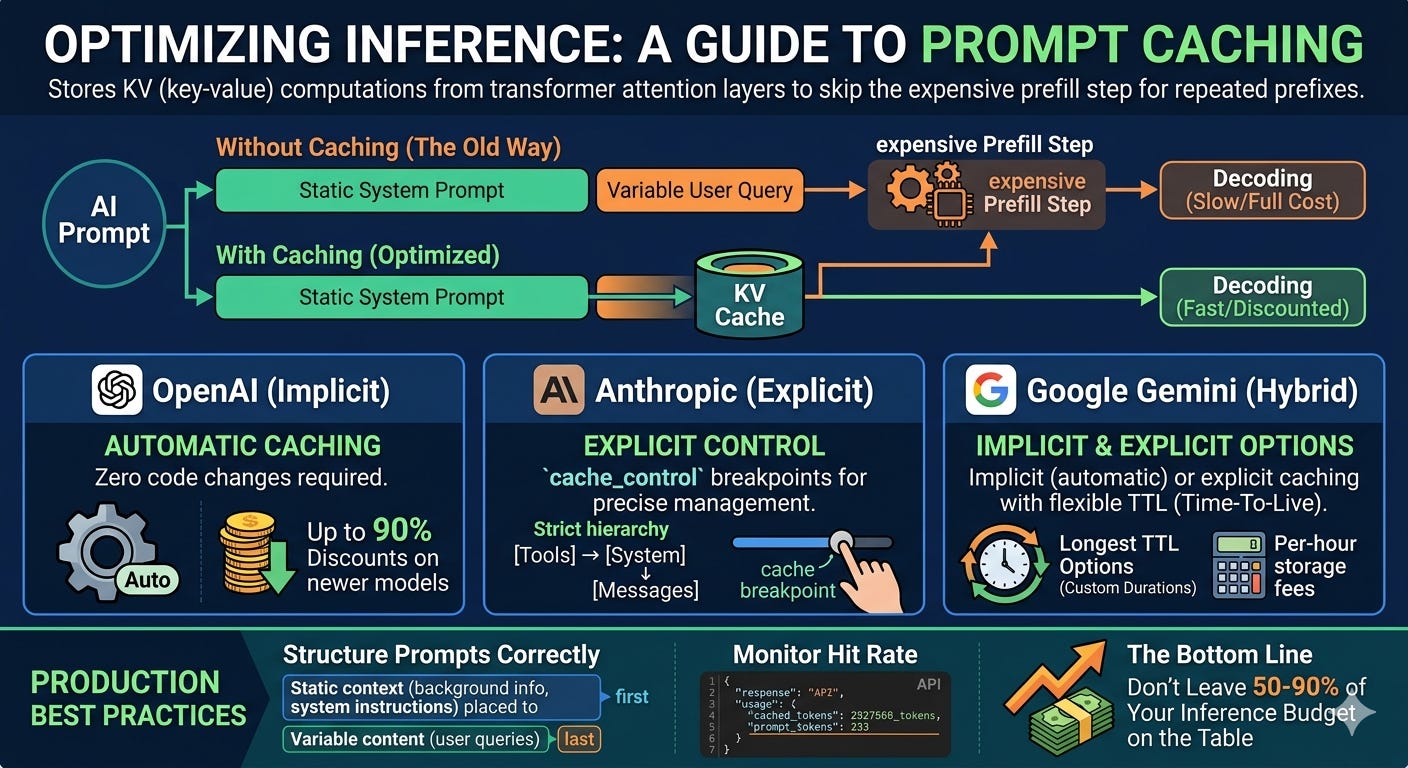
Prompt Caching: One of the Most Underrated Optimizations in LLM Systems
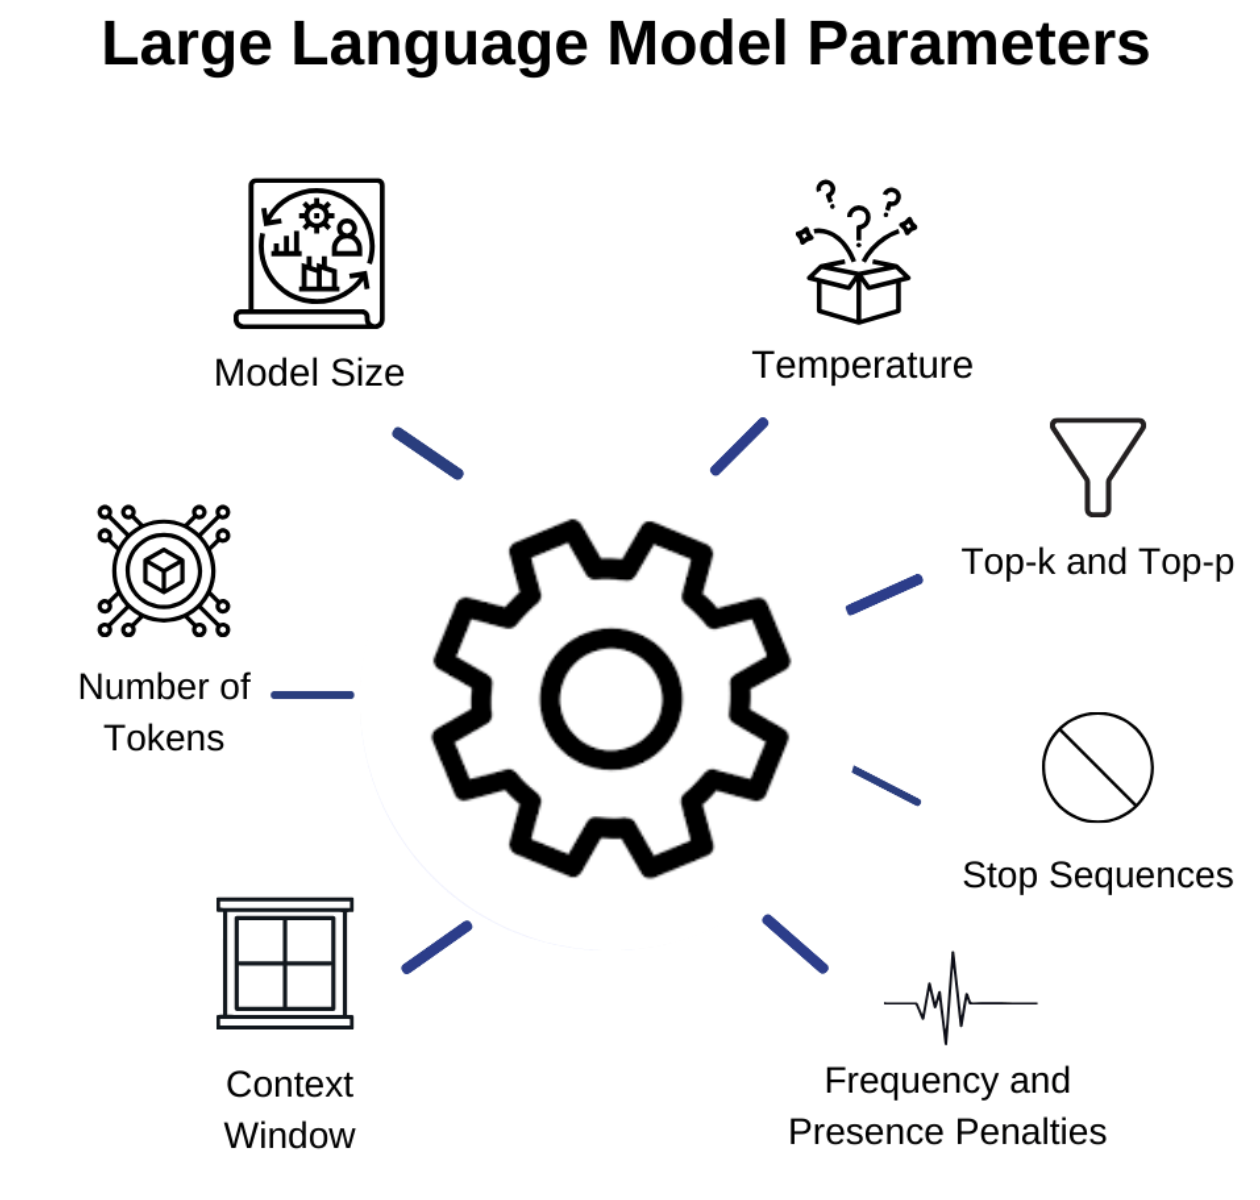
Prompt Caching - LLM Parameter Guide - Vellum
Prompt Caching in LLM Systems. Table of Contents: - Caching Strategy ...
A Deep Dive into LLM Prompt Caching
LLM Apps: Boost Performance & Cost with Prompt Caching | Omar Chaaban ...
当我们在说 prompt cache 的时候我们在说什么 | 墨筝
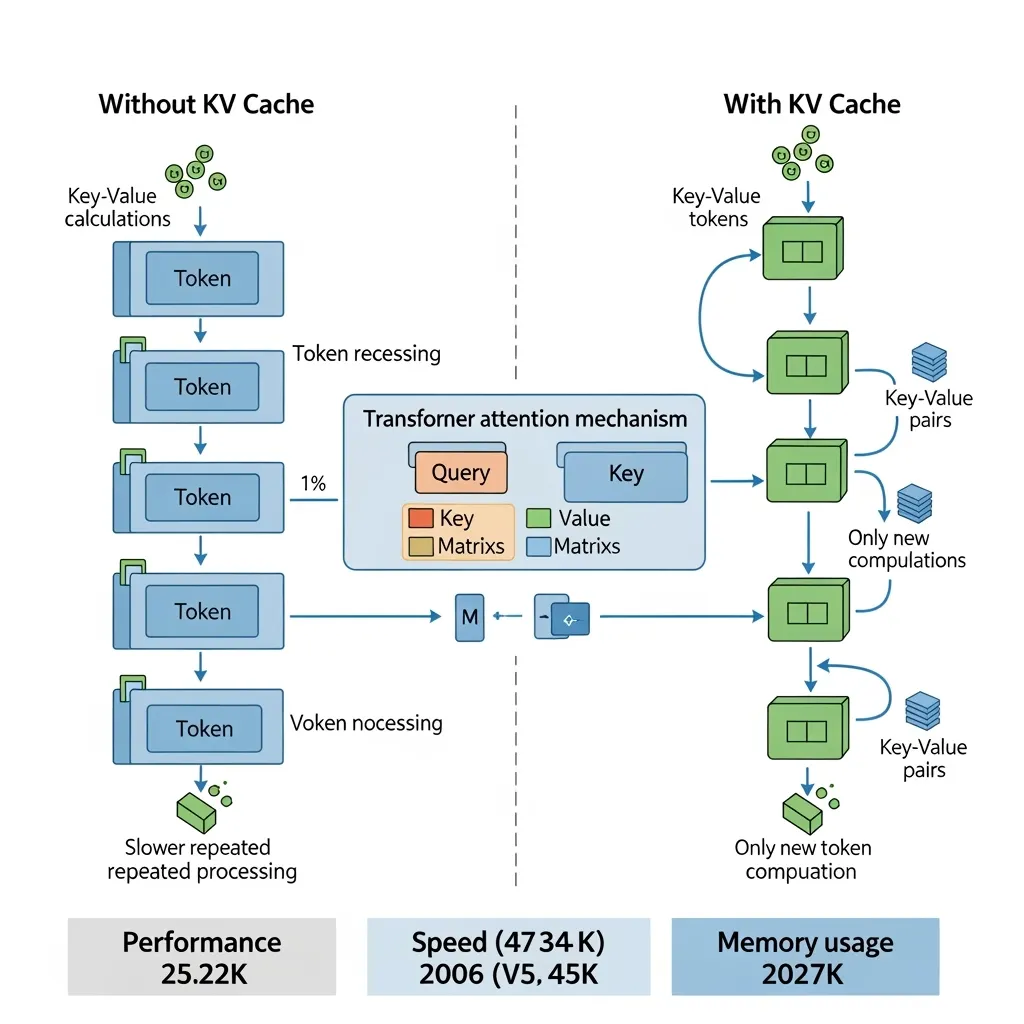
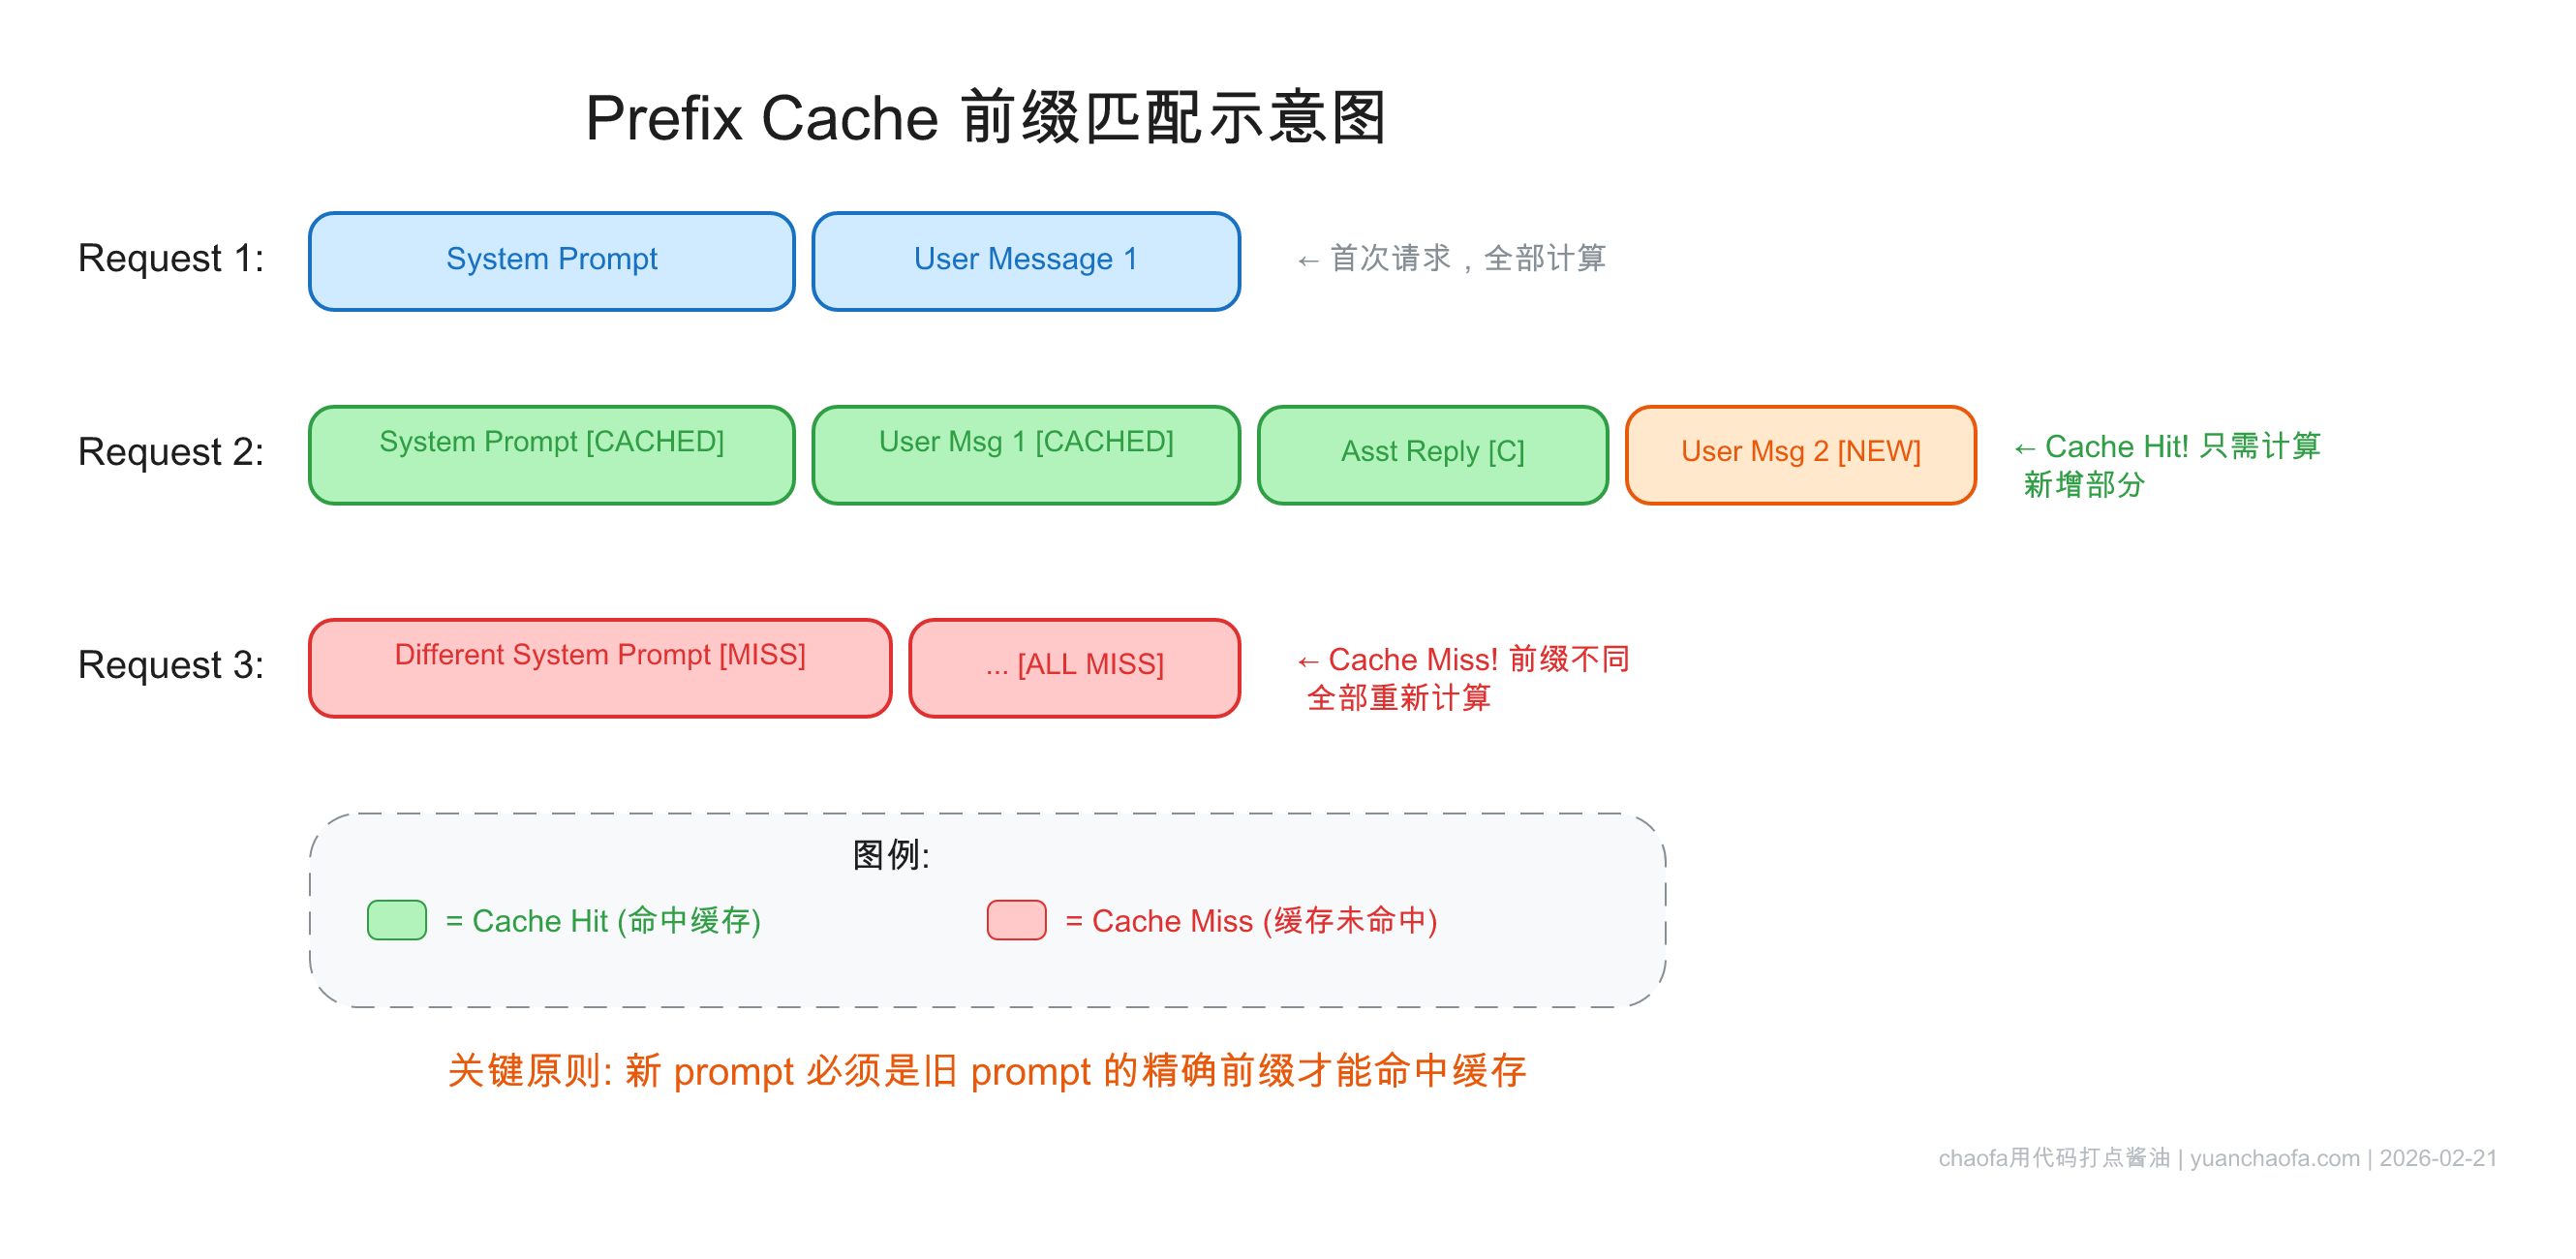
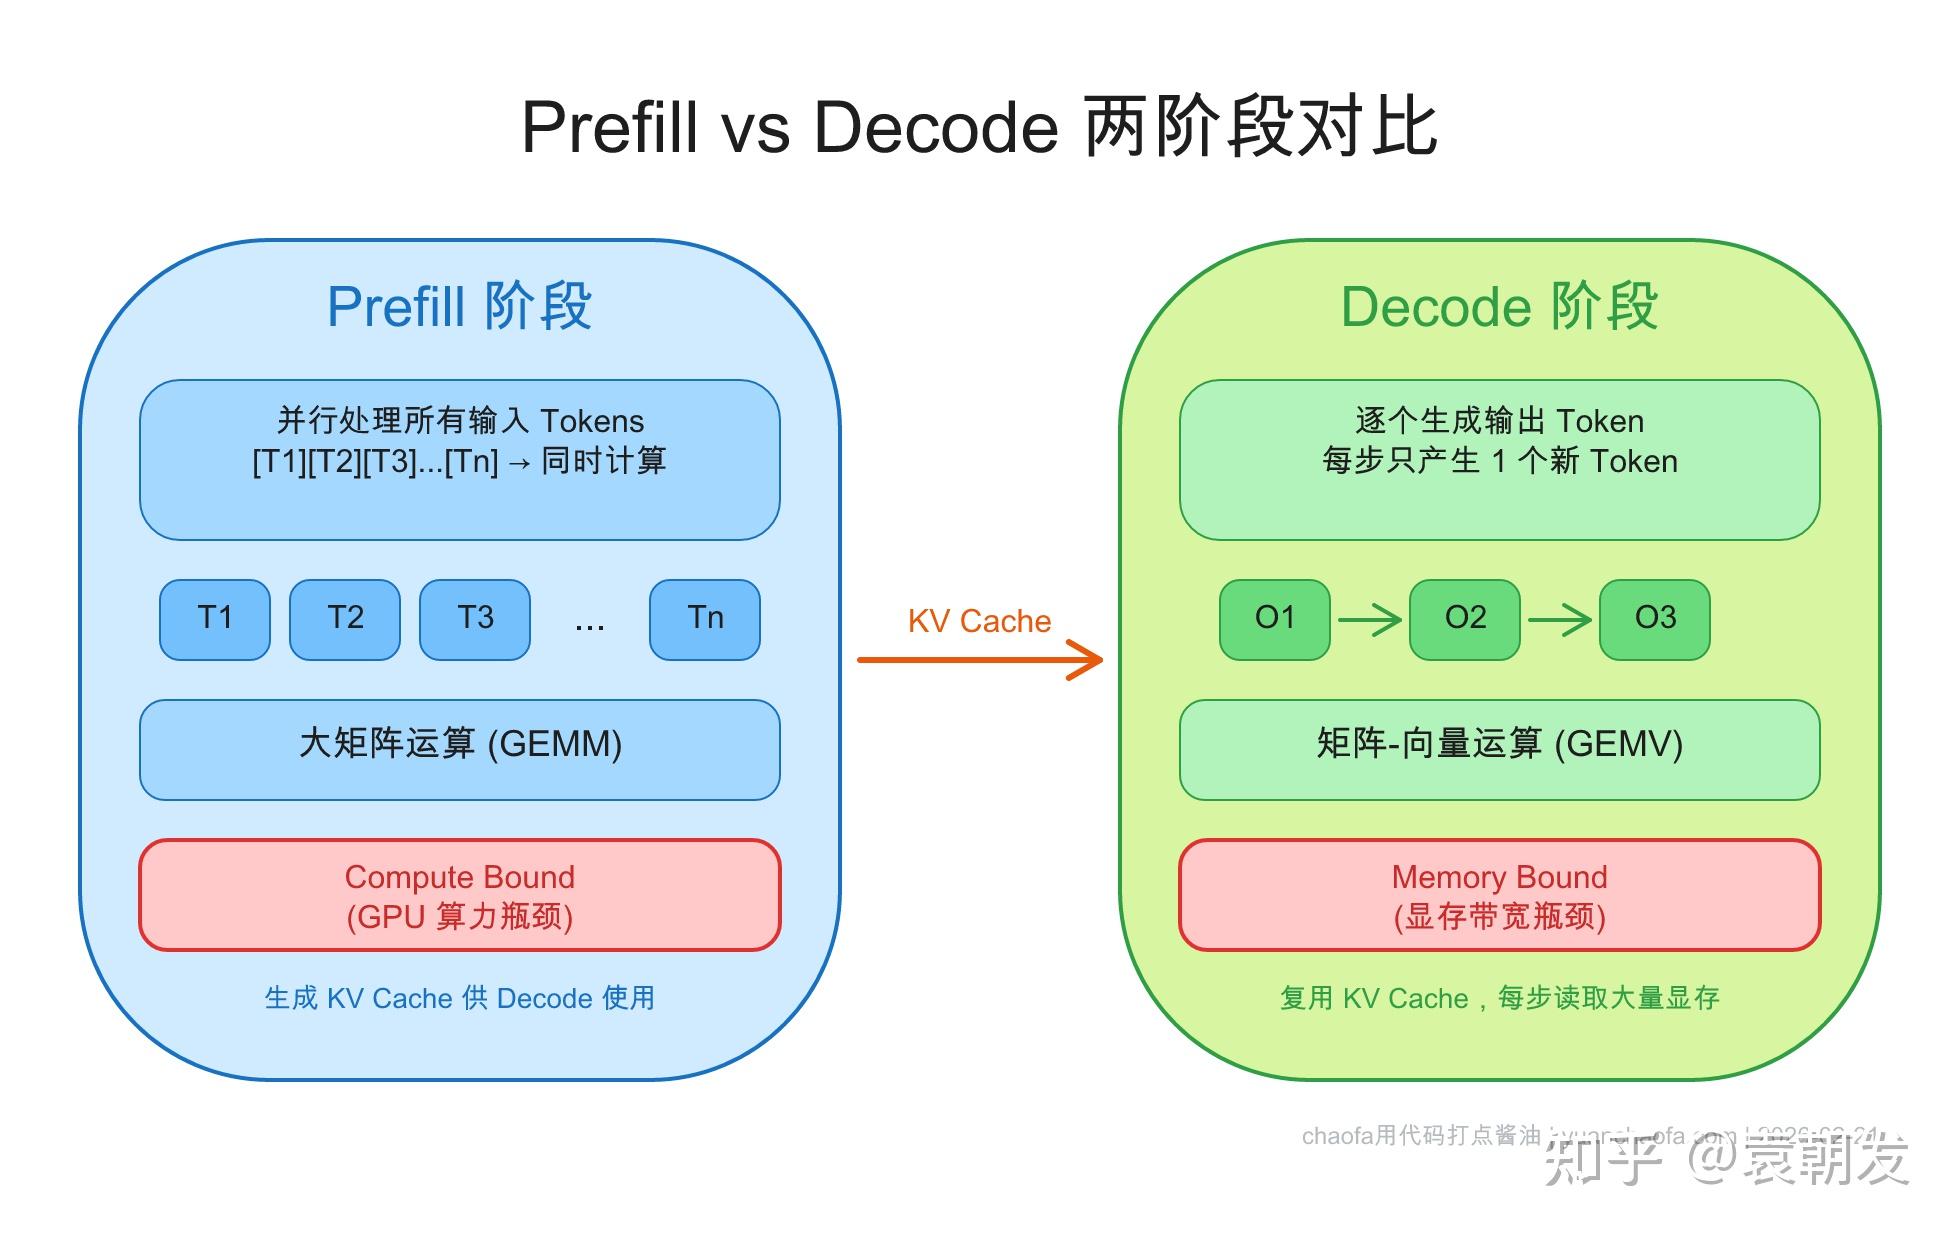
理解 KV Cache 与 Prompt Caching:LLM 推理加速的核心机制 | chaofa用代码打点酱油
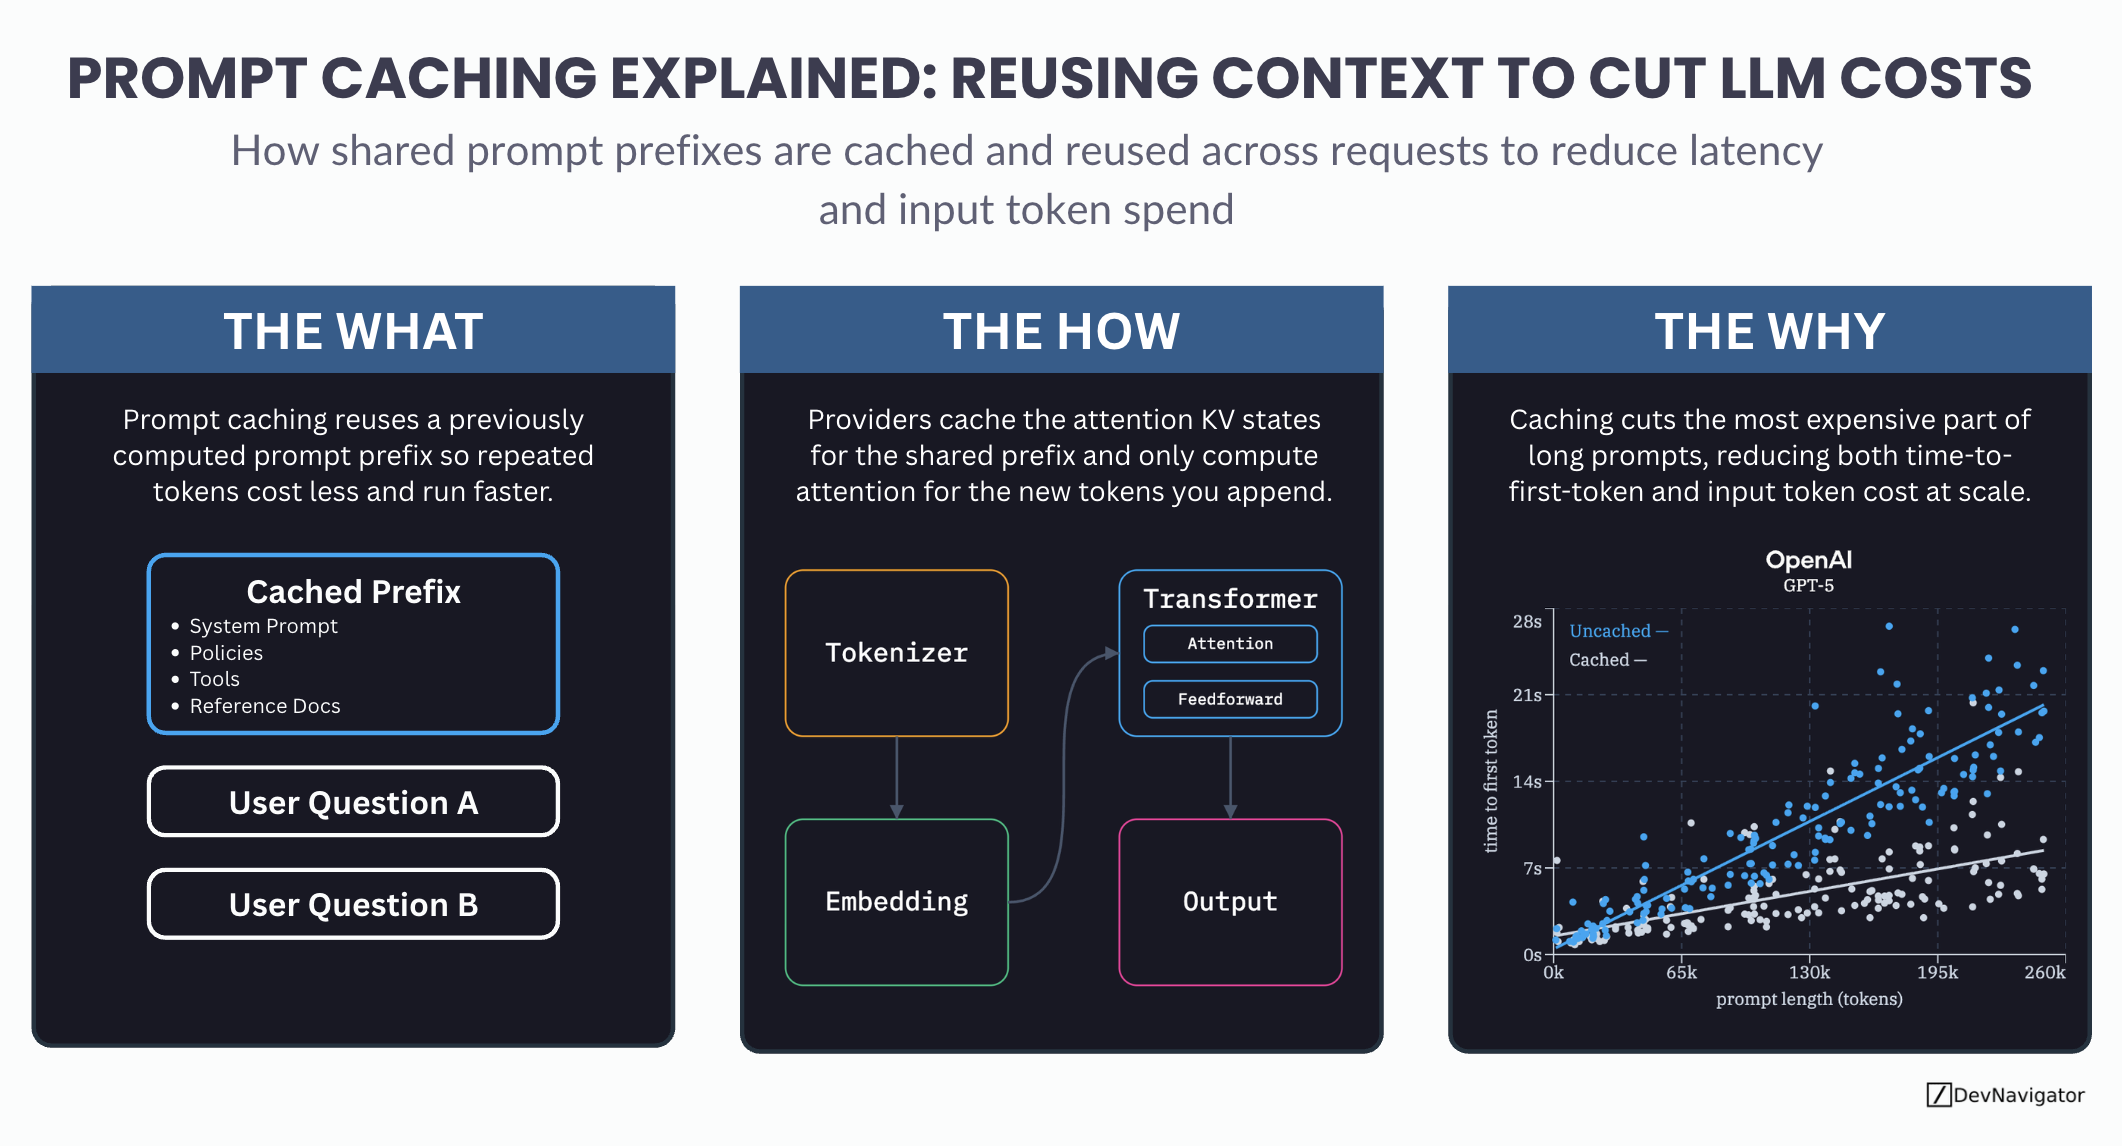
What Is Prompt Caching? How LLM Prompt Caching Reduces Cost and ...
Cache Usage in LLMs: LangChain Cache and OpenAI Prompt Caching | Pedro ...
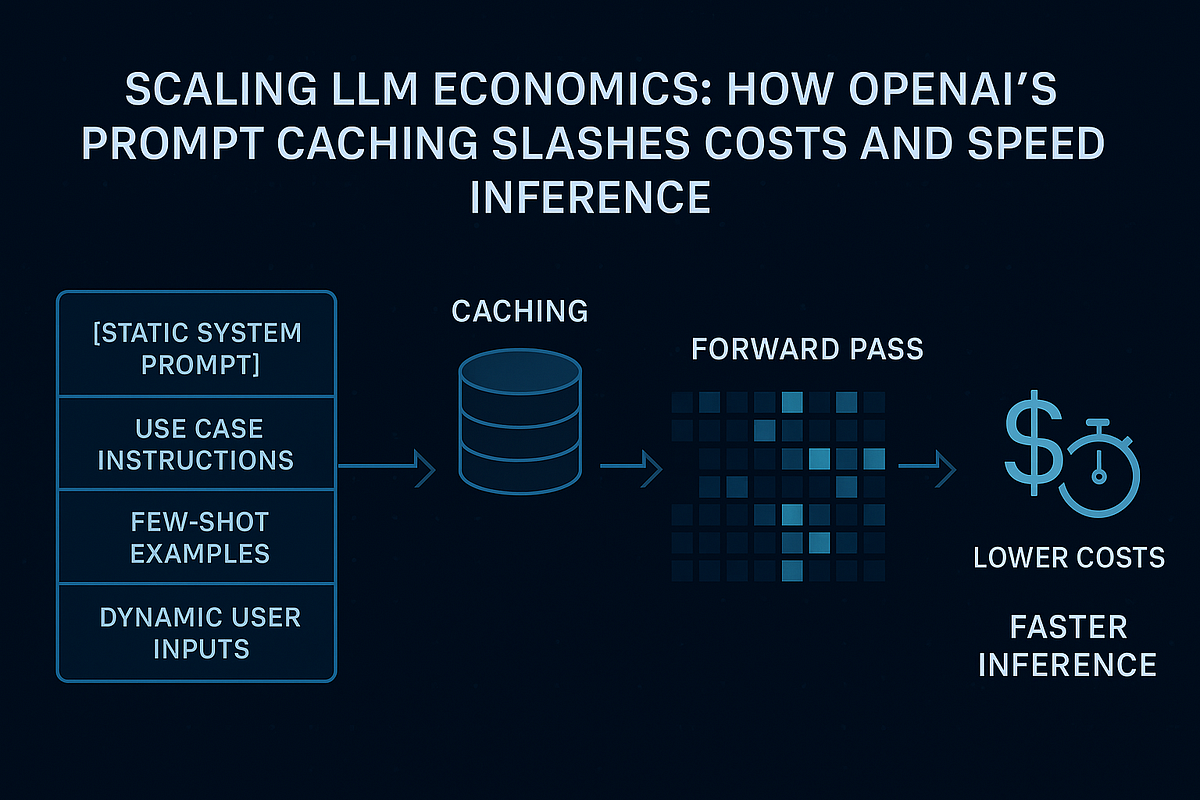
Scaling LLM Economics: How Prompt Caching Slashes Costs and Speeds ...
Prompt Caching Strategies to Reduce LLM Cost | Medium
How to Write System Prompts That Control LLM Behavior | AI Kaptan
理解 KV Cache 与 Prompt Caching:LLM 推理加速的核心机制 - 知乎
LLM Prompt Caching Guide 2026: Cut API Costs 70% with Anthropic and ...
LLM Latency & Cost Optimization with Prompt Caching | Ahmed Kayani ...
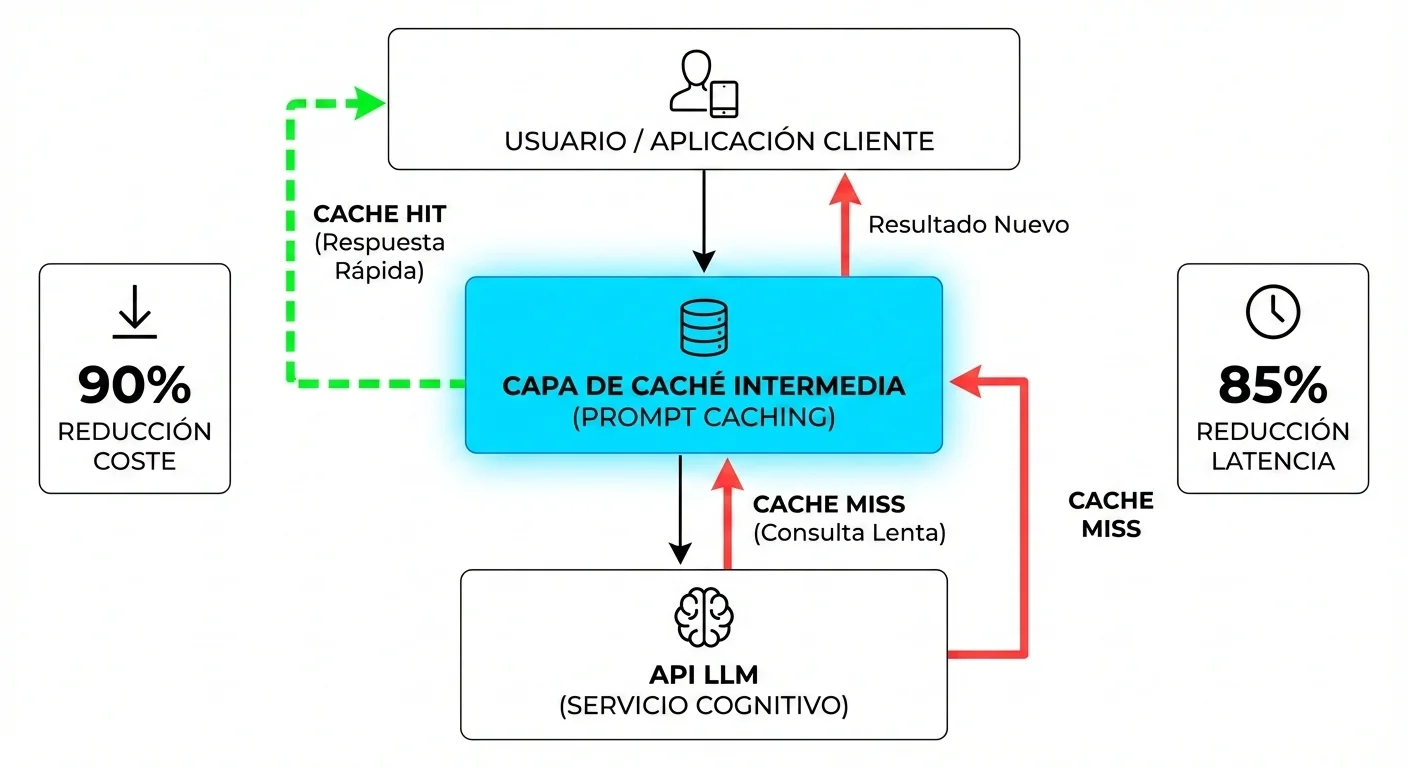
Unlock 85% LLM Latency Reduction with Prompt Caching | Ahmed ALMubarak ...
Prompt Caching: Cách tối ưu độ trễ và chi phí API LLM hiệu quả — GoClaw ...
How to use System Prompt Caching in version 0.8.0? · Issue #1426 ...
Prompt Caching: A Technical Guide to LLM Efficiency | Blog
A Solutions Architect's Guide to Caching LLM Prompt Embeddings with ...
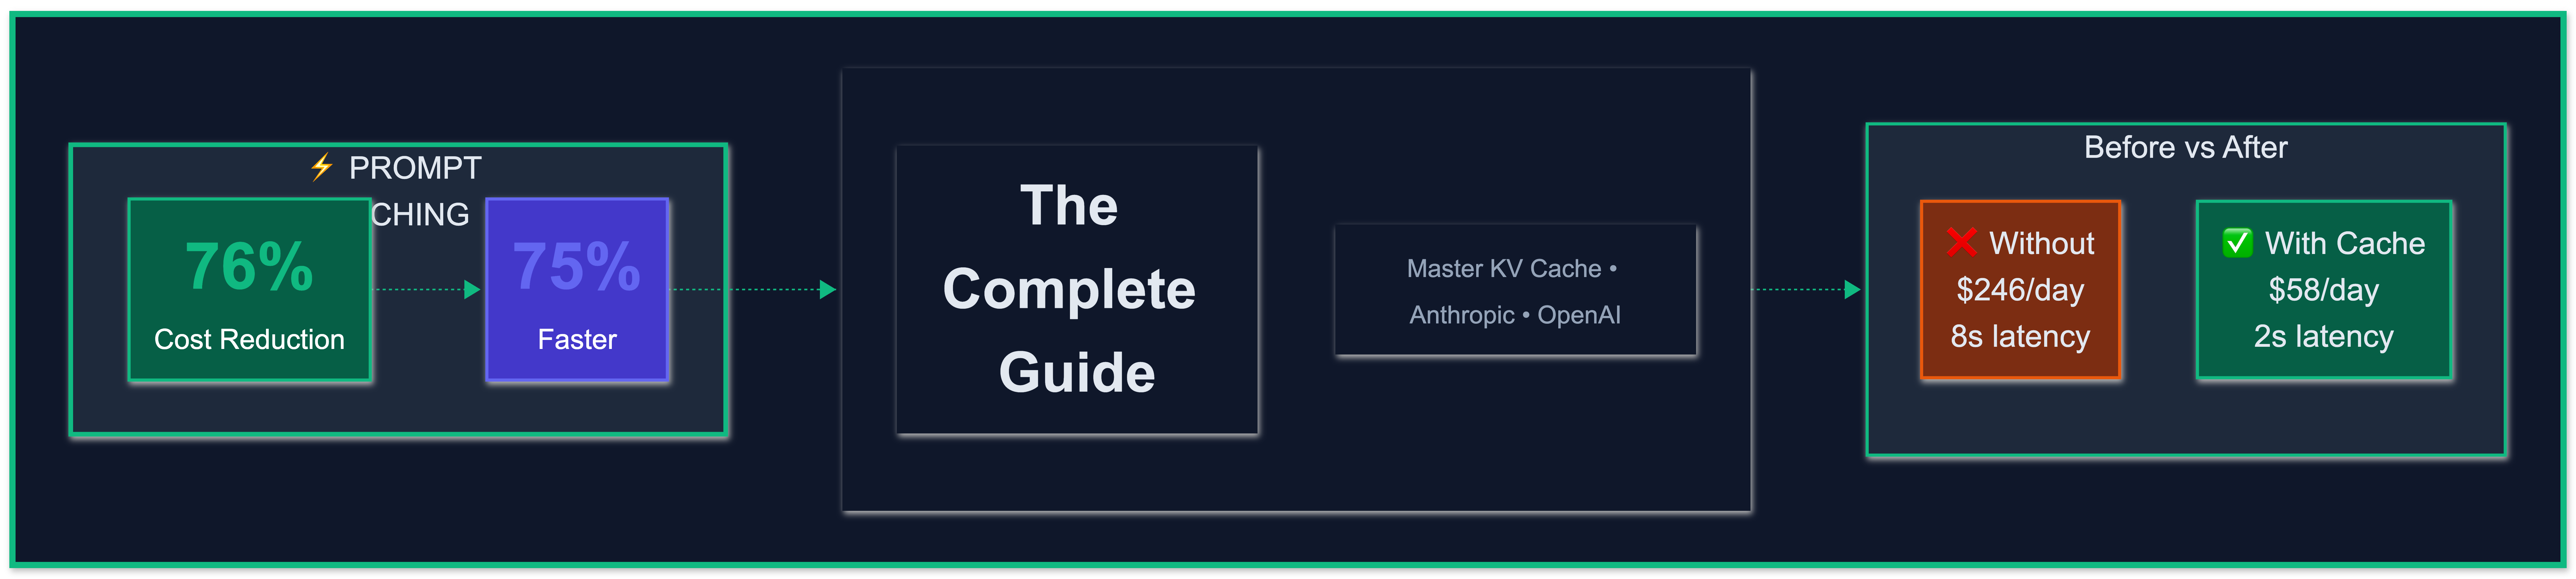
LLM Prompt Caching: The Complete 2026 Guide - DEV Community
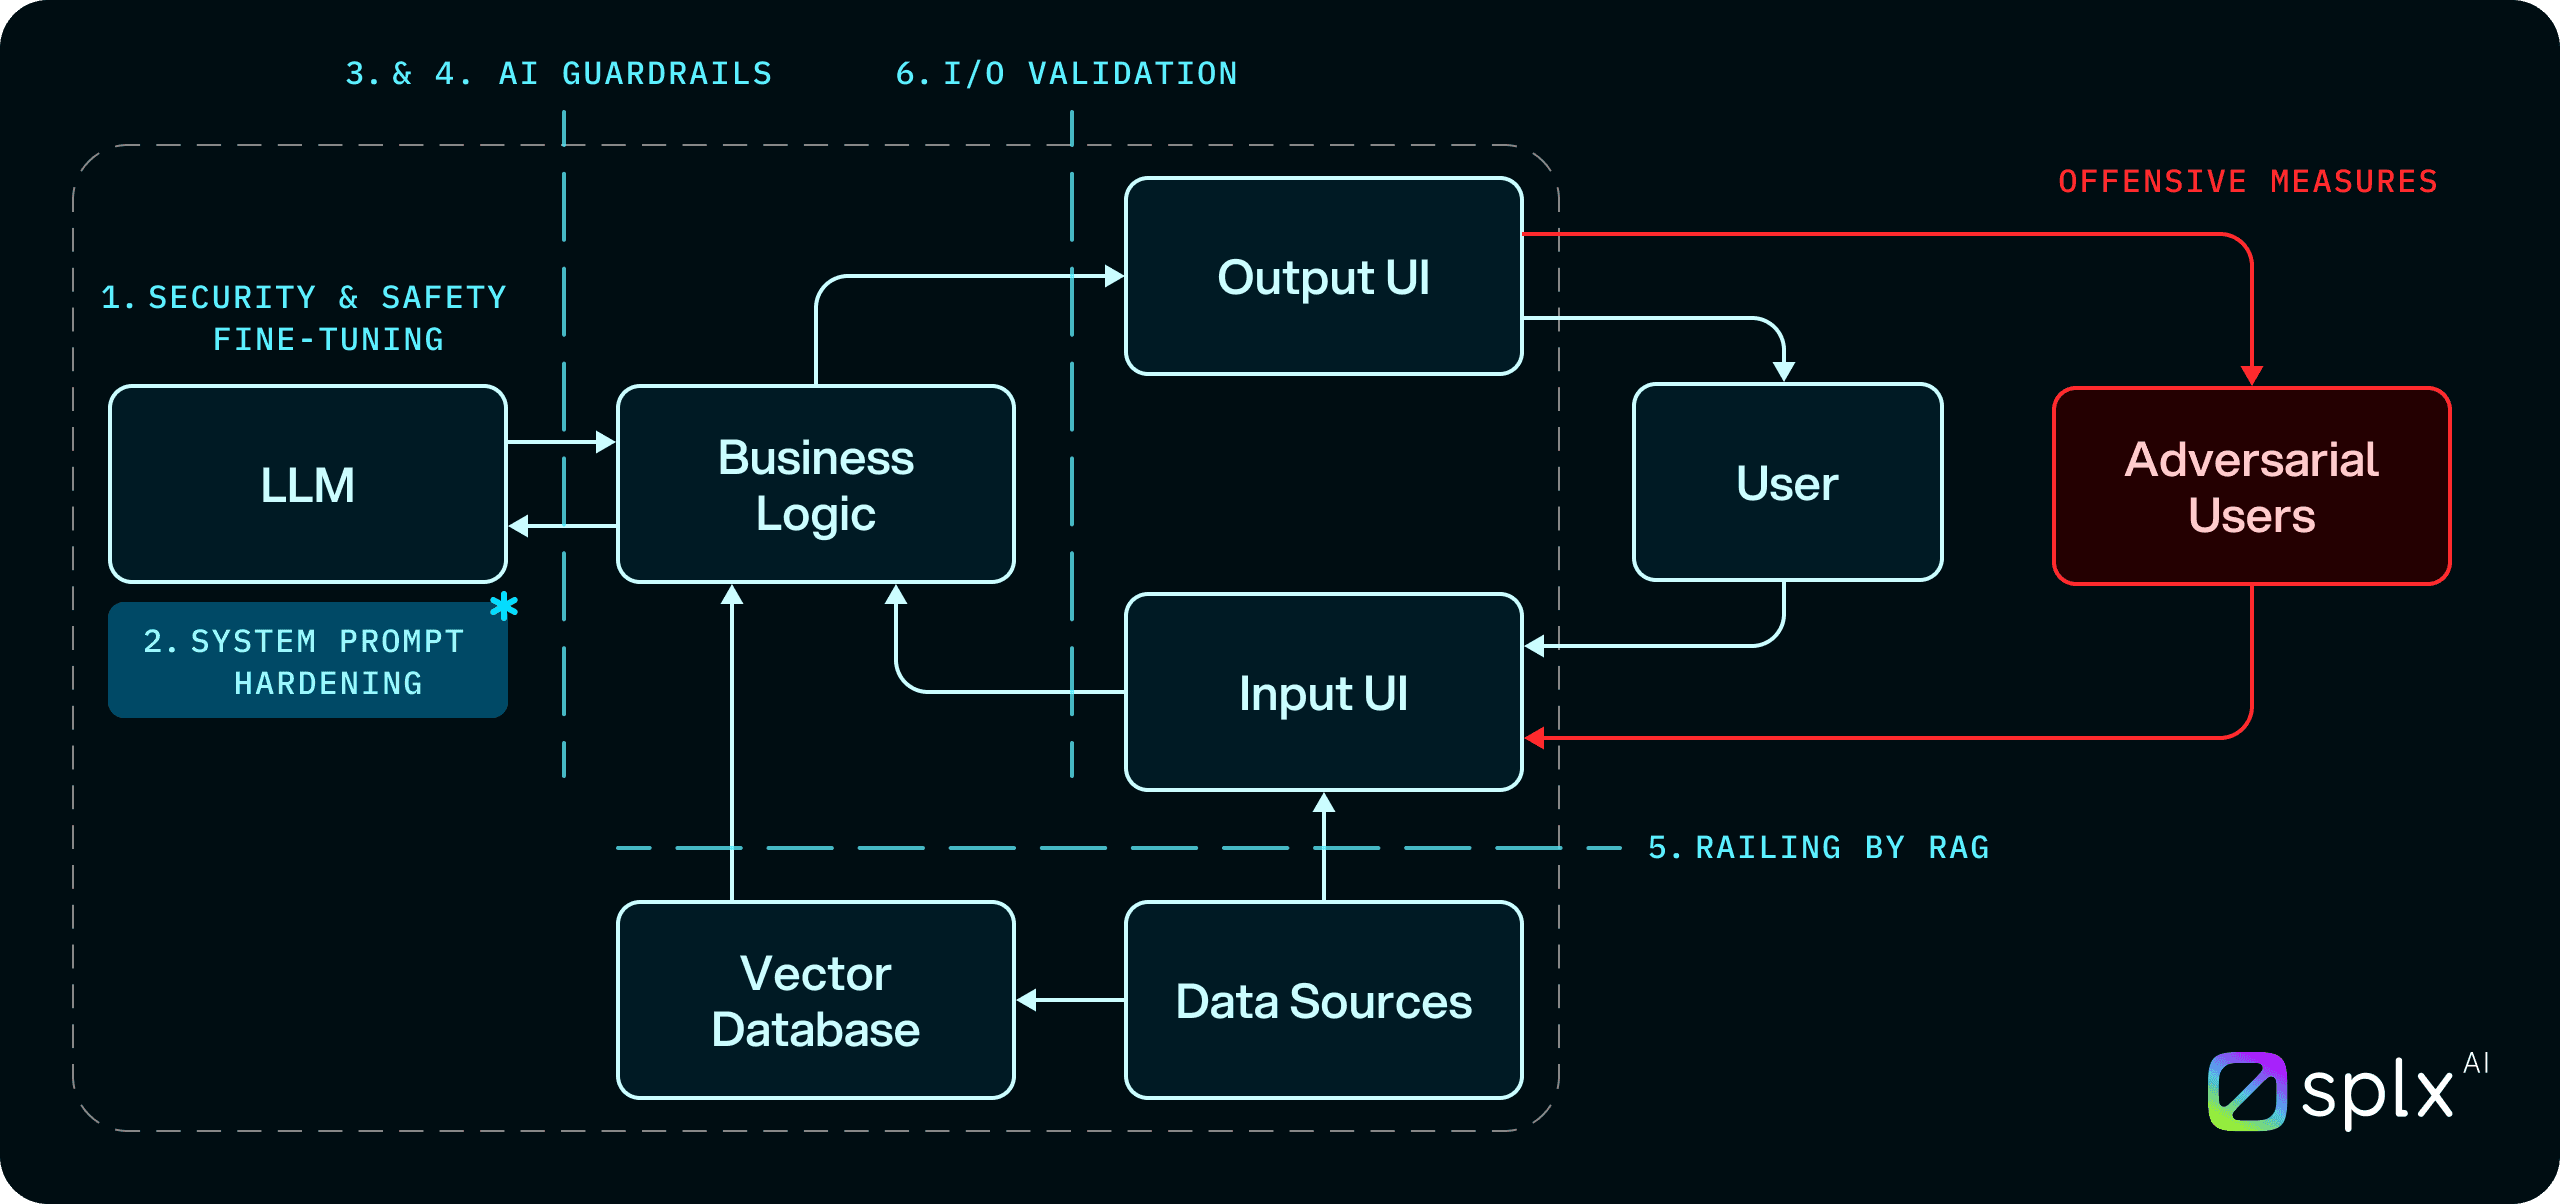
System Prompt Hardening: The Backbone of Automated AI Security
Prompt Caching:将 LLM 成本降低 90% 的优化方案
Prompt Caching | LLM Knowledge Base
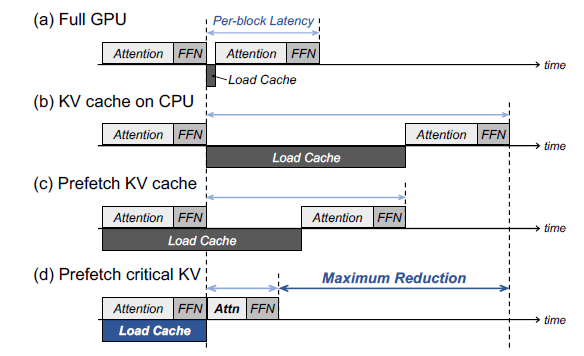
Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium
Prompt Caching: Saving Time and Money in LLM Applications | Caylent
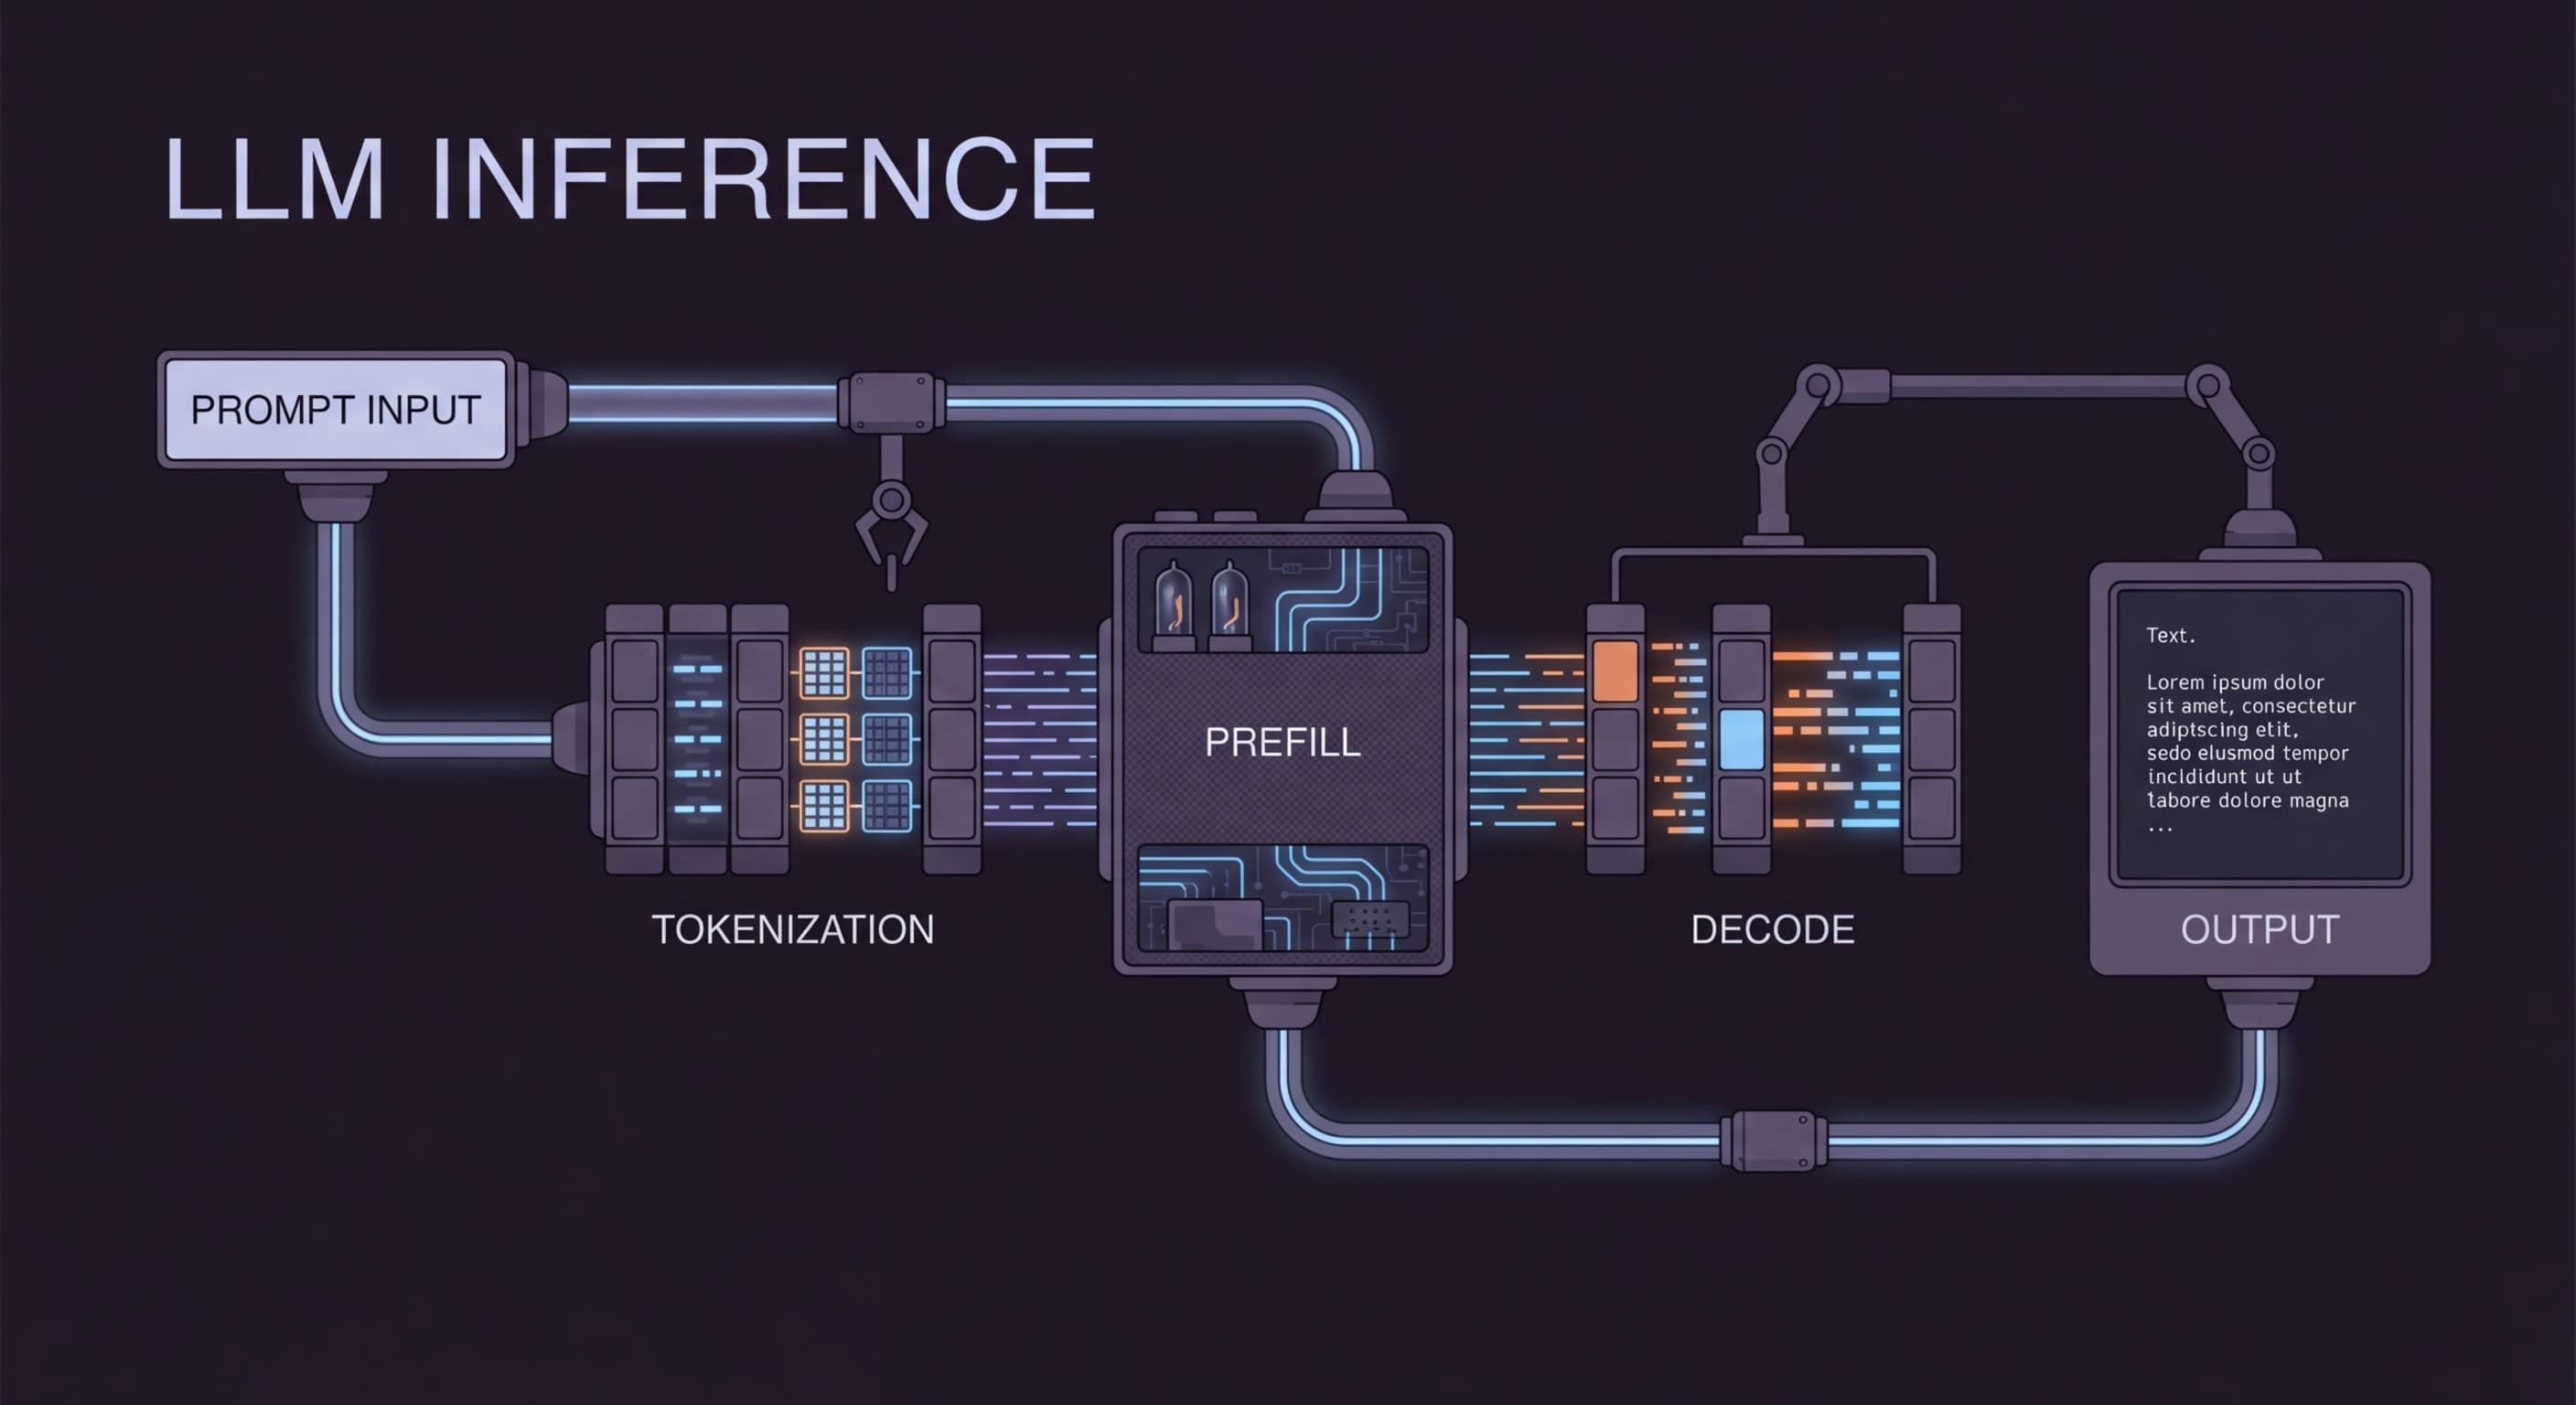
LLM Inference: Prefill, Decode, KV Cache & Cost Guide (2026) | Morph
Prompt Caching Explained — Save Up to 90% on LLM API Costs
The Complete Guide to Prompt Caching: Cut LLM Costs by 90%
Prompt 缓存暗藏隐患?研究揭示 LLM API 的潜在隐私泄露风险 - 知乎
Оптимизация производительности LLM с Cache LM: архитектуры, стратегии и ...
What is Prompt Caching : Reduce LLM cost by 90%! | by Mohamed EL ...
What is Prompt Caching? Complete LLM Guide
LLM Prompt Cache深度解析(非常详细):从KV Cache原理到推理架构,从入门到精通,收藏这一篇就够了!_the five ...
Prompt caching: 10x cheaper LLM tokens, but how? | ngrok blog
Launching LLM apps? Beware of prompt leaks - DEV Community
Cut Your LLM Costs by 90% With Prompt Caching (And Why Most Developers ...
LLM Prompt Caching: Performance and Security Guide | Medium
Optimize LLM Calls with Prompt Caching | Suneel Yadkikar posted on the ...
LLM Prompt Caching | MatterAI Blog
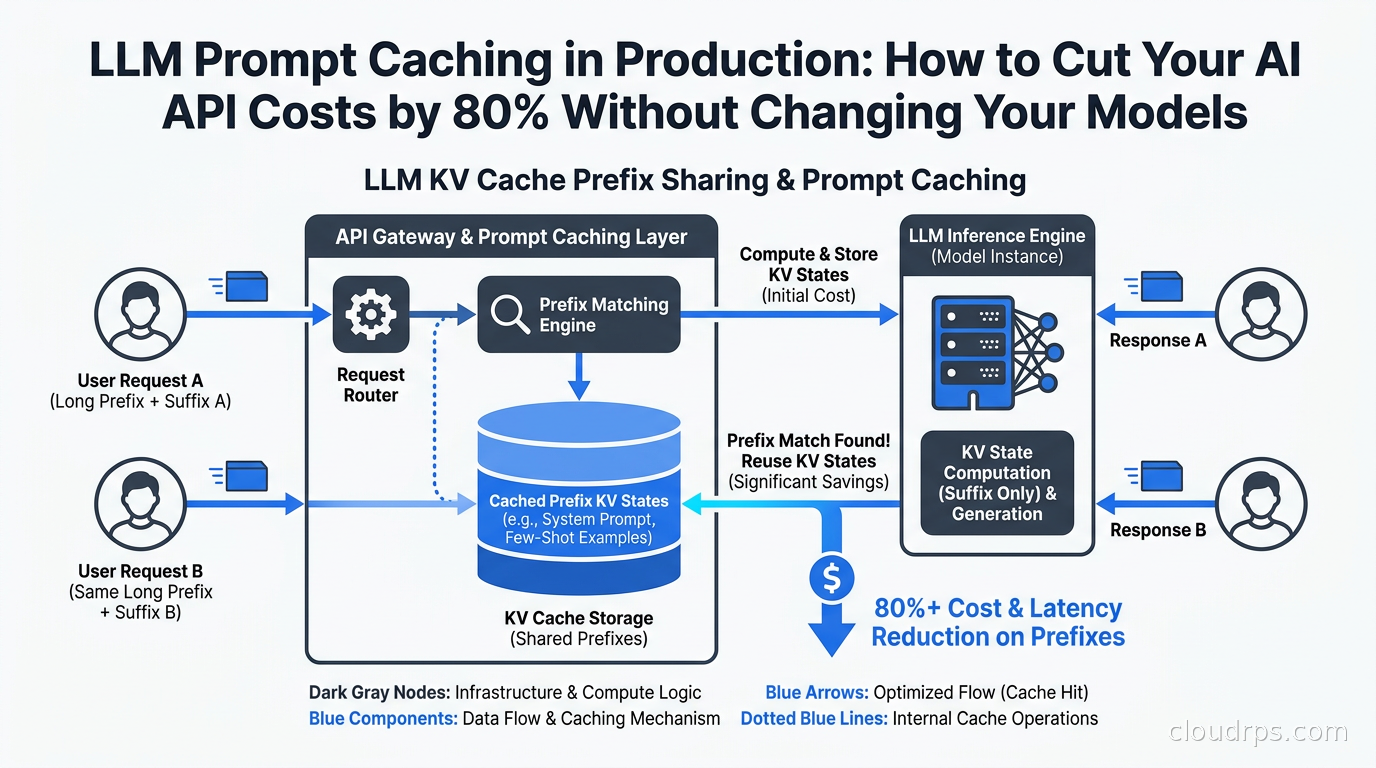
LLM Prompt Caching: Cut AI API Costs 80% in Production
How We Cut LLM Costs by 59% With Prompt Caching — ProjectDiscovery Blog
Prompt Caching: Tối Ưu Hiệu Suất và Chi Phí Khi Làm Việc Với LLM API ...
What is Prompt Caching ???. Imagine this: You’re interacting with a ...
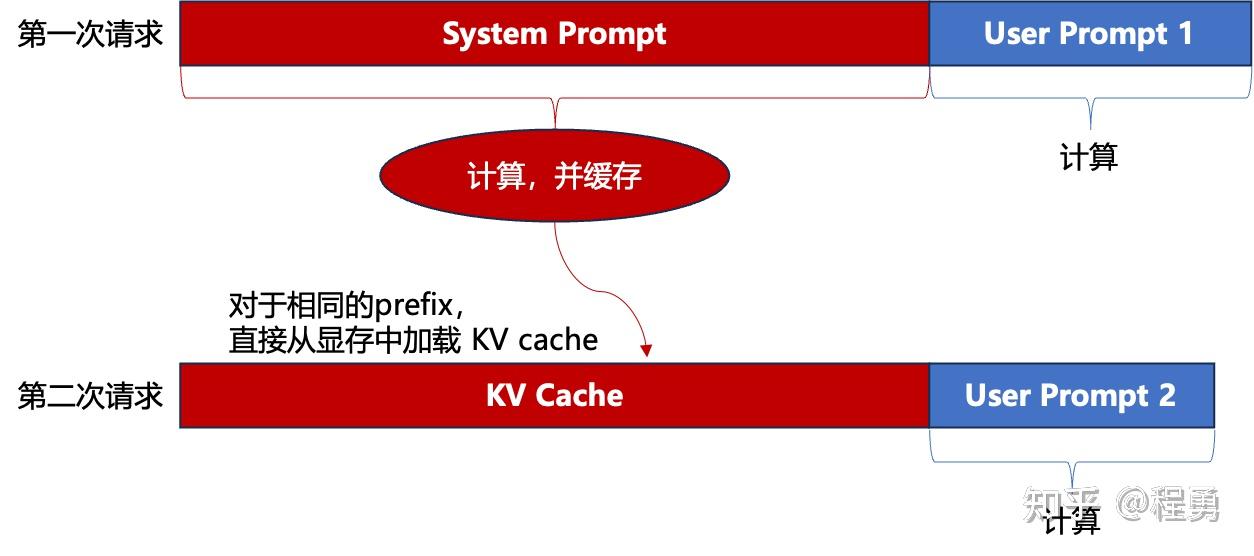
LLM推理:首token时延优化与System Prompt Caching - 知乎
Prompt Caching Explained: Improving Speed and Cost Efficiency in Large ...
Prompt Caching in LLMs: How It Reduces Cost, Improves Speed, and Scales ...
Prompt Caching in LLMs: Intuition | Langflow | Low-code AI builder for ...
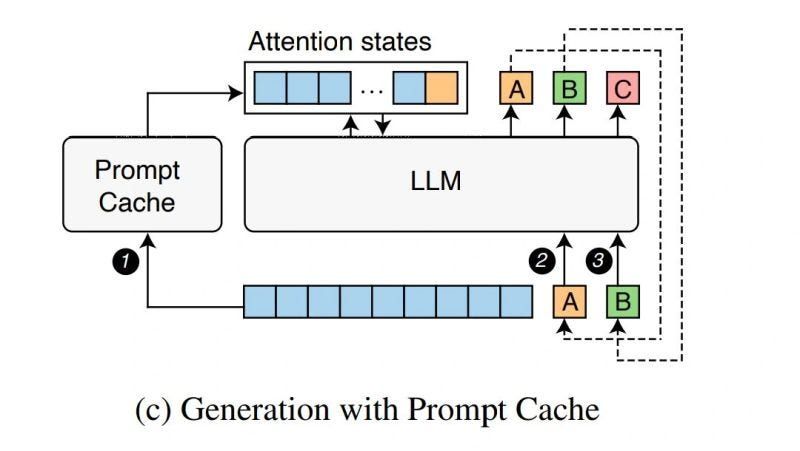
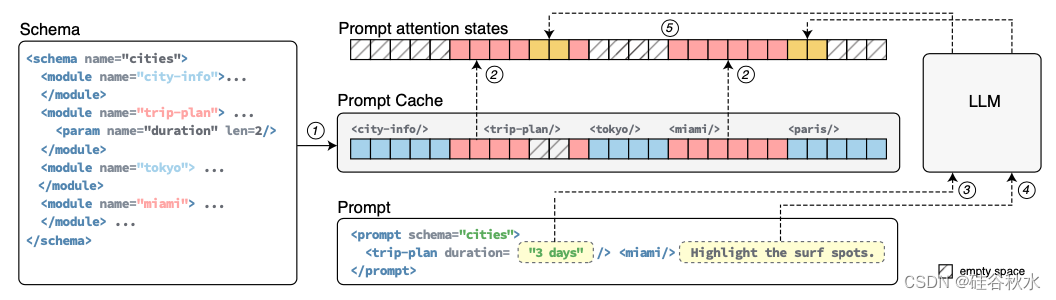
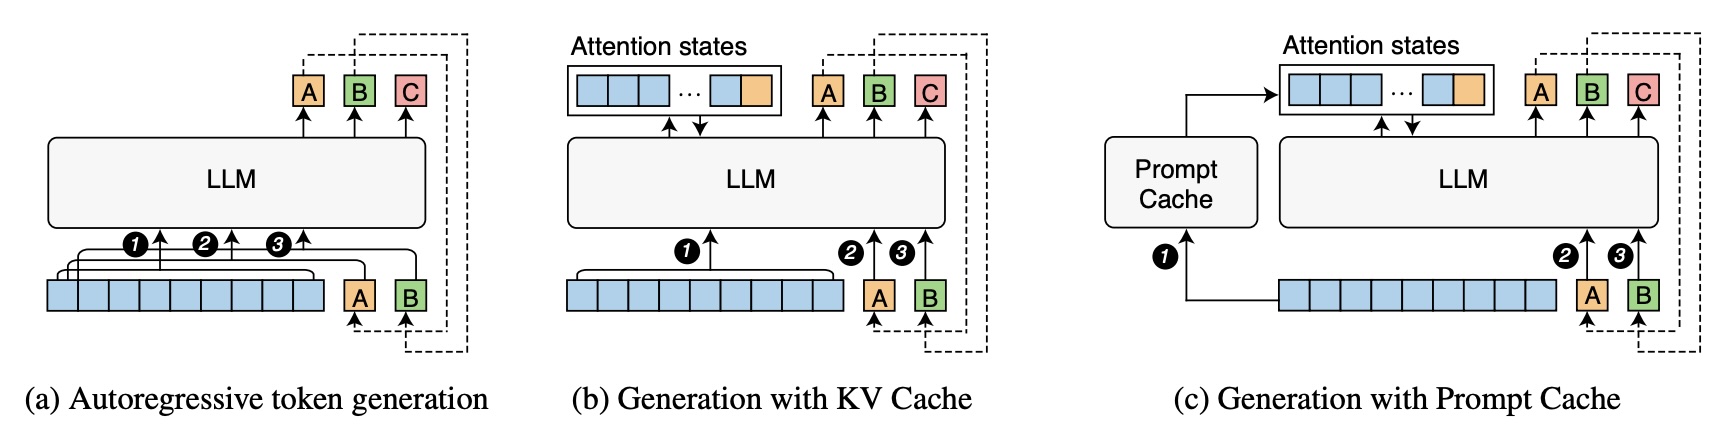
Prompt Cache:模块化注意重用实现低延迟推理_prompt cache: modular attention reuse for ...
How Prompt caching works? - API - OpenAI Developer Community
Prompt Caching Explained: A Smarter Method for Reusing Context to Cut ...
A Primer on LLM Security – Hacking Large Language Models for Beginners
Prompt Caching: A Guide With Code Implementation | DataCamp
Build Faster and Cheaper LLM Apps With Couchbase and LangChain - The ...
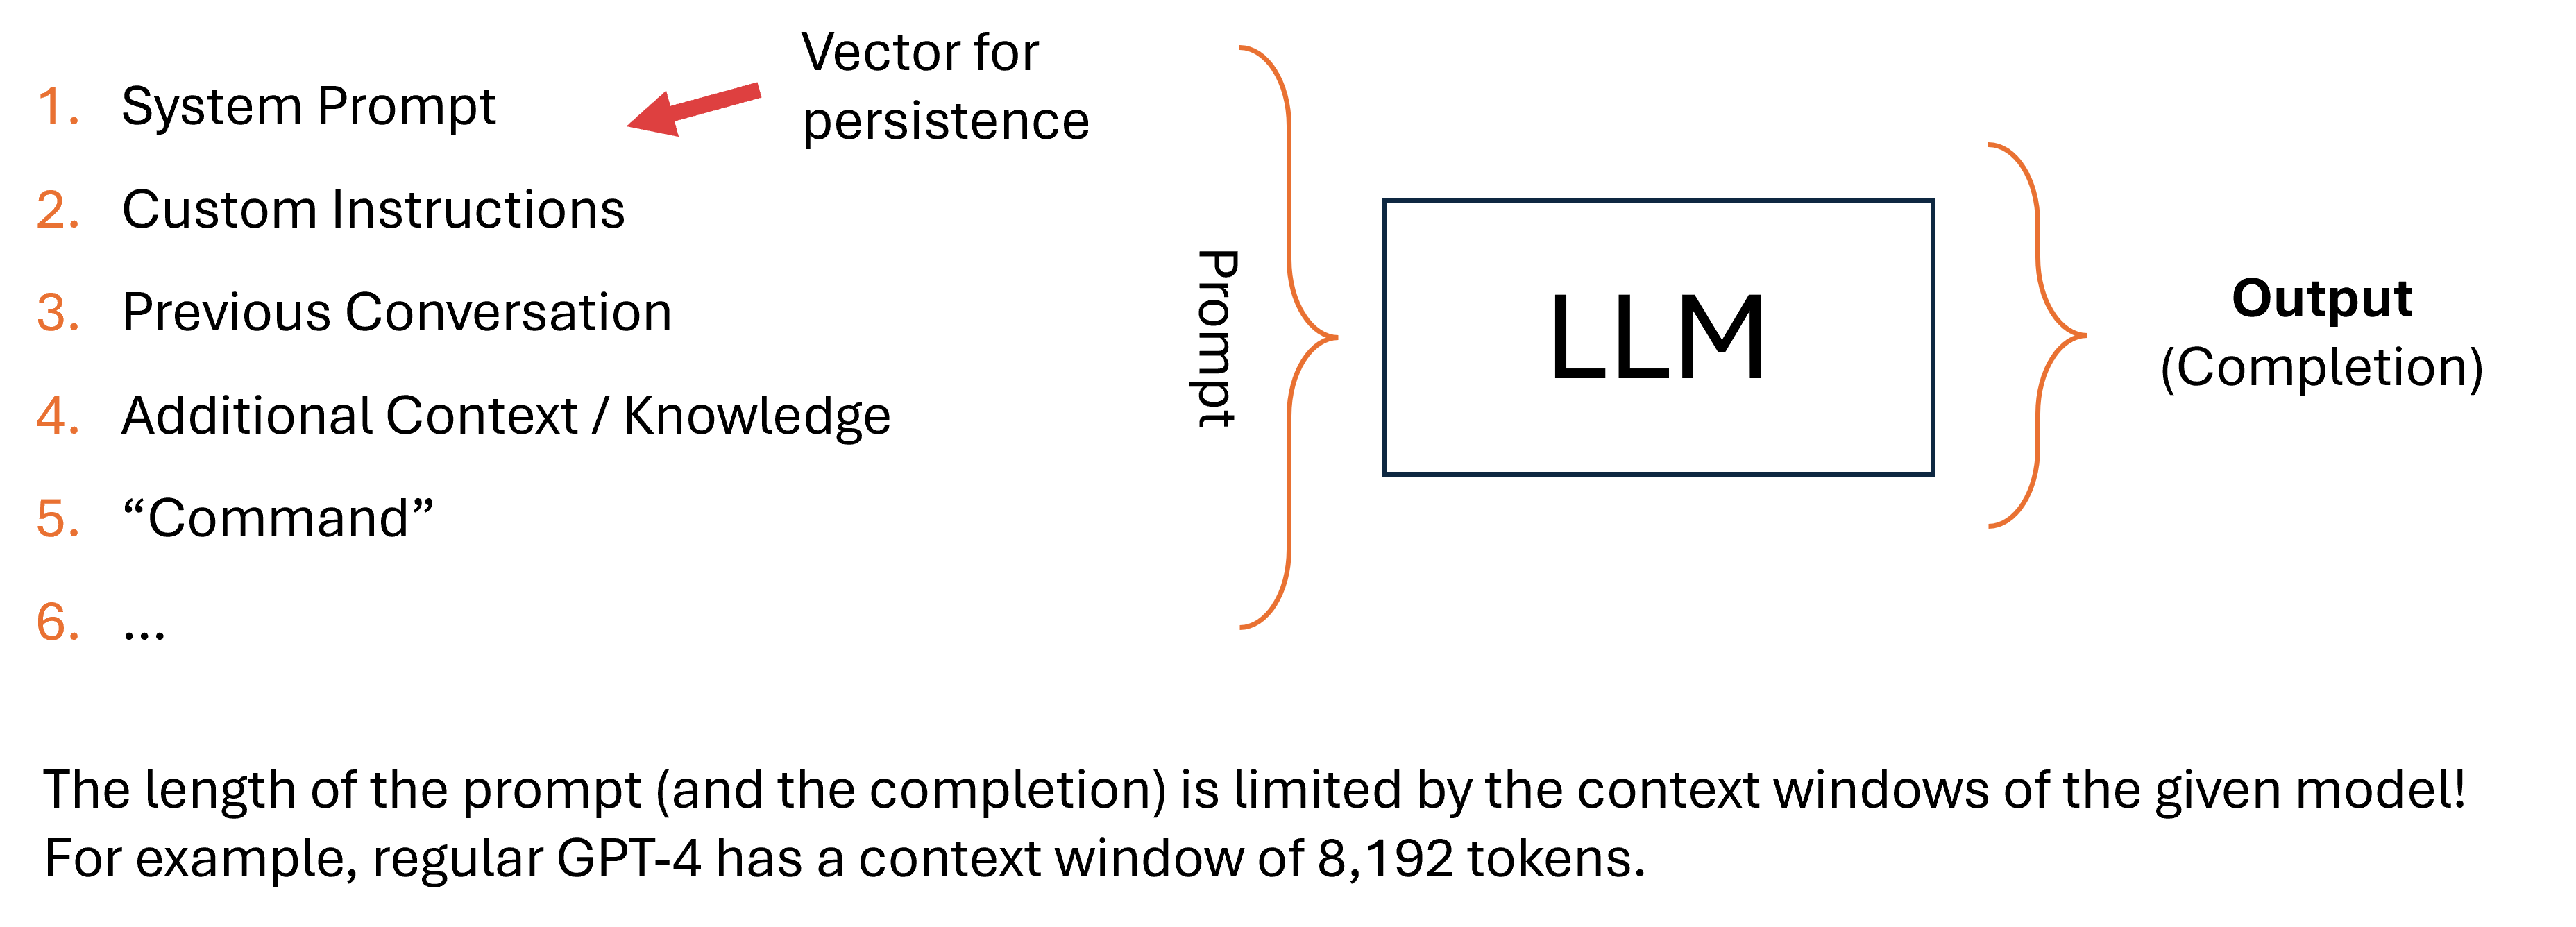
Behind an LLM’s Answer!! How system prompts, context, conversation ...
GitHub - yale-sys/prompt-cache: Modular and structured prompt caching ...
You’re Paying 10x Too Much for LLM Inference (And Your Provider Already ...
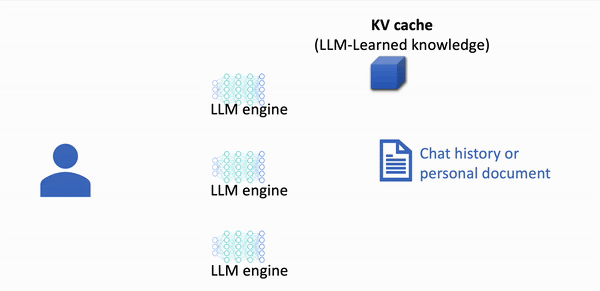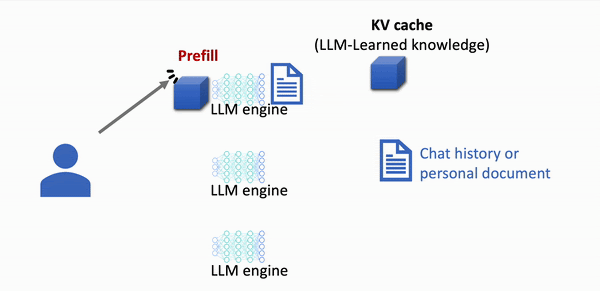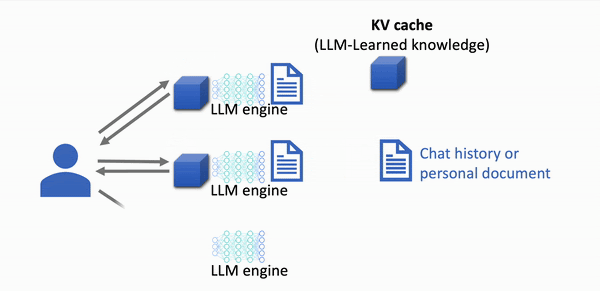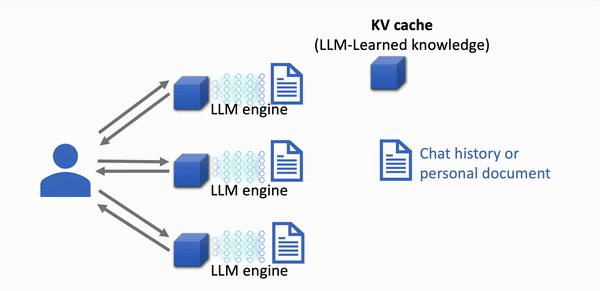
LMCache: Accelerating LLM Inference with Smart KV Caching (Part 1 of 2 ...
10 Técnicas de Optimización LLM para Reducir Costes 73% en Producción ...
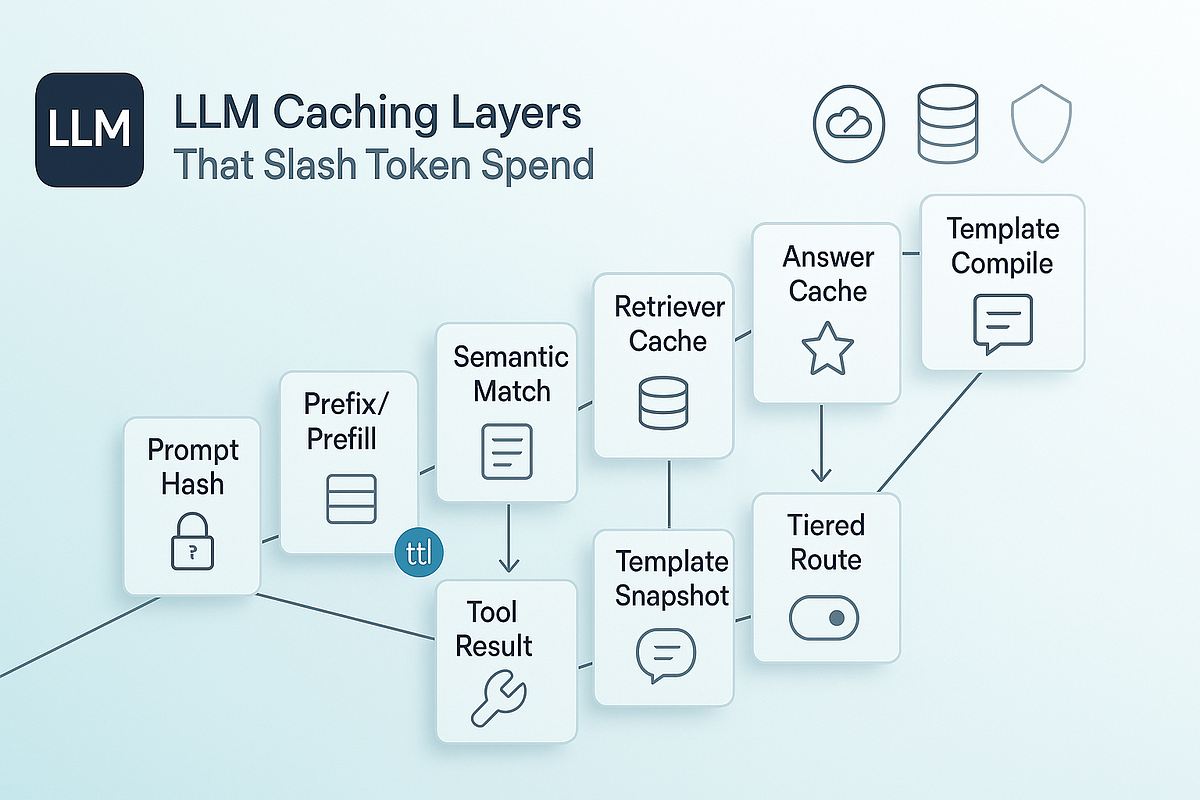
10 LLM Caching Layers That Slash Token Spend | by Syntal | Medium
Prompt Caching in LLMs: Intuition | Towards Data Science
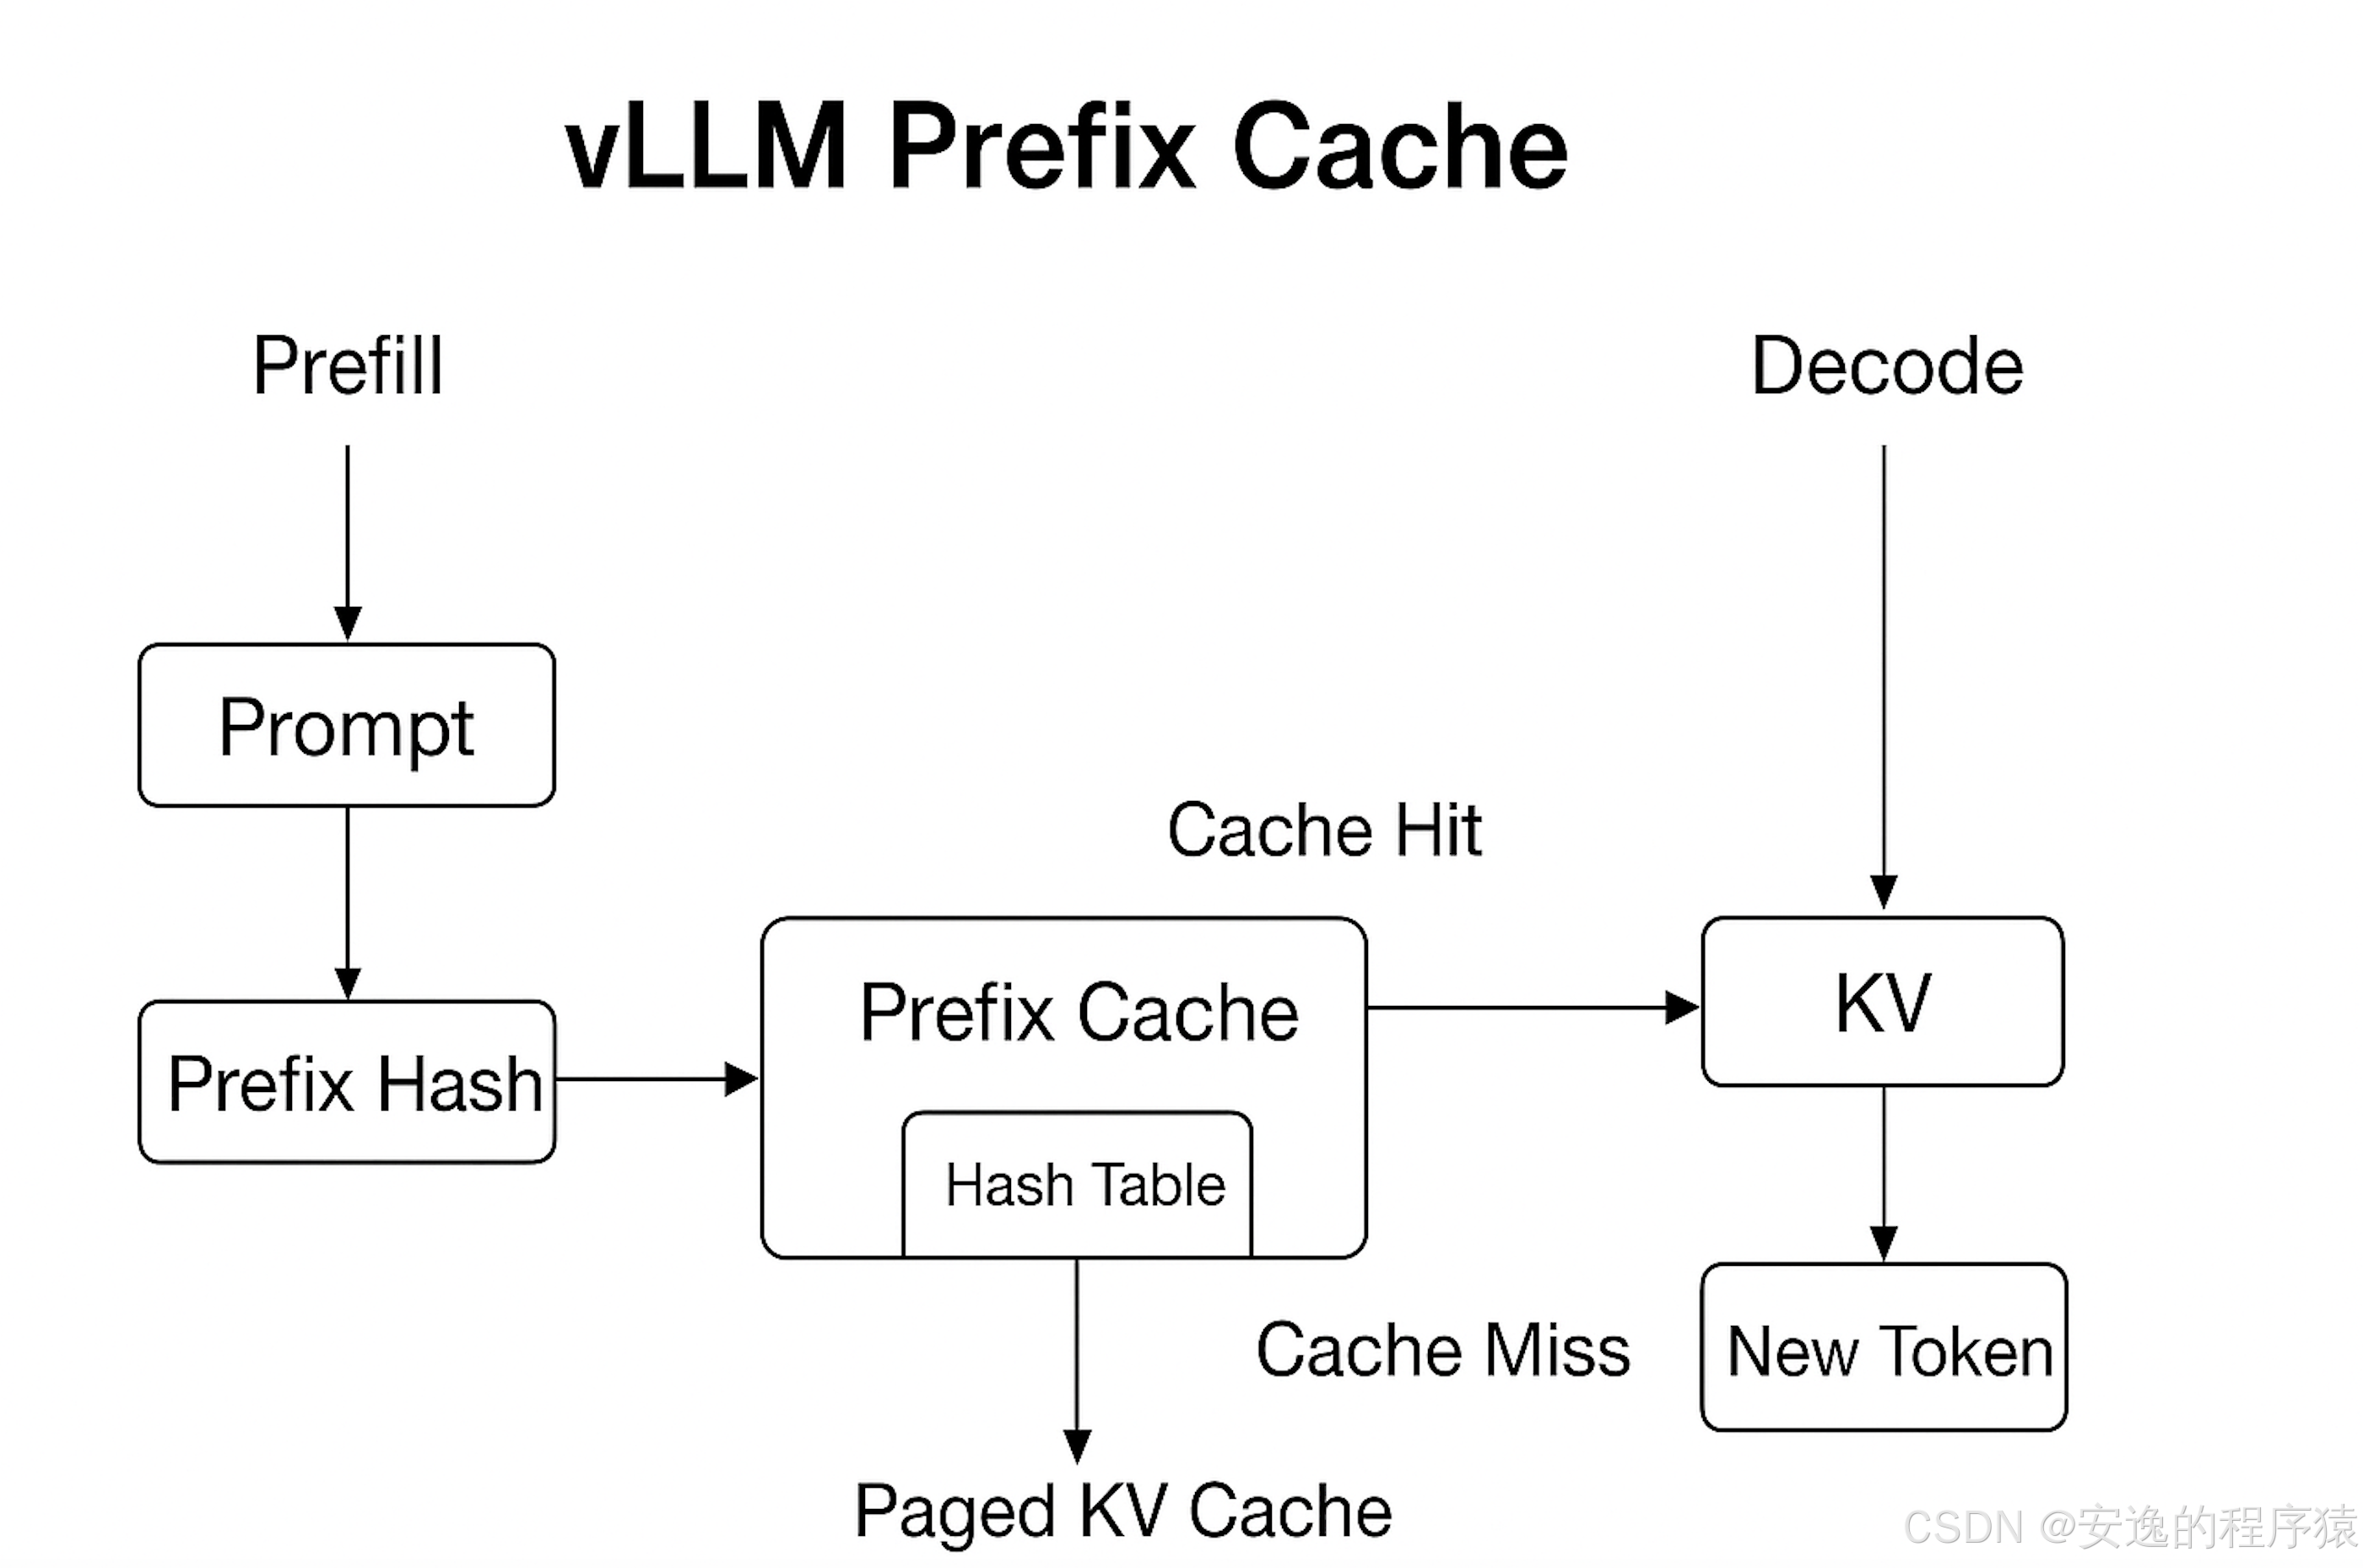
大模型推理框架vLLM 中的Prompt缓存实现原理_vllm prompt cache-CSDN博客
LLM Inference Series: 3. KV caching explained | by Pierre Lienhart | Medium
Langchain Prompt Caching | IBM
All You Need to Know About Prompt Caching for LLMs
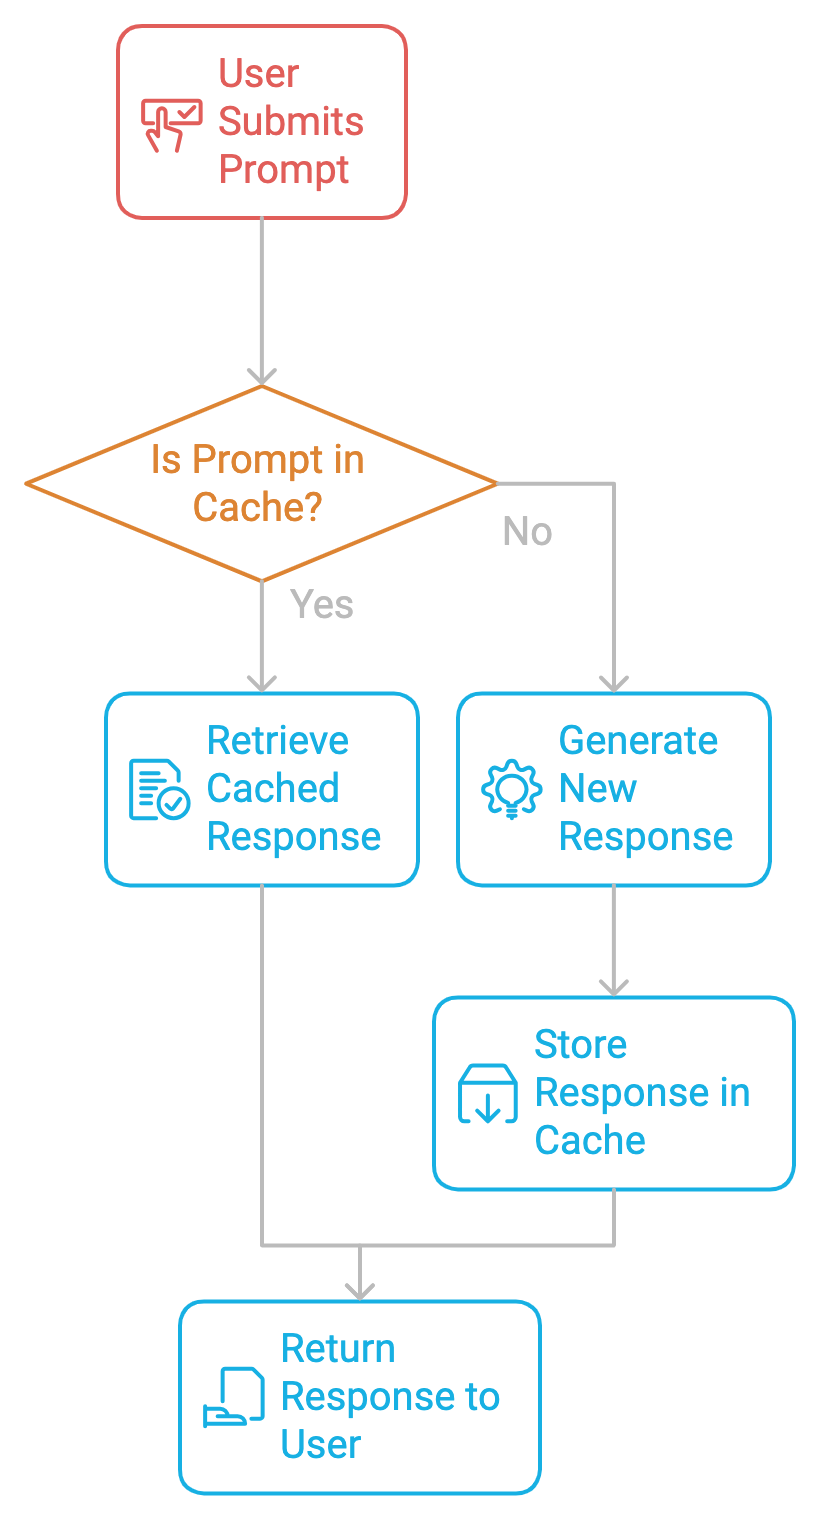
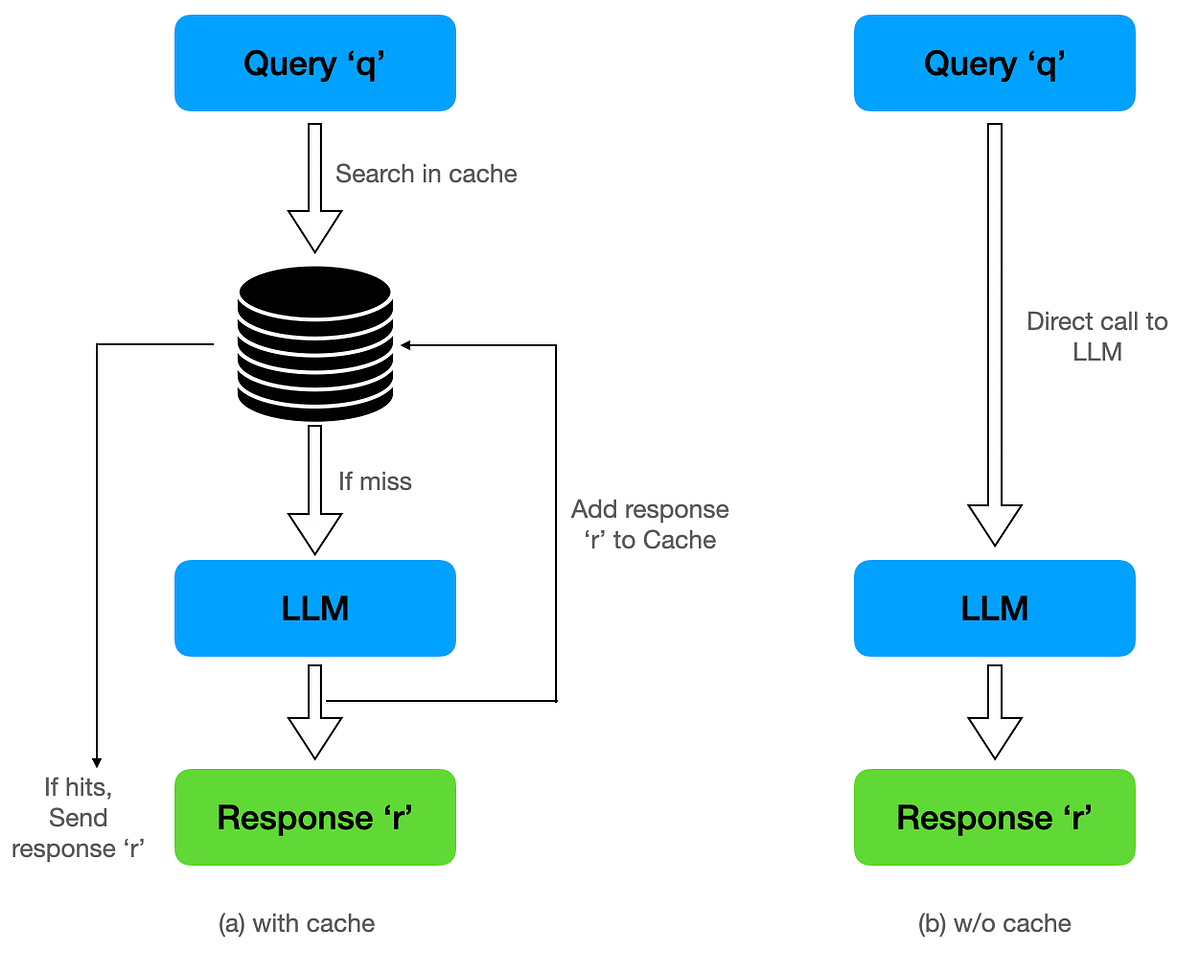
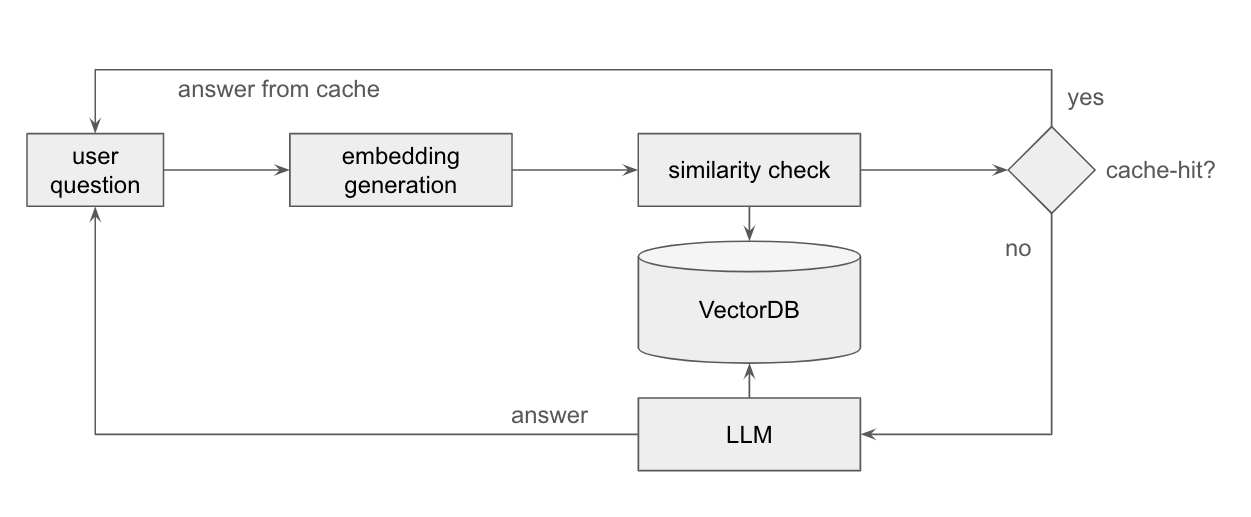
The Beginner’s Guide to Semantic Caching in LLM Systems
OWASP Top 10 for LLM Applications - Securiti
Prompt Caching in Production 2026: How OpenAI and Anthropic Reduce 90% ...
KnowledgeFocus LLM Node - GoInsight.AI
Prompt Caching, LiteLLM, and the 8,600‑Token Bug: A Practical Guide to ...
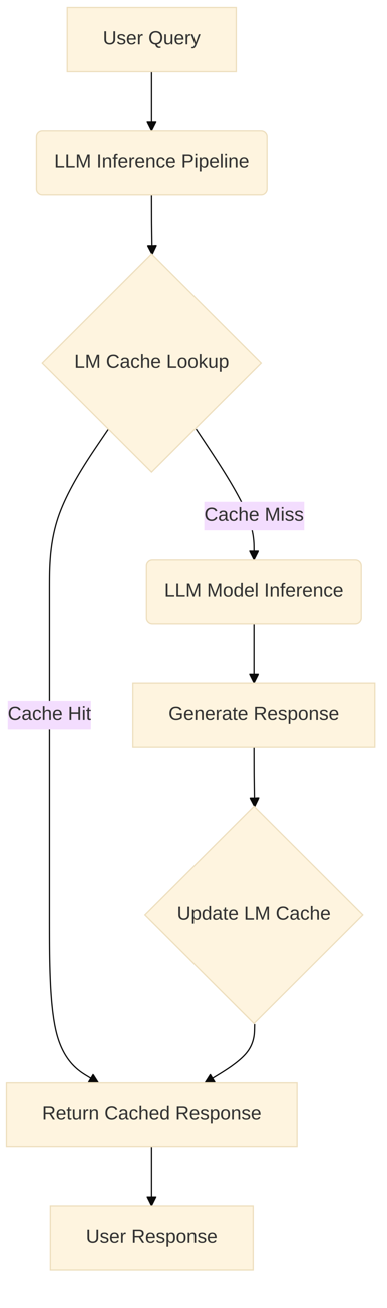
Optimizing LLM Performance with LM Cache: Architectures, Strategies ...
Learn How to get 10x better results from LLM models 😌 ?? An ...
Prompt caching with LLM’s. Introduction | by Smit Agrawal | Medium
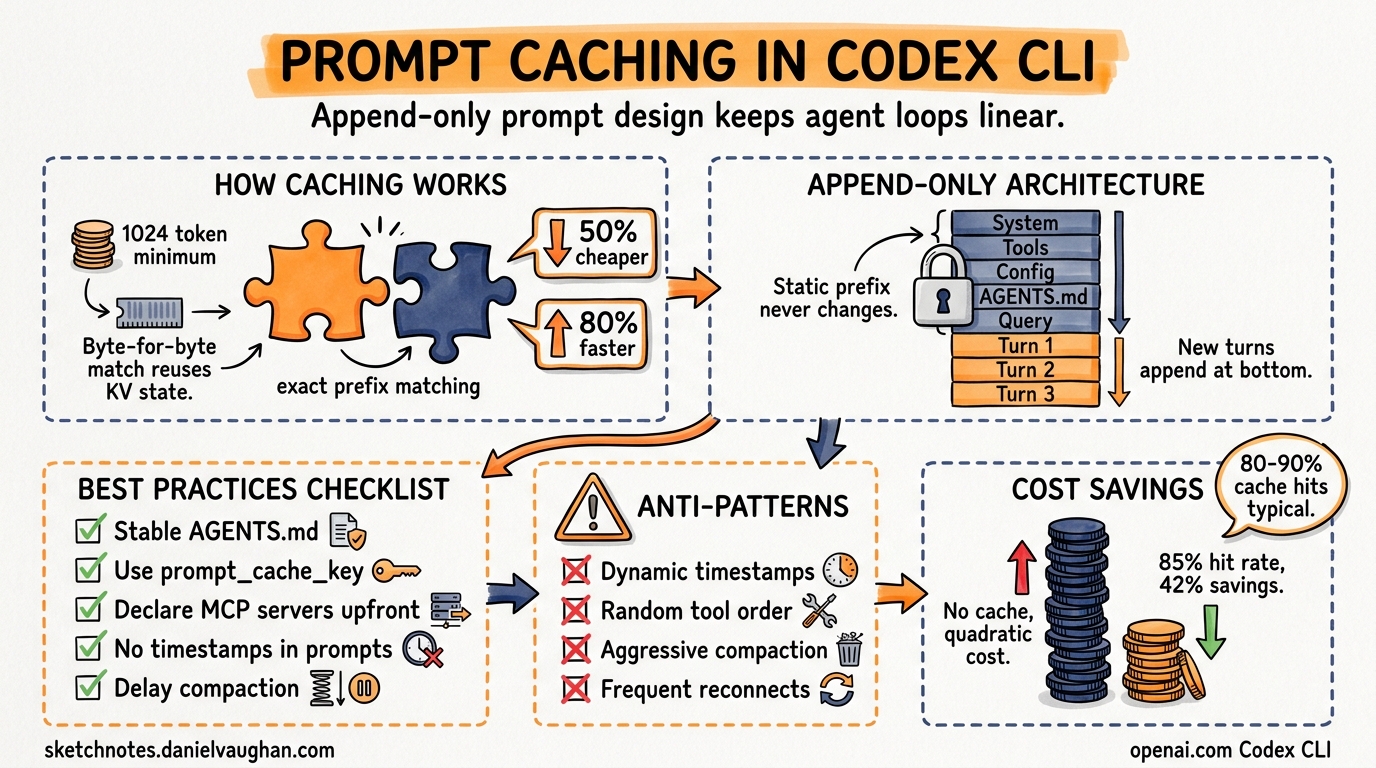
Prompt Caching in Codex CLI: How the Agent Loop Stays Linear and How to ...
What is prompt caching? How can product managers leverage it to develop ...
Semantic Caching for LLM Inference: GPTCache, Redis Vector Cache, and ...
LLM Panels in Logfire: Inspect LLM App Spans
LLM Caching
How LLMs Treat System and User Prompts | by Himanshu Bhoir | Medium
What is Prompt caching? Prompt caching has now become a common feature ...
Medium
Caching techniques in ML systems design | UnfoldAI
LLMのprompt caching完全解説 | AIFCC
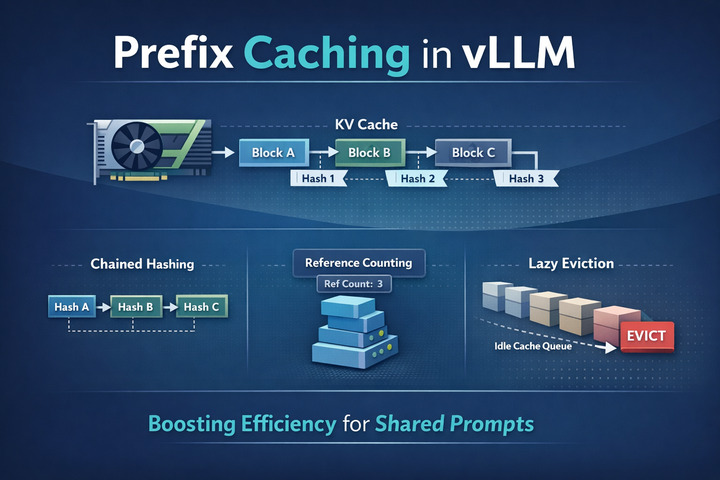
[Prefill优化][万字]🔥原理&图解vLLM Automatic Prefix Cache(RadixAttention): 首 ...
vLLM Prefix Caching详解:引用计数与LRU缓存驱逐策略 - 知乎
Optimizing Latency and Cost via Attention, Prompt, and Semantic Caching ...
原理&图解vLLM Automatic Prefix Cache首Token时延优化 - 极术社区 - 连接开发者与智能计算生态
Patterns for Building LLM-based Systems & Products
Unlock Efficiency: Slash Costs and Supercharge Performance with ...
prompt-cache论文速读 - Zhang
Claude Code 実践ガイド | 中小企業のためのAI活用
GitHub - LMCache/LMBenchmark: Systematic and comprehensive benchmarks ...
LMCache
AI时代的猫鼠游戏 -- 一文快速了解LLM“越狱” - 知乎
一文读懂LLM API应用开发基础(万字长文)-CSDN博客
Local Large Language Models
PromptCaching 为什么总不命中?拆解 4 家LLM API 的缓存规则与排查清单_缓存命中的规则-CSDN博客
LLM의 답변을 결정하는 시스템 프롬프트란?