Showing 119 of 119on this page. Filters & sort apply to loaded results; URL updates for sharing.119 of 119 on this page
Post-Training Quantization of LLMs with NVIDIA NeMo and NVIDIA TensorRT ...
TensorRT quantization Optimization - TensorRT - NVIDIA Developer Forums
Quantization icon design | Premium AI-generated vector
Creative quantization icon | Premium AI-generated vector
TensorRT NOT match result from pytorch quantization · Issue #988 ...
Quantization flow using TensorRT (what is recommended for CNN?) · Issue ...
Object Detection at 2530 FPS with TensorRT and 8-Bit Quantization ...
INT8 Quantization of dinov2 TensorRT Model is Not Faster than FP16 ...
Cannot export models to TensorRT with int8 quantization · Issue #82463 ...
使用 NVIDIA TensorRT 在 Apache Beam 中简化和加速机器学习预测 - NVIDIA 技术博客
Float8 (FP8) Quantized LightGlue in TensorRT with NVIDIA Model ...
End-to-End AI for NVIDIA-Based PCs: NVIDIA TensorRT Deployment | NVIDIA ...
NVIDIA TensorRT Accelerates Stable Diffusion Nearly 2x Faster with 8 ...
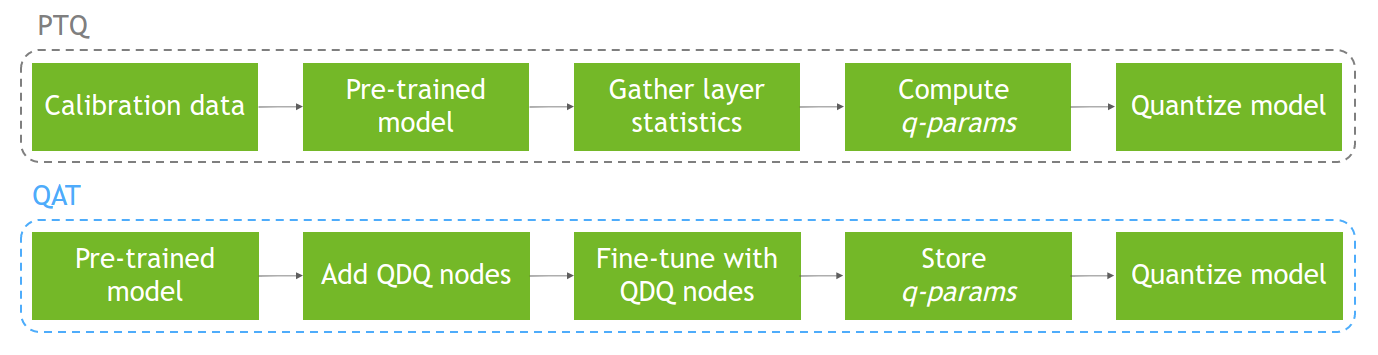
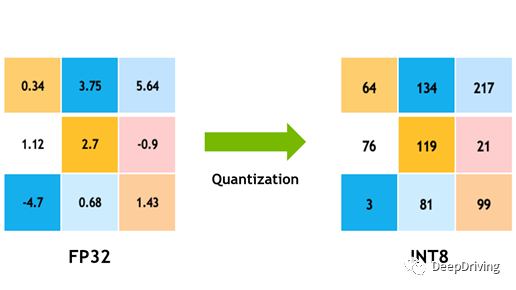
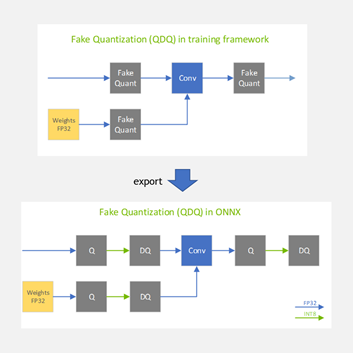
利用 NVIDIA TensorRT 量化感知训练实现 INT8 推理的 FP32 精度 - NVIDIA 技术博客
NVIDIA TensorRT 8.6.11 Developer Guide for DRIVE OS :: NVIDIA TensorRT ...
NVIDIA TensorRT 通过 8 位预训练量化将 Stable Diffusion 的速度提升近 2 倍 - NVIDIA 技术博客
TensorRT to faster inference for Deeplearning Model- Viblo
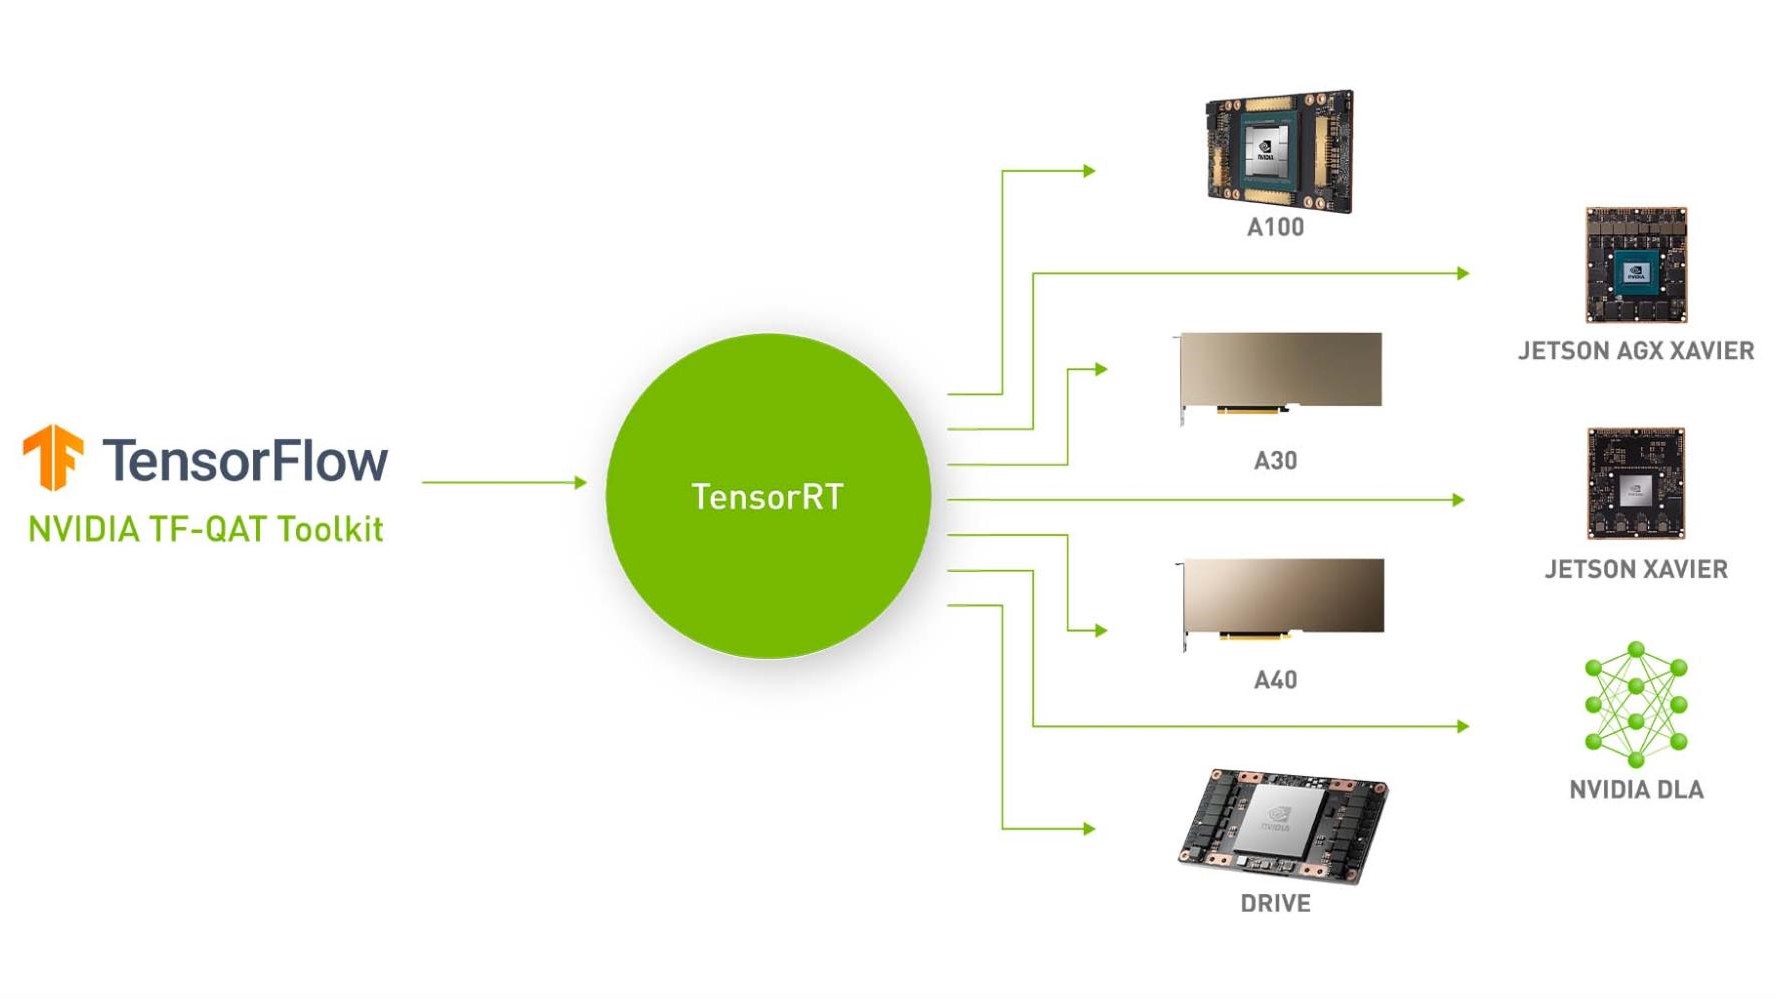
NVIDIA 技术博客:使用 NVIDIA QAT 工具包为 TensorFlow 和 NVIDIA TensorRT 加速量化网络-CSDN社区
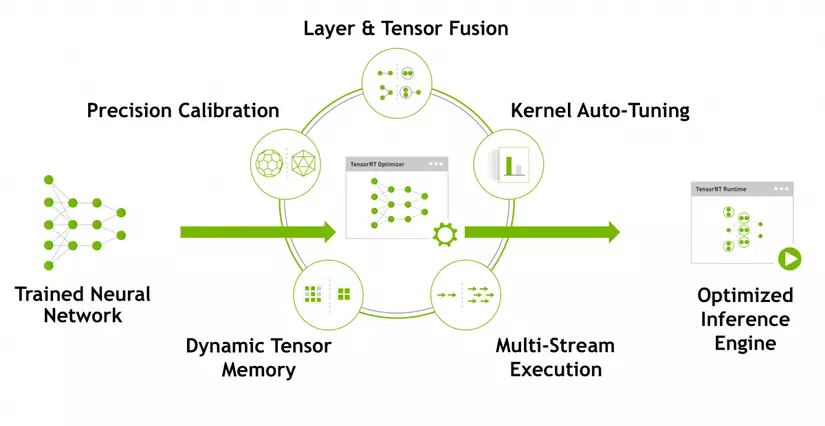
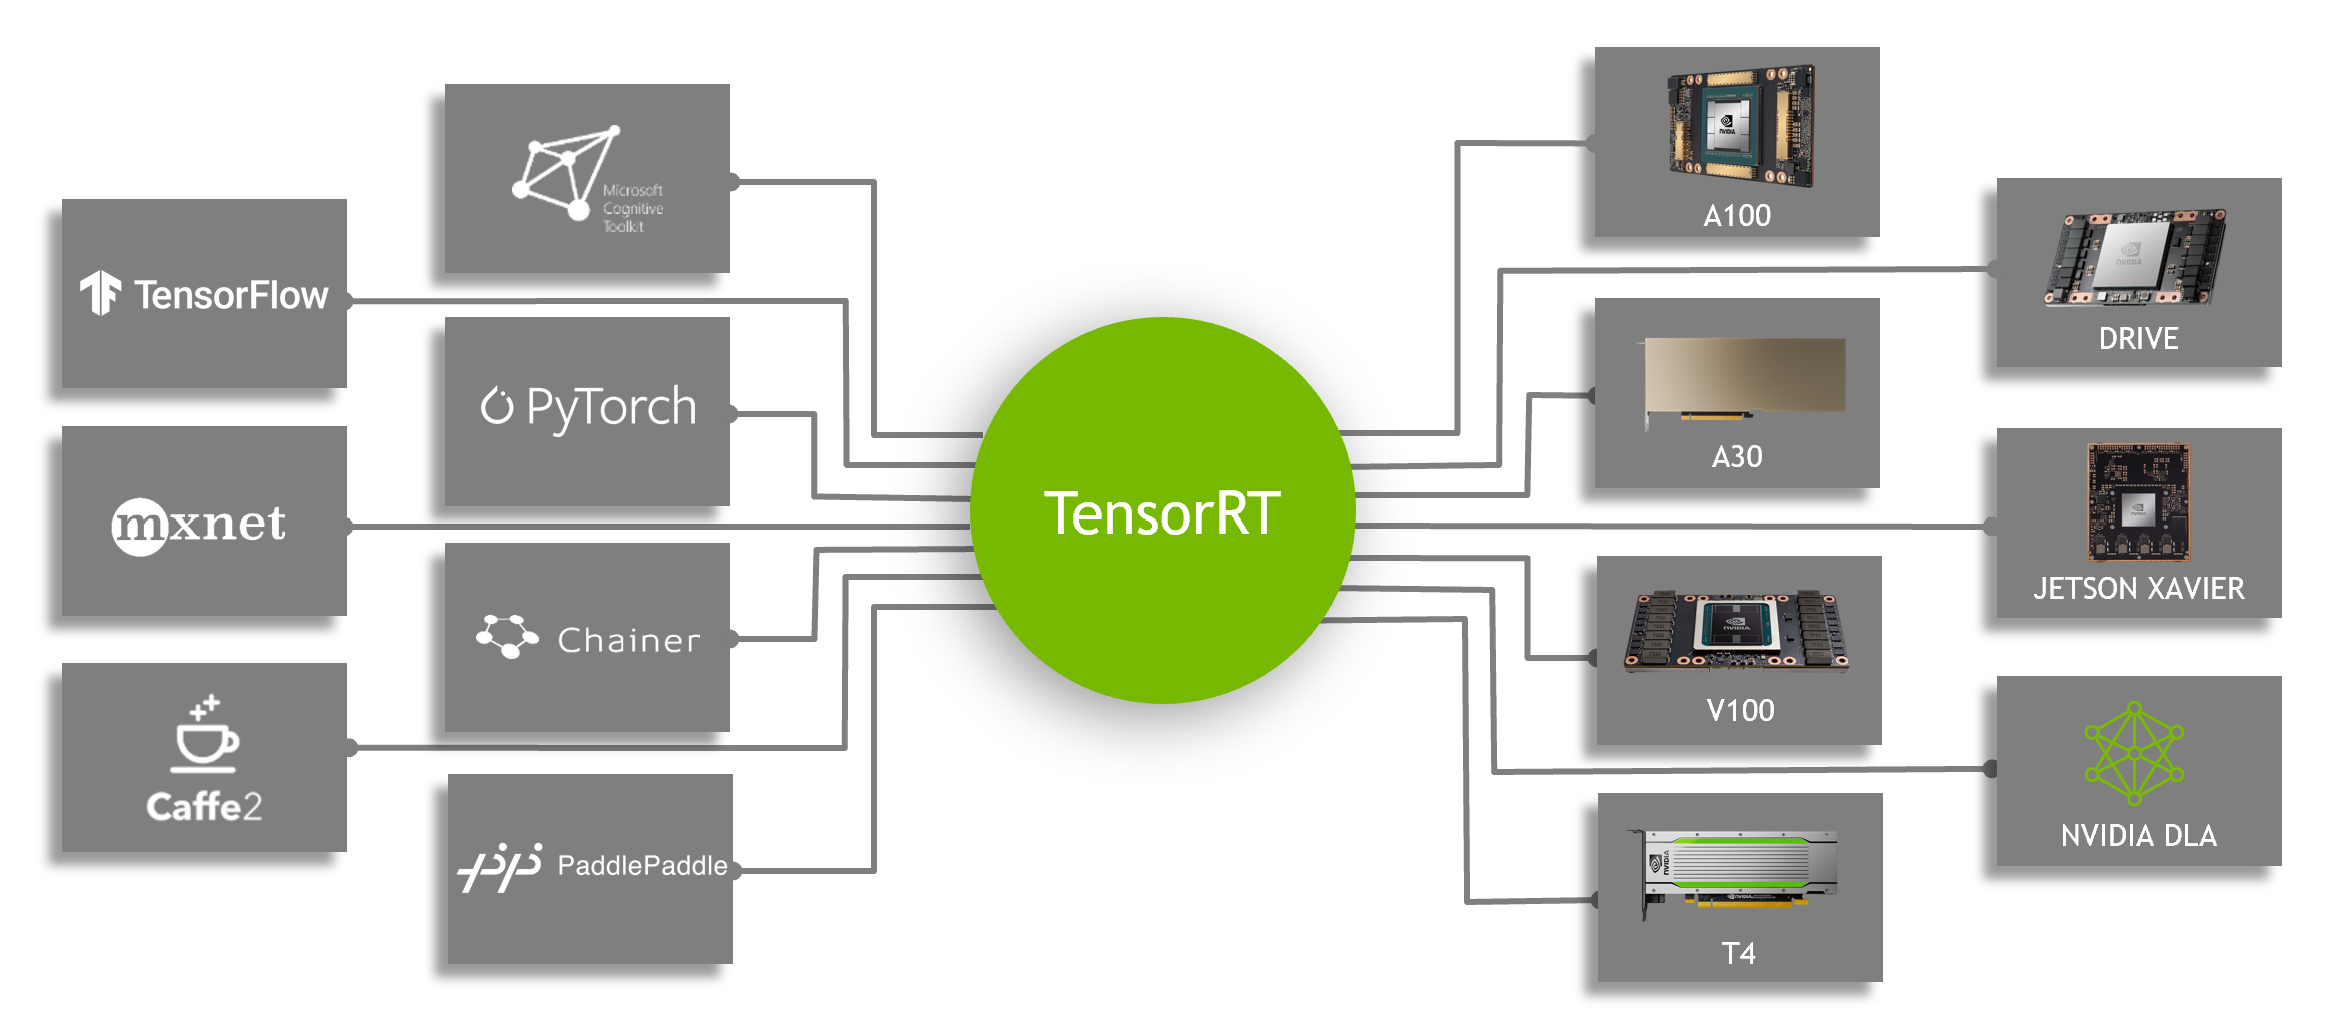
TensorRT SDK | NVIDIA Developer
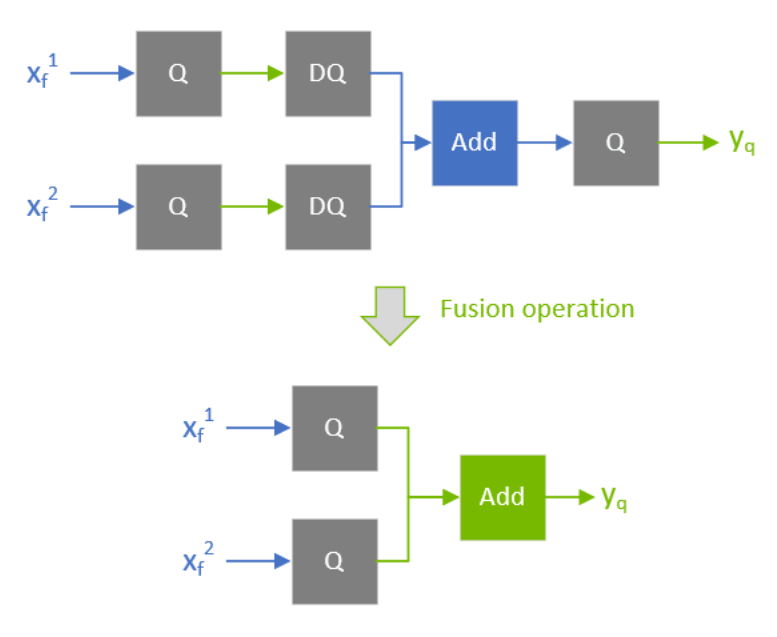
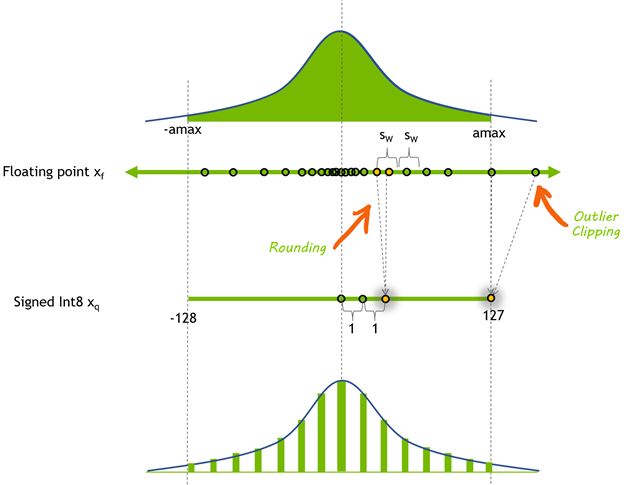
Achieving FP32 Accuracy for INT8 Inference Using Quantization Aware ...
Working with Quantized Types — NVIDIA TensorRT 10.10.10 Developer Guide ...
使用 NVIDIA QAT 工具包为 TensorFlow 和 NVIDIA TensorRT 加速量化网络 - NVIDIA 技术博客
Quantum Entanglement Flat Icon 39495594 Vector Art at Vecteezy
TensorRT - TensorRT - NVIDIA Developer Forums
Quantitative Meticulous Yellow shadow icon
10+ Vector Quantization Stock Illustrations, Royalty-Free Vector ...
TensorRT Quantization: NVIDIA's INT8 Inference SDK | Inference Systems
Quantization Methods | geoffreyQiu/TensorRT-LLM | DeepWiki
How am I able to make TensorRT work and quantize the AI model to FP4 ...
Restructuring Vector Quantization with the Rotation Trick
基于 tensorrt 量化模型 | 年轻人起来冲
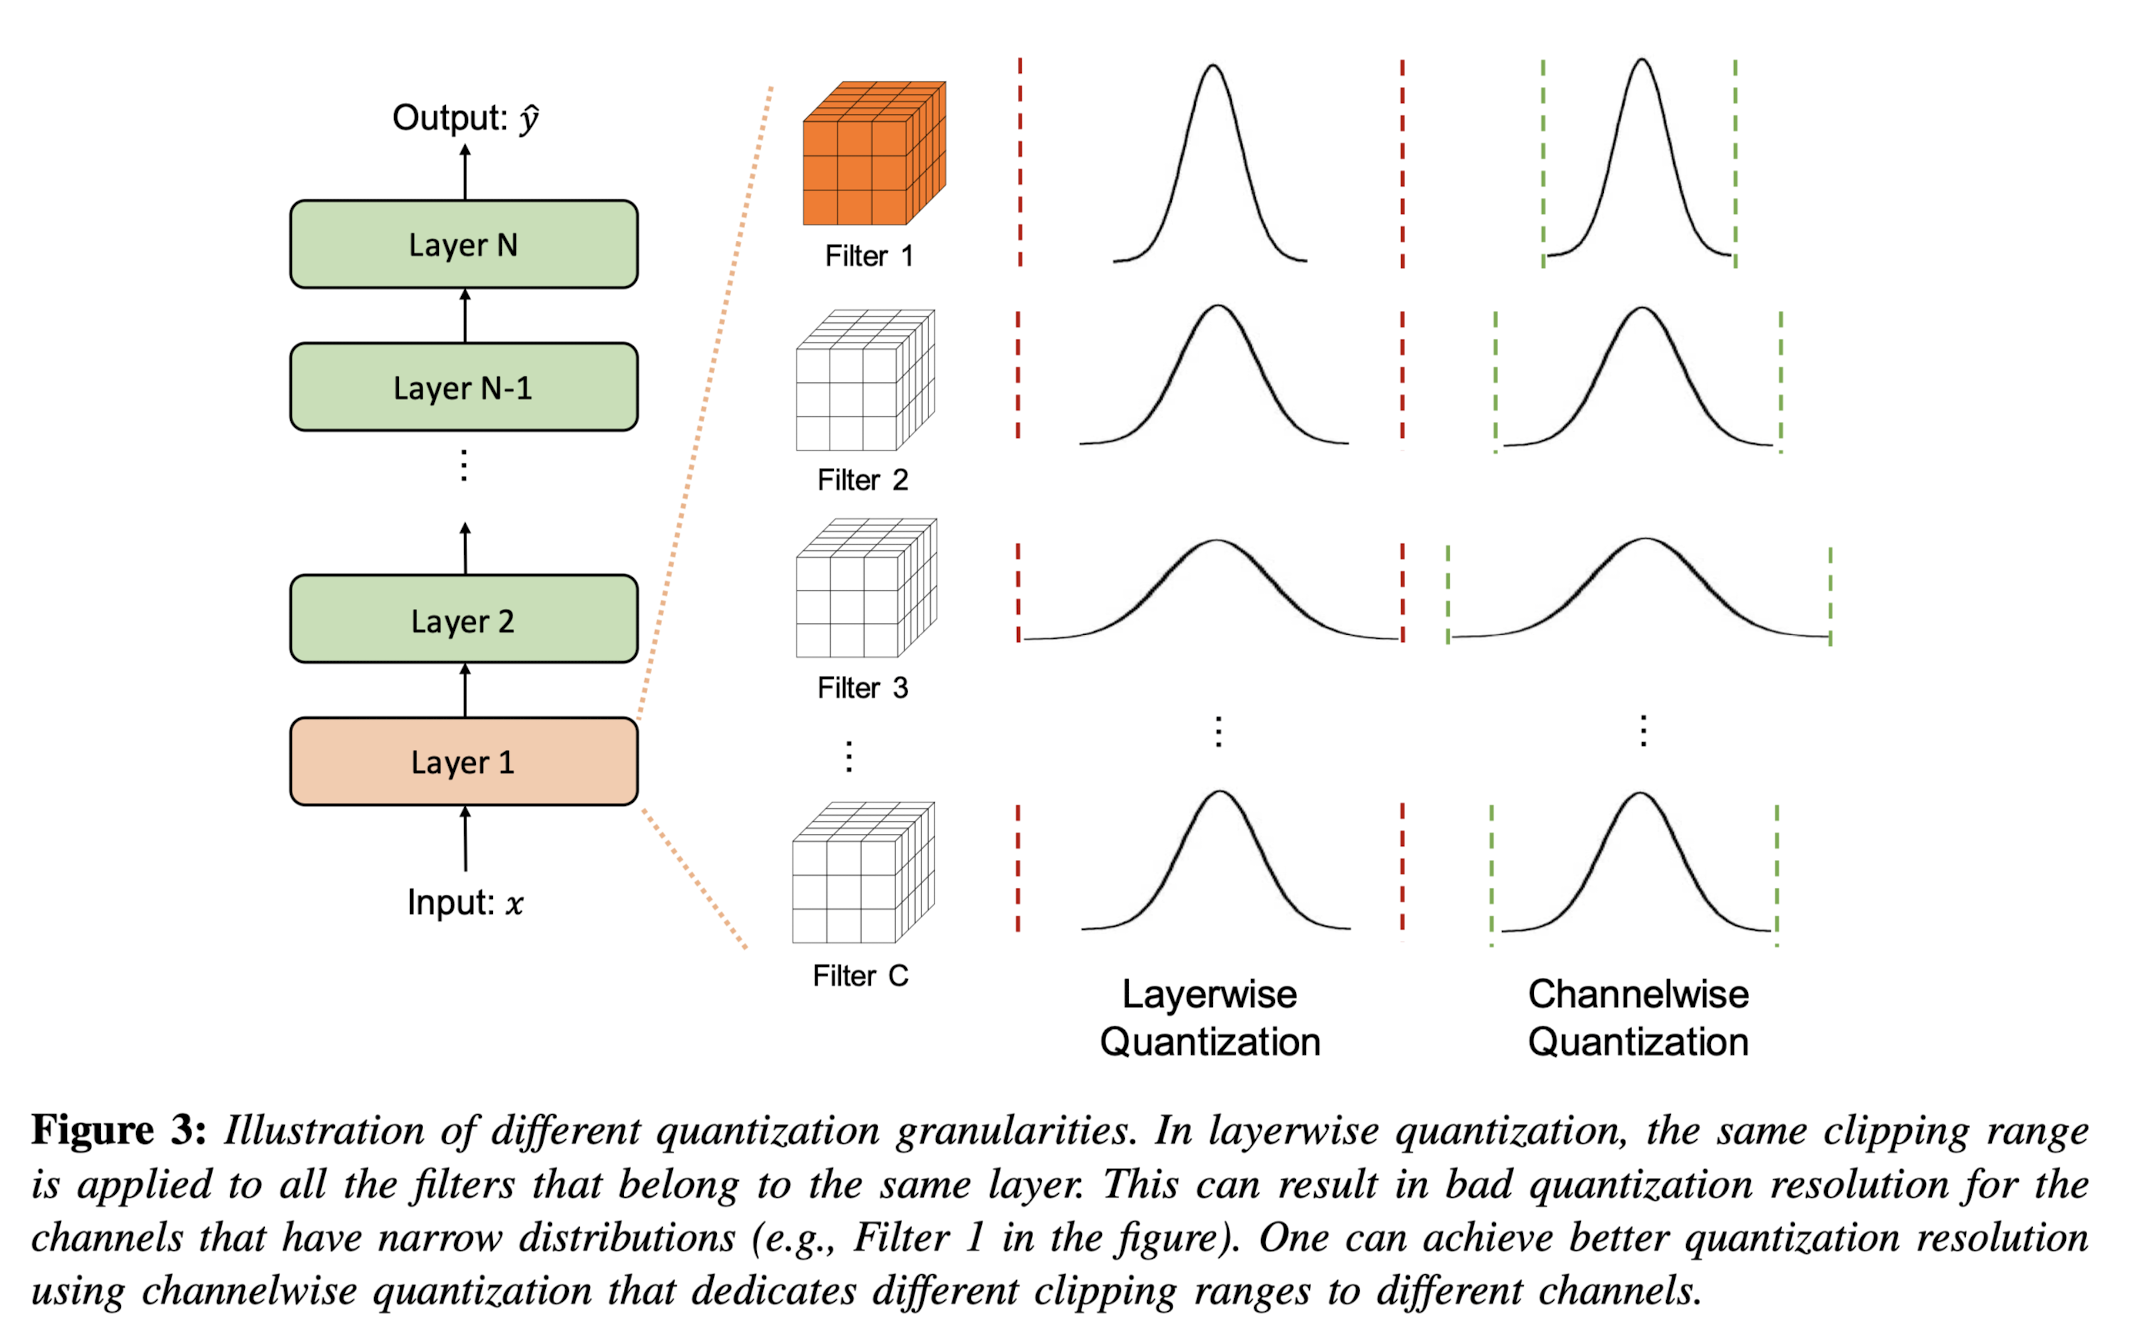
Per channel quantization · Issue #2392 · NVIDIA/TensorRT · GitHub
SmoothQuant: Accurate and Efficient Post-Training Quantization for ...
Canonical quantization hi-res stock photography and images - Alamy
How to Quantize Transformer-based model for TensorRT Deployment - The ...
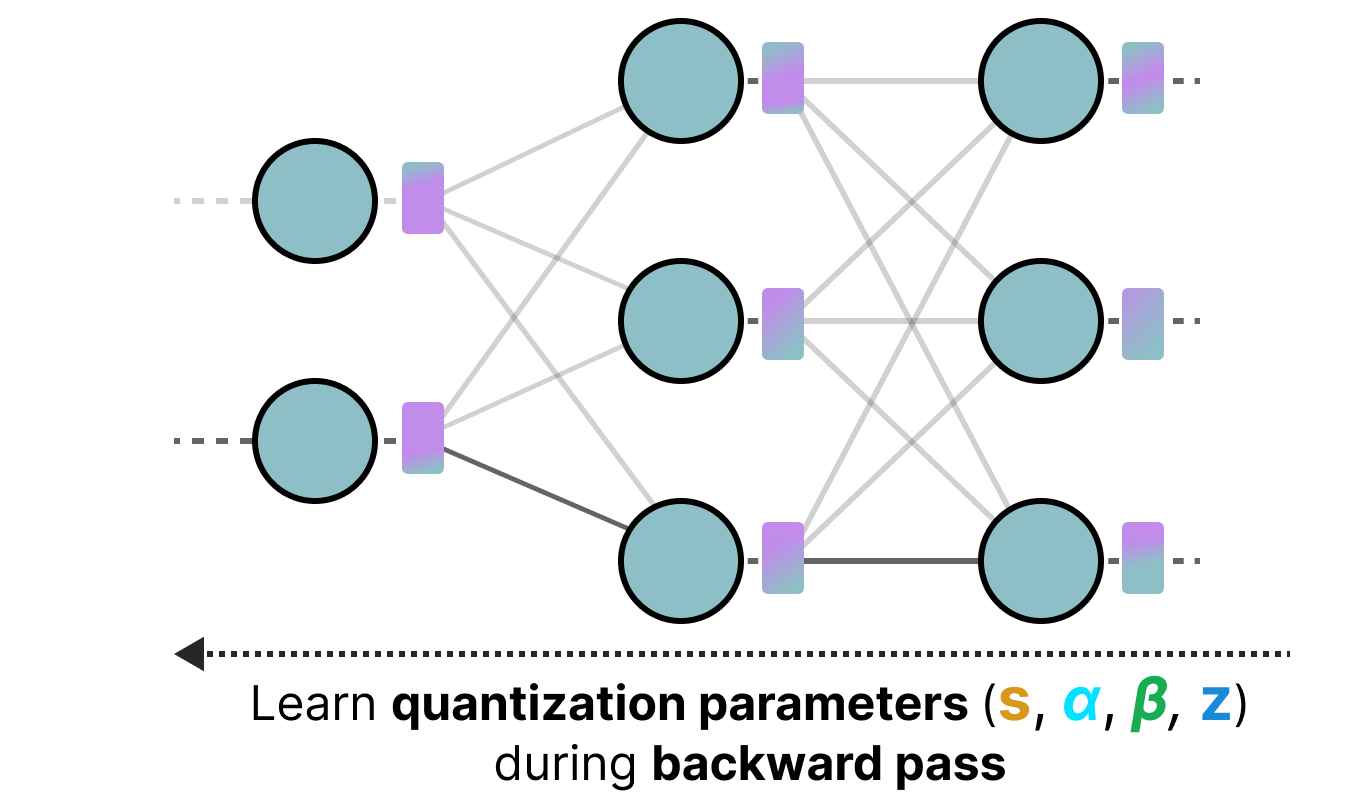
A Visual Guide to Quantization - by Maarten Grootendorst
Working with Quantized Types — NVIDIA TensorRT
INT8 quantization with same model and different weights · Issue #2705 ...
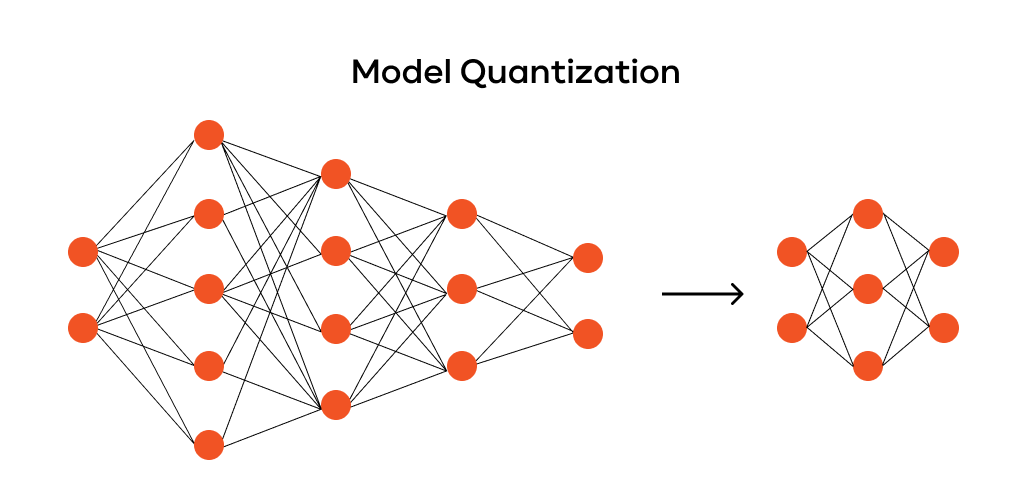
Model Quantization - A Lazy Data Science Guide
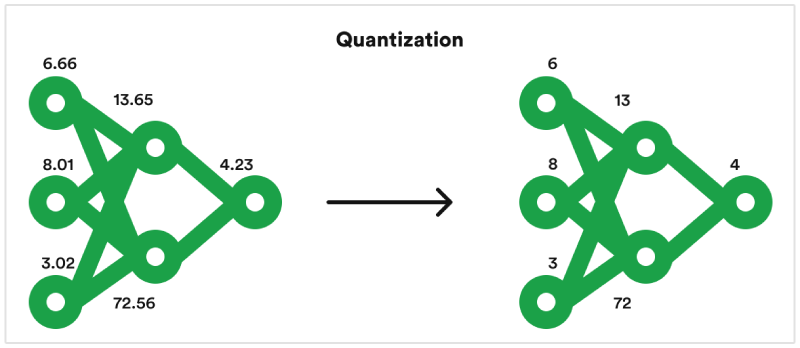
Quantization in the context of deep learning and neural networks
NVIDIA TensorRT 8.5.10 Developer Guide for DRIVE OS :: NVIDIA TensorRT ...
Adaptive Inference in NVIDIA TensorRT for RTX Enables Automatic ...
[vLLM vs TensorRT-LLM] #6. Weight-Only Quantization - SqueezeBits ...
how to disable per-channel quantization · Issue #2414 · NVIDIA/TensorRT ...
Incredible Color Image Quantization Matlab References
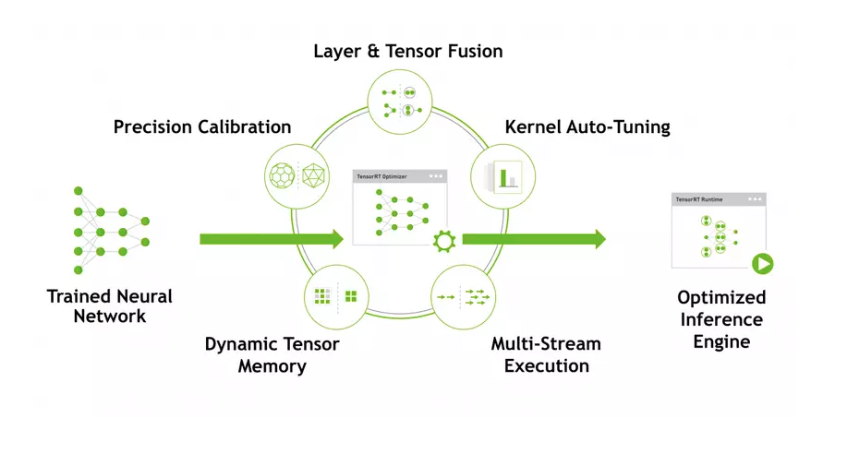
TensorRT - Sự vượt trội với bài toán tối ưu mô hình Deep Learning - Viblo
NVIDIA TensorRT 10.0 Upgrades Usability, Performance, and AI Model ...
Optimizing LLMs for Performance and Accuracy with Post-Training ...
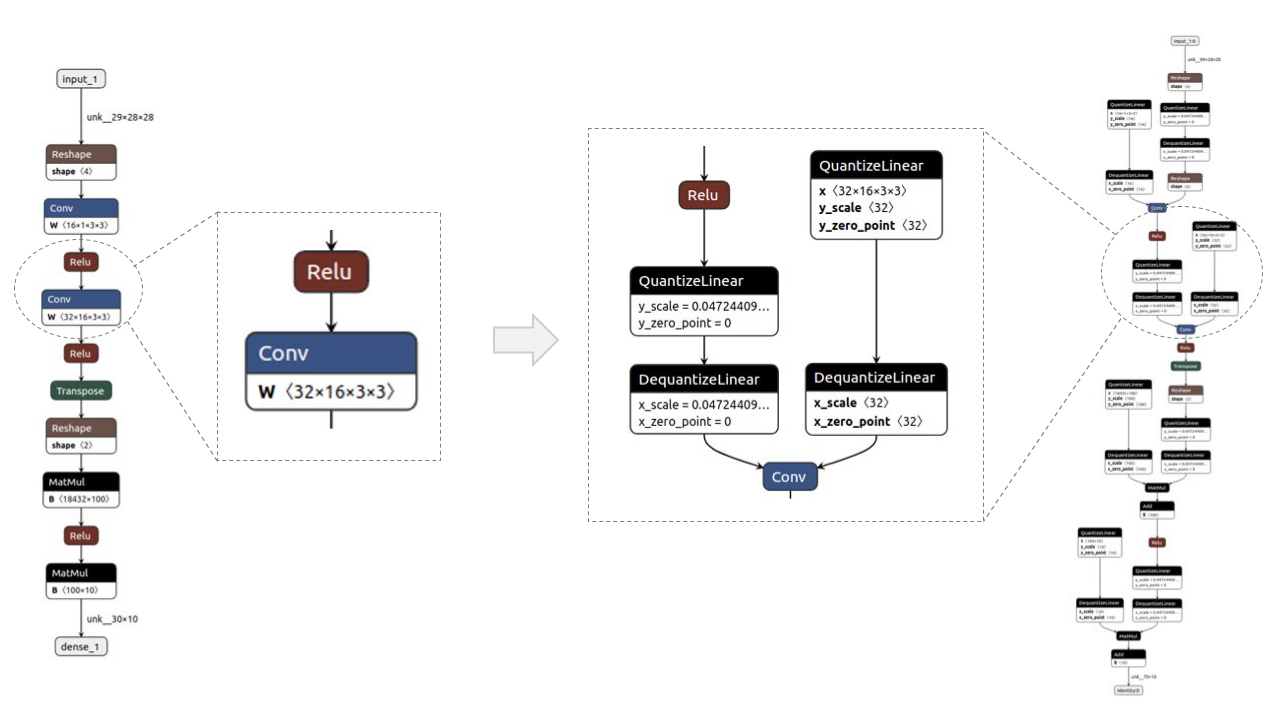
INT8 Inference of Quantization-Aware trained models using ONNX-TensorRT ...
What is TensorRT? Overview & Use Case
TensorRT-LLM-Quantization/quant.ipynb at main · CactusQ/TensorRT-LLM ...
TensorRT模型,INT8量化Python实践教程 - 智源社区
What Is A Quantizer at Tyson Macgillivray blog
GitHub - SunJianboGitHub/TensorRT-quantization: 模型量化基础、非对称量化、对称量化以及 ...
GitHub - xuanandsix/Tensorrt-int8-quantization-pipline: a simple ...
GitHub - HongJinSeong/quantization_tensorRT_ONNX · GitHub
Model-Quantization-ONNX-and-TensorRT-Optimization/docker at main ...
An Introduction to Speculative Decoding for Reducing Latency in AI ...
Quantitative - Free business and finance icons
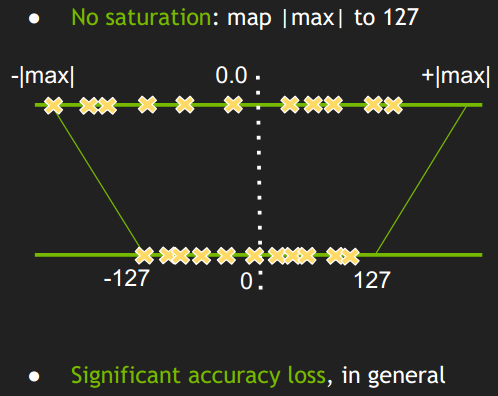
tensorRT_quantization/量化PPT.pptx at main · shouxieai/tensorRT ...
四. TensorRT模型部署优化-quantization(quantization granularity)_tensorrt ...
利用NVIDIA TensorRT实现推理的QAT伪量化-电子发烧友网
TensoRT量化第四课:PTQ与QAT_onnx qat例子-CSDN博客
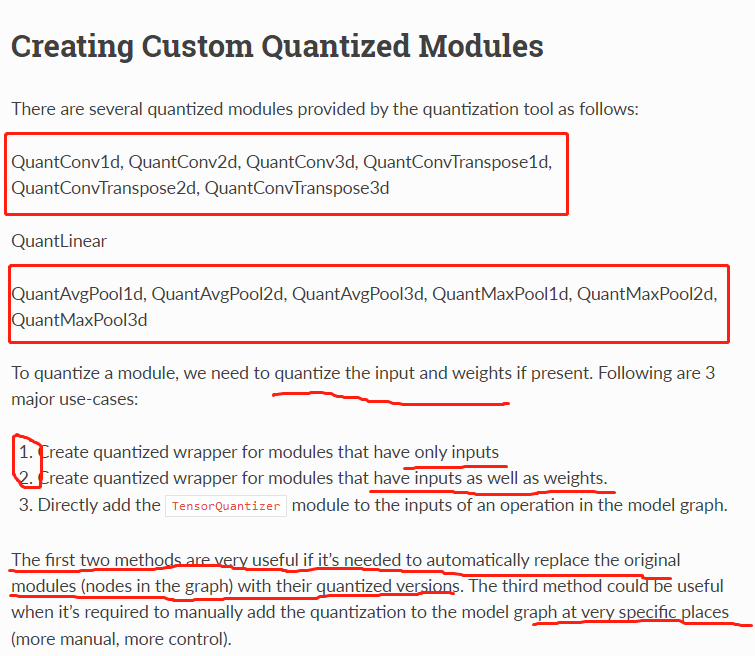
TensorRT量化实战课YOLOv7量化:pytorch_quantization介绍_模型量化实战-CSDN博客
TensorRT量化实战课YOLOv7量化:pytorch | 奔跑的IC
Tensorrt一些优化技术介绍 - 吴建明wujianming - 博客园
Tensor Quantization: The Untold Story | by Dhruv Matani | TDS Archive ...
TensorRT(5)-INT8校准原理 | arleyzhang
TensorRT量化实战课YOLOv7量化:pytorch_quantization介绍_pytorch-quantization-CSDN博客
model-compression-and-acceleration.md | AiHub
TensorRT详细入门指北,如果你还不了解TensorRT,过来看看吧_tensor drt-CSDN博客
Spotlight: Perfect Corp. Delivers Personalized Digital Beauty ...
Mixed-Precision ResNet-50 Using Tensor Cores with TensorFlow | NVIDIA ...
Author: Josh Park | NVIDIA Technical Blog
TensorRT-量化指北 | WEAF 周刊
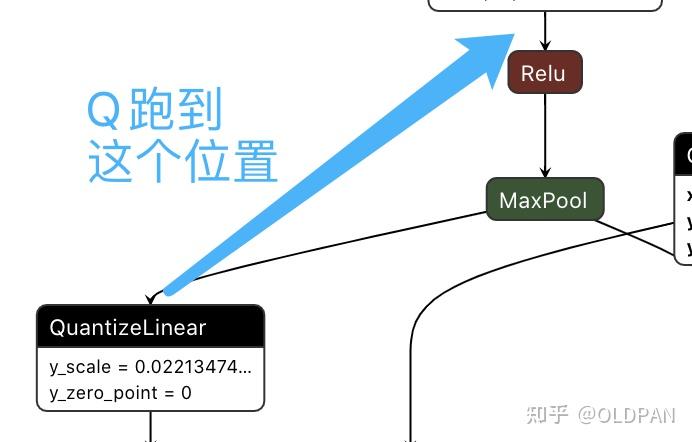
一起实践量化番外篇——TensorRT-8的量化细节-腾讯云开发者社区-腾讯云
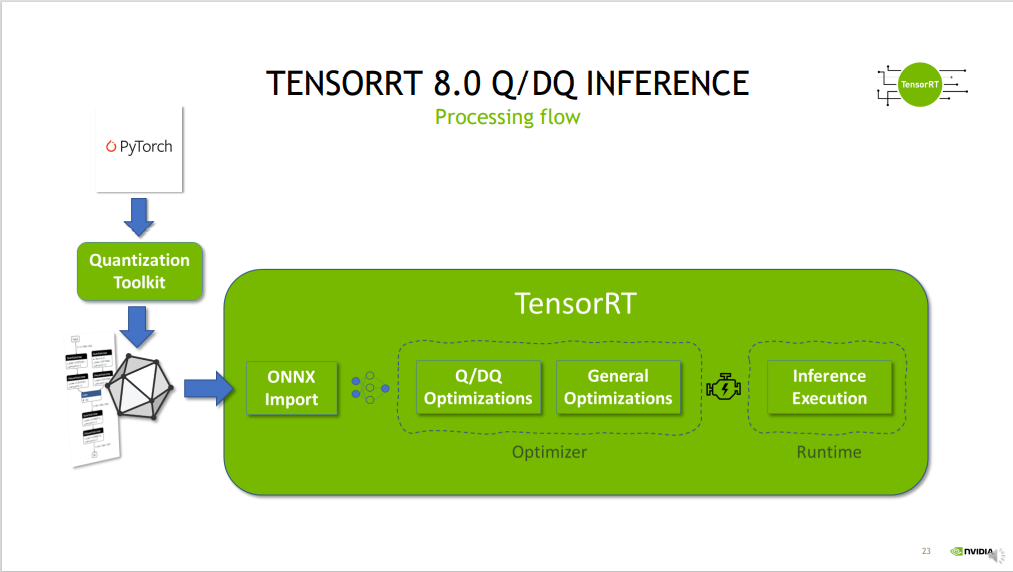
Accelerating Quantized Networks with the NVIDIA QAT Toolkit for ...
Model Quantization: Concepts, Methods, and Why It Matters | NVIDIA ...
TensorRT-8量化分析 - 吴建明wujianming - 博客园
TensorRT_tensorrt和cuda的区别-CSDN博客
LSQ using pytorch_quantization · Issue #3076 · NVIDIA/TensorRT · GitHub
pytorch_quantization error - undefined symbol in `pytorch_quantization ...
Model Quantization: Tối Ưu Hóa Hiệu Năng Mô Hình AI
量化番外篇——TensorRT-8的量化细节 - 知乎
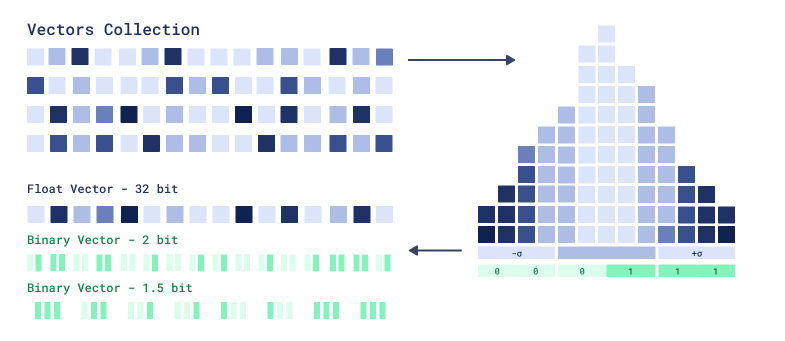
Building Performant, Scaled Agentic Vector Search with Qdrant
Model Quantization: Turn FP8 Checkpoints into High-Performance ...
GitHub - liukang1811/TensorRT-Model-Optimizer: A unified library of ...
NVIDIA TensorRT-LLM Now Accelerates Encoder-Decoder Models with In ...
GitHub - Y-T-G/TensorRT-Model-Optimizer: A unified library of state-of ...
Beyond Basics: 8 Must-Know Deep Learning Tools in 2024
GitHub - shoxa0707/Model-quantization: Quantize all type of Yolov8 ...
AI Model Optimization: Maximizing Performance and Efficiency | IT-Magic
PyTorch-Quantization Toolkit · Issue #981 · NVIDIA/TensorRT · GitHub
Accelerating Large Language Model Inference with TensorRT-LLM: A ...