Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
Transformer Architecture Before passing the output tensor (7x7x2048 ...
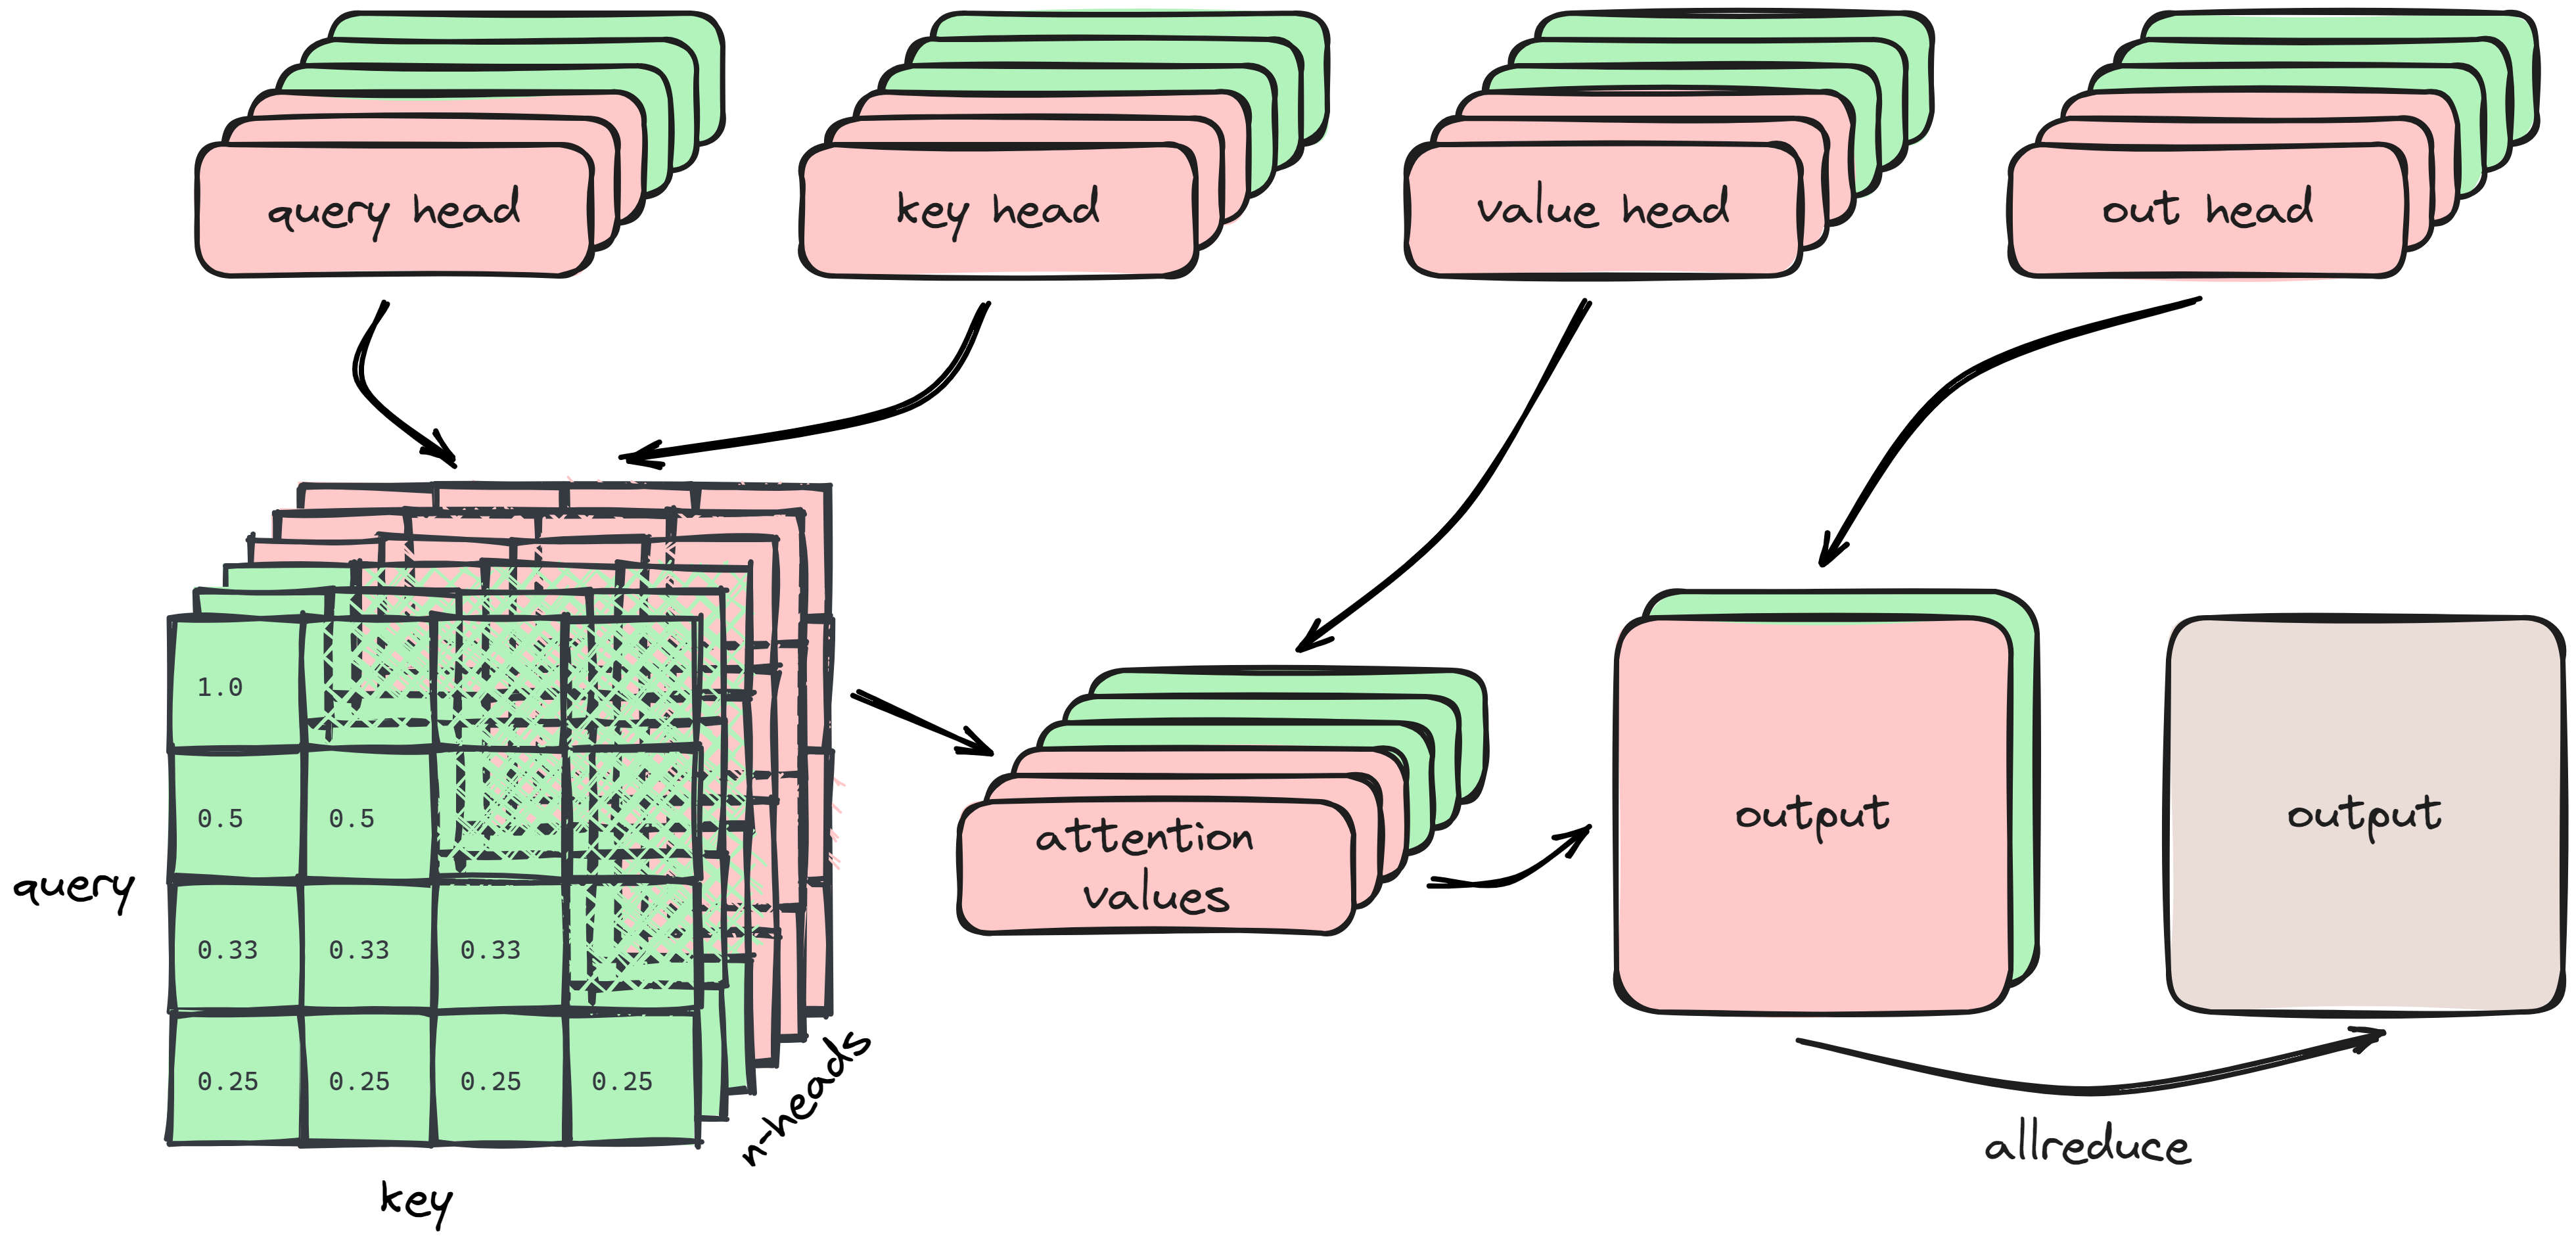
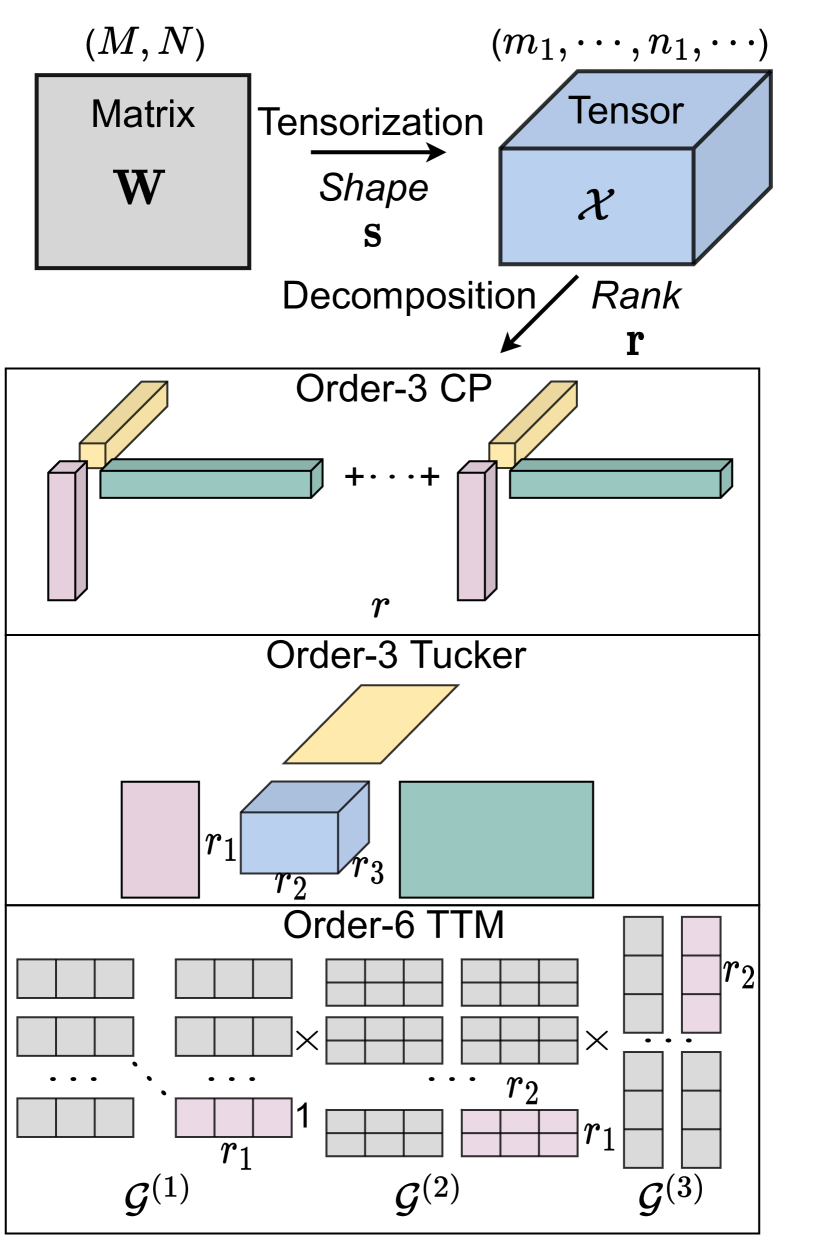
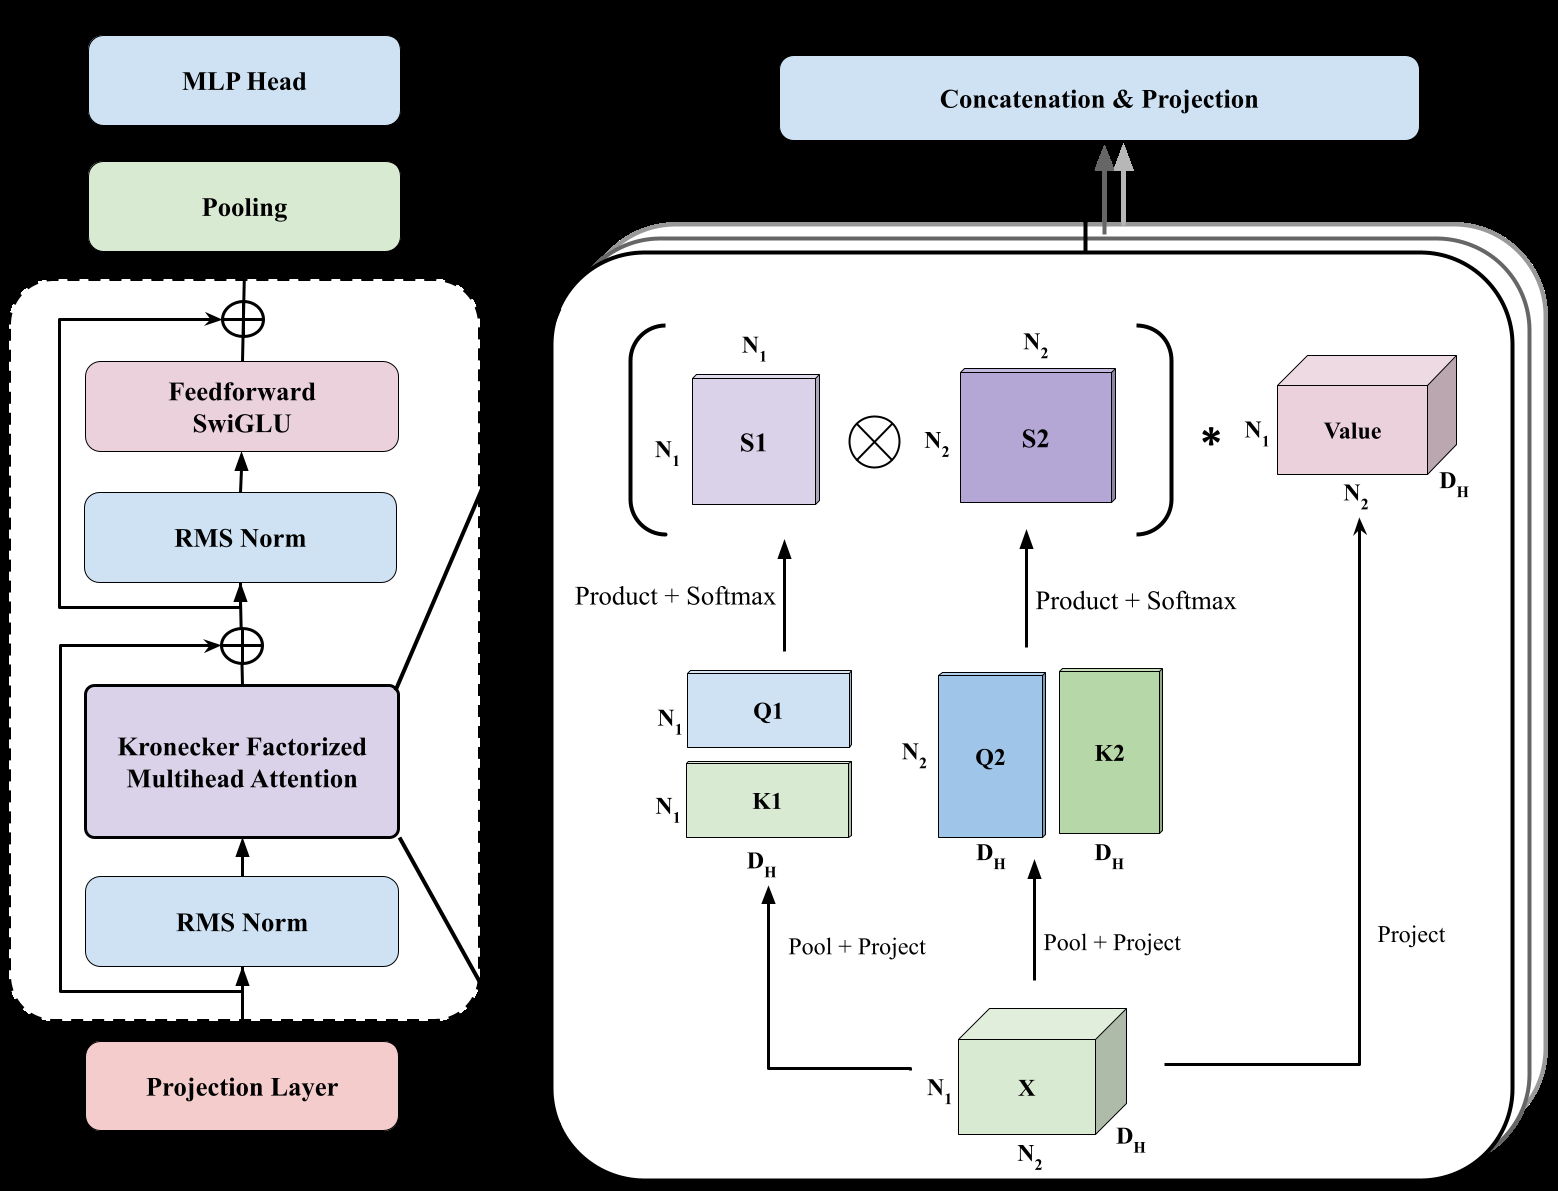
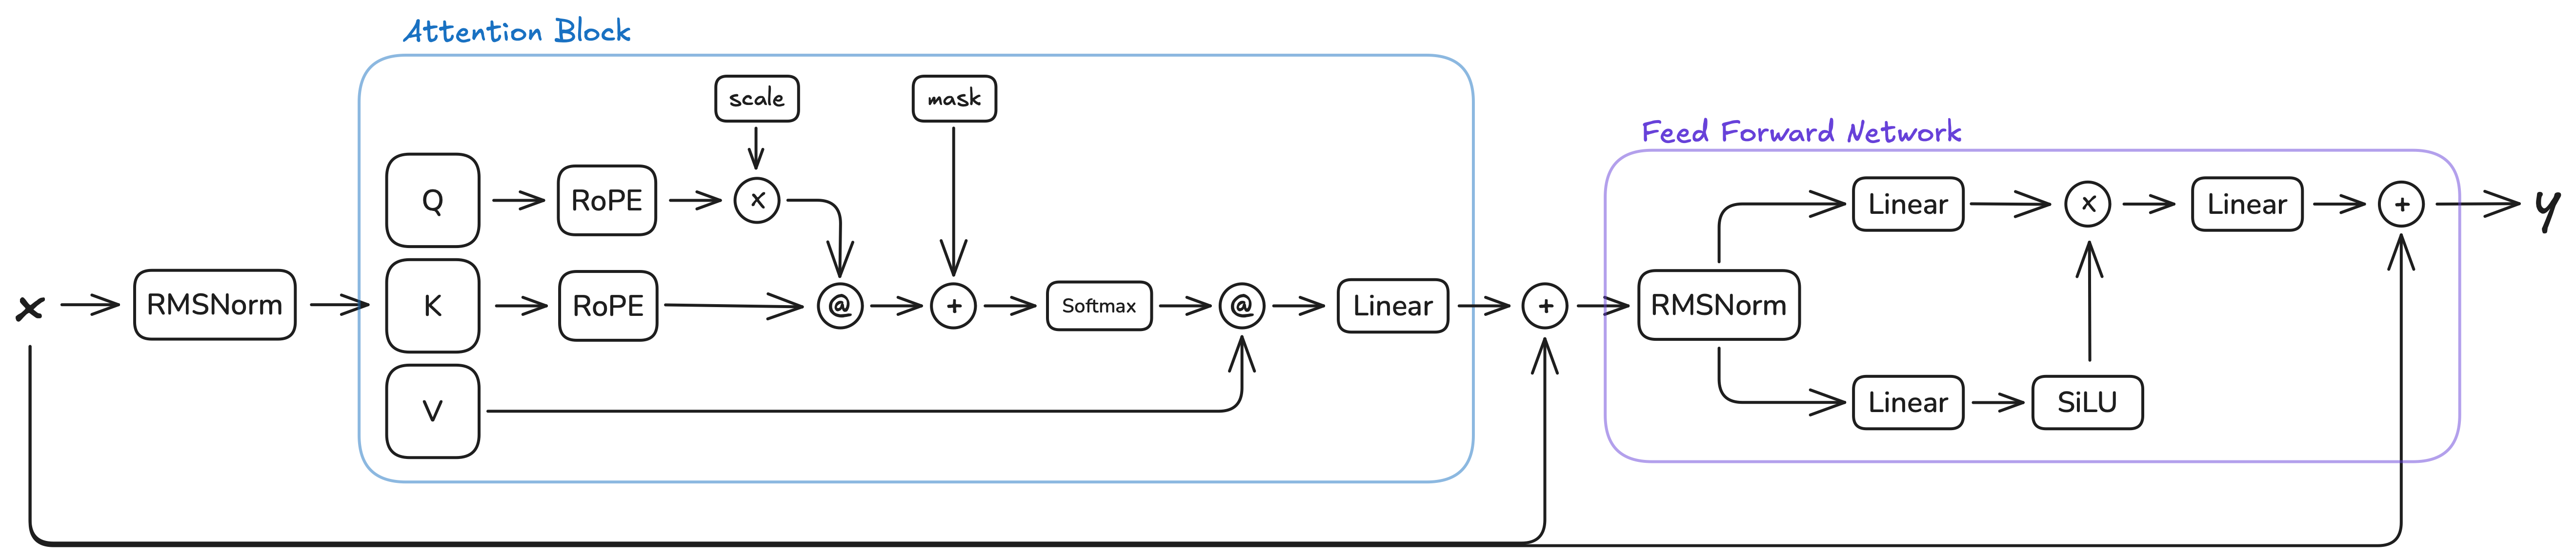
Tensor Product Attention Transformer
[2201.05701] Diffusion Tensor Estimation with Transformer Neural Networks
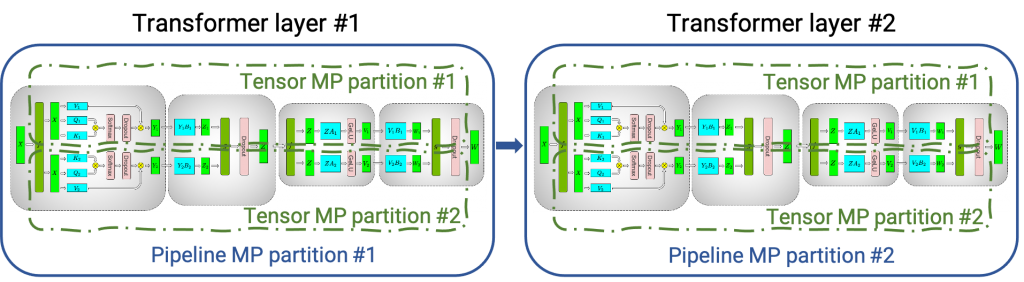
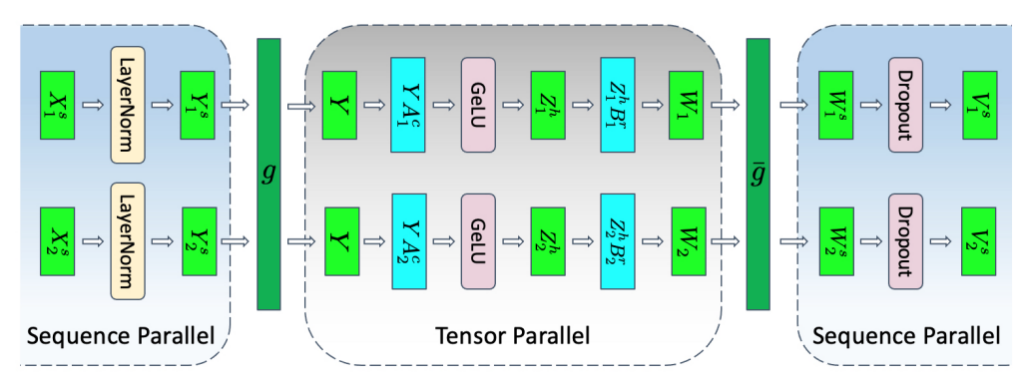
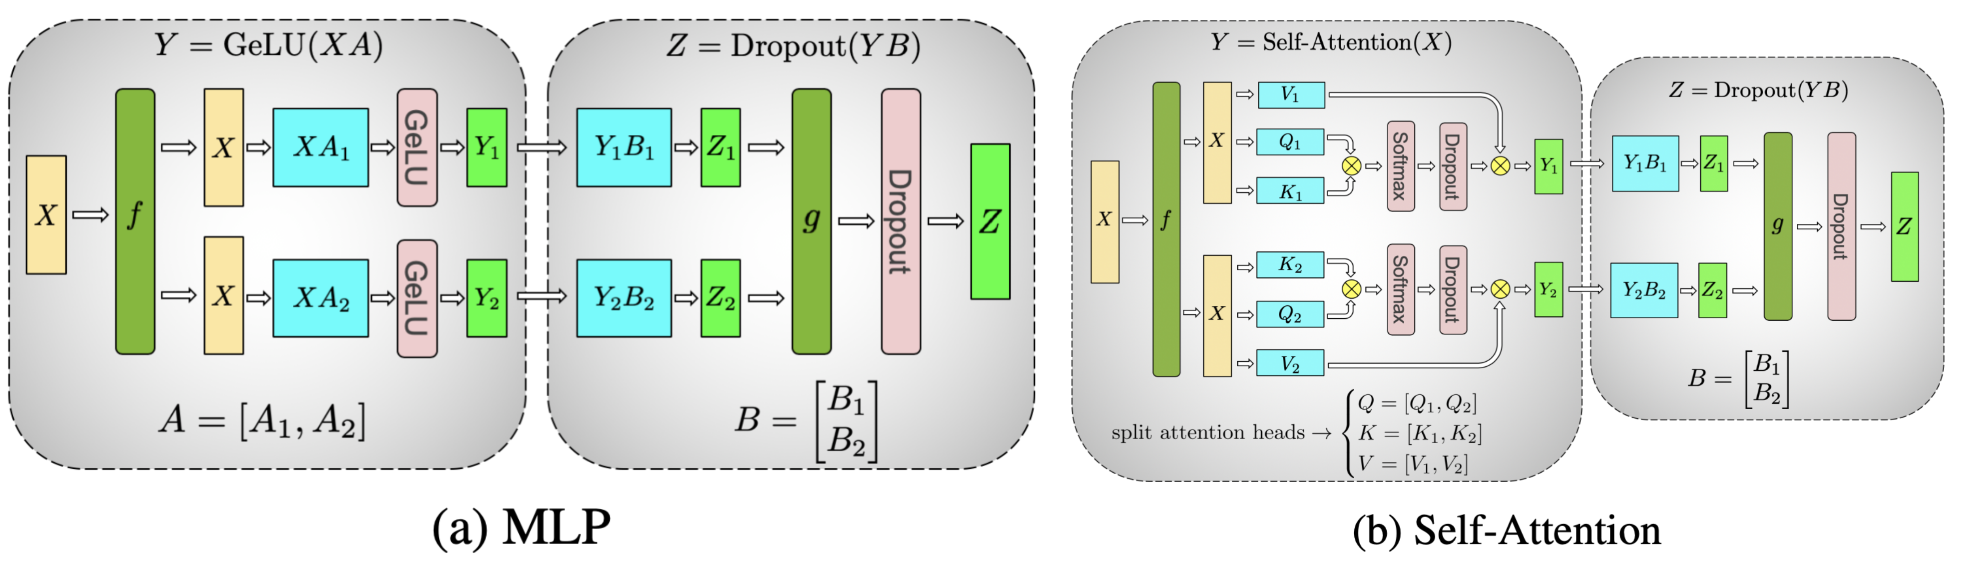
Large Scale Transformer Model Training With Tensor Parallel – ACMMB
Differential geometry & Tensor analysis | Transformer explanatory video ...
(PDF) Diffusion Tensor Estimation with Transformer Neural Networks
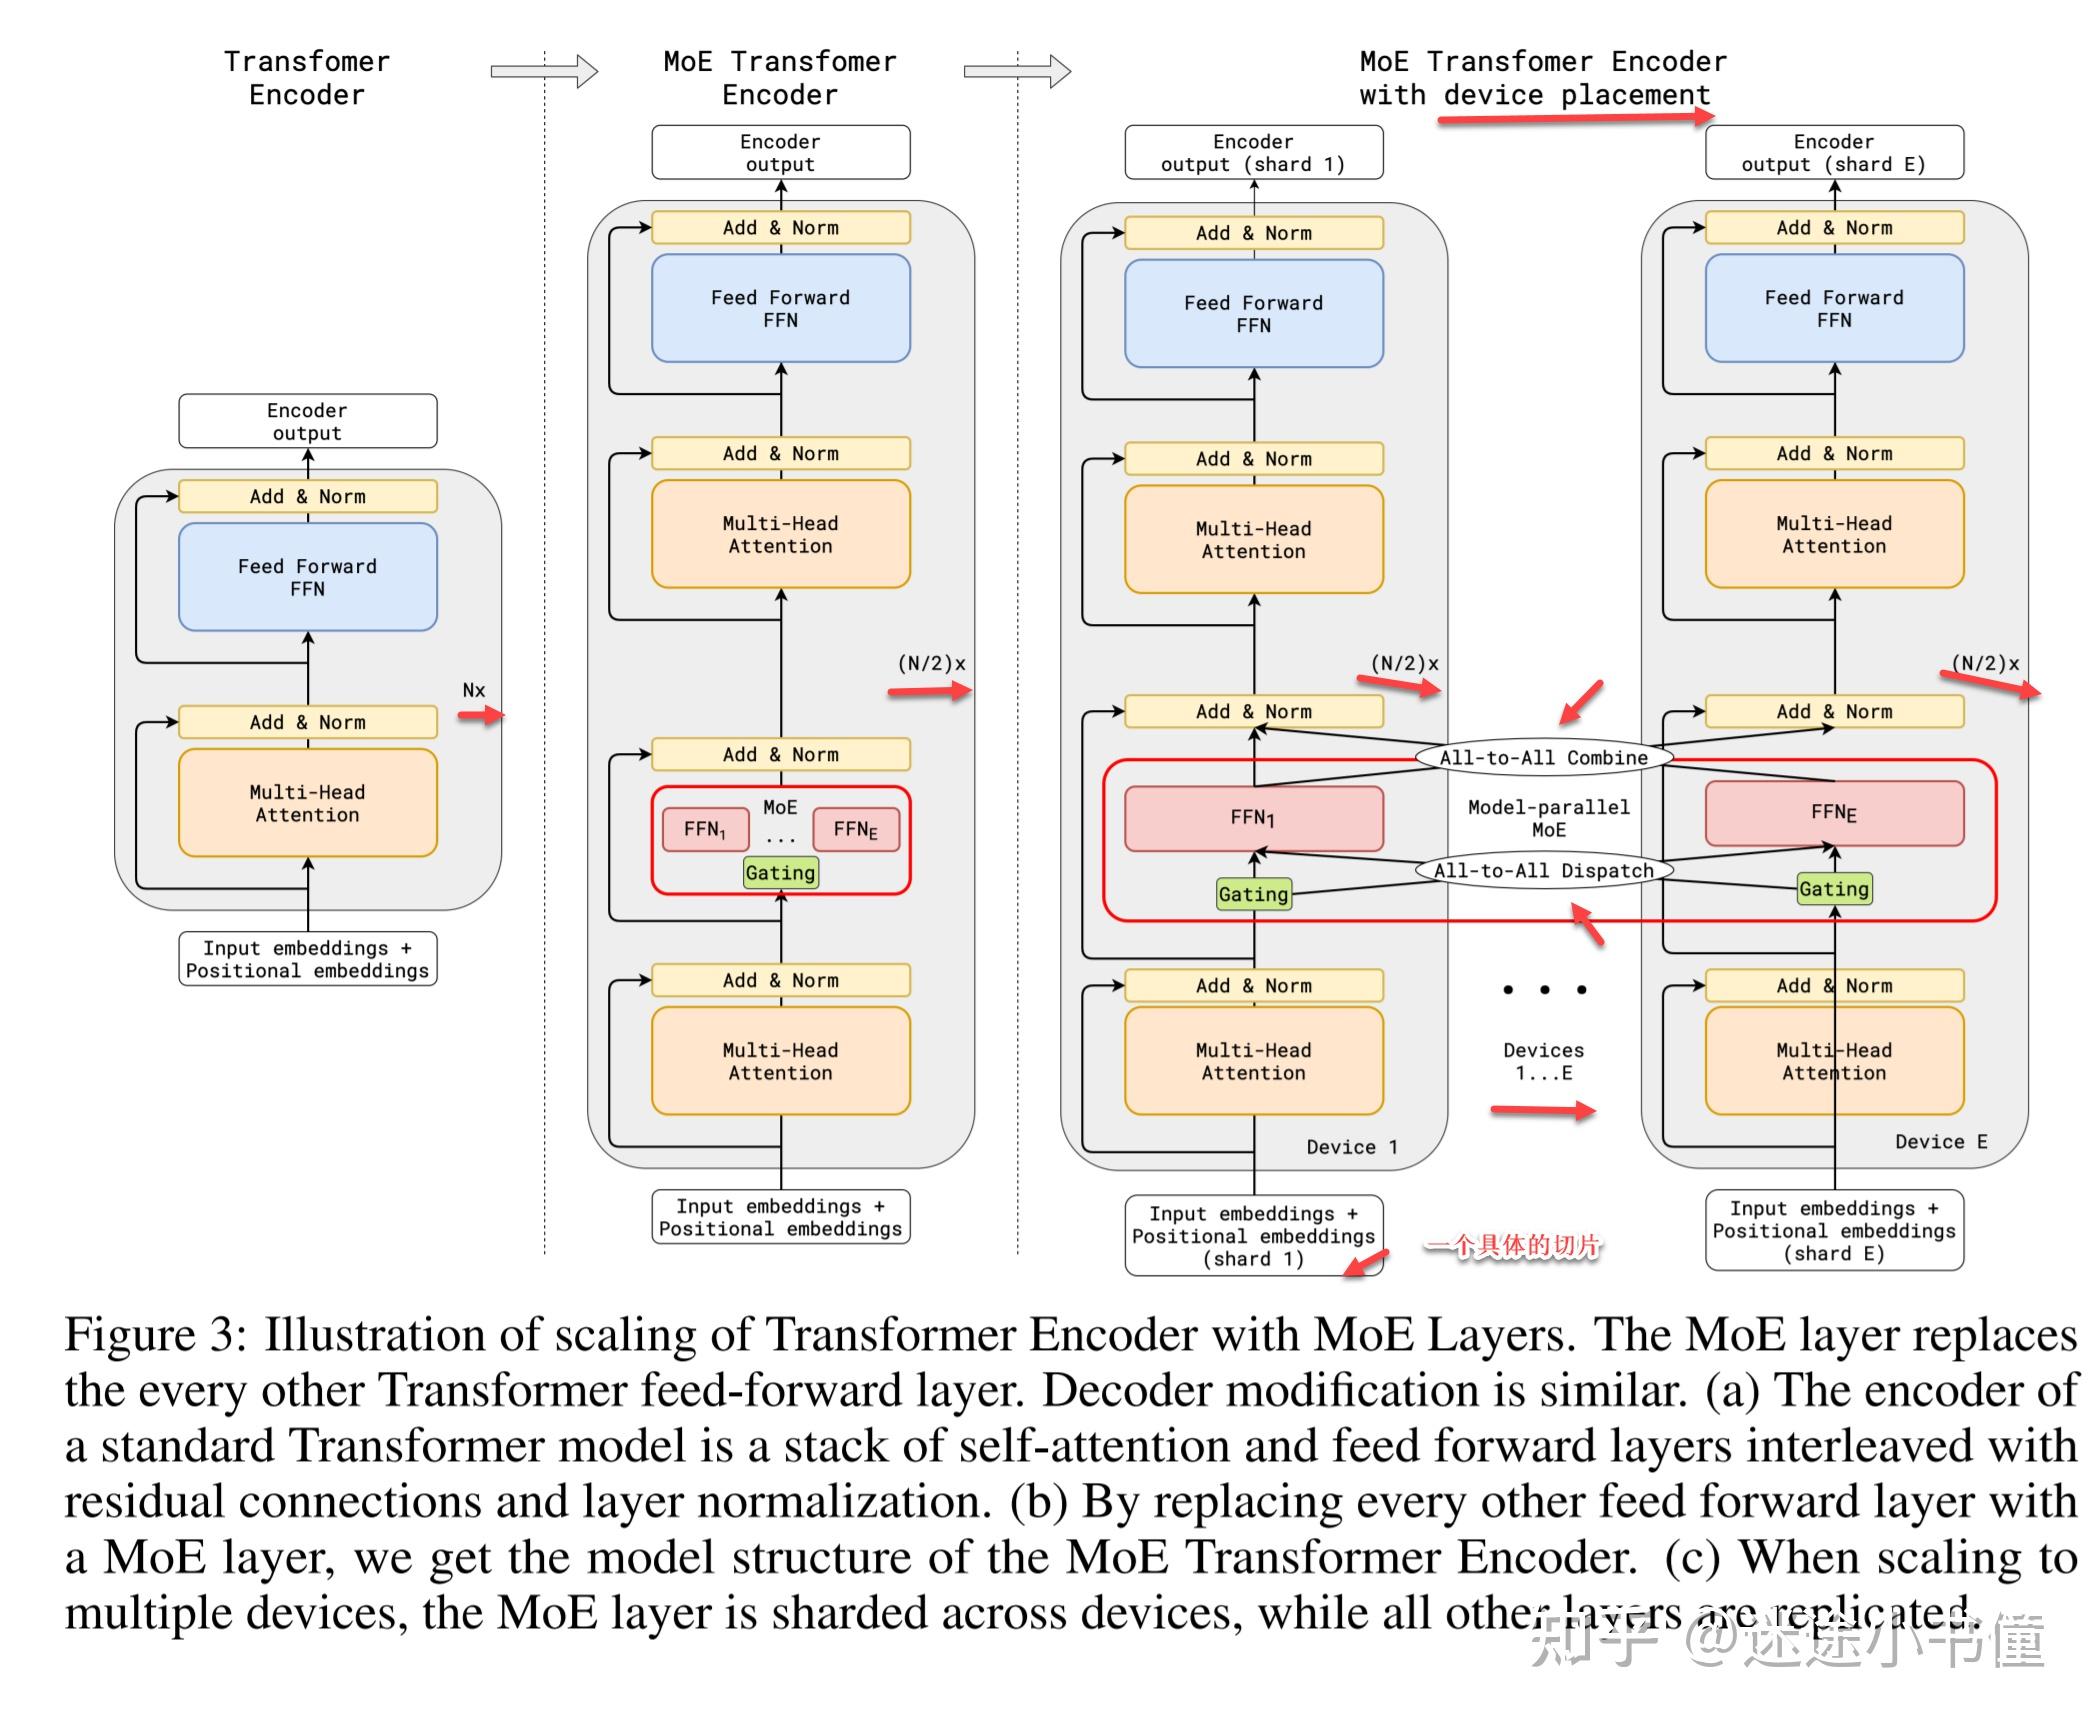
Reducing Activation Recomputation in Large Transformer Models | DeepAI
Transformers in depth - Part 1. Introduction to Transformer models in 5 ...
LeeMeng - 淺談神經機器翻譯 & 用 Transformer 與 TensorFlow 2 英翻中
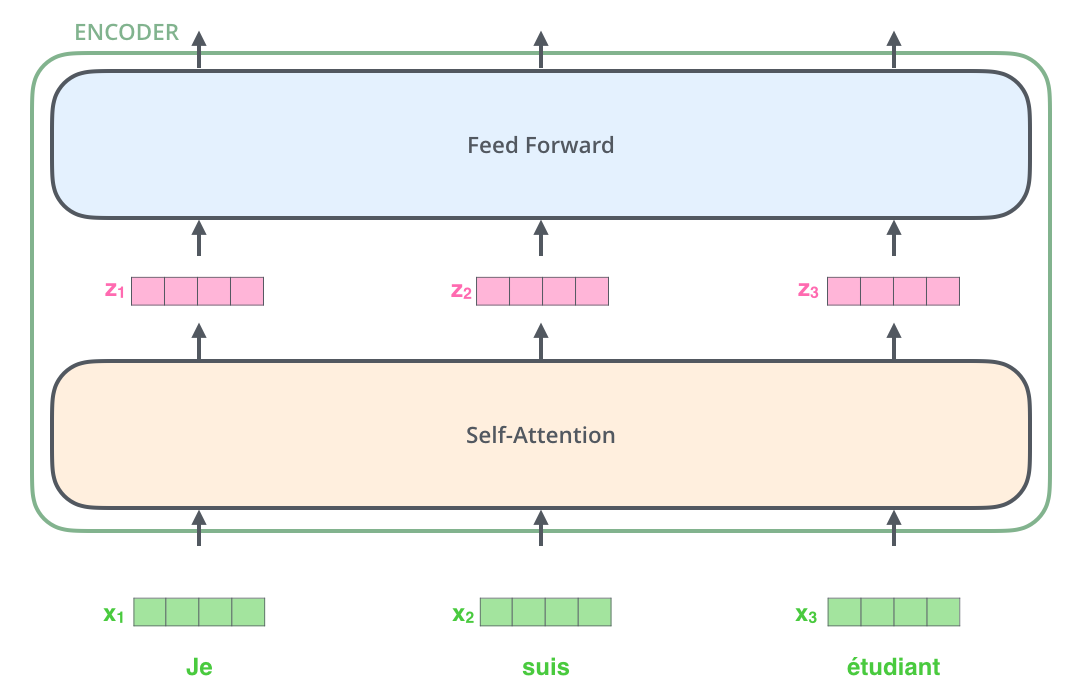
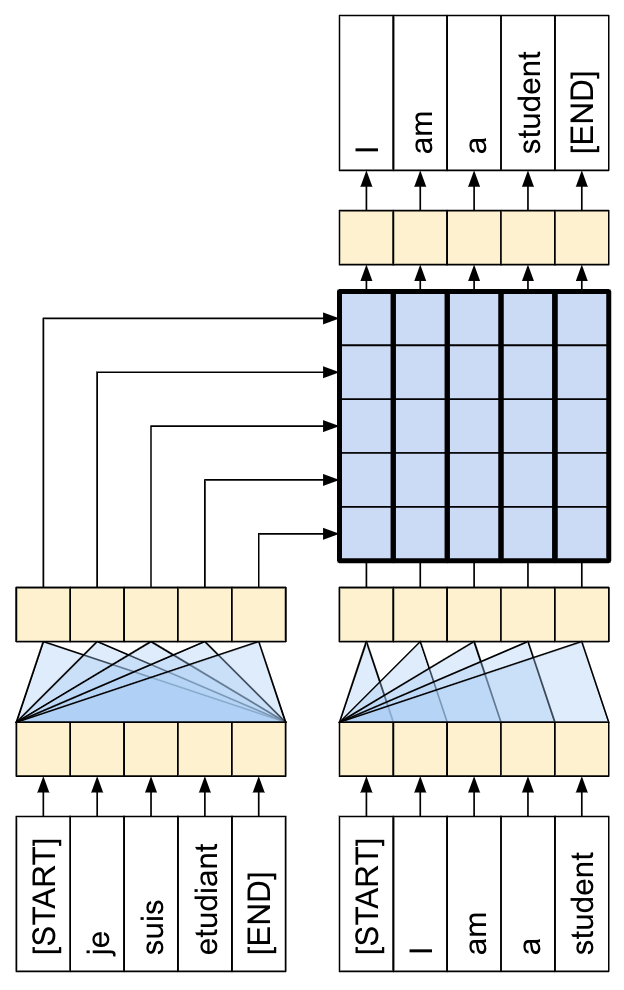
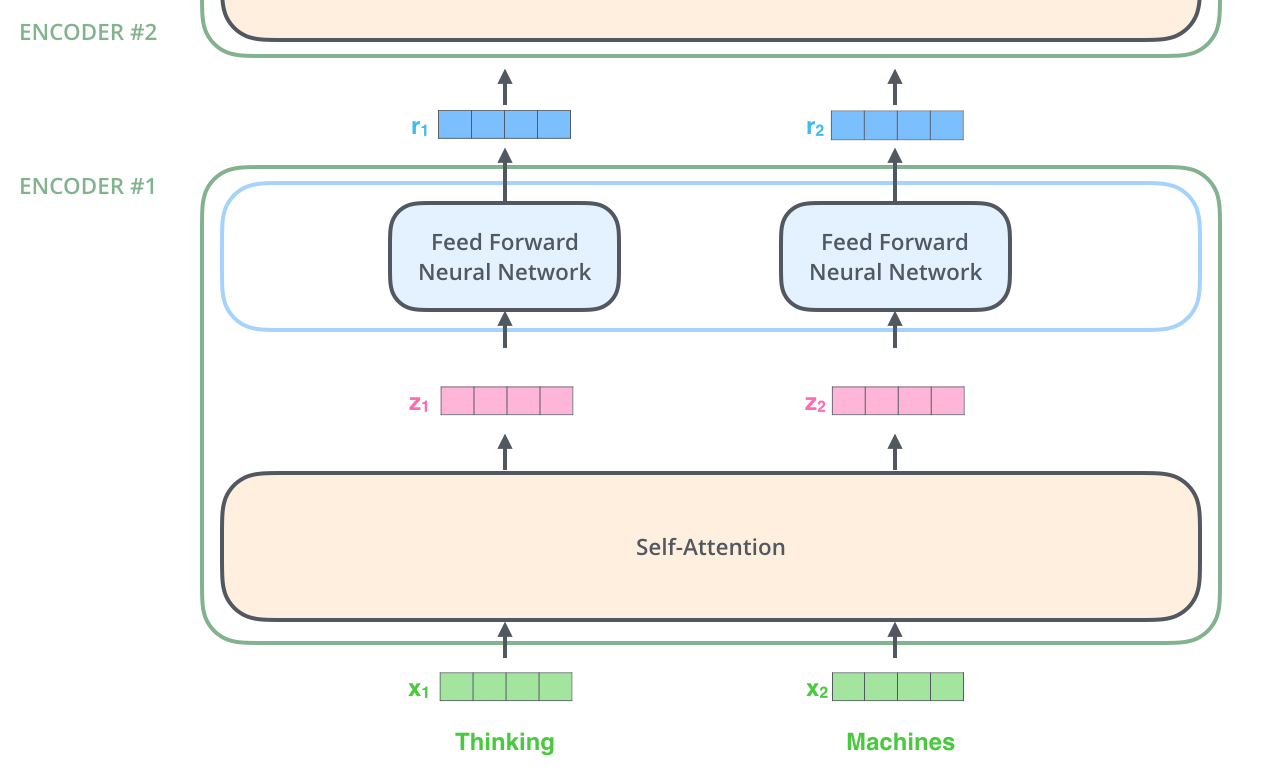
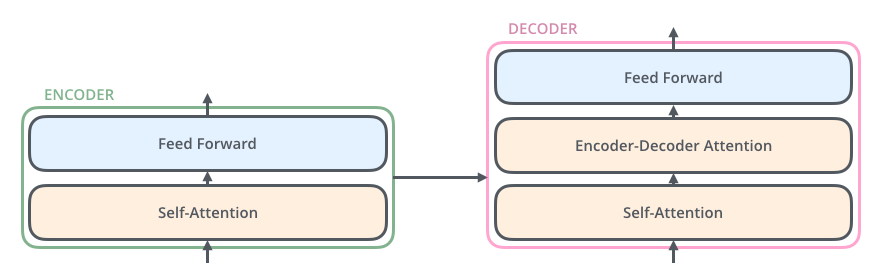
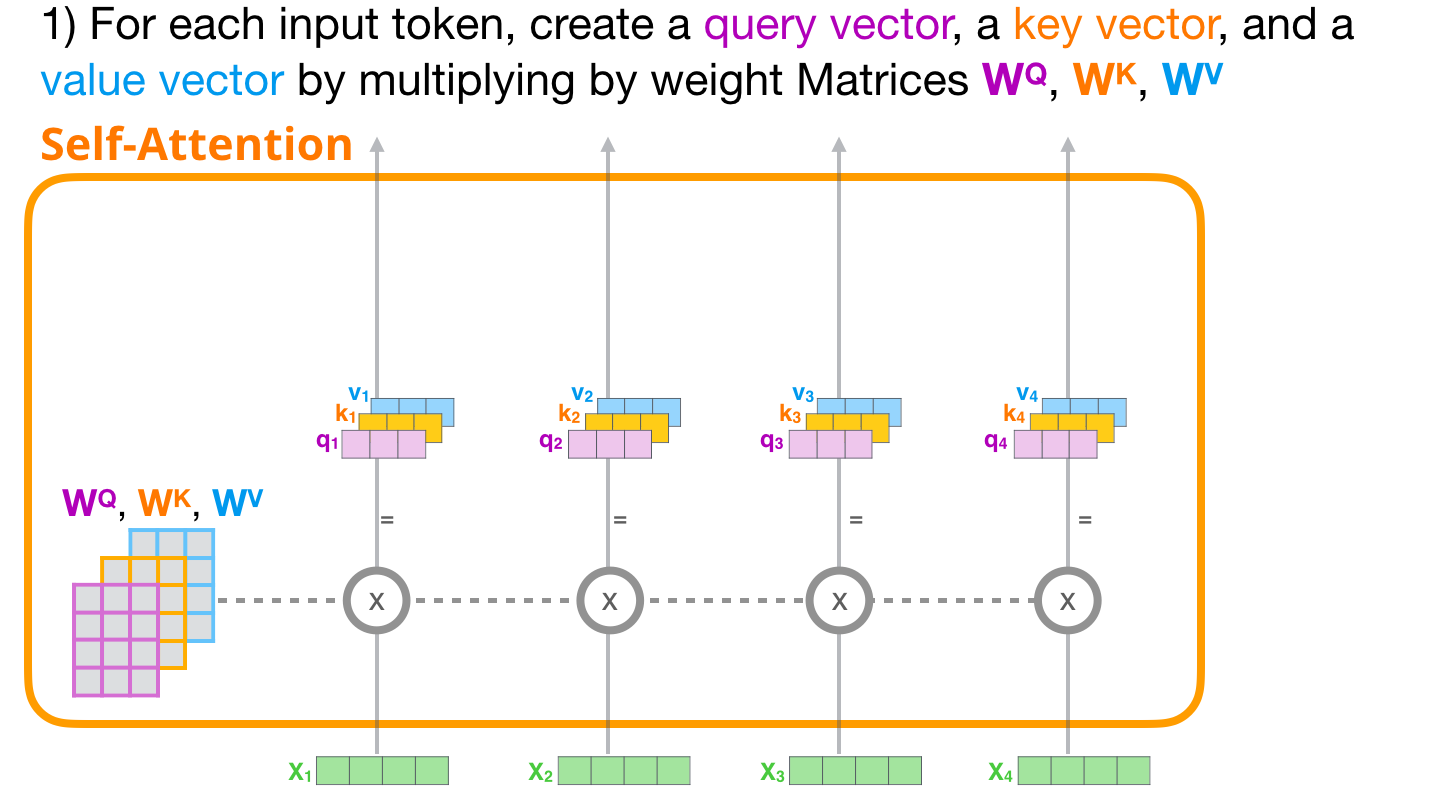
The Illustrated Transformer – Jay Alammar – Visualizing machine ...
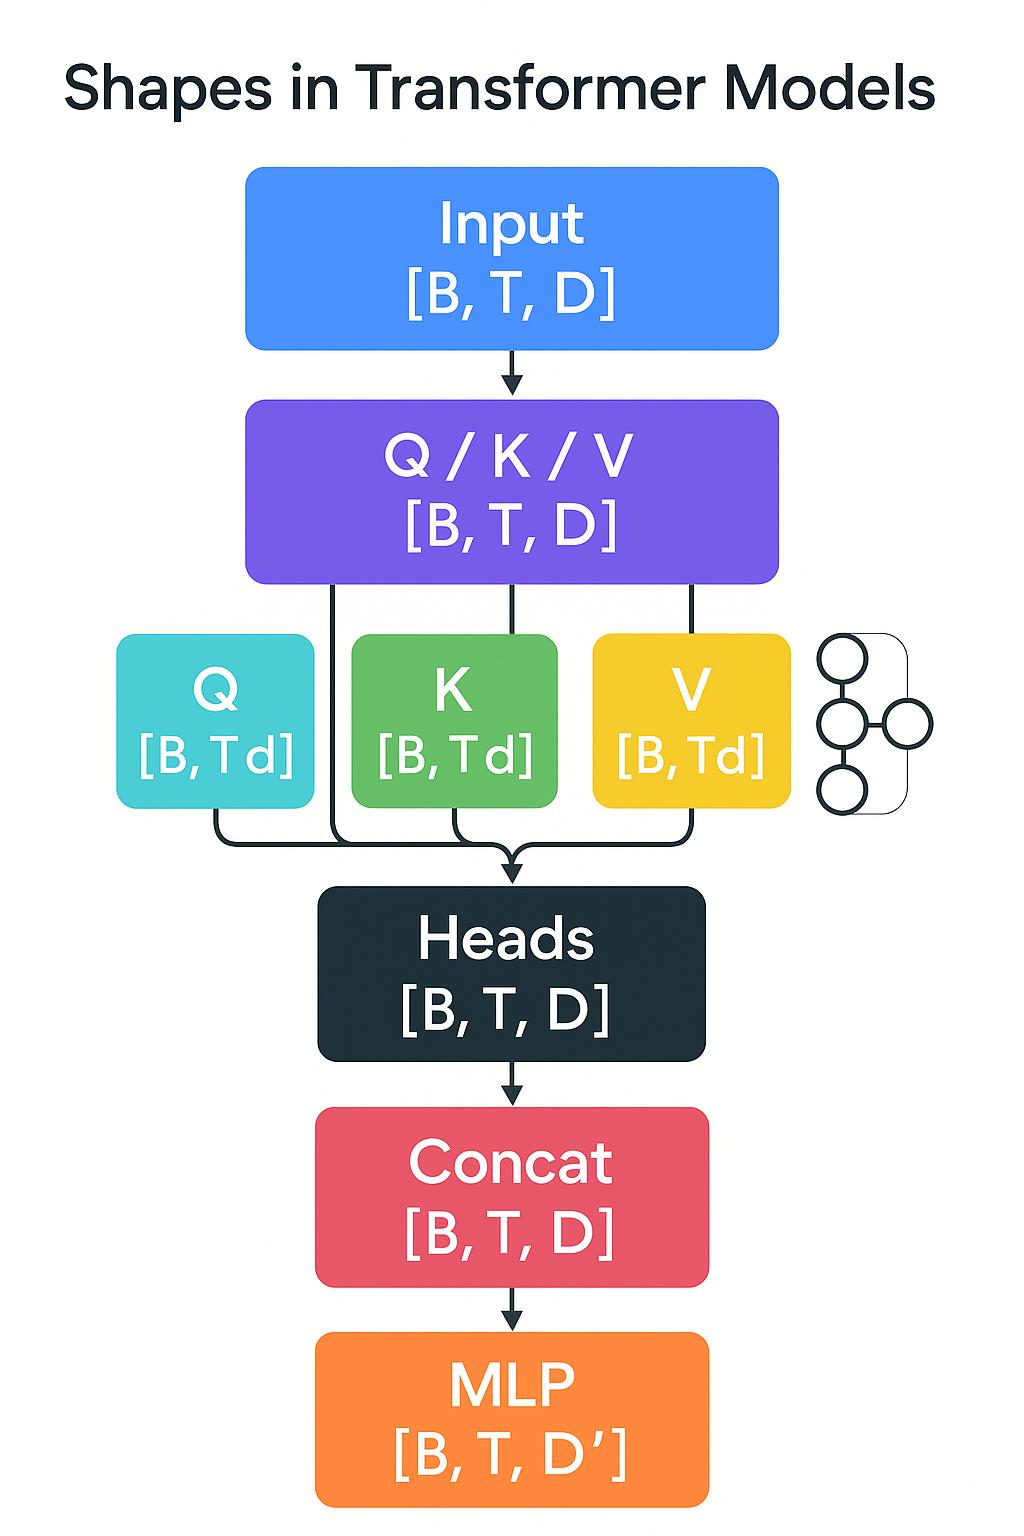
Mastering Tensor Dimensions in Transformers
[논문 리뷰] TensorLens: End-to-End Transformer Analysis via High-Order ...
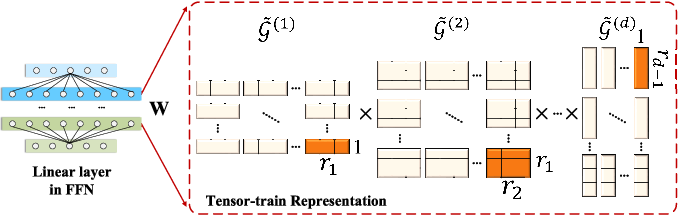
Tensor Product Attention Is All Your Need
A Knowledge Concept Recommendation Model Based on Tensor Decomposition ...
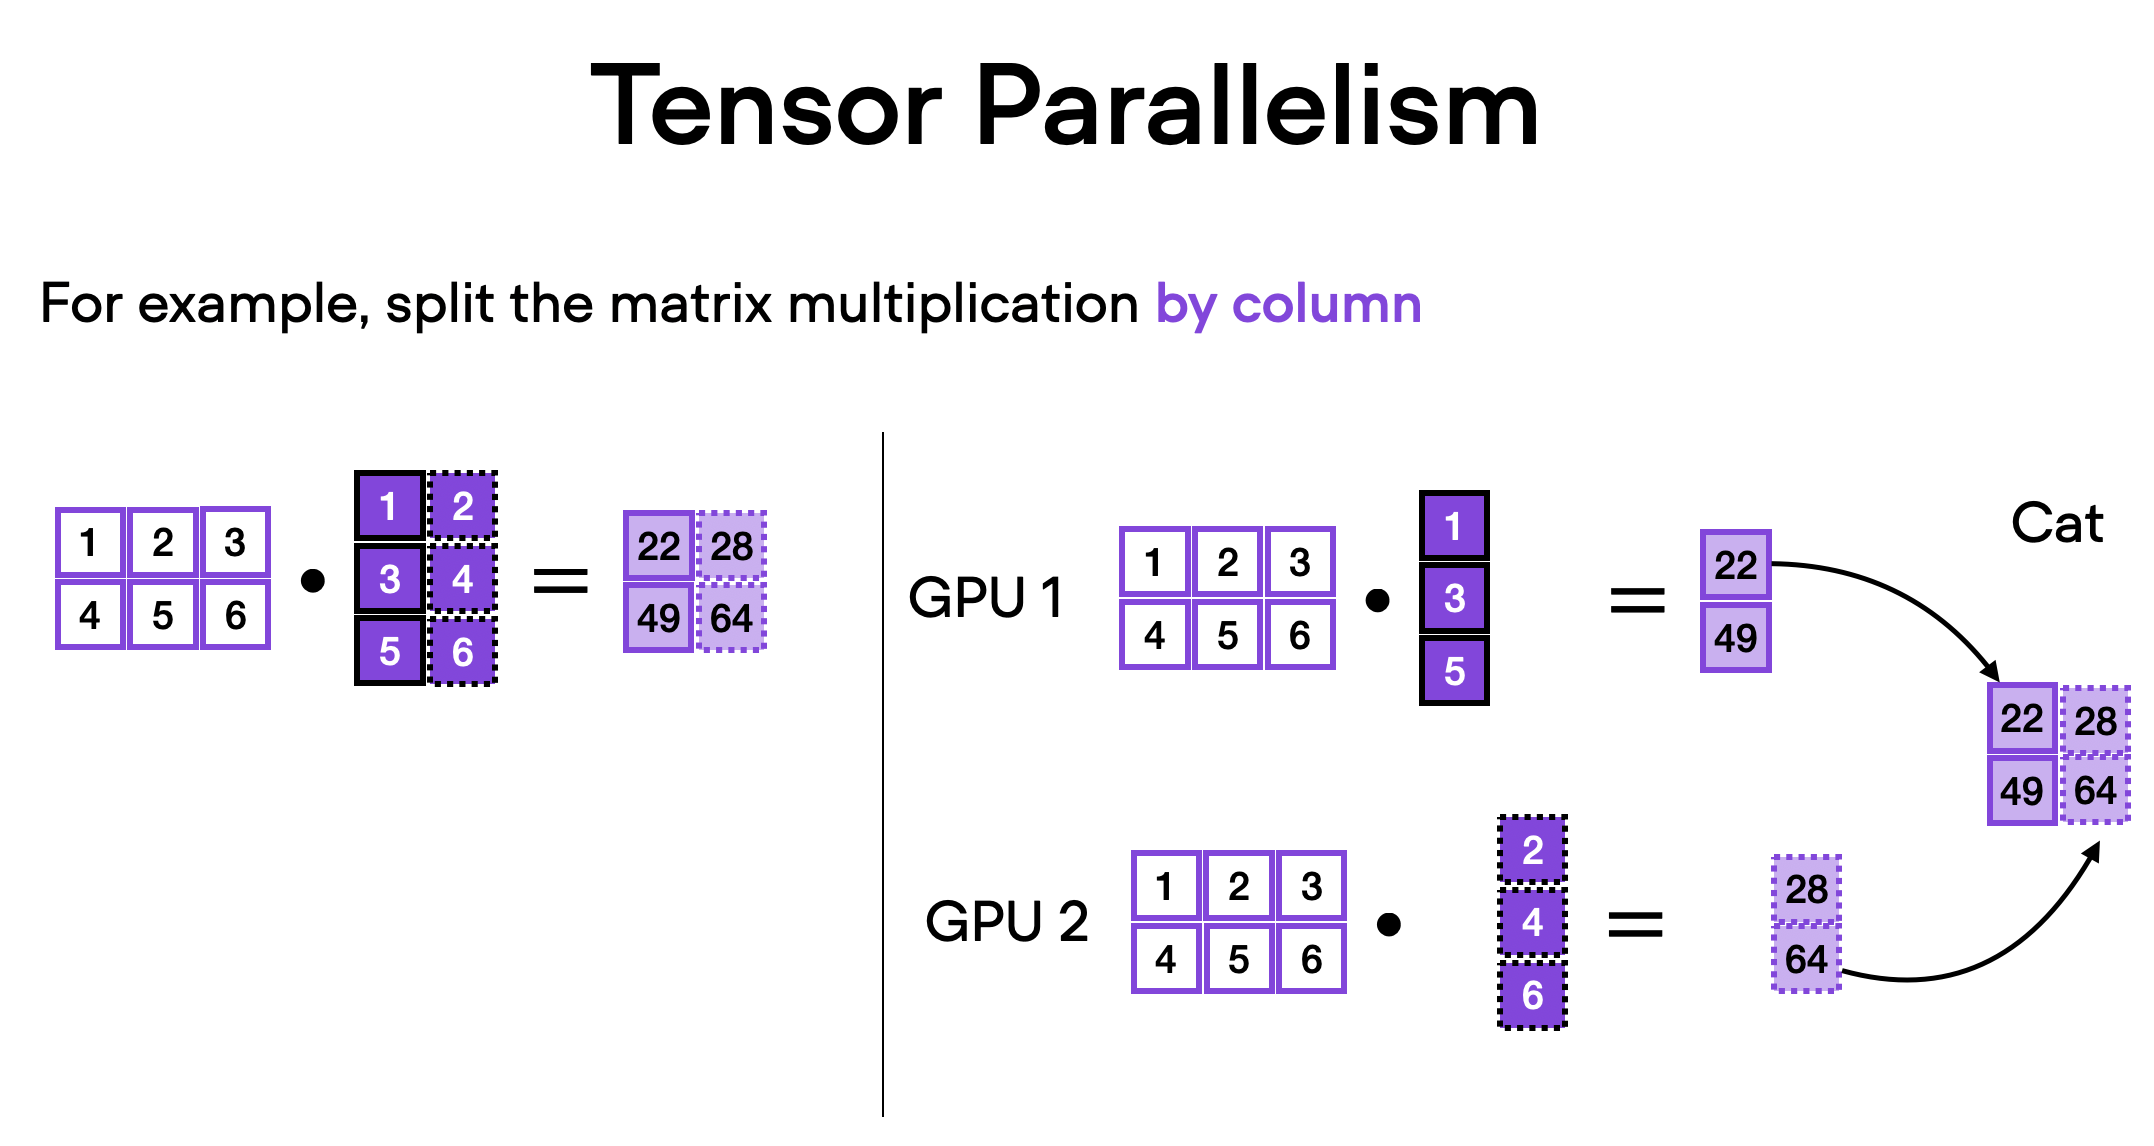
Tensor Parallelism
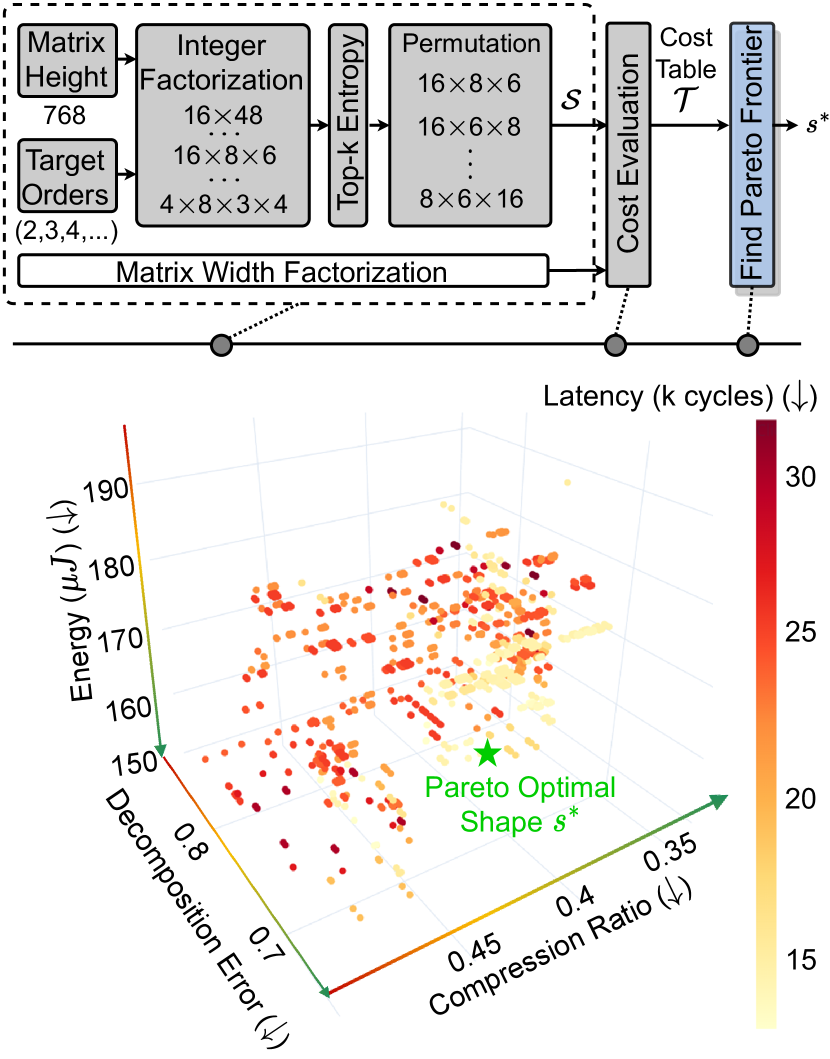
[2211.16749] HEAT: Hardware-Efficient Automatic Tensor Decomposition ...
Figure 1 from Transformer-Based Tensor Nuclear Norm for Multi ...
TensorLens: End-to-End Transformer Analysis via High-Order Attention ...
Mô hình Transformer – Transformer model
使用 FasterTransformer 和 Triton 推理服务器加速大型 Transformer 模型的推理 - NVIDIA 技术博客
Neural machine translation with a Transformer and Keras | Text | TensorFlow
Tensor Logic: One Equation to Rule Them All | rewire.it
使用张量并行 (TP) 进行大规模 Transformer 模型训练 | PyTorch stable -- Pytorch官方文档 ...
Support Tensor Machine : Theories, algorithms and applications in ...
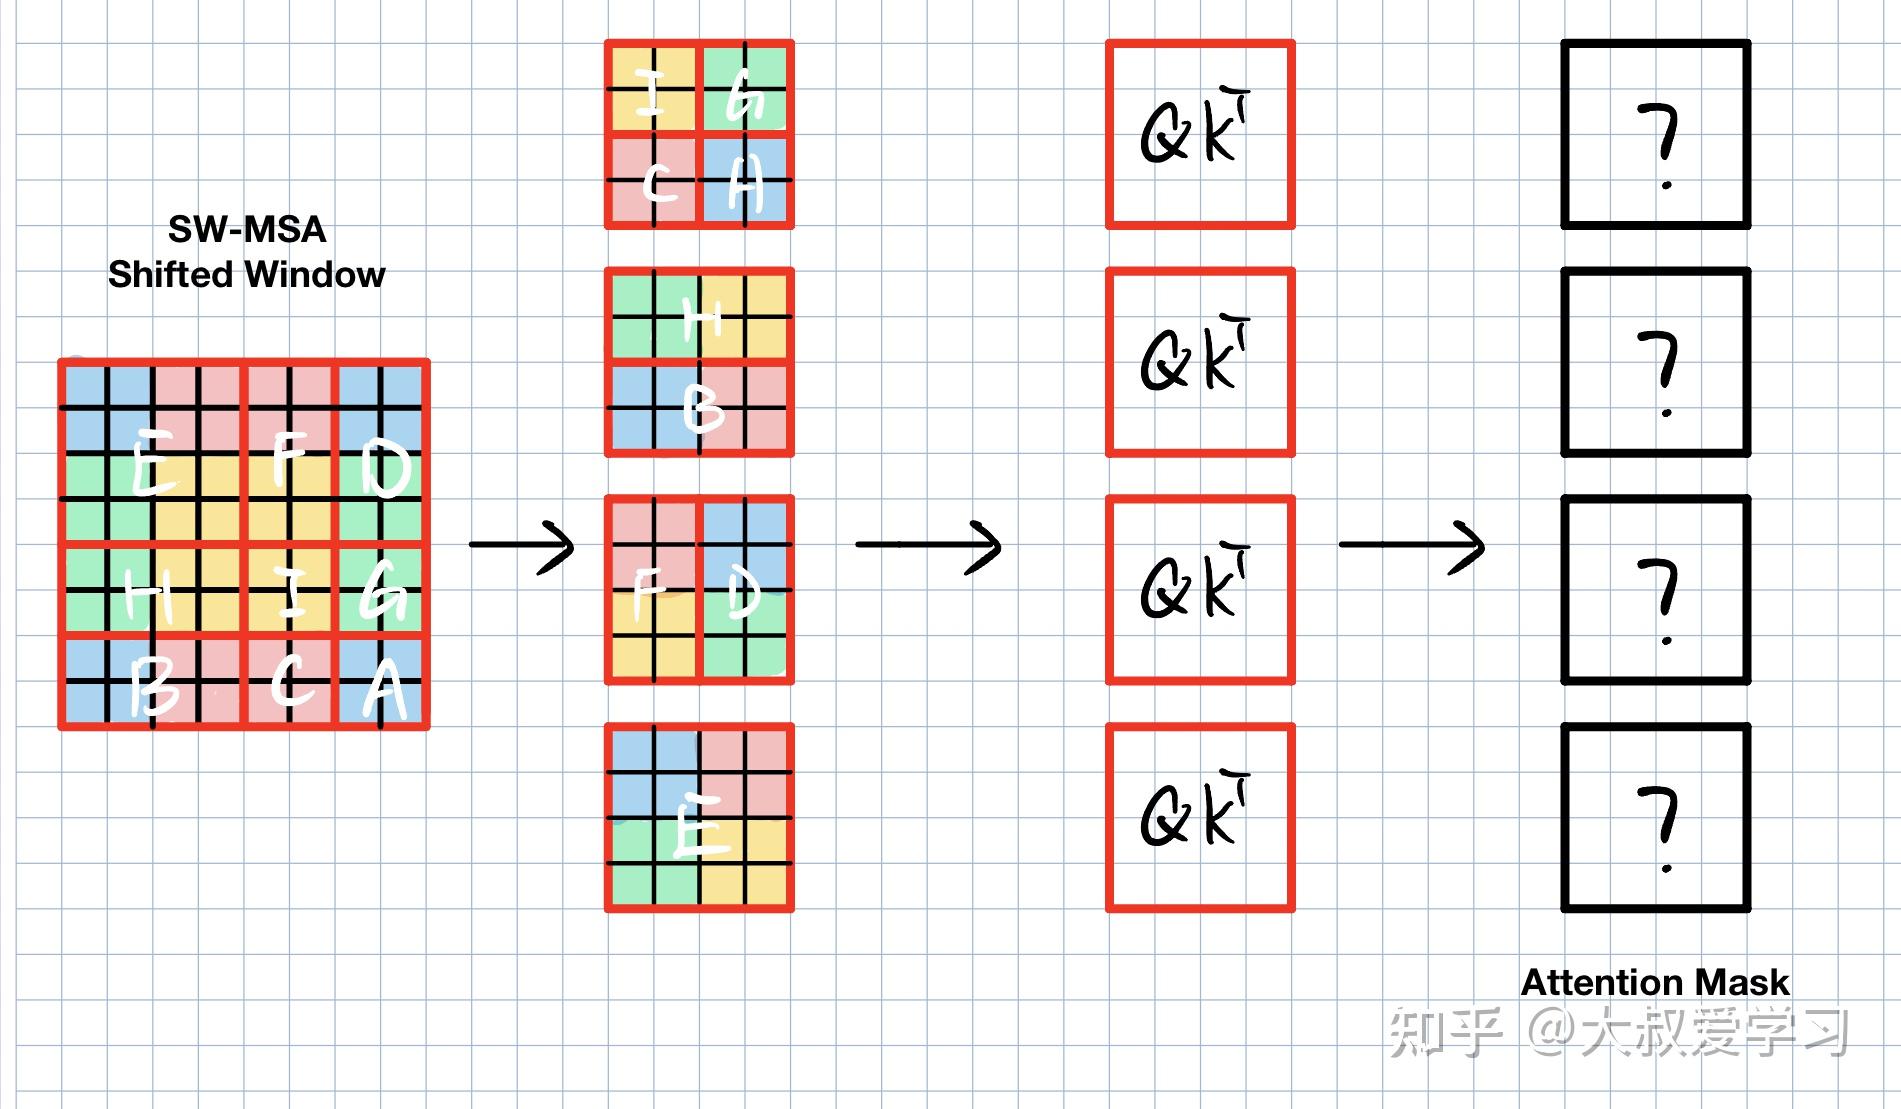
Vision Transformer 超详细解读 (原理分析+代码解读) (三十) - 知乎
Part 4.3: Transformers with Tensor Parallelism — UvA DL Notebooks v1.2 ...
pytorch - Transformers: Cross Attention Tensor Shapes During Inference ...
Perceiver io : Is there any way to specify the query tensor - 🤗 ...
Alternatives and detailed information of Transformer Tensorflow - GitPlanet
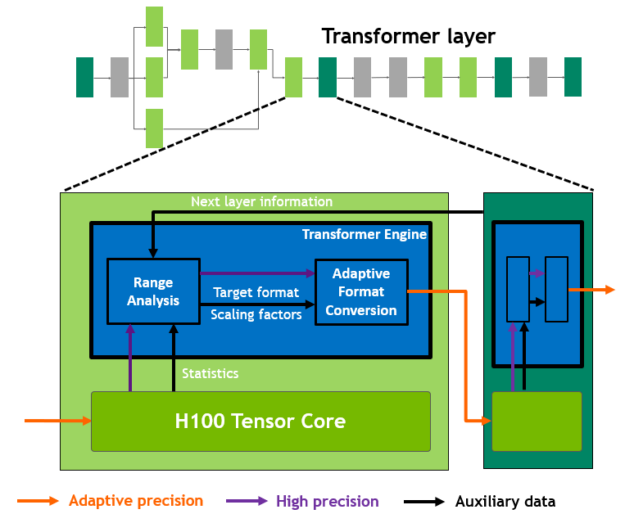
Tensor Abstraction System | NVIDIA/TransformerEngine | DeepWiki
Tensor Parallelism (TP) in Transformers: 5 Minutes to Understand
Paper page - TensorLens: End-to-End Transformer Analysis via High-Order ...
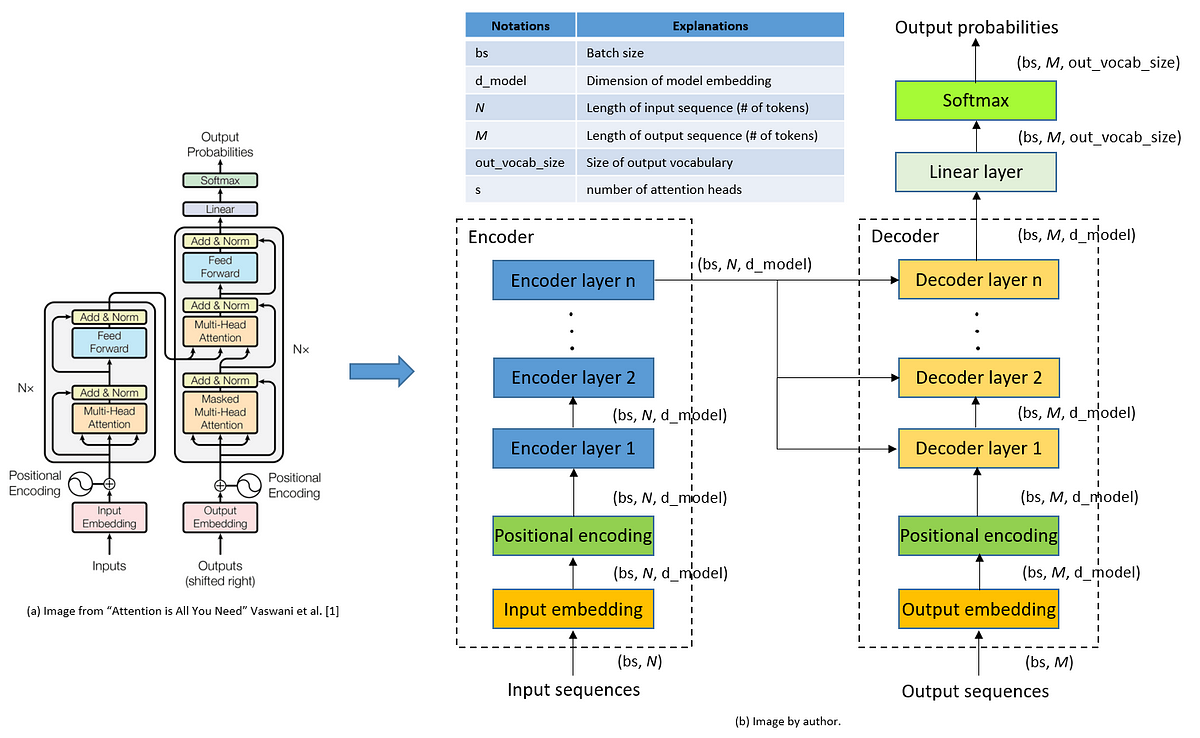
A Deep Dive Into the Transformer Architecture – The Development of ...
Tensor Product Attention(TPA)とは?Transformerのメモリ効率を改善する新手法 | AI-Papers
Table 1 from Transformer-Based Tensor Nuclear Norm for Multi ...
Tensor Memory: Fixed-Size Recurrent State for Long-Horizon Transformers
Figure 3 from Transformer-Based Tensor Nuclear Norm for Multi ...
理解语言的 Transformer 模型 | TensorFlow Core
Schematic diagram of transformer model. | Download Scientific Diagram
Higher Order Transformers: Efficient Attention Mechanism for Tensor ...
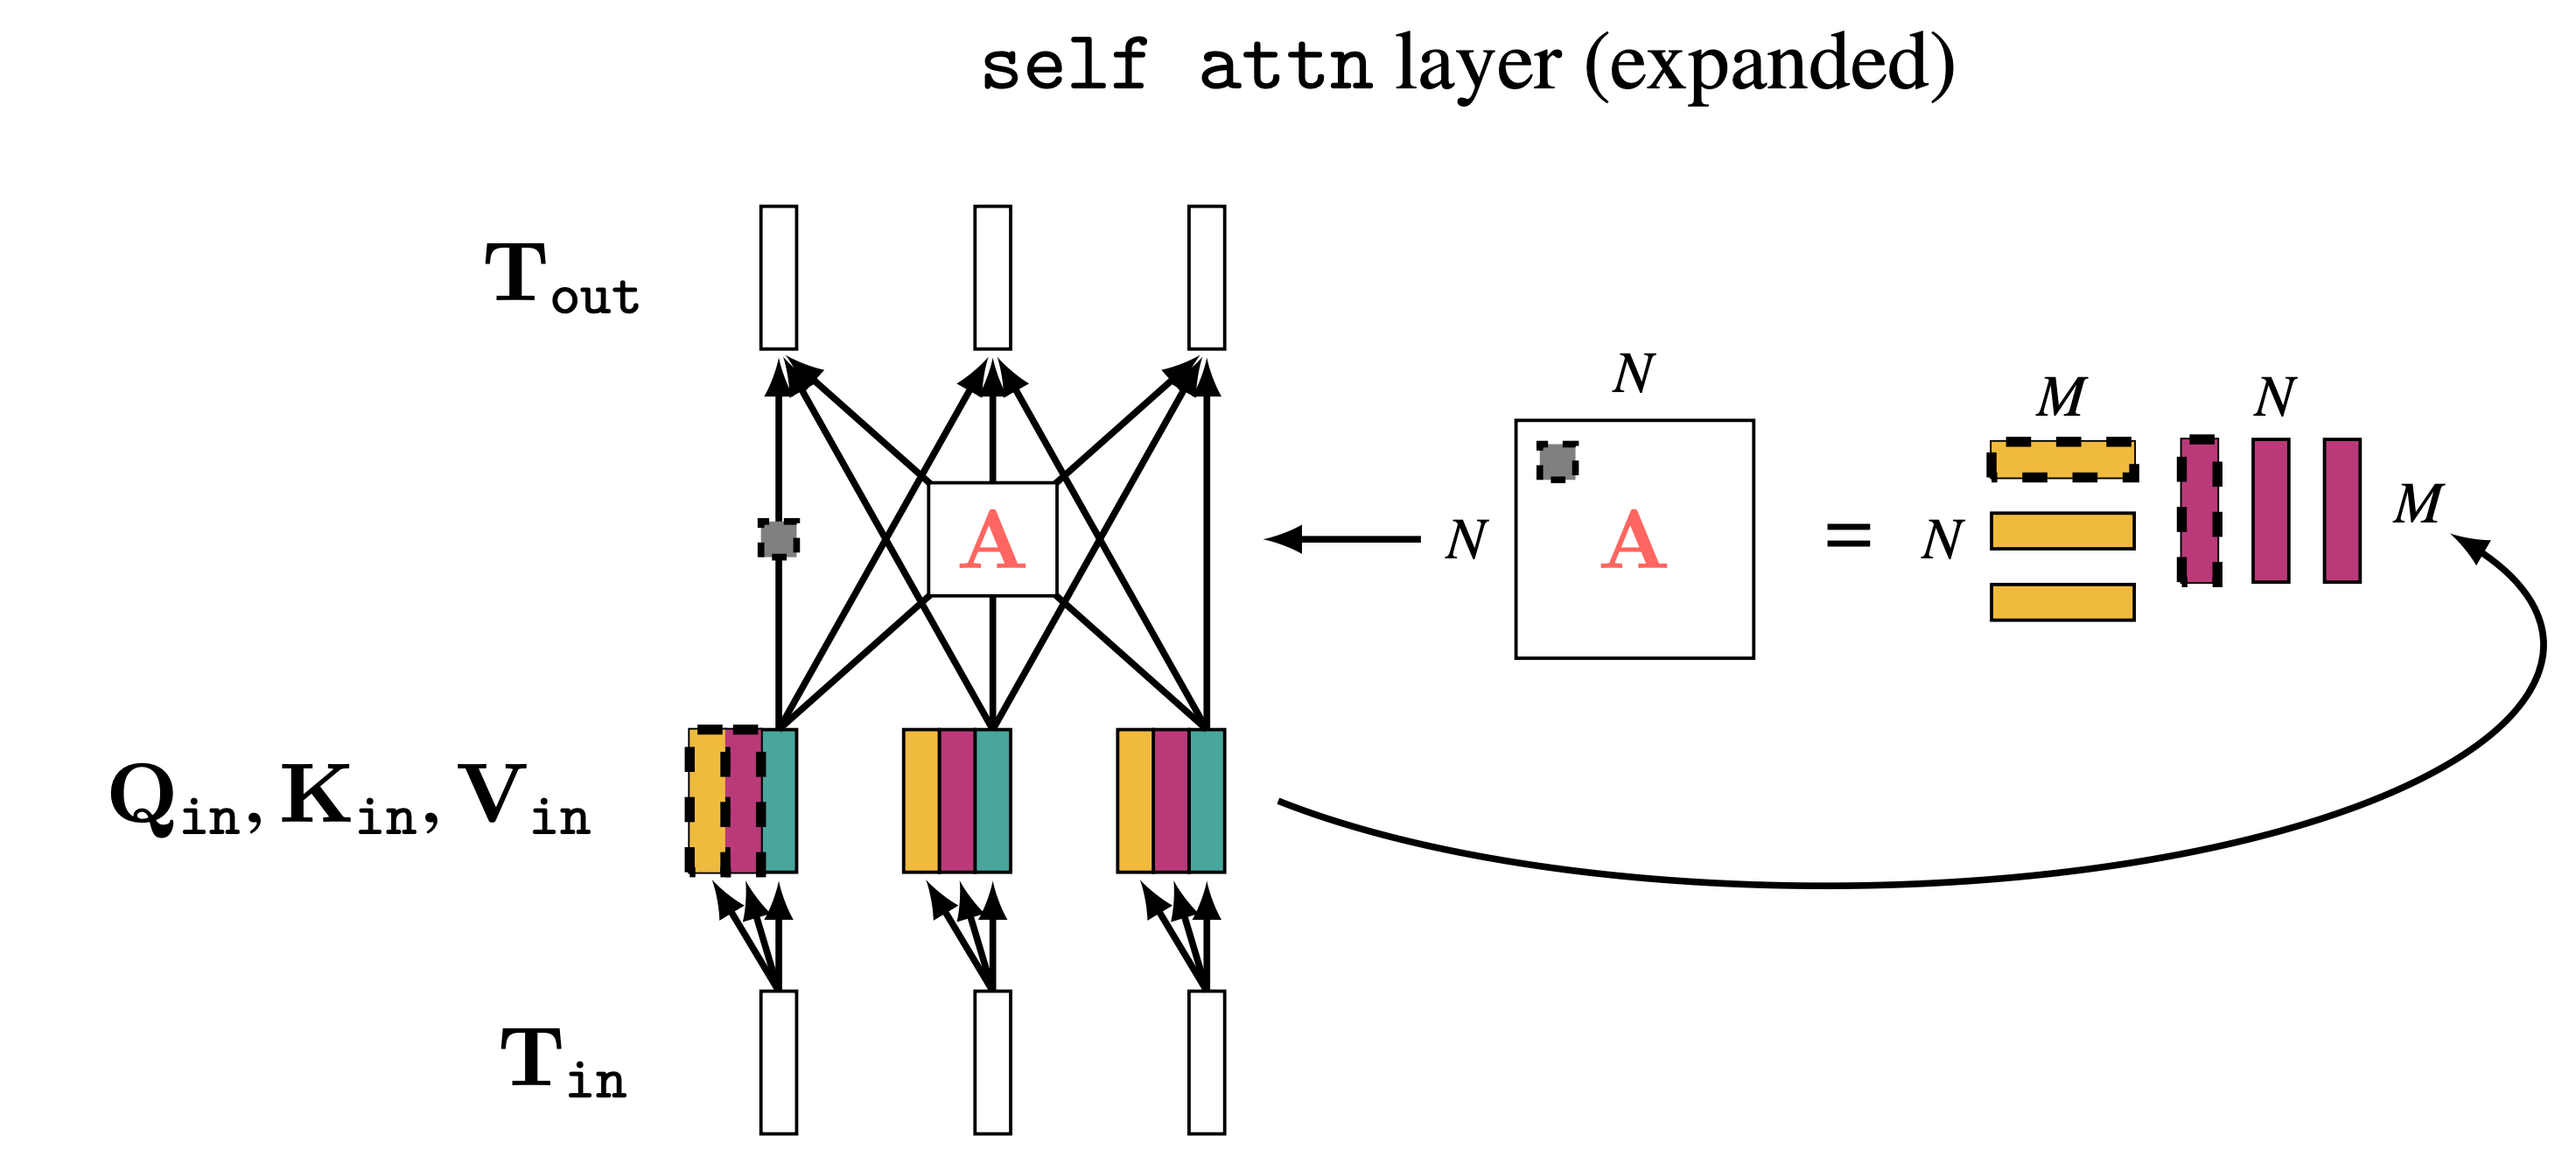
Transformer Architecture (Part 2— Self-Attention) | by Eugene Ku | Medium
Tensor Parallelism — MLX 1.0.0 documentation
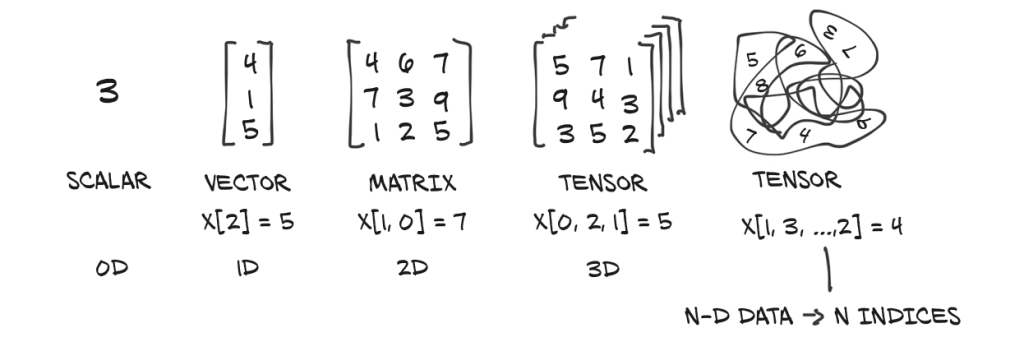
Tensor Fundamentals: Empowering Artificial Intelligence Advancements ...
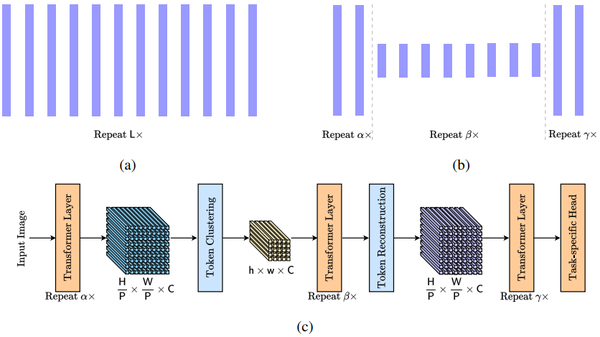
Figure 2 from A $T^{2}$-Tensor-Aided Multiscale Transformer for ...
Transformer Block | luisquintanilla/dotnet-tensors-guide | DeepWiki
Illustration of transformer unit and multi-head selfattention module ...
An Overview of Transformer Architecture Using Self-Attention Mechanism ...
Mastering LLM Techniques: Inference Optimization | NVIDIA Technical Blog
Tensors in Large Language Models – My AI Site
Medium
Google Colab
NVIDIA 技术博客:NVIDIA Hopper 深入研究架构-CSDN社区
[论文评述] TEAFormers: TEnsor-Augmented Transformers for Multi-Dimensional ...
【Transformer 基础系列】手推显存占用 - 知乎
Pytorch一行代码便可以搭建整个transformer模型 - 知乎
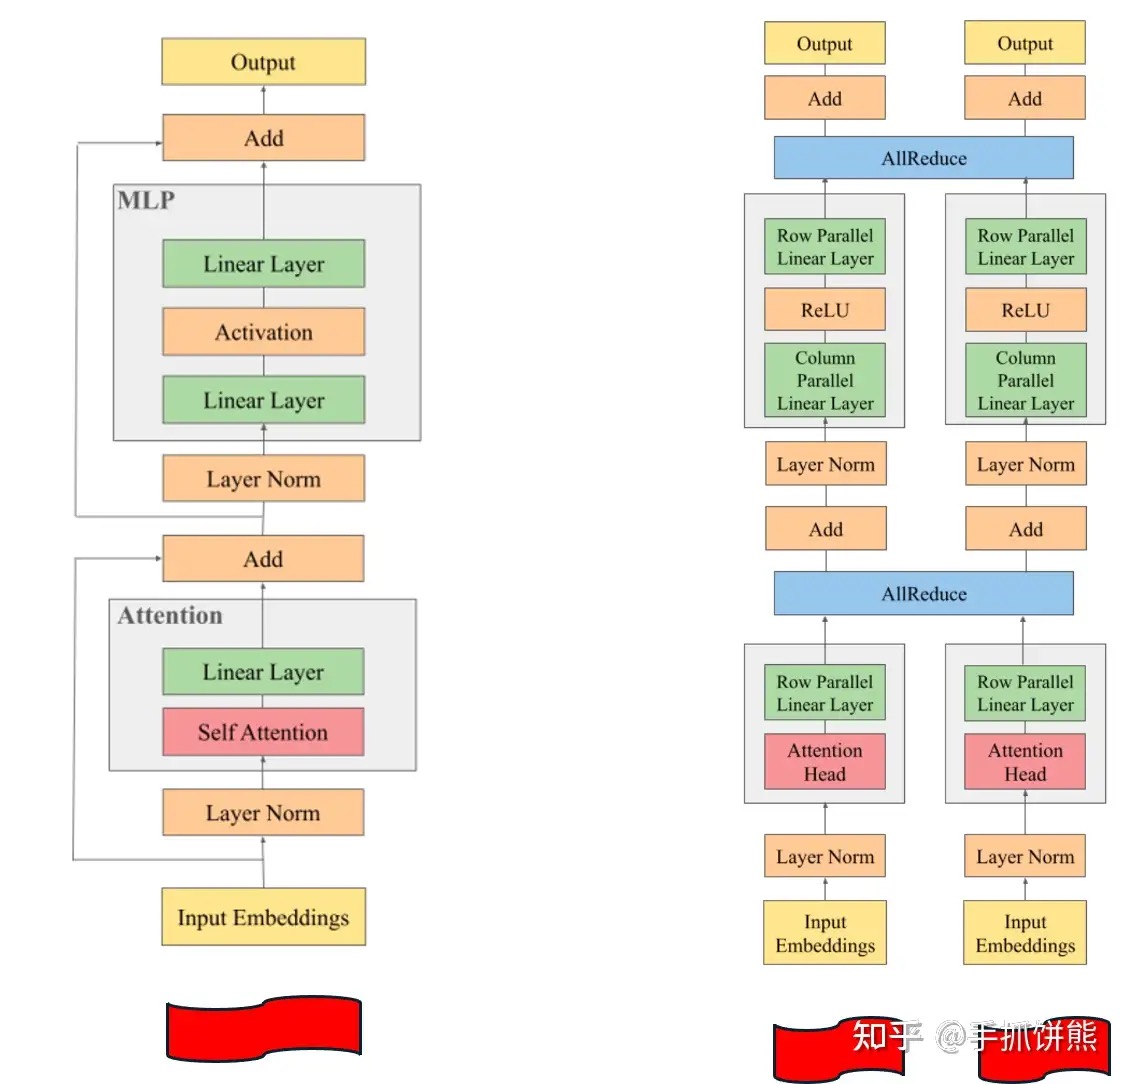
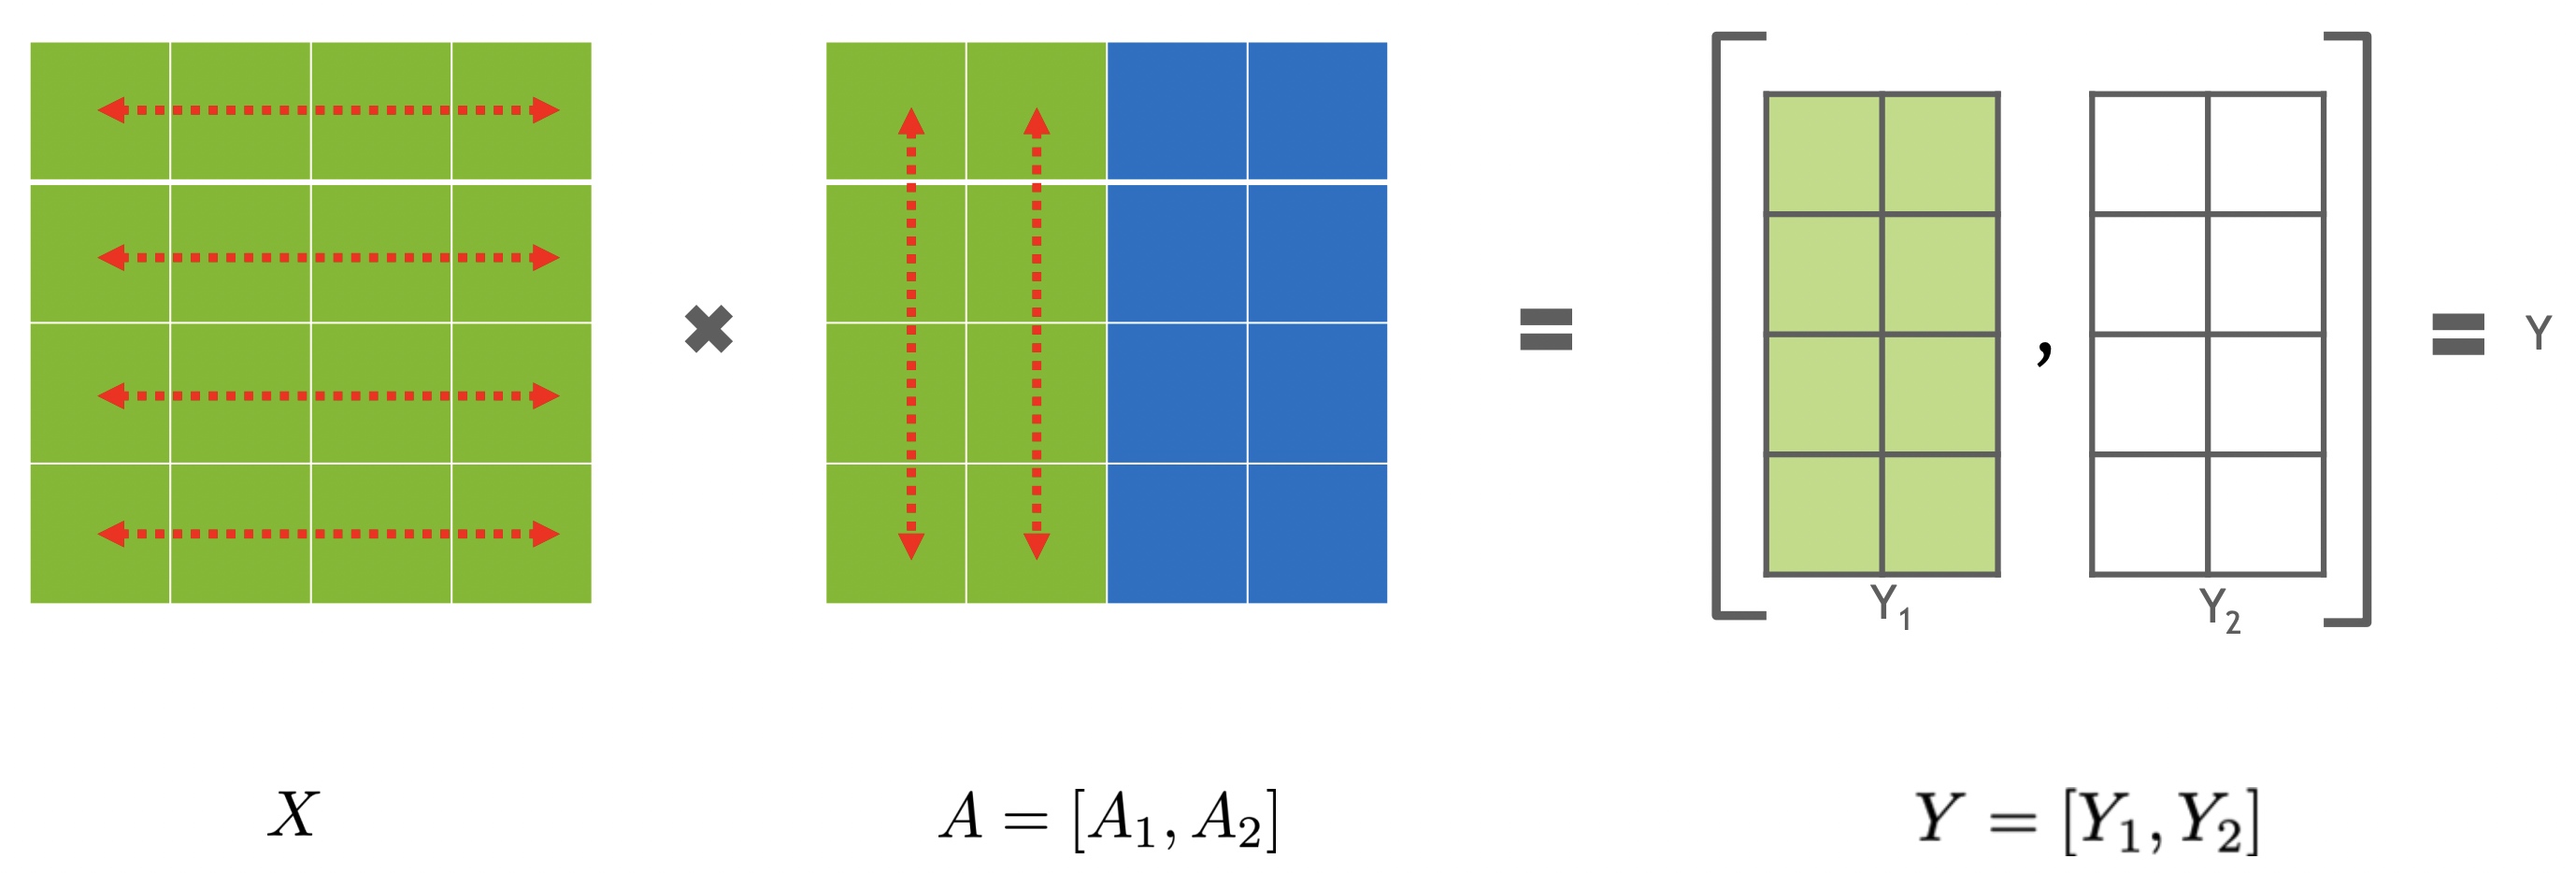
详解MegatronLM Tensor模型并行训练(Tensor Parallel) | MLTalks
[2110.04725] Yuan 1.0: Large-Scale Pre-trained Language Model in Zero ...
详解MegatronLM Tensor模型并行训练(Tensor Parallel)_megatron-lm-CSDN博客
Behind the Magic: How Tensors Drive Transformers | Towards Data Science
简单易懂地从底至上地学懂CuTe - Edwardlyz - 博客园
Transformer的最简洁pytorch实现_transformer模型代码-CSDN博客
TensorDictModule — tensordict 0.4 documentation
训练大模型并行和内存优化技术 | Yue Shui 博客
Pytorch Transforms Tensordataset – SBMOQQ
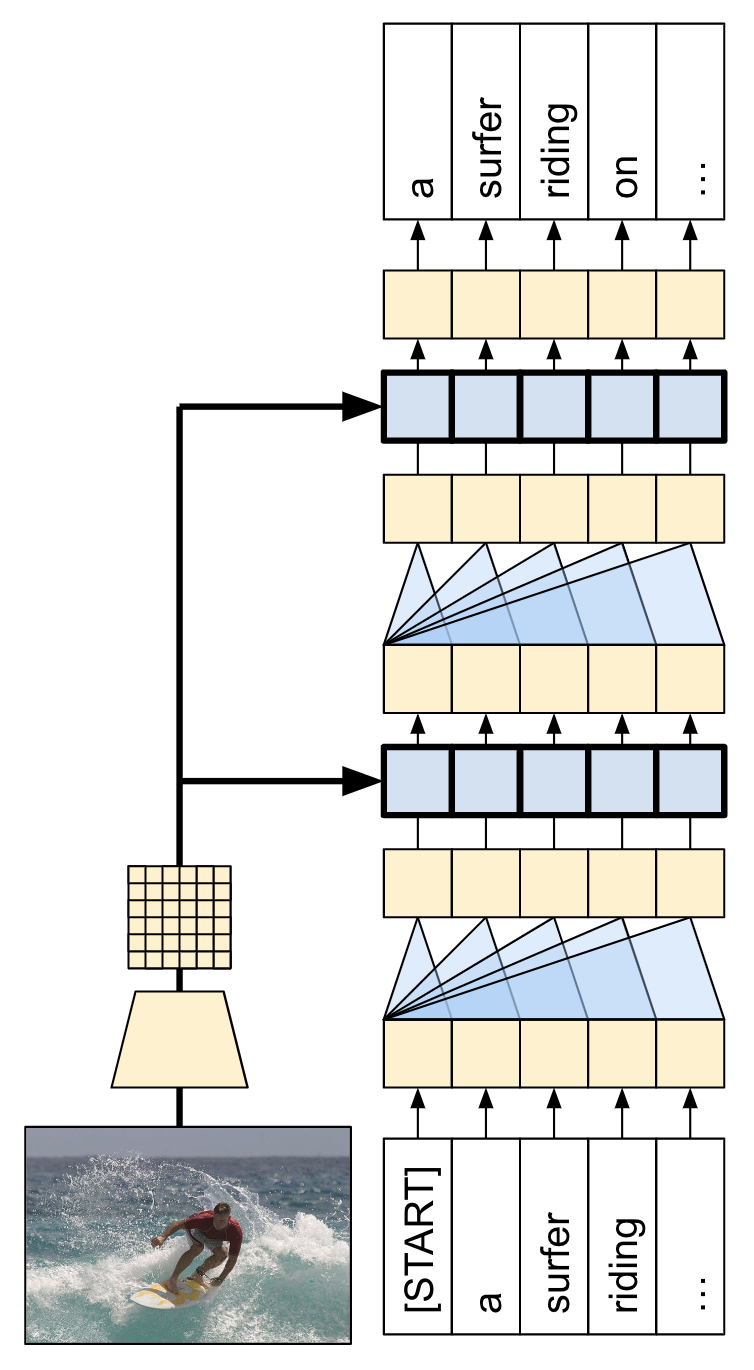
使用视觉注意力生成图像描述 — tensorflow-book 0.0.1 文档
Figure 2 from Toward Compact Transformers for End-to-End Object ...
Transformer模型拆解分析_transformer 模型 tensor并行 拆分-CSDN博客
NiuTrans - 小牛开源社区
Figure 3 from Toward Compact Transformers for End-to-End Object ...
Coursework Projects - Mugdha
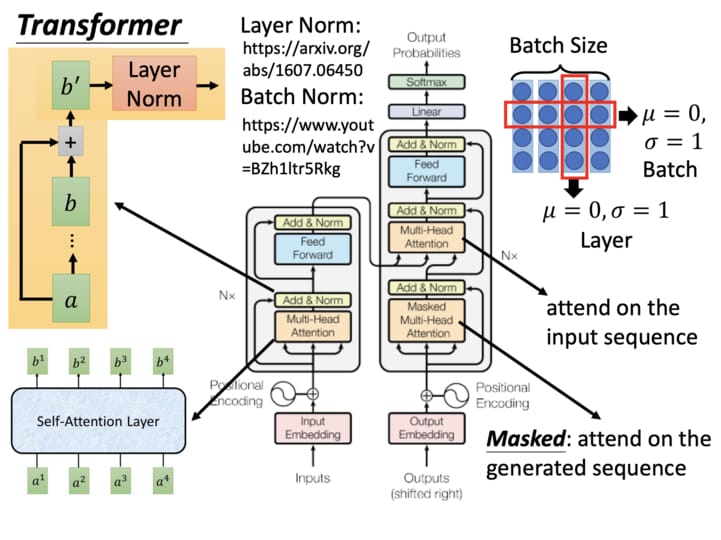
[综述] A survey of Transformers-[7] LayerNorm和FFN - 知乎
From Text to Tensors: Loading Data, Tokenizing, and Embedding in ...
GitHub - tensorops/TransformerX: Flexible Python library providing ...
TensorFlow.org-Transformer-for-machine-translation/transformer_machine ...
【必收藏】手把手教你理解Transformer的词嵌入与位置编码-CSDN博客
Transformers: The Architecture That Changed Everything ...
What is Supervised Machine Learning?
通过高效的长上下文大语言模型训练扩展到数百万个 Token - NVIDIA 技术博客
Raj Gandhi on LinkedIn: #100dayschallenge #machinelearning # ...
[PDF] A Multimodal Fusion Network for Student Emotion Recognition Based ...
26 Transformers – Foundations of Computer Vision
Transformer(Pytorch)部分讲解_number of encoder and decoder layers-CSDN博客
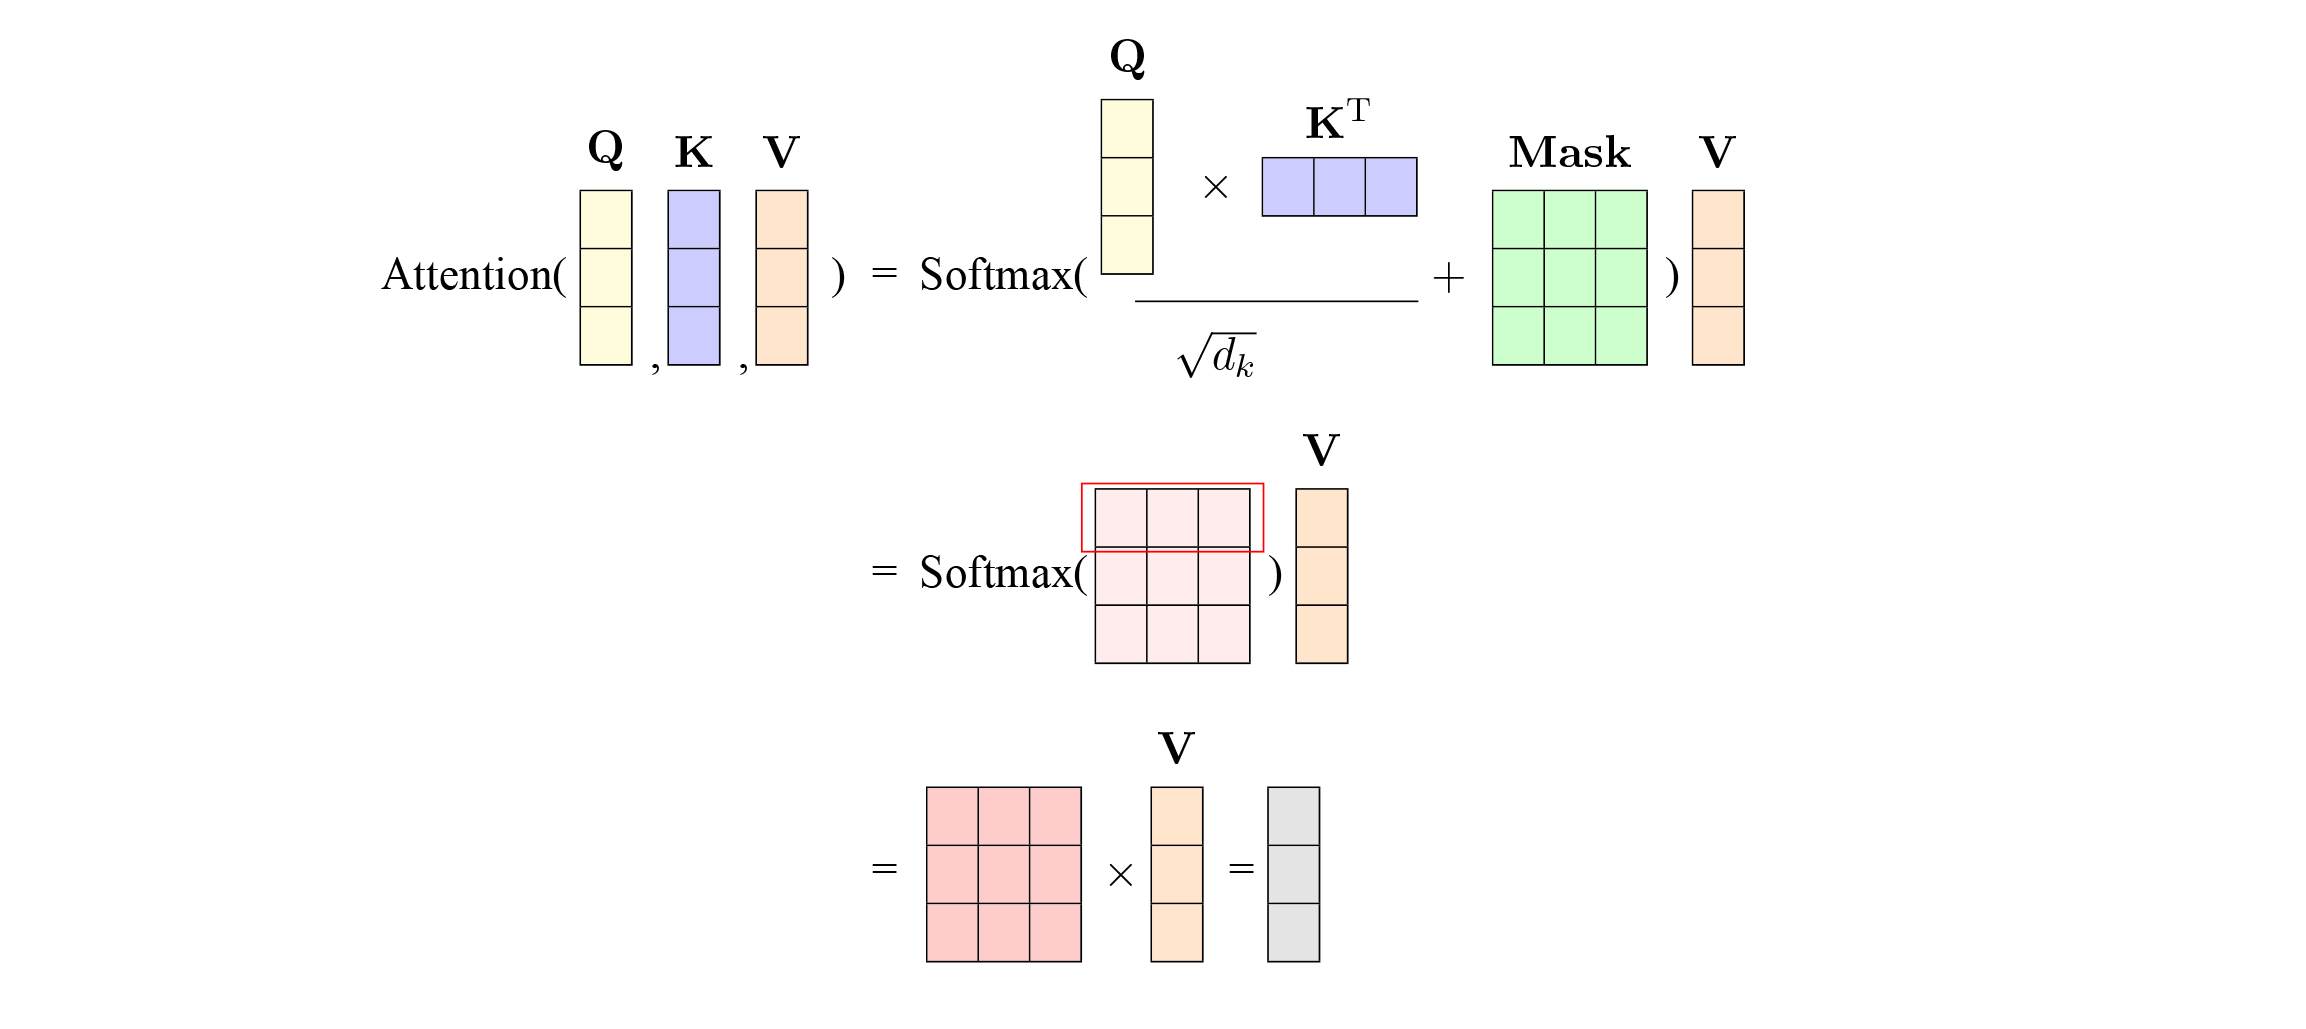
Self Attention 설명 : 최소한의 수식과 관련 논문으로 쉽게 이해하기
TRANSFORMERS | Tensor.Art
트랜스포머 (Transformer) · Data Science
Optimizing Memory Usage for Training LLMs and Vision Transformers in ...
大模型训练 - 李乾坤的博客
Transformers and Self-Attention | John Lambert
Attention机制详解(二)——Self-Attention与Transformer - 你的雷哥 - 博客园
【Transformer】认识 Self-Attention - 墨天轮