Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
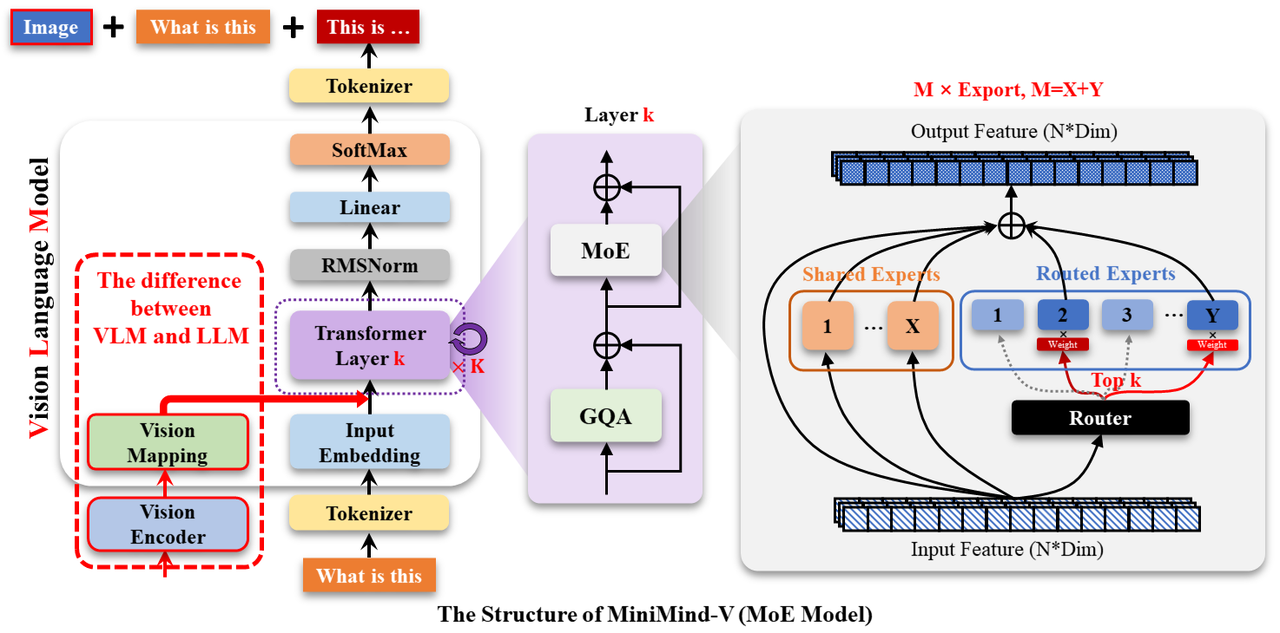
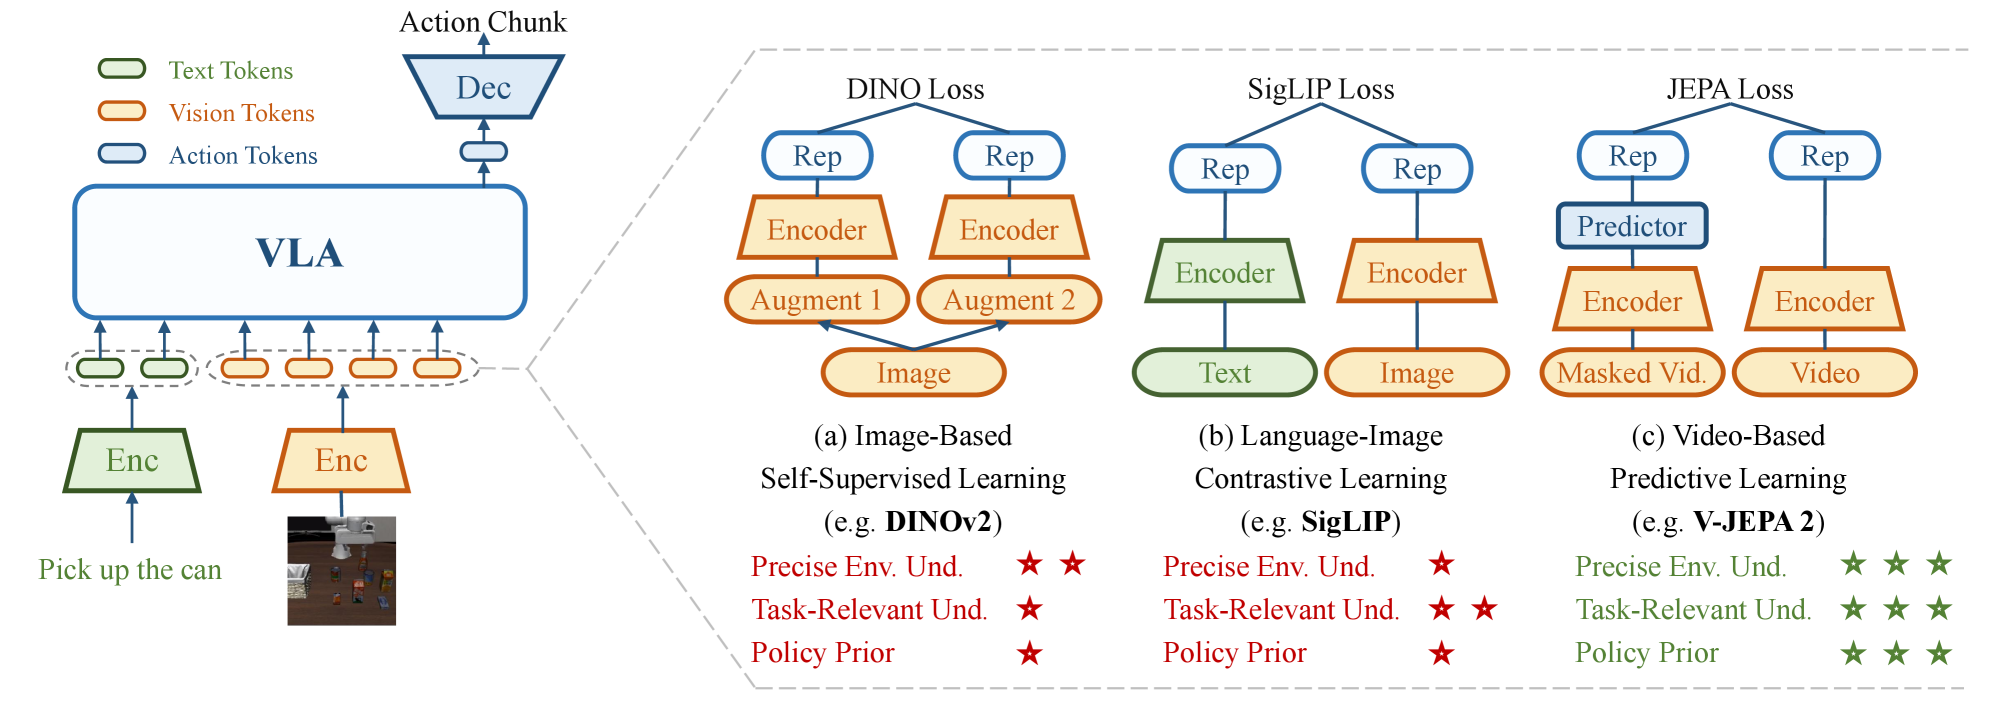
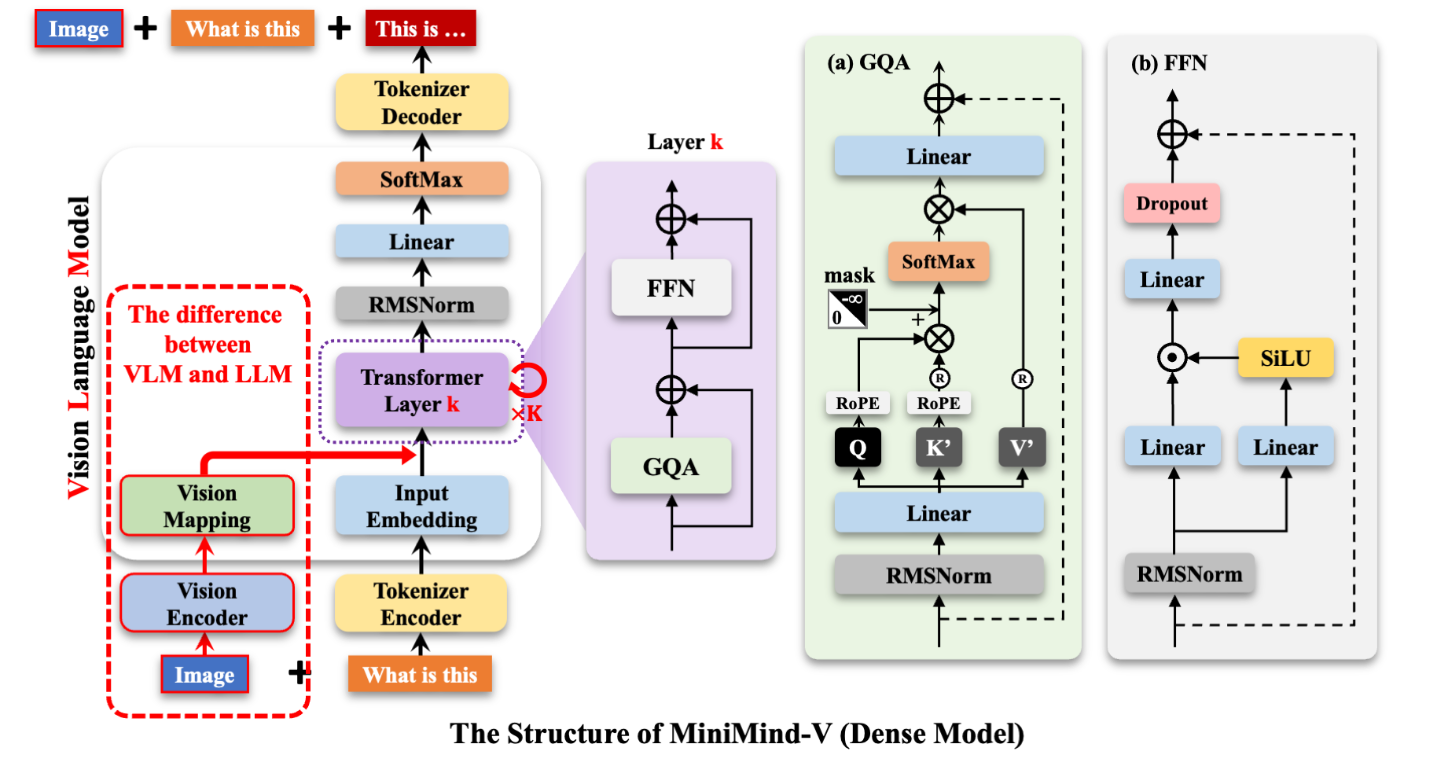
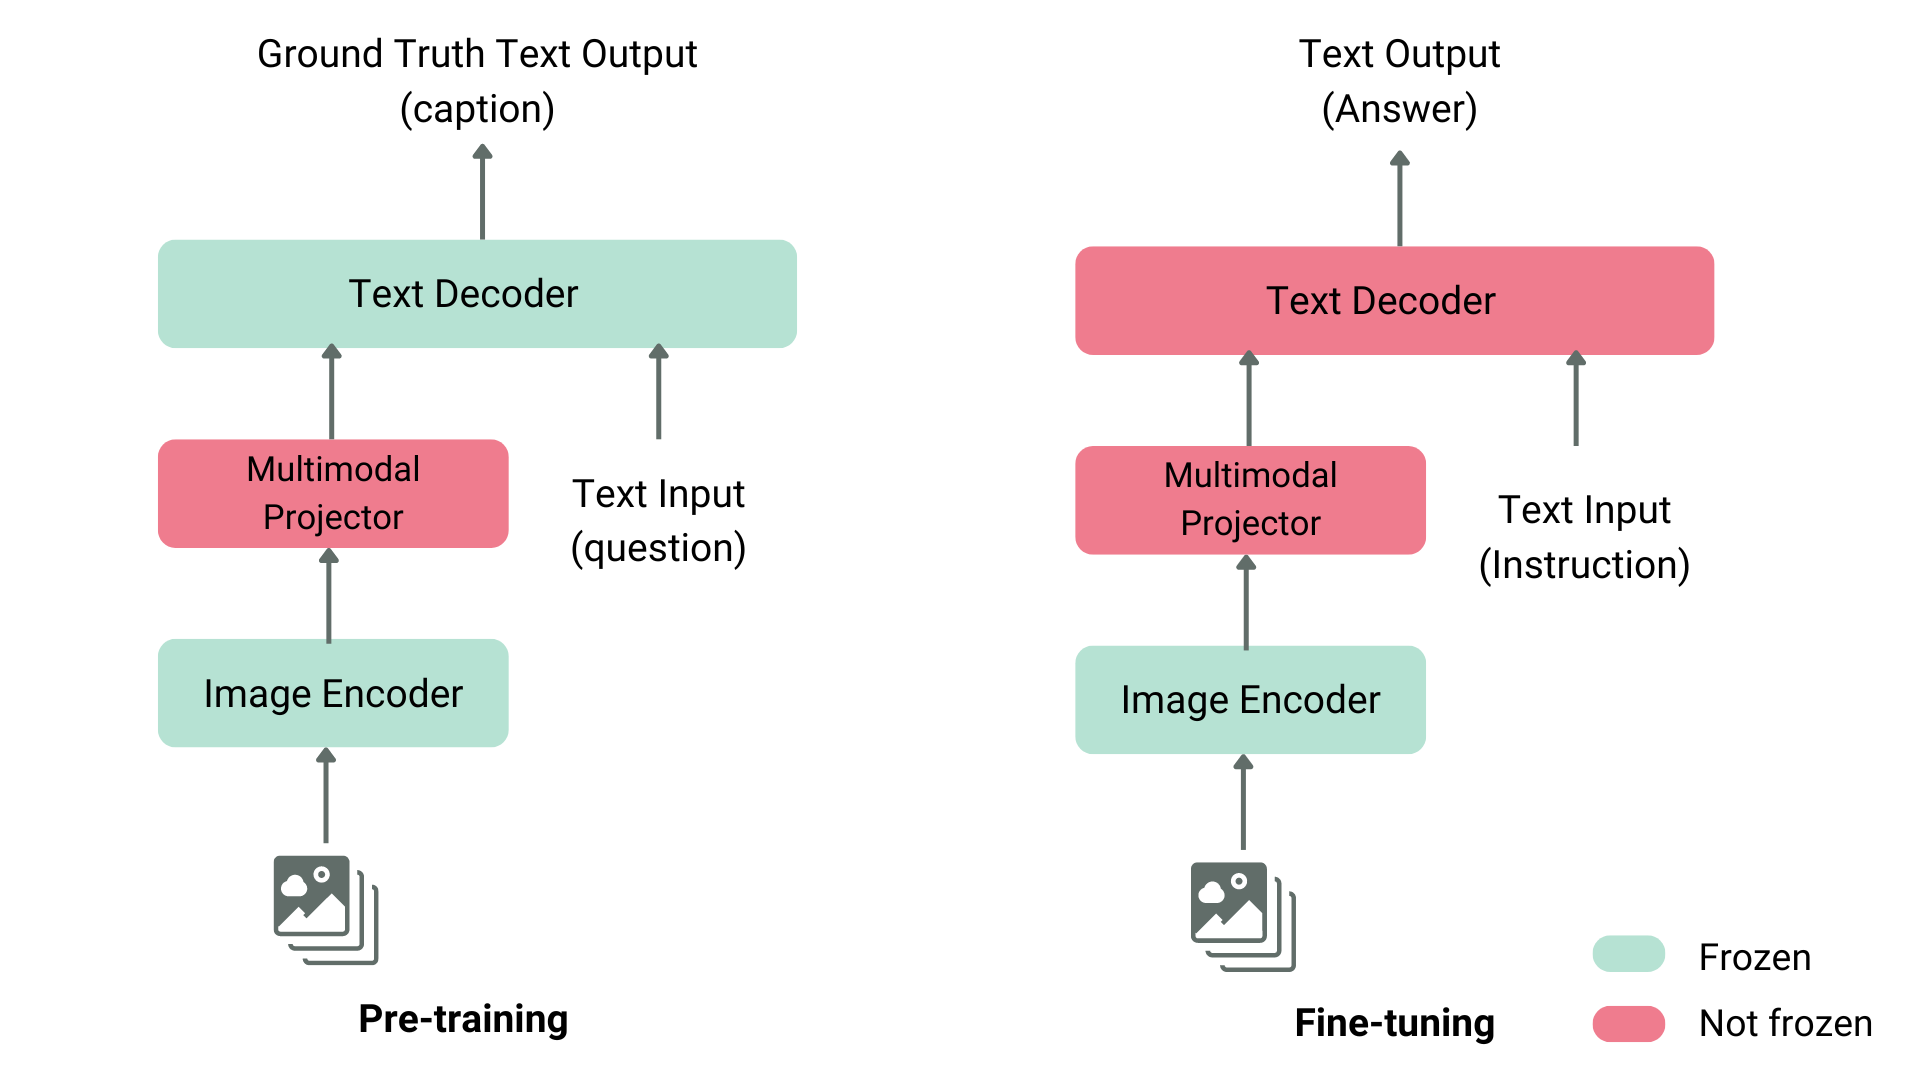
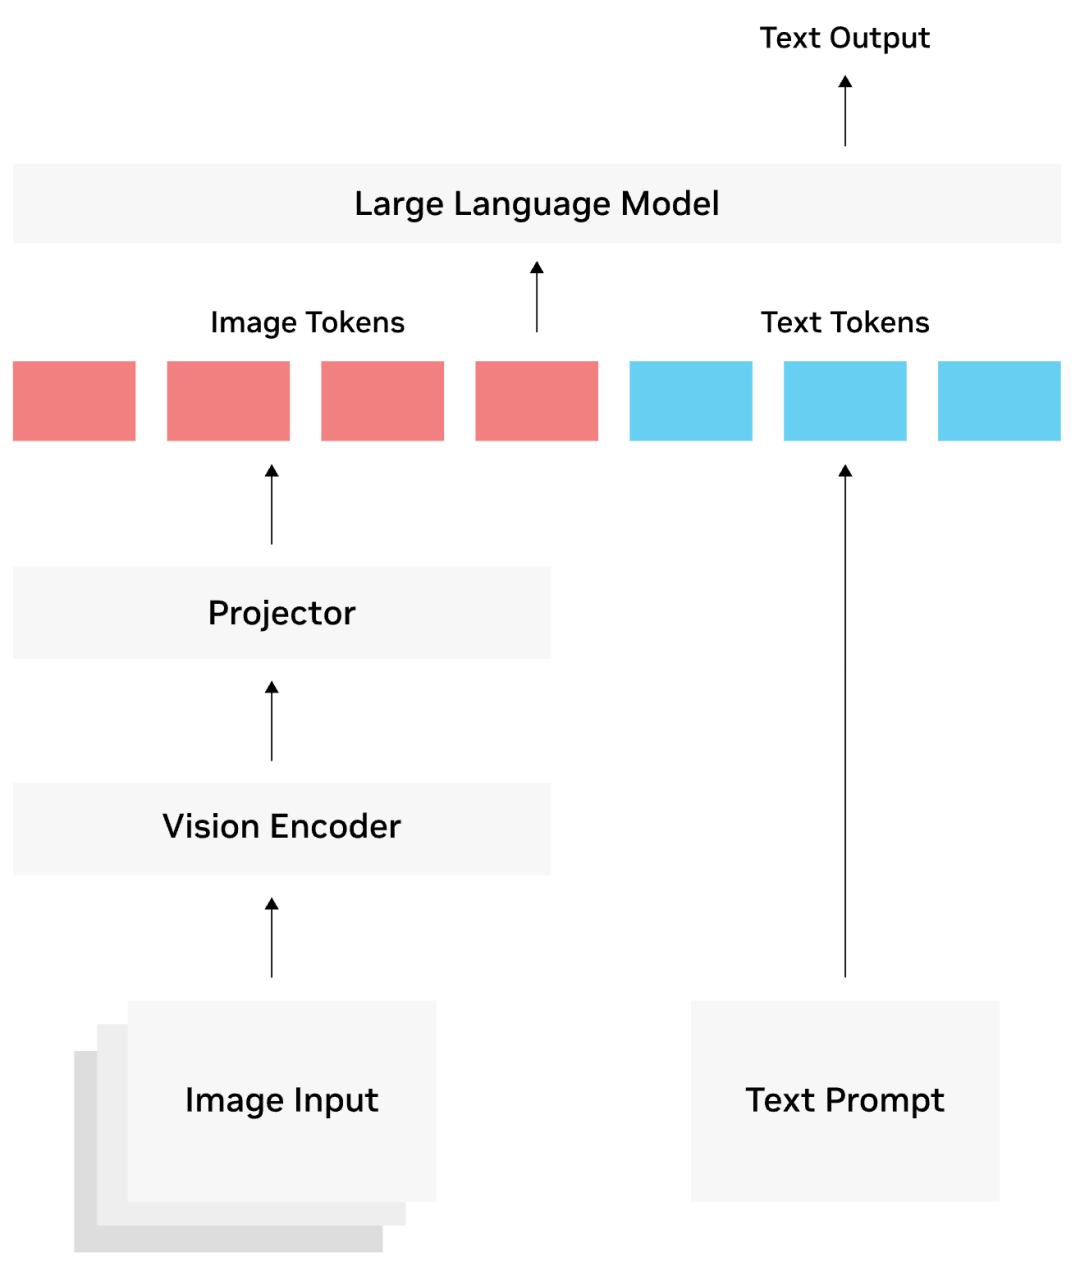
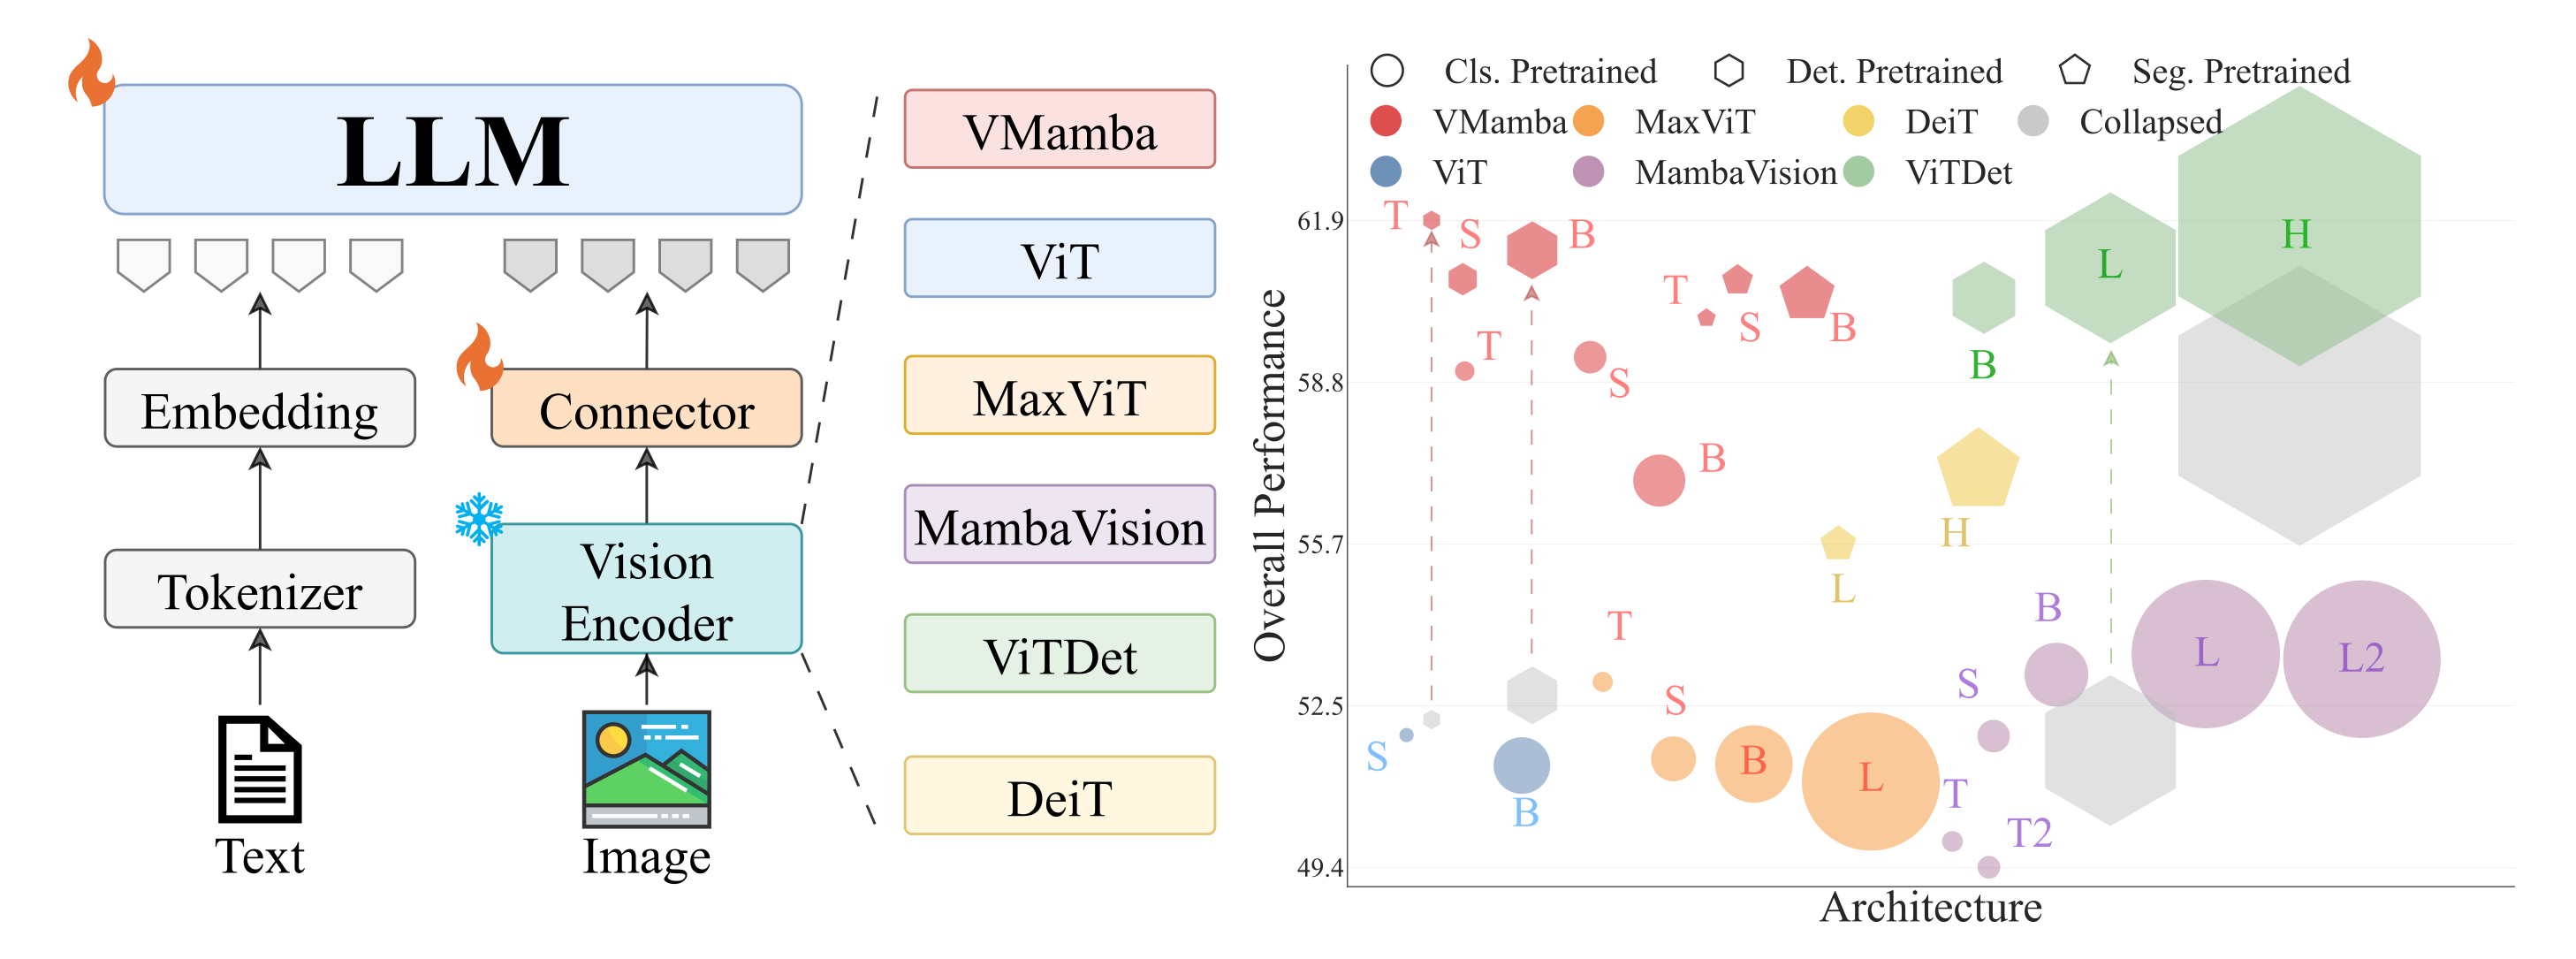
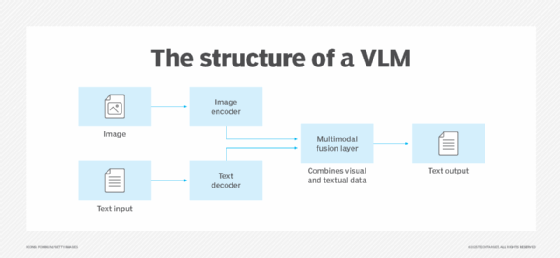
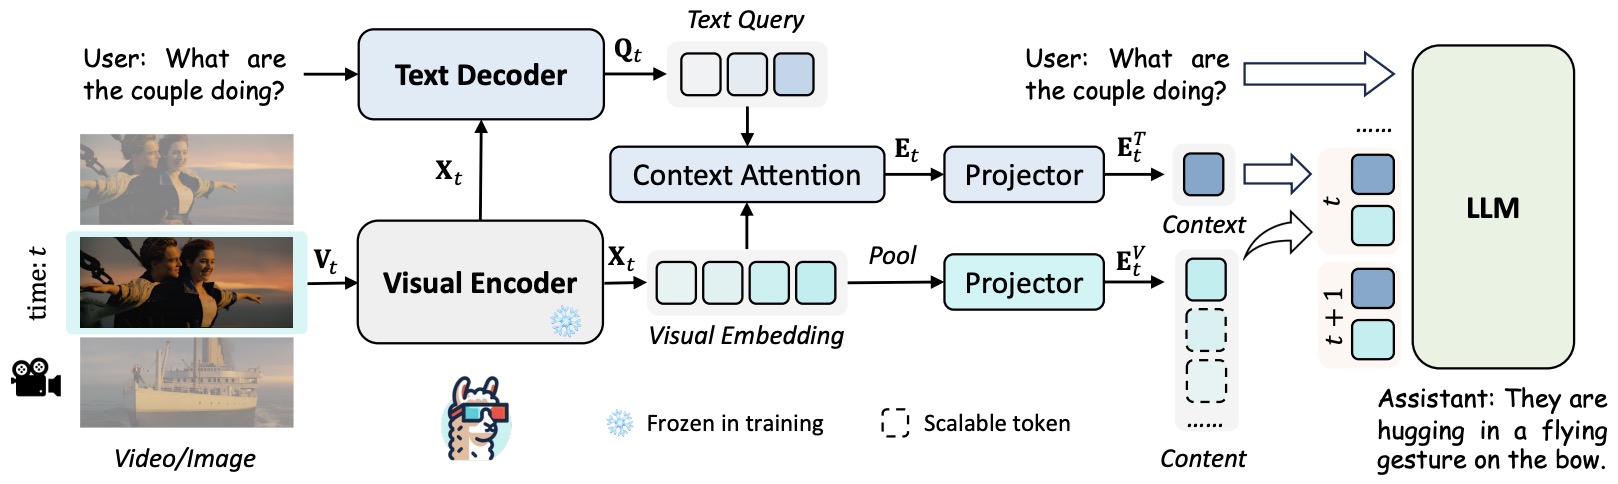
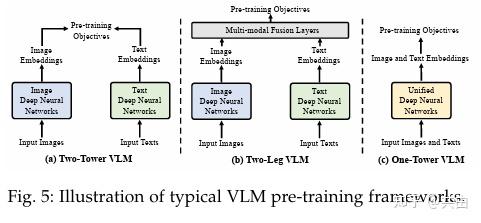
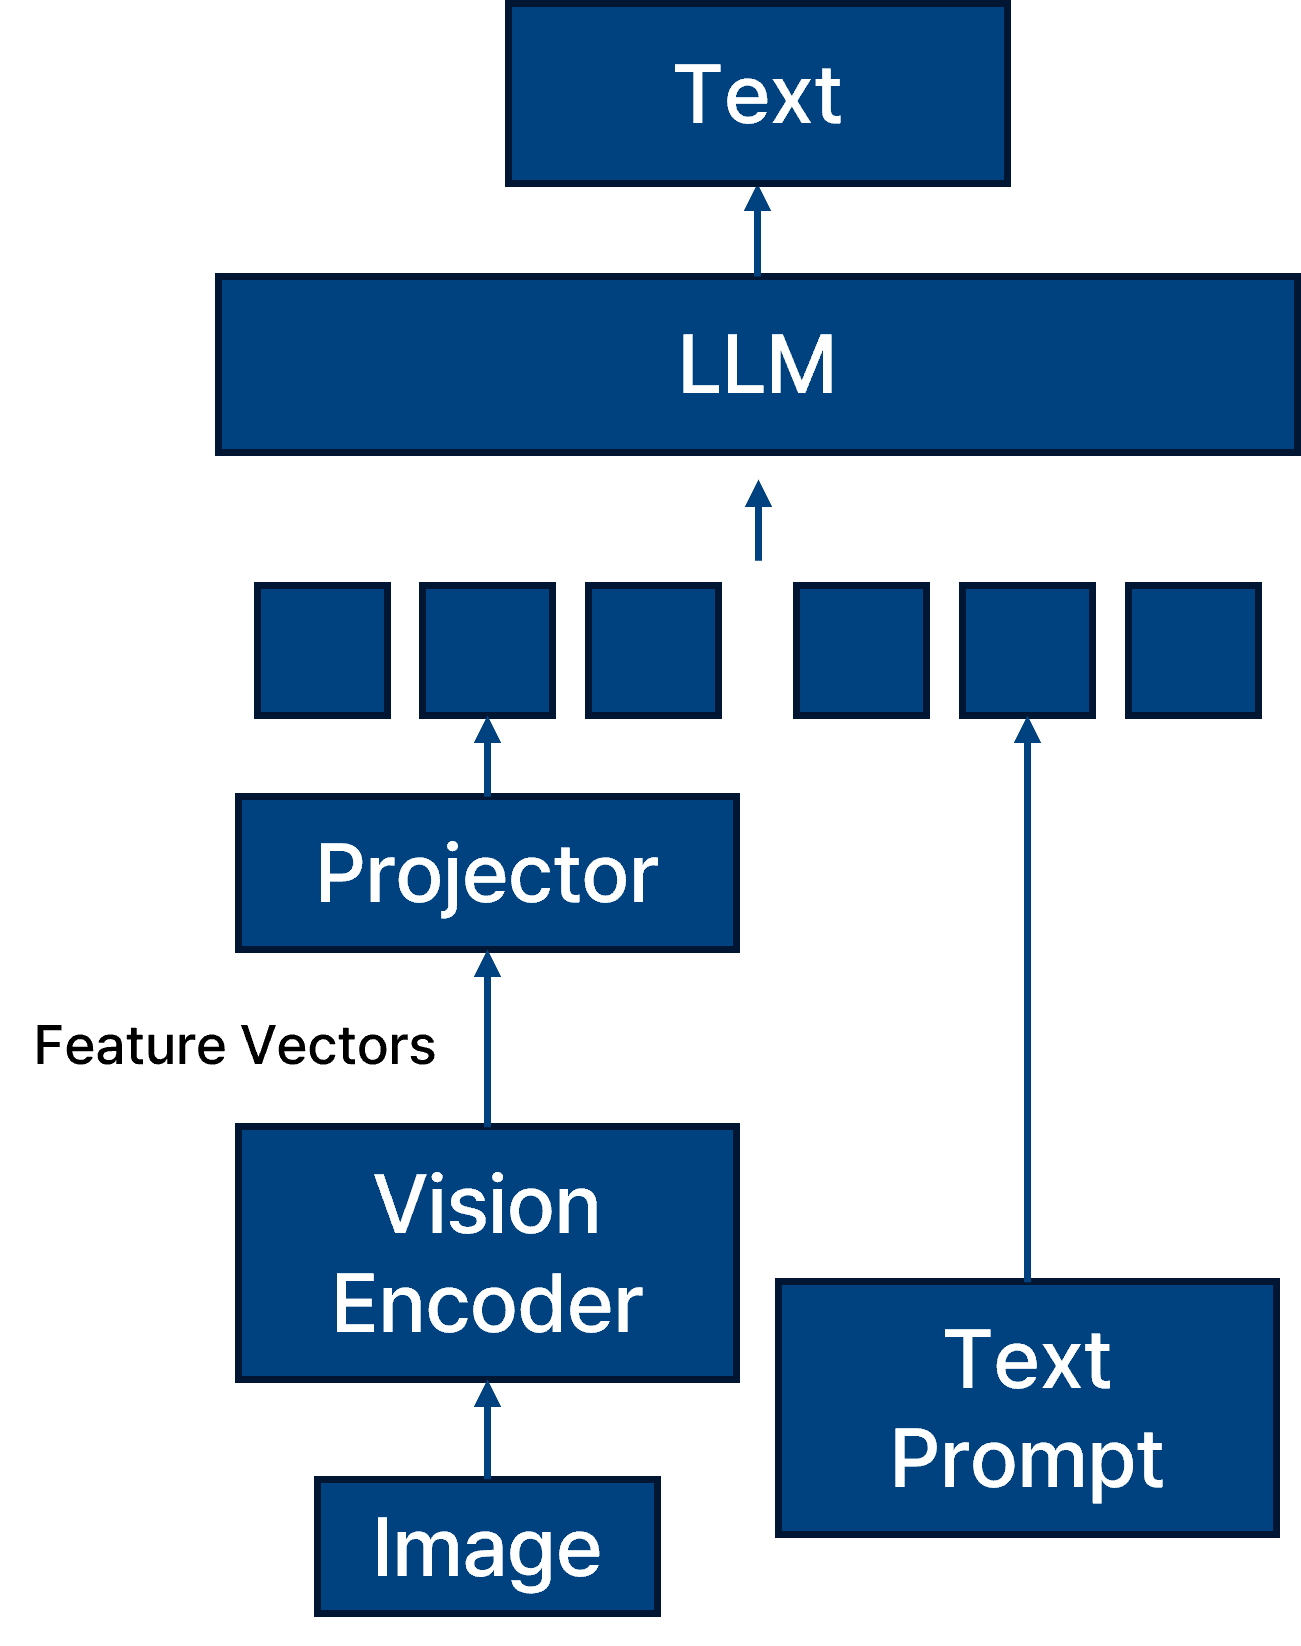
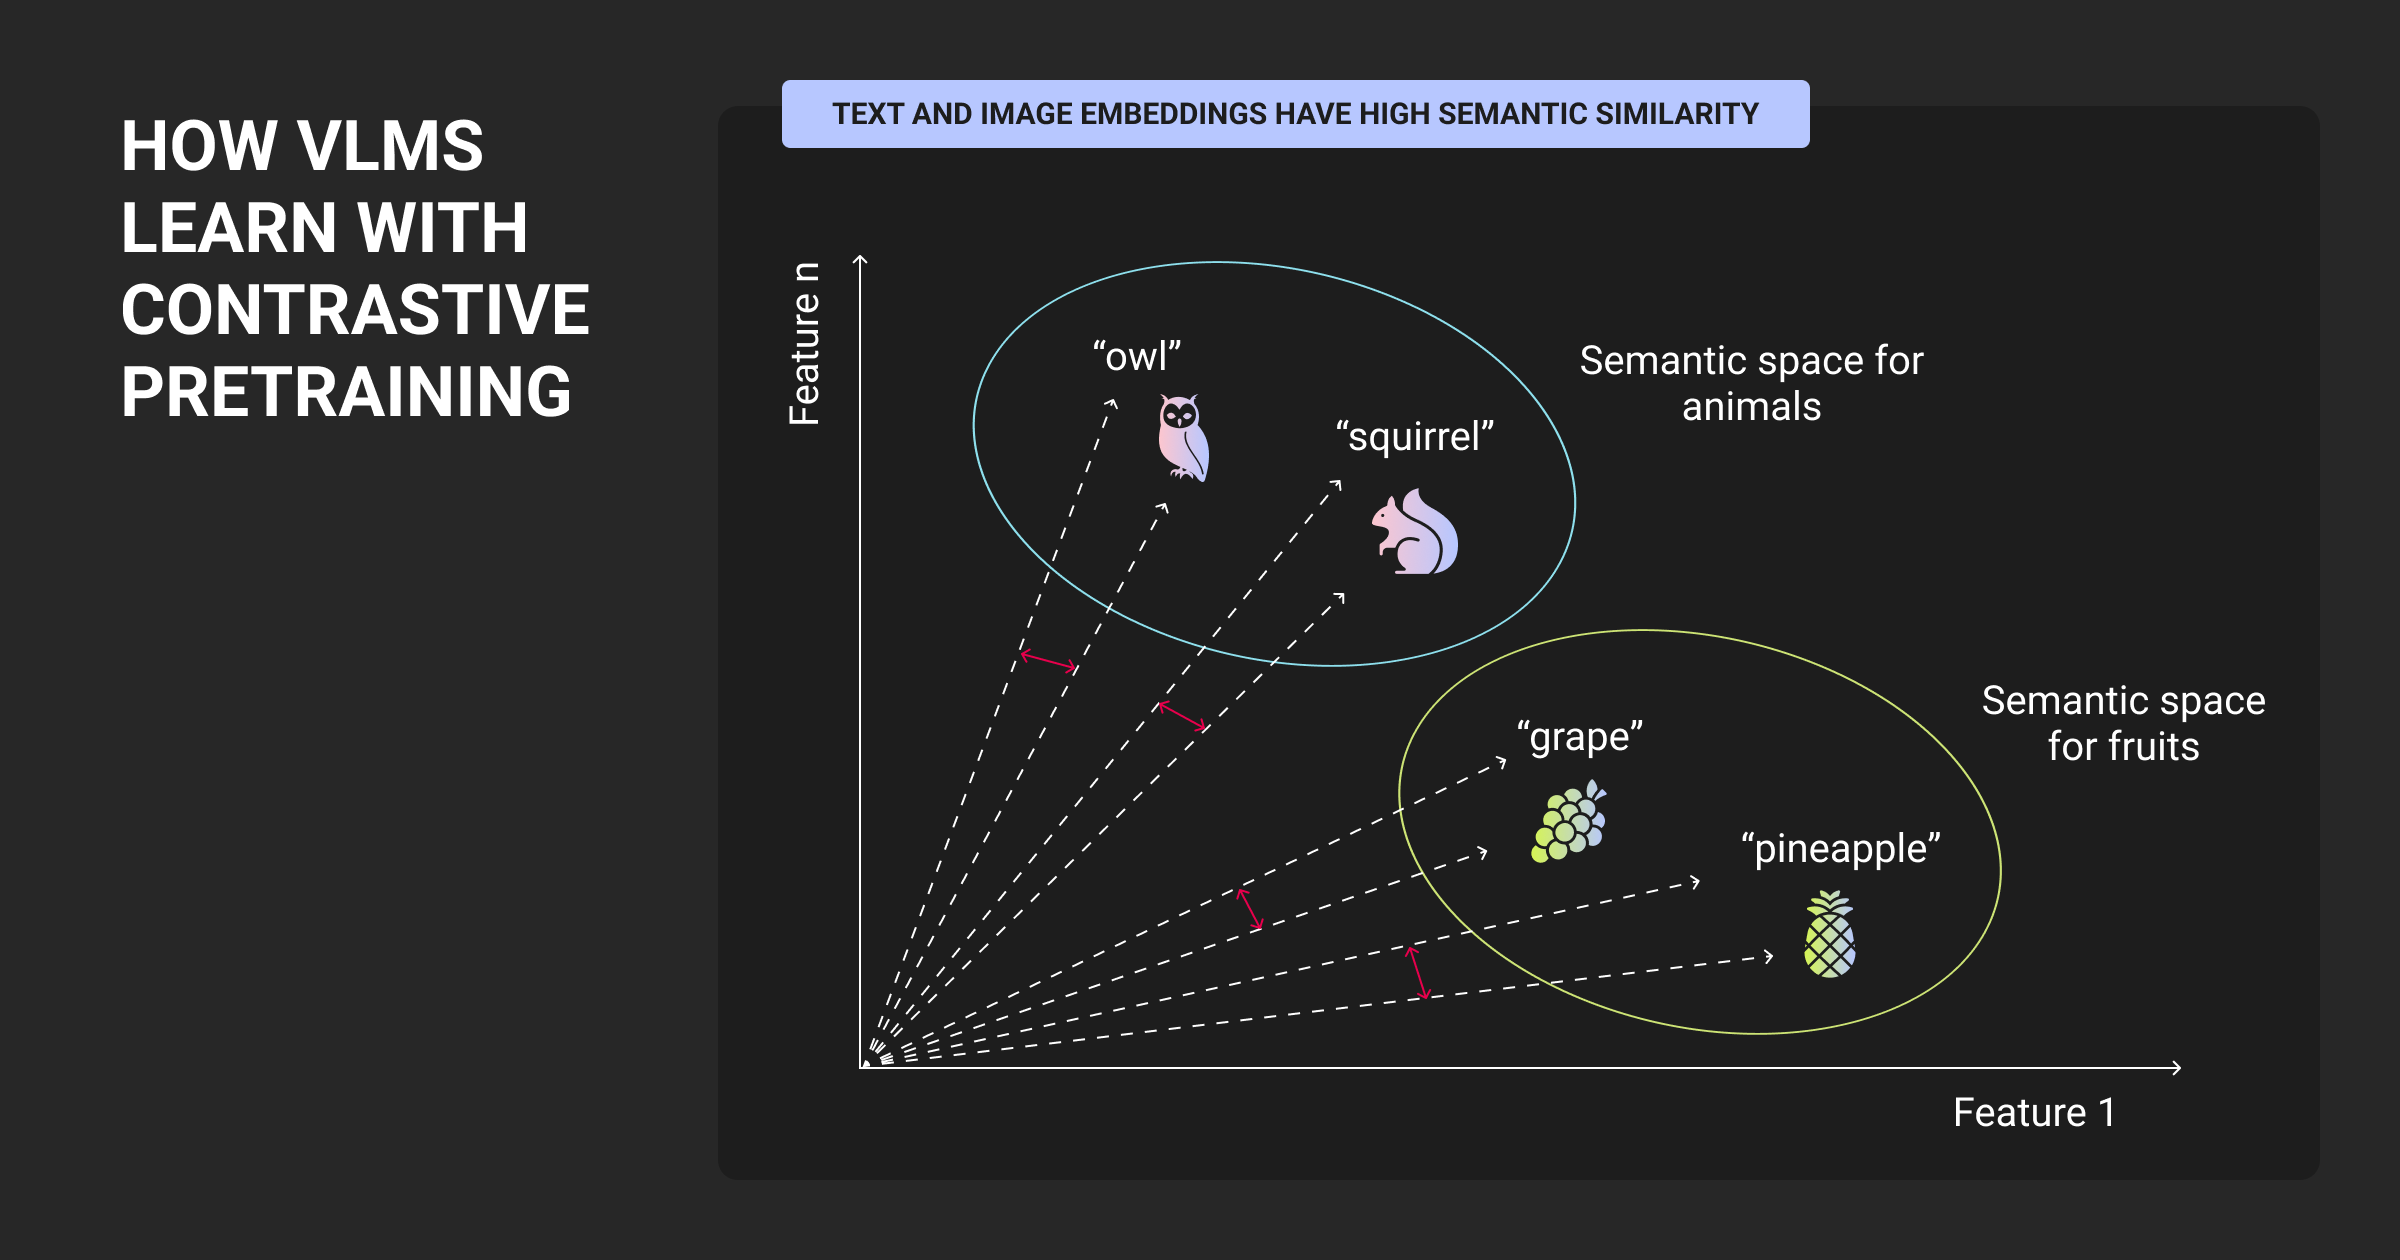
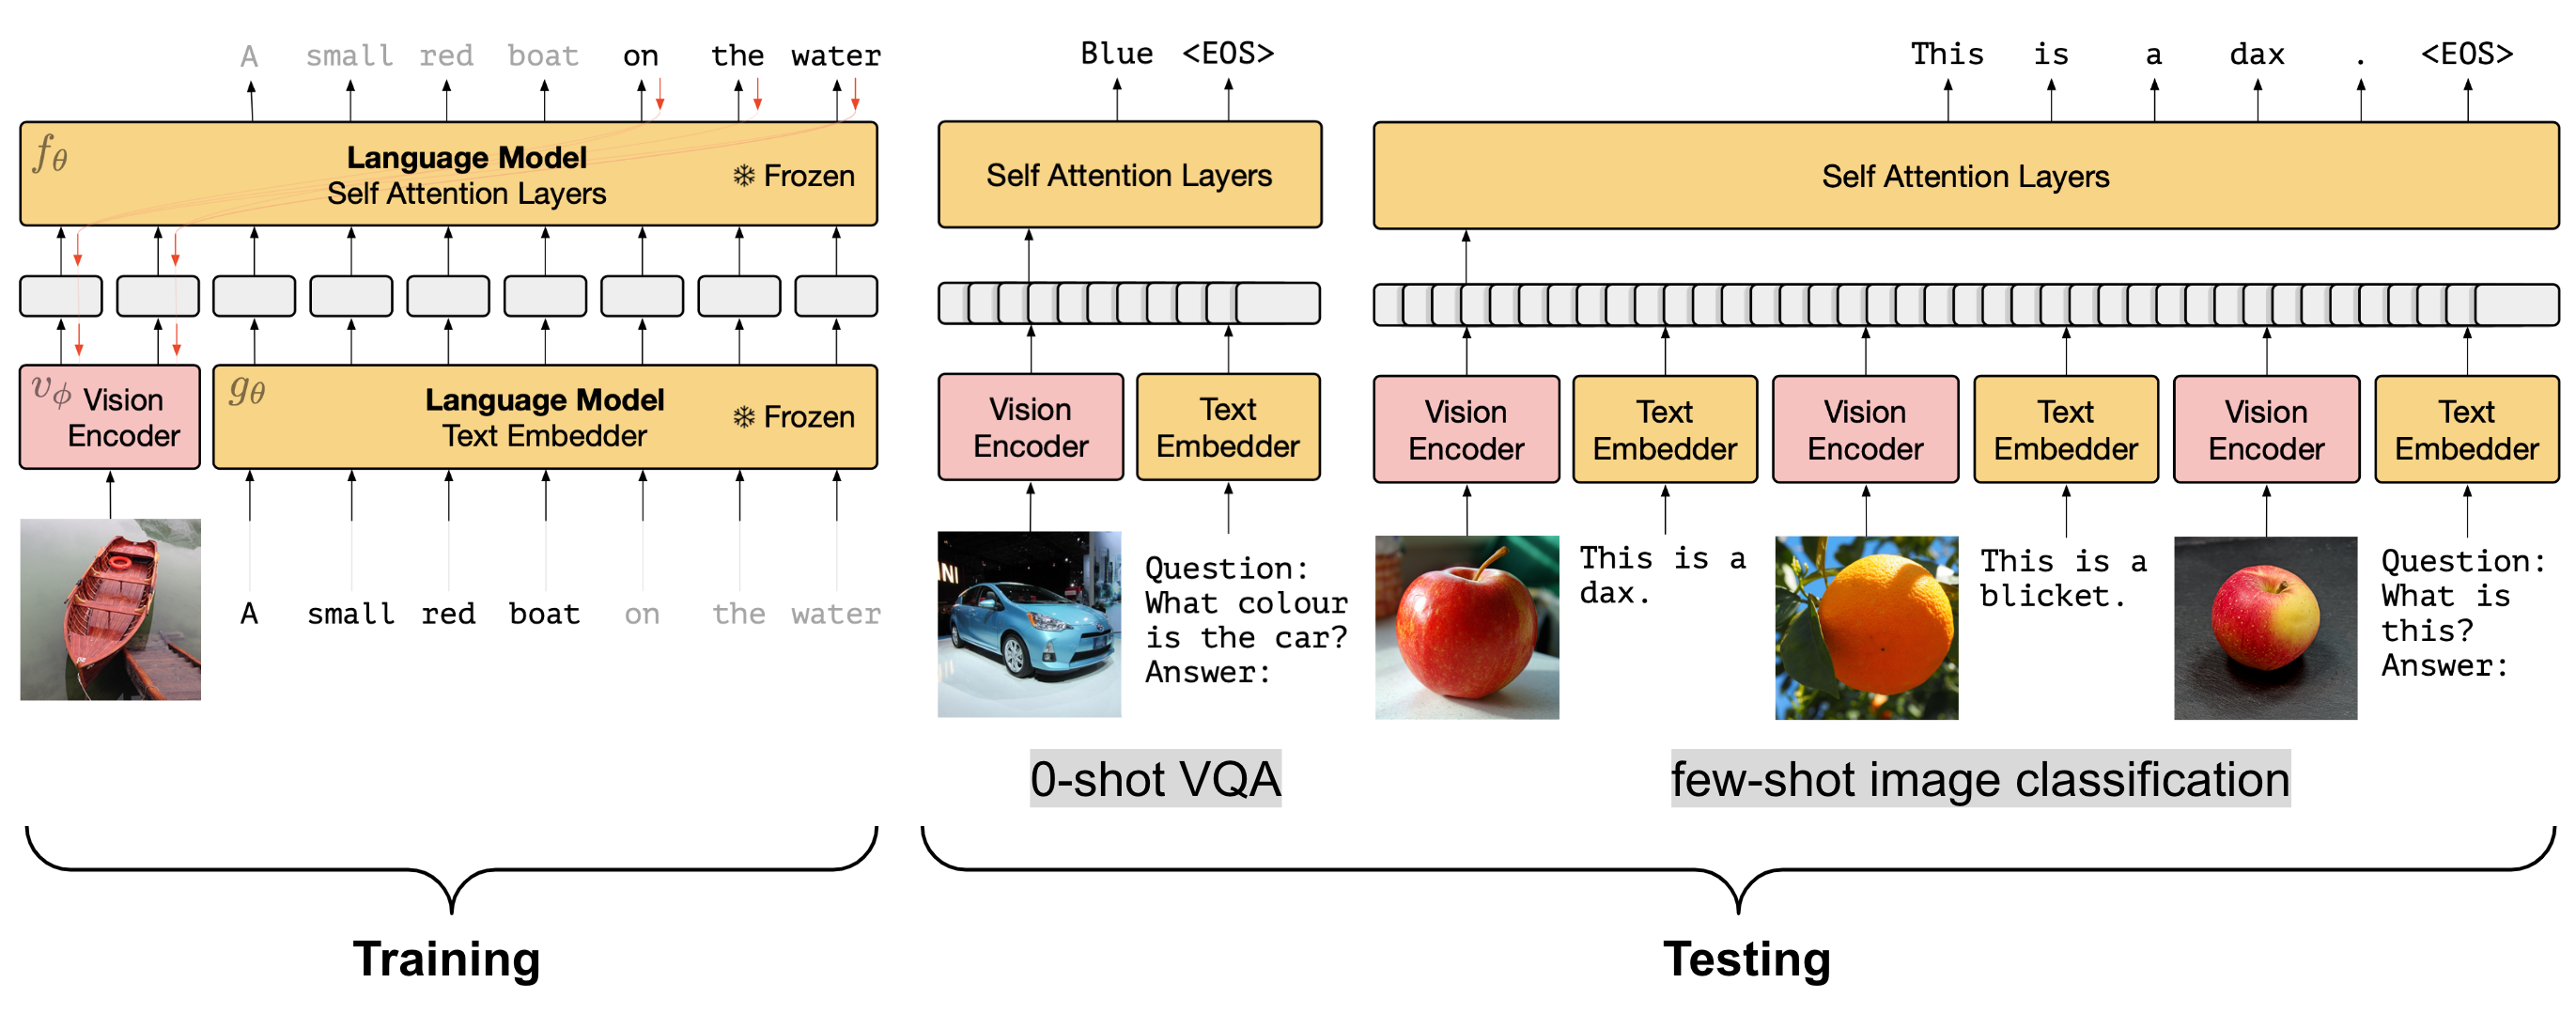
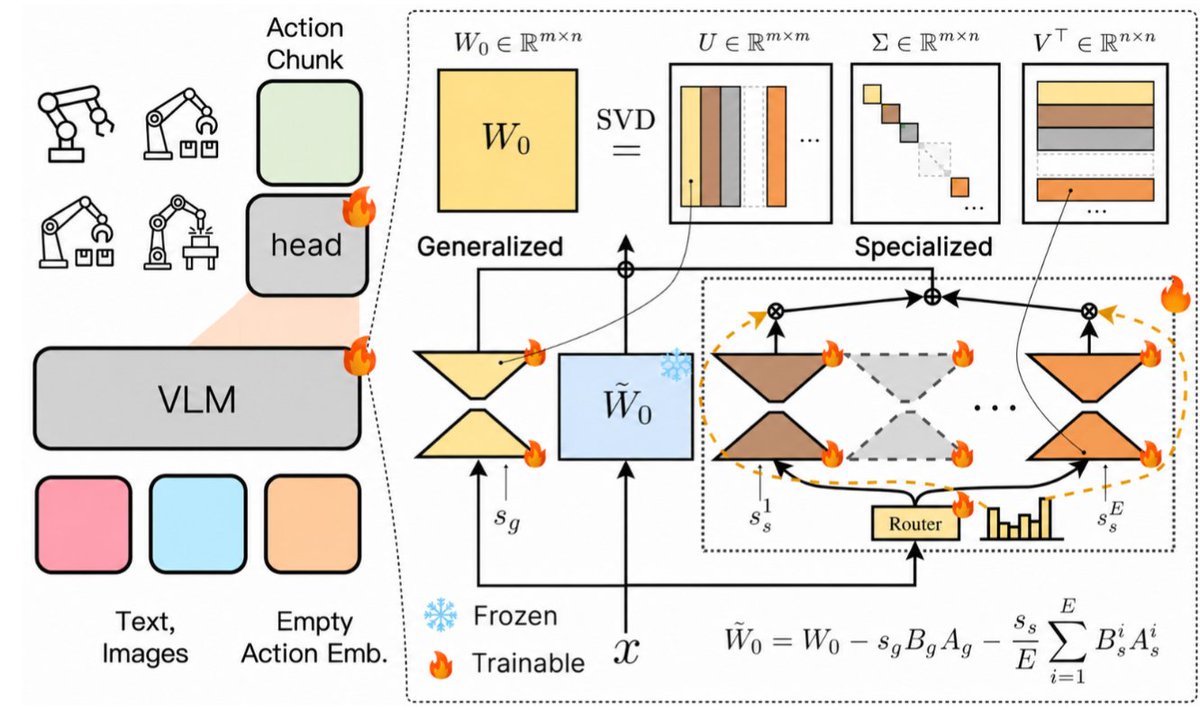
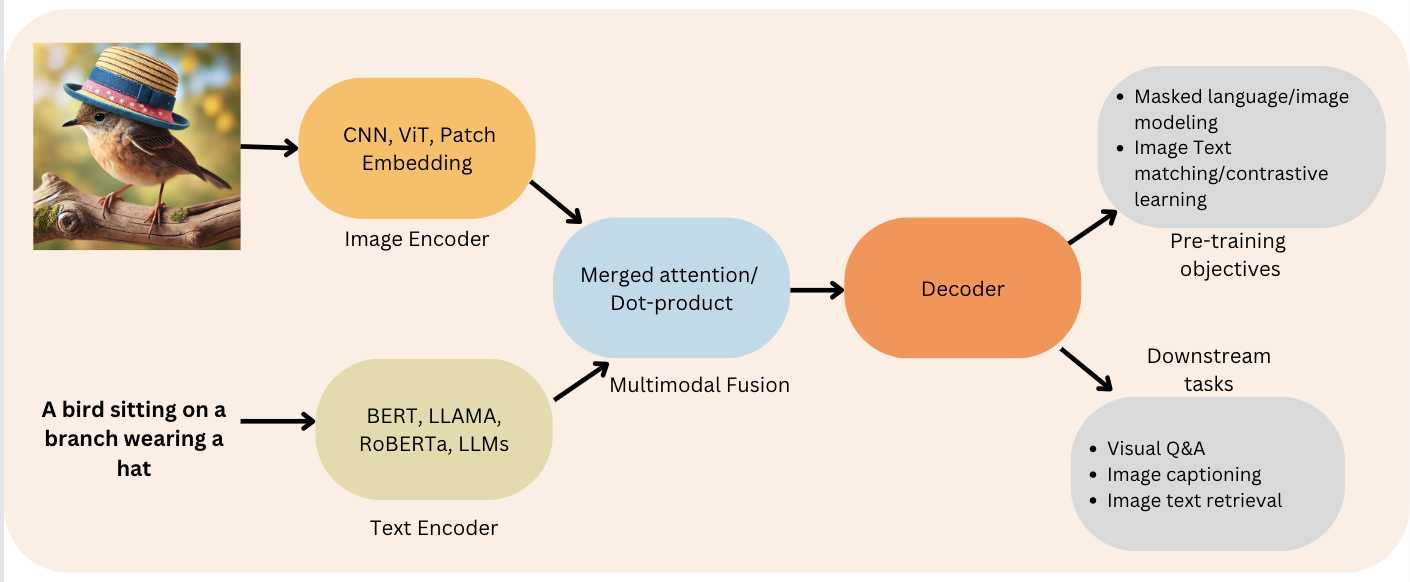
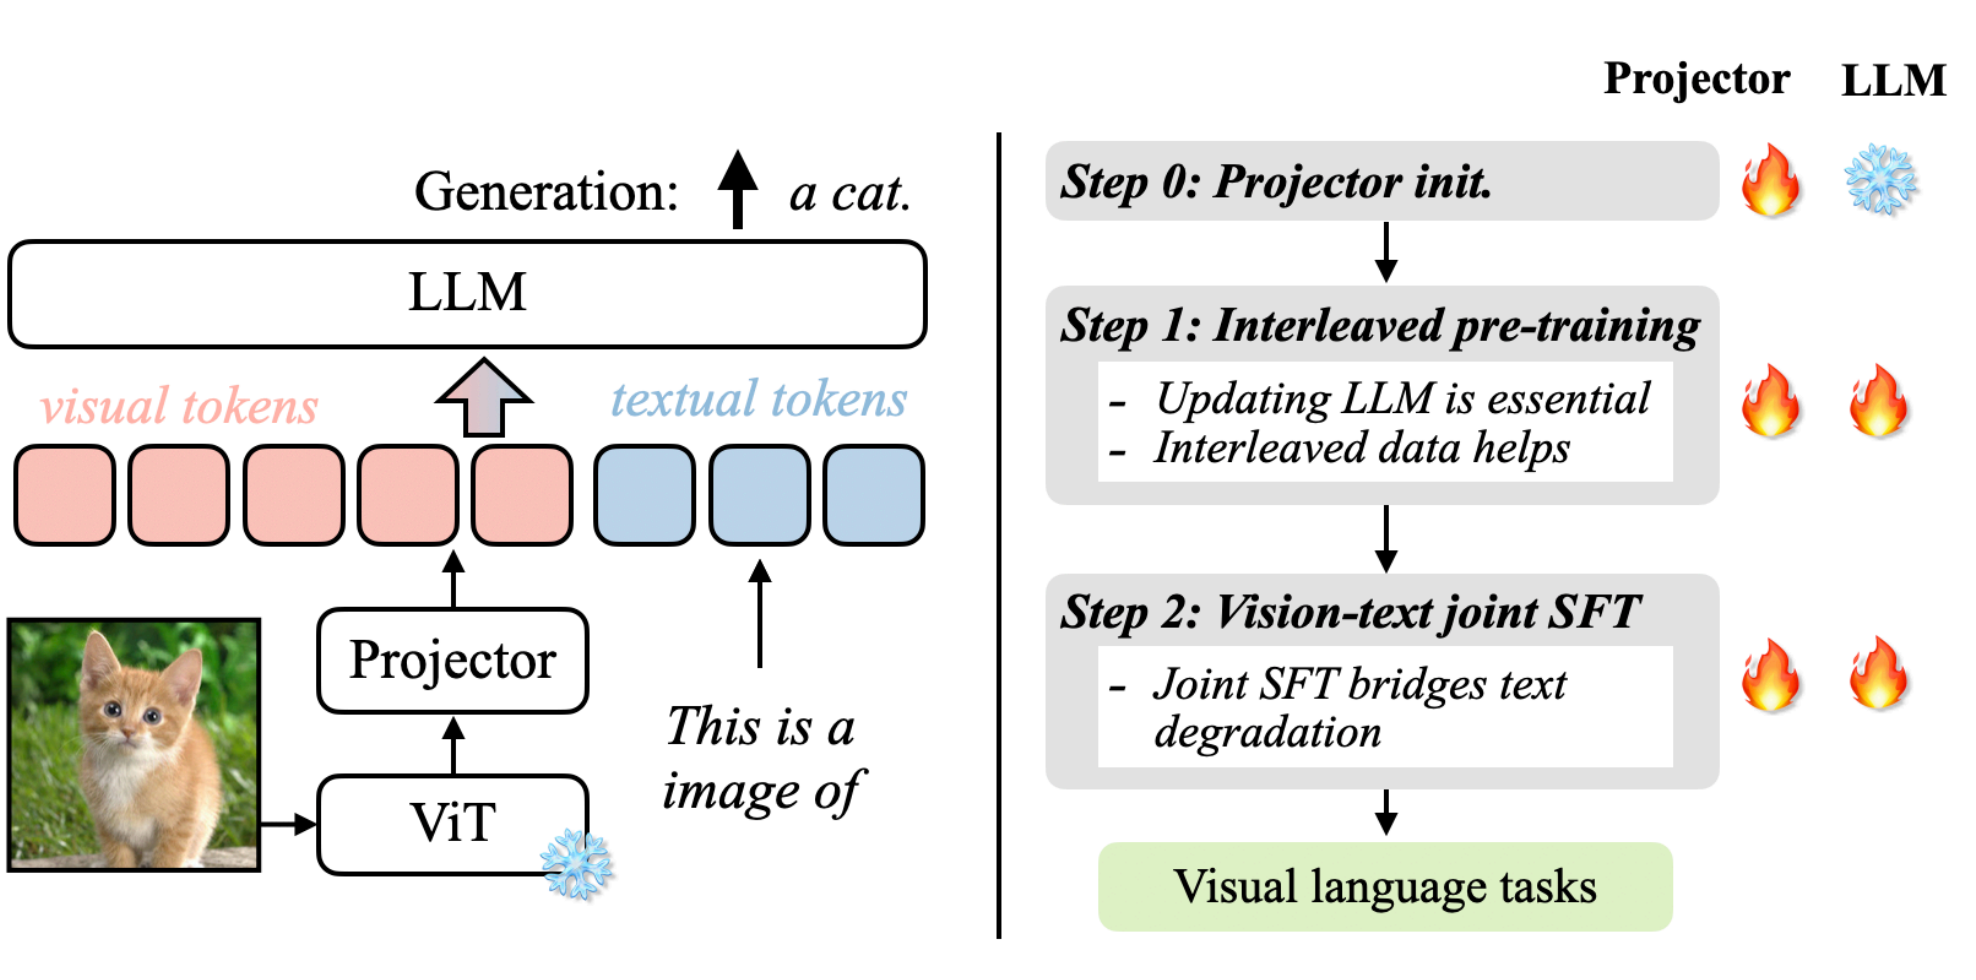
Model architecture.The left image illustrates the VLM pretraining ...
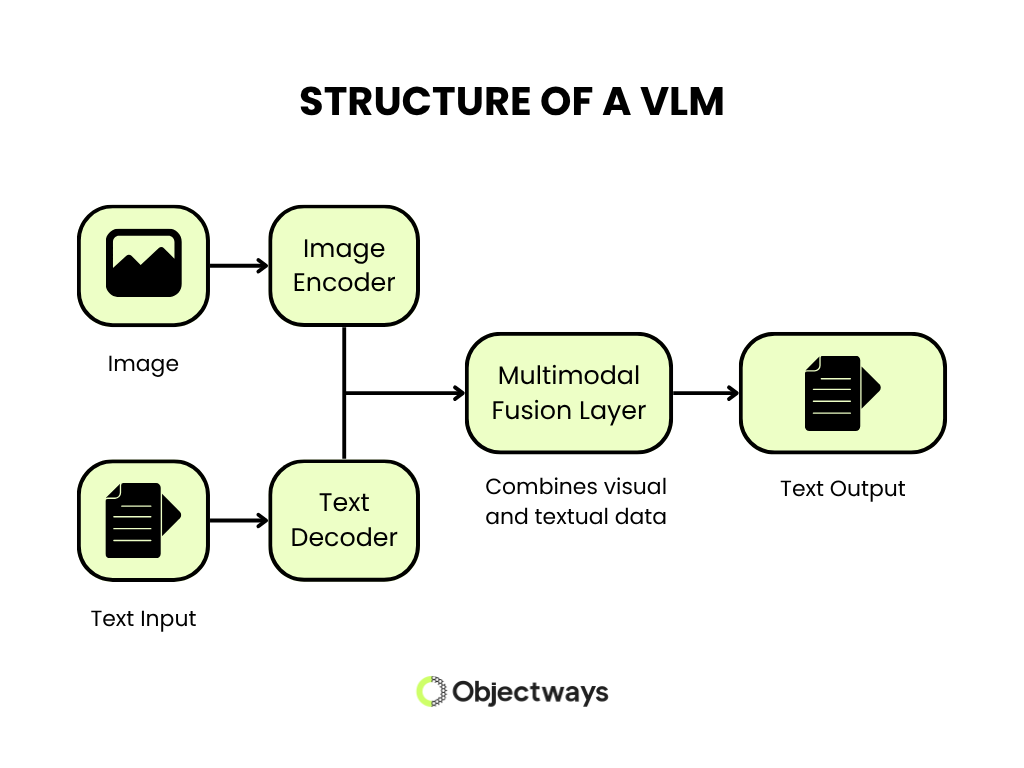
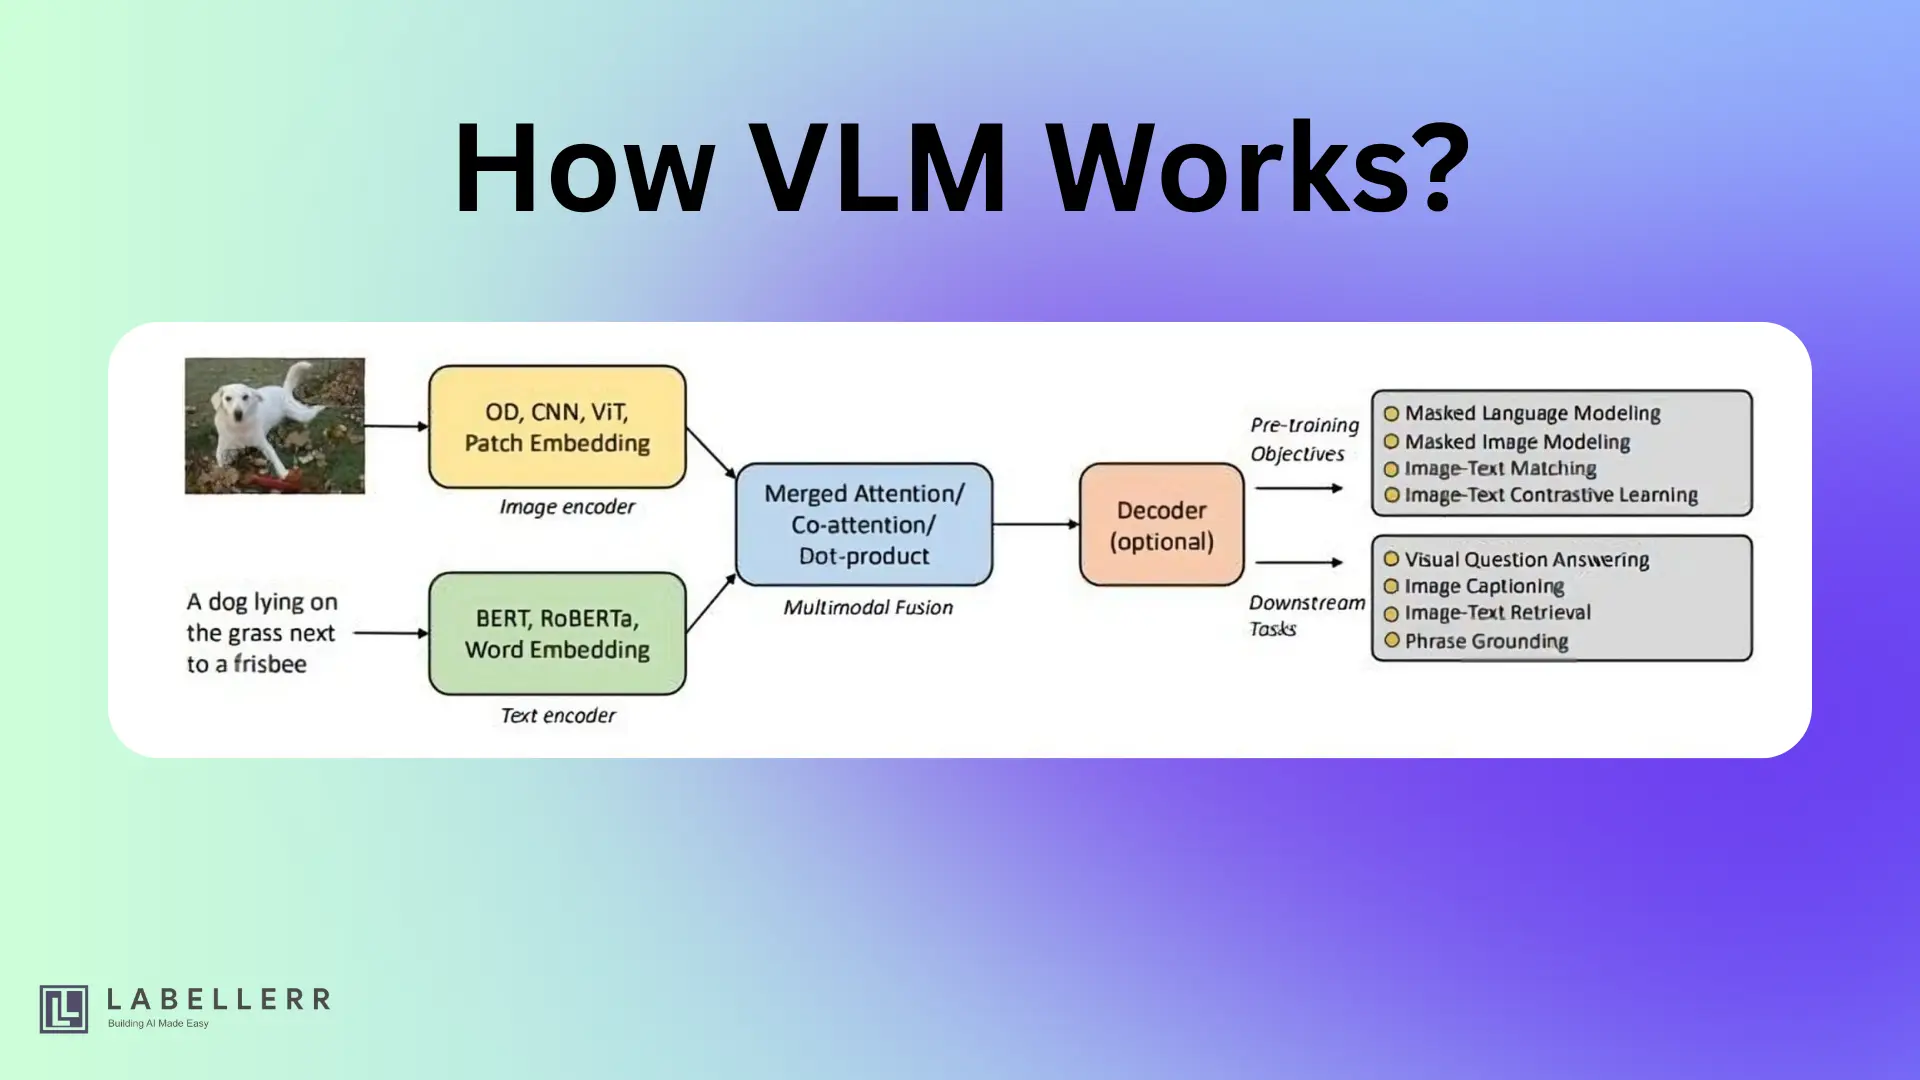
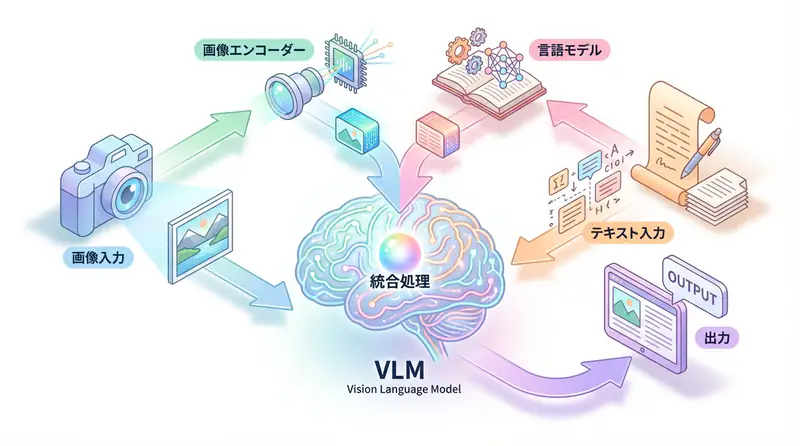
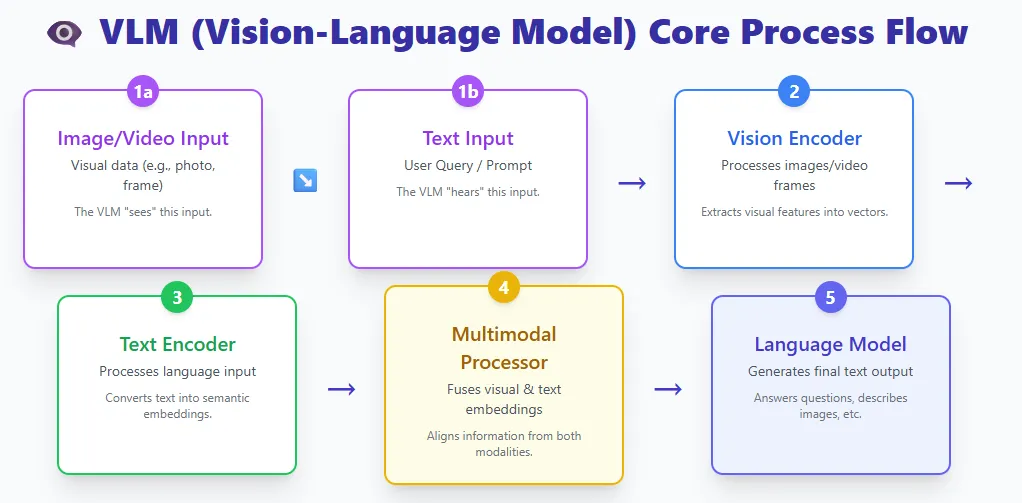
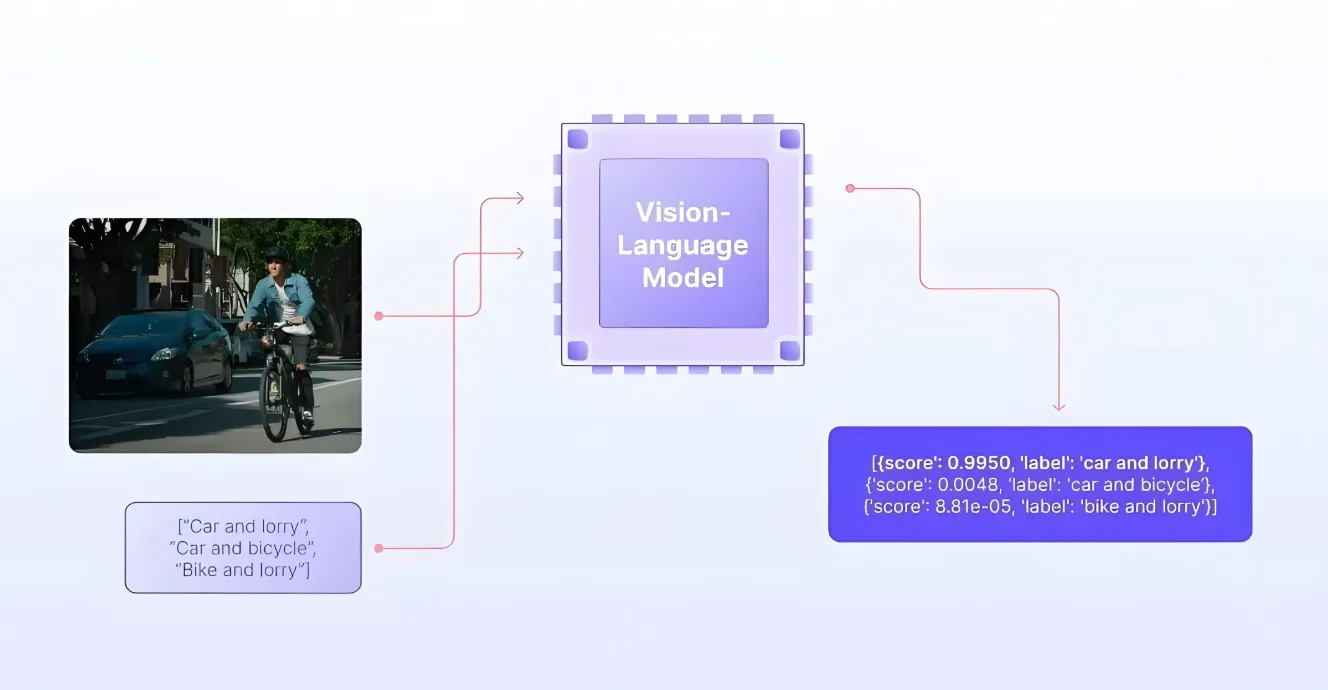
VLM AI Model Explained | Vision-Language Models Simplified for ...
Llama3-V: A SOTA Open-Source VLM Model Comparable performance to GPT4-V ...
vlm - Image model than can run on phone - GenAI Stack Exchange
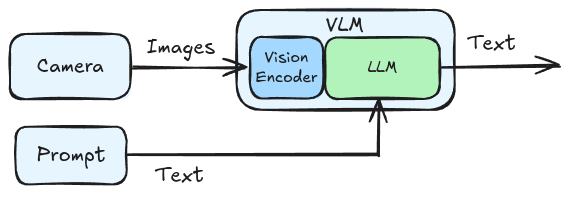
Accelerating LLM and VLM Inference for Automotive and Robotics with ...
大模型 | VLM 初识及在自动驾驶场景中的应用 - 地平线智能驾驶开发者 - 博客园
Kimi k1.5 : OpenAI-o1 level multi-modal model | by Mehul Gupta | Data ...
VLA Foundry - Vision-Language-Action Model Training Framework
📰 시각적 정보와 언어적 정보의 결합, VLM
Vision-language model - Wikiwand
Haber - VLM (Vision Language Model) Nedir? | Ubden® Community ...
VLM (Vision Language Model) Explained
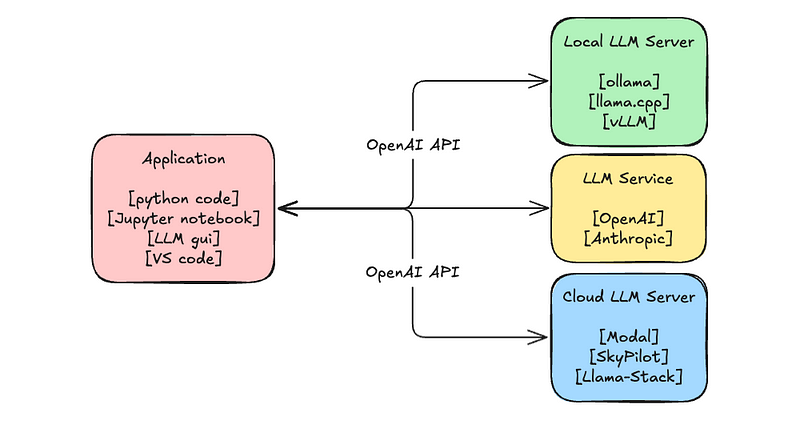
Trying out vLLM in Colab. vLLM Python library provides easy LLM… | by ...
API-Based VLM Models | docling-project/docling | DeepWiki
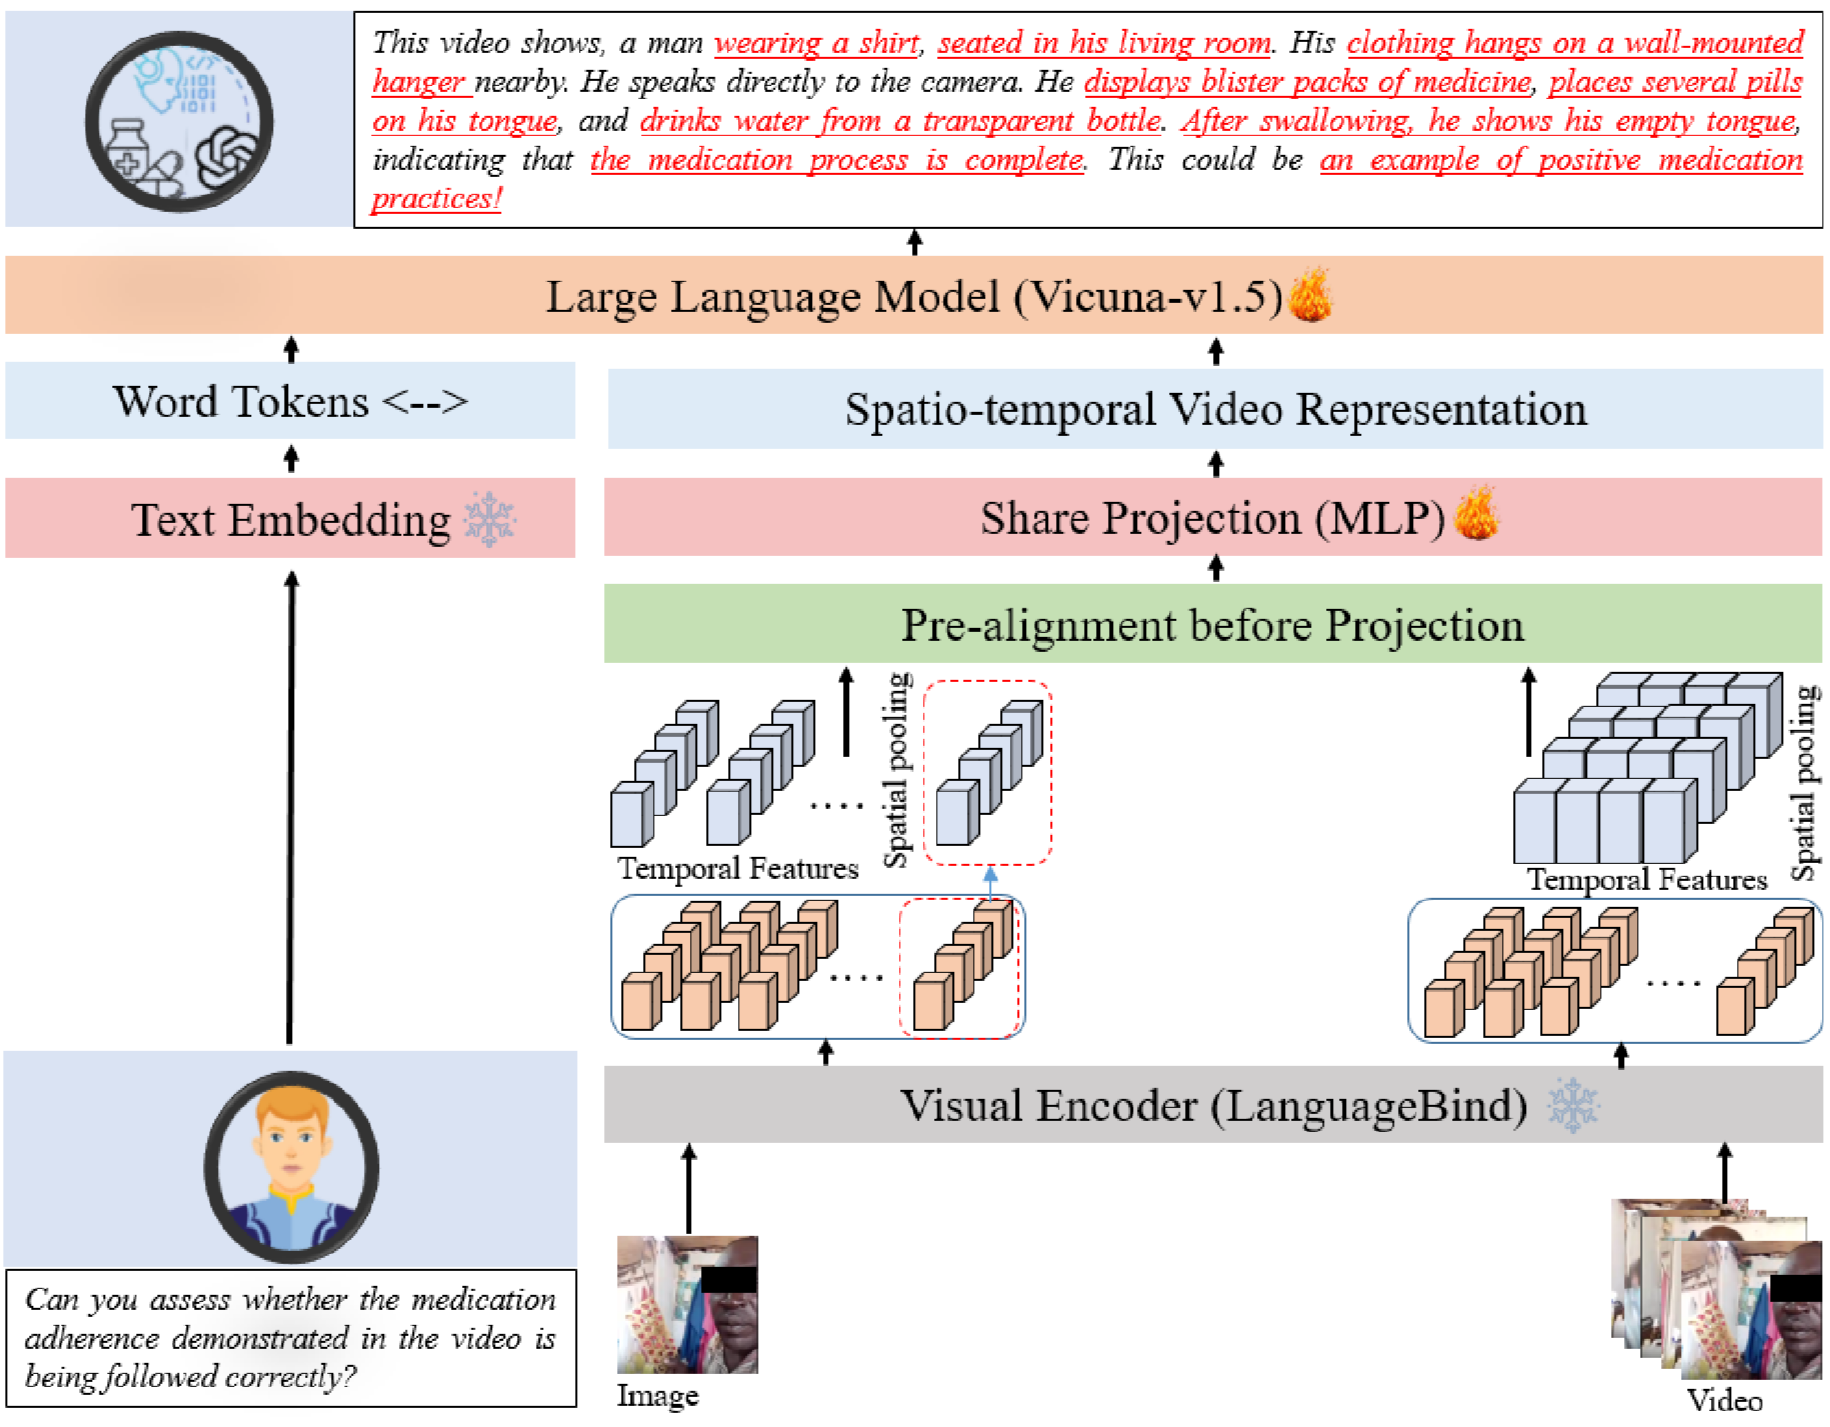
[논문 리뷰] AdCare-VLM: Leveraging Large Vision Language Model (LVLM) to ...
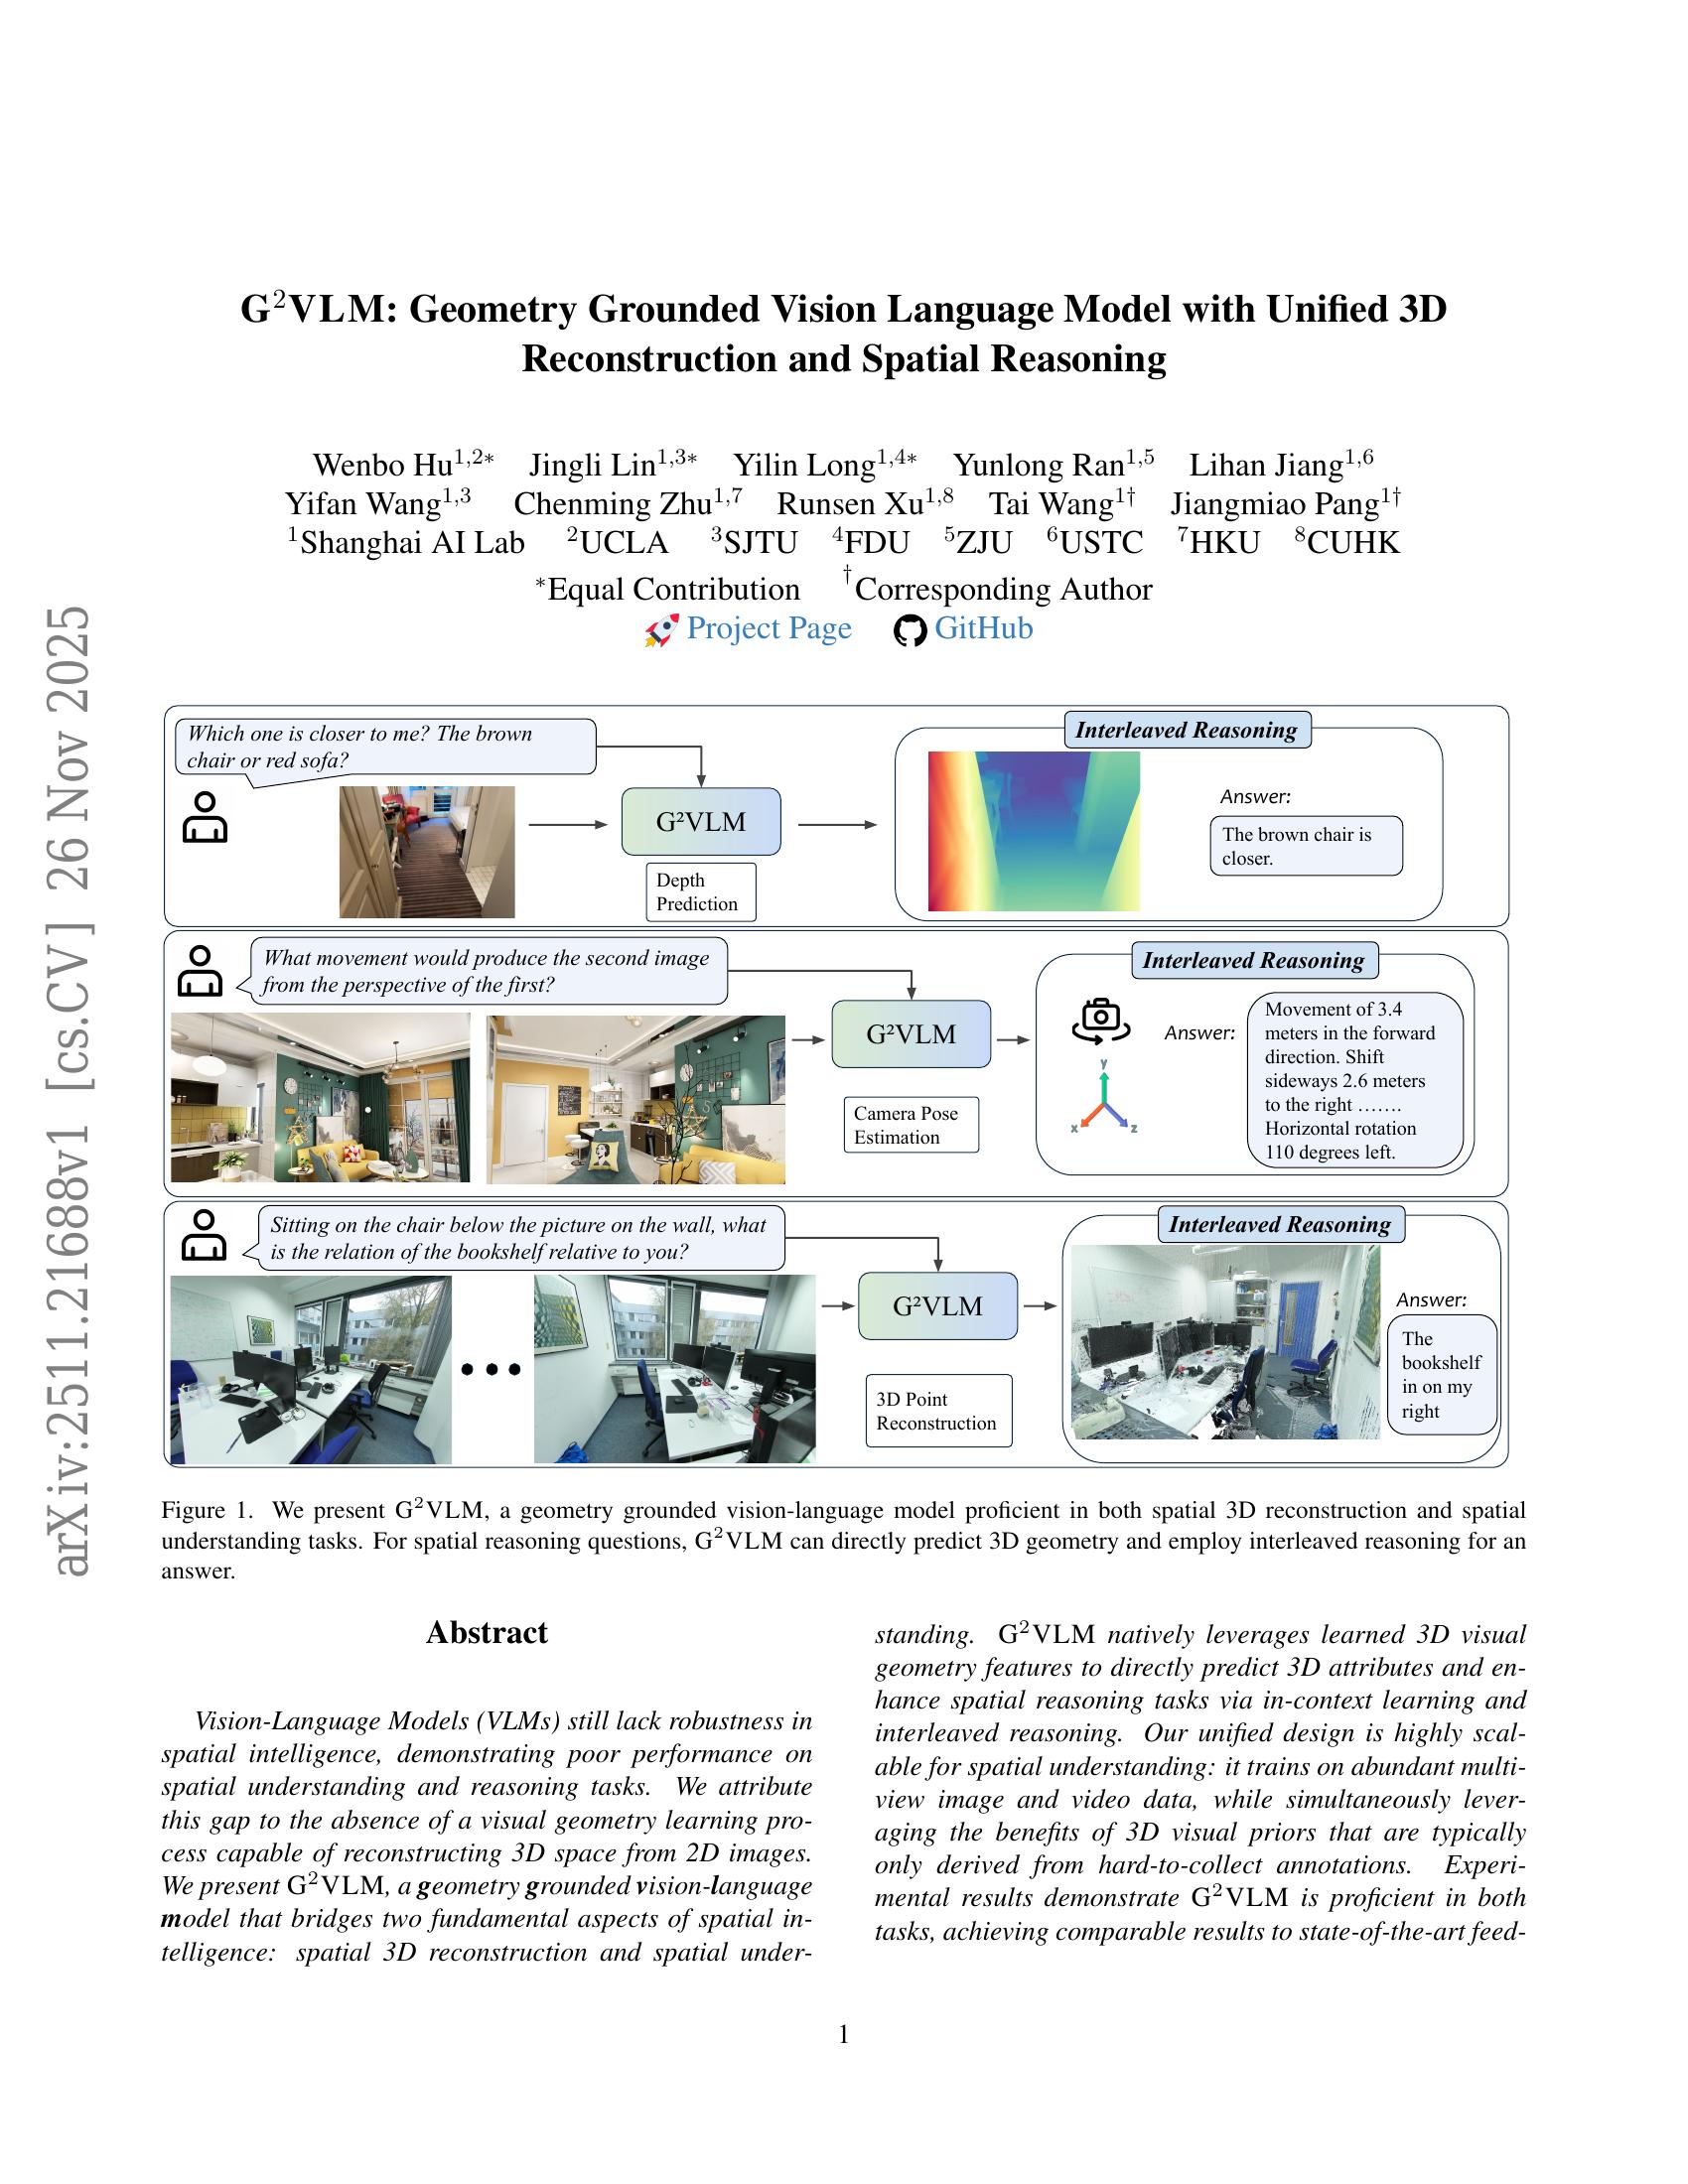
G$^2$VLM: Geometry Grounded Vision Language Model with Unified 3D ...
Beyond Graph Model: Reliable VLM Fine-Tuning via Random Graph Adapter ...
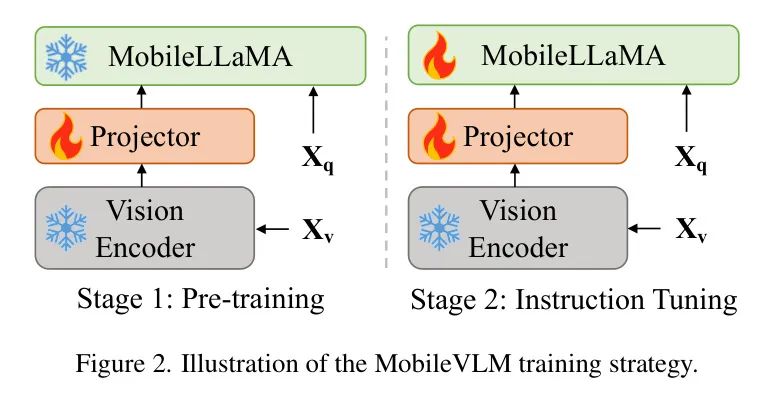
Meet MobileVLM: A Competent Multimodal Vision Language Model (MMVLM ...
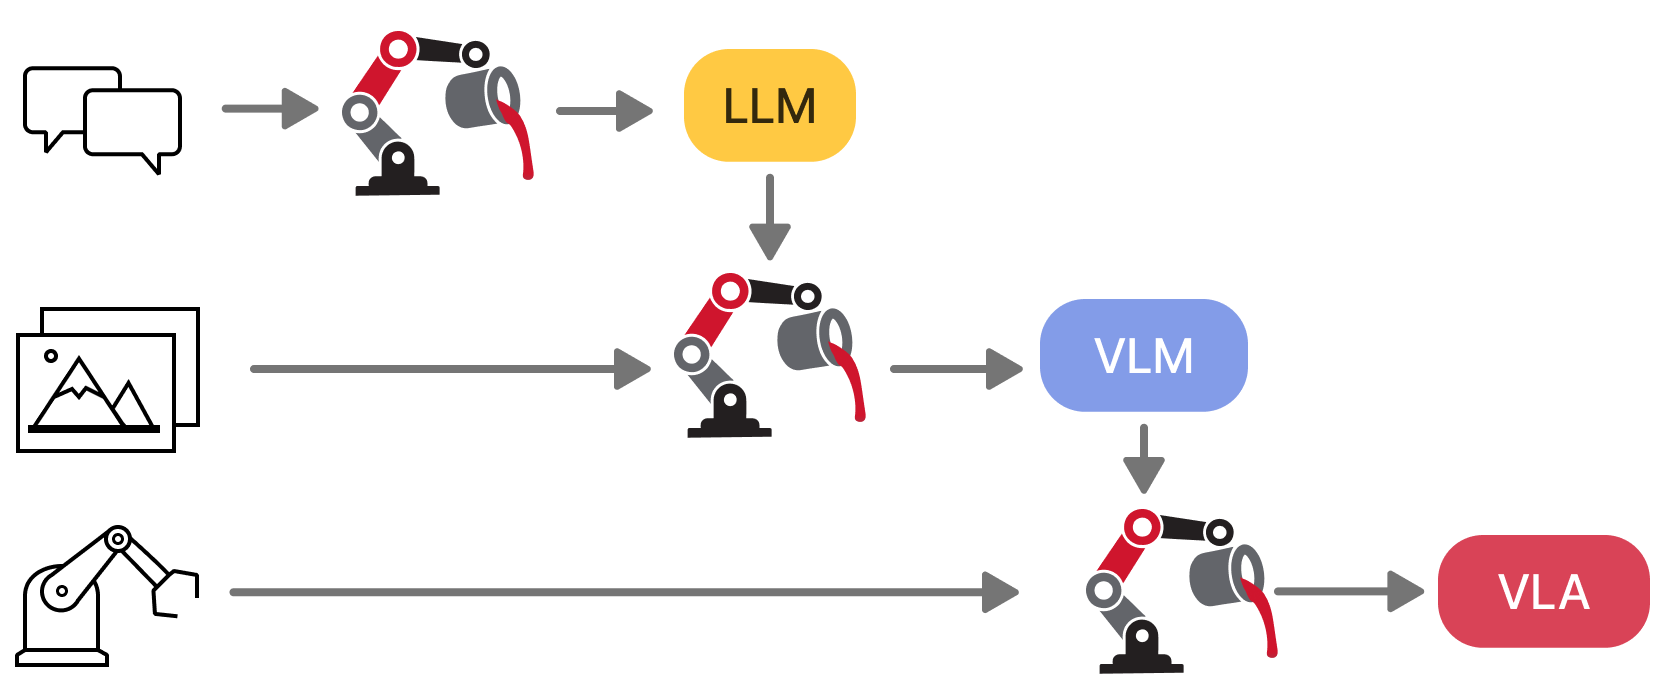
World Models Explained: Why VLM and VLA Aren't Enough for Physical AI ...
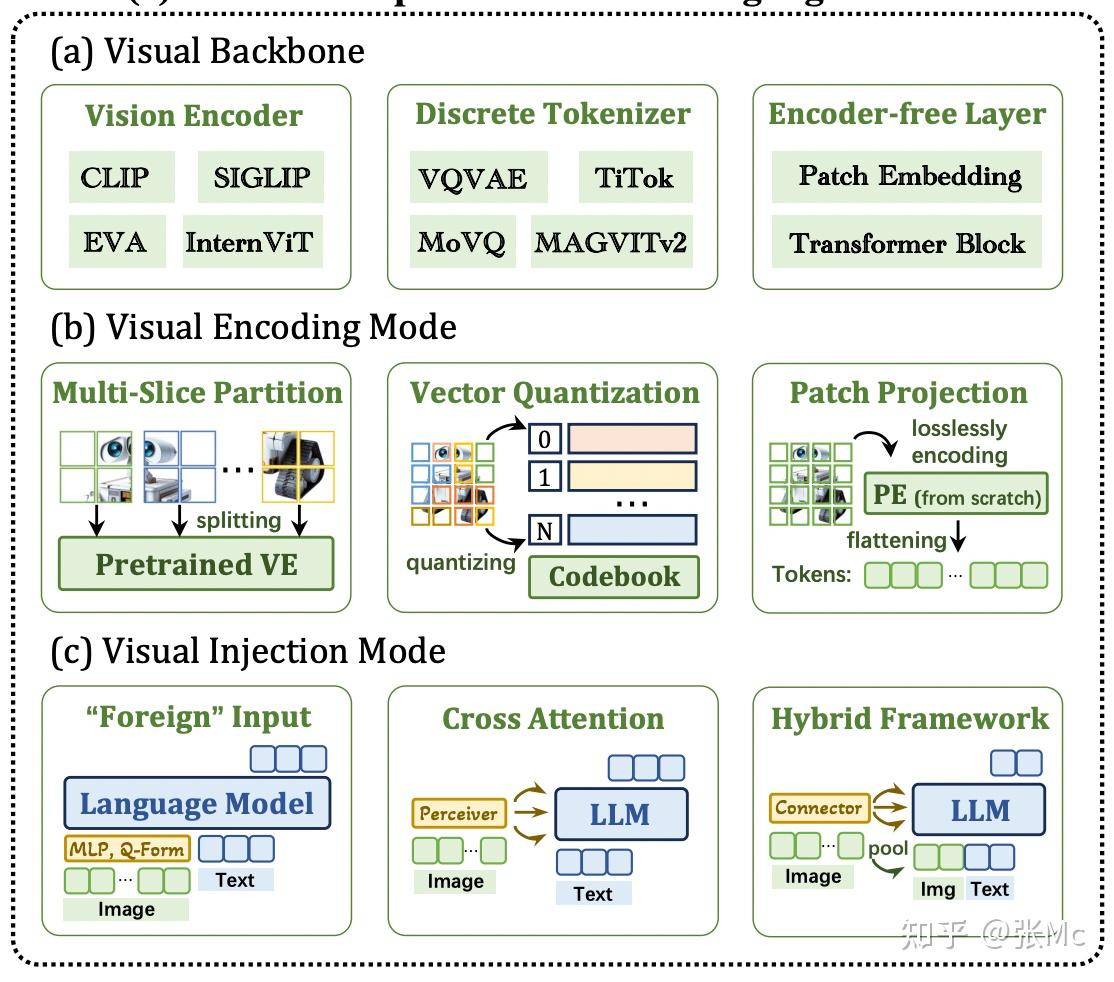
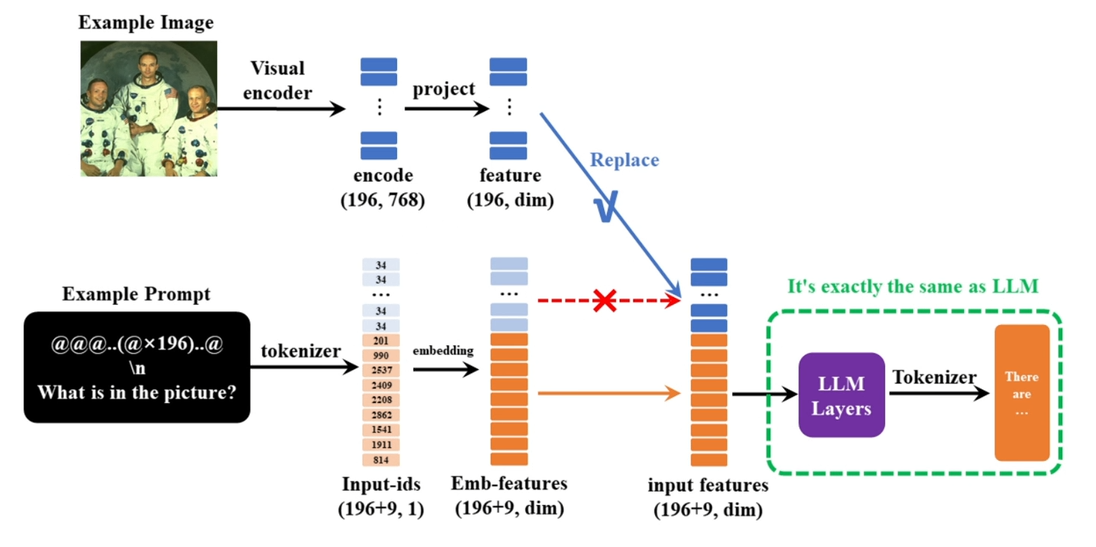
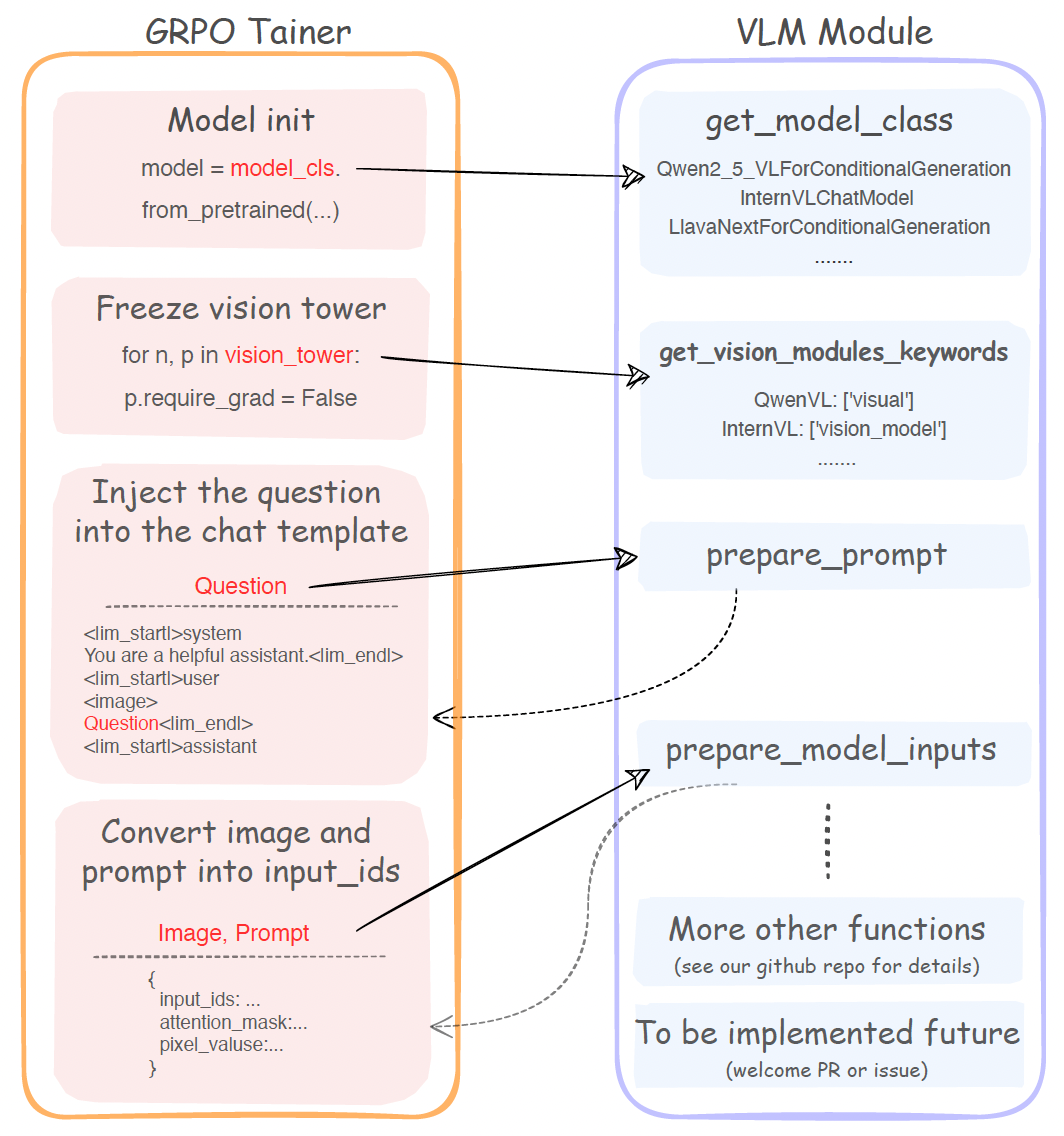
备忘:关于 VLM 一些实现点 - 知乎
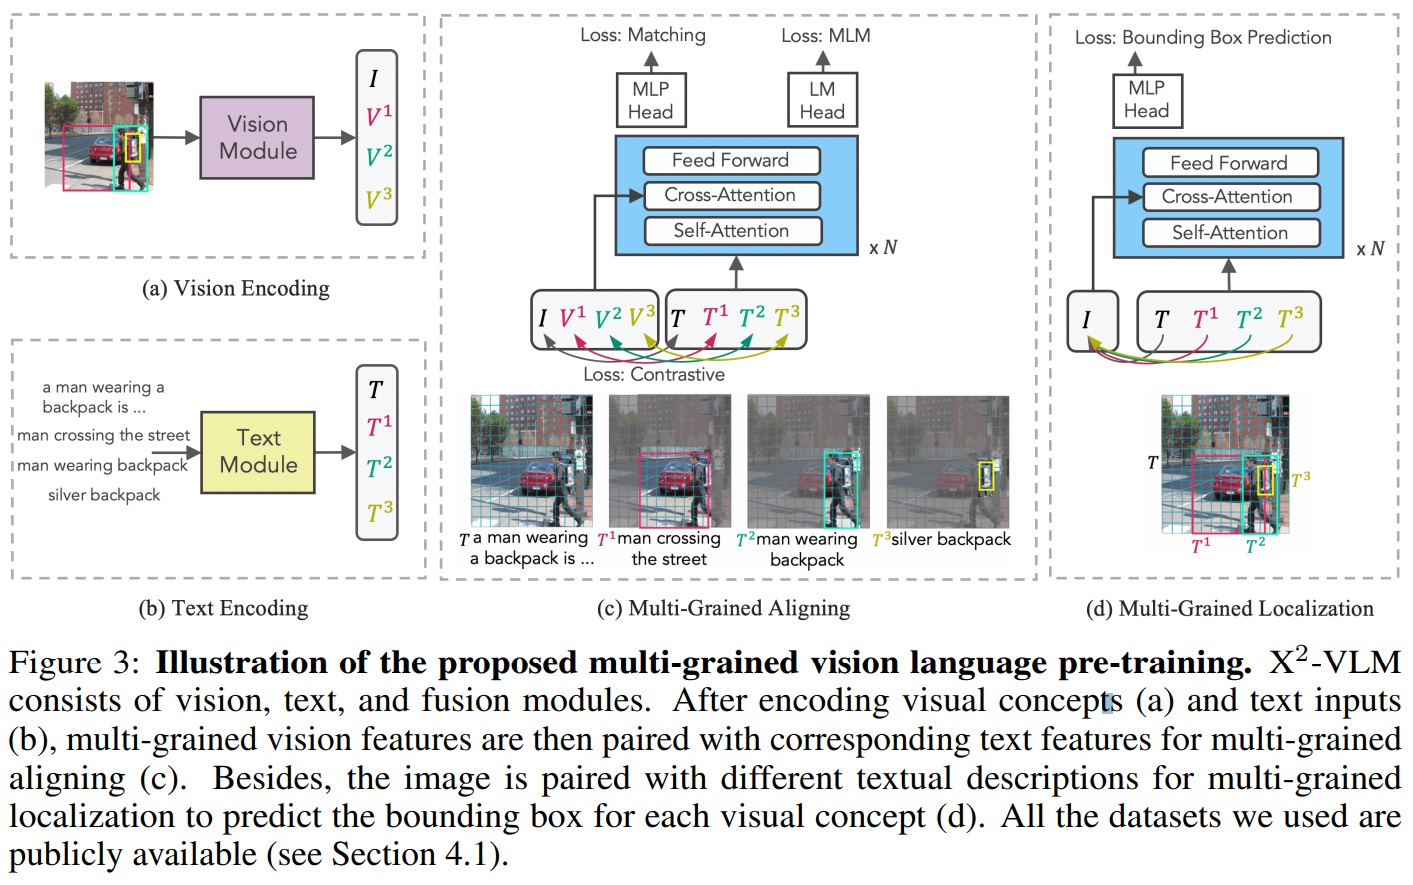
X2-VLM: All-In-One Pre-trained Model For Vision-Language Tasks | 오상진의 ...
VLM: How Vision-Language Models Work (2026 Guide) | Label Your Data
实验室工作 - kingdom-of-warriors
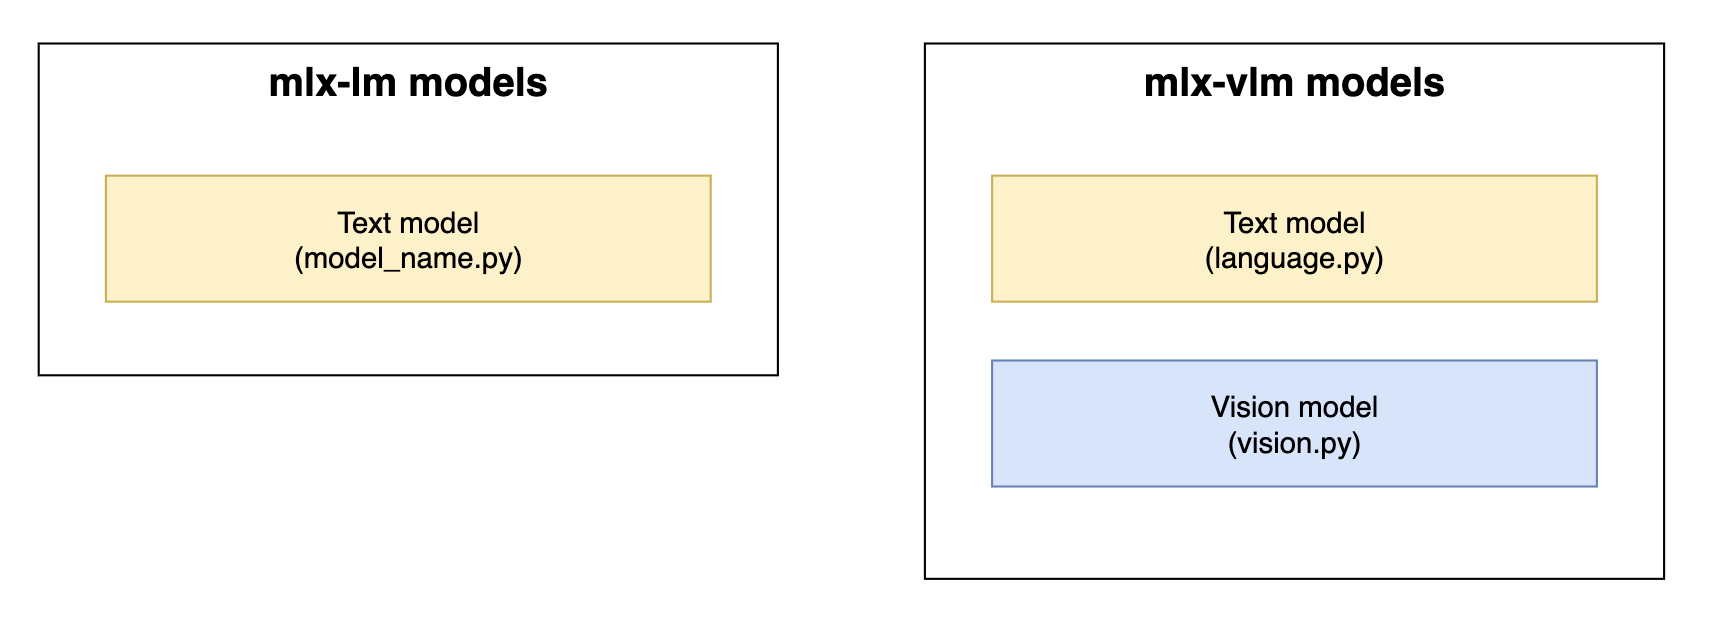
Introducing the unified multi-modal MLX engine architecture in LM ...
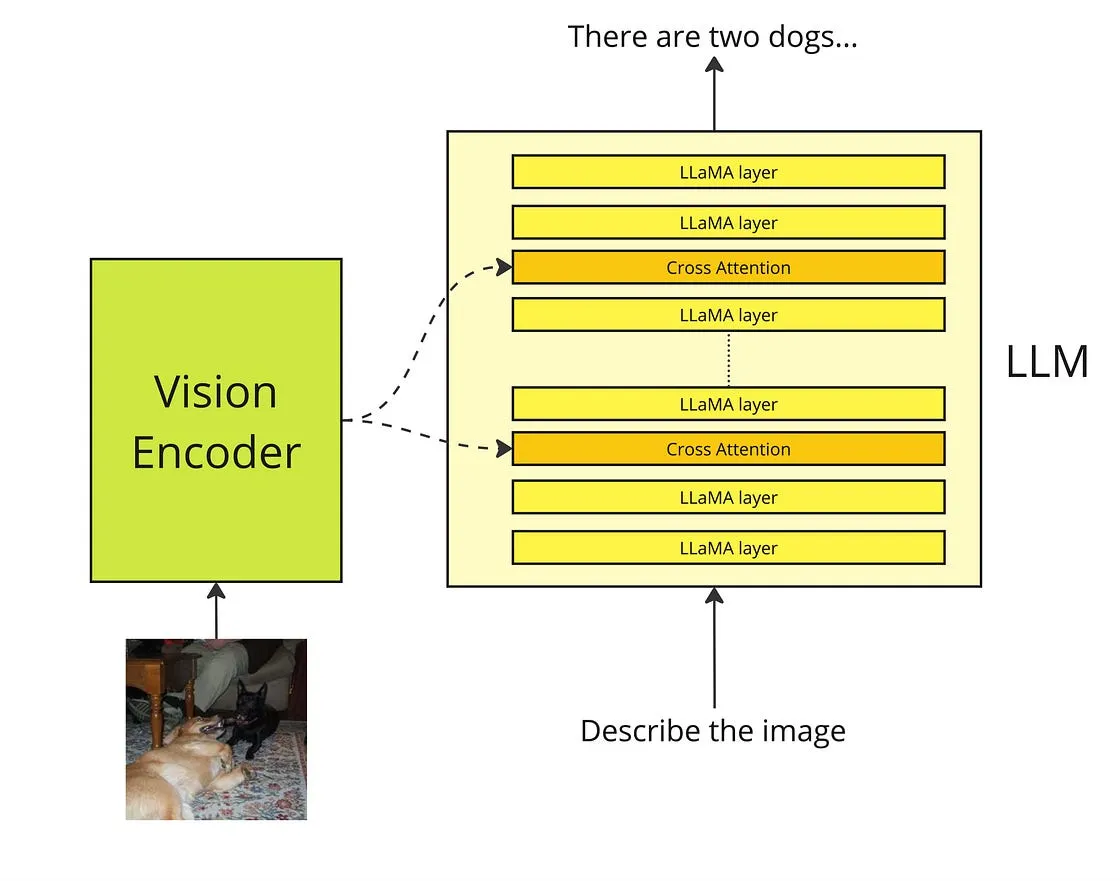
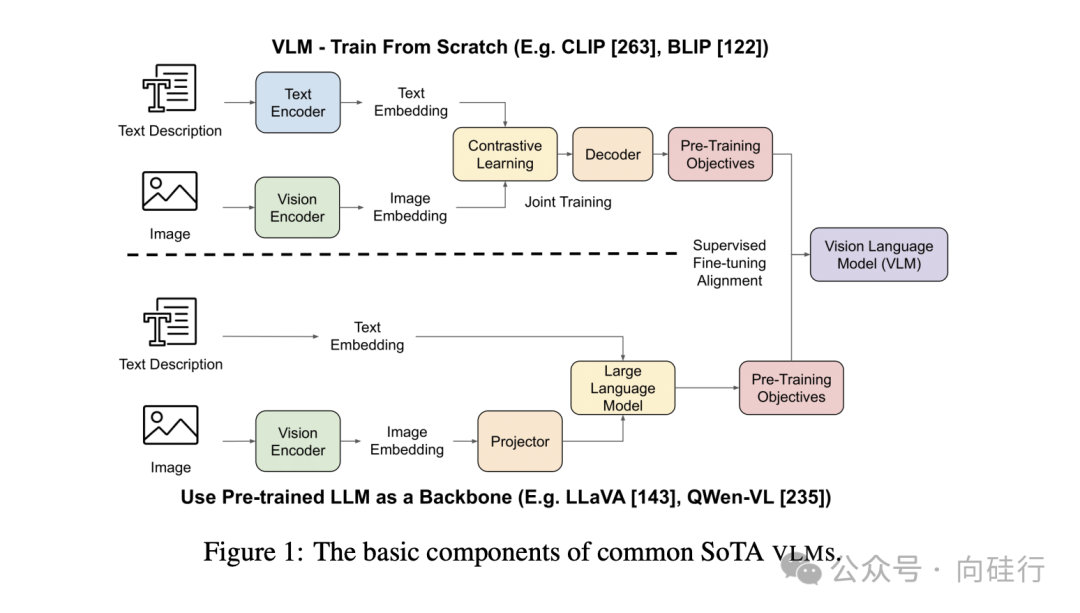
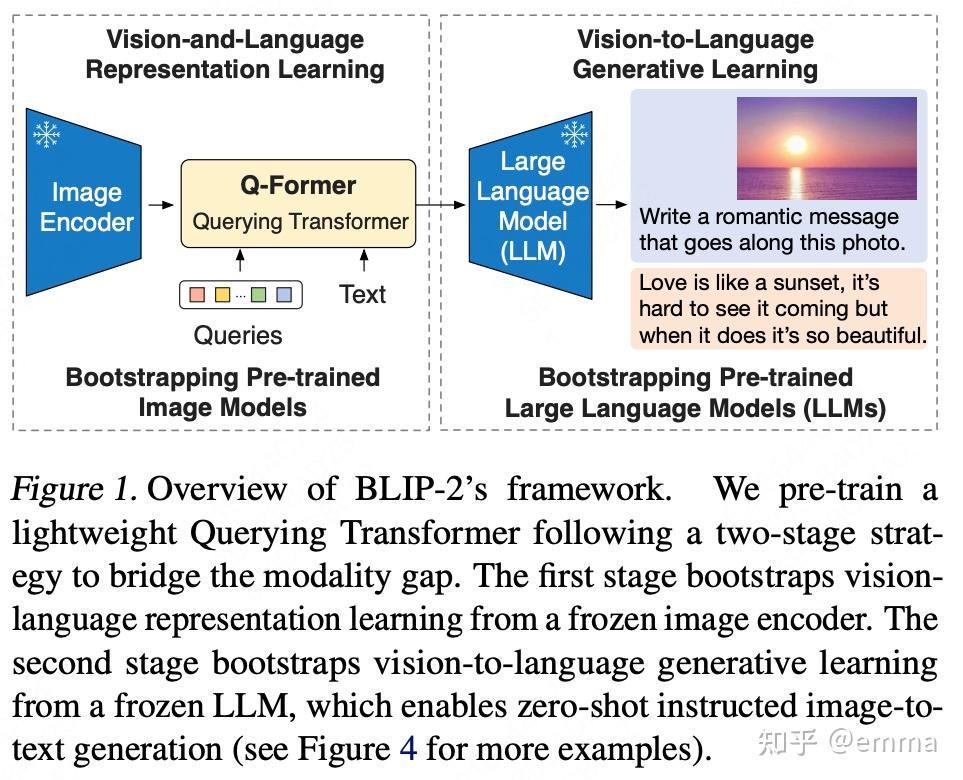
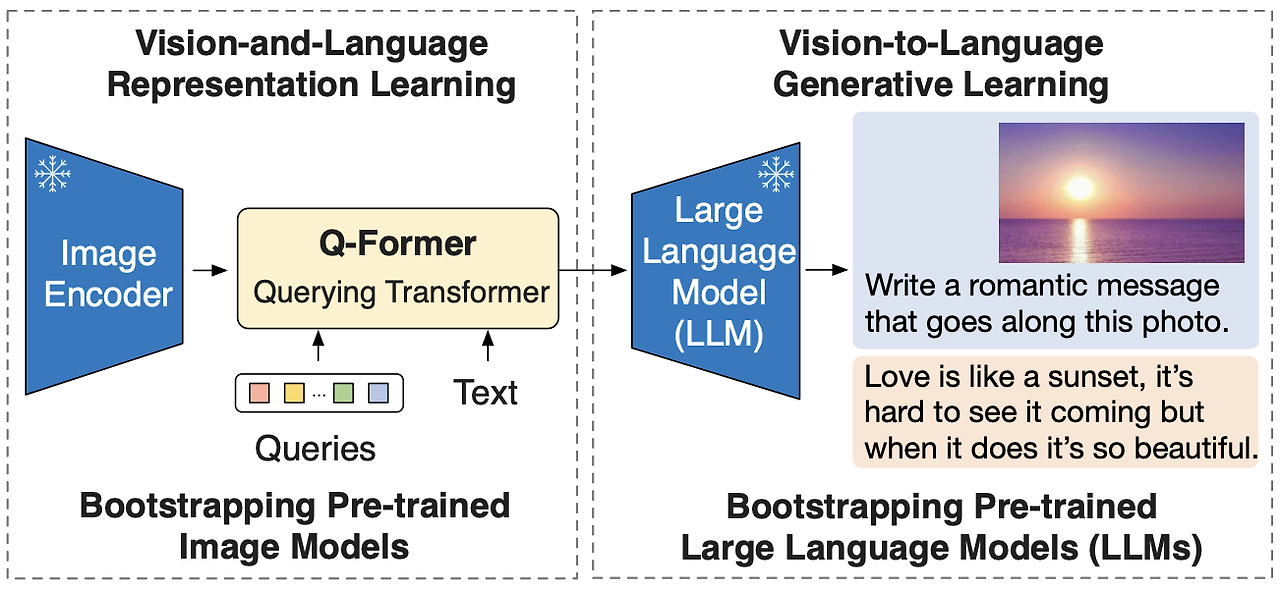
主流VLM原理深入刨析(CLIP,BLIP,BLIP2,Flamingo,LLaVA,MiniCPT,InstructBLIP,mPLUG ...
Large Vision Models Take Visual Reasoning a Step Further
GitHub - CladernyJorn/VLM4VLA: Implementation of VLM4VLA · GitHub
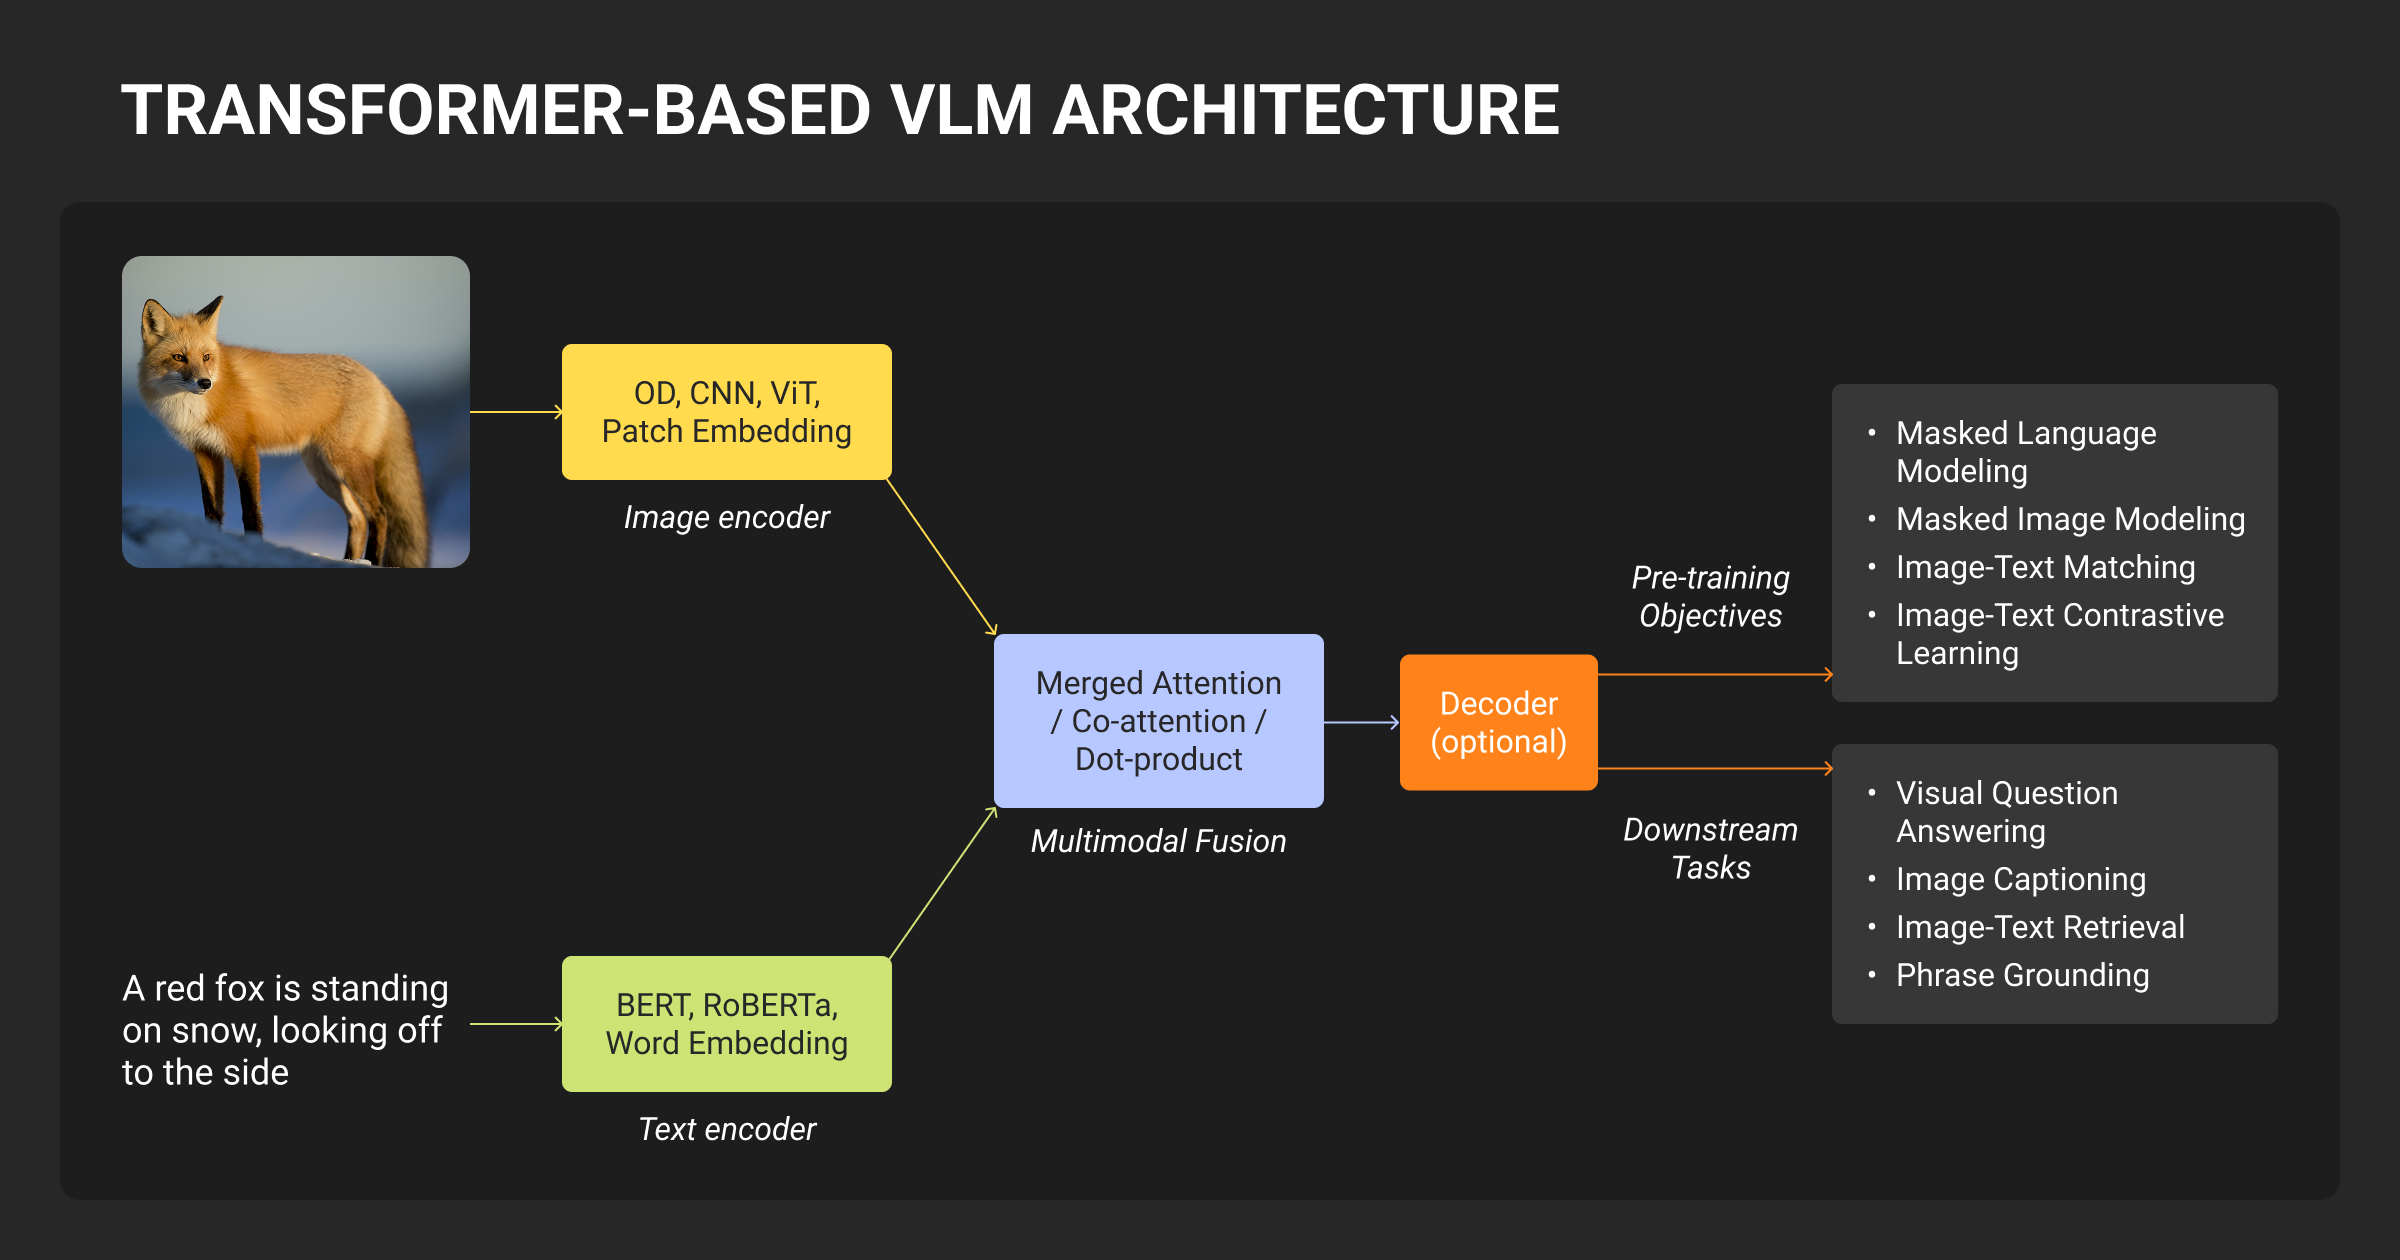
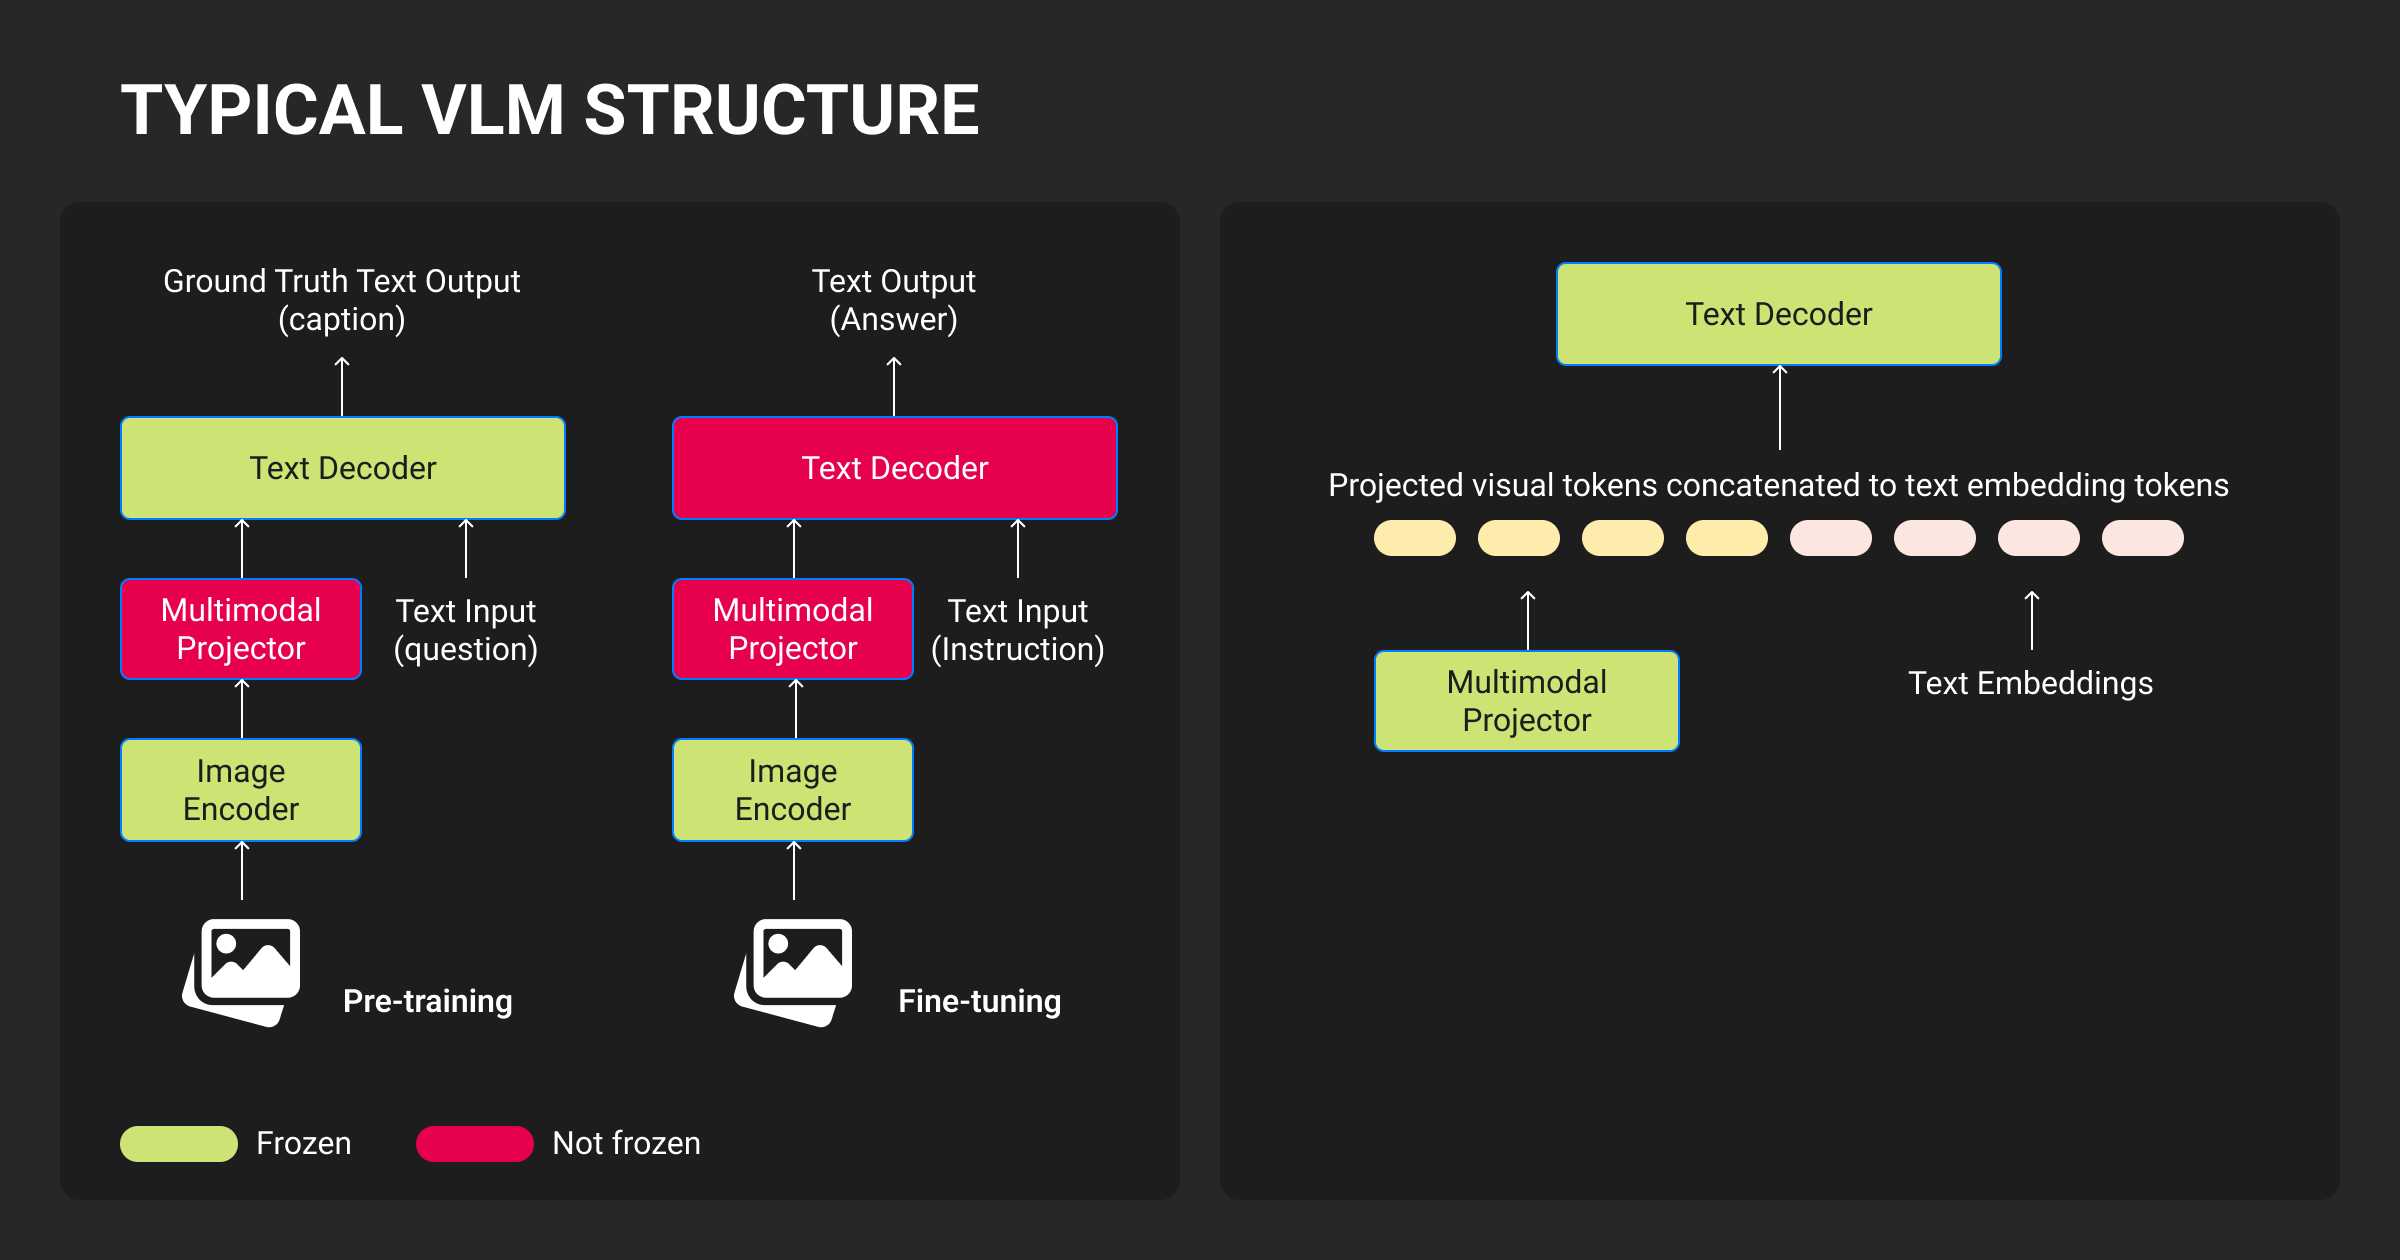
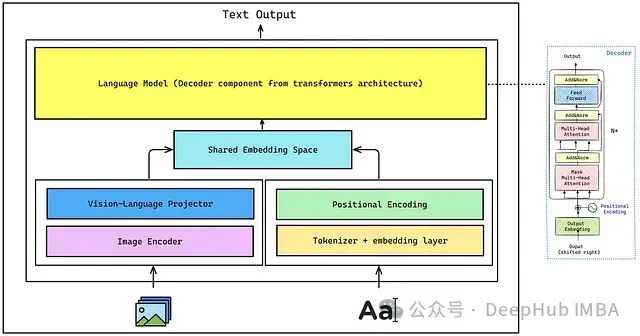
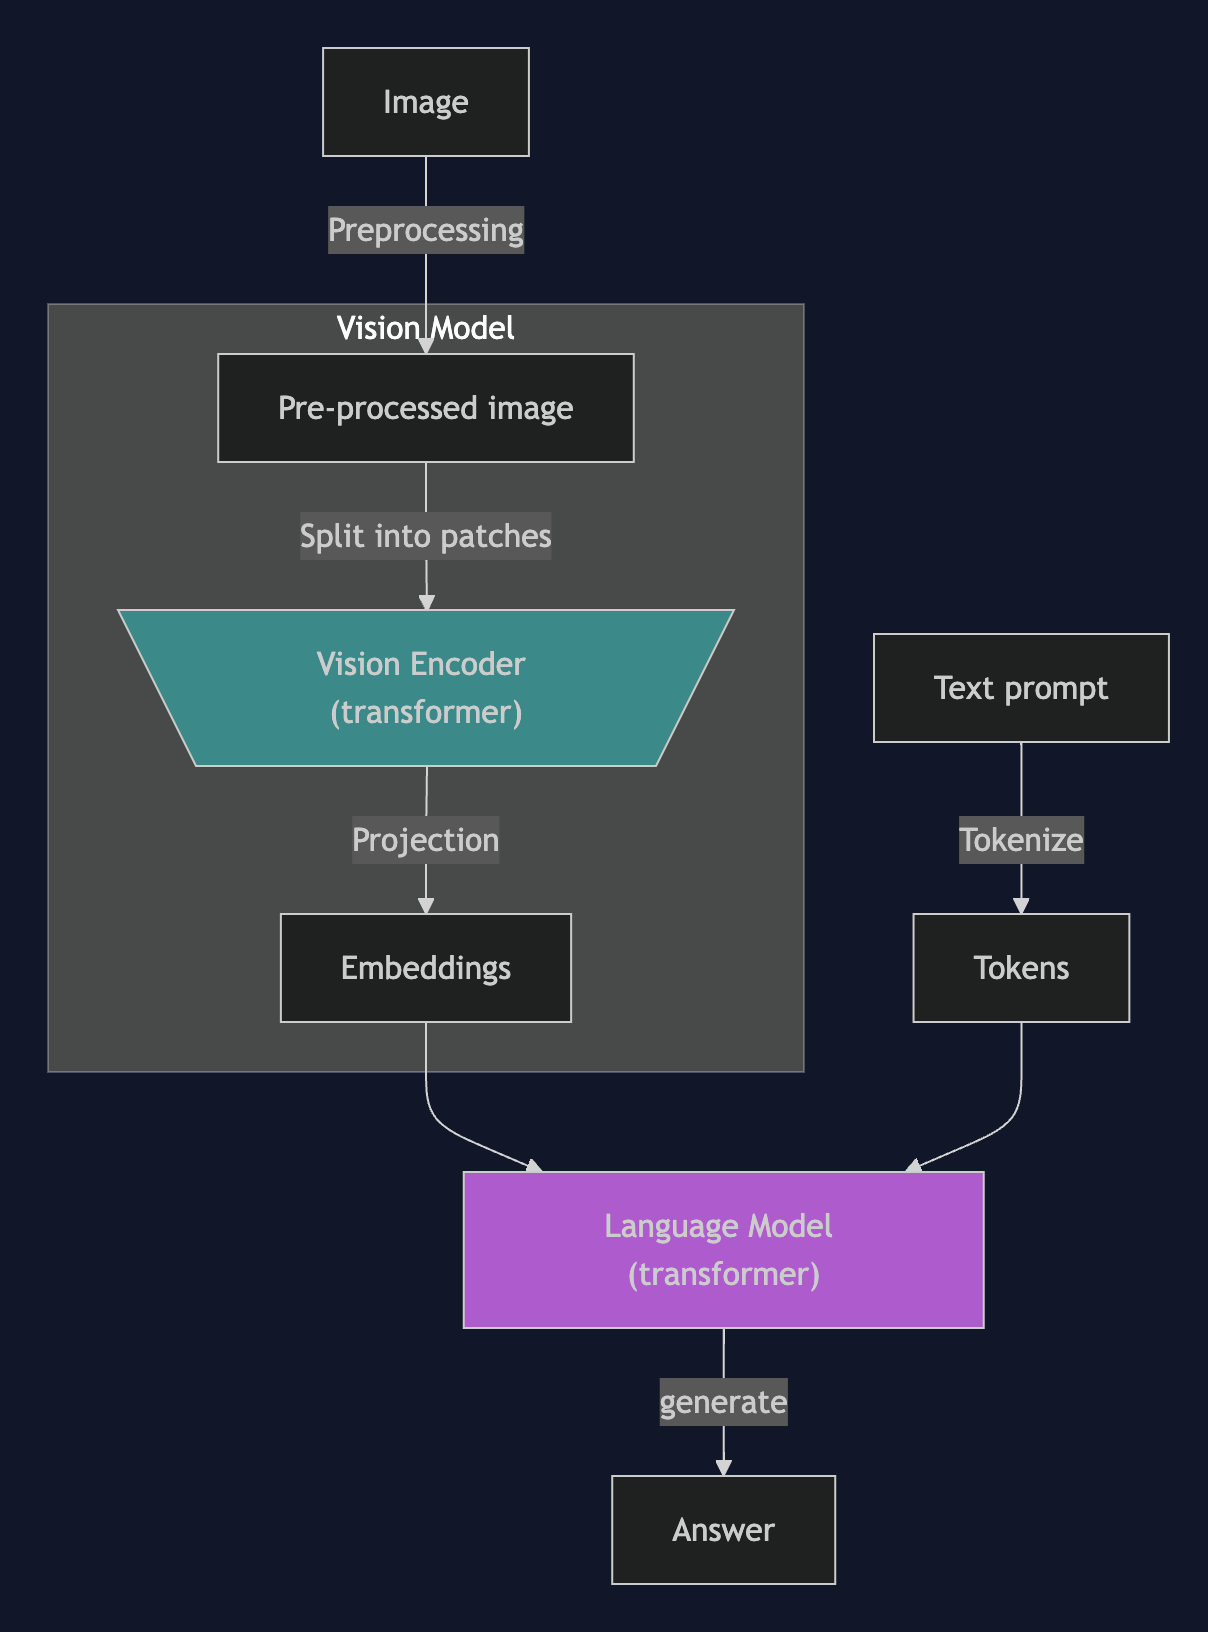
Vision Language Model(VLM)的经典模型结构是怎样的? - 知乎
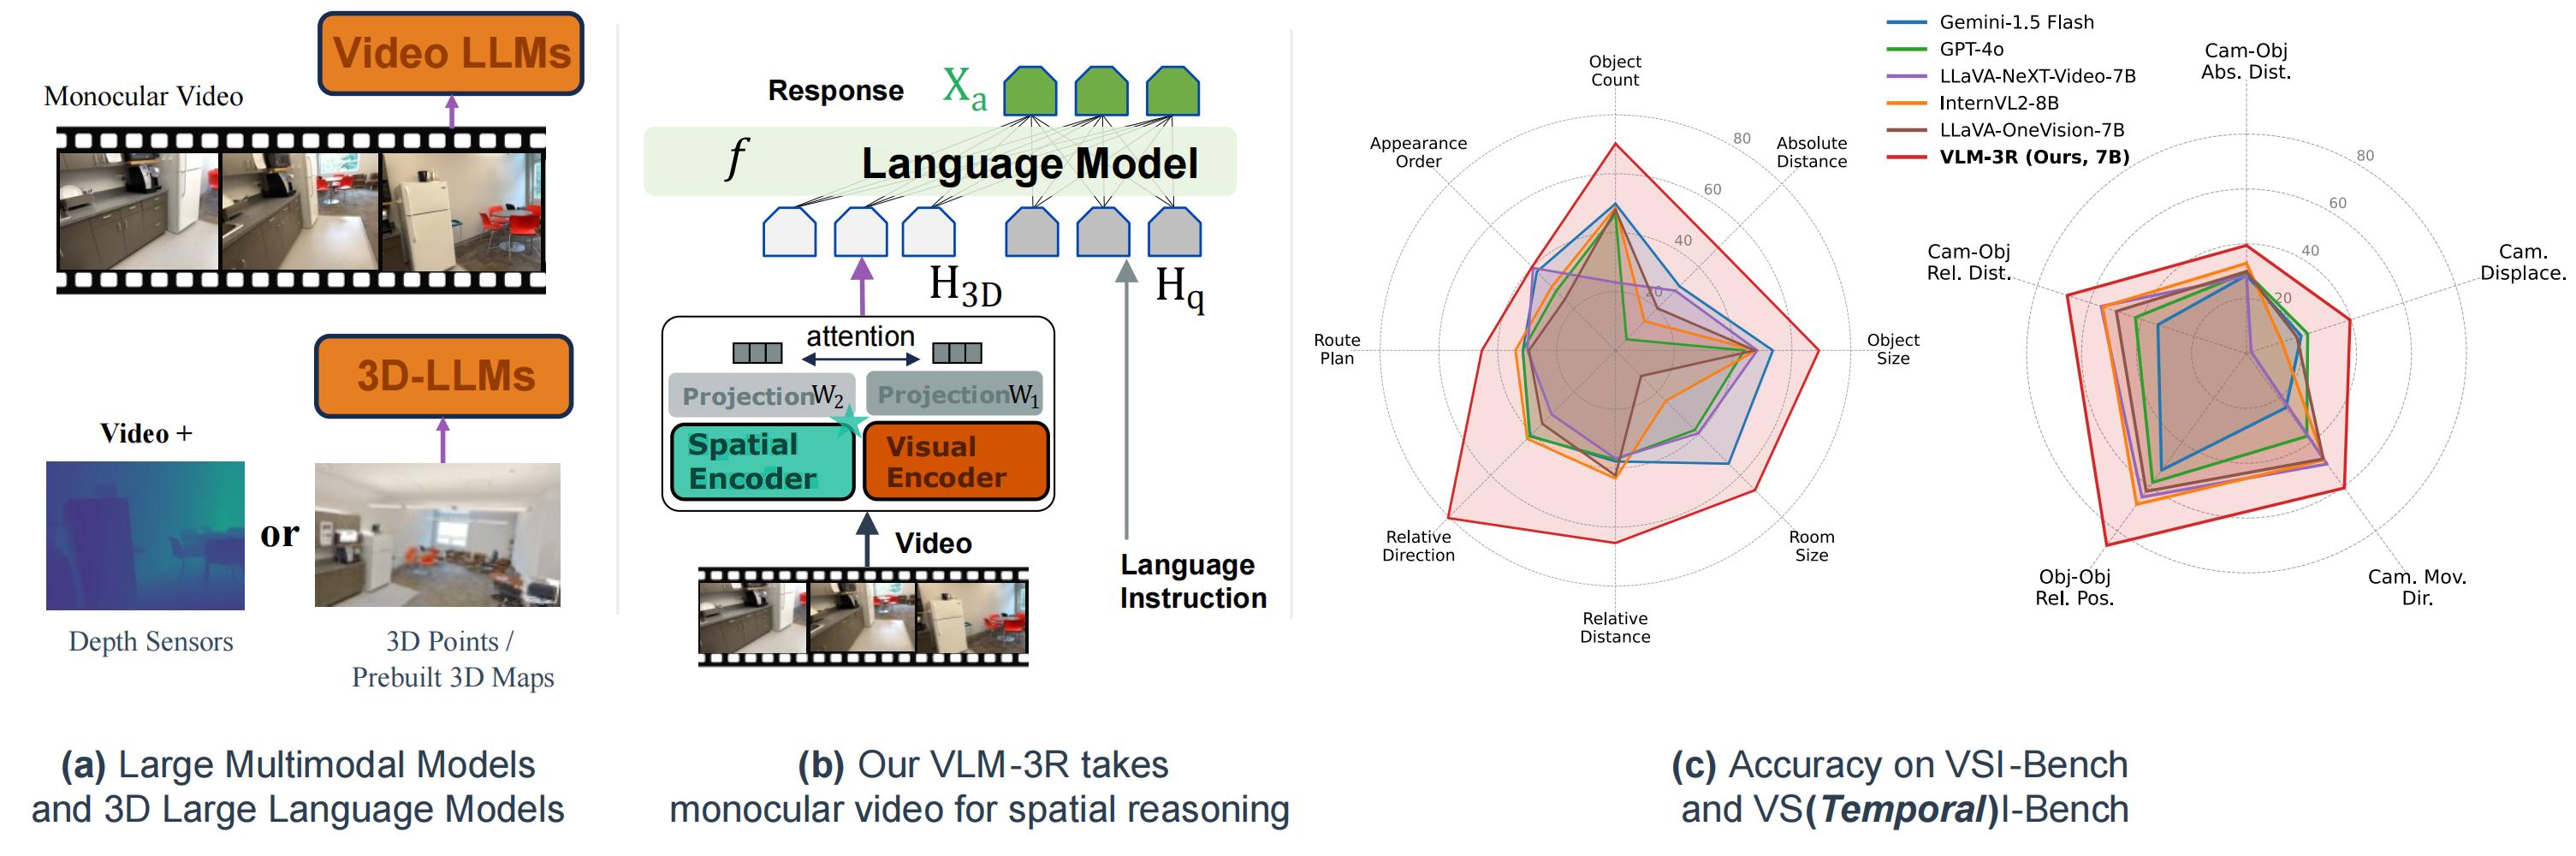
VLM-3R: Vision-Language Models Augmented with Instruction-Aligned 3D ...
[论文评述] Q-VLM: Post-training Quantization for Large Vision-Language Models
Vision Language Models Guide: The Complete Handbook for ML Teams
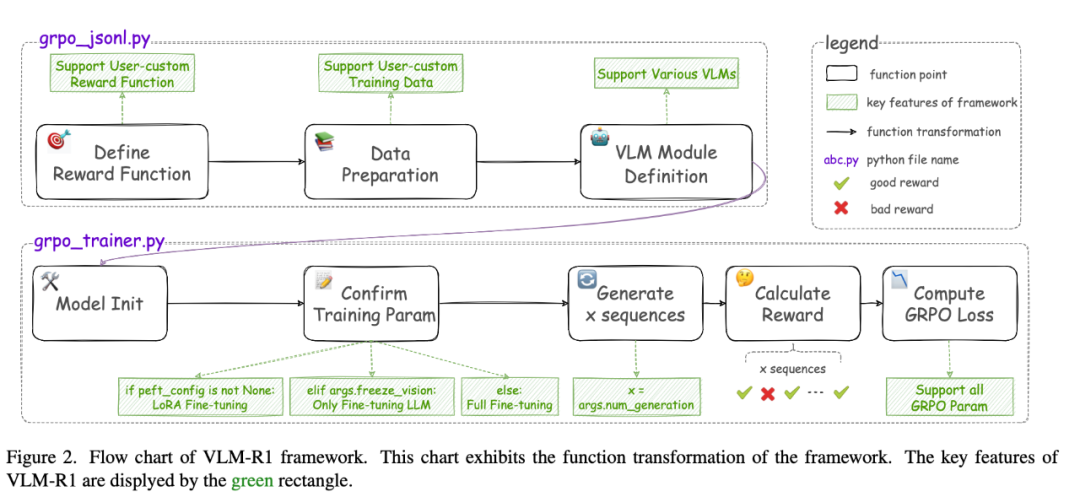
等到了!VLM-R1完整细节首度公开:RL的一小步,视觉语言模型推理的一大步 - 知乎
使用Pytorch构建视觉语言模型(VLM)-51CTO.COM
Pre‑Trained Models in Deep Learning: 10 Top Architectures
一文深度看懂视觉语言模型(VLM)-电子工程专辑
Introduction to VLMs
视觉语言模型VLM原理推理优化与评测全解析-开发者社区-阿里云
梳理几个概念,弄懂具身智能发展主线:LLM、VLM、VLA,以及端到端模型,非常详细建议收藏!-CSDN博客
Best Vision-Language Models: Guide to Using VLMs
An Introduction to VLMs: The Future of Computer Vision Models | Towards ...
vlm-toolbox | Vision-Language Models Toolbox: Your all-in-one solution ...
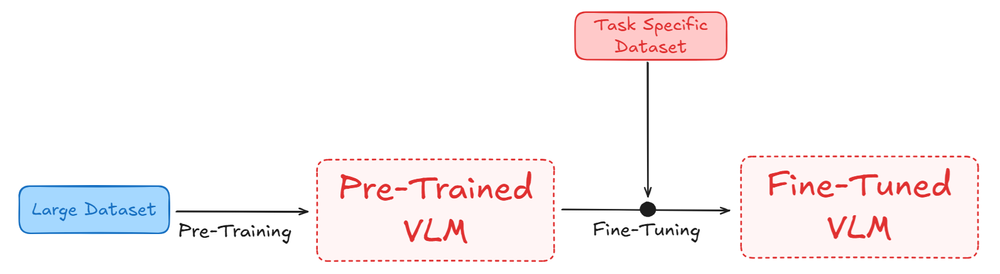
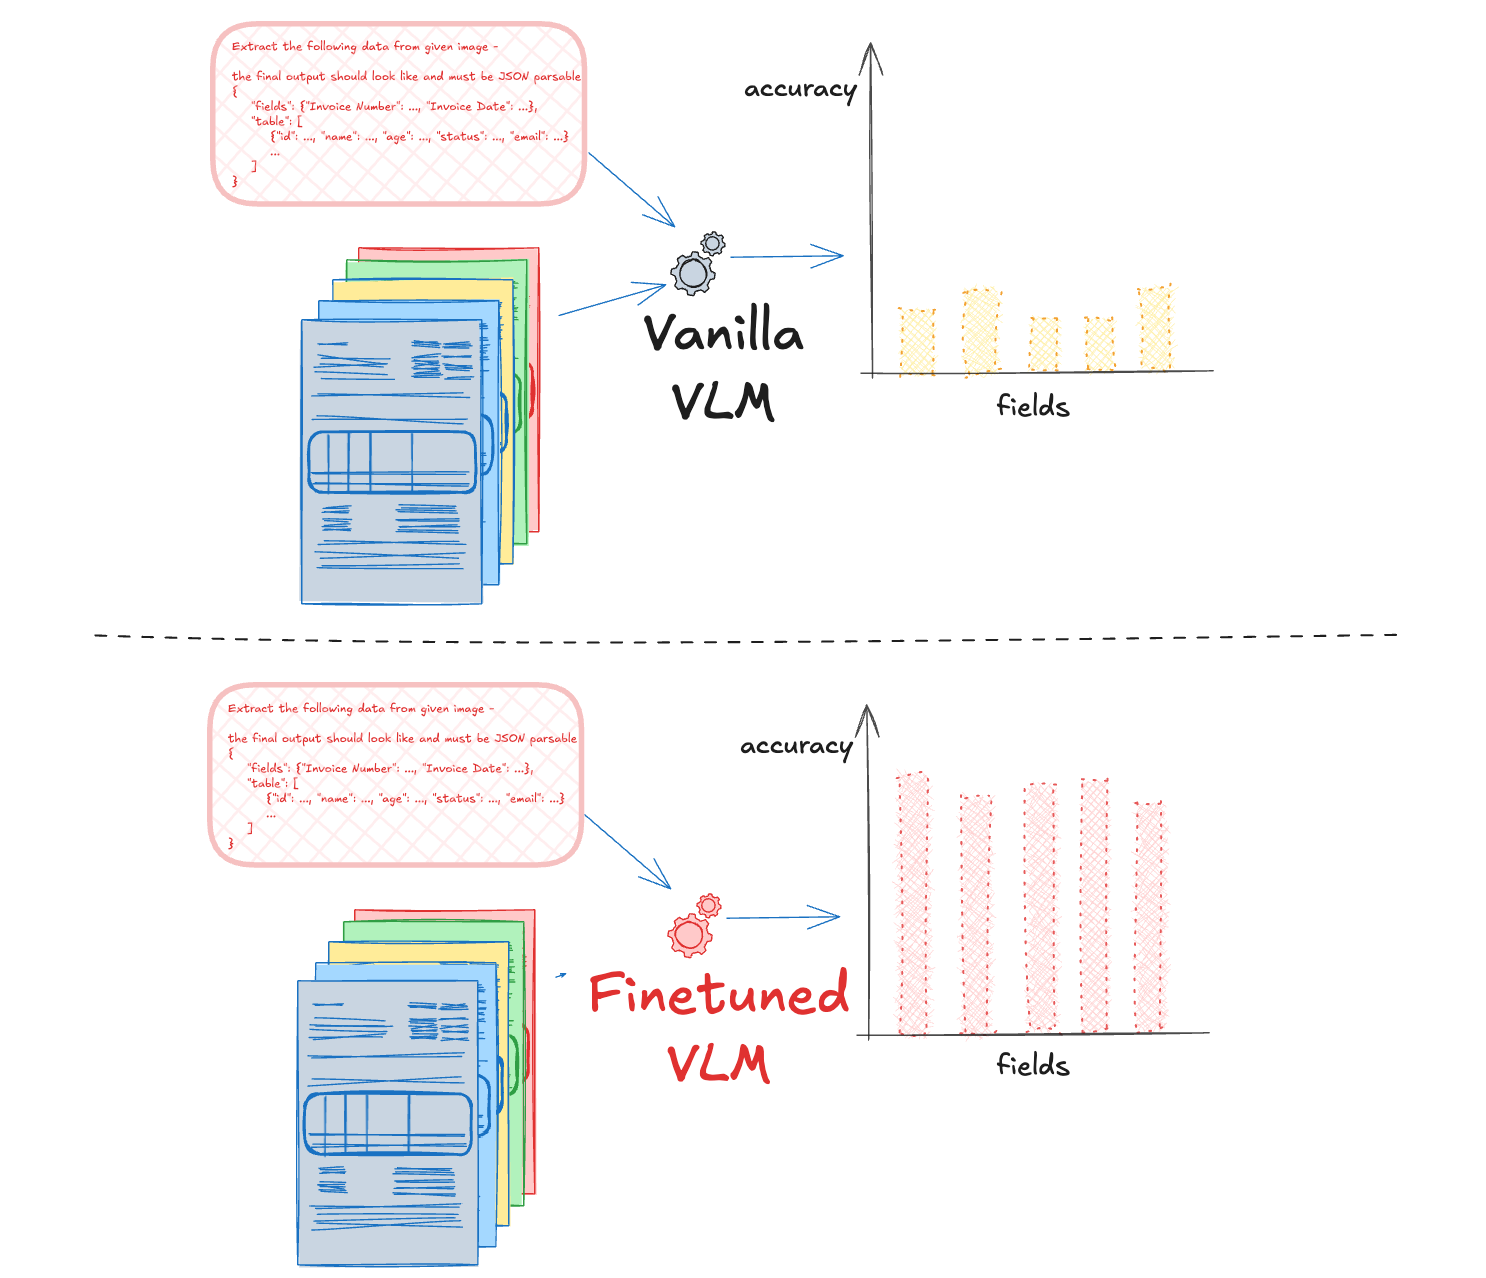
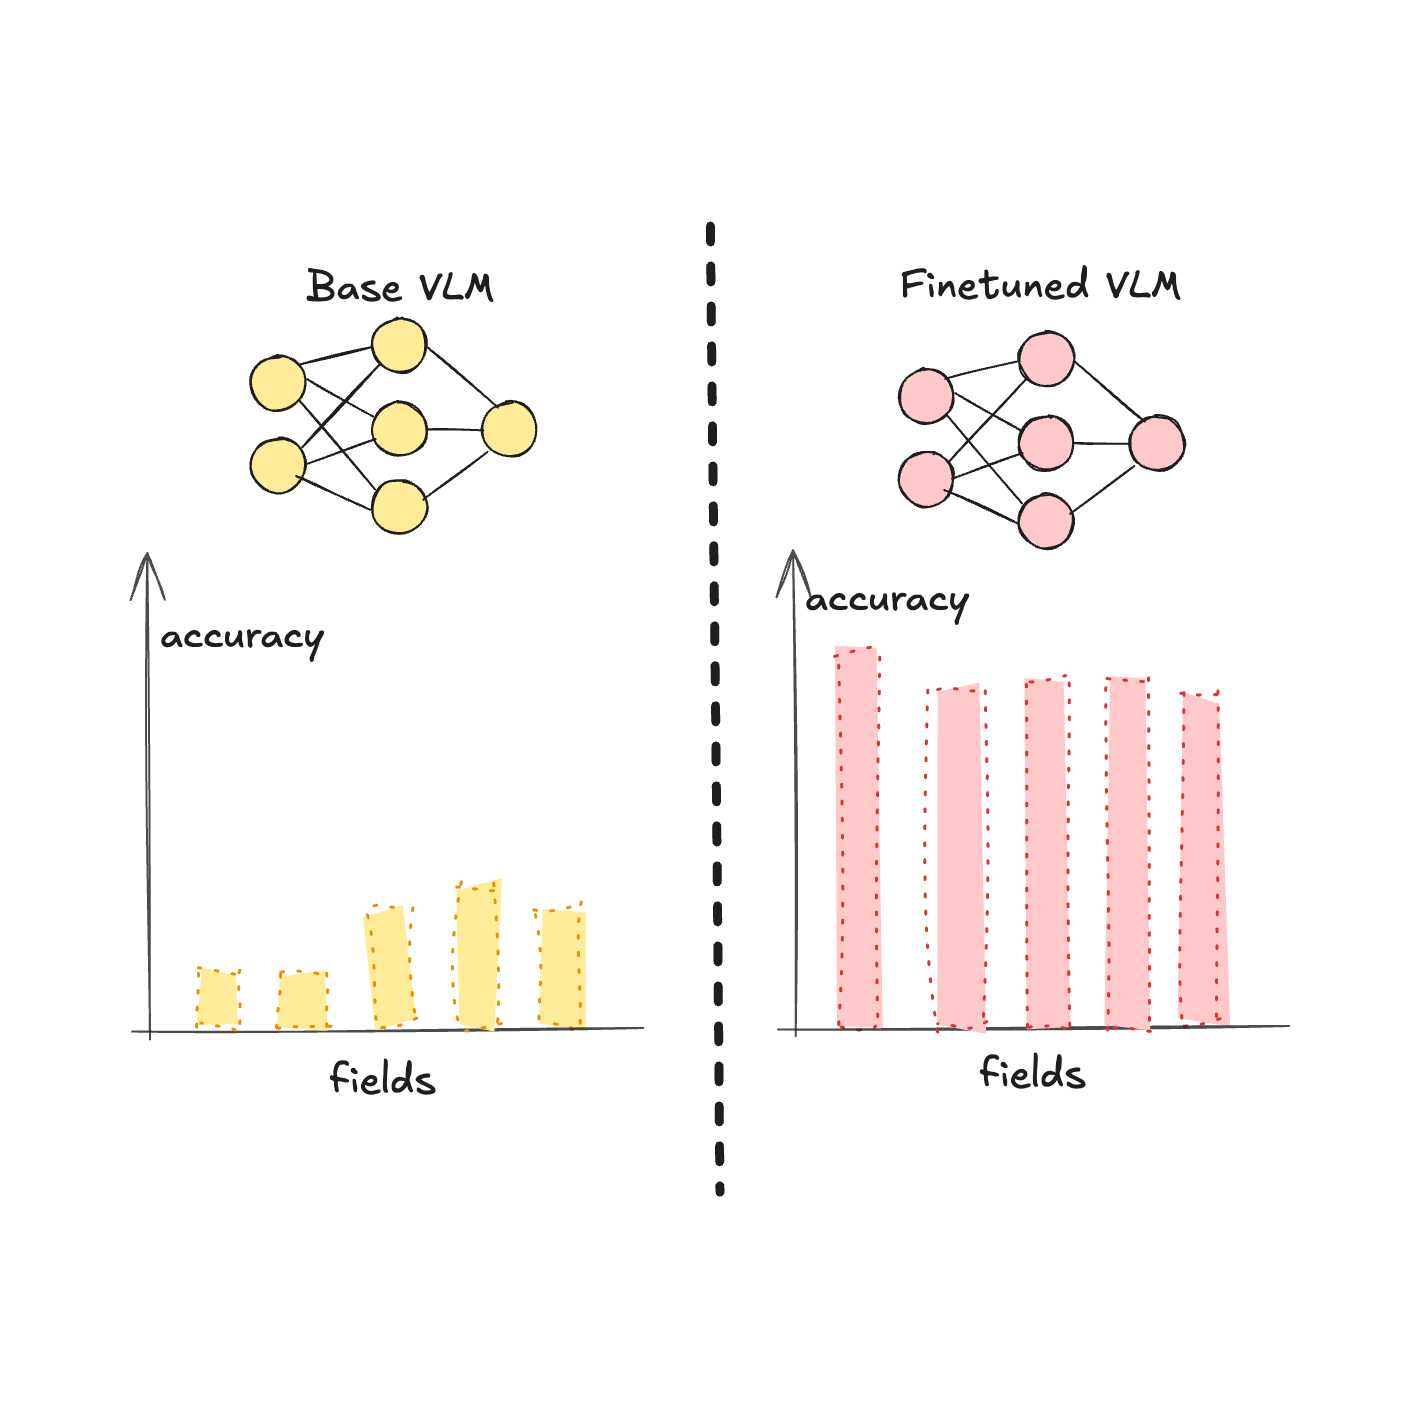
Fine-Tuning Vision Language Models (VLMs) for Data Extraction
Best Open-Source Vision Language Models of 2026
Do VLMs Need Vision Transformers? Evaluating State Space Models as ...
Visual Language Model(VLM)简介 - 知乎
Structured Output in Local Vision Language Models (VLMs): A Step-by ...
내원 - LLM부터 VLM, Omni-modal, Physical AI, World Model까지 도식 정리. 나름대로 한번 ...
Top 10 Open Source LLMs in 2025 & their Enterprise Use Cases
新出行百科|VLA、VLM 到底是什么?_百科_新出行
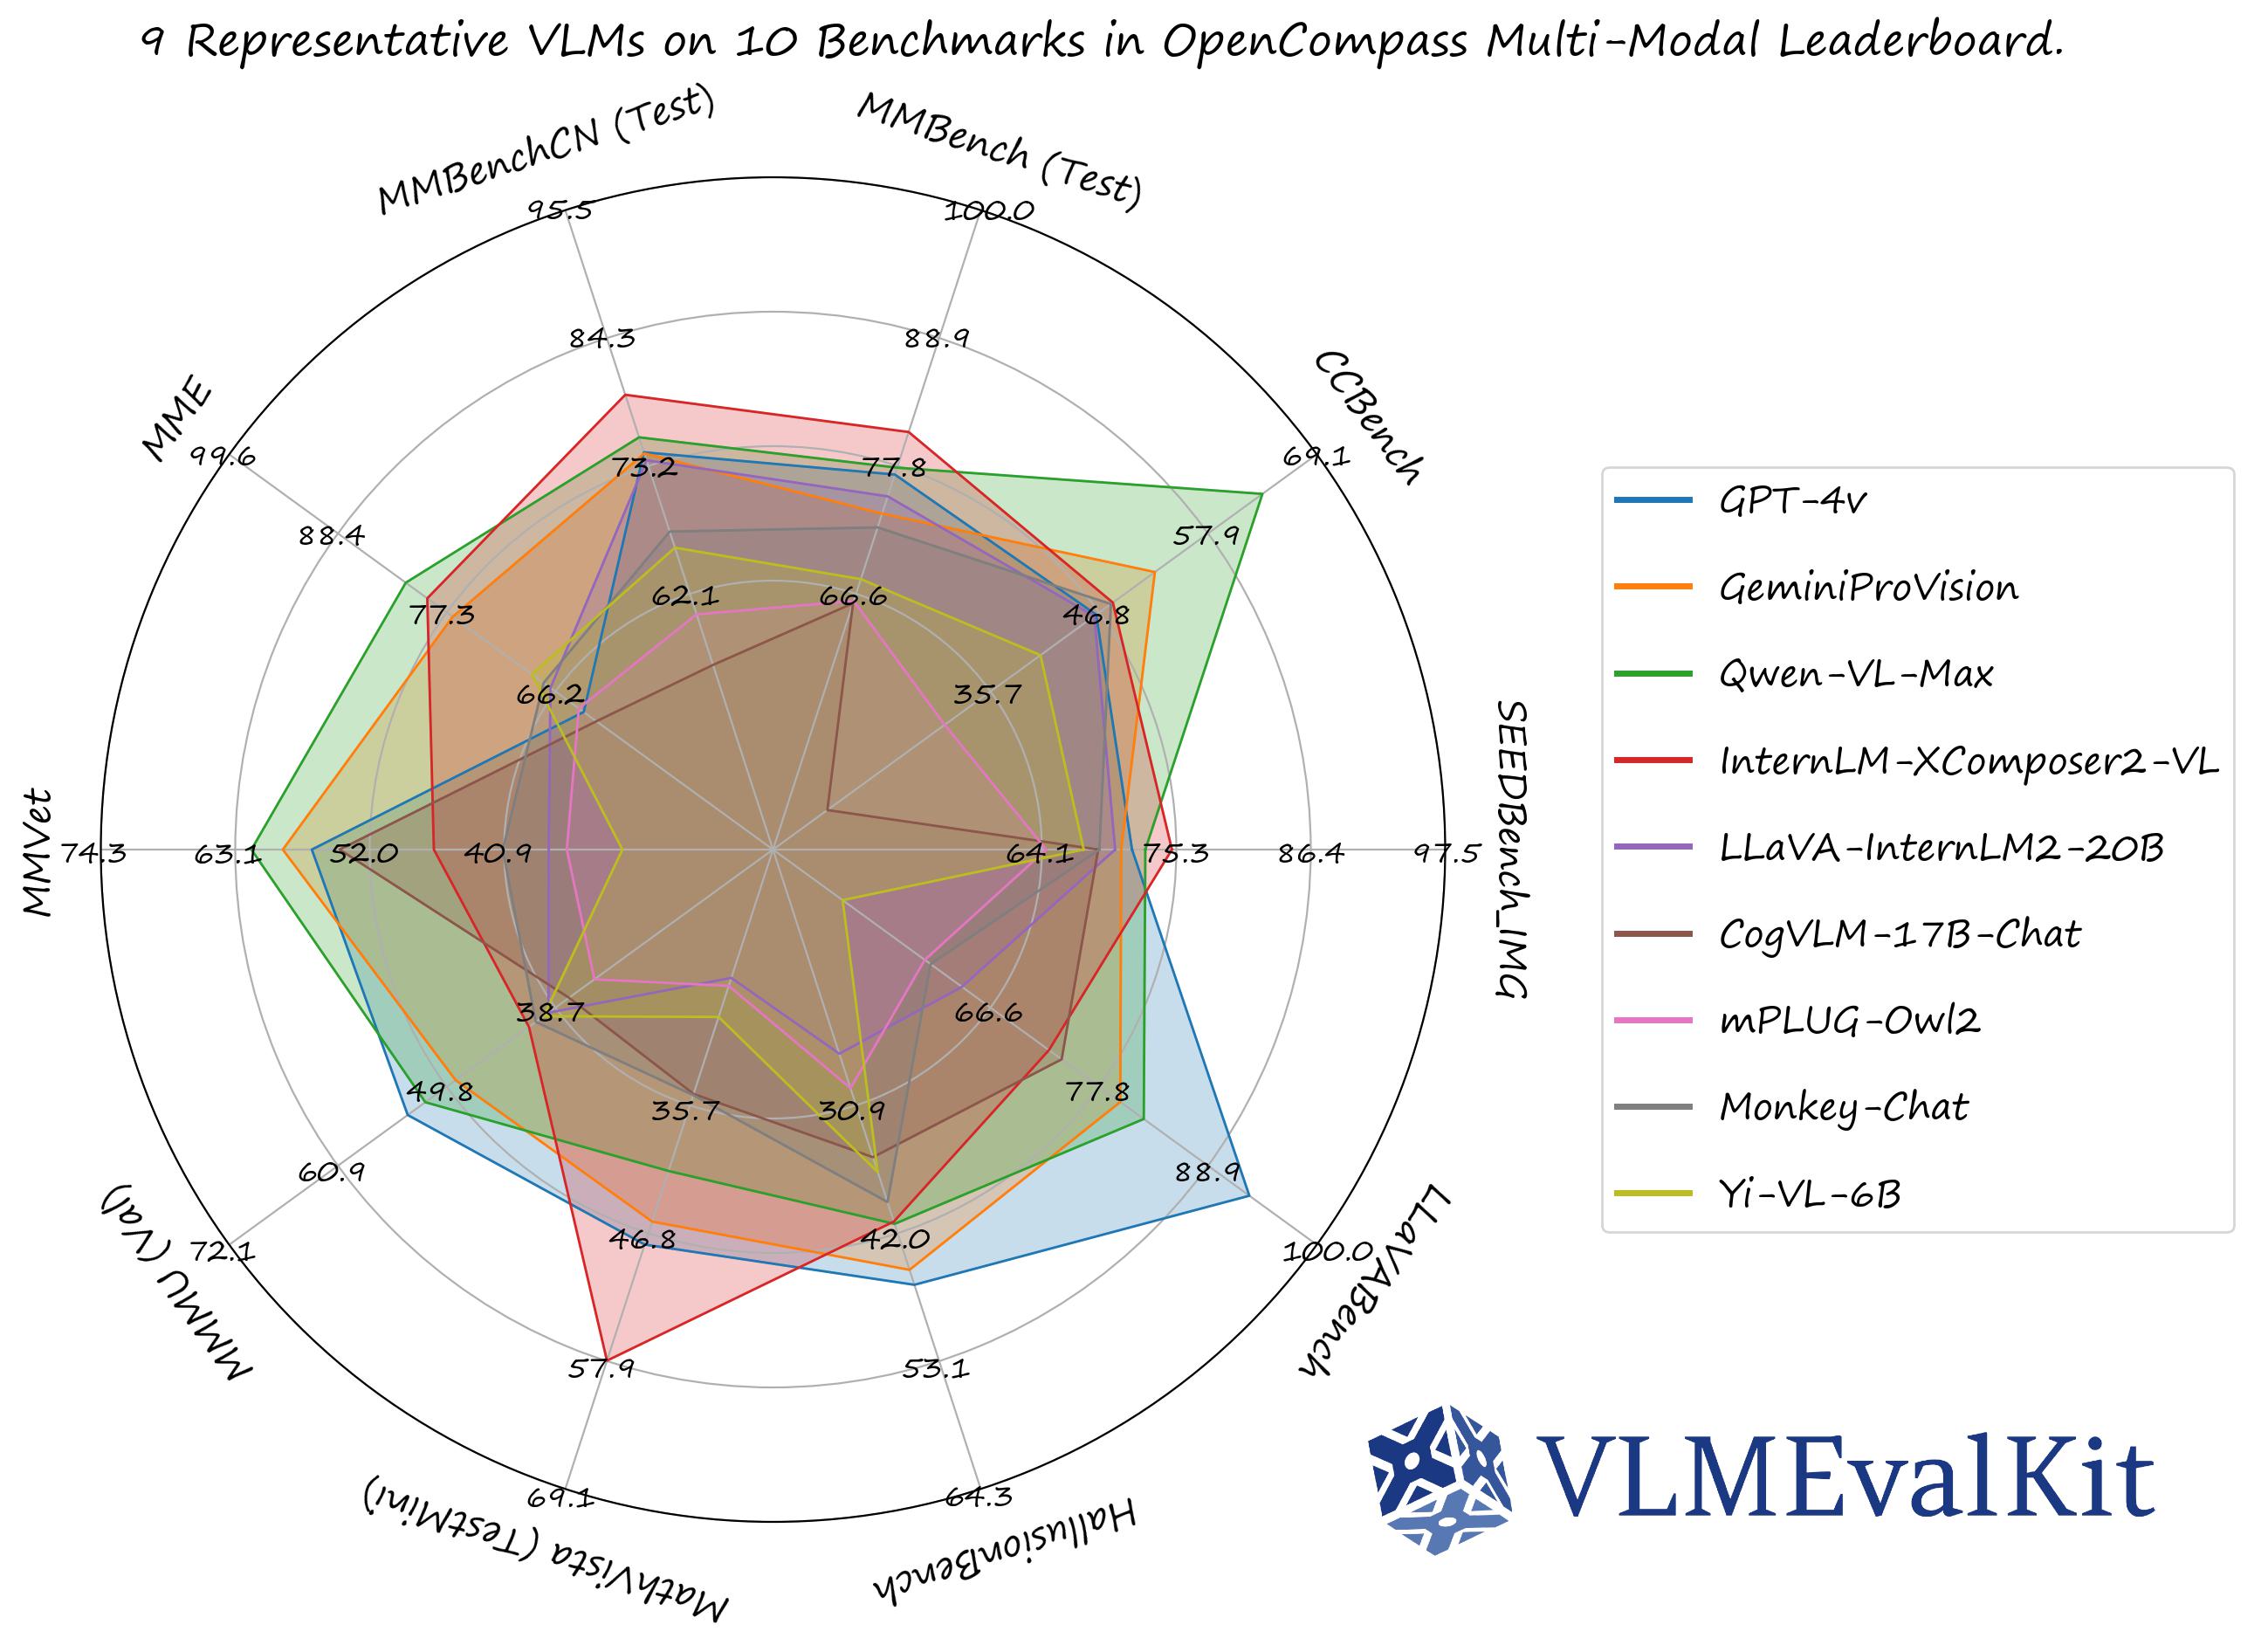
GitHub - mfarre/VLMEvalKit-official: Open-source evaluation toolkit of ...
What puts the A in VLA? | Baltic Vectors
Understanding Visual Language Models - Gradient Flow
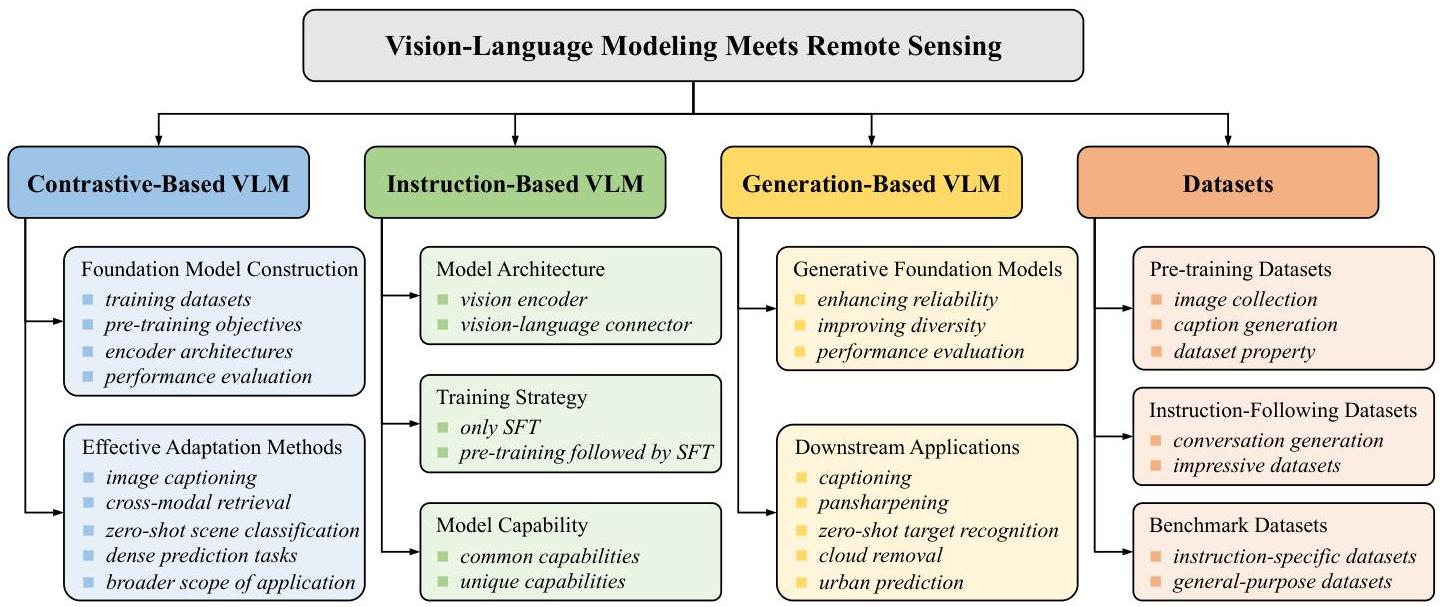
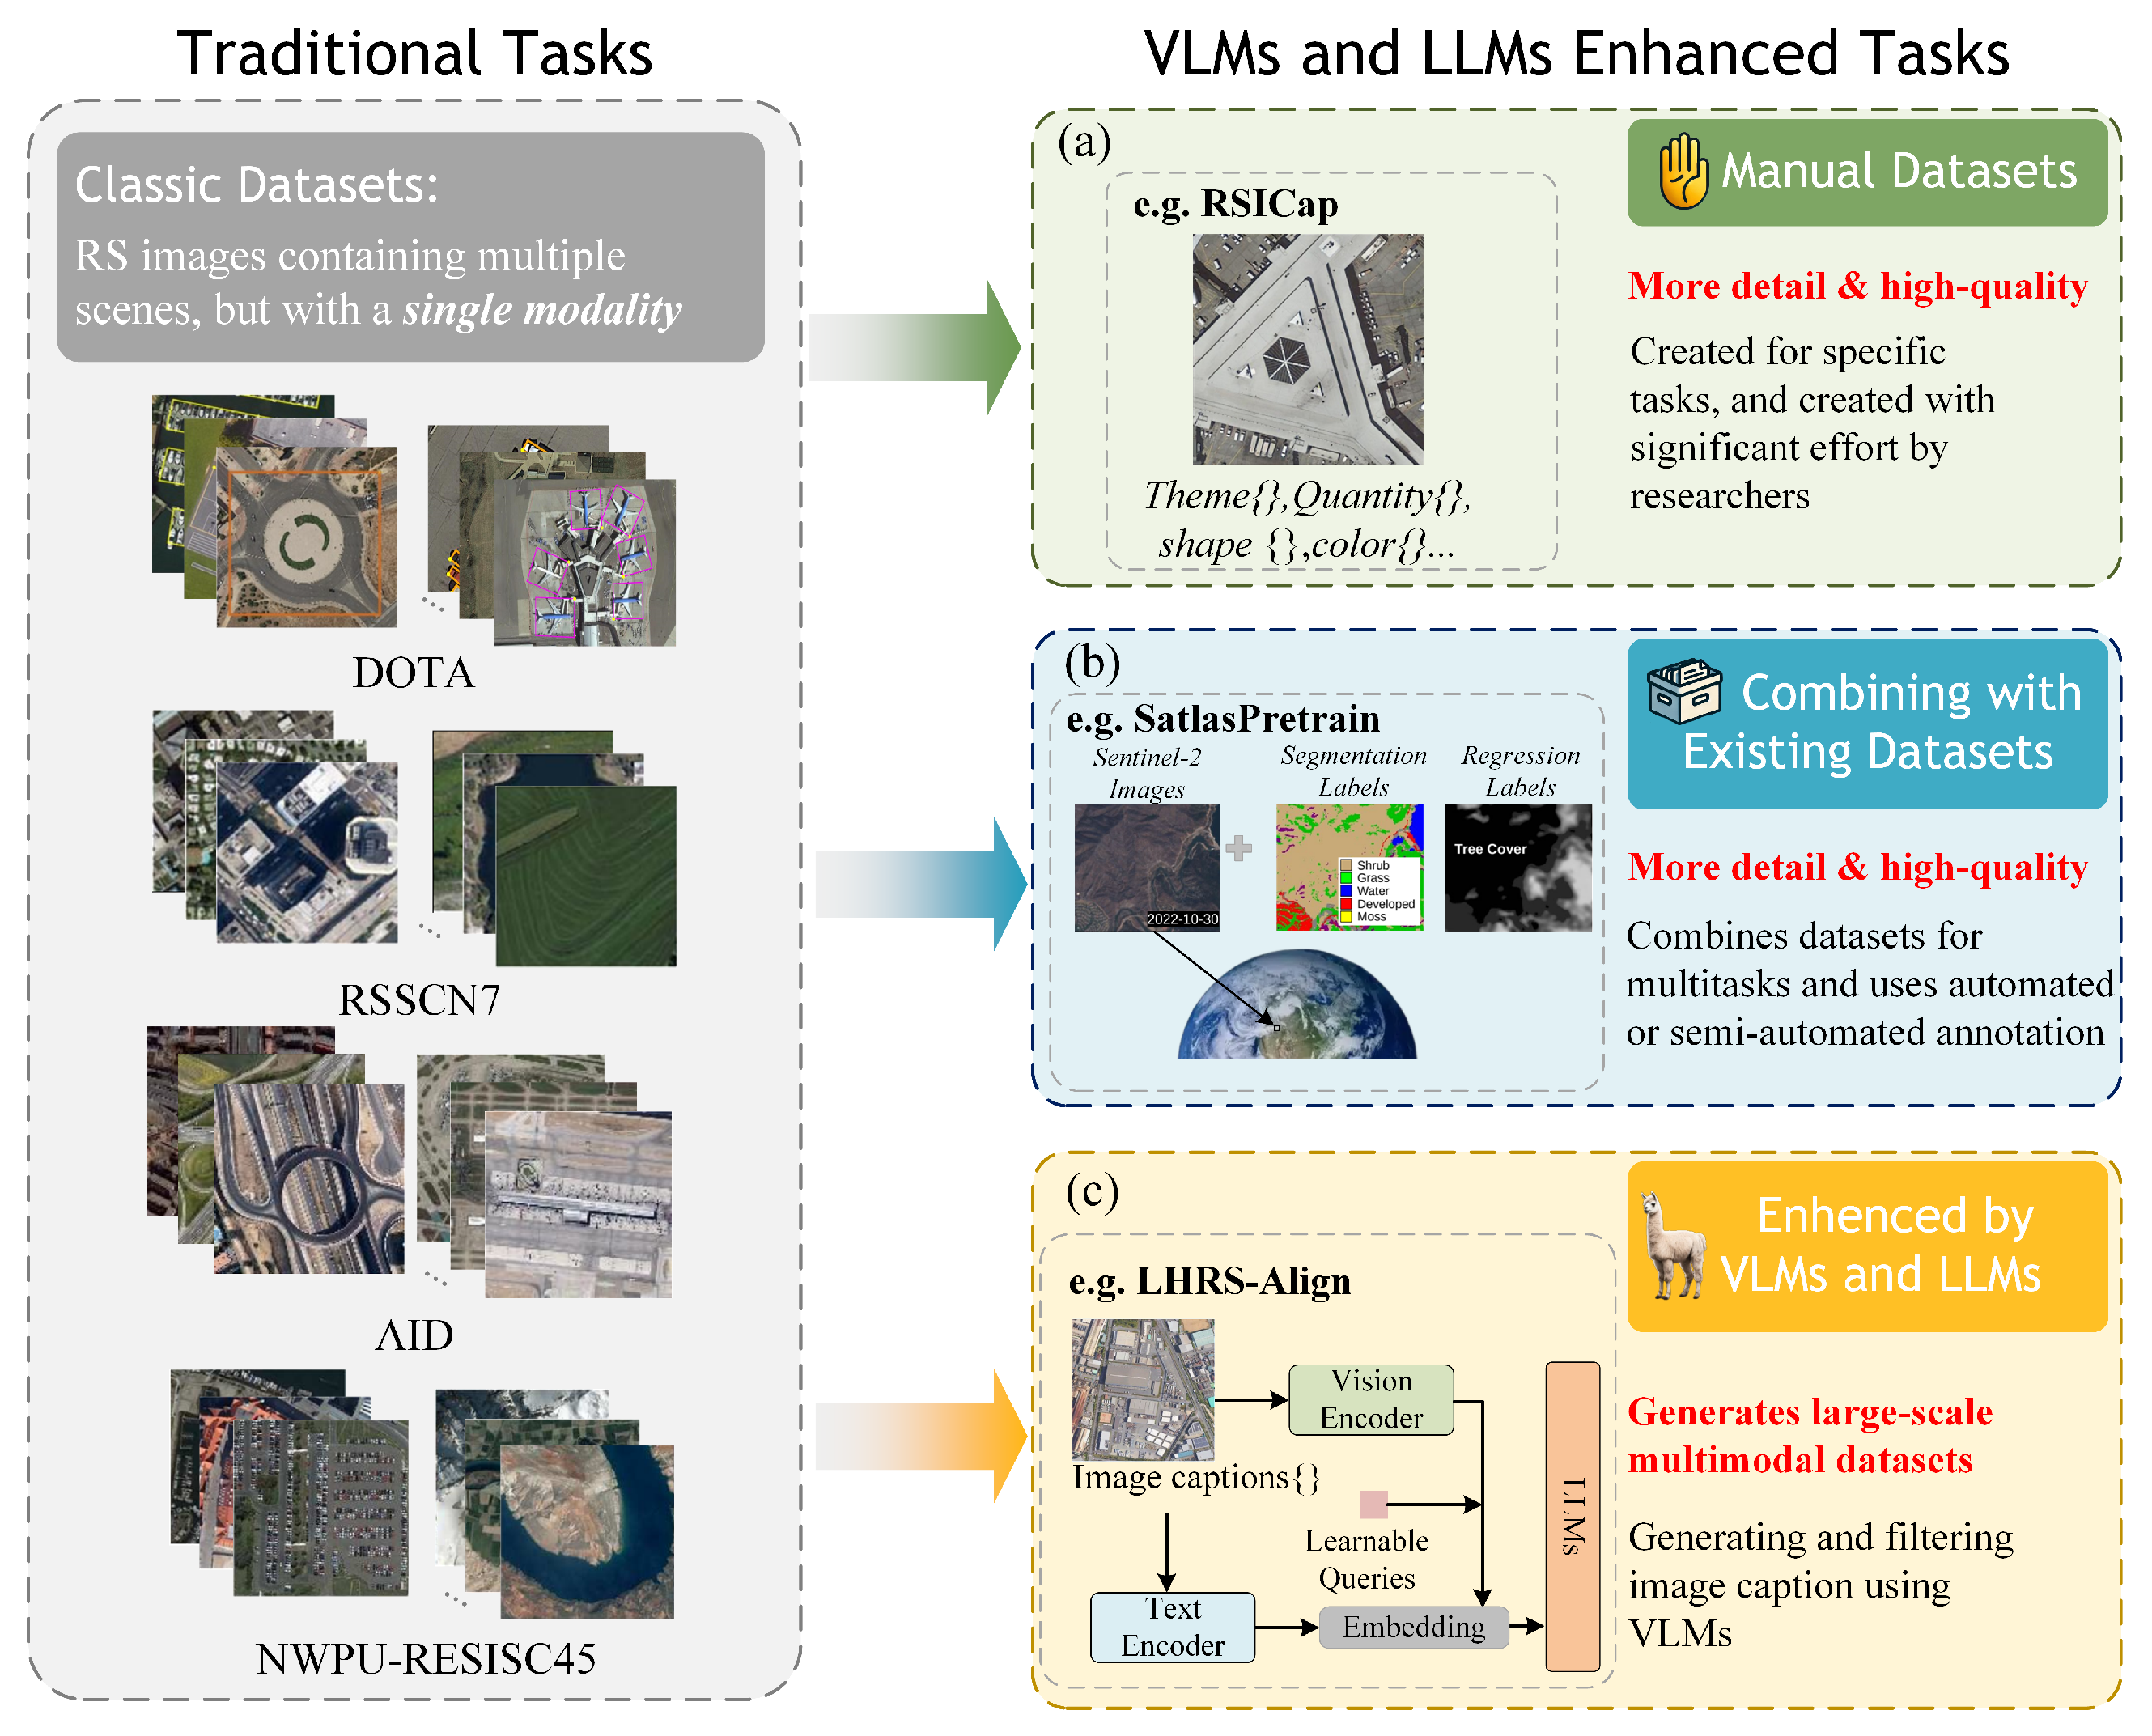
Vision-Language Modeling Meets Remote Sensing: Models, Datasets and ...
Aman's AI Journal • Primers • Vision Language Models
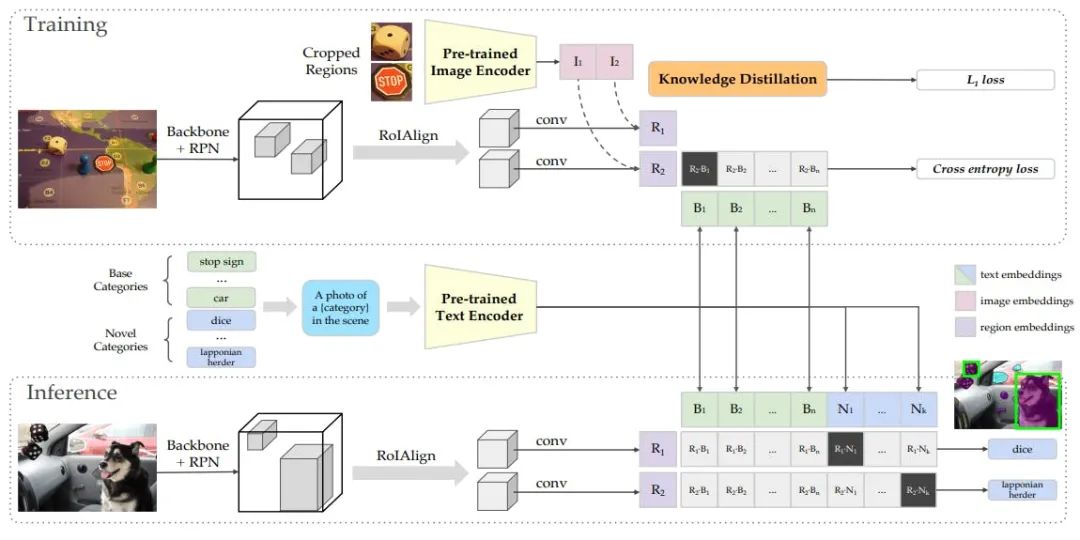
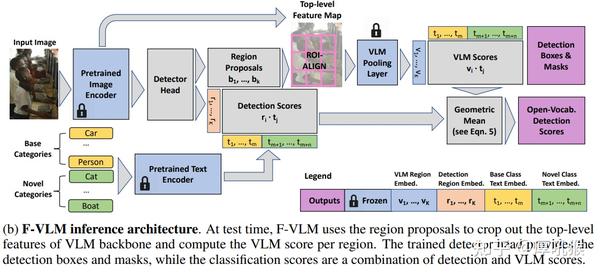
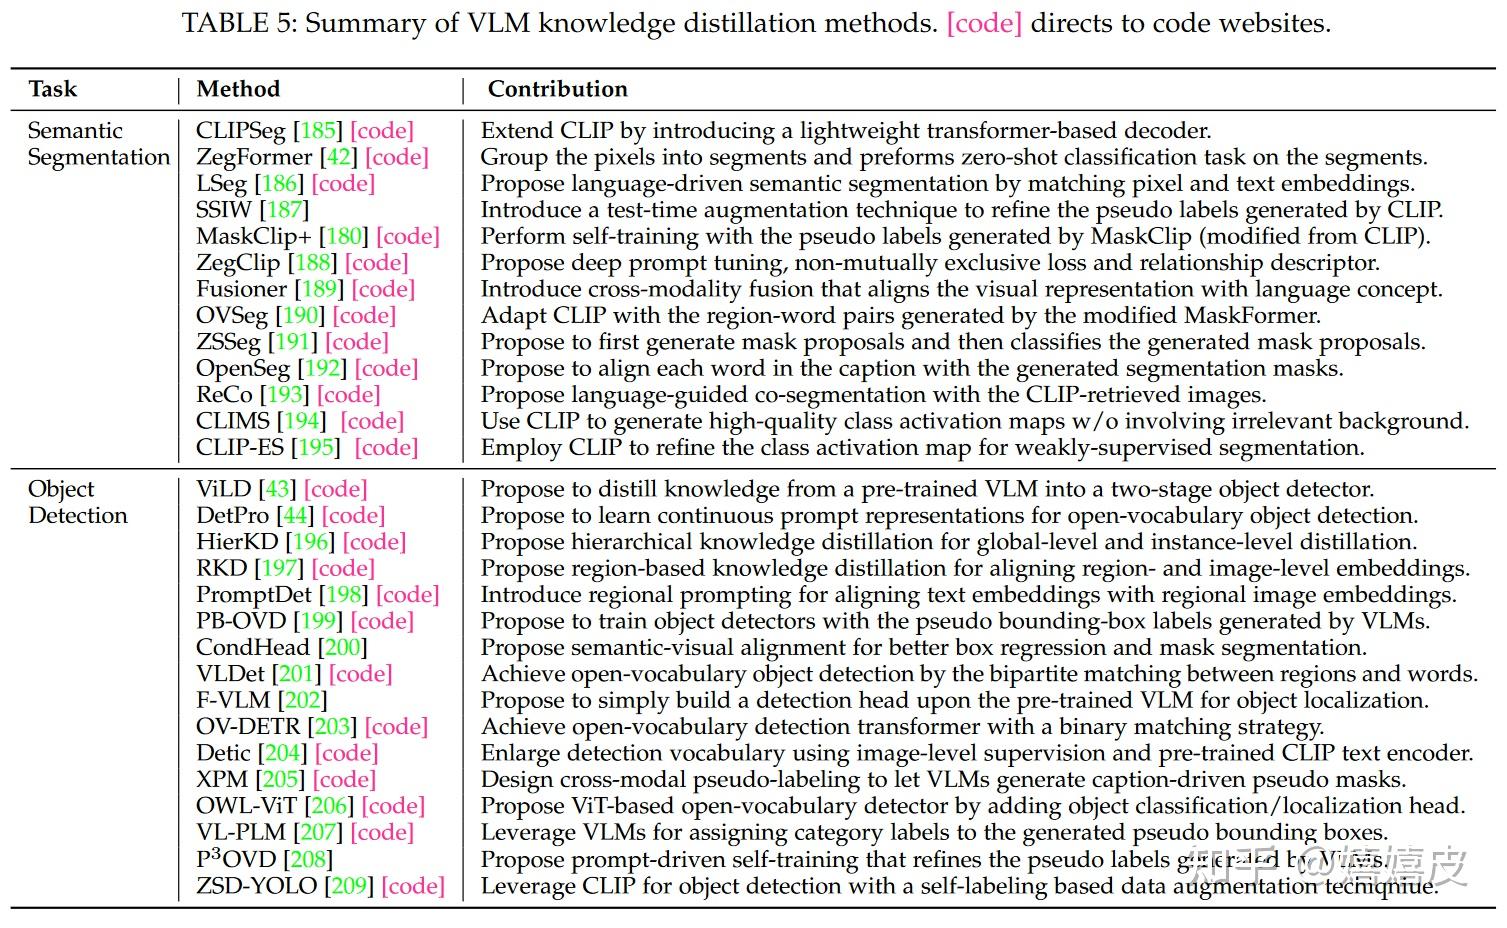
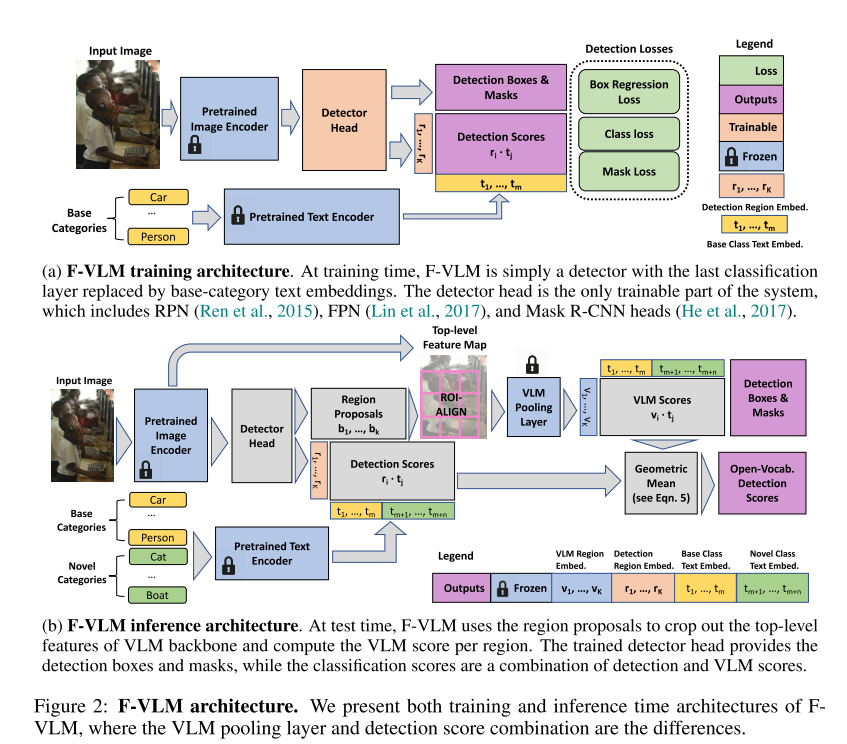
[论文碎碎念]F-VLM: OPEN-VOCABULARY OBJECT DETECTION UPON FROZEN VISION AND ...
使用Pytorch构建视觉语言模型(VLM)_vlm构建-CSDN博客
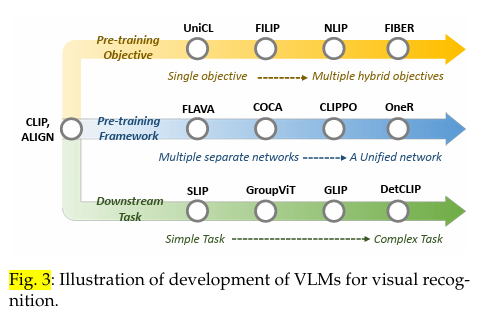
从视觉识别任务出发,深入探索视觉语言模型(VLM)基础篇章—VLM学习综述及论文详解:Vision-Language Models for ...
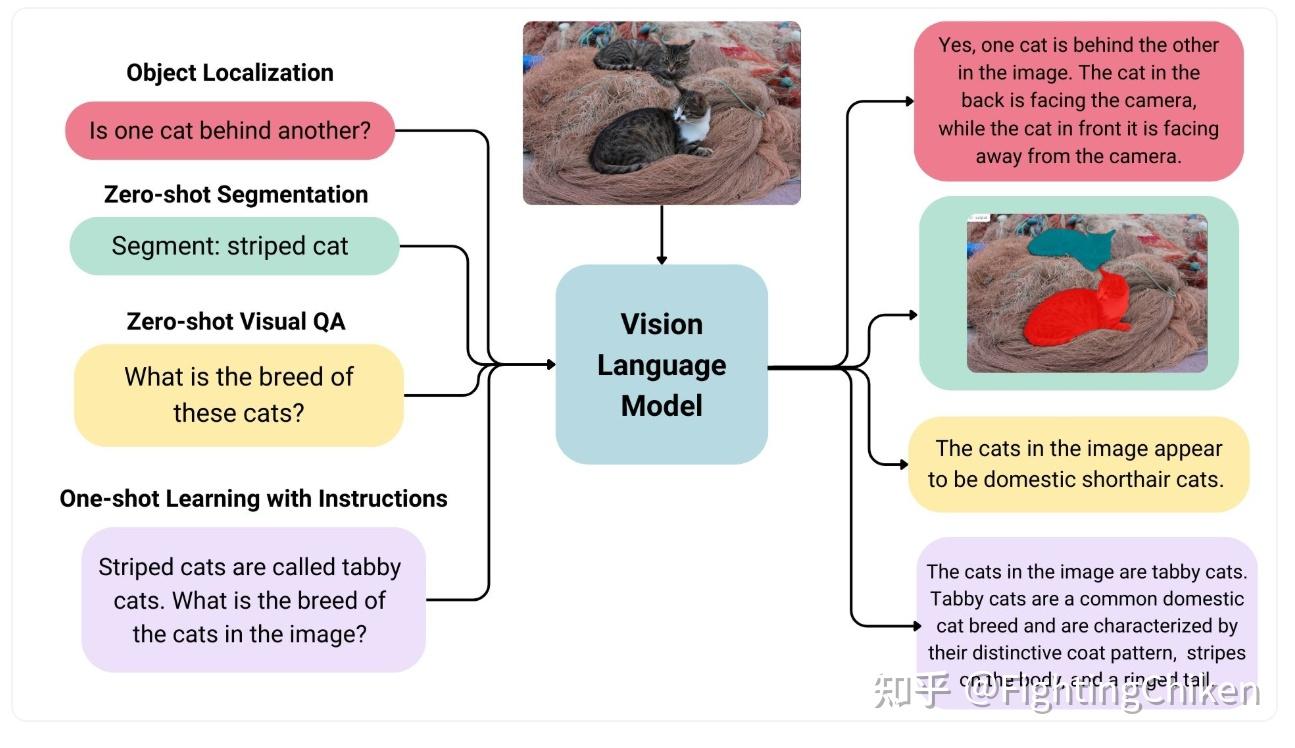
Vision Language Models (VLM) Complete Guide - How AI Understands Images ...
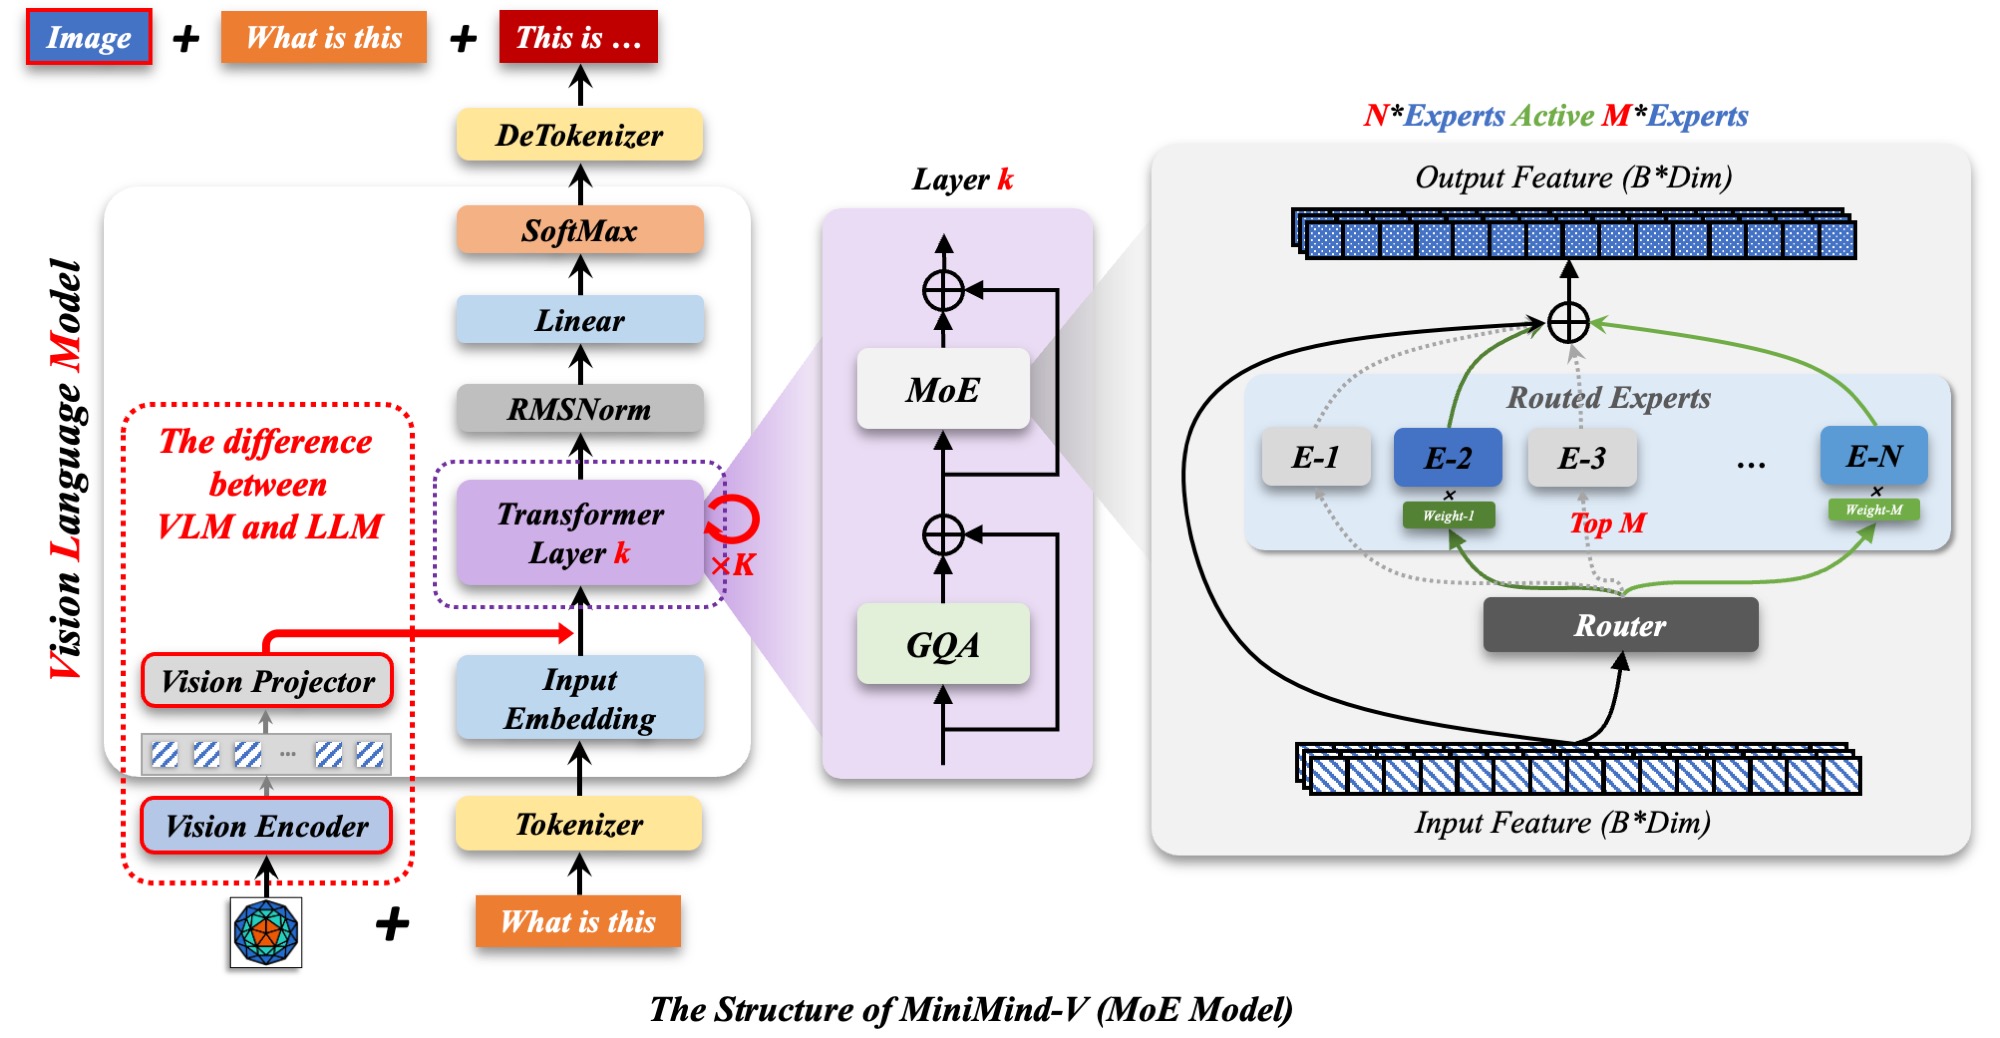
MiniMind-V - Train Vision-Language Models from Scratch
SVLM 모델의 취약성 | hanleju
Vision Language Models (VLM) 完全ガイド - 画像を理解するAIの仕組みと実装 | Agenticai Flow ...
Commonsense Reasoning for Legged Robot Adaptation with Vision-Language ...
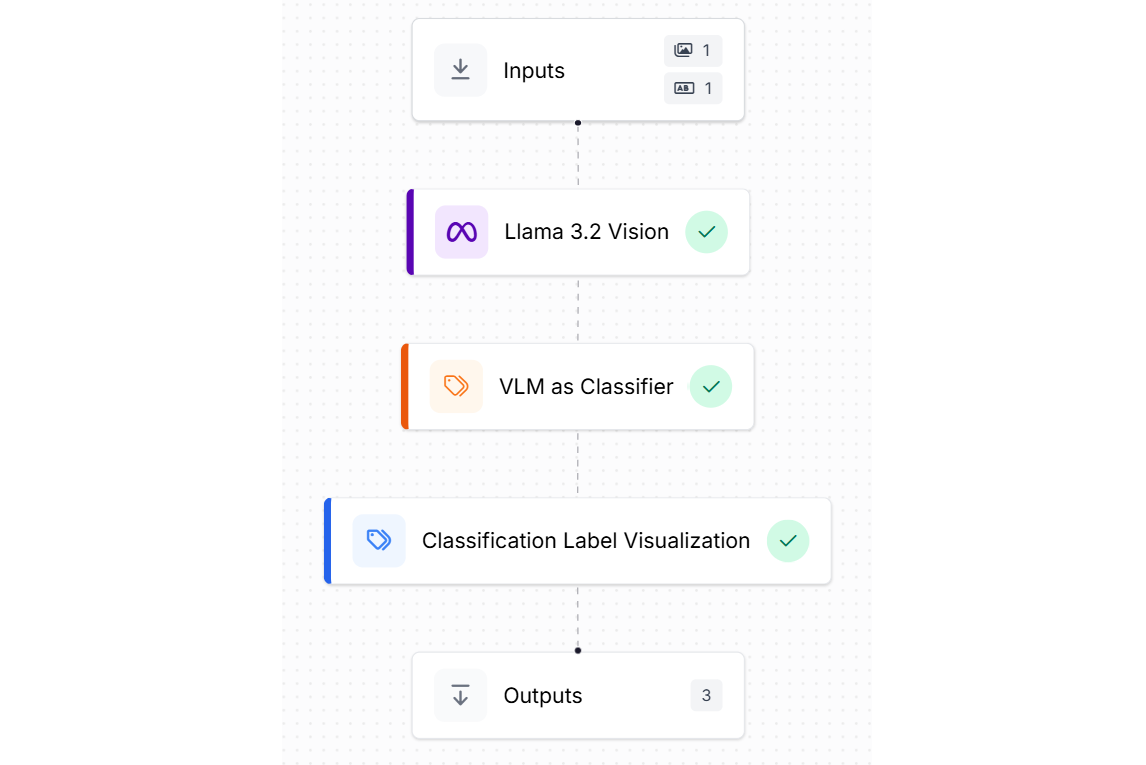
Vision language models: how LLMs boost image classification
【Pycon mini 東海 2024】Google Colaboratoryで試すVLM - Speaker Deck
Scene-VLM: Multimodal Video Scene Segmentation via Vision-Language Models
Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...
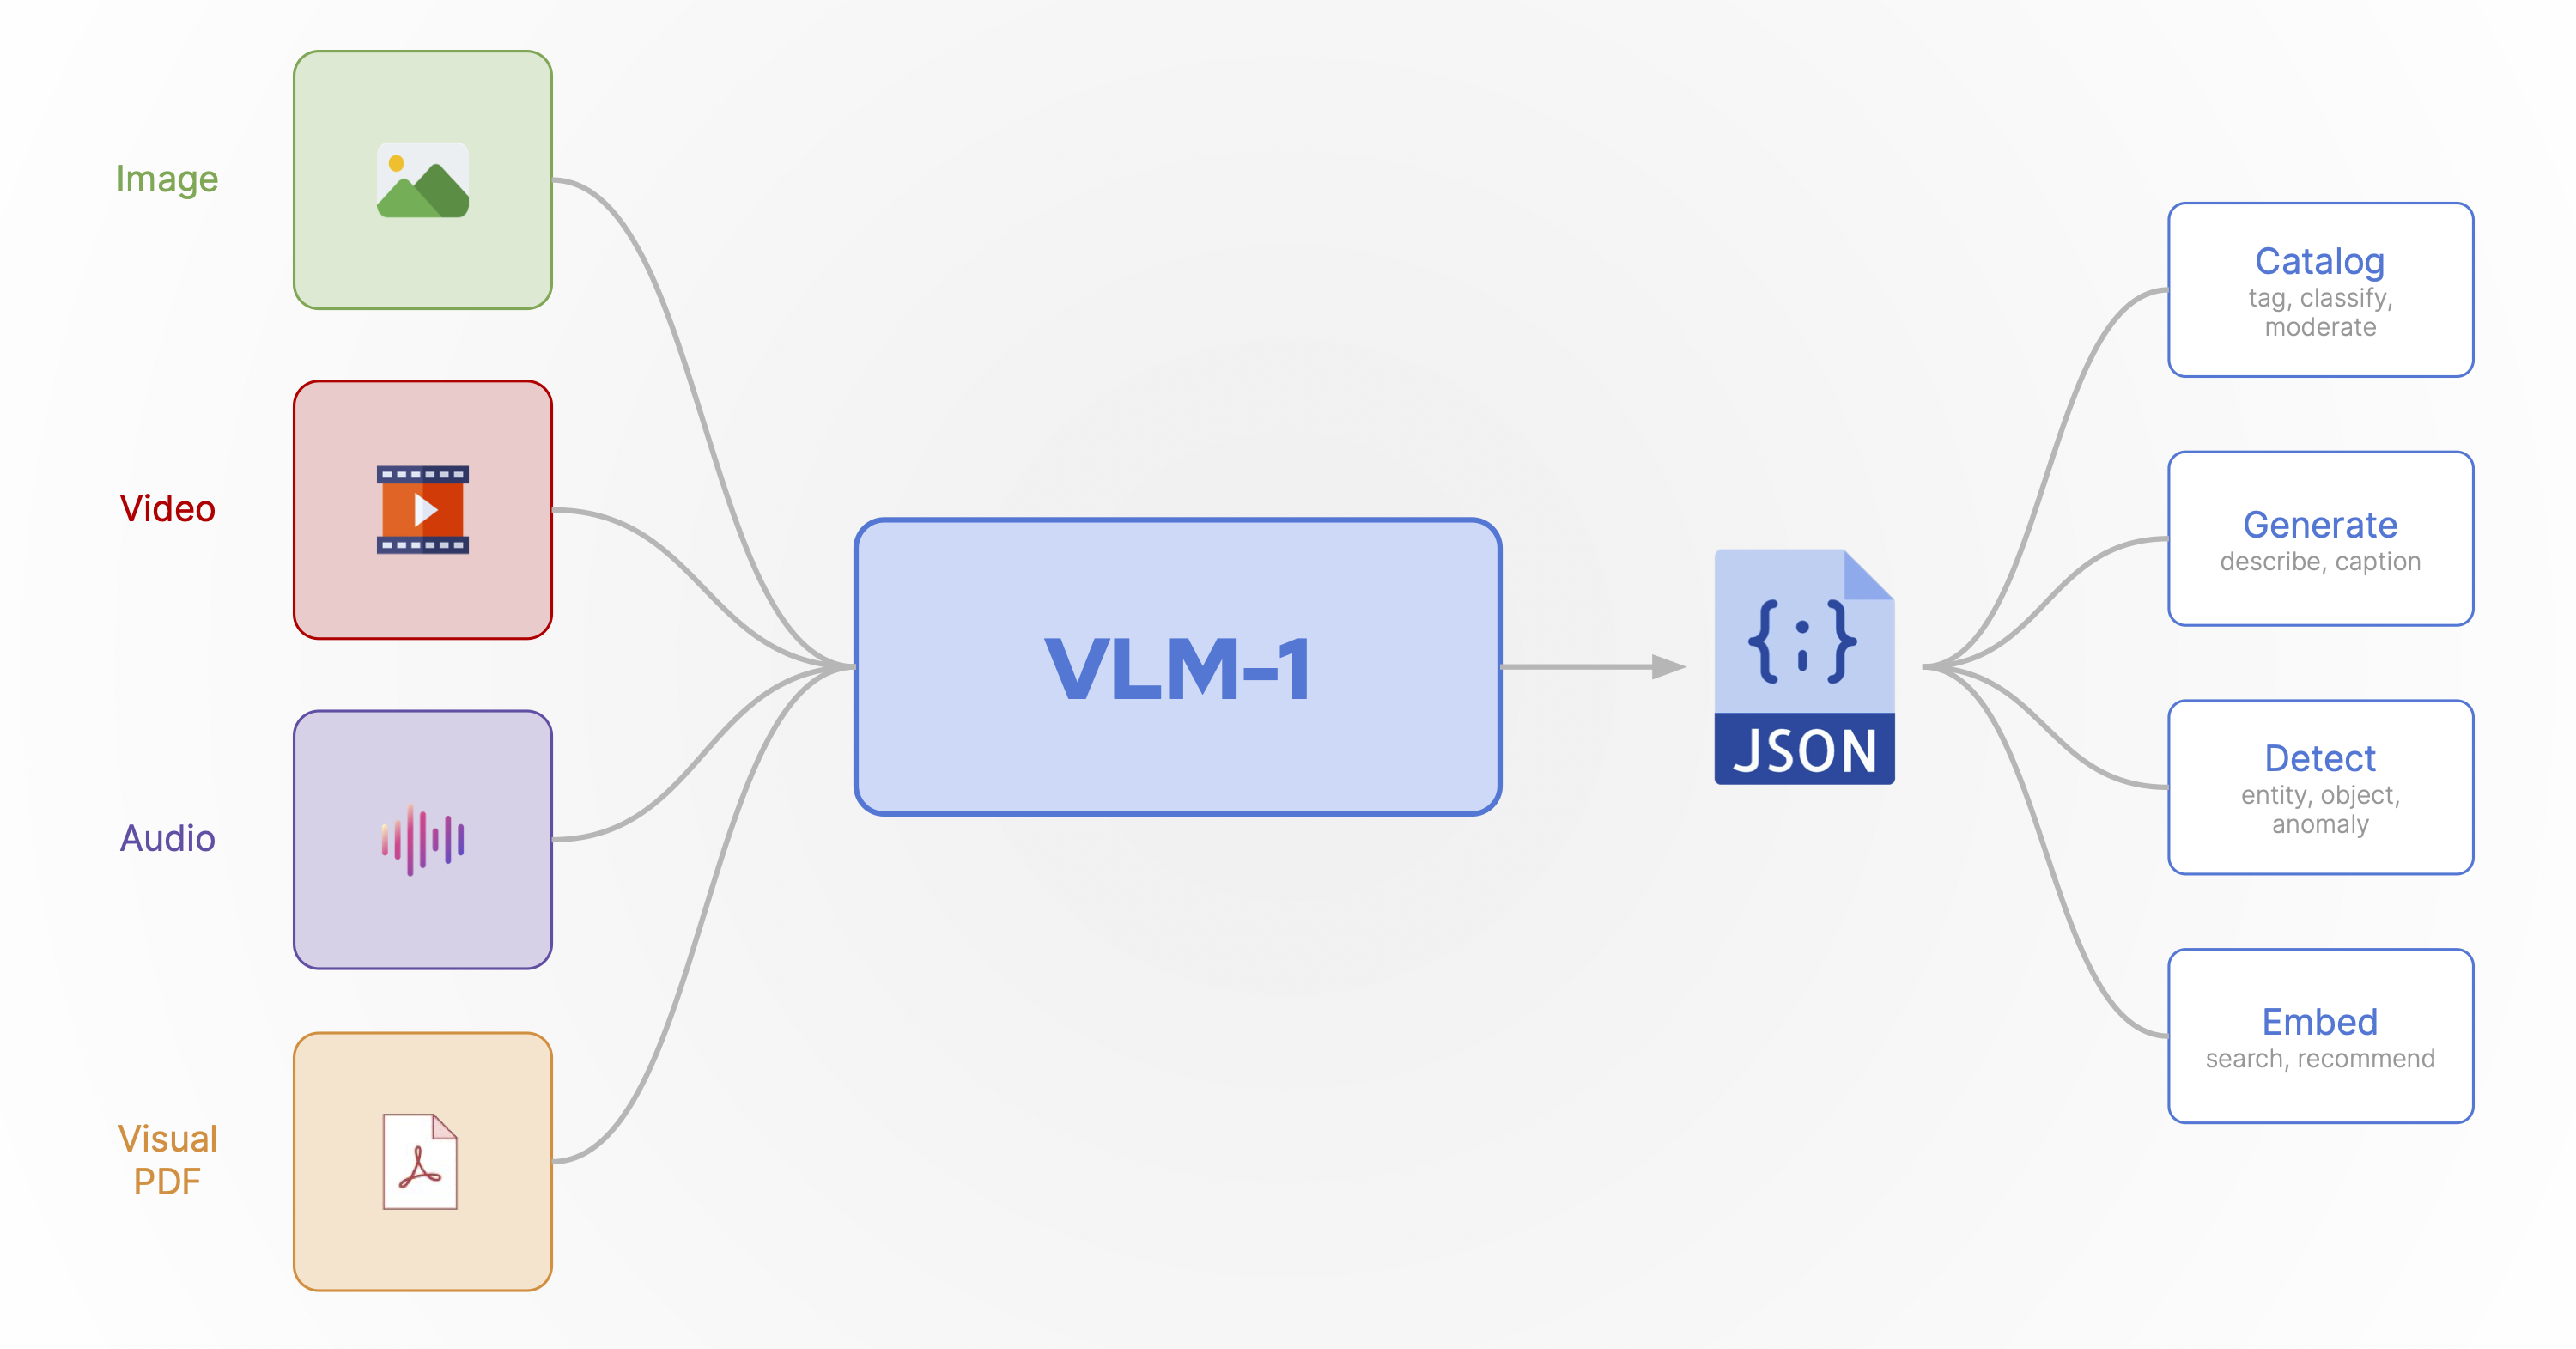
Introduction - VLM-1
Vision Language Model(VLM) in a Nutshell
It's time for LAM (Large Action Models) over LLM and VLM... how it works?
Part 14 · Using Pretrained VLMs | Smol Course | TastyRiceLog
Explicación de los modelos de lenguaje visual | Ultralytics
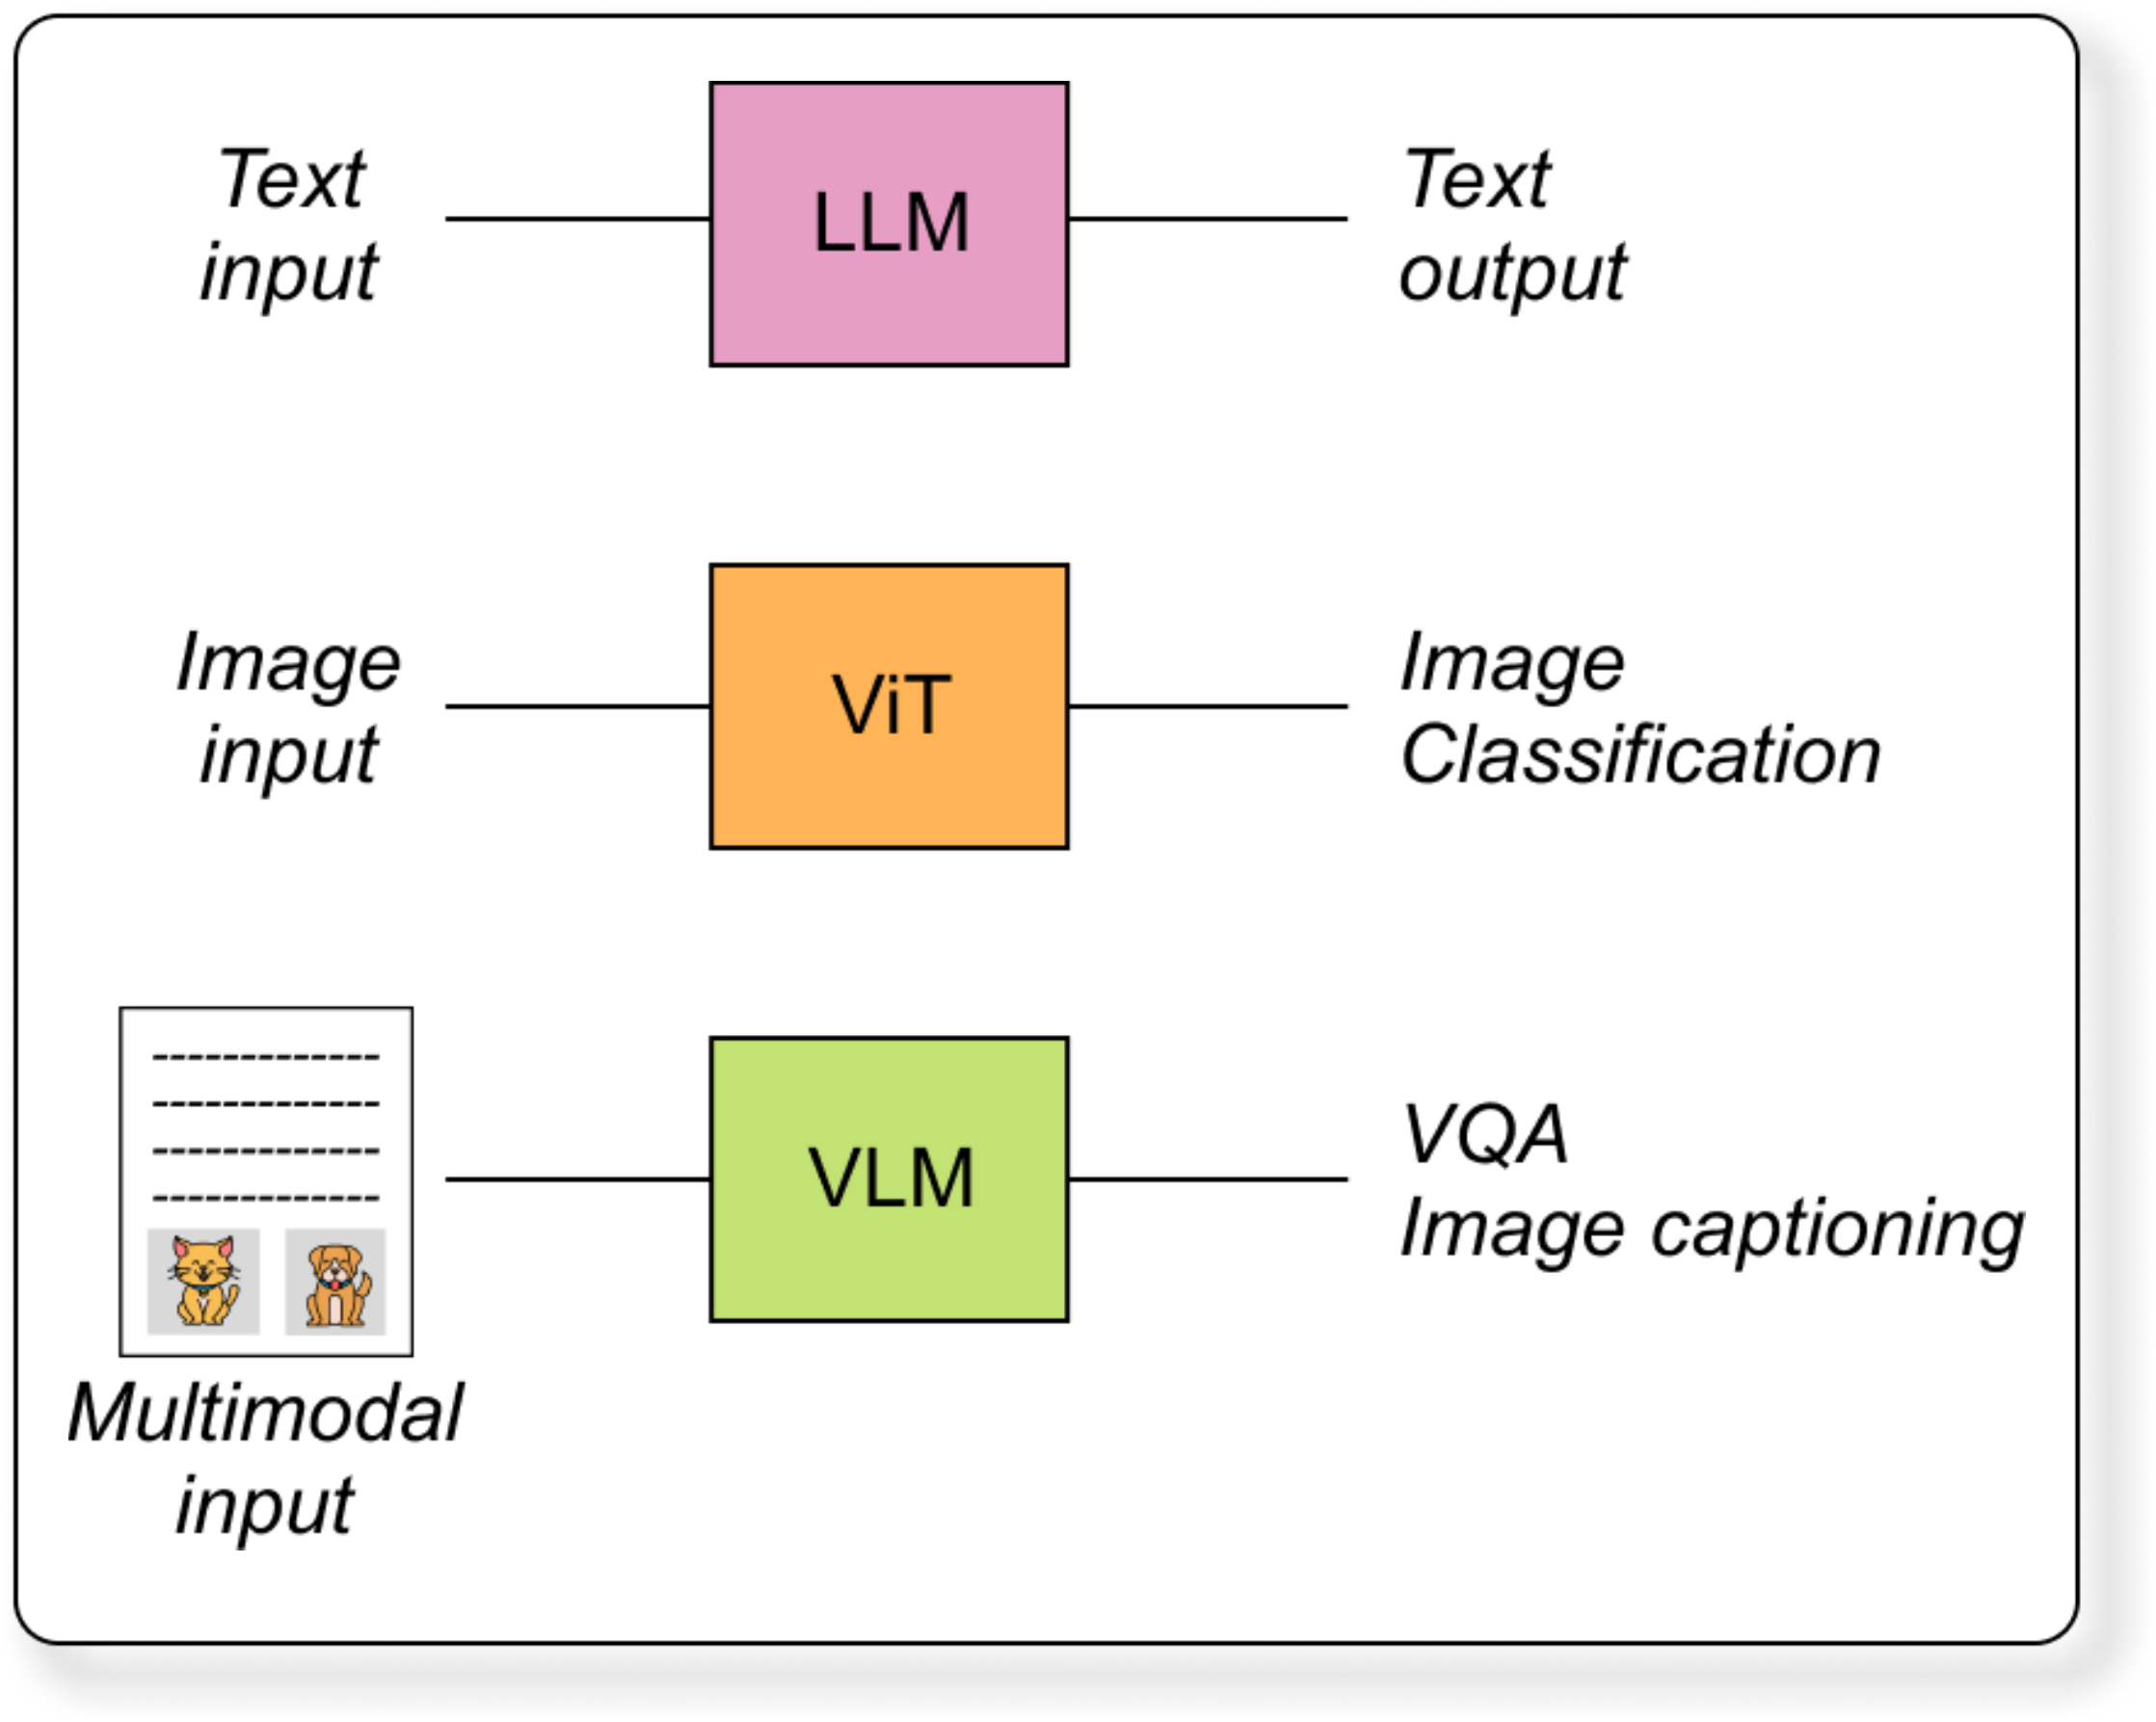
从入门到精通:AI技术栈必备——一文读懂LLM、VLM、MoE、LAM和SLM五大核心架构,建议收藏!_llm moe-CSDN博客
Vision-Language Models(VLM)学习(一)原理_vlm模型-CSDN博客
视觉语言模型(VLM)学习笔记-CSDN博客
VLM综述:An introduction to Vision-Language Modeling(一) - 知乎
Generalized Visual Language Models | Lil'Log
Vision Language Modelと完全自動運転AIの最新動向 - Speaker Deck
Vision Language Models (VLMs) - GeeksforGeeks
VLM-3D:End-to-End Vision-Language Models for Open-World 3D Perception ...
[VLM] Vision Language Models 1
Visual Language Models (VLM): A Deep Dive into the Future of Multimodal ...
Vision-Language Models for Vision Tasks: A Survey - 知乎
F-VLM: Open-vocabulary object detection upon frozen vision and language ...
Vision-Language Models Tutorial – Devansh’s Blog
【综述】An Introduction to Vision-Language Modeling【一】-EW帮帮网
VLA models inherit powerful vision-language priors from VLMs, but ...
Vision Language Models (VLMs) Explained | DataCamp
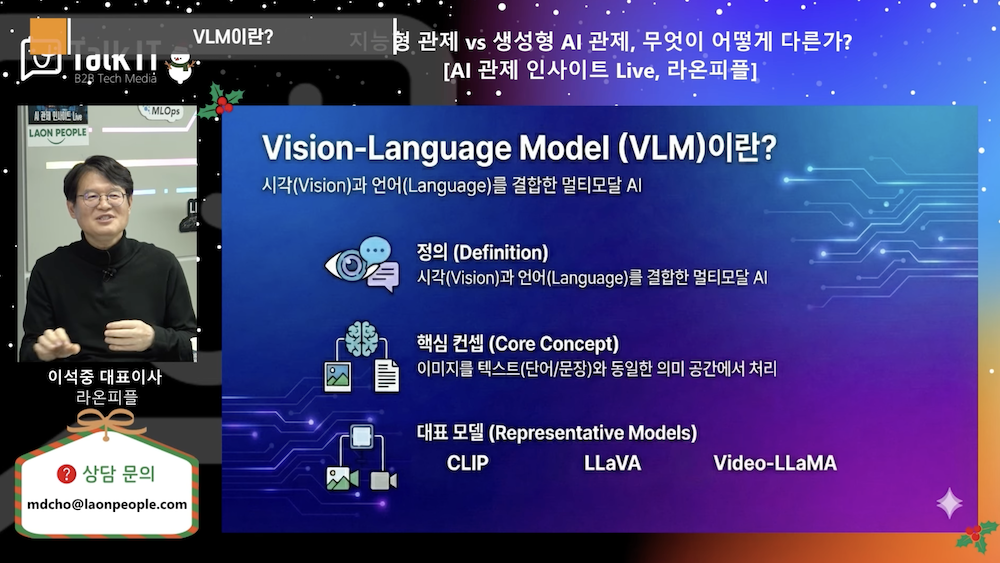
피지컬 AI시대 주목받는 VLM(비전 언어 모델), 무엇이고 어떻게 동작하는가? (이석중 대표 / 라온피플) | 고우성의 잇(IT)터뷰
Vision Language Models (VLM) like ViLA can do scene perception and ...
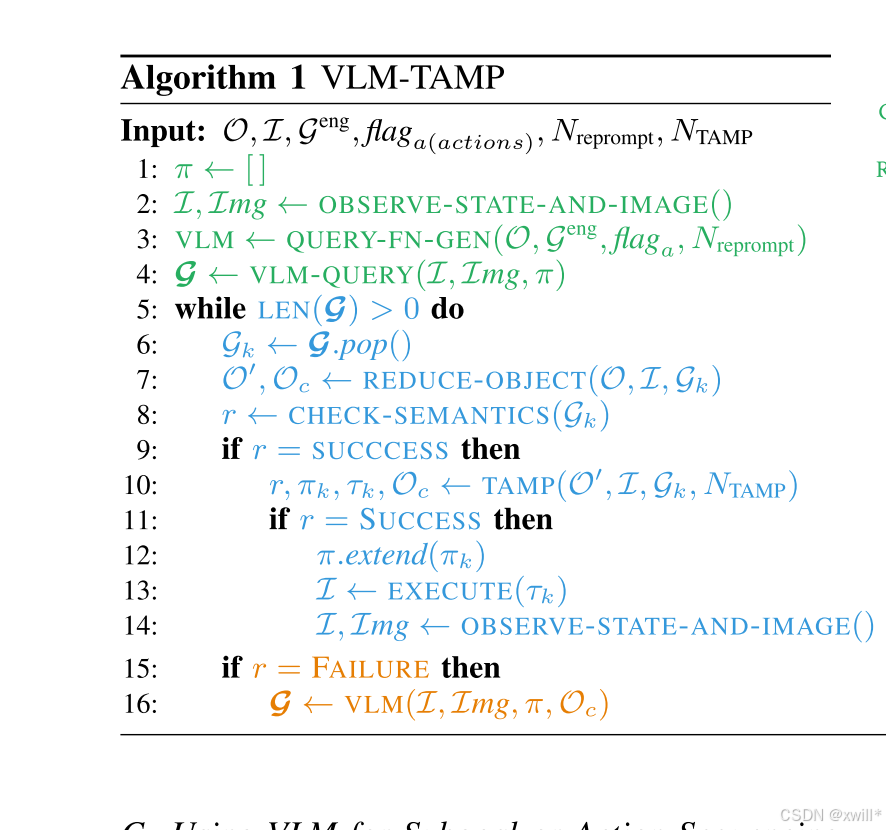
Guiding Long-Horizon Task and Motion Planning with Vision Language ...
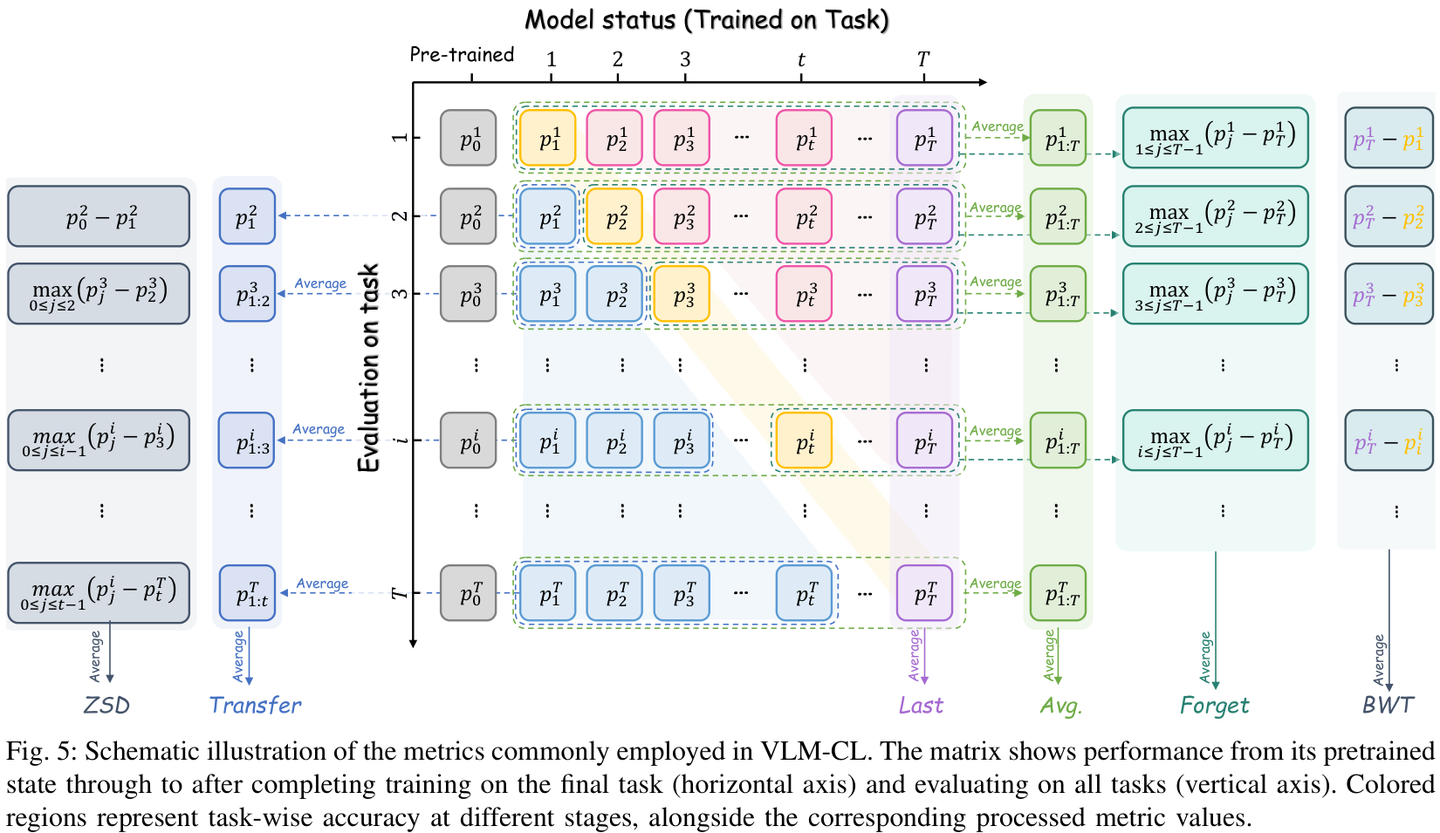
GitHub - YuyangSunshine/Awesome-Continual-learning-of-Vision-Language ...
【领域论文】VLM(视觉语言模型)系列论文总结 - 知乎
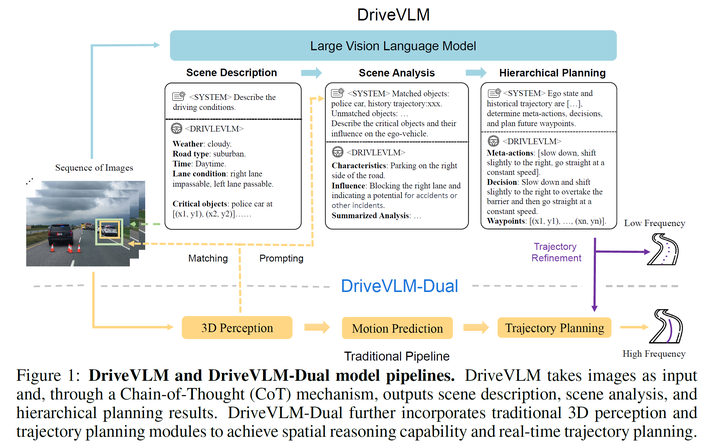
[논문 리뷰] VLM-AD: End-to-End Autonomous Driving through Vision-Language ...
Can VLMs Unlock Semantic Anomaly Detection? A Framework for Structured ...
美团/浙大提出MobileVLM | 骁龙888实时运行,边缘多模态大模型之战打响 - 智源社区
VLM-R1 (2504):R1风格强化学习视觉语言模型 - 知乎
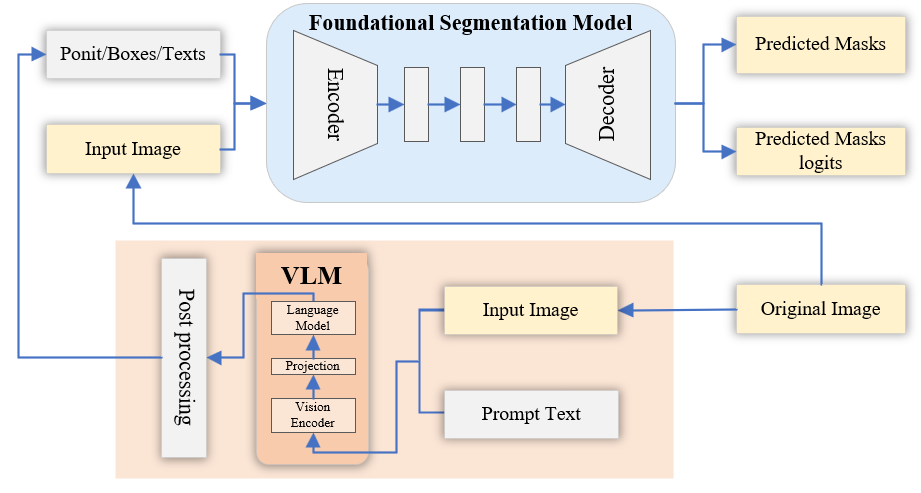
VLM与基础分割模型的联合使用_vllm怎么分割模型-CSDN博客
视觉Token如何注入语言模型?VLM拆解_vit vlm区别-CSDN博客
VLM(Vision-Language Model) 기술 현황 : CLIP에서 LLaVA까지 - Jin’s Doodle
Advancements in Vision–Language Models for Remote Sensing: Datasets ...
VLM系列文章3-VILA(On Pre-training for Visual Language Models)_vila: on pre ...
【LVLMs】F-vlm: Open-vocabulary object detection upon frozen vision and ...
VLM的“终身学习”难题:首篇系统性综述,为视觉-语言模型打破遗忘魔咒指明方向 - 知乎
[논문 리뷰] VLM-PL: Advanced Pseudo Labeling Approach for Class Incremental ...
GitHub - Amogh-Goel/lightweight-VLM-model: A lightweight Vision ...