Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
Web App for Image Captioning and Generation Using Gradio and LLMs - YouTube
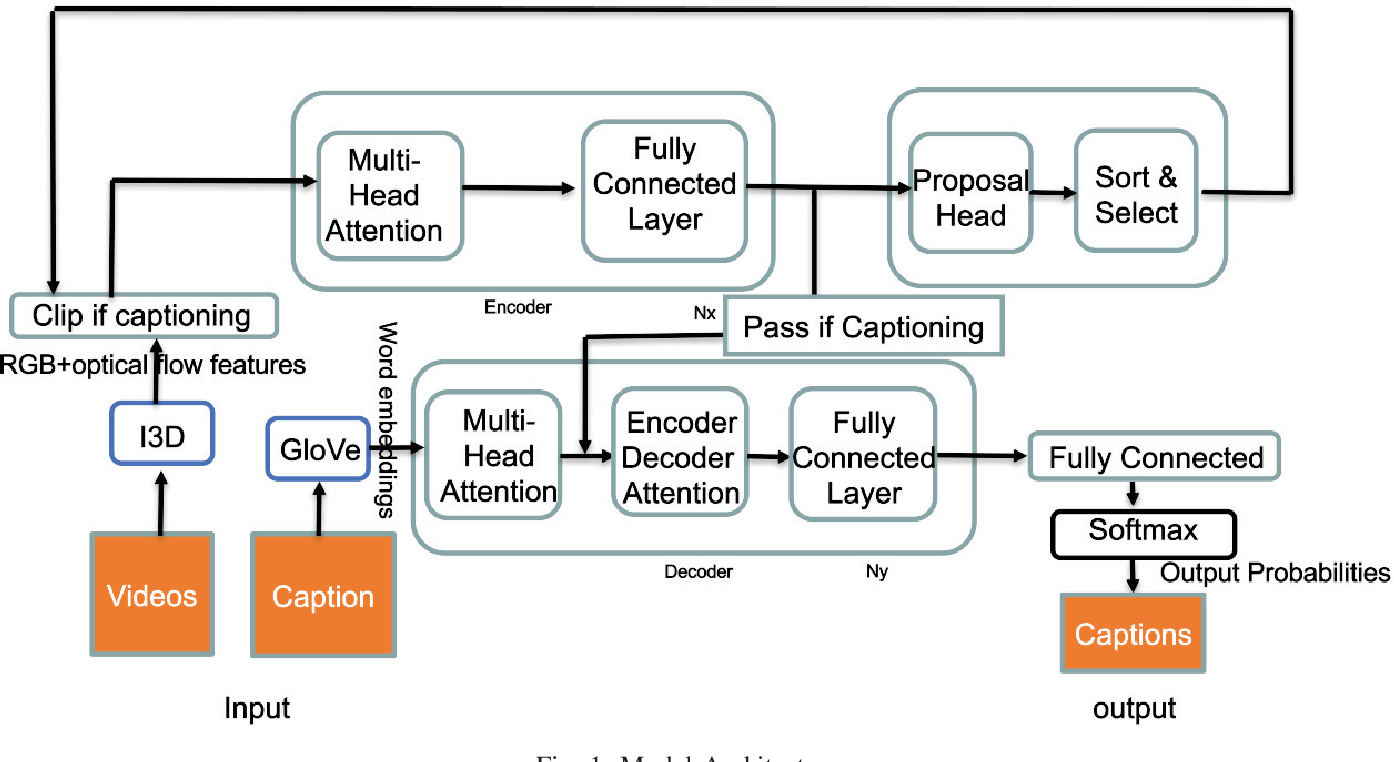
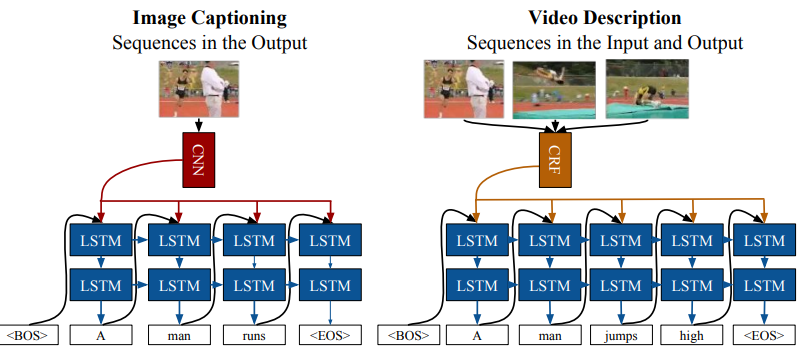
Squacc BiLSTM: a framework for dense video captioning using neural ...
Figure 1 from Video Captioning using Deep Learning and NLP to Detect ...
LAVCap: LLM-based Audio-Visual Captioning using Optimal Transport
Multi-Task Video Captioning with a Stepwise Multimodal Encoder
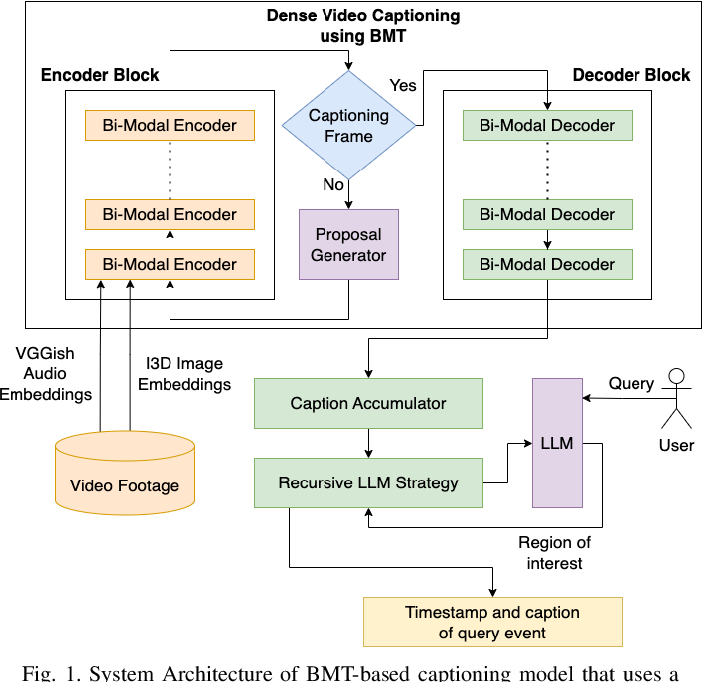
Figure 1 from Leveraging LLMs for Video Querying | Semantic Scholar
[2402.13250] Video ReCap: Recursive Captioning of Hour-Long Videos
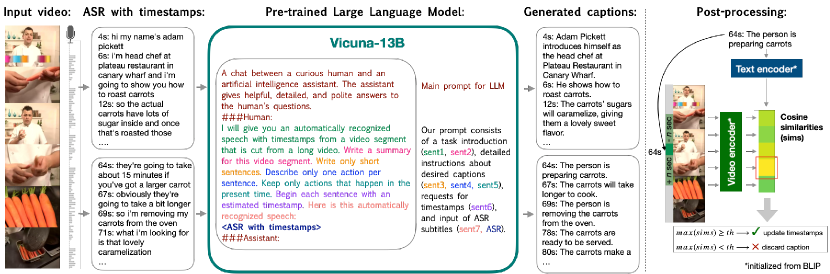
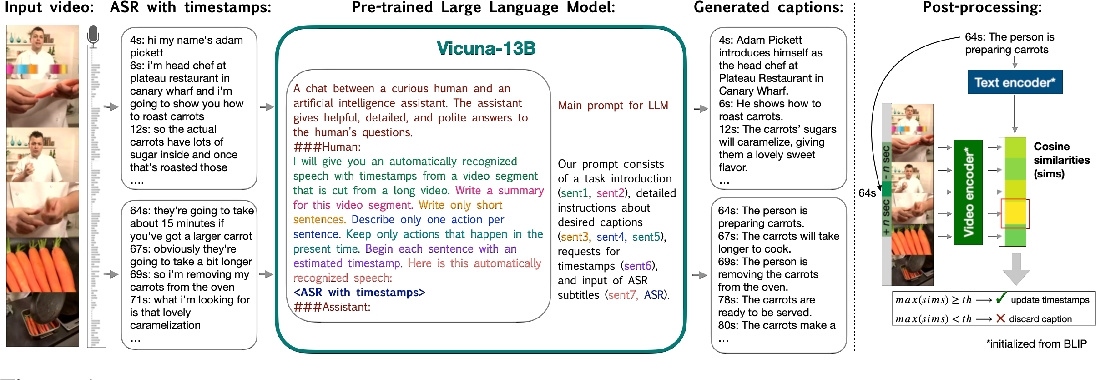
[2310.04900] HowToCaption: Prompting LLMs to Transform Video ...
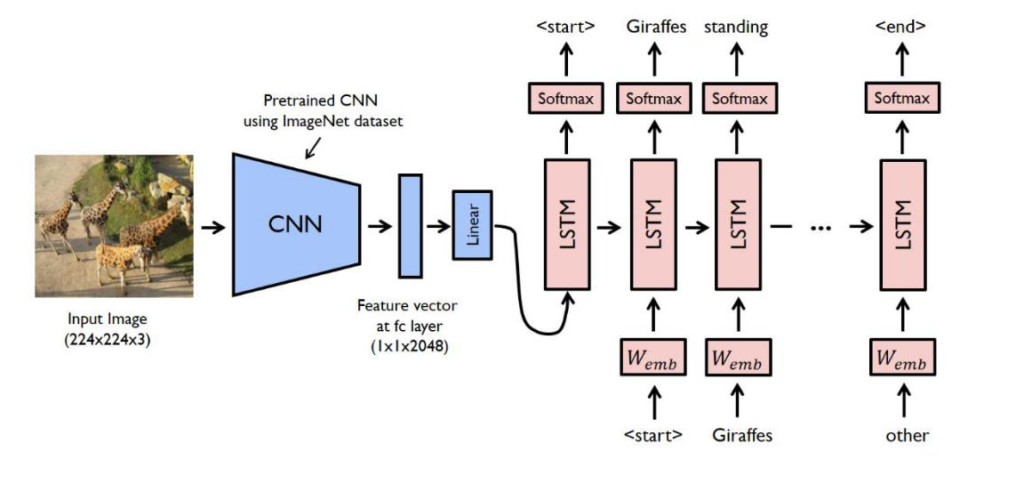
Image Captioning using Deep Learning - AI PROJECTS
Retrieval Augmented Captioning with LLMs
[论文评述] VideoCap-R1: Enhancing MLLMs for Video Captioning via Structured ...
Figure 1 from HowToCaption: Prompting LLMs to Transform Video ...
GitHub - DavidMChan/caption-by-committee: Using LLMs and pre-trained ...
(PDF) VideoCap-R1: Enhancing MLLMs for Video Captioning via Structured ...
[논문 리뷰] Image Captioning Evaluation in the Age of Multimodal LLMs ...
Empowering Video Translation using Multimodal Large Language Models
A Guide to Using LLMs for Customer Support Solutions
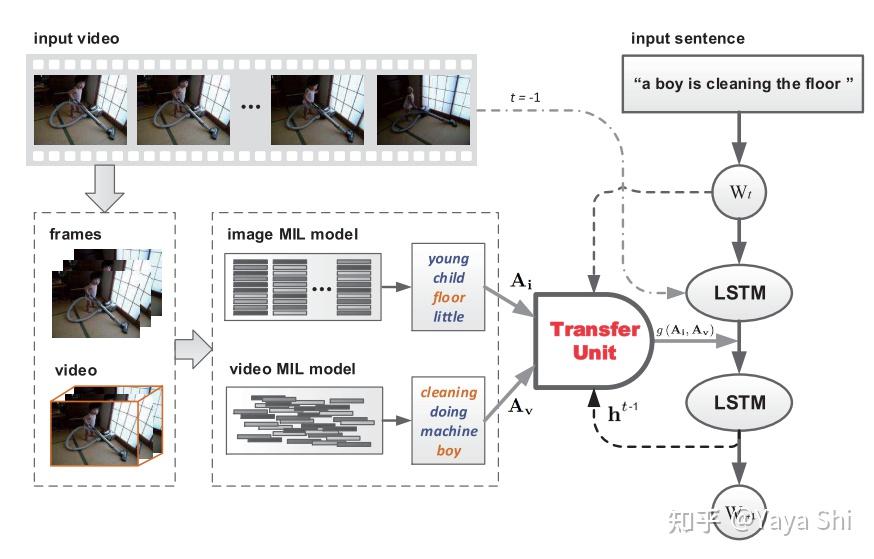
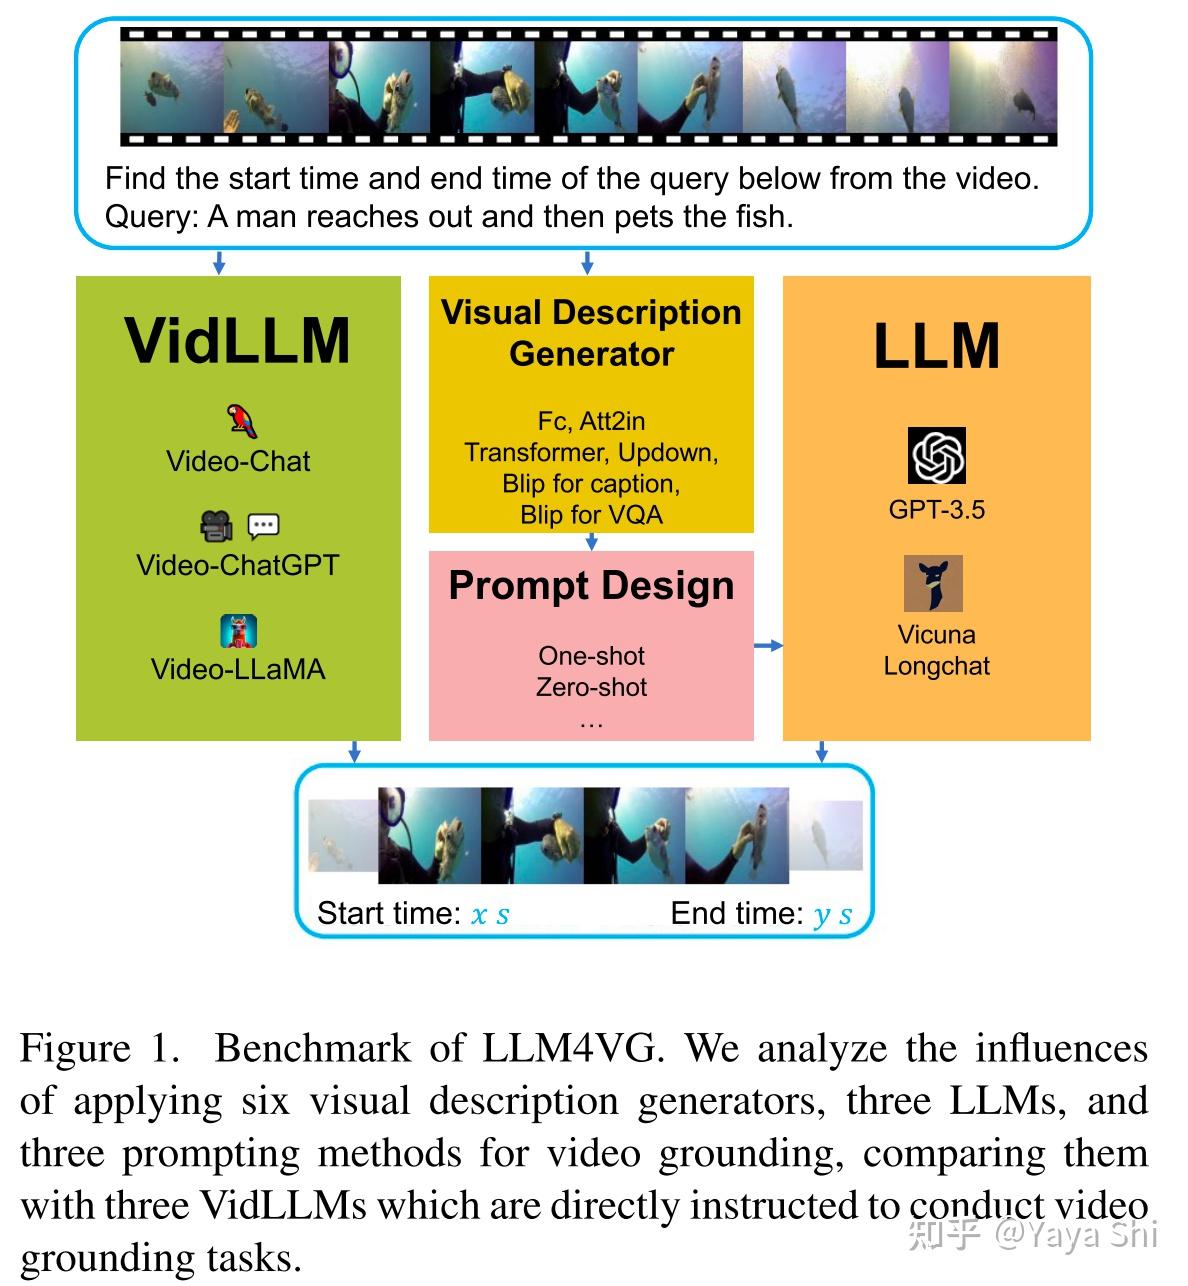
Video Captioning 总结与展望 - 知乎
LLMs Based Image Captioning by Ghaith Alsahli on Prezi
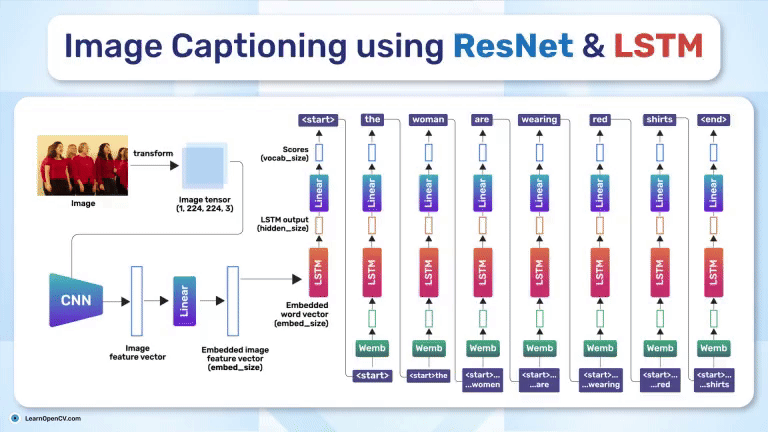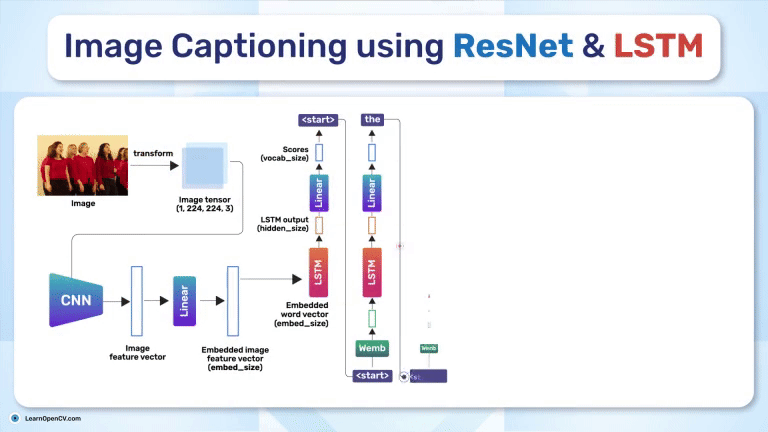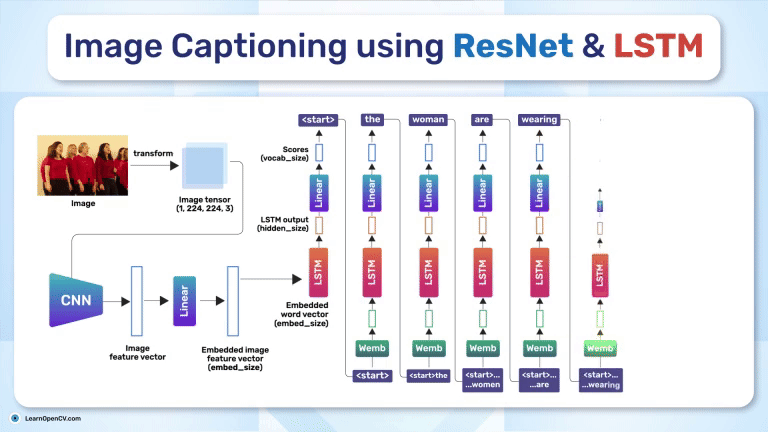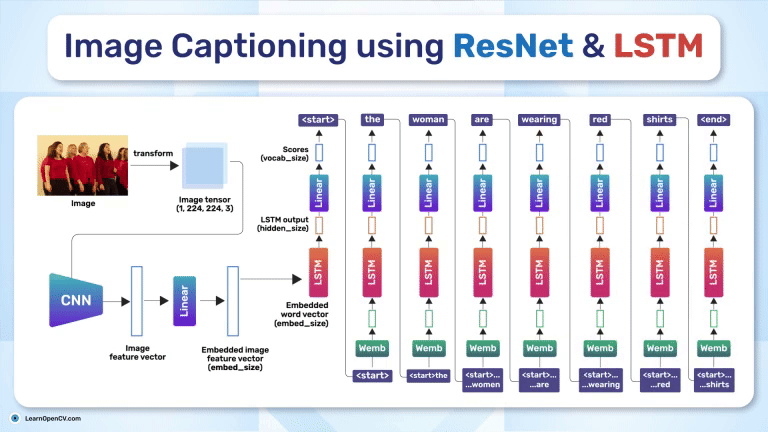
Image Captioning using ResNet and LSTM
[2402.13546] LLMs Meet Long Video: Advancing Long Video Comprehension ...
Free Video: Multi-Modal LLMs for Image, Sound and Video - Episode 6.3 ...
Using LLMs as Context-Aware Text Embedding Models - NV-Embed Paper Review
Super excited that our automatic caption generation tool using LLMs is ...
Video LLMs 相关的评测数据集 - 知乎
LifelongMemory: Leveraging LLMs for Answering Queries in Long-form ...
Video Summarization with Large Language Models
[論文レビュー] Enhancing Multimodal LLM for Detailed and Accurate Video ...
[2404.16038] A Survey on Generative AI and LLM for Video Generation ...
SLAM-AAC: Enhancing Audio Captioning with Paraphrasing Augmentation and ...
Multi-view Captioning with Semantic Delta Re-ranking for Zero-Shot ...
Figure 2 from A Simple LLM Framework for Long-Range Video Question ...
[论文阅读]Album Storytelling with Iterative Story-aware Captioning and ...
Figure 1 from Improving Automated Audio Captioning with LLM Decoder and ...
LAMB: LLM-based Audio Captioning with Modality Gap Bridging via Cauchy ...
A Comprehensive Guide to Multimodal LLMs and How they Work
[Revisión de artículo] Multi-Modal LLM based Image Captioning in ICT ...
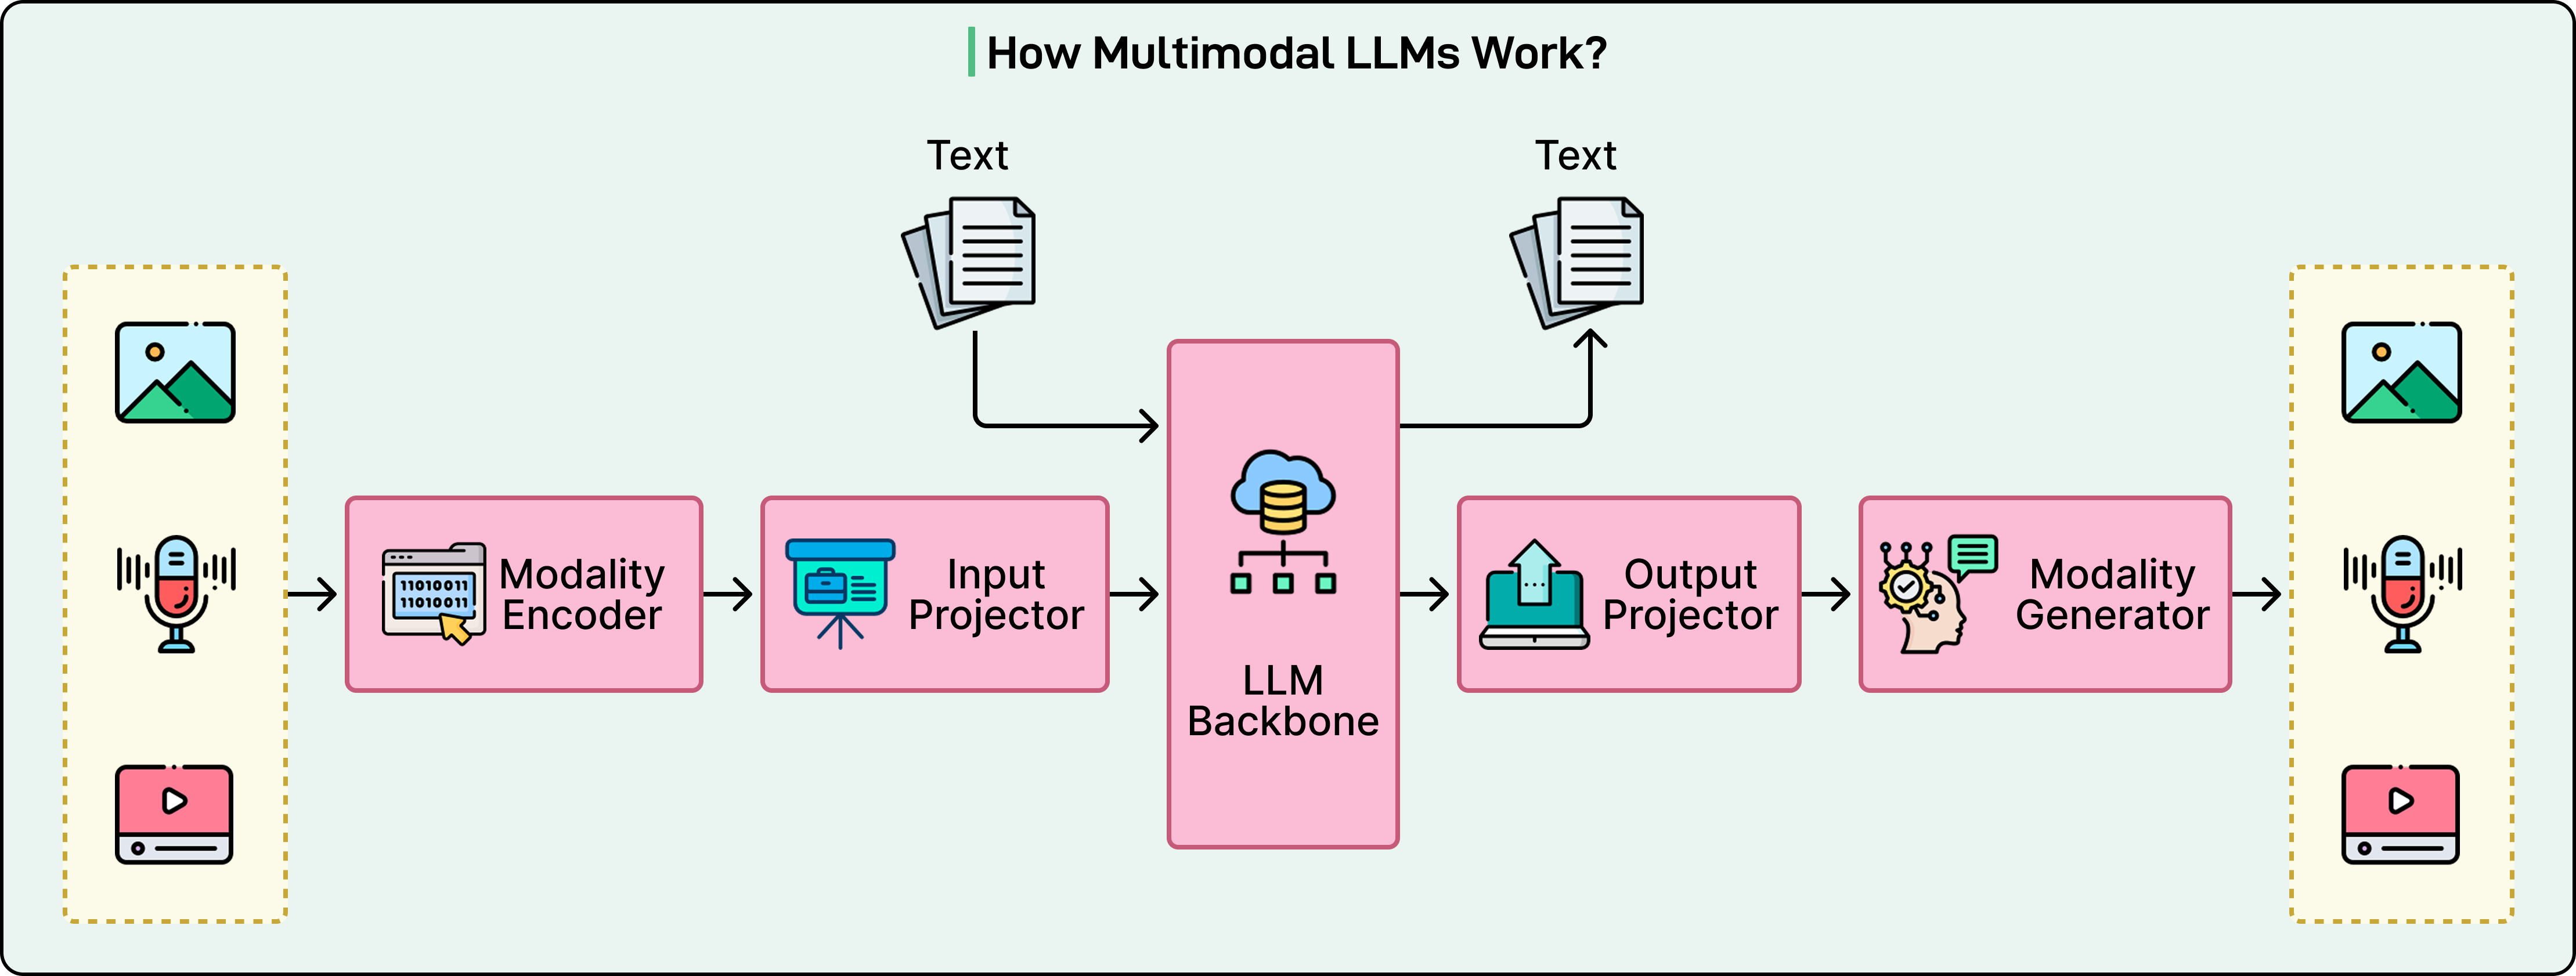
Multimodal LLMs Basics: How LLMs Process Text, Images, Audio & Videos
Multimodal Models - LLMs that can see and hear | Towards Data Science
LLMs for Accessibility Tools | AI Tutorial | Next Electronics
Image Captioning Evaluation in the Age of Multimodal LLMs: Challenges ...
Paper page - LP-MusicCaps: LLM-Based Pseudo Music Captioning
Figure 1 from Less for More: Enhanced Feedback-aligned Mixed LLMs for ...
(PDF) From Alt-text to Real Context: Revolutionizing image captioning ...
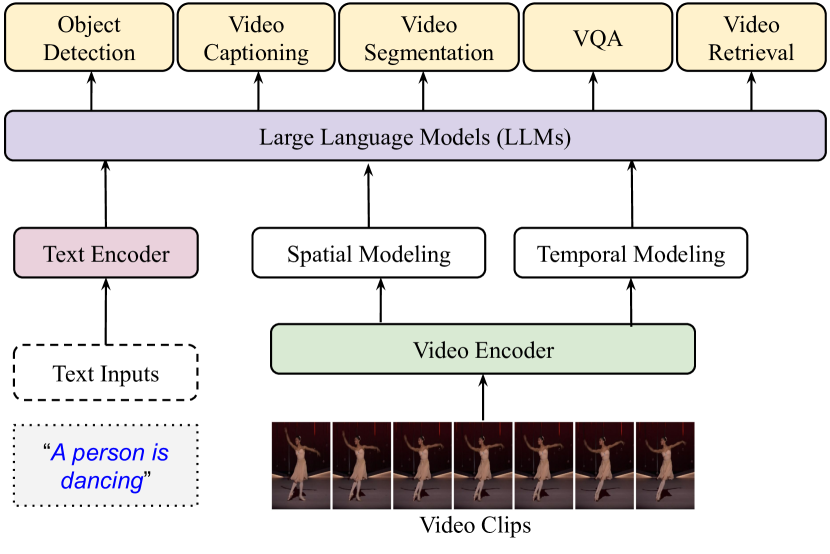
Multimodal Large Language Models for Video Understanding | SpringerLink
Understanding Multimodal LLMs
VCR: Video representation for Contextual Retrieval
Figure 2 from A Framework for Accurate and Efficient Image Captioning ...
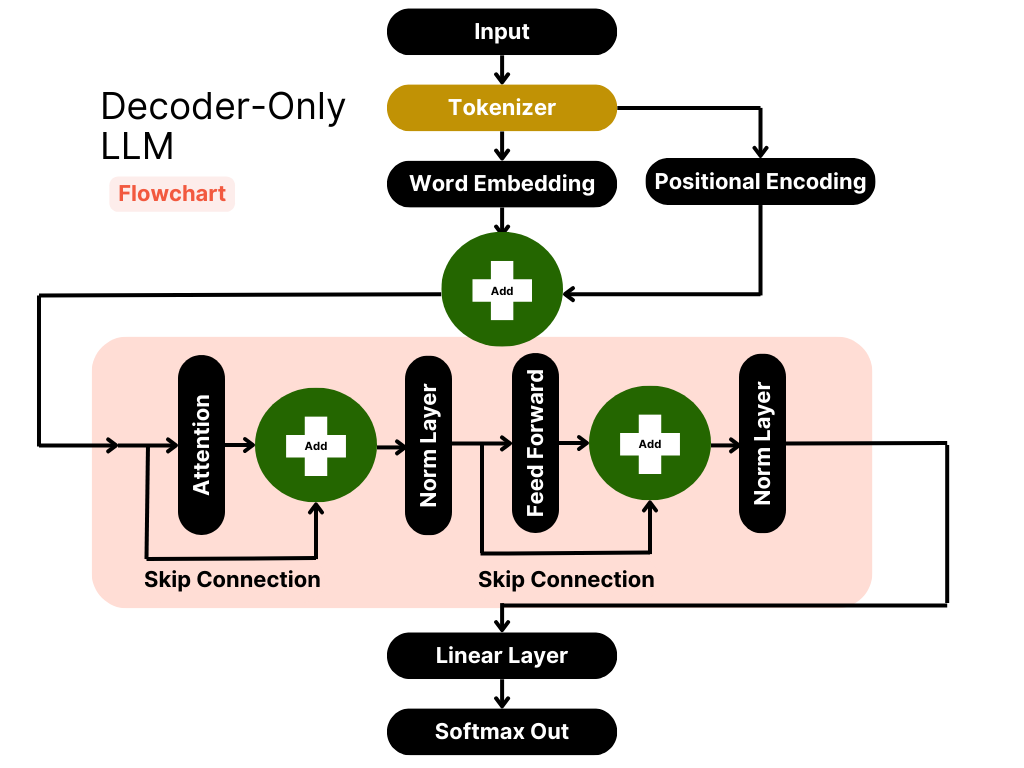
Understanding Encoder And Decoder LLMs
Understanding the Various Types of LLMs & Their Applications
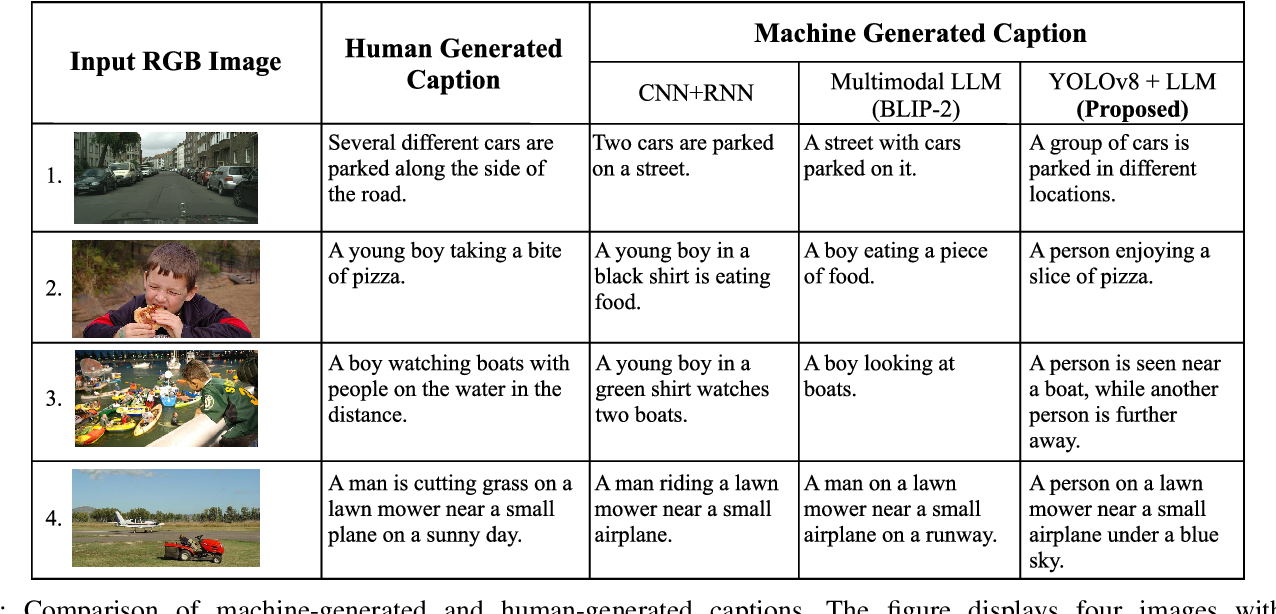
Multi-Modal LLM based Image Captioning in ICT: Bridging the Gap Between ...
Enhancing LLMs with Vector Database with real-world examples | JFrog ML
Customized Visual Storytelling with Unified Multimodal LLMs
OpenVoxel: Training-Free Grouping and Captioning Voxels for Open ...
Understanding and Coding the KV Cache in LLMs from Scratch
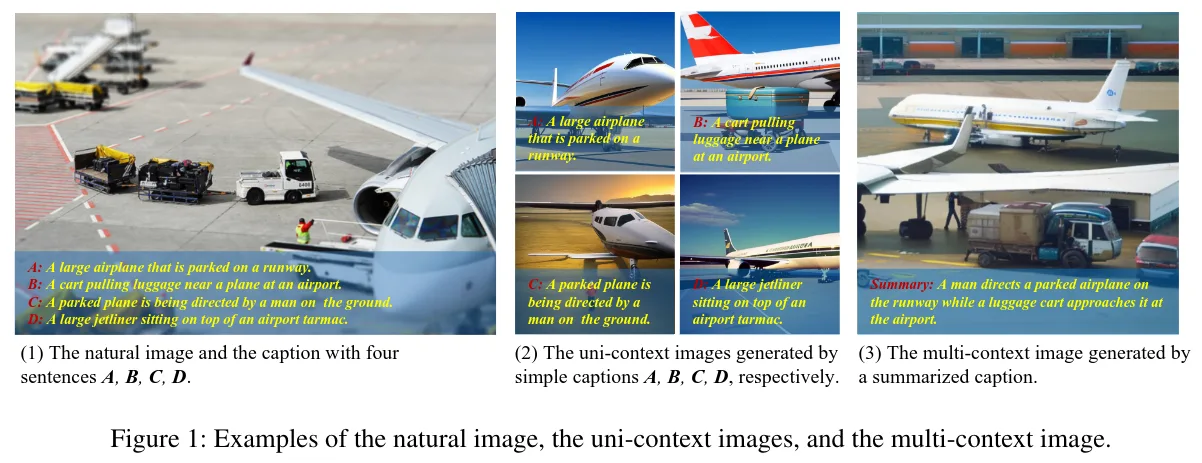
LLMs Learn to Caption Images, Video, and Audio Without Further Training ...
Train LLMs to Understand Beyond Text - Yan Lin's Blog
How Multimodal LLMs Actually Work: Part 1 — Foundations and Vision ...
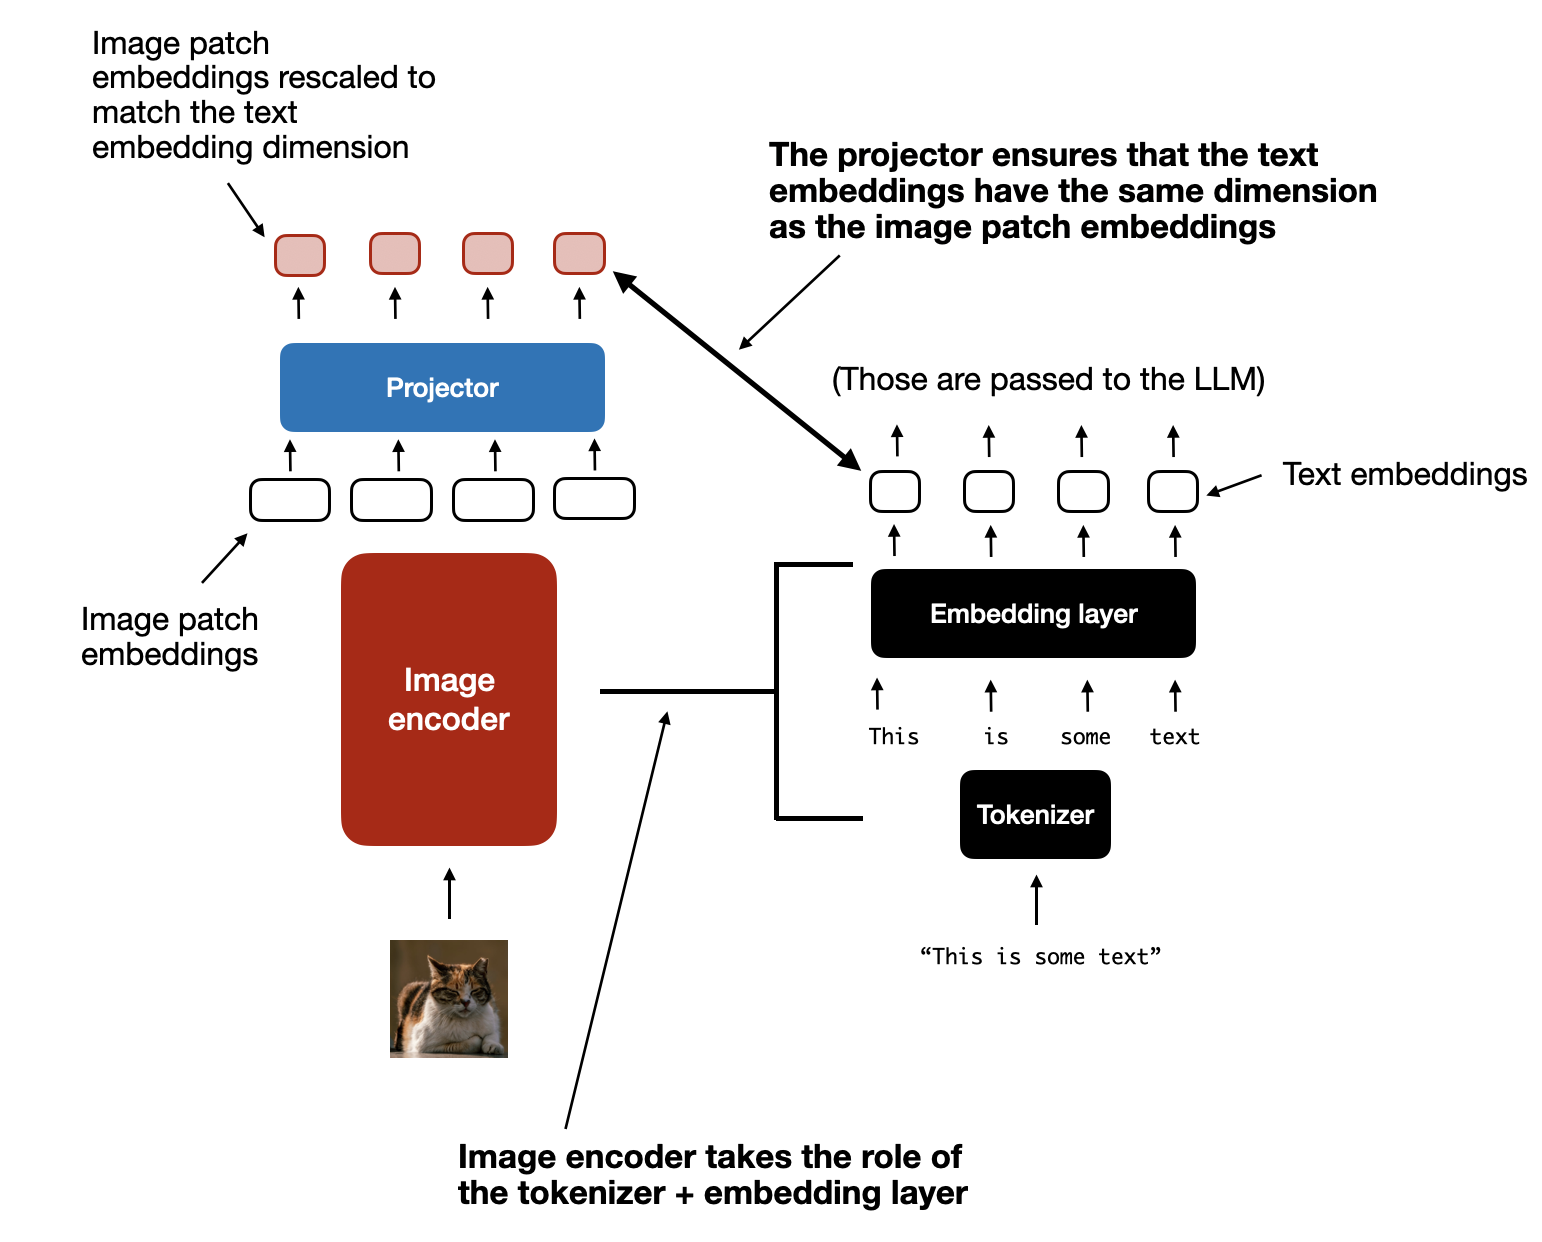
Understanding Multimodal LLMs - by Sebastian Raschka, PhD
(PDF) LP-MusicCaps: LLM-Based Pseudo Music Captioning
Funcionamento dos LLMs e Machine Unlearning - Data Science Academy
Empowering AI with Senses: A Journey into Multimodal LLMs Part 1
An overall taxonomy of deep learning-based visual captioning | Download ...
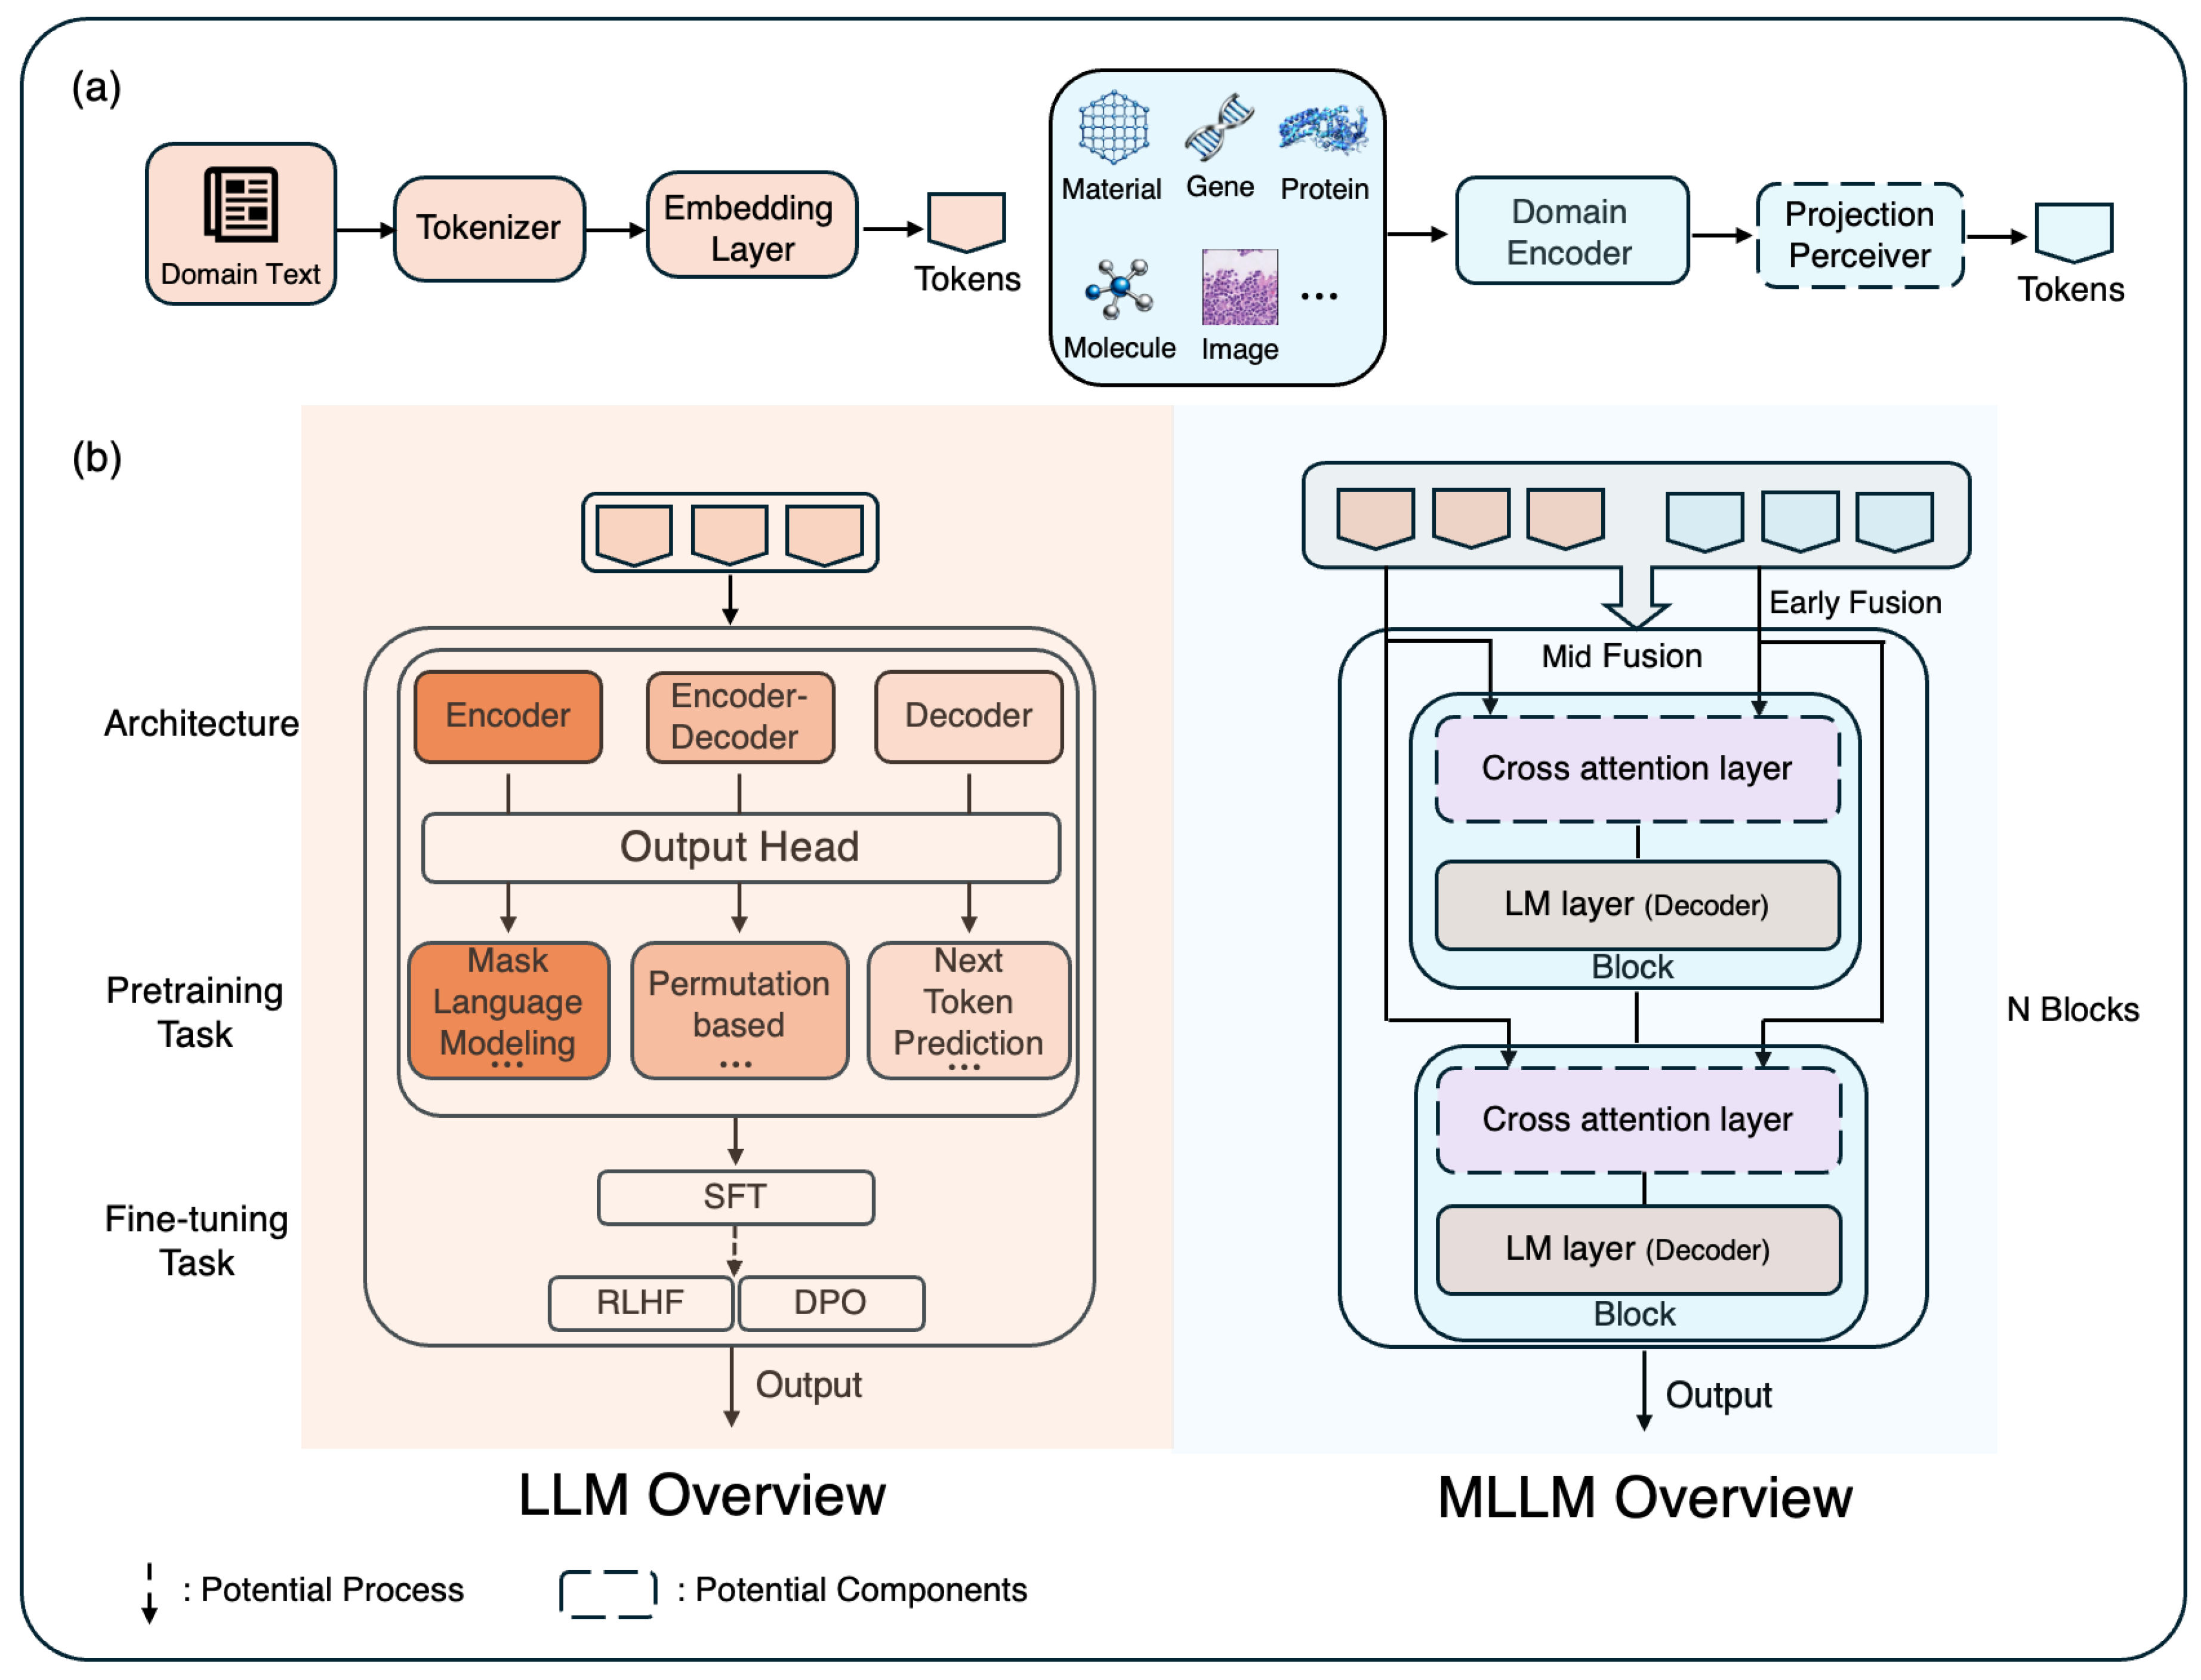
A Comprehensive Survey of Multimodal LLMs for Scientific Discovery[v1 ...
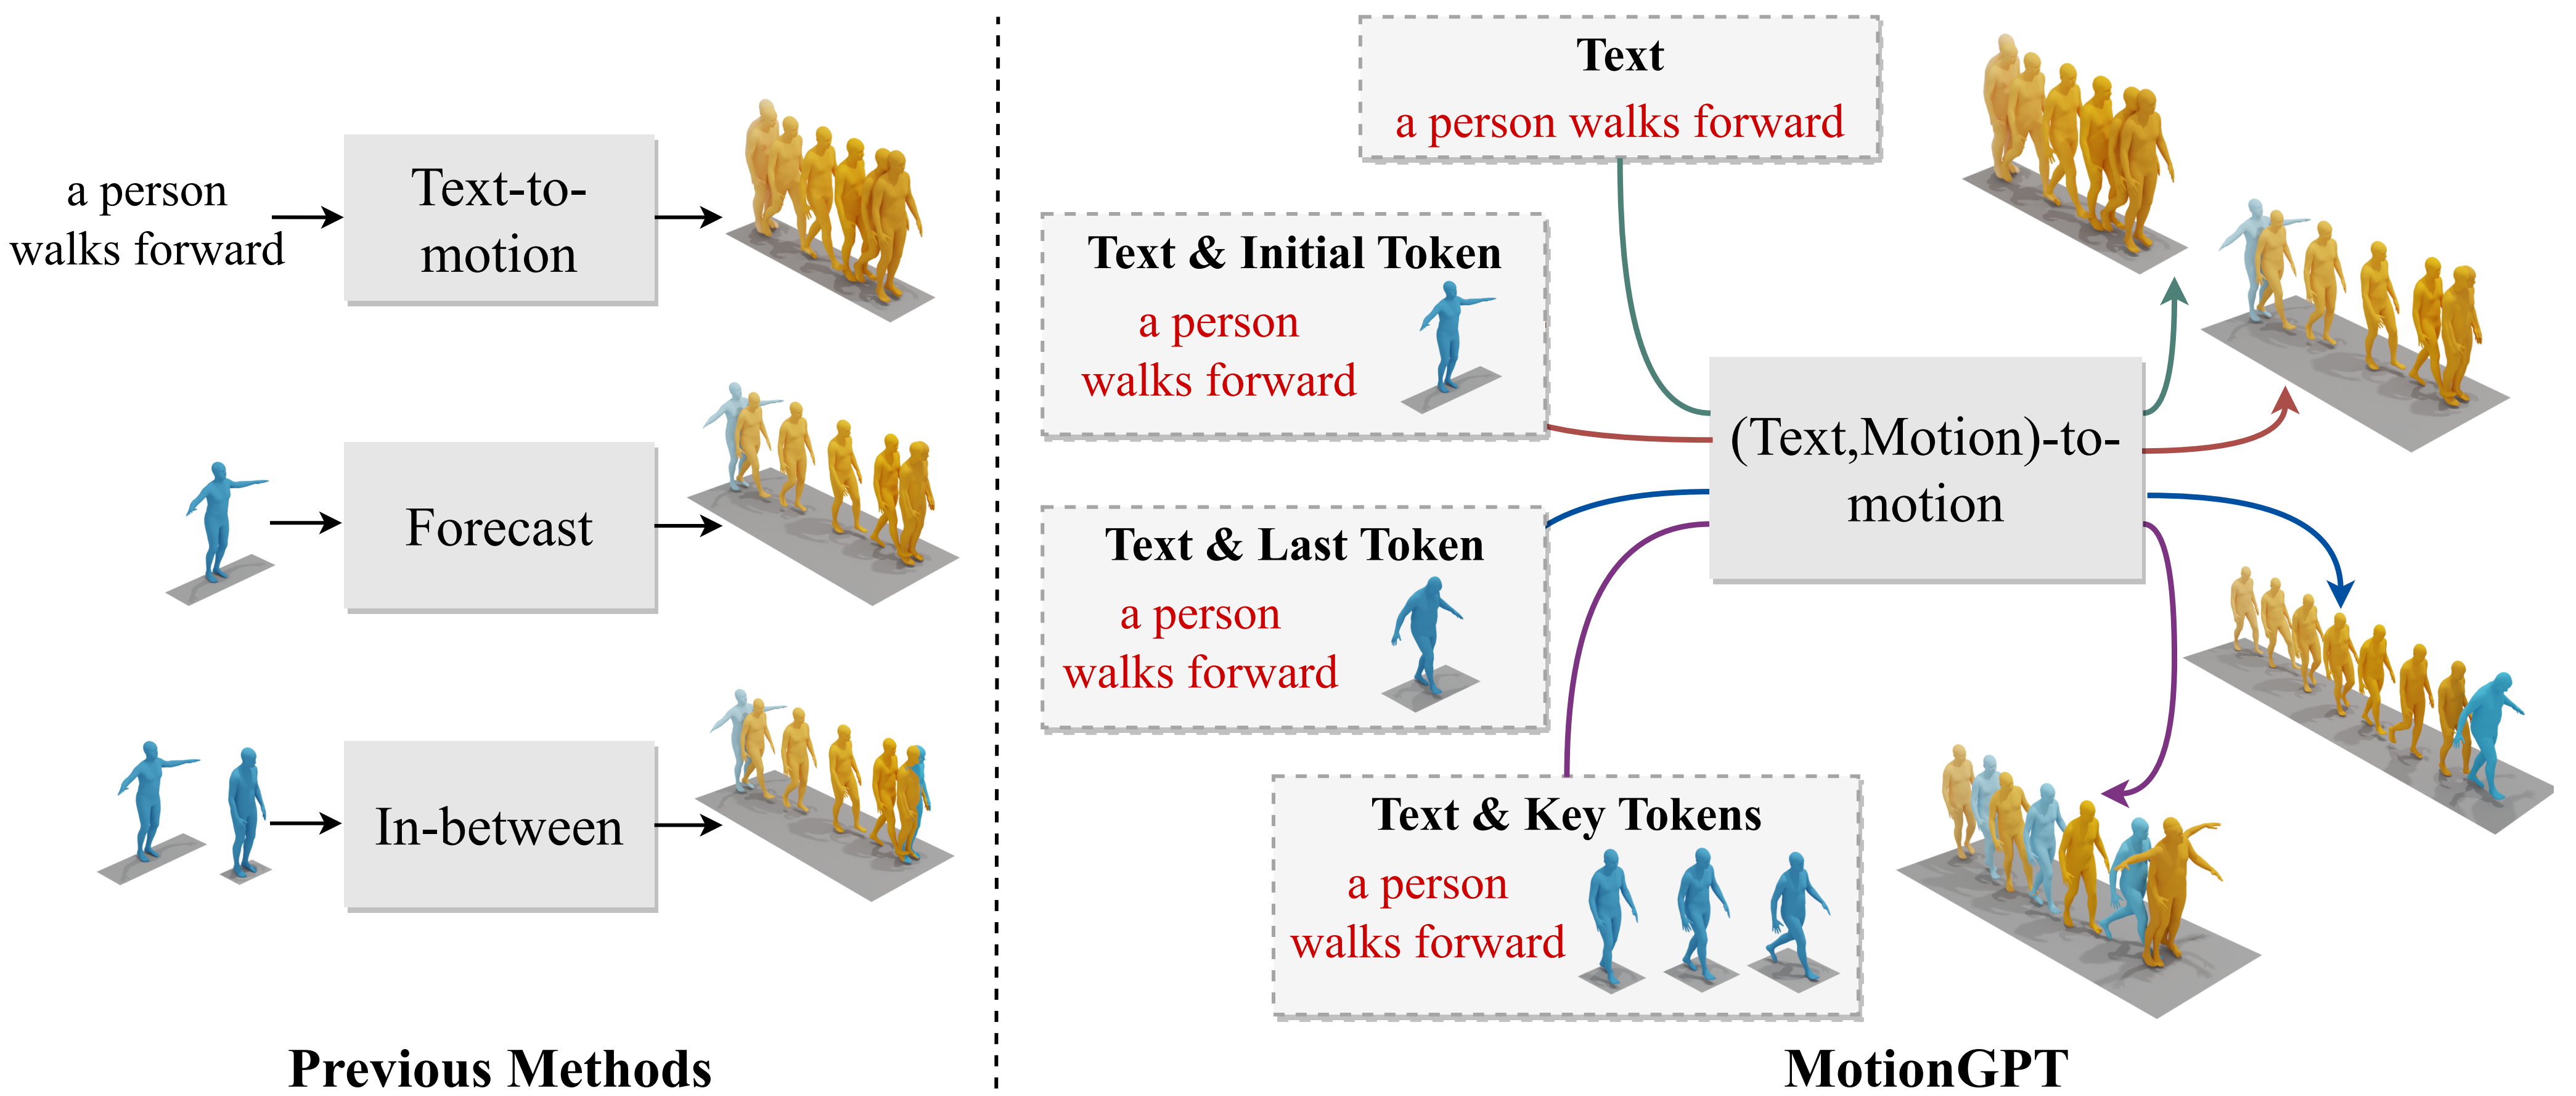
MotionGPT: Finetuned LLMs are General-Purpose Motion Generators
LLM Training and Applications: LLMs are trained on a corpus (large ...
Template Based Image Captioning – UOPRY
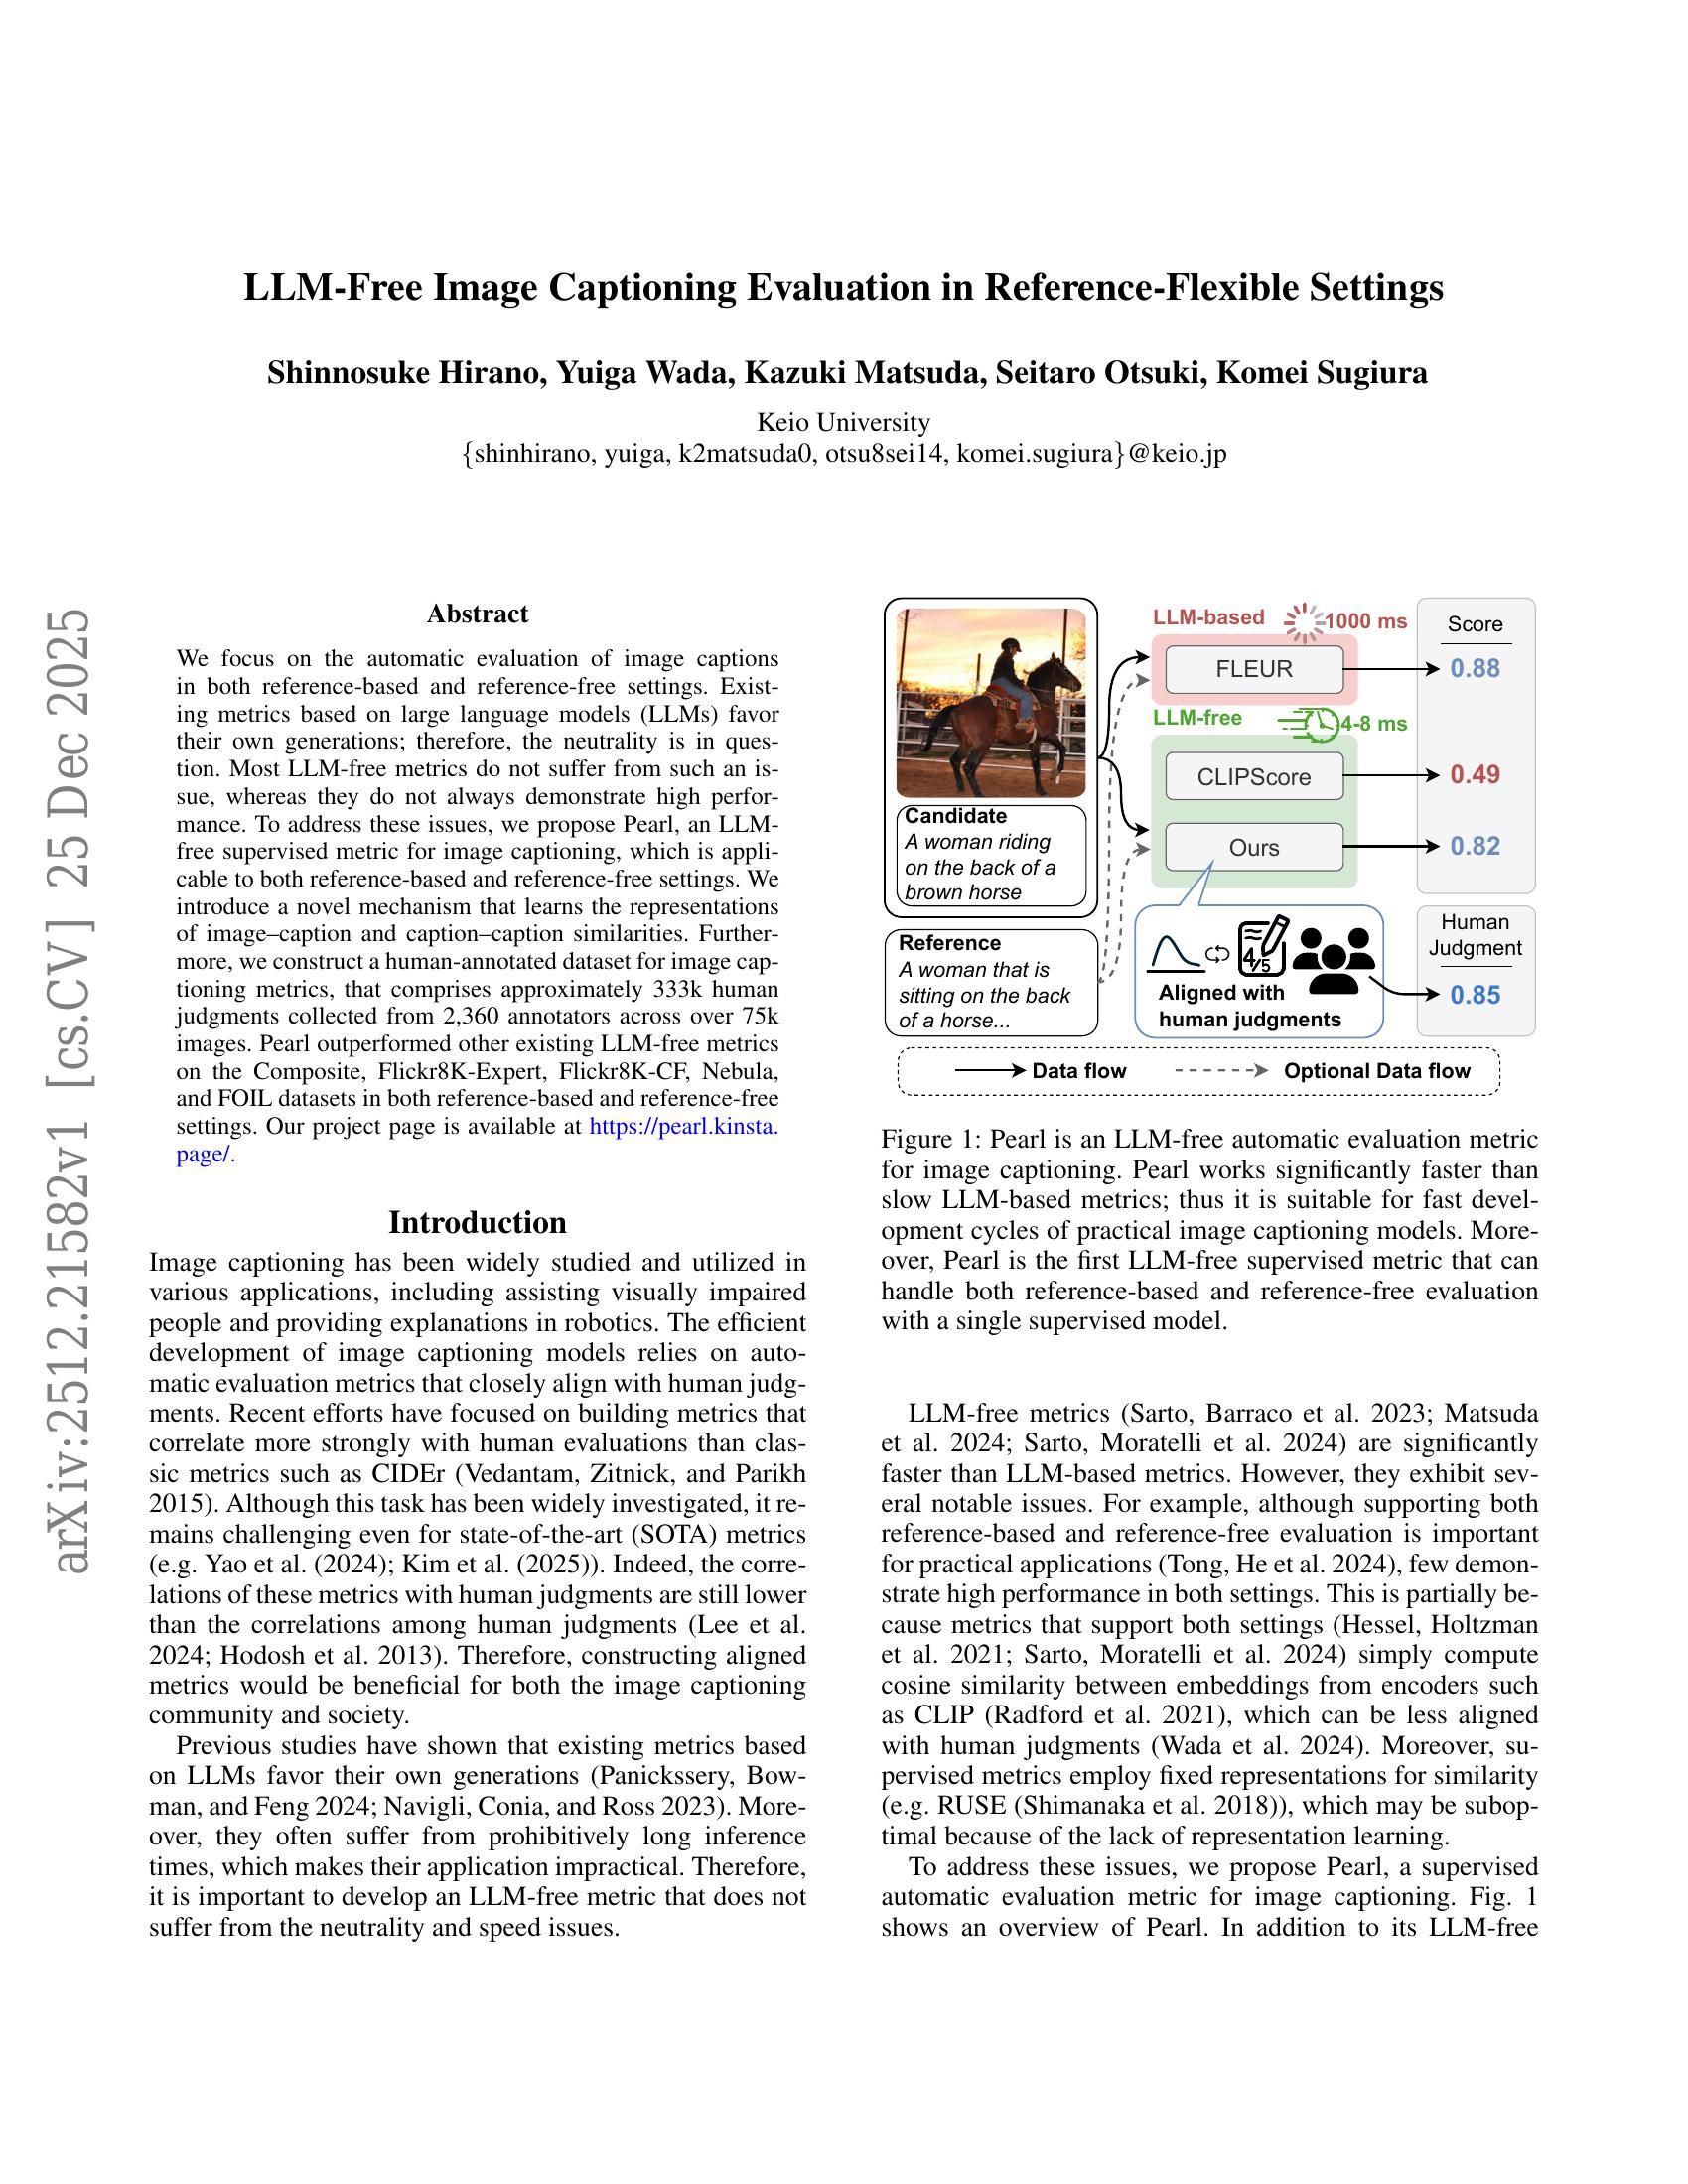
LLM-Free Image Captioning Evaluation in Reference-Flexible Settings - 智 ...
NVIDIA AI Releases Describe Anything 3B: A Multimodal LLM for Fine ...
[论文评述] Personalizing Multimodal Large Language Models for Image ...
Describing Land Cover Changes via Multi-Temporal Remote Sensing Image ...
GitHub - Pavansomisetty21/Image-Caption-Generation-using-LLMs-GEMINI ...
Figure 1 from Enhancing Journalism with AI: A Study of Contextualized ...
Jongmin Choi
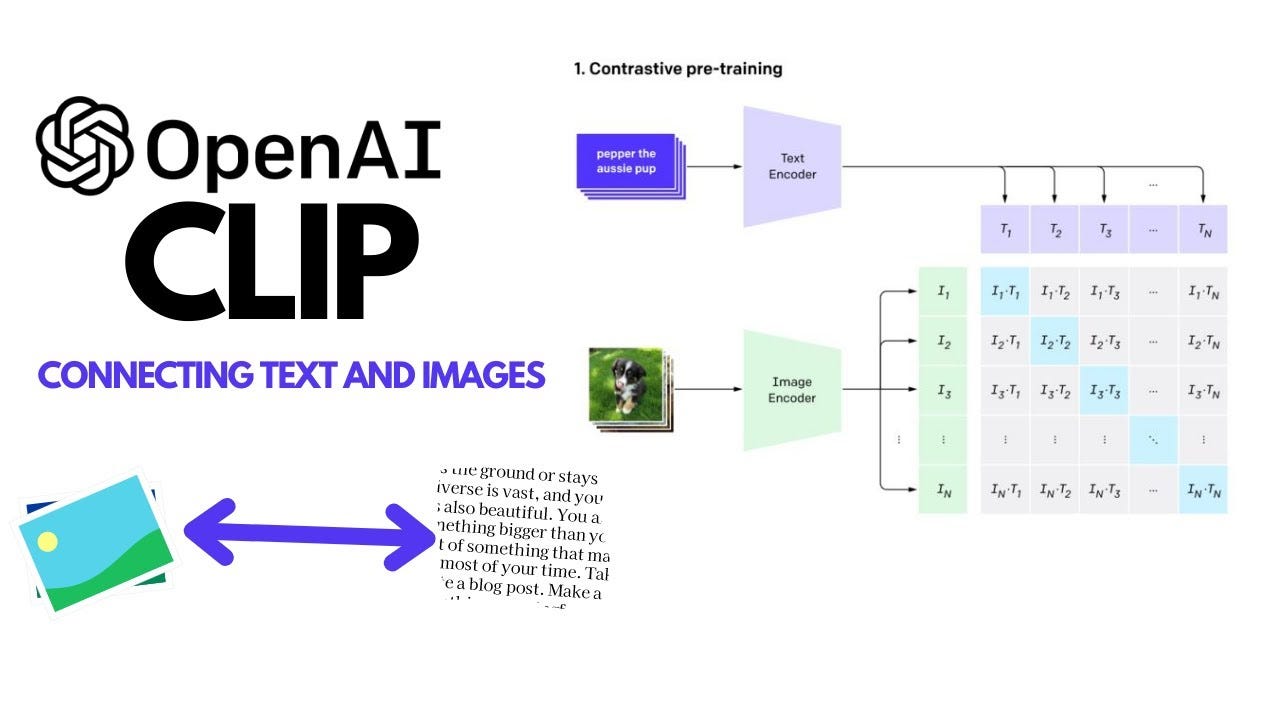
Supercharging CLIP with LLMs: A New Era for Multimodal AI
image caption 必看论文,模型整理_image caption模型代码github-CSDN博客
How Does A Multimodal LLM Work? The Vision Story
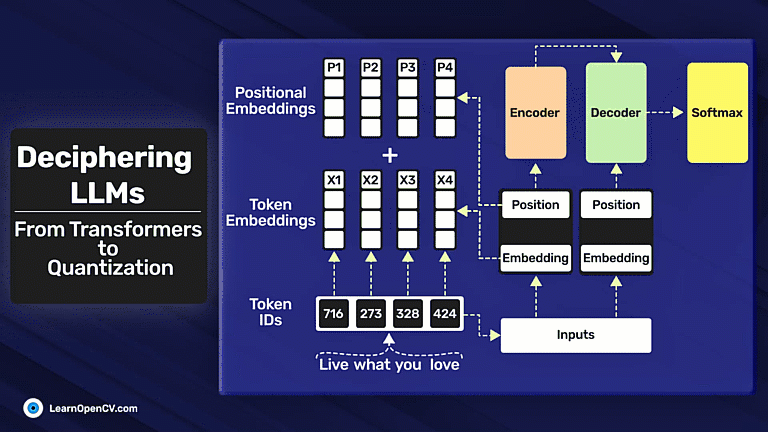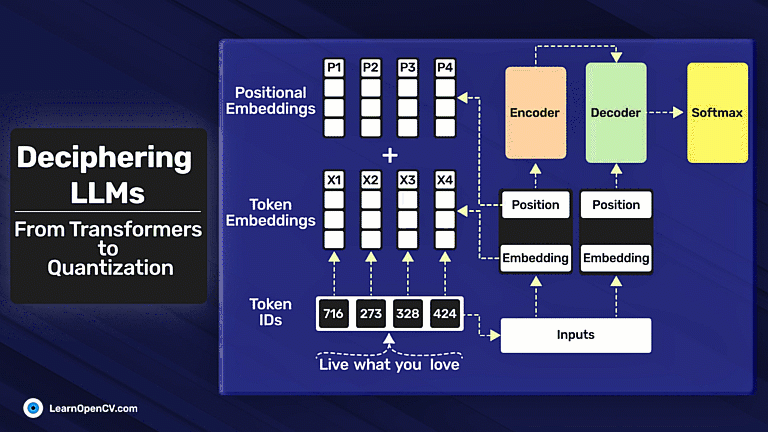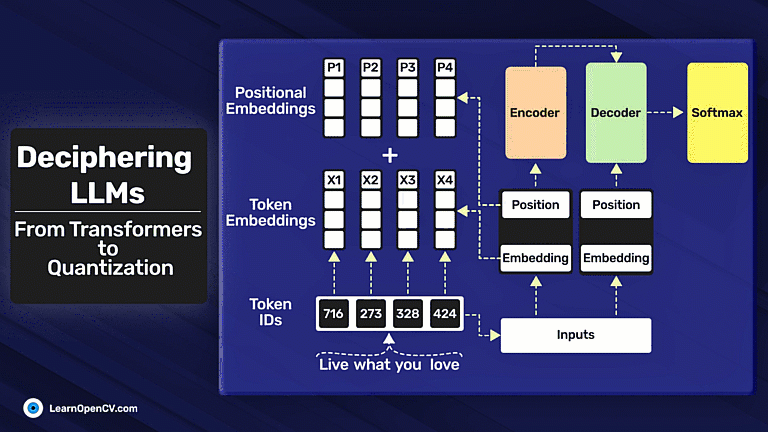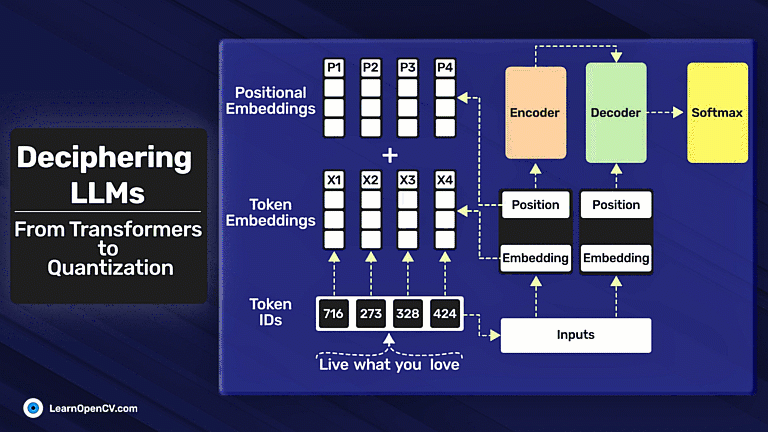
deciphering-llms-feautured-image | LearnOpenCV
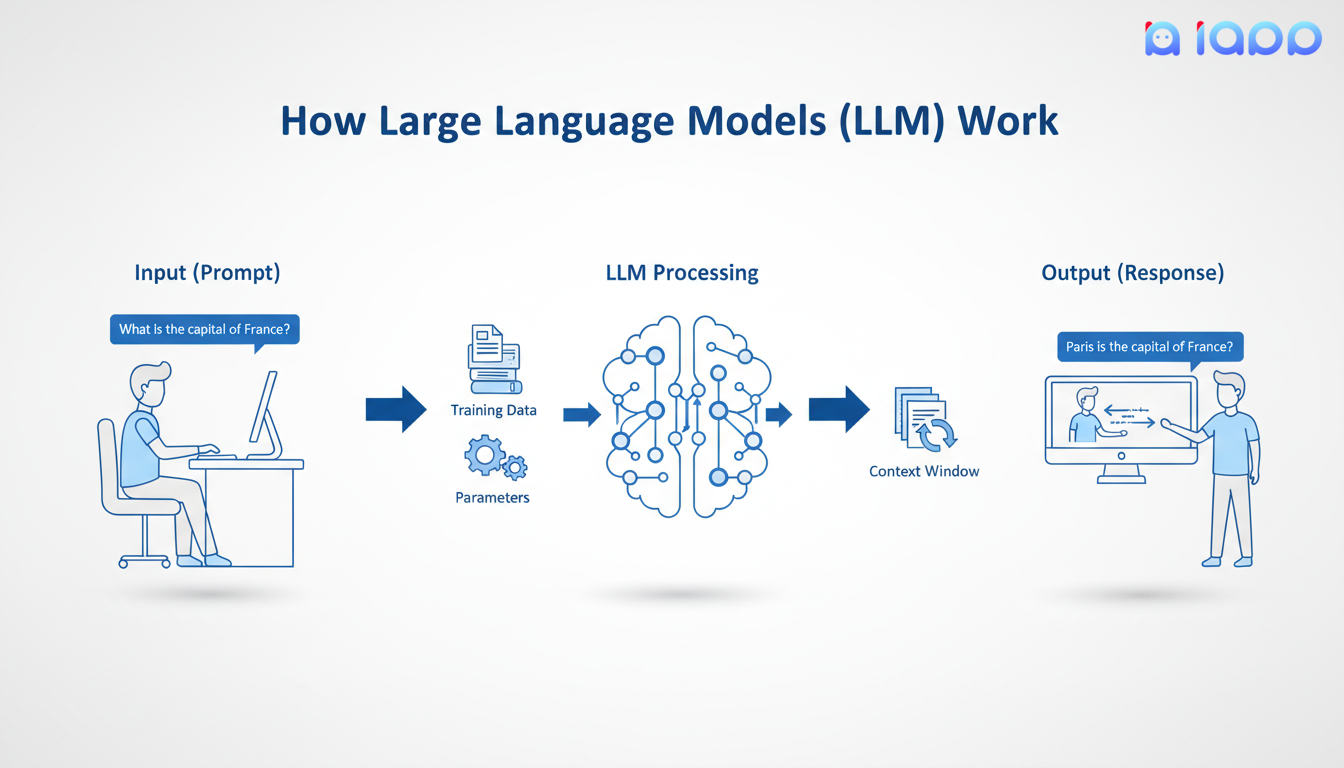
3 posts tagged with "Tutorial" | iApp Technology
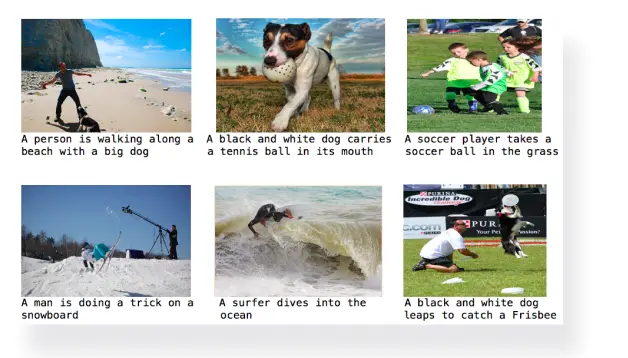
LLM-Powered Image Captioning: Challenges & Applications
[논문 리뷰] Mastering Text-to-Image Diffusion: Recaptioning, Planning, and ...
Which Off-the-Shelf LLM Is Best for Image Captioning? | Sama
Personalizing LLM Interactions: Harnessing Generative Feedback Loops ...
Multimodal LLM Study
What is a Large Language Model (LLM) - GeeksforGeeks
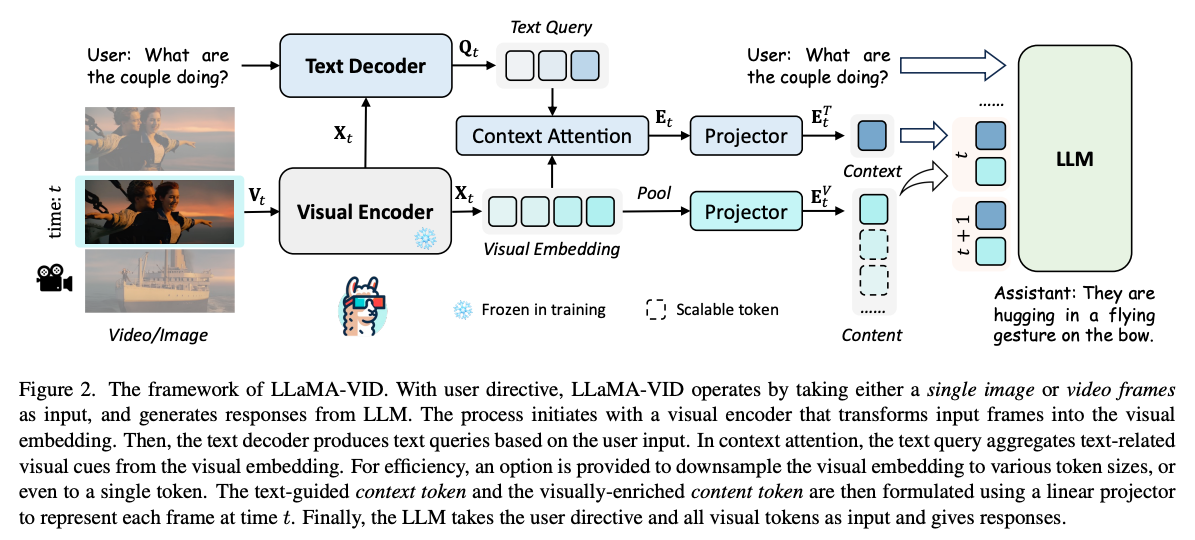
Meet Video-LLaMA: A Multi-Modal Framework that Empowers Large Language ...
[2309.03905] ImageBind-LLM: Multi-modality Instruction Tuning
LLM Chronicles
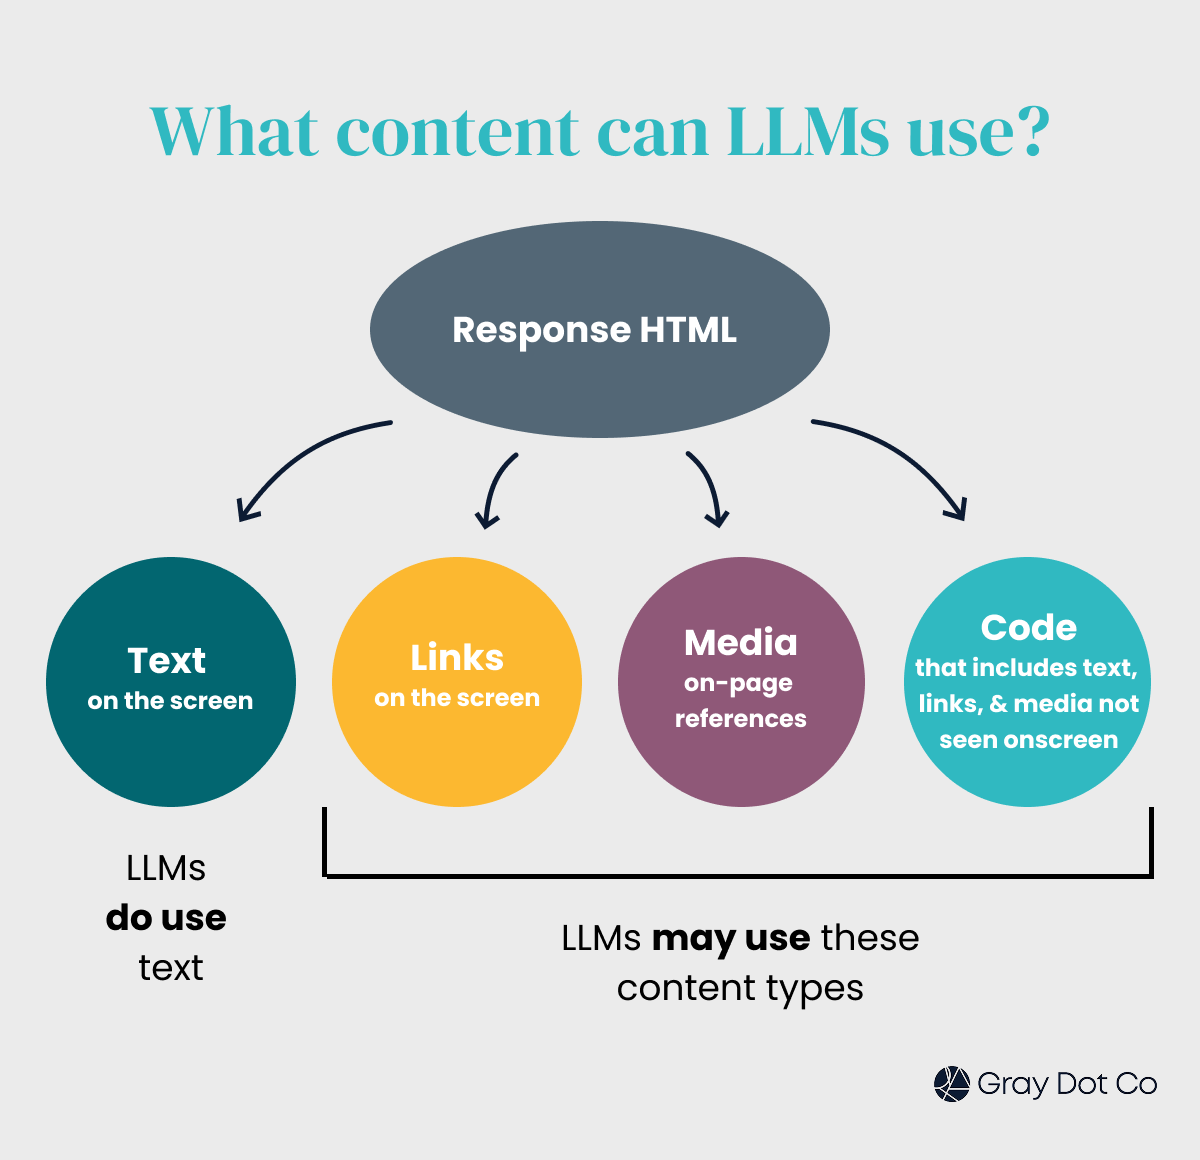
How AI Bots Crawl: Tech Auditing for LLM Visibility | Gray Dot Co
Vision-Language Models. Vision-Language Models (VLMs) feature a… | by ...
A Visual Guide to LLM Agents - by Maarten Grootendorst
Multimodal Learning - 시각적 이해를 위한 머신러닝 9
alcaitiff/LLM-CAPTION · Hugging Face
All You Need to Know about Vector Databases and How to Use Them to ...
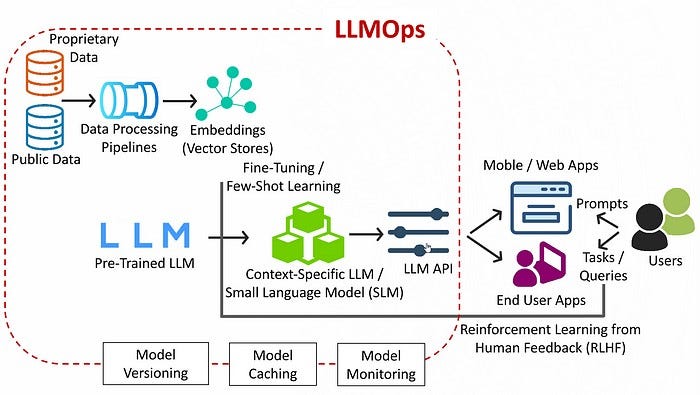
Prompt Engineering and LLMOps: Building LLM Applications
GitHub - baroodya/llm-captions: Research into the ability of Large ...
Understanding Multimodal LLMs. In this article, i aim to explain how ...
Optimizing-Multimodal-LLMs-for-Scientific-VQA-using-Caption-Aware-SFT ...
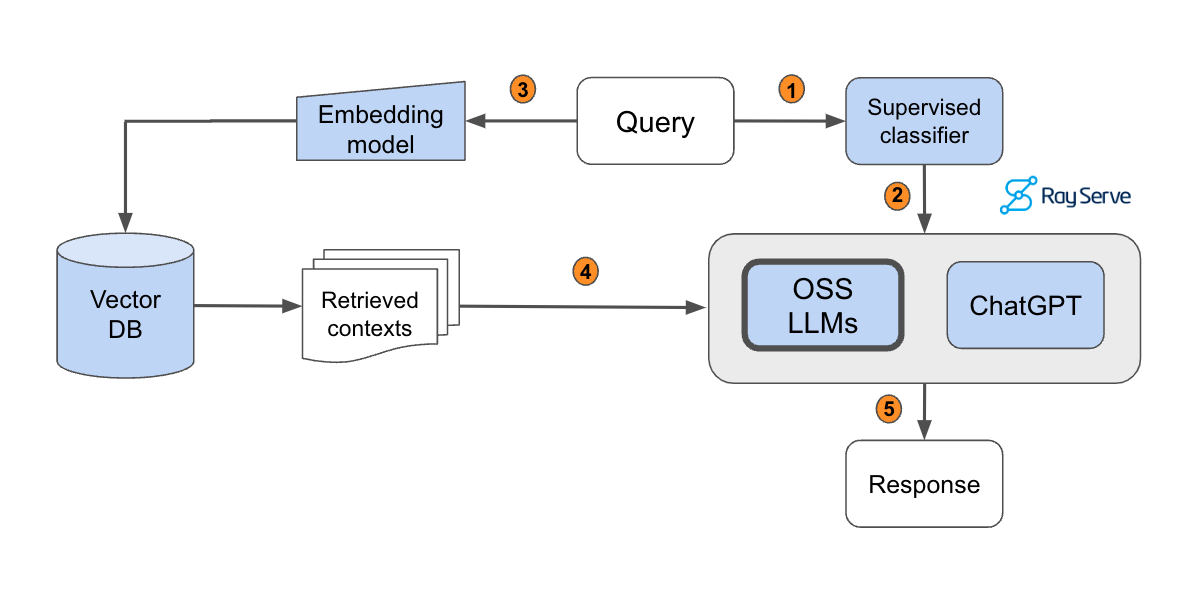
Building RAG-based LLM Applications for Production
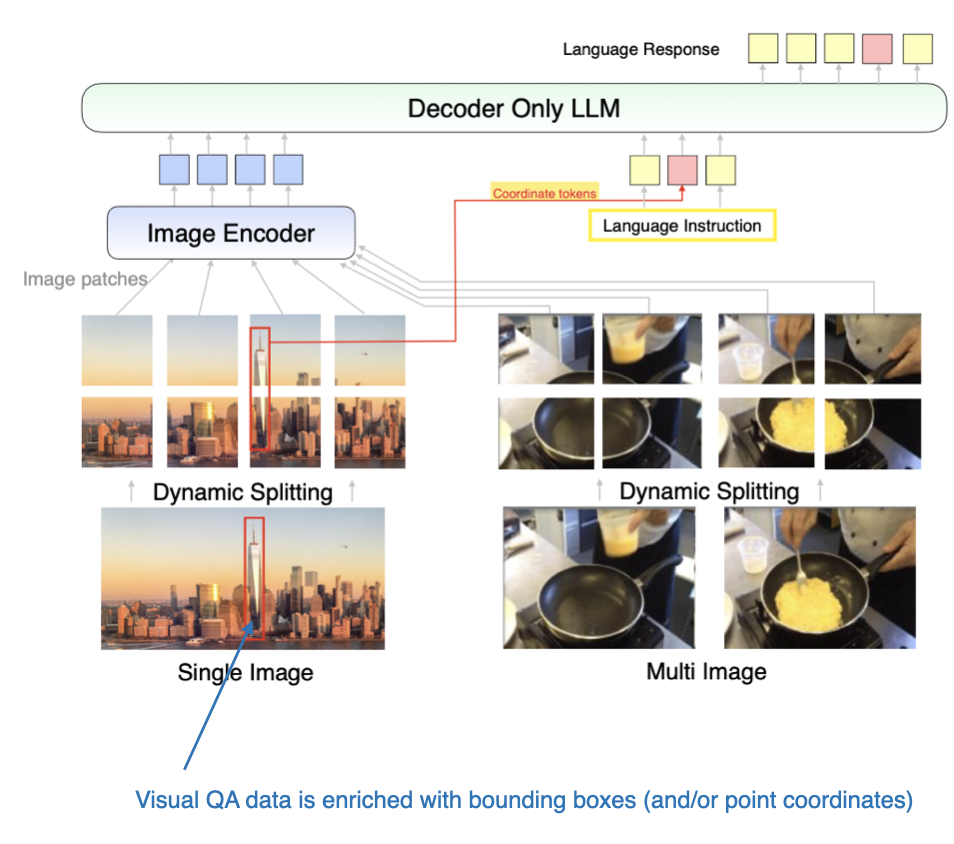
[논문 리뷰] From Image to Video, what do we need in multimodal LLMs?
Do Modern Video-LLMs Need to Listen? A Benchmark Audit and Scalable Remedy
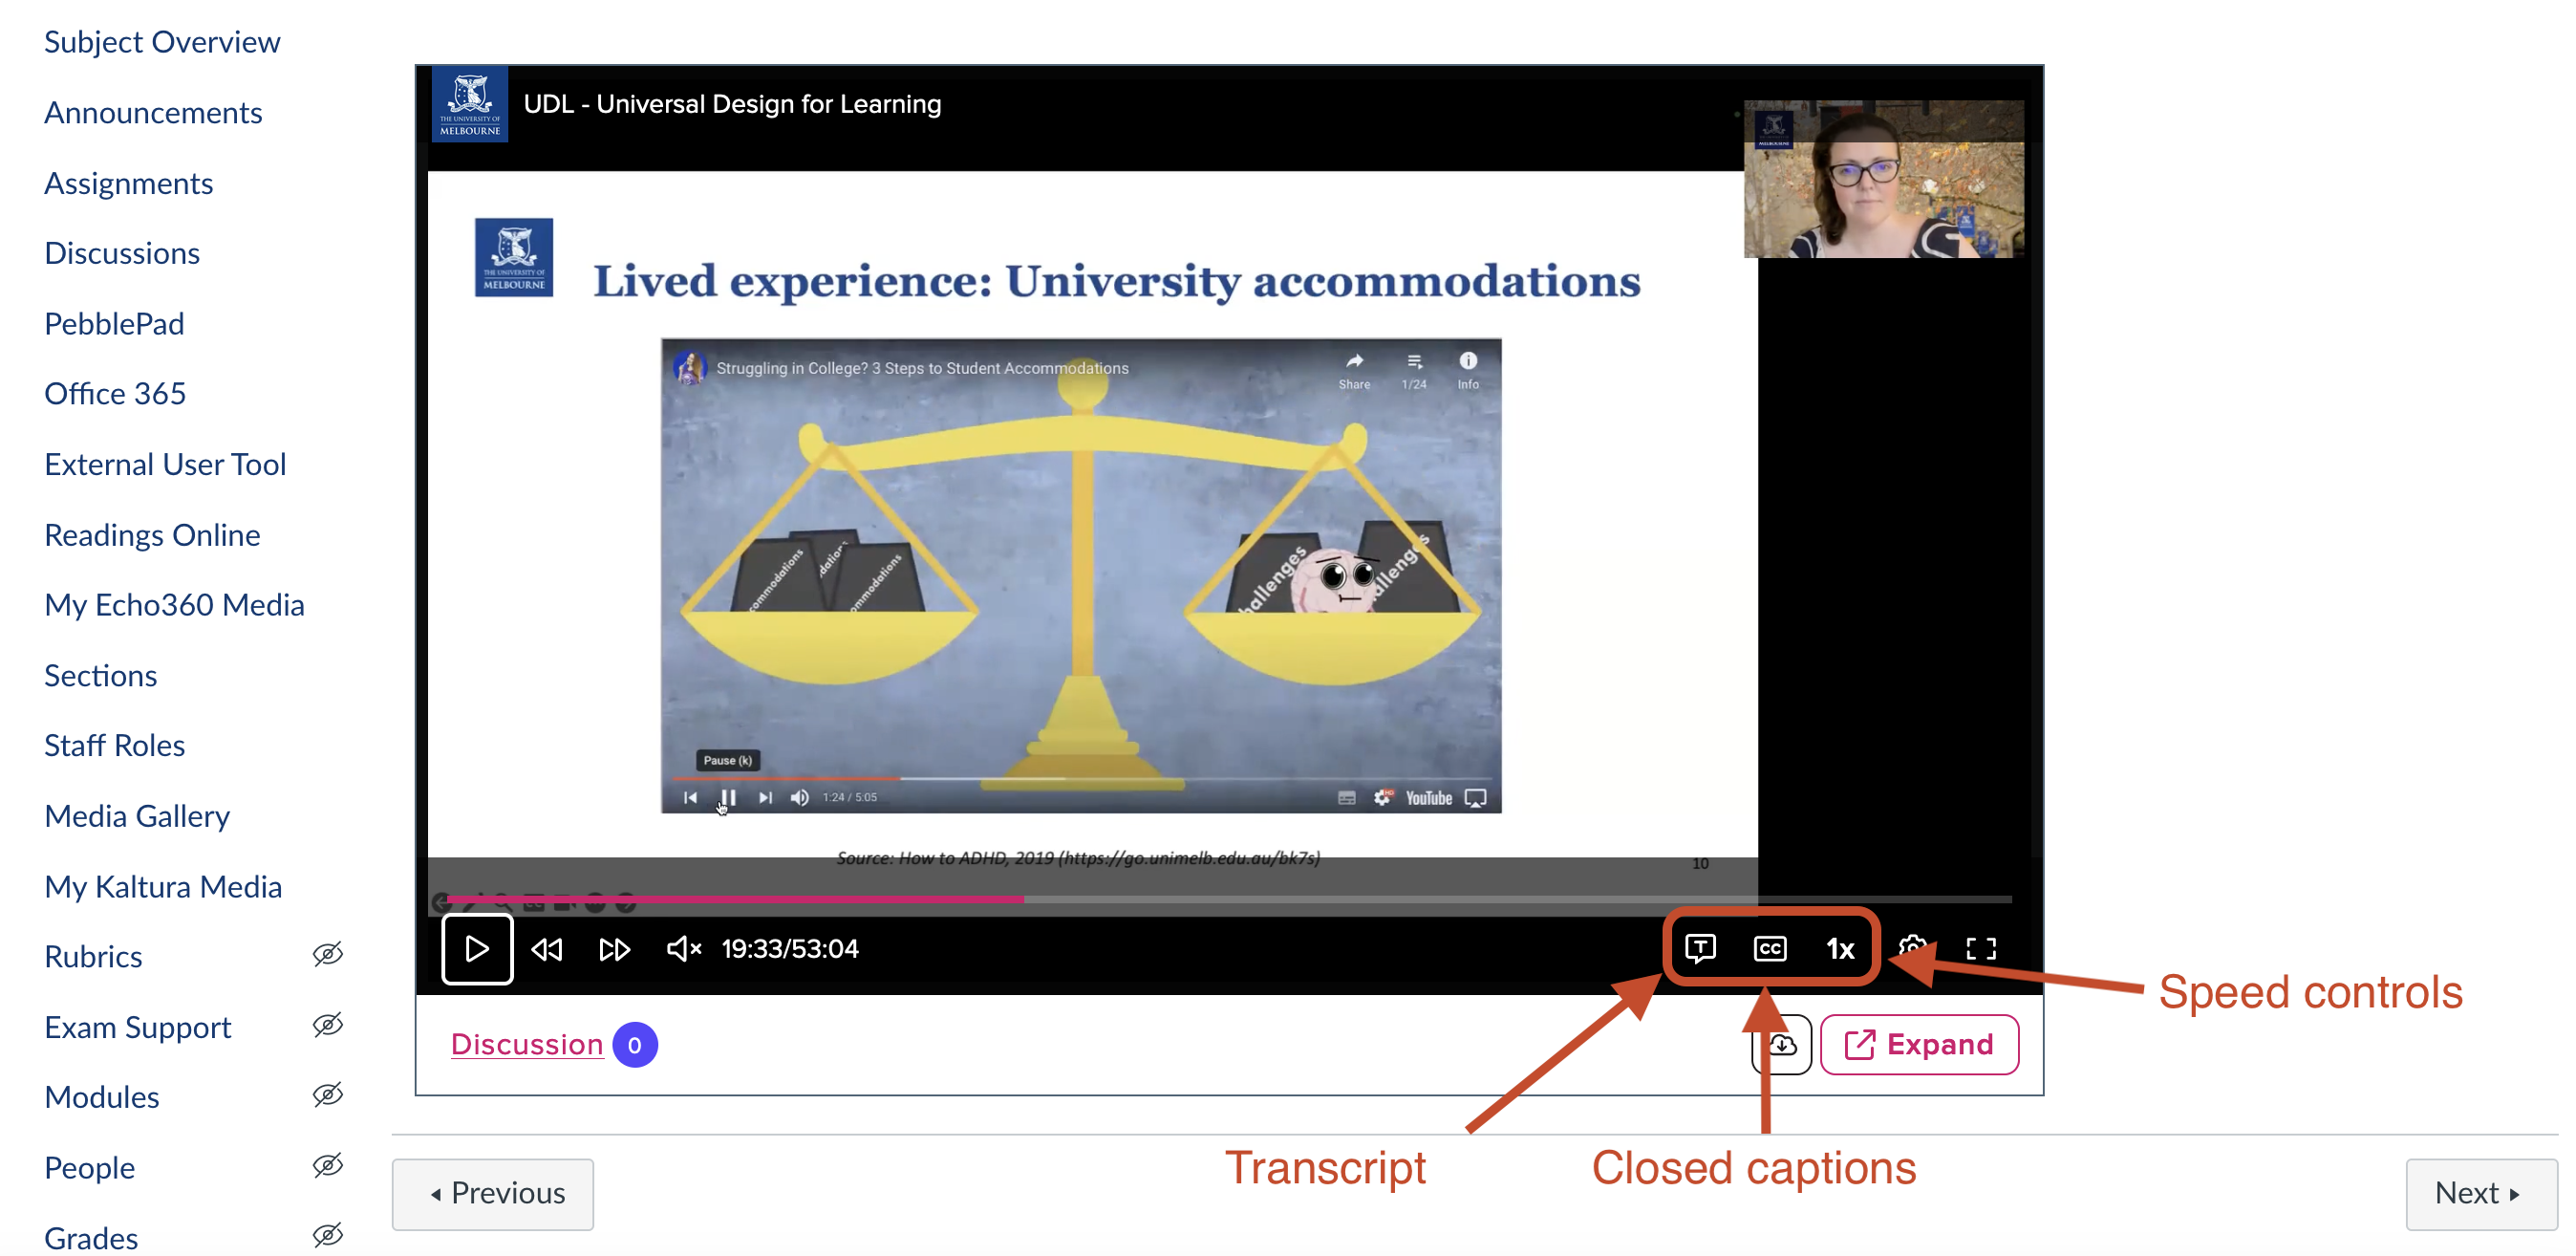
Ten tips: Creating accessible subjects in the LMS
The Future of Generative AI: Where Are Large Language Models Headed?