Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
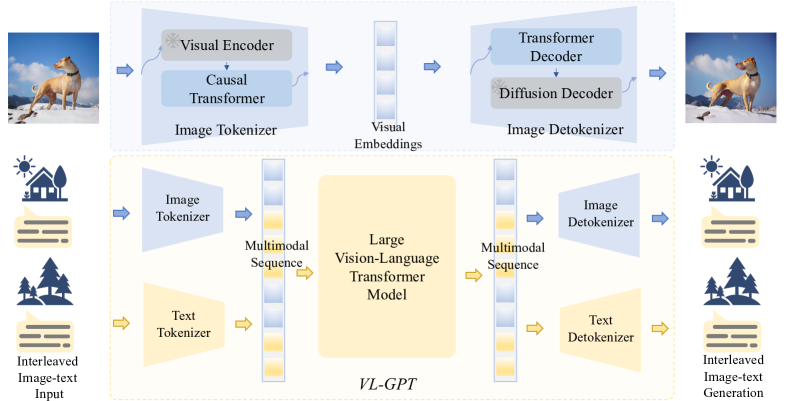
VL-GPT: A Generative Pre-trained Transformer for Vision and Language ...
[2312.09251] VL-GPT: A Generative Pre-trained Transformer for Vision ...
Vision Large Language Models (vLLMs)
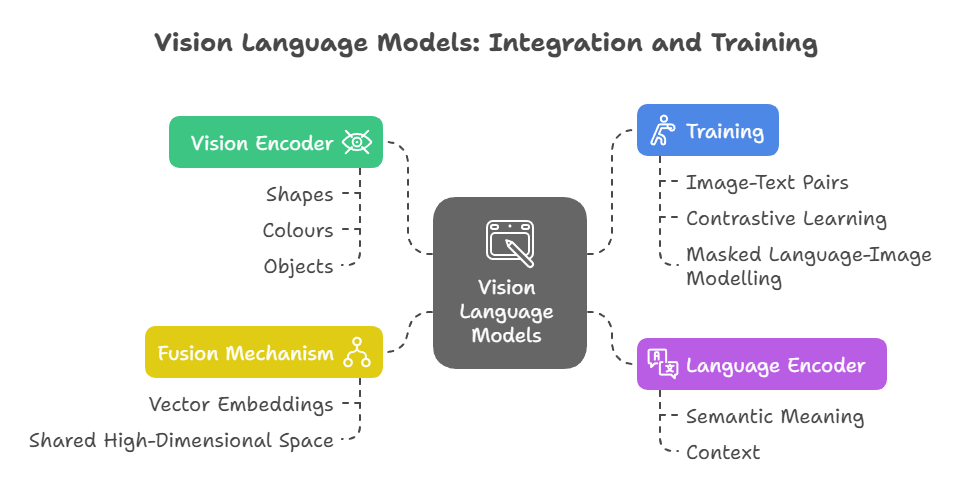
Unlock AI Potential with Vision Language Models
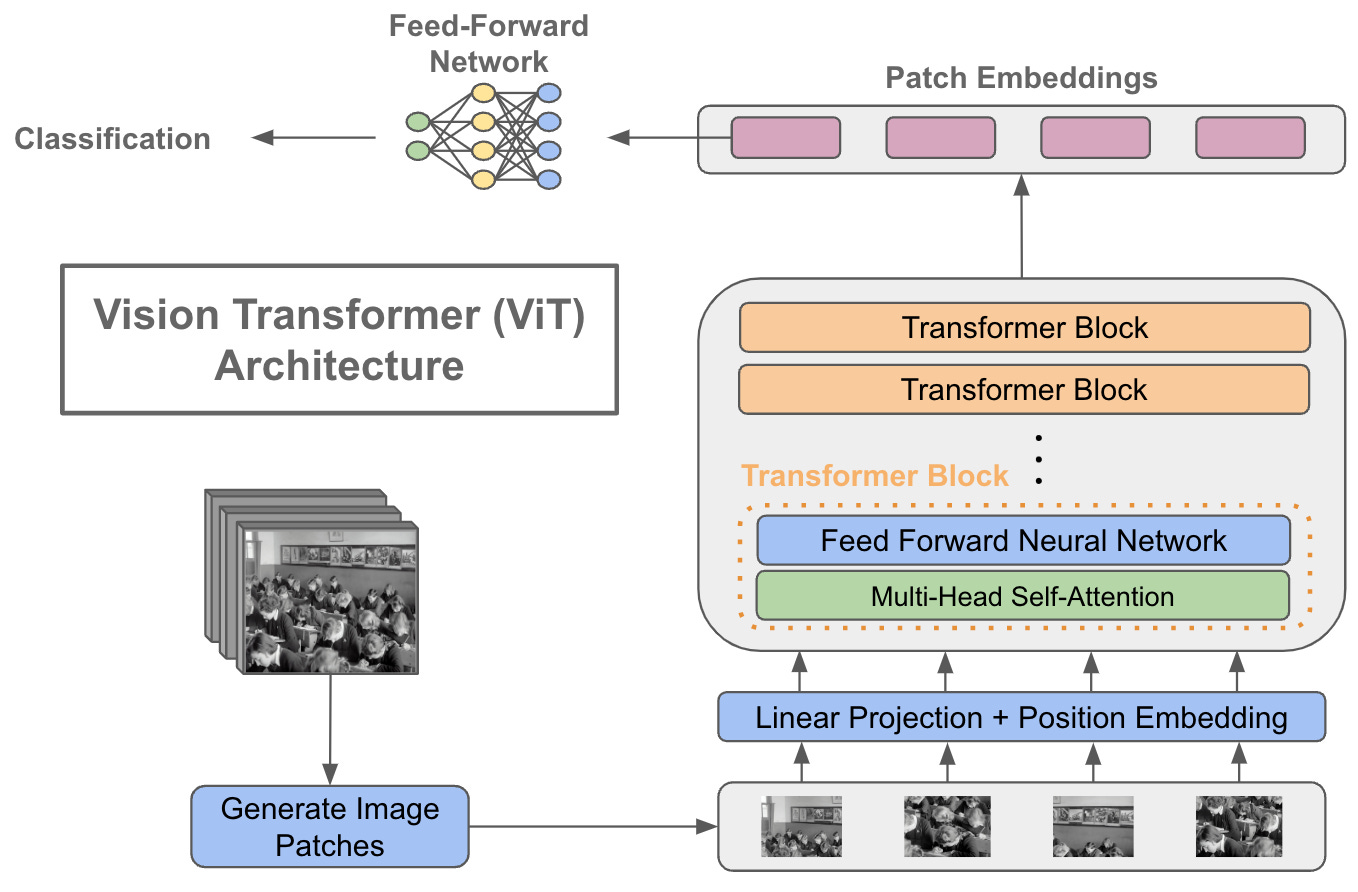
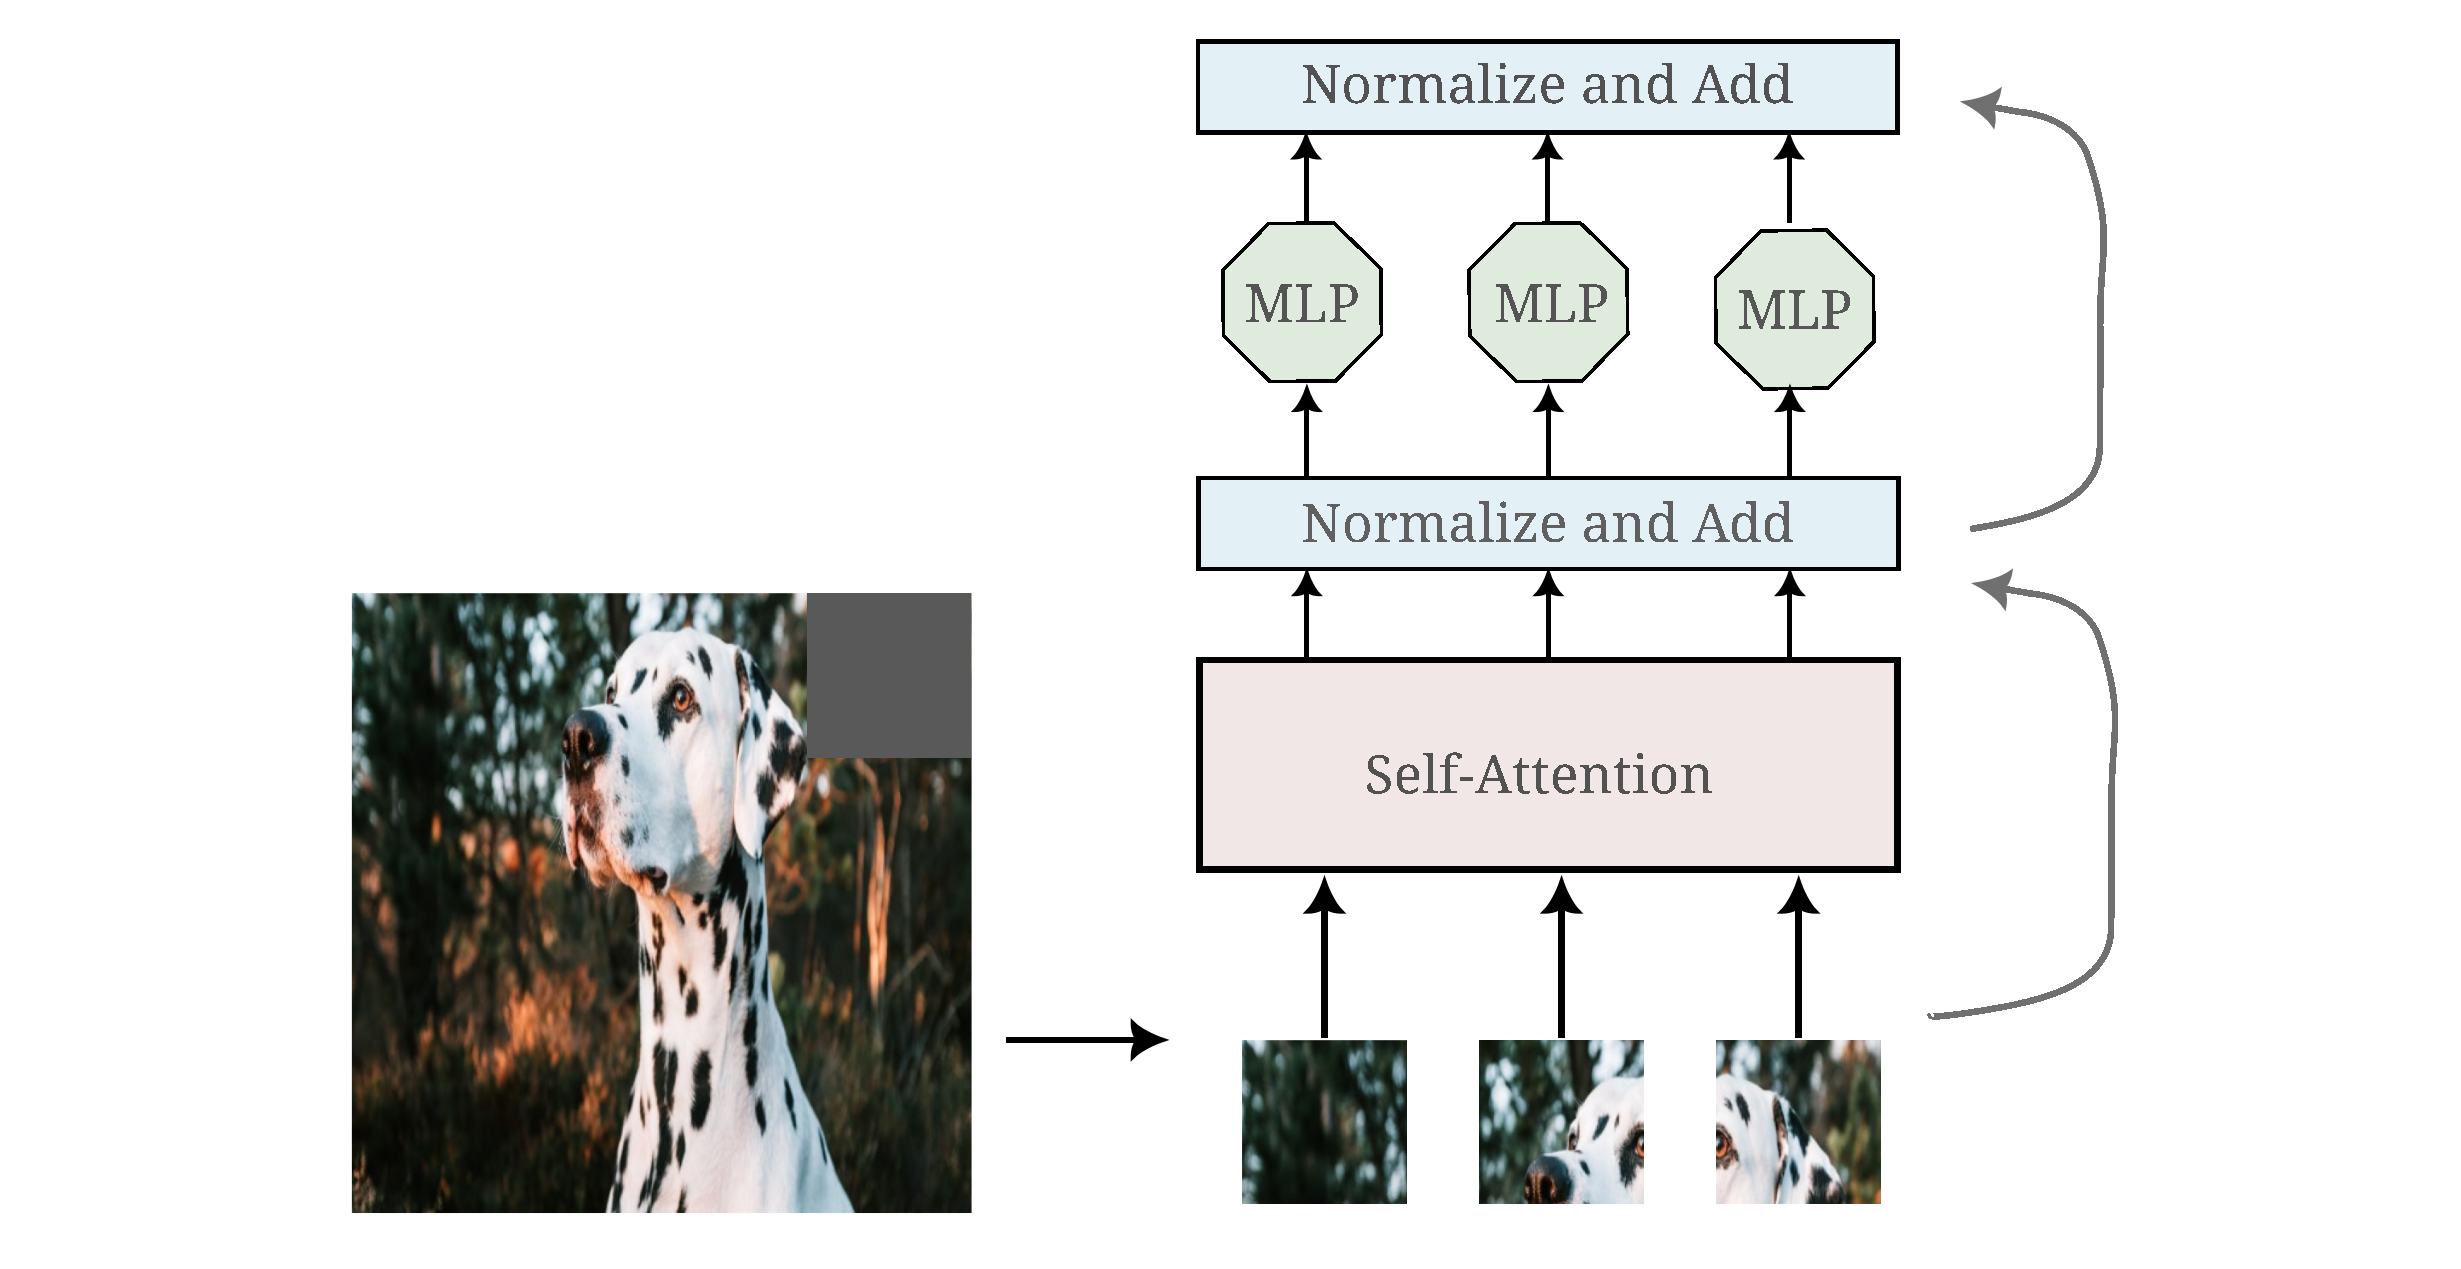
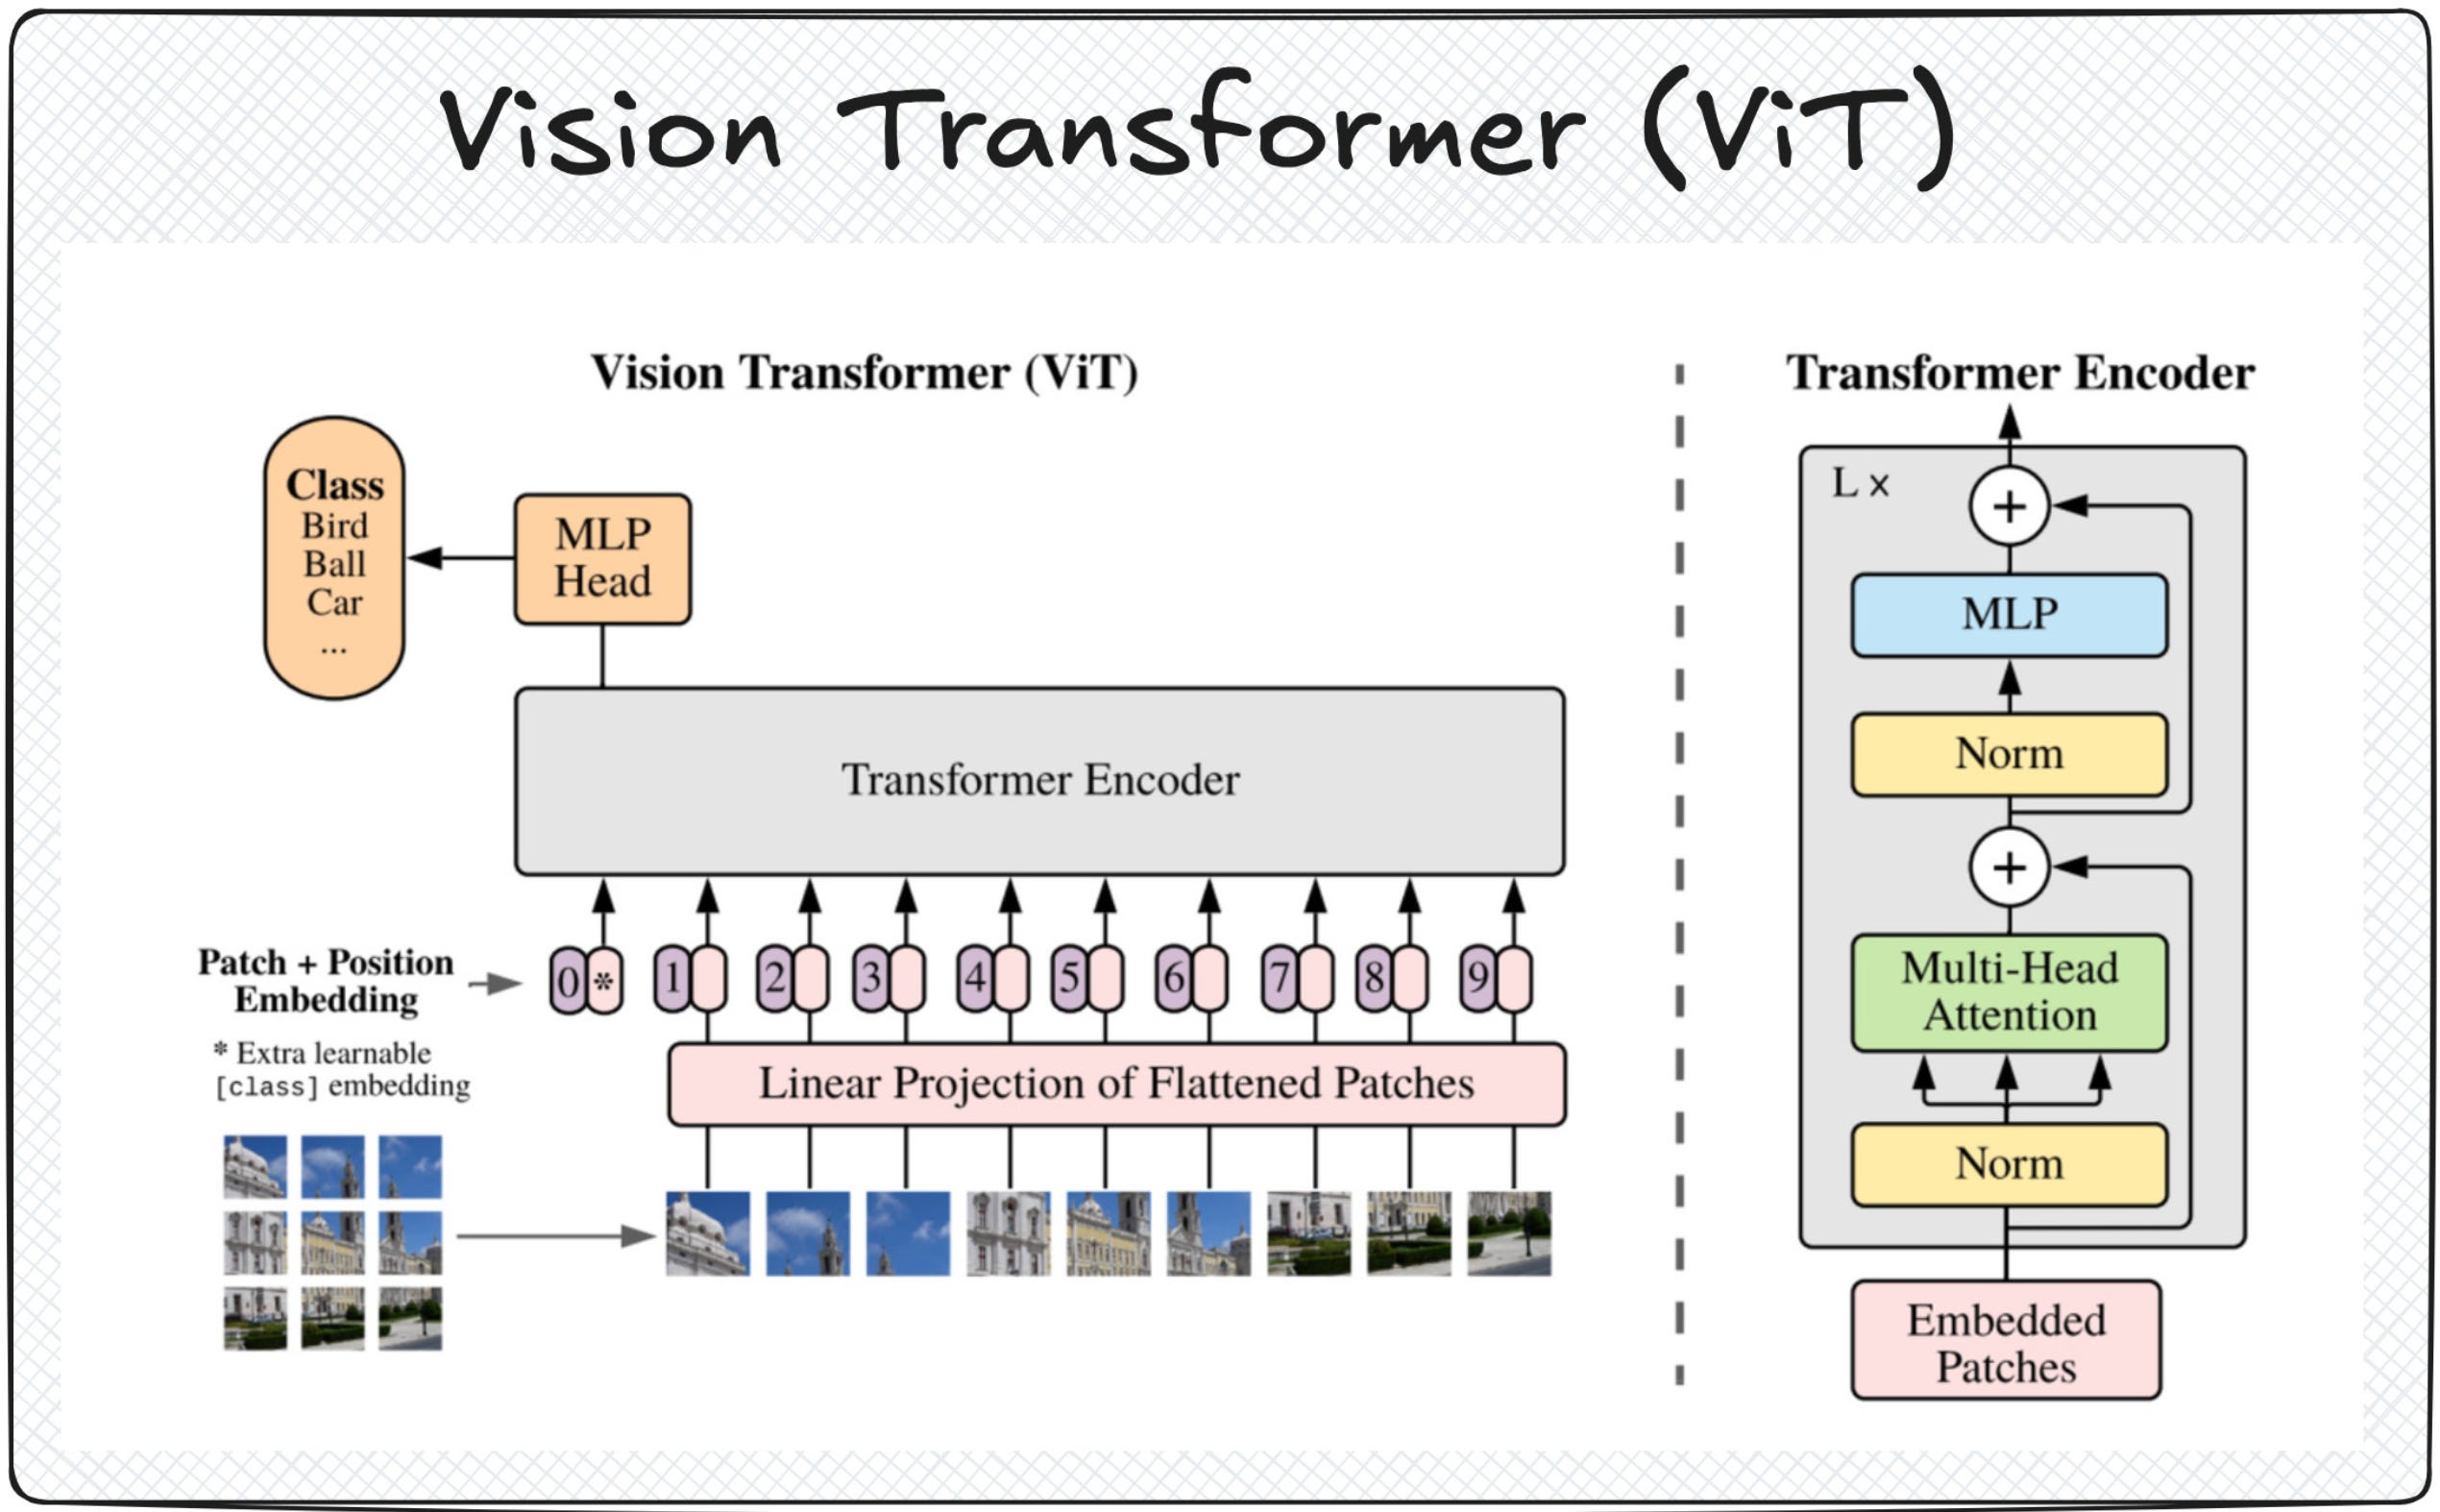
Vision Transformers Explained: From Attention to Vision Language Models ...
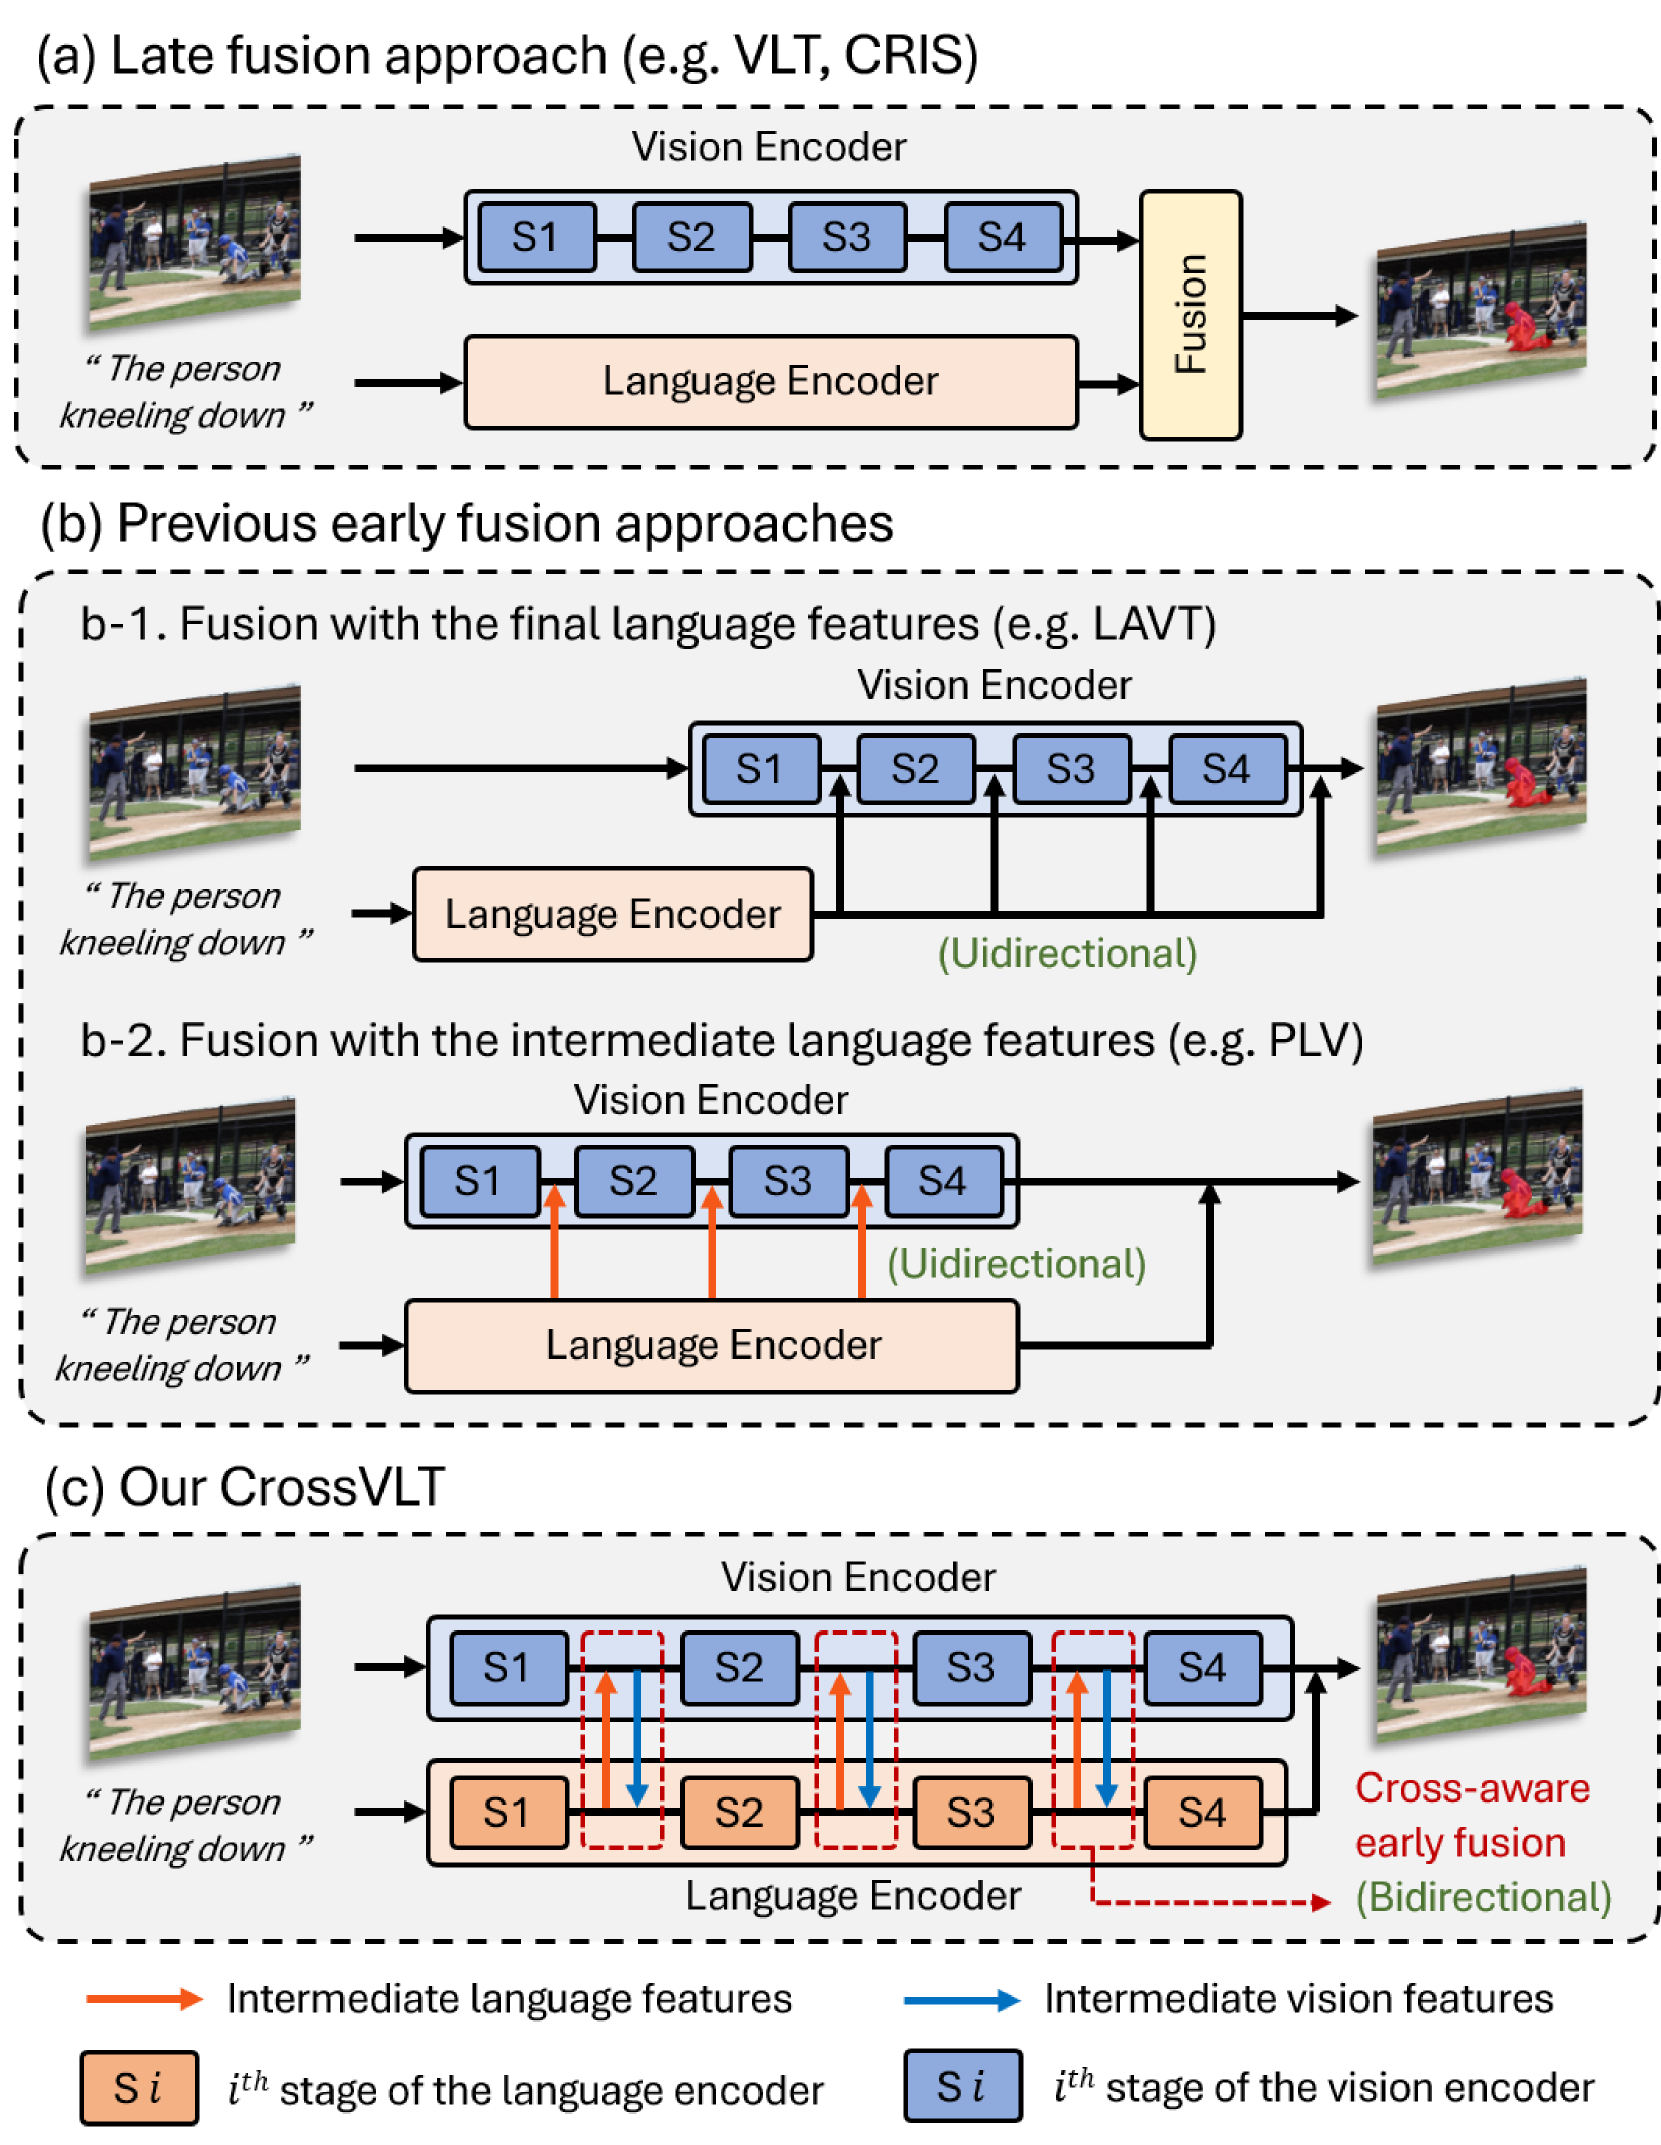
Cross-aware Early Fusion with Stage-divided Vision and Language ...
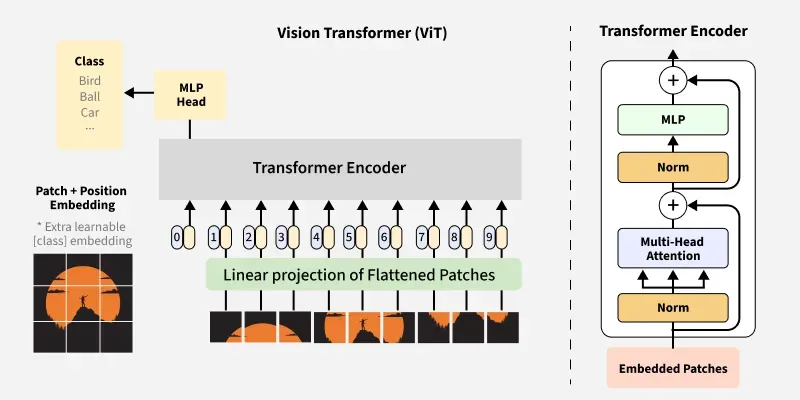
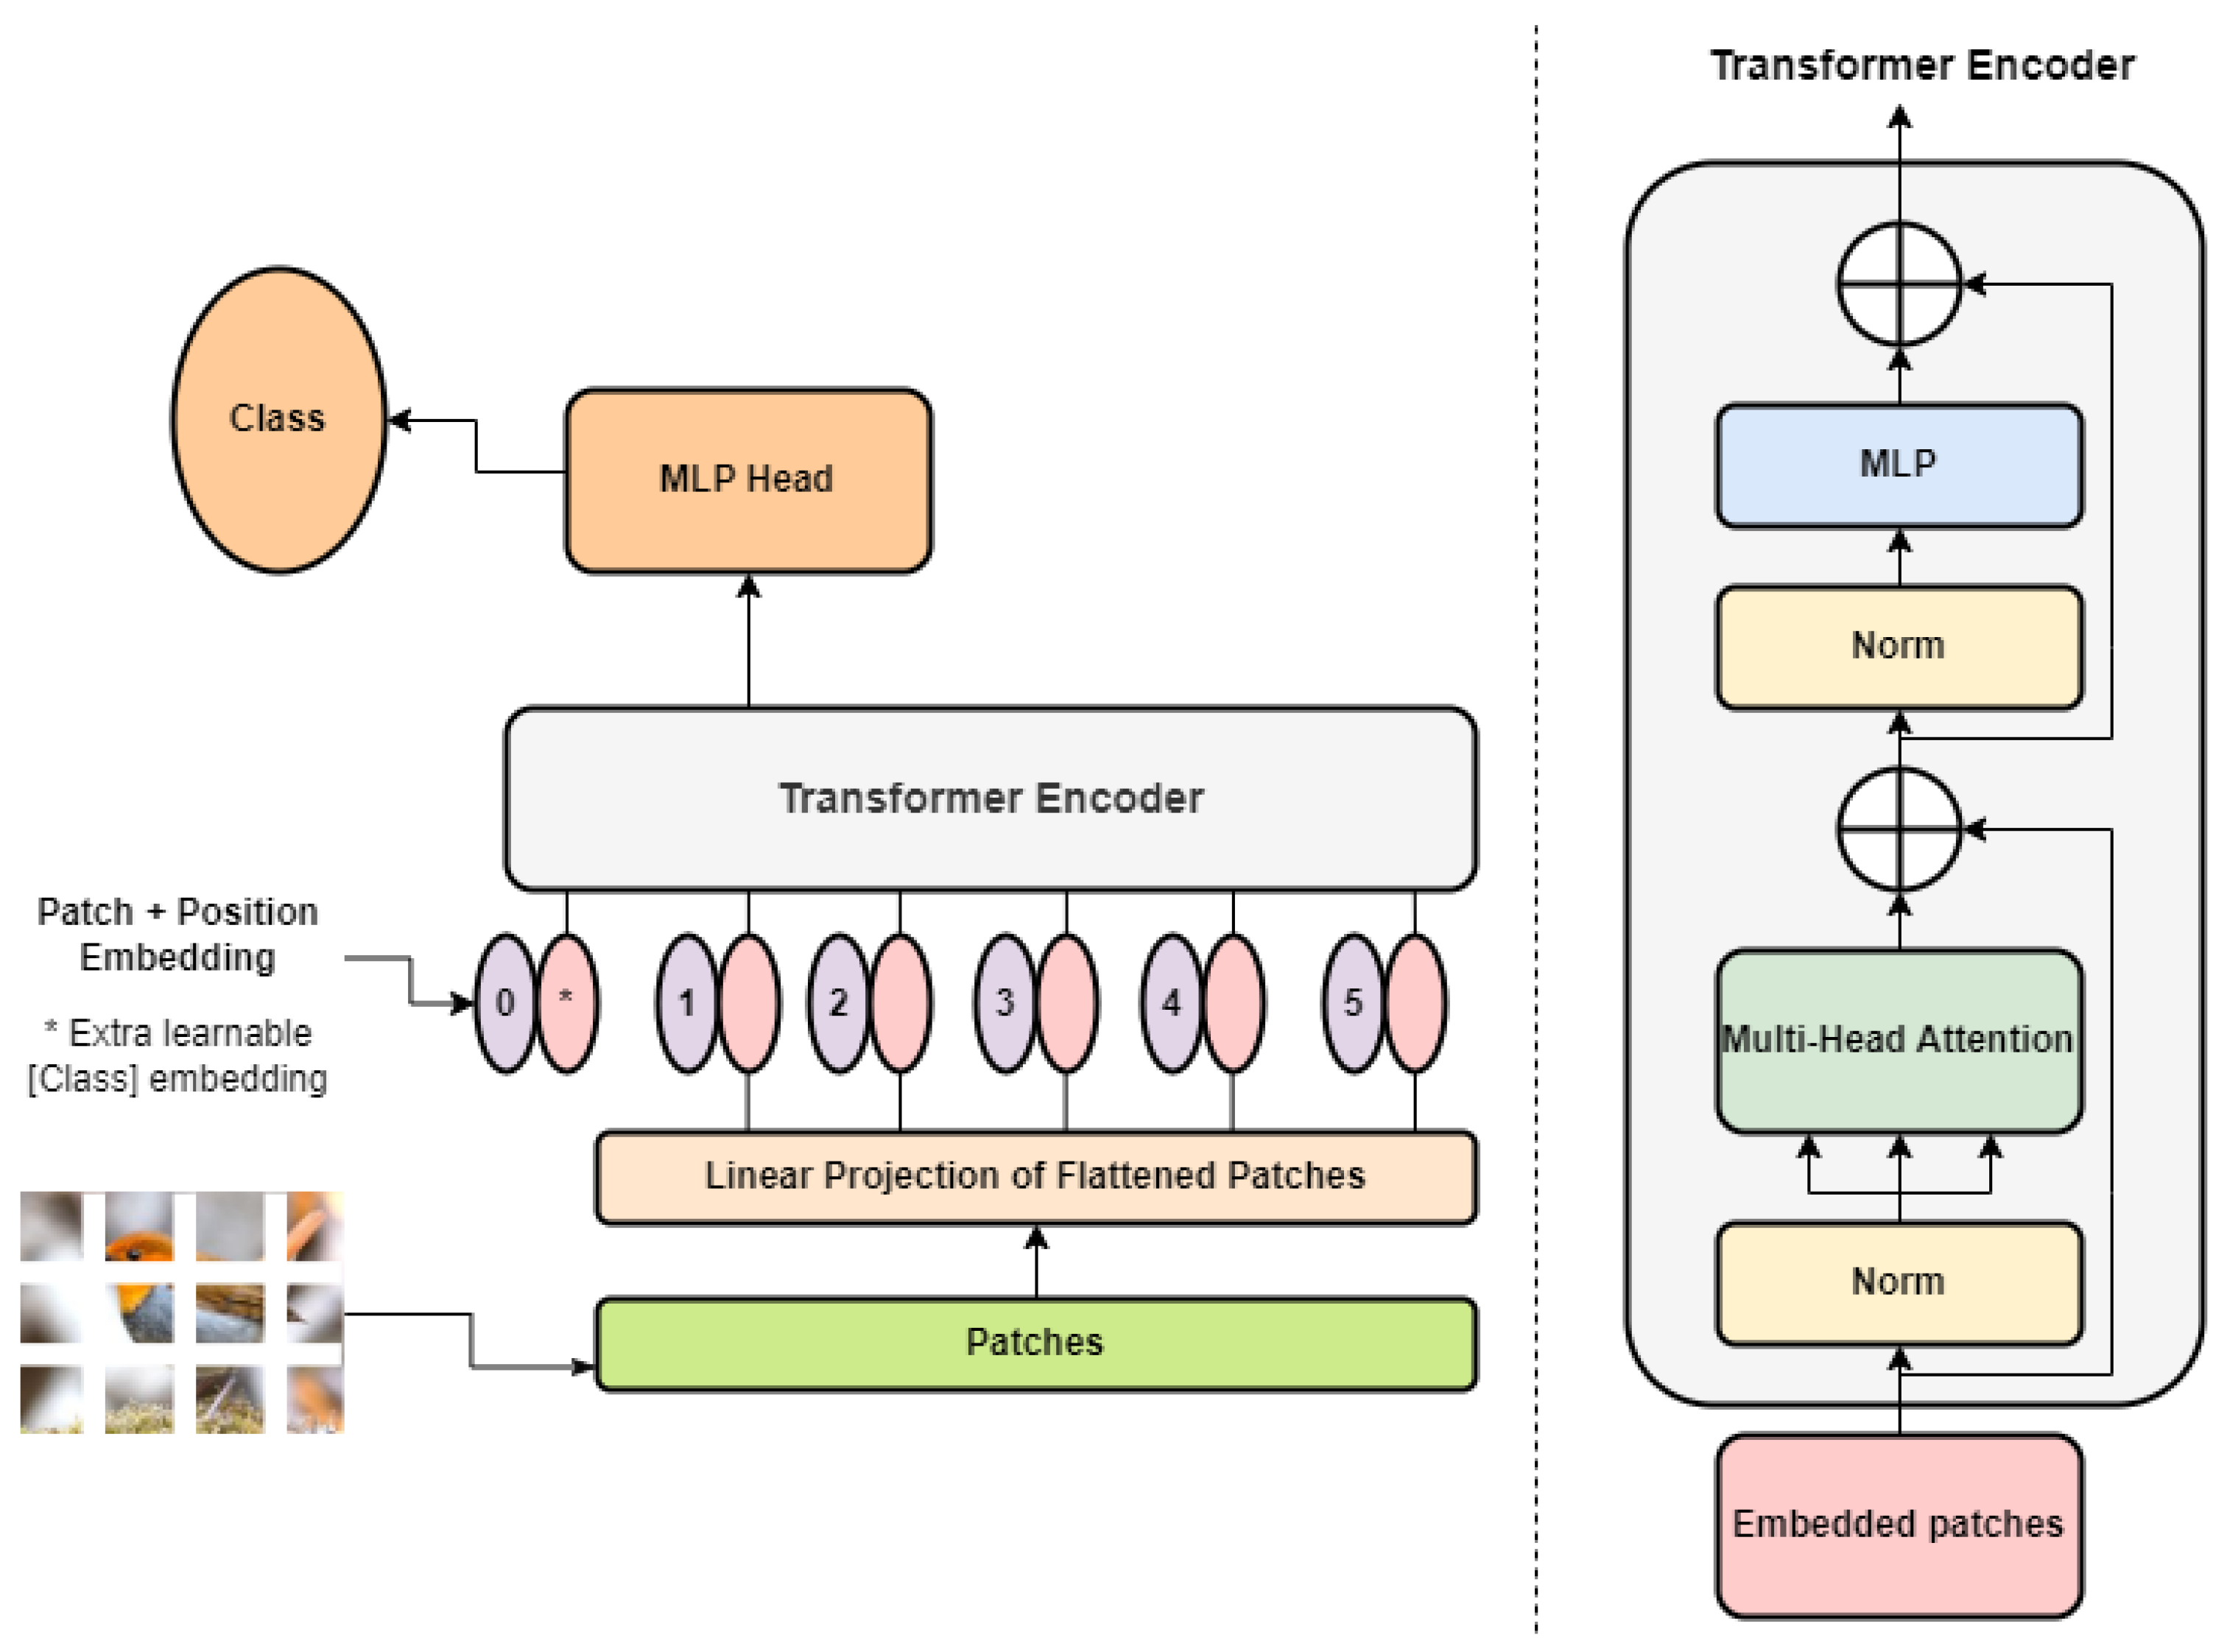
Vision Transformer in Computer Vision - GeeksforGeeks
Survey of transformers for vision language
Vision Transformer Model: How It Works & Benefits
Aman's AI Journal • Primers • Vision Language Models
An Intuitive Introduction to the Vision Transformer - Thalles' blog
Vision Language Models là gì? Nguyên lý hoạt động, lợi ích và ứng dụng
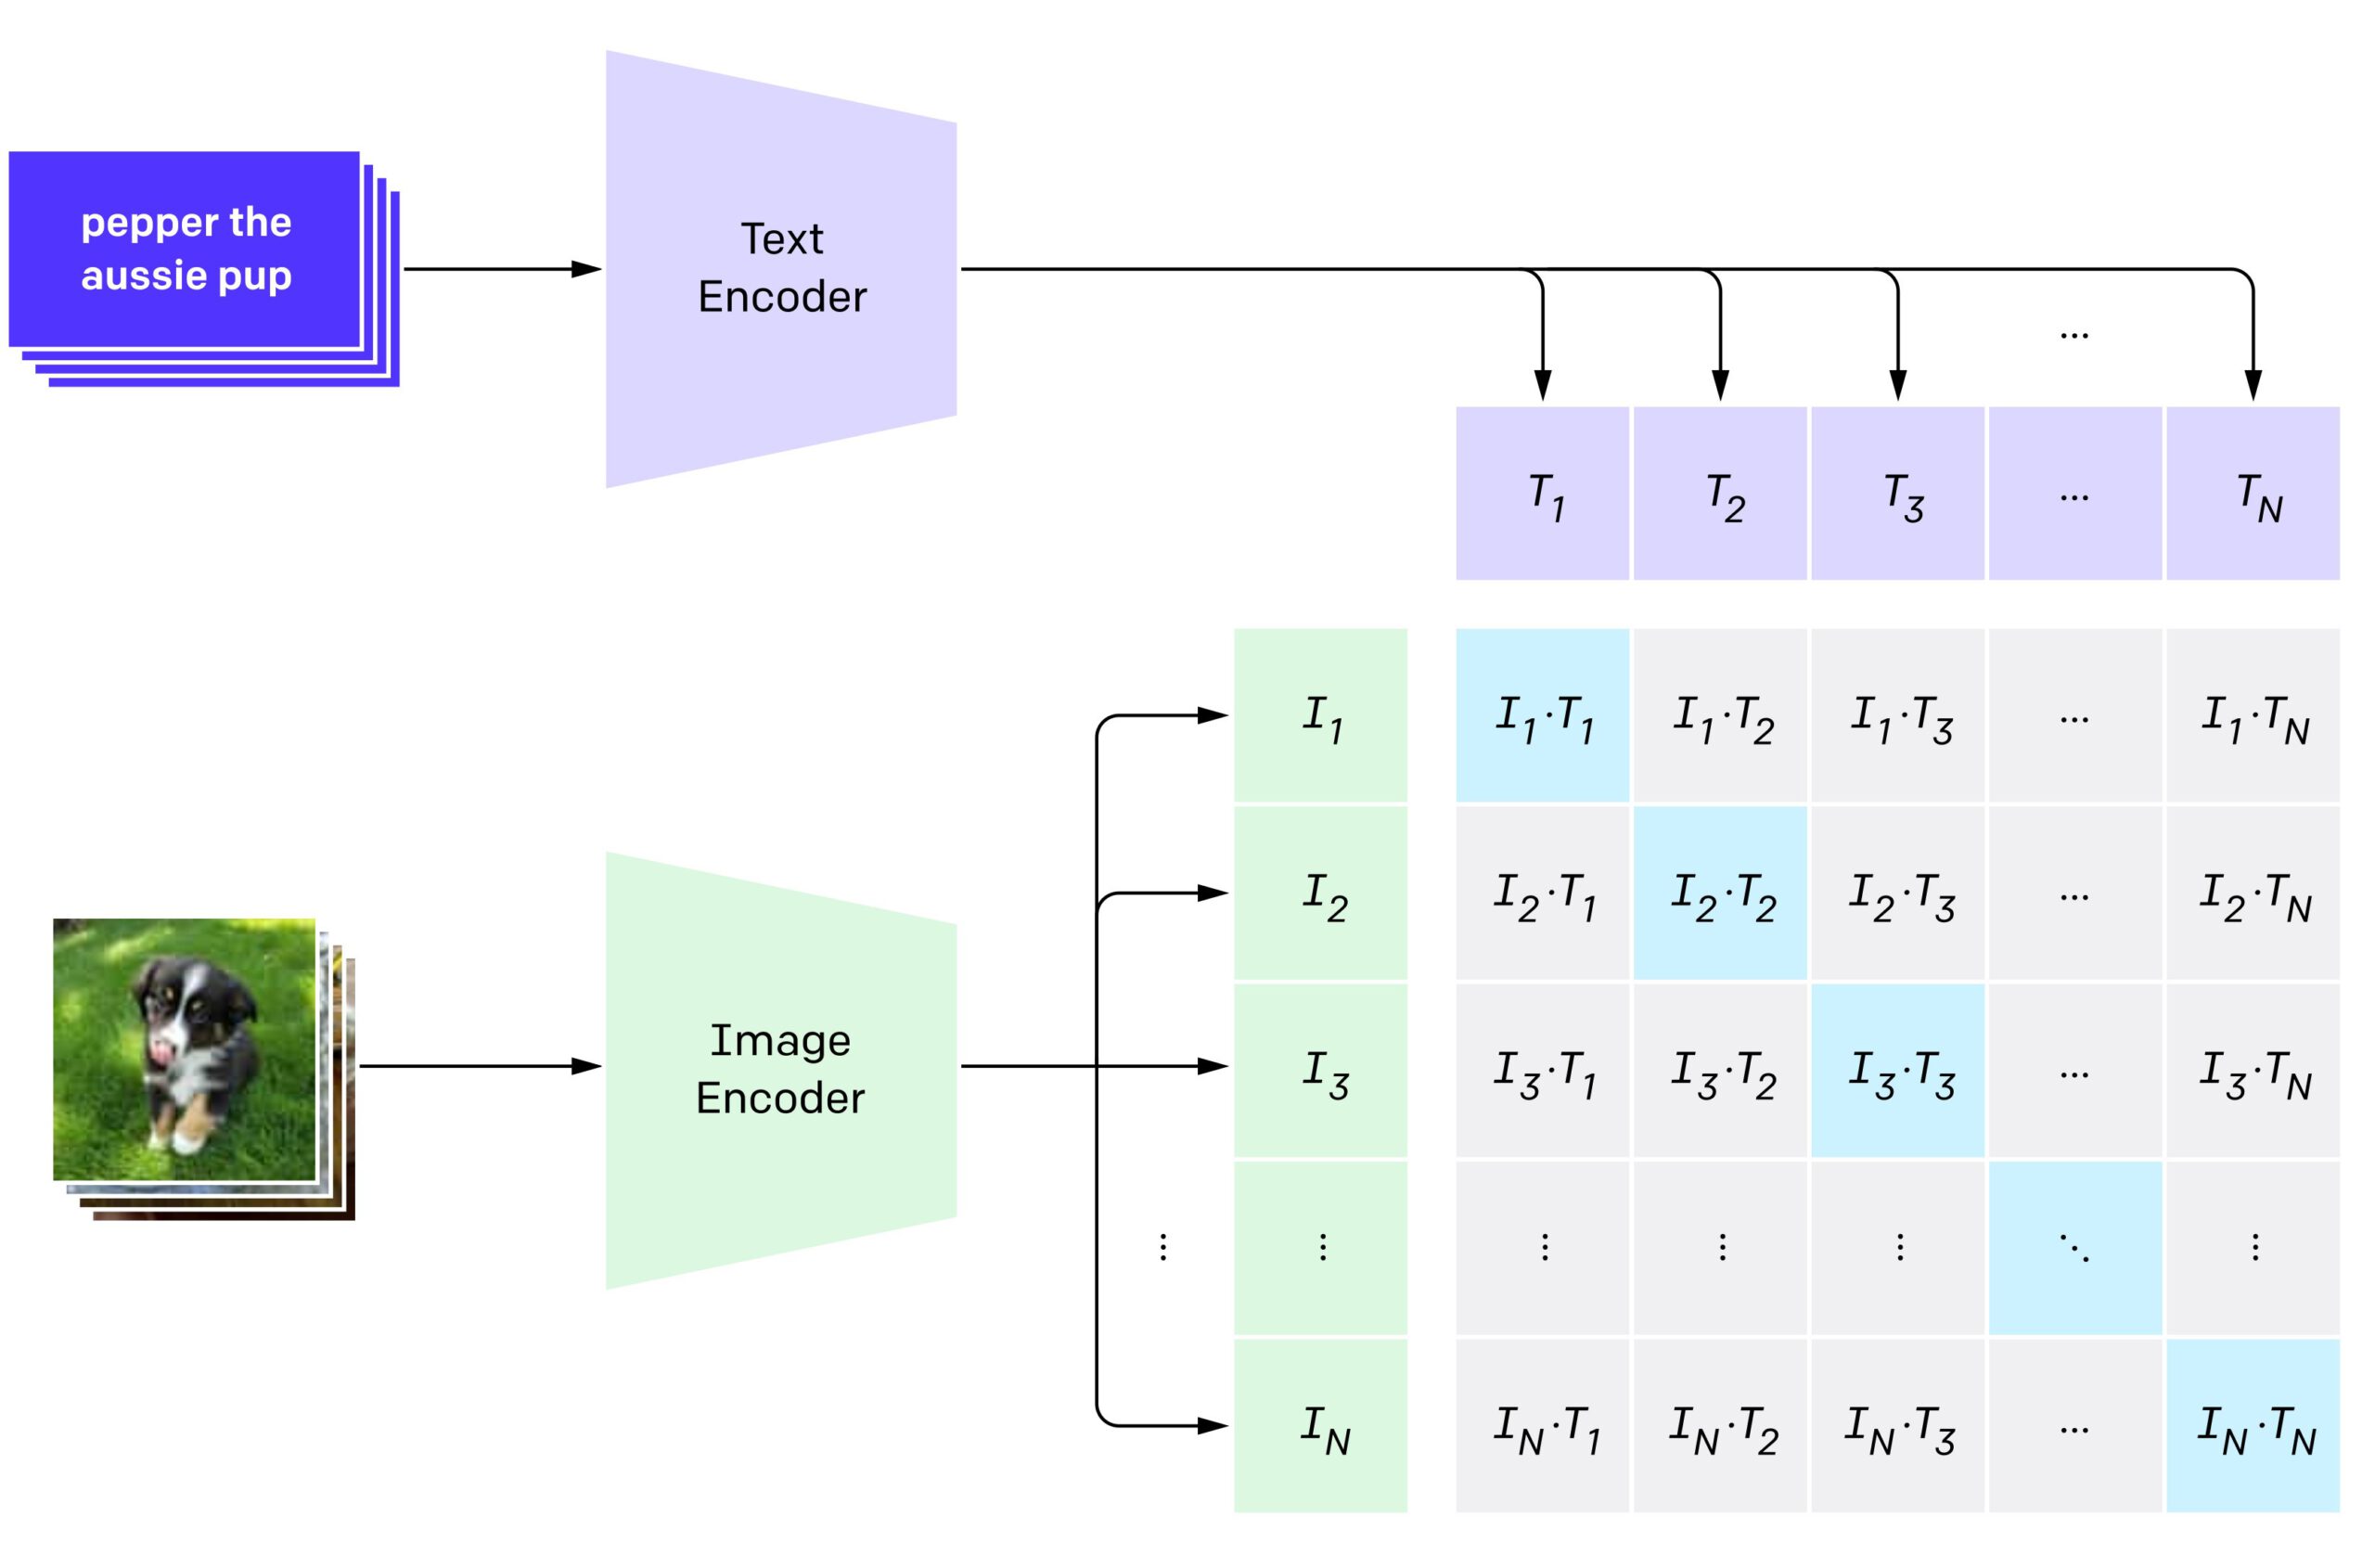
What are Vision Language Models and How Do They Work?
Vision Transformers: Natural Language Processing (NLP) Increases ...
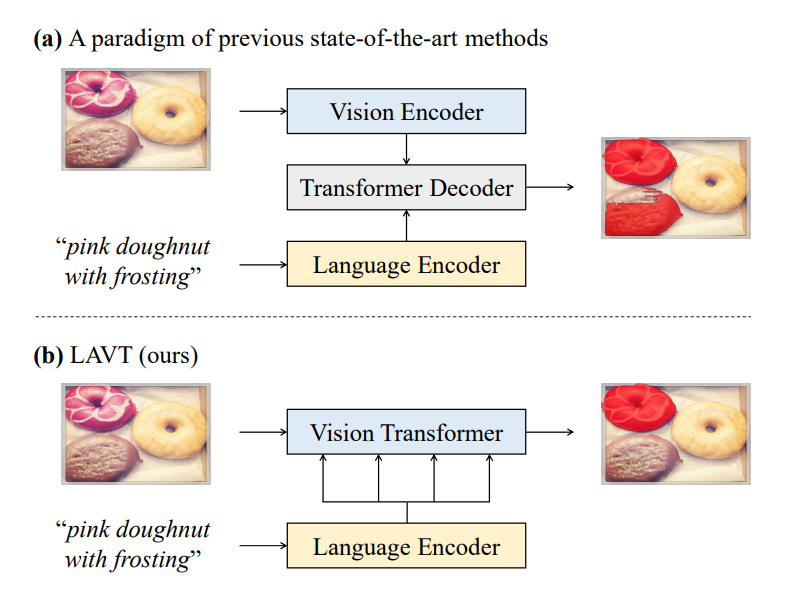
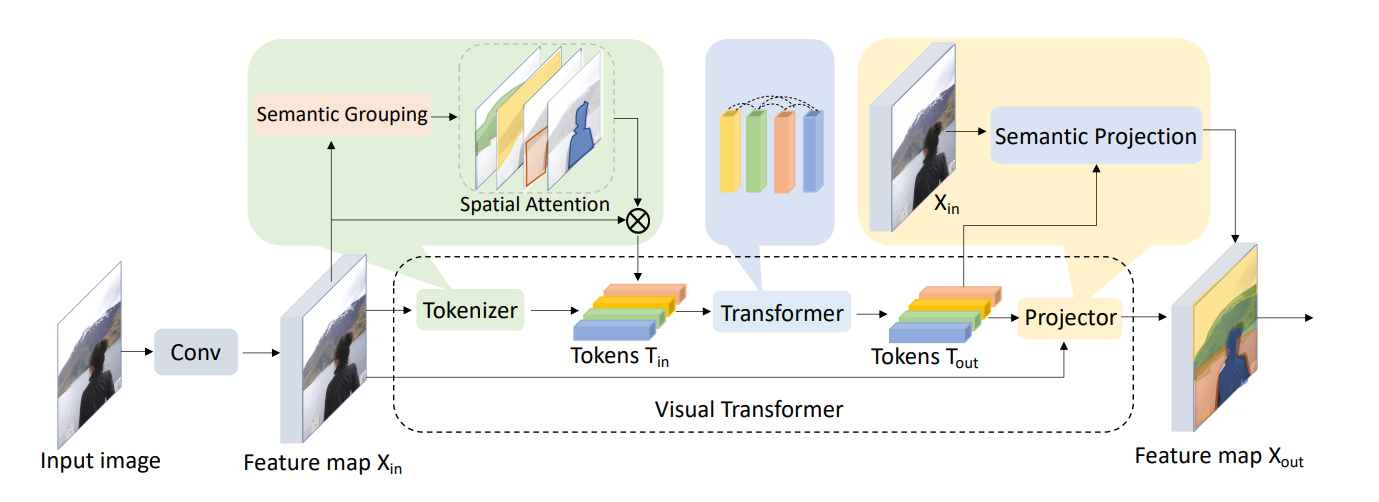
结合 Swin-Transformer 的 LAVT: Language-Aware Vision Transformer for ...
(PDF) Vision Language Transformers: A Survey
The Progression of Transformers from Language to Vision to MOT: A ...
Understanding Vision Language Models
LAVT: Language-Aware Vision Transformer for Referring Image ...
LLaVA Image Recognition in Python with Ollama and Vision Language ...
Introduction to Vision Language Models
Transformer / Vision and Languageの基礎 - Speaker Deck
Overview of the Vision Transformer architecture (Adapted from [12 ...
Multimodal Deep Learning with Vision Language Models: Exploring ...
Language-Aware Vision Transformer for Referring Image Segmentation - 知乎
Vision Transformer Image Classification | MindSpore 2.0 Tutorials ...
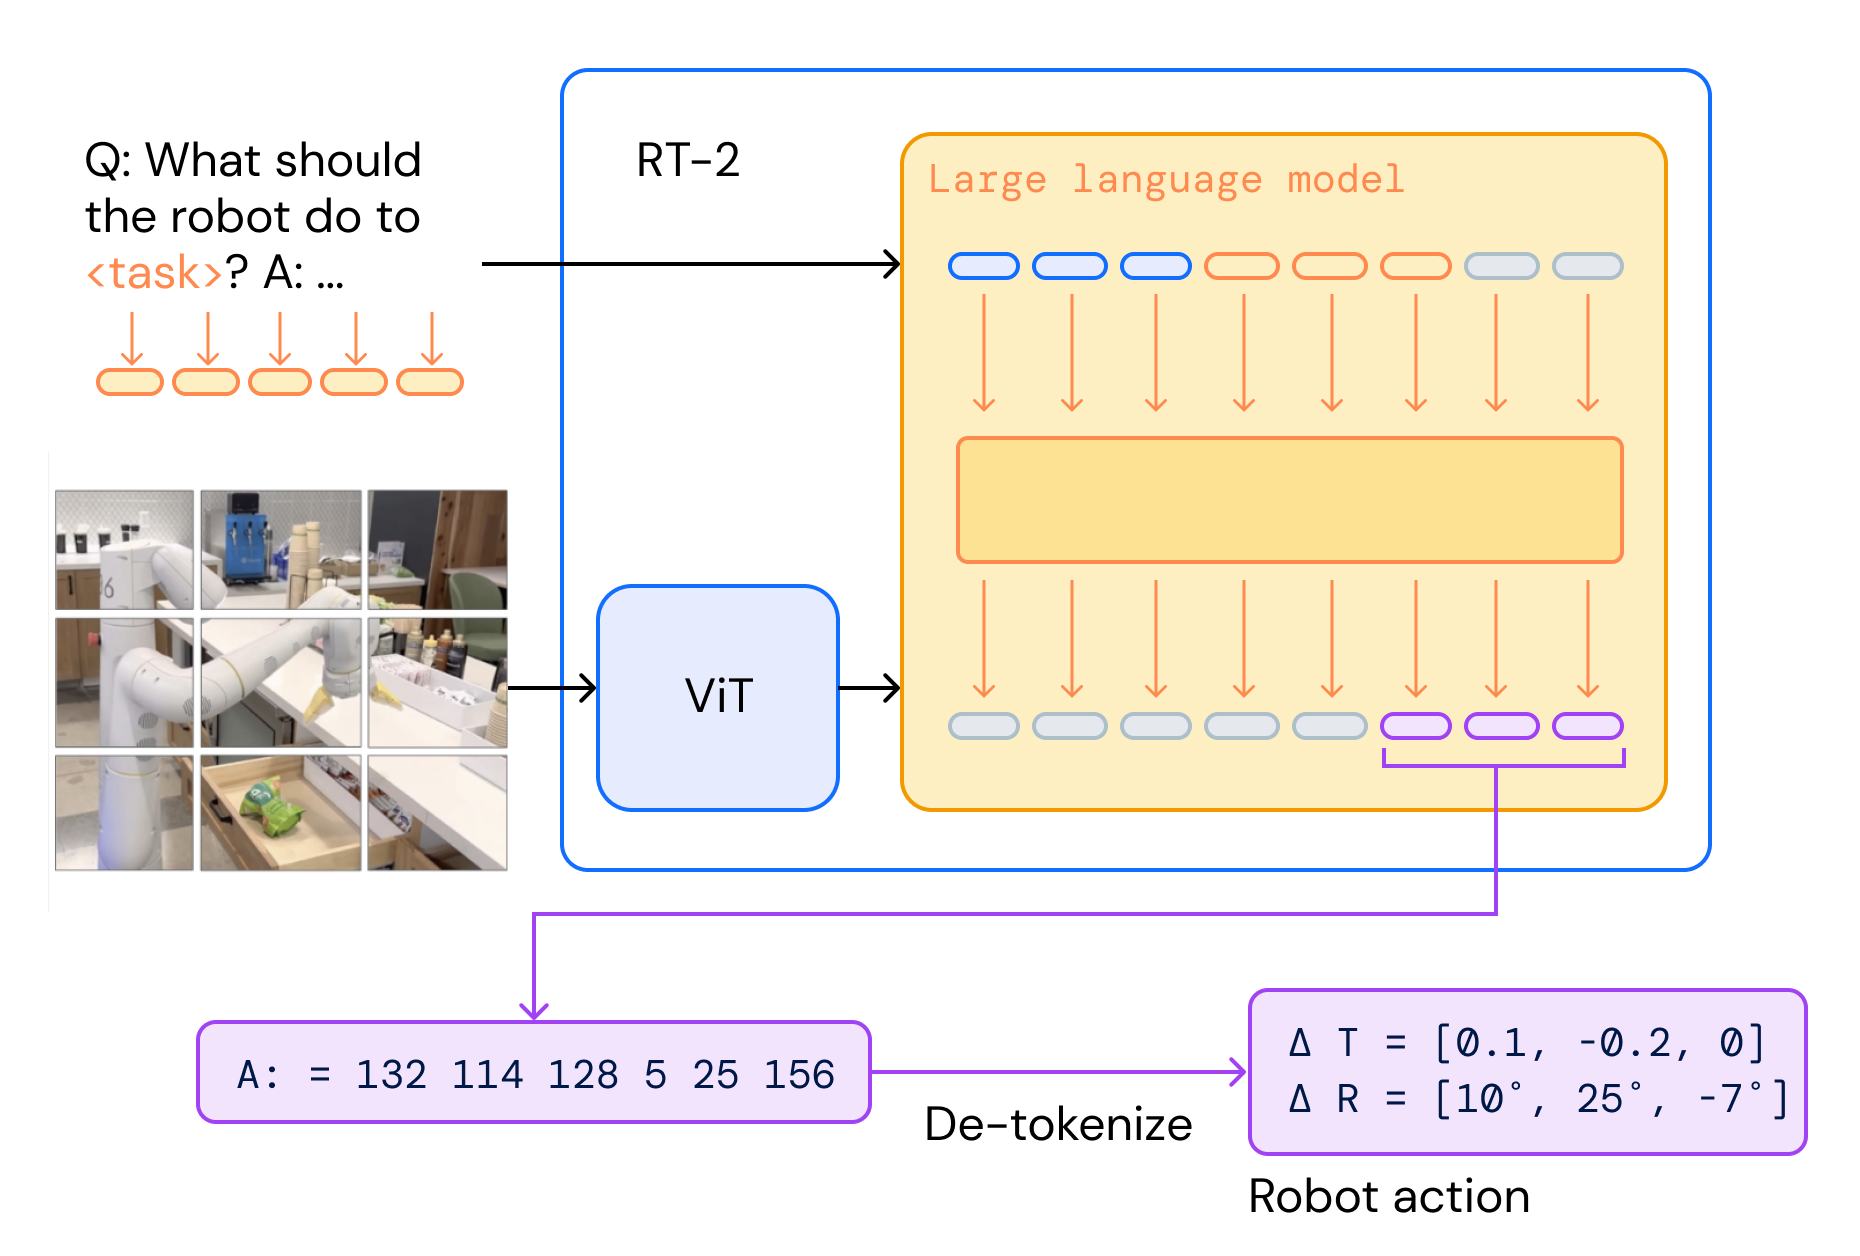
Vision Language Action Models (VLA) & Policies for Robots
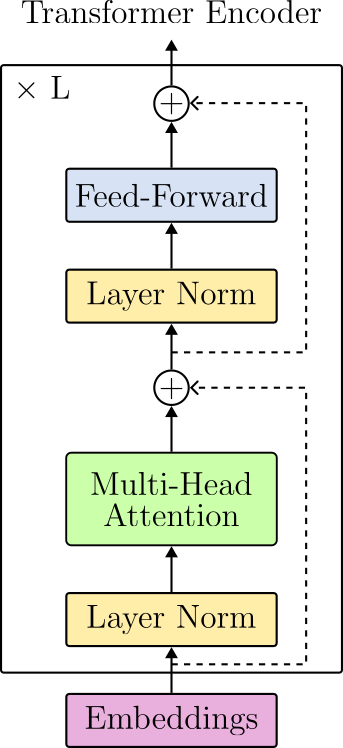
Detailed description of the vision transformer block. (A) The overall ...
Vision Transformer 图像分类识别 基于 ViT(Vision Transformer)的图像十分类 实战 完整代码 毕业设计 ...
Vision Language Models Explained | Ultralytics
Vision Transformers - by Cameron R. Wolfe, Ph.D.
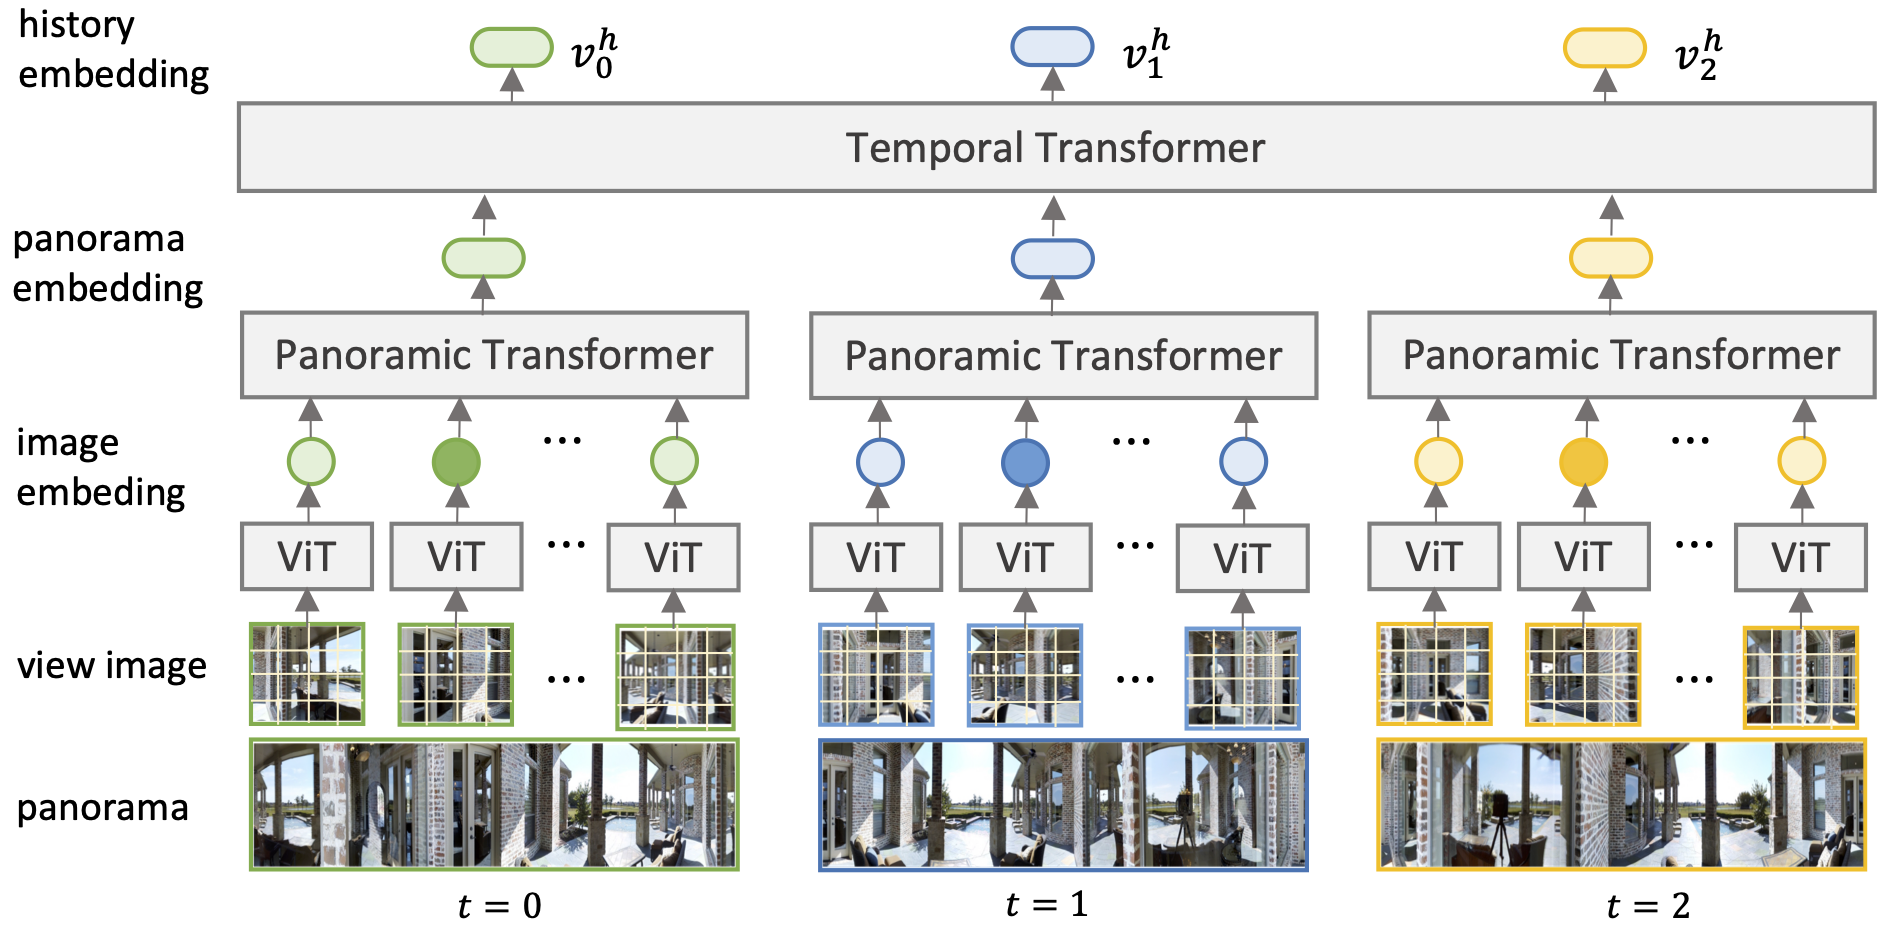
History Aware Multimodal Transformer for Vision-and-Language Navigation
Vision Transformers: From Idea to Applications (Part Two)
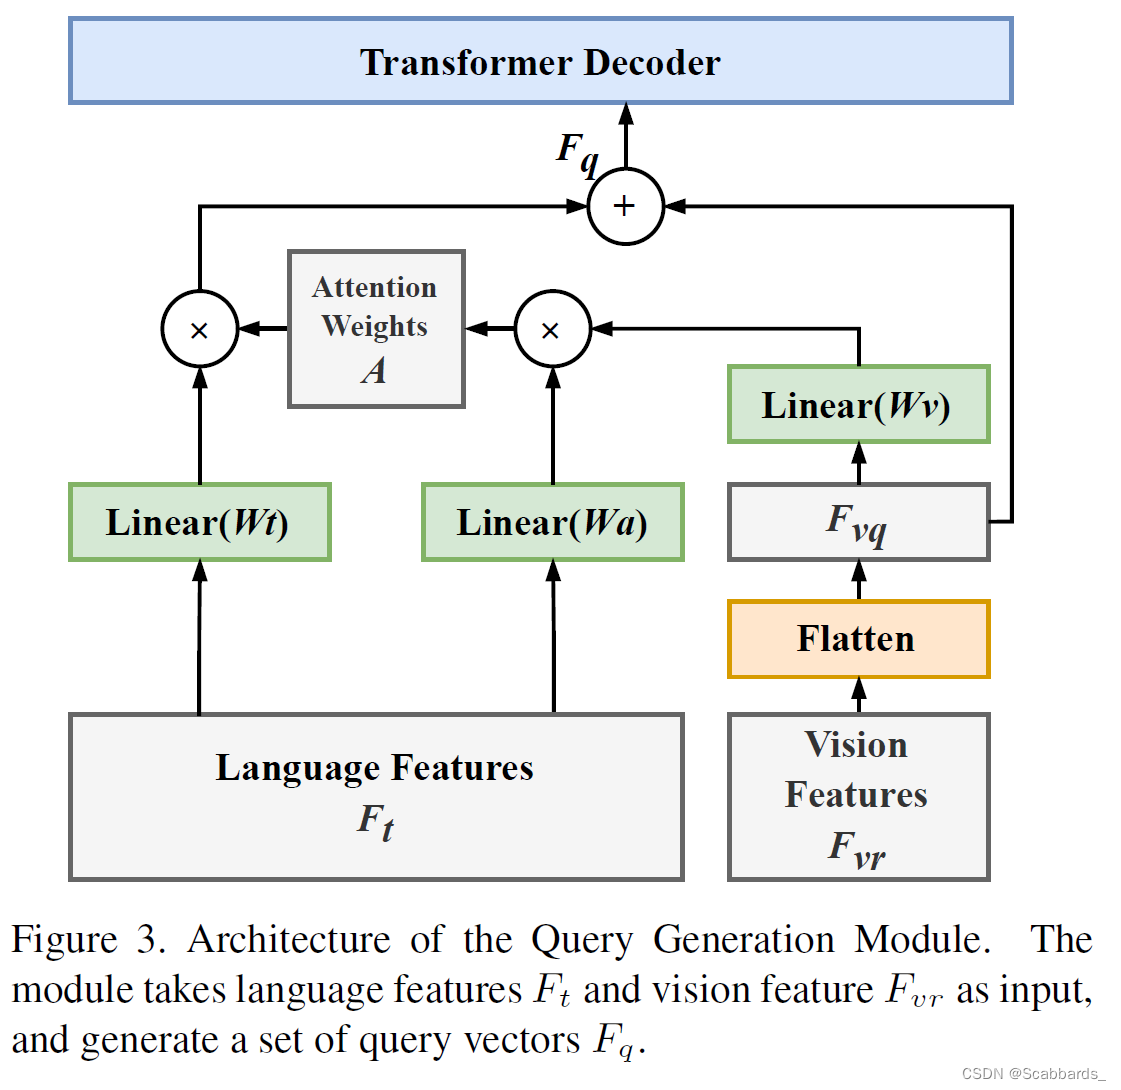
[2210.15871] VLT: Vision-Language Transformer and Query Generation for ...
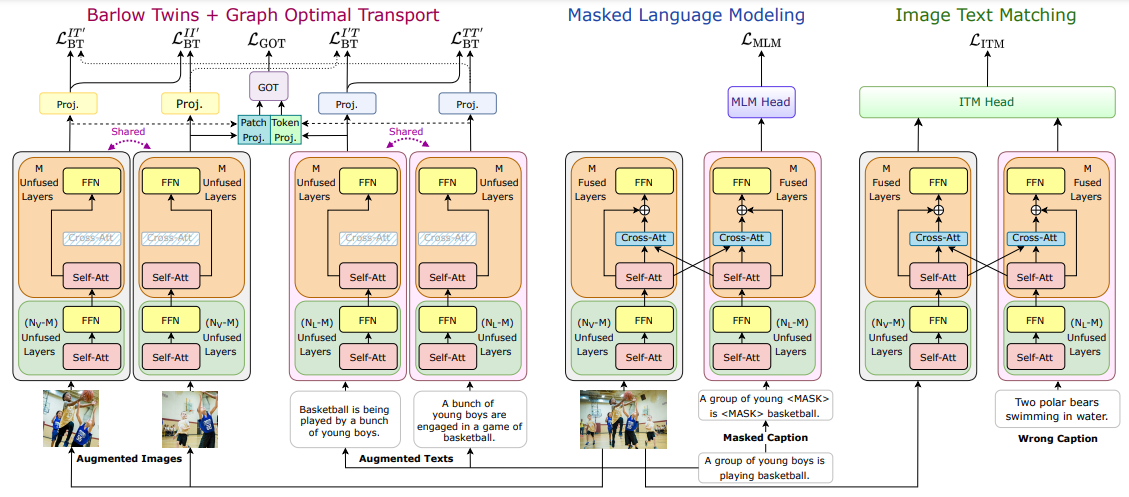
VoLTA: Vision-Language Transformer with Weakly-Supervised Local-Feature ...
【大模型系列】Language-Vision Transformer(LaVIT, ICLR2024)_unified language ...
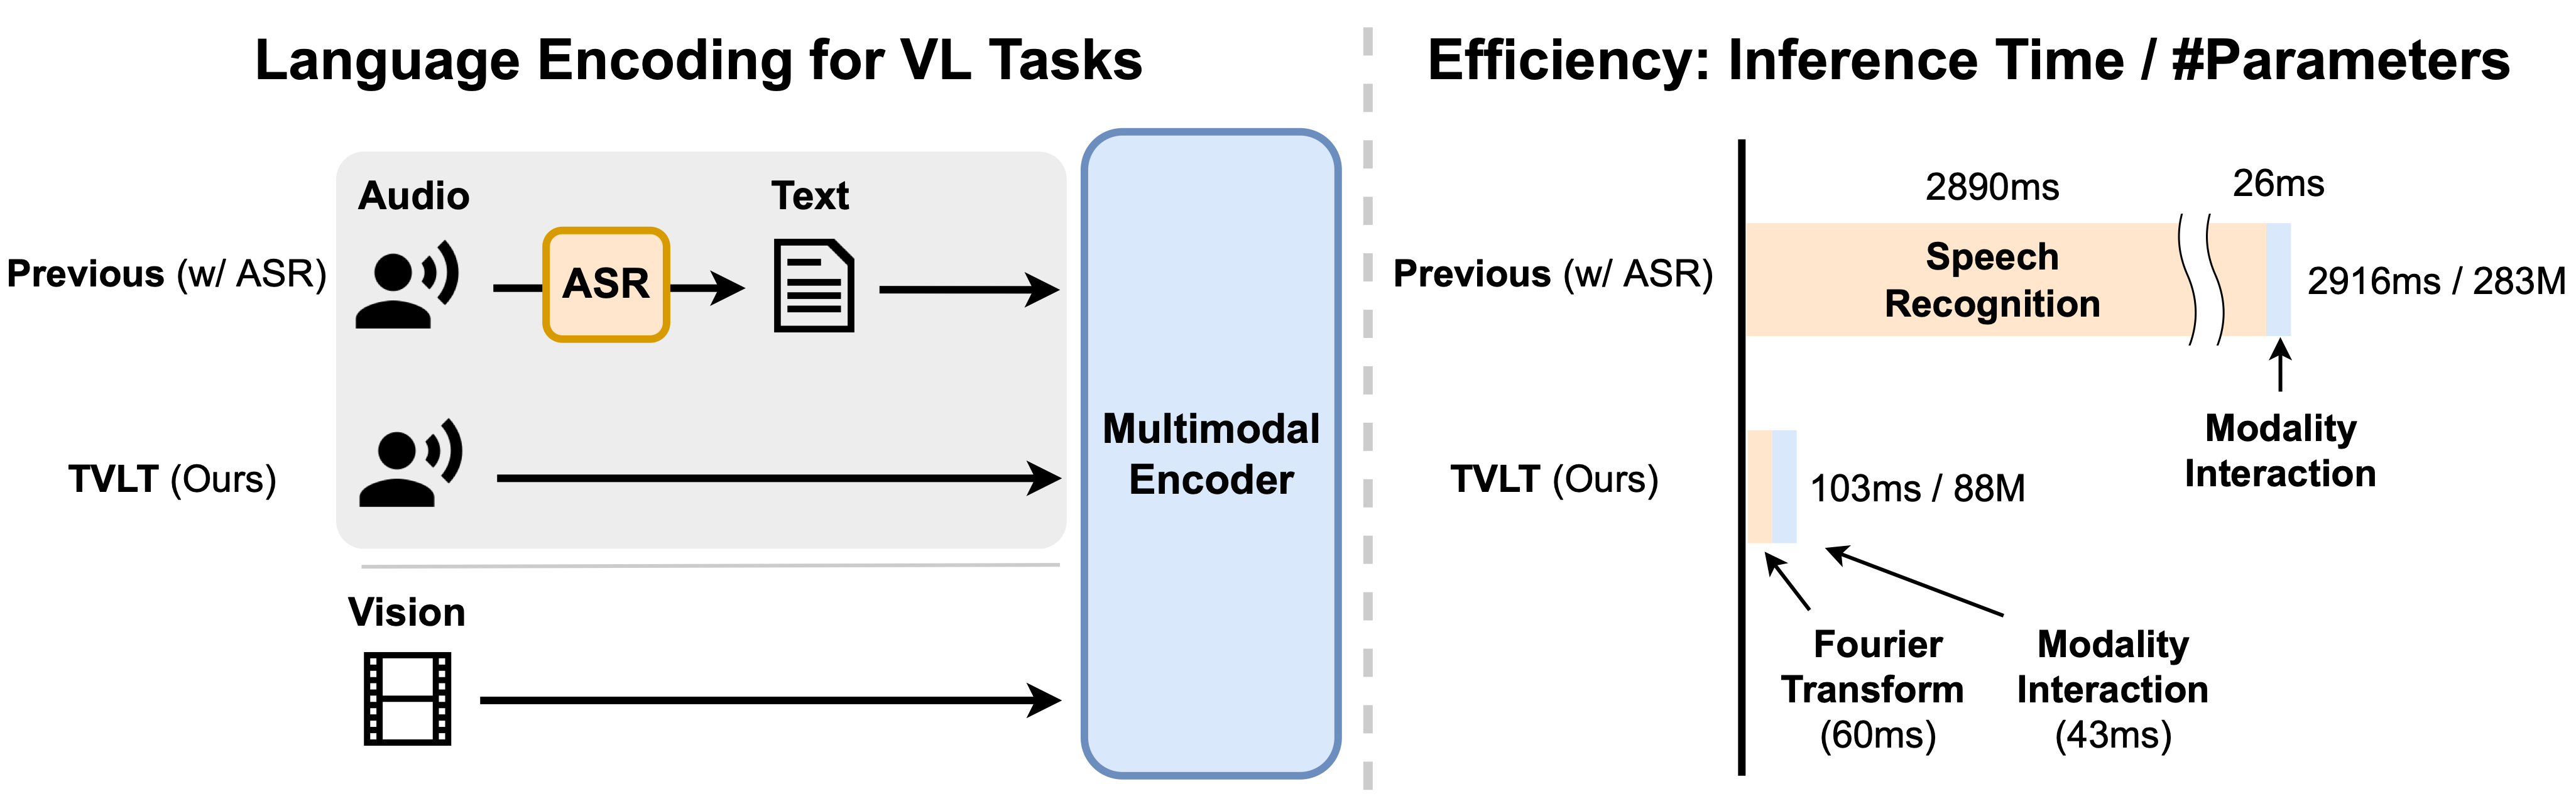
[2209.14156] TVLT: Textless Vision-Language Transformer
Figure 3 from Vision-Language Transformer and Query Generation for ...
A Single Transformer for Scalable Vision-Language Modeling | AI ...
Generalized Visual Language Models | Lil'Log
ViLT Vision-and-Language Transformer Without Convolution or Regi - 哔哩哔哩
Transformers Transforming the Field of Computer Vision - SemiWiki
Figure 2 from Vision-Language Transformer and Query Generation for ...
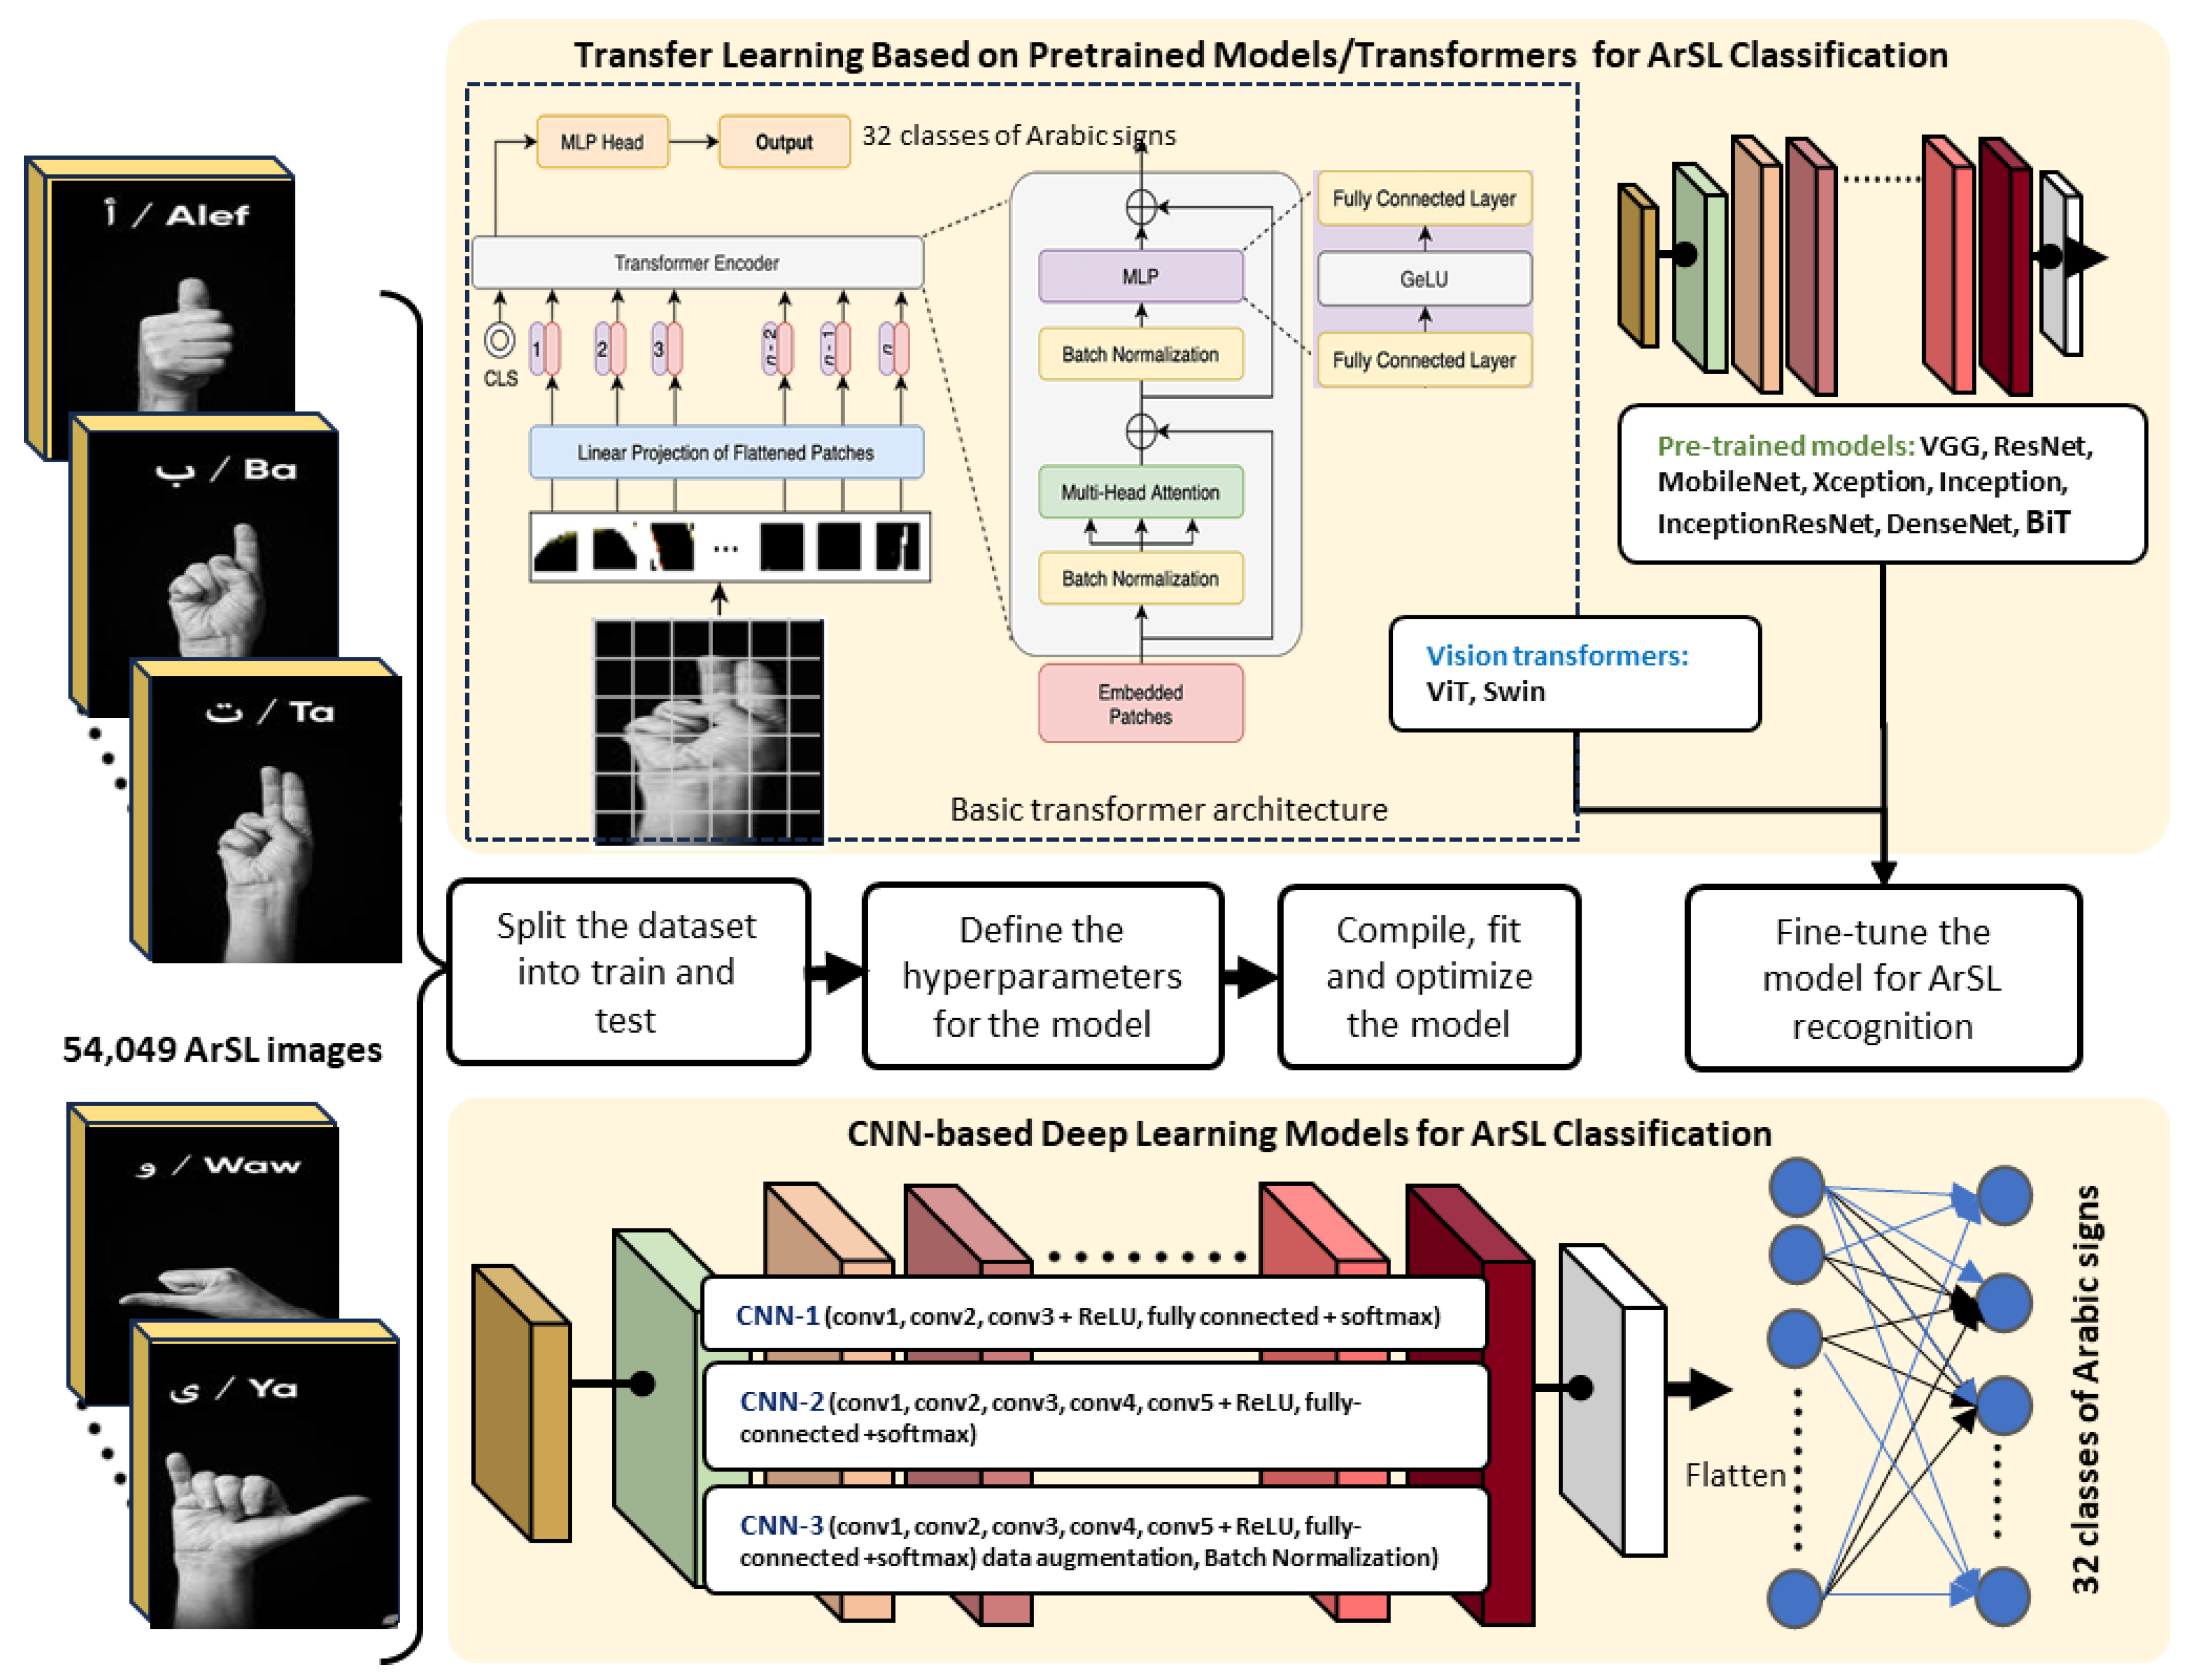
Vision Transformers and Transfer Learning Approaches for Arabic Sign ...
HSVLT: Hierarchical Scale-Aware Vision-Language Transformer for Multi ...
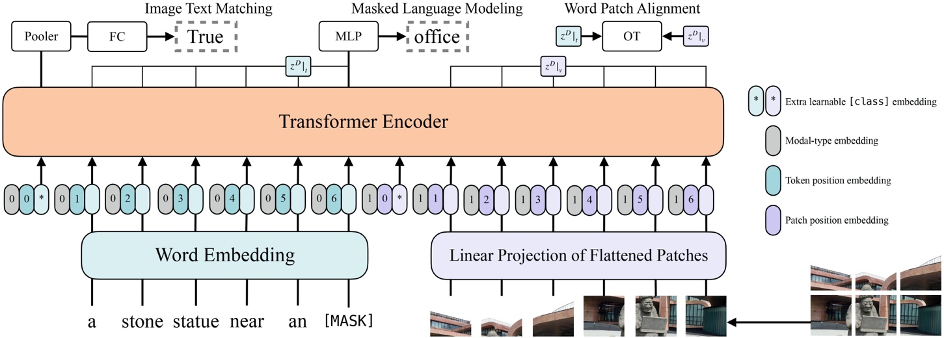
An In-Depth Exploration of the Vision-and-Language Transformer (ViLT ...
Figure 1 from History Aware Multimodal Transformer for Vision-and ...
Figure 1 from Visual-Language Transformer for Referring Video Object ...
Figure 1 from VAuLT: Augmenting the Vision-and-Language Transformer for ...
VLMT: Vision-Language Multimodal Transformer for Multimodal Multi-hop ...
Figure 2 from Vision-Language Transformer for Interpretable Pathology ...
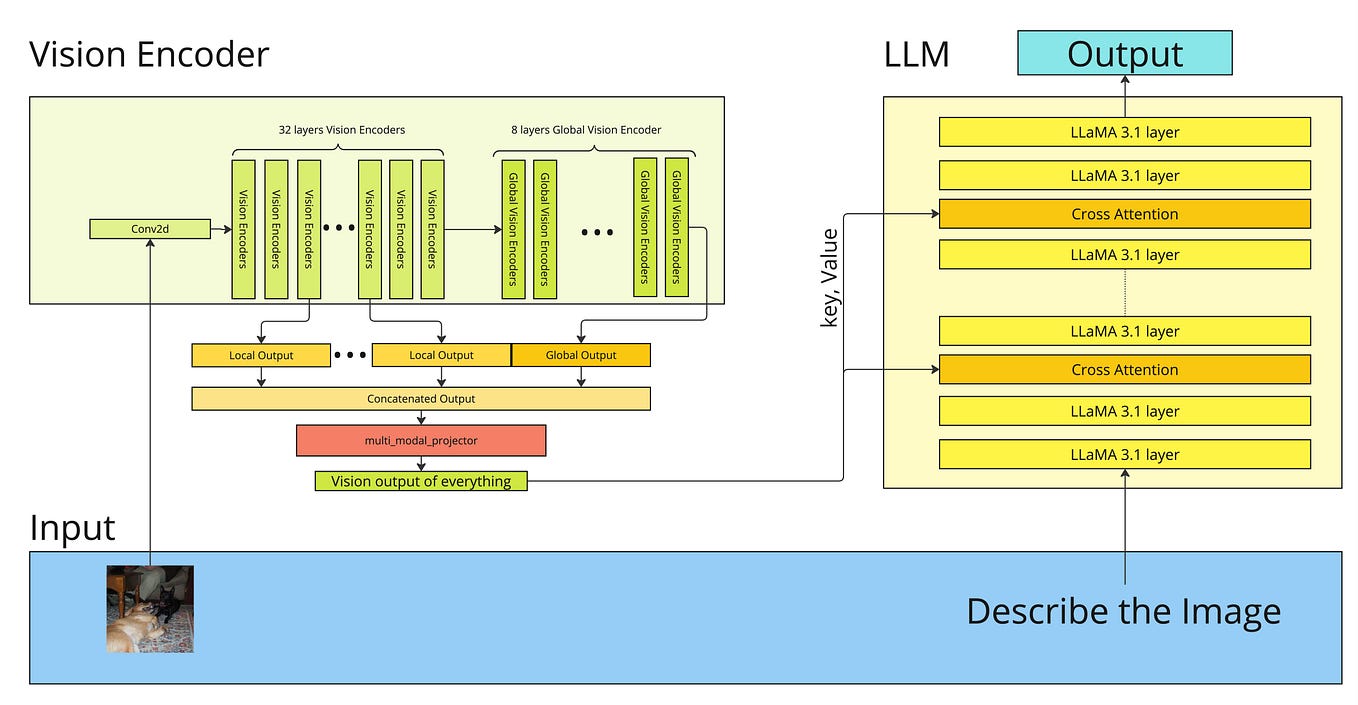
A Guide to Implement the Vision Encoder for LLaVA | Medium
Figure 2 from Visual-Language Transformer for Referring Video Object ...
Vision Transformers, Explained. A Full Walk-Through of Vision… | by ...
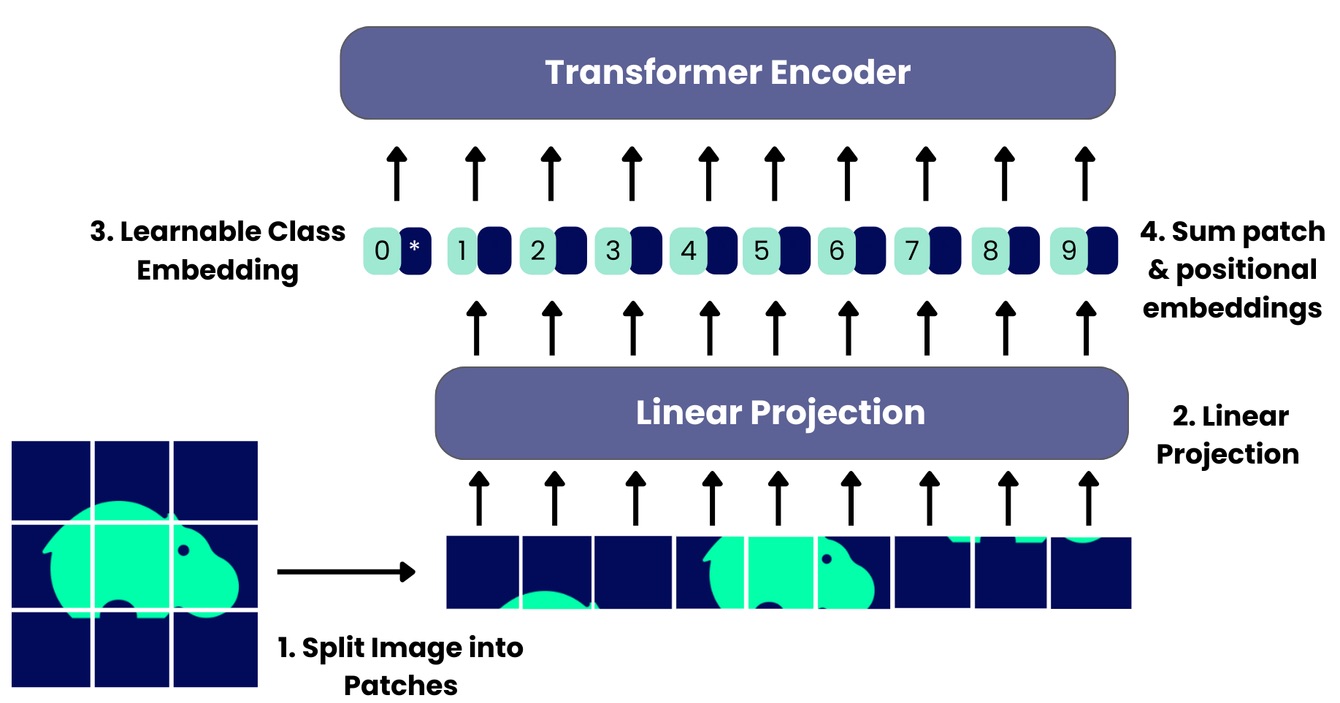
An Image Is Worth 16×16 Words — Vision Transformers — A Visual Walkthrough
[VL | RIS] VLT:Vision-Language Transformer and Query Generation for ...
[略读]FROZEN TRANSFORMERS IN LANGUAGE MODELSARE EFFECTIVE VISUAL ENCODER ...
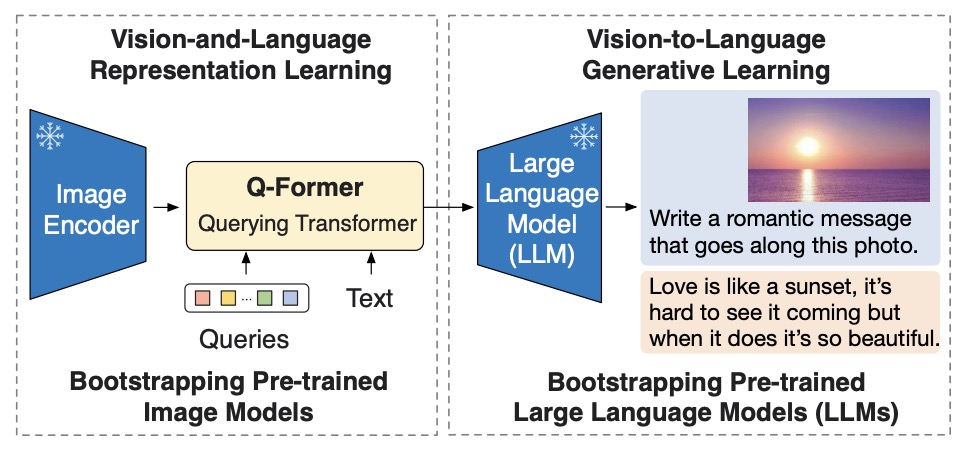
Bootstrapping vision–language transformer for monocular 3D visual ...
(PDF) VoLTA: Vision-Language Transformer with Weakly-Supervised Local ...
PAMI2023: VLT: Vision-Language Transformer and Query Generation for ...
Vision Transformers: From Idea to Applications (Part Four)
Figure 3 from FashionVLM - Fashion Captioning Using Pretrained Vision ...
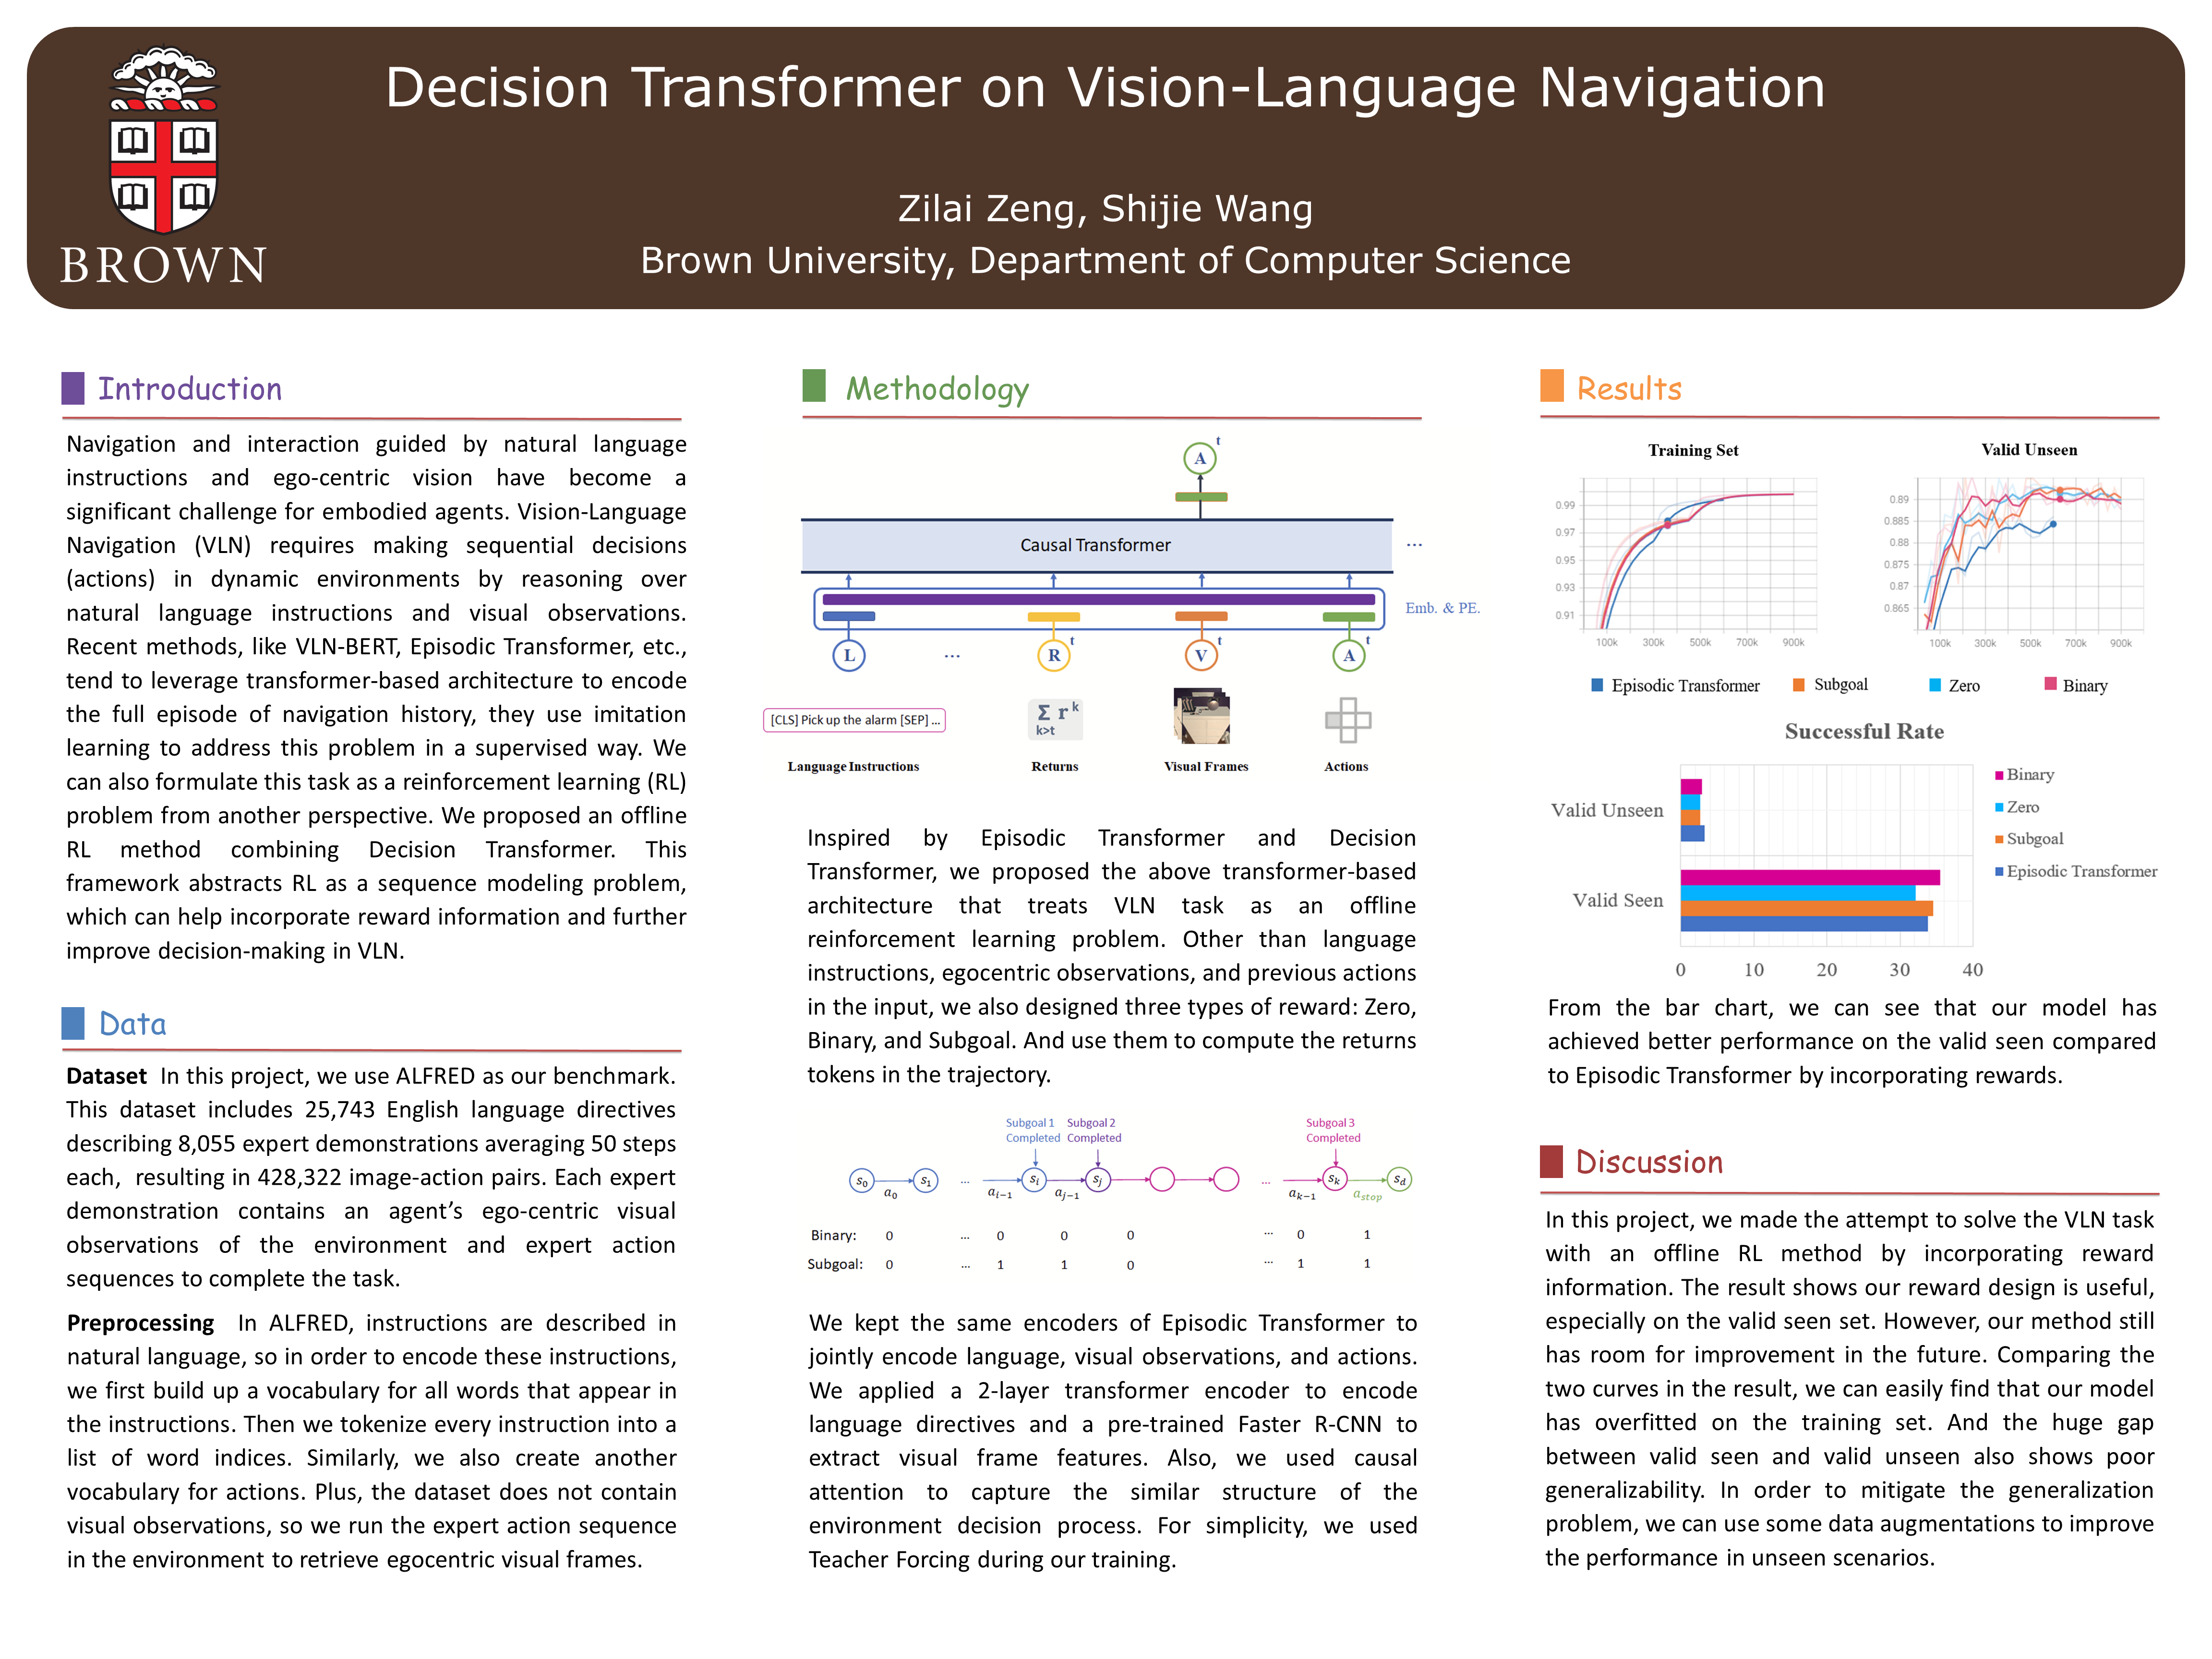
Decision Transformer on Vision-Language Navigation | Devpost
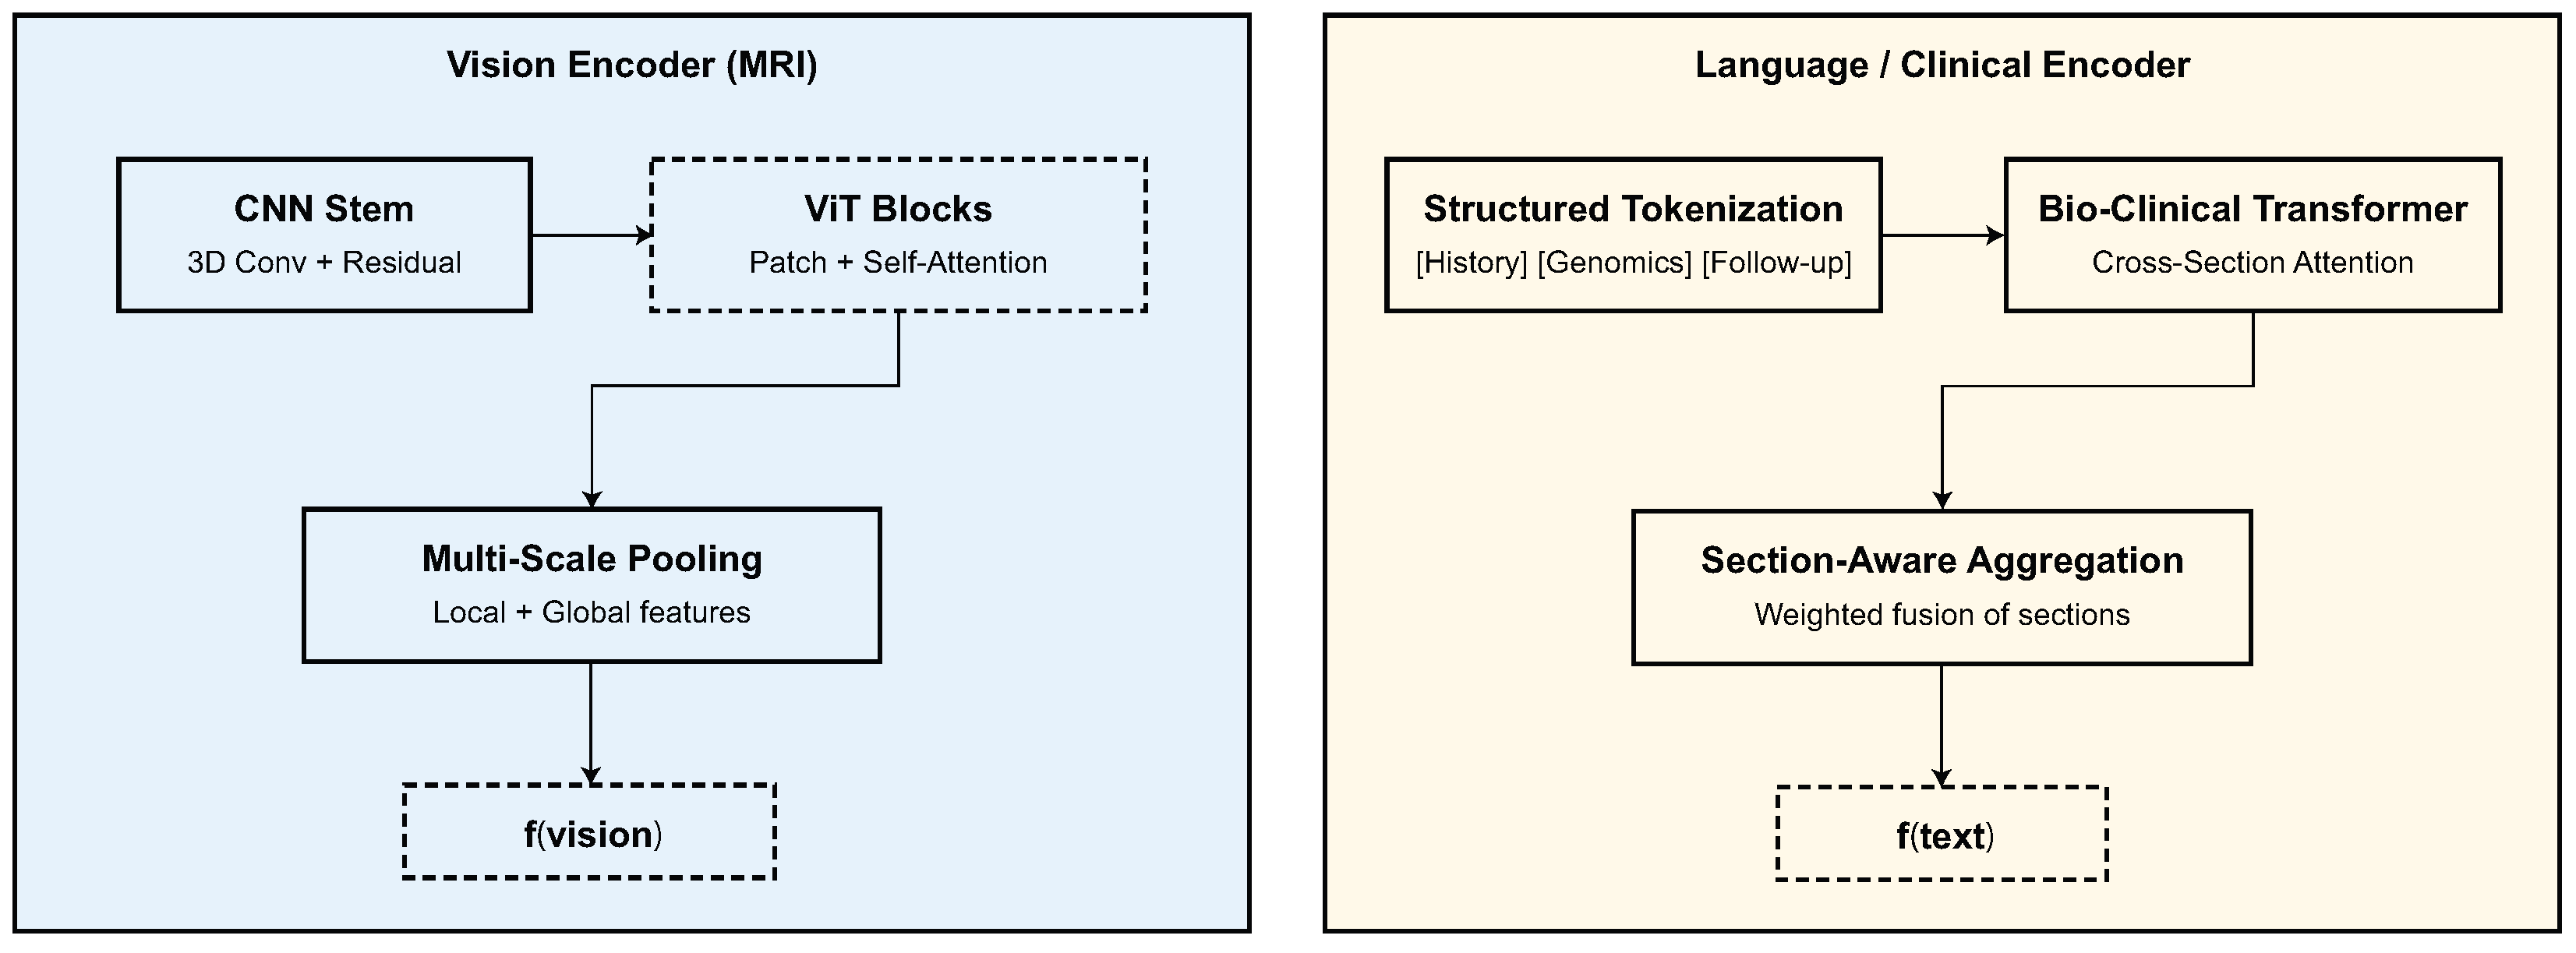
Adaptive Vision–Language Transformer for Multimodal CNS Tumor Diagnosis
How do Vision Transformers Work? Architecture Explained | Codecademy
(PDF) VLDeformer: Learning Visual-Semantic Embeddings by Vision ...
Actra: Optimized Transformer Architecture for Vision-Language-Action ...
GitHub - GewelsJI/MVLT: Masked Vision-Language Transformer in Fashion ...
Figure 4 from Vision-Language Transformer and Query Generation for ...
(PDF) Masked Vision-language Transformer in Fashion
COST: Contrastive One-Stage Transformer for Vision-Language Small ...
Comparing Vision Transformers and Convolutional Neural Networks for ...
TVLT: Textless Vision-Language Transformer | Jaemin Cho
Tensor-To-Image: Image-To-Image Translation With Vision Transformers – VLIB
Vision Transformers Explained at Hunter Berry blog
Advancements in Vision–Language Models for Remote Sensing: Datasets ...
Why do we need transformers for vision?
[논문 리뷰] GCS-M3VLT: Guided Context Self-Attention based Multi-modal ...
Overall architecture of the Unified Vision-language Hashing ...
Figure 1 from VL-InterpreT: An Interactive Visualization Tool for ...
UNC Chapel Hill’s Textless Vision-Language Transformer: Comparable ...
VLT:Vision-Language Transformer用于引用的视觉语言转换和查询生成分割-CSDN博客
Vision-Language的几篇工作:向更简便更scale的路 - 知乎
Figure 1 from HSVLT: Hierarchical Scale-Aware Vision-Language ...
RT-2: Vision-Language-Action Models
image
Figure 11 from Intriguing Differences Between Zero-Shot and Systematic ...
Joe99/visionlanguageTransformer · Hugging Face
Vision-Language-Action Models and the Search for a Generalist Robot Policy
(Previous work) The mainstream approaches for vision-language modeling ...
Unified Vision-Language Pre-Training for Image Captioning and VQA - 知乎
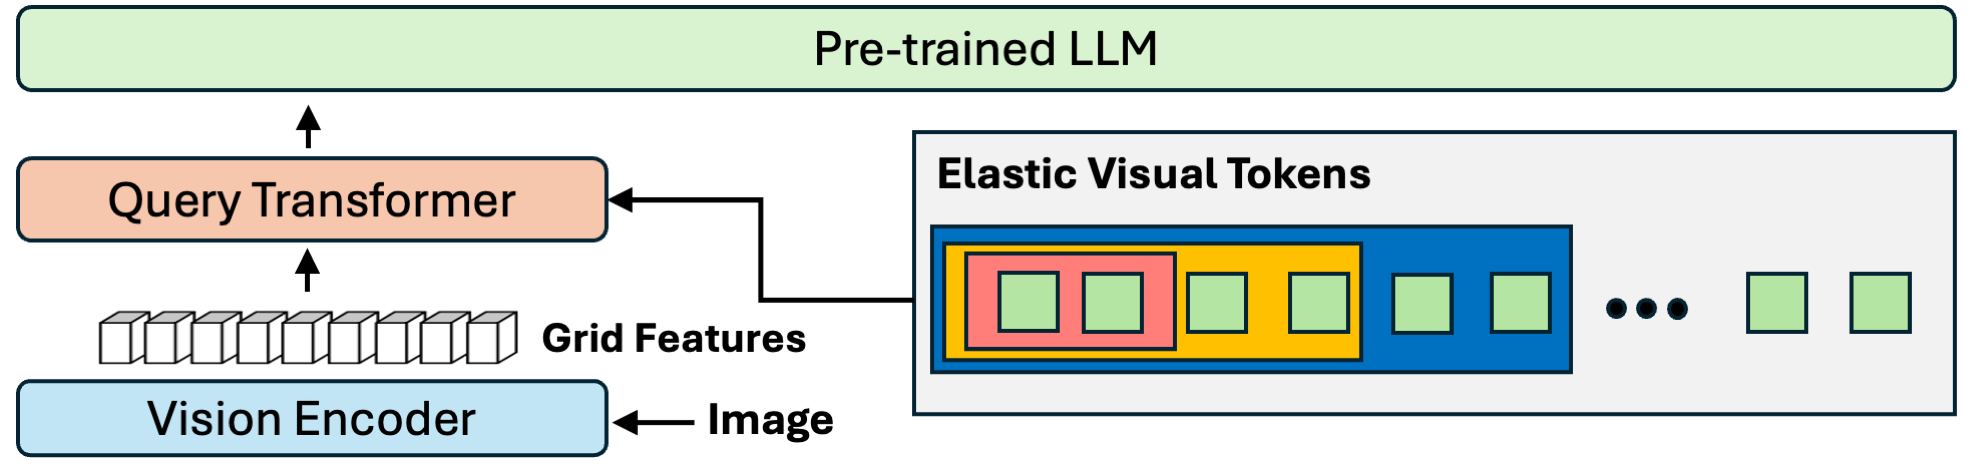
Matryoshka Query Transformers For Large Vision-Language Models ...
Beyond Language: Transformers for Vision, Audio, and Multimodal AI
Applications of Vision-Language Models - Real World Use Cases
This Artificial Intelligence Research Introduces A Vision-Language ...
CMC | Free Full-Text | A Review on Vision-Language-Based Approaches ...
BRIDGETOWER: A Novel Transformer-based Vision-Language VL Model that ...
[2312.04231] Adventures of Trustworthy Vision-Language Models: A Survey
Figure 2 from Training Vision-Language Transformers from Captions Alone ...
Paper page - A Spark of Vision-Language Intelligence: 2-Dimensional ...
[论文评述] M3ET: Efficient Vision-Language Learning for Robotics based on ...
Masked Vision-Language Transformers for Scene Text Recognition
Figure 2 from DPL: Decoupled Prototype Learning for Enhancing ...
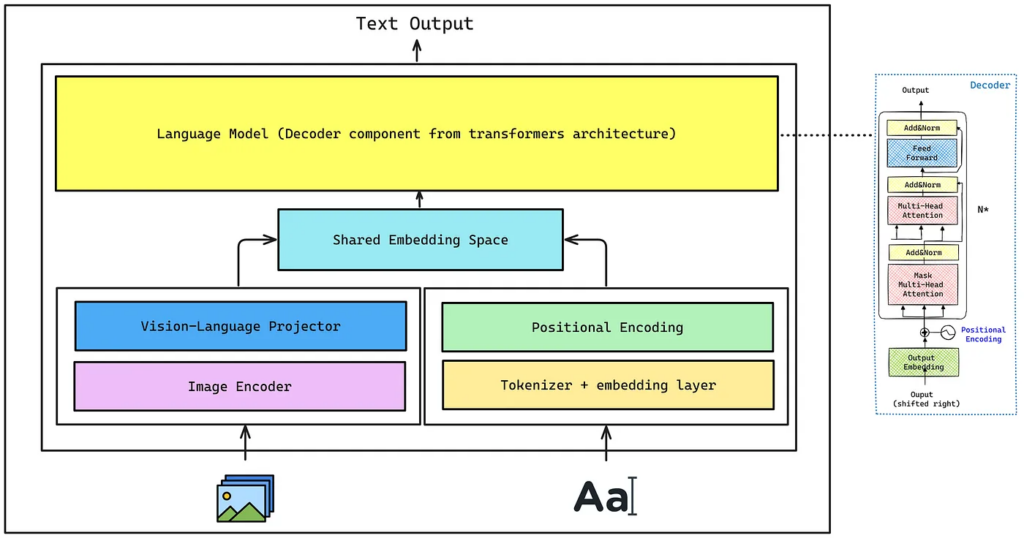
Vision-language model architecture | How it works under the hood 🔥🔥🔥 ...
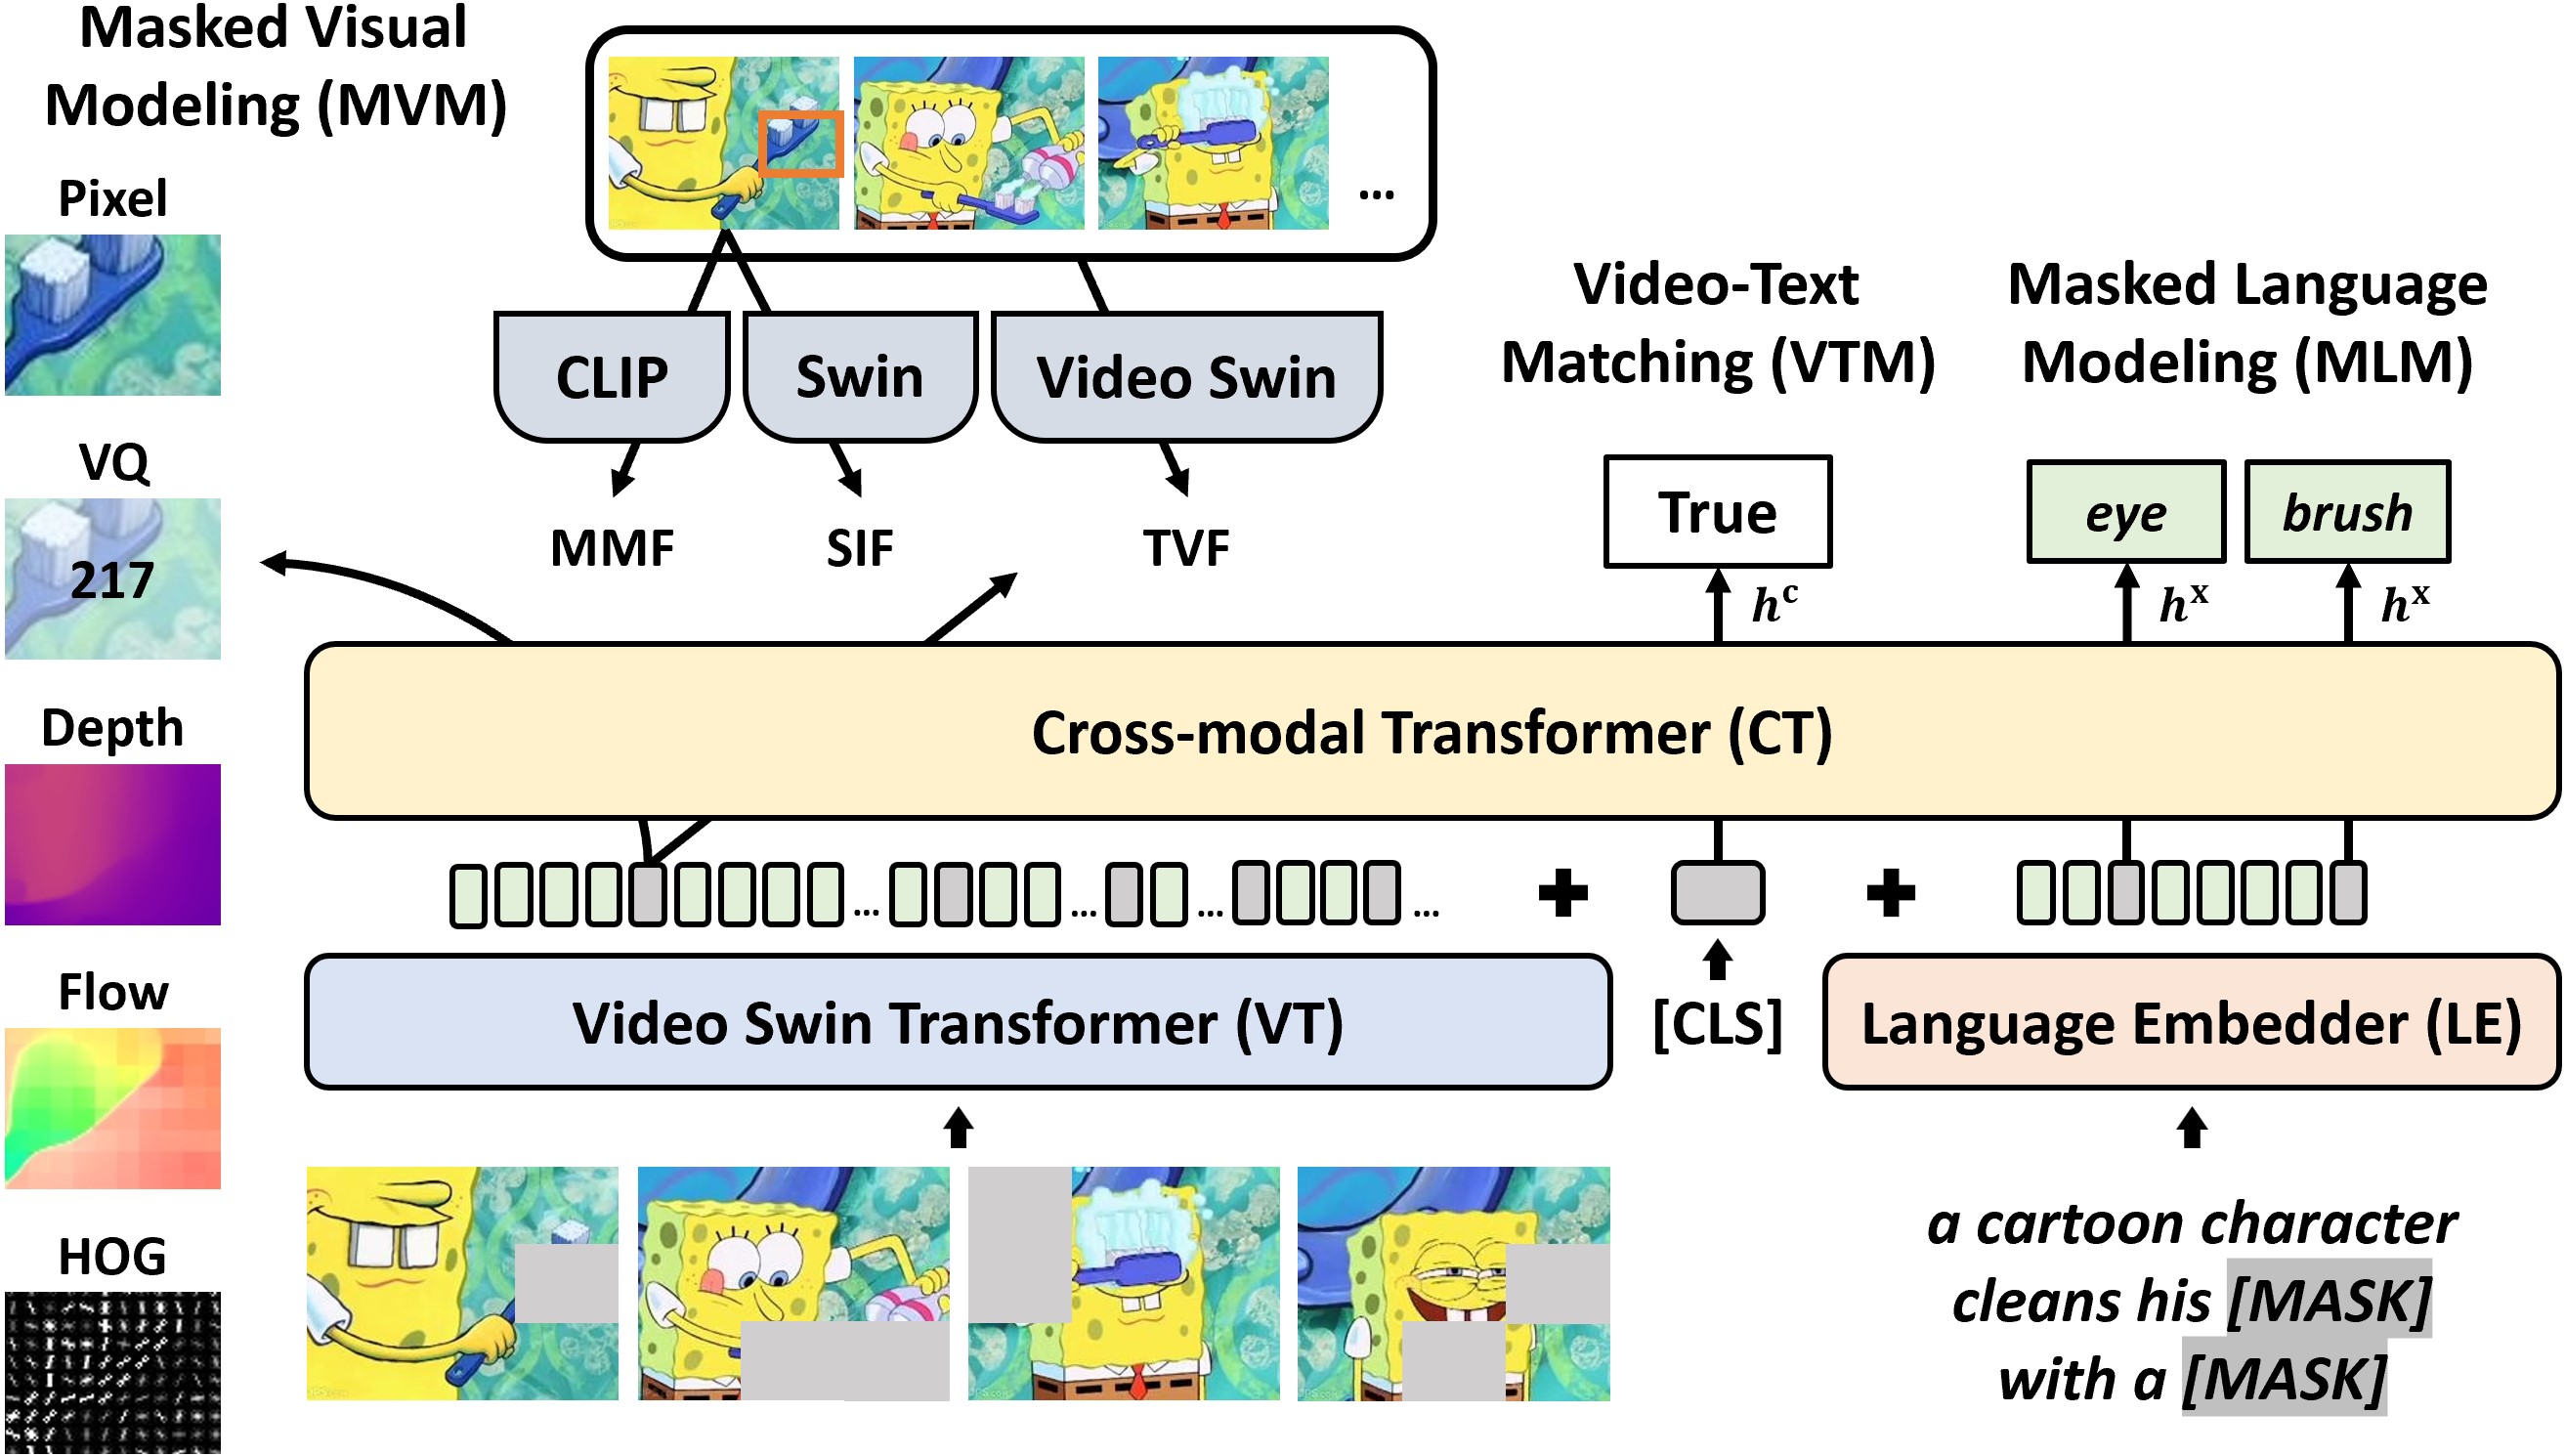
[2209.01540] An Empirical Study of End-to-End Video-Language ...
Figure 1 from Supplementary: Weakly Supervised Grounding for VQA in ...
How Vision-Language-Action Models Powering Humanoid Robots
Understanding Neural Network Regularization and Key Regularization ...