Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
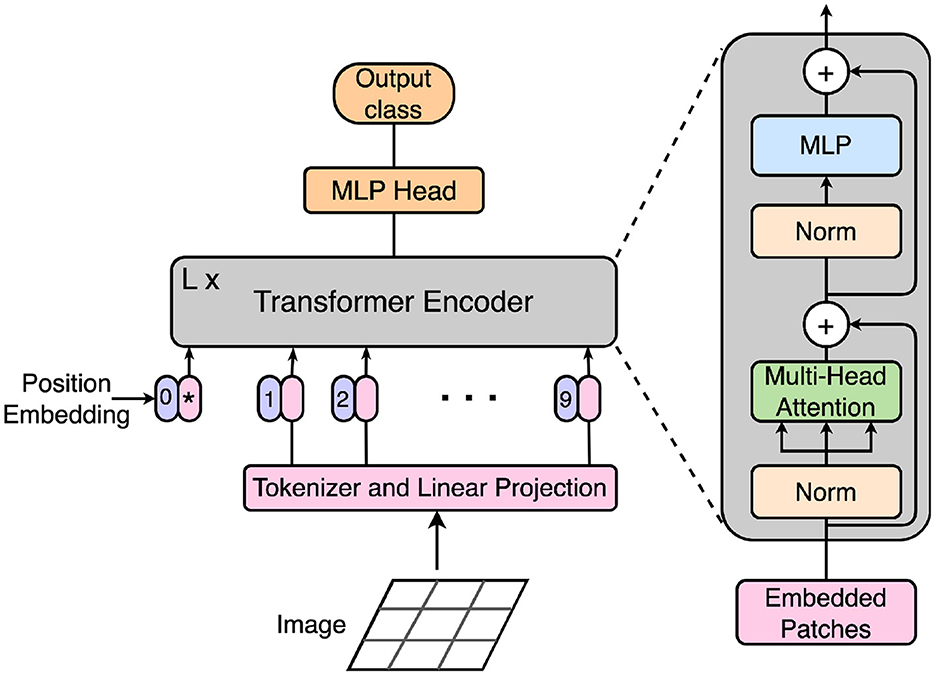
Deep learning image classification strategy. (a) ViT model architecture ...
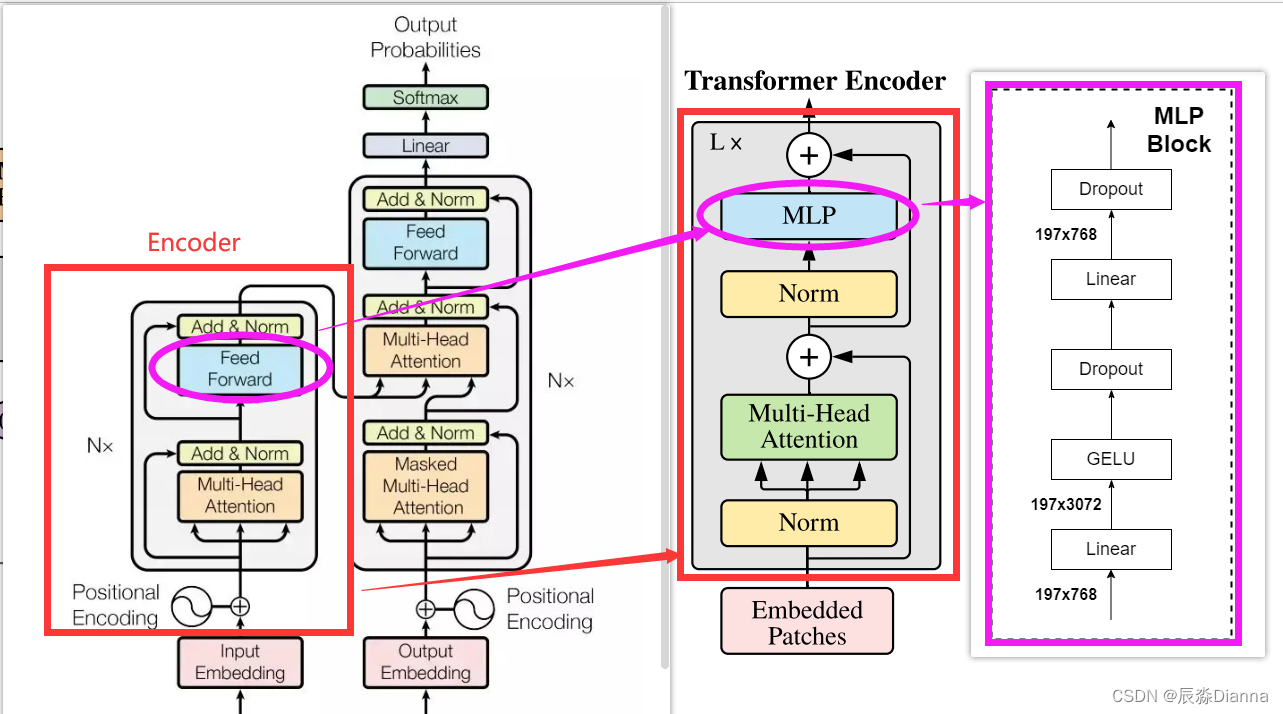
ViT model and transformer encoder [34] | Download Scientific Diagram
The Pre-Trained ViT Model. | Download Scientific Diagram
Build Your Own ViT Model from Scratch
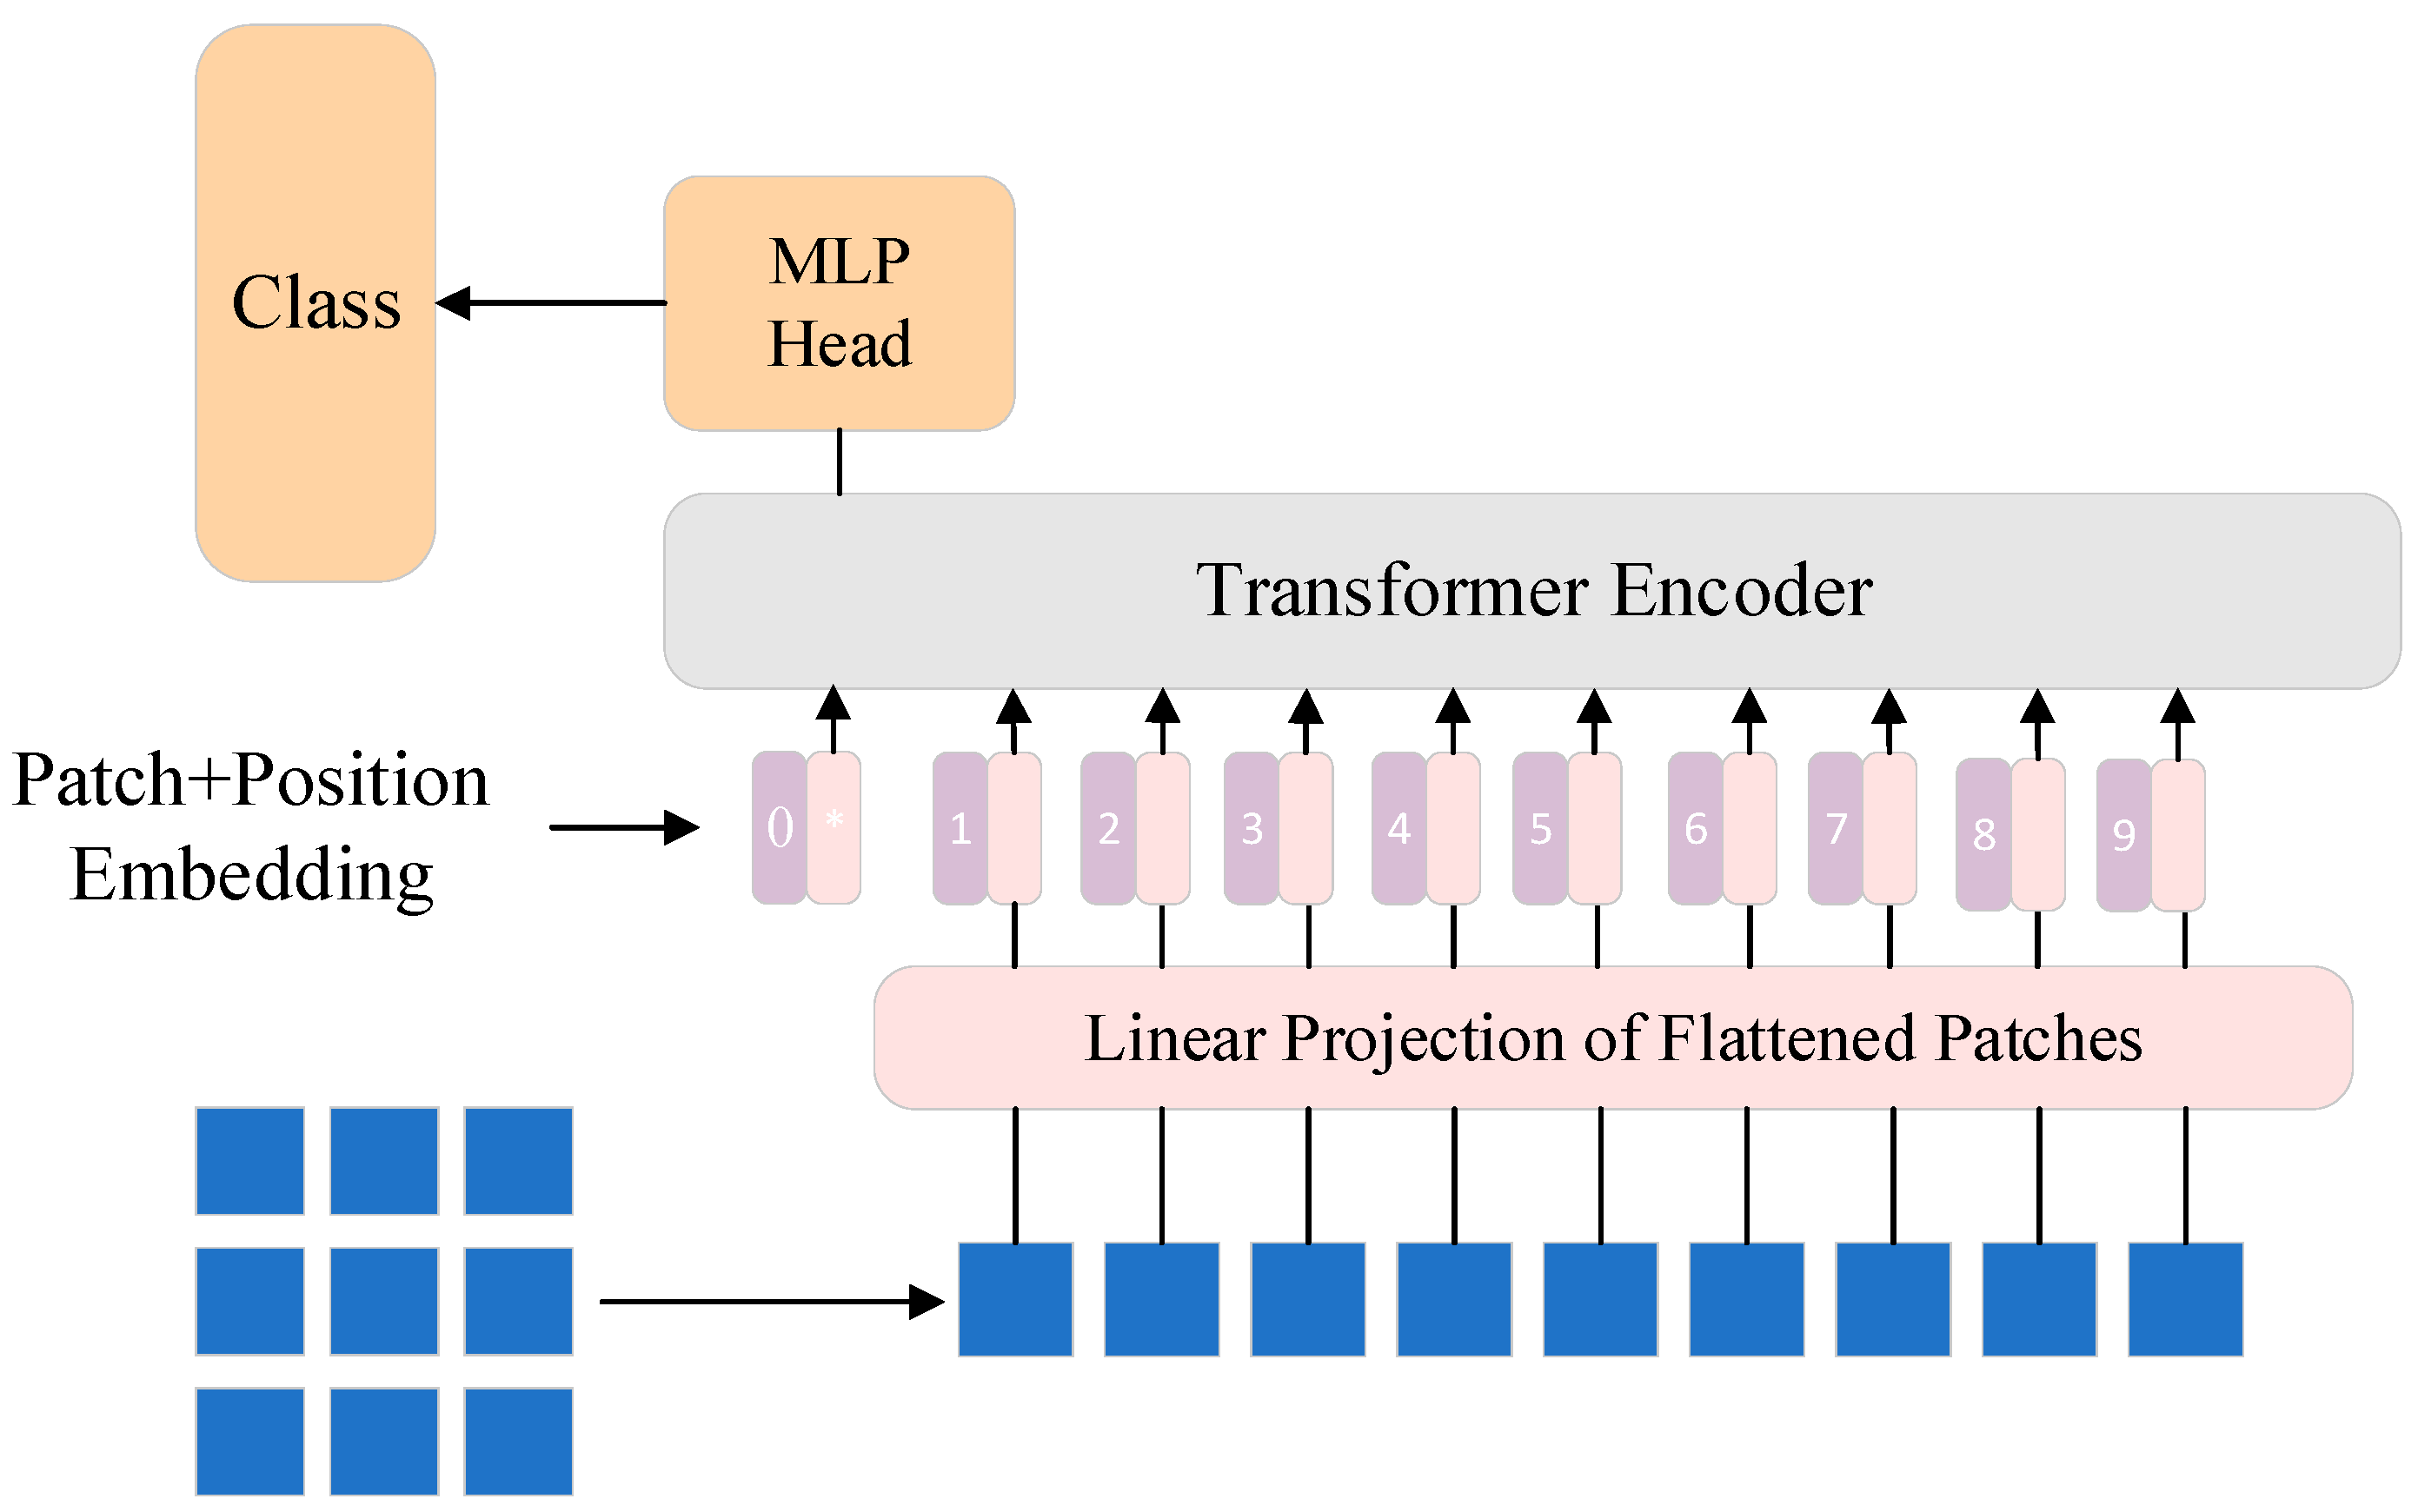
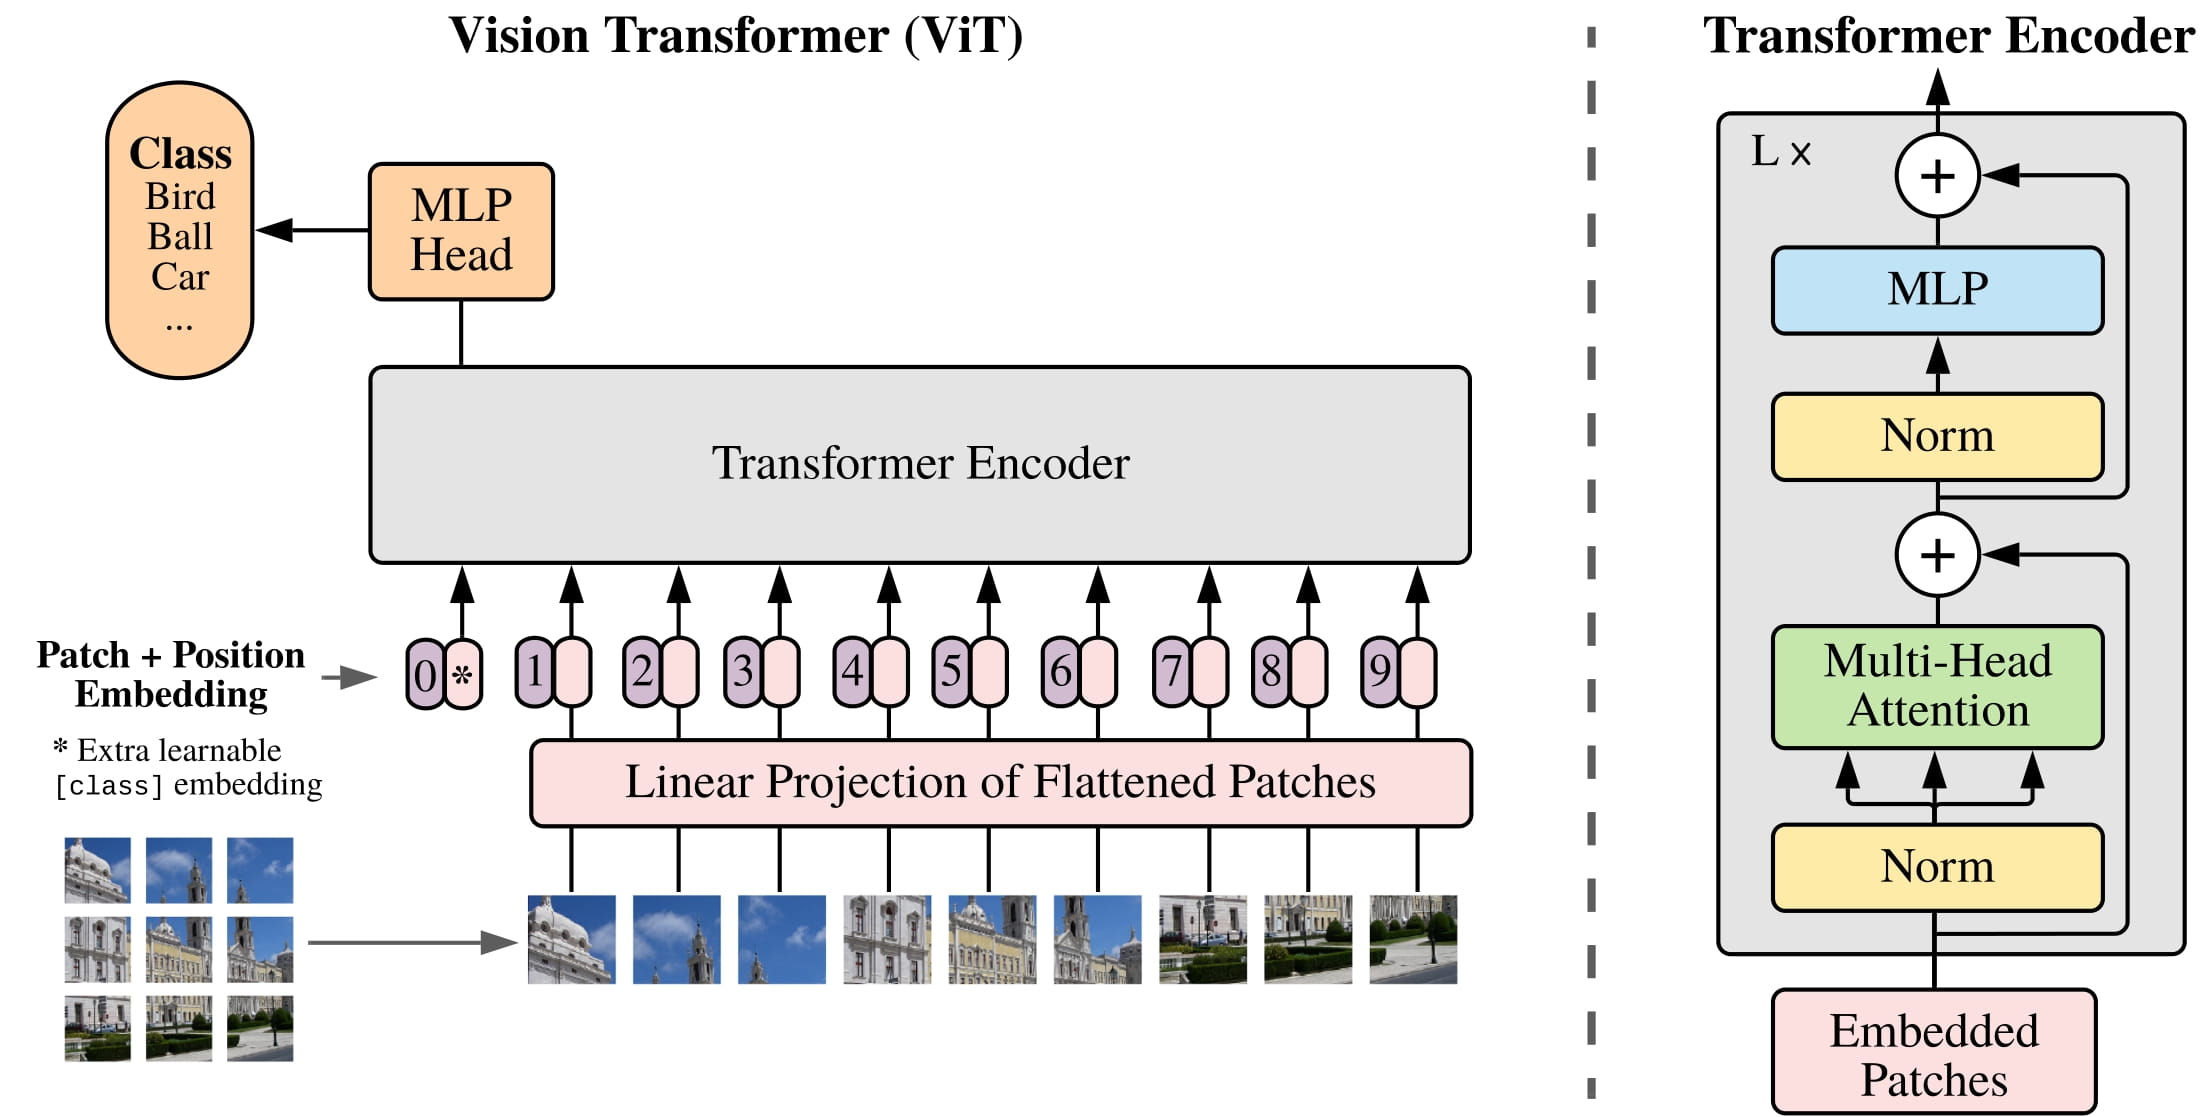
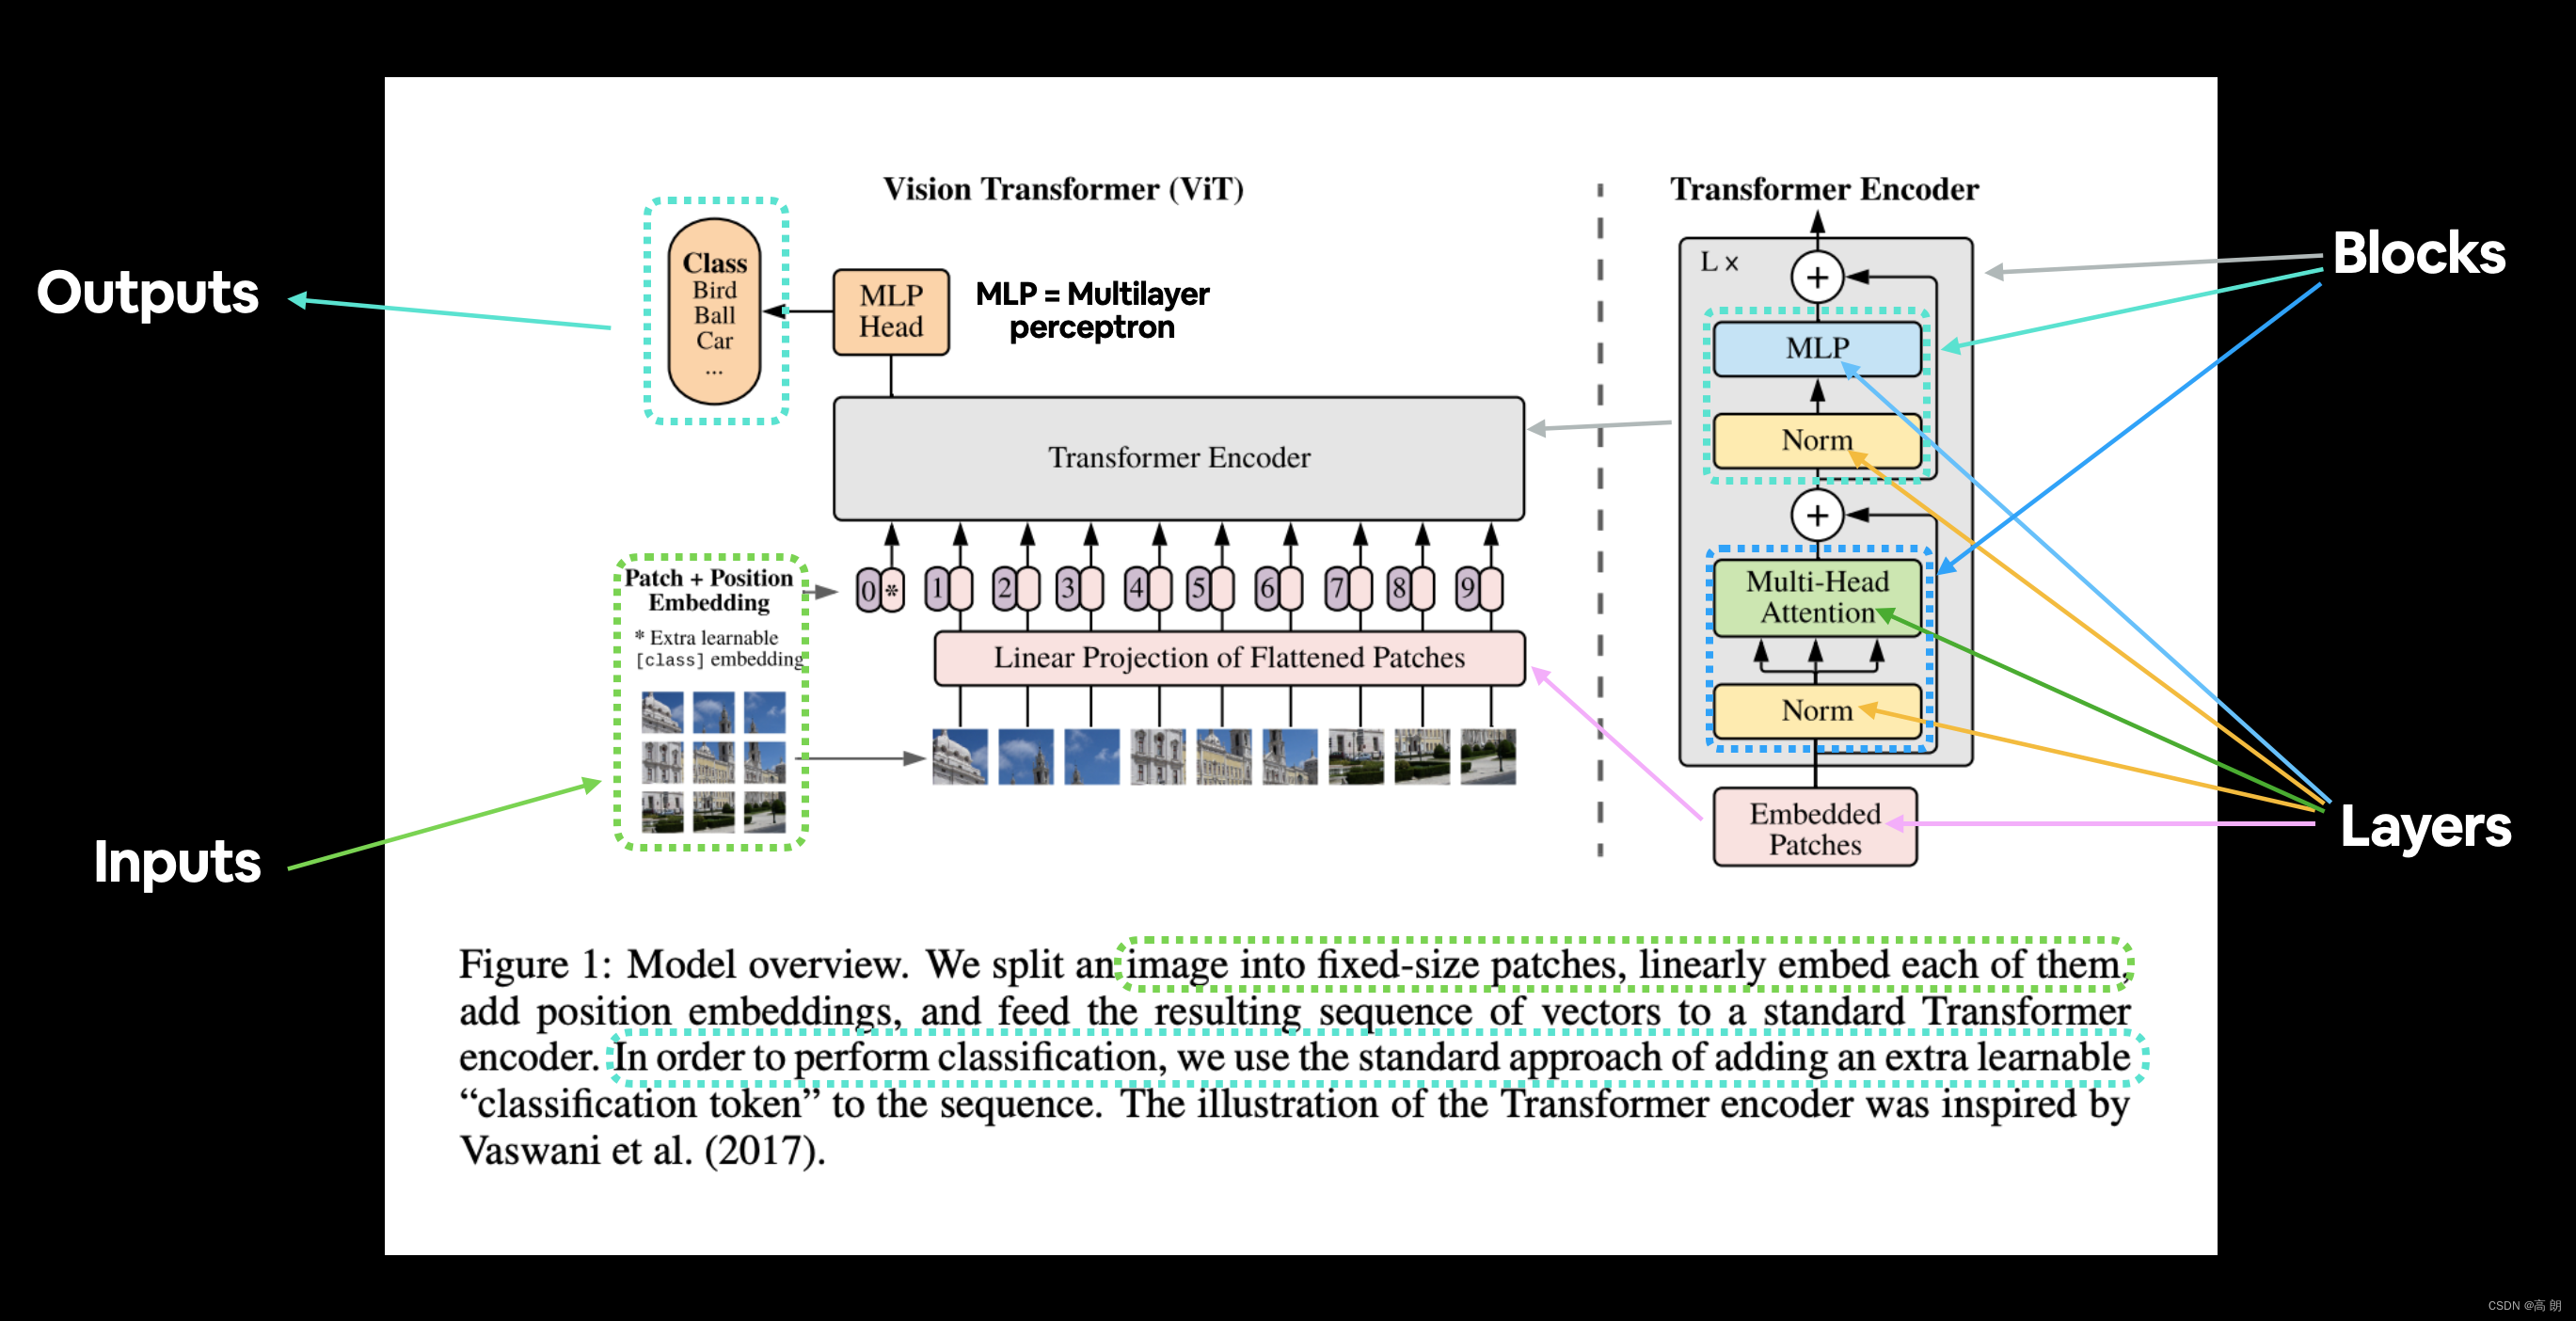
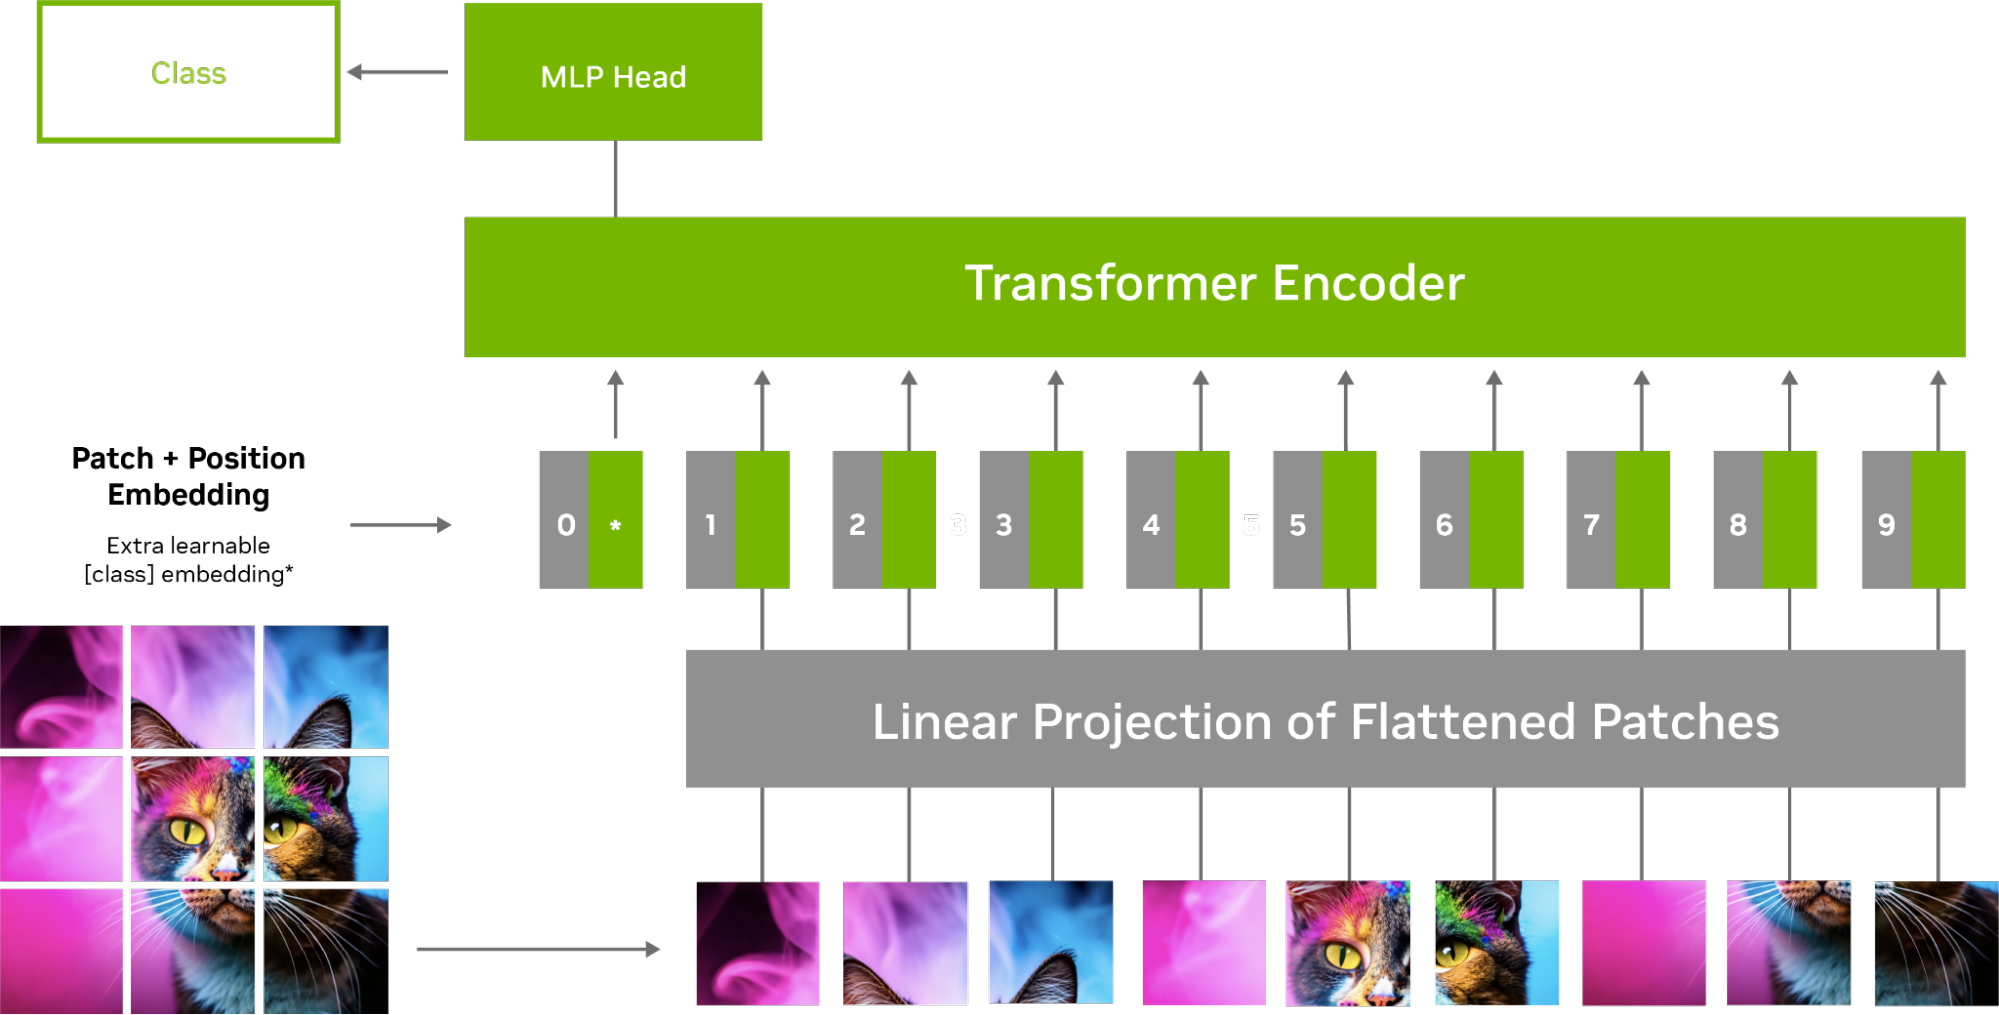
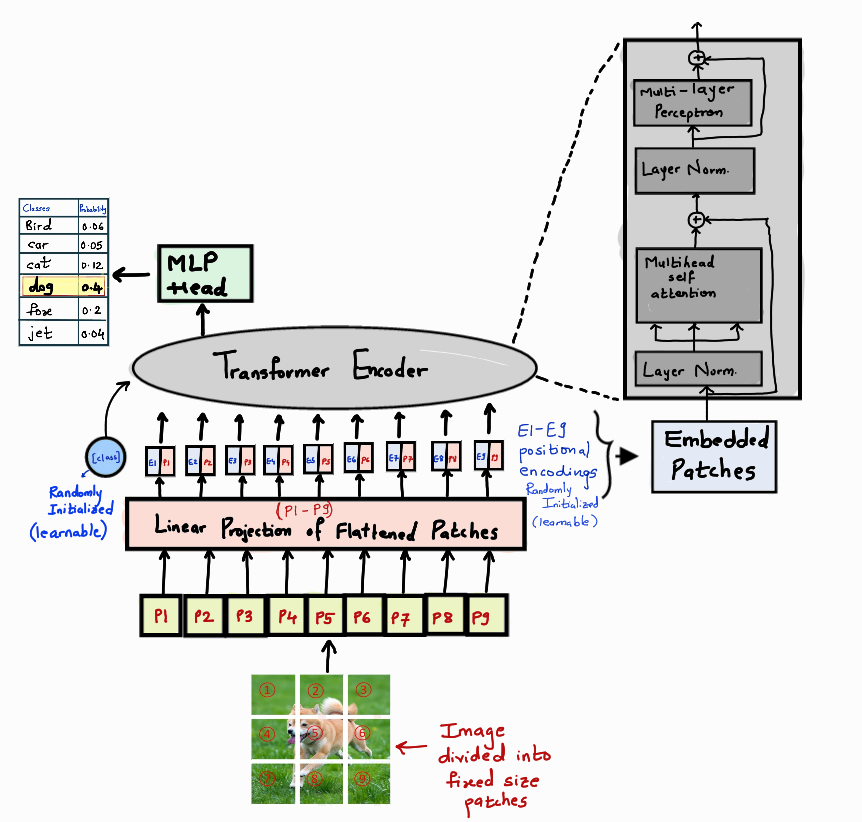
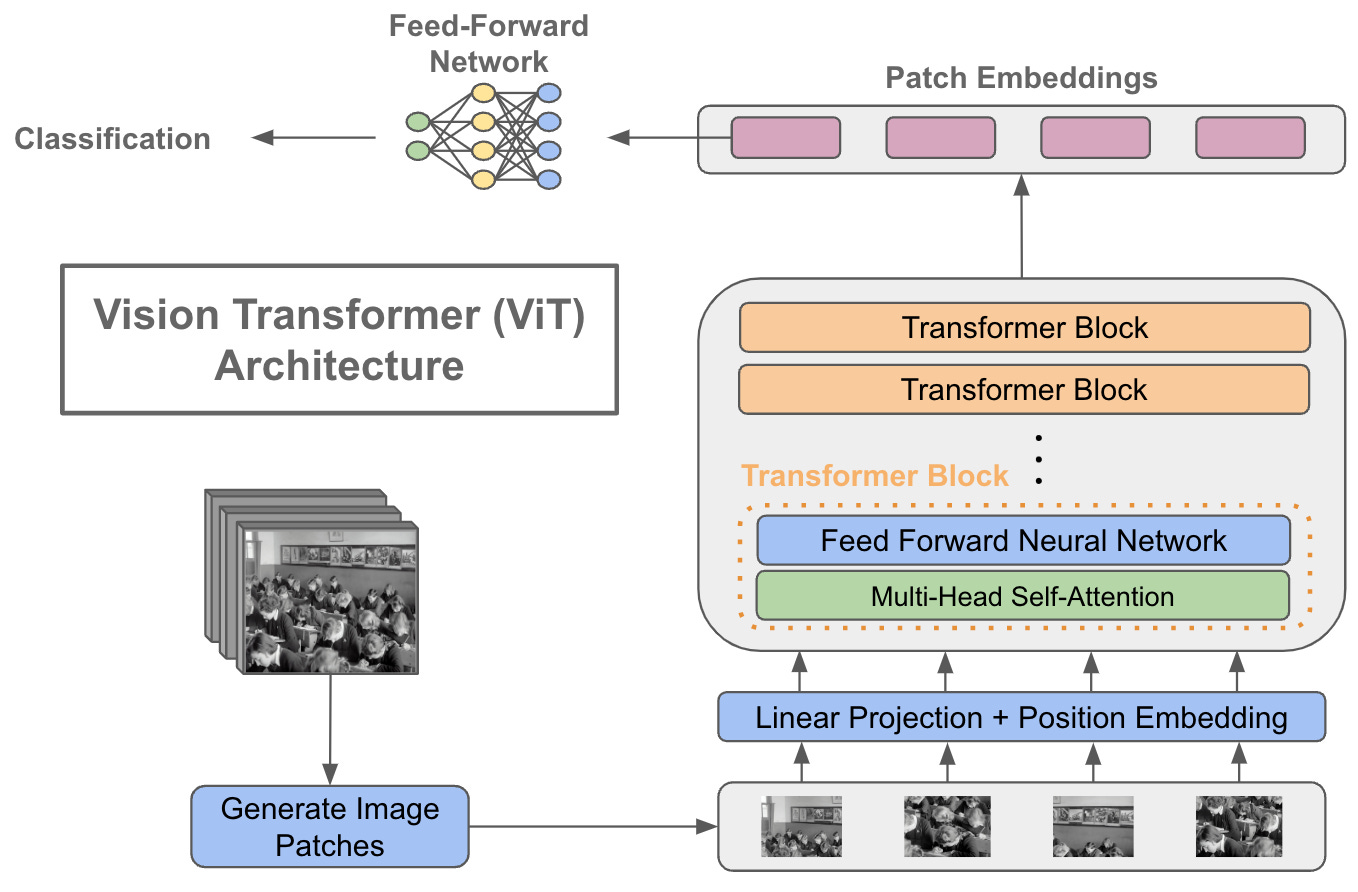
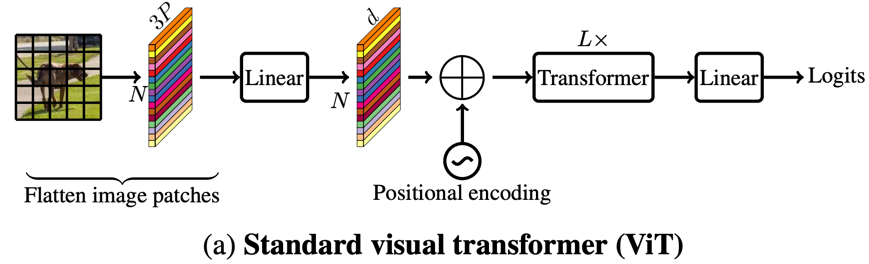
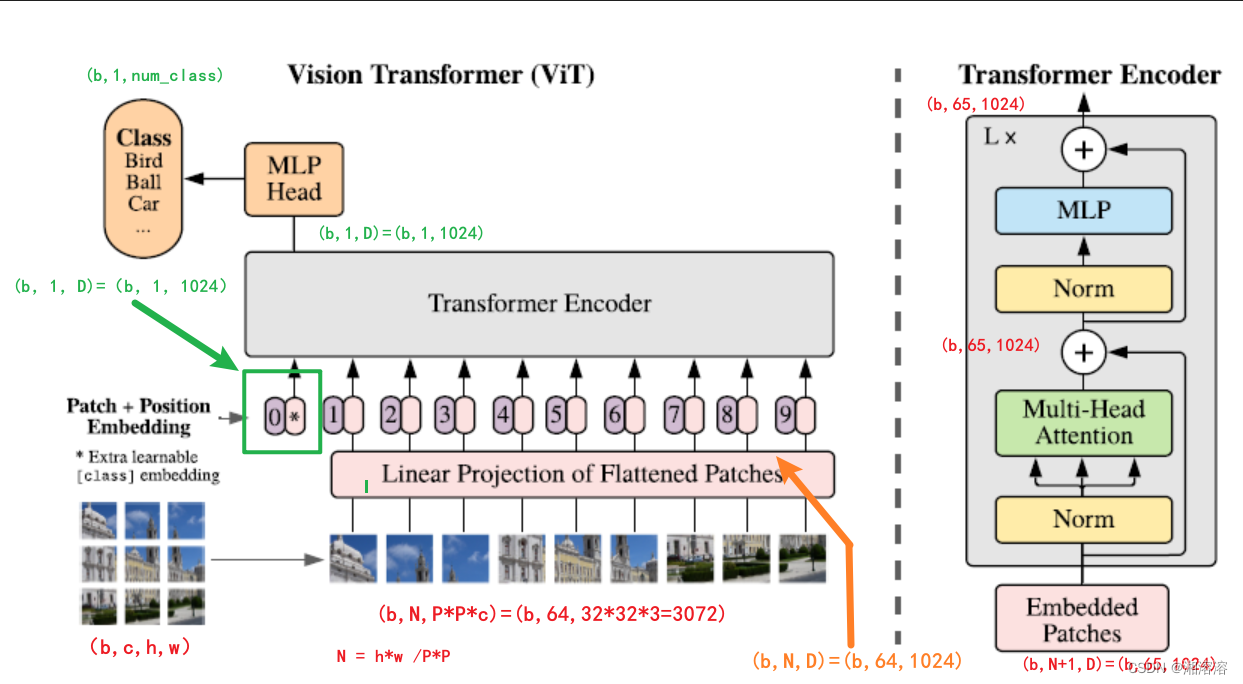
Vision Transformer (ViT) model architecture. ViT breaks the image into ...
Schematic illustration of ViT model [58] | Download Scientific Diagram
ViT model architecture. | Download Scientific Diagram
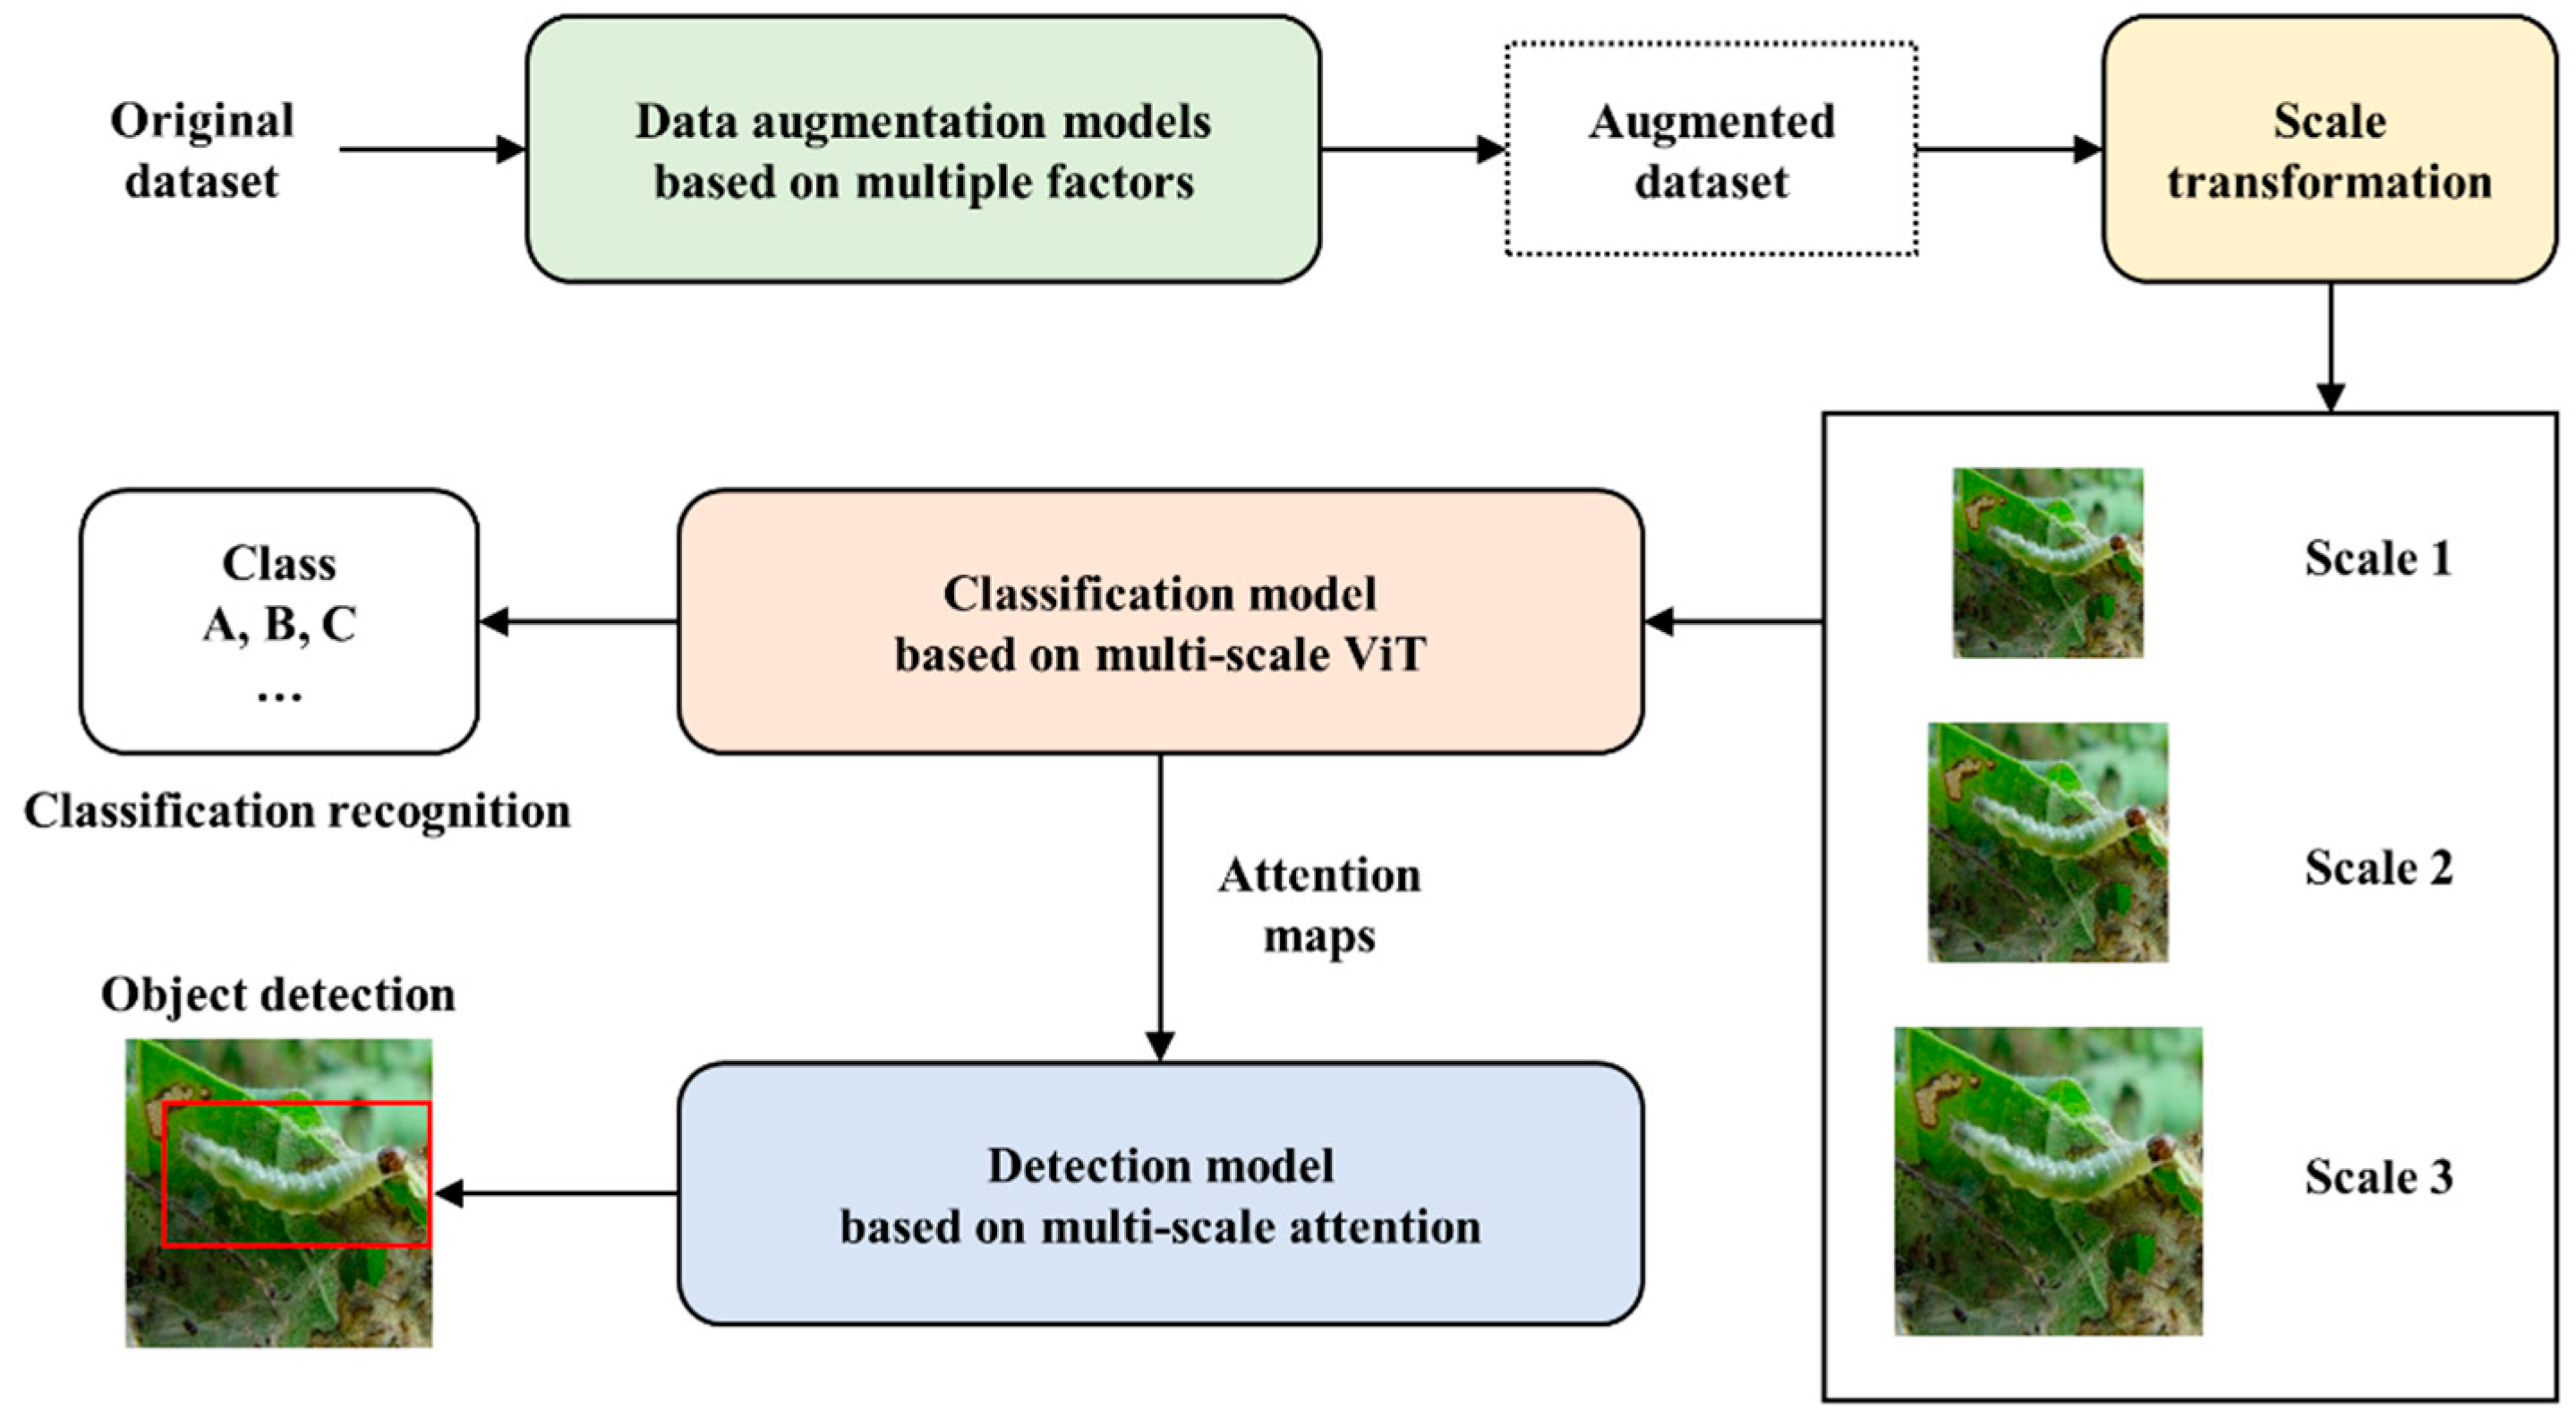
Multi-Scale and Multi-Factor ViT Attention Model for Classification and ...
shows the architecture of ViT model in detail. It is based on the model ...
The ViT model for aperture photometry feasibility assessment. The ViT ...
The ViT model extracts image feature process | Download Scientific Diagram
The 3D ViT architecture implemented in this work. | Download Scientific ...
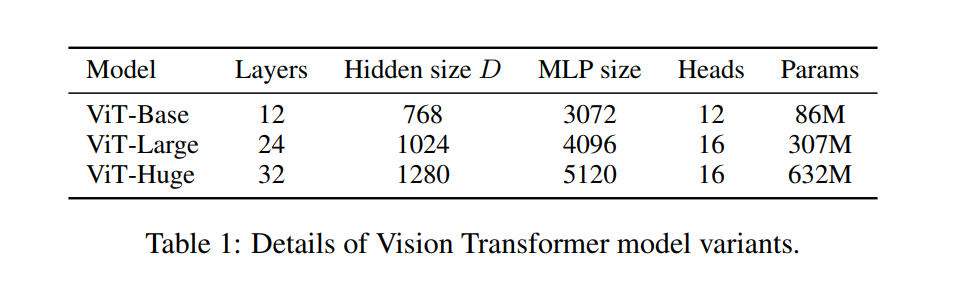
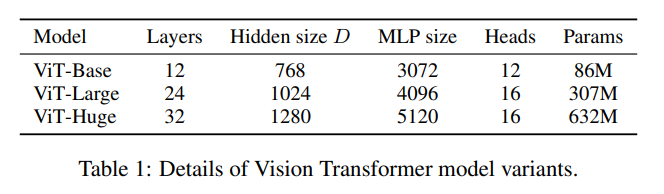
ViT 模型变体 (一) - 知乎
Vision Transformer ViT model overall architecture | Download Scientific ...
The ViT-based encoder architecture. The ViT model takes an input image ...
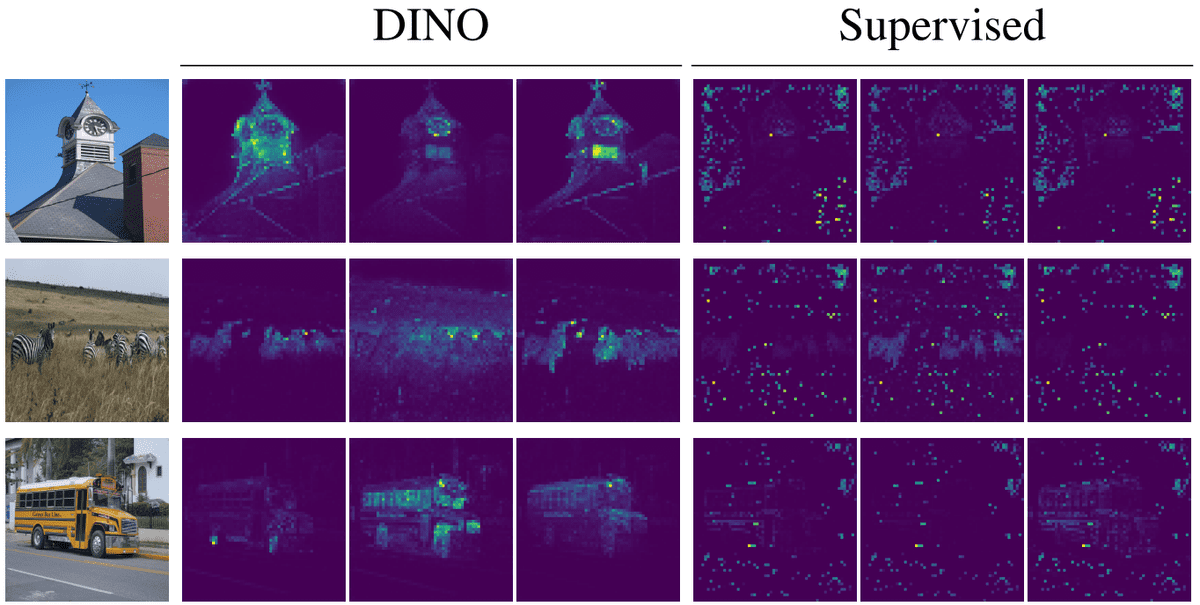
Attention map of the ViT model on sample image from the BreakHis ...
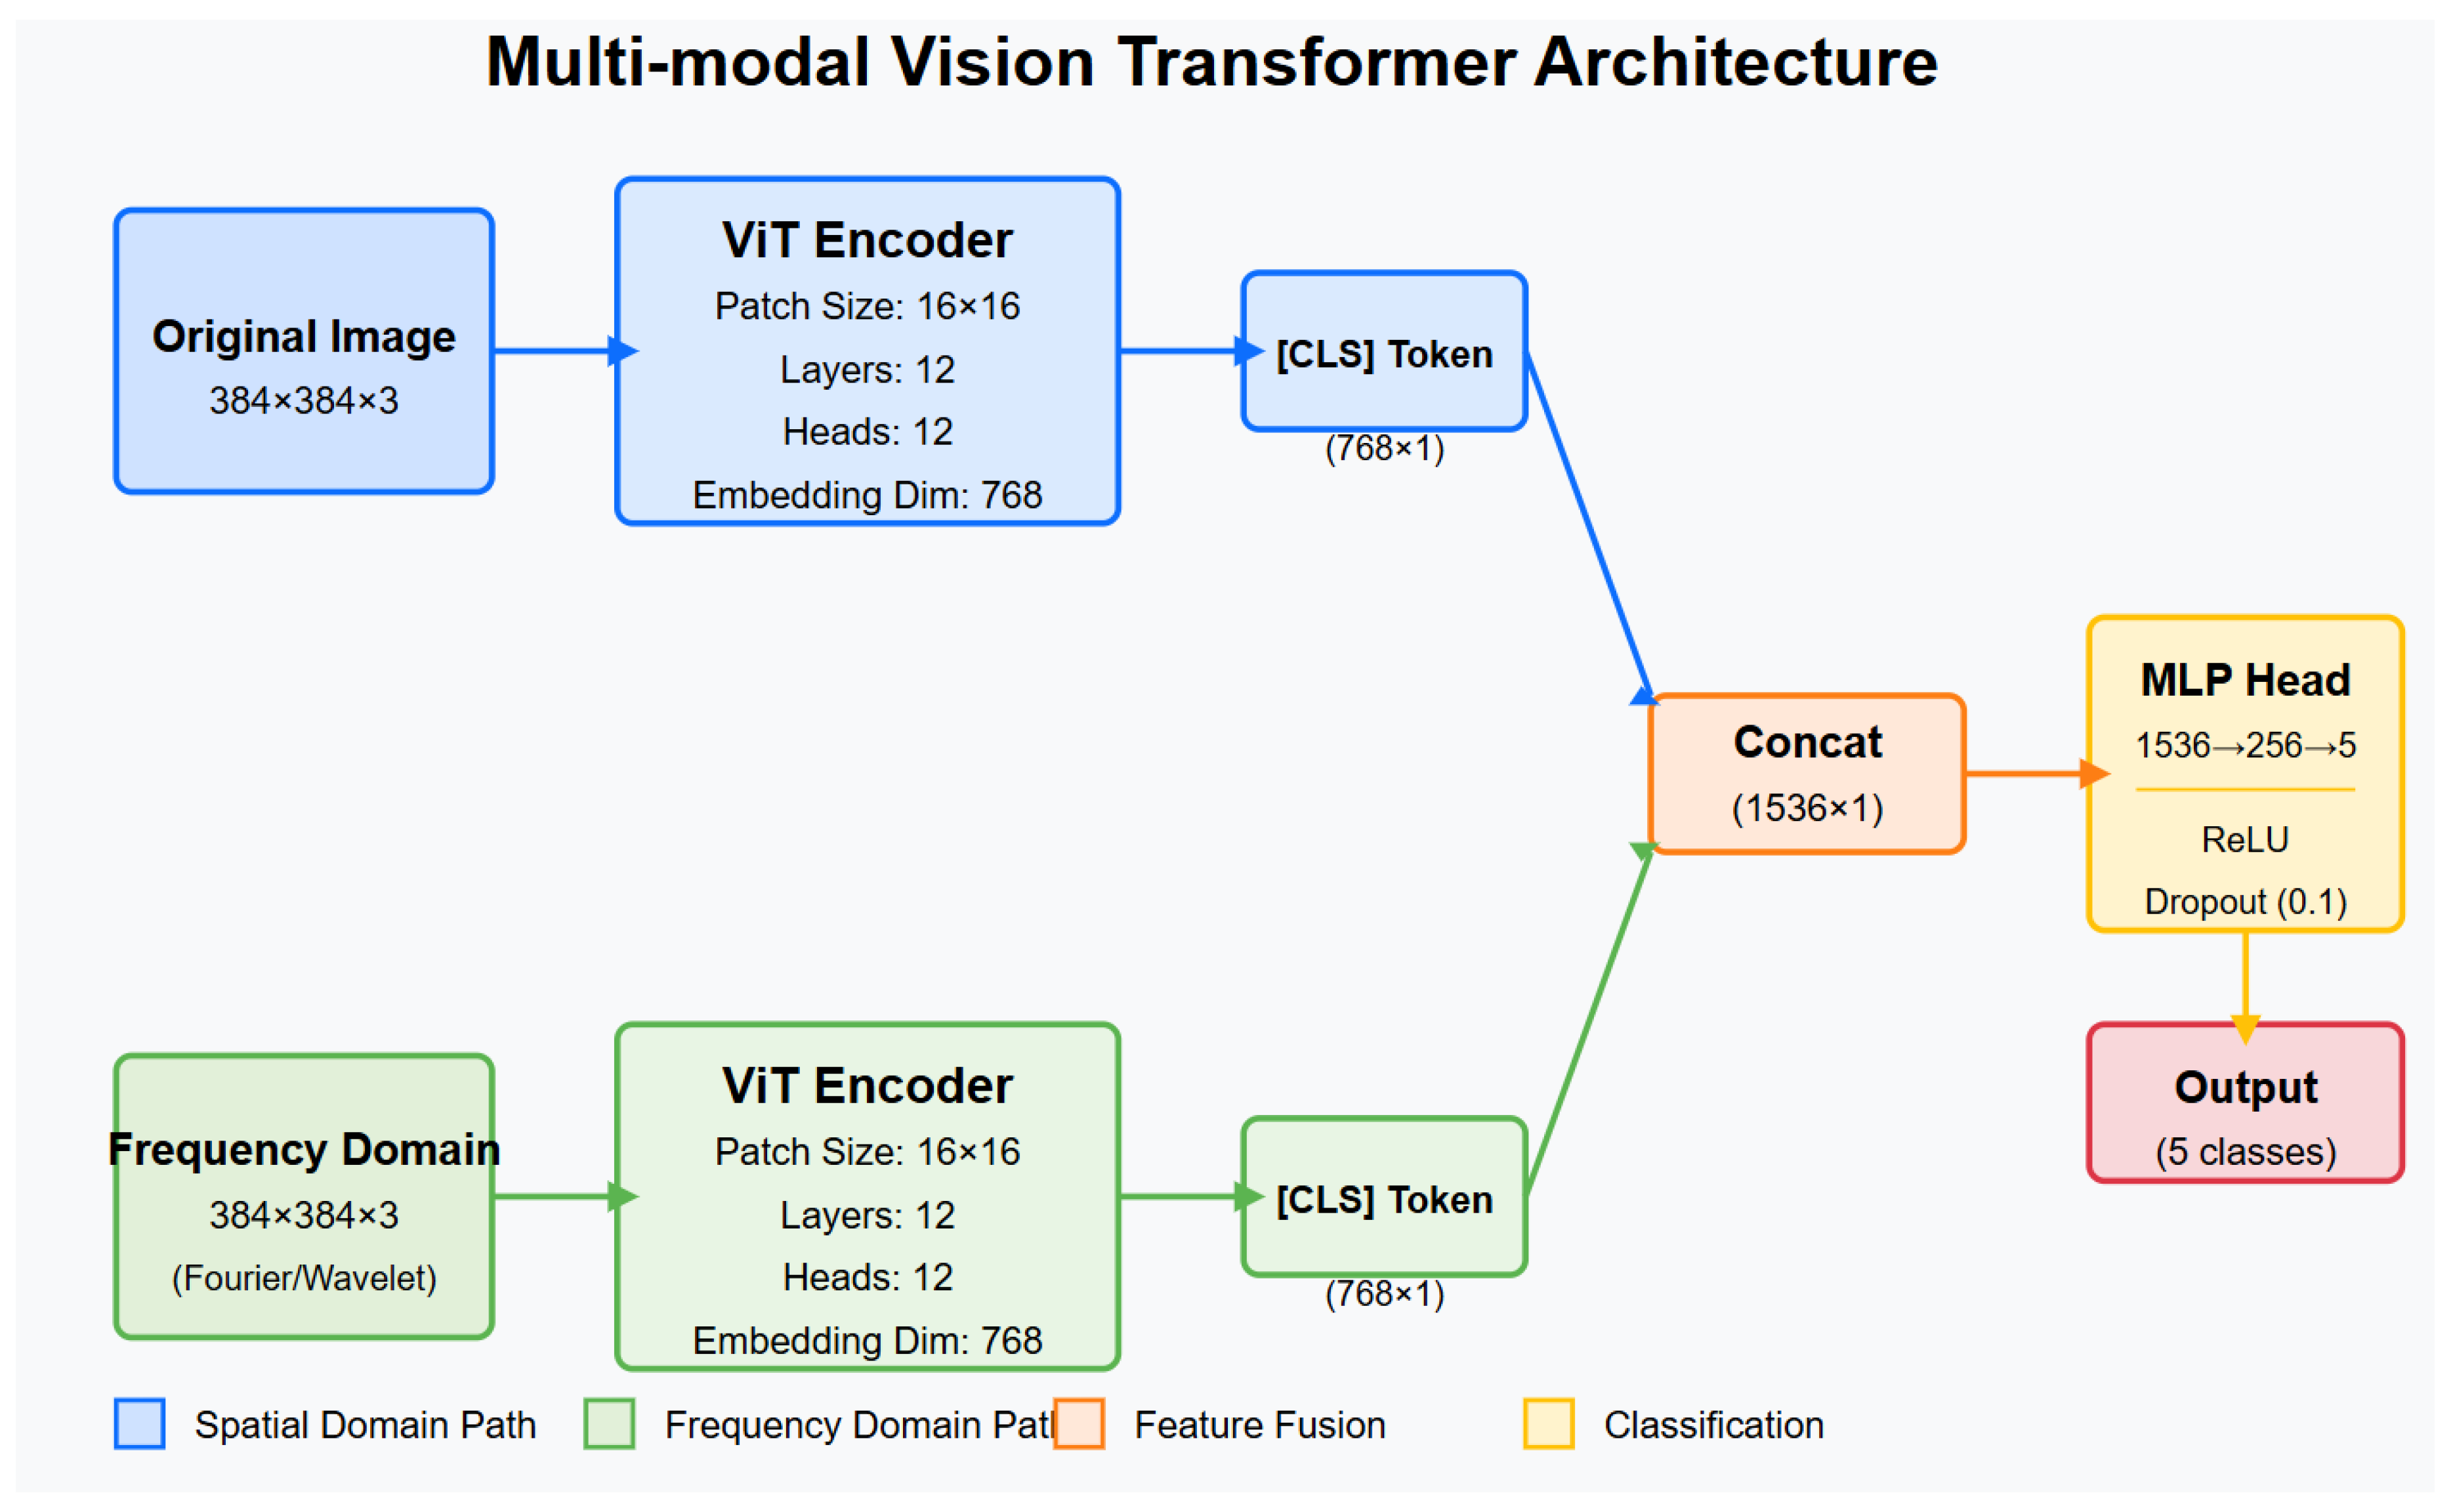
A Multi-Information Fusion ViT Model and Its Application to the Fault ...
The proposed ViT model for COVID-19 detection. | Download Scientific ...
The illustration of the proposed ViT architecture. (a) The main ...
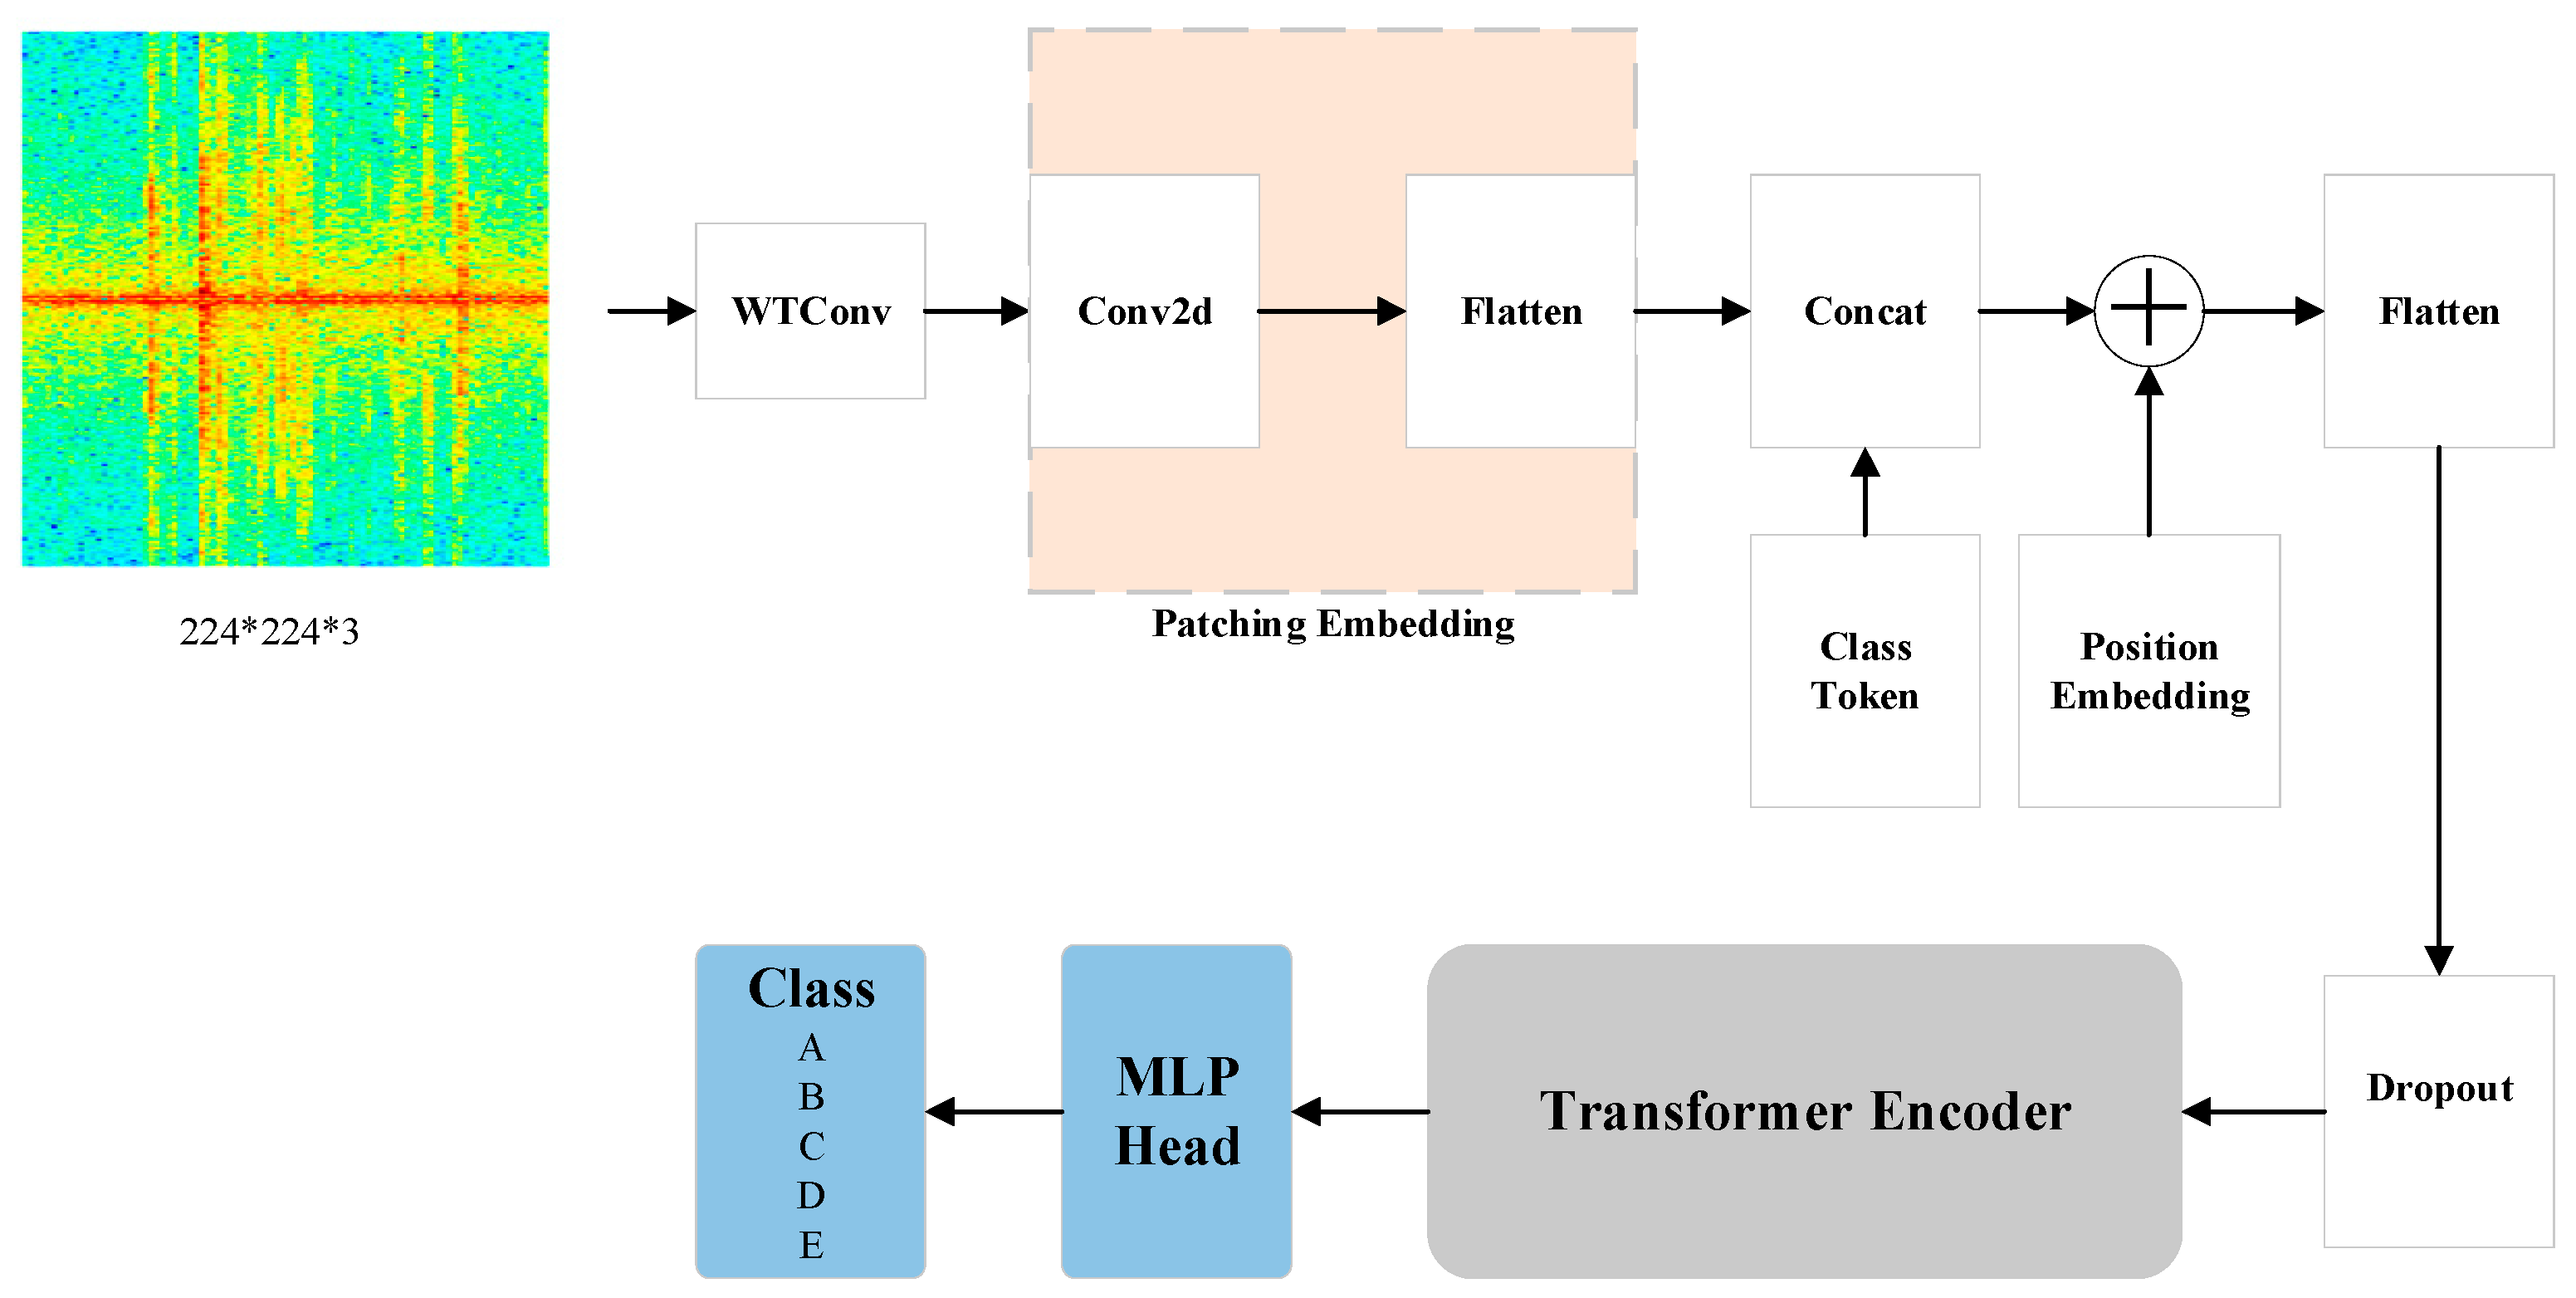
A Novel ViT Model with Wavelet Convolution and SLAttention Modules for ...
Overview of ViT model, adapted from [18]. | Download Scientific Diagram
Comparison with popular ViT models. Our CF-ViT is built upon LV-ViT-S ...
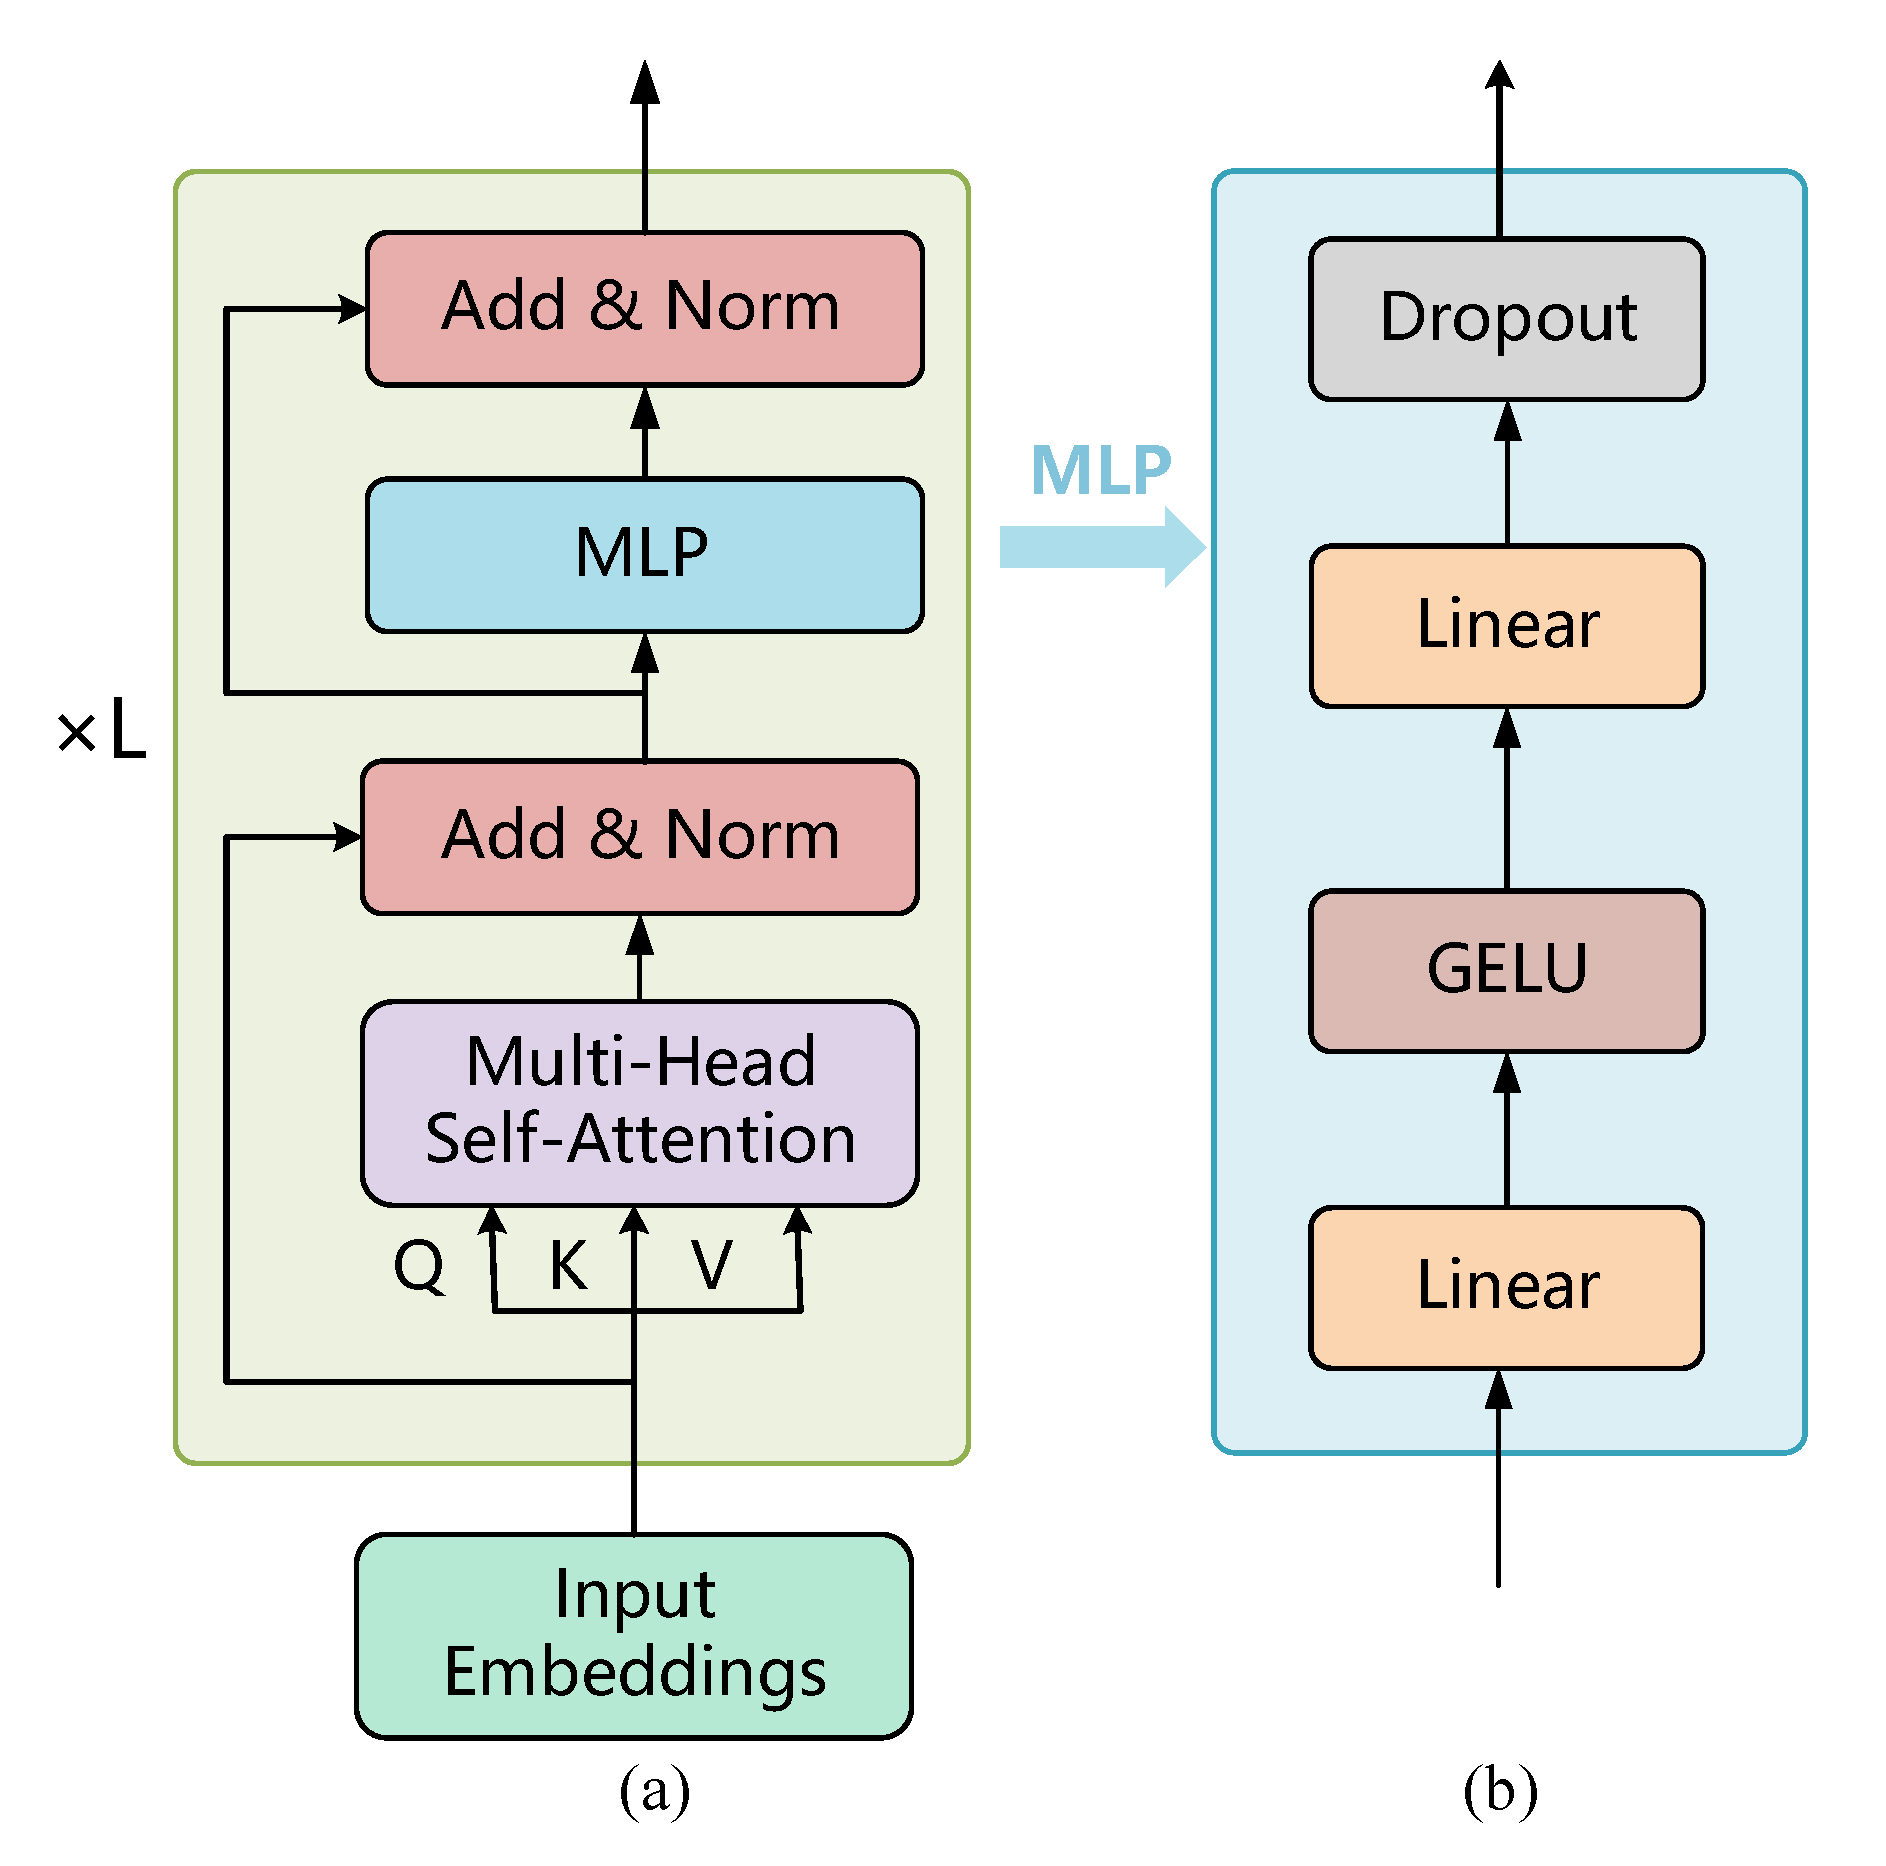
Detailed structure of the lth layer in the ViT model. (Q, K , and V are ...
Accuracy of ViT model variants with and without GAN on COVID-CT and ...
通用 Vision Backbone 超详细解读 (十五):FlexiViT:一个适应所有 Patch 大小的 ViT 模型 - 知乎
ViT (Visual Transformer) - 知乎
Change The Input Size Of Timm’S Vit Model – YNVI
Figure 2 from Lightweight ViT Model for Micro-Expression Recognition ...
The overall framework TRT-ViT. Left: ViT model. Right: Our proposed ...
A Performance Comparison of Japanese Sign Language Recognition with ViT ...
ASK-ViT: A Model with Improved ViT Robustness through Incorporating SK ...
ViT Model explanation and example how to appied | PDF
Normalized confusion matrix of the ViT model. | Download Scientific Diagram
Illustration of our proposed ViT model for COVID-19 detection using CXR ...
High level view of ViT model applied to Hlog. The Hlog 1-D input vector ...
ViT model structure diagram. | Download Scientific Diagram
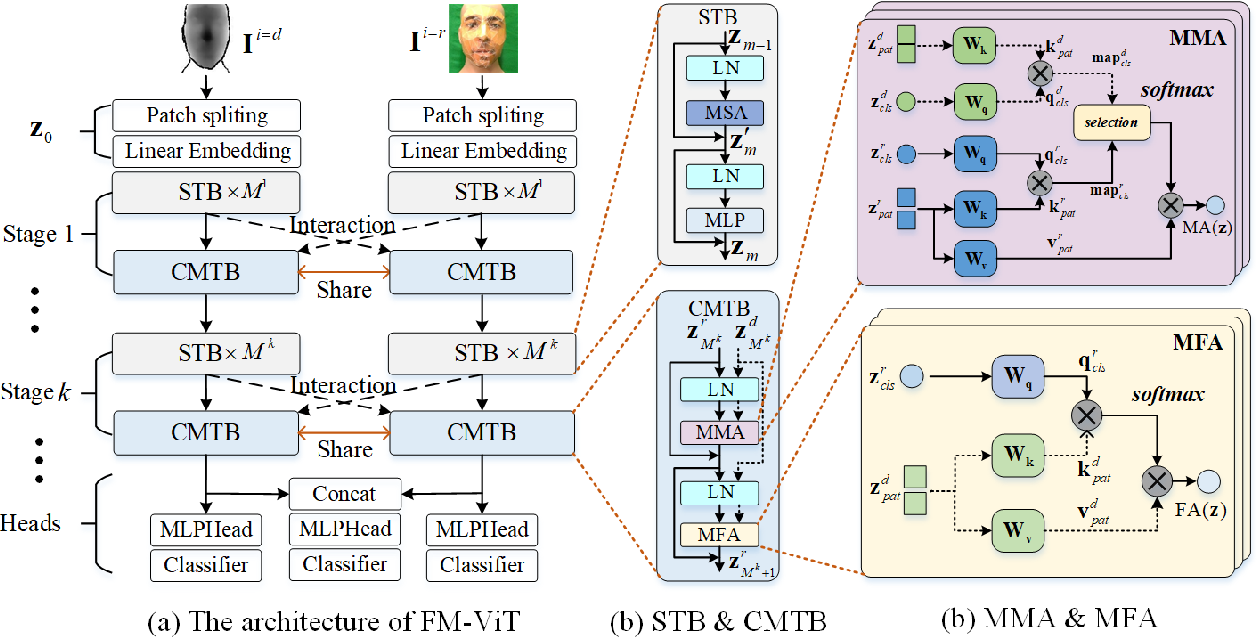
FM-ViT: Flexible Modal Vision Transformers for Face Anti-Spoofing
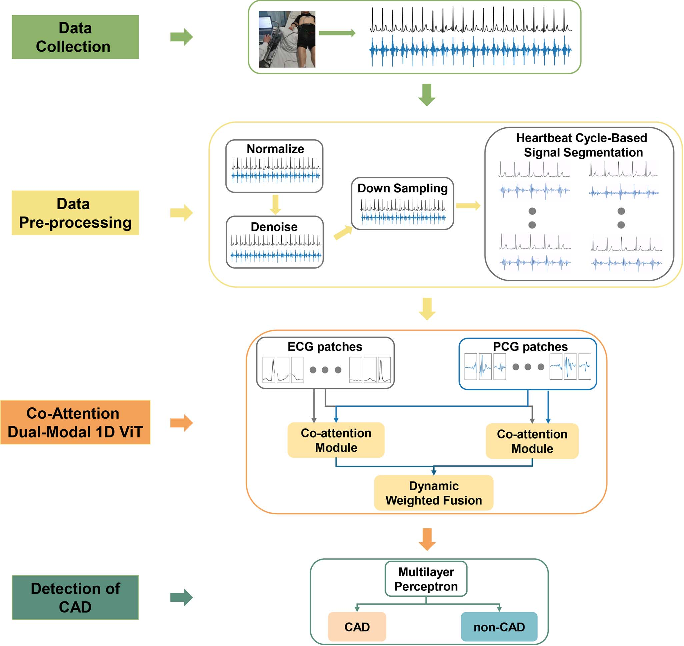
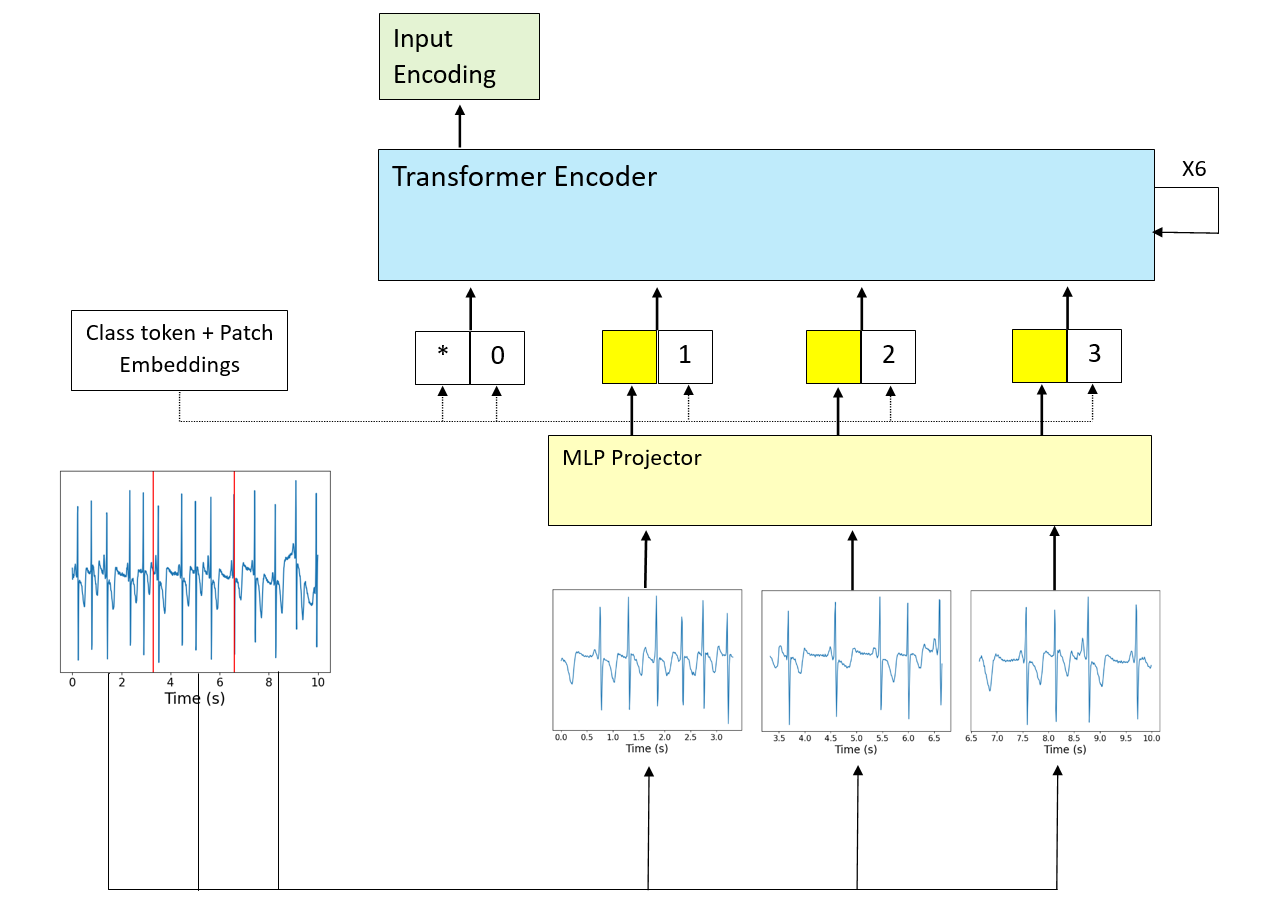
Figure 1 from Integrating ECG and PCG Signals through a Dual-Modal ViT ...
Frontiers | Lightweight ViT Model for Micro-Expression Recognition ...
Correct classification result of proposed ViT model. | Download ...
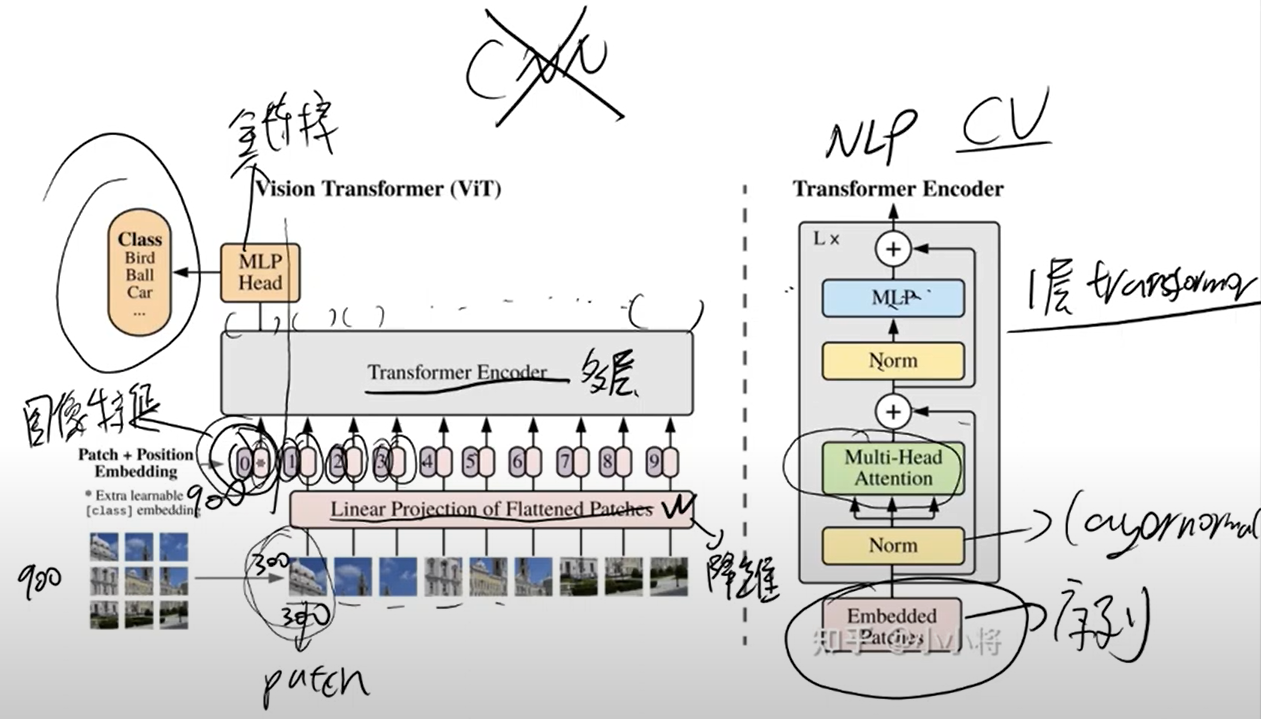
Vision Transformer (ViT)
Vision Transformer (ViT)及各种变体_vit架构-CSDN博客
Vision Transformer Model: Architecture, development and applications
Vision Transformer (ViT) Notes | Wenwen Kong
ViT(Vision Transformer)论文速读 - 哔哩哔哩
Vit: Quantifying Chest X-Ray Images Using Vision Transformer – QNBR
10 Attention Craving Quotes
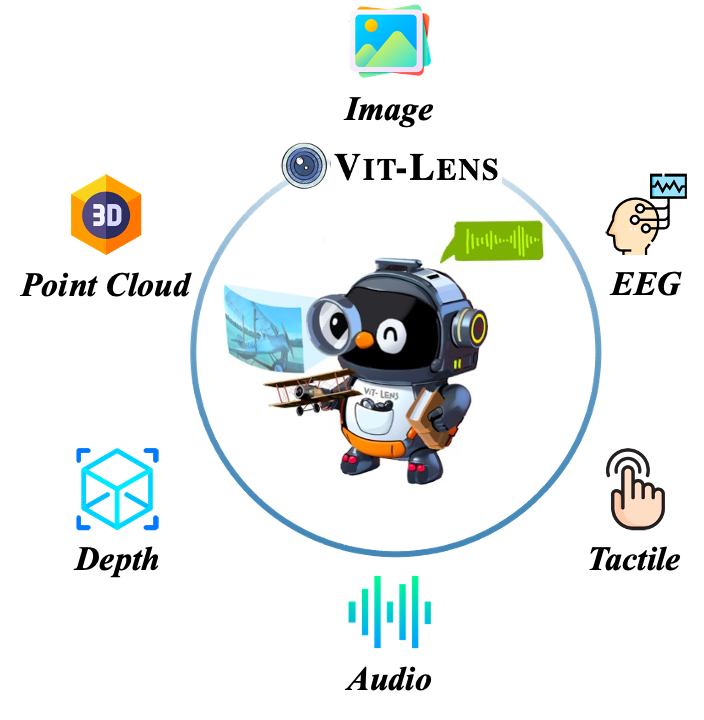
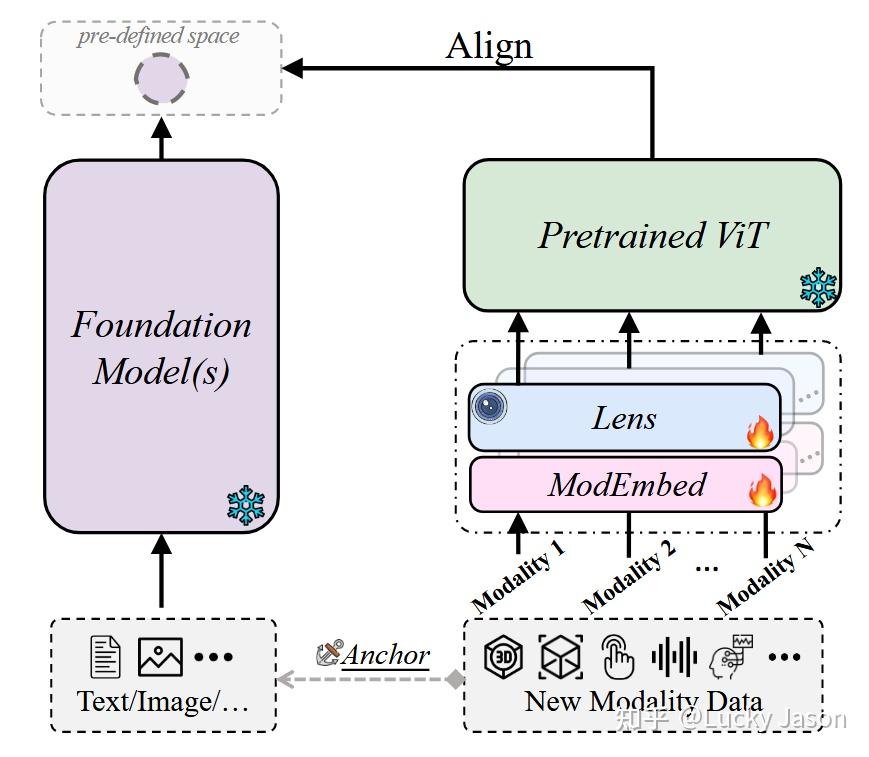
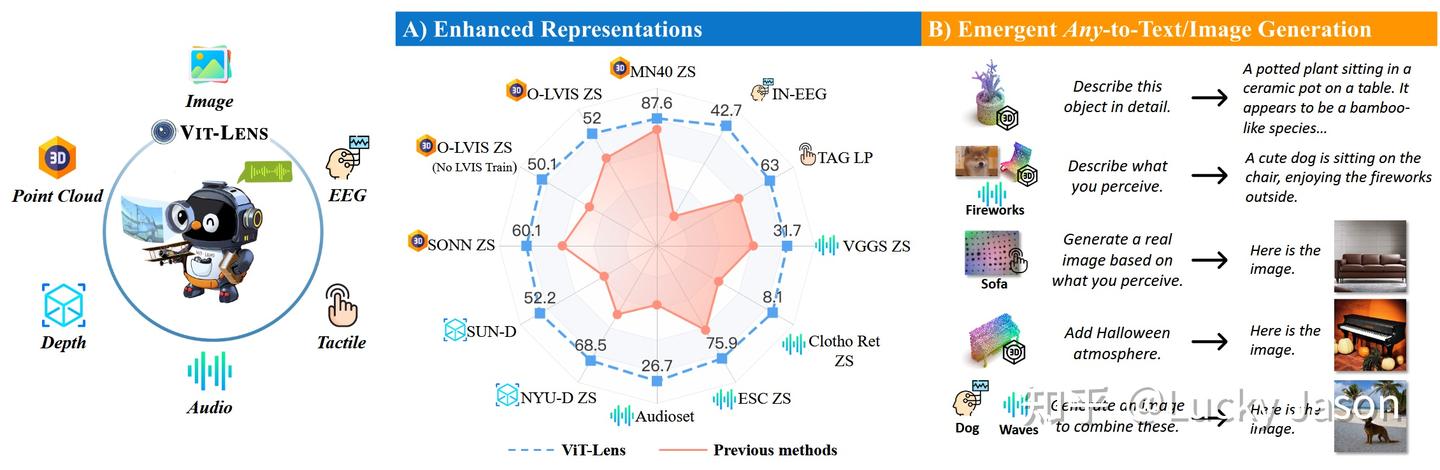
ViT-Lens
【Pytorch】论文复现 Vision Transformer (ViT)_vit复现-CSDN博客
How Transformers Drive Computer Vision Innovation
Visual Transformer (ViT)模型详解-CSDN博客
U-ViT(CVPR2023)——ViT与Difussion Model的结合-CSDN博客
How is a Vision Transformer (ViT) model built and implemented? | PDF ...
How is a Vision Transformer (ViT) model built and implemented? | PDF
Google AI Introduces ViT-22B: The Largest Vision Transformer Model 5.5x ...
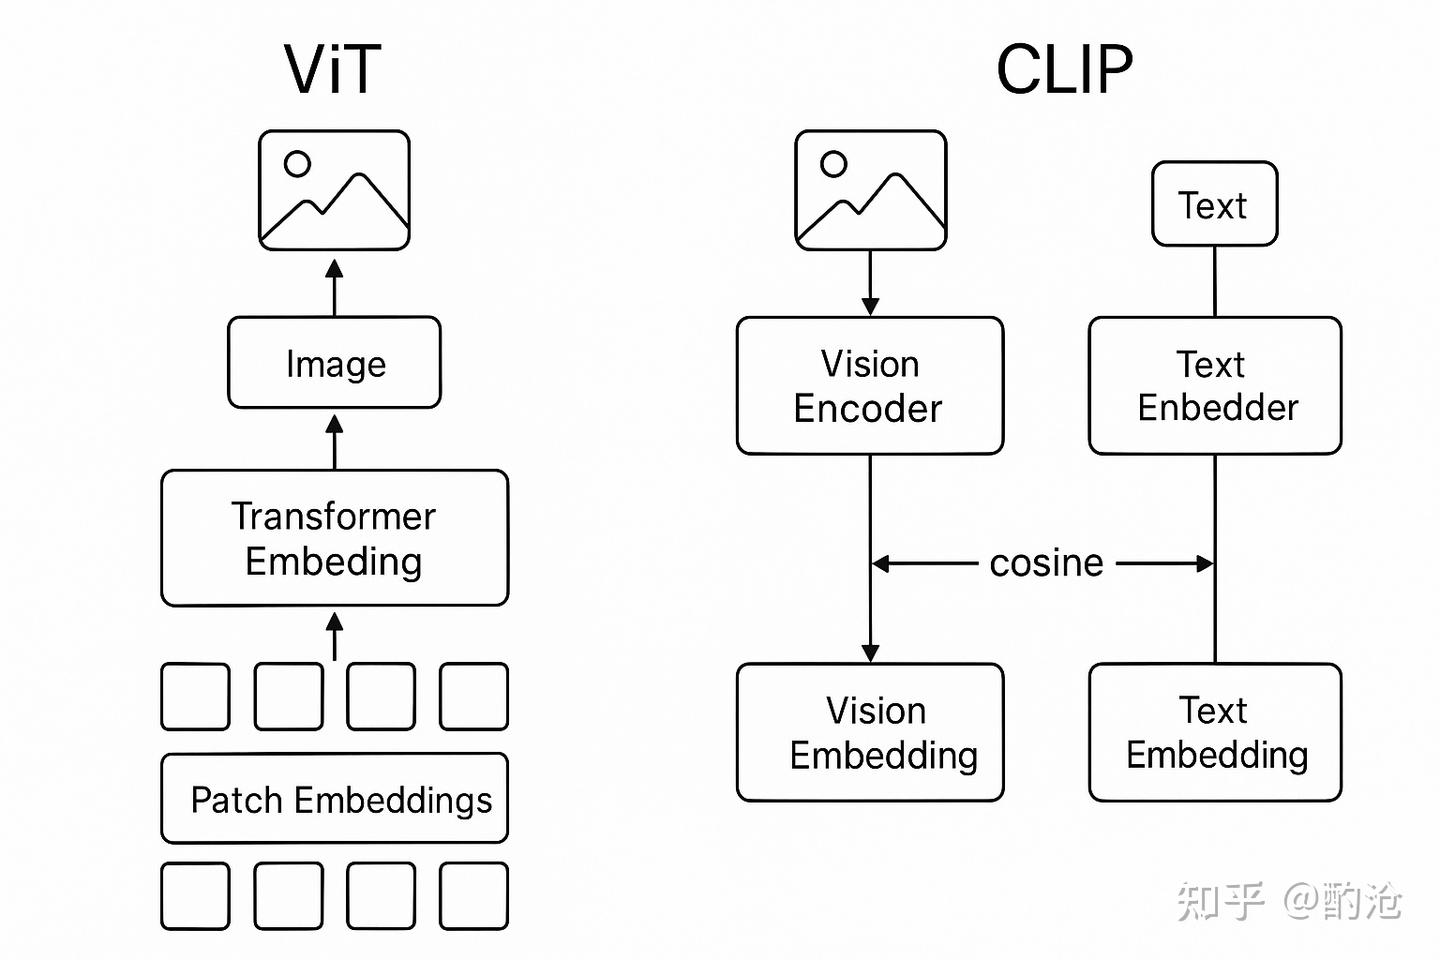
ViT与CLIP:图像×文本 多模态读心术揭秘 - 知乎
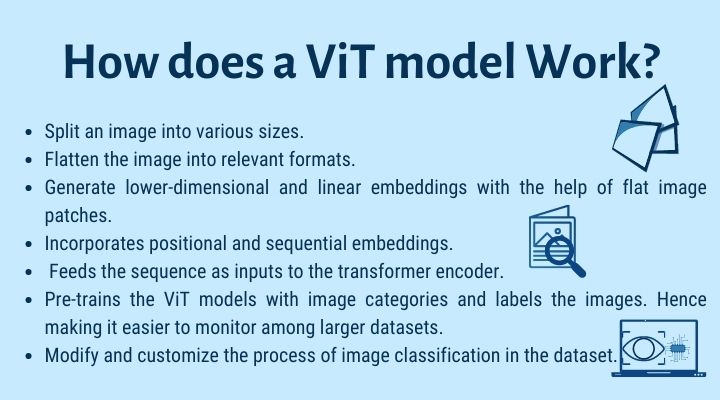
VIT(vision transformer)模型介绍+pytorch代码炸裂解析 - 知乎
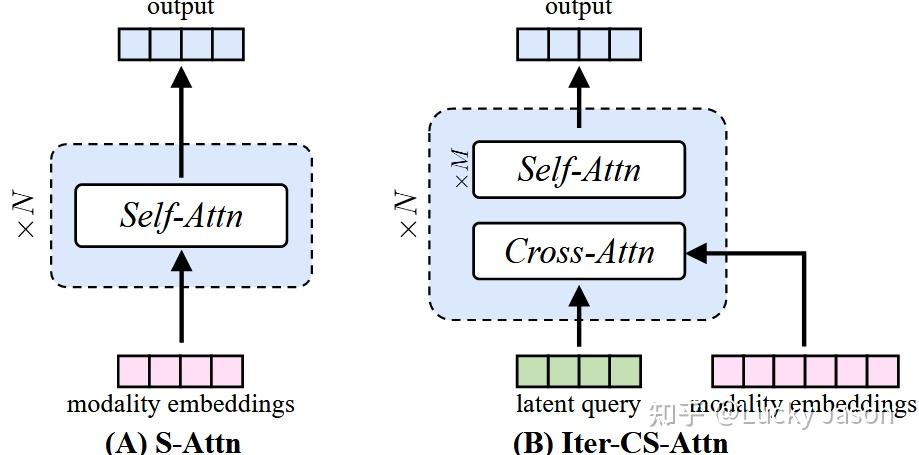
【论文笔记】VIT-LENS: Towards Omni-modal Representations - 知乎
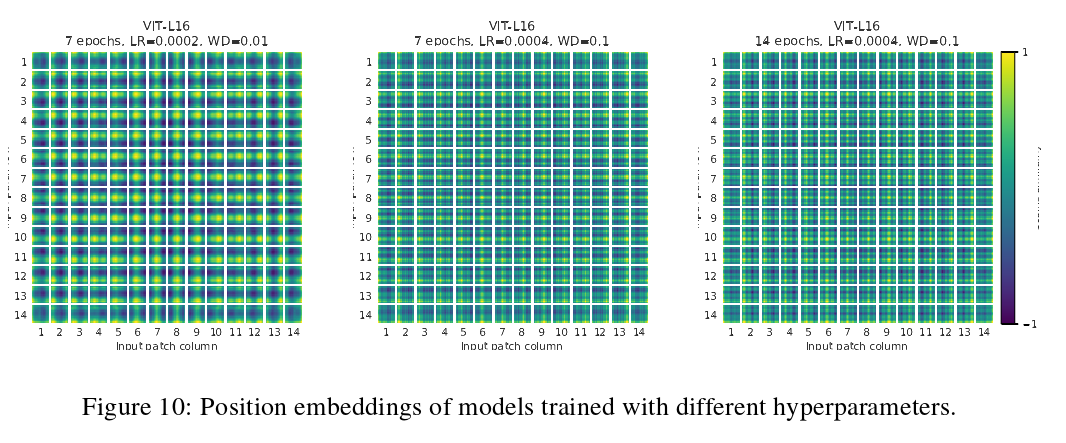
Frontiers | Self-attention in vision transformers performs perceptual ...
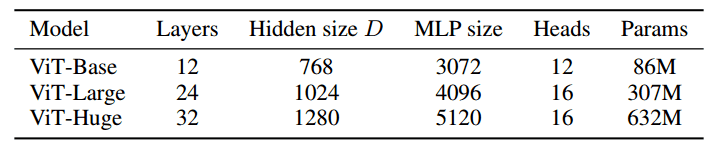
ViT常见的模型规格以及源码记录_vit模型不同版本大小-CSDN博客
Vision Transformers (ViT) Explained | Pinecone
Improve Accuracy and Robustness of Vision AI Apps with Vision ...
《Vision Transformer (ViT)》论文精度,并解析ViT模型结构以及代码实现_vit论文下载-CSDN博客
Gait-Vit: Gait Recognition With Vision Transformer – KVMY
Vision Transformer (ViT)初识:原理详解及代码_vit-transformer代码-CSDN博客
Understanding Vision Transformers (ViTs): Hidden properties, insights ...
RUFake: Online Tool for Detecting AI-Generated Photos | UC Berkeley ...
How is a Vision Transformer (ViT) model built and implemented? : r ...
Model structure of a VIT. | Download Scientific Diagram
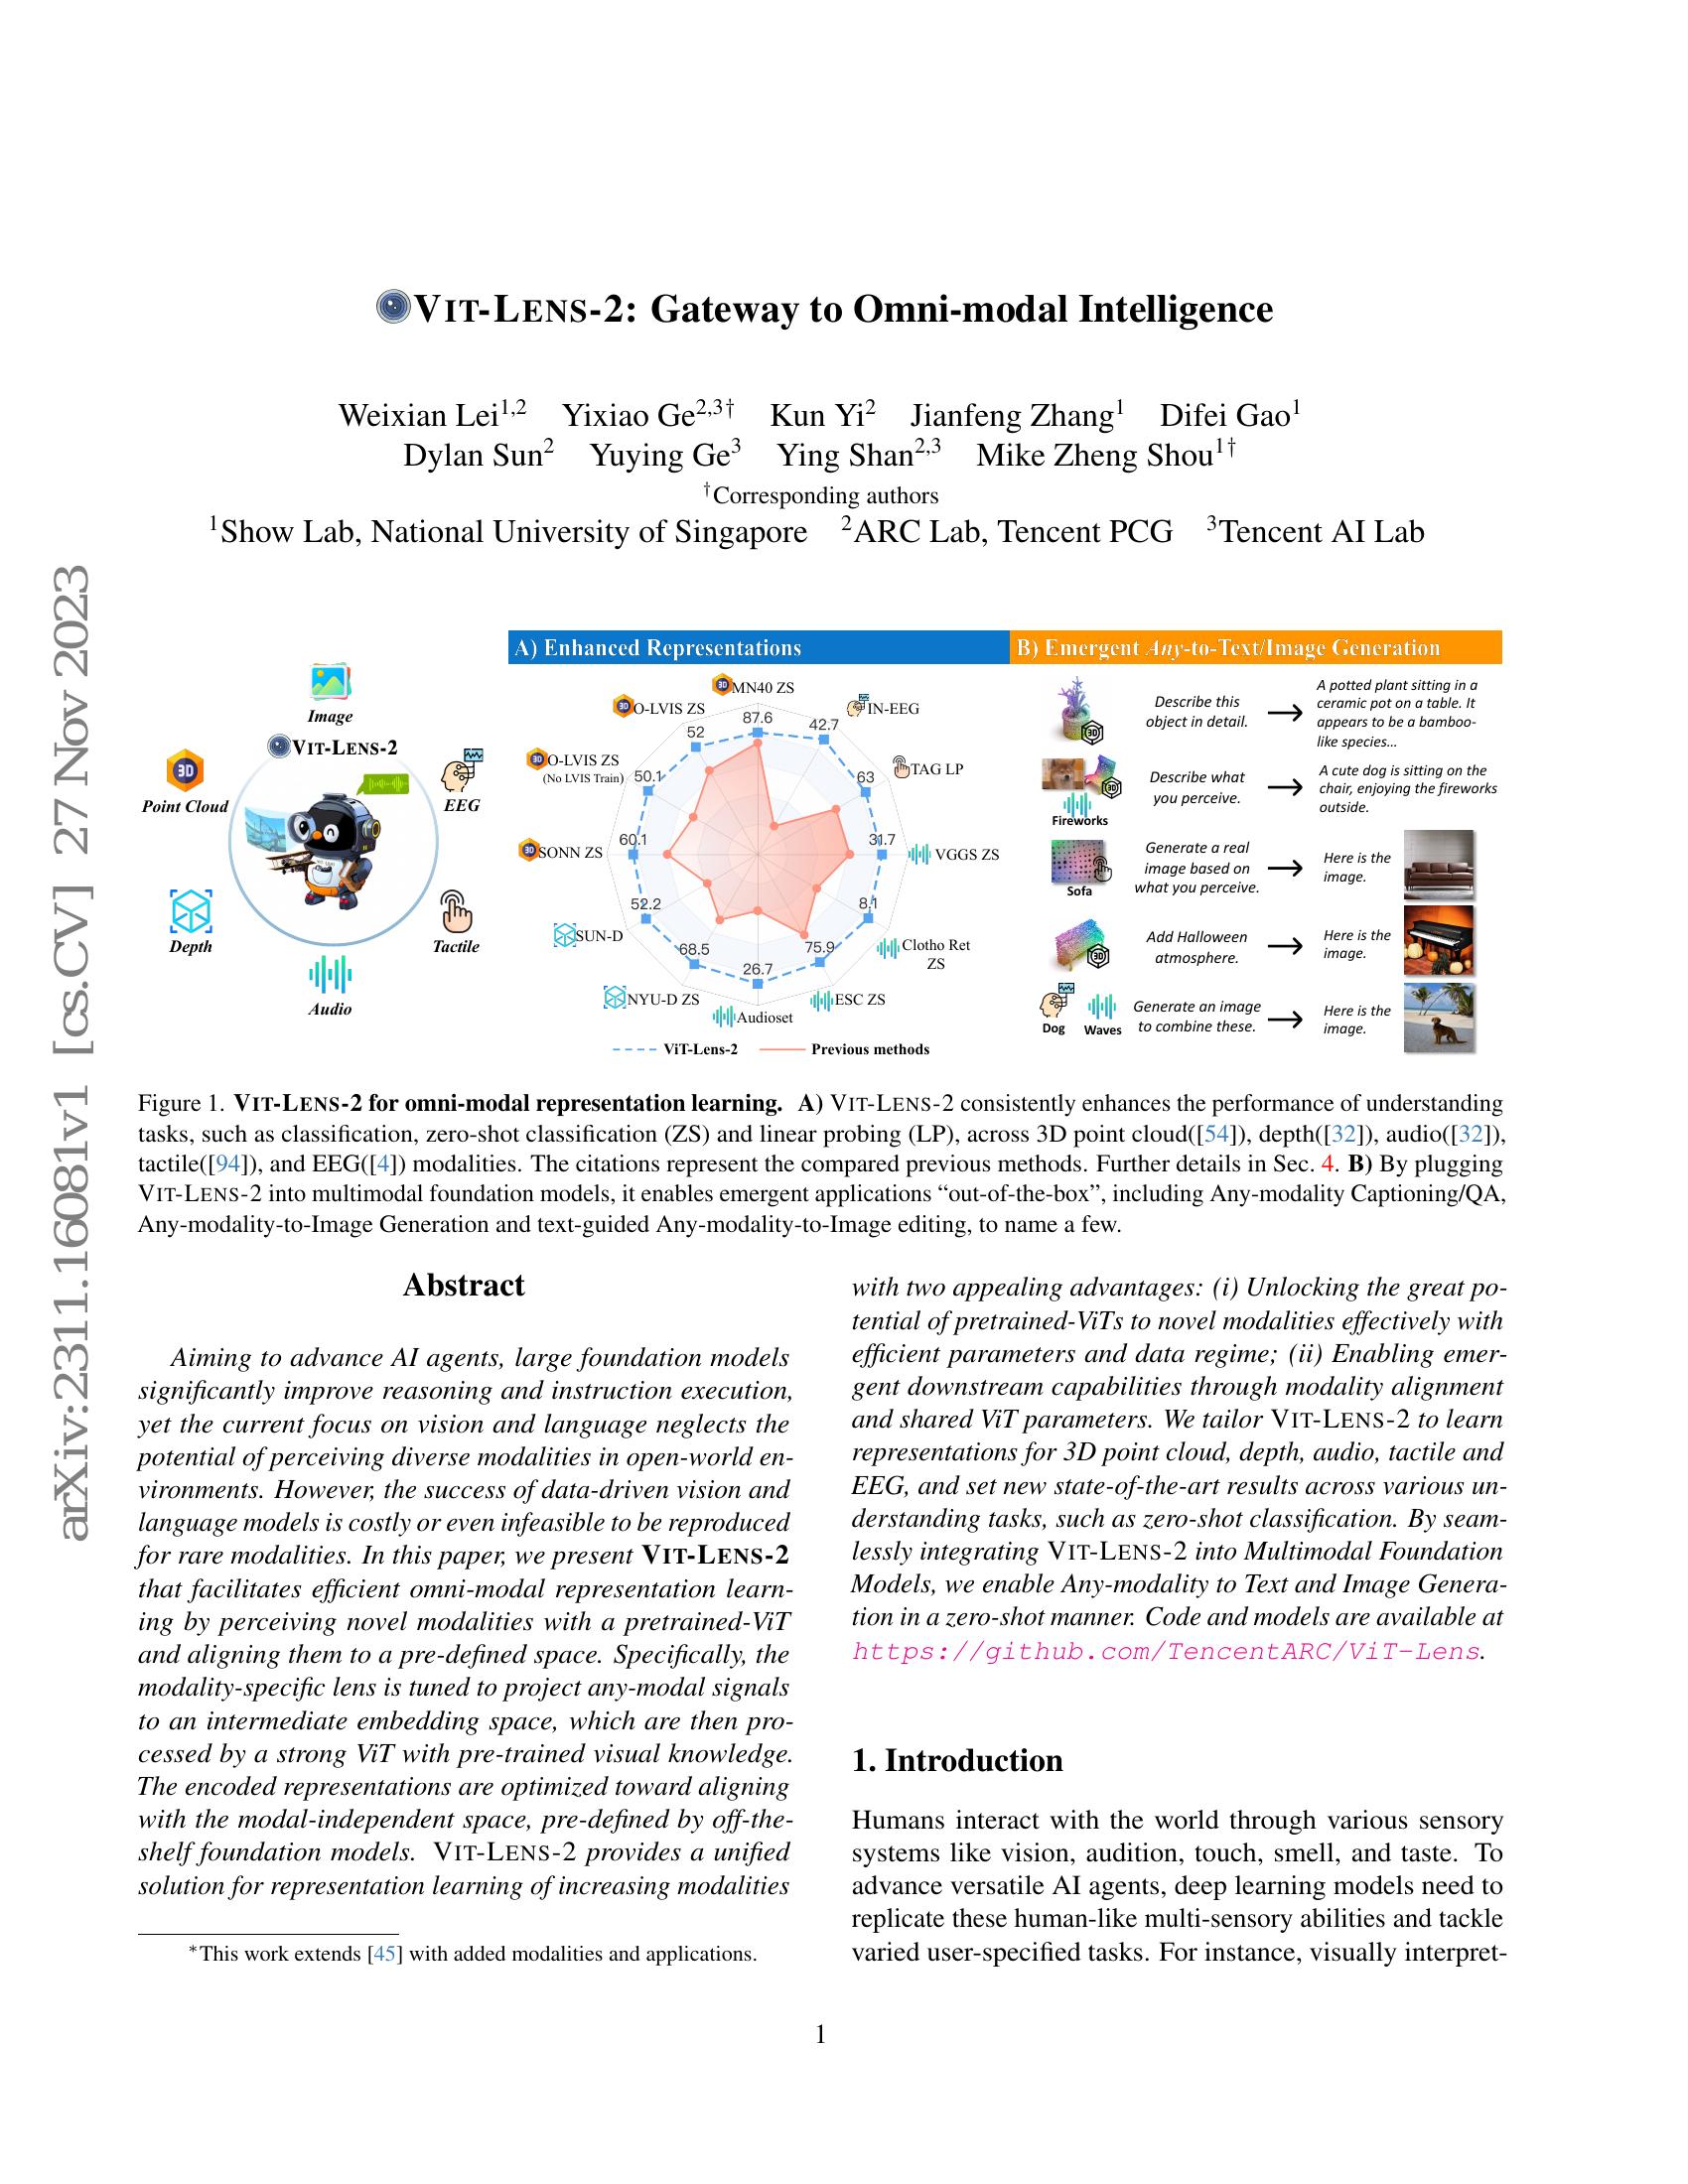
ViT-Lens-2: Gateway to Omni-modal Intelligence
Uncovering the Hidden Properties, Insights, and Robustness of Vision ...
Vision-Language Models Tutorial – Devansh’s Blog
GitHub - TencentARC/ViT-Lens: [CVPR 2024] ViT-Lens: Towards Omni-modal ...
[2305.10347] Subject-based Non-contrastive Self-Supervised Learning for ...
YOLOv5s-ViT model structure diagram. | Download Scientific Diagram
Transformer 画像生成 _ 生成Ai トランスフォーマー – INHEPO
【Transformer系列】深入浅出理解ViT(Vision Transformer)模型-CSDN博客
ViT模型架构和CNN区别_vit transformer比cnn-CSDN博客
Mobile-ViT (MobileViT)网络讲解-CSDN博客
ViT-Lens/vitlens/src/open_clip/modal_video/processors/vt_processors.py ...
ViT模型计算流程图解 - 知乎
MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision ...
Aman's AI Journal • Primers • Vision Transformer (ViT)
ViT-Adapter:[ICLR 2023 Spotlight] Vision Transformer Adapter for Dense ...
GitHub - globaledgesoft/ViT-Model-Compilation-and-Integration-on-RB5 ...
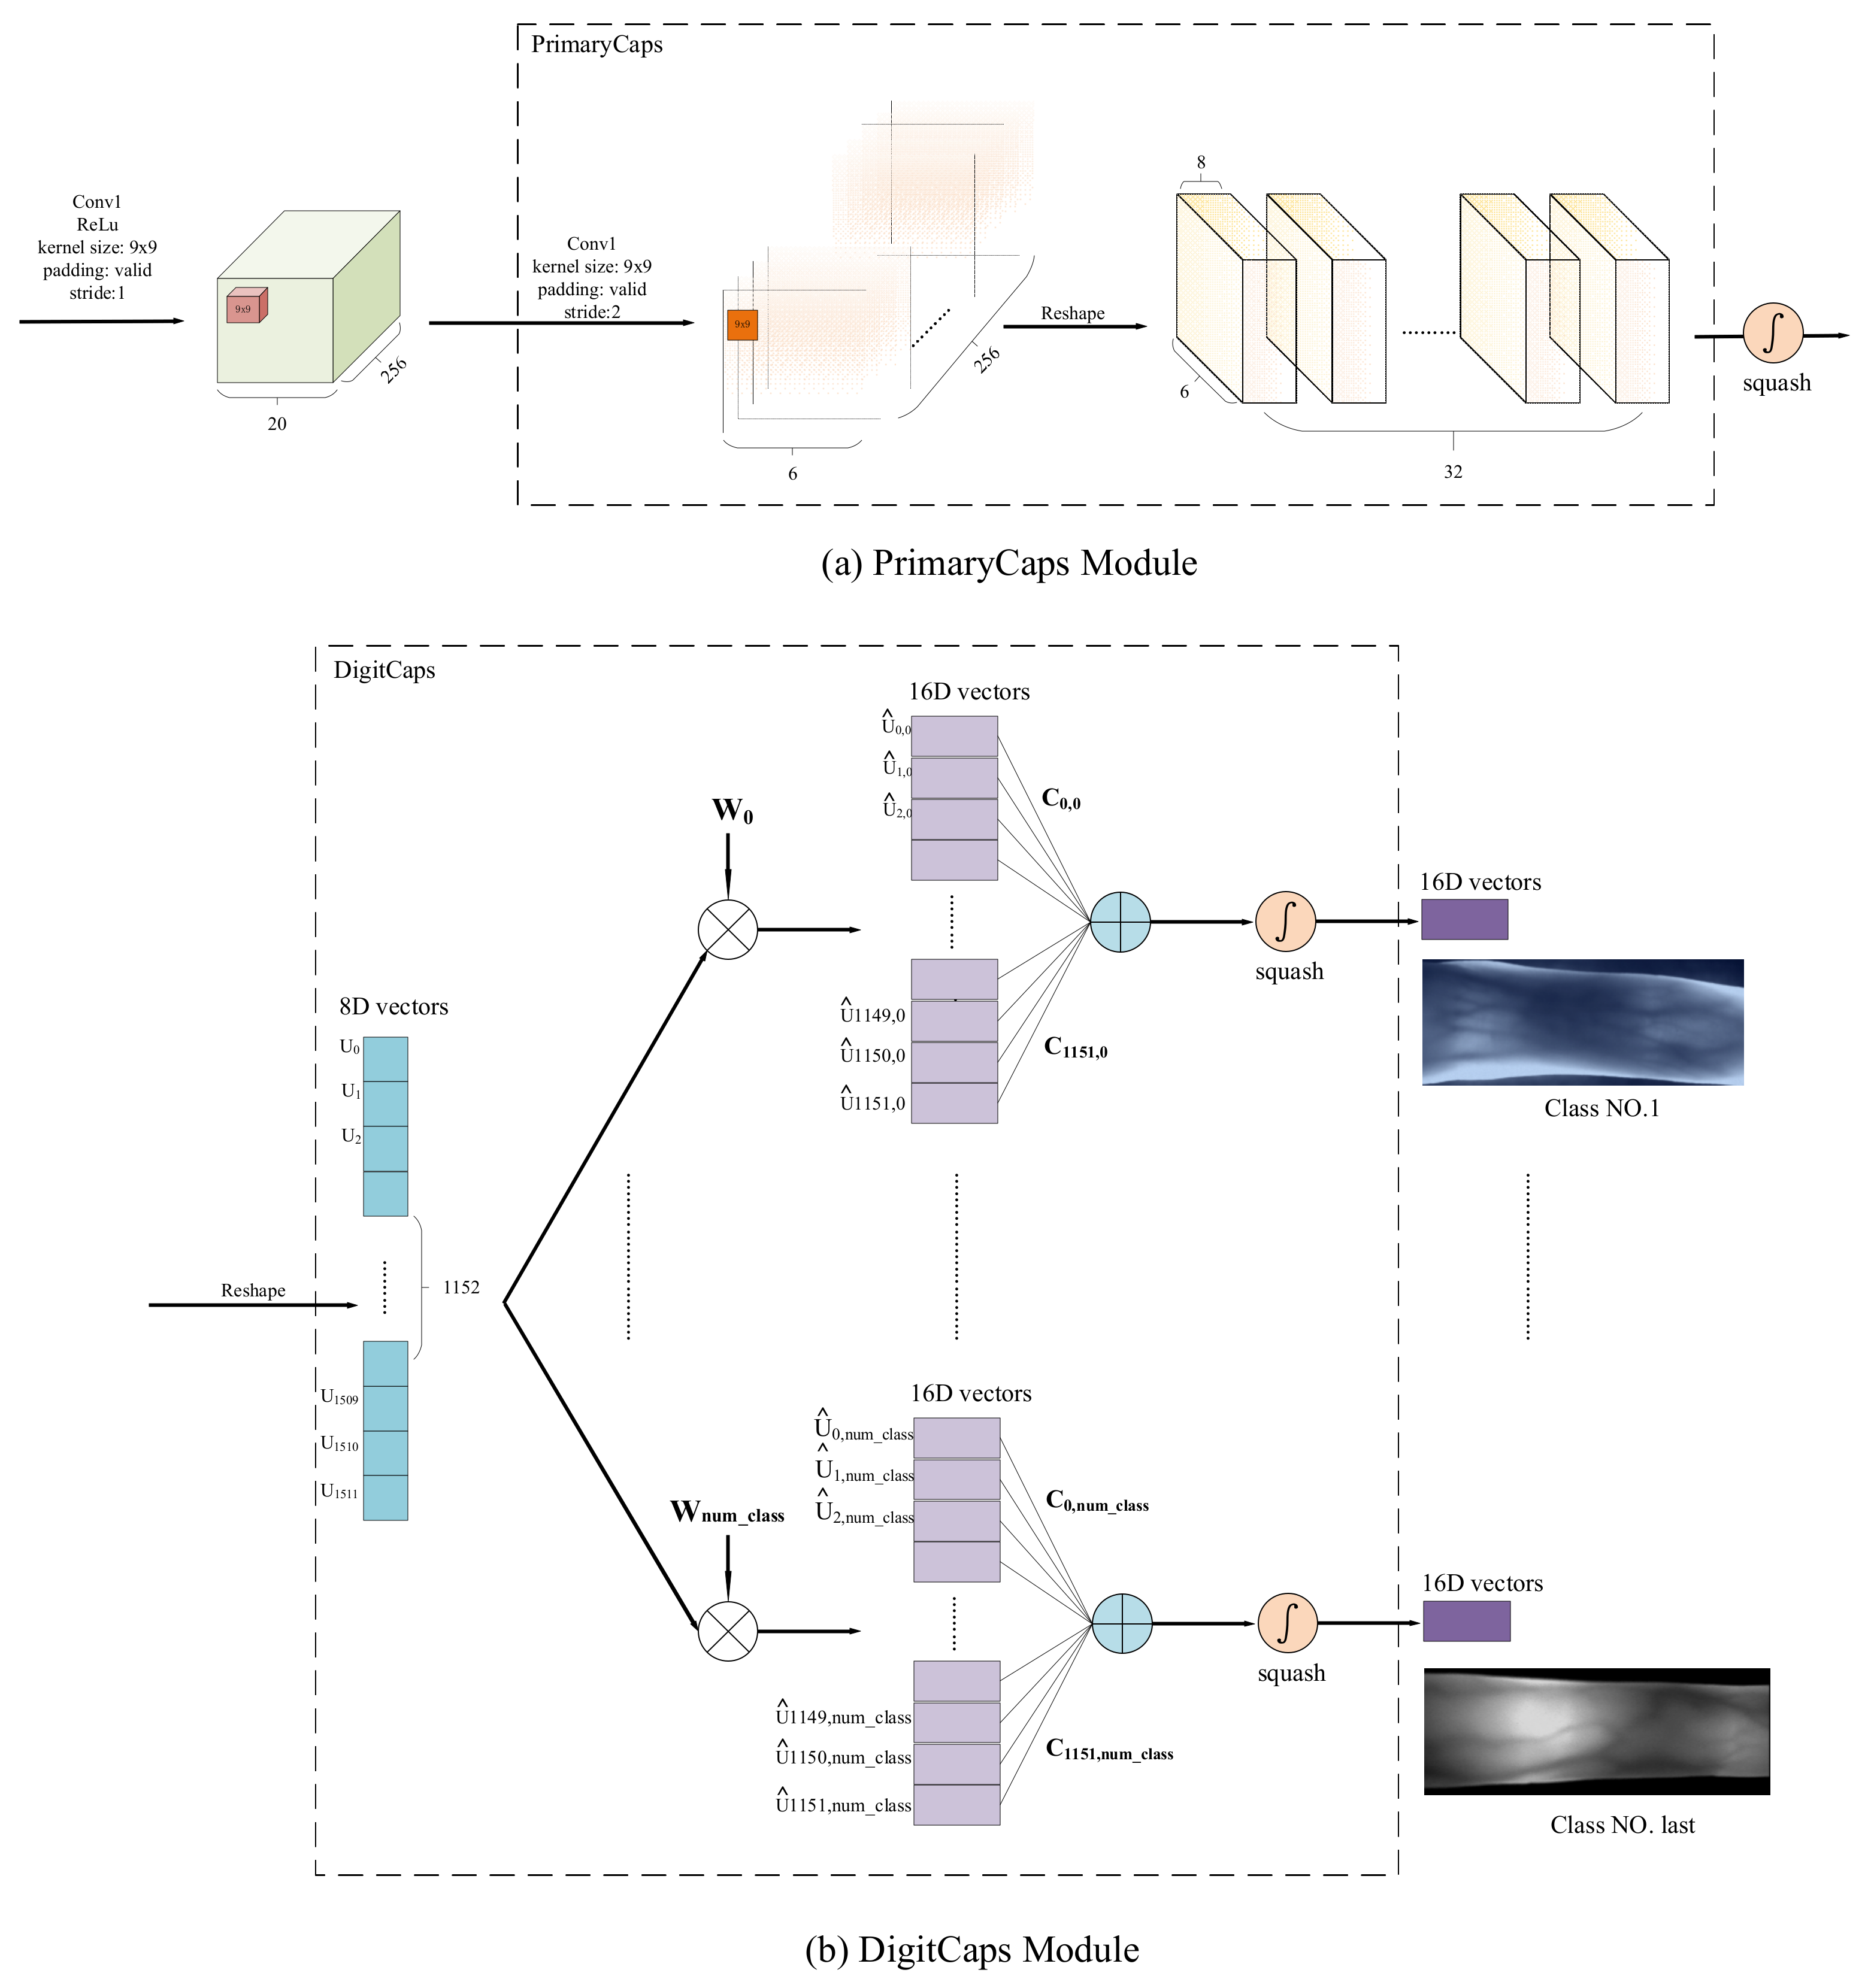
ViT-Cap: A Novel Vision Transformer-Based Capsule Network Model for ...
(PDF) ViT-Lens: Towards Omni-modal Representations
Multi-Modal Vision Transformer Integration for Enhanced Canine ...
ViT-Lens-2: Gateway to Omni-modal Intelligence - 智源社区论文
2024-02-05 - Vit模型基础 - 卢菁 - 流雨声 - 博客园
An Image is Worth 16x16 Words: A Deep Dive into the Vision Transformer ...
Vit代码-CSDN博客
The typical detailed flow chart of Our TSAM+CB+ViT model in Fig. 1 ...
VIT~~6_vit模型的输入可以是文本吗-CSDN博客
如何把 Transformer 应用到图像领域 | gqjia
Vision Transformers (ViT) and the Rise of Multi-Modal Deep Learning
MobileViT - 知乎
Access the Latest in Vision AI Model Development Workflows with NVIDIA ...
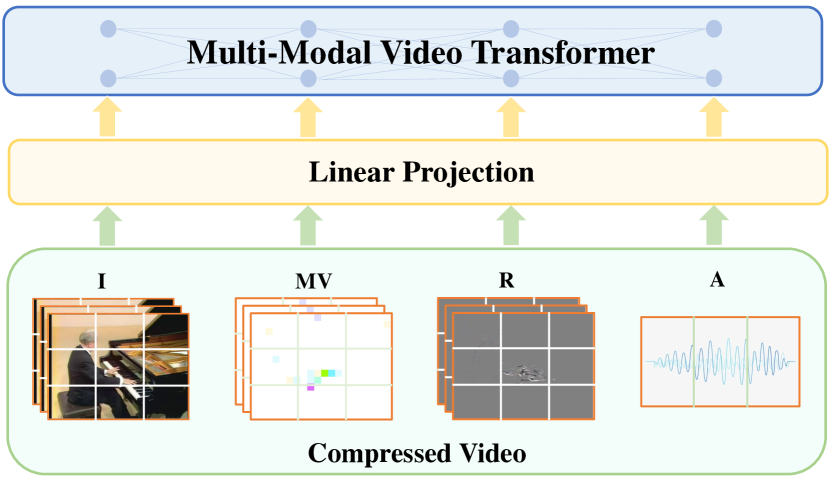
[2108.09322] MM-ViT: Multi-Modal Video Transformer for Compressed Video ...
Vision transformer (ViT)-based deep learning model for diagnosis of ...
Overview of ViT. The model segments the image into fixed‐size patches ...
VIT模型个人笔记-CSDN博客
An Information Entropy Masked Vision Transformer (IEM-ViT) Model for ...
[2311.16081] Vit-Lens-2: Gateway to Omni-modal Intelligence
ViT-Adapter:用于密集预测任务的视觉 Transformer Adapter-极市开发者社区
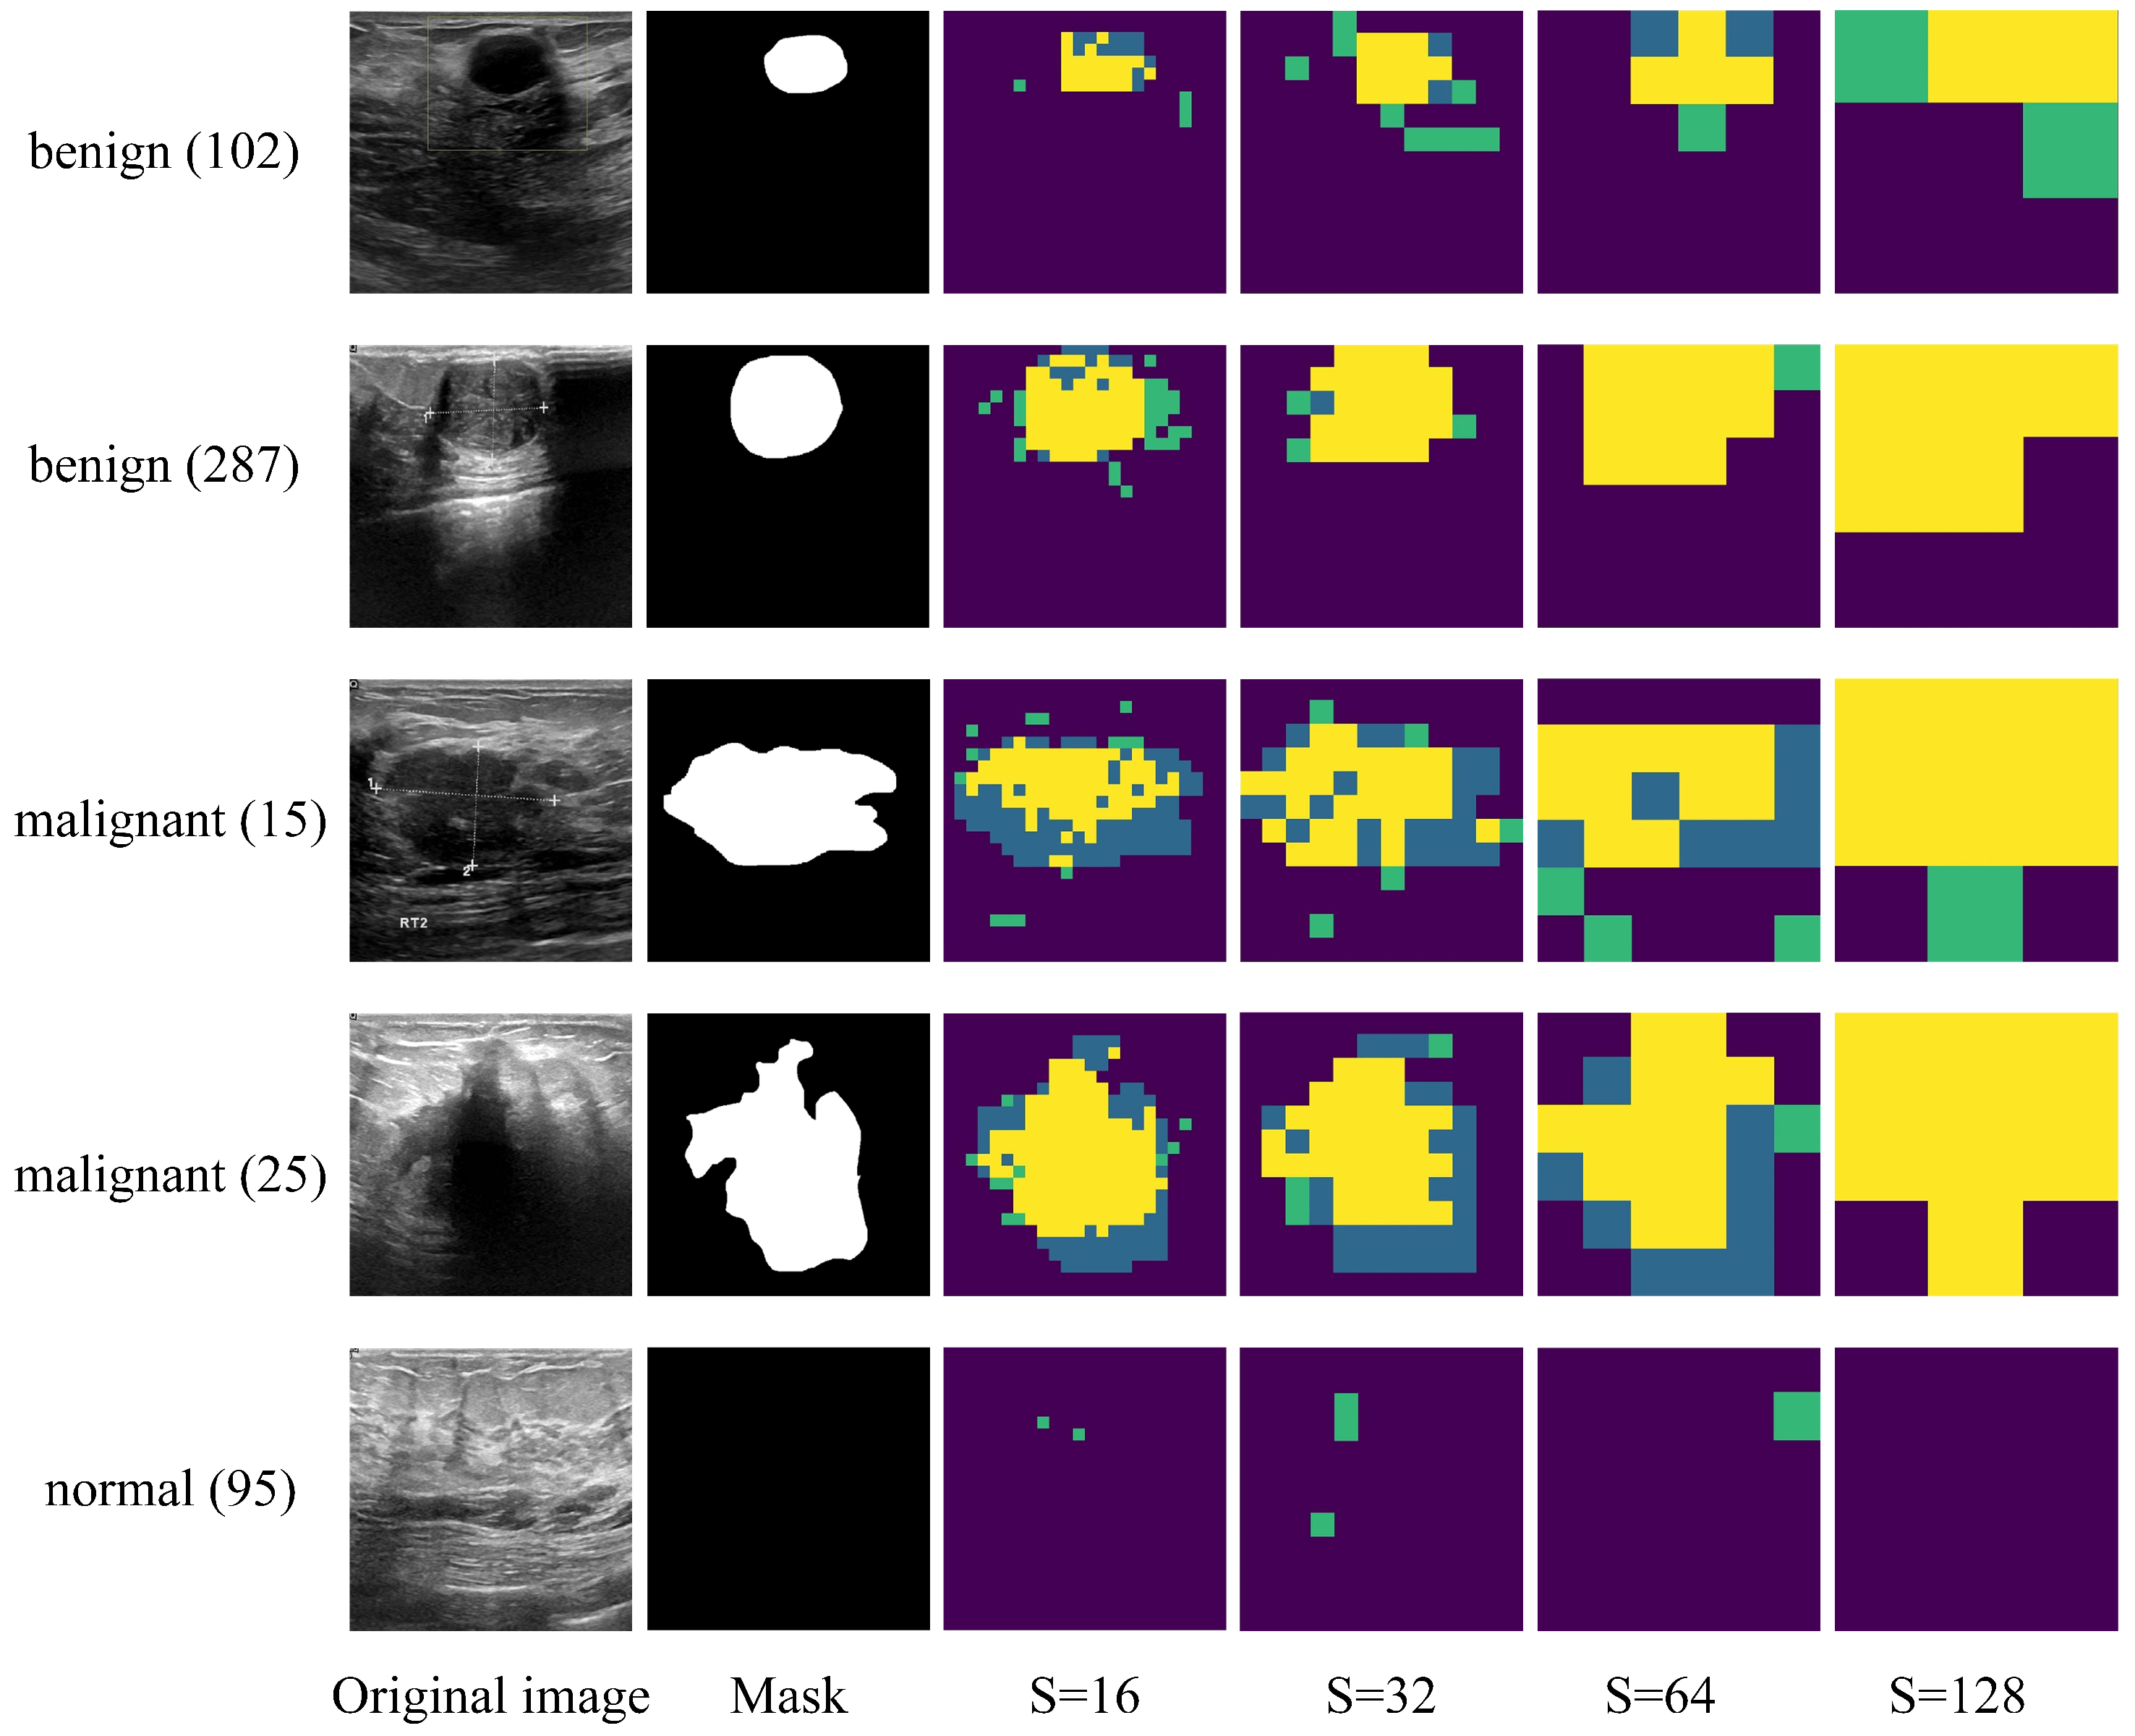
Identifying Malignant Breast Ultrasound Images Using ViT-Patch
Anatomy-Guided Hybrid CNN–ViT Model with Neuro-Symbolic Reasoning for ...
The chart a displays the statistics of the papers presented in this ...
【多模态LLM】以ViT进行视觉表征的多模态模型1(BLIP、BLIP-2、InstructBLIP)_vit llm-CSDN博客