Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
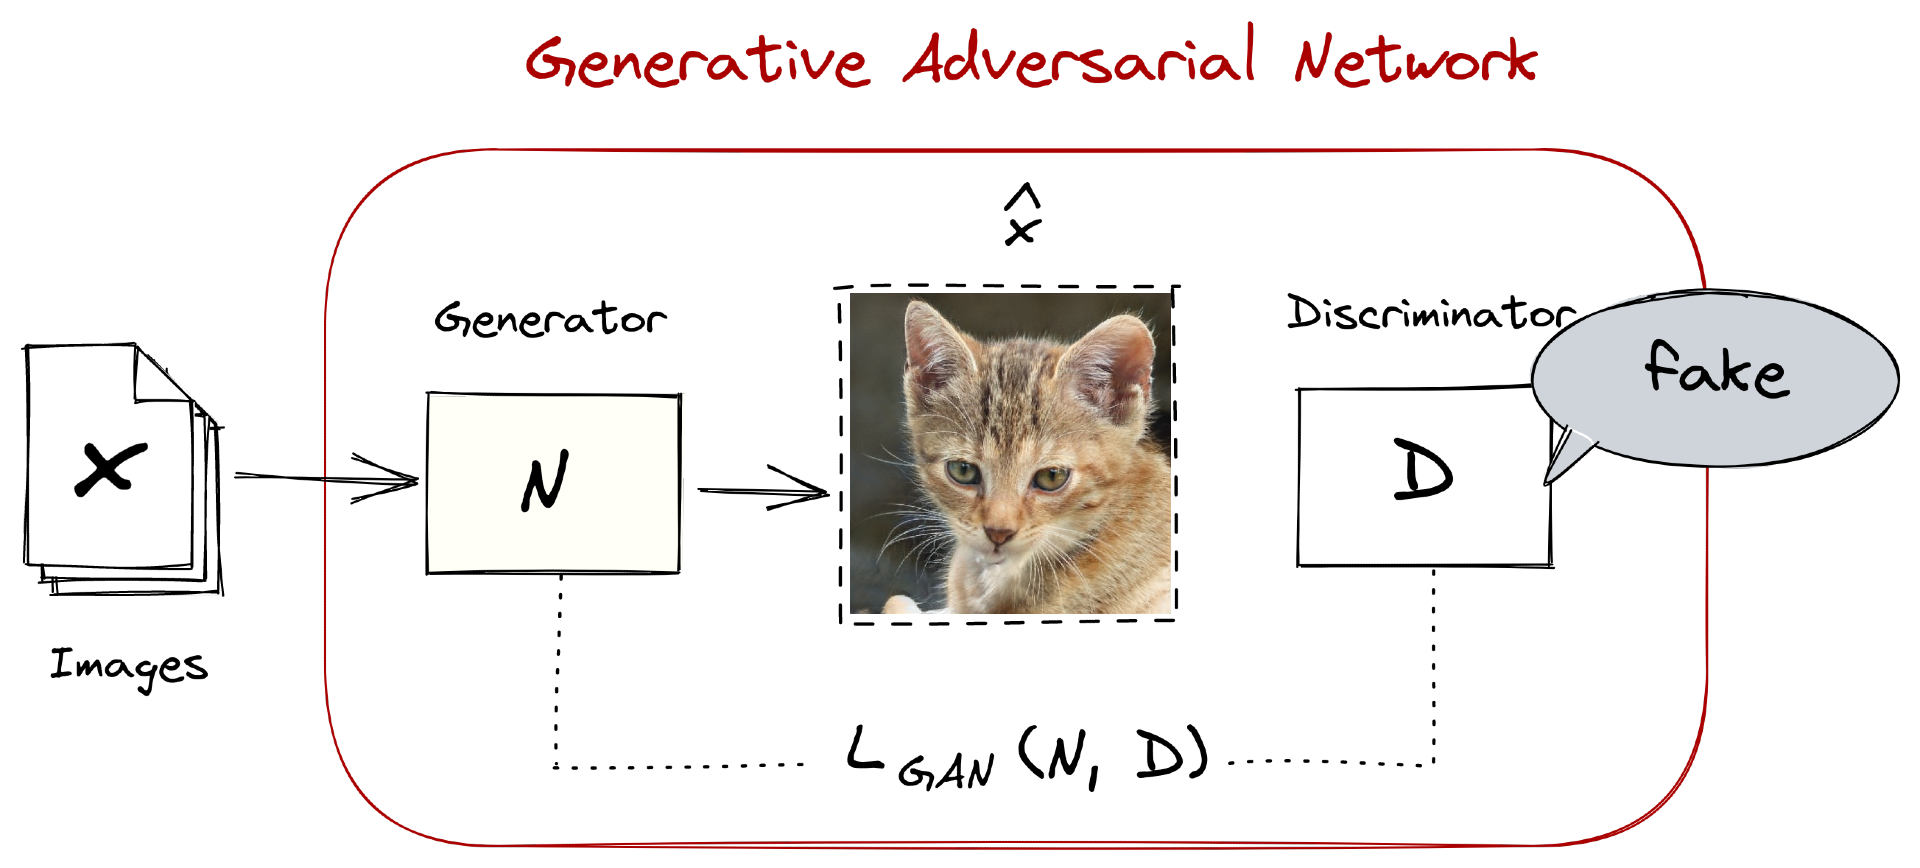
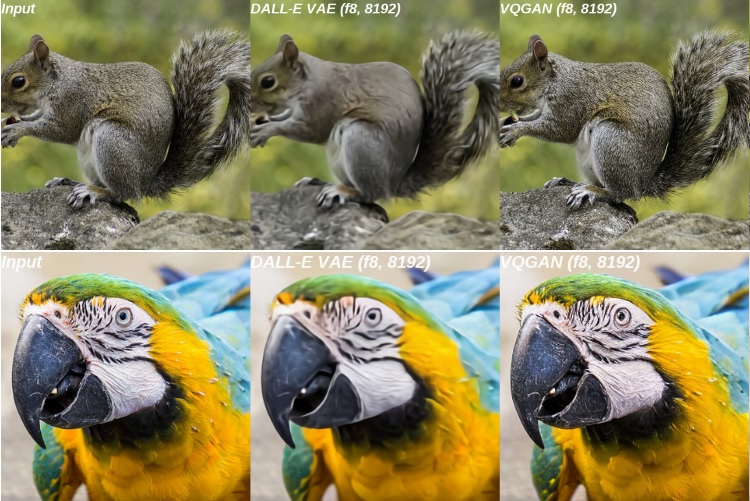
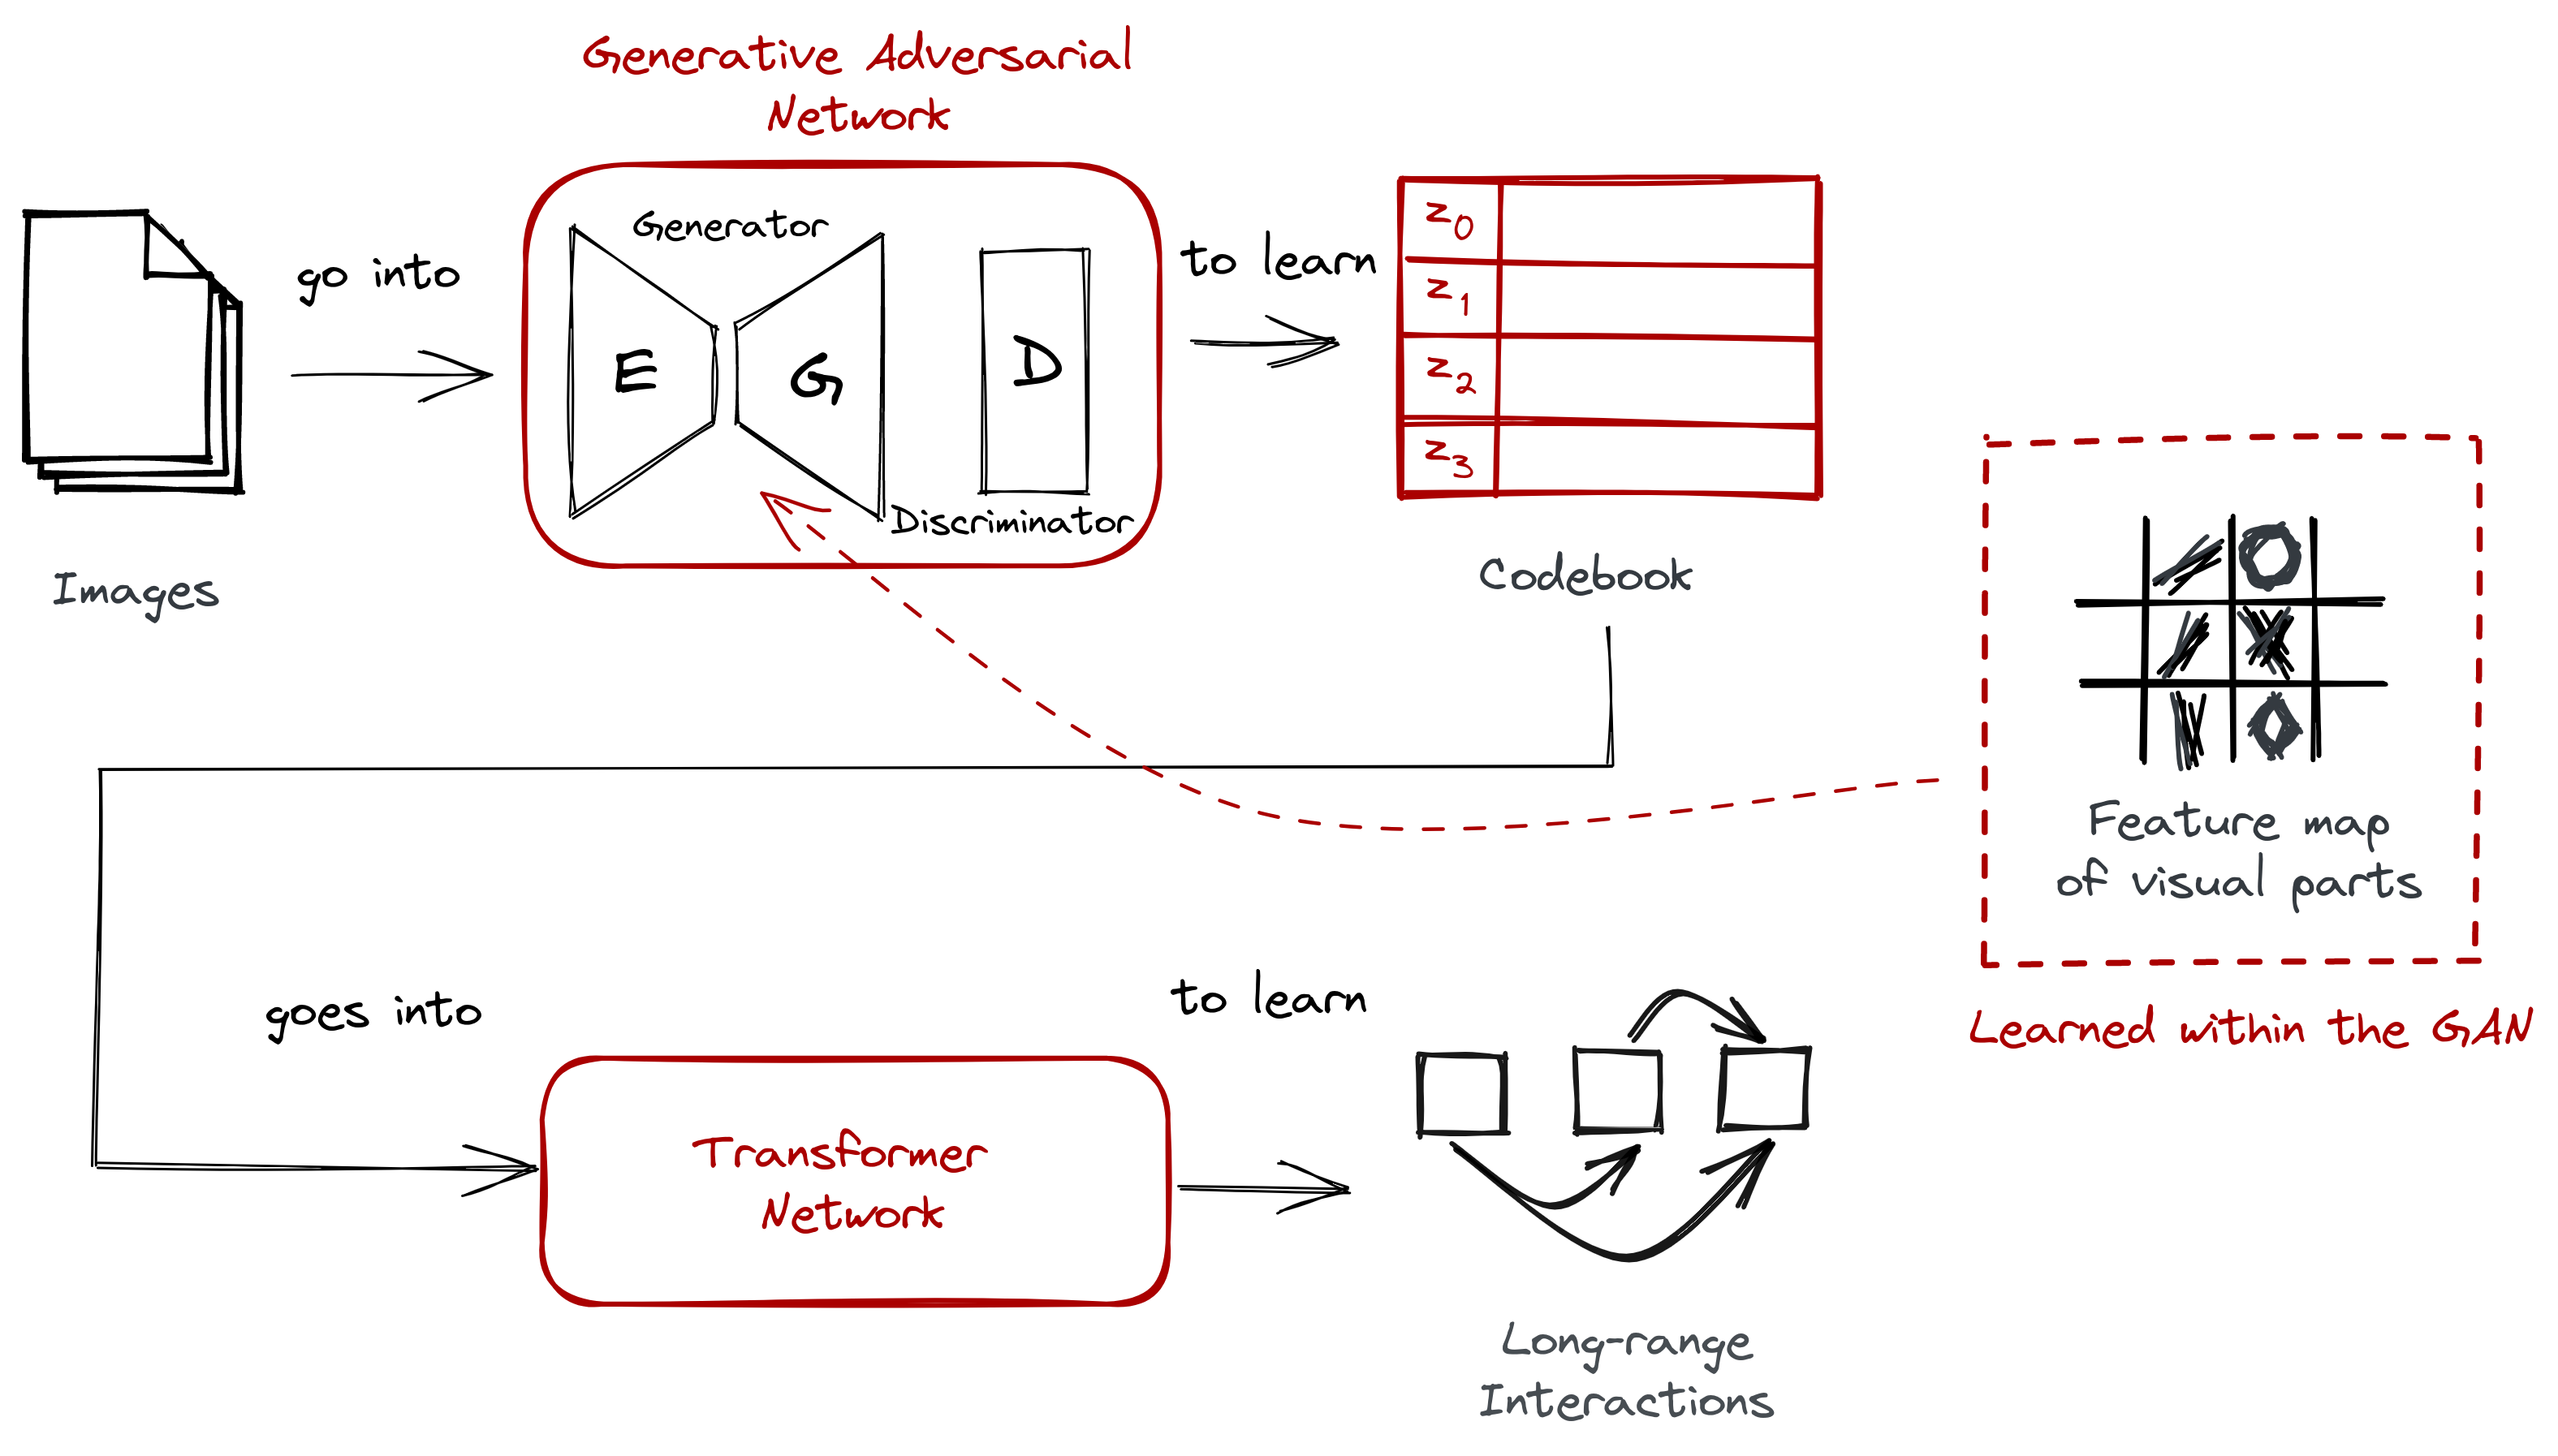
The Illustrated VQGAN
Scaling the Codebook Size of VQGAN to 100,000 with a Utilization Rate ...
Examples of Vegan Foods for Every Taste
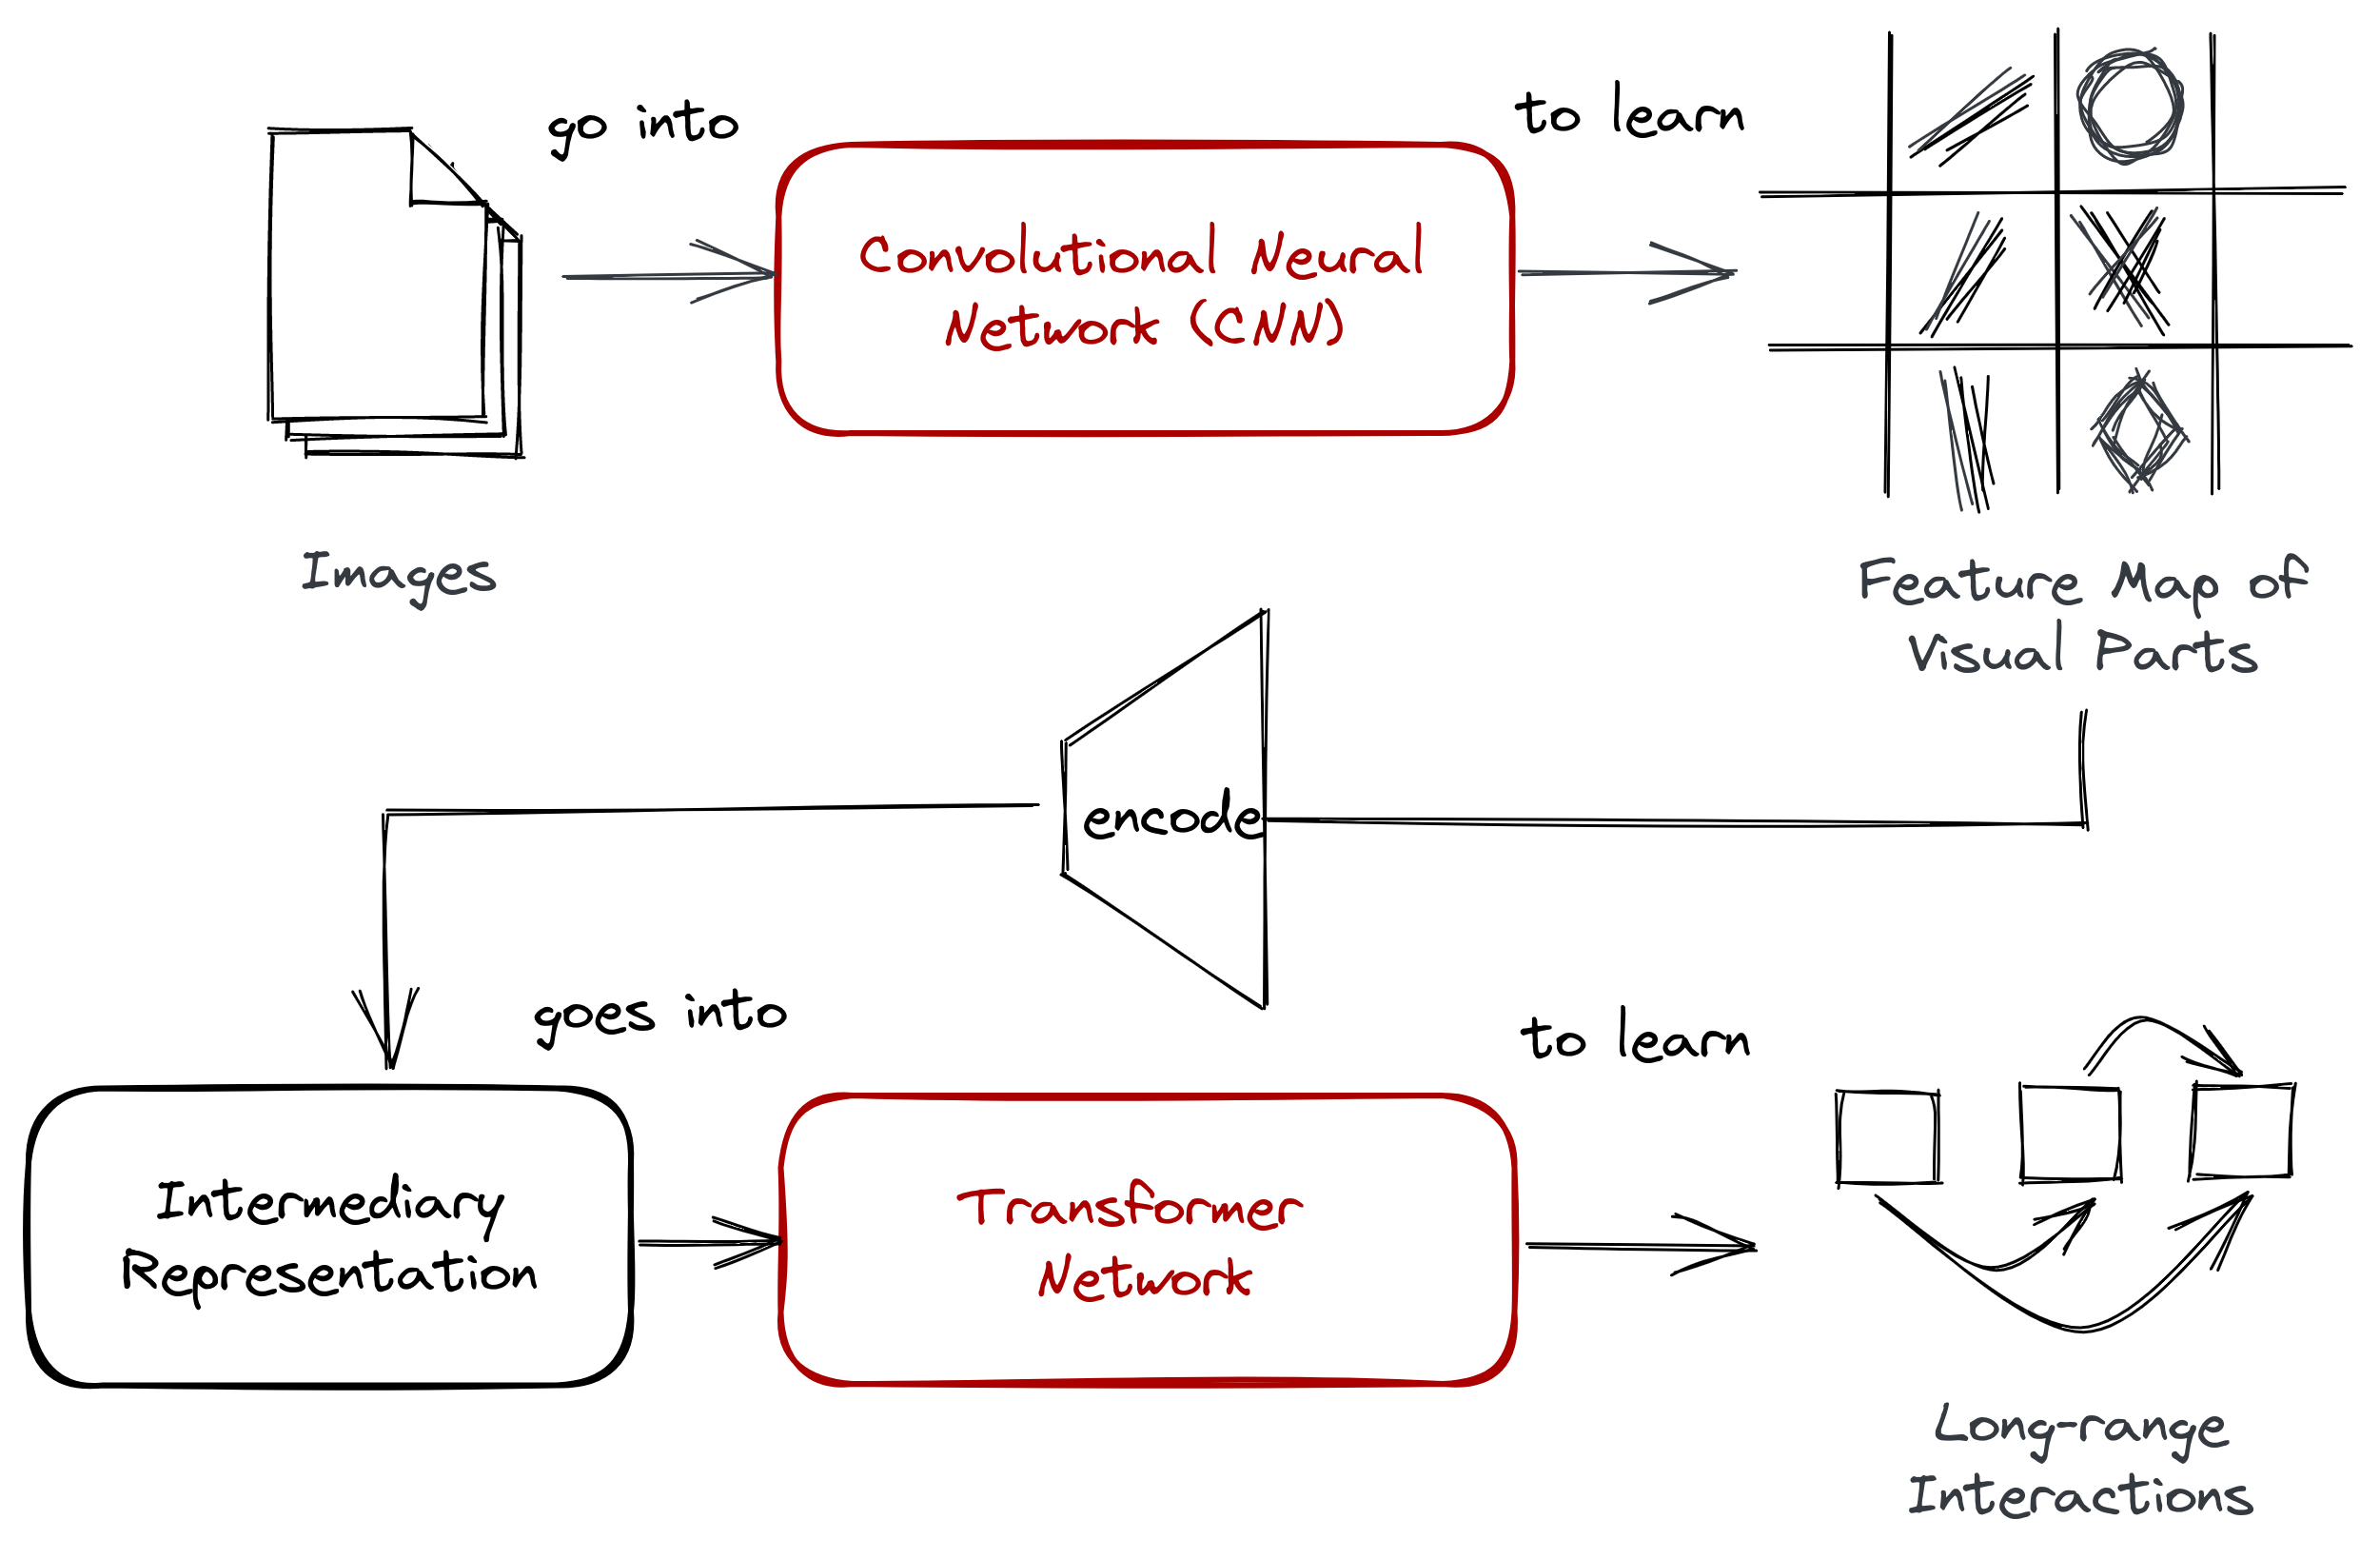
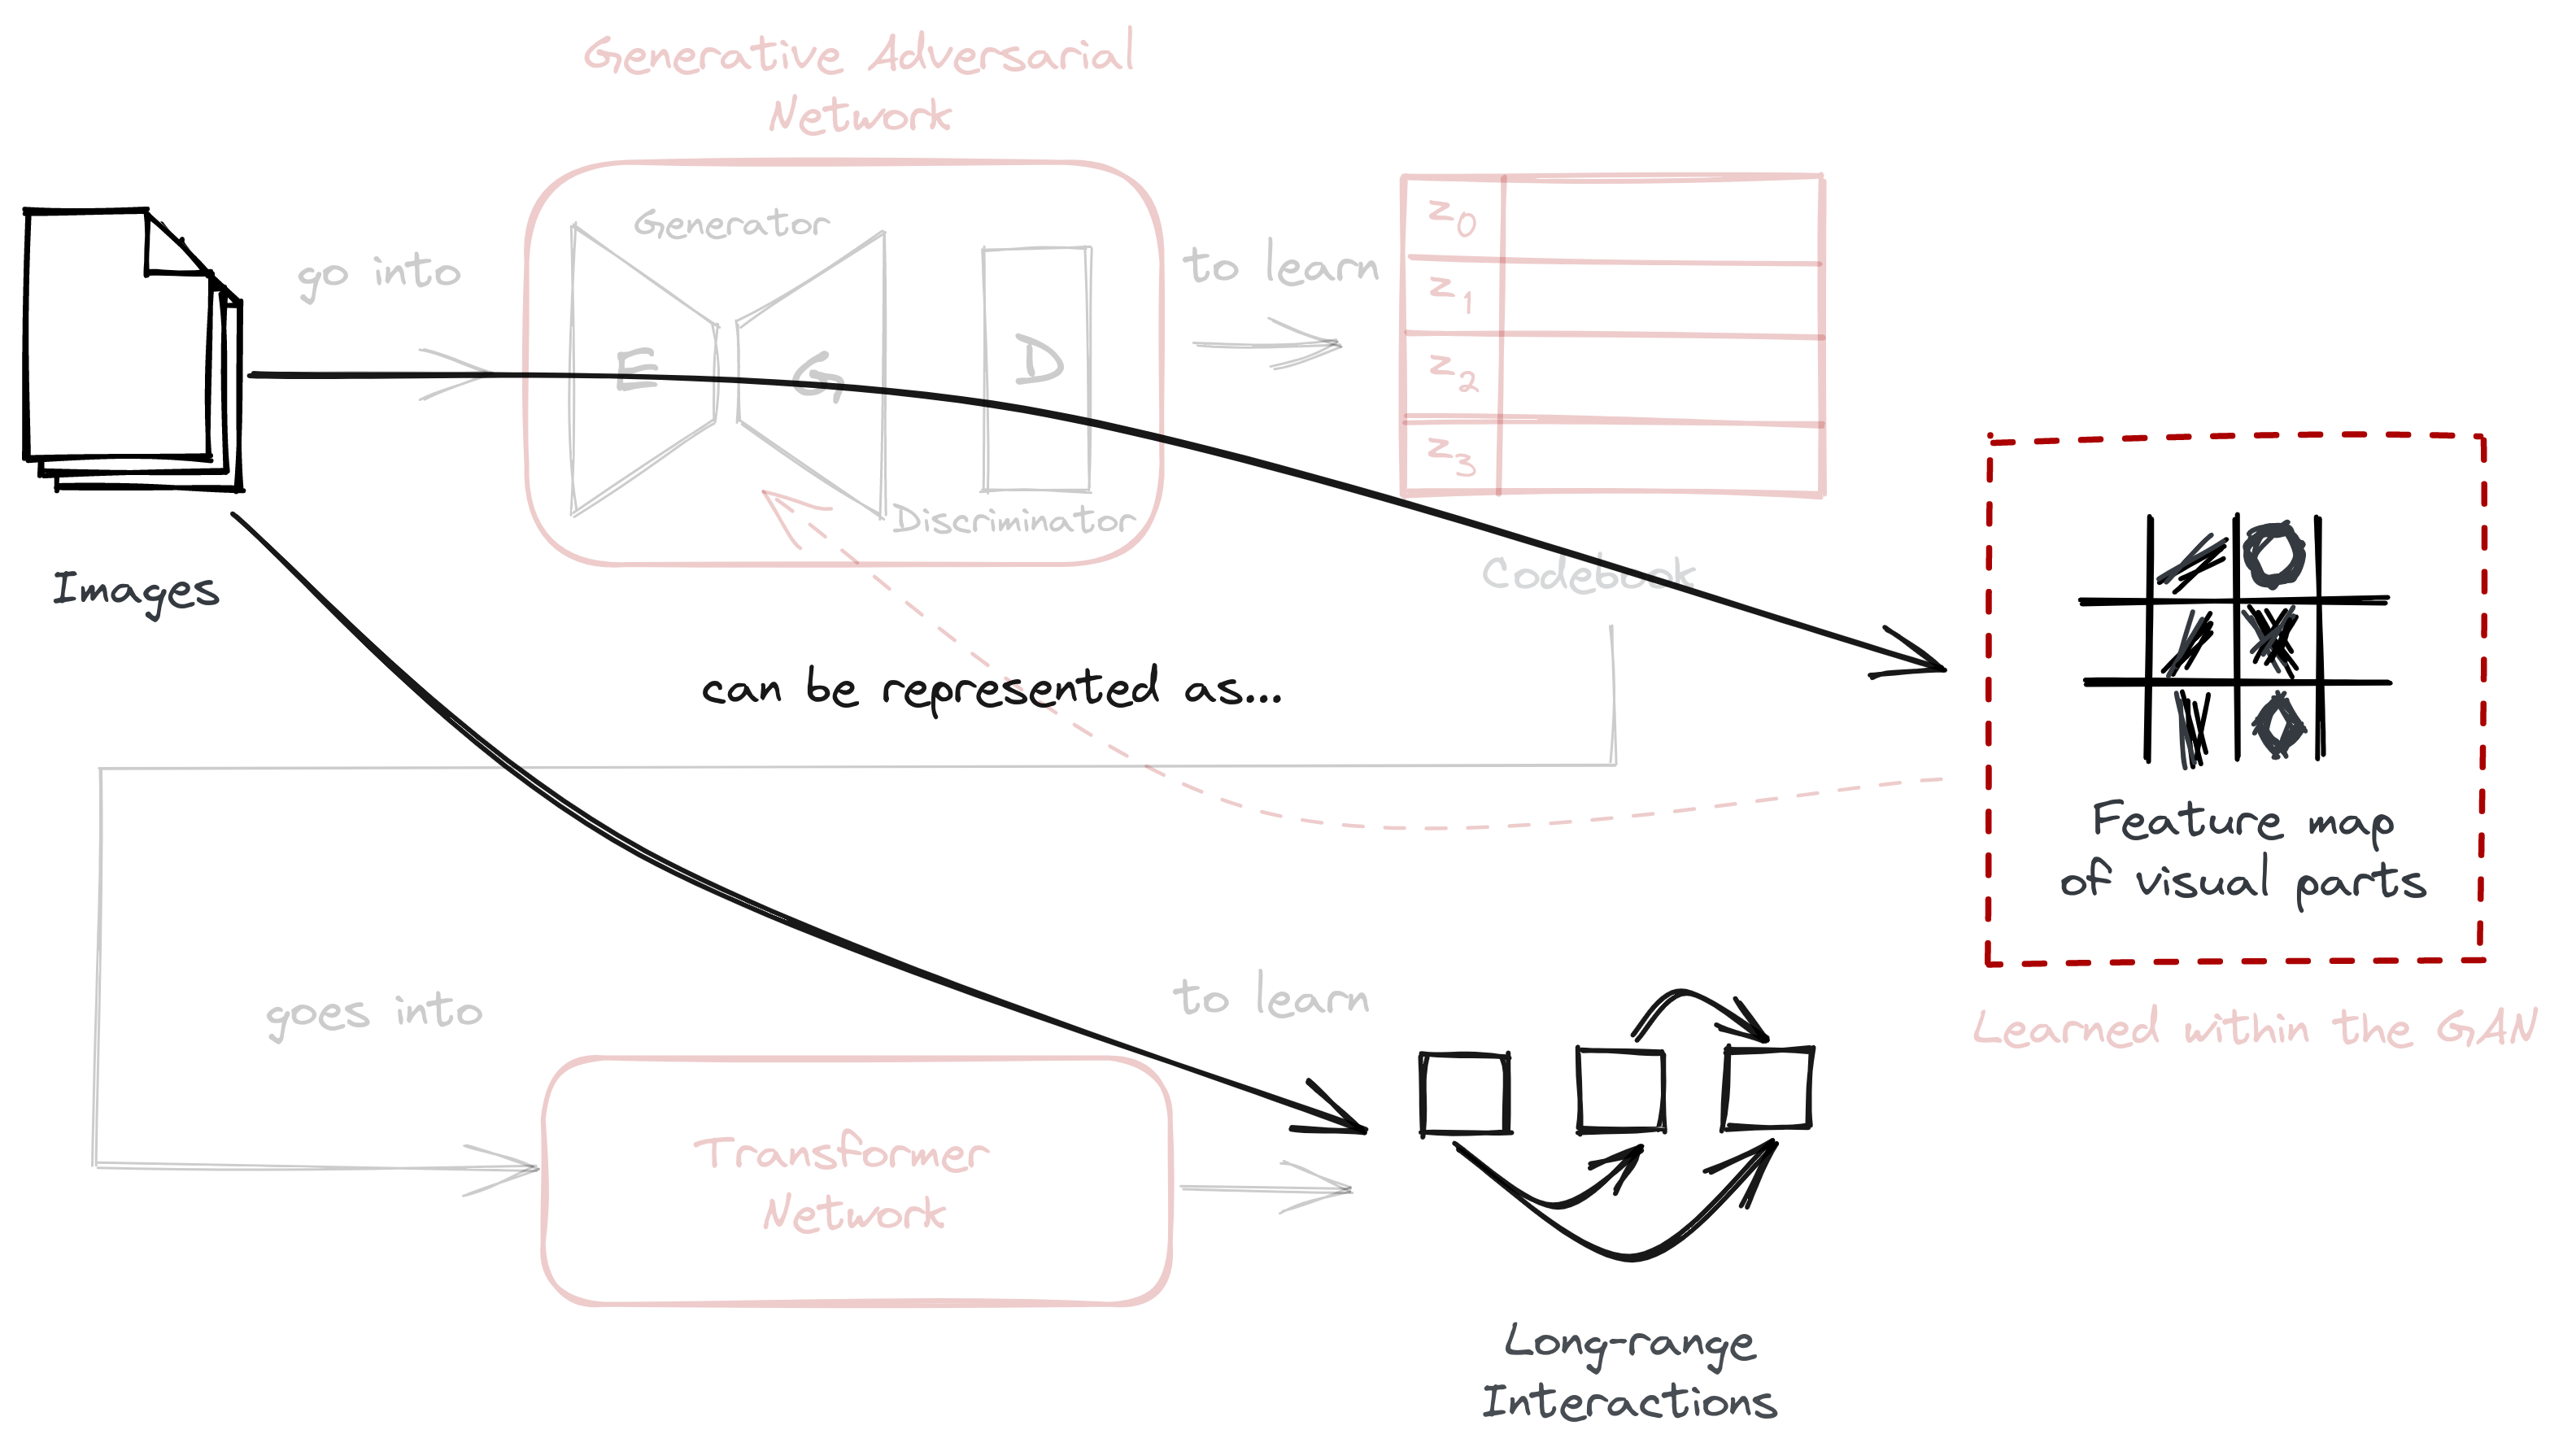
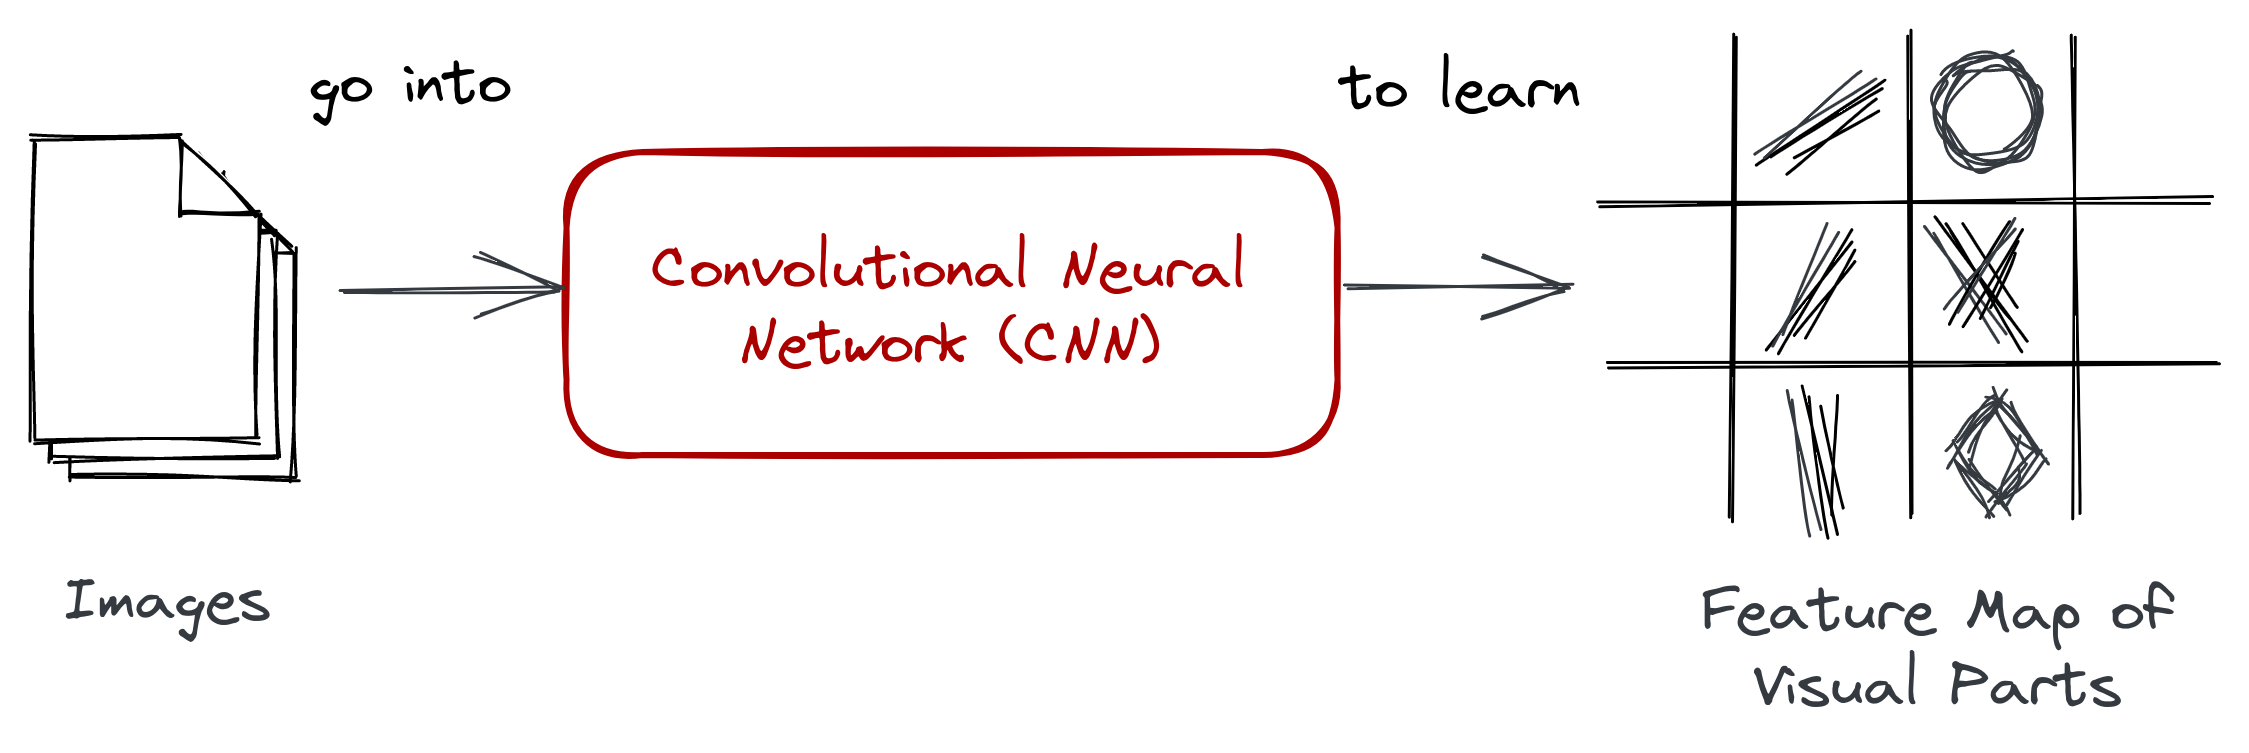
A visualization of the flow of VQGAN image processing with a CNN ...
Text-to-image generation examples of clearer imagination a Generation ...
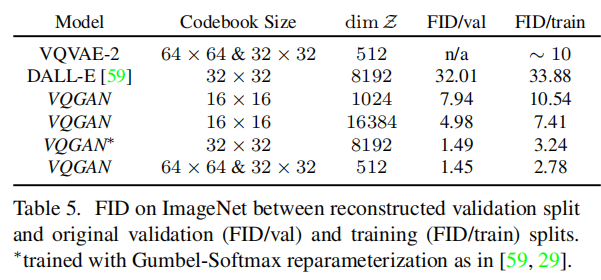
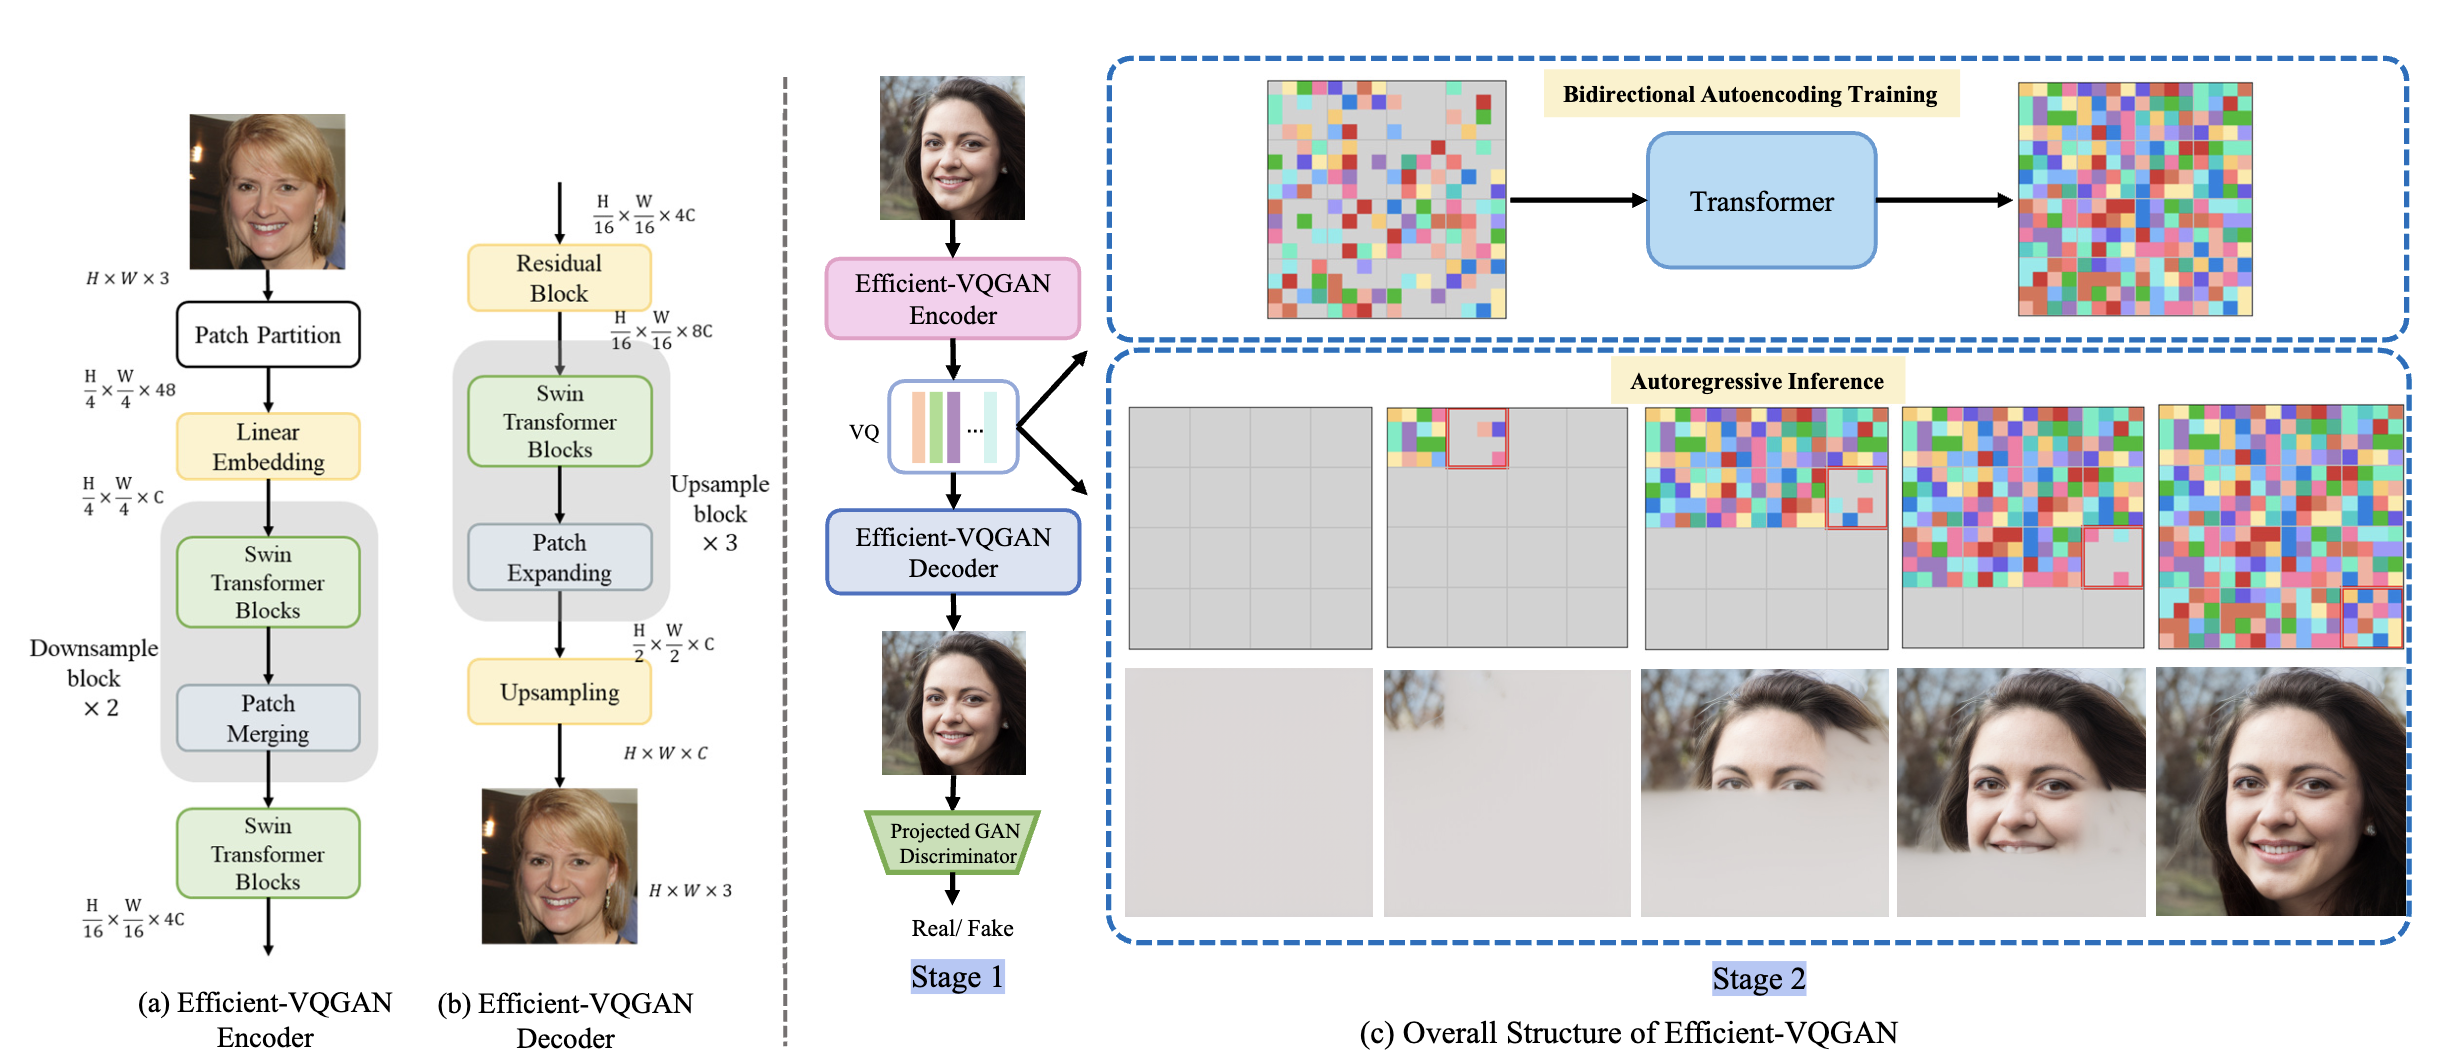
Vector-Quantized Image Modeling with Improved VQGAN : r/PaperArchive
Brief illustration of VQGAN model [29]. | Download Scientific Diagram
[论文阅读] Vector-quantized Image Modeling with Improved VQGAN - NoNoe - 博客园
Vegan Meal Examples
[2306.04632] Designing a Better Asymmetric VQGAN for StableDiffusion
VQ-VDM: Video Diffusion Models with 3D VQGAN
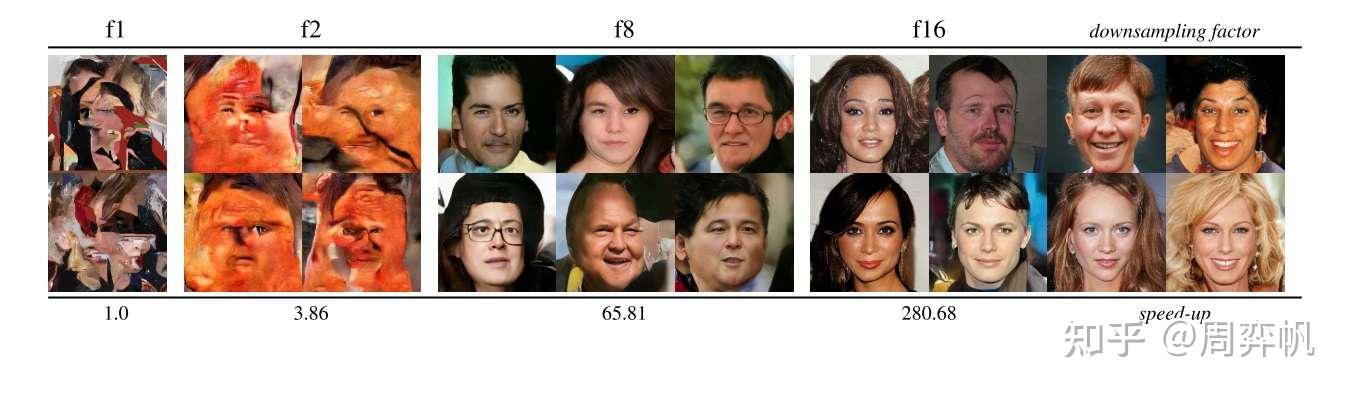
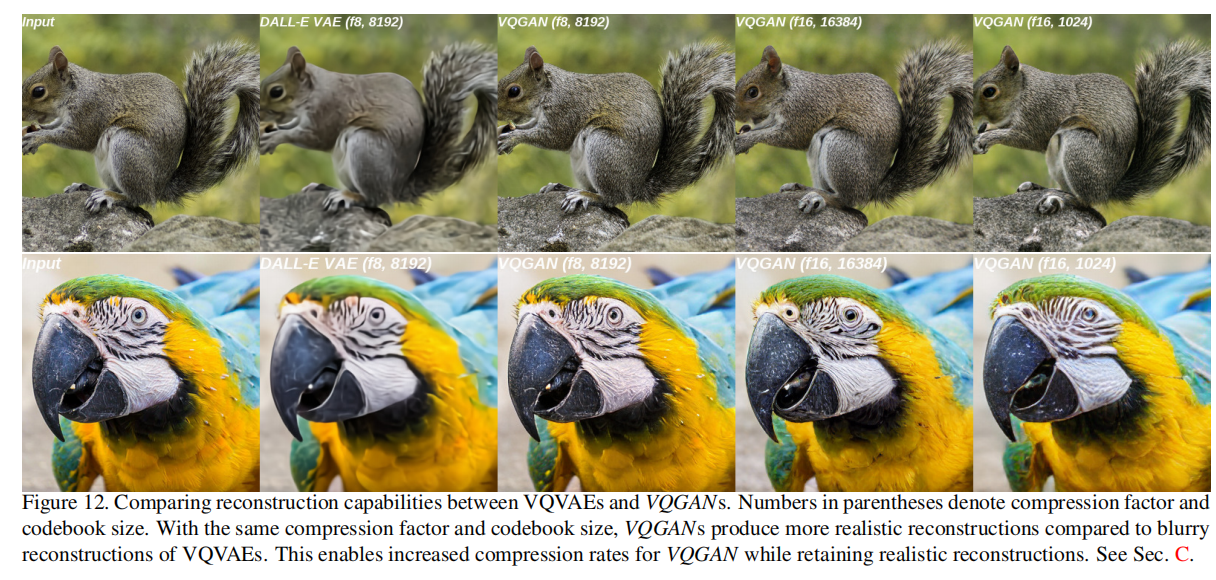
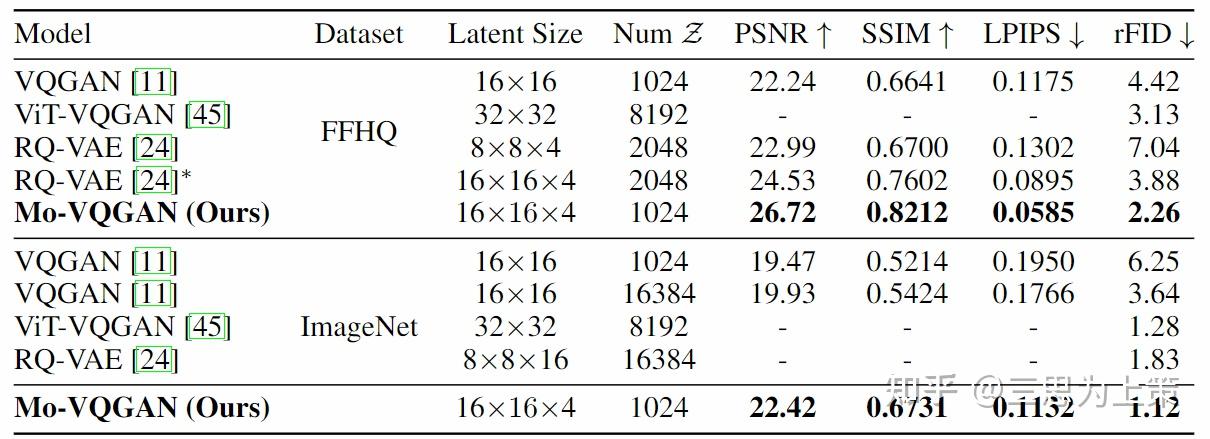
VQGAN 论文与源码解读:前Diffusion时代的高清图像生成模型 | 周弈帆的博客
VQGAN 论文与源码解读:前Diffusion时代的高清图像生成模型 - 知乎
Paper page - Designing a Better Asymmetric VQGAN for StableDiffusion
Examples from the VQGAN-sim random samples. We visualize both the ...
Video generation results with a vanilla video VQGAN and a time-agnostic ...
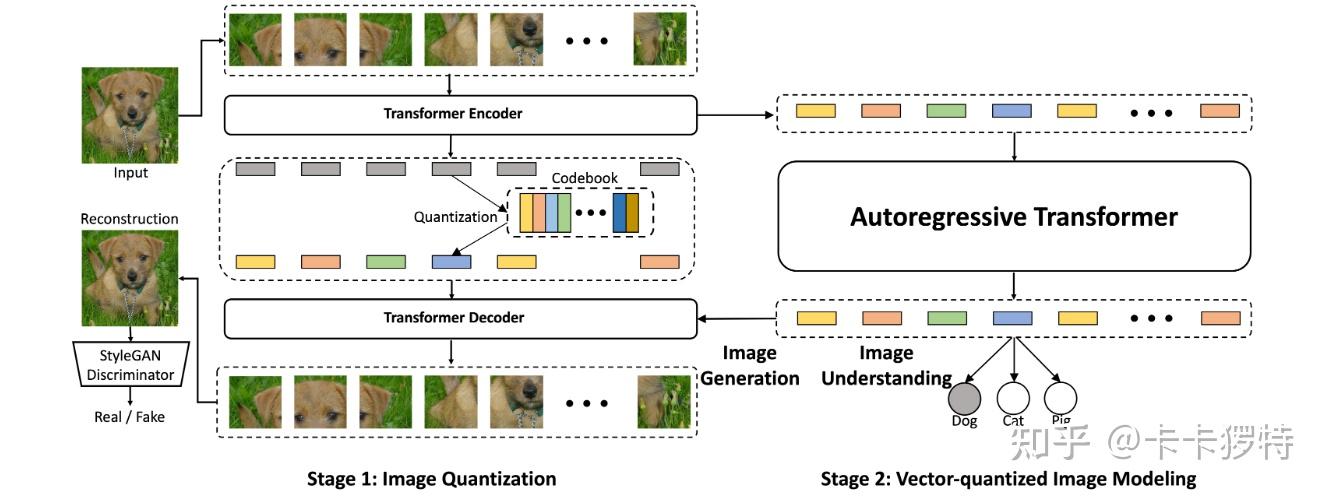
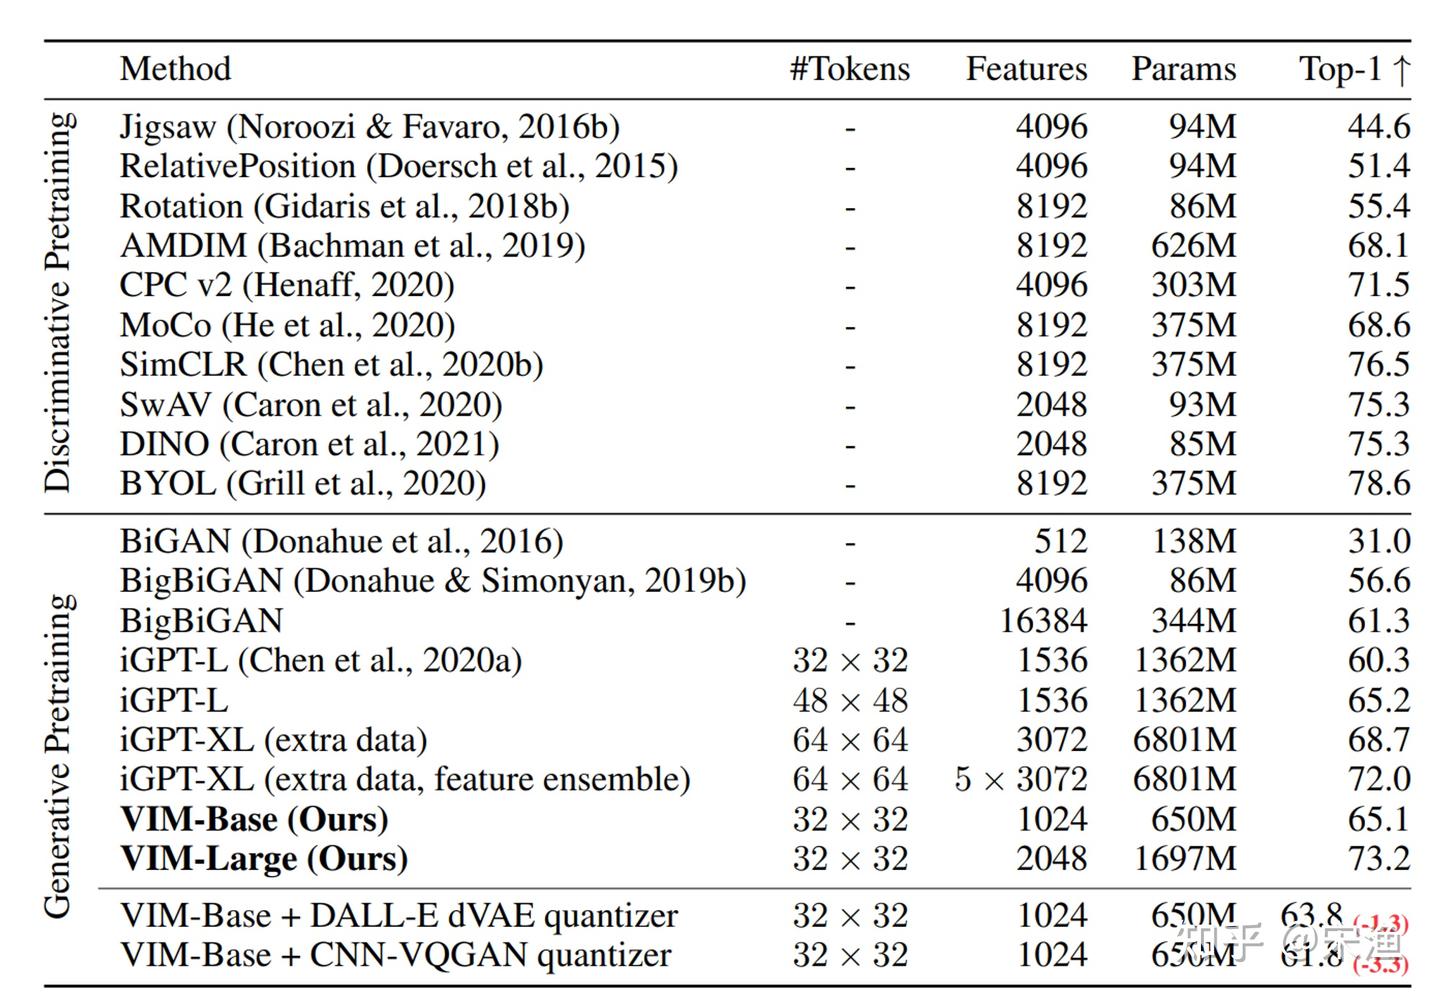
自回归视觉生成模型解读 (七):VIM:使用 ViT 改进的 VQGAN 进行矢量量化图像生成 - 知乎
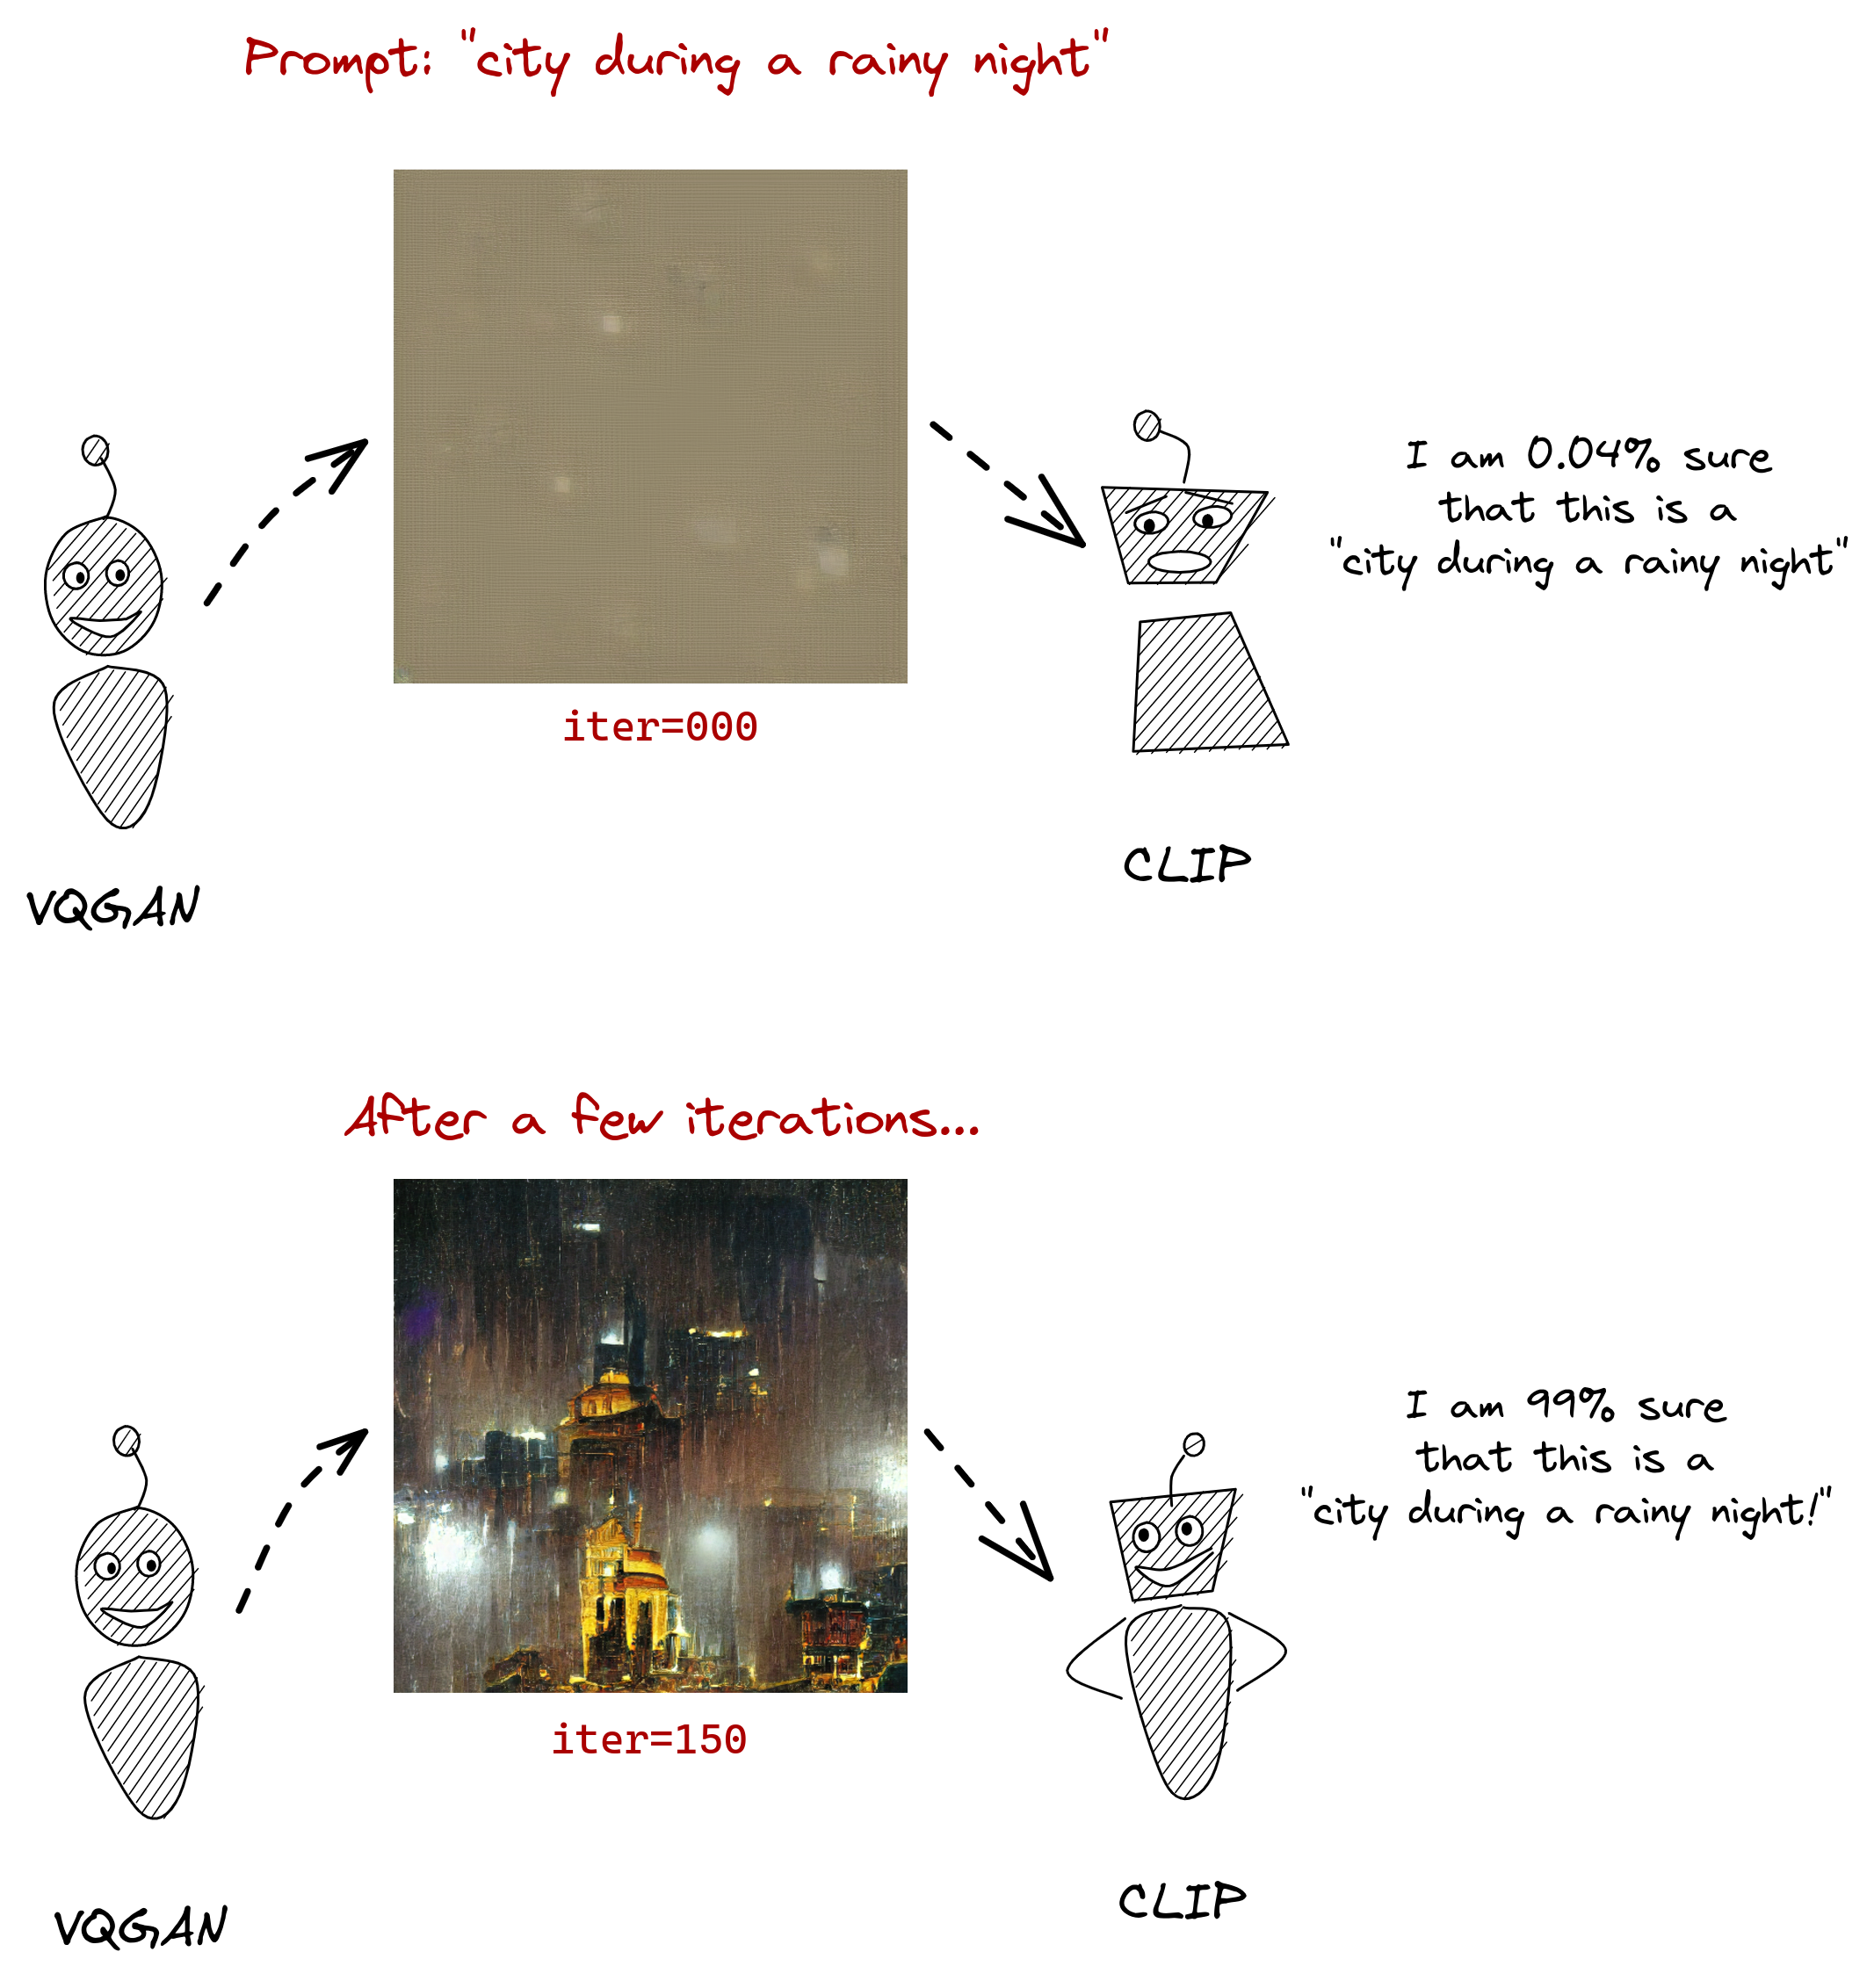
Three samples of generative deep learning using VQGAN and CLIP ...
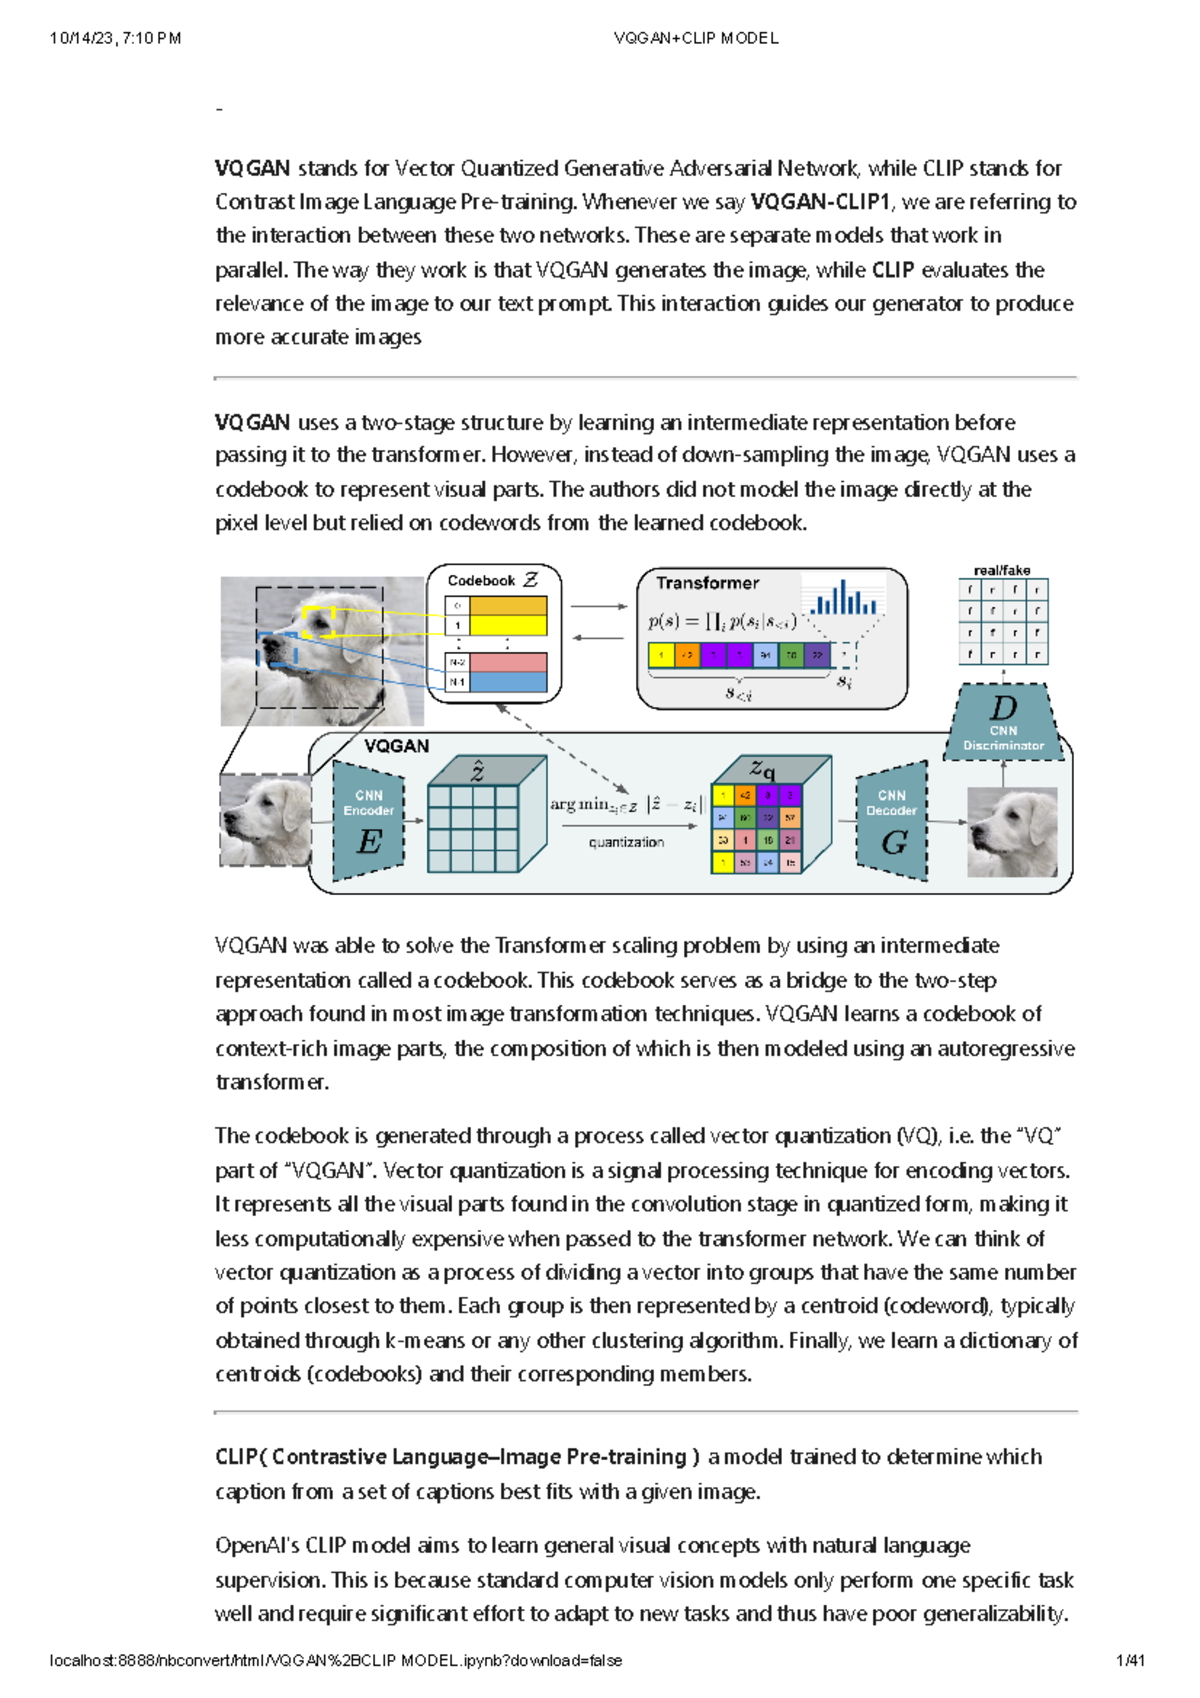
Vqgan+CLIP Model - VQGAN Contrast Image Language Pre-training. Whenever ...
Designing a Better Asymmetric VQGAN for Stable Diffusion : r ...
Using initial images with VQGAN + Clip | Unlimited Dream Co.
Text to Image Generation | VQGAN Transformer & CLIP (Part 2) - YouTube
🌅 Edge#229: VQGAN + CLIP - by Jesus Rodriguez
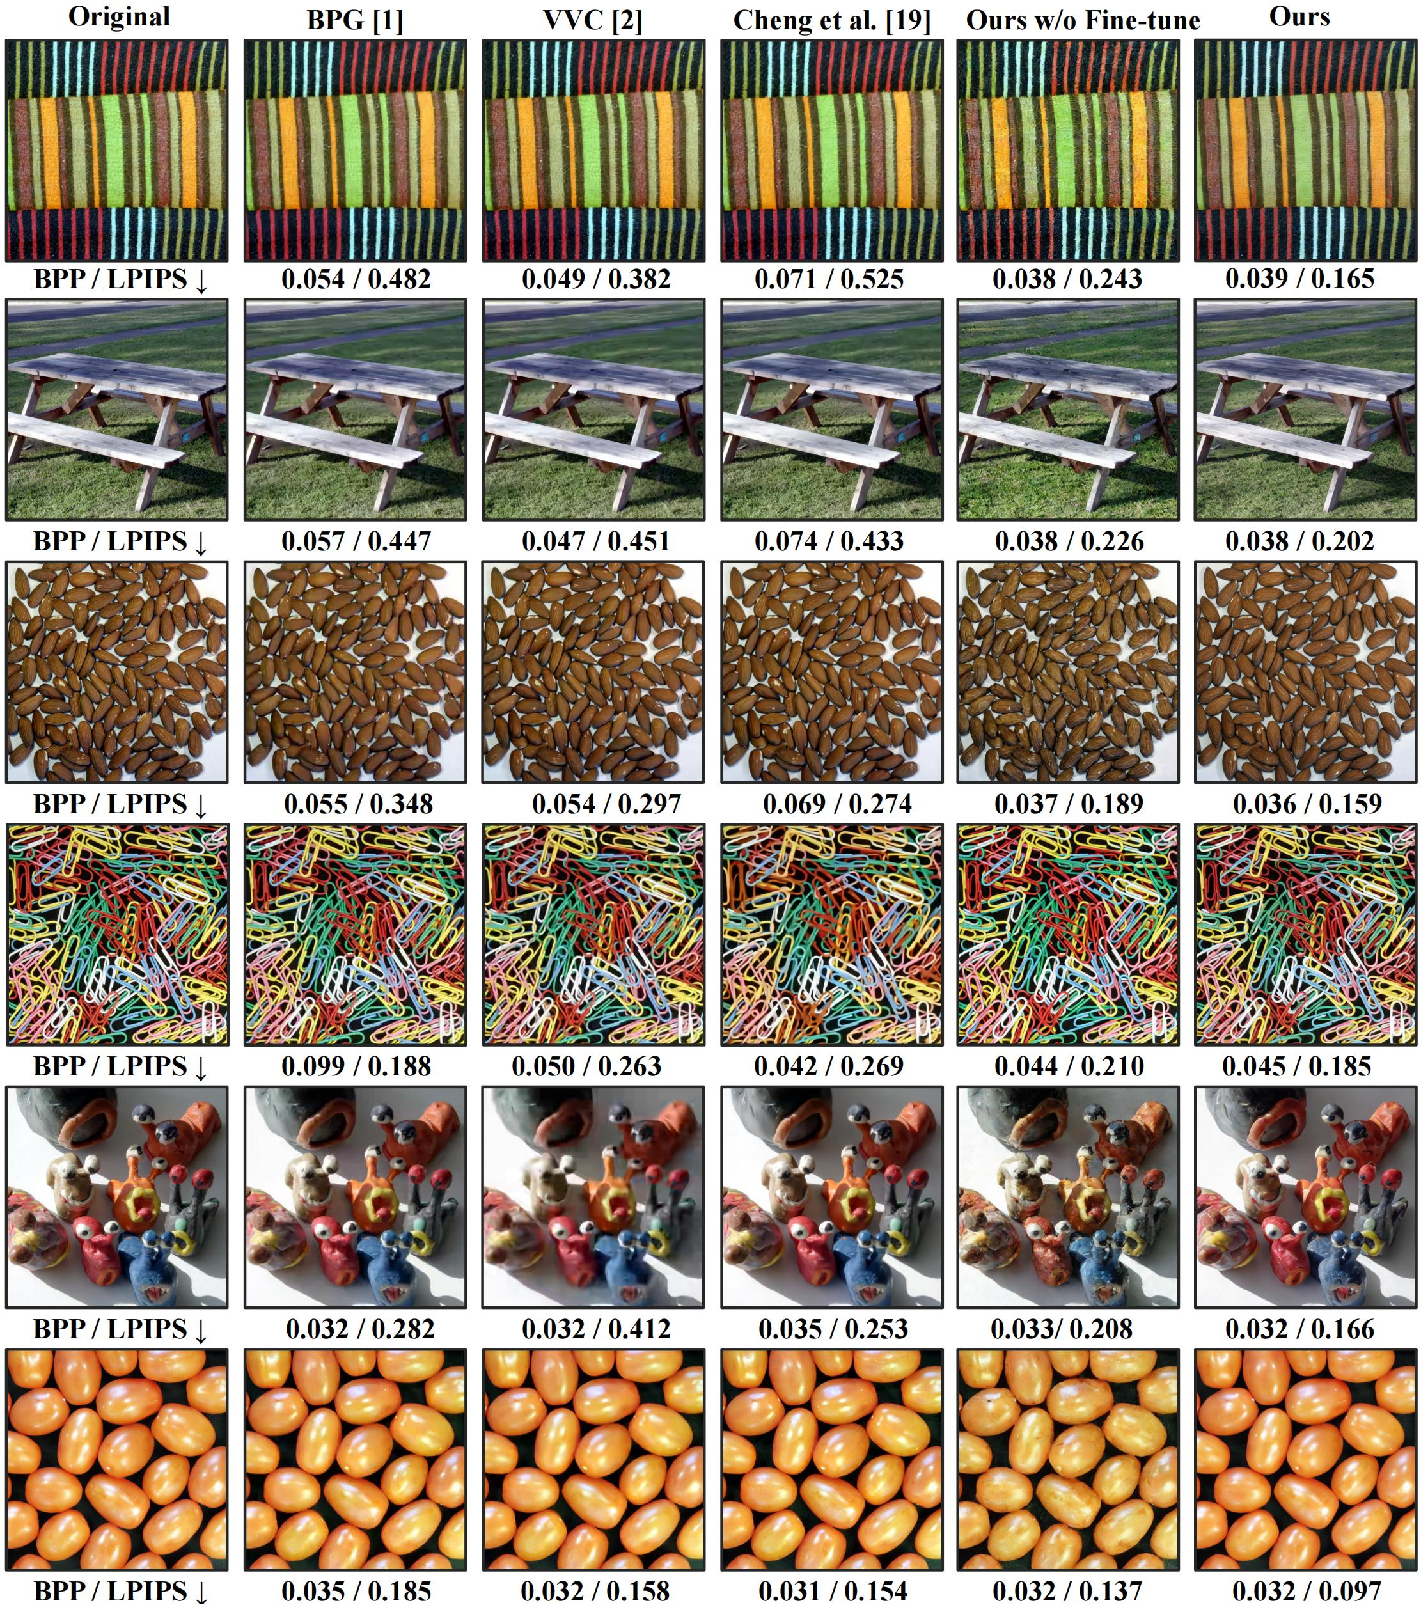
Figure 1 from Extreme Image Compression using Fine-tuned VQGAN Models ...
Figure 10 from Extreme Image Compression using Fine-tuned VQGAN Models ...
[P] Training a VQGAN but GAN loss keeps going up : r/MachineLearning
Synthetic imagery and VQGAN+CLIP
Vector-Quantized VAE / GAN / Diffusion - 知乎
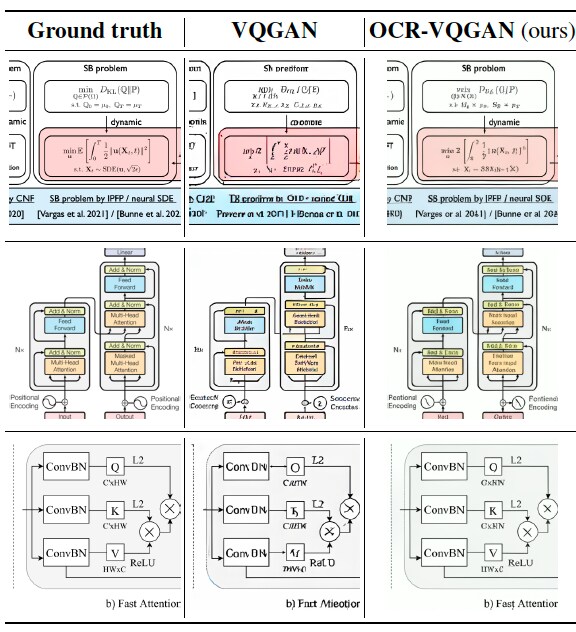
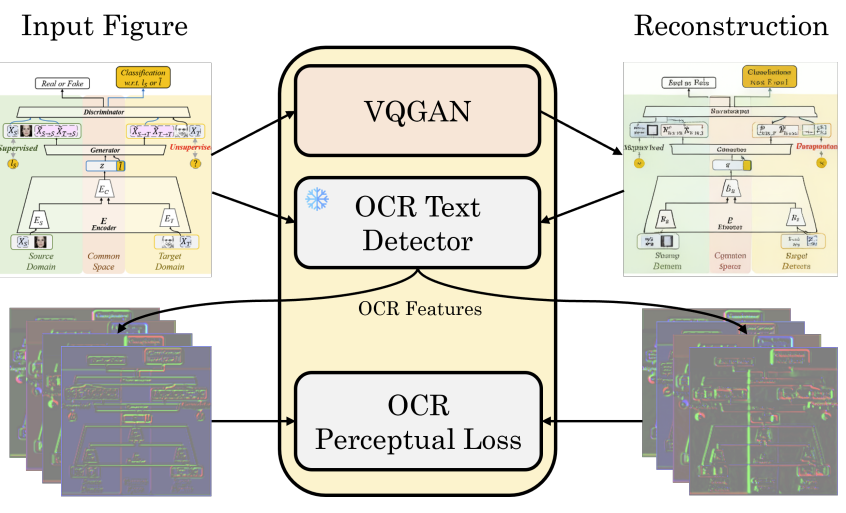
OCR-VQGAN: Taming Text-within-Image Generation | David Vázquez
100 images generated using the VQGAN+CLIP code and evaluation of their ...
自回归图像生成中的Visual Tokenizers第三谈 - 知乎
GitHub - hongrui16/VQ-VAE-GAN-Diffusion · GitHub
SpookyGAN - Rendering Scary Faces with Machine Learning | Towards Data ...
AIGC实战——VQ-GAN(Vector Quantized Generative Adversarial Network)_vqgan和 ...
VQGAN(Vector Quantized Generative Adversarial Network)模型简介-CSDN博客
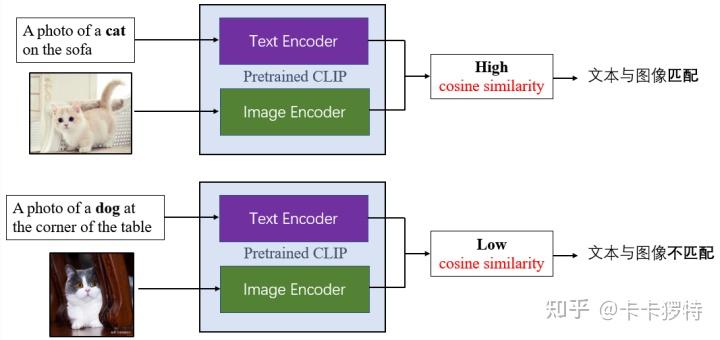
详解VQGAN(三)| VQGAN在文本-图像生成(+CLIP) · 图像理解/分类 · 图像修复等方面的应用 - 知乎
(Color online) Figure inspired from [4] presenting the training ...
VQGAN: Empowering Computer Vision with Compositional Modeling
What's a VQGAN? : r/StableDiffusion
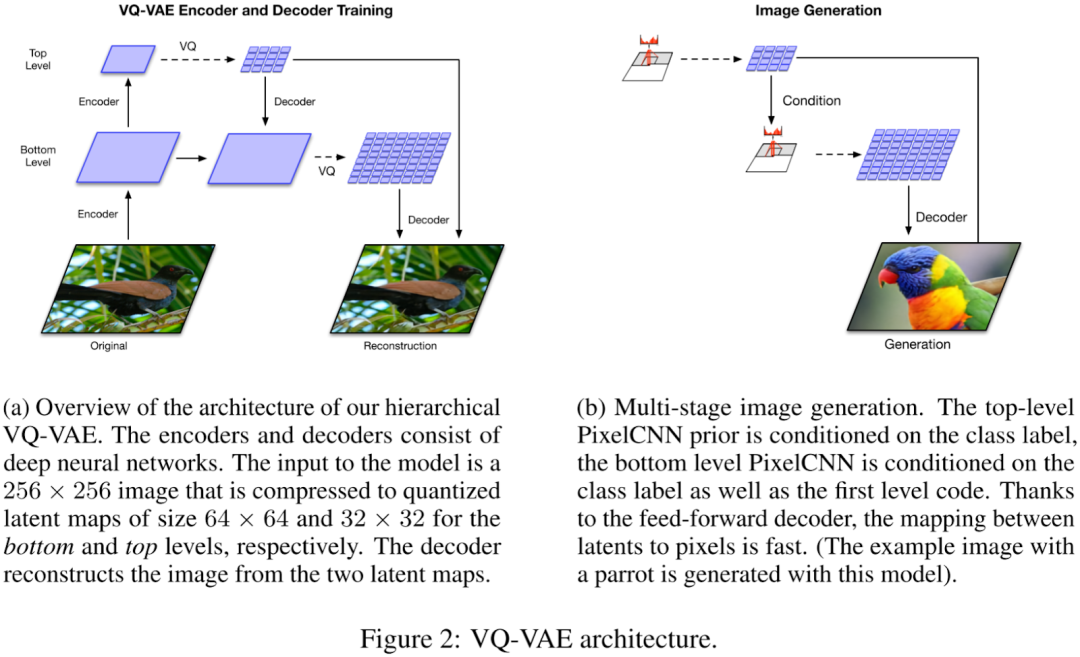
VQ-VAE/VQGAN及改良工作小汇总 - 知乎
Go Vegan! - EXAMPLE.PL | Going vegan, Vegan recipes, Food
Meal Planner – Born Free
ViT-VQGAN:Vector-quantized Image Modeling with Improved VQGAN论文笔记 - 知乎
ibm-research/materials.3dgrid_vqgan · Hugging Face
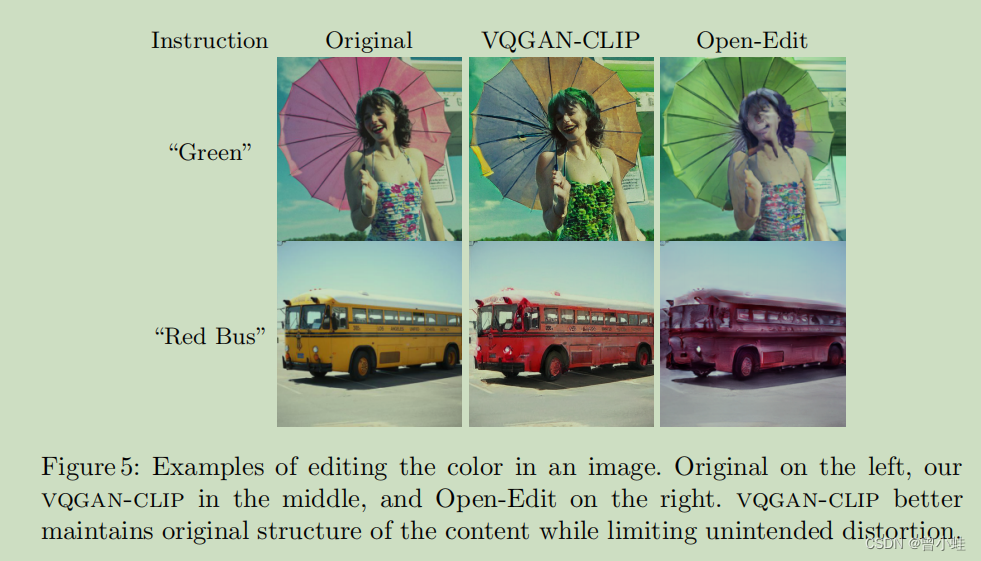
论文笔记:VQGAN-CLIP:Open Domain Image Generationand Editing with Natural ...
VQGAN: Taming Transformers for High-Resolution Image Synthesis [Paper ...
The VQ-GAN is a fully convolutional network which contains three main ...
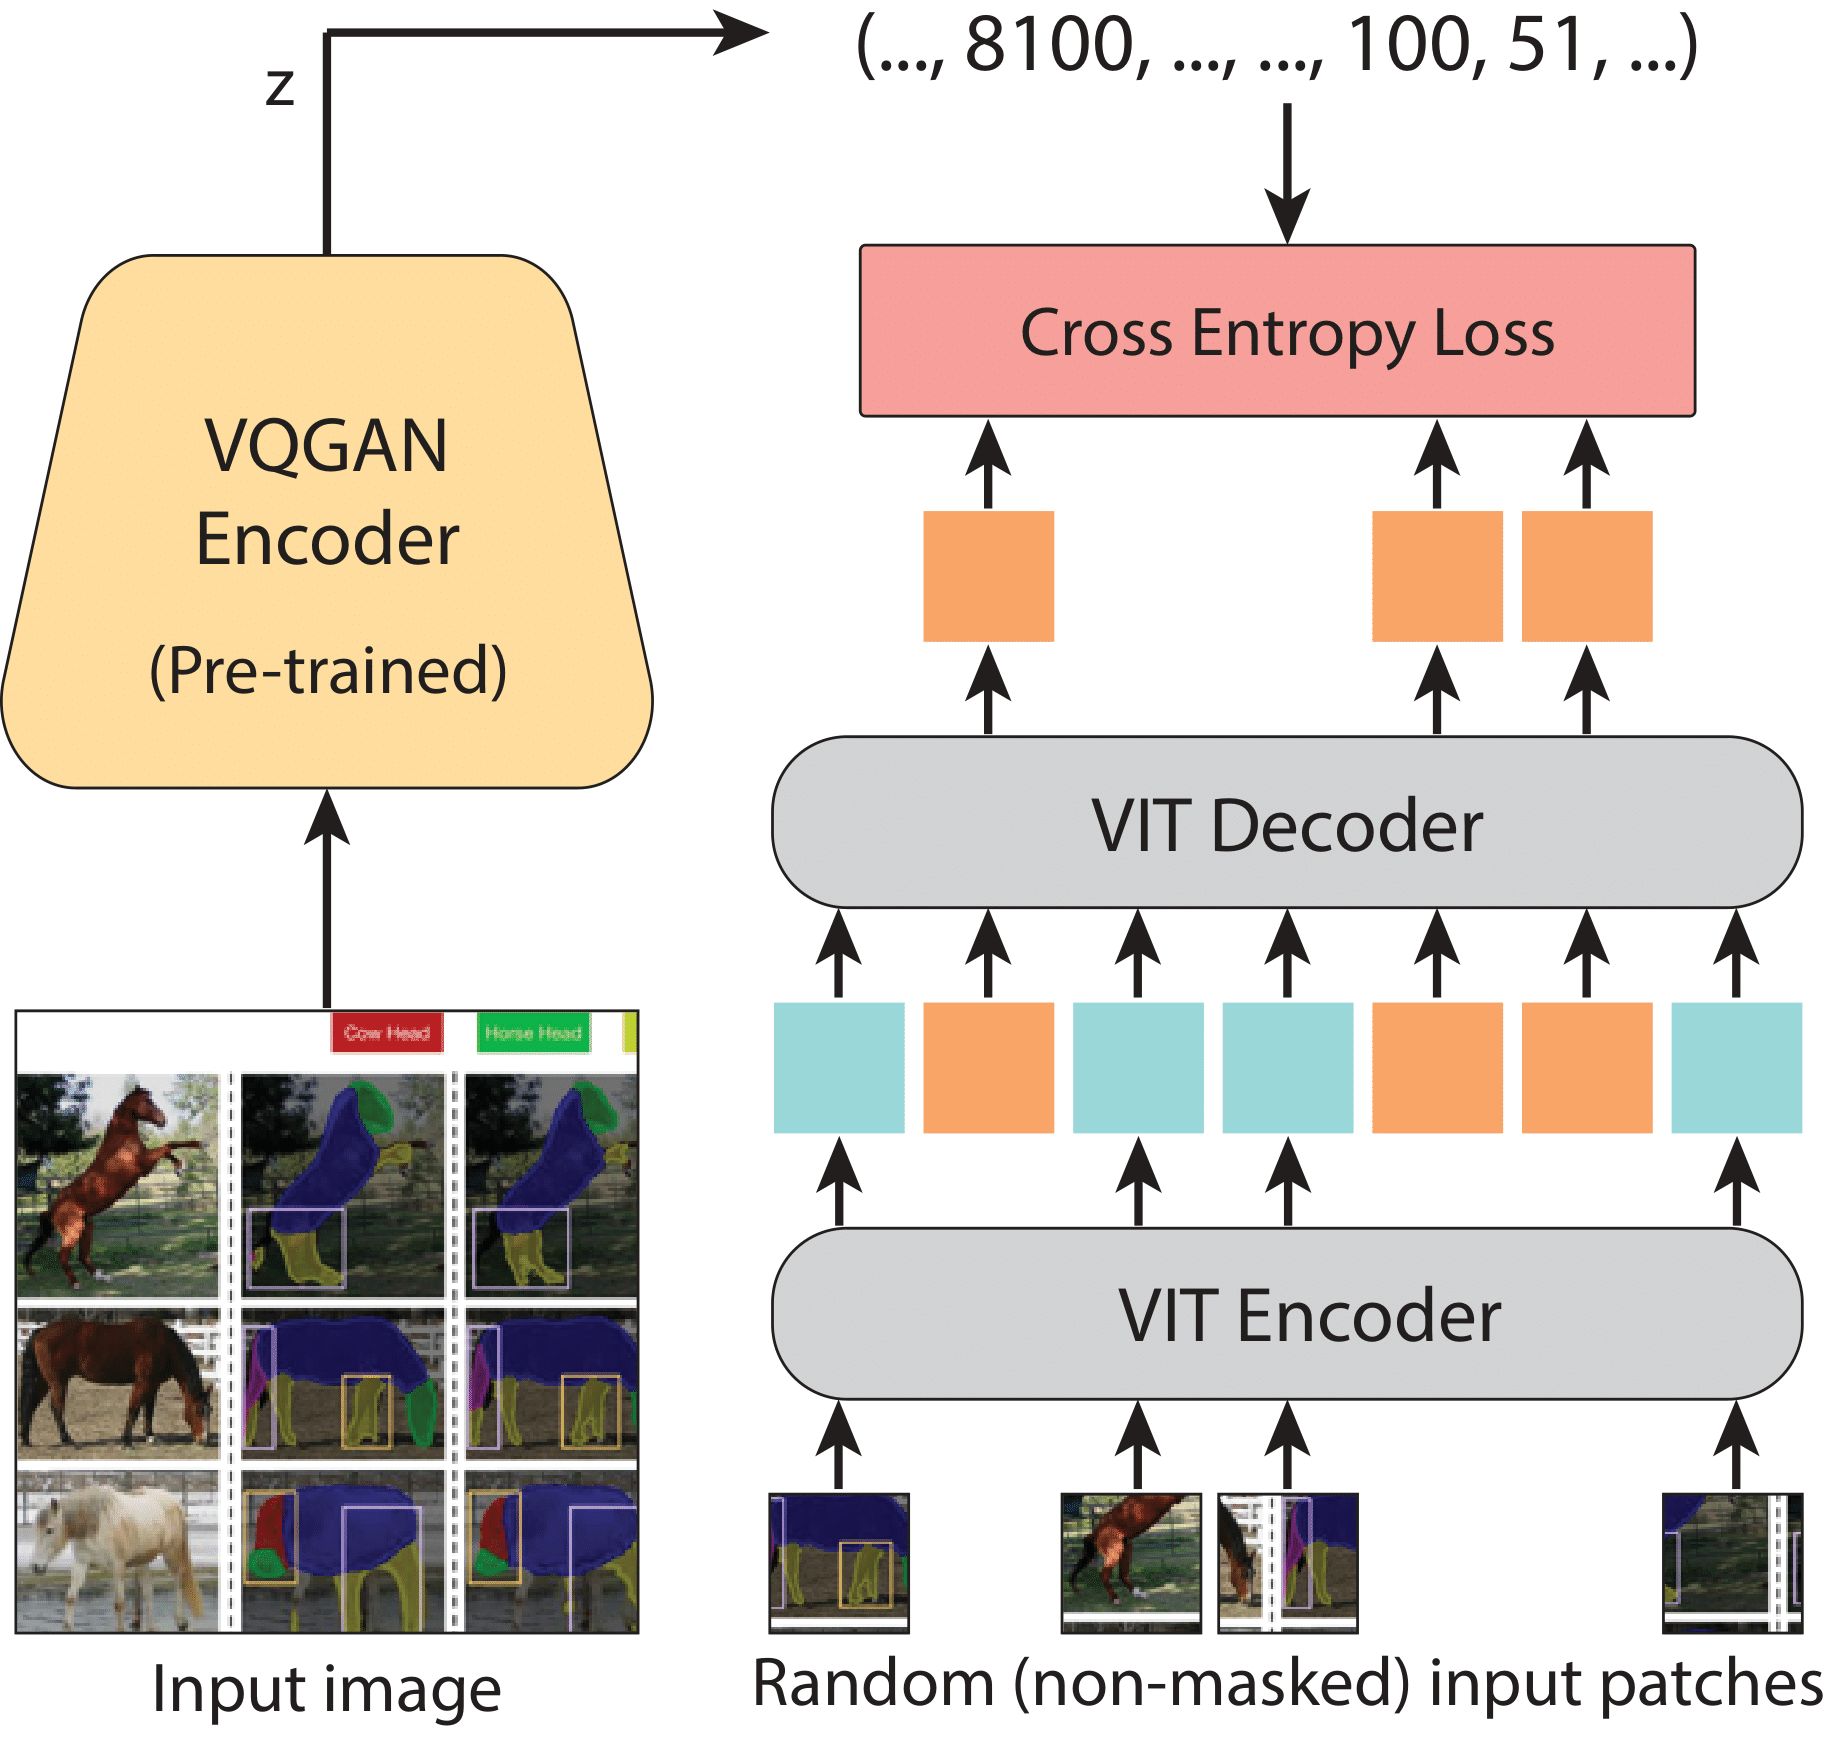
Visual Prompting via Image Inpainting
VQGAN-CLIP: Open Domain Image Generationand Editing with Natural ...
VQGAN理论加代码一对一详解,小白向解析-CSDN博客
[D] How to do VQGAN+CLIP in a single iteration - CLIP-GEN: Language ...
CLIP+VQGAN 风格关键词示例 | 混沌猫的窝
VQGAN图像生成(离散化加对抗训练)-CSDN博客
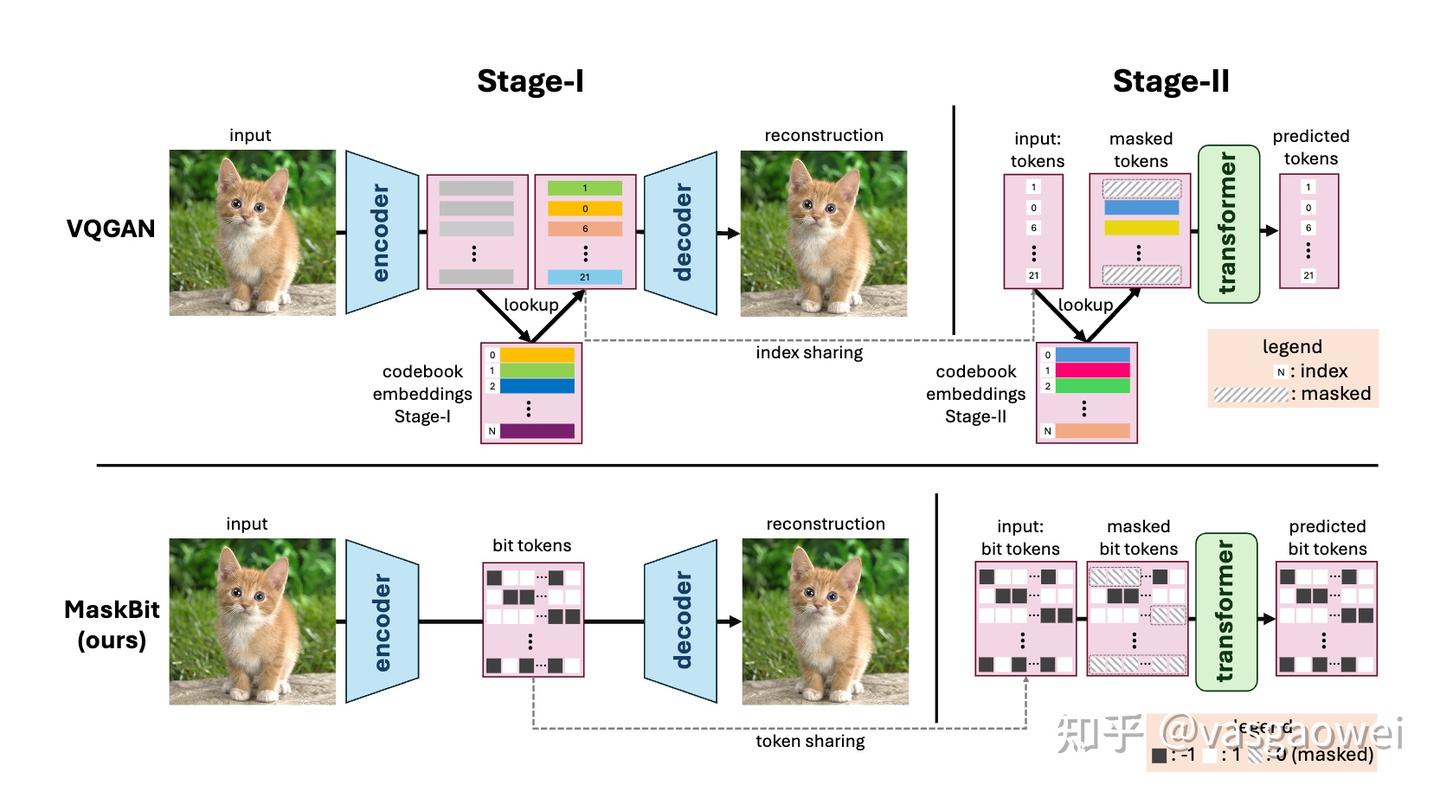
TokenFlow的Shared Mapping实现_vqkd 模型-CSDN博客
1 Day Vegan Meal Plan _ 7-Day Healthy Vegan Meal Plan – GEBK
CV每日论文--2024.6.19_vqgan-lc-CSDN博客
VQGAN源码解析 | 认养一只猪
多模态经典论文精读:VQGAN-CSDN博客
CLIP, VQGAN, VQGAN-CLIP, Stable-Diffusion - 知乎
[2210.11248] OCR-VQGAN: Taming Text-within-Image Generation
[2307.08283] Complexity Matters: Rethinking the Latent Space for ...
VQ-GAN (+CLIP) paper explained! : r/learnmachinelearning
Joan Rodriguez
【多模态】AE、VAE、VQVAE、VQGAN原理解读 - 知乎
Research steps using Vector Quantized Generative Adversarial Network ...
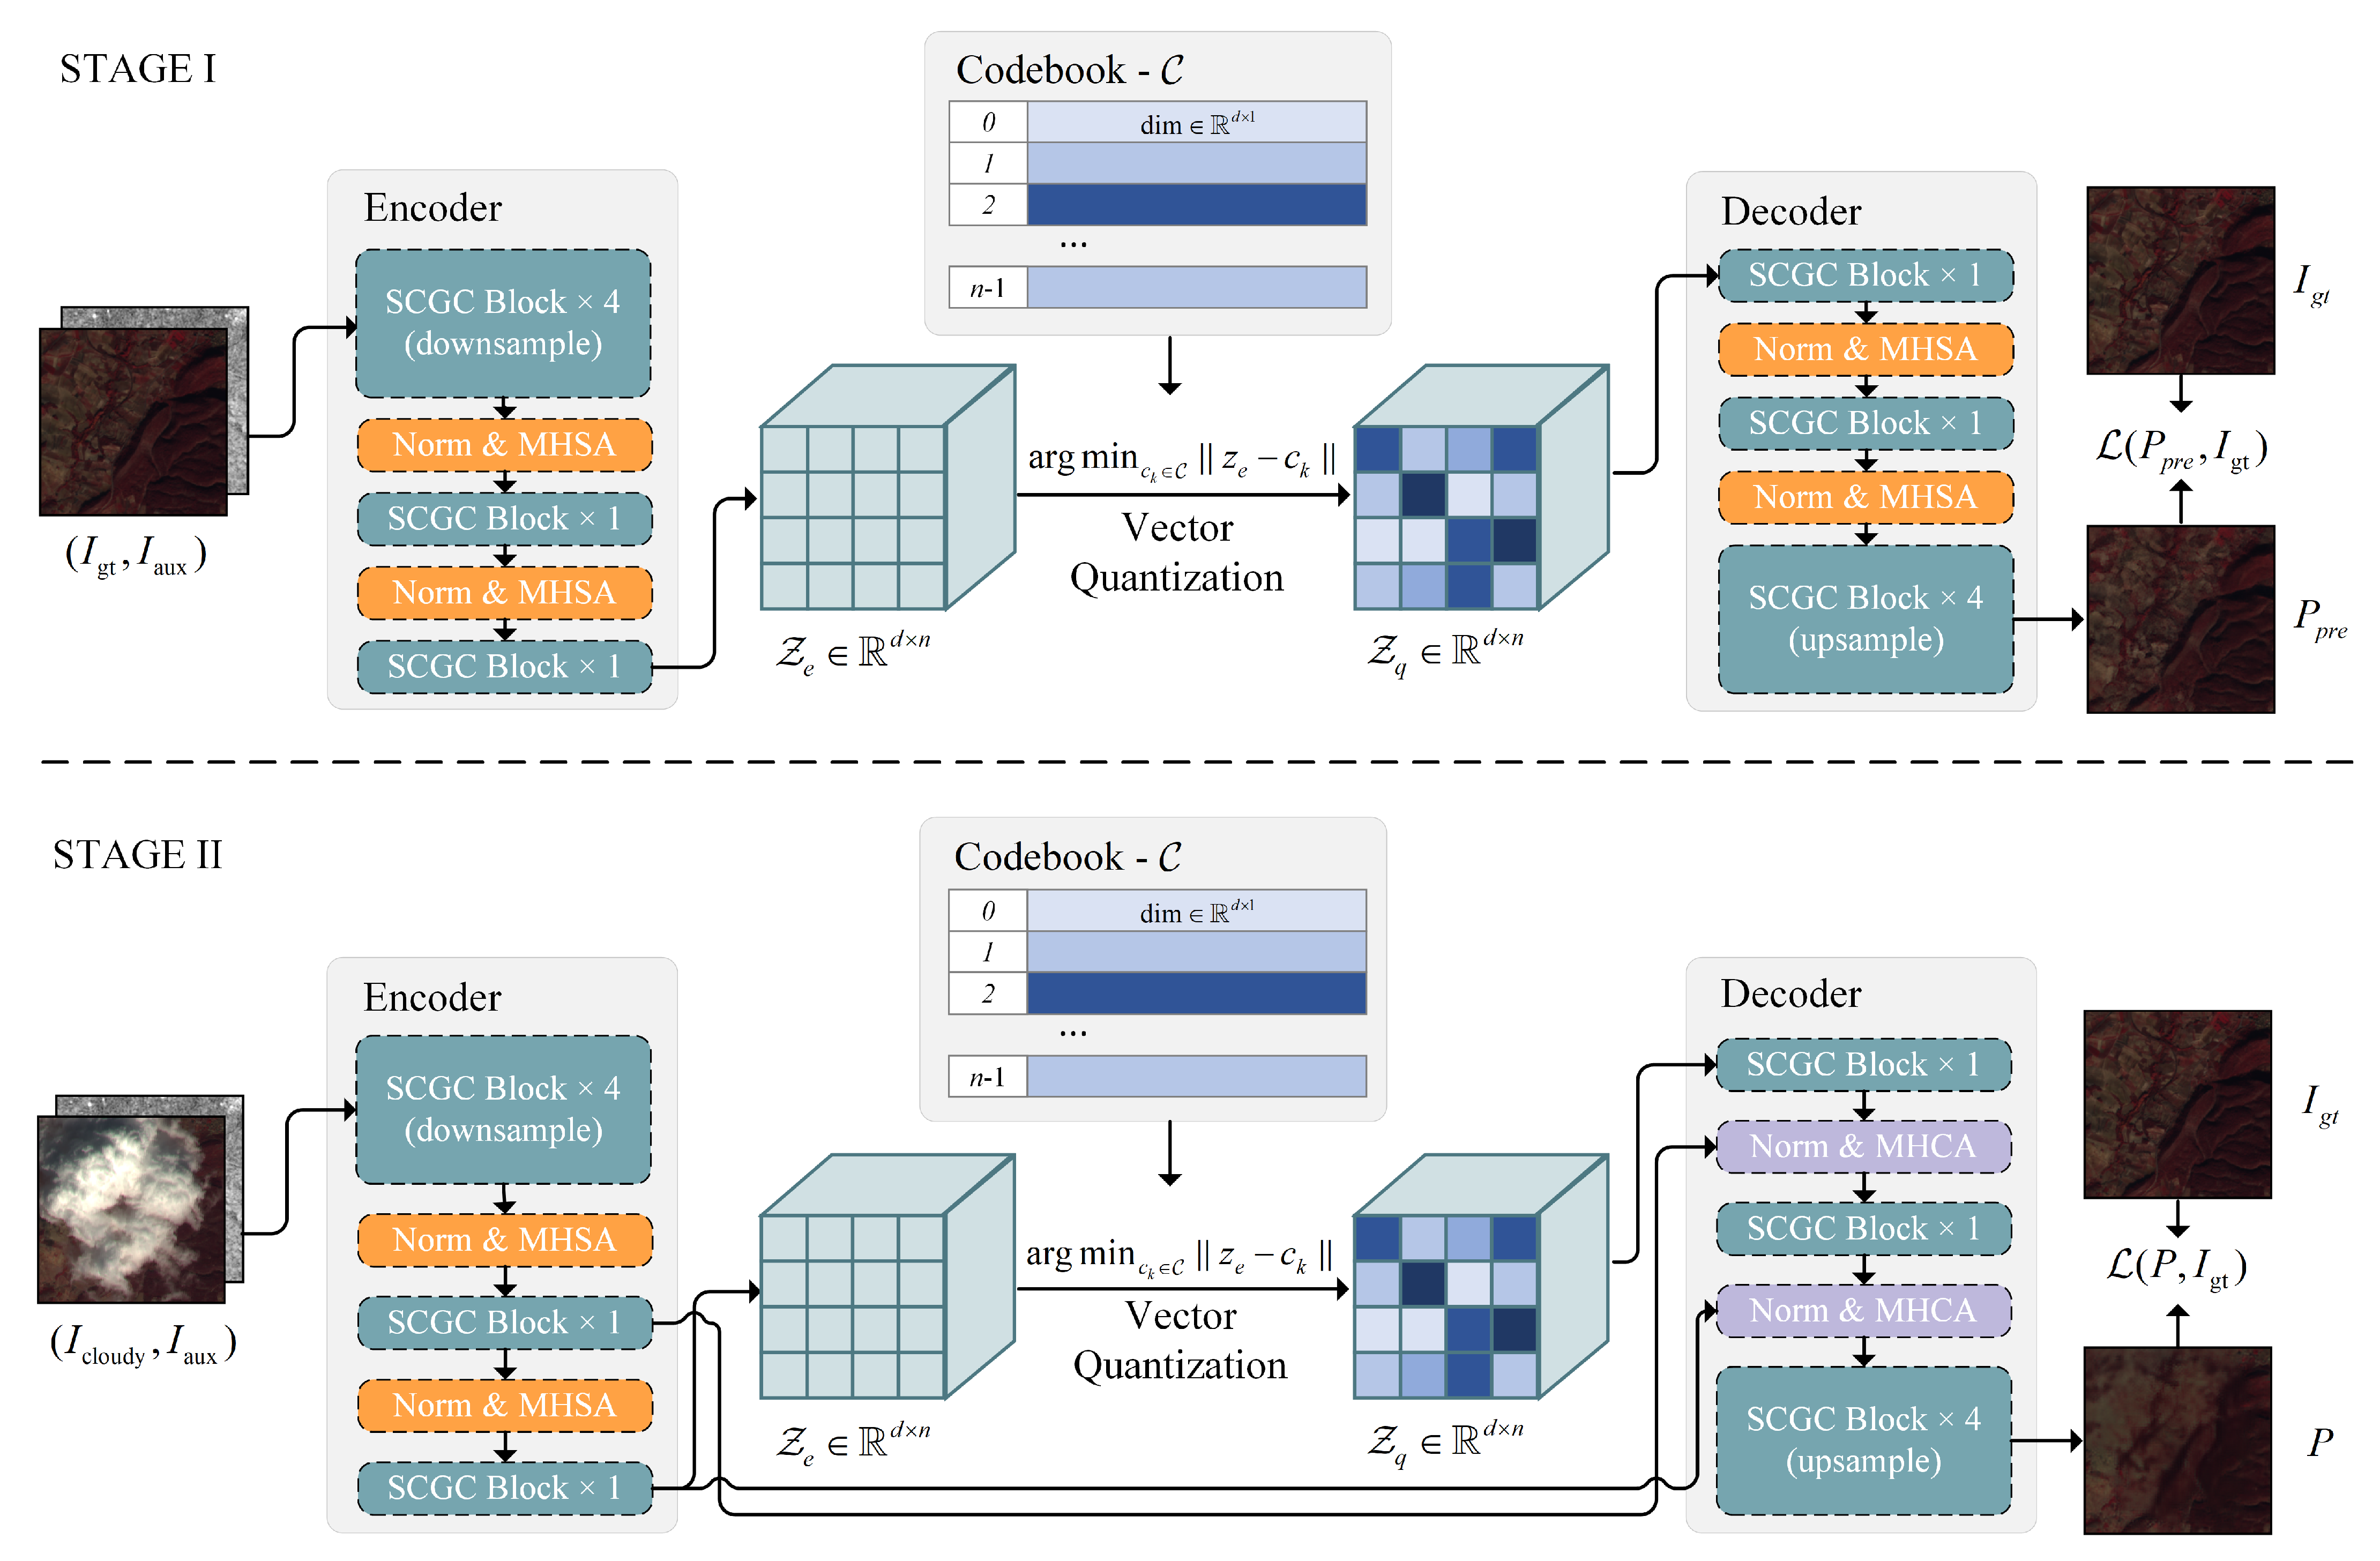
SGC-VQGAN: Towards Complex Scene Representation via Semantic Guided ...
GitHub - CUC-MIPG/VQGAN-Compression: Extreme Image Compression using ...
VQGAN(2021-06:Taming Transformers for High-Resolution Image Synthesis ...
Figure 1 from SGC-VQGAN: Towards Complex Scene Representation via ...
【论文简介】2204.VQGAN-CLIP(已开源):Open Domain Image Generation and Editing ...
[6] [GAN] VQ-GAN - 知乎
VGAN-Based Image Representation Learning for Privacy-Preserving Facial ...
Yueqin Yin (殷月琴) - Academic Homepage
VQ-VAE - Drenched in my pain.
GitHub - ambient-intelligence/diffusion-VQGAN-CLIP · GitHub
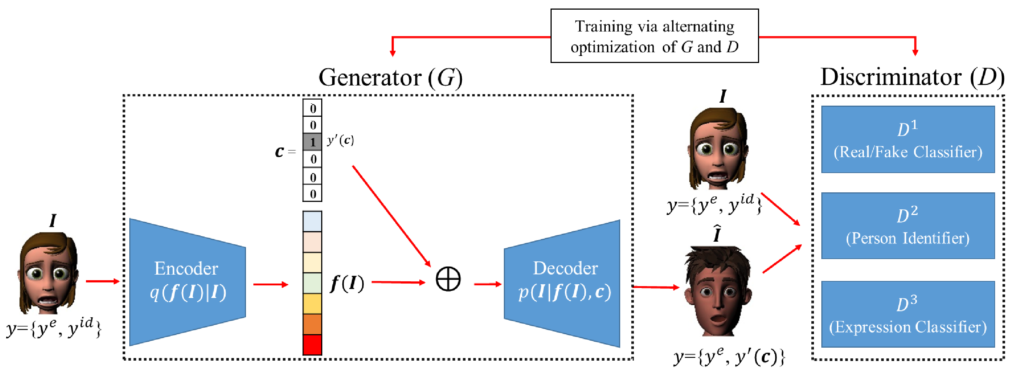
The Architecture of The VAECGAN model | Download Scientific Diagram
TCF-VQGAN: Two-Stage Codebook Fusion Vector-Quantized GAN for ...
Paper page - OCR-VQGAN: Taming Text-within-Image Generation
VQGAN,CLIP,文生图(text to image) - 知乎
文生图:AE/VAE/VQVAE/VQGAN/DALLE模型_vqvae2生成-CSDN博客
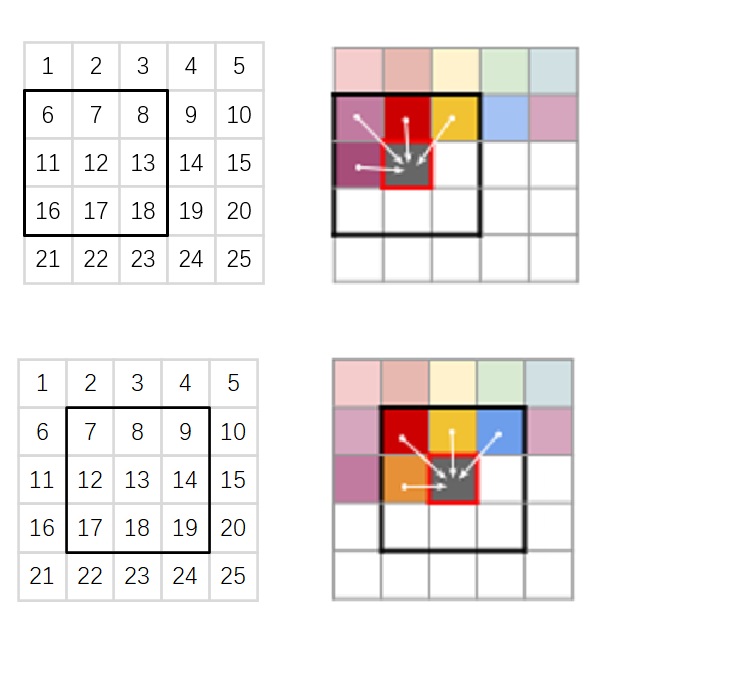
关于VQ-GAN利用滑动窗口生成 高清图像_vqgan滑动窗口-CSDN博客
GitHub - JupyterJones/vqgan-generator: Implements VQGAN+CLIP for image ...
Throwback to 2021, when the best thing we had was VQGAN+CLIP – At that ...
The network architecture of Vector Quantized Generative Adversarial ...