Showing 116 of 116on this page. Filters & sort apply to loaded results; URL updates for sharing.116 of 116 on this page
DocVQA 文档开放式问答数据集 | 数据集 | HyperAI超神经
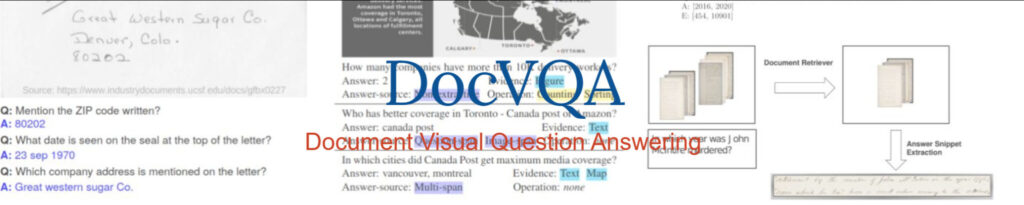
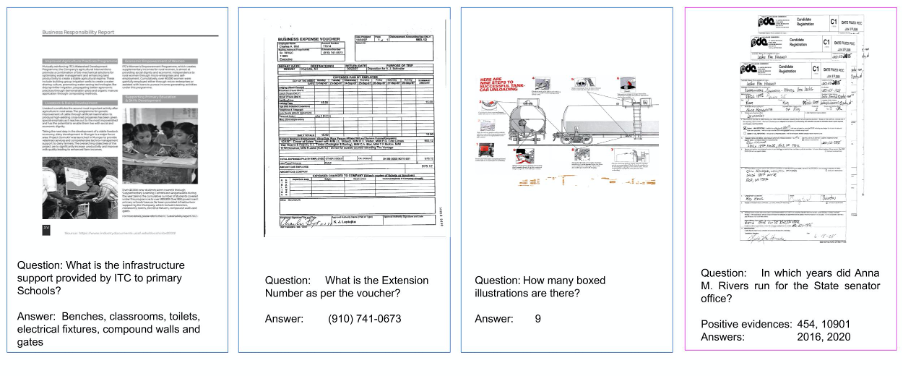
DocVQA — Loupy
DocVQA Demo - a Hugging Face Space by Vaishali12
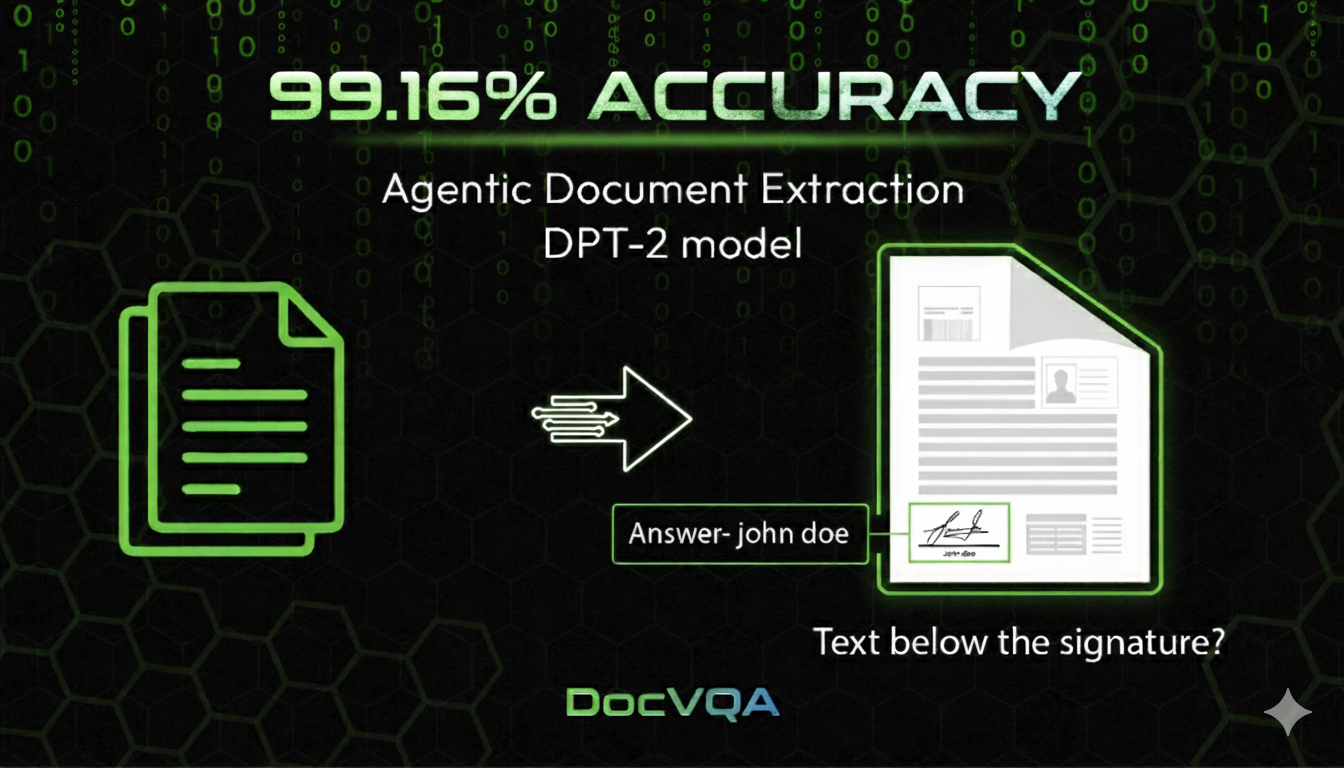
Landing AI 刷新 DocVQA 记录,成为新的文档理解 SOTA DocVQA 原记录是 Qwen2-VL 97.25%,人类基准是 ...
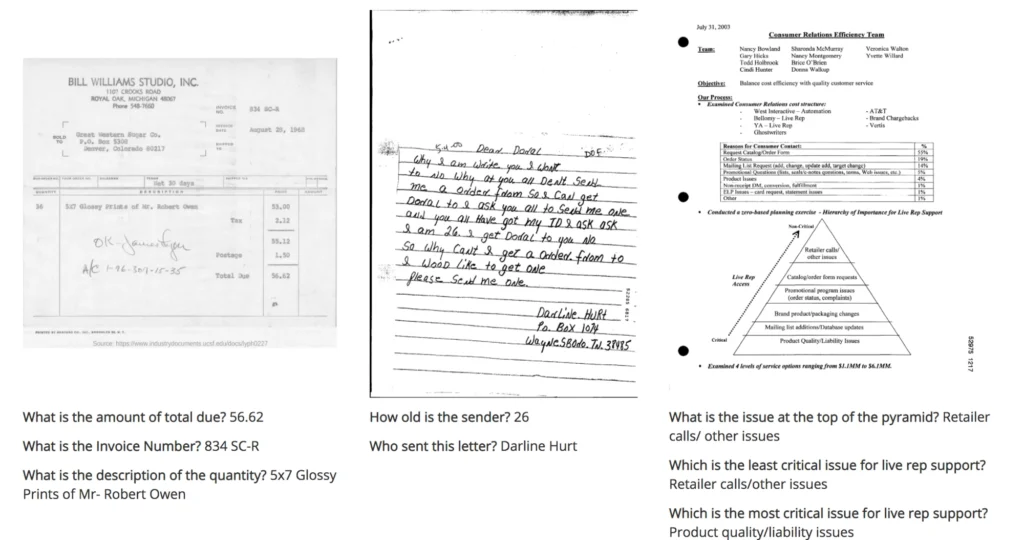
DocVQA | ICDAR 2021
DocVQA - Datasets
DocVQA (Document Visual Question Answering) - Deploy - YouTube
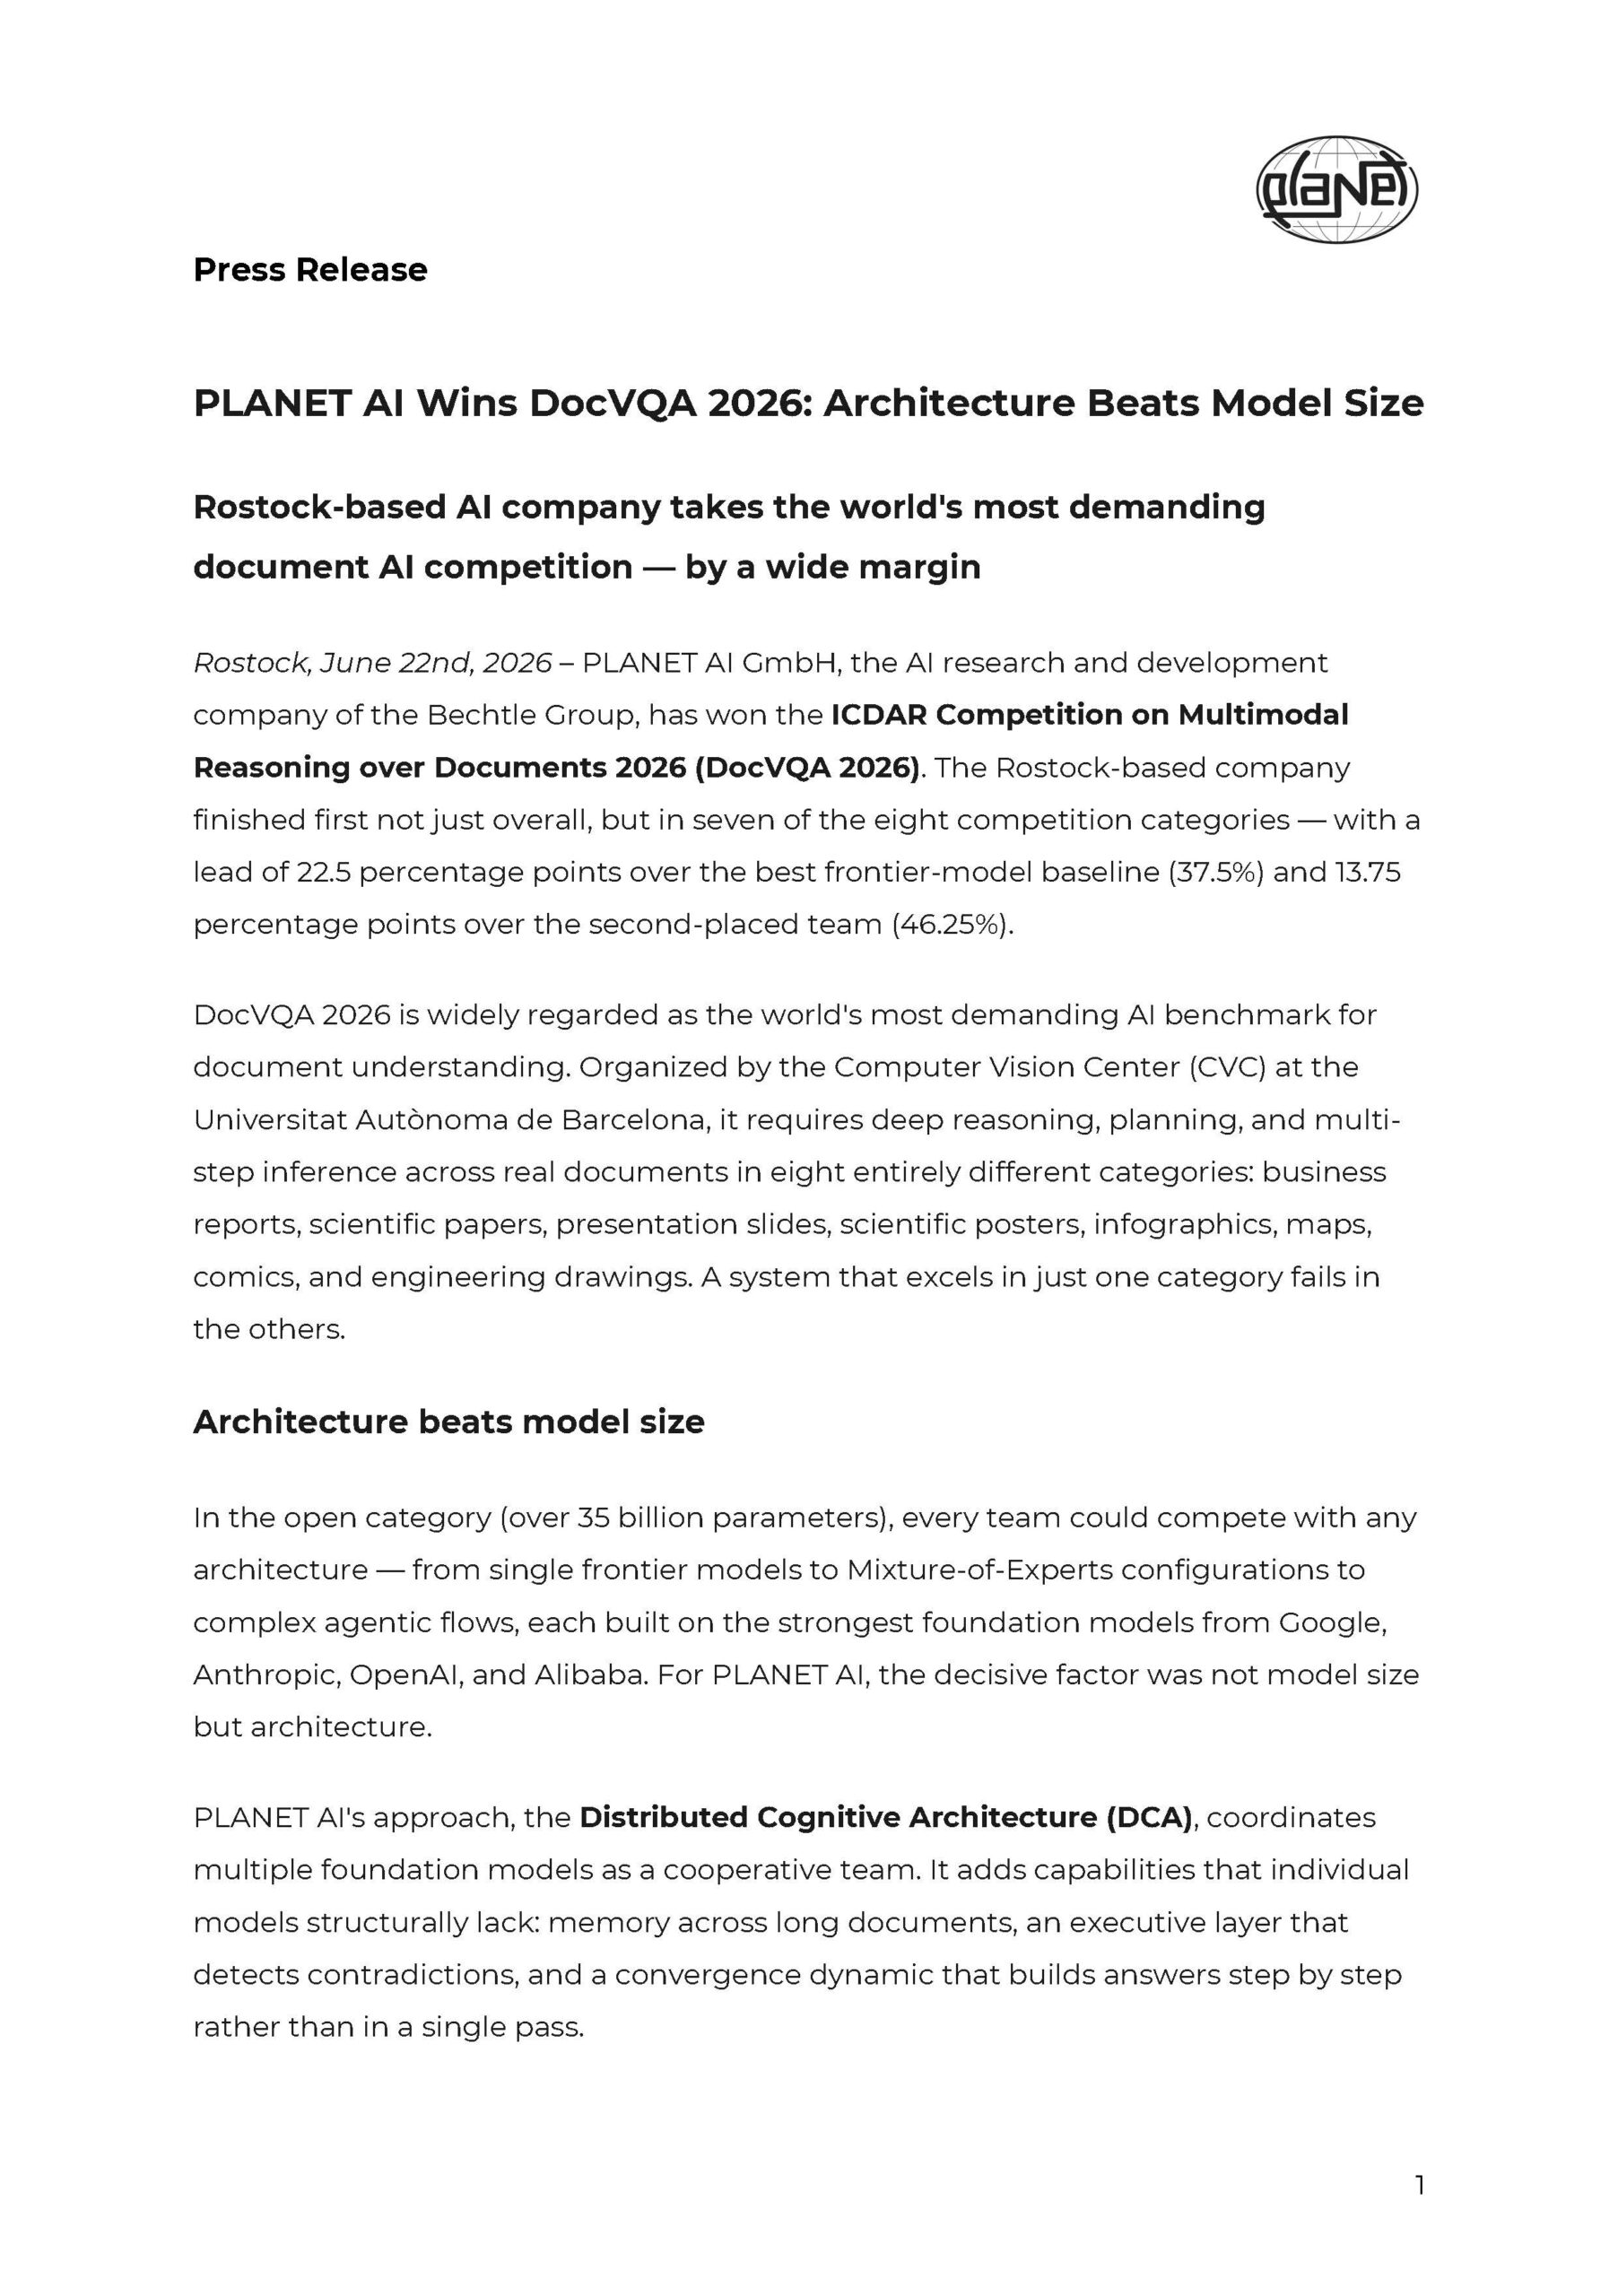
DocVQA | PLANET AI
Revolutionizing Document Processing Through DocVQA
LayoutLM DocVQA x PaddleOCR - a Hugging Face Space by christmaple
DIVE-Doc DocVQA - a Hugging Face Space by JayRay5
OCR and DocVQA | kijai/ComfyUI-Florence2 | DeepWiki
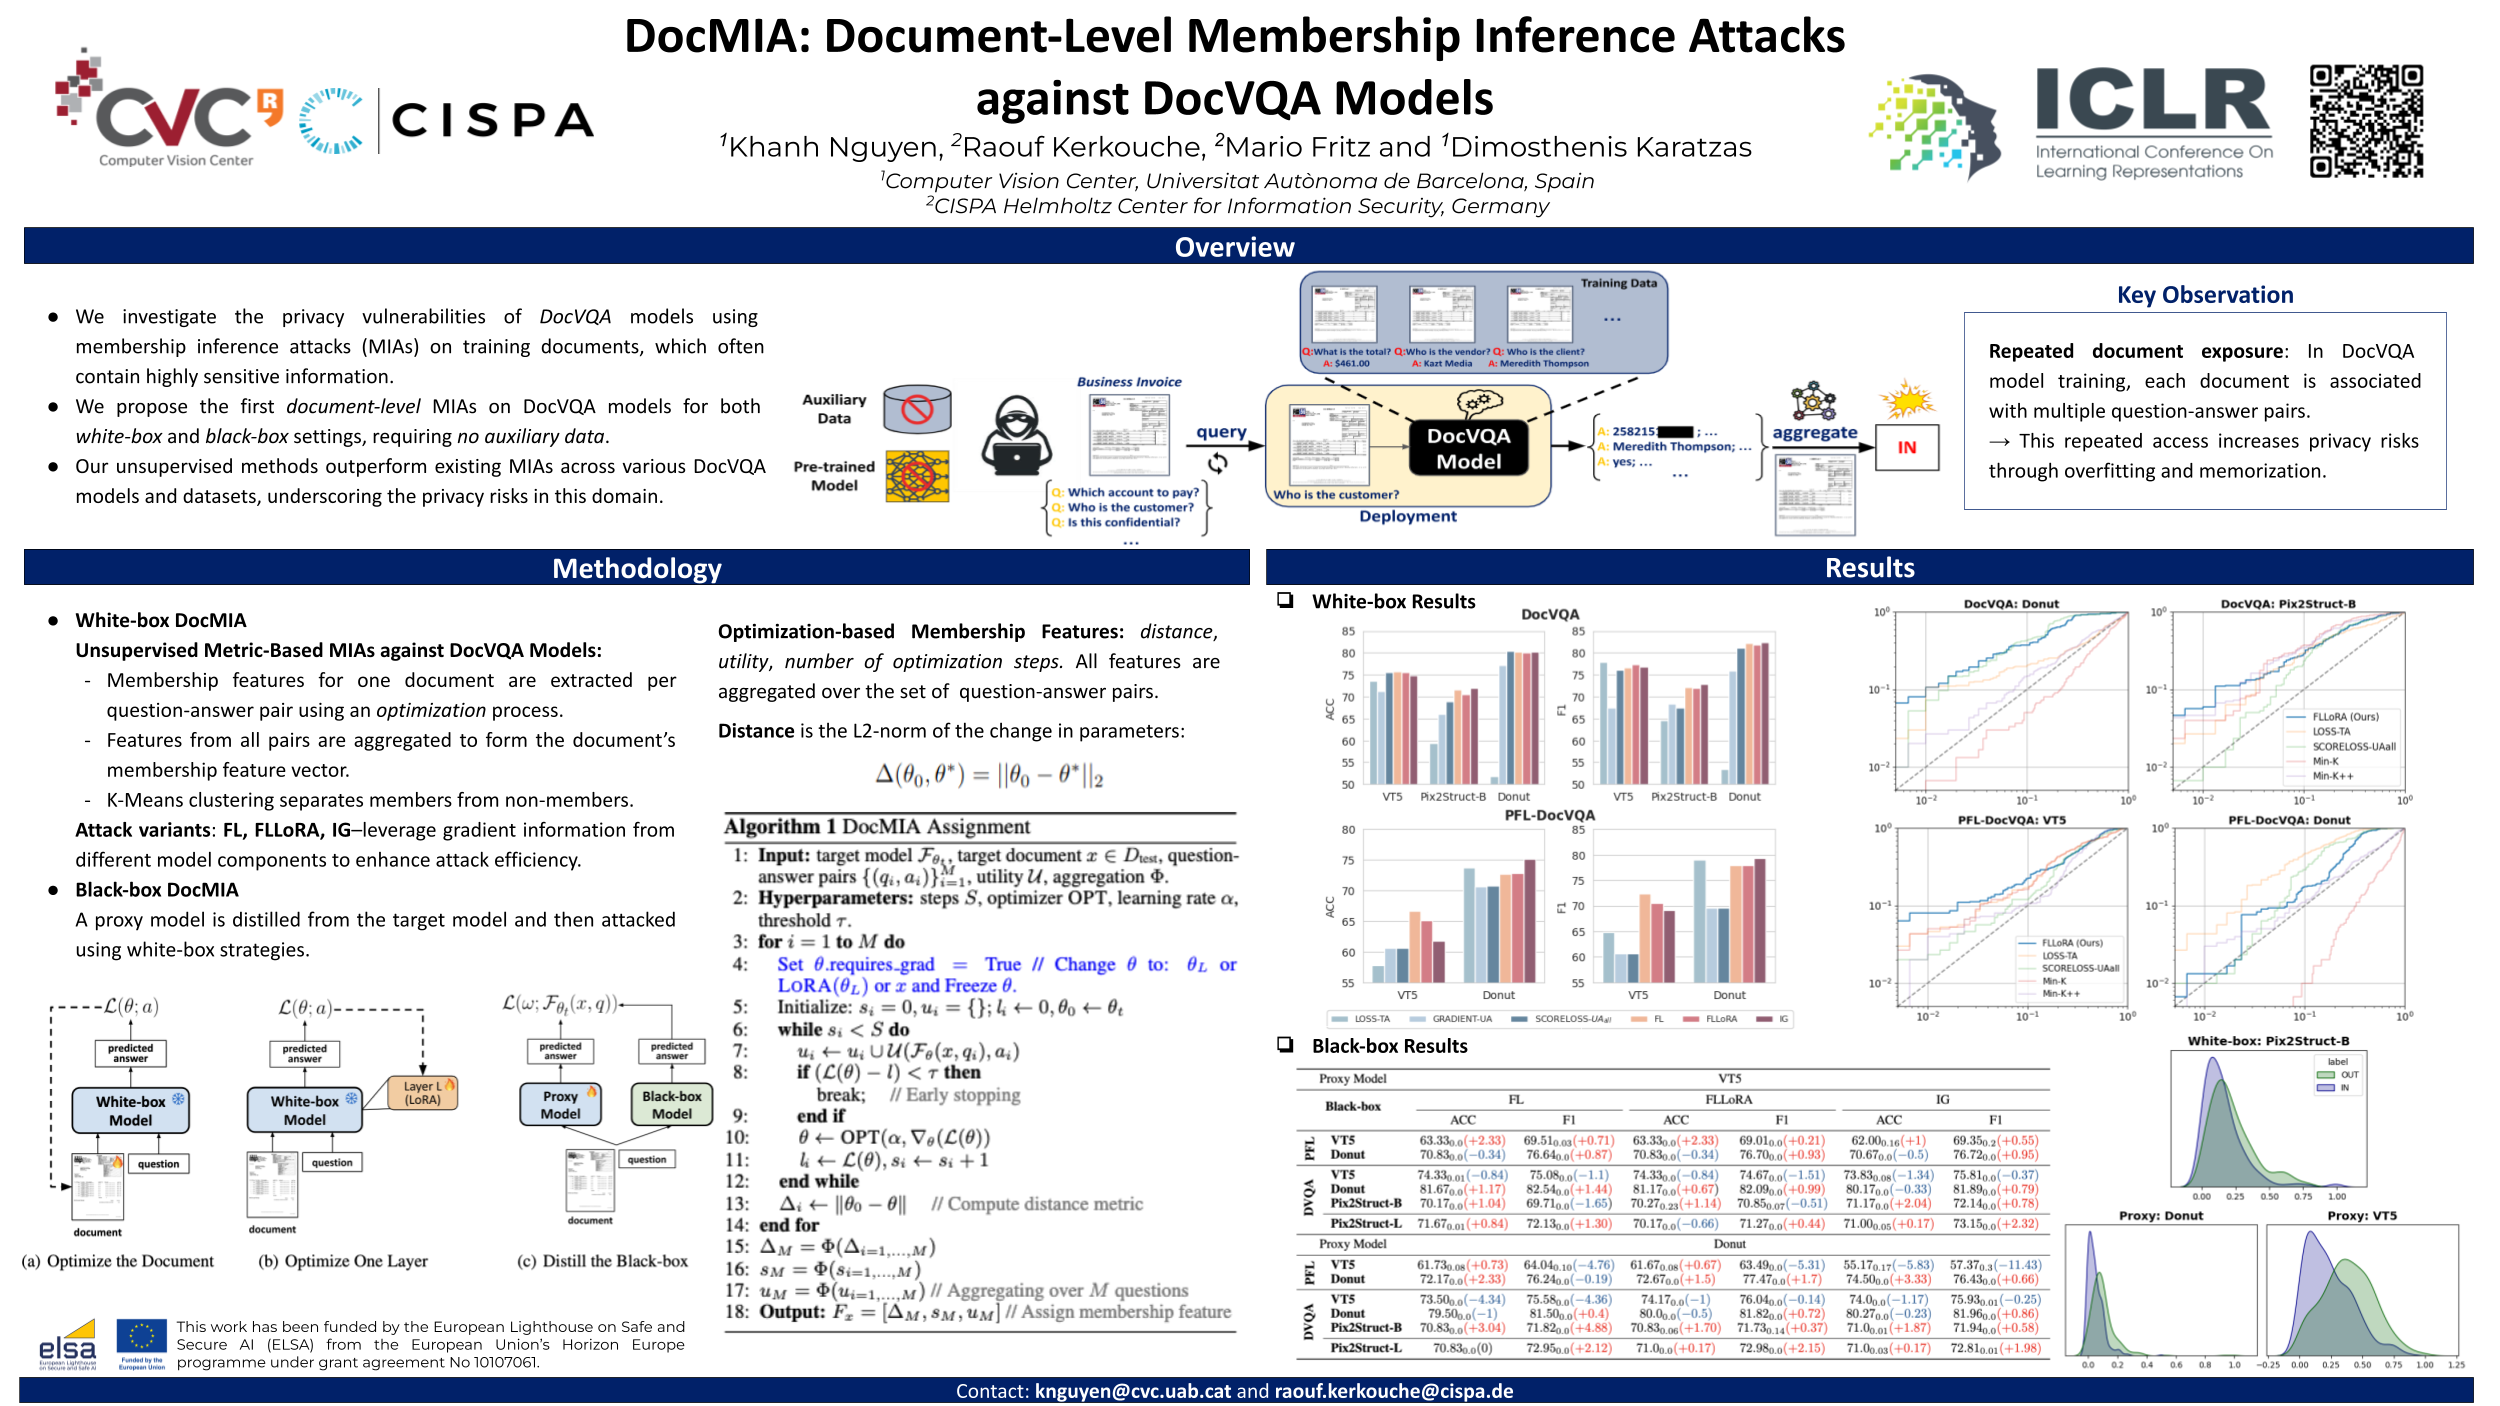
Document-Level Membership Inference Attacks Against Docvqa Models | PDF ...
Florence 2 DocVQA by HuggingFaceM4 — VRAM 3.3GB | LLM Explorer
The rankings of the top 10 models on the DocVQA leaderboard, before and ...
DocVQA Benchmark: 99.16% Accuracy Using Agentic Document Extraction ...
#docvqa #docvqa2026 #docvqa #multimodalai #documentunderstanding # ...
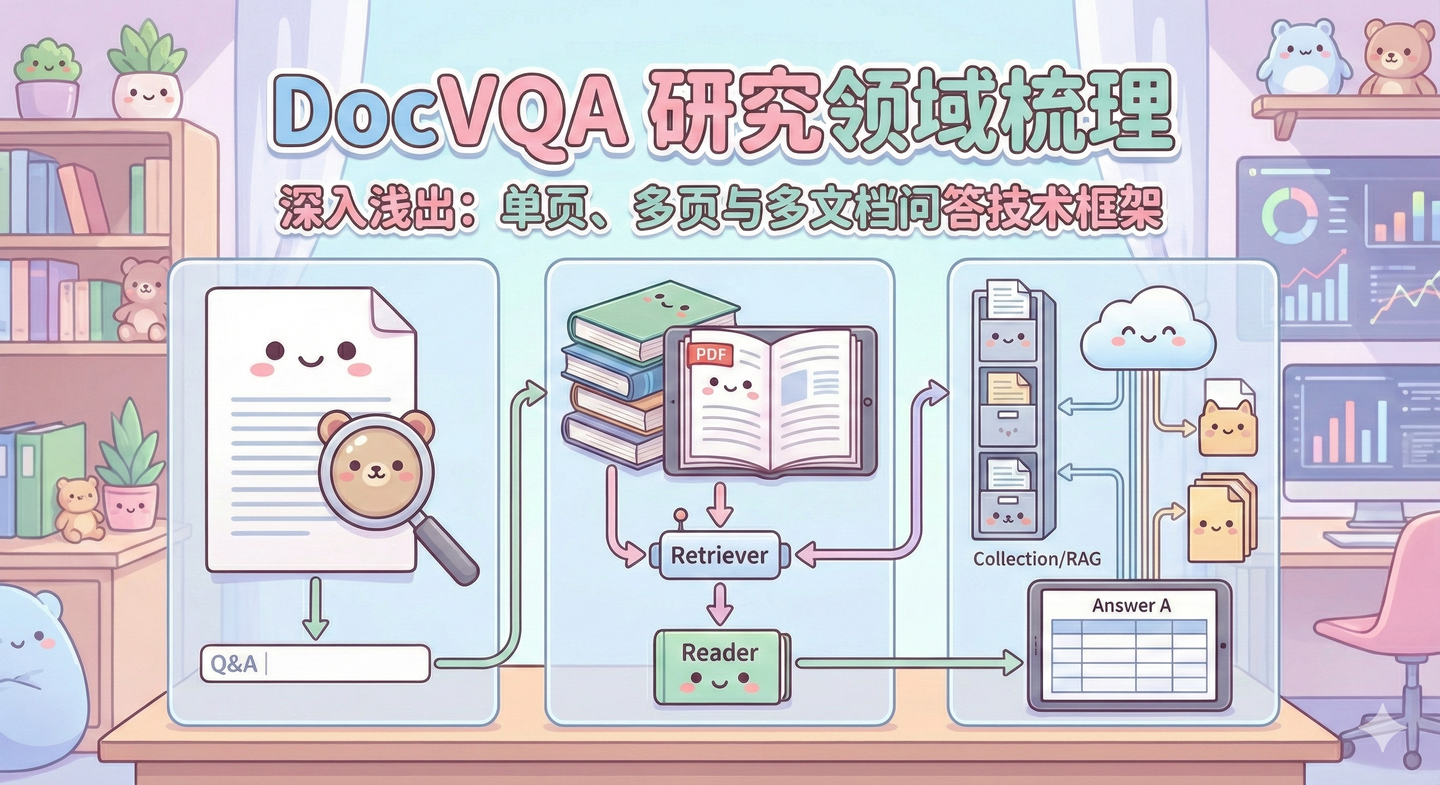
文档视觉问答(DocVQA)全景解析:从单页感知到海量多模态检索推理的研究报告 - 知乎
DocVQA|文档理解数据集|视觉问答数据集
DocVQA-2026
[Electronic Devices Datasheet Information Extraction using Visual ...
Taner Akdeniz on LinkedIn: Document Visual Question Answering (DocVQA ...
DocVQA|文档处理数据集|问答系统数据集
[논문 리뷰] AdaDocVQA: Adaptive Framework for Long Document Visual Question ...
开启智能时代:深度解析智能文档分析技术的前沿与应用-腾讯云开发者社区-腾讯云
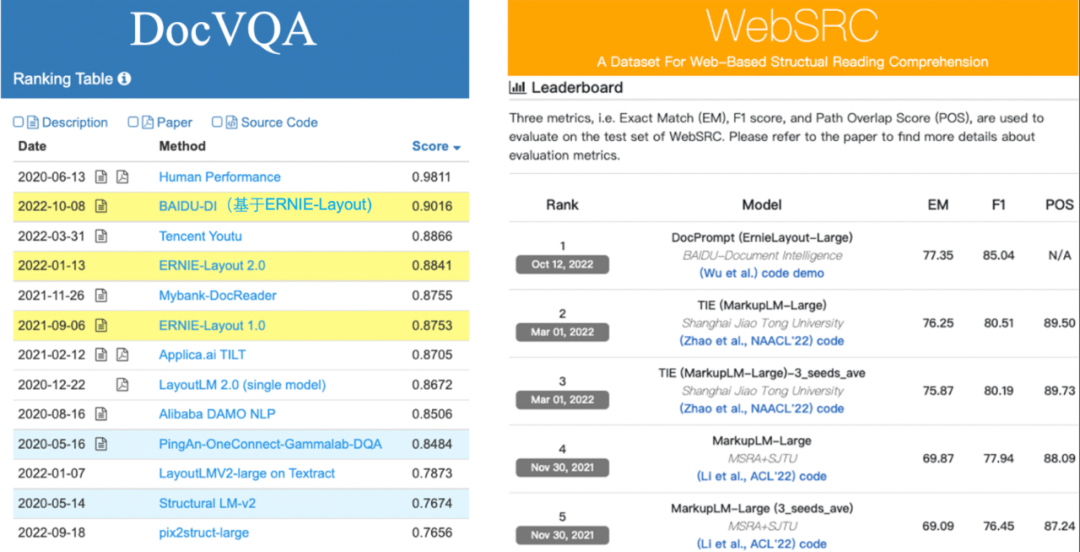
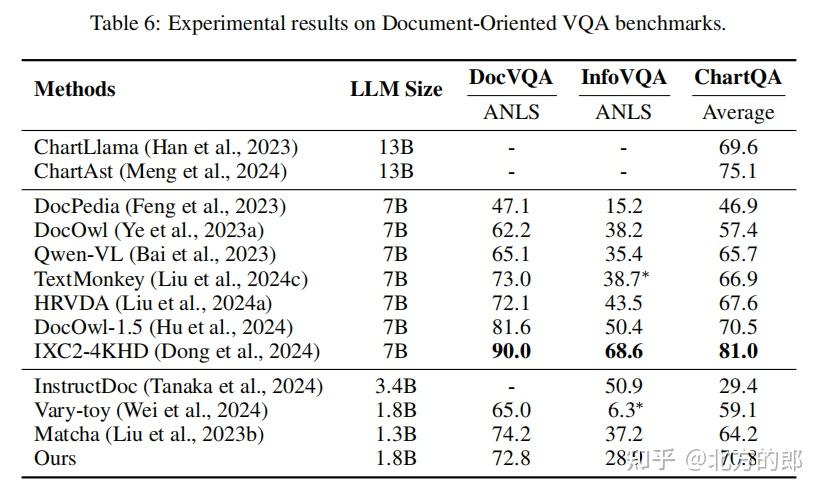
文档智能SOTA被刷爆,DocVQA榜单首次突破90大关-CSDN博客
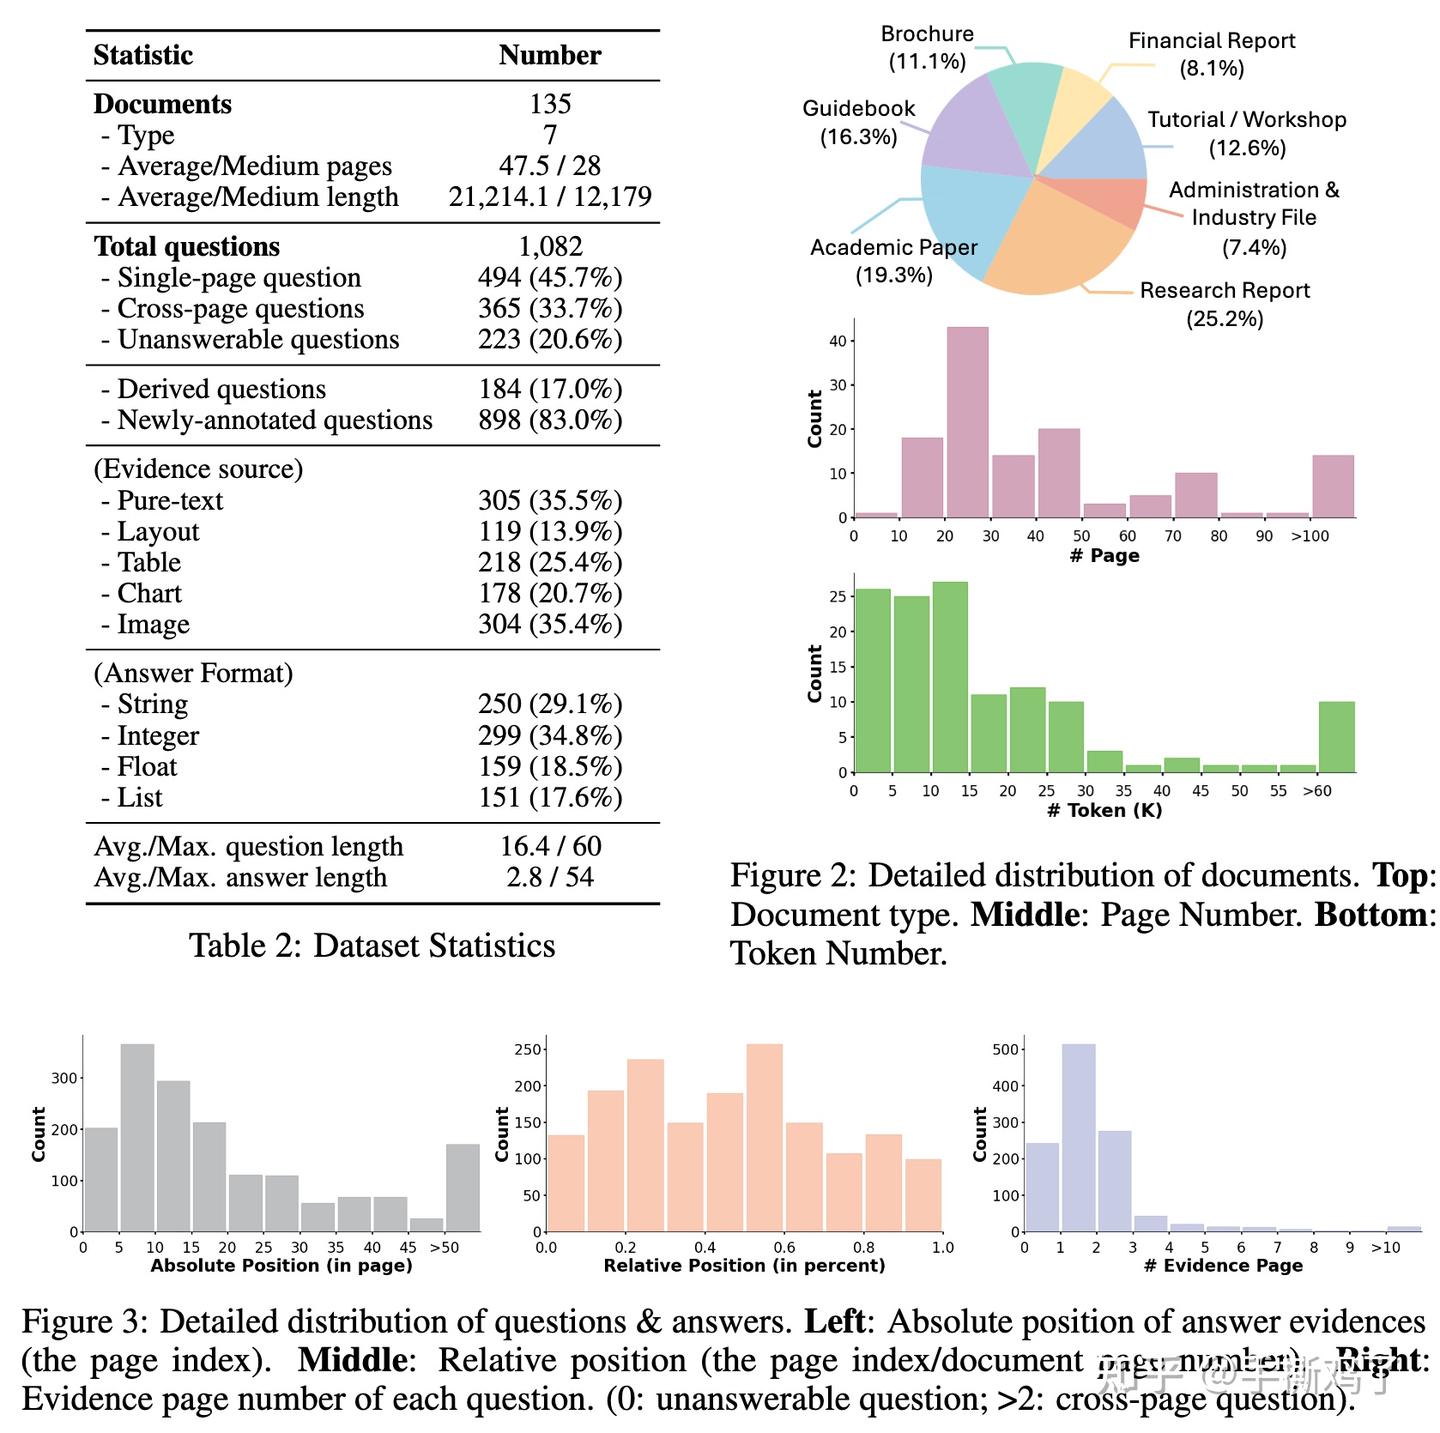
[논문 리뷰] BBox DocVQA: A Large Scale Bounding Box Grounded Dataset for ...
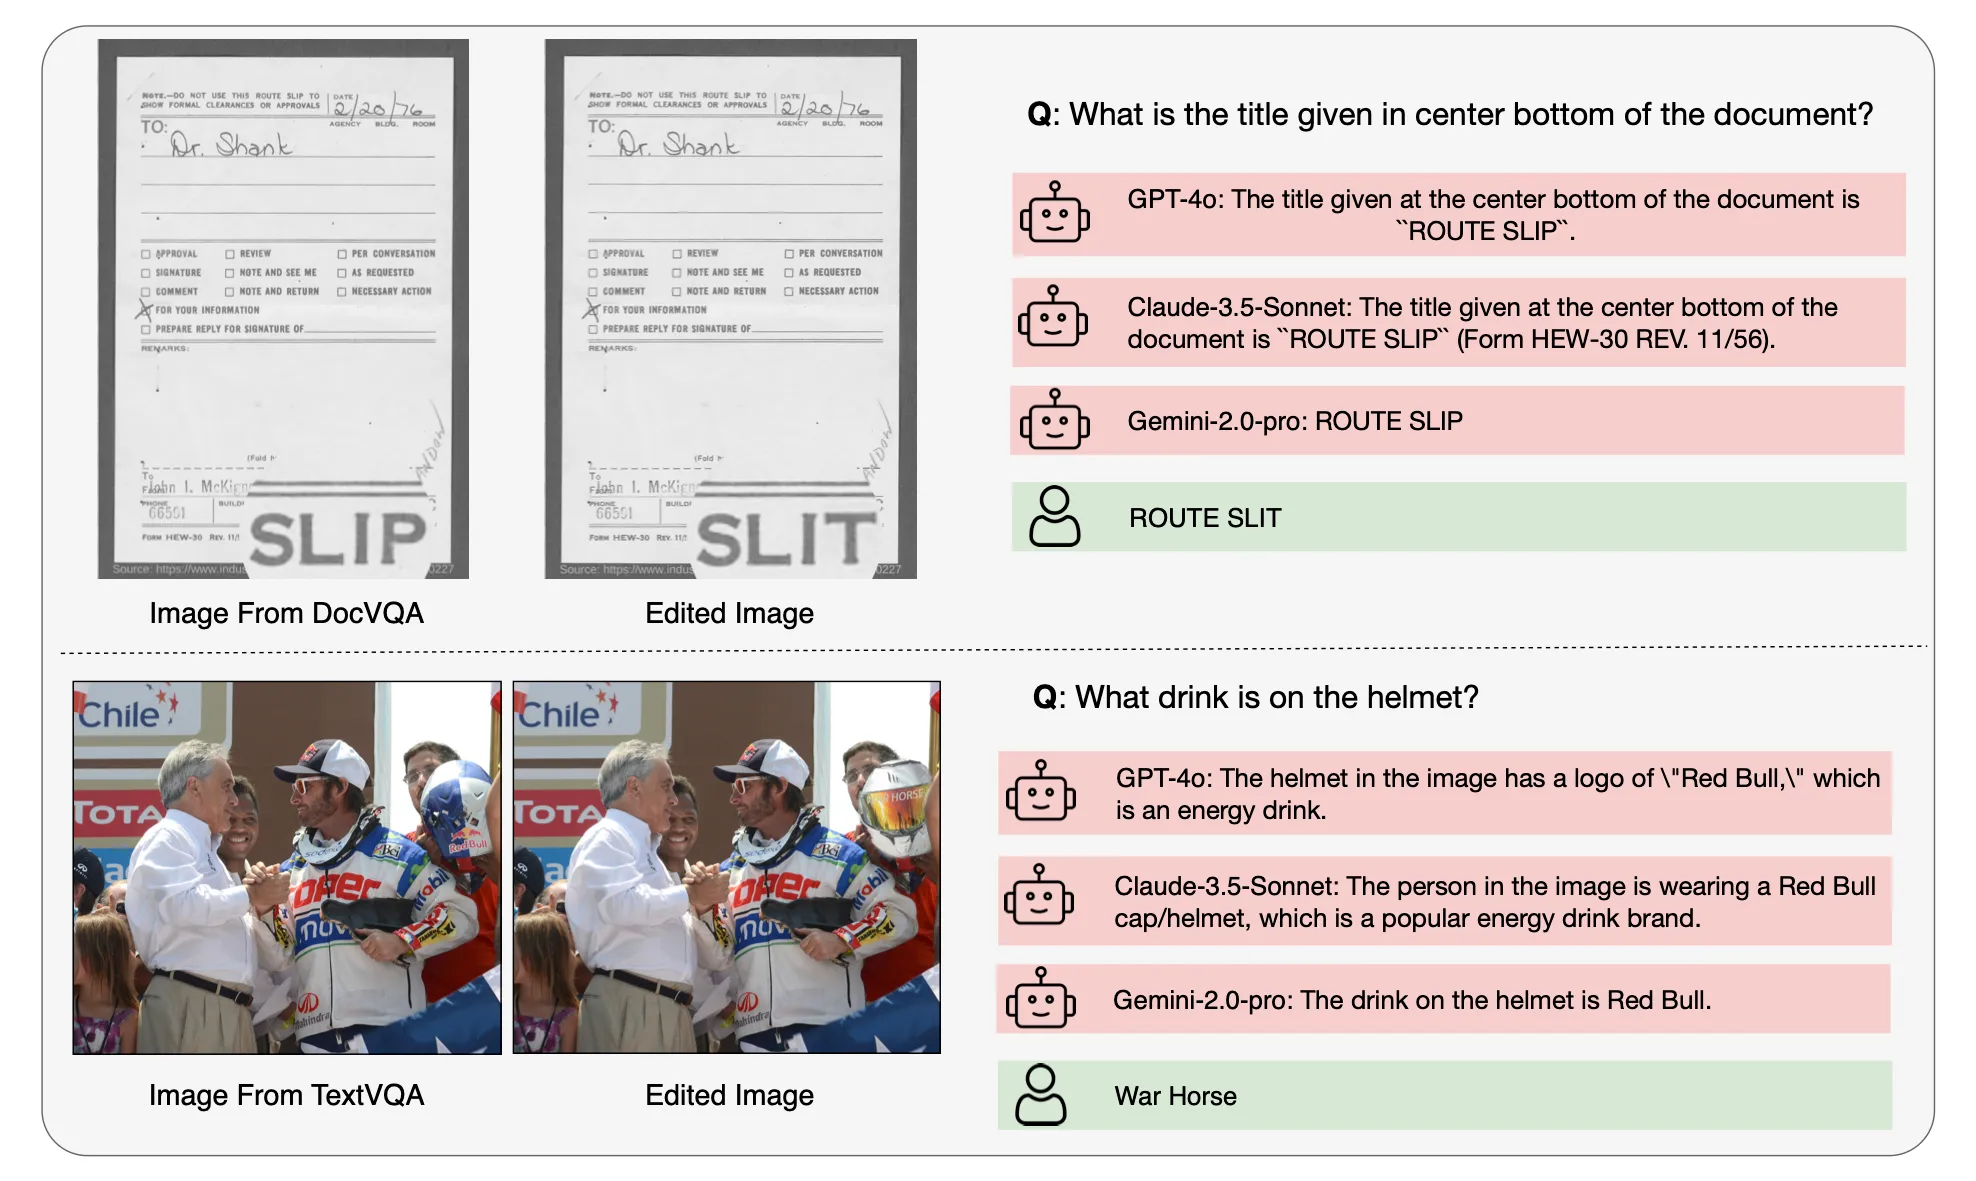
A Status Check on Current Vision-Language Models in Text Recognition ...
LAVE:使用 LLM 在 Docmatix 上进行零样本 VQA 评估 - 我们还需要微调吗? - Hugging Face 文档
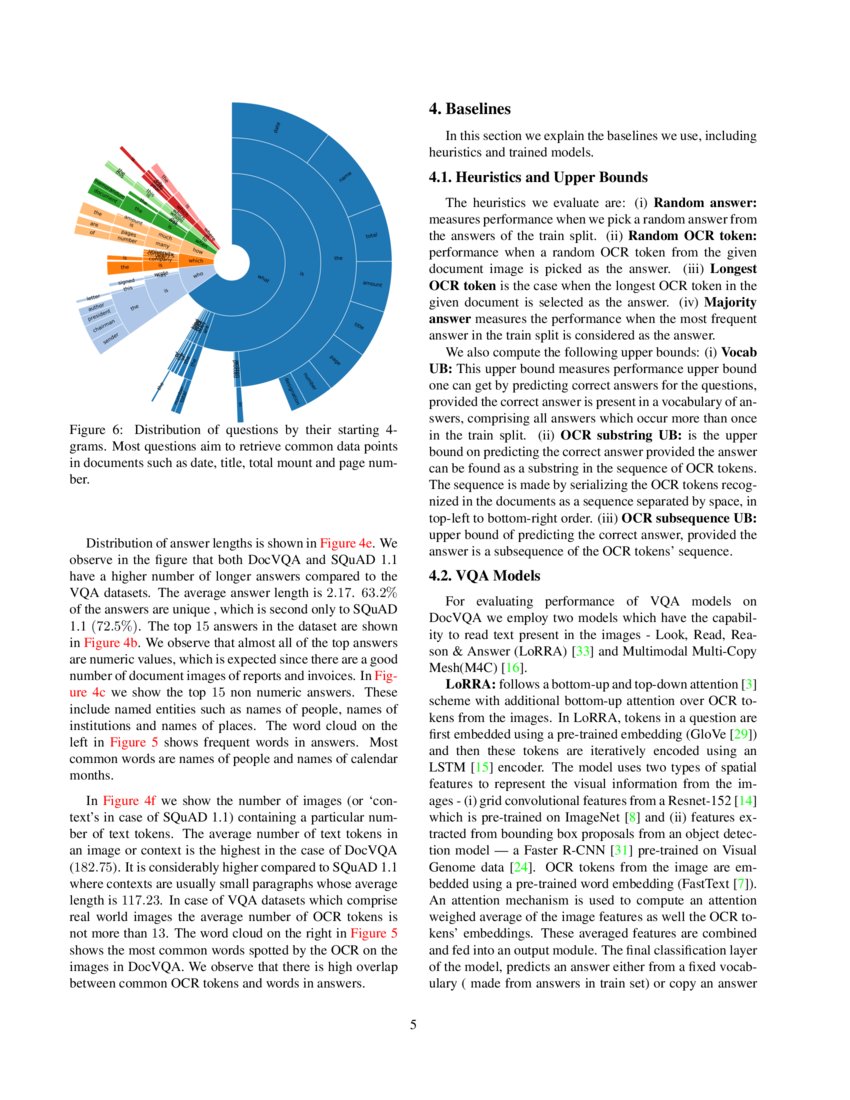
DocVQA: A Dataset for VQA on Document Images | DeepAI
Document Visual Question Answering
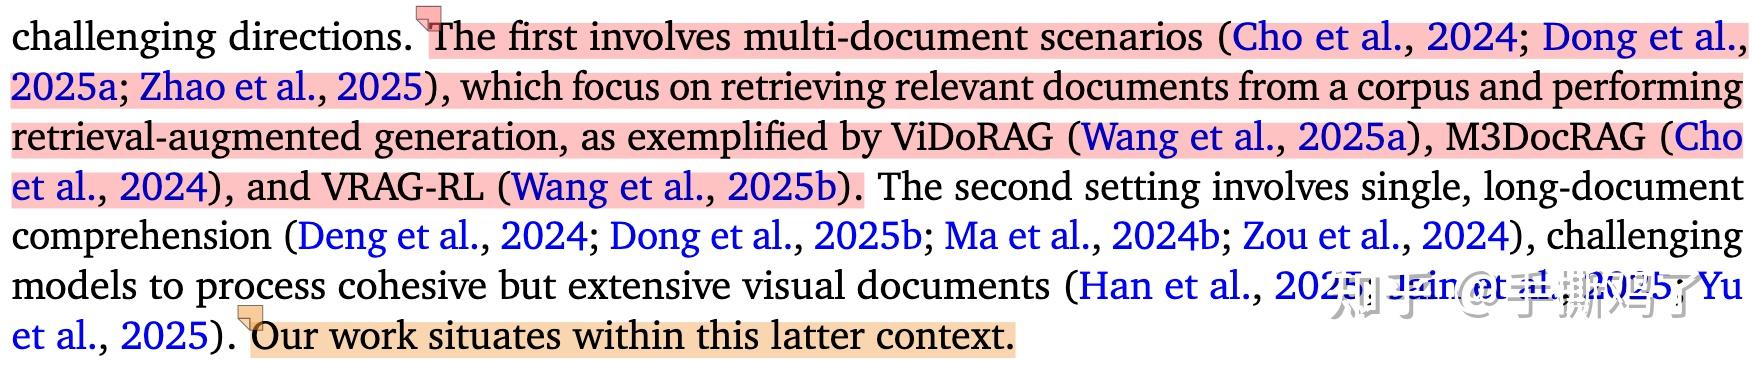
【RAG&多模态】再看多模态RAG进行文档问答的方案 - 知乎
StrucTexTv3:高效的文本密集图像感知与理解模型 - 知乎
rubentito/mp-docvqa|文档分析数据集|视觉问答数据集
LAVE:使用 LLM 对 Docmatix 进行零样本 VQA 评估 - 我们还需要微调吗?
Document VQA论文梳理 - 知乎
Multimodal language modeling
LAVE: 使用 LLM 对 Docmatix 进行零样本 VQA 评估 - 我们还需要微调吗? - HuggingFace - 博客园
Docmatix - 超大文档视觉问答数据集-CSDN博客
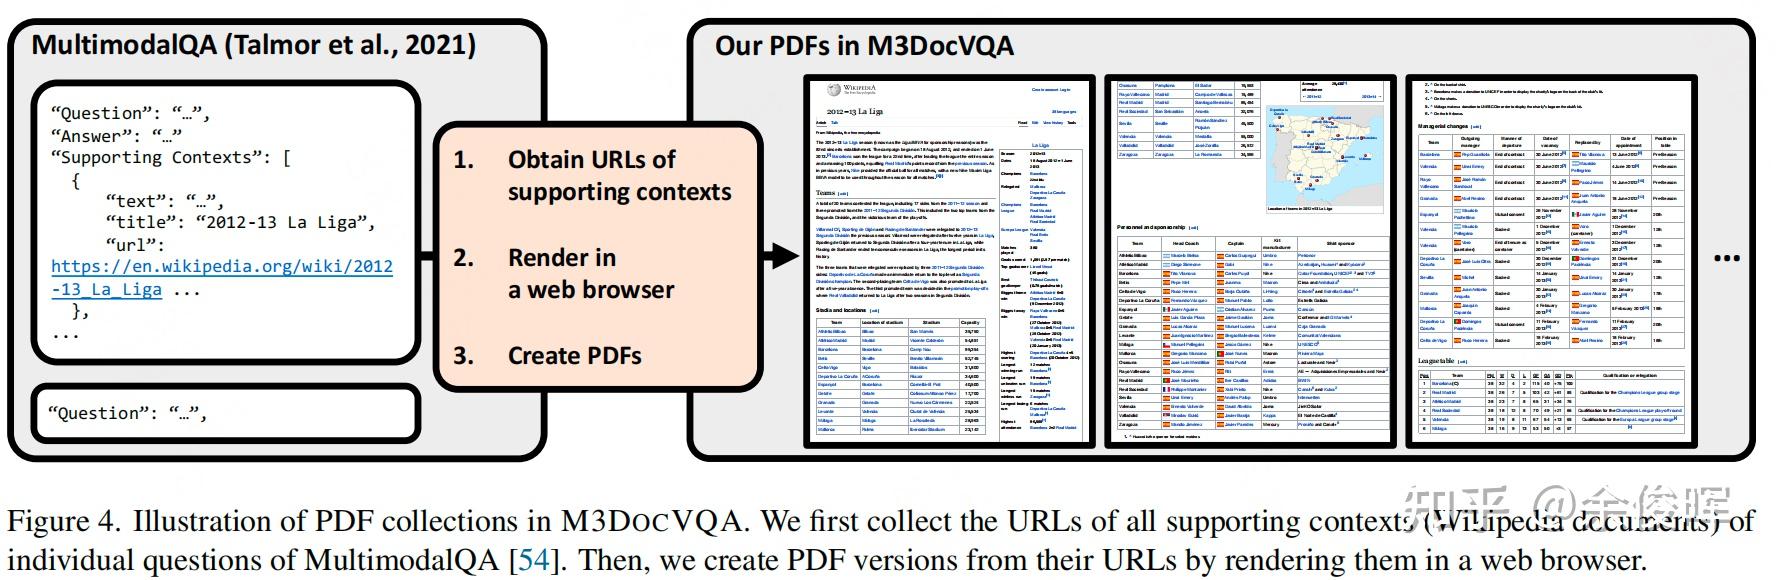
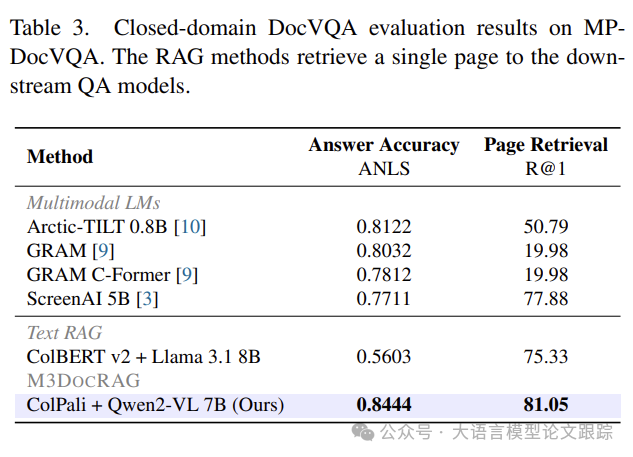
M3DocRAG:文档问答用哪个多模态大模型效果最好?-CSDN博客
docvqa-gen/qa_on_image.py at main · svjack/docvqa-gen · GitHub
DocVQA: Visual QA Dataset for Documents | PDF | Technology & Engineering
lmms-lab-encoder/DocVQA · Datasets at Hugging Face
OCR-DocVQA - a MohdRasheed Collection
ade-docvqa-benchmark/gallery.html at main · landing-ai/ade-docvqa ...
视觉问答(VQA)12篇顶会精选论文合集,附常用数据集下载_ocr-vqa数据集下载-CSDN博客
发布 docvqa-val 数据集, 应用在 文档视觉问答、图像文本识别 领域
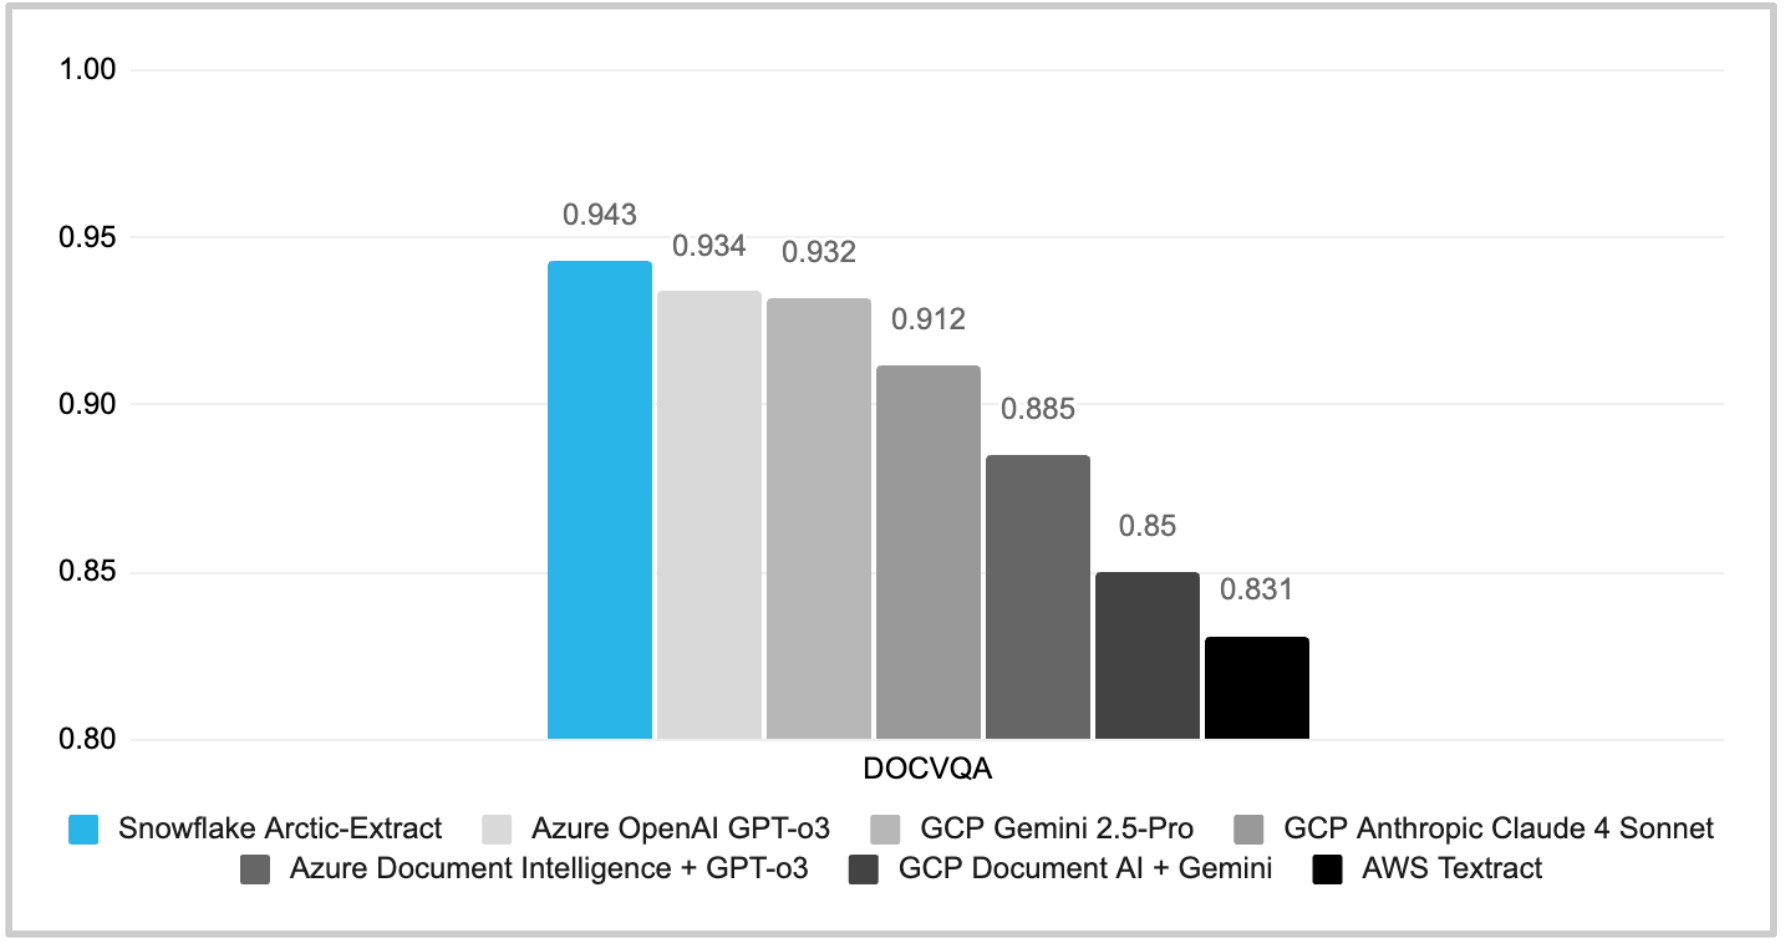
복잡성이 높은 문서에서 실행 가능한 인사이트를 도출하는 Snowflake Document AI
GitHub - boostcampaitech4lv23nlp1/final-project-level3-nlp-03: Multi ...
am-infoweb/LayoutLM_test_docvqa at main
Paper page - DocVQA: A Dataset for VQA on Document Images
GitHub - rubenpt91/MP-DocVQA-Framework
Beschleunigung von Document AI
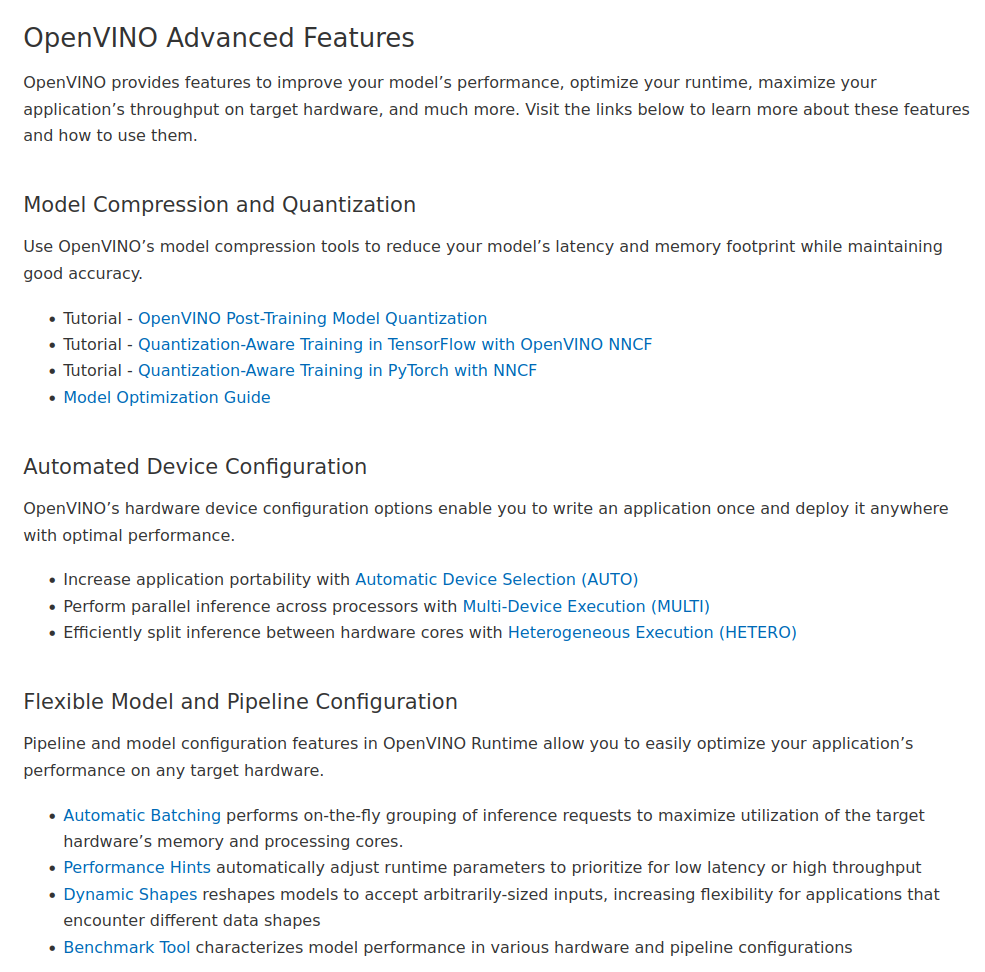
Document Visual Question Answering Using Pix2Struct and OpenVINO ...
Visual Question Answering 简介 + 近年文章-极市开发者社区
Document VQA Datasets - a pixparse Collection
doc-vqa/DocVQA-inference.ipynb at main · thingumajig/doc-vqa · GitHub
#machinelearning #documentunderstanding #docvqa #ai #m3docrag # ...
LayoutLMv3-DocVQA/preprocessing.md at master · allanj/LayoutLMv3-DocVQA ...
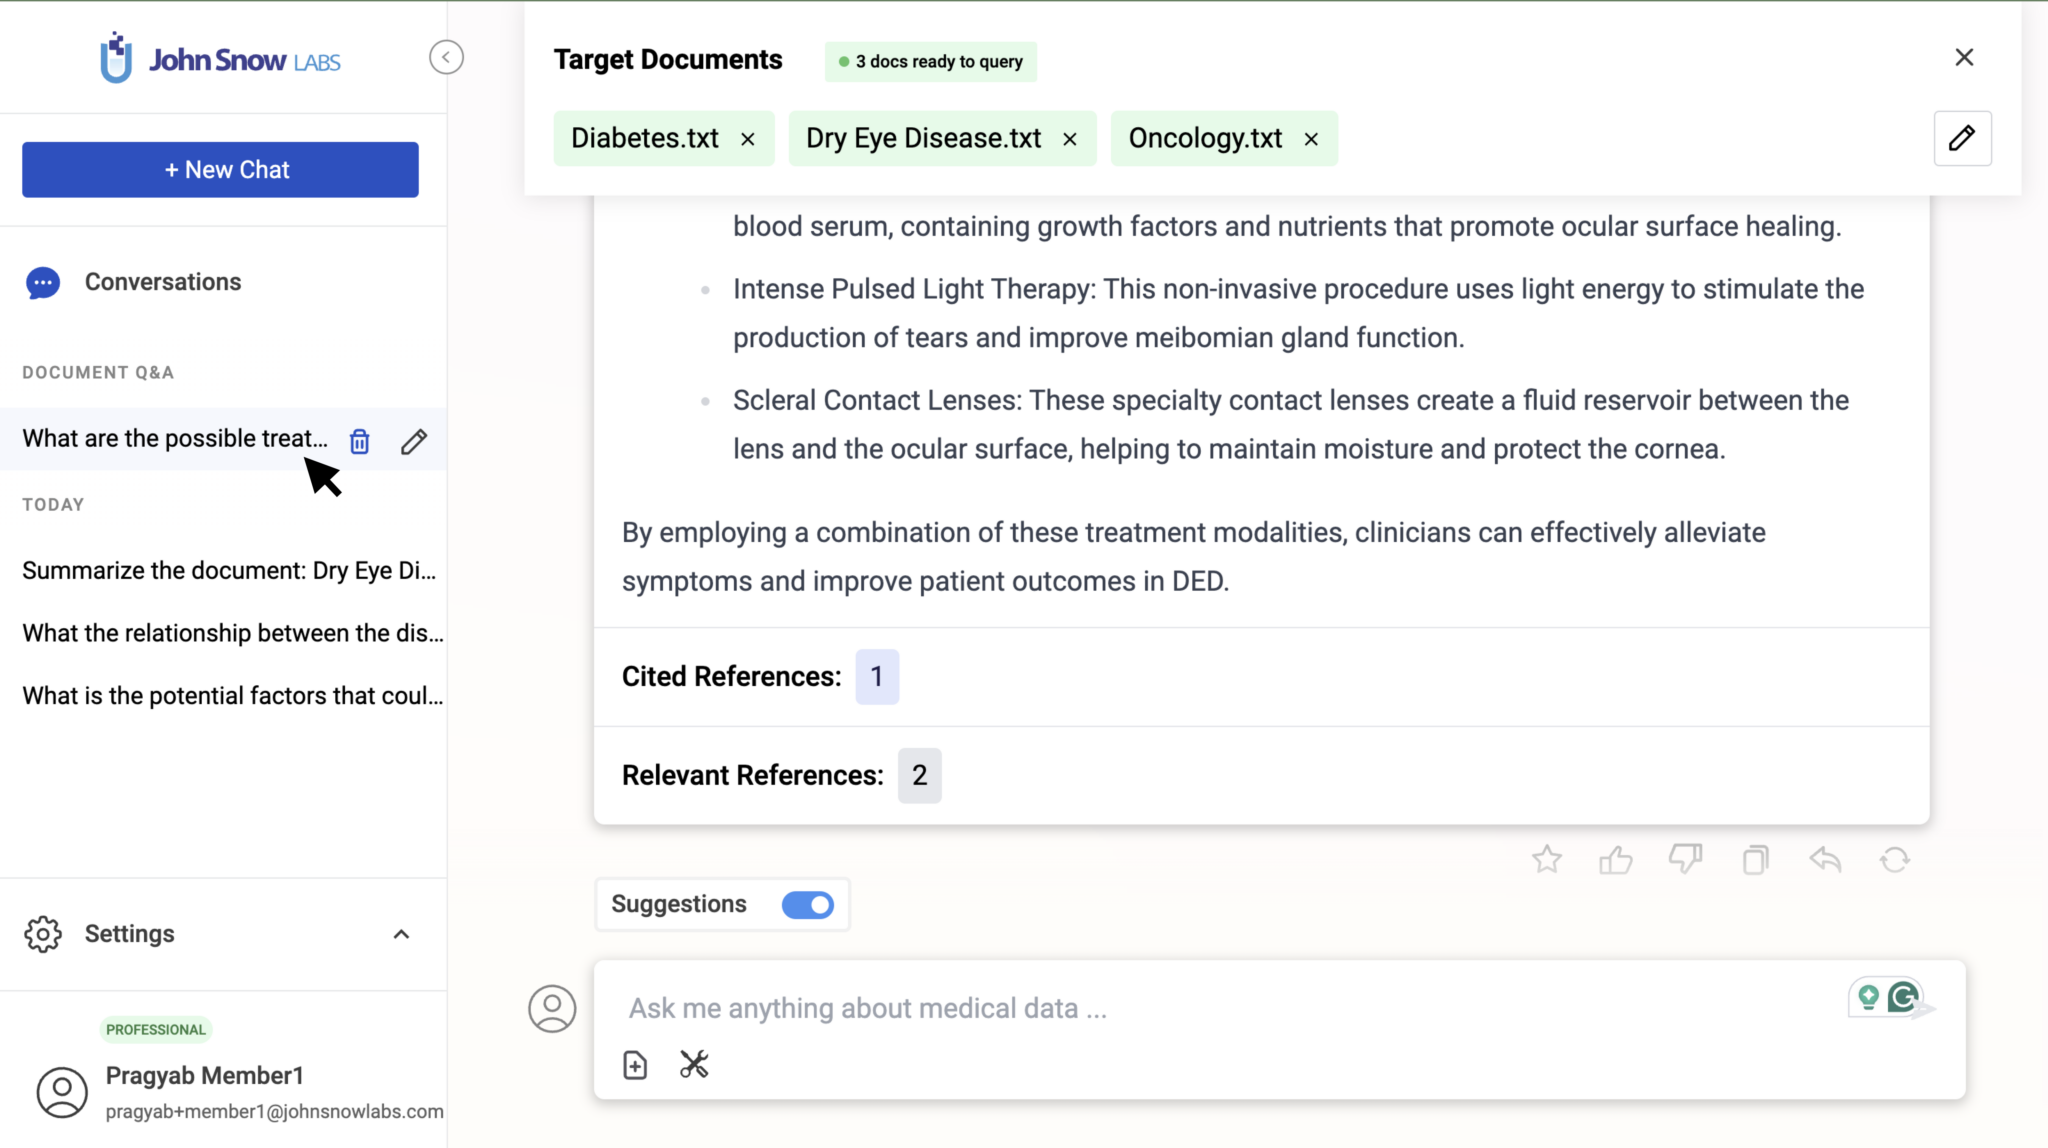
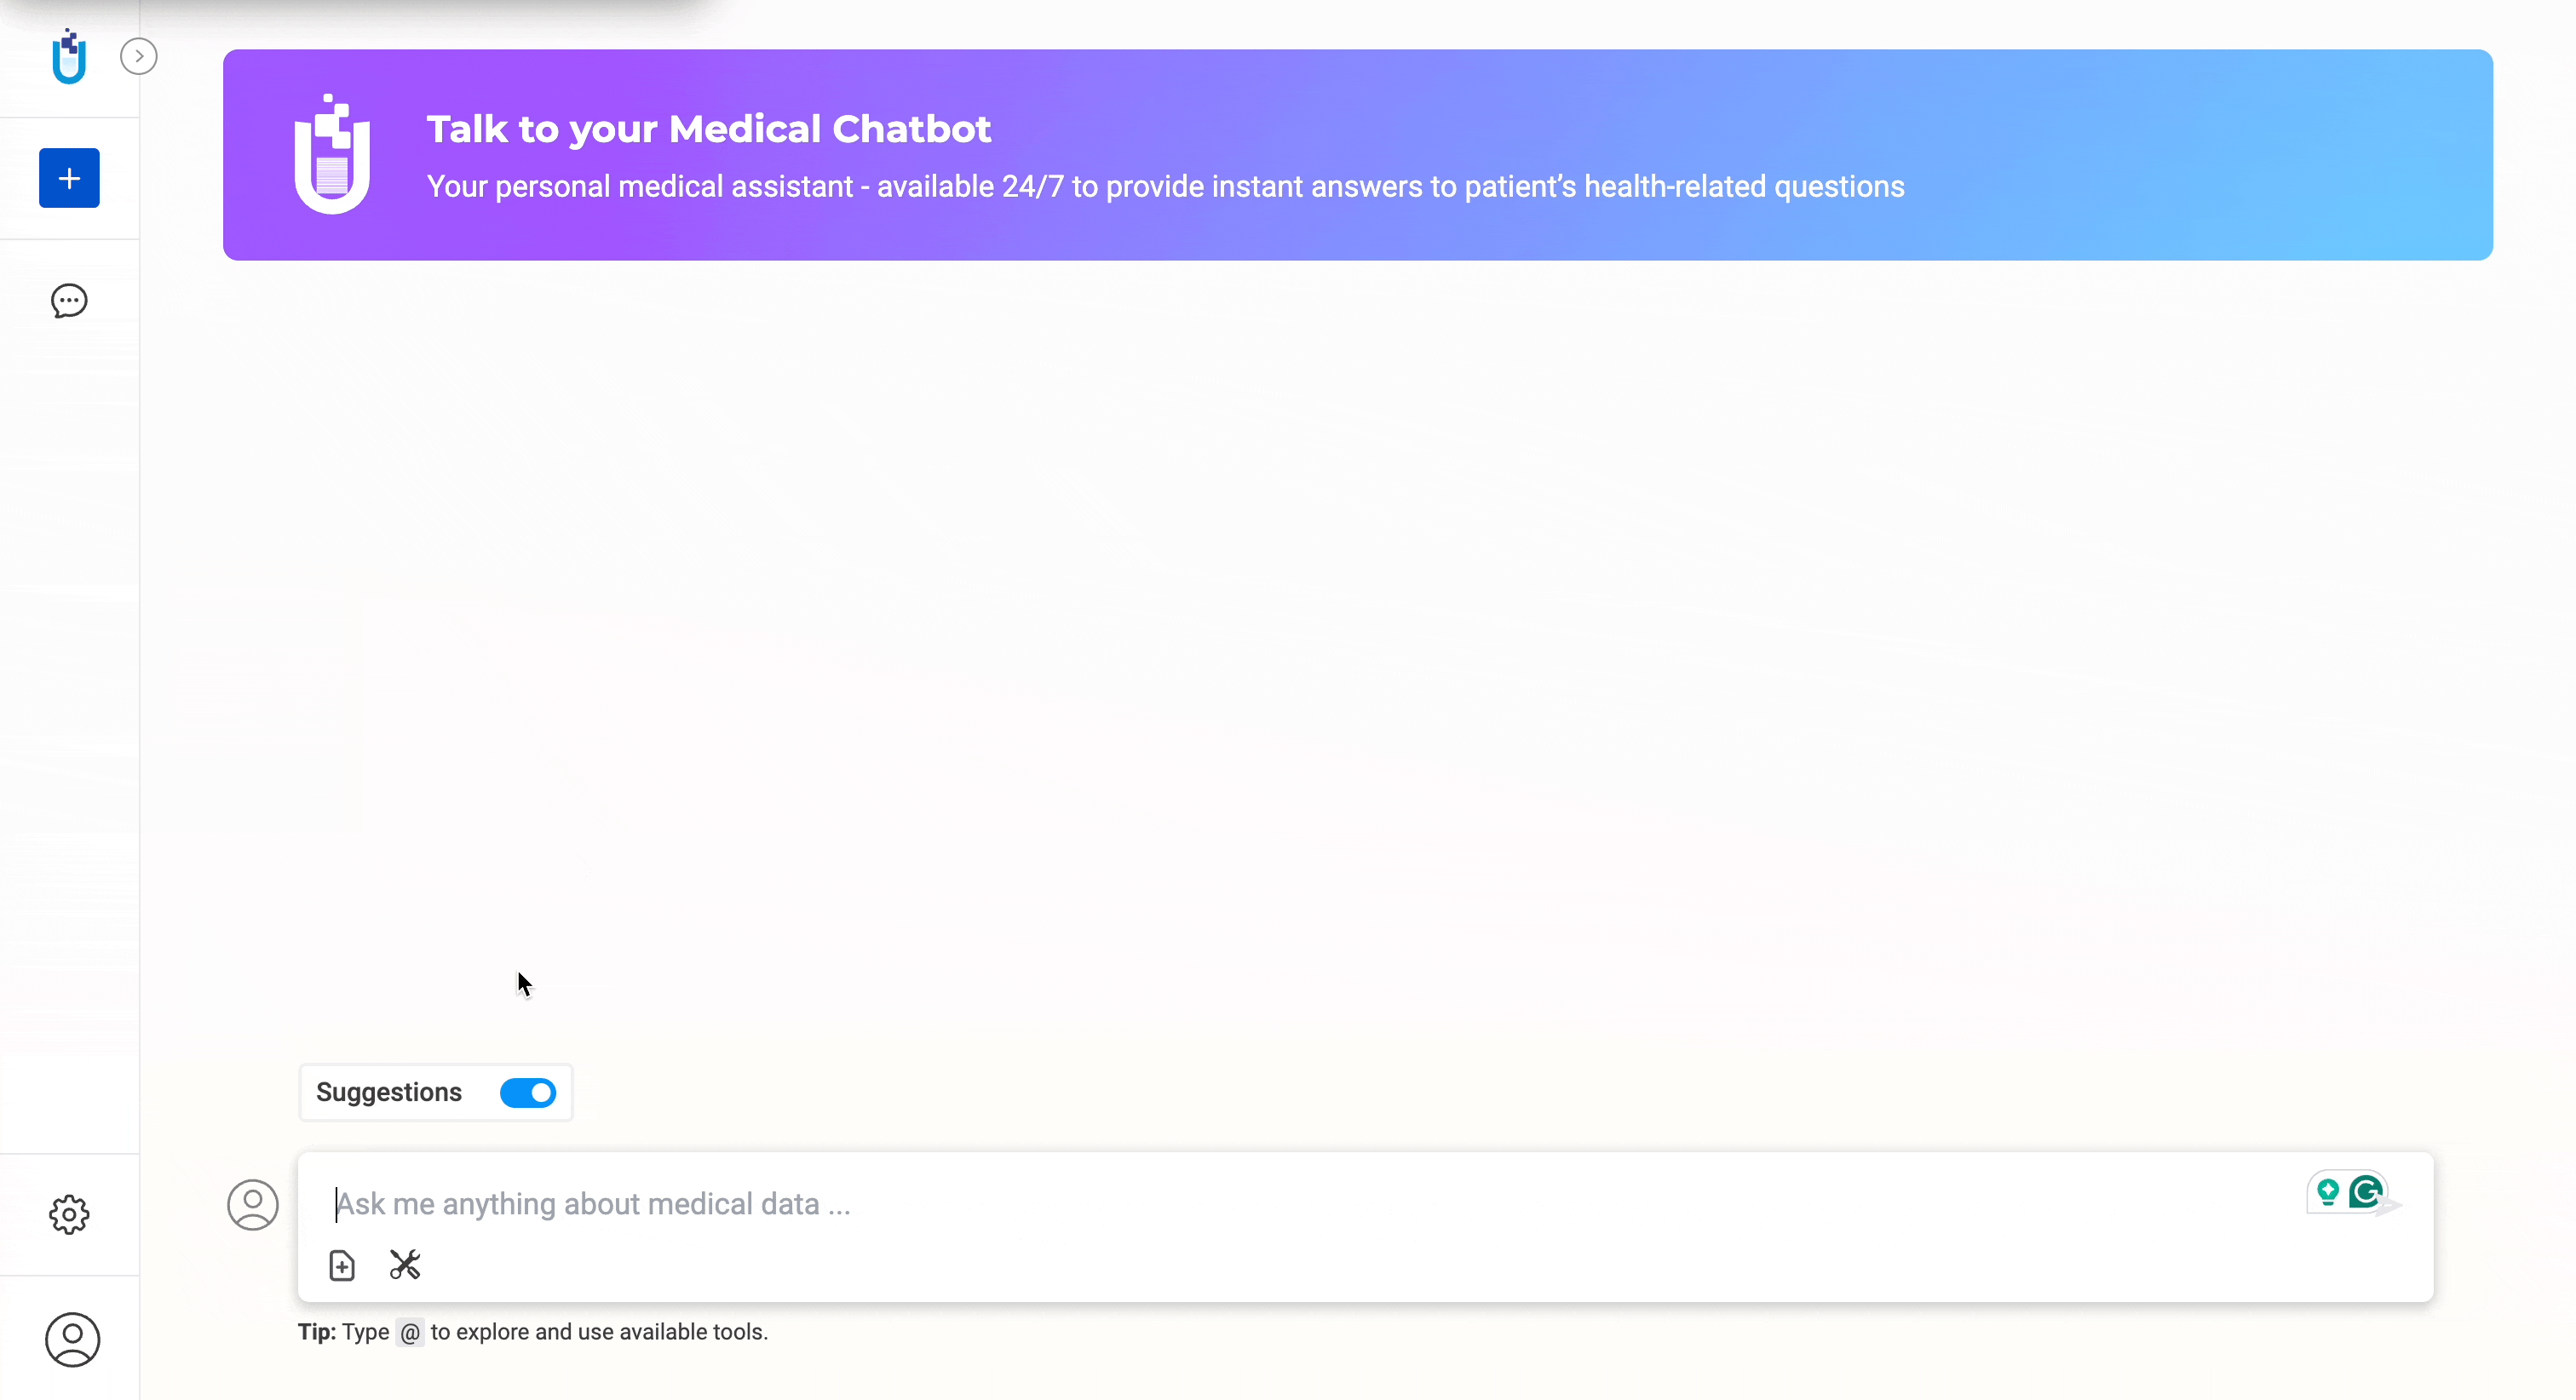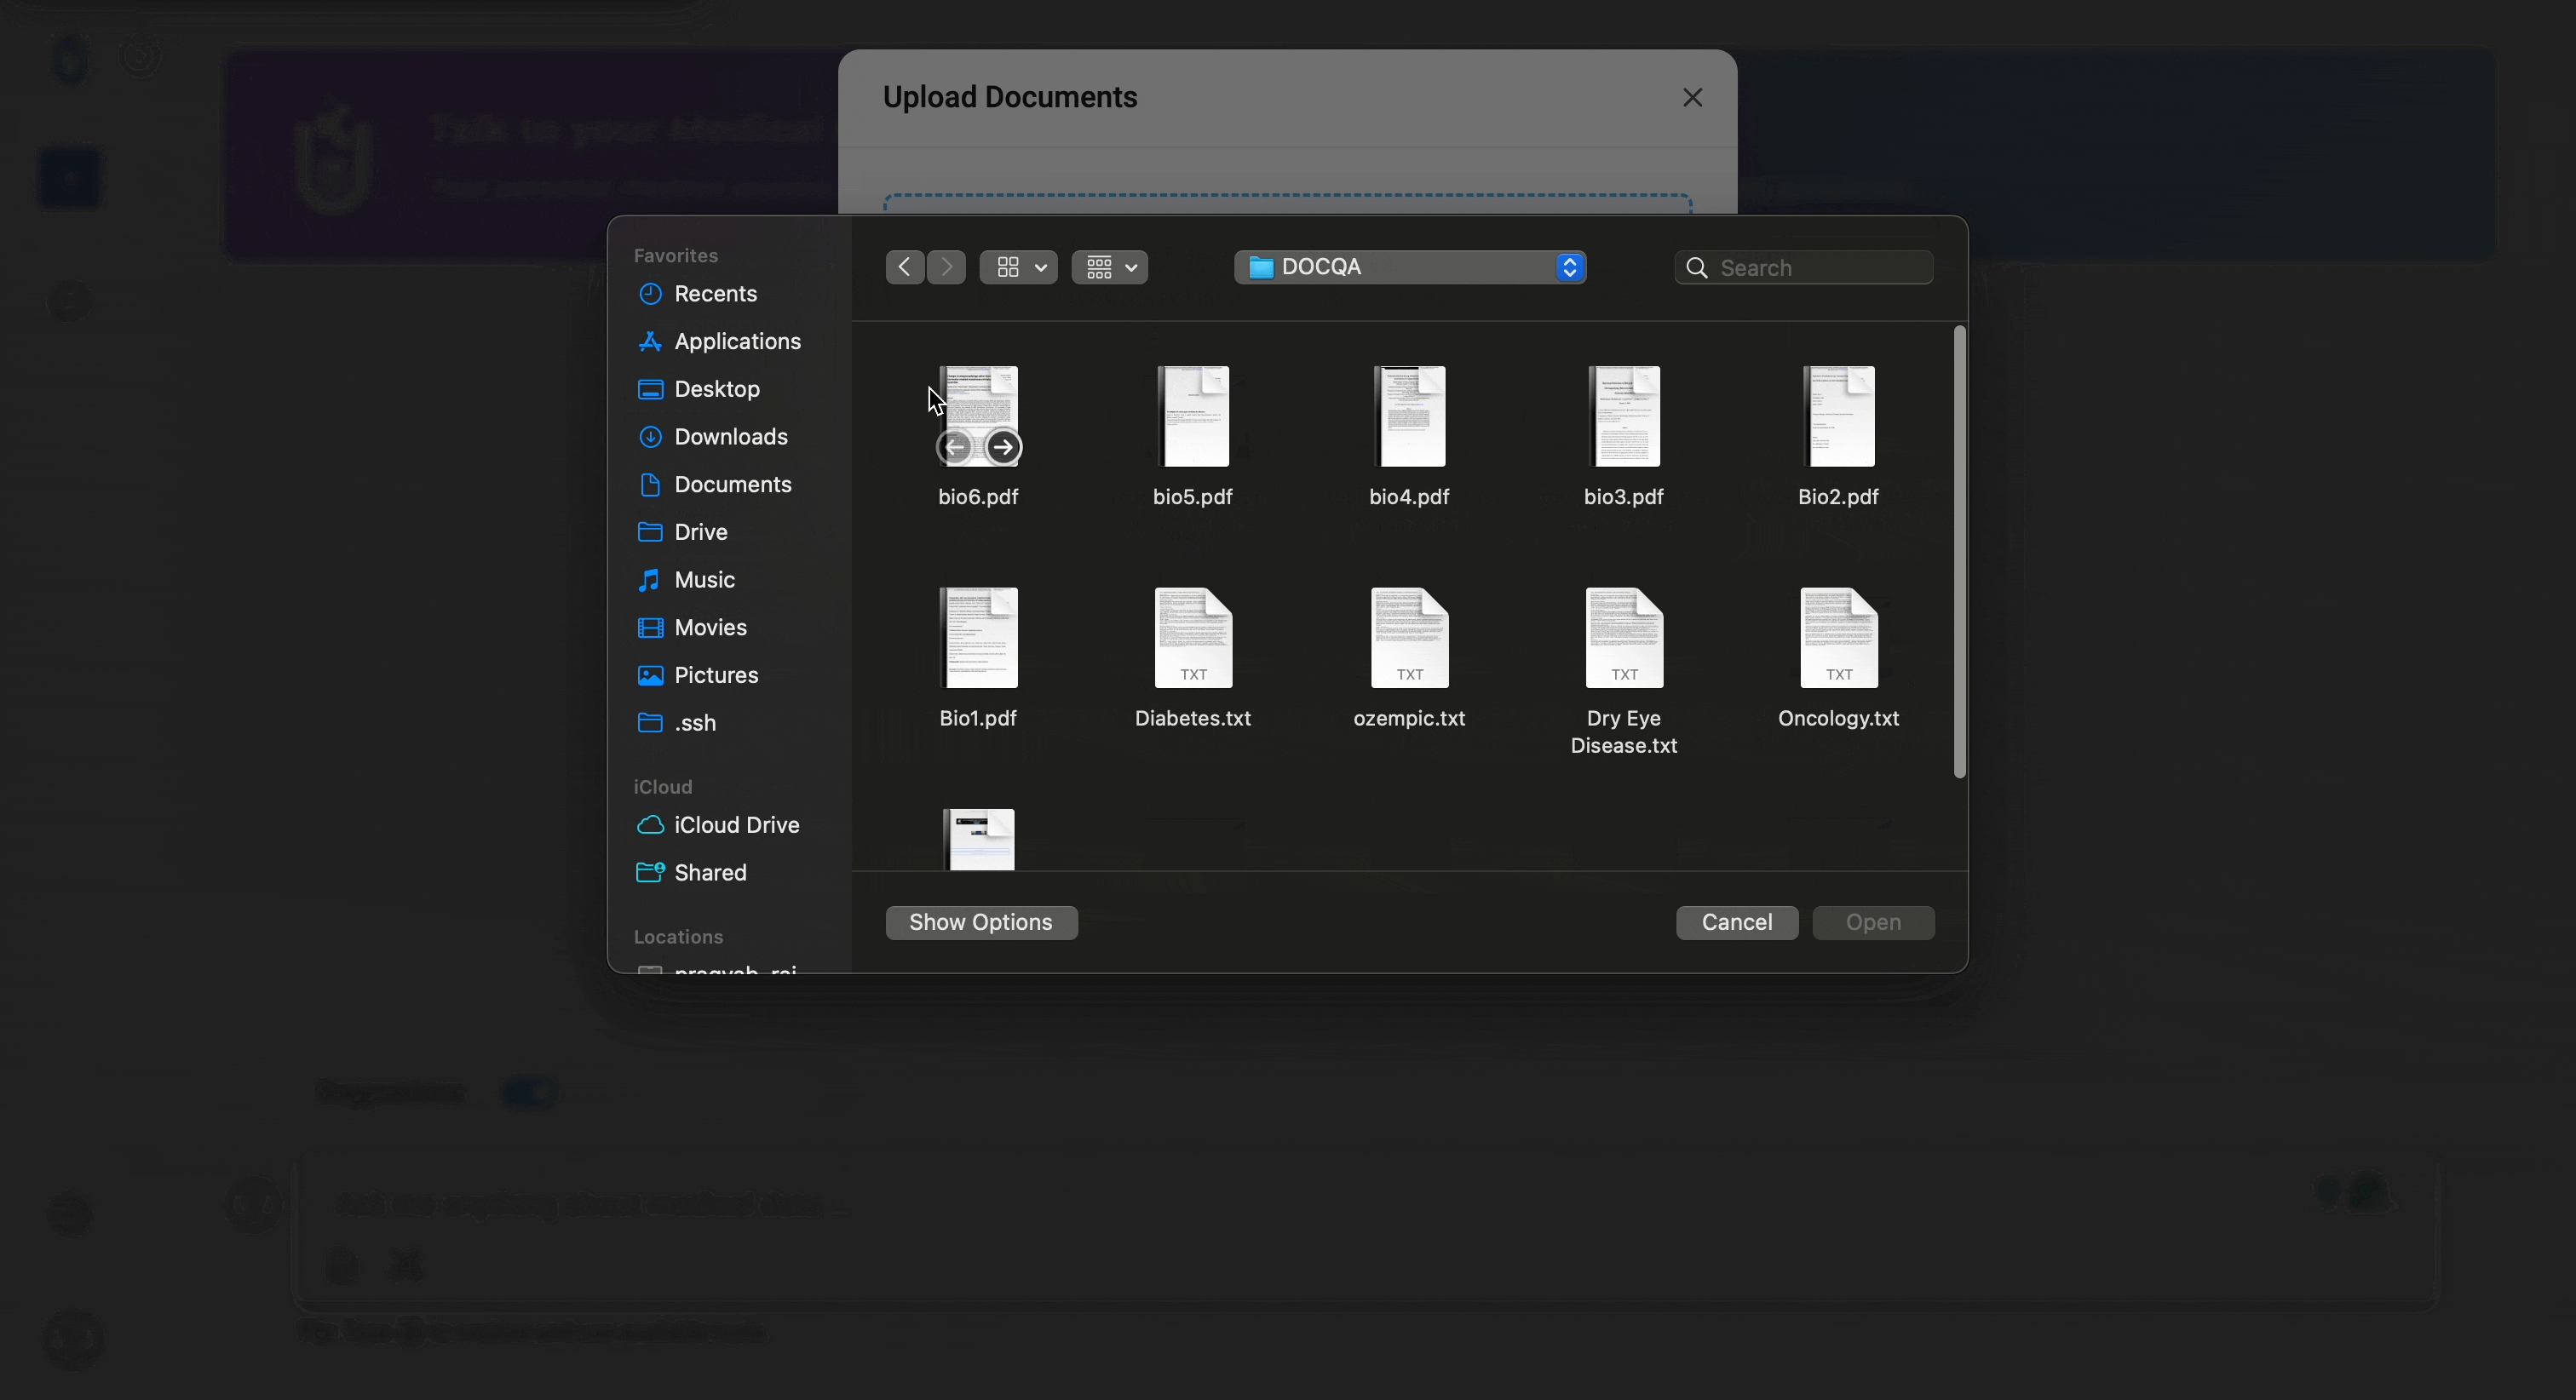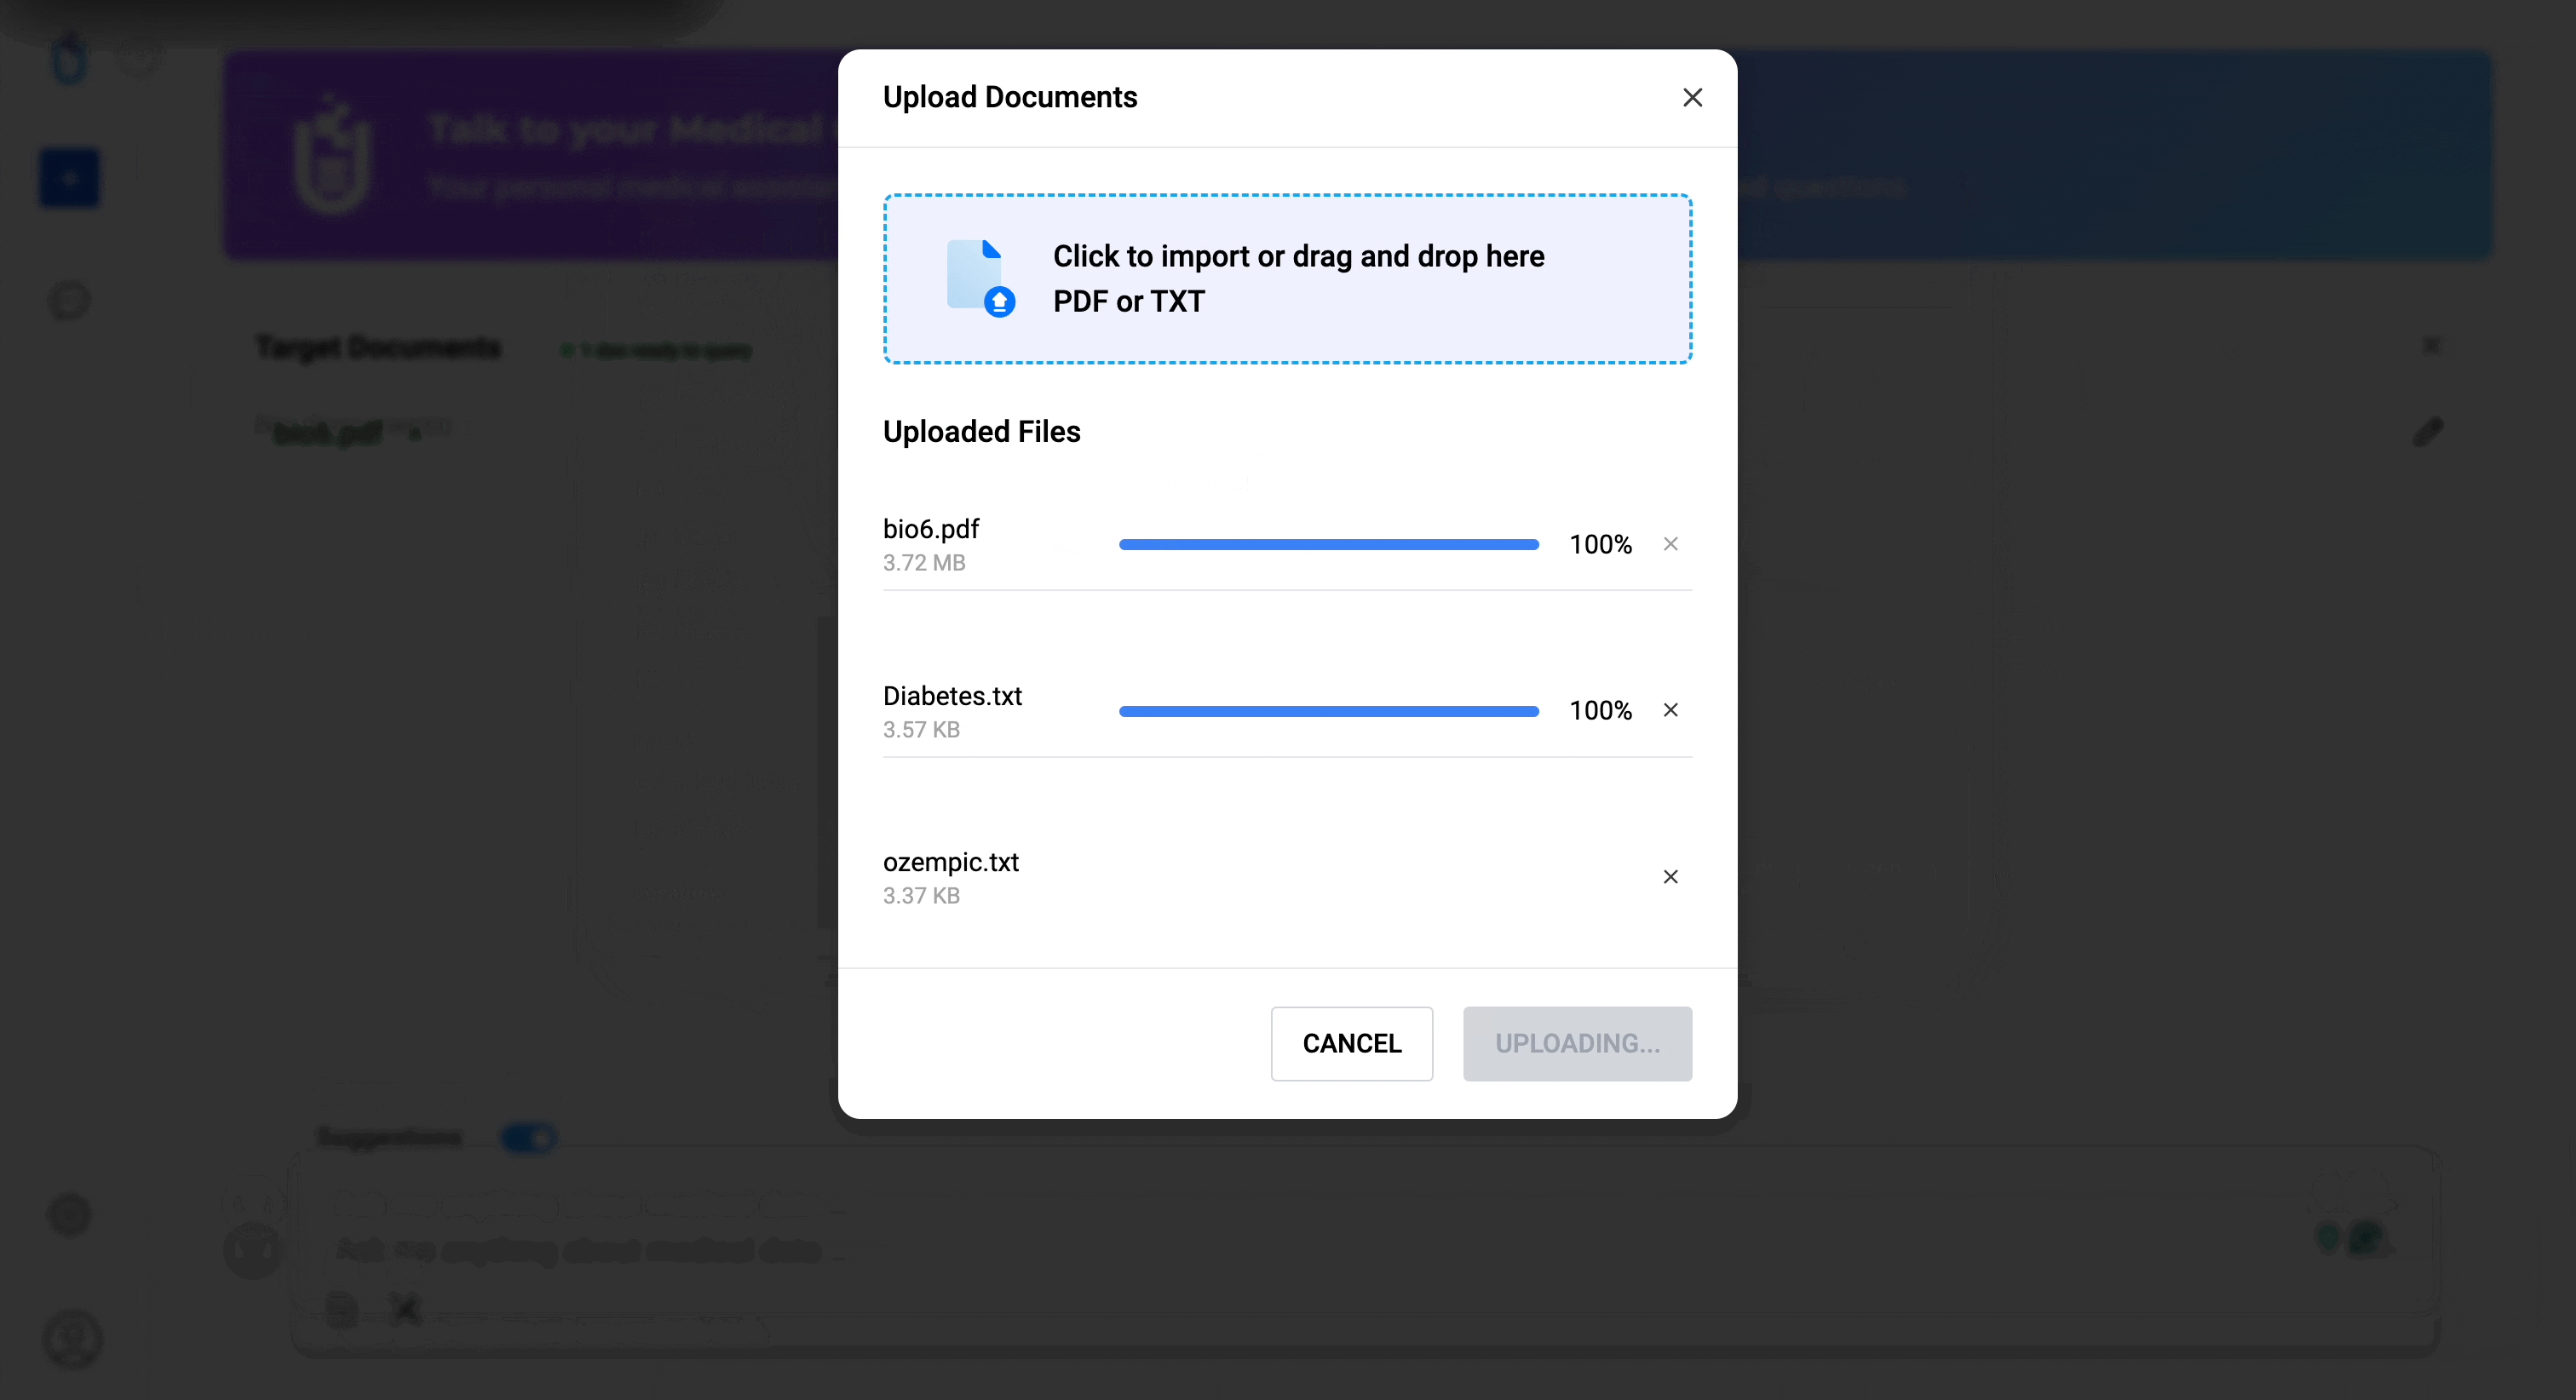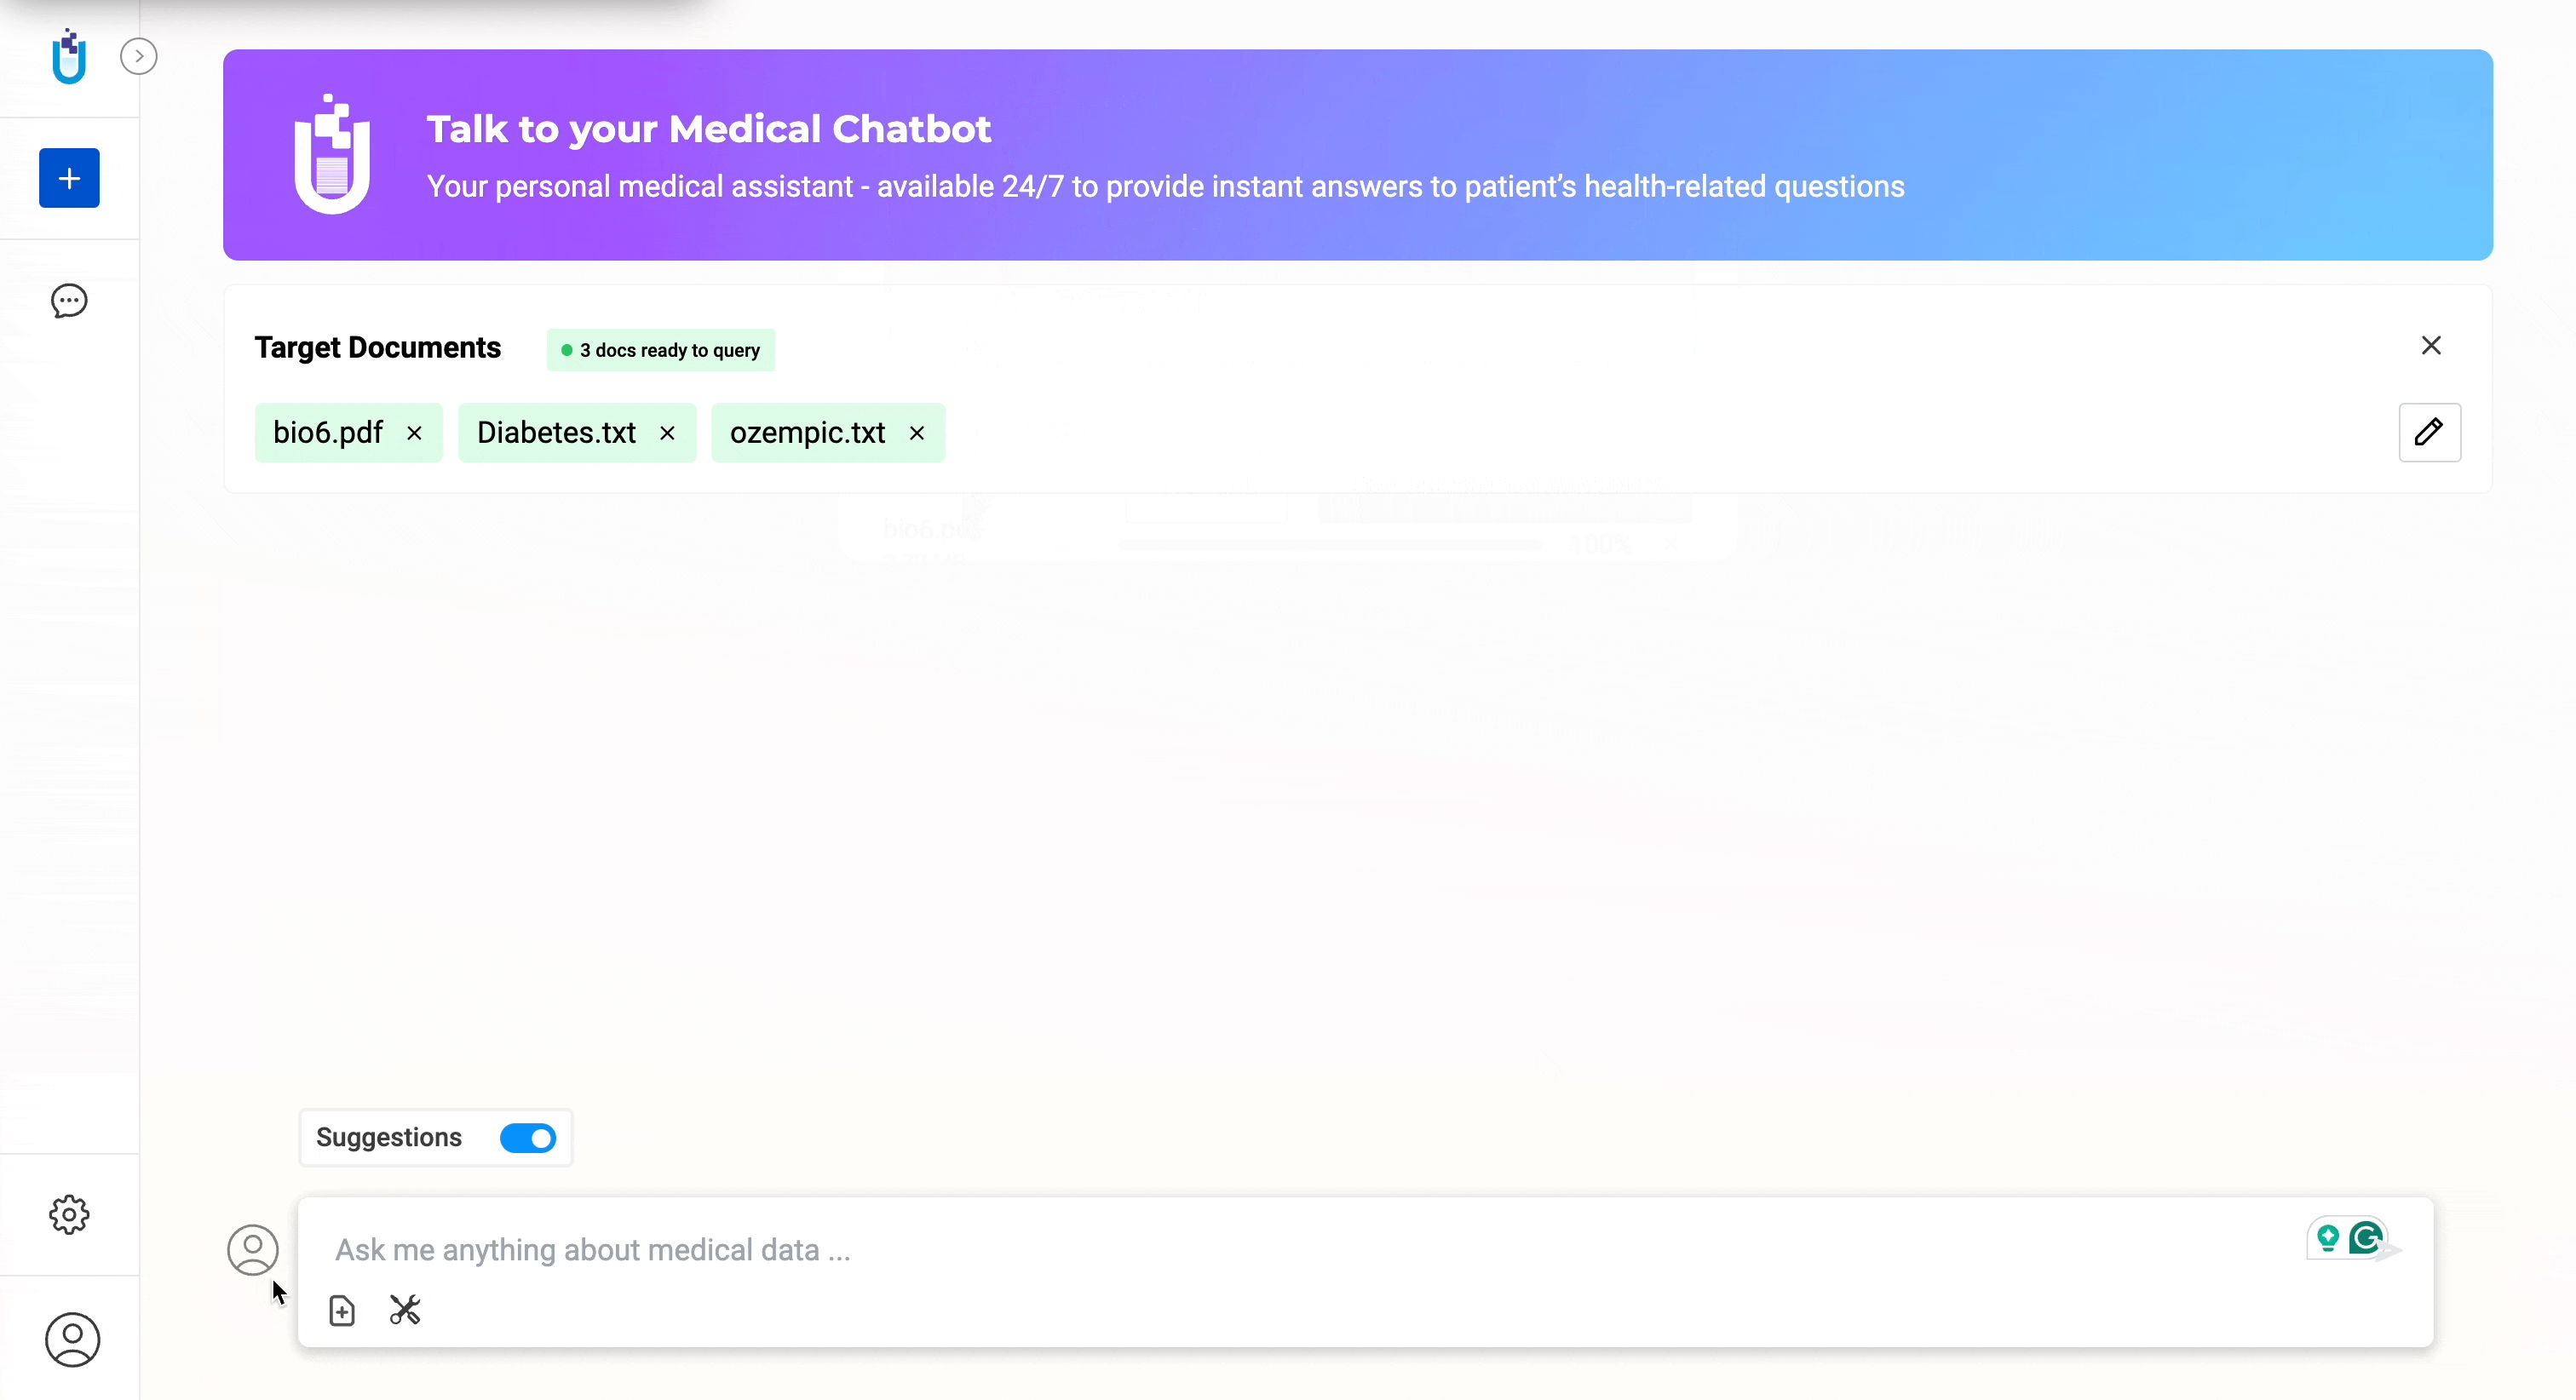
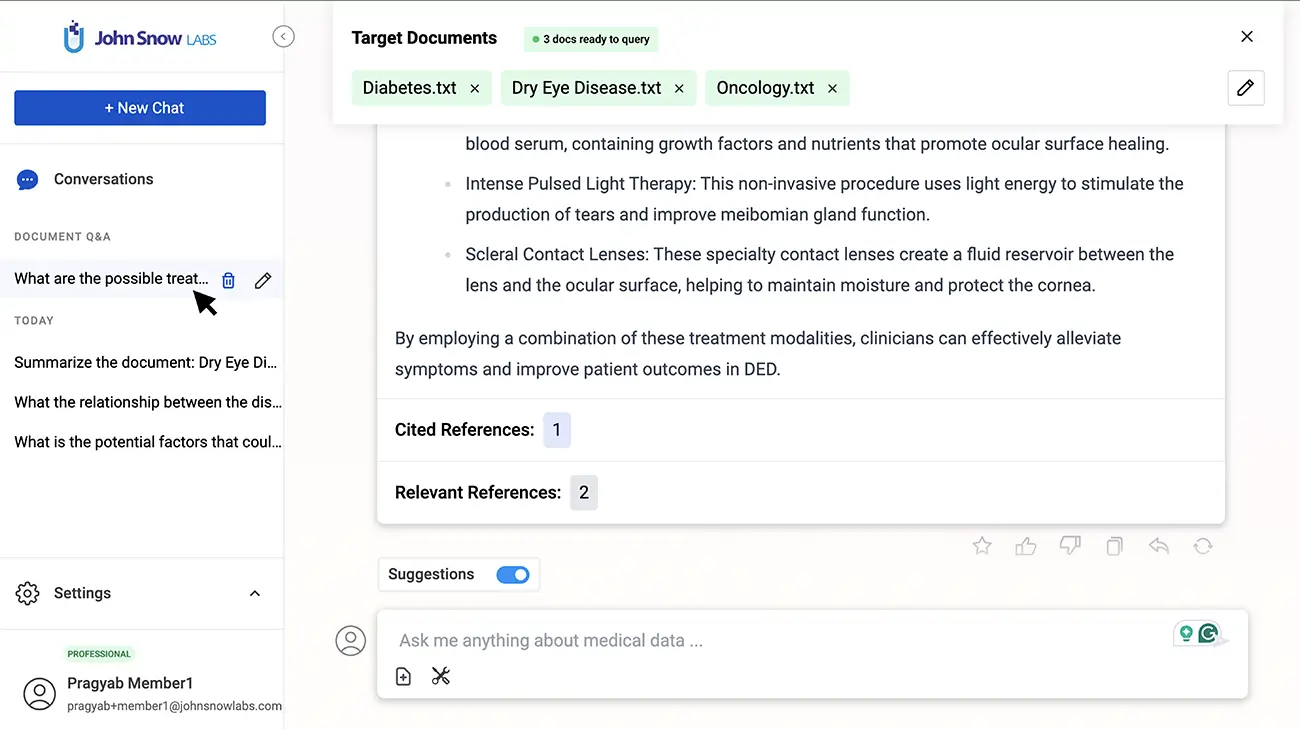
Introducing Document Q&A (DocQA) Feature in Medical Chatbot - John Snow ...
352 - DocVQA: A Dataset for VQA on Document Images - YouTube
DocVQA学习 - 知乎
GitHub - Code-Yan-ZX/multipage-docvqa-diagnosis · GitHub
VISion On Request: Enhanced VLLM efficiency with sparse, dynamically ...
ICLR Poster DocMIA: Document-Level Membership Inference Attacks against ...
[2007.00398] DocVQA: A Dataset for VQA on Document Images
DocVQA_TEST和InfoVQA_TEST无法评测 · Issue #504 · open-compass/VLMEvalKit ...
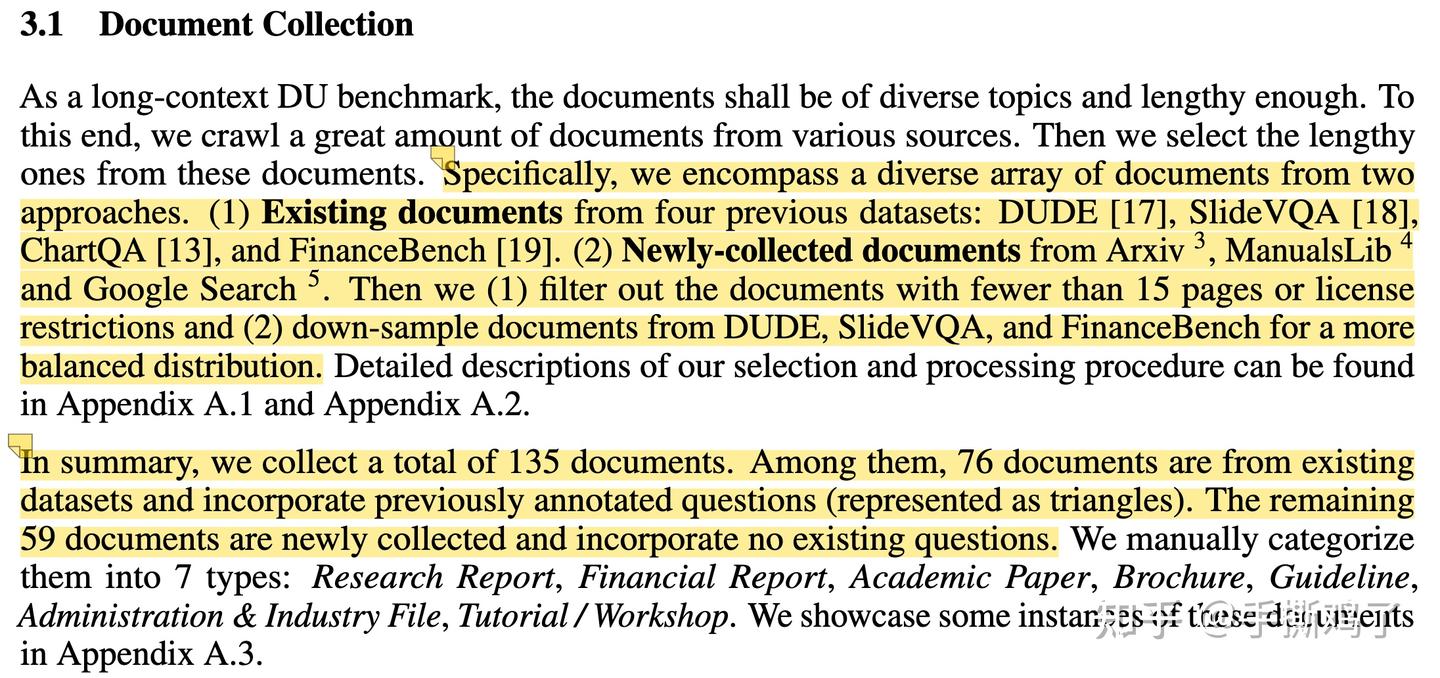
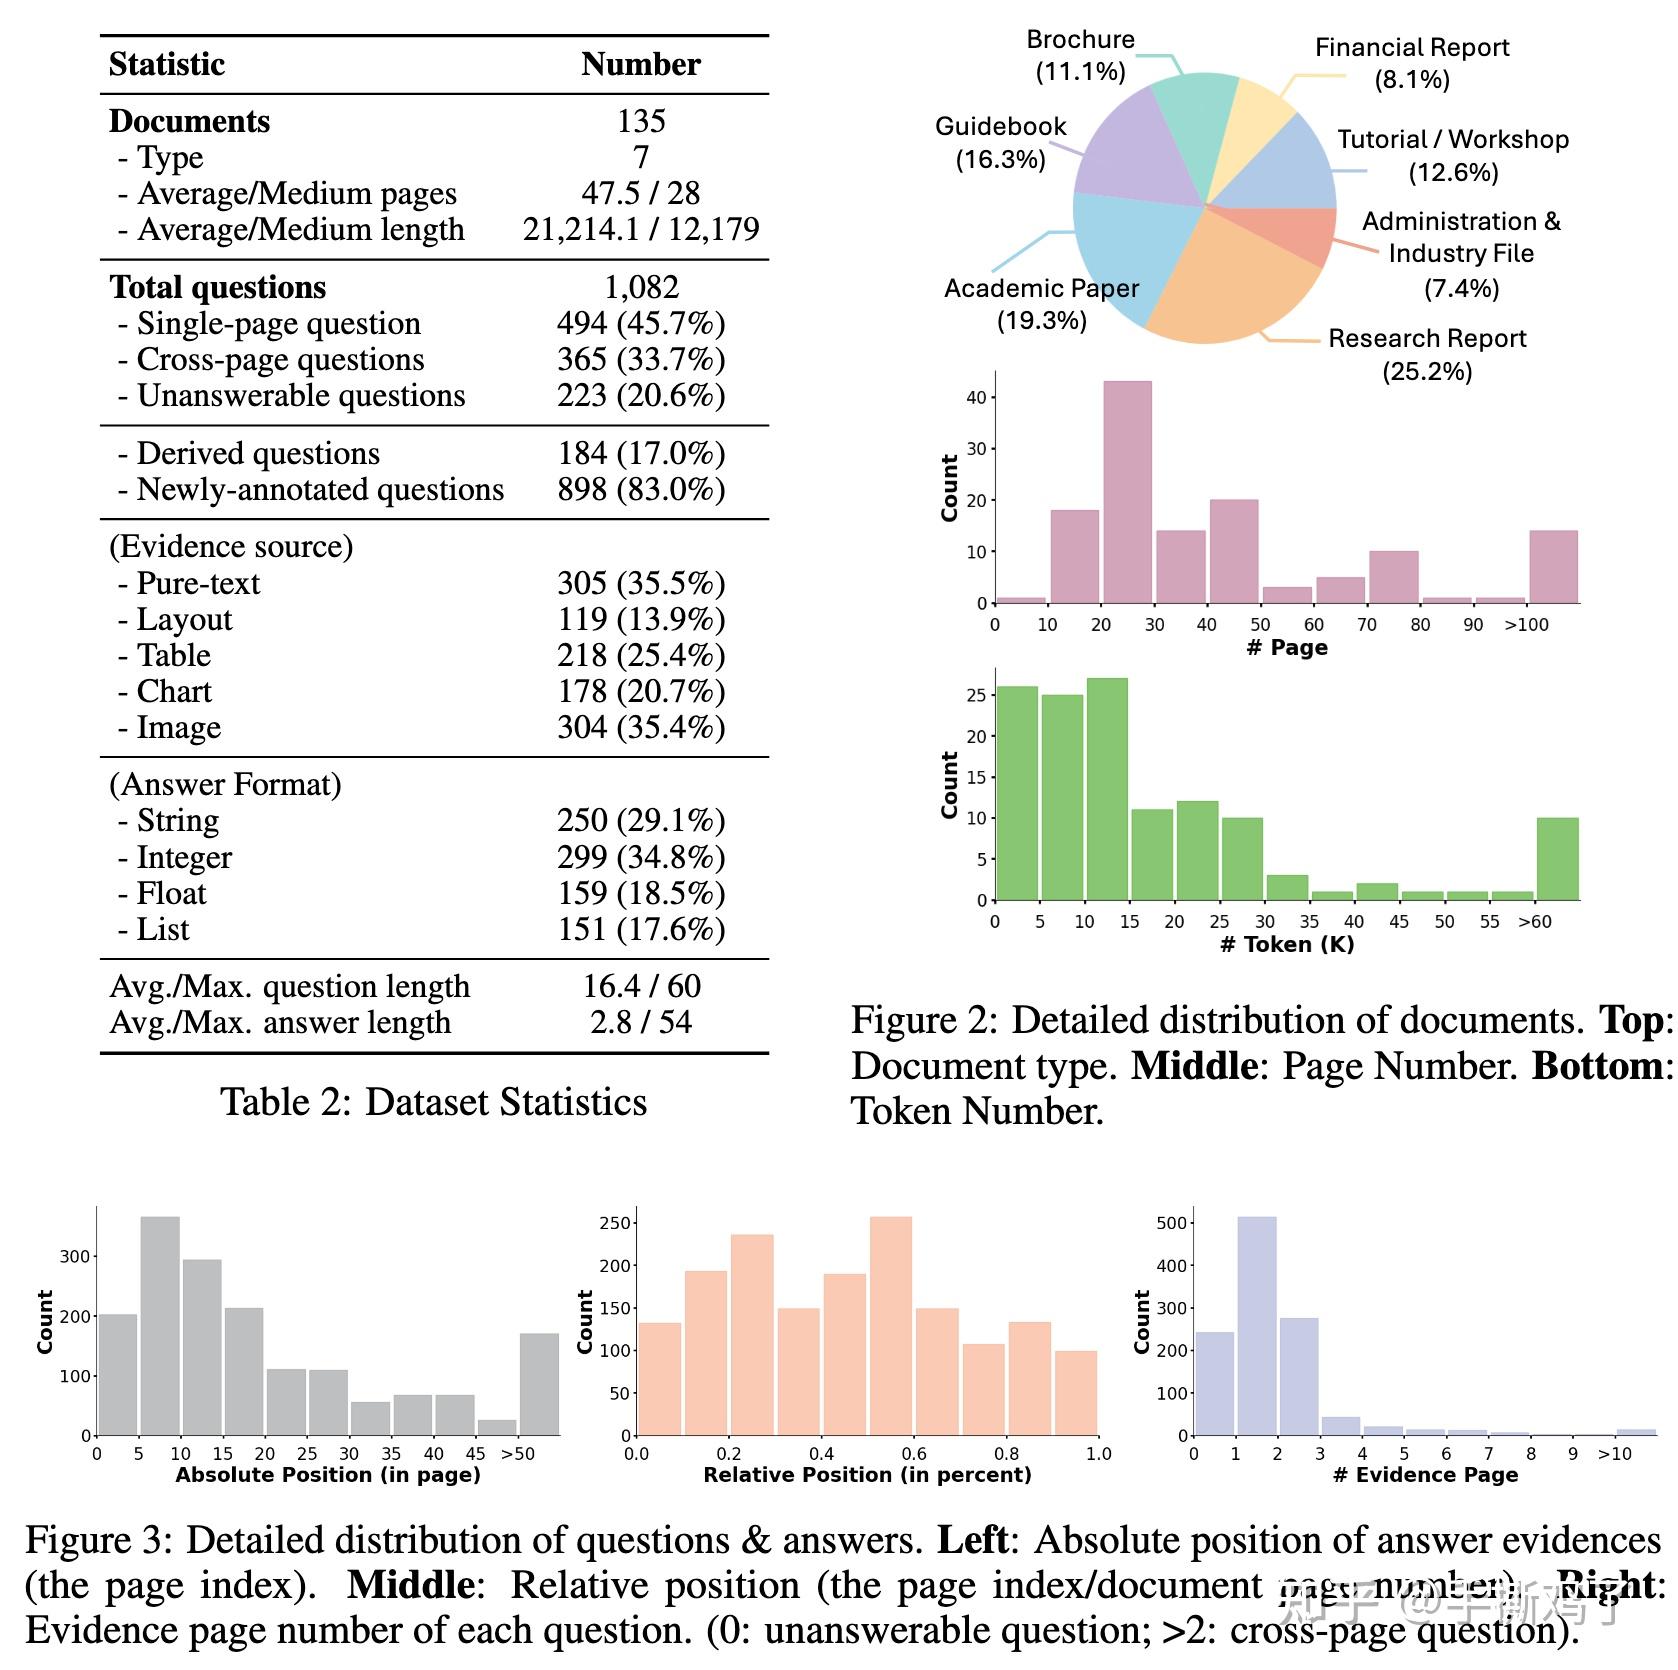
MMLongBench: Benchmarking Long-Context Vision-Language Models ...
Document QA
Visual question answering vqa | PDF
Native Visual Understanding: Resolving Resolution Dilemmas in Vision ...
[Question]: DocVQA-ZH数据集的preprocess问题 · Issue #3554 · PaddlePaddle ...
VQA (Visual Question Answering)|视觉问答数据集|图像理解数据集
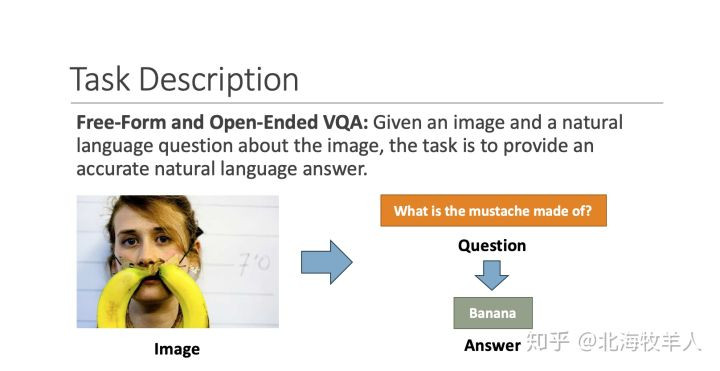
Understanding DocVQA: Document Visual Question Answering | by Krishna ...
VoQA: Visual-only Question Answering | AI Research Paper Details
Overview - docqa Documentation
LlamaFactory-SciEGQA/saves/bbox_docvqa_crop/qwen3-vl-8b at main ...
Modular Visual Question Answering VQA System For Autonomous Mobility | PDF
Transforming Document Processing with Pix2Struct and TrOCR: A Deep Dive ...
VQA: Visual Question Answering | PDF
vidore/docvqa_test_subsampled_captioning · Datasets at Hugging Face
merve/docvqa-media-judged · Datasets at Hugging Face
coldoc/docvqa_test_subsampled_captioning · Datasets at Hugging Face
多文档DocVQA-论文收集 - 知乎
Venkat-Ram-Rao/docvqa-tables-lists · Datasets at Hugging Face
cactusgame/donut-docvqa-demo · Hugging Face
dddraxxx/docvqa-augmented-rl-sm-test · Datasets at Hugging Face
GitHub - svjack/docvqa-gen: Question Answering dataset generator of ...
Mahir-Ahmed/DocVQA_Incomplete · Datasets at Hugging Face
am-infoweb/layoutlmv2-finetuned_docvqa · Hugging Face
(PDF) DocVQA: A Dataset for VQA on Document Images
TriDyme/Florence-2-DocVQA-test · Hugging Face
indra-inc/docvqa_en_full_test_processed · Datasets at Hugging Face
Sharka/DocVQA_for_LayoutLM · Datasets at Hugging Face
Slicky325/DOCVQA · Datasets at Hugging Face
vidore/docvqa_test_subsampled at main
AbdulMuqtadir/DocVQA_Processed_Dataset · Datasets at Hugging Face
doceoSoftware/docvqa_invoices_v1 at main