Showing 110 of 110on this page. Filters & sort apply to loaded results; URL updates for sharing.110 of 110 on this page
Paper page - DocVQA: A Dataset for VQA on Document Images
[2007.00398] DocVQA: A Dataset for VQA on Document Images
[2511.15090] BBox-DocVQA: A Large-Scale Bounding-Box–Grounded Dataset ...
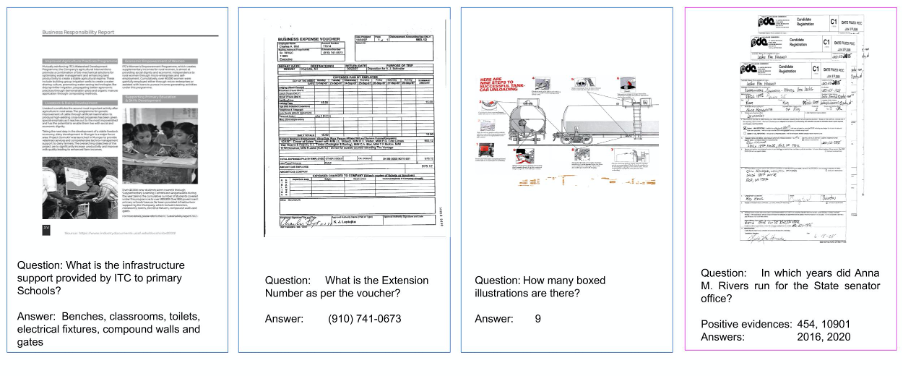
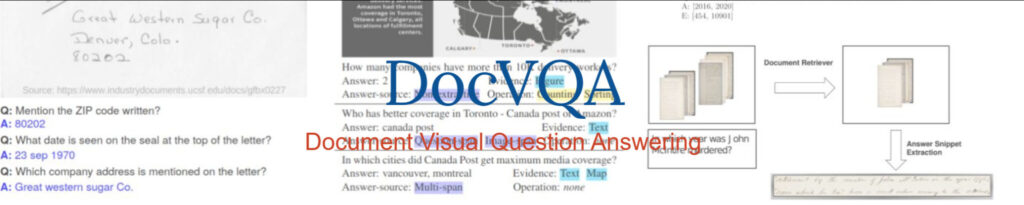
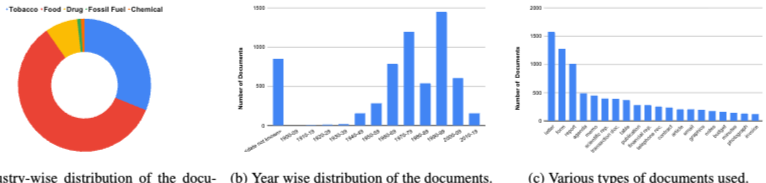
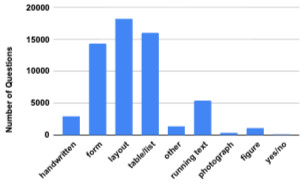
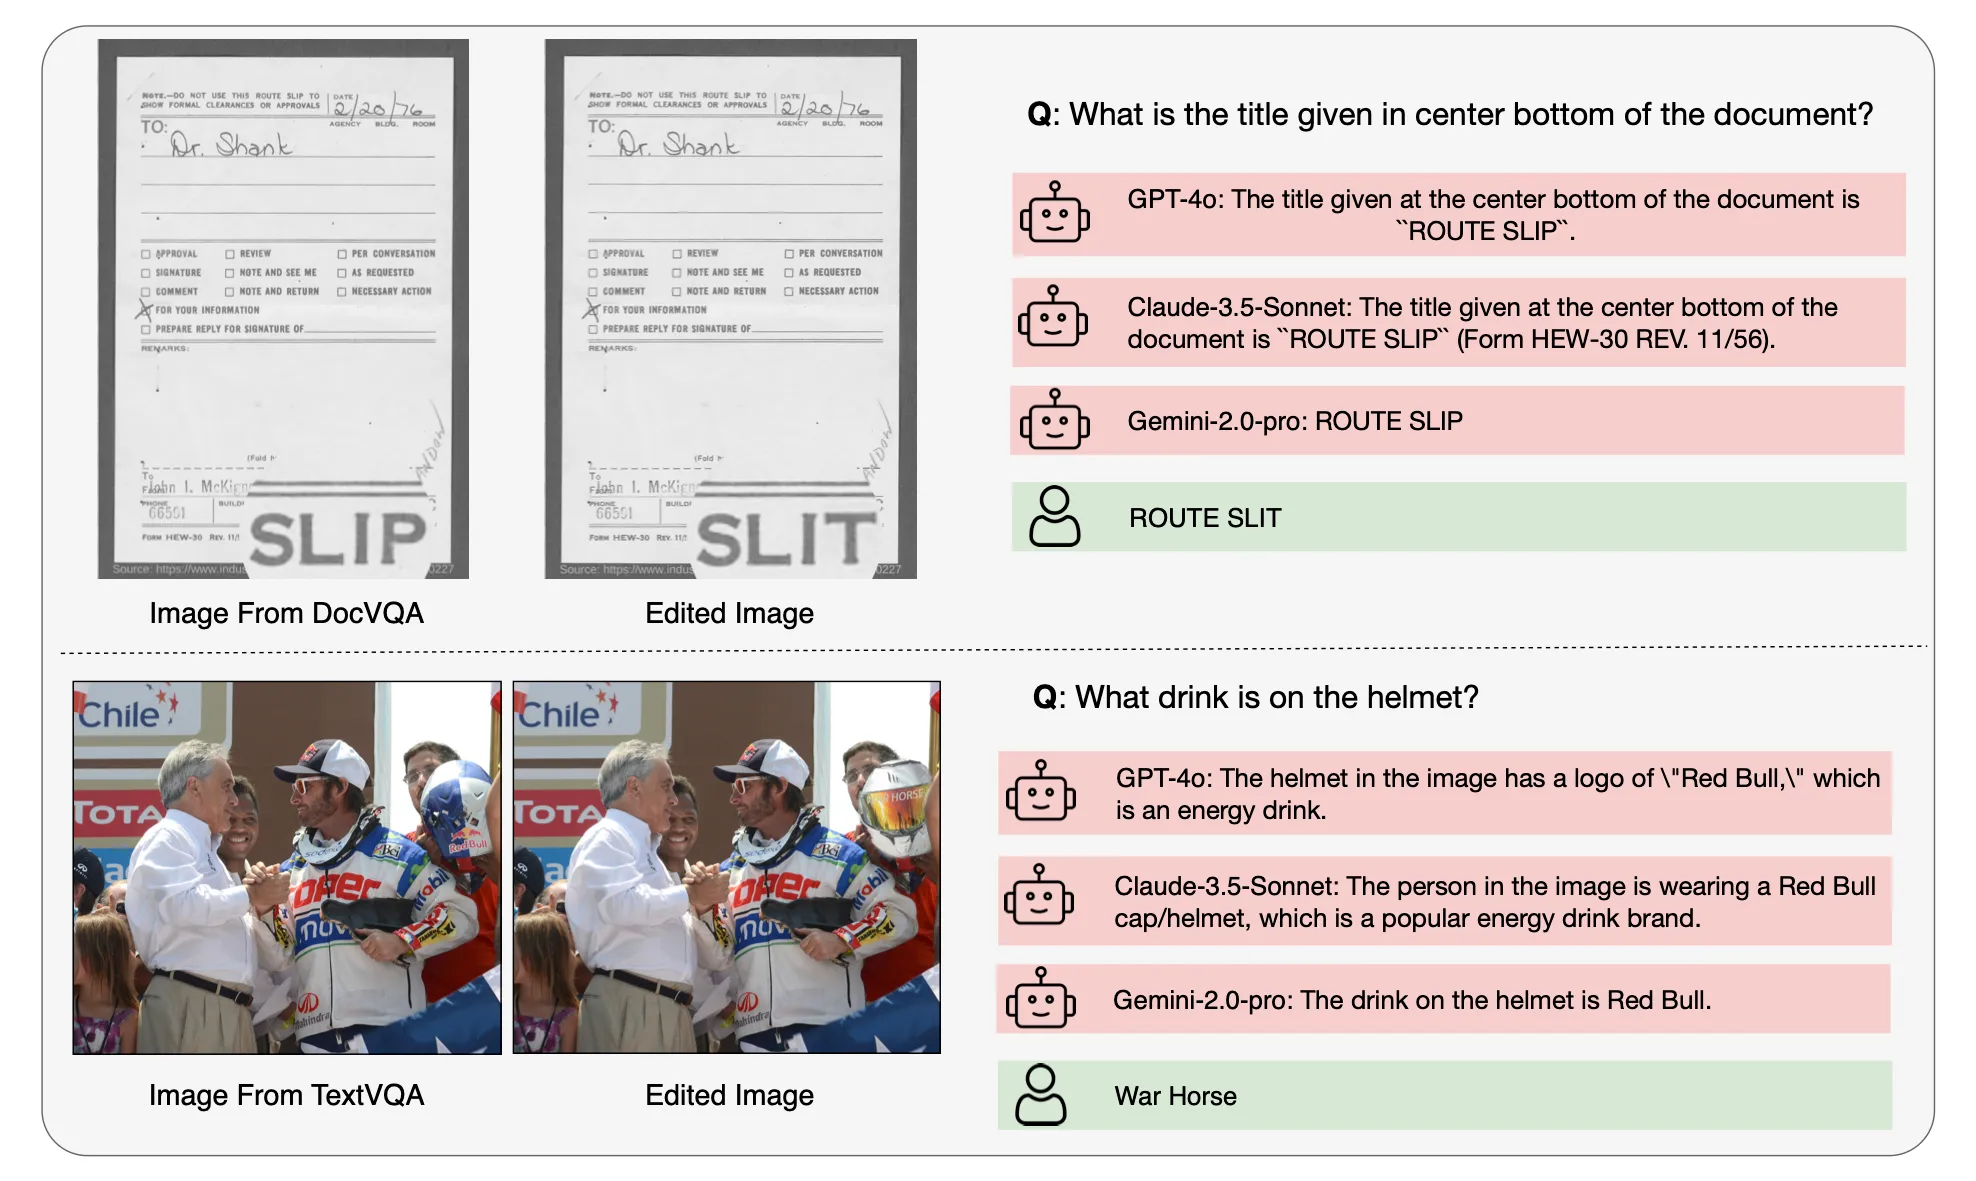
Fig 1. Illustrations of examples from the DocVQA dataset. Source ...
DocVQA — Loupy
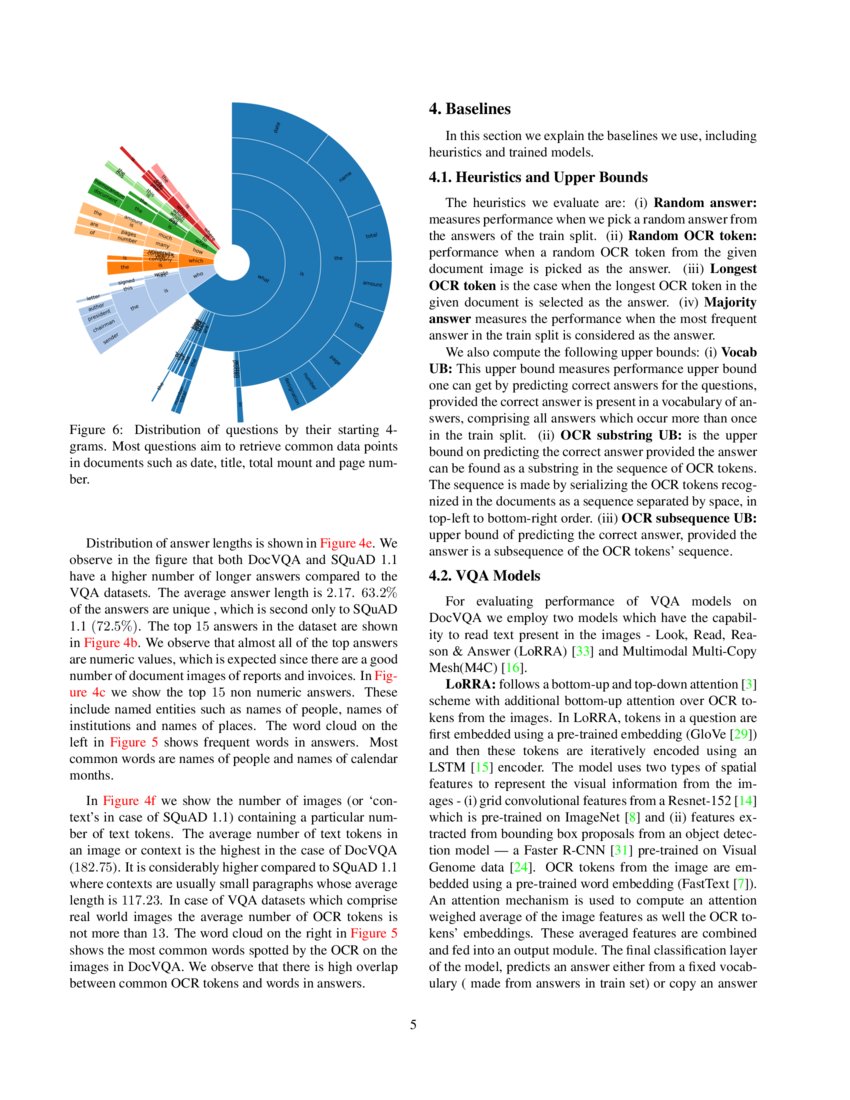
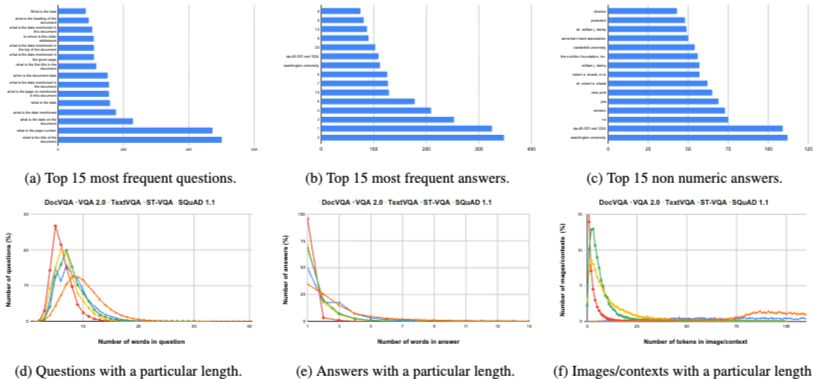
DocVQA: A Dataset for VQA on Document Images | DeepAI
DocVQA | ICDAR 2021
DocVQA: A Dataset for VQA on Document Images
(PDF) DocVQA: A Dataset for VQA on Document Images
DocVQA 文档开放式问答数据集 | 数据集 | HyperAI超神经
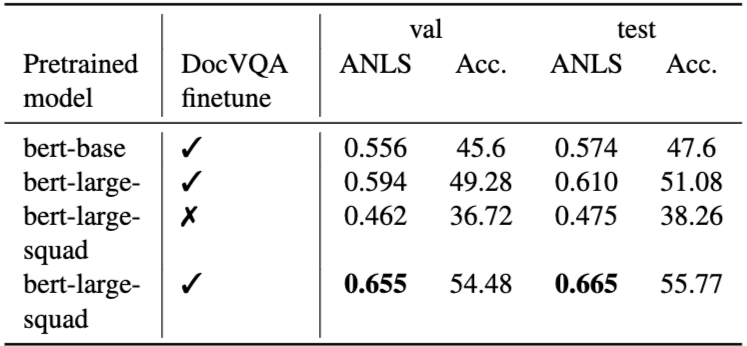
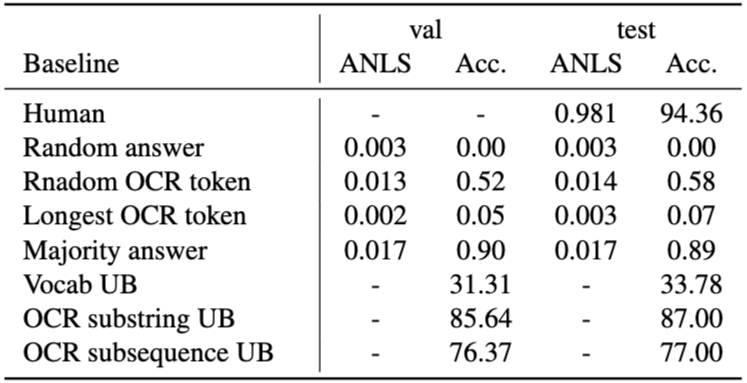
Performance comparison on DocVQA dataset. | Download Scientific Diagram
(PDF) BBox DocVQA: A Large Scale Bounding Box Grounded Dataset for ...
Paper page - BBox DocVQA: A Large Scale Bounding Box Grounded Dataset ...
BBox DocVQA: A Large Scale Bounding Box Grounded Dataset for Enhancing ...
GitHub - svjack/docvqa-gen: Question Answering dataset generator of ...
DocVQA Benchmark: 99.16% Accuracy Using Agentic Document Extraction ...
352 - DocVQA: A Dataset for VQA on Document Images - YouTube
DocVQA - Datasets
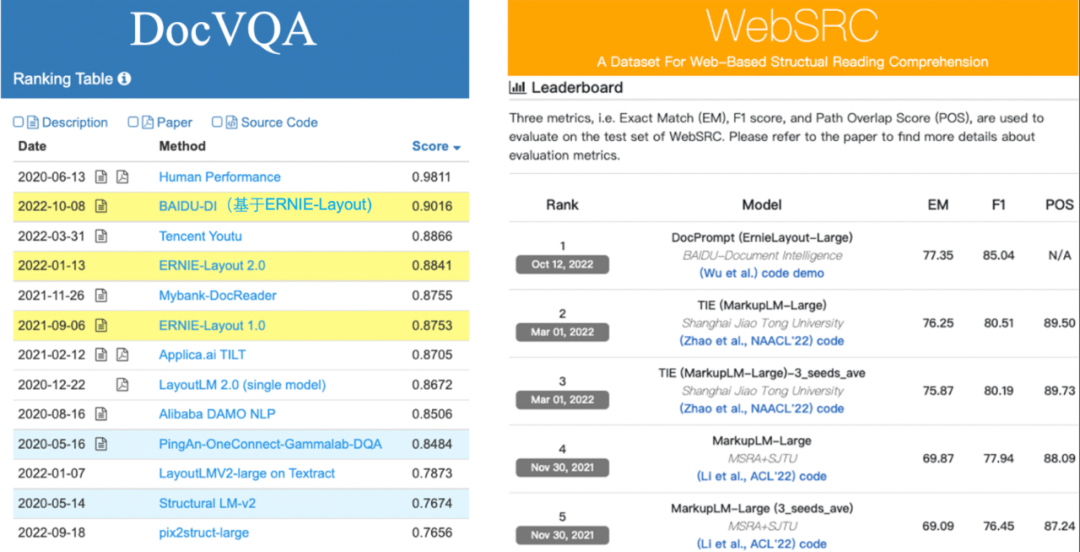
The rankings of the top 10 models on the DocVQA leaderboard, before and ...
LLaVAR reproduced results on DocVQA and STVQA do not match reported ...
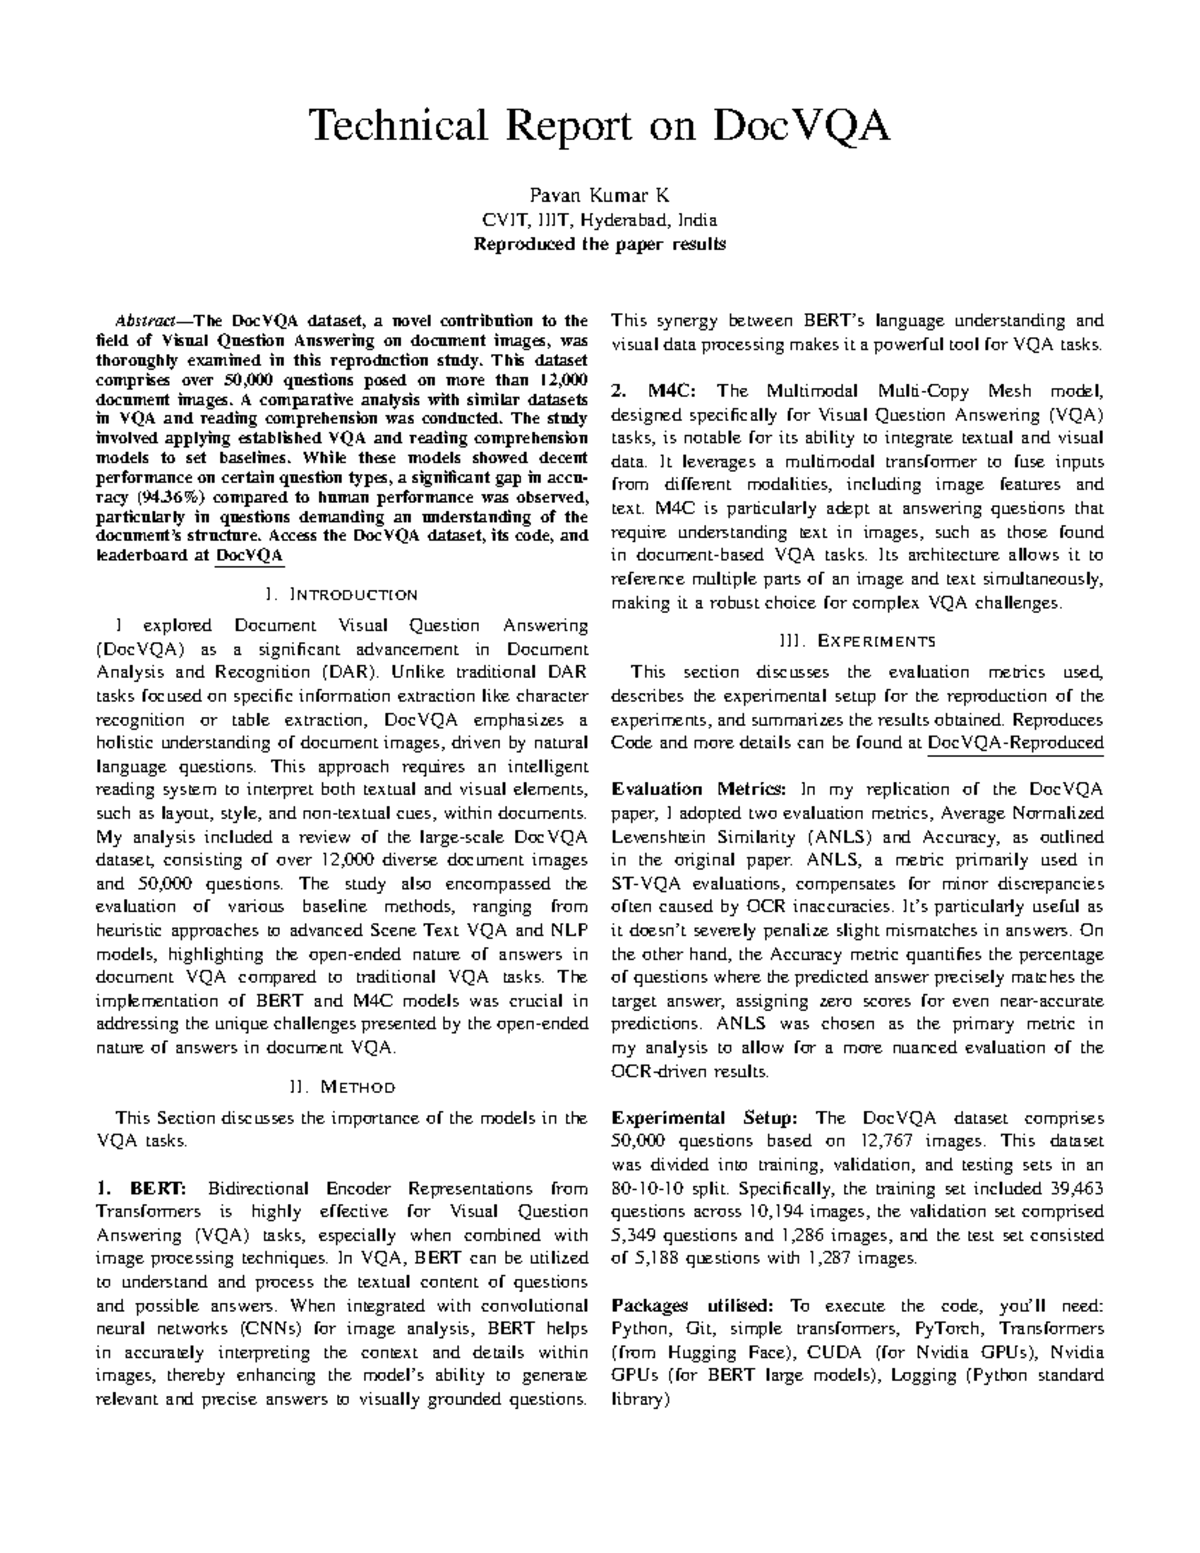
DocVQA Technical Report: Reproduction Study & Analysis - Studocu
[2301.04883] SlideVQA: A Dataset for Document Visual Question Answering ...
Document-Level Membership Inference Attacks Against Docvqa Models | PDF ...
Revolutionizing Document Processing Through DocVQA
DocVQA: A Dataset for VQA on Document Images – Inspect Evals
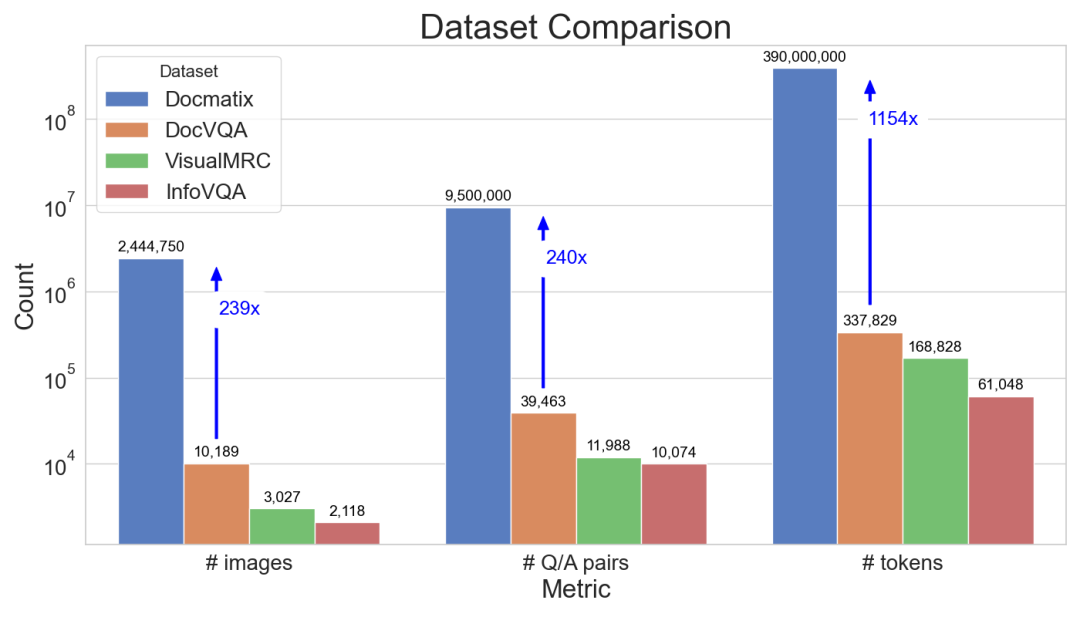
LAVE: Zero-shot VQA Evaluation on Docmatix with LLMs - Do We Still Need ...
#docvqa #docvqa2026 #docvqa #multimodalai #documentunderstanding # ...
Native Visual Understanding: Resolving Resolution Dilemmas in Vision ...
[Electronic Devices Datasheet Information Extraction using Visual ...
Pretraining scores compared to the baseline models on four datasets ...
hub-docs/docs/hub/datasets-viewer-embed.md at main · huggingface/hub ...
Multimodal language modeling
Docmatix - 超大文档视觉问答数据集 - 智源社区
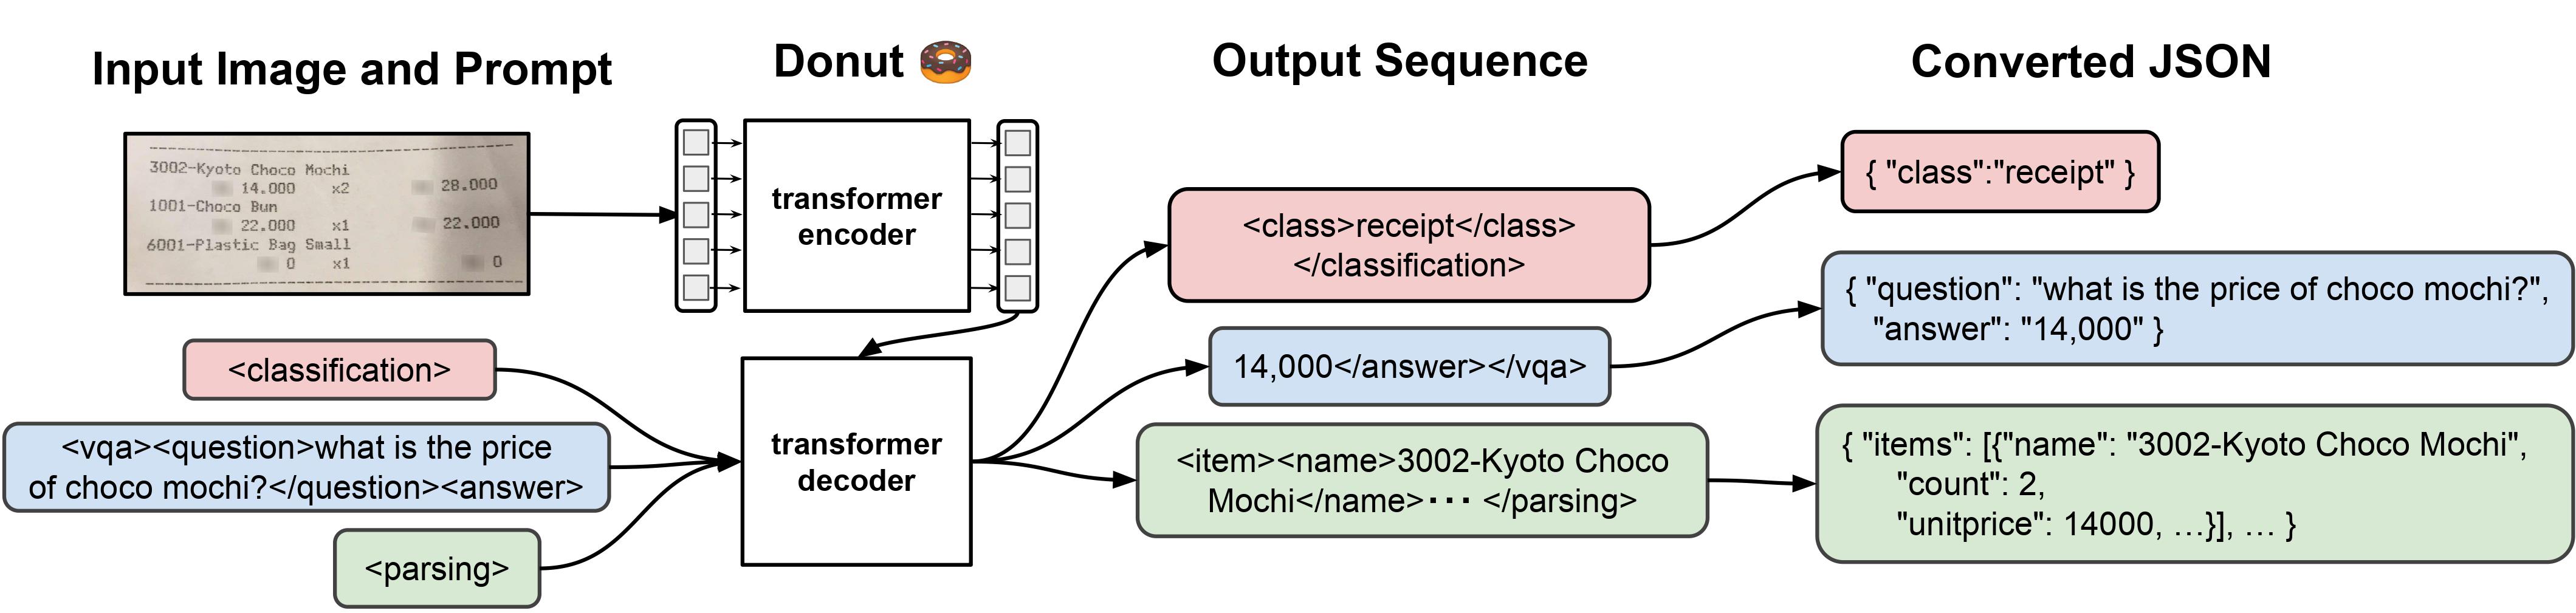
donut-base-finetuned-docvqa: 这个模型可能是用于图像分类任务的预训练模型,但具体细节尚未被公开或广泛讨论 ...
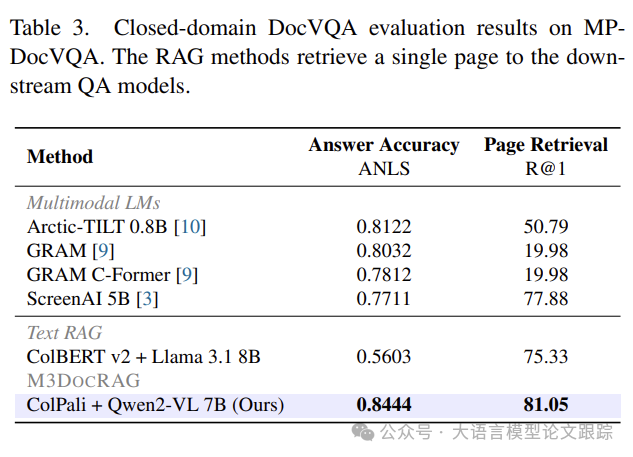
M3DocRAG:文档问答用哪个多模态大模型效果最好?-CSDN博客
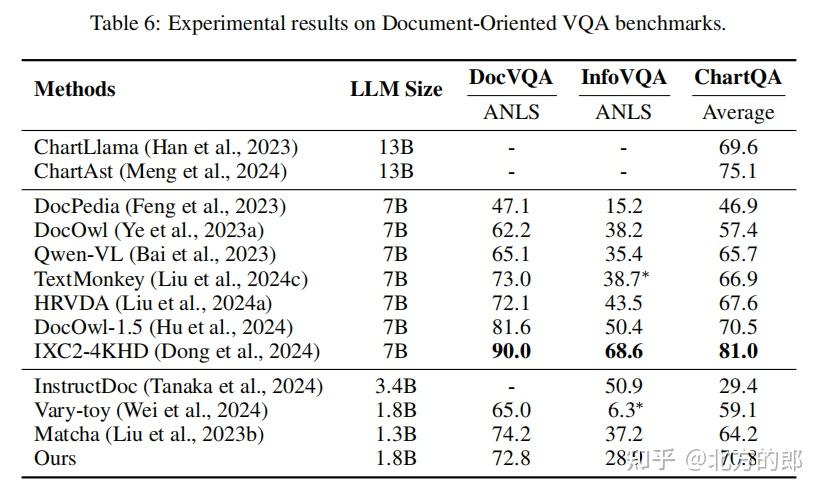
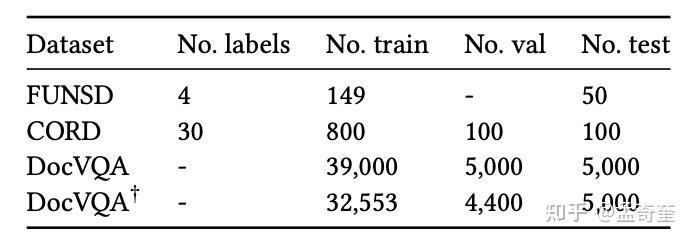
Document VQA论文梳理 - 知乎
VibhorBhatt/docvqa_funsd_dataset_example · Datasets at Hugging Face
GitHub - inamdarmihir/Florence-2-DocVQA: Fine tuned Florence 2 Model on ...
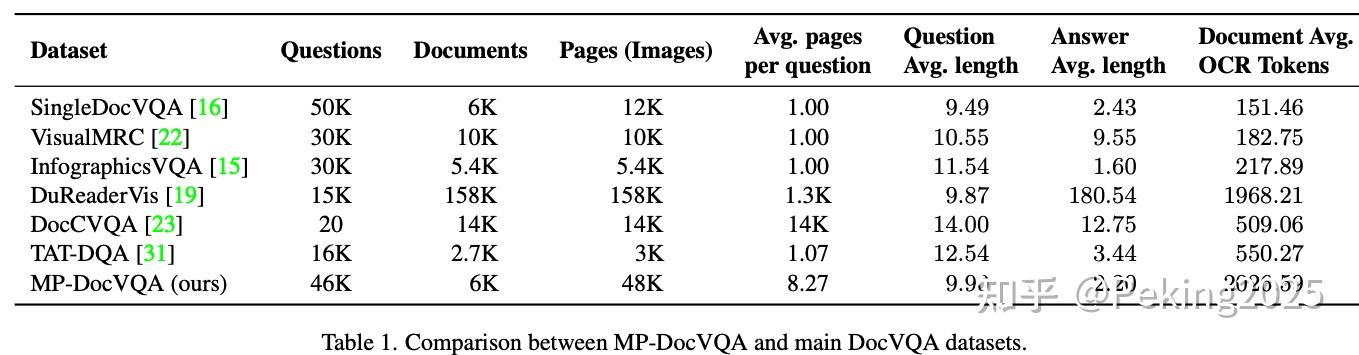
MP-DocVQA - ModelScope 魔搭社区
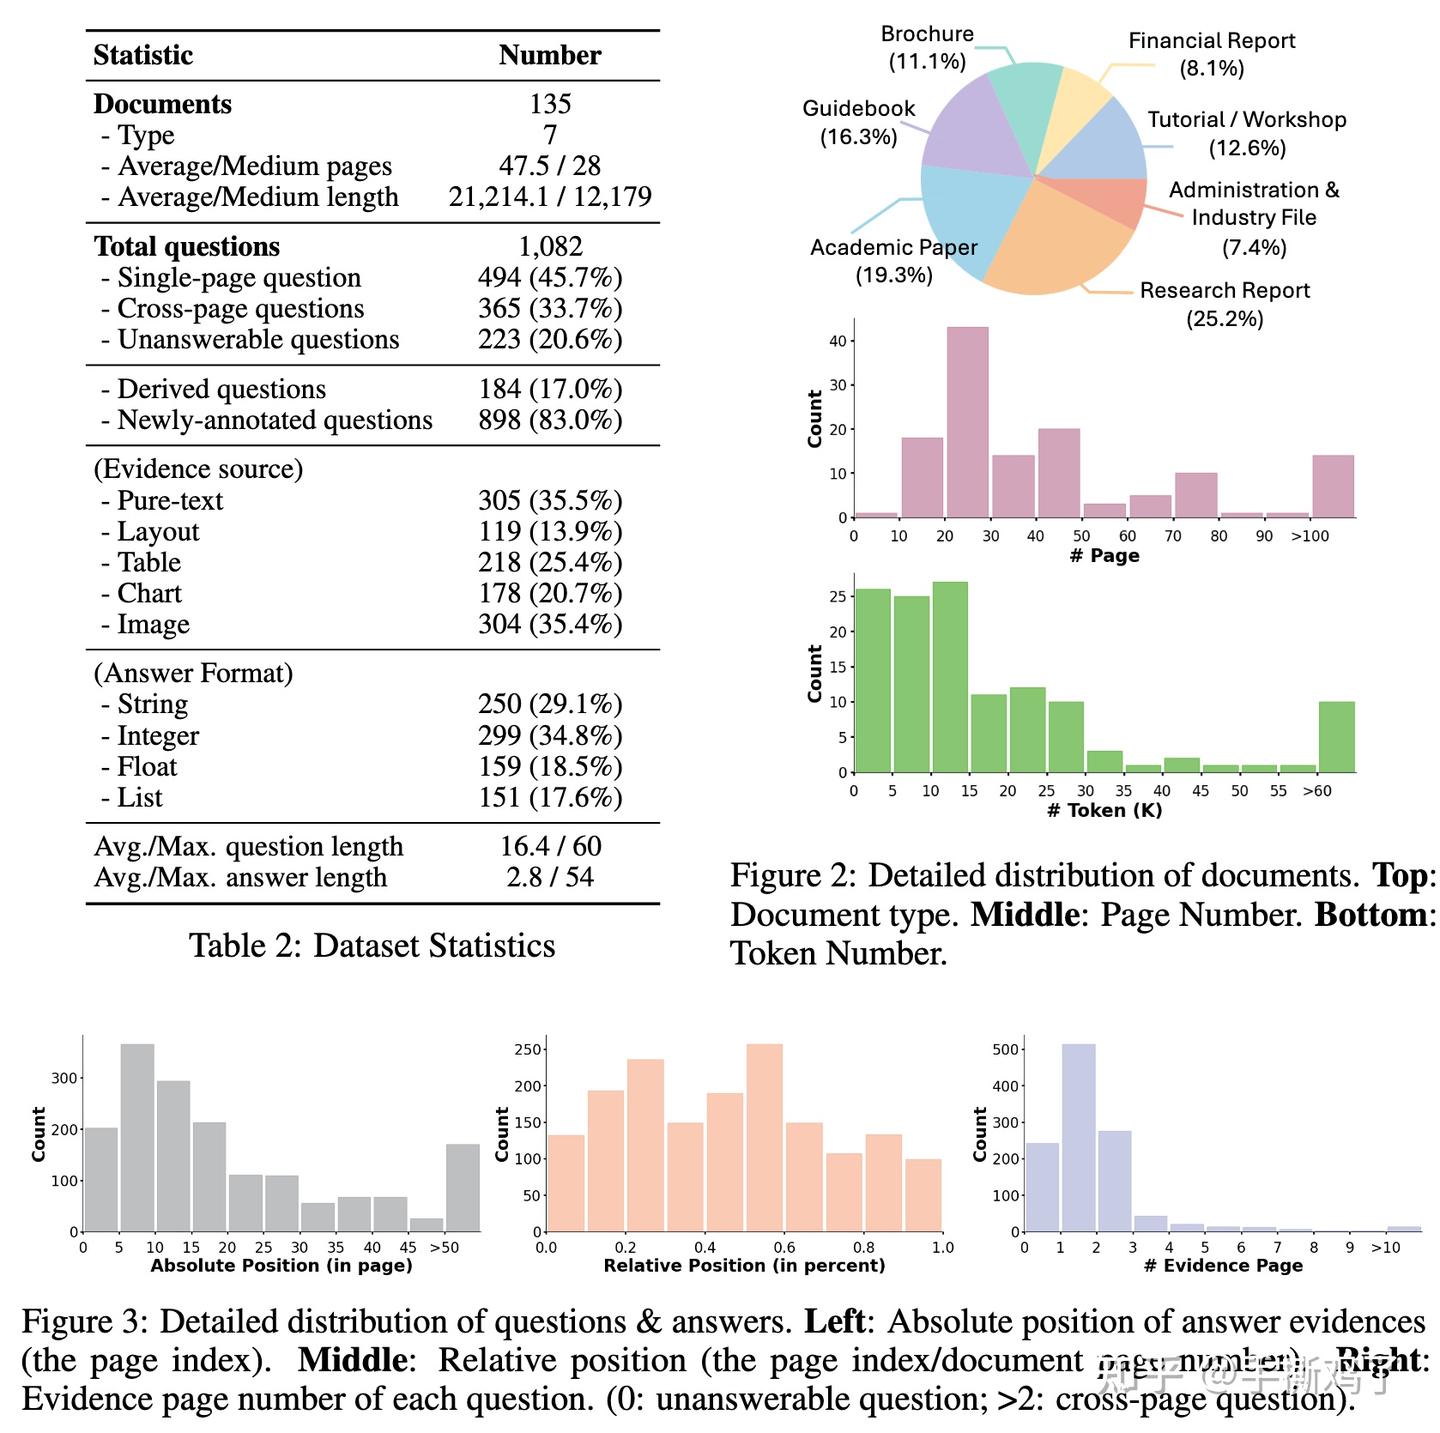
MMLongBench: Benchmarking Long-Context Vision-Language Models ...
[论文评述] Extracting Training Data from Document-Based VQA Models
InternVL: Scaling up Vision Foundation Models and Aligning for Generic ...
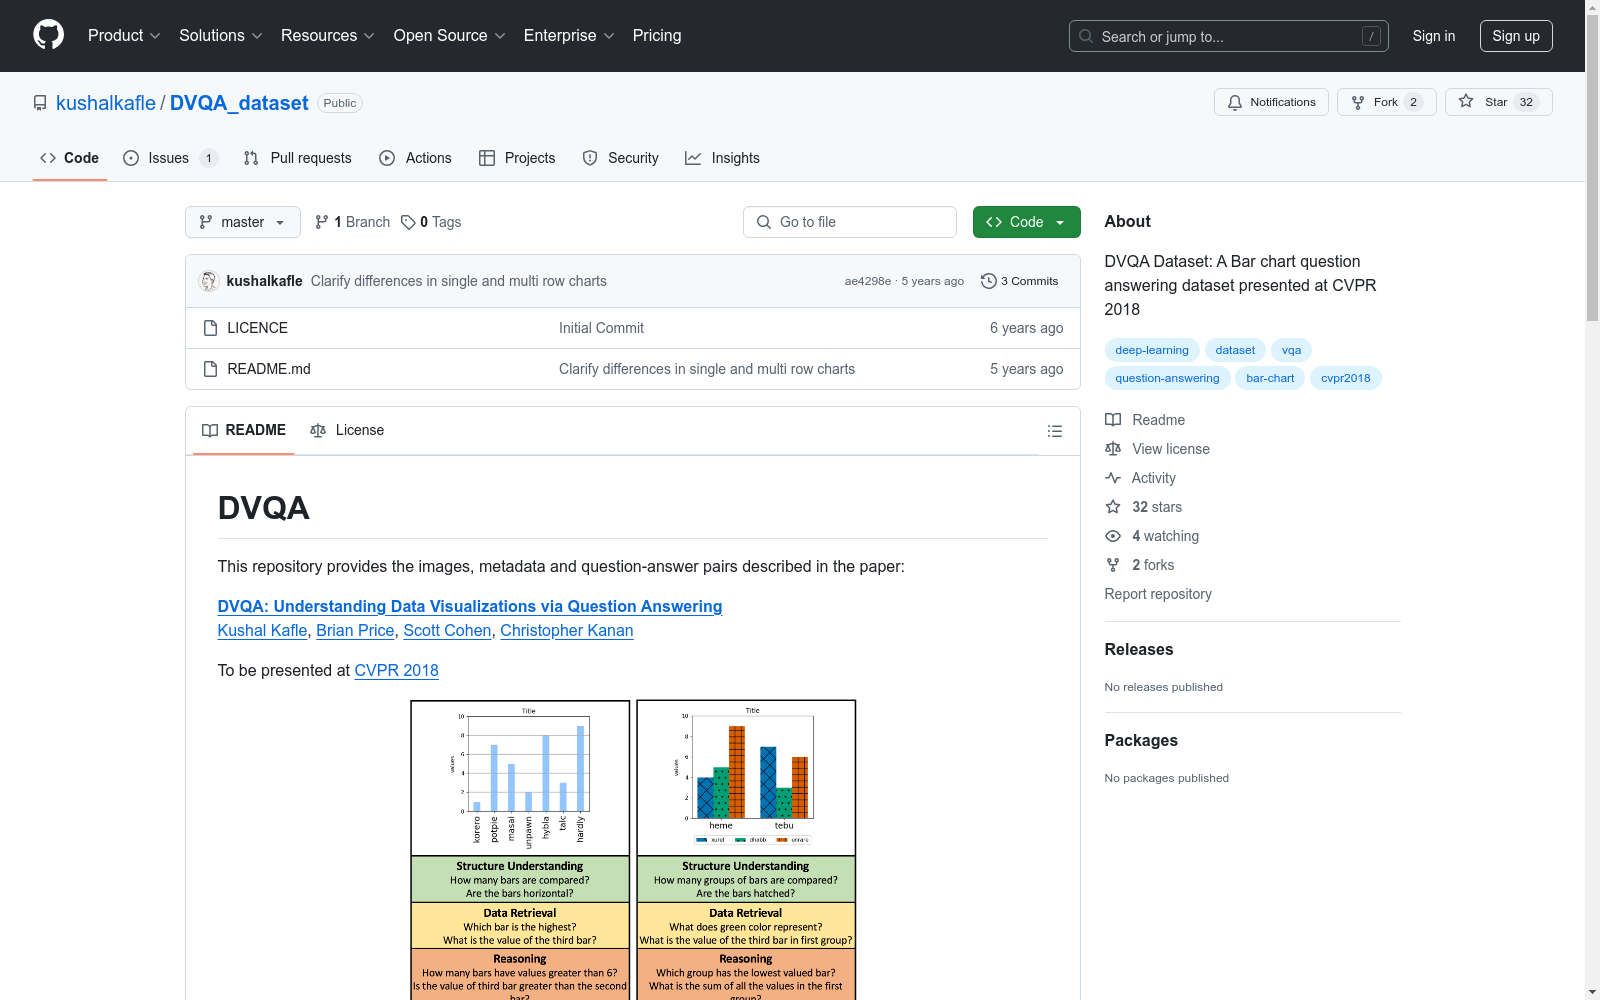
Paper page - DVQA: Understanding Data Visualizations via Question Answering
docvqa/create_dataset.py at master · anisha2102/docvqa · GitHub
[2311.07306] What Large Language Models Bring to Text-rich VQA?
Tracing Information Flow in LLaMA Vision: A Step Toward Multimodal ...
Document VQA Datasets - a pixparse Collection
Cost-Aware Model Orchestration for LLM-based Systems
StrucTexTv3:高效的文本密集图像感知与理解模型 - 知乎
vidore/docvqa_train · Datasets at Hugging Face
Taner Akdeniz on LinkedIn: Document Visual Question Answering (DocVQA ...
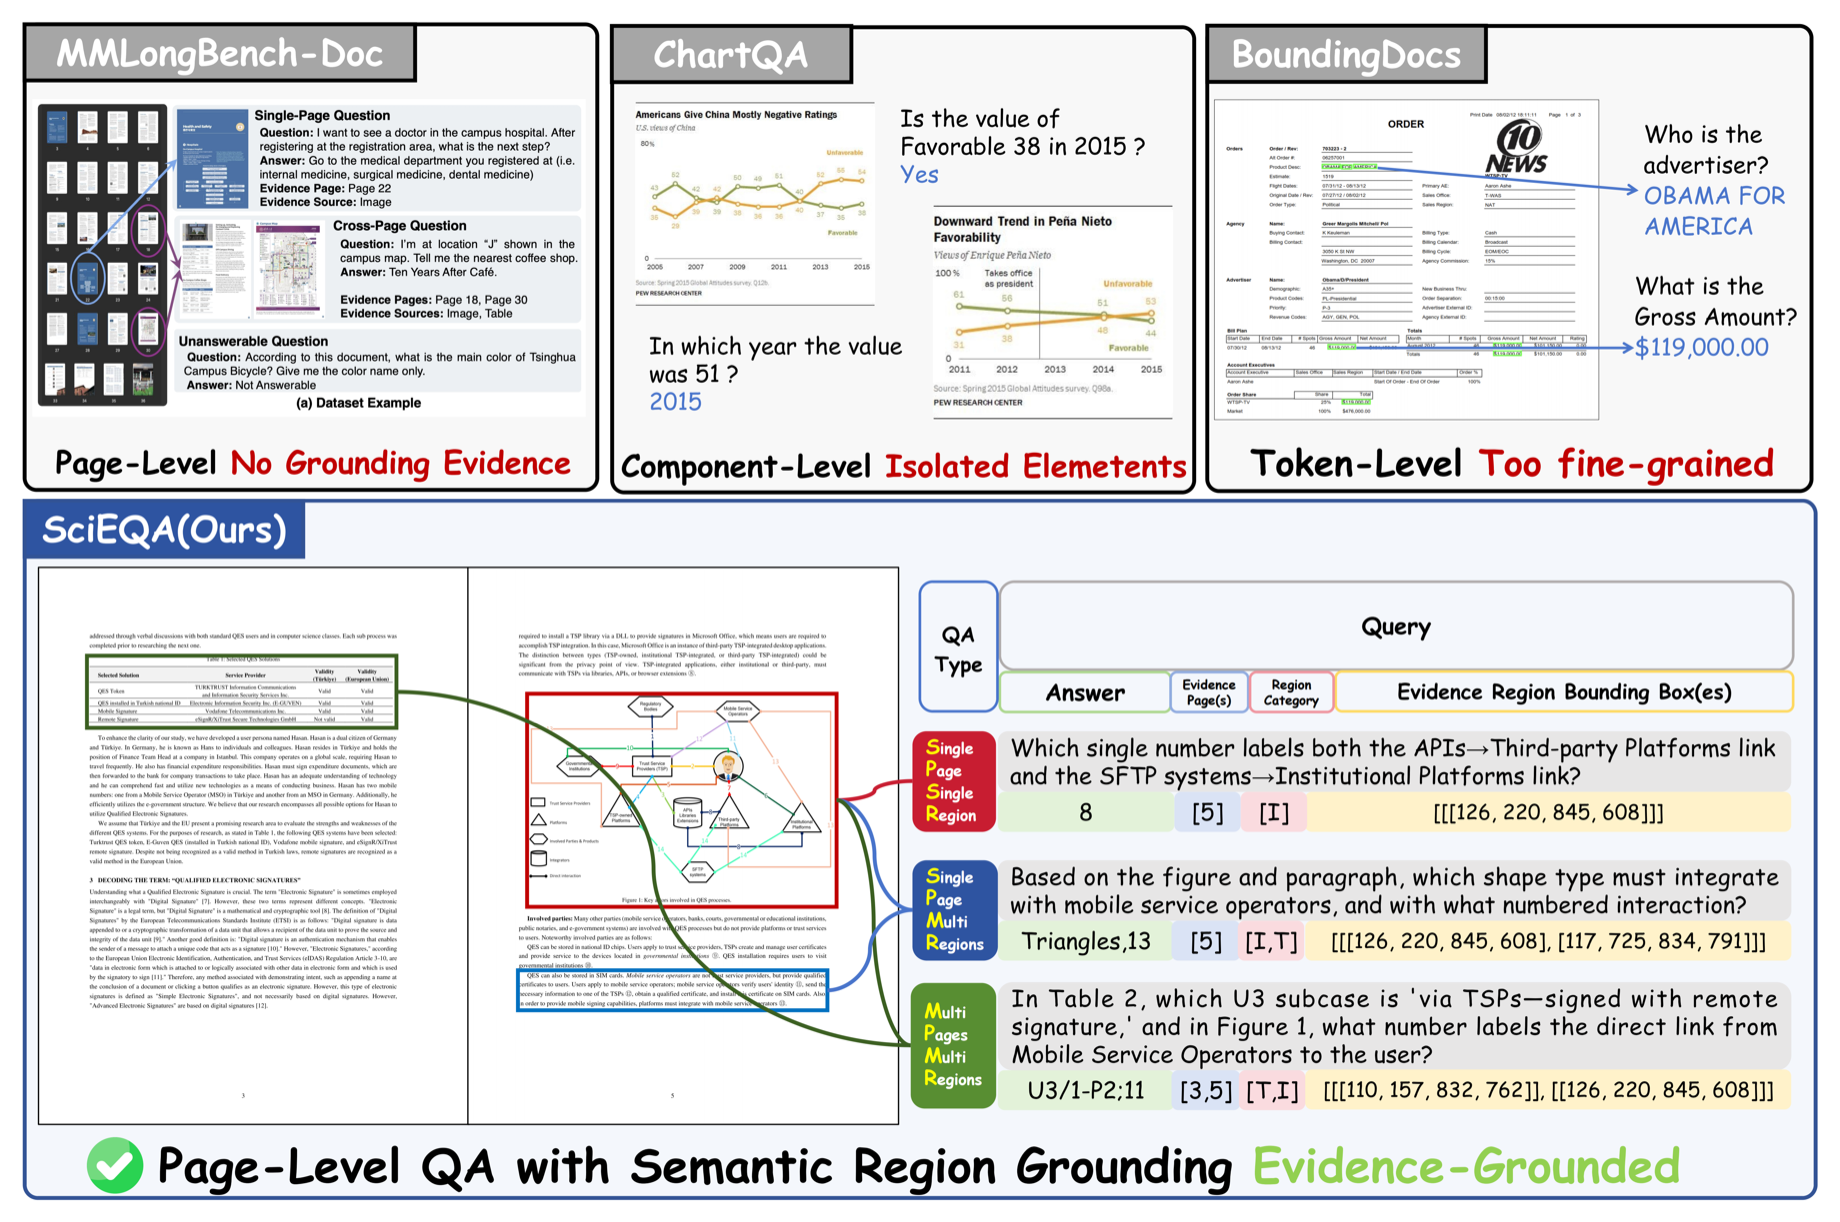
SciEGQA: Visual Evidence-Grounded QA on Scientific Documents
开启智能时代:深度解析智能文档分析技术的前沿与应用_牛客网
llamastack/docVQA · Datasets at Hugging Face
mosshoon/docvqa-1k · Datasets at Hugging Face
donut-base-finetuned-docvqa: Image-to-Text model — overview, use cases ...
A Status Check on Current Vision-Language Models in Text Recognition ...
EliMC/DocVQA · Datasets at Hugging Face
文档智能SOTA被刷爆,DocVQA榜单首次突破90大关-CSDN博客
OpenBMB 发布 VisRAG-Ret-Test-MP-DocVQA 数据集, 应用在 视觉问答、工业文档 领域
SalmanFaroz/idefics2-8b-DocVQA-SP · Hugging Face
ananoymous/MP-DocVQA · Datasets at Hugging Face
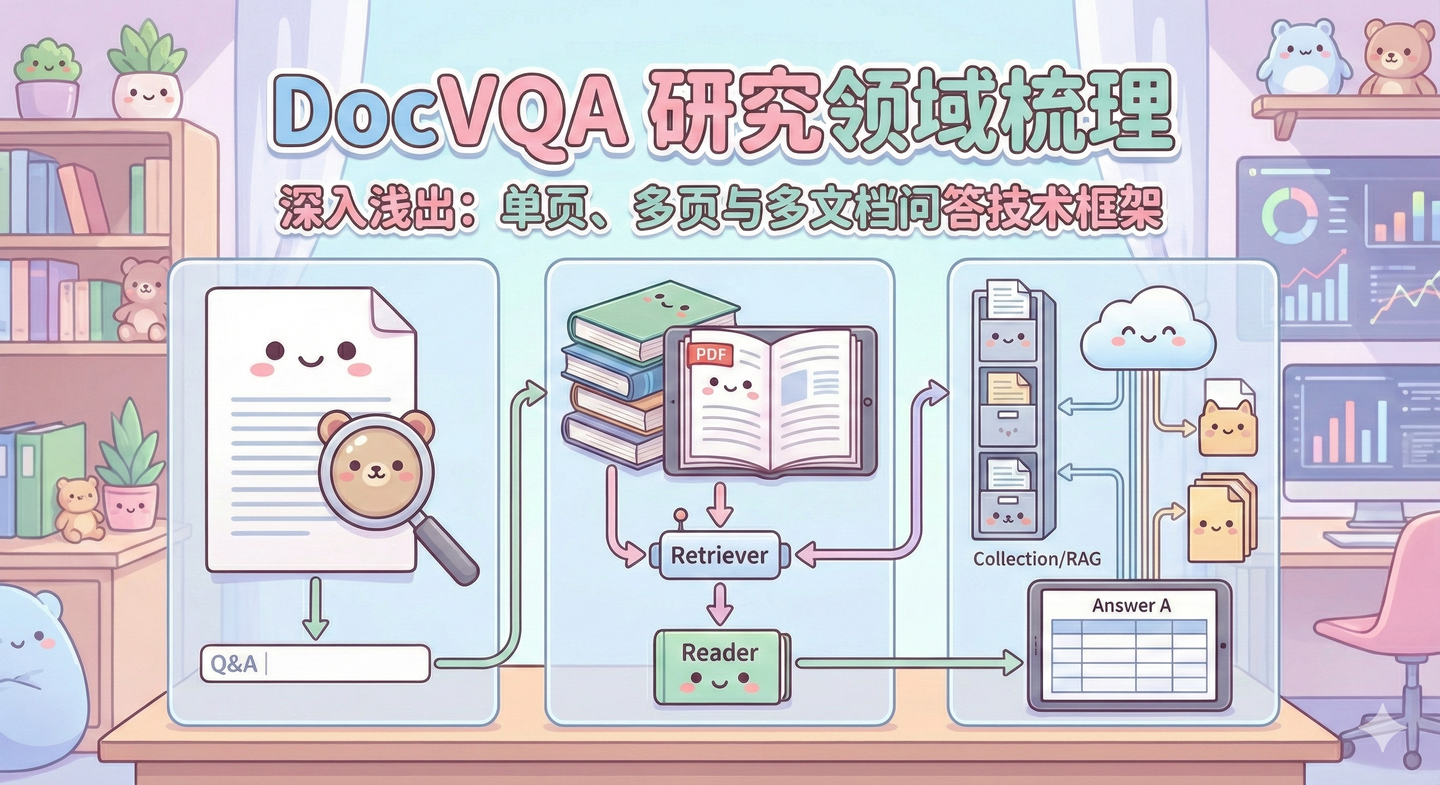
文档视觉问答(DocVQA)全景解析:从单页感知到海量多模态检索推理的研究报告 - 知乎
yizaochen/docvqa_validation · Datasets at Hugging Face
DVQA|数据可视化数据集|问答系统数据集
(a) Existing layout-aware multimodal pre-training methods align ...
rweics5cs7/VisRAG-Ret-Test-MP-DocVQA-enhanced-URIE · Datasets at ...
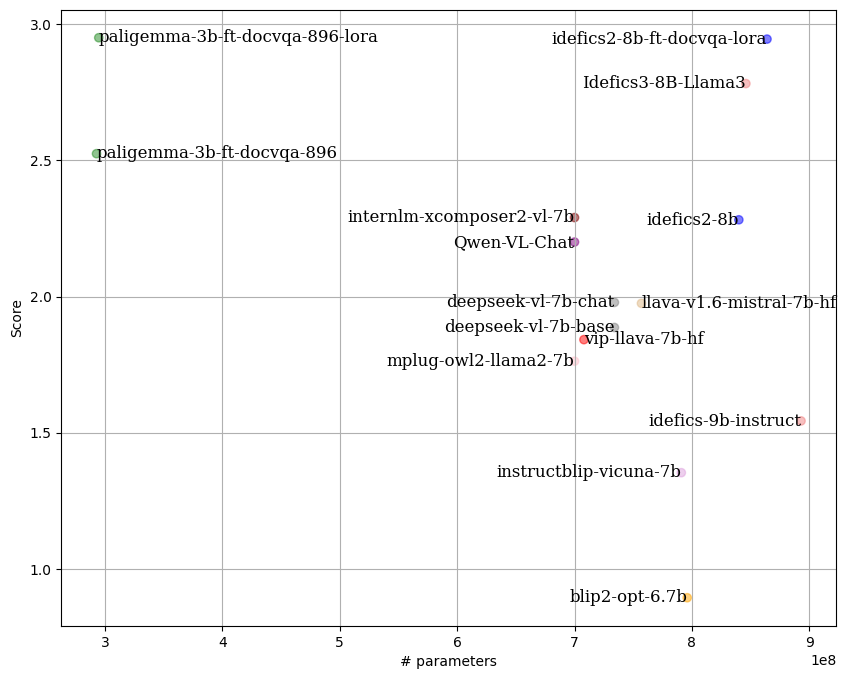
cmarkea/idefics2-8b-ft-docvqa-lora · Hugging Face
DocGraphLM:用于信息提取的文档图语言模型(二) - 知乎
Ajay Patel (@ajayp95) / Posts / X
[2502.03692] DocMIA: Document-Level Membership Inference Attacks ...
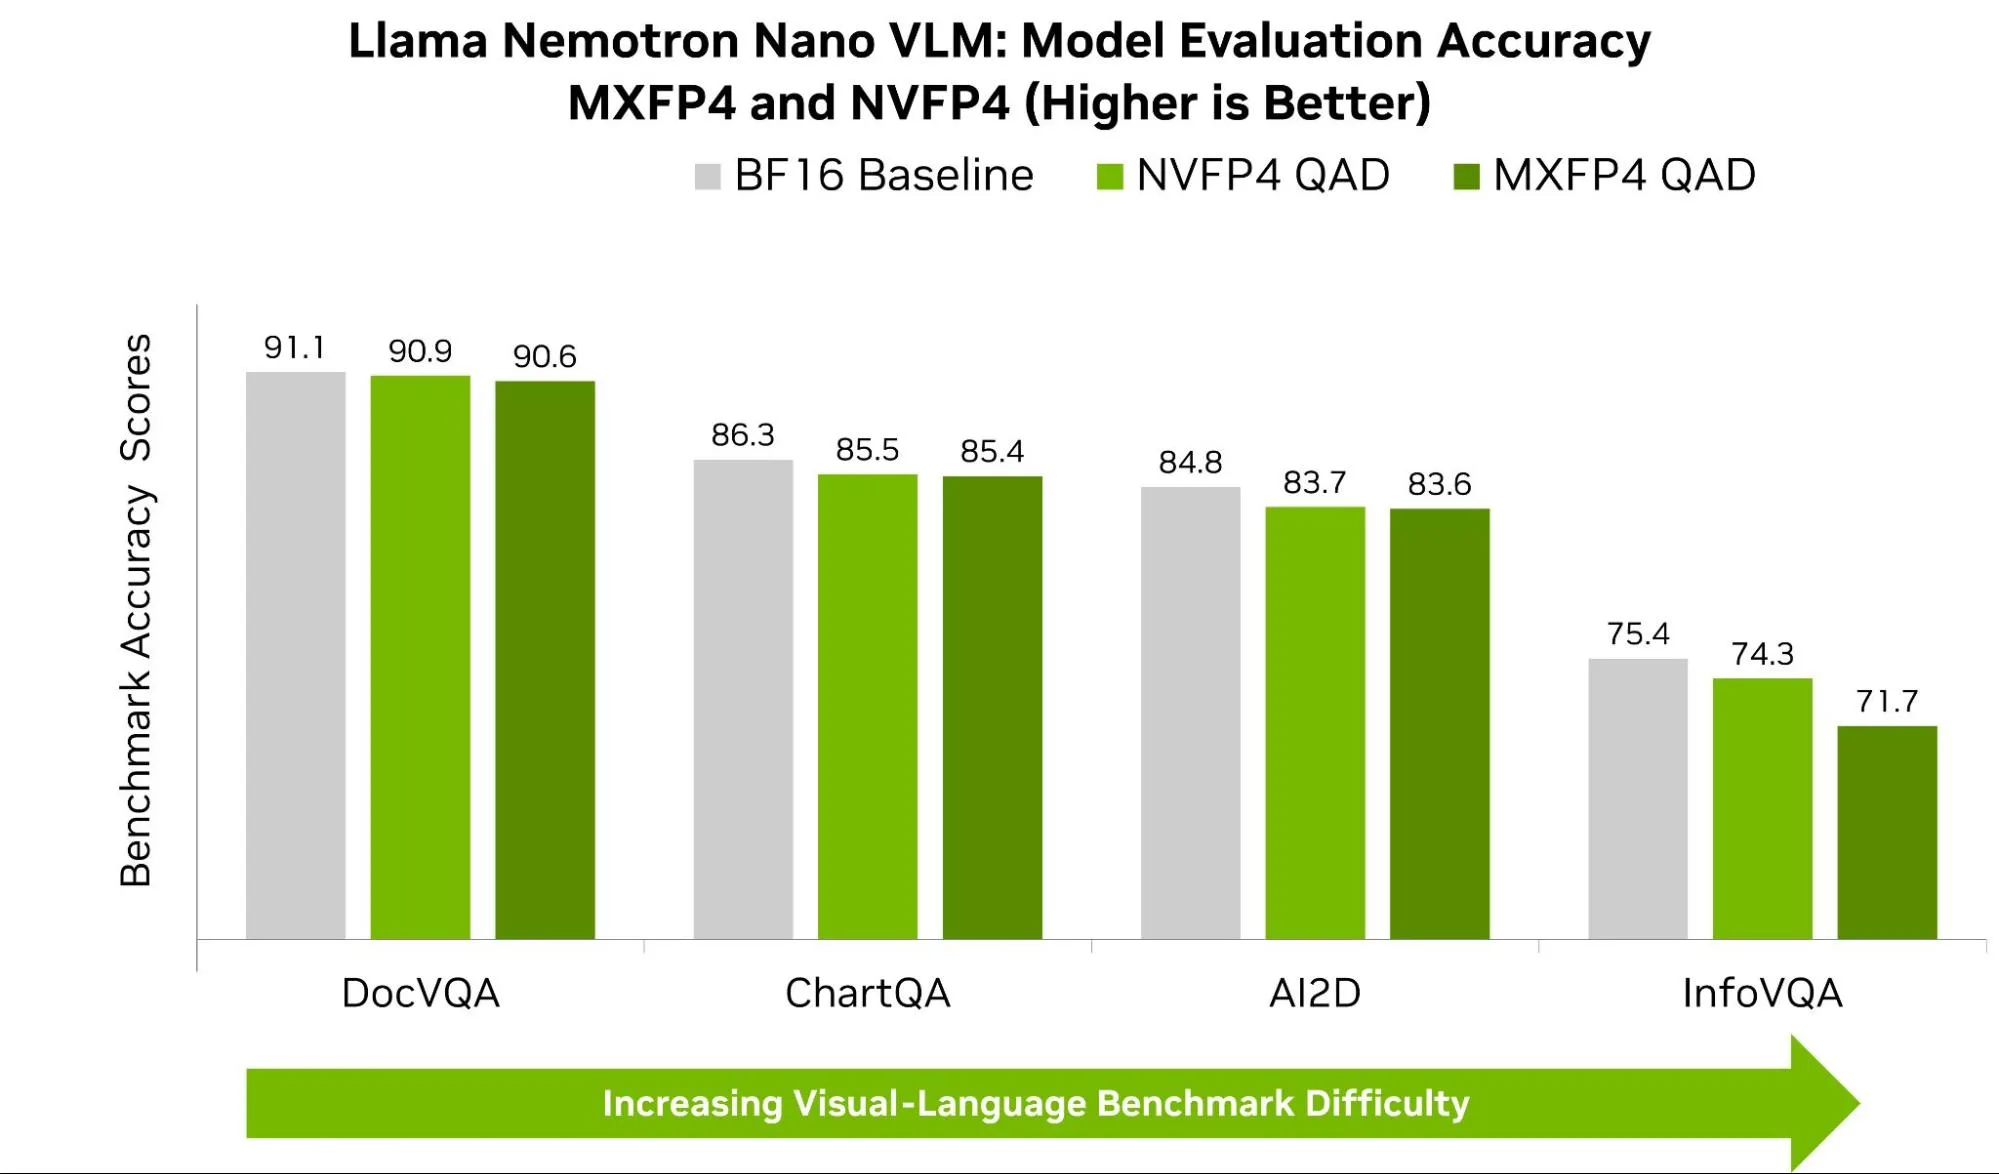
How Quantization Aware Training Enables Low-Precision Accuracy Recovery ...
Hierarchical multimodal transformers for Multi-Page DocVQA笔记 - 知乎
DocVQA学习 - 知乎
Unlock Actionable Insights from Your Most Complex Documents with ...
GitHub - rubenpt91/MP-DocVQA-Framework
[2212.09621] Wukong-Reader: Multi-modal Pre-training for Fine-grained ...
[论文] Donut: OCR-free Document Understanding Transformer - 知乎
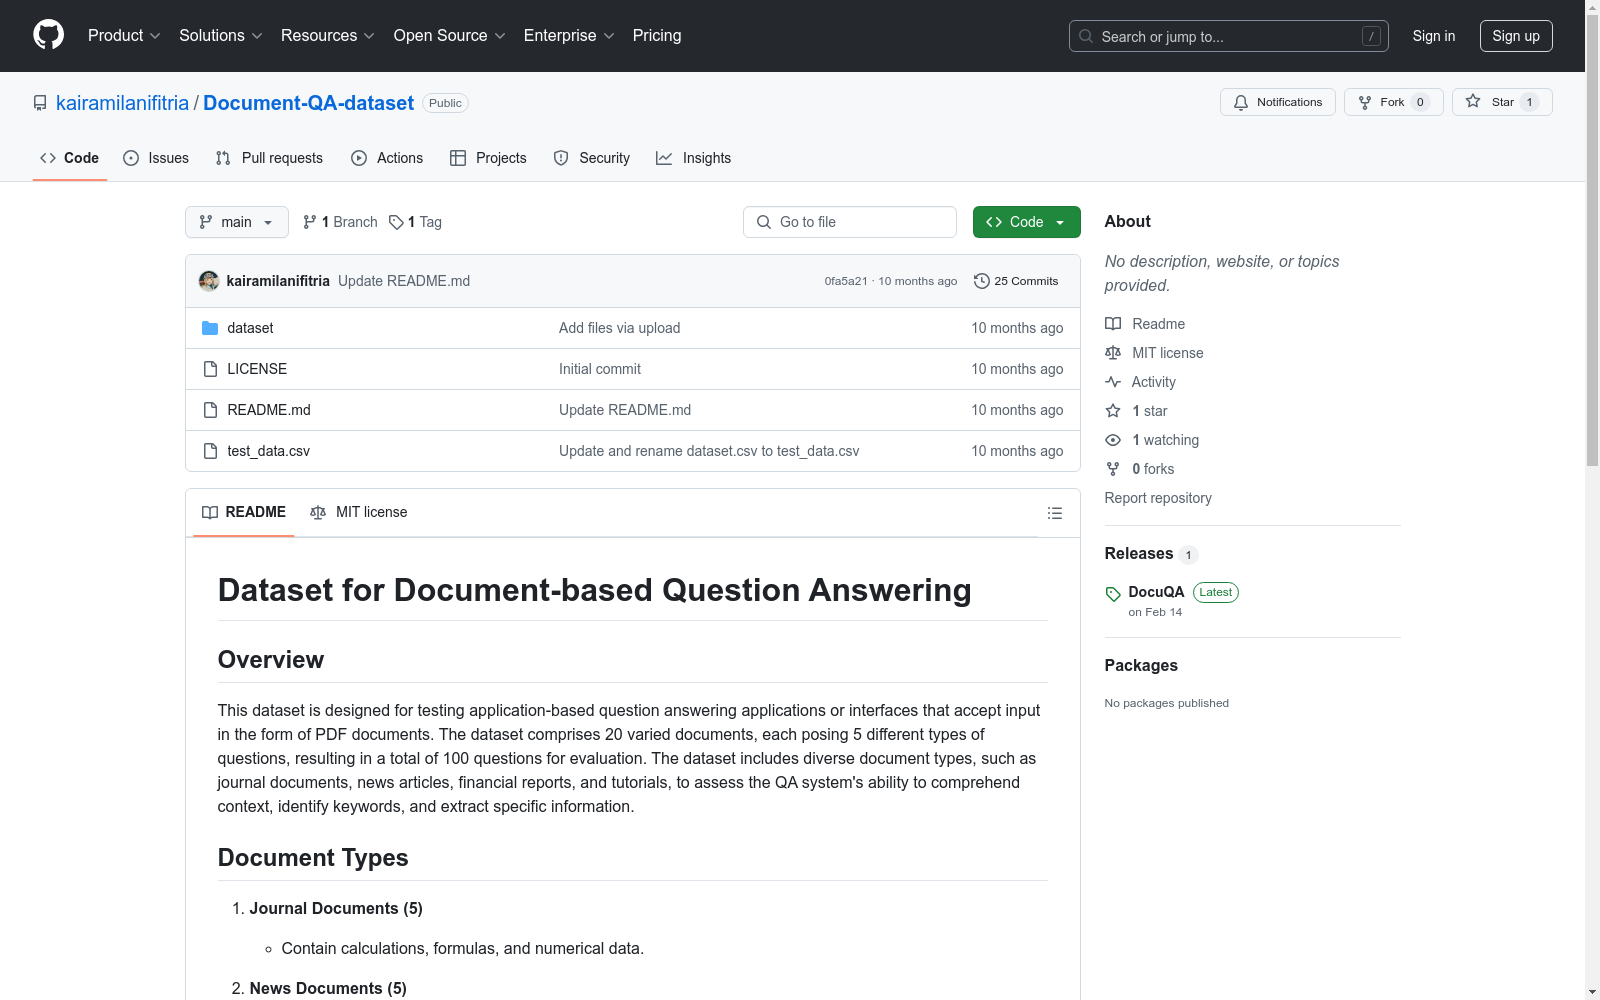
DocuQA|文档问答数据集|自然语言处理数据集