Showing 116 of 116on this page. Filters & sort apply to loaded results; URL updates for sharing.116 of 116 on this page
Quantization Aware Training. Или как правильно использовать fp16 ...
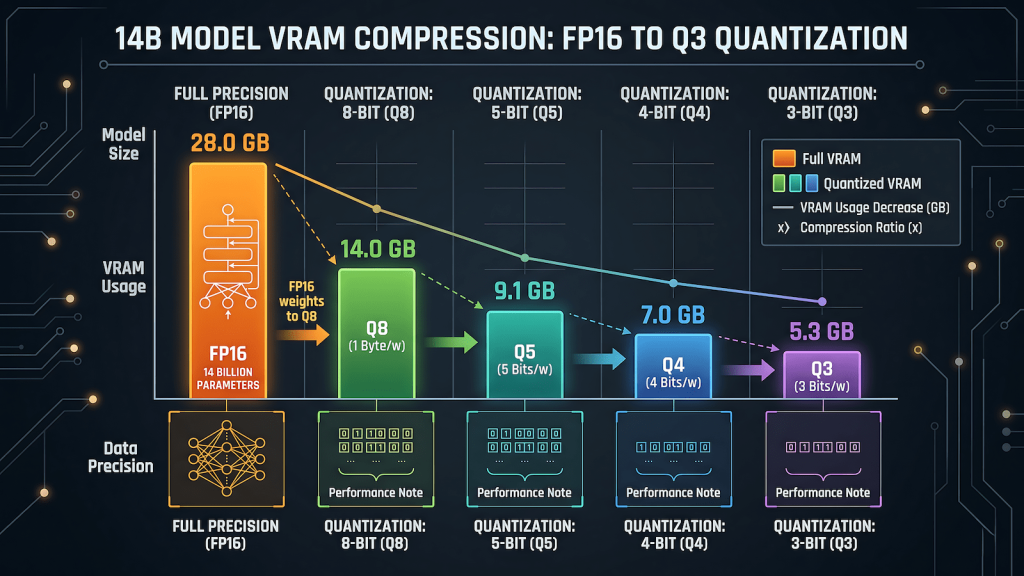
Quantization Explained: Q4 vs Q8 vs FP16 — What You Actually Lose ...
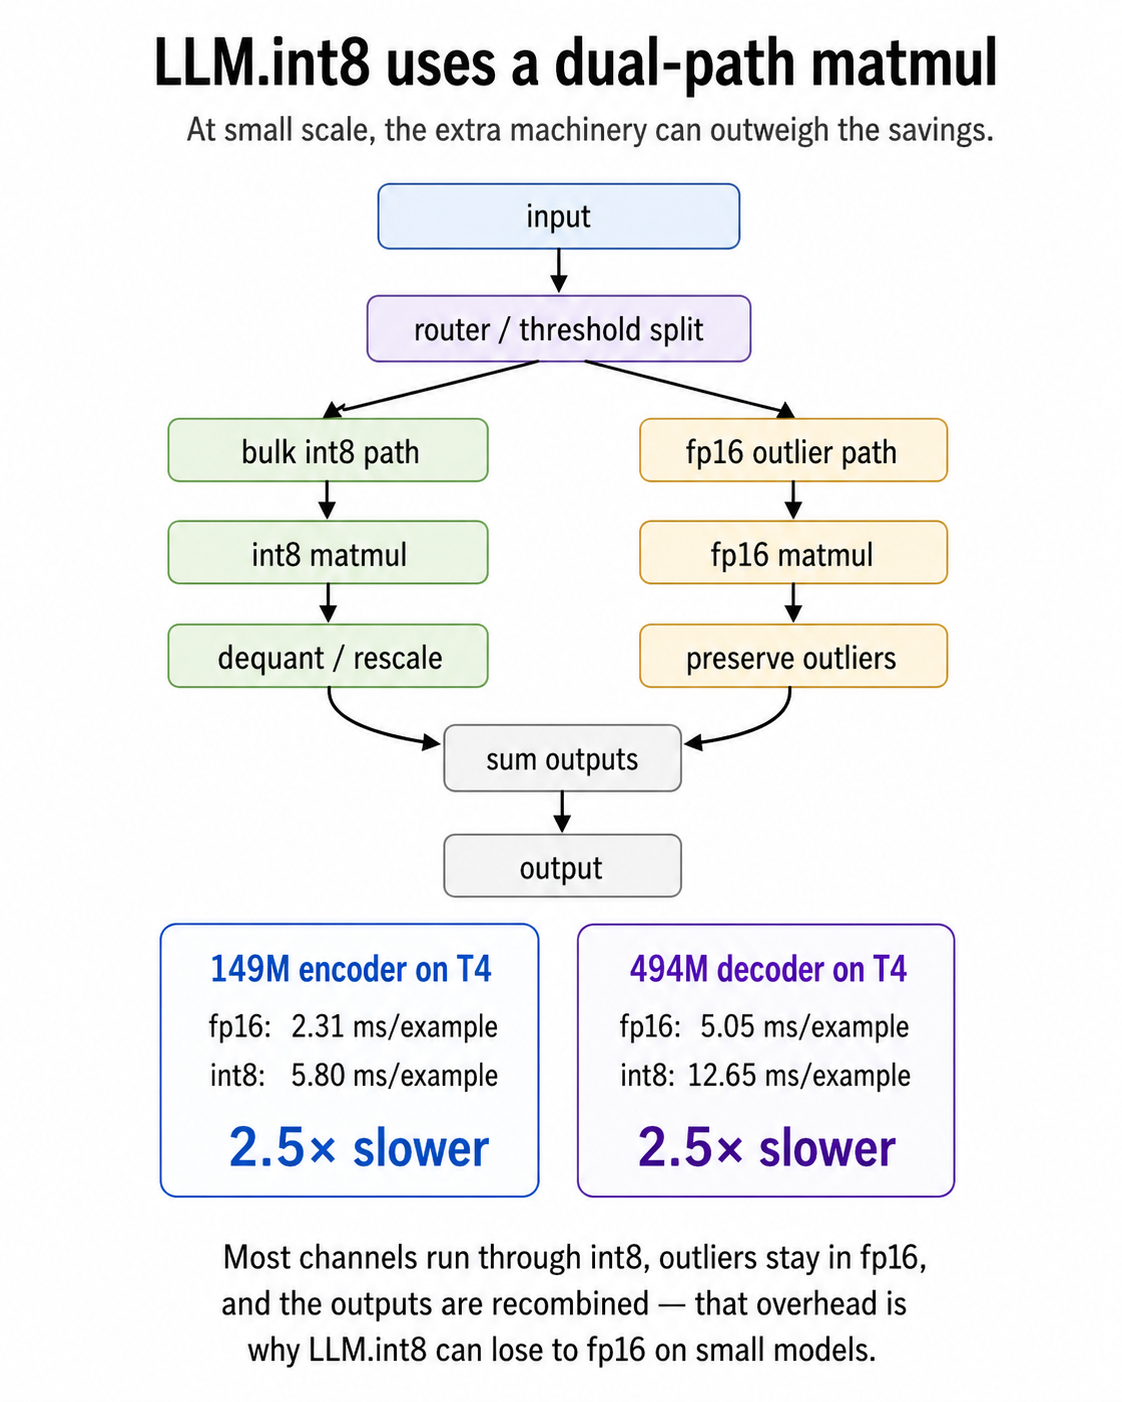
Your int8 Quantization Is 2.5× Slower Than fp16 | Applied Deep Learning
PyTorch to Torchscript with FP16 Quantization · Issue #9430 ...
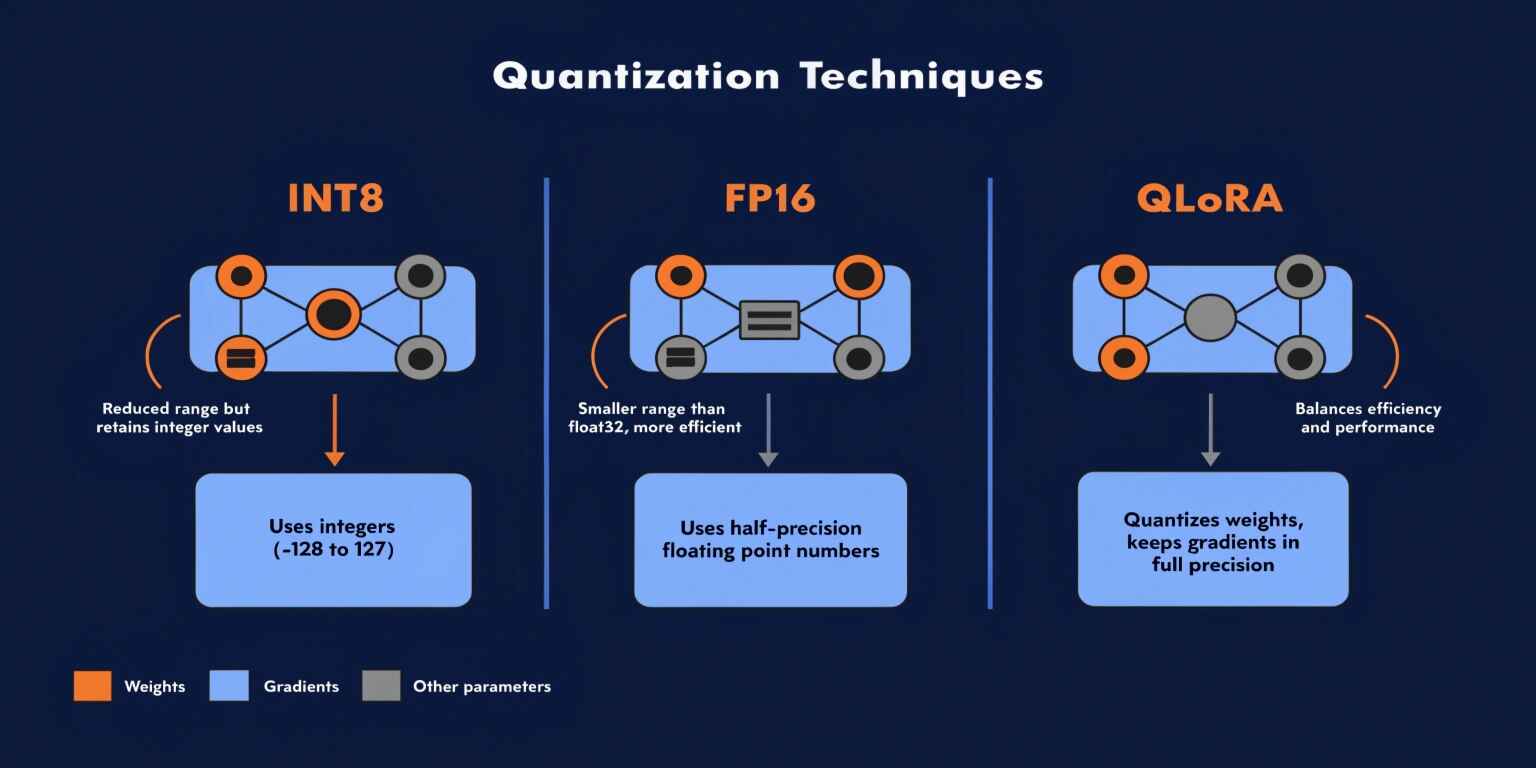
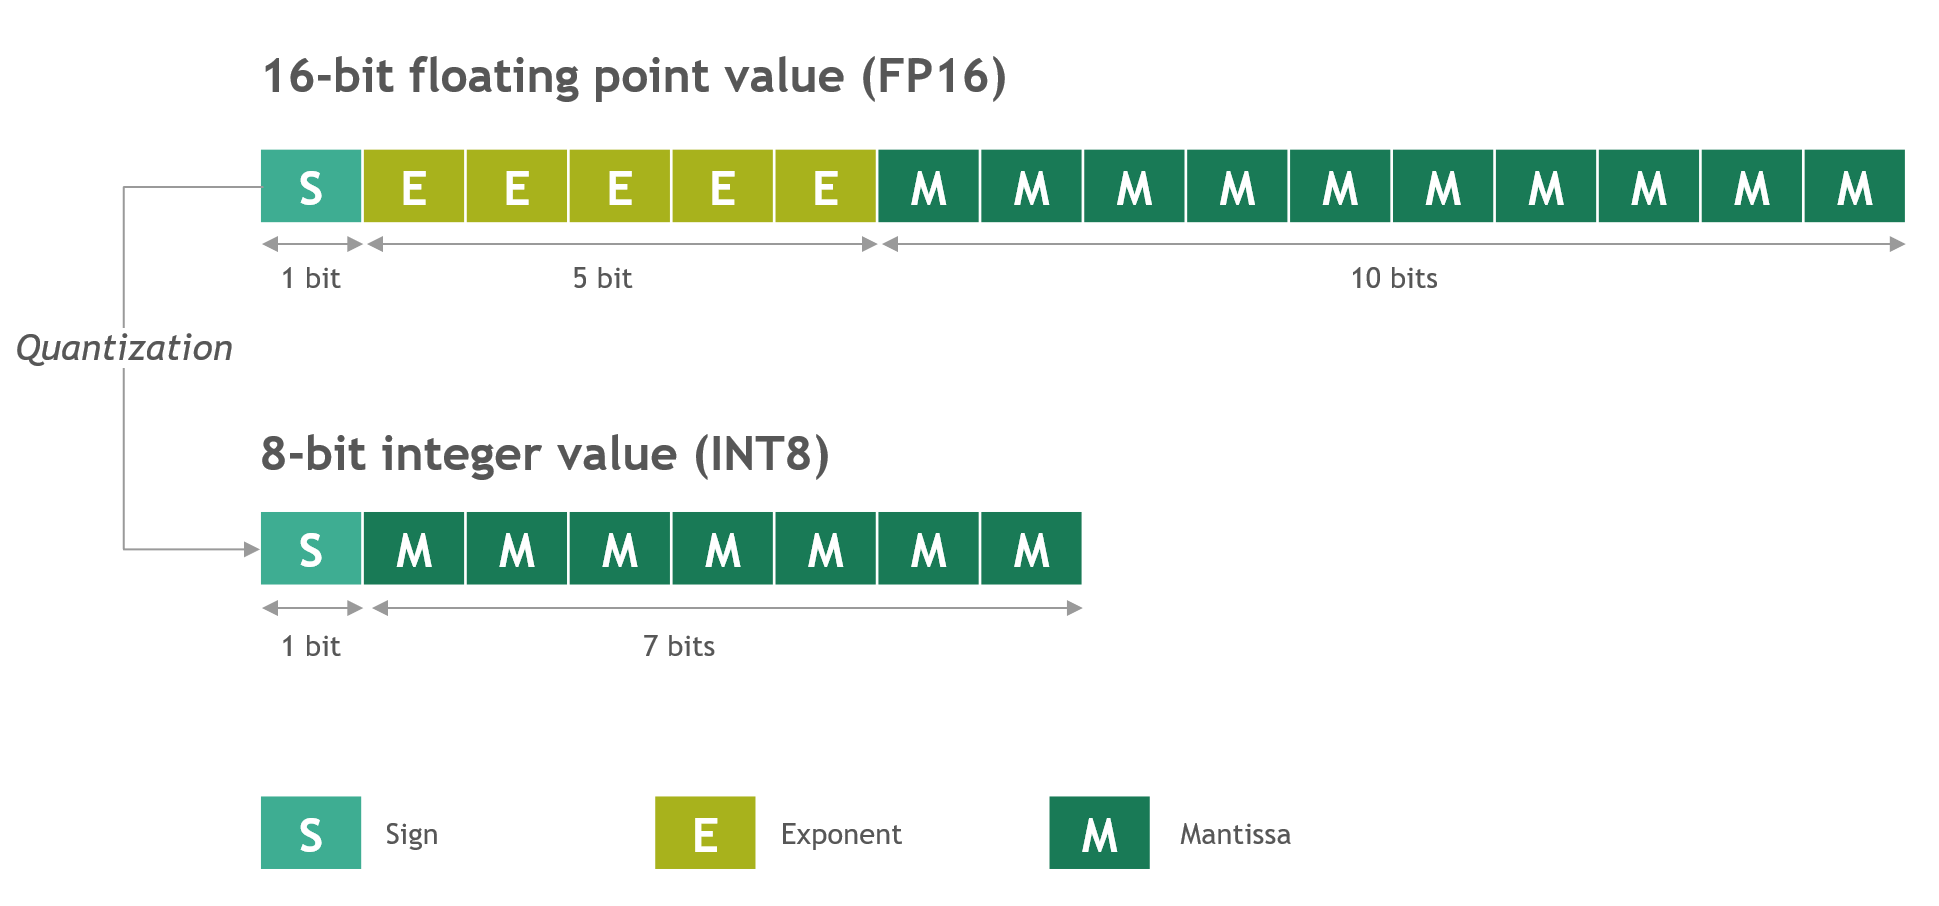
INT8 vs FP16 vs QLoRA: Modern AI Quantization Techniques Explained
Quantization FP16 model using pytorch_quantization and TensorRT · Issue ...
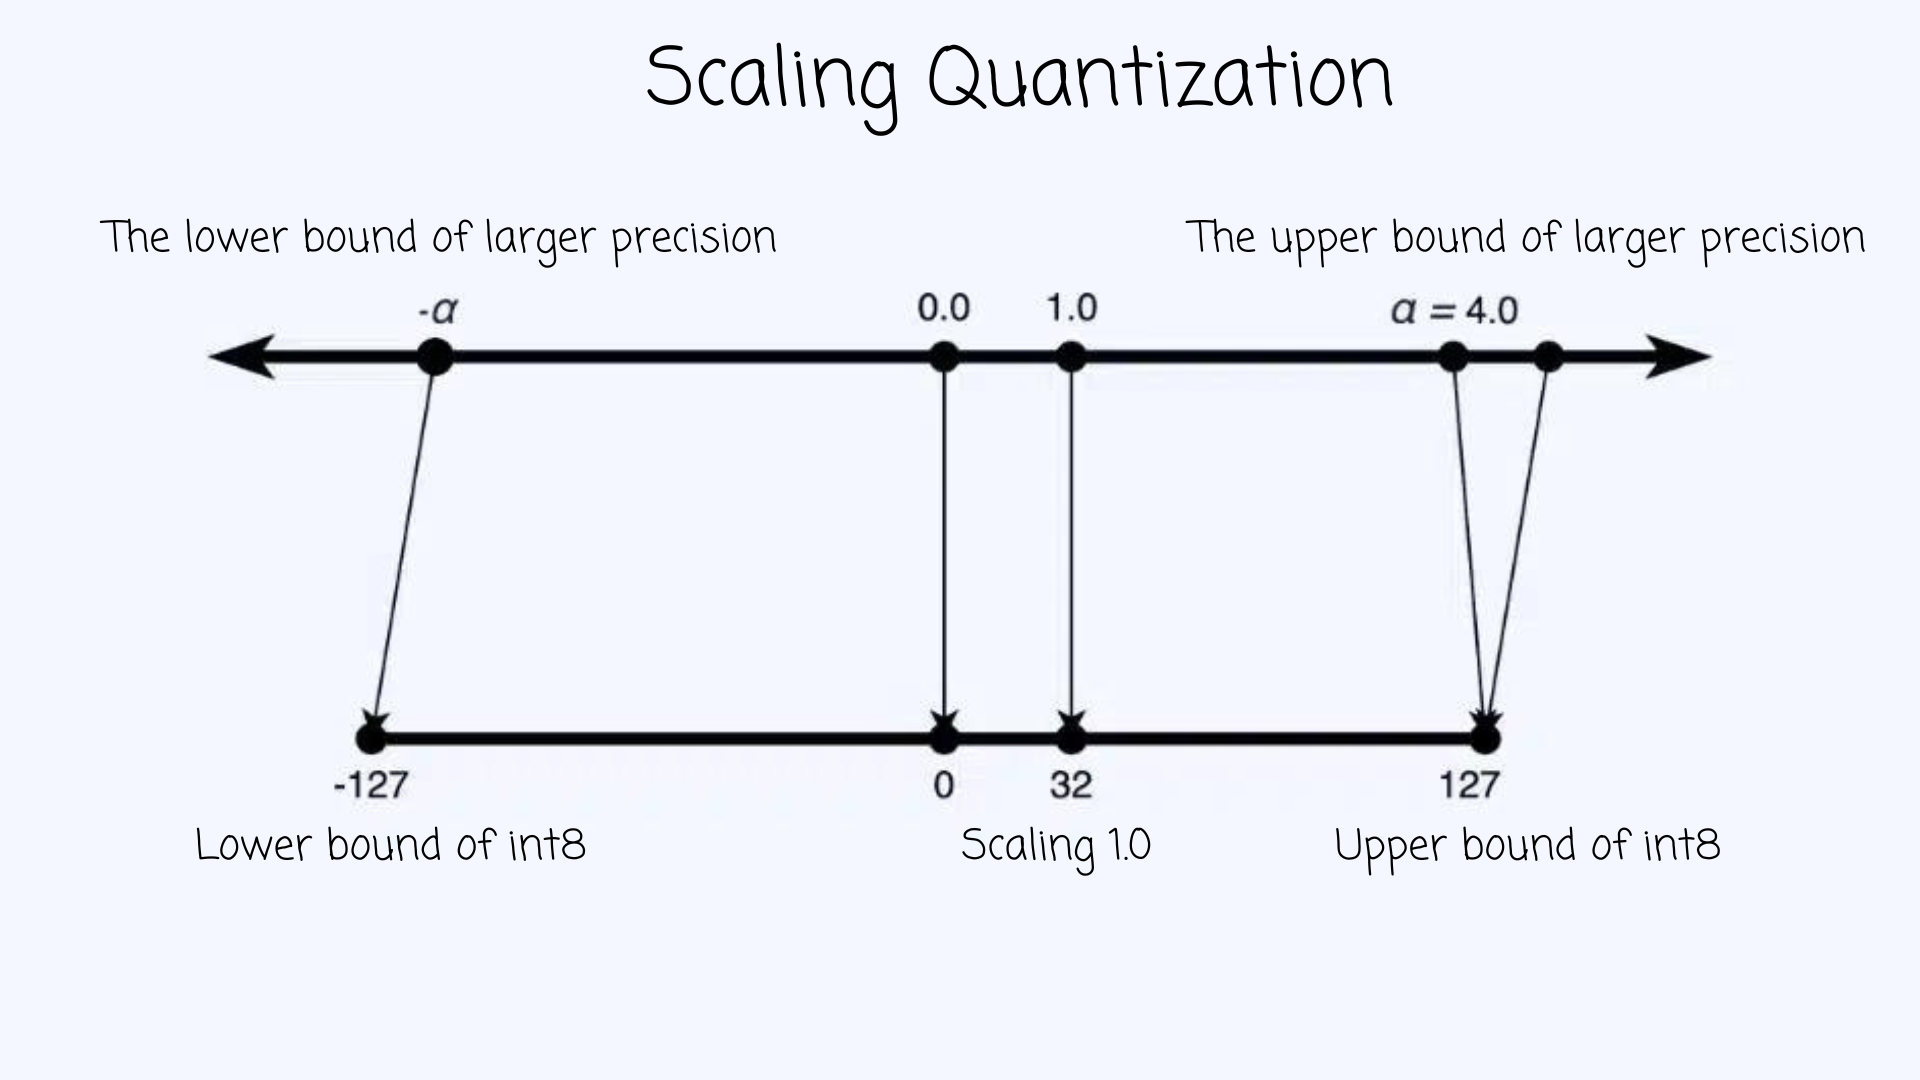
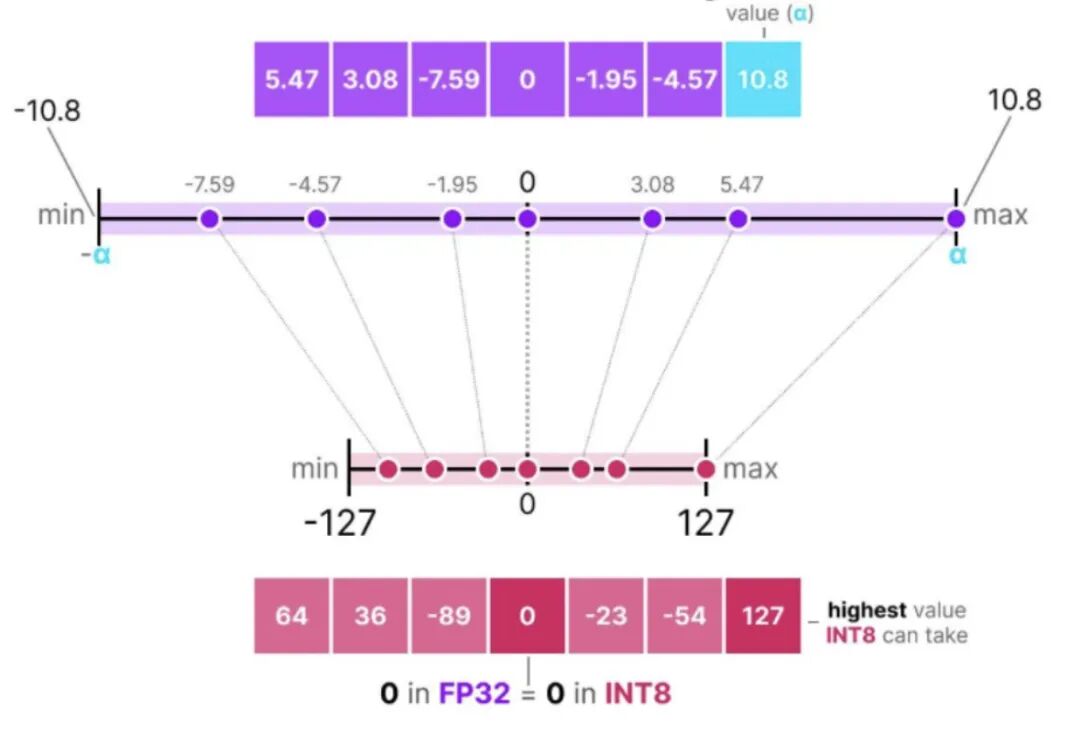
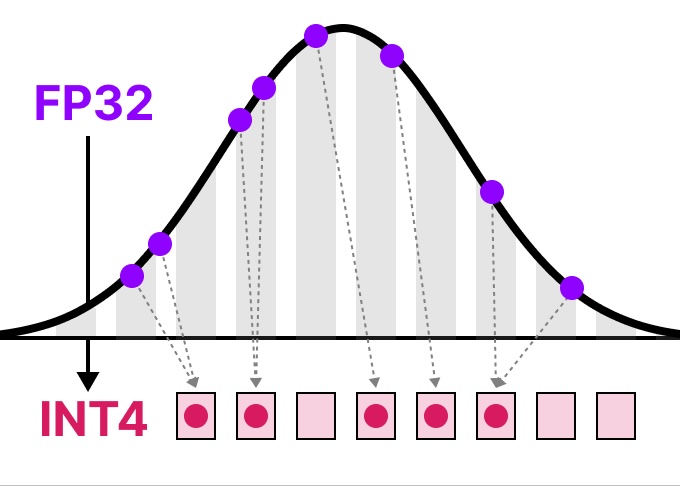
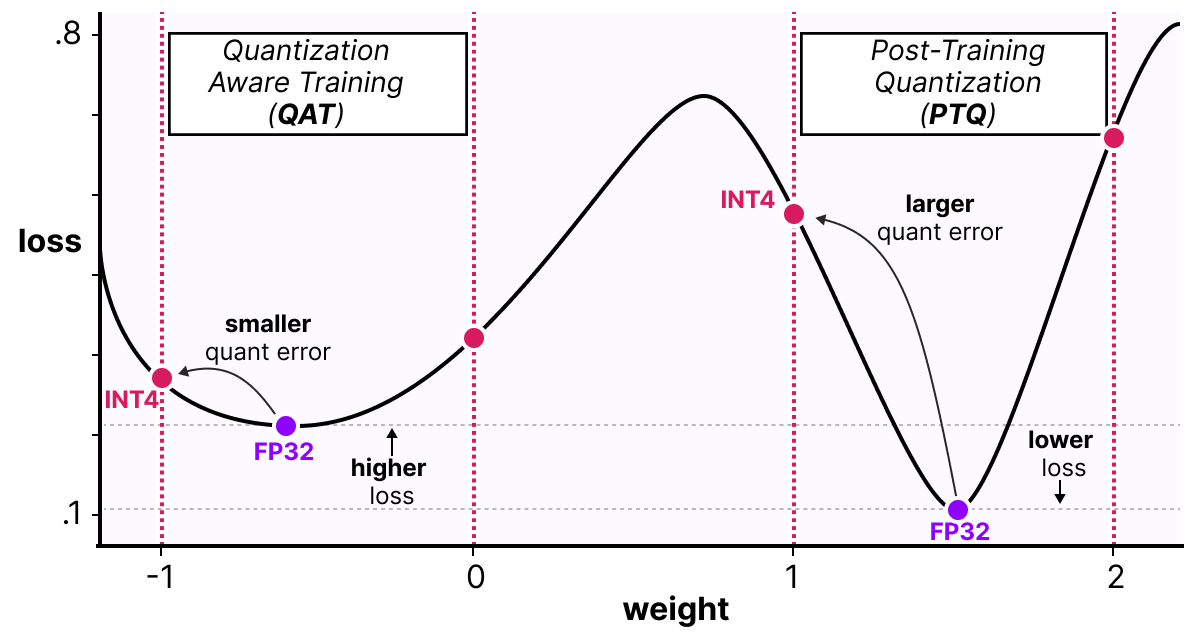
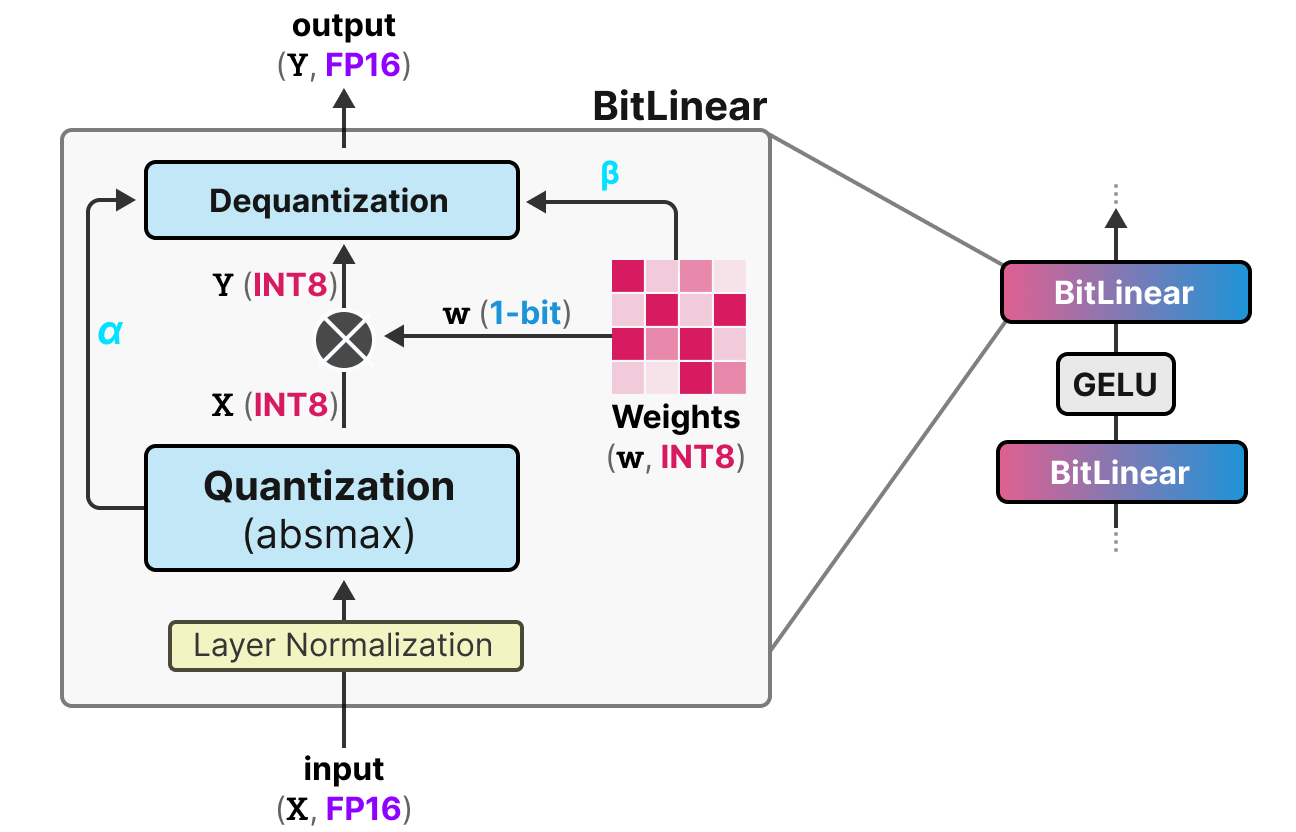
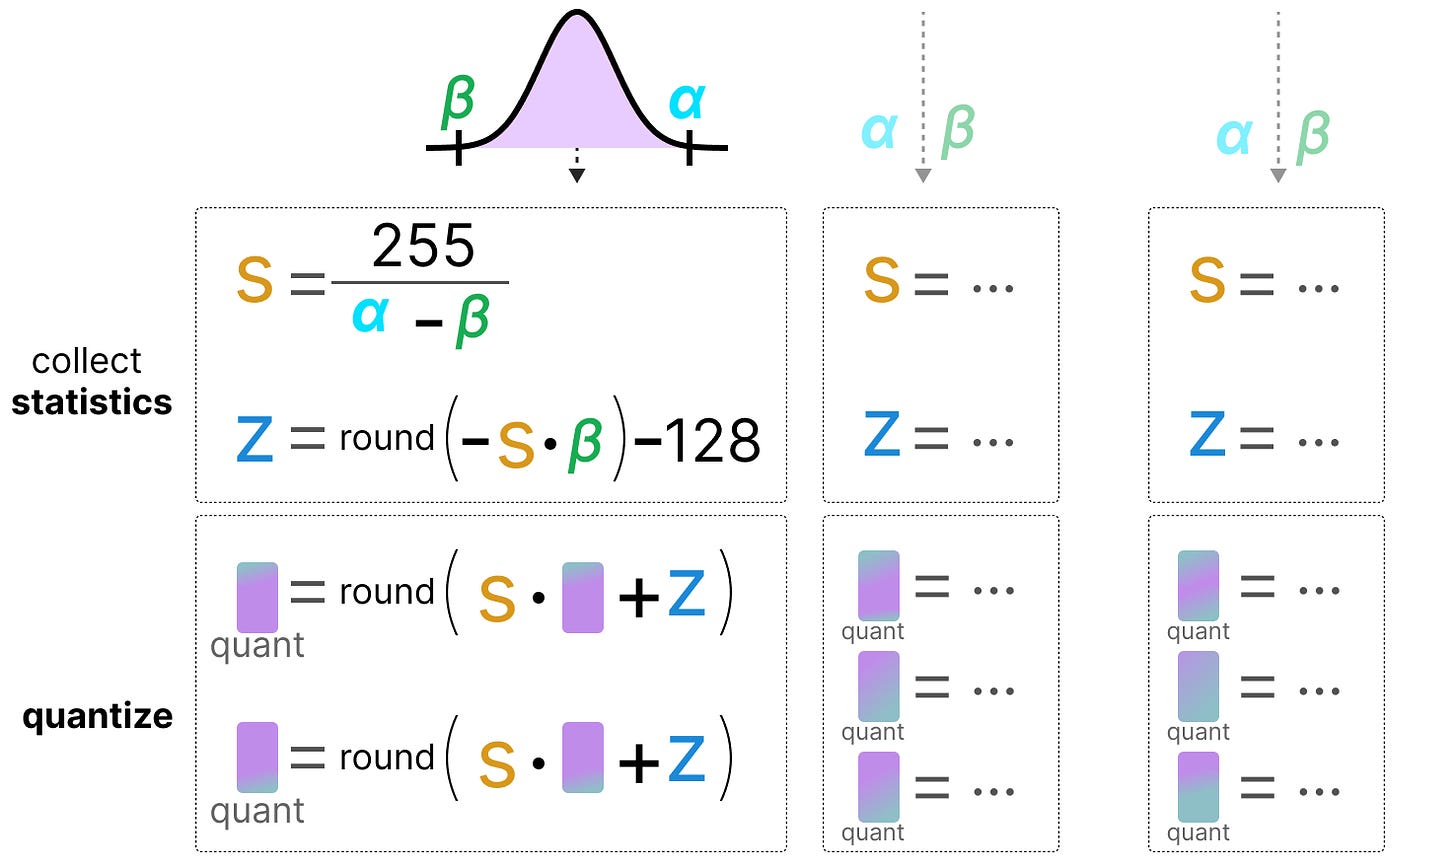
A Visual Guide to Quantization - Maarten Grootendorst
A Hands-On Walkthrough on Model Quantization - Medoid AI
Quantization Fundamentals Study - 01 – Changjiang Cai's Blog
Key Factors in AI's Advancement: Research Papers, Quantization ...
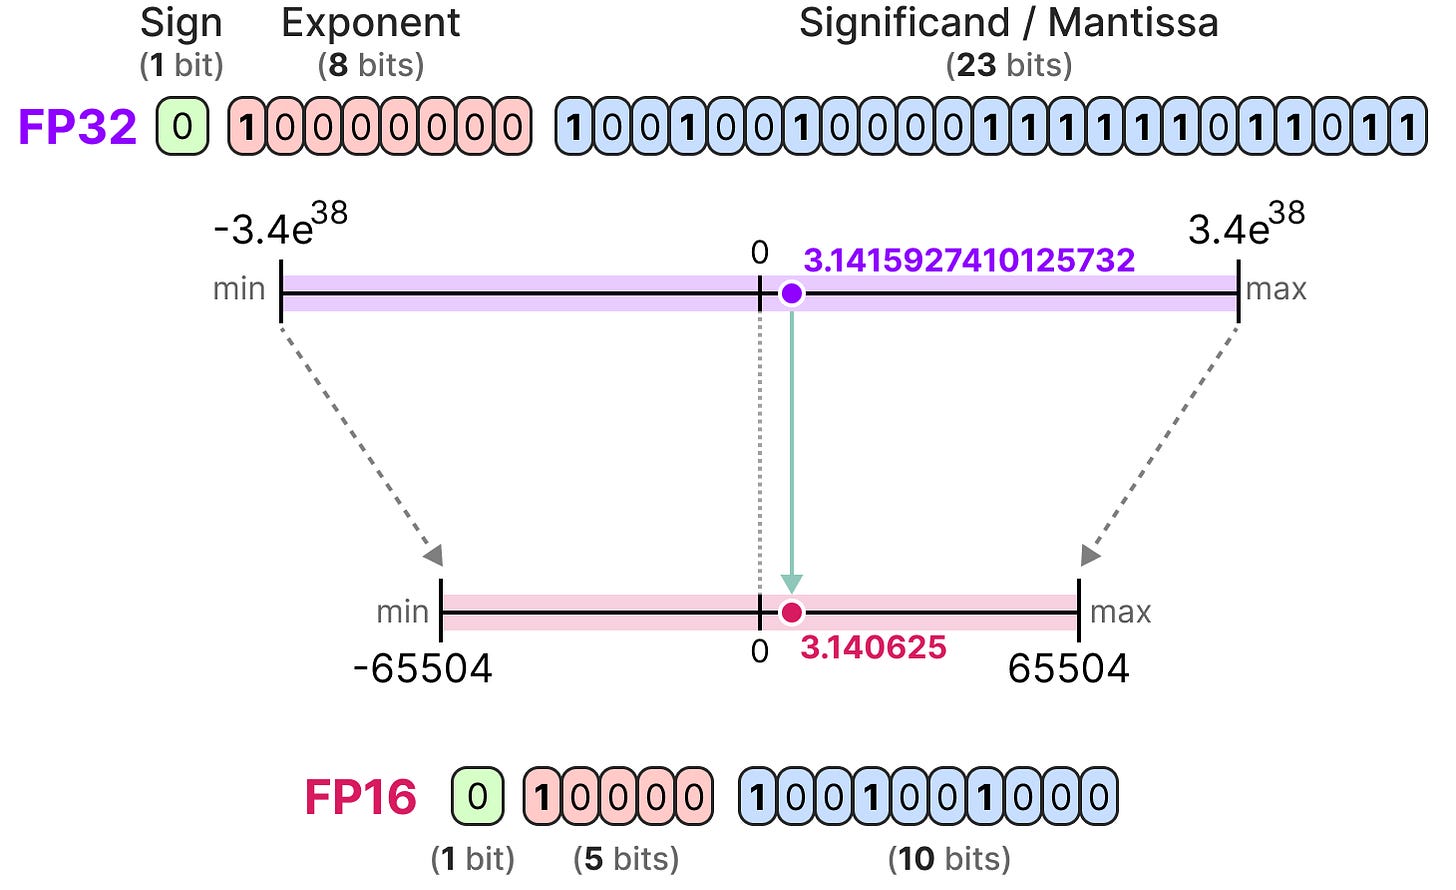
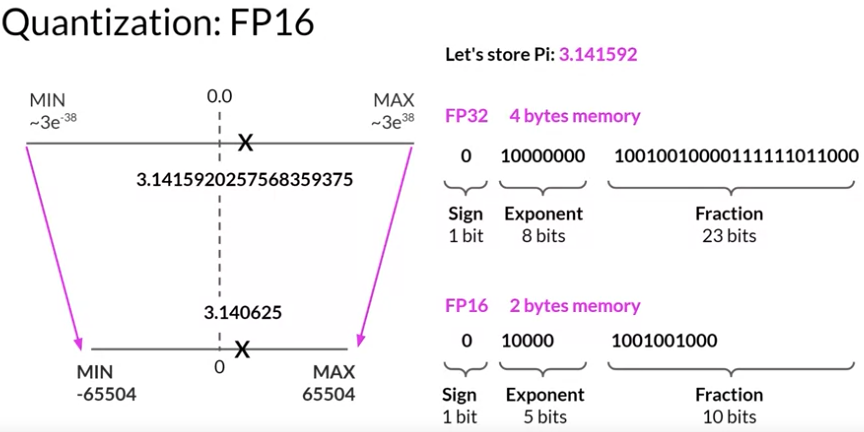
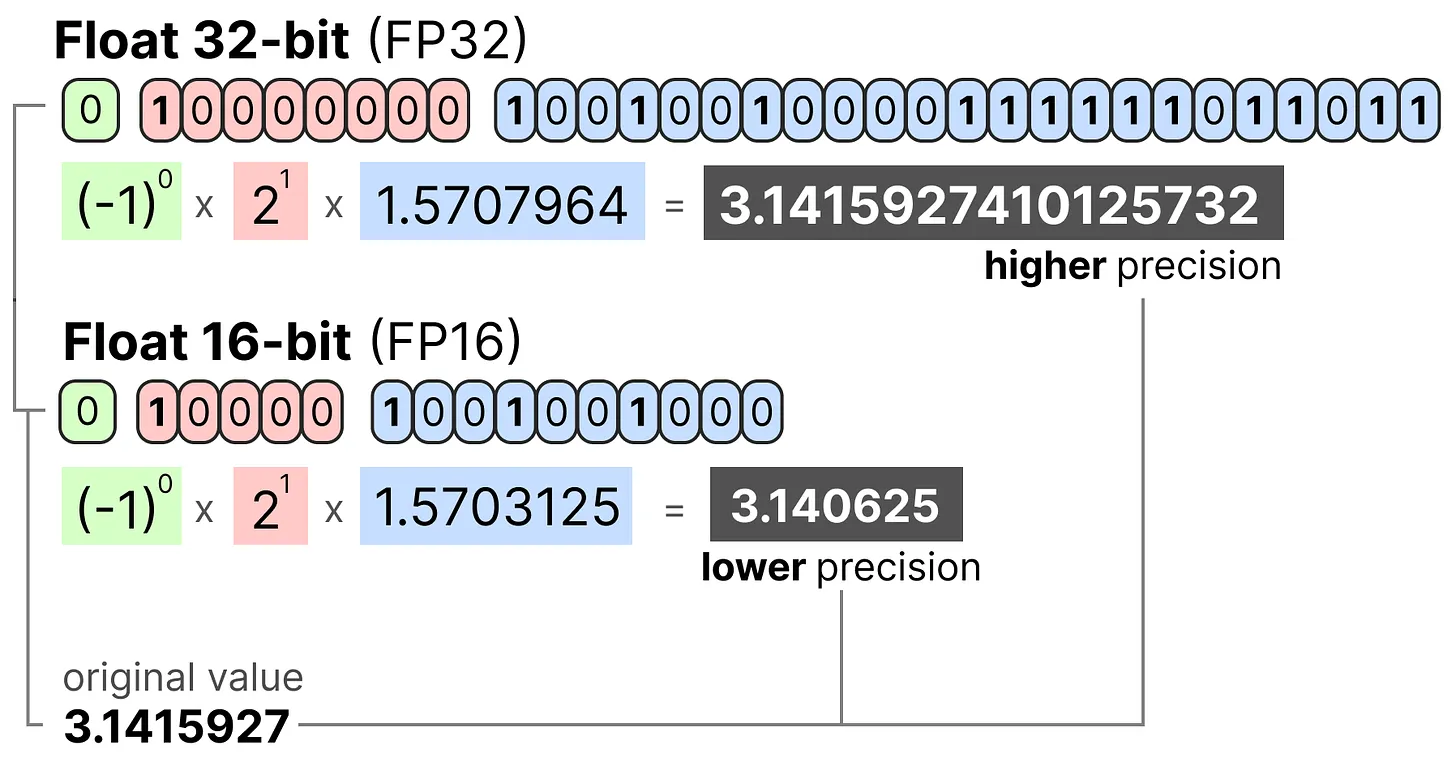
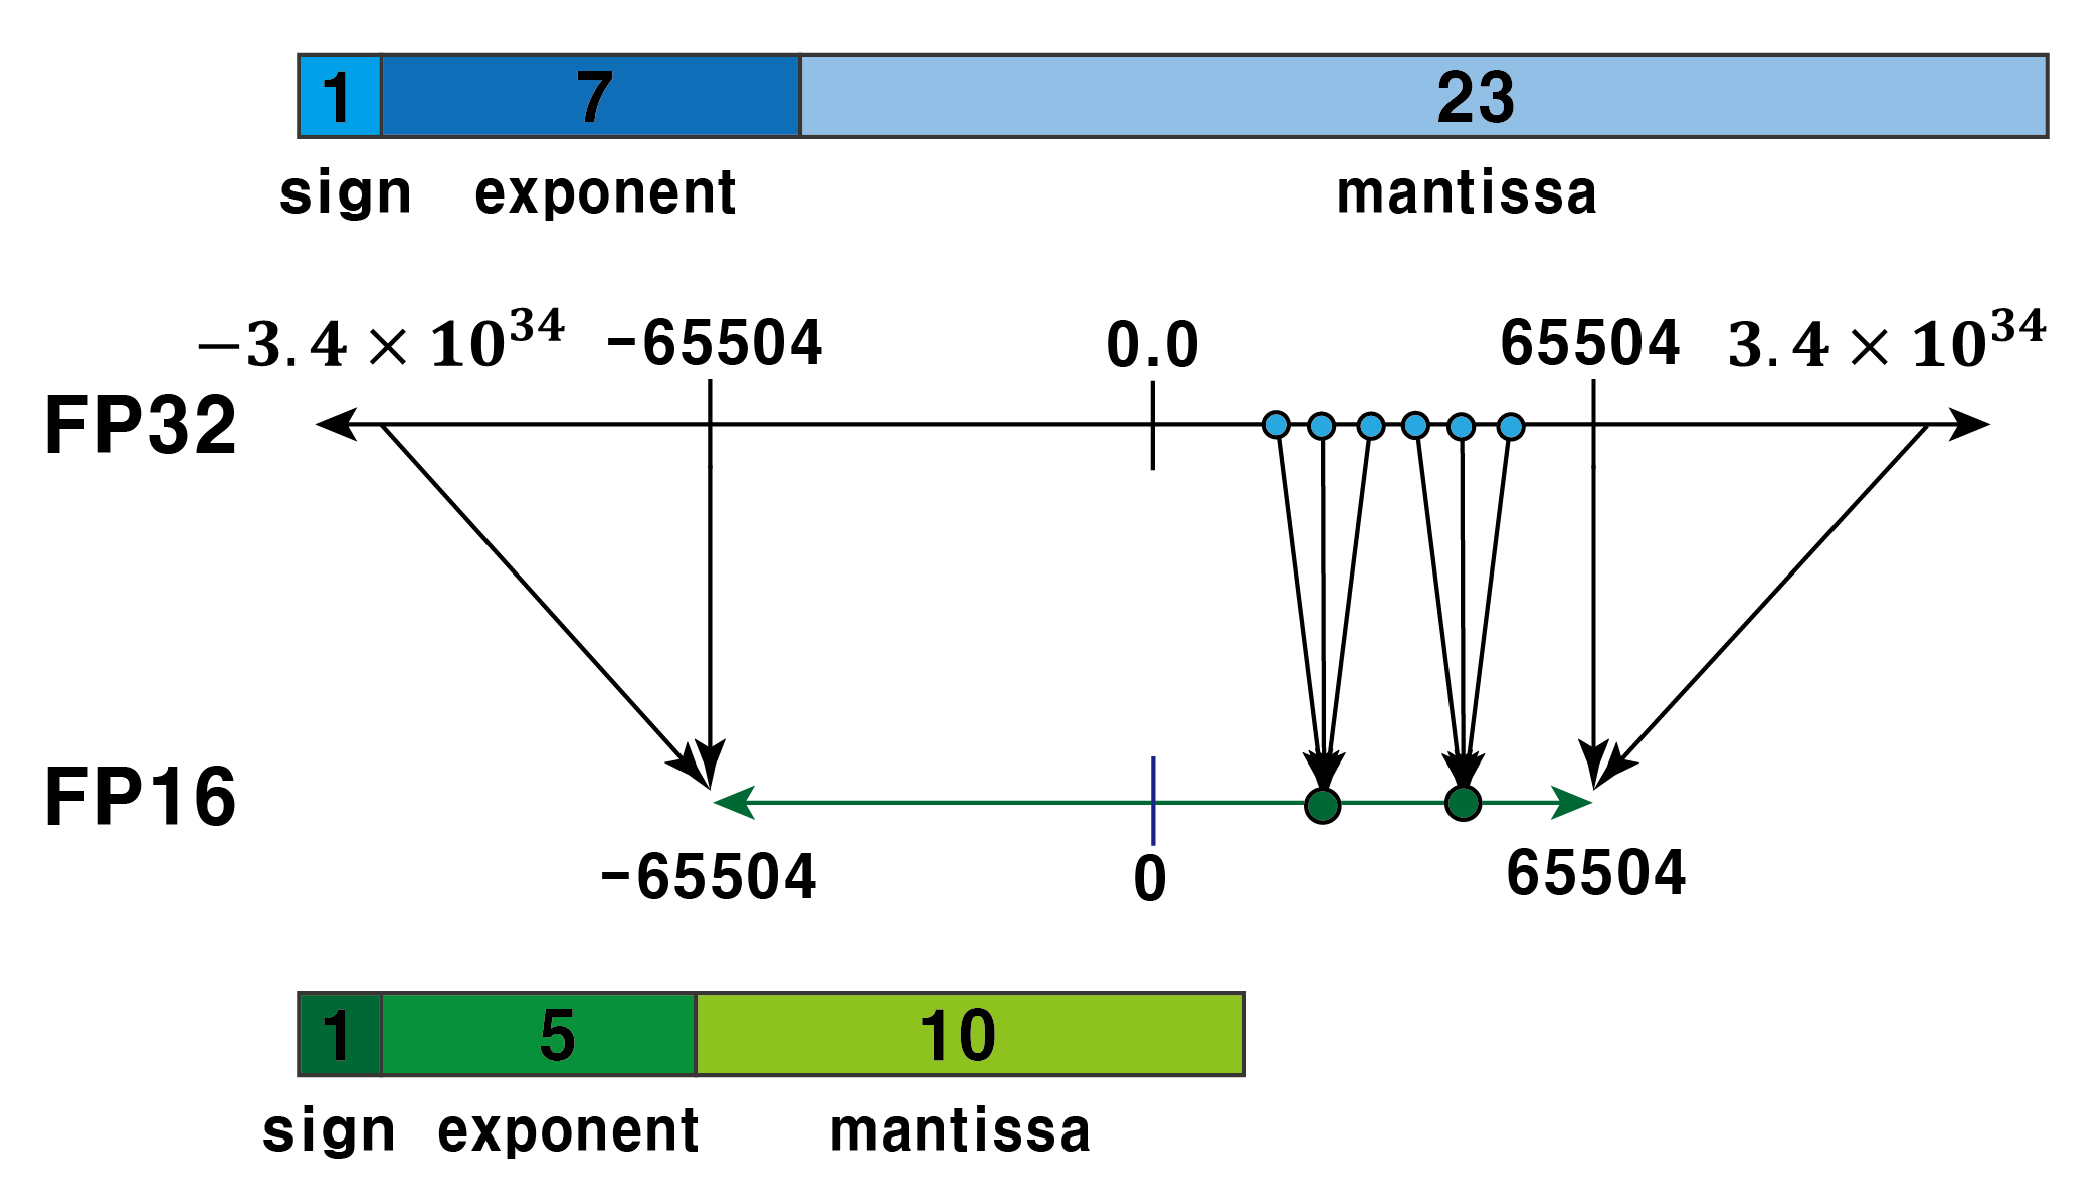
Quantization from FP32 to FP16. | Download Scientific Diagram
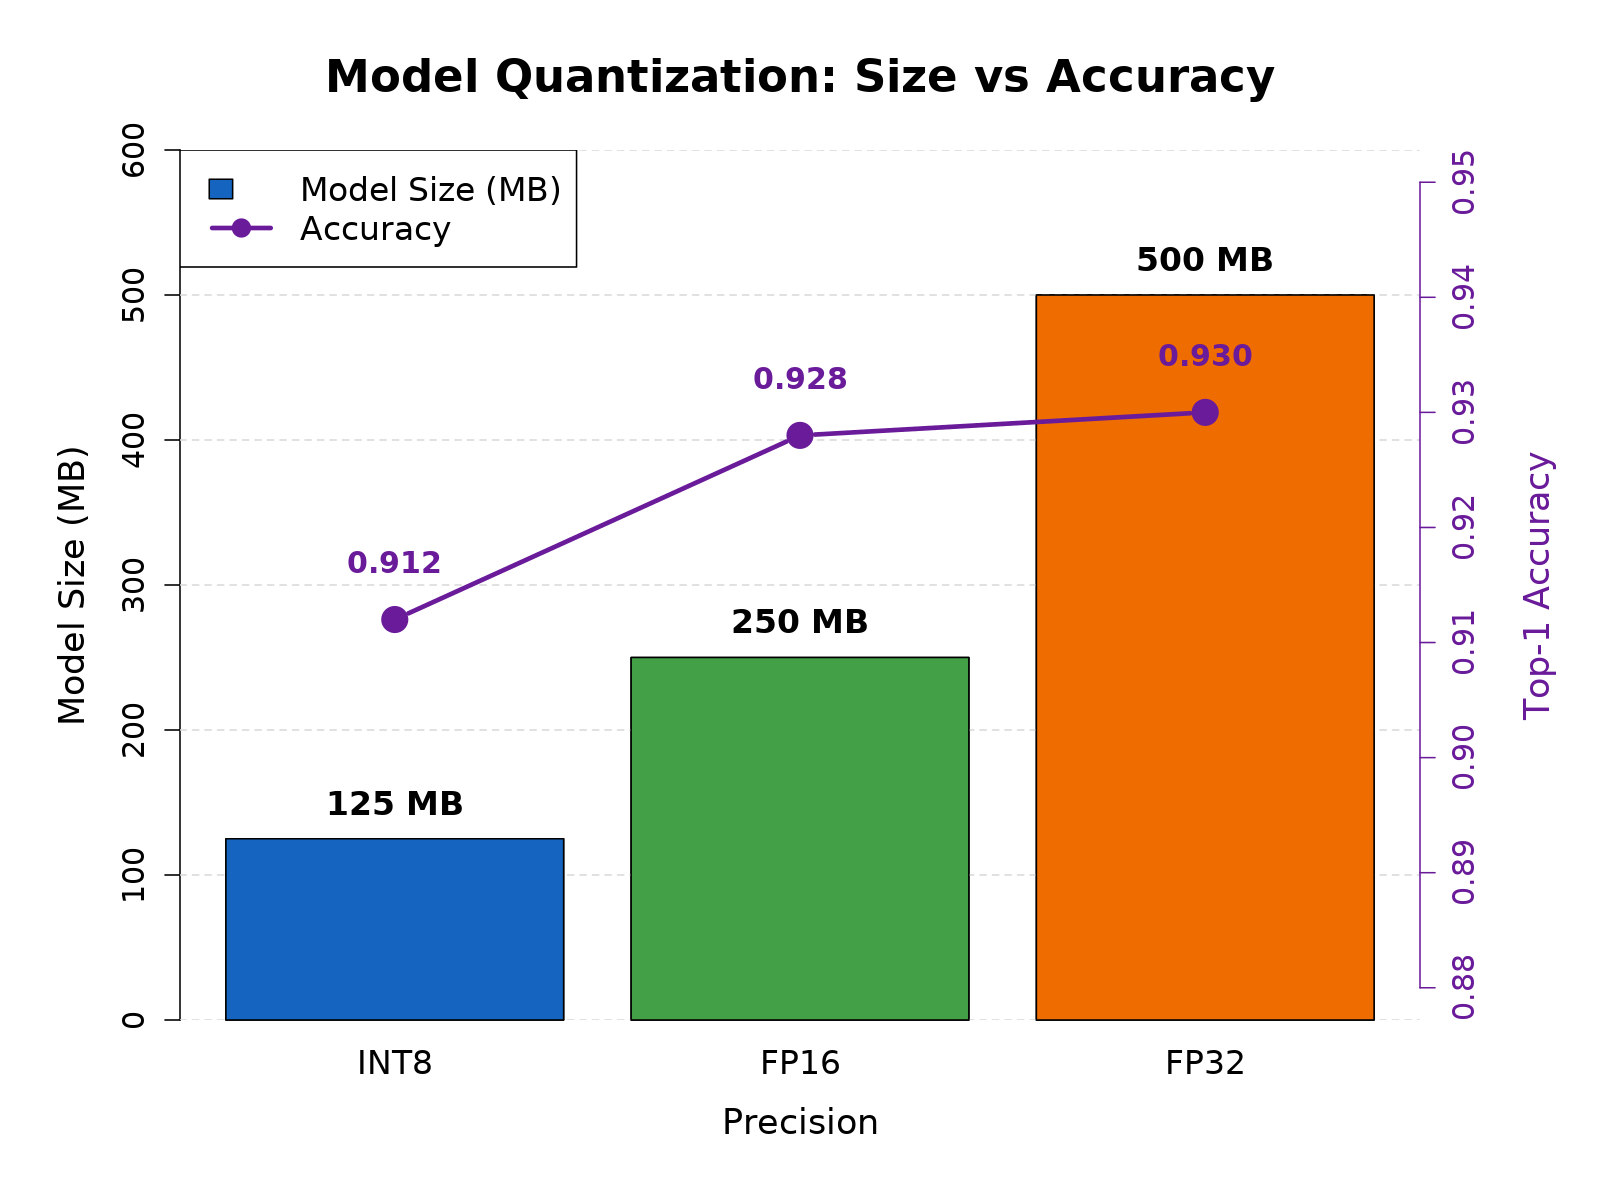
Quantization: INT8 vs FP16 vs FP32 | MetricGate
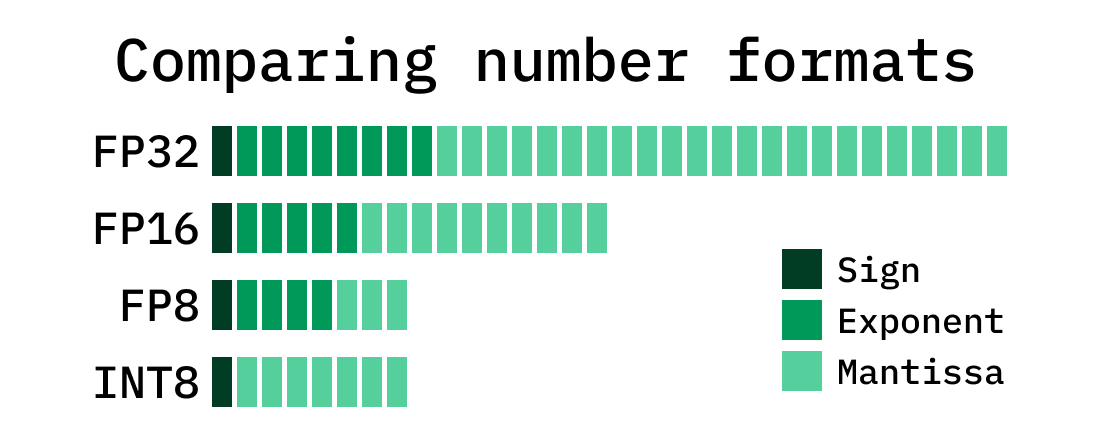
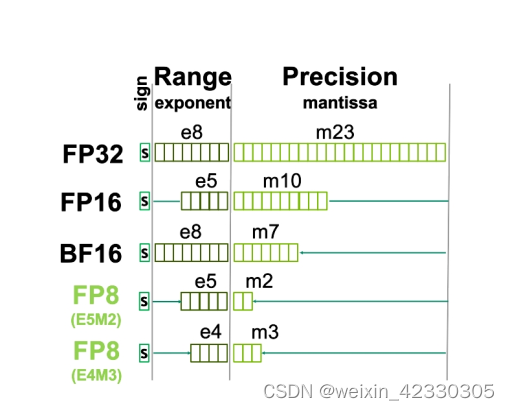
Precision Comparison: FP64 FP32 FP16 TF32 BF16 INT8
GPTQ Quantization (3-bit and 4-bit) · Issue #9 · ggml-org/llama.cpp ...
Quantization với Pytorch (Phần 1)
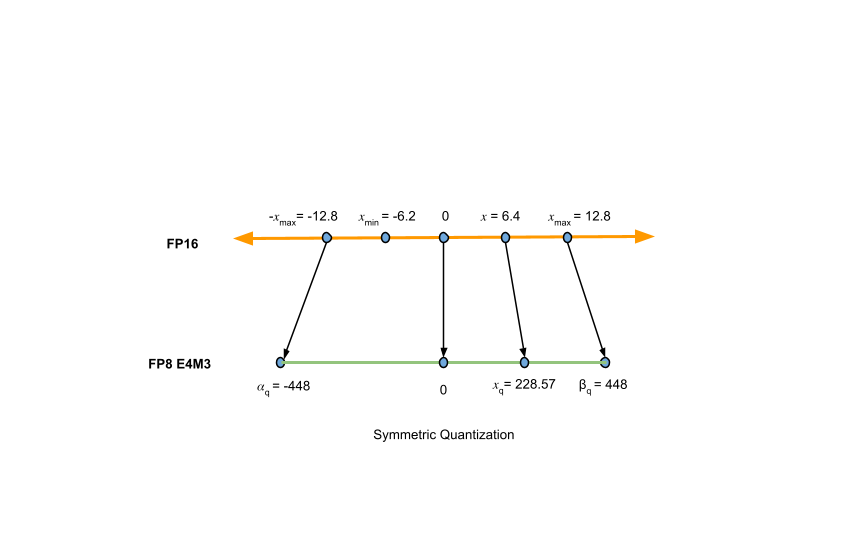
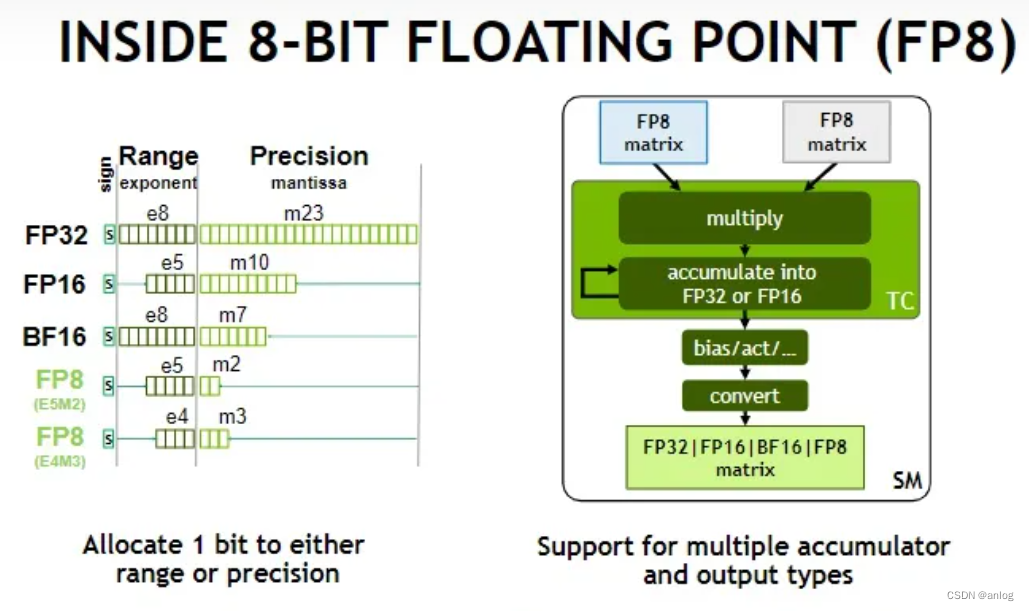
FP8 Quantization for Ultra-Low Latency AI | AI Tutorial | Next Electronics
Introduction to Quantization cooked in 🤗 with 💗🧑🍳
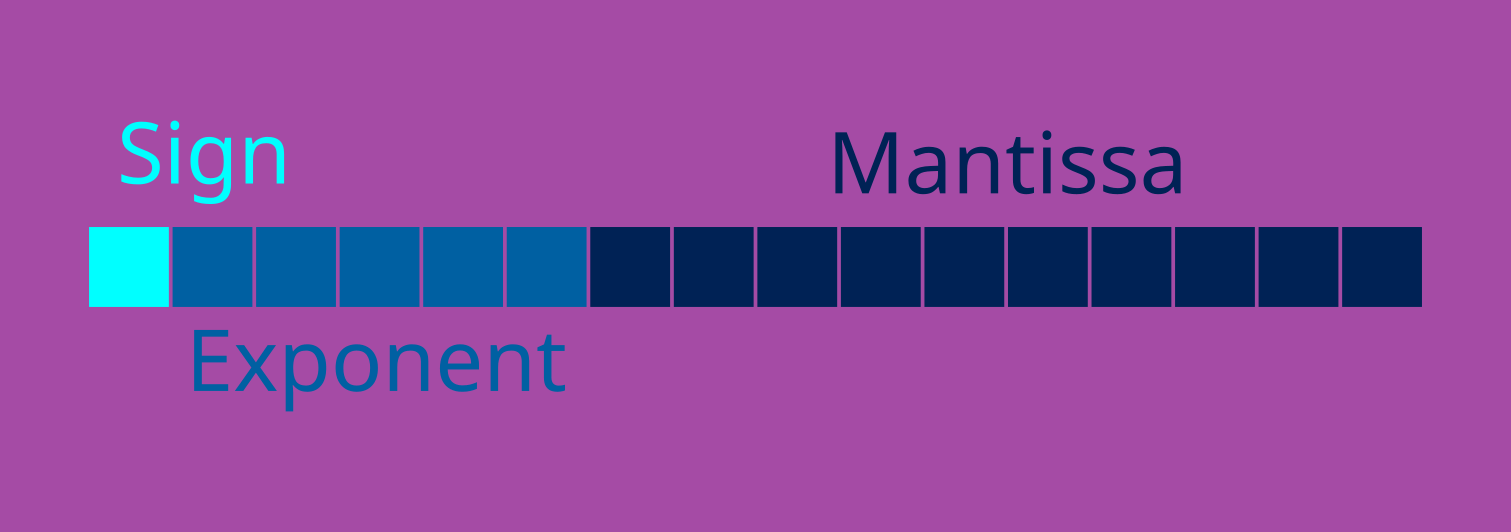
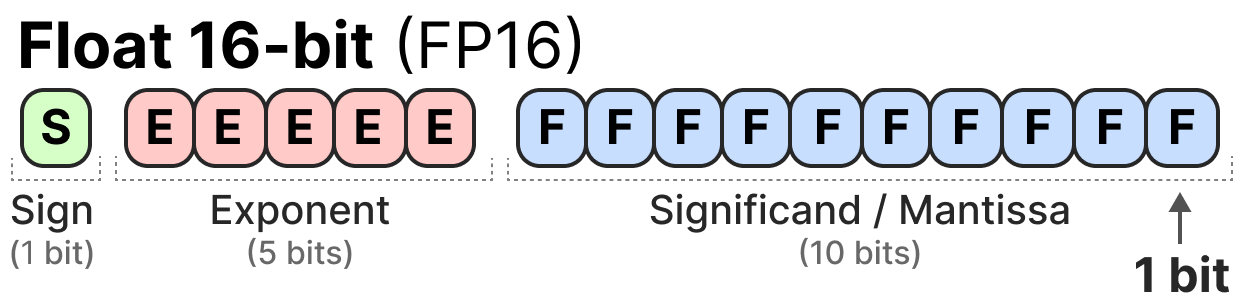
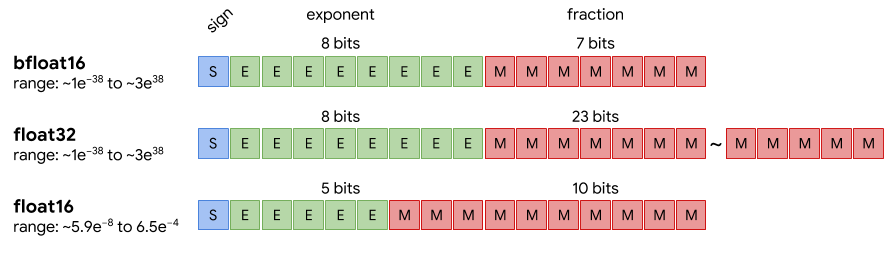
Representation of FP32, BF16, FP16 floating point types. | Download ...
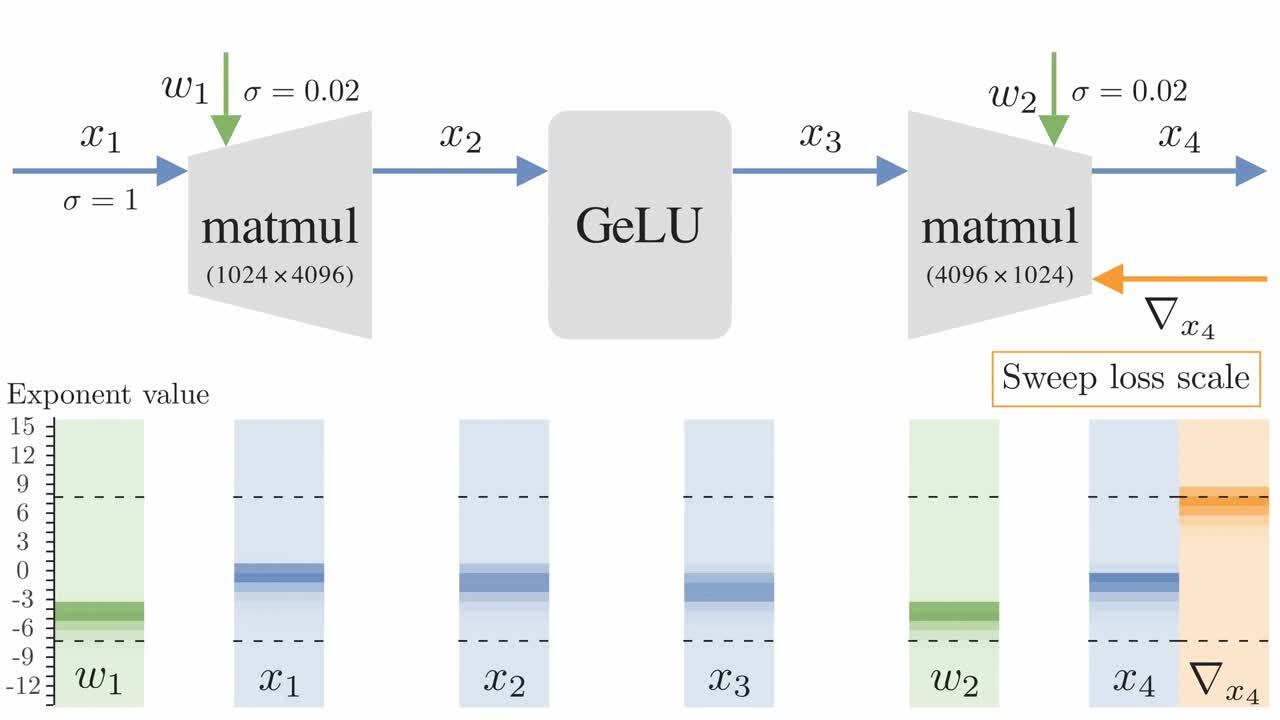
Simple FP16 and FP8 training with unit scaling
[RFC][Relay] FP32 -> FP16 Model Support - pre-RFC - Apache TVM Discuss
FP16 vs FP32 - What Do They Mean and What's the Difference? - ByteXD
Quantizing LLMs Step-by-Step: Converting FP16 Models to GGUF ...
Quantization — Cours Deep Learning
Advanced Model Quantization Techniques (INT8, FP16, etc.)
Fast and Accurate GPU Quantization for Transformers
Improving LLM Inference Latency on CPUs with Model Quantization ...
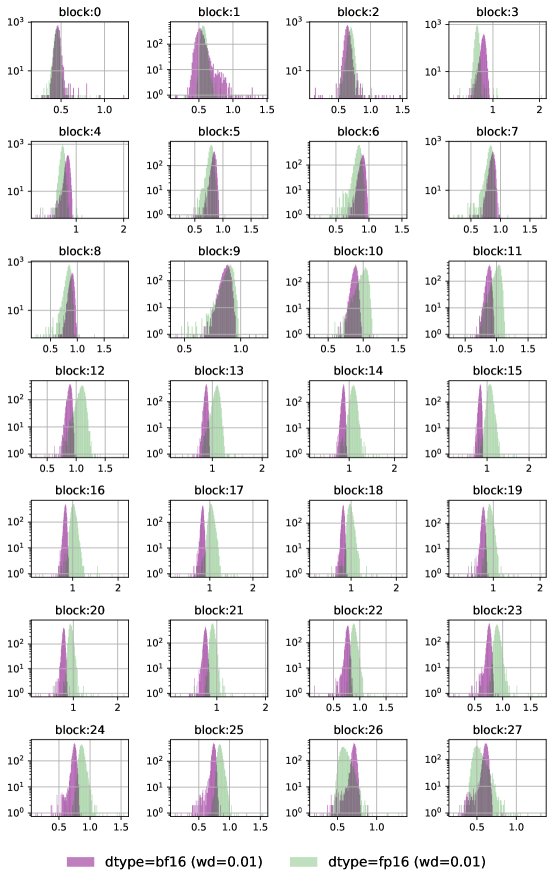
BF16 vs FP16 vs FP8 vs GGUF: Which One to Download
基于 NVIDIA 的 PC 端到端人工智能:从 FP32 过渡到 FP16 优化人工智能 - NVIDIA 技术博客
LLM Quantization Explained: What Q4, Q5, and Q8 Actually Mean for Your GPU
Making FP16 and FP8 easy to use with our new unit scaling library
[2305.19268] Intriguing Properties of Quantization at Scale
The differences between running simulation at FP32 and FP16 precision ...
Float Quantization at Sally Patrick blog
Microscaling FP4 Quantization
TensorFlow Model Optimization Toolkit — float16 quantization halves ...
A Method of Deep Learning Model Optimization for Image Classification ...
Cuantización — Deep Learning Course
Running Llama 2 on CPU Inference Locally for Document Q&A | Towards ...
Optimizing LLMs for Performance and Accuracy with Post-training ...
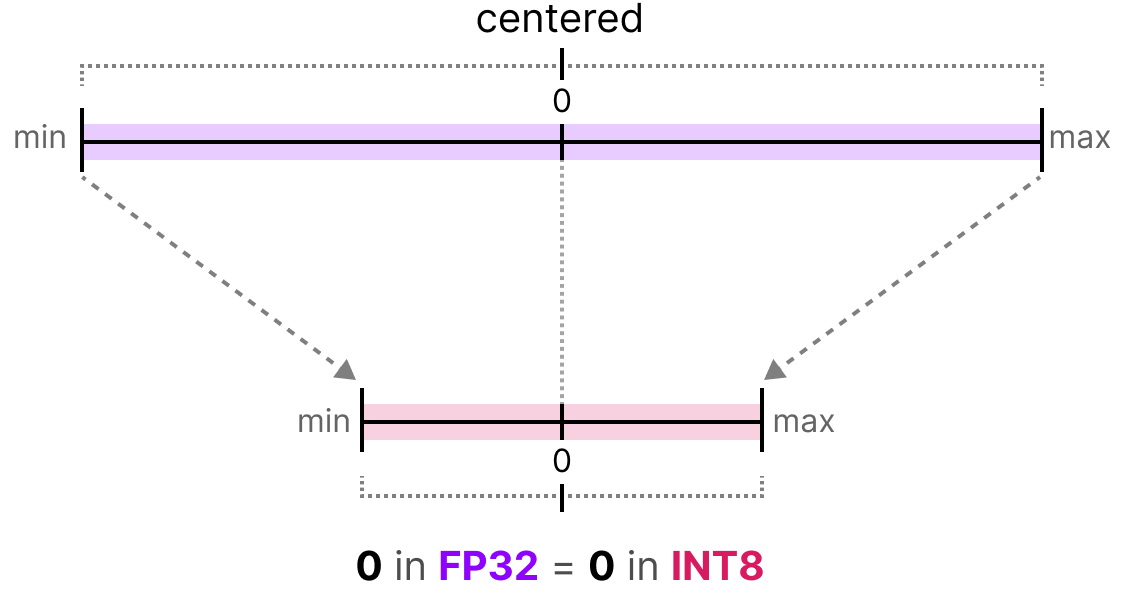
模型量化1-概述1:量化的过程就是选取合适量化参数(scale factor,zero point,clipping value)以及数据映射 ...
Model Quantization: Concepts, Methods, and Why It Matters - NViNiO News ...
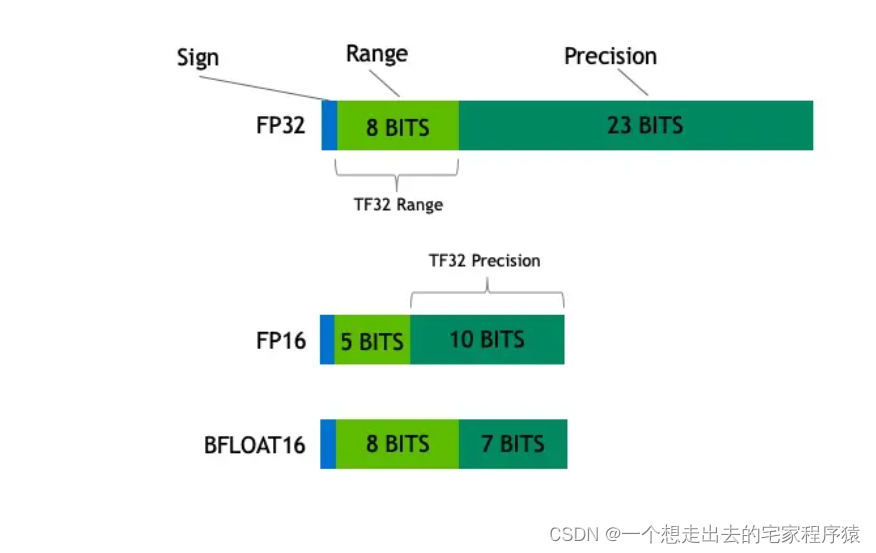
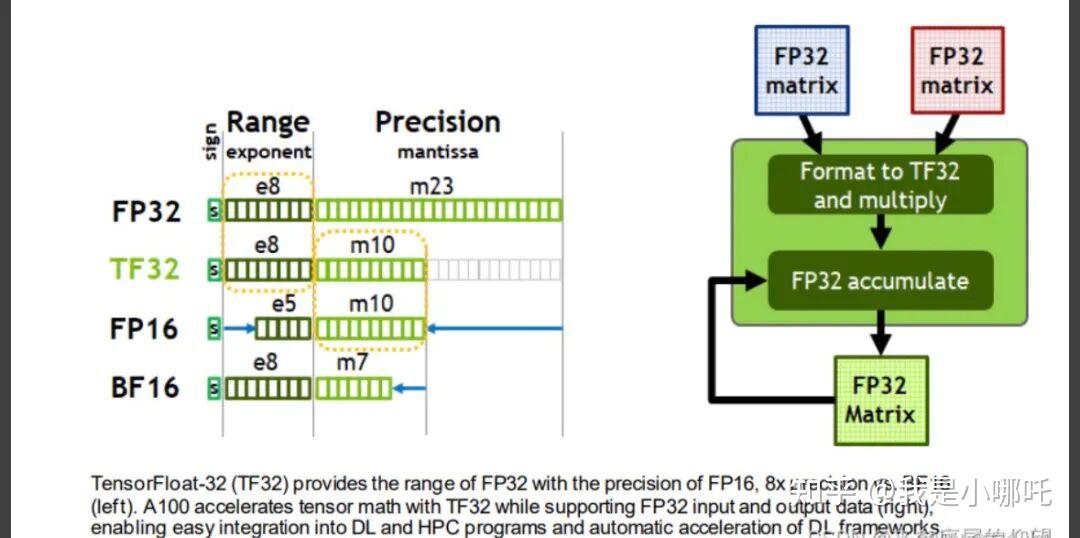
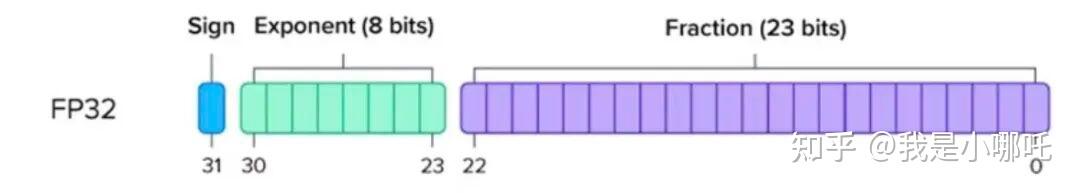
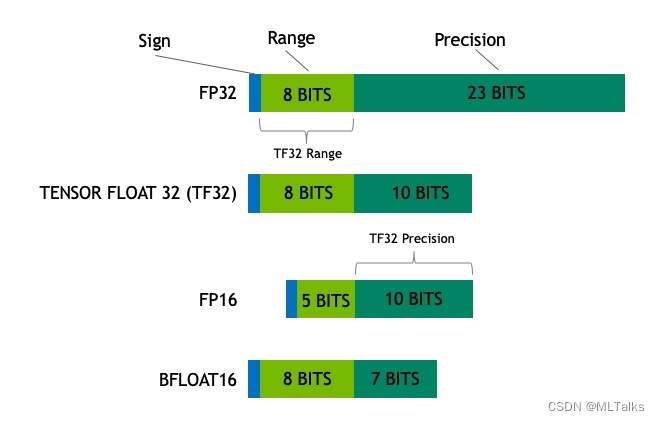
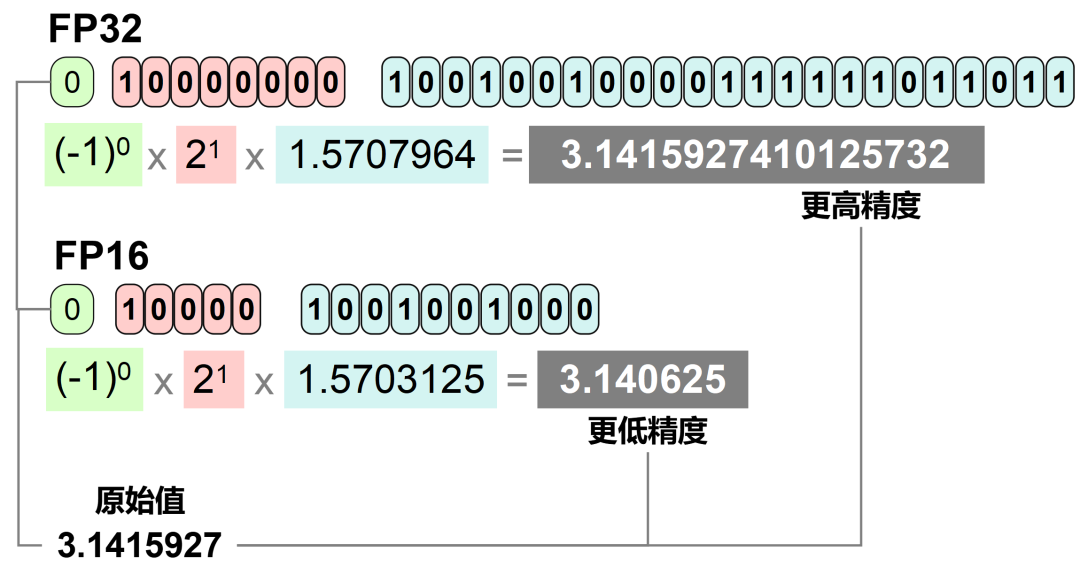
一文彻底理解AI大模型系列之:FP32、FP16、TF32、BF16、混合精度-CSDN博客
小白必读:到底什么是FP32、FP16、INT8?-电子工程专辑
What is floating point precision (FP64, FP32, and FP16)? - Vapor IO
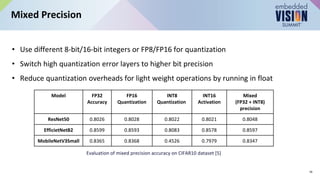
“DNN Quantization: Theory to Practice,” a Presentation from AMD | PDF
Accelerating Large Language Models with Mixed-Precision Techniques ...
混合精度 | MindSpore 1.7 教程 | 昇思MindSpore社区
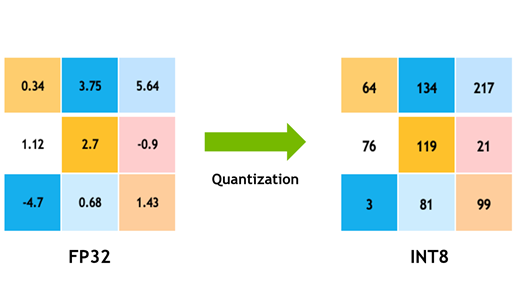
小白也能懂!INT4、INT8、FP8、FP16、FP32量化-CSDN博客
大模型开发中的浮点数精度选择:FP32、FP16、BF16详解! - 知乎
Quantization: Reducing Model Precision (FP16, INT8)
大模型开发中的浮点数精度选择:FP32、FP16、BF16详解!-CSDN博客
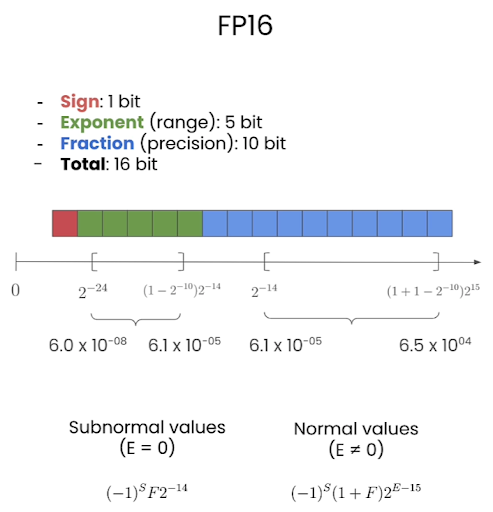
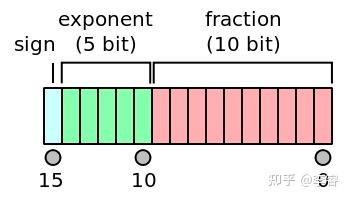
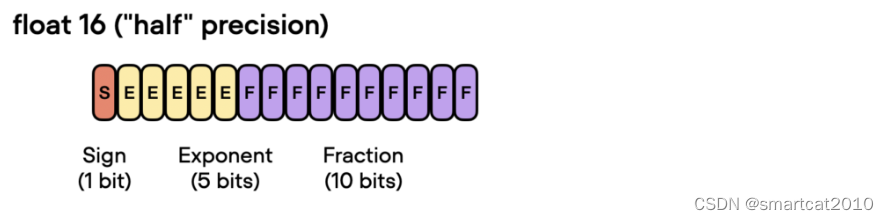
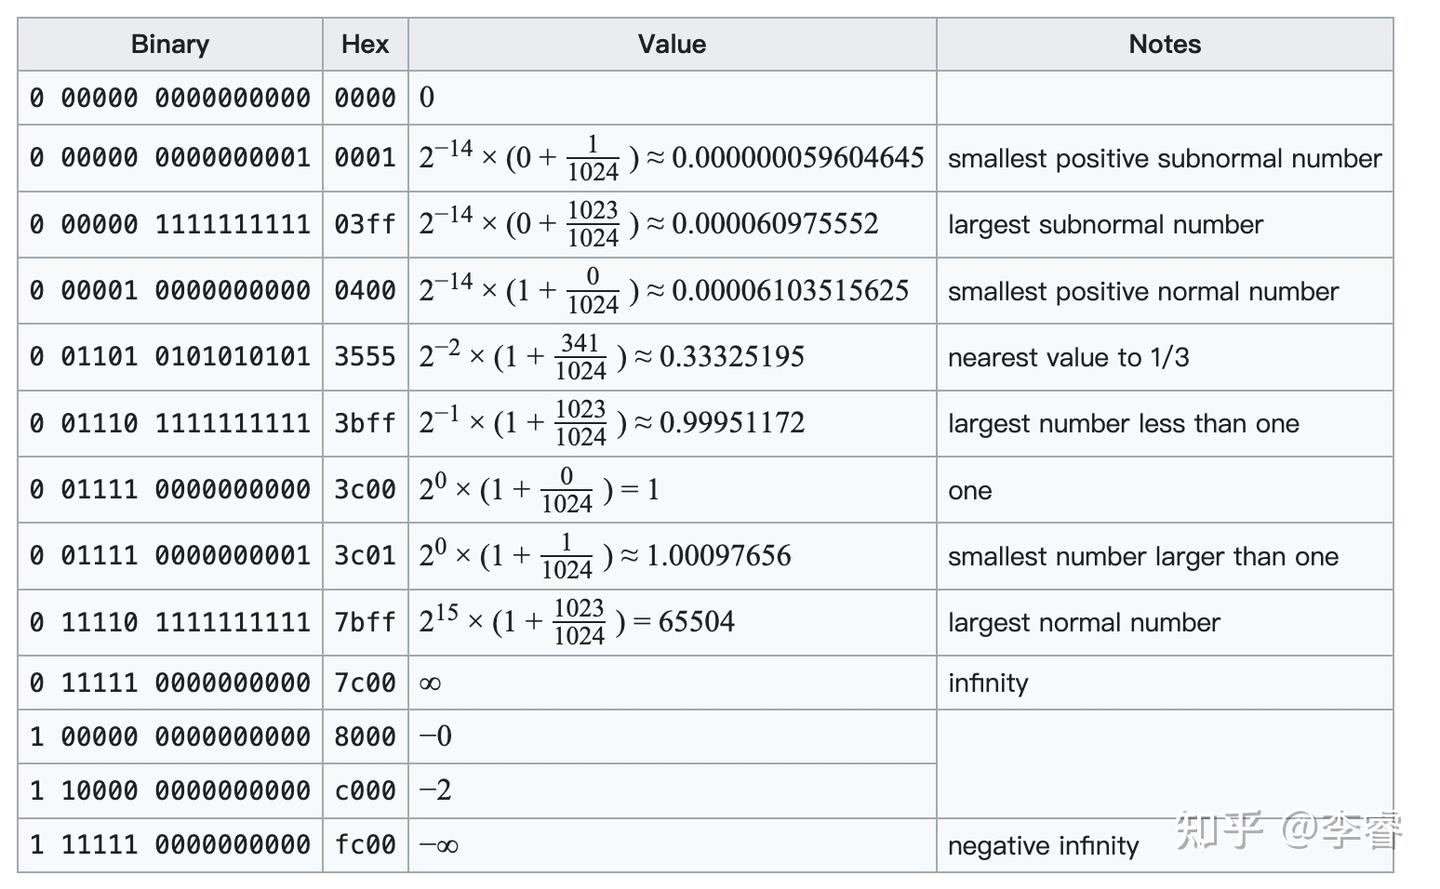
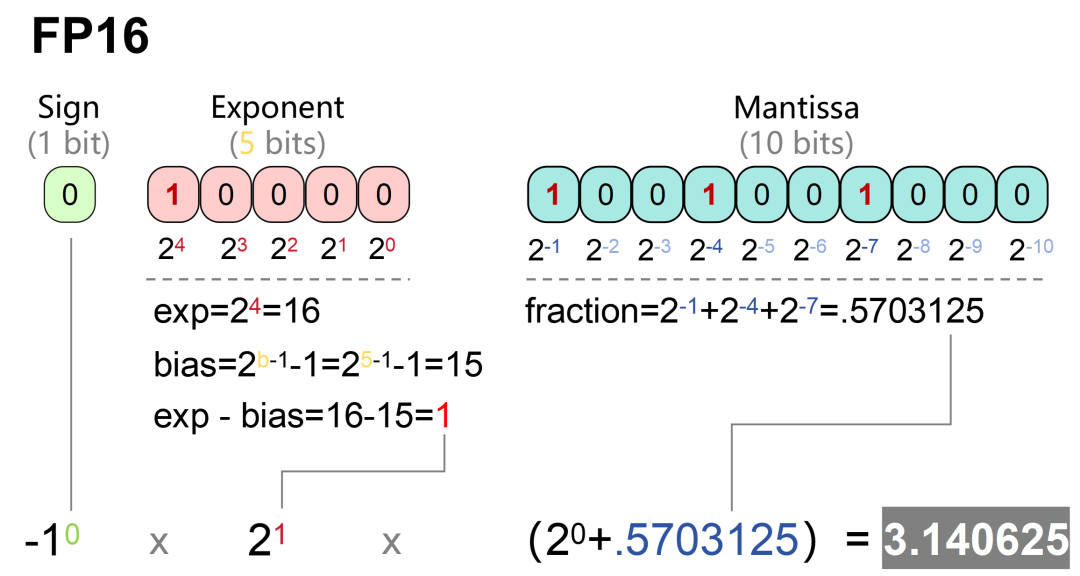
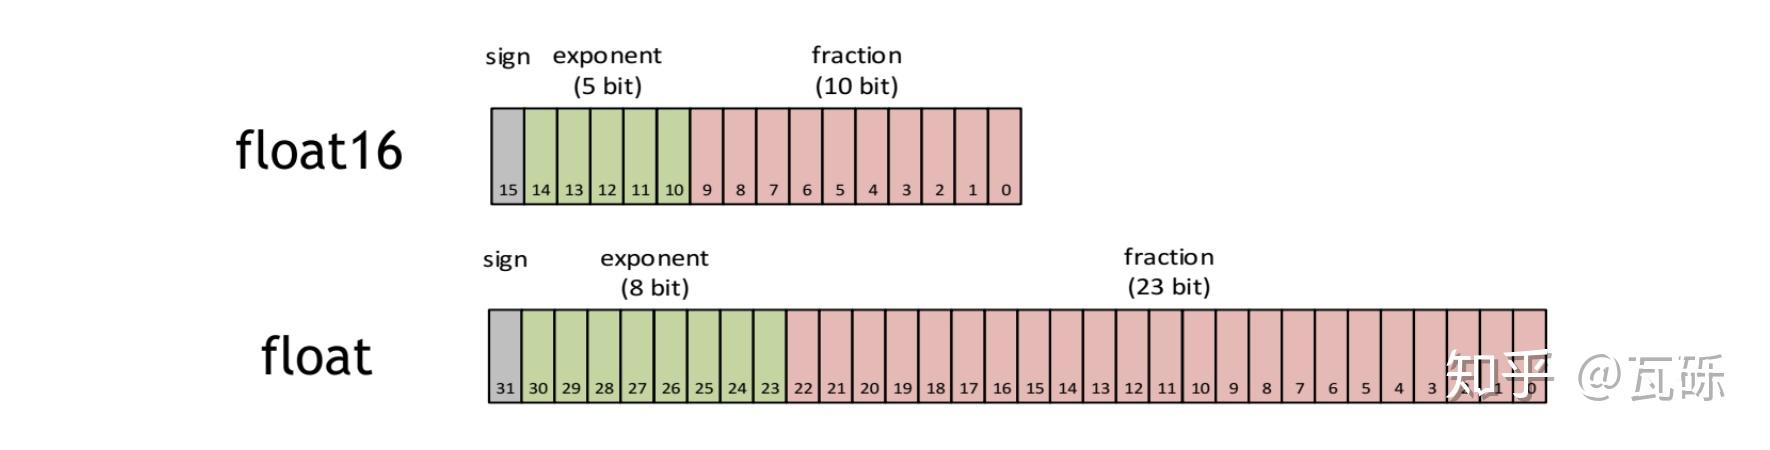
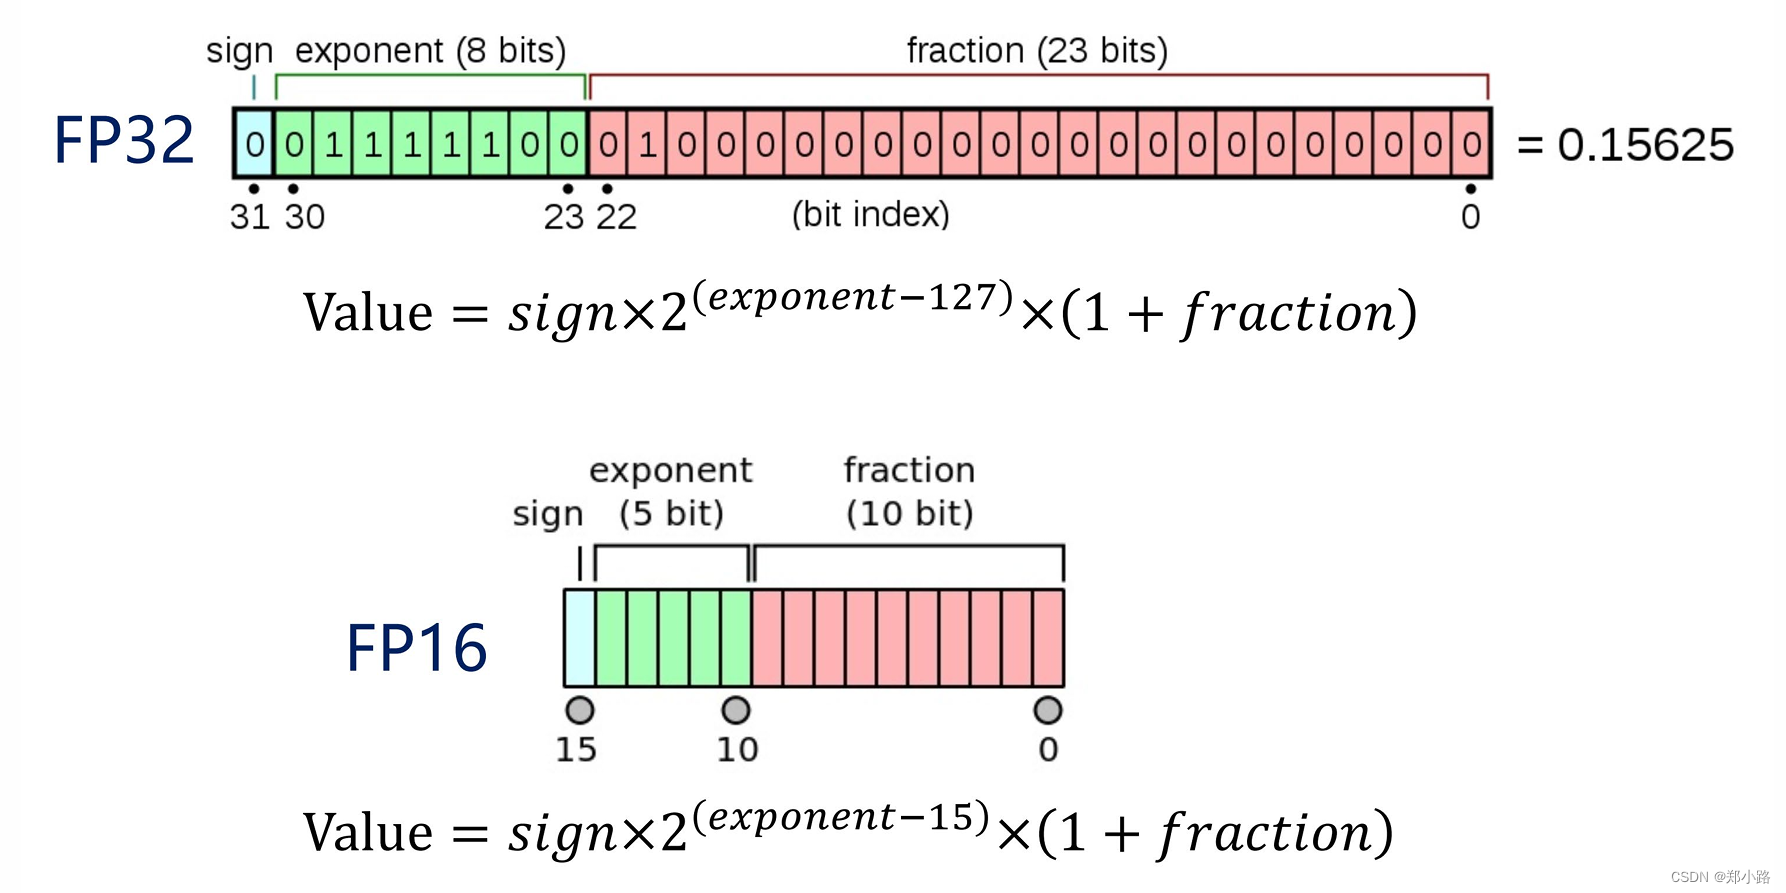
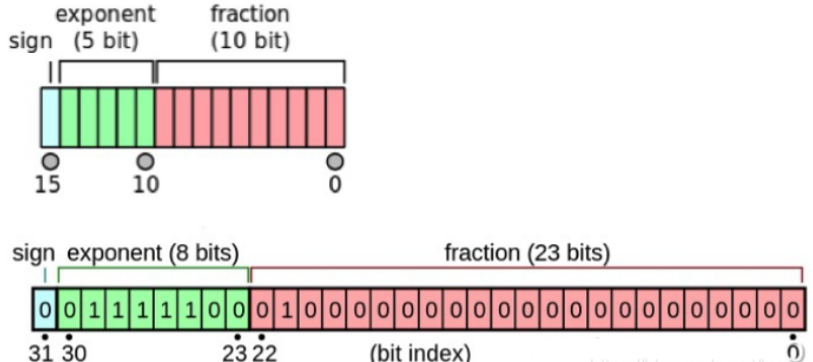
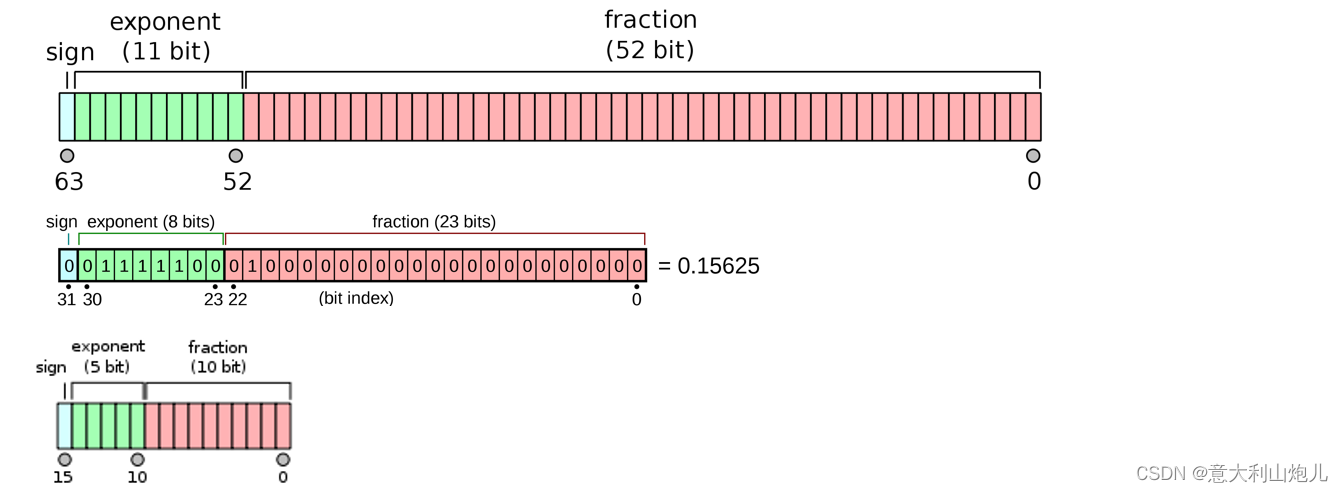
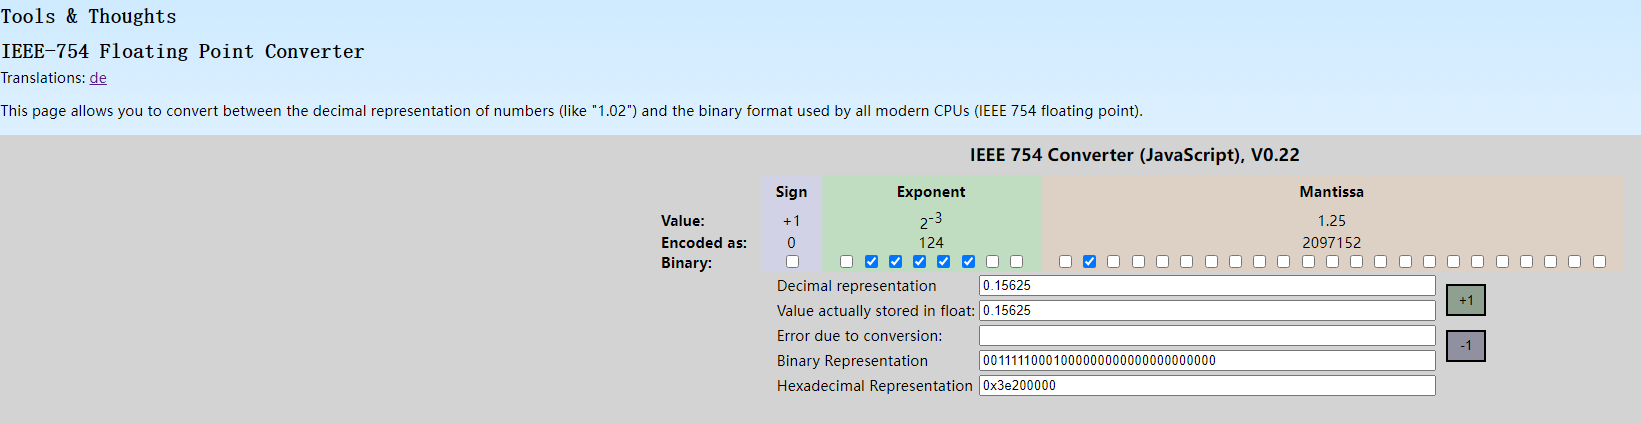
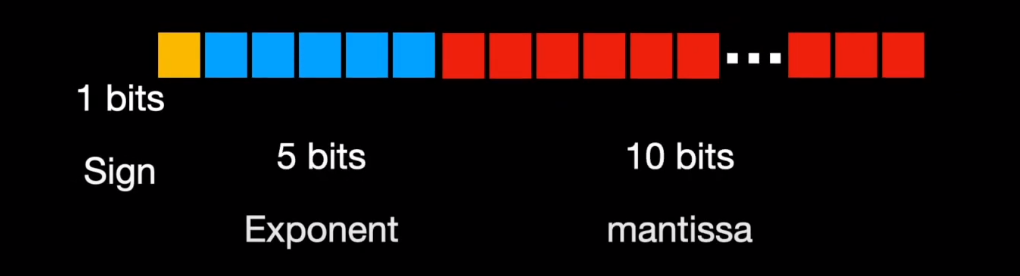
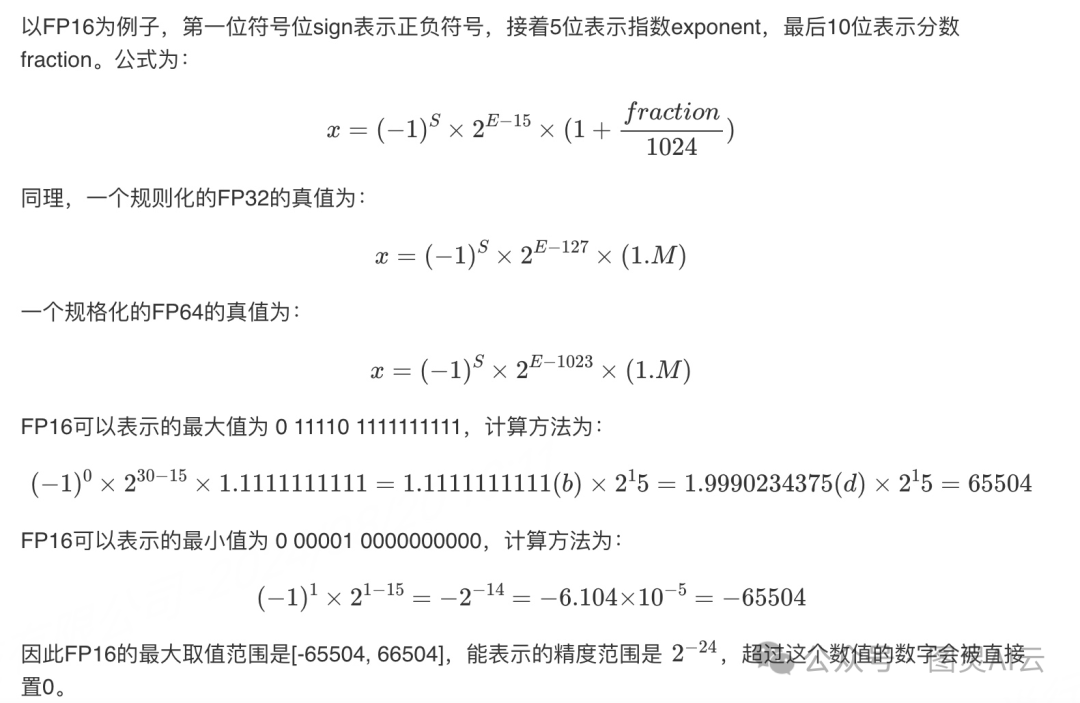
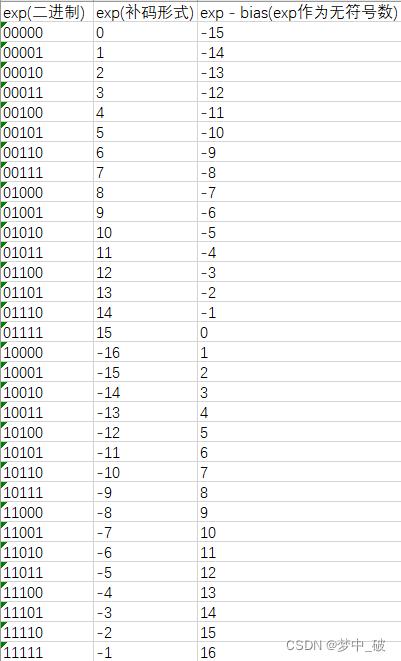
[转]FP16数据格式详解 - 知乎
What is FP64, FP32, FP16? Defining Floating Point | Exxact Blog
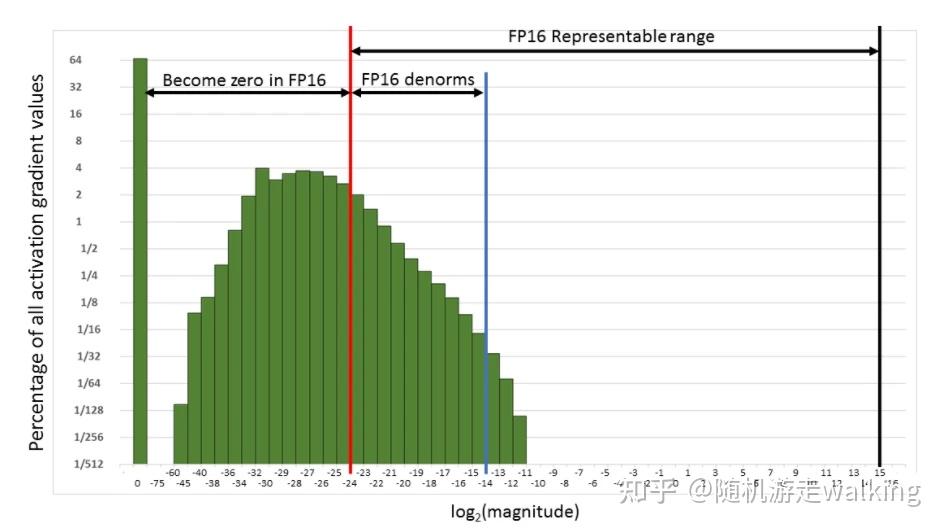
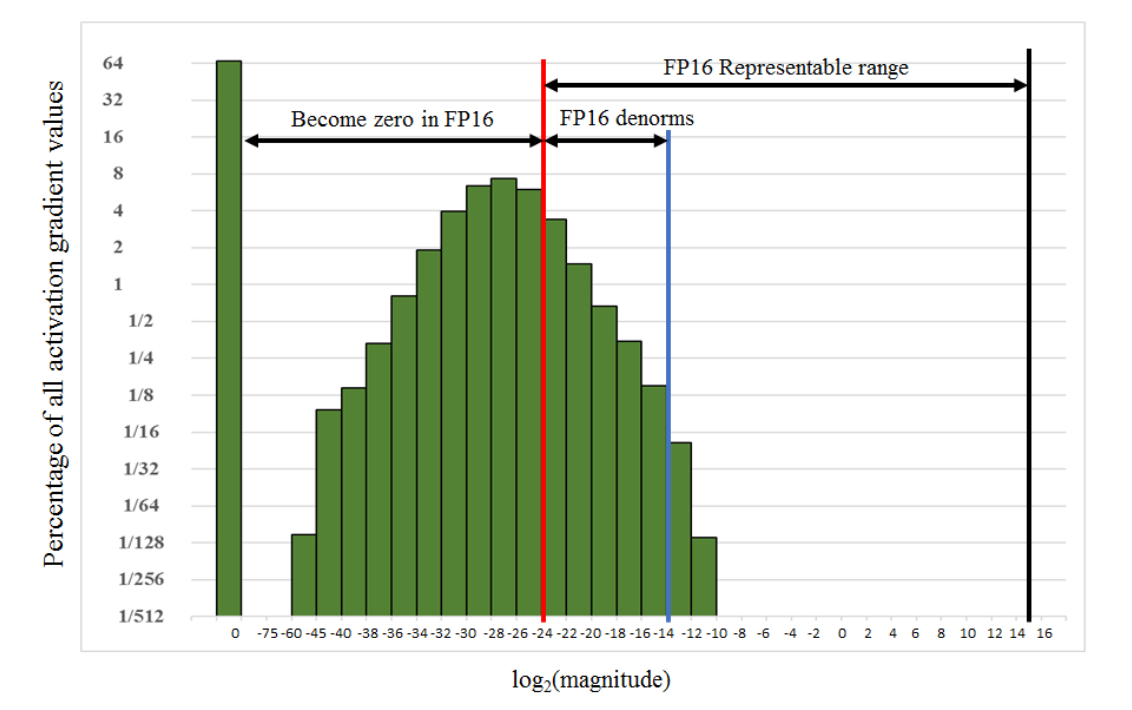
fp16训练的问题 | dragon
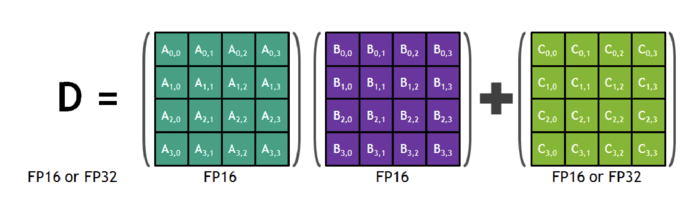
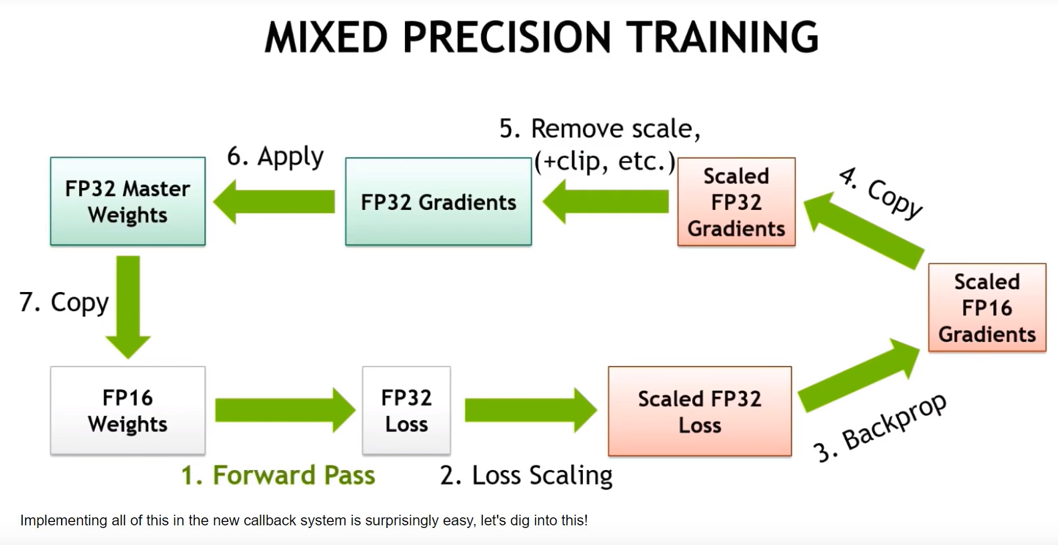
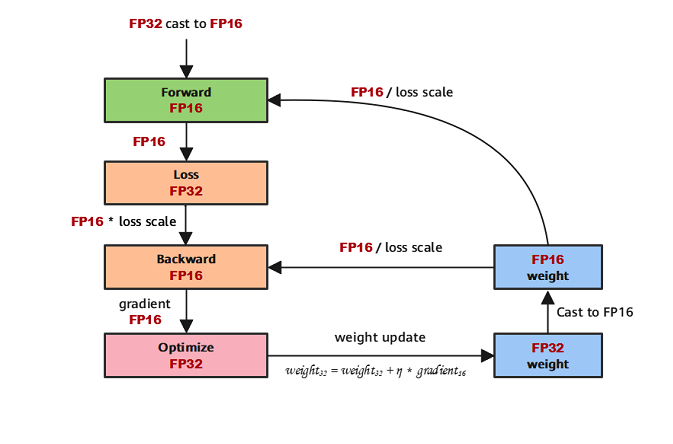
Mixed-precision计算原理(FP32+FP16)_fp16和fp32是如何相加的-CSDN博客
图像预处理的数据精度问题报出的Nan - 海_纳百川 - 博客园
FP16数据格式详解-CSDN博客
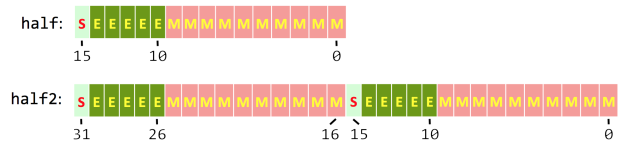
CUDA使用FP16进行半精度运算_怎么使用半精度计算-CSDN博客
深度学习中的数据类型介绍:FP32, FP16, TF32, BF16, Int16, Int8 ...-CSDN博客
Medium
一文搞懂神经网络混合精度训练 - 知乎
【干货】大模型算力优化全攻略——FP32、FP16、INT8数据格式精讲与实战应用_fp16和fp32-CSDN博客
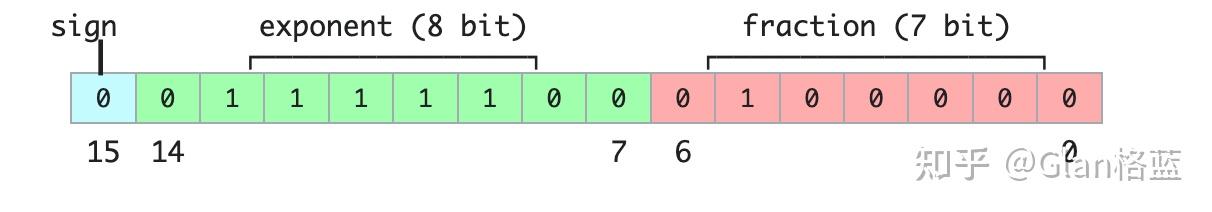
FP16与BF16区别_bf16 fp16-CSDN博客
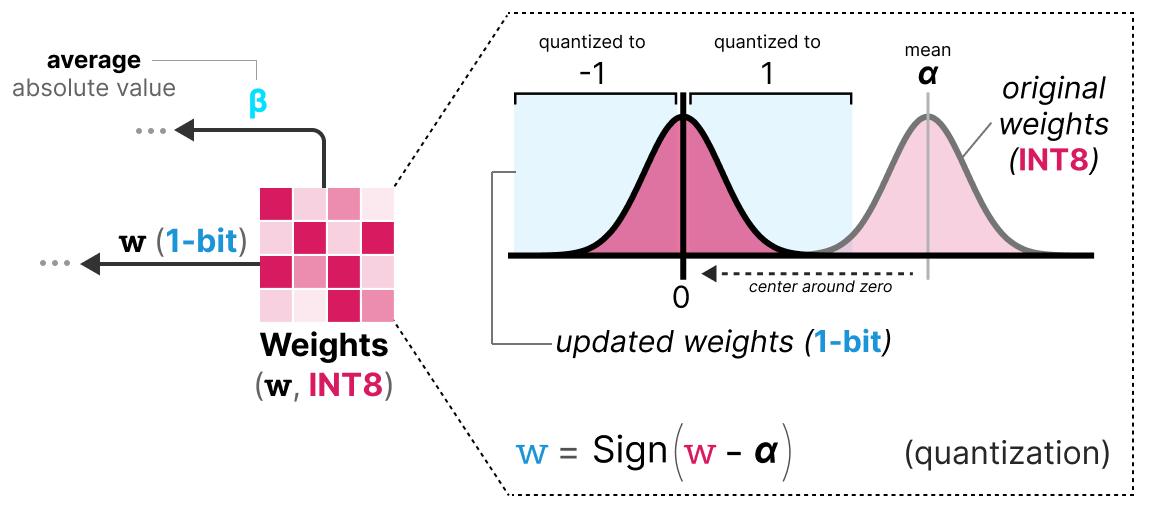
50张图解密大模型量化技术:INT4、INT8、FP32、FP16、GPTQ、GGUF、BitNet_gptq量化-CSDN博客
FP16\FP32\INT8\混合精度的含义-CSDN博客
“Quantization Techniques for Efficient Deployment of Large Language ...
LLM大模型之精度问题(FP16,FP32,BF16)详解与实践 - 知乎
一文读懂 LLM:FP16、FP32、BF16 精度的性能与显存占用权衡 - 知乎
FP8: Efficient model inference with 8-bit floating point numbers ...
Training using half-precision floating point (fp16) can be up to 3x ...
【PyTorch】唯快不破:基于Apex的混合精度加速 - 知乎
大模型数值精度完全指南:FP32/FP16/BF16/FP8对比与应用实战!_bfloat16 fp8-CSDN博客
GPU memory requirements for serving Large Language Models | UnfoldAI
模型量化技术综述:揭示大型语言模型压缩的前沿技术_gptq论文详解-CSDN博客
Top 5 AI Model Optimization Techniques for Faster, Smarter Inference ...
FP8格式理解解析-CSDN博客
TensorRT:FP16优化加速的原理与实践_tensorrt fp16-CSDN博客
Snowflake AI Research Optimizes Llama 3.1 405B for Efficient AI Deployment
Pytorch混合精度(FP16&FP32)(AMP自动混合精度)/半精度 训练(一) —— 原理(torch.half)-CSDN博客
mmdetection2.X--混合精度训练(fp16 & fp32)_mmdetection 混合精度训练-CSDN博客
BF16和FP16对比-CSDN博客
大模型推理量化(Quantization)基础速览 - 知乎
浮点运算的定点化_bf16和fp16-CSDN博客
FP32FP16INT8数据类型计算原理与存储结构详解-开发者社区-阿里云
Demystifying Quantization: Shrinking Models for Efficient AI | Bimal ...
pytorch的fp16精度训练怎么绝对的杜绝nan的出现? - 知乎
FP64、FP32、FP16、FP8简介-CSDN博客
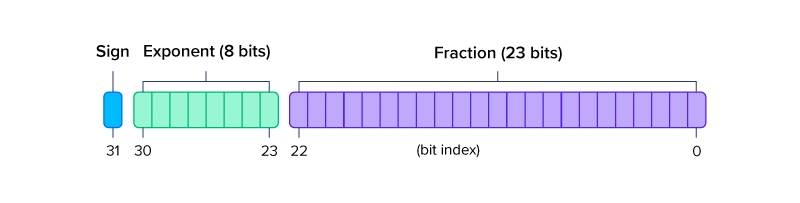
FP32, FP16, BF16 и FP8 — разбираемся в основных типах чисел с плавающей ...
Optimizing LLMs for Performance and Accuracy with Post-Training ...
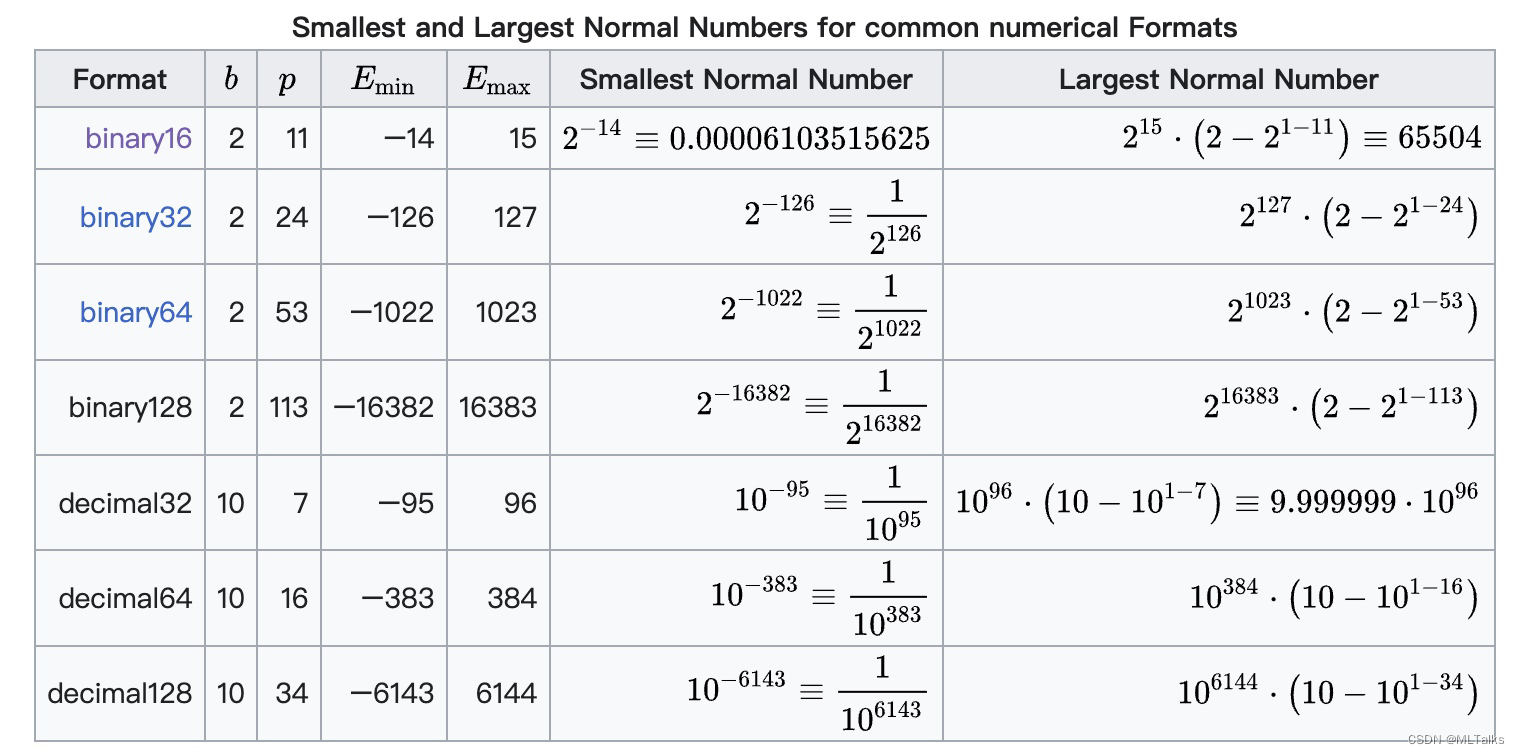
FP16数据格式详解 | MLTalks
Introducing NVFP4 for Efficient and Accurate Low-Precision Inference ...
您需要知道的:大模型中的算力精度FP16 vs. FP32_fp32和fp16算力区别-CSDN博客
BF16 vs FP16: Key Differences, Precision, and Best Use Cases
FP8 低精度训练:Transformer Engine 简析 - 知乎
DQN rewards for fp32, fp16, and int8 policies. | Download Scientific ...
Optimization Strategies Applied to Deep Learning Models for Image ...
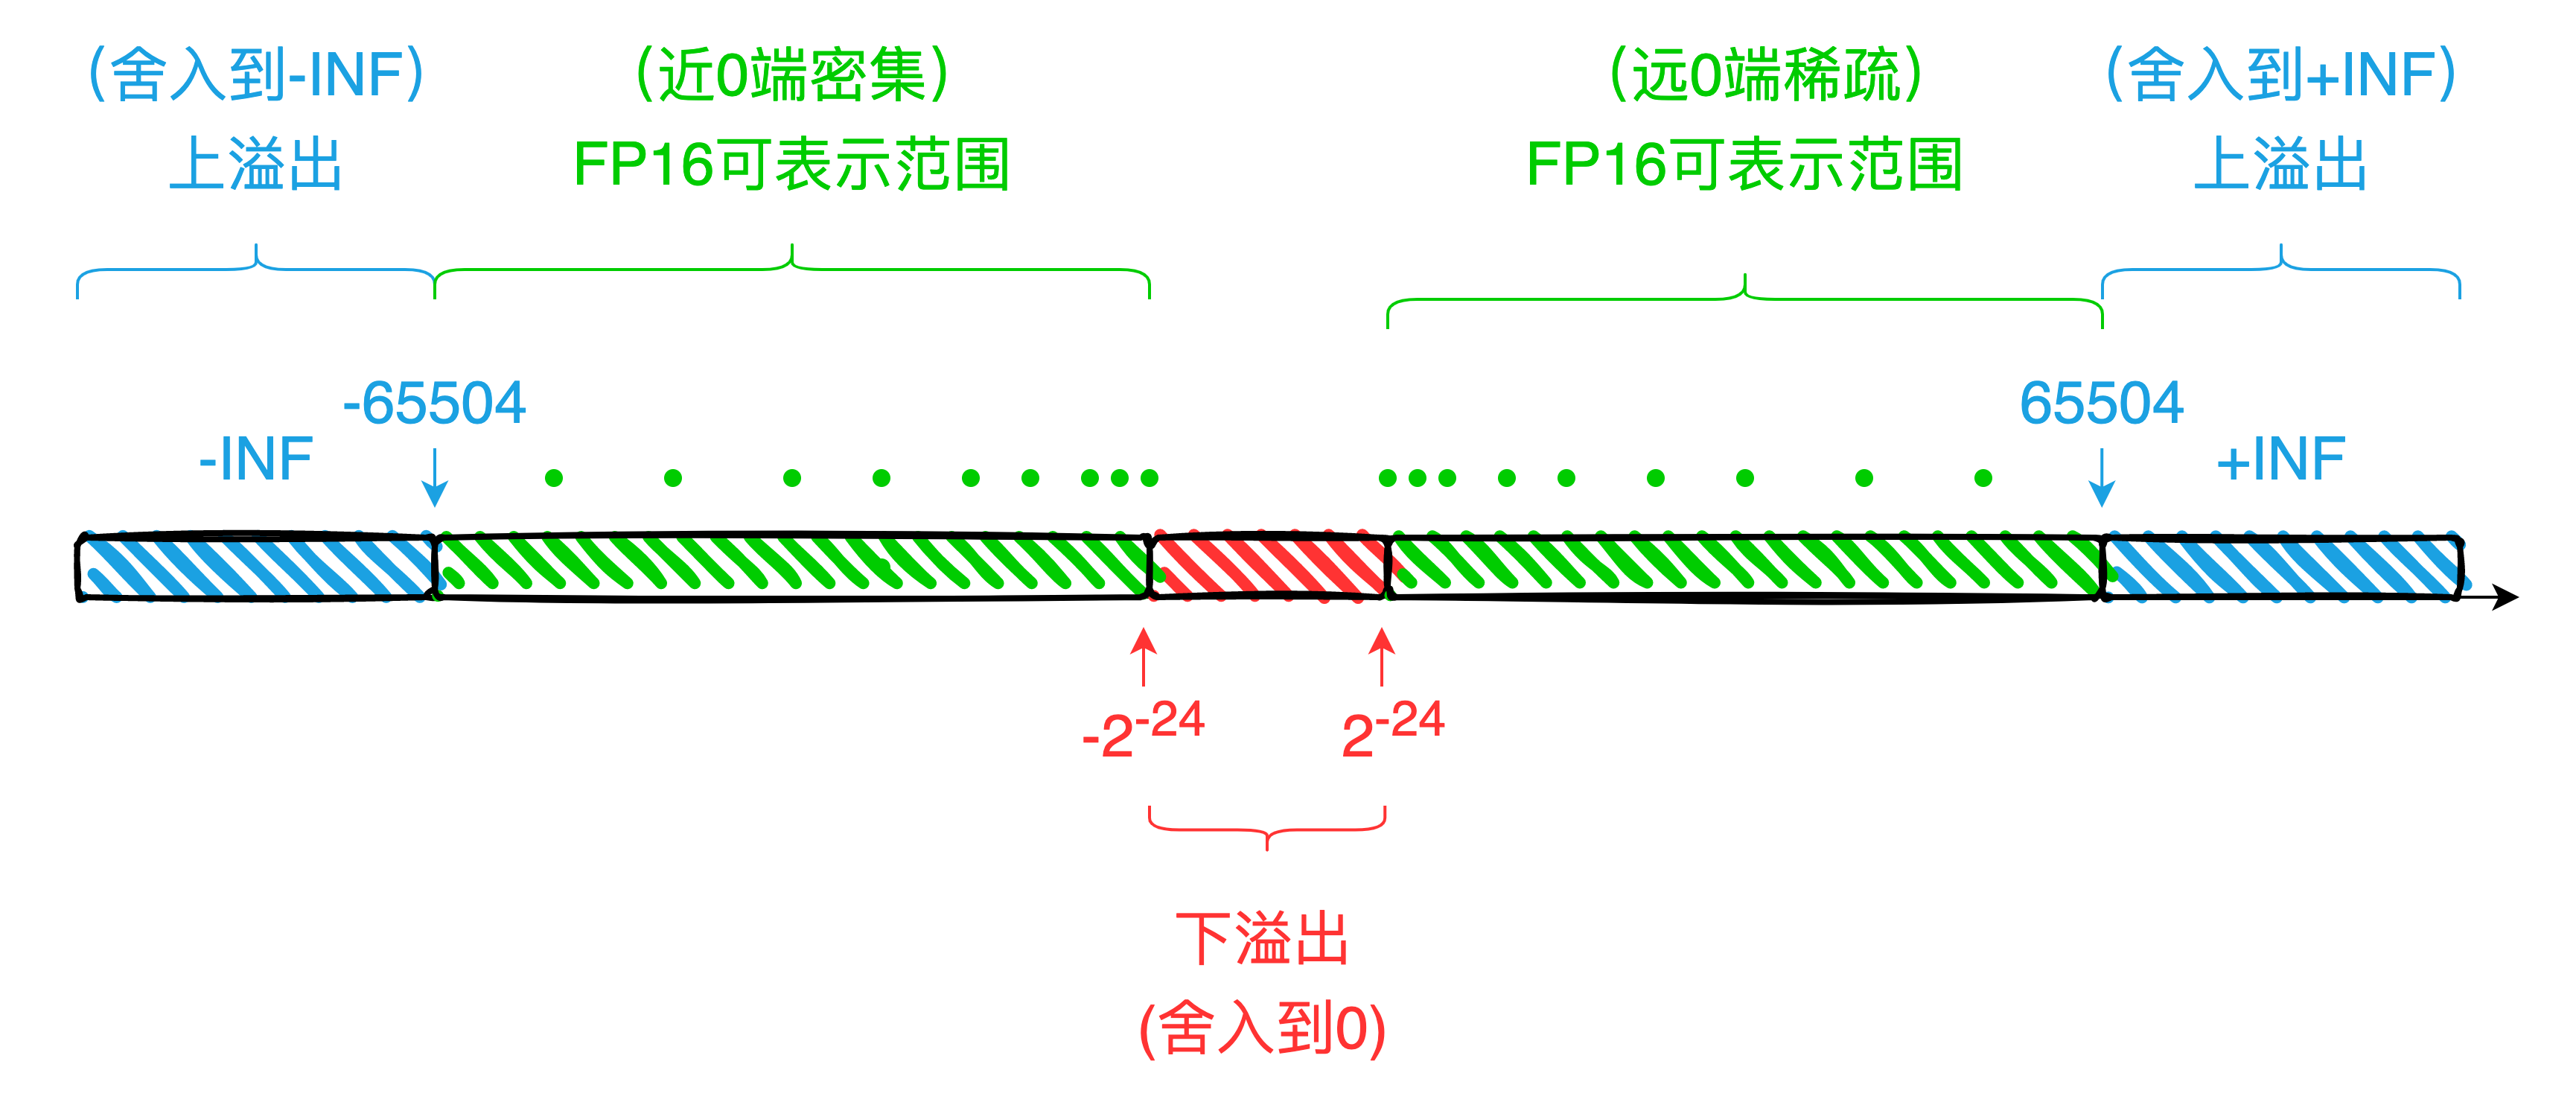
机器学习-fp16表示_fp16表示范围-CSDN博客
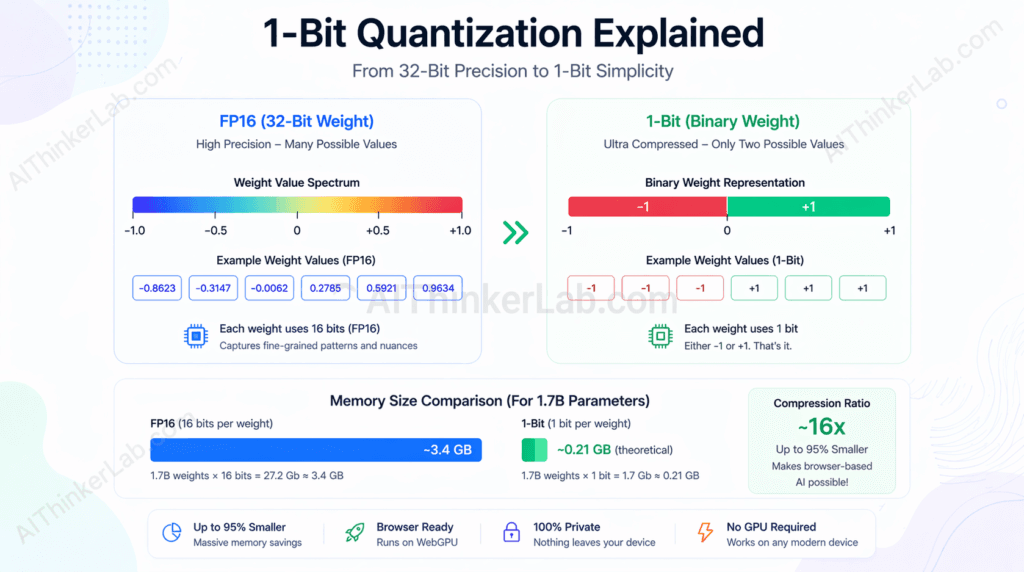
Run an AI Model Locally in Your Browser — No GPU, No Cloud
大模型中的计算精度——FP32, FP16, bfp16之类的都是什么???-CSDN博客
大模型涉及到的精度有多少种?FP32、TF32、FP16、BF16、FP8、FP4、NF4、INT8都有什么关联,一文讲清楚 - 53AI ...