Showing 119 of 119on this page. Filters & sort apply to loaded results; URL updates for sharing.119 of 119 on this page
INT8 Inference: 8-bit Quantization for AI Model Speed | Inference Systems
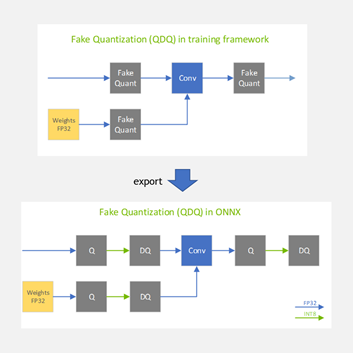
Improving INT8 Accuracy Using Quantization Aware Training and the ...
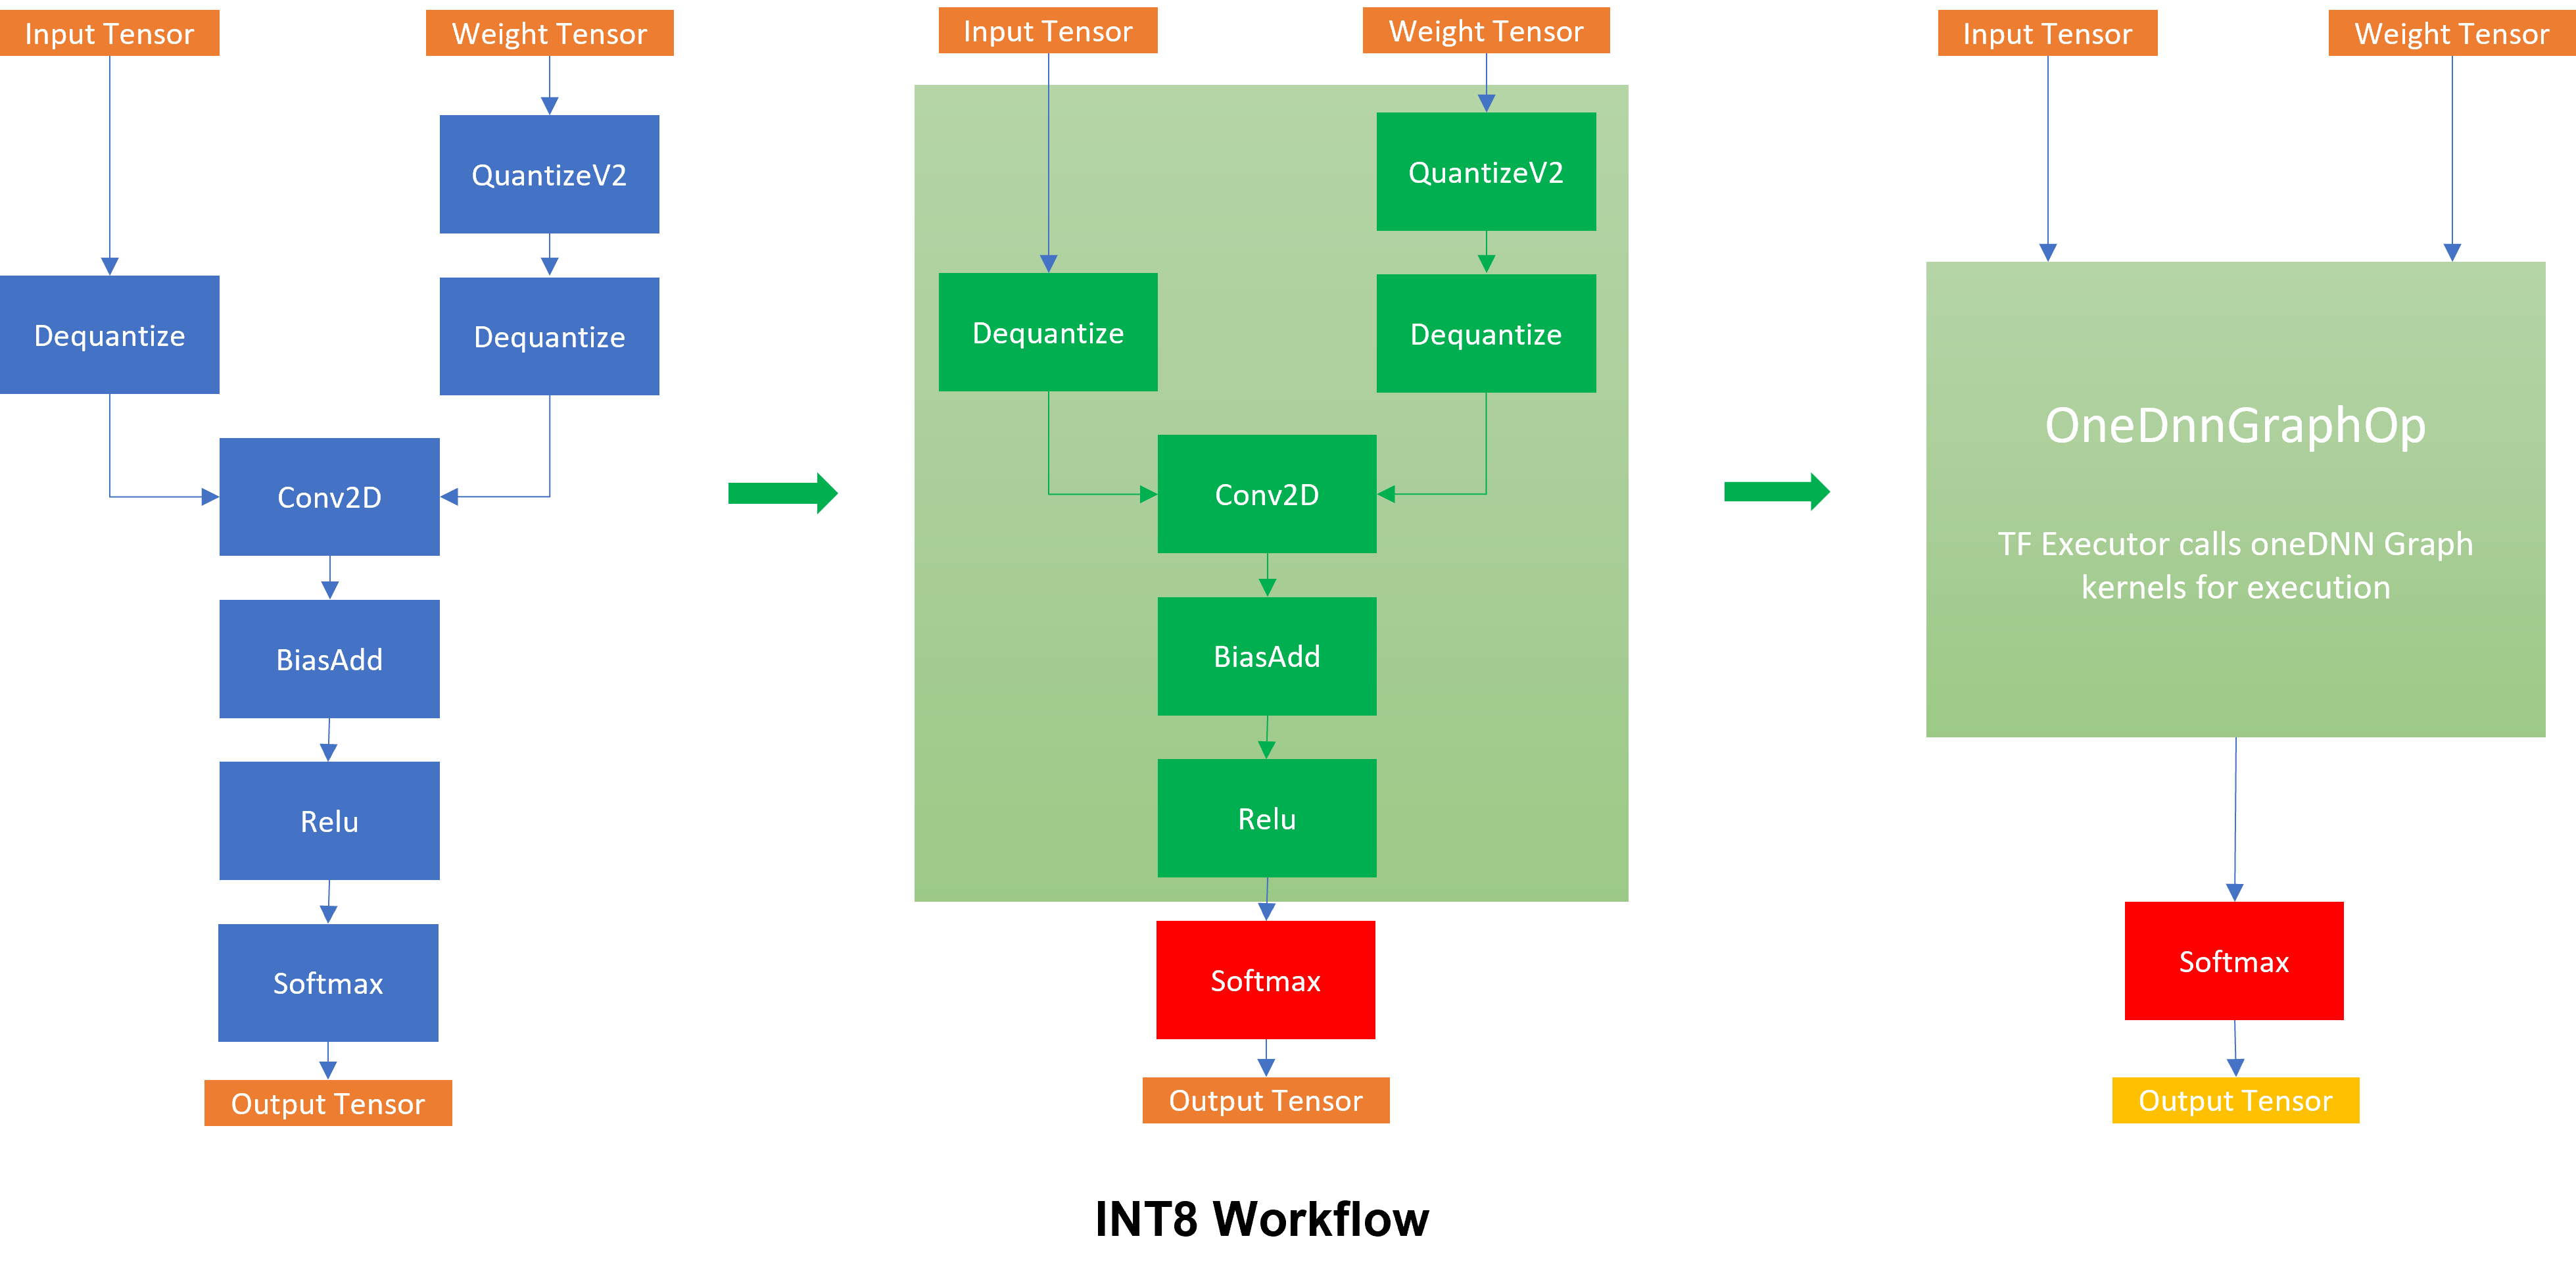
INT8 Quantization — Intel® Extension for TensorFlow* 0.1.dev1+ge26b4db ...
INT8 Quantization | amd/ZenDNN | DeepWiki
Quantization icon design | Premium AI-generated vector
Creative quantization icon | Premium AI-generated vector
Deep Learning INT8 Quantization MATLAB Simulink, 42% OFF
Deep Learning INT8 Quantization - MATLAB & Simulink
Achieving FP32 Accuracy for INT8 Inference Using Quantization Aware ...
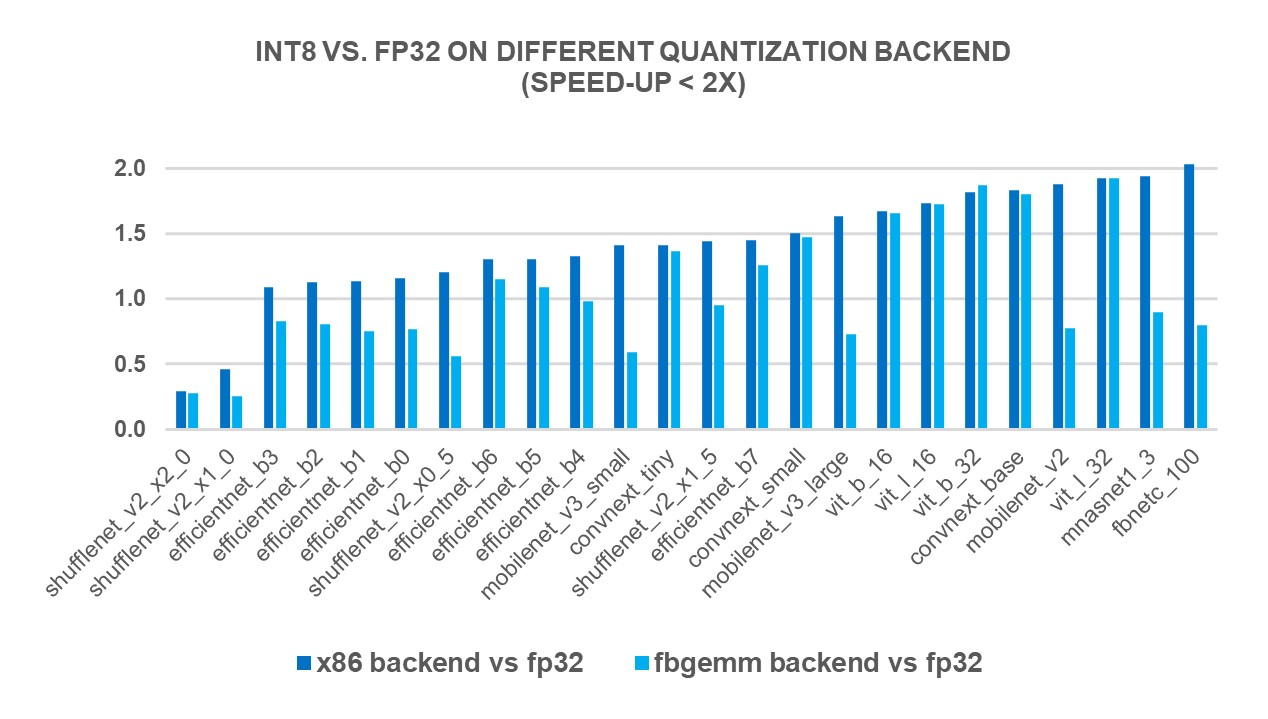
Improve Inference with INT8 Quantization for x86 CPU in PyTorch
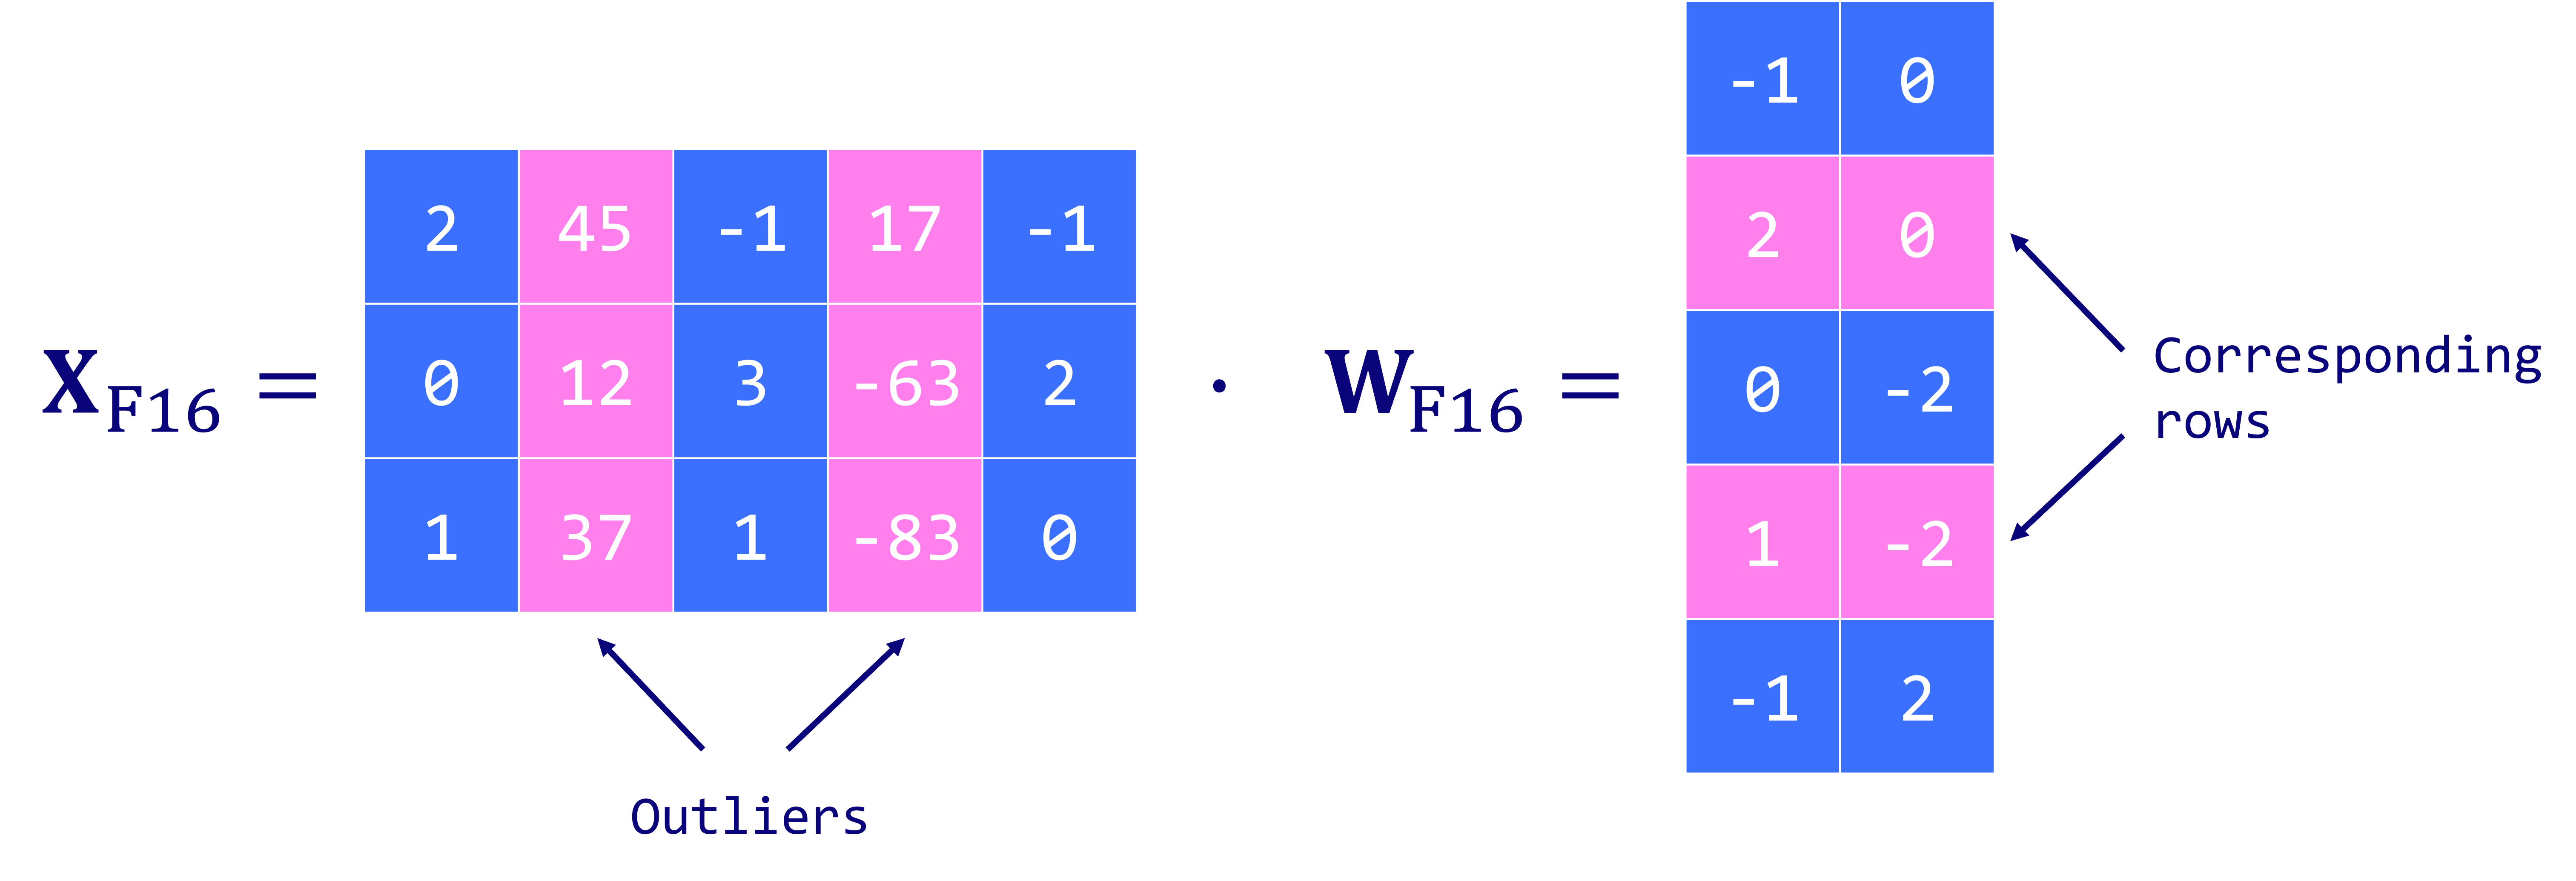
What Is int8 Quantization and Why Is It Popular for Deep Neural ...
INT8 Quantization — Practical 8-Bit Inference for LLMs | tutorialQ
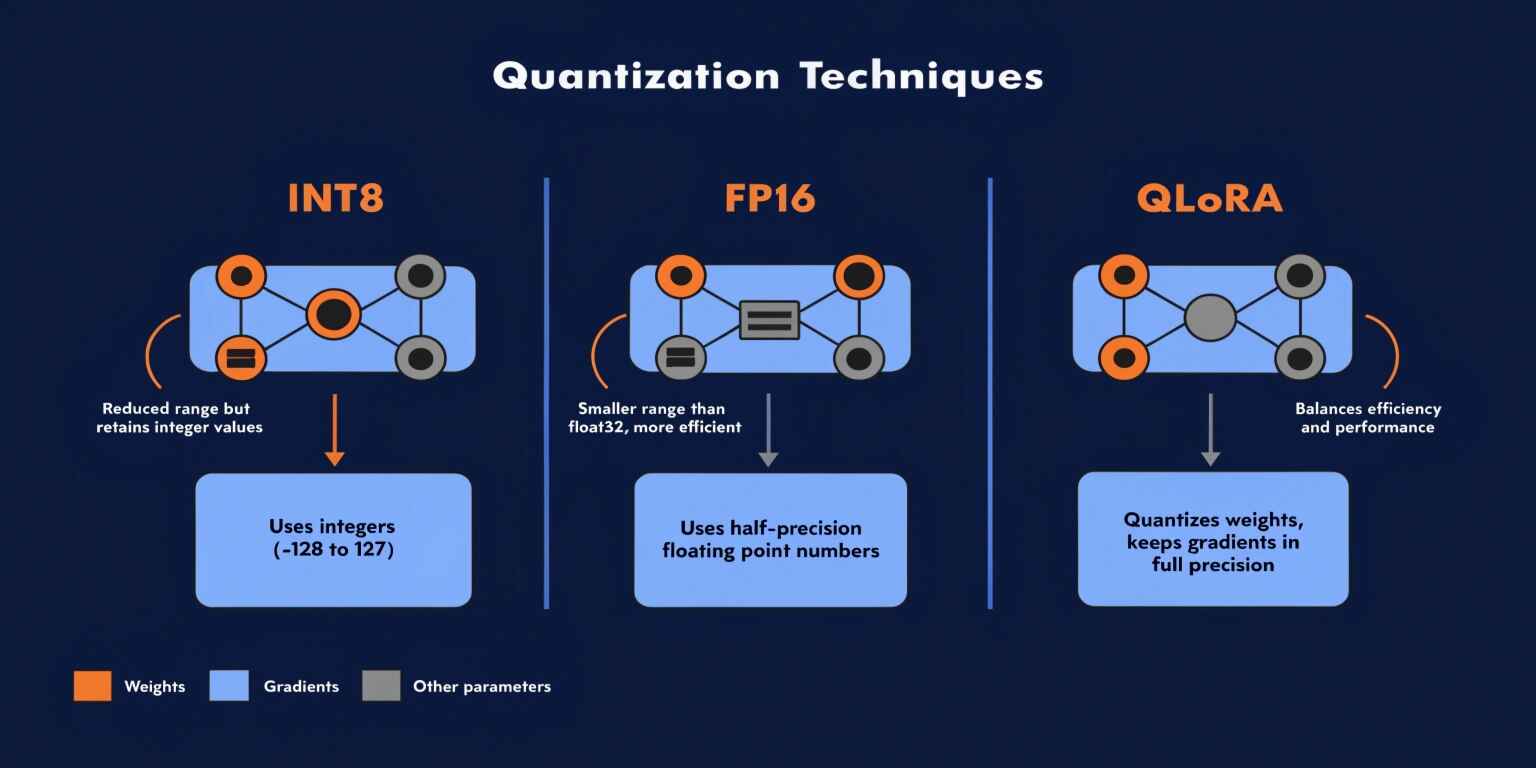
INT8 vs FP16 vs QLoRA: Modern AI Quantization Techniques Explained
GPU-Accelerated INT8 Quantization for KV Cache Compression in Large ...
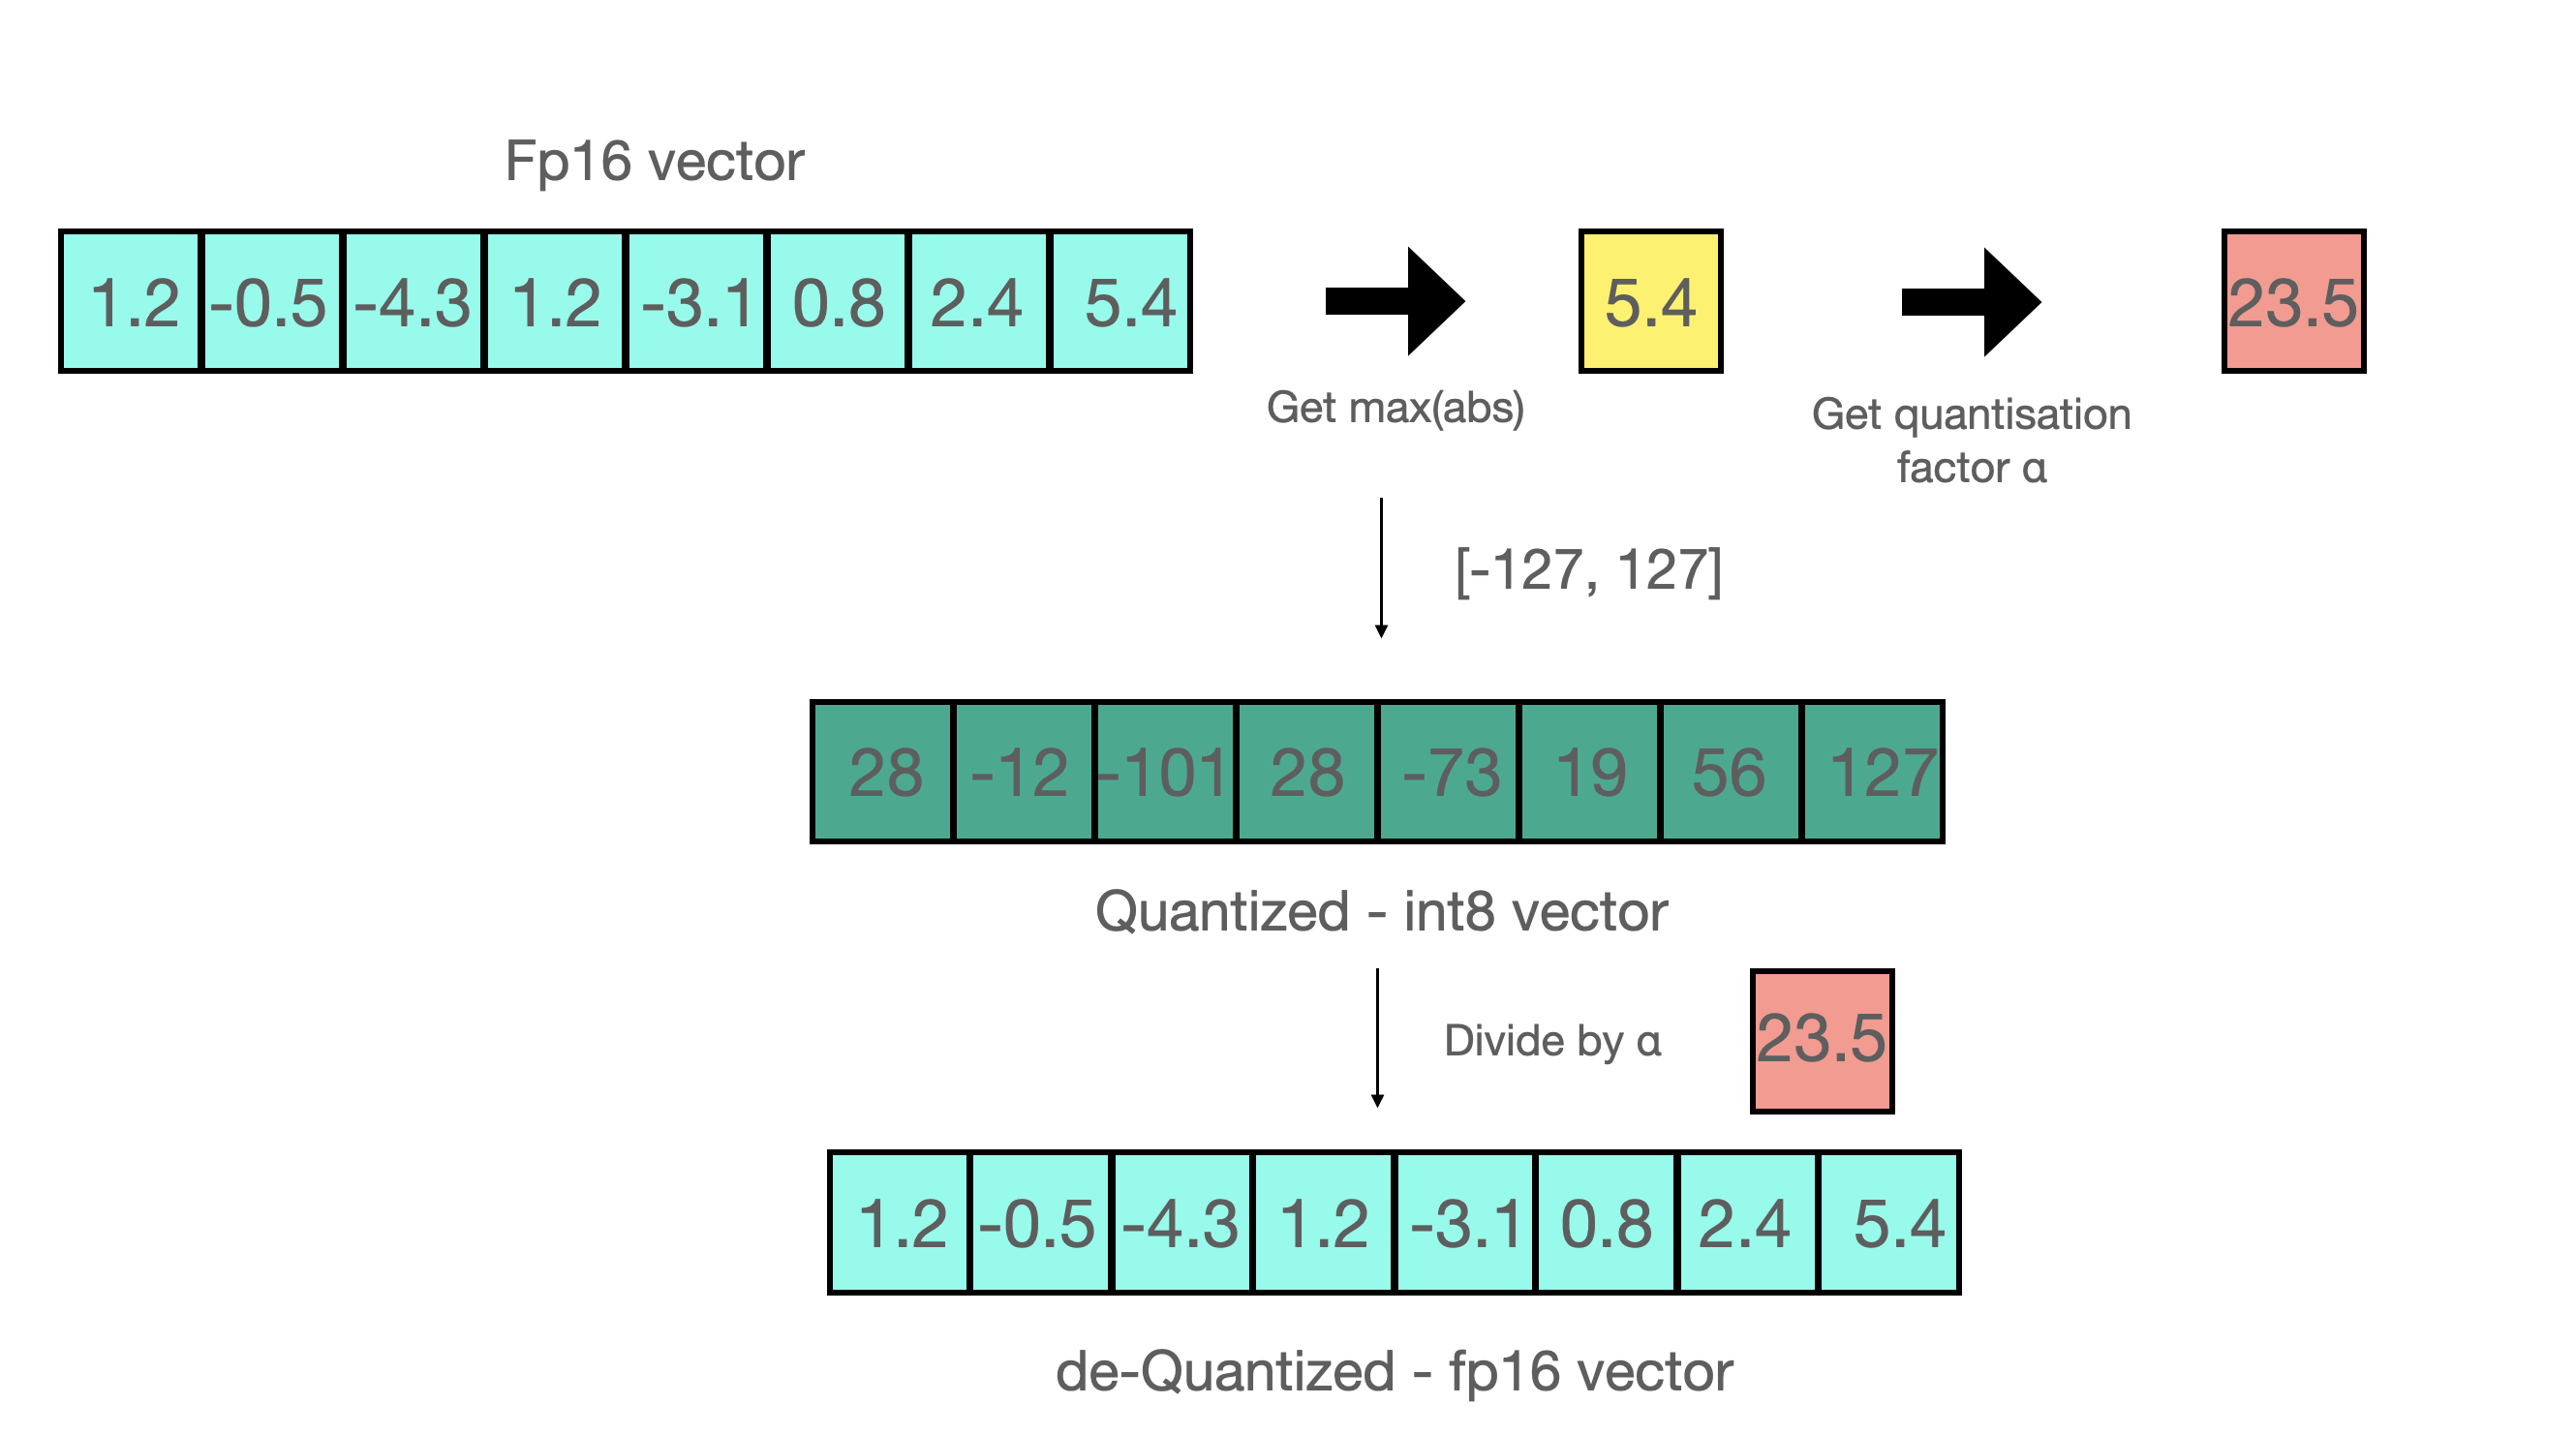
INT8 Quantization: Absmax, Smooth Quantization & Implementation ...
INT8 / UINT8 for Quantization · Issue #1187 · triton-lang/triton · GitHub
Understanding int8 neural network quantization - YouTube
INT-FlashAttention: Enabling Flash Attention for INT8 Quantization | AI ...
int8 Weight and Activation Quantization - LLM Compressor Docs
INT8 quantization with same model and different weights · Issue #2705 ...
YOLOv5 Model INT8 Quantization based on OpenVINO™ 2022.1 POT API ...
TencentARC/PhotoMaker-V2 · Quantization into int8
Update #31: Expectations for AI + Healthcare and 8-bit Quantization
A Hands-On Walkthrough on Model Quantization - Medoid AI
INT8 Quantization: Definition & AI Model Optimization | Inference Systems
Quantization Overview — Guide to Core ML Tools
The Ultimate Handbook for LLM Quantization | Towards Data Science
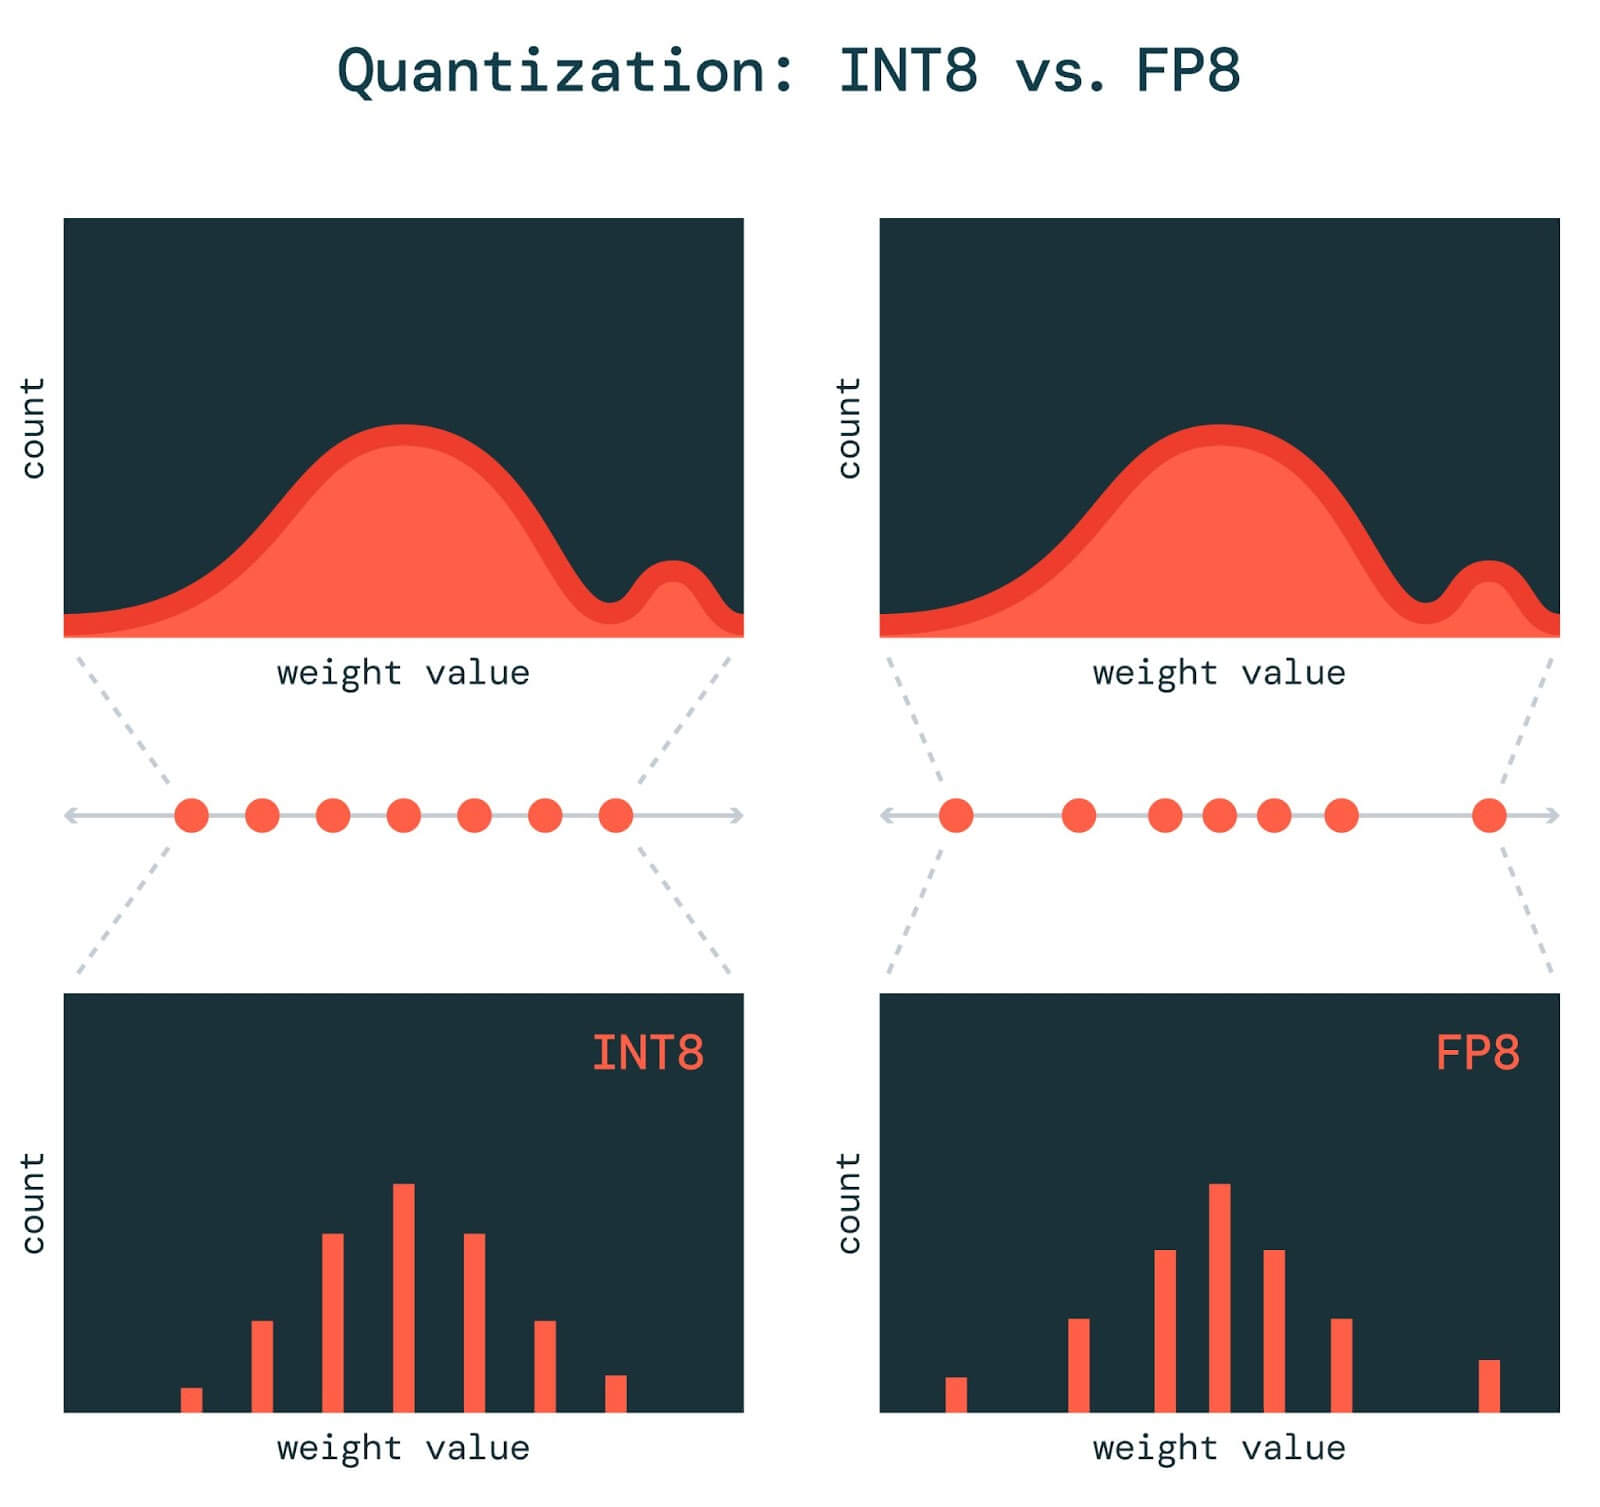
[2303.17951] FP8 versus INT8 for efficient deep learning inference
INT8 Quantization: Absmax - Interactive
Improving LLM Inference Latency on CPUs with Model Quantization ...
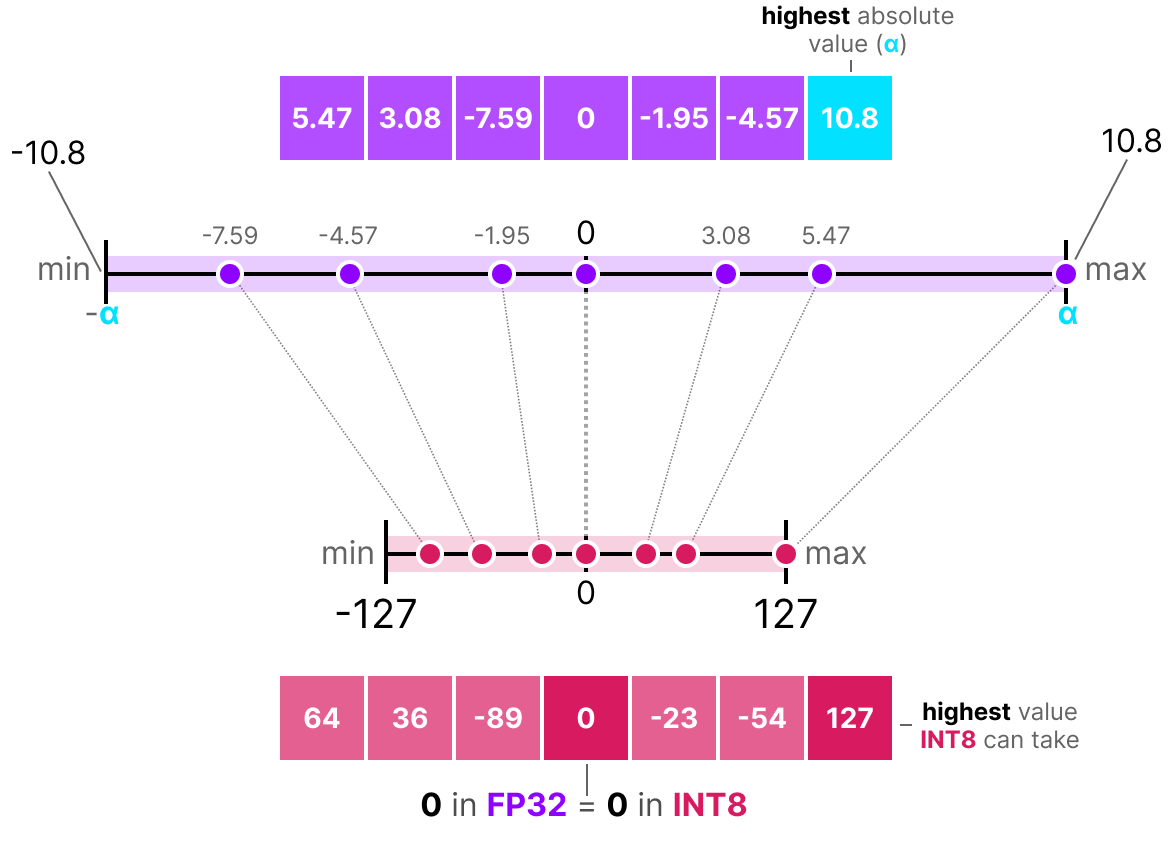
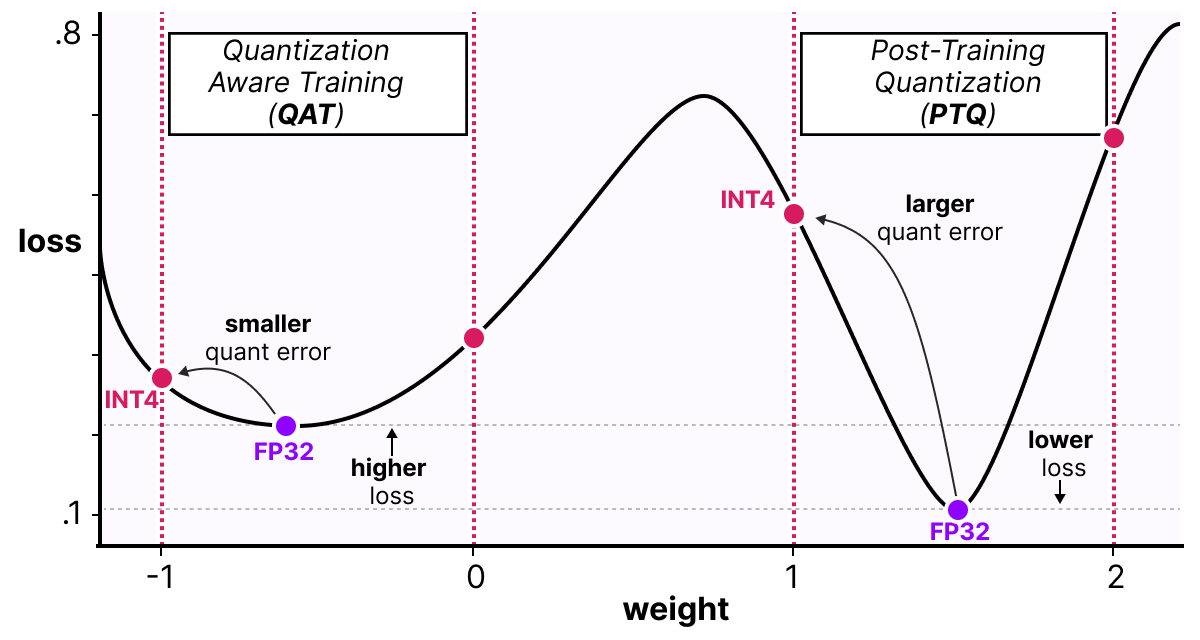
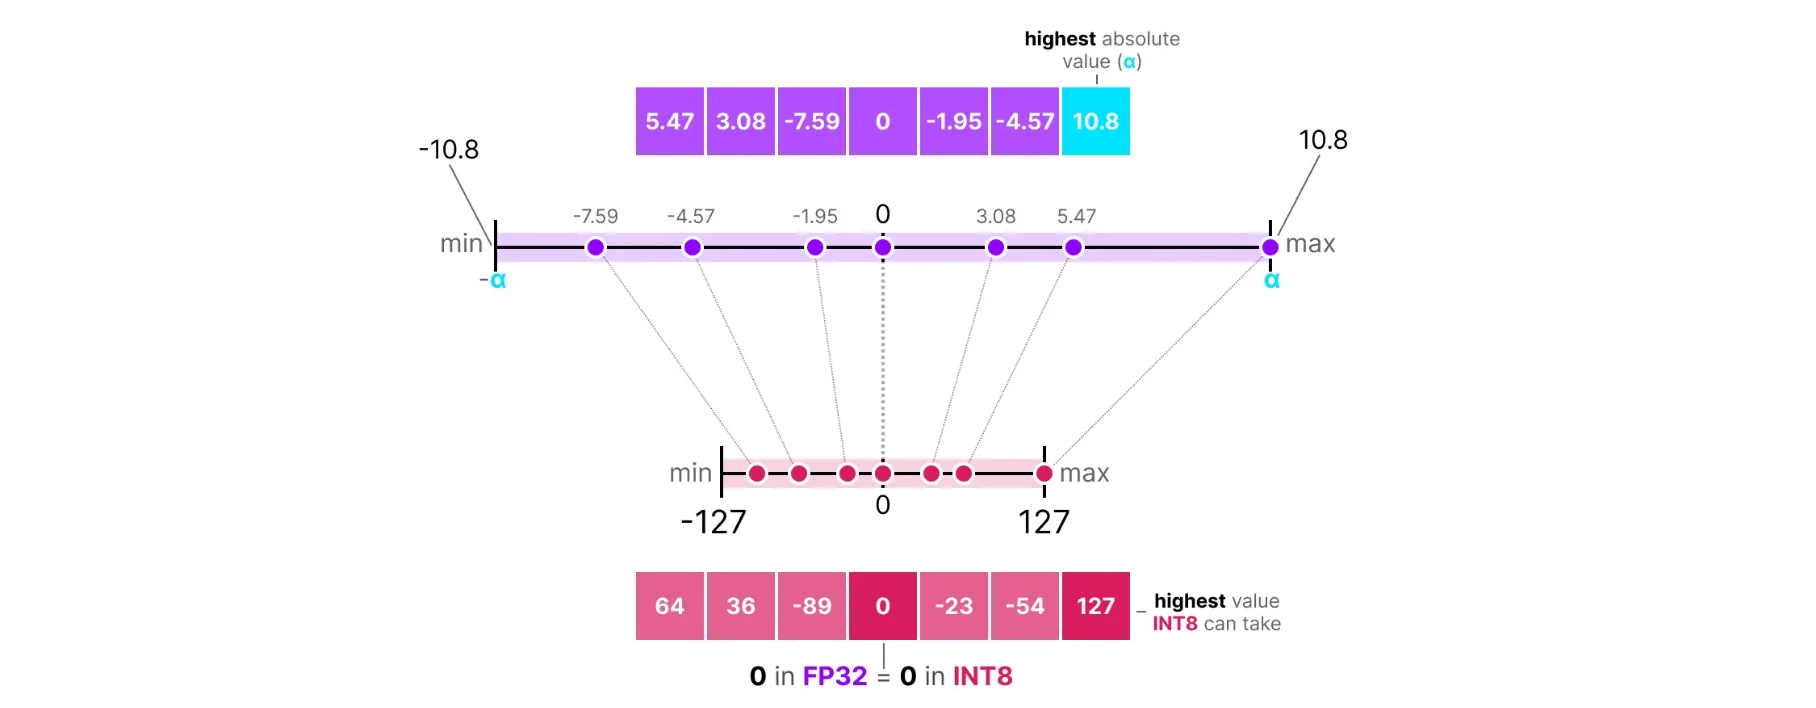
A Visual Guide to Quantization - by Maarten Grootendorst
Fast and Accurate GPU Quantization for Transformers
利用 NVIDIA TensorRT 量化感知训练实现 INT8 推理的 FP32 精度 - NVIDIA 技术博客
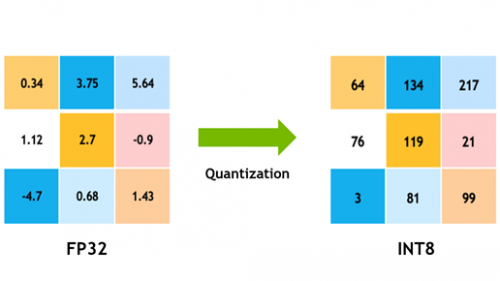
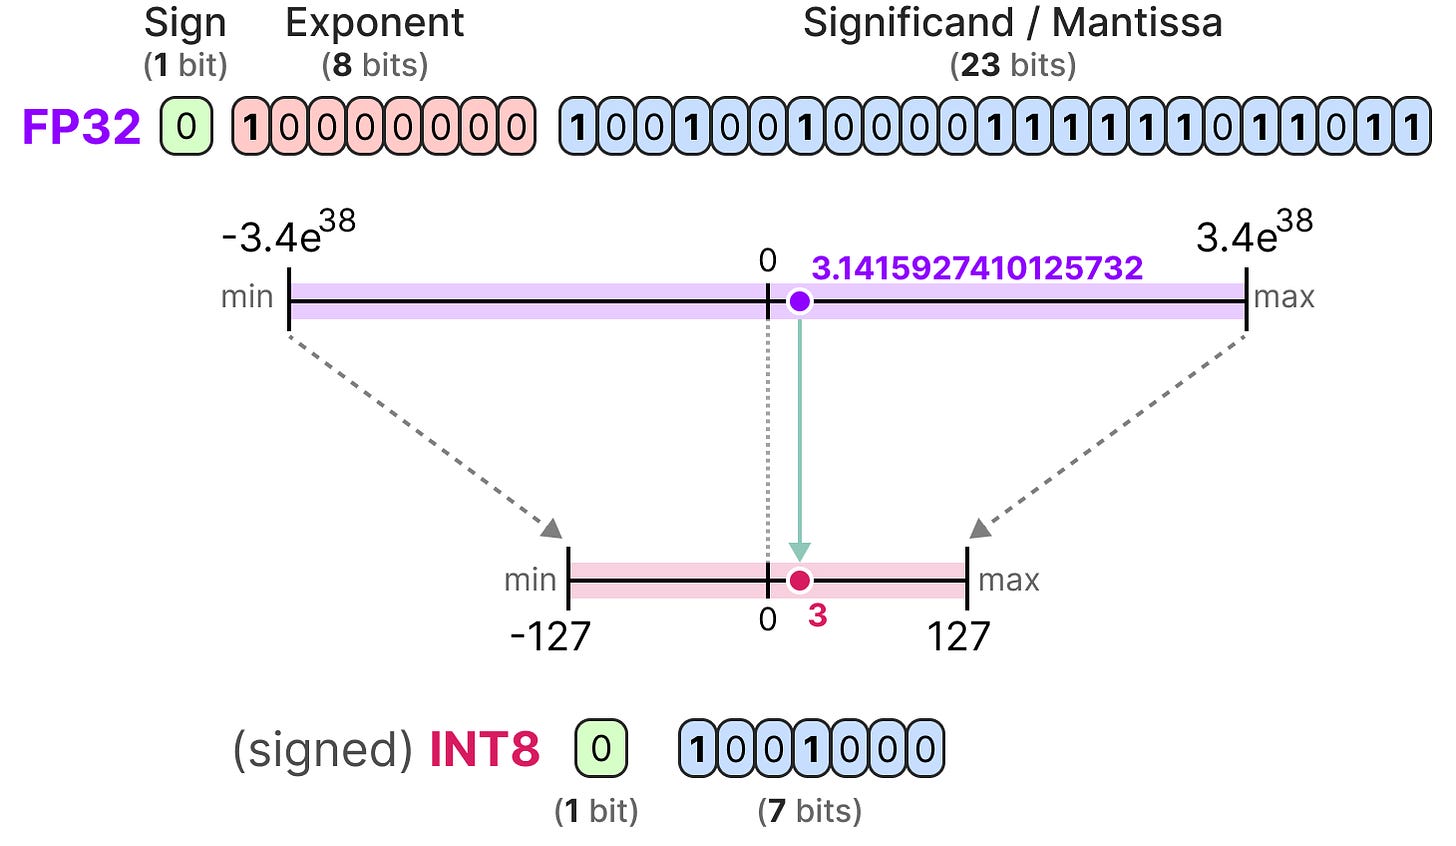
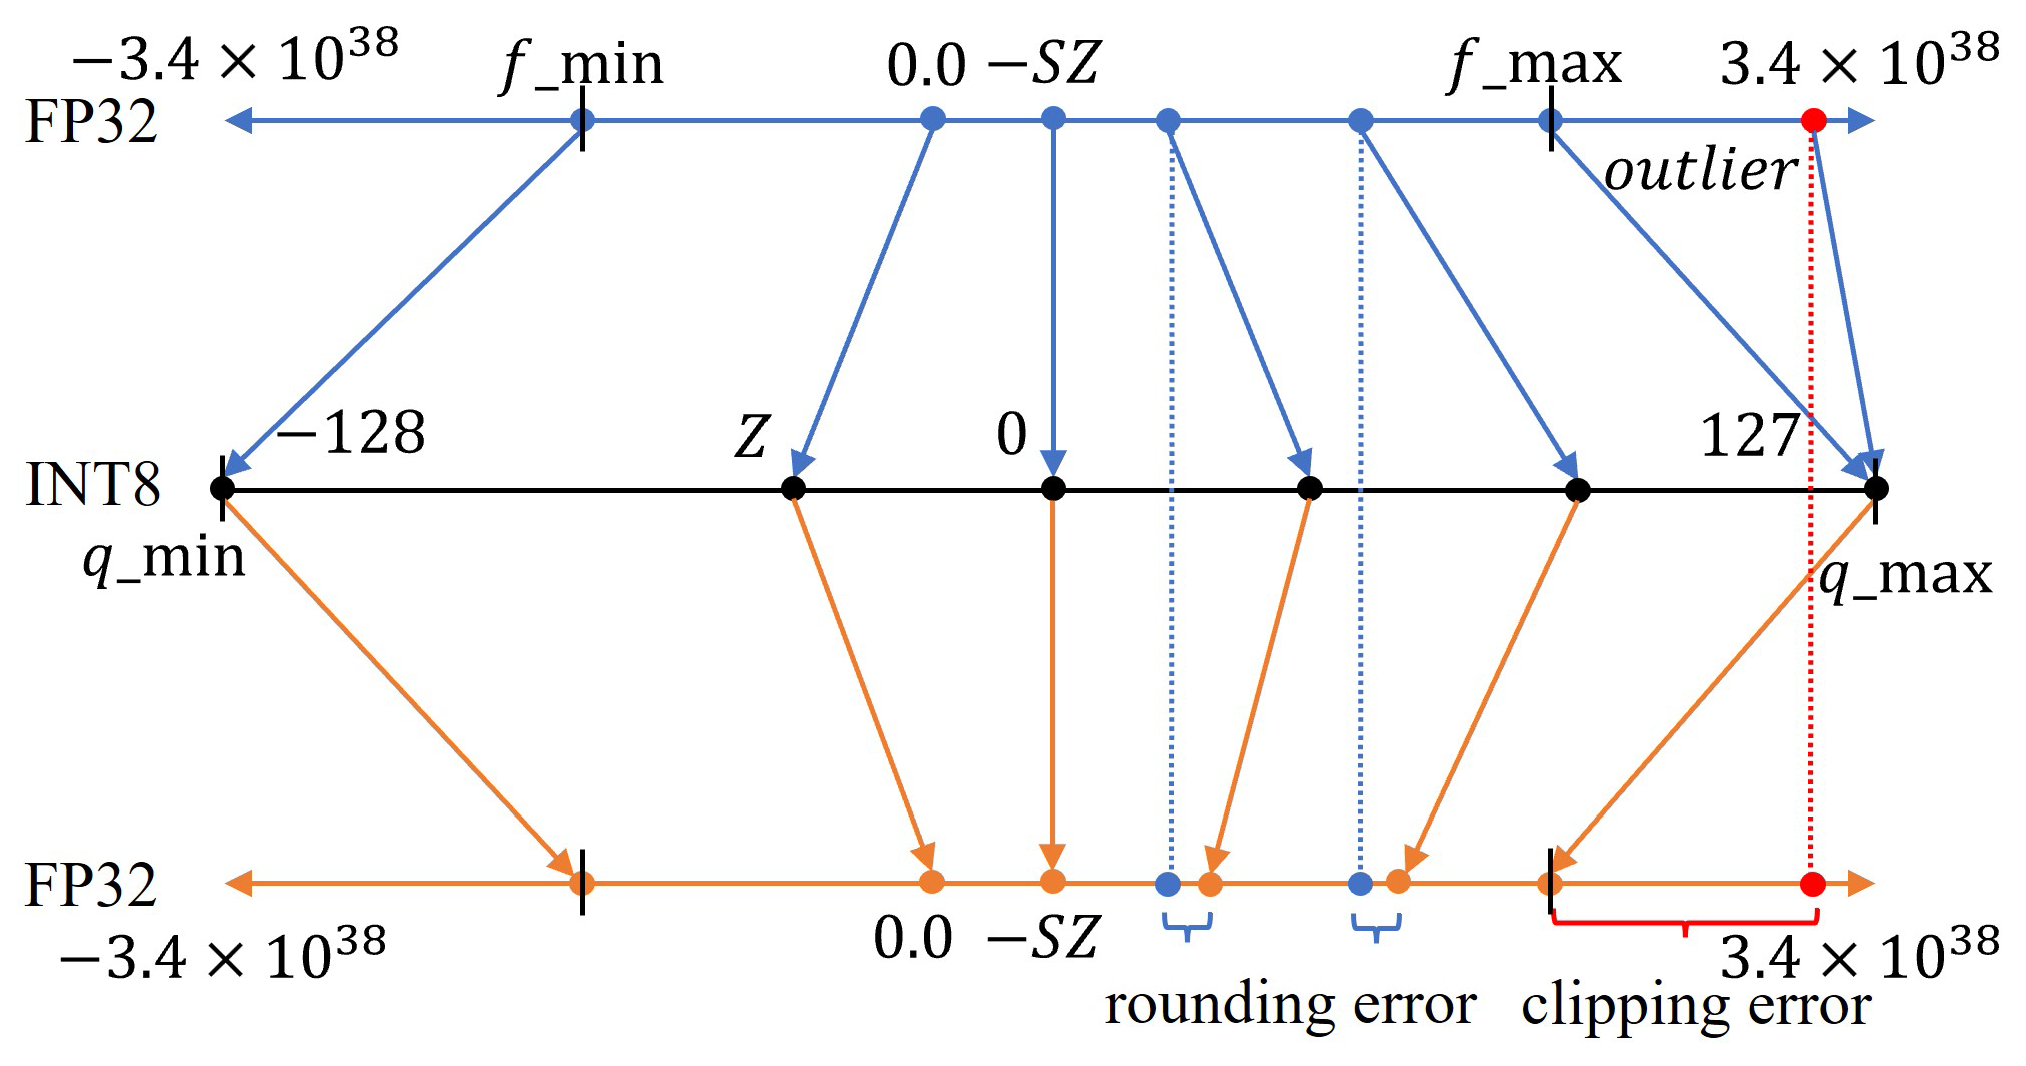
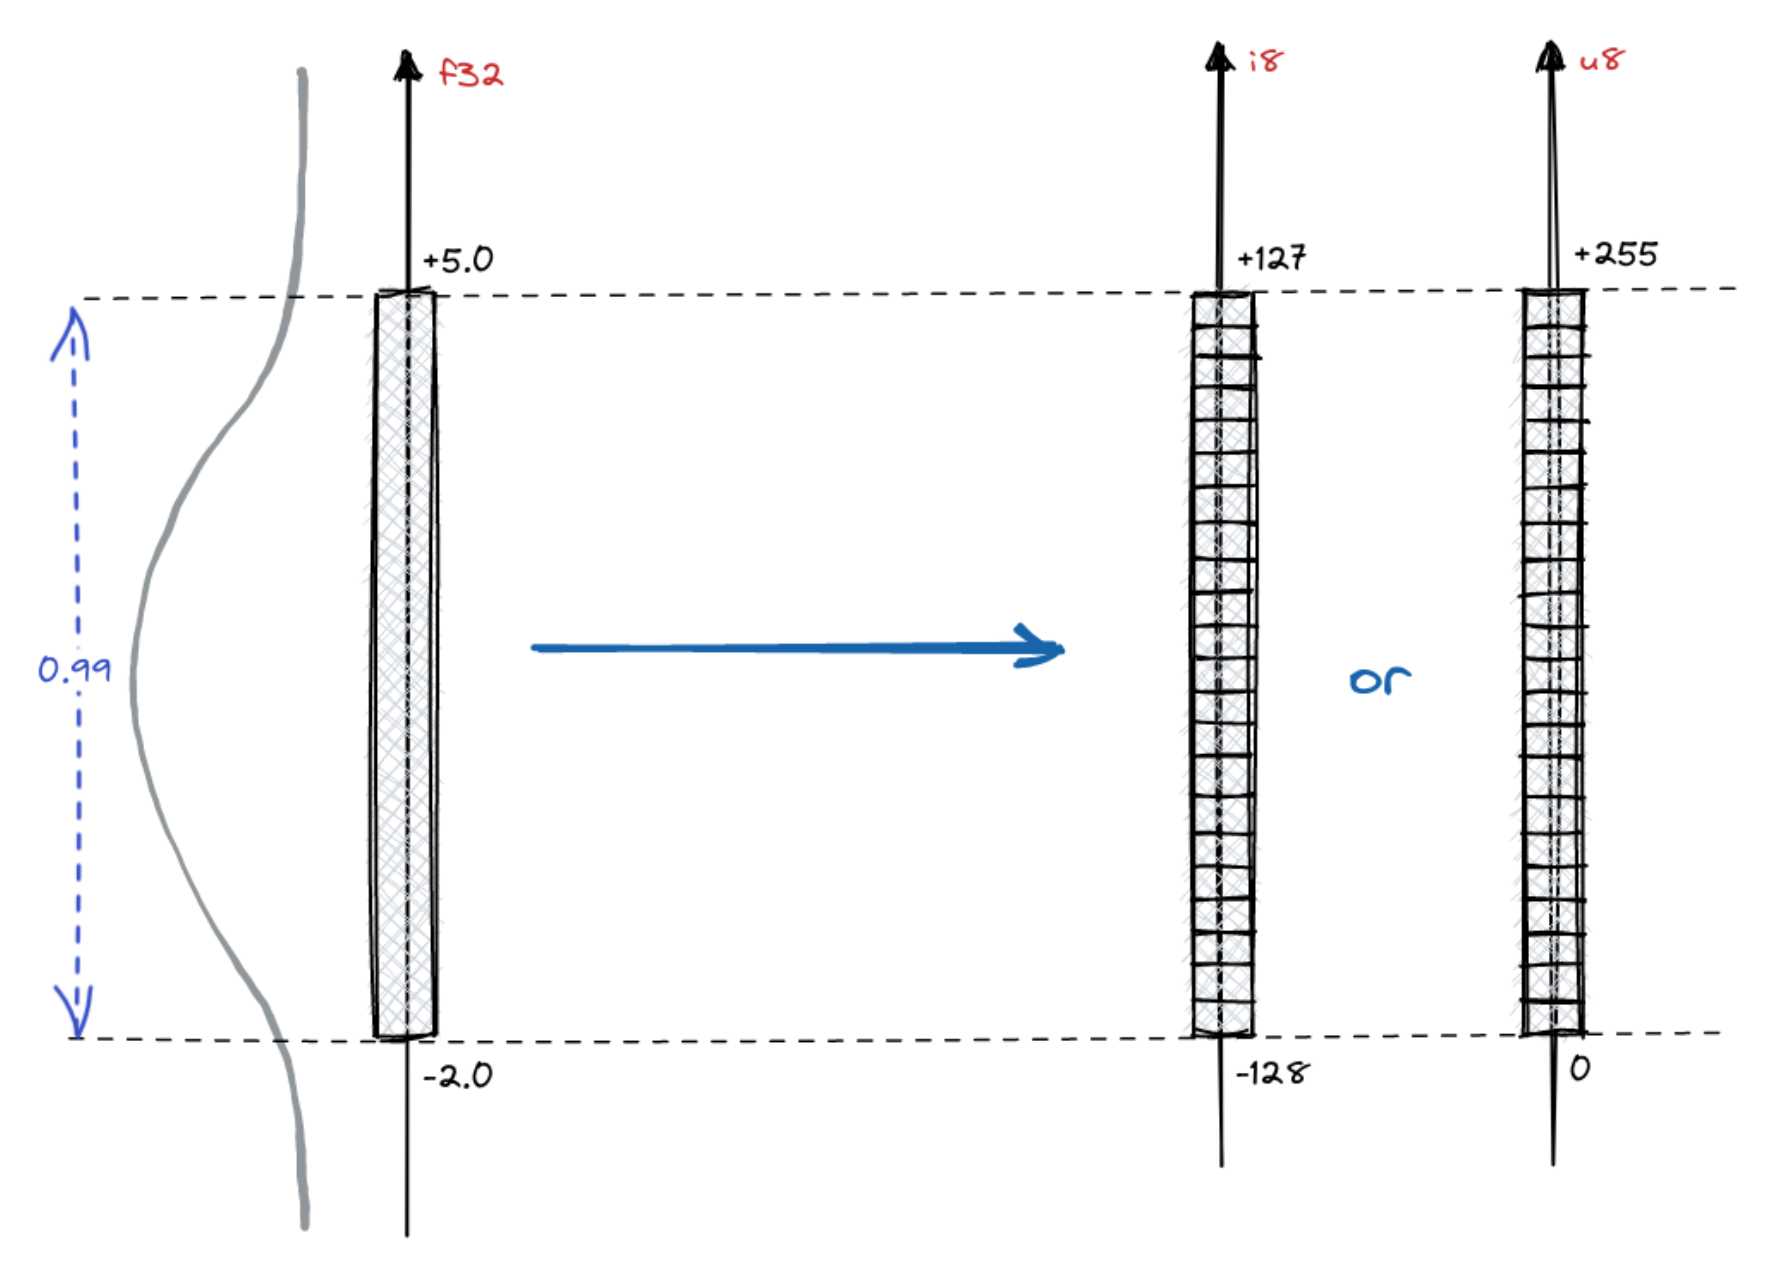
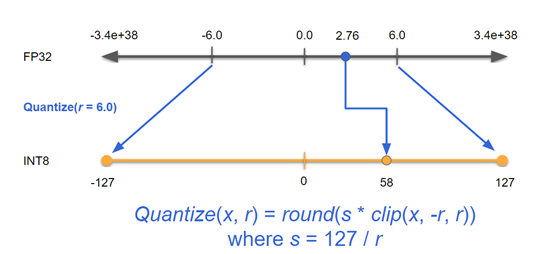
Quantization from FP32 to INT8. | Download Scientific Diagram
8-bit Integer Quantization in Keras
Quark Quantized INT8 Models - a amd Collection
Quantitative Meticulous Yellow shadow icon
Quantization for Real Systems — INT4/INT8 Deploy | tutorialQ
[Deep Learning] 양자화 Quantization - 1. 정의, 사용 경우 및 종류
Mastering QLoRa : A Deep Dive into 4-Bit Quantization and LoRa ...
A Visual Guide to Quantization - Maarten Grootendorst
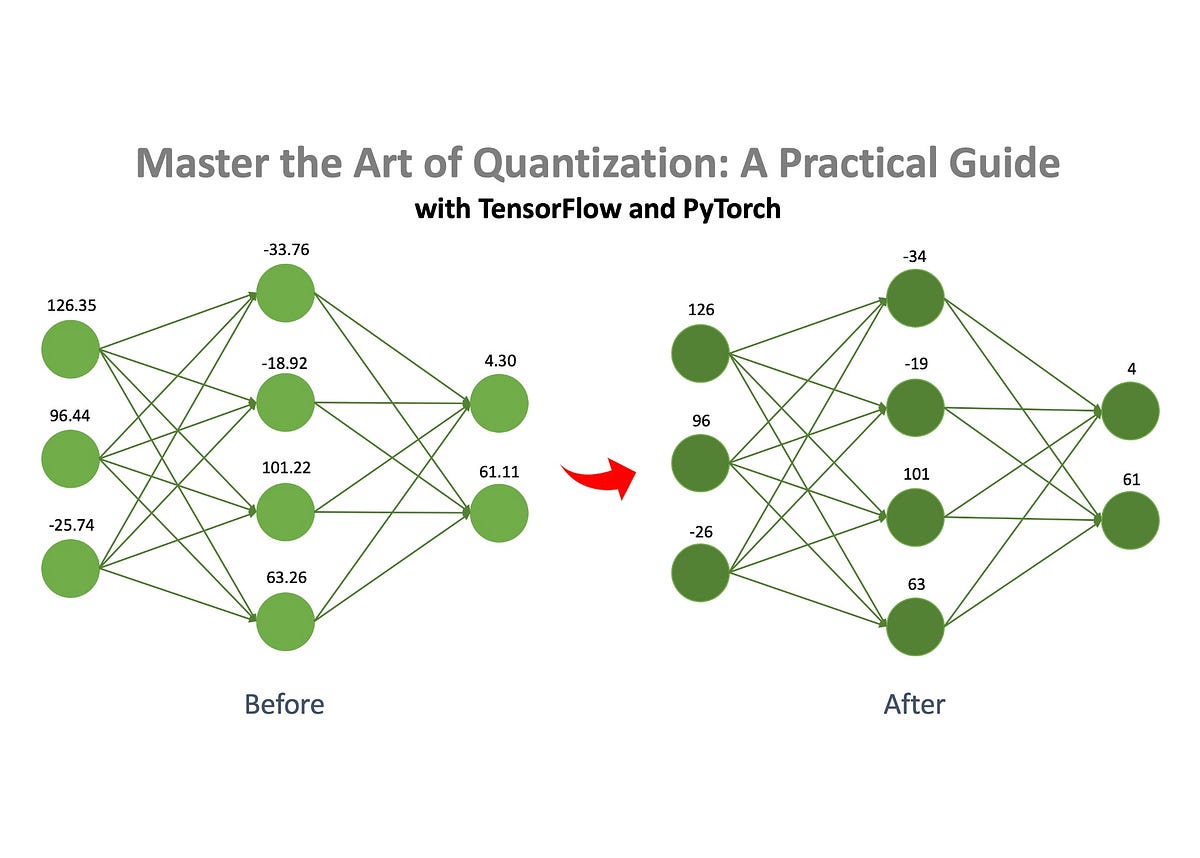
A Practical Guide to Neural Network Quantization
A conventional integer quantization architecture for inference and the ...
Quantum Computing Line Icon Set. Qubit, Entanglement, Quantum Processor ...
ELU int8 model quantized with Dequantize/Quantize stubs · Issue #60789 ...
Quantum Entanglement Flat Icon 39495594 Vector Art at Vecteezy
Excuse me, does the 3060Ti graphics card support TensorRT int8 ...
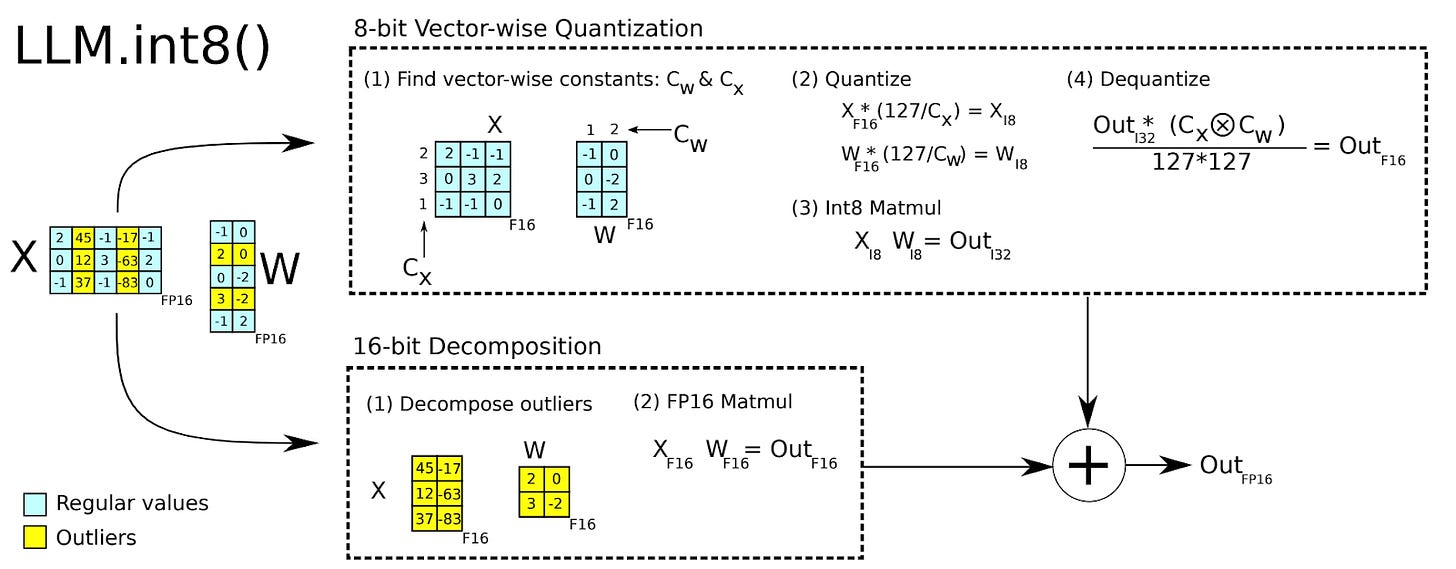
llm.int8(): 8-bit Quantization for Transformers | MaximoFN
Mapping issue in Quantization
Quantitative Generic Gradient icon
Int8 Quantized model same output on different inputs · Issue #23330 ...
The Complete Guide to LLM Quantization with vLLM: Benchmarks & Best ...
How TinyML uses quantization to make AI models tiny | Salah-eddine ...
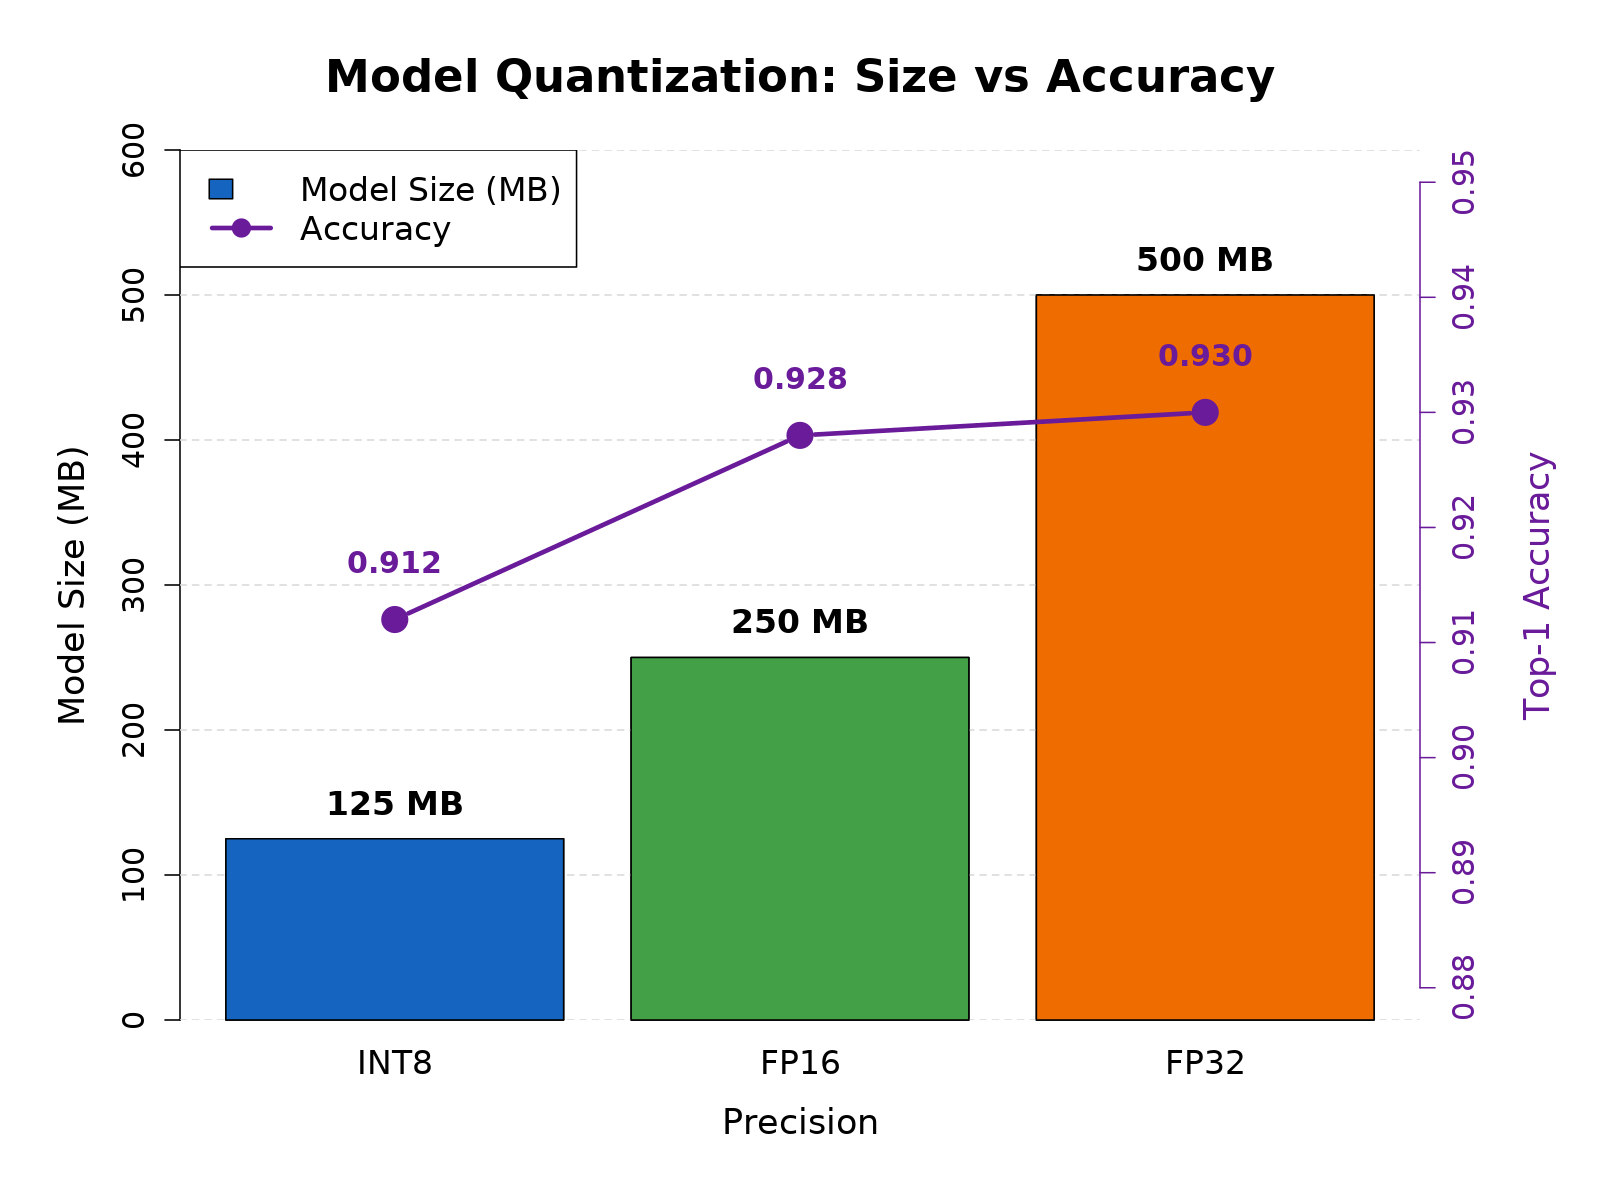
Quantization: INT8 vs FP16 vs FP32 | MetricGate
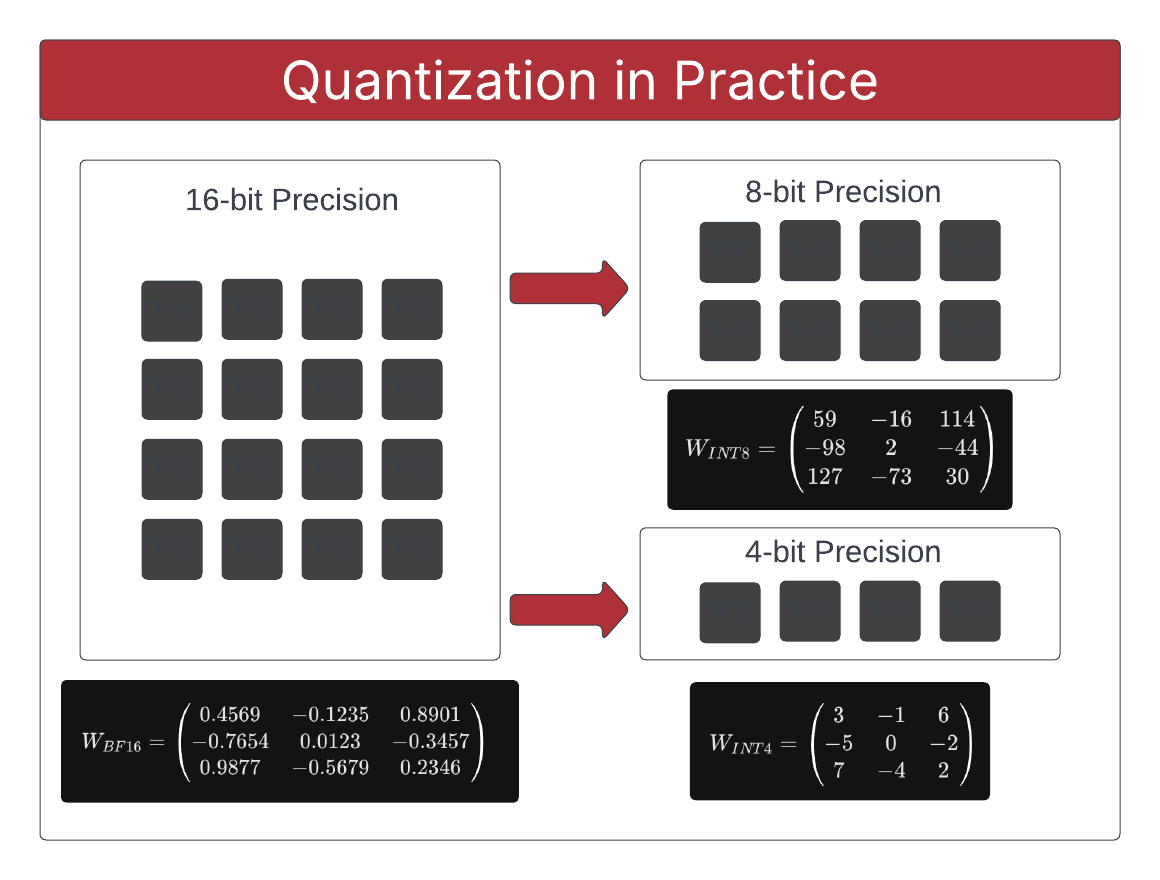
INT8, INT4 and Other Integer Types for Quantization
Quantization INT8/INT4 — Ít bit hơn, nhỏ hơn 8x, vẫn chính xác | Trồi Sinh
Local Large Language Models | Int8
KV Cache Compression: Eviction, Quantization & H2O Algorithm ...
How Quantization Works & Quantizing SAM
(PDF) FP8 versus INT8 for efficient deep learning inference
Introducing Post-Training Model Quantization Feature and Mechanics ...
Introduction to Weight Quantization | Towards Data Science
How to Convert a Custom-Trained YOLO11 Model to a TensorRT INT8 Engine ...
La quantization des LLM : comment faire tourner une IA sur votre ...
Optimizing LLMs for Performance and Accuracy with Post-Training ...
BridgePhase » Insights
GPU memory requirements for serving Large Language Models | UnfoldAI
Serving Quantized LLMs on NVIDIA H100 Tensor Core GPUs | Databricks
INT8模型量化:LLM.int8 - 知乎
Sparsity in INT8: Training Workflow and Best Practices for NVIDIA ...
A Gentle Introduction to 8-bit Matrix Multiplication for transformers ...
GitHub - xuanandsix/Tensorrt-int8-quantization-pipline: a simple ...
50张图解密大模型量化技术:INT4、INT8、FP32、FP16、GPTQ、GGUF、BitNet_gptq量化-CSDN博客
Efficient Memory Management In Mobile Apps – peerdh.com
Deep Learning Performance Characterization on GPUs for Various ...
想加速模型推理?试试用int8量化呢_pytorch qat量化教程 pytorch模型int8量化-CSDN博客
ch1
INT4, INT8, and When Accuracy Actually Drops | Luca Berton
[2407.09111] Inference Optimization of Foundation Models on AI Accelerators
PyTorch模型INT8量化基础_pytorch int8量化-CSDN博客
Floating-point arithmetic for AI inference — hit or miss? | Qualcomm
GitHub - Armitawh/Edge-ML-Quantization-Benchmark: Hardware-aware ...
Working with Quantized Types — NVIDIA TensorRT 10.10.10 Developer Guide ...
在 Xeon 上透過 🤗 Optimum Intel 加速 StarCoder:Q8/Q4 和投機解碼(Speculative ...
Bedovyy/Anima-INT8 · Hugging Face
What Is A Quantizer at Tyson Macgillivray blog
GitHub - caslabai/yolov3tiny_tensorflow_int8_quantized: yolov3_tiny ...
[2307.09782] ZeroQuant-FP: A Leap Forward in LLMs Post-Training W4A8 ...
Perform Model Optimization Using Intel® Neural Compressor
大模型LLM.int8()量化技术原理与代码实现-CSDN博客
Quantization, A Core Technology for Building ‘Lightweight’ AI Models
标量量化:背景、实践及更多 | Qdrant 向量数据库
Cuantización FP16/INT8 para Inferencia de LLM
pytorch_quantization模型int8量化 - 知乎
Sambhavnoobcoder/gpt2-test-quantization-Quanto-int8-Quanto-int8 ...
Mì AI - Model Quantization, model nhẹ, nhanh hơn trên... | Facebook
Object Detection on GPUs in 10 Minutes | NVIDIA Technical Blog
[2305.12356] Integer or Floating Point? New Outlooks for Low-Bit ...
大模型量化部署进阶:从 INT8/INT4 原理到高性能推理实战 - 知乎
从TensorRT看INT8量化原理 - nanmi - 博客园
Ableton Note Manual | Ableton
RobAgrees/quantized-dia-1.6B-int8 · Hugging Face